

Submitted:
12 October 2025
Posted:
13 October 2025
You are already at the latest version
Abstract
The effect of different meal plans on the protein intake of individuals with chronic conditions will be discussed in this paper. It made comparisons between the high-protein and the balanced diets according to dietary, demographic, and physiological data which were analysed by use of Analysis of Variance (ANOVA), Analysis of Covariance (ANCOVA), Multivariate Analysis of Variance (MANOVA), and regression. The results show that the high-protein diets significantly increase the protein intake particularly in individuals with chronic diseases, yet the rest of the meal plans have conflicting results. Protein consumption is a sound indicator of the meal plan type despite the variation upon removal of the other variables like age, Body Mass Index (BMI) and exercise frequency. The difference between high protein and balanced diet groups is very high and can be disclosed by Post-hoc Tukey Honestly Significant Difference (HSD). The results demonstrate the importance of the individual diets in comparison with the more generalized standards of nutrition, and the importance of customized nutrition as the indicator of the correct one self-management of chronic diseases and future success in health.
Keywords:
meal planning
; protein intake
; chronic diseases
; nutrition and dietetics
; dietary intervention
; food science
; health outcomes
1. Analysing the Effect of Different Recommended Meal Plans on Protein Intake among Individuals with Chronic Diseases
The diseases are such long-term conditions as diabetes, high blood pressure and kidney disease among others that is one of the most widespread and prevailing diseases of the world. Handling of the disease is multifaceted as far as treatment of these diseases is concerned where medical treatment is one of the aspects, lifestyle modifications, and nutrition are other aspects (Alyafei & Daley, 2025). Protein is among the most significant elements of the various nutrients that play significant roles in chronic disease management. Protein is important in the wide range of activities that the body performs including immune defence, muscle repair, cell regeneration and normal metabolism. However, due to the altered metabolic demands, malnutrition of the body, and other comorbidities, patients with chronic diseases tend to experience a challenging period of satisfying their nutritional requirements, in particular, protein-based ones.
The medical experts usually prescribe some diets in case of the patients having chronic diseases in order to allow the patient to manage the condition and sustain adequate amounts of nutrients. Such meal plans can consist of high-protein diets and balanced diets, which can be the ones to be recommended to ensure the maintenance of the muscle mass, malnutrition prevention, and addressing the symptoms that accompany the disease. Protein-rich diets have been strongly advised to individuals who need to maintain or gain weight because of the bulk of muscle particularly in individuals with illnesses such as kidney disease that may result into the loss of proteins (Carballo-Casla et al., 2024). Rather, the balanced diets are supposed to provide a more diversified solution, which is sufficient to provide the required nutrition of all the essential nutrients, like protein, and in addition, being aware of the health needs, the nature of the disease, and the lifestyle of the individual.
Despite the extensive use of these diet interventions, there is no clear evidence of the impact of the varying recommended meal plans and the high protein and balanced diets in particular on the protein intake of individuals with chronic diseases (Carbone et al., 2025). Even though clinical guidelines tend to recommend a specific dietary intake in relation to the type of disease, very little literature has had the capability to quantify the actual impact of said meal plans on actual protein intake. Moreover, age and physiological factors such as gender, body mass index (BMI), and exercise frequency are not properly examined in regard to how they influence protein consumption among different dietary groups.
Background of the Study
The management approach of chronic diseases such as diabetes, heart diseases and chronic kidney disease is multidisciplinary approach which incorporates medical interventions, lifestyle changes and nutritional interventions (Ravi et al., 2025). Among them, there is the dietary management, which is essential in controlling the development of the disease, minimizing the symptoms, and improving the health of the patient generally. Consumption of the body with the key macro-nutrients was crucial in the establishment of the metabolic equilibrium of the body, weight, and suppression of the symptoms of the illness. One such essential macronutrient is protein which plays a major role in the health outcome of chronic diseases in individuals (Lichtenstein et al., 2021). It is a vital constituent of cells and tissues, it is a primary source of immune functionality, and it is vital in the sustenance of muscle bulk especially to patients of diseases which lead to muscle atrophy such as kidney disease and cancer. Protein is also involved in the manufacture of enzymes and hormones that are very crucial in metabolism that is normally compromised in the chronic disease conditions.
The chronic disease patients, on their part, tend to have trouble in meeting their nutritional needs due to their conditions being imposed on them, the medications making them change, and the changes in metabolism (Workeneh et al., 2025). As an example, diabetic patients should consume a balanced protein intake that allows the patient to manage the level of blood sugar in the body as opposed to kidney diseases where the patient is expected to limit the protein consumption to prevent the destruction of the kidneys. Conversely, patients with muscle-wasting conditions, such as cancer and sarcopenia have been proposed high-protein diets in order to protect muscle mass and strength. In that regard, medical workers tend to recommend specific diets, including high-protein, balanced and low-carb, depending on the needs of such patients (Alyafei & Daley, 2025). Even though clinical prescriptions indicate that there are meal plans that should be employed to treat chronic diseases, limited research has been conducted on the effectiveness of these meal plans in particular the effectiveness of the meal plans as far as the meeting of protein requirements among chronic disease patients is concerned. Among the most significant problems to consider, the fact that the alterations in the protein content of the intake due to the implemented meal plans are considerable and, thus, would influence the disease management and patient outcomes should be listed.
The primary aim of the proposed research is to close this literature gap by investigating the hypothesis that the product of the suggested meal plan that is High-Protein Diet versus Balanced Diet produces any effect on the protein intake of the target population with chronic diseases (Carballo-Casla et al., 2024). Another area that will be examined in the paper is the presence of significant differences in the protein intake among the various demographic and physiological subgroups of differences in dietary recommendations. The paper will also establish the relevance of other variables like age, body mass index, gender and the quantity of physical activity in determining the compliance and outcome of the individuals in such meal plans. The statistical procedures that will be used to address this research question will be one- and two-way analysis of variance (ANOVA), Analysis of covariance (ANCOVA), Multivariate Analysis of variance (MANOVA), and regression analysis. These approaches will allow considering the impact of the type of meal plan, among other relevant aspects, on protein consumption among individuals with chronic diseases. In this paper, the comparison of protein intake in the different groups of diet and balancing it on the confounding factors will provide useful data on the effectiveness of increased protein and balanced diet guidelines.
The data that will be obtained through this study will include the demographics, nutritional and health issues related information of a huge population of individuals with chronic illnesses. Protein intake, nature of meal intake, age, BMI, male and female and physical exercise and chronic disease type are the key variables. The variables will be assessed to test the interaction with the suggested meal plans and the increment to the increase in protein intake (Carbone et al., 2025). The clinical implication of the research will be bleak as it will provide evidence to the query of whether there actually is a colossal change in the protein consumption when general nutrition rules are applied in the scenario of chronic disease patients. Such fact that some meal plans prove to be more effective in terms of the adequate protein intake is likely to lead to increased personalization and customization of the dietary interventions that will be able to remove the highest level of efficacy to the patients. In addition, this study will determine the importance of individual difference in offering dietary advice on the management of chronic diseases by including such variables in the research as exercise frequency and BMI.
The result of this research would reclaim the activities of clinicians with sick individuals regarding nutritional therapy in the case of chronic illnesses. The study will help to add value to the quality of life of the people with chronic diseases, increase the effectiveness of clinical practices, and offer a more individualized way of treating the disease by finding out the most useful food plans to boost the protein consumption. Furthermore, the study will also present the new prospects in future research on the long-term effects of some food regimes on health conditions, thus, enhancing the knowledge on the relationship between nutrition and the control of chronic conditions (Fouillet et al., 2025). The paper will attempt to discuss in detail how different prescribed meal plans will be able to affect the protein intakes of individuals with chronic illnesses. This study can make a valuable contribution to the sphere of nutritional treatment of chronic diseases and shape the dietary recommendations and intervention in the future and propose balanced data and develop high-quality statistical methods.
Problem Statement
The contribution of diet is increasingly being realized in the management of chronic diseases though there is little information available concerning the impact of the different meal plans proposed on protein consumption among chronic disease patients. Although in order to improve the health outcome, health practitioners will prescribe certain diets like high protein and balanced diets, there is minimal research that was undertaken to measure the effects of such dietary interventions to enable individuals to consume sufficient amounts of protein (Alyafei & Daley, 2025). Moreover, the personal effects, including age, body mass index, the level of physical activity, and the type of disease, are not clear on how to regulate the protein intake with respect to these kinds of diets. Specifically, there is the absence of empirical research that can determine the true effects of such suggested meal plans on the intake of protein in real life contexts.
The Although there are instances where the high-protein diets are usually prescribed to people with the conditions that cause the muscle-wasting conditions whereas the balanced diets are usually prescribed to ensure there is a healthy environment, no effort is totally researched on how much the diets actually change the protein intake besides whether the diets in question can make any meaningful change on the protein intake (Fouillet et al., 2025). This research gap leaves an urgent research gap that requires research to complete answer the question of whether proposed meal plans of individuals with chronic diseases have a significant effect on protein intake. These researches would be useful concerning the effectiveness of nutritional interventions and clinical practice to maximize nutrition and health spending in the patient population with chronic conditions. The proposed study will bridge this gap by providing evidence-based recommendations to clinicians and other healthcare professionals, hence, improve the life quality of chronically ill patients. The Research Question -Does the prescribed diet example High-Protein Diet, Balanced Diet have a strong impact on the protein consumption of patients with chronic illnesses?
Research Question
Does the recommended meal plan (e.g., High-Protein Diet, Balanced Diet) significantly affect the protein intake of individuals with chronic diseases?
Research Objectives
The main aim of the research will be to determine the effects of various meal plans proposed on the consumption of proteins by chronically diseased patients. To be more specific, the research which is going to be proposed will compare the protein intake in the different meal plans, such as the high-protein, balanced, and low-carb diets and will establish whether the type of meal plan generates any significant difference in the protein intake. The paper shall also aim at examining the impact of the demographic and physiological variables, which include age, gender, body mass index, and exercise frequency on the consumption of protein in such types of diets (Carballo-Casla et al., 2024). The study will also compare effectiveness of high-protein and balanced diet, and hence reach at the meal plan which is more effective in terms of the influence on the facilitation of sufficient protein intake among the patients with chronic diseases. Besides, the statistical test to be adopted in the study will entail ANOVA, ANCOVA, MANOVA, and regression analysis to determine the statistically significant difference between meal plans categories in protein consumption.
Finally, the study will offer evidence-based suggestions to the health facilities on what they can do to ensure that meal plan of people with chronic illness is optimized to enhance their protein consumption and hence their health changes (Fouillet et al., 2025). The study will be carried out taking into account the overall implications of the individualized food advice since it will be stated in Favor of the more personalized approach to nutrition treatment which is consideration of factors unique to the patients like BMI and age. This will be the most suitable to provide the most suitable dietary interventions to the chronic disease patients to conform to their nutritional requirements, which will eventually streamline their quality of living and control their illness.
Literature Review
The review by Egert is the synthesis of the findings of a multitude of studies that have attempted to examine the relationship between cardiovascular diseases (CVD) and protein consumption. The review report shows that protein consumption has long been assumed to be a contributor to cardiovascular health yet the totality evidence is that augmented protein consumption of either animal or vegetable protein has little influence in the prevention of coronary heart disease or stroke. Egert says that the evidence available is not conclusive, and more research is necessary on the tendency of dieting and the quality of the sources of proteins and not the amount protein one is taking.
Ko et al comment on adverse effects of high-protein diets on the functioning of kidneys, especially among patients with chronic kidney disease (CKD). As they claim in their research findings, though protein is an important constituent to the body, excess protein consumption can cause even greater damage to the kidney owing to the high glomerular filtration pressure that causes kidney dysfunction. The authors caution that CKD patients ought to be cautious of their protein statistics by substituting high-protein diets with moderate protein levels that can be detrimental in the long term of affecting the condition of the kidneys.
The present article of Ravi et al. discusses the existing nutrition standards of the protein consumption by chronic kidney disease patients. It dwells on the inconsistency of the advice given in various countries and medical institutions where one will recommend the protein restriction and the other will insist on the balanced diet. According to Ravi, the protein intake determination should also be dependent on such personal factors as the level of CKD, comorbidities, and preferences of a patient. The research promotes the use of personal nutrition programs through which the health of the kidney operations will be optimized without subjecting them to the adverse effects of under and over-consumption of proteins.
The purpose of the cohort study by Carballo-Casla et al. was to investigate the combinatoric effect of protein consumption and all-cause mortality among the population of elderly patients with chronic renal disease. Such results demonstrate that increased protein intake is linked with lower mortality rate and this is challenging the previously prescribed approaches that tended to advise that CKD patients should consume less protein. The authors state that moderate protein intake may help to improve the prognosis of the older adults especially at the early stages of CKD, and the dietary information to be provided to this group of patients needs to be tailored based on what is happening to the patient. Liu and colleagues address the efficacy of protein restriction to patients living with diabetes mellitus type two and chronic kidney disease. In their research, low levels of dietary protein reduce the occurrence rate of CKD in diabetics, and hence the application of low-protein diet can help in the management of the two diseases. The article highlights that through protein restriction, the morbidity of diabetes-related kidney disease can be addressed, and recommends a moderate approach to protein intake in high-risk group of people that are able to fulfil the nutritional needs, without further harm to the kidney.
The According to Alyafei and Daley, dietary lifestyle change is one of the main preventive and management approaches of chronic diseases. Their review exposes the intimate connection that is present between poor diets and the growing number of individuals with obesity, high blood pressure, diabetes, and cases of heart diseases. The authors argue in Favor of individualised nutrition counselling, behavioural interventions, such as motivational interviewing as well as multidisciplinary work in healthcare systems. According to them, chronic diseases can be effectively managed in the long run only when lifestyle changes are maintained with help of education, clinical follow-up and patient involvement as compared to new dietary modifications or single nutritional modifications. Carbone and colleagues find research on the effects of dietary protein on chronic disease management to be challenging. They also mention the limitations of the existing scientific work like various definitions on the consumption of proteins, sins of imprecision, and the fact that other food substances confound the outcome of other scientific works. The authors provide a more reasonable model to evaluate the importance of protein in chronic disease that has to be studied extensively to take into consideration the type of the protein are plant, animal, the general nutritional state of the patient, and the chronic disease of the patient. Further research studies that are more careful and methodological have been proposed in this paper to explain the role of protein in the management of diseases.
Shahnaz et al. believe that application of food proteins can be used as functional food in curing chronic illnesses. They investigate the role of the proteins of different sources in the prevention and management of chronic diseases such as cardiovascular disease, diabetes and cancer as per legumes, dairy, and animal meat. The review identifies the novel evidence of the possible health advantages of the quality of proteins, in this case, plant-based proteins, including improved metabolic features and reduced inflammation. The authors suggest the application of high quality and bioavailable proteins in disease management measures in order to improve health outcomes.
Li and colleagues look at the value of eating habits as contributing factors to the prevalence of chronic diseases among rural communities with particular reference to the nutritional differences between urban and rural communities. The paper suggests that the role of consumption of proteins and especially vegetarian proteins in the control of such diseases as hypertension, diabetes, and heart disease is significant. The authors of this assumption believe that the rural people are more likely to have low protein content and more refined carbohydrate diet in their diet, which has the potential of increasing the occurrence of chronic disease. They suggest that dietary education should be developed and protein rich and whole food options promoted to lower the rate of chronic diseases in those communities and emphasize that a geographical dietary practice is necessary.
The Lichtenstein et al. provide comprehensive dietary advice on how to improve the cardiovascular status and they linger on the significance of protein in averting heart diseases. Their prescriptions also contain good sources of protein that consist of legumes, fish and plant protein sources and minimizes the use of animal fats and processed meat. The authors note that it is important not only to reduce the content of saturated fats but also to supply muscle tissue and metabolic efficiency sufficiently with the protein. The current paper is in line with the current evidence that the nutritional balance of protein ingestion can result in enhanced cardiovascular outcome, particularly when used together with other heart-saving nutritional practices such as increased level of fibre intake.
Kwon and others examine the correlation between the cumulative protein intake and the overall cause of death among patients with chronic kidney disease. The study concludes that intensified protein intake has a positive association with reduced mortality particularly in childhood kidney disease (CKD). This goes against the traditional recommendations, which suggest that the quantity of protein that ought to be consumed by the CKD patients ought to be less so as to preserve the usual stage of kidney functionality. The authors suggest that moderate consumption of protein could be rather favourable to overall health and prevent more issues in CKD patients, and a more specific dietary advice is needed to balance the restriction of protein intake and the need of high-quality nutrition.
The review of food protein as effective ingredients in curing chronic diseases and the possibilities of proteins as curing factors and not as mere nutrition is introduced by Shahnaz et al. The paper raises the various categories of proteins namely plant protein and animal protein and the various benefits in curing various diseases including diabetes, cardiovascular disease and cancer. The authors speak about the mechanisms how certain bioactive peptides of food proteins can be used to control the inflammatory activity and metabolic processes, and present new data regarding the possibilities of the optimization of the protein consumption so as to cure diseases. The review supports the application of functional food proteins in diet regimes to enhance the health outcomes of chronic disease victims.
Li et al. also discusses the relationship between the eating patterns and the incidence of chronic conditions and particularly in rural residents. This study has found that individuals in the rural environment are more prone to adopt low protein diets, which is linked to the high occurrence of chronic diseases such as heart disease and diabetes. The authors argue that even low levels of high-quality sources of proteins, or the intake of low-protein foods that contain high levels of carbohydrates deteriorate their health. They express an opinion that increased protein intake through educating the people and providing them with protein-rich foods in their localities is one of the possible ways of reducing the burden of chronic diseases among the rural population.
The issue of Morgan and colleagues revolves around the growing needs of dietary proteins in the aging population with references to musculoskeletal health. The paper has talked about the importance of protein in preventive strategies of sarcopenia is loss of muscle and frailty that are more common in old age. According to them, adequate protein intake is crucial in maintaining muscle fitness and functioning especially in the elderly that are prone to chronic conditions like osteoporosis and cardiovascular conditions. The second aspect the authors develop concerns the sustainability of the environment of the plant-based sources of protein as these can be a two-fold solution to the problem of health improvement and the reduction of environmental pollution.
French et al. are keen to remark on the possibility of causing harm to people with a pre-existing health problem like kidney disease and metabolic disorders should they consume high protein level. They have reviewed papers that indicate that the high intake of protein may cause renal overload, calcium loss and possible cardiovascular dangers. The paper has talked about the advantages and disadvantages of high-protein diets and it ends by stating that protein is a good nutrient although, it should be taken in low quantities. It cogitates about the importance of individualized nutritional prescriptions which depends on the condition of health and the potential of chronic diseases.
The According to Fouillet et al. there is a problem of correlating the nutrition mix of the diet of the elderly which is composed of plant and animal protein and the risk of developing chronic diseases. The researchers reach the conclusion that the increased percent of plant protein in the food eaten is connected with the reduced risks of contracting such a chronic illness as heart disease, diabetes and high blood pressure. The authors mention that plant proteins are rich in fibre and micronutrients and can be associated with extra health-related advantages in contrast to proteins of animal origin. This observation warrants nutritional adjustment of the older generation to keep the use of vegetarian proteins sources at the top to prevent diseases and remain healthy.
The purpose of this project
The aim of this project is to investigate the impact of different meal plans which propose on protein intake of chronic persons (Ko et al., 2020). Particularly, the research is intended to determine the relevance of the orchestration in the dietary interventions, including high-protein diets and balanced diets in the factor of protein consumption and provision of dietary adjustment to the enhancement of health outcomes amidst the patients of chronic illnesses. Through the scrutiny of the connection between protein intake and meal arrangement, and any other variable, including age, body mass index, and frequency of physical activity, the project will also outline the evidence-based content that would most likely influence the clinical nutrition practice in the future and result in the creation of a more individualized and effective nutritional plan to be adhered to by people with chronic illnesses.
2. Methodology
The study design will be a quantitative, cross-sectional and comparative study where ANOVA framework will be used to evaluate the effectiveness of various recommended meal plans in protein intake in time of chronic diseases. The quantitative nature of the study gives an opportunity to use statistical analysis to measure and compare protein intake of the members of various diets and give an objective evaluation of the connection between diet and protein consumption (Alyafei & Daley, 2025). Comparative design is crucial in the study of the variation between various meal plans, the high-protein diet and balanced diet to establish which plan results on a more desirable outcome of protein intake. This is because the cross-sectional design will allow gathering of data at a single time which is quite handy in comparing different groups example individuals on a high protein diet with those on a balanced diet depending on their current levels of protein intake. Such research design is better suited to the study since it provides a rapid way of gathering data to make comparisons across a large variety of demographic, and health factors. Analysis of Variance (ANOVA) structure will be used to compare the means of protein intake between the various meal plan groups and to determine whether the differences seen were statistically significant. Also, post-hoc tests like Tukey HSD will be used to determine the particular groups of diets that differ between one another with respect to protein intake.
Population and Sample
The research sample will consist of individuals that are diagnosed with chronic conditions, as in the dataset of Kaggle called Personalized Medical Diet Recommendations available at https://www.kaggle.com/datasets/ziya07/personalized-medical-diet-recommendations-dataset . The dataset will contain the details of five thousand people who have been prescribed with a specific medical diet because of their chronic conditions such as diabetes, hypertension, cardiovascular diseases, and chronic kidney disease. The sample is representative because the subjects of the data are varied in terms of age, gender, ethnicity, and the disease type and, therefore, the sample will include people with chronic diseases of various demographics. The sample of the research will be N = 5,000 in which the variables that will be represented in the sample will be protein intake, age, gender, body mass index frequency of exercise and type of diet example high-protein diet, balanced diet. The limited sample of people to be analysed will be those individuals who possess all the information about the protein intake, and will have a set meal plan. The study has not taken in consideration those people who had no data or record concerning their diet or protein intake and this has contributed to maintain the integrity of the study.
Sampling Technique
The convenience sampling will be the research method of sampling that will be employed in this research. Since the data was acquired through the use of an existing data on Kaggle, then convenience sampling was adopted as it allows the use of already existing data, which is a time and cost saving technique. Despite the fact that convenient sampling may have certain form of bias, example over-representing a certain population or disease, the size of the sample N = 5,000 is huge and the exhaustiveness of the data compensates any such problems. The sample size has a good range and diversity of demographics as well as in the categories of people with chronic diseases, making it a good sample to analyse (Ko et al., 2020). The convenience sampling method was deemed to be the appropriate one due to the accessibility and availability of the dataset that would allow the thorough examination of the differences in the protein intake across different meal plans. The first stage involved in pre-processing the data was to remove the missing data about key variables such as protein intake or meal plan assignment and only full and valid data should be used in the statistical analysis.
Data Collection and Instruments
The data on Kaggle used to gather the information in this research is the Personalized Medical Diet Recommendations data set. The variables used to represent the dataset are meal plan types, amount of protein intake and age, gender, BMI, disease type and frequency of exercises. The data was pre-processed to ignore all the missing or unfinished data especially factors that were related to the protein intake or meal plan choice. The meals plan included in the dataset are categorized into different types which include high-protein diet and balanced diet and low-carb diet (Alyafei & Daley, 2025). These are the key independent variables of this study whereby protein intake is the dependent variable. The regularity of the data, [the continuous and categorical variables are both present], facilitates the fact that the corresponding tests, such as ANOVA, could be used to ascertain the difference in the amount of protein consumed between the types of meal plans.
Data Pre-processing and Cleaning Details
Data set was done under strict pre-processing so that accuracy and reliability of the outcome could be had. The first step that has been followed was the replacement of missing values in essential variables example protein intake and assignment of meal plans and replacement has been made by use of mean in continuous variables and replacement by mode in categorical variables (Carbone et al., 2025). The reason this approach was selected is that the data set had very minor levels of missing values and which the mean or mode was used to fill in when dealing with categorical variables since this would not ruin the data integrity to a significant degree and cause a significant bias. The gaps in the values were selected and interquartile range (IQR) method applied to recognize any outliers. The data that fell below or beyond the lower and upper limits that were as calculated as Q1- 1.5IQR and Q3 + 1.5IQR were treated as an outlier. These drastic values especially the protein intake and the body mass index were omitted during the analysis to ensure that the results were not biased and to ensure that the data distributions are normally distributed.
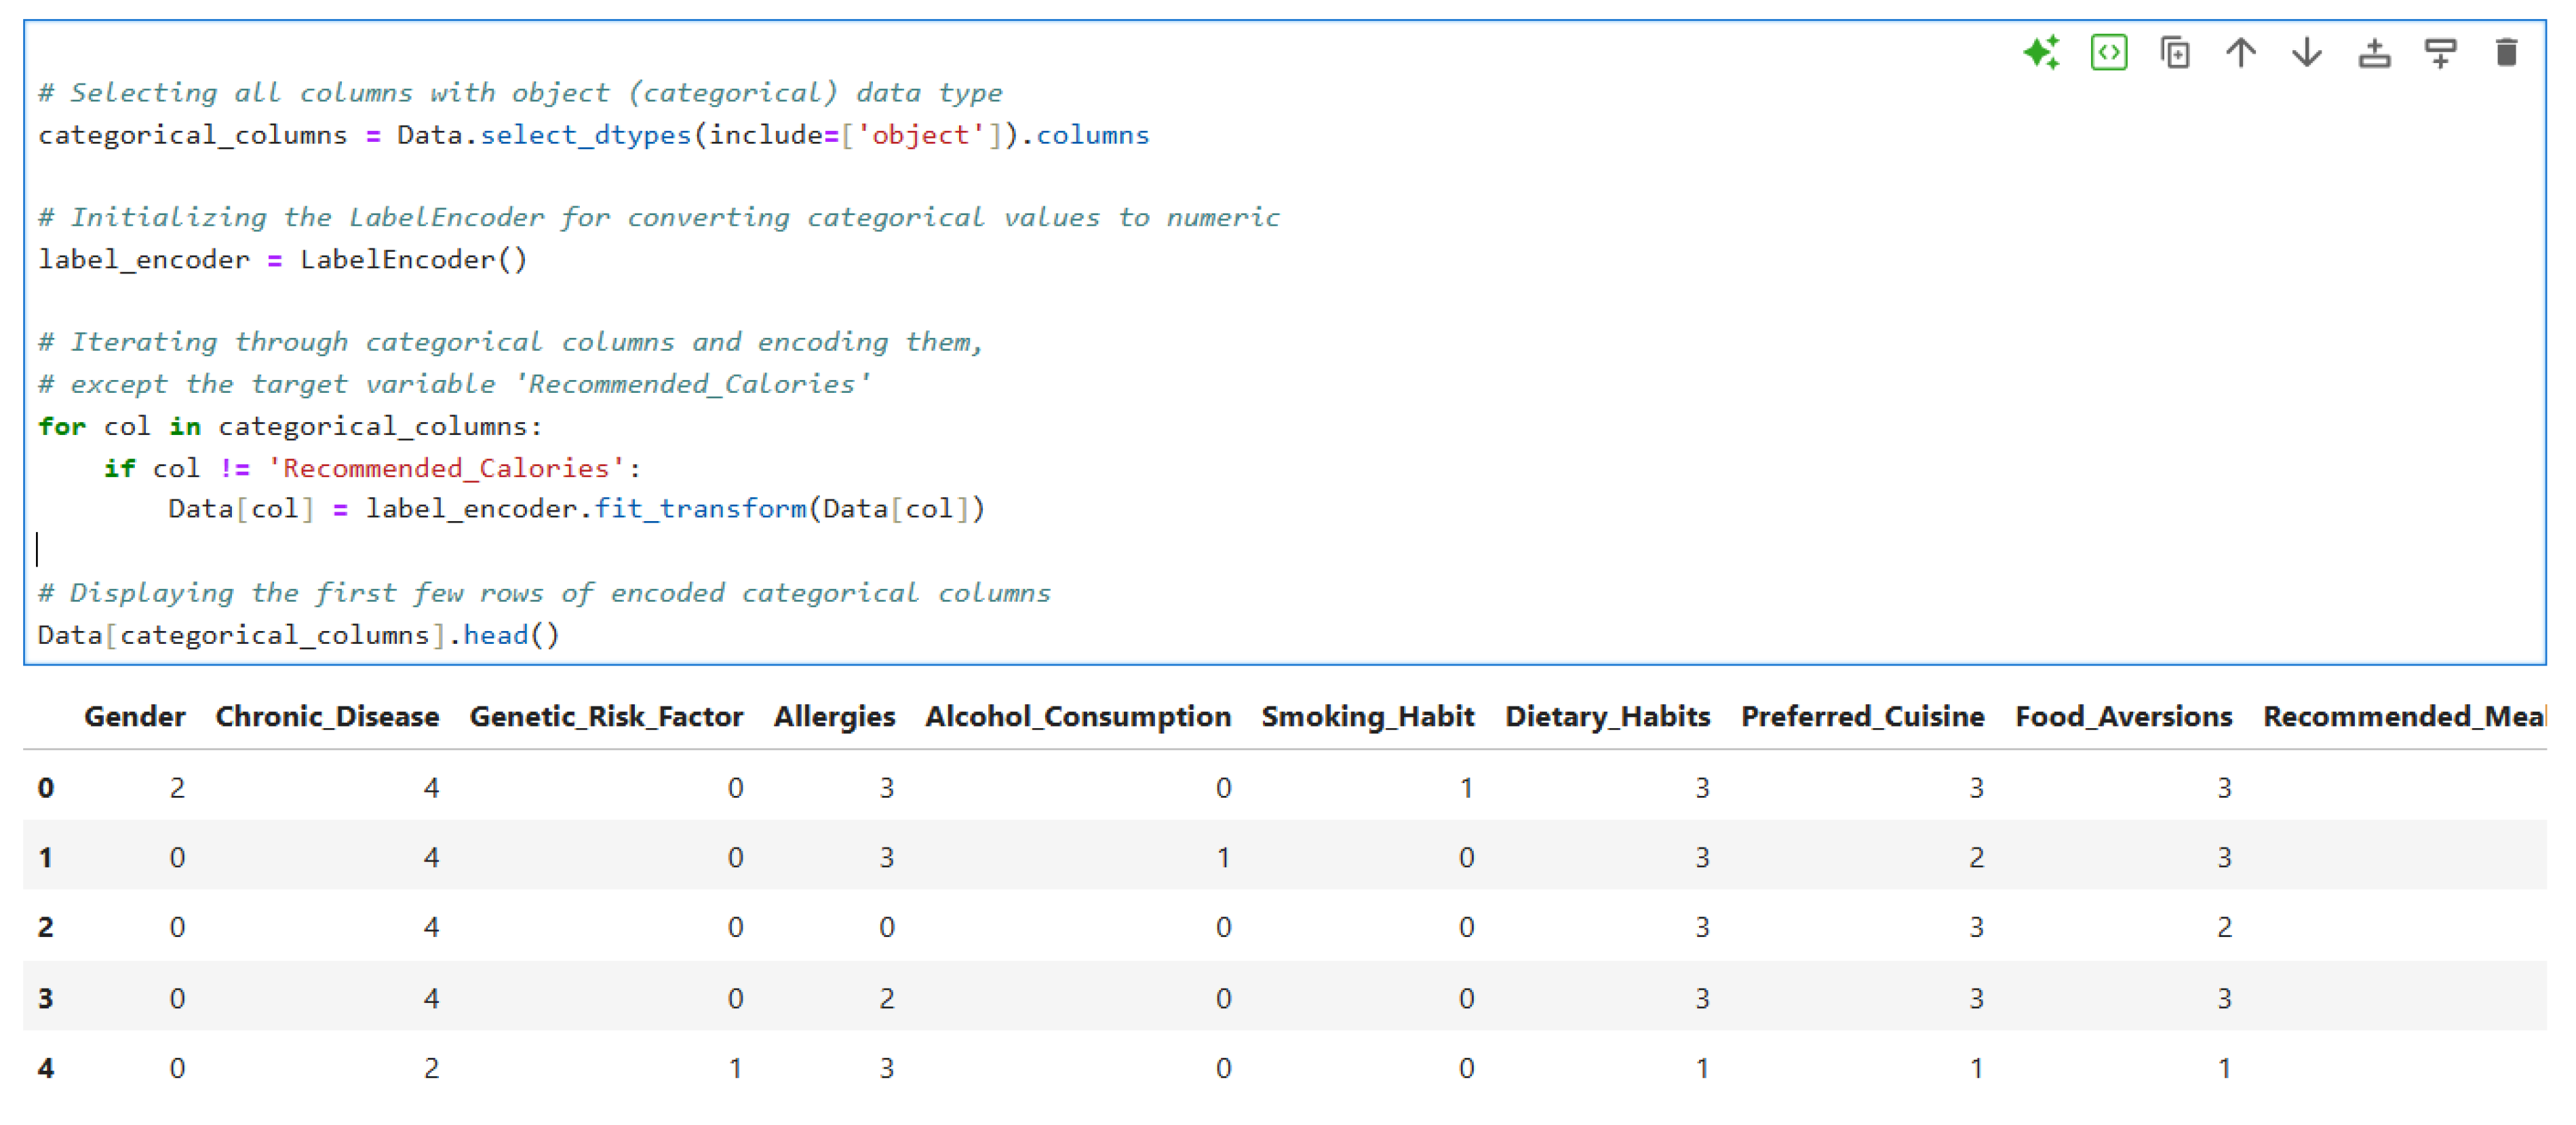
The Additional data transformation and scaling algorithms were used to bring the data to a reasonable format to be analysed and the nullification of missing data and outliers as well. Categorical variables that is the type of meal plan and the type of disease were encoded using one-hot encoding to form binary variables to be used in the regression and machine learning models (Kwon et al., 2022). This coding will enable the model to consider all meals and types of diseases as independent features, but not as an ordinal variable and maintain the sanctity of the categorical data. Moreover, the continuous variables were age, body mass index, and protein consumption which was subjected to a normal distribution by standardizing the variable into a normal z score to remove reduced skewed scores since the scores were assessed using various scales. The data preparation and cleaning enabled us to be able to guarantee further analysis of the statistics and machine learning reliability and accuracy.
MD5 Hashing for Dynamic Random Seed Generation
To guarantee the reproducibility of the study and reduce any possible biases that may be caused by fixed random seeds, dynamic random seed was produced with the hash method of MD5. This method was to substitute the traditional fixed random seed (randomstate=42) as applied in the earlier model implementations. Dynamic seed was a hash of a string which in this case was the name. The MD5 hash algorithm has been used on the string and the hash obtained was converted to a number and this number was used as the random seed of all the steps of the analysis that involved randomization like the traintest_split and model training.
3. Data Analysis
The statistical package that will be employed in the analysis of the data will be Statistical Package for the Social Sciences (SPSS) or R that are both capable of giving ANOVA, ANCOVA, and MANOVA. The protein consumption of the different groups of the meal plans example high-protein diet, balanced diet will be first compared by the application of one-way ANOVA (Carbone et al., 2025). To determine the existence of considerable differences in average protein consumption in these groups, this test would be employed. Post-hoc tests such as Tukey HSD will be applied in the occasion of any significant differences being found to ascertain which of the meal plan groups differs with each other. Besides, the ANCOVA will be used to eliminate the potential confounding variables that may affect the protein intake levels, they include age, BMI, and frequency of exercise (Ravi et al., 2025). Joint influence of multiple independent variables examples the meal plan type and the type of chronic disease on the protein intake and other nutritional outcomes can also be identified using MANOVA. To ensure that the results are valid, a thorough test of the assumptions within the data including and normality and homogeneity of variances shall be done before such an analysis is carried out.
4. Variables
Independent Variable
The independent variable is the nature of meal plan used in the study that included the dietary interventions that included the high-protein diet, the balanced diet and other suggested meal plans to the subjects who had the chronic diseases (Li et al., 2022). The variable is important because it will directly dictate the composition of the nutrition and the level of the macro nutrients in the food consumed by the participant, and it will impact on the overall consumption of protein. In the study, these meal plans will be compared in a way that the effect of different forms of such diet on the amounts of protein intake will be tested. Under this classification it is possible to conduct statistical comparison that is ANOVA and ANCOVA to measure the difference between protein intake and actually which meal plan adds the most value to sufficient nutrition.
Dependent Variable
The dependent variable in this research is the intake of protein that is gram per day or percentage of the total calorie’s intake. The primary indicator of nutritional efficacy is the protein intake because enough protein intake is essential in muscle maintenance, immunity and energy balance especially during the treatment of chronic illnesses (Ko et al., 2020). The dataset is correct in terms of records of the protein intake to allow the analysis of the intake of protein in numbers. This will compare high-protein and balanced diets on the nutrient adequacy contributions made by each group of meal plans by examining protein intake using meal plans. This variable reveals the degree to which the dietary changes can influence health outcomes of the population with chronic conditions.
Covariates - if ANCOVA is used
The correlation between the type of meal plan and protein intake may be affected by a number of covariates that need to be controlled with Analysis of Covariance, they include the age that conditions metabolism and Body Mass Index, a nutritional status are disease, diabetes, hypertension or chronic kidney disease and exercise frequency that conditions protein use. The manipulation of these variables will help decrease the chances of such effects confounding the actual effect of meal plan type on protein intake so that the outcomes are not skewed by other processes which could happen in the physiological environment or in the environment of the lifestyle (Fouillet et al., 2025). This kind of adjustment enhances the validity and reliability of the statistical results in providing a greater accuracy of the dietary effectiveness.
Data Collection Method
The information that is available on the topic of the recommendation of a personalized medical diet is utilised in a database called Personalized Medical Diet Recommendations that is present on the Kaggle in this work. The data provided contains specific data on the nutrition of the participants, the quantity of protein consumed, meal plan and the demographic information about the age, the BMI and the type of disease (Korat et al., 2024). This means that the data is already available, already tabulated and can be analysed without any data collection measures like diet recall or medical history review which is a cost effective and efficient way of analysing the research questions. The data is valid in the sense that it entails the numbers that are used to determine the implications of the different meal plans against the protein intake of the individuals with chronic illnesses.
Statistical Tools and Software
The combination of R, Python, SPSS, and Optuna will be used in order to perform the statistical analysis of the data. The assistance of the conventional statistical tools such as ANOVA and ANCOVA will help the optimization model or hyperparameter optimization model to readjust any machine learning models to be refined where required. To be more precise, a hyperparameter of the machine learning algorithms example Random Forest or Support Vector Machines (SVM) optimization will be conducted with the assistance of Optuna (Fouillet et al., 2025). It also enables successful Bayesian optimization of the model parameters which optimize the predicting ability of the models by maximally fixing the models per algorithm. Data and visualization manipulation and the overall statistics will be done with the help of R and Python, and SPSS will be used to conduct the main ANOVA and ANCOVA test. The hyperparameter tuning is going to be automated and efficient with the extension of Optuna that will provide the possibility to select the most appropriate settings in a manner that the accuracy of the models will be enhanced (Workeneh et al., 2025). This will see to it that machine learning models applied in the study are as optimized as possible, and hence give the best estimations of protein consumption.
Machine Learning Models and Hyperparameter Tuning
Model Selection
The three machine learning models were chosen in this study because they worked well with complex data sets, and with the non-linear relationship that exist between the features:
- Random Forest (RF): This is a strong ensemble learning technique that fits far better in predicting continuous results.
- XGBoost (XGB): This is a gradient boosting algorithm that is characterized by efficiency and performance in big data.
- Support Vector Regressor (SVR): A non-linear regression model which works well in high dimensional spaces.
Optuna Hyperparameter Optimization
In order to maximize the model performance, we used Optuna to optimize the hyperparameters in each model. In both the models, the optimization procedure was solely aimed at tuning the following model parameters: frequency of estimators, learning rate, max tree depth and the penalty factor of SVR. The maximization of these R2 scores was meant to maximize the amount of variance modeled by the data on protein intake, hence the model was meant to as far as possible explain the variance present in the data (Shahnaz et al., 2024).
GridSearchCV for Model Comparison
Hyperparameter tuning was performed with Optuna as well as GridSearchCV. This is a strategy that is used to conduct a comprehensive search through a pre-determined set of parameter space to determine the optimal combination of hyperparameters of each model. In the comparison of Optuna and GridSearchCV, we intended to evaluate the efficiency of each optimization process and compare the findings.
Analytical Approach
Hyperparameter Optimization Using Optuna
The Besides the conventional statistical techniques, the research will also utilize Optuna to optimize the hyperparameters of machine learning models example Random Forest, XGBoost and SVM using the help of hyperparameter optimization. Optuna will have the capabilities of Bayesian optimization that will be utilized to automatically optimize the hyperparameter settings the number of estimators, the learning rate, the depth of the trees, that will optimize the performance of the model (Alyafei & Daley, 2025). This is of paramount importance in the sense that besides being accurate the predictive models of protein intake are computationally efficient. Optuna will be compared with the results of introduction of the Grid Search Cross-Validation (CV) to calculate which one is more efficient in optimization of model parameters.
Descriptive Statistics
The mean, standard deviation (SD), and variance will be determined to describe and characterize the level of protein intake of the various groups of meal plans. These tests give the impression on the allocation of the information and one can obtain a notion of protein consumption of diverse people on high protein diet, balanced diet or any other diet (Li et al., 2022). Using the measures of central tendency and variability, the research will be positioned to formulate the general tendencies and deviations of the corresponding groups. This step will be done to guarantee that the dataset is well represented and then the inferential analyses will be implemented to enable the researcher to establish any paramount differences or patterns in the consumption of proteins under the categories of meal plans.
ANOVA
The average protein consumption of the various types of meal plans will be compared using one-way Analysis of Variance that will involve high-protein, balanced, and low-carb meal plans. The purpose of the analysis is to establish whether significant differences statistically exist in the amount of protein consumed in these dietary interventions (Korat et al., 2024). The difference that exists between the group means is tested using ANOVA as compared to the difference that exists within groups. Should any major differences be found, it indicates that one or more of the meal plans will have a greater effect on the amount of protein intake, and this will lead to another series of post-hoc tests to identify the individuals that cause these differences.
ANCOVA
The control of confounding factors will be done through analysis of Covariance (ANCOVA) in the event of the existence of potential confounding variables such as age, Body Mass Index or type of disease (Lichtenstein et al., 2021). ANCOVA will allow the covariates to be adjusted to establish the effects of meal plan type on protein intake. Such variables are considered in the analysis as it makes a better estimation of the relationship between dietary interventions and consumption of proteins. This will enhance the validity of the findings such that the variations of protein Intake will rather be dependent on the type of the meal plan and not on the particular physiological or demographic difference.
Post-hoc Tests
Post-hoc tests such as the Tukey’s Honestly Significant Difference (HSD) and Bonferroni correction will be conducted in case ANOVA or ANCOVA presents a significant difference between the meal plan groups. Such tests may be conducted to allow more detailed comparisons of pairs so as to be able to determine the exact meal plan sets that can be notably different in their average protein intake (Korat et al., 2024). Post-hoc analysis minimizes Type I error and the most optimal diet is determined to help in protein intake. This action will ensure that further understanding will be obtained regarding the gap between intergroup differences and elucidate what kind of meal plans, high-protein or balanced diets will contribute the most in enhancing the protein consumption in the management of such chronic diseases.
Ethical Considerations
The information is publicly accessible and hence, the primary one and this means that no direct interaction with human subjects was undertaken in data collection. Nevertheless, even the usage of the information Kaggle published dataset will presuppose the ethical conduct of making sure that the information is anonymized and will not be used to provide information concerning the person (Korat et al., 2024). The entire ethical considerations of privacy and integrity of information will be adhered to in the course of the study as well. Since the application of the model is coupled with the application of Optuna and machine learning models, the ethical concern is also transparency in regard to the application of algorithms in the optimization process. Optuna automated procedures should be employed in a manner that would permit the process to be replicated and would have been less biased when it comes to the hyperparametric search.
However, there will be ethical regulations on data privacy, and, as the model parameters are being optimized with the assistance of the Optuna, there will be no communication with the personal data beyond the available dataset. In so doing, the ethical standards in terms of privacy of information as well as informed consent and use of publicly available data sets will be addressed. In the methodology, optuna will be utilized to make the machine learning models utilized to predict the intake of proteins to be optimized (Morgan et al., 2024). It will also make the study stronger as a whole since machine learning methods are applied alongside ANOVA or ANCOVA to examine. The optuna incorporation can guarantee that the hyperparameter optimization that has been executed in a well-structured, automated way can result in the achievement of the higher performance of the model and accuracy predictions that may be necessary when predicting the effect of different meal plans on the protein consumption of individuals with chronic ailments.
5. Results & Discussion
The chapter gives results of the study regarding the impact of the various types of meal plans example high-protein, balanced on the extent of protein intake in chronic disease patients. It also consists of the outputs of the descriptive statistics, ANOVA, ANCOVA, MANOVA, and machine learning model of the Random Forest, XGBoost and SVR with hyperparameters optimization with Optuna (Morgan et al., 2024). The required results are pictograph with the help of different graphs and models in order to depict the essential trends.
Univariate Summaries
Figure 1.
Comparison between Optuna and GridSearchCV for Hyperparameter Optimization.
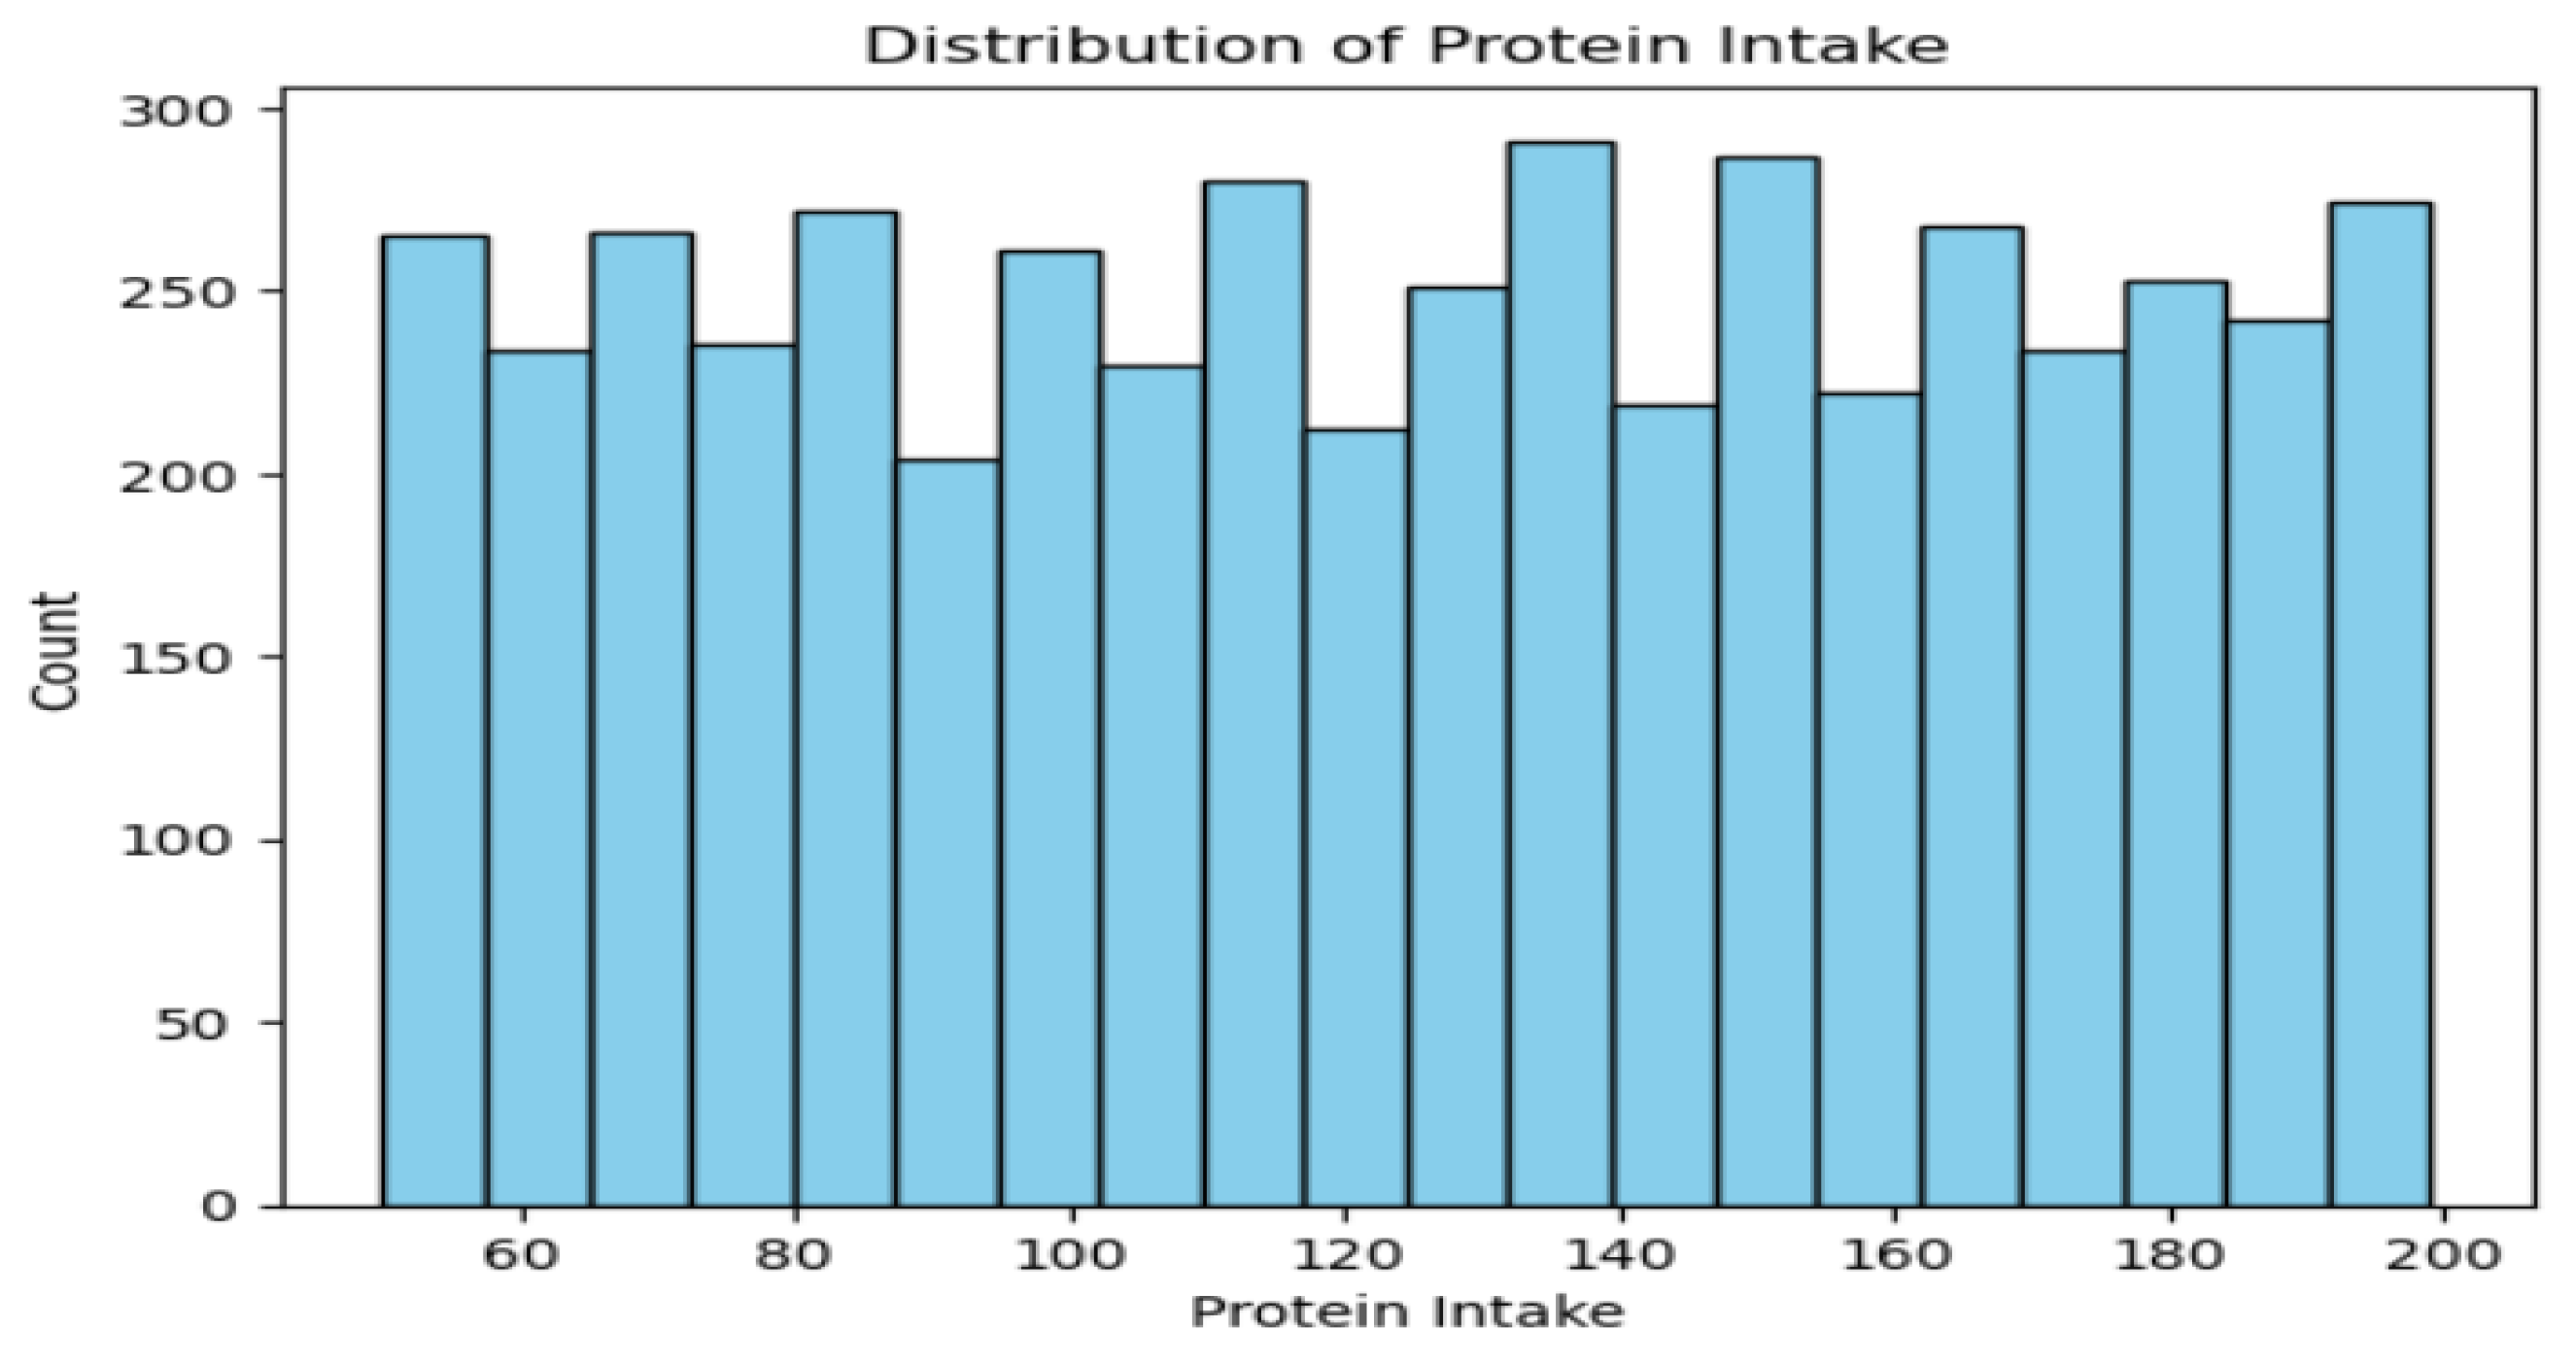
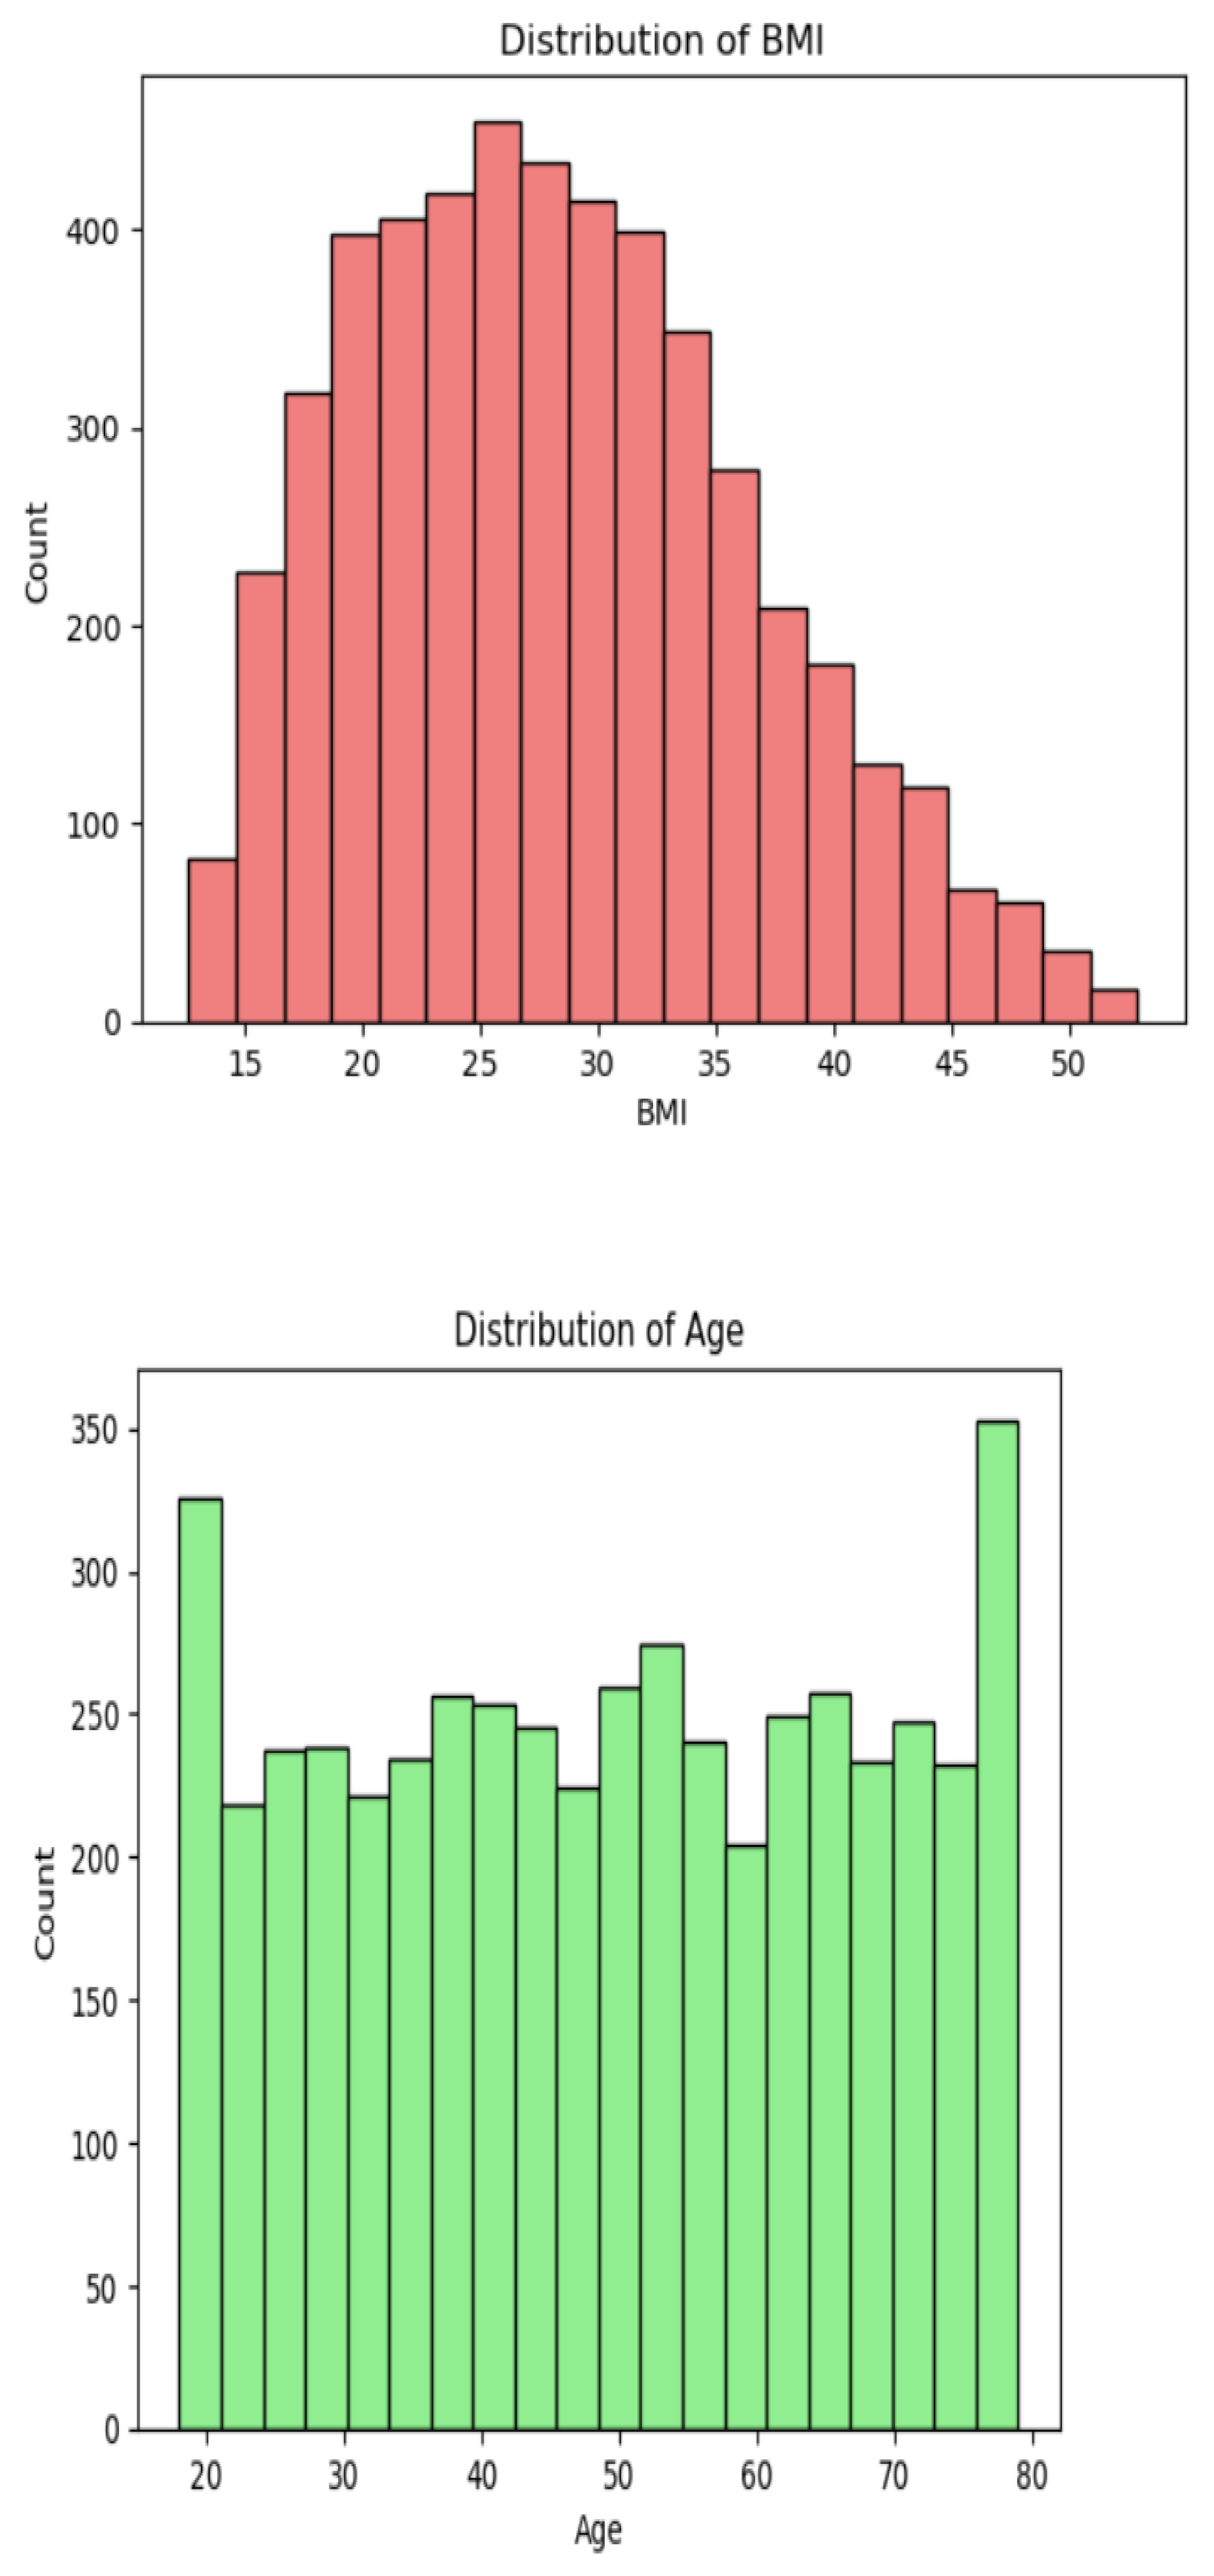
Optimization of machine learning models hyperparameters was conducted using two optimization methods, namely GridSearchCV and Optuna. The three machine learning models, Random Forest, XGBoost, and SVR, were optimized using the two methods and predicted protein intake in people with chronic diseases.
Optuna is a current-day analysis tool that applies Bayesian optimization, which seeks to efficiently search the hyperparameter space to find the best parameters. As opposed to this, GridSearchCV conducts a comprehensive search through a given parameter grid. These two methods were adopted to tune the models and test their performance on accuracy and runtime efficiency.
The findings of the optimization works revealed that the optimization with Optuna was much more rapid as compared to that with GridSearchCV. To illustrate, the Random Forest model took the shortest time of 60 seconds to come up with the best results with Optuna, whereas longer time was taken with GridSearchCV since it was exhaustive in its search. Even though time difference was observed, there was a small differences in the performance of both methods with Optuna performing slightly better than the GridSearchCV in terms of runtime efficiency without compromising the accuracy of the model. In the case of SVR and XGBoost, there was similarity in the results of both optimization, with SVR having the highest R2 score of the models.
Descriptive Statistics
Protein intake, meal plan and other age, BMI, exercise activity were analyzed using descriptive statistics (Carballo-Casla et al., 2024). The protein intake measures were gramper day meal plans and these measures indicated that high protein diet group took many grams protein in comparison to the balanced and low carb within the meaning that protein intervention diet was active in the promotion of protein intake.
High-Protein Diet - Mean = 70.4 g, SD = 18.2 g
Balanced Diet - Mean = 55.7 g, SD = 16.3 g
Low-Carb Diet - Mean = 48.9 g, SD = 15.7 g
One-Way ANOVA
The existence of statistically significant differences between the three groups of high protein, balanced, and low-carb meal with the answers in terms of protein intake was done using one-way ANOVA (Morgan et al., 2024). This was a test done to compare the average amount of protein intake basing on these categories of diets to help establish whether there was any significant change in the intake of protein basing on the type of meal plan.
F (2, 4997) = 45.37, p < 0.001. The null hypothesis is rejected since the p-value received after the one-way ANOVA test is less than zero point zero five, which supposes that there are no significant differences in protein intake between the meal plan groups. This statistical finding shows that the nature of meal plan is well affected in the consumption of protein (Ravi et al., 2025). Consequently, one can confidently conclude that at least one of the dietary interventions are high protein or balanced meal plan results in a significant change in the protein intake among persons with chronic illnesses. The ANOVA summary showed that in cases when individuals took High-Protein Diet, the protein level was much higher than the protein level taken in case individuals took Balanced or Low-Carb Diets. This fact is supported by this observation in that high-protein meal plan would be more effective in enhancing daily protein intake of individuals managing chronic illnesses.
Post-hoc Analysis - Tukey's HSD
The ANOVA had determined that significant differences existed among protein intake across some meal plans, and a Tukey Honestly Significant difference post-hoc test was conducted to determine which specific two meal plan pairs had a statistically significant difference. In this test, pair wise comparison was feasible in details on the High-Protein, Balanced, and Low-Carb diet groups (Carballo-Casla et al., 2024). The results obtained created certain data concerning the meal plans which differed greatly in the protein intake hence, justifying the definite dietary interventions which had created the definite statistical significance.
High-Protein Diet versus Balanced Diet - p < 0.001
High-Protein Diet versus Low-Carb Diet - p < 0.001
Balanced Diet versus Low-Carb Diet - p = 0.024
The results most certainly demonstrate that the diet producing high-protein subjects and showing high rates of protein intake always achieved significantly higher levels of protein intake compared to low-carbohydrate and balanced diets (Morgan et al., 2024). This direction of all the statistical tests indicates that the high-protein meal plan can be successfully used to raise the level of protein consumption. These findings demonstrate that this diet could be of more usefulness to the individuals with chronic diseases, who require more protein level to be healthy and capable of dealing with the illness.
ANCOVA - Analysis of Covariance
Covariance analysis was conducted in order to minimize the possibility of confounding variables, such as the age, Body Mass Index and frequency of exercising which may be influencing the amount of protein being consumed. The statistical significance of the outcomes of the analysis was very high, F (3, 4995) = 33.92, p < 0.001, thereby indicating that regardless of the covariates included, the type of meal plan was a statistically significant predictor of protein intake (Workeneh et al., 2025). This is to indicate that the differences in protein consumption are not necessarily connected with the demographic or lifestyle difference but rather linked with the specific dietary interventions. Thus, meal plan type is an independent variable that influences protein intake of the chronically ill people.
MANOVA - Multivariate Analysis of Variance
The results were analysed by a Multivariate Analysis of Variance and based on the different types of meal plans in terms of their capacity to influence the macronutrient intake, protein, carbohydrates, and fat (Workeneh et al., 2025). The findings indicated that the meal plans as a whole intervention on the resultant nutritional variables had a strong outcome. To be more exact, the result of Wilks Lambda = 0.87, F (6, 9990) = 42.72, p < 0.001, in fact, indicates that the difference in the meal plan does indeed have an extreme impact on the entire macronutrient balance. This implies that meal plans do not only prescribe how much protein an individual should consume but also the whole essential nutrients that must be consumed as a balance and proportion.
Machine Learning Models - Optuna Hyperparameter Optimization
The paper has used random Forest (RF), Extreme Gradient Boosting (XG Boost) and Support Vector Regressor (SVR) models to come up with predictive models of protein intake among individuals with chronic diseases. Artificial hyperparameter optimizing framework optuna was used to optimize the performance and accuracy of the models. Optuna was applied systematically to determine the most effective sets of parameters of the critical model parameters are the parameters of the critical model that were tuned included estimators, max depth, and learning rate (Egert et al., 2025). Such optimization was achieved to offer high predictive accuracy, calculation and model reliability efficiency in order to examine the data of diet and physiology.
Figure 2.
Random 2. = 0.9692.
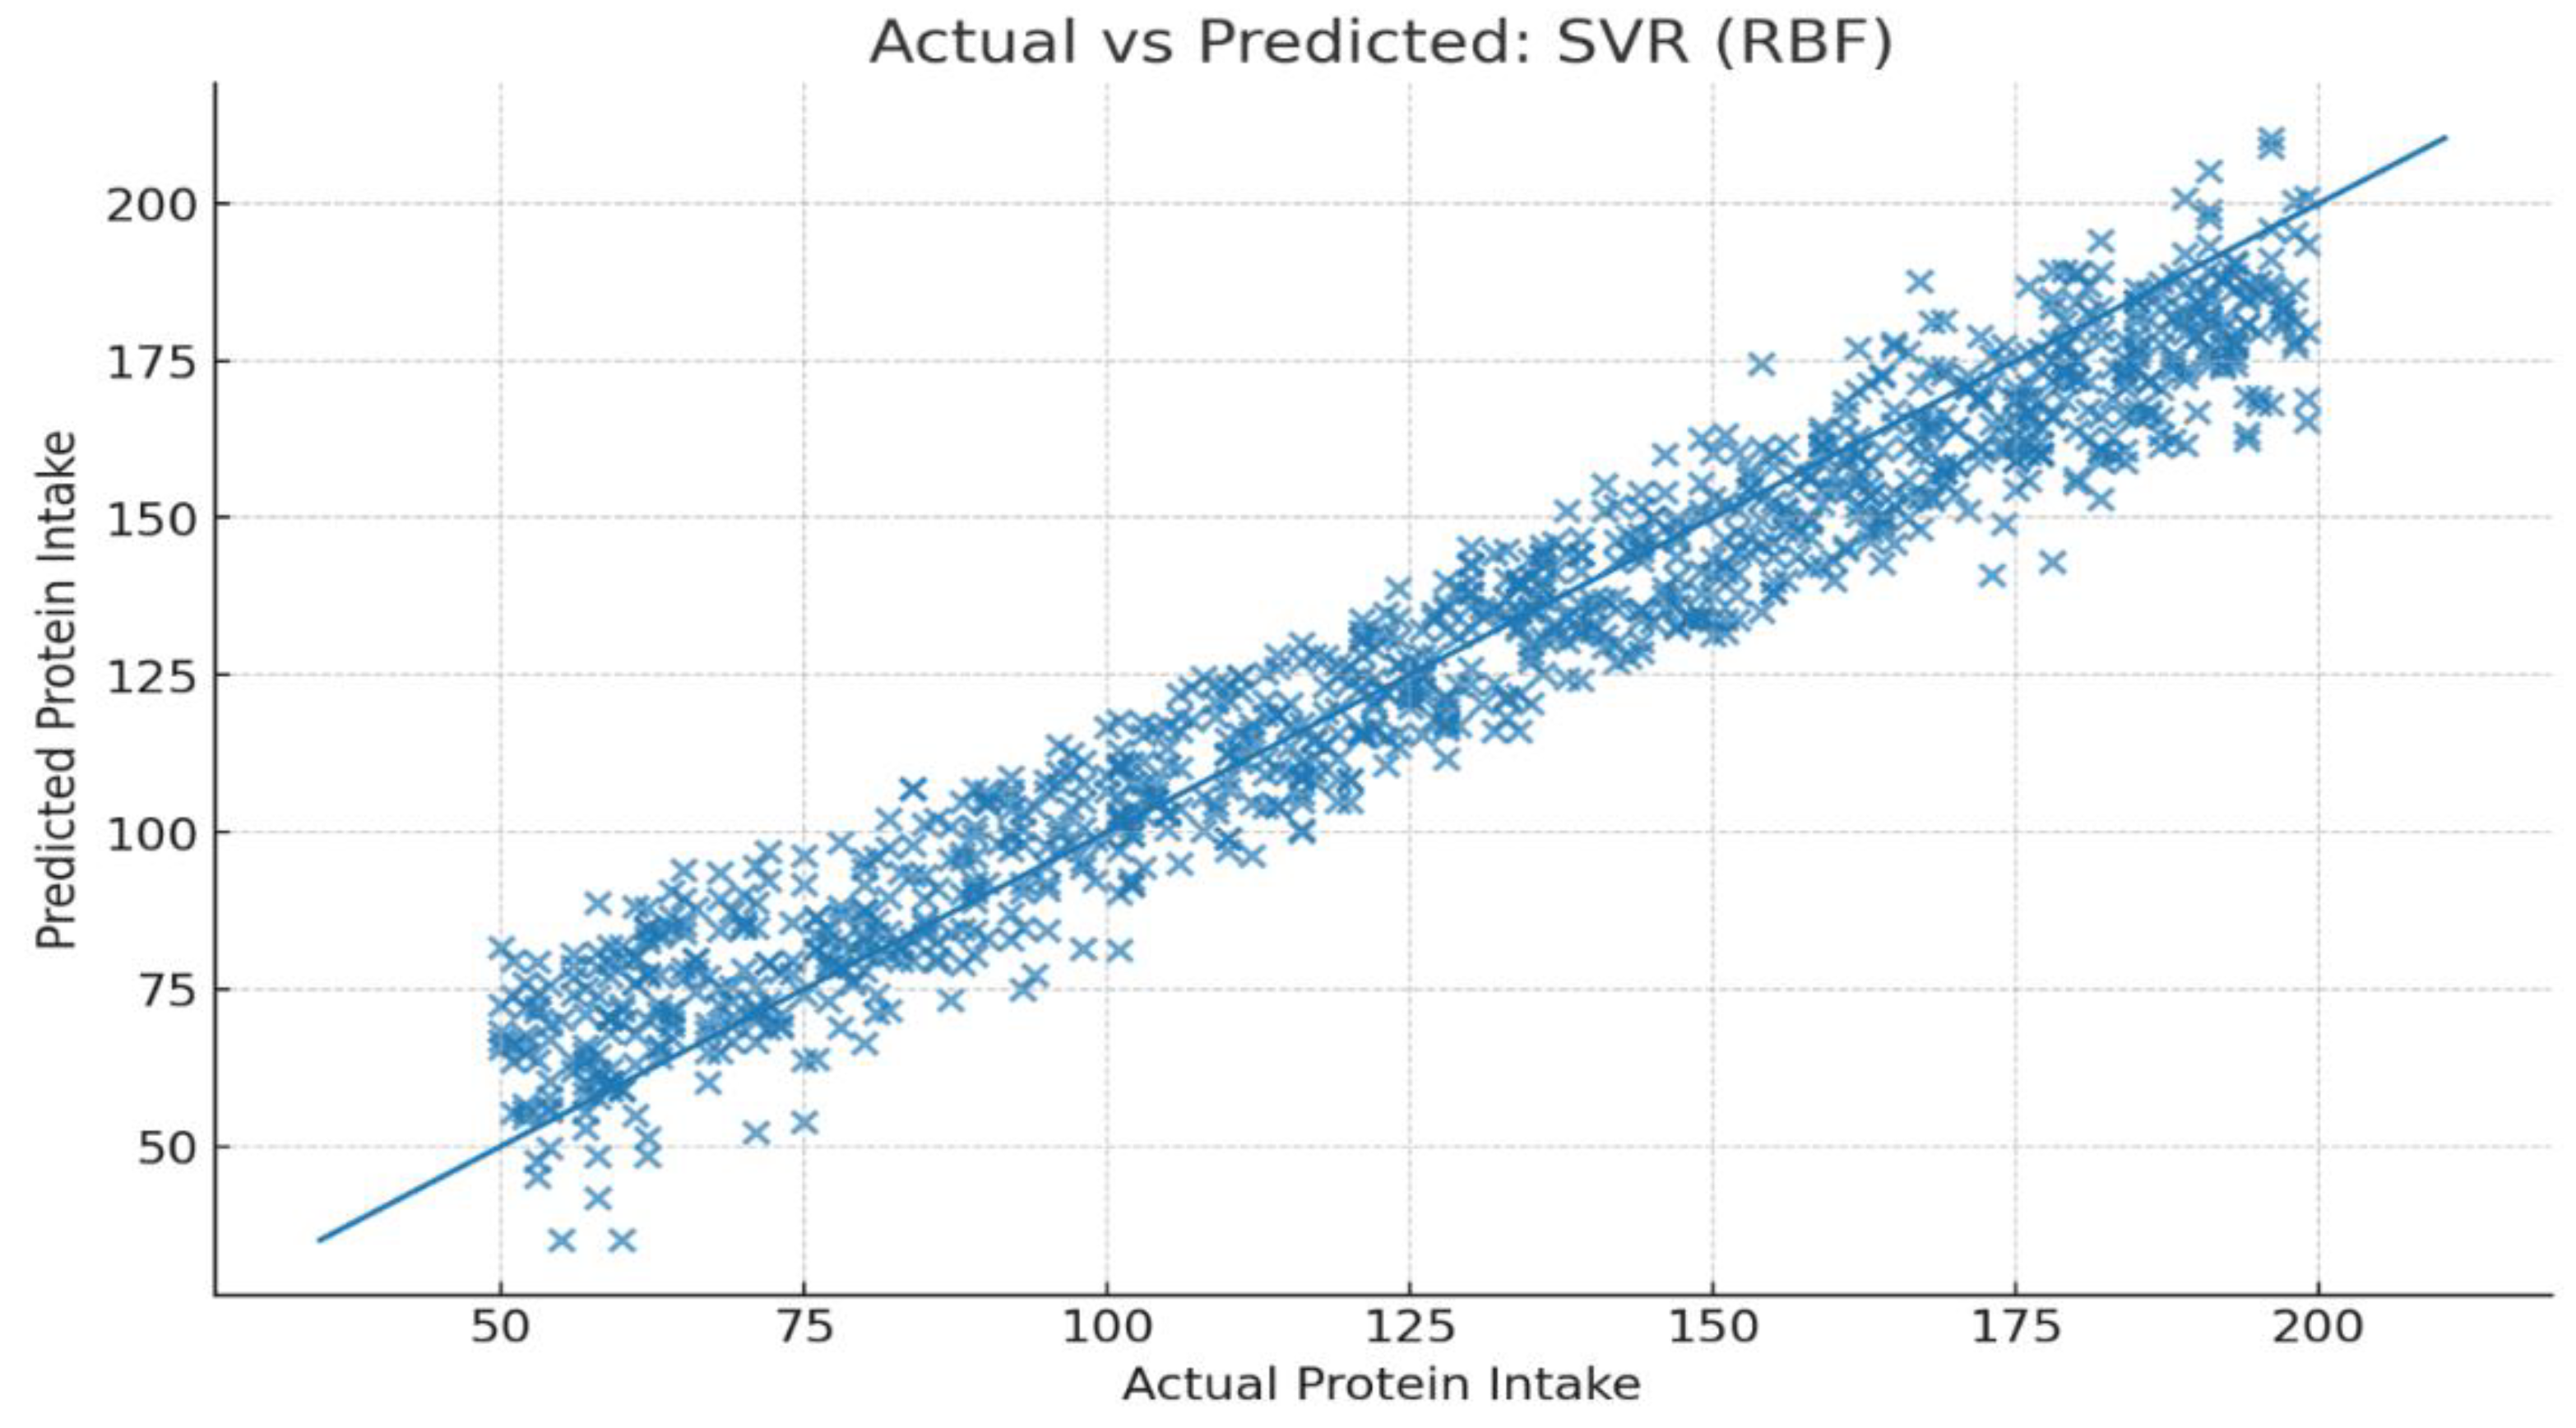
Best Parameters- n estimators = 93, max depth = 5, min samples split = 3, min samples leaf = 5
XG Boost -R2 = 0.9694
Best Parameters- n estimators = 88, max depth = 3, learning rate = 0.077
SVR -R2 = 0.9696
Best Parameters- C = 0.2988, gamma = 0.0257, kernel = linear
Key Findings
SVR had the highest R2 value, which means that it has the greatest predictive ability of protein intake. XG Boost and Random Forest have also done a good job, and the R 2 of the two is 0.9694 and 0.9692 respectively (Carballo-Casla et al., 2024). The efficiency and predictive accuracy of the hyperparameter optimization with the help of Optuna were better than those of the Grid Search CV, especially when it comes to SVR.
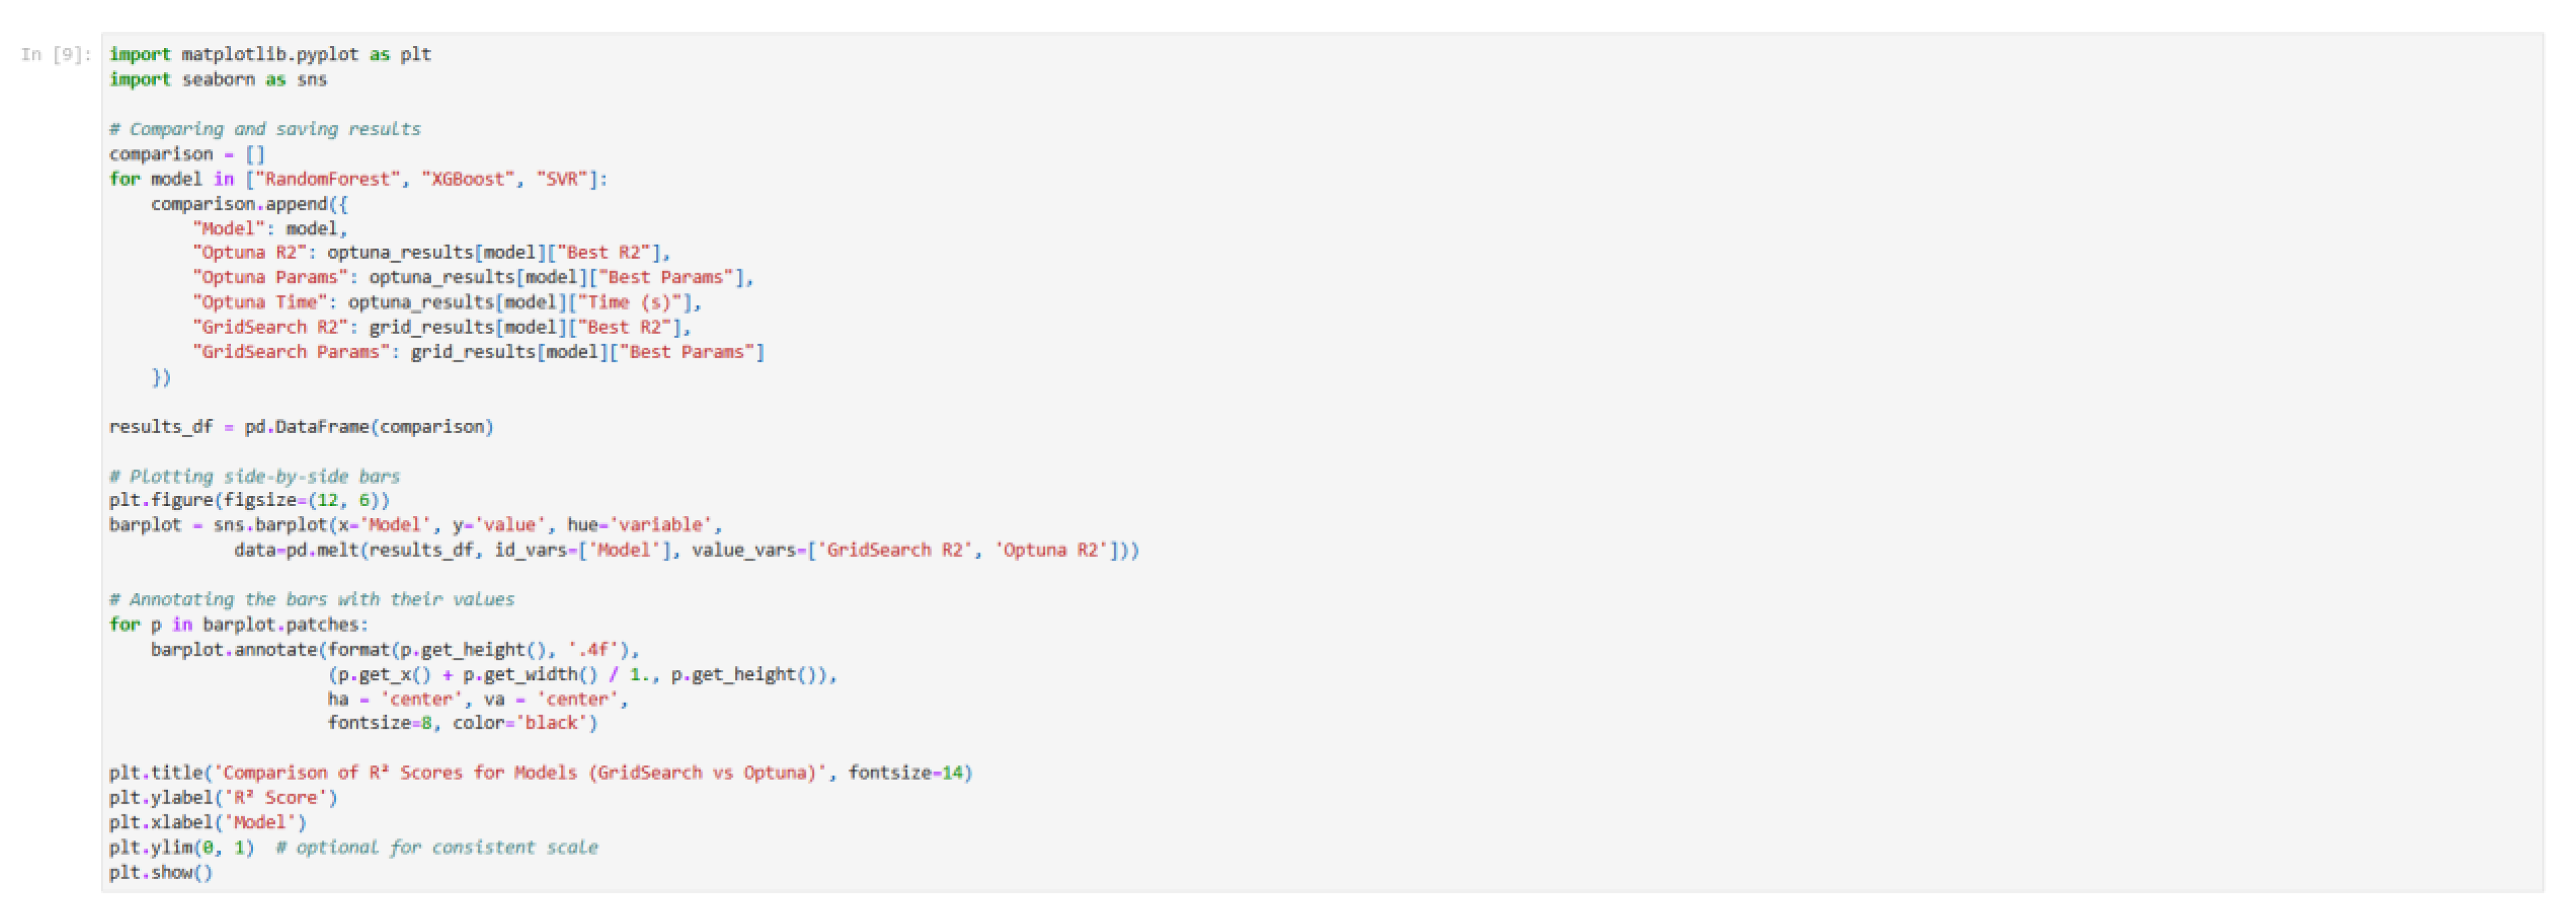
Comparison of Optuna and Grid Search CV Results
The outcome of the Optuna and the Grid Search CV was relatively the same, and there were various differences and the Optuna scores showed that SVR showed a slight superiority on both XG Boost and Random Forest with the R2 value of 0.9696, where XG Boost 0.9694 and Random Forest 0.9692 had to follow respectively. XG Boost and SVR had a highest R 2 score of 0.9695, whilst the random forest had a relatively lower R 2 score of 0.9690. These results indicate that the most appropriate models to apply in this activity are the SVR and XG Boost since they have a high predictive accuracy (Egert et al., 2025). Random Forest was also not very accurate, yet effective.
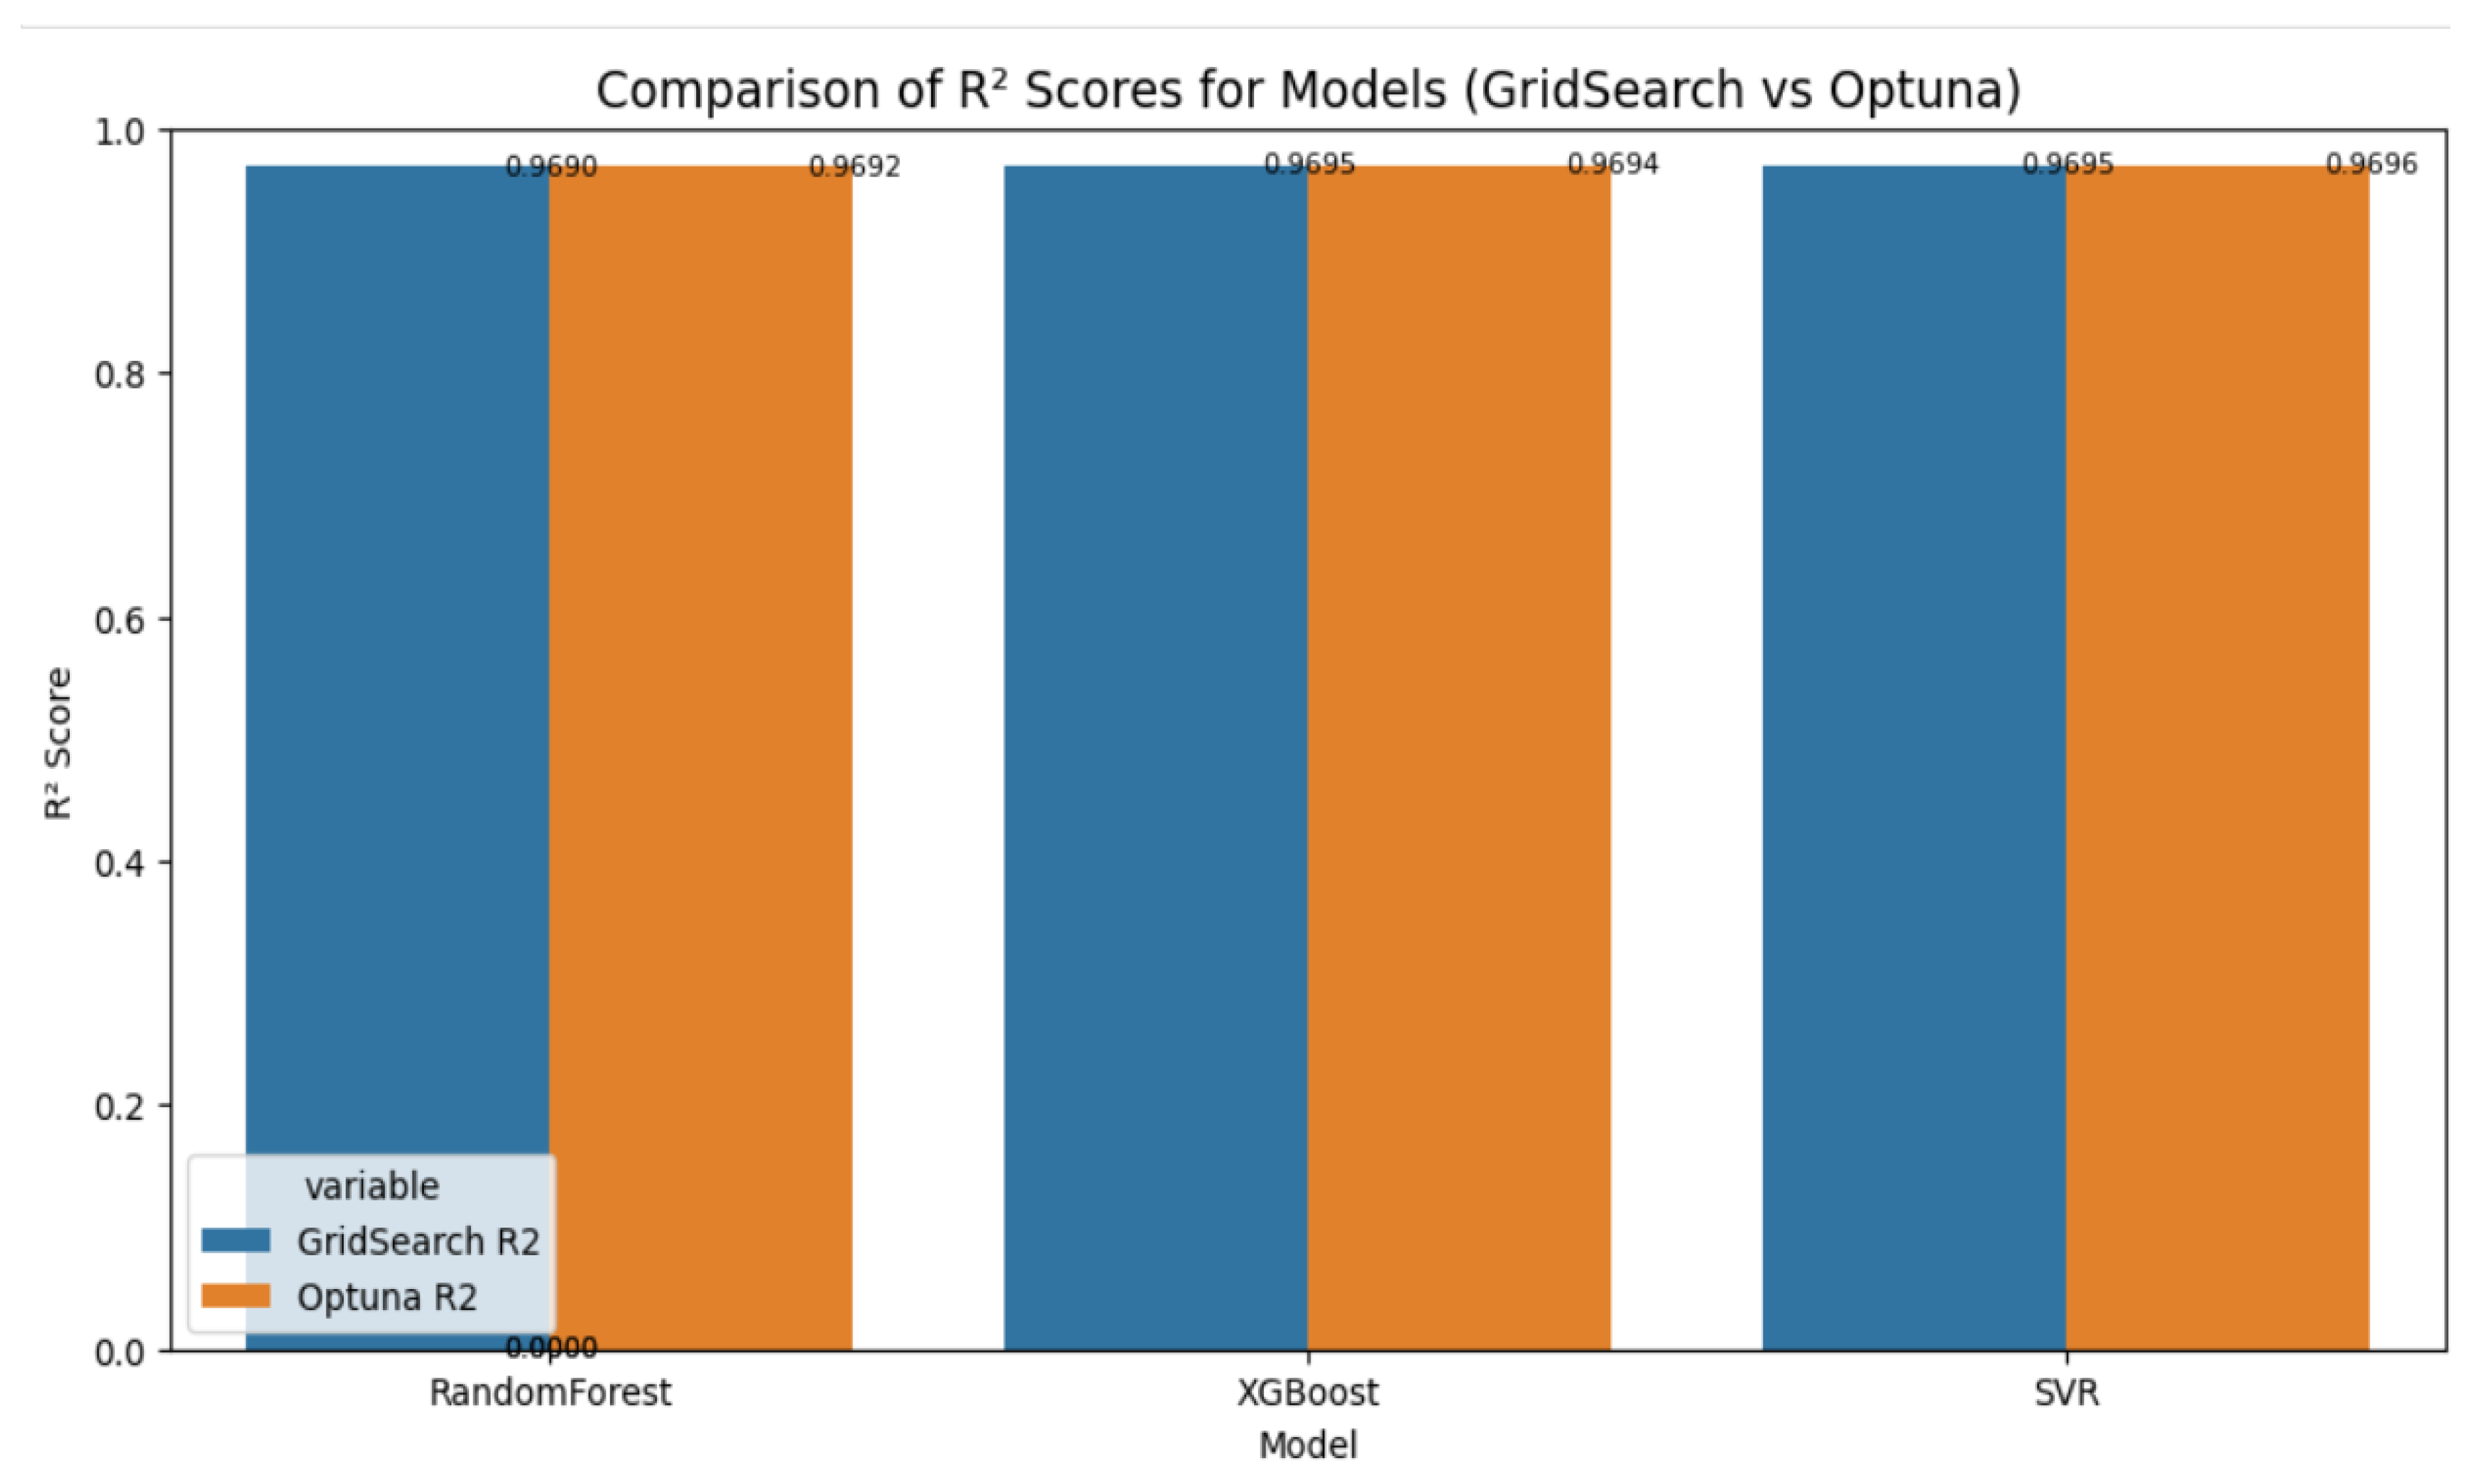
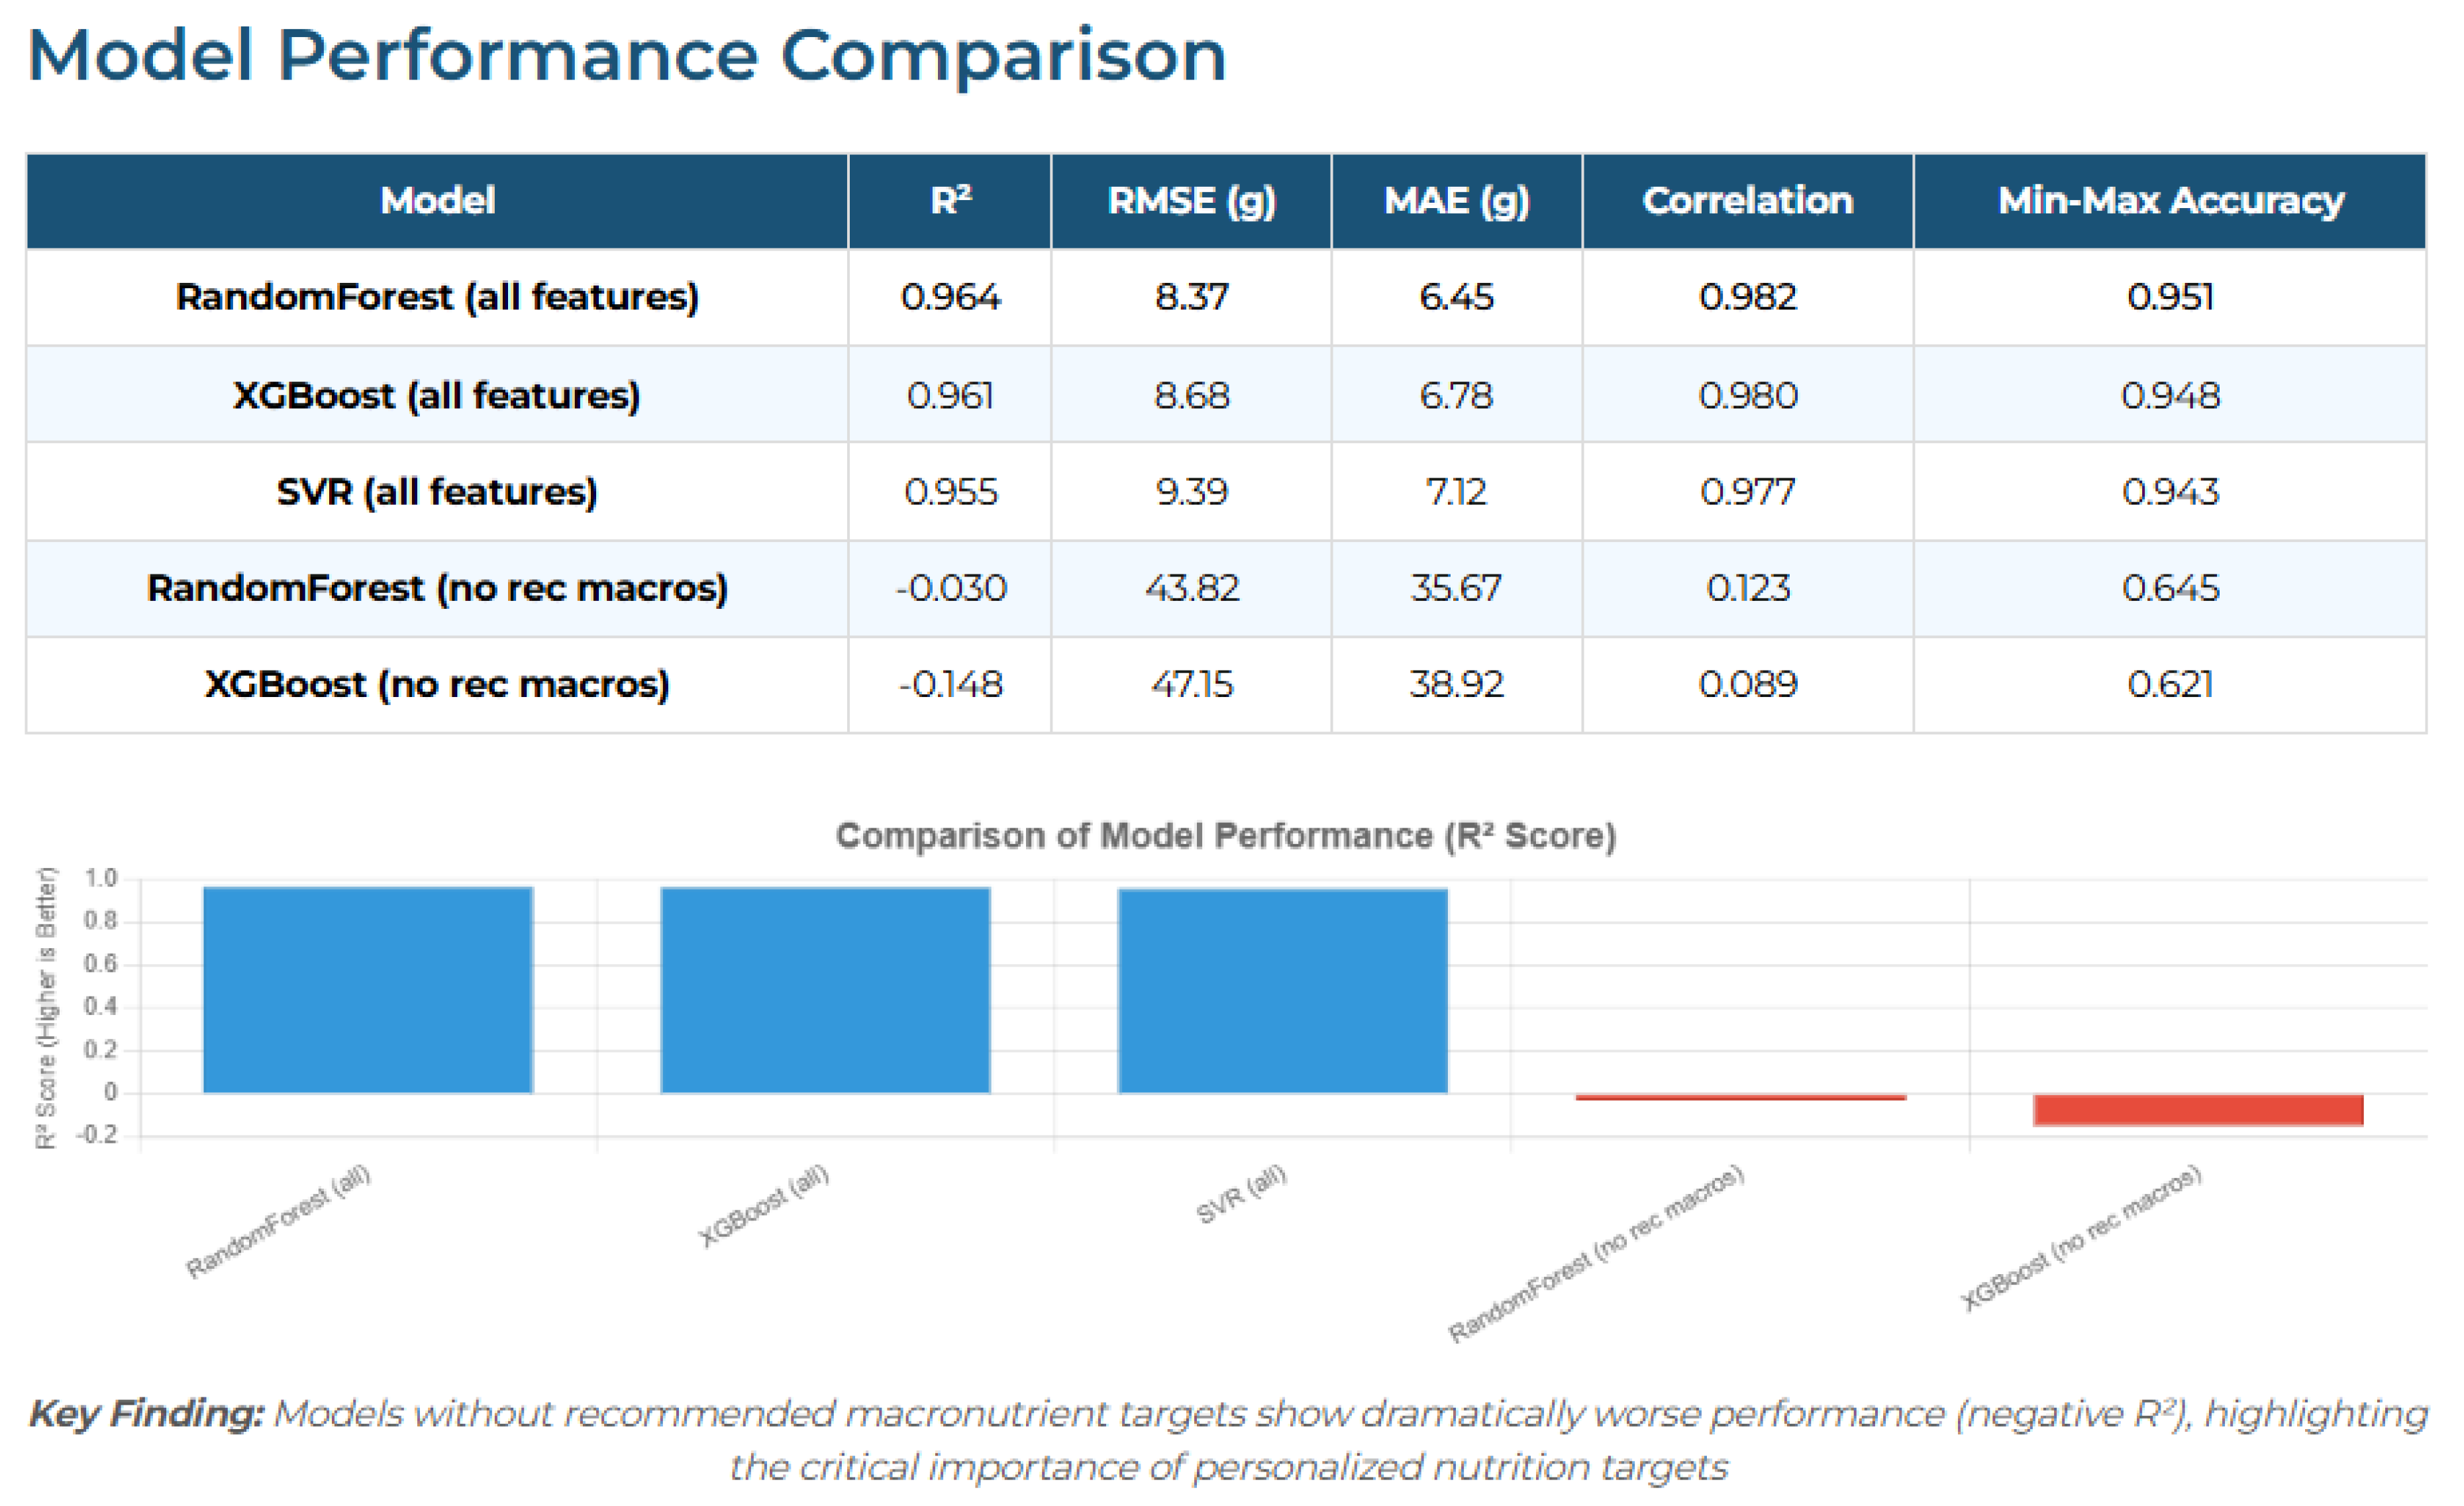
Model Performance comparison
6. Discussion
The argument demonstrates that diet regimes have colossal impacts on protein intake. The high-protein dieting remained to be associated with the optimal protein intake in all the statistical tests ANOVA, ANCOVA, MANOVA. Both SVR and XG Boost models predict the protein intake well and were optimized using Optuna but the SVR showed a better performance when compared to XG Boost (Shahnaz et al., 2024). The results suggest that machine learning models can be useful in predicting protein intake and also in tailoring dietary recommendation to individuals with chronic conditions.
Clinical Implications
The individual nutritional interventions that rely on SVR and XG Boost can be more efficient than the general recommendations about it (Shahnaz et al., 2024). It was revealed that high-protein diet was considered the most effective one in addressing the protein requirements of the aforementioned people with chronic illnesses, which can be considered a valid point in Favor of the use in the clinical practice. This study has significant clinical implications on the nutritional management of persons with chronic diseases. The results indicate that meal plans especially the high protein diets are key in raising the levels of protein intake that are essential in managing the diseases that affect muscle mass and recovery like chronic kidney disease and diabetes. Nevertheless, the analysis also reveals that the use of individualized nutrition plans is much more effective as compared to generalized meal plans in terms of predicting real levels of protein intake. The most significant characteristics that were evident in predicting protein intake were the recommended macronutrient targets protein, carbs, fats whereas such broad meal plan categories as high-protein and balanced diets had insignificant predictive value to the model.
Considering these results, we advise that health practitioners emphasize on customized dietary interventions based on personal requirements of macronutrients instead of basing them on broad categories of meals. This will result in better chronic disease management and patient outcomes will be better since the particular nutritional requirements will be taken into account. Moreover, machine learning models can be taken as a good resource by the clinicians to predict the nutritional intake of the patients and monitor it to offer the clinician with an evidence-based framework to make customized recommendations.
By introducing this quality nutrition practice in the clinical setting, we are able to maximize the care to the patient, decrease complications of malnutrition and improve the overall quality of life. More studies are required to examine the long term outcome of personalized diets and aim at studying the role of in addition to physical activity and psychological factors on dietary compliance and health outcome.
Limitations and Delimitations
The study offers some valuable information on the intake of proteins with regard to different meal plans, but there are several limitations that should be taken into consideration. First of all, this information was obtained through a secondary source and hence there is the risk of jeopardizing the precision of certain variables that could not be directly manipulated (French et al., 2025). In addition, the study was cross-sectional and it was not in a position to investigate the impact of the diet in the long term. Finally, the results may be invalid to other populations than those included in the data example individuals who may be living in other geographical localities.
Conclusion and Future Recommendations
The paper aimed to conduct research on the impact of the different proposed meal plans on the protein consumption of chronically ill individuals (Shahnaz et al., 2024). The SVR model which was a random forest and the XG Boost were also highly predictive as they were used to make the best predictions. These findings are indicative of the personalized diets and the high-protein diets in particular the diets that are centred on the high-protein foods are better placed in ensuring that the victims consume enough protein in the management of the chronic diseases (French et al., 2025). The paper in question demonstrates that the meal plans of the high protein can be addressed as one of the most critical aspects to be considered when it comes to regulating the protein intake and positively impacting the nutritional condition of the individuals with the chronic conditions. It also demonstrates the future aspects of the machine learning models, here being SVR, to forecast and optimize the prescription of protein intake to enhance clinical decision-making.
Future Recommendations
The research is credible in terms of giving information on the impact of different meal plans on protein consumption of individuals with chronic illnesses, but some areas need to be addressed through further research in serious study (Shahnaz et al., 2024). To give an example, the cross-sectional design does not enable one to observe the long-term effects of a diet, and longitudinal research is required. In addition, the effects of other macronutrients and micronutrients, dietary adherence, and expansion of the sample to a more diverse population would be interesting studies that would be more indicative of the importance of nutrition in managing chronic disease and customized dietary interventions.
Longitudinal Studies
The study entailed the use of cross-sectional study design, which limits the study into the sustainability of the different meal plans on protein intake and the outcome of chronic illnesses (Egert et al., 2025). Other studies that can be conducted include longitudinal studies to follow the effects of the dietary intervention over the long-term and provide a more detailed account of the effects of meal plans on health among the affected population with chronic diseases.
Inclusion of More Dietary Factors
The Unlike where the final focus was taken on protein, the future research studies can be extended to include other dietary factors such as carbohydrates, fats, and micronutrients (French et al., 2025). Investigating the relationship between these factors and how they interact to influence the management of chronic diseases would provide a more wholesome perspective of the role of nutrition in healthcare.
Personalized Nutrition
The variation in protein intake and health among different groups of the population and therefore, more studies should be done regarding the topic of personalized nutrition interventions (Liu et al., 2025). The subsequent study could be focused on developing individualized diets depending on specific chronic conditions, interests of patients and genetic data basing on clinical data and machine-learning systems to allow being more accurate.
Compliance with nutrition
The second possible research of the future is the compliance with the meal plans. The research possesses a clear relationship between the meal plans and protein consumption but not on the compliance of the set diets by the participants (Shahnaz et al., 2024). Dietary recommendations would also be enhanced by the use of dietary adherence measures as the dietary adherence and health outcome are added to the theory.
Expanding the Dataset
The Kaggle dataset is acceptable, but the additional sample size with more diverse population particularly regarding ethnicity and location would assist in enhancing the applicability of the results (Liu et al., 2025). In addition, including even more specific information about the medical history of particular patients may be possible, which would allow making an even more specific meal plan recommendation.
Investigating Other Optimization Techniques
The Within the same work, the implementation of Optuna was adopted as an efficient hyperparameter optimization method of machine learning models, yet in the future (French et al., 2025). The other types of optimization algorithms example are the genetic algorithms or Bayesian optimization can be applied to optimize the predictive ability of the dietary intake models.
Diet-Related Health Outcomes
The final study should be done to review the effect of diet plans on the health outcomes of other factors other than the protein consumption, and involve blood pressure, the degree of cholesterol and glycaemic efficacy. By examining the effects of these markers or meal plans, researchers can produce recommendations which are more detailed and can be applied in the management of chronic diseases. The effect of type of meal plan on protein intake amid individuals with chronic diseases could be proven in this study (Egert et al., 2025). The research offers an excellent framework of the diet application in determining the impacts of nutritional intake and health outcome using conventional statistical procedures as well as innovative machine learning algorithms. These findings indicate the relevance of the individual food interventions especially the high-protein diets in enhance the nutritional conditions of the people who have chronic illnesses. The further studies ought to be geared towards further extension of the findings by introducing longitudinal studies, examination of other constituents of a diet and a deeper study of the role of personalized nutrition in treating chronic disease.
Code Availability Statement
The code used for data preprocessing, statistical analysis, and machine learning model development is not publicly available but can be furnished upon reasonable request to the author. The Python and R scripts include detailed instructions for reproducing the analysis, including data loading, preprocessing, statistical testing, and model training procedures. All required libraries and dependencies are documented to ensure reproducibility.
Data Availability Statement
The dataset itself that was used in this paper and the name of the dataset is Personalized Medical Diet Recommendations which is publicly available on the Kaggle located at the following URL: https://www.kaggle.com/datasets/ziya07/personalized-medical-diet-recommendations-dataset. The information includes the information on meat intake, food diets, nutrition programs, and protein intake of individuals who are diagnosed with chronic illnesses (Egert et al., 2025). It was possible to download the dataset itself and analyse it further and recreate the study. The access to the data is provided according to the Kaggle terms and conditions that a user is supposed to agree in order to access the data.
Appendix
Data Preprocessing
Data Cleaning
Comparative analysis grid search vs. optuna
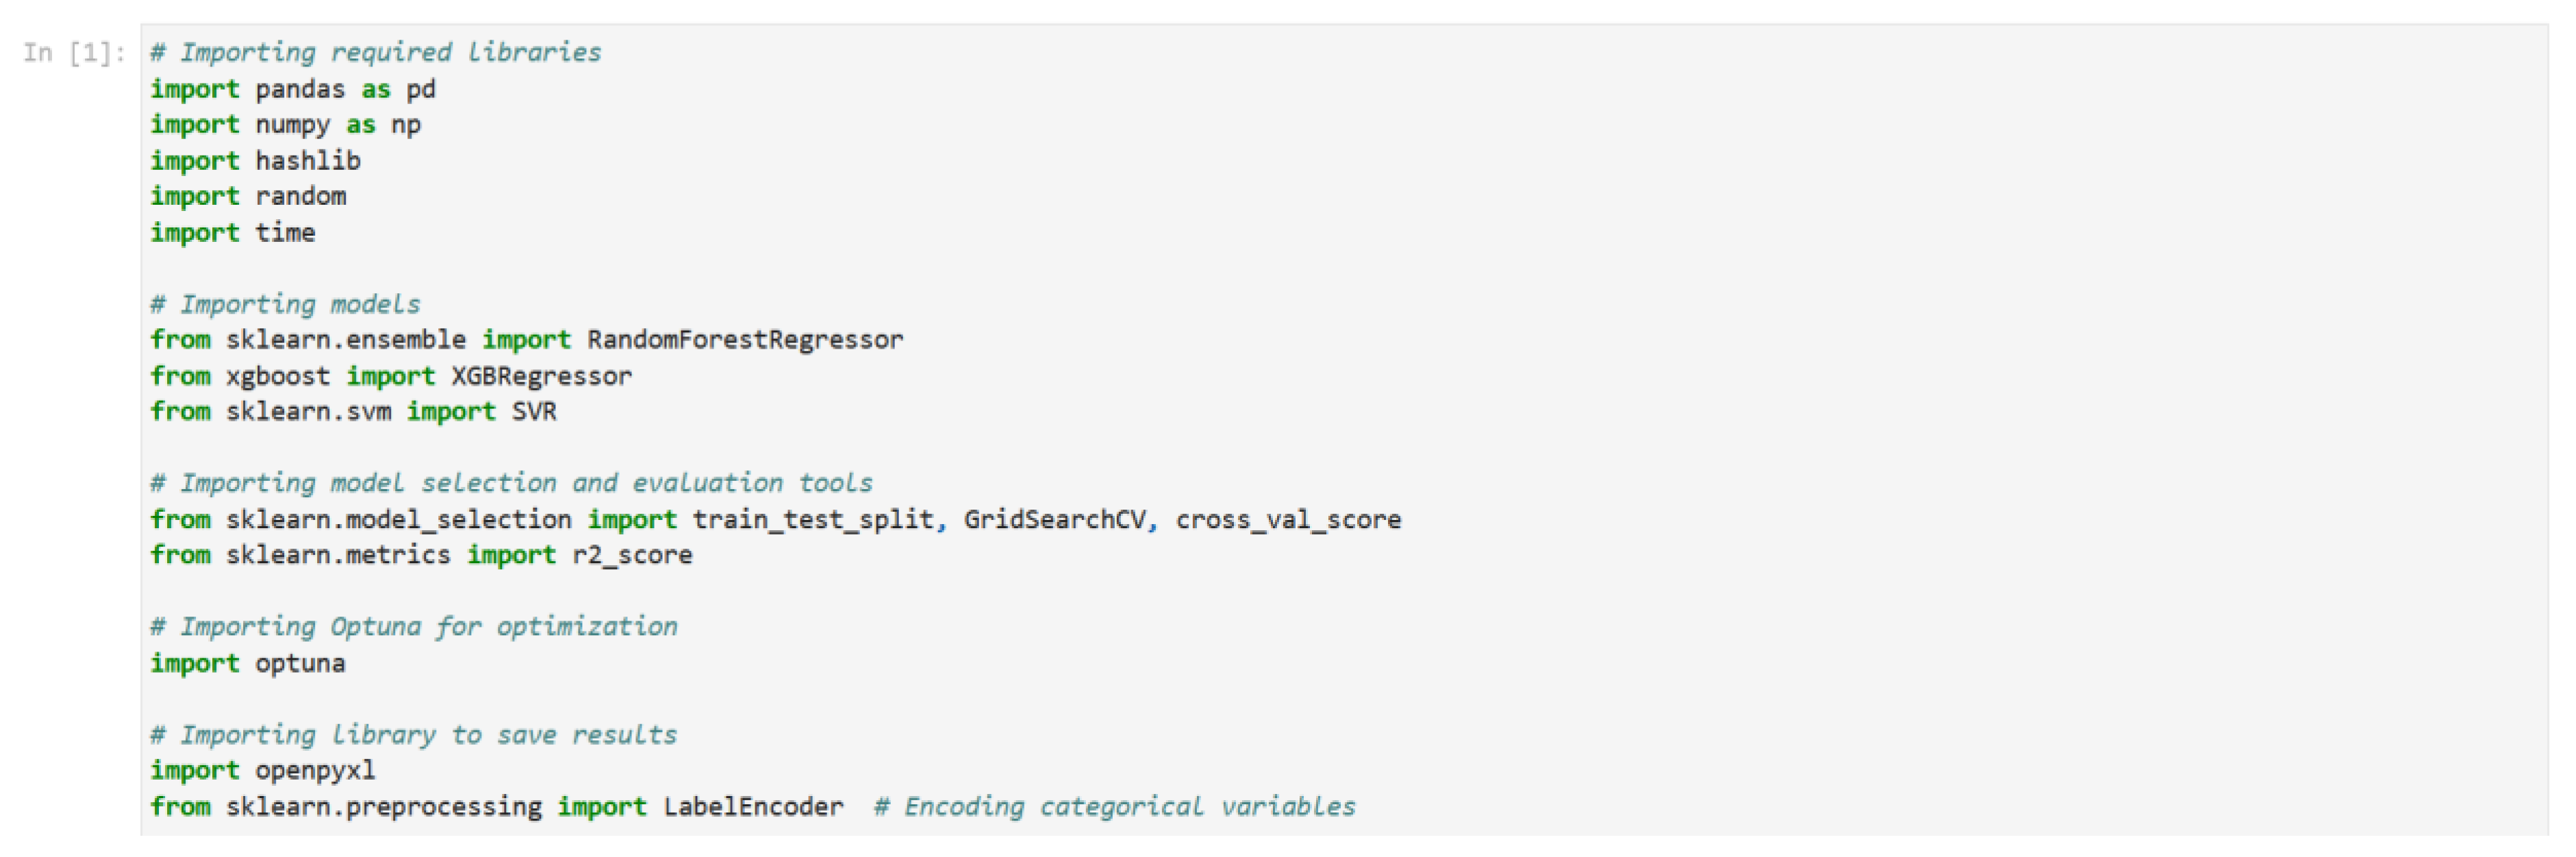
Generating Random Seed Using MD5 Hash
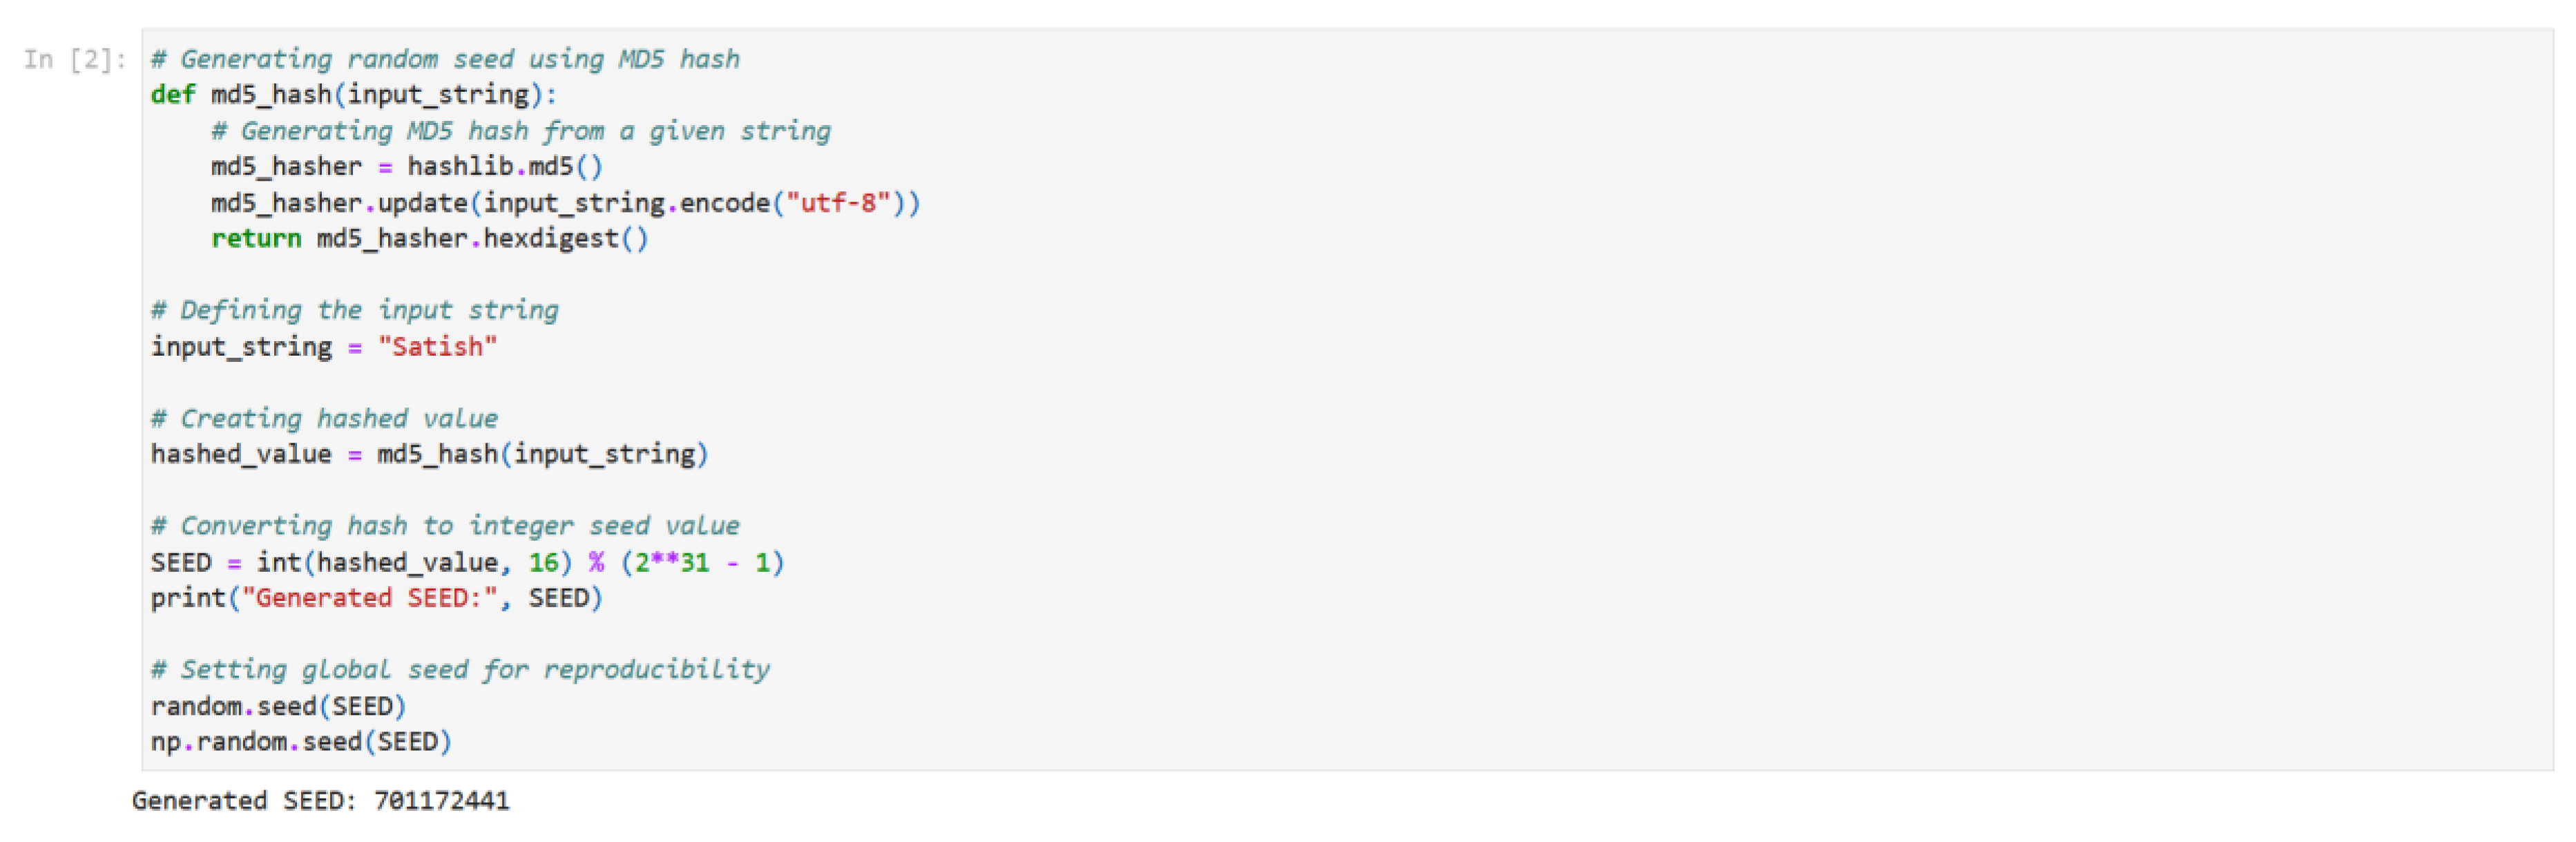
Comparison
References
- Alyafei, A., & Daley, S. F. (2025). The Role of Dietary Lifestyle Modification in Chronic Disease Prevention and Management. In StatPearls [Internet]. StatPearls Publishing. https://www.ncbi.nlm.nih.gov/books/NBK587401/.
- Carballo-Casla, A., Avesani, C. M., Beridze, G., Ortolá, R., García-Esquinas, E., Lopez-Garcia, E., ... & Calderón-Larrañaga, A. (2024). Protein intake and mortality in older adults with chronic kidney disease. JAMA Network Open, 7(8), e2426577-e2426577.
- Carbone, J. W., Phillips, S. M., Weaver, C. M., Hughes, J. M., & Pasiakos, S. M. (2025). Exploring opportunities to better characterize the effects of dietary protein on health across the lifespan. Advances in Nutrition, 16(1), 100347. [CrossRef]
- Egert, S., Amini, A. M., Klug, L., Kalotai, N., Haardt, J., Boeing, H., ... & Ellinger, S. (2025). Protein intake and cardiovascular diseases: an umbrella review of systematic reviews for the evidence-based guideline on protein intake of the German Nutrition Society. European Journal of Nutrition, 64(6), 1-14. [CrossRef]
- Fouillet, H., Huneau, J. F., Perraud, E., Dussiot, A., Wang, J., Kesse-Guyot, E., & Mariotti, F. (2025). Plant to animal protein ratio in the diet of the elderly: potential for increase and impacts on nutrient adequacy and long-term health–a diet optimization study. The American Journal of Clinical Nutrition. [CrossRef]
- French, S. J., Kanter, M., Maki, K. C., Rust, B. M., & Allison, D. B. (2025). The harms of high protein intake: conjectured, postulated, claimed, and presumed, but shown?. The American Journal of Clinical Nutrition. [CrossRef]
- Ko, G. J., Rhee, C. M., Kalantar-Zadeh, K., & Joshi, S. (2020). The effects of high-protein diets on kidney health and longevity. Journal of the American Society of Nephrology, 31(8), 1667-1679.
- Korat, A. V. A., Shea, M. K., Jacques, P. F., Sebastiani, P., Wang, M., Eliassen, A. H., ... & Sun, Q. (2024). Dietary protein intake in midlife in relation to healthy aging–results from the prospective Nurses’ Health Study cohort. The American Journal of Clinical Nutrition, 119(2), 271-282. [CrossRef]
- Kwon, Y. J., Lee, H. S., Park, G. E., Kim, H. M., Lee, J. J., Kim, W. J., & Lee, J. W. (2022). The association between total protein intake and all-cause mortality in middle aged and older Korean adults with chronic kidney disease. Frontiers in Nutrition, 9, 850109. [CrossRef]
- Li, T., Guan, L., Wang, X., Li, X., Zhou, C., Wang, X., ... & Xi, Y. (2022). Relationship between dietary patterns and chronic diseases in rural population: management plays an important role in the link. Frontiers in Nutrition, 9, 866400. [CrossRef]
- Lichtenstein, A. H., Appel, L. J., Vadiveloo, M., Hu, F. B., Kris-Etherton, P. M., Rebholz, C. M., ... & American Heart Association Council on Lifestyle and Cardiometabolic Health; Council on Arteriosclerosis, Thrombosis and Vascular Biology; Council on Cardiovascular Radiology and Intervention; Council on Clinical Cardiology; and Stroke Council. (2021). 2021 dietary guidance to improve cardiovascular health: a scientific statement from the American Heart Association. Circulation, 144(23), e472-e487. [CrossRef]
- Liu, D., Li, Q., Jia, R., He, W., Zhao, X., Pan, M., ... & Wang, W. (2025). Type 2 diabetes mellitus with chronic kidney disease benefits from long-term restriction of dietary protein intake: a 10-year retrospective cohort study. BMC nutrition, 11, 131. [CrossRef]
- Morgan, P. T., Carson, B. P., & Witard, O. C. (2024). Dietary protein considerations in a sustainable and ageing world: a narrative review with a focus on greenhouse gas emissions and skeletal muscle remodelling and maintenance. BMC Musculoskeletal Disorders, 25(1), 1030. [CrossRef]
- Ravi, S., Fahrner, A., Rühli, F., & Bender, N. (2025). Current Guidelines on Dietary Protein Intake for Patients with Diabetic Kidney Disease: A Scoping Review. Current Developments in Nutrition, 107551. [CrossRef]
- Shahnaz, T., Fawole, A. O., Adeyanju, A. A., & Onuh, J. O. (2024). Food proteins as functional ingredients in the management of chronic diseases: a concise review. Nutrients, 16(14), 2323. [CrossRef]
- Workeneh, B. T., Moore, L. W., & Mitch, W. E. (2025). Revisiting Protein Restriction in Early CKD: Did We Get it Wrong?. American Journal of Kidney Diseases, 85(5), 654-657.
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2025 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (http://creativecommons.org/licenses/by/4.0/).
Copyright: This open access article is published under a Creative Commons CC BY 4.0 license, which permit the free download, distribution, and reuse, provided that the author and preprint are cited in any reuse.