

Submitted:
22 September 2026
Posted:
22 September 2026
You are already at the latest version
Abstract
Marine invertebrates and their microbial partners provide distinctive chemical scaffolds, but computational prioritization alone can overstate translational progress when experimental support and material supply remain limited. This critical narrative review proposes a linked-record framework for evaluating exact entity-indication pairs on two independent axes: therapeutic-evaluation stage (E1, in silico, to E4, human intervention) and production readiness (S1, discovery access, to S4, GMP or commercial manufacture). E records the highest stage documented in the reviewed sources, not evidence strength or therapeutic success. Computational contribution, evidence direction, study quality, provenance, and scenario-specific supply adequacy remain separate attributes; E and S are not combined into a composite score. Contrasting lineages involving halichondrin B and eribulin, (+)-aeroplysinin-1, a sea-star steroid, acanthomanzamine C, cynthichlorine, gukulenin A, and meridianin mixtures illustrate how uncertain chronology, test-article mismatch, incomplete validation, and poorly characterized production routes affect interpretation. A worked mass balance distinguishes physical access from the amount required for a defined experiment. Supply-by-design therefore integrates identity, route feasibility, demand, ecological constraints, and access obligations at nomination. The framework is preliminary and requires independent reliability and prospective utility testing.
Keywords:
marine natural products
; marine invertebrates
; machine learning
; virtual screening
; molecular docking
; therapeutic-evaluation stage
; production readiness
; sustainable supply
; bioprospecting
1. Introduction
Natural products contribute to medicines as unmodified structures, semisynthetic derivatives, synthetic analogues, and templates for medicinal chemistry. Marine environments extend this chemical repertoire through halogenated metabolites, macrocycles, densely stereogenic scaffolds, unusual amino acids, and polyether systems. Sponges, tunicates, molluscs, bryozoans, cnidarians, and echinoderms are important collection hosts for compounds with cytotoxic, ion-channel-modulating, anti-infective, and molecular-probe activities [1,2]. Their chemical diversity creates opportunities for discovery, but useful biological activity and practical access must be established for the same defined material.
The term ‘invertebrate-derived’ can overstate provenance because the collection host is not necessarily the biosynthetic producer. Associated microorganisms may synthesize or modify the recovered metabolite; for example, an uncultivated sponge symbiont was shown to encode several distinct polyketide families [3]. We therefore use ‘marine invertebrate-associated’ unless biosynthesis has been assigned more specifically. Distinguishing the host from the producer informs route selection, ecological assessment, provenance, and access-and-benefit-sharing considerations.
Established marine drug lineages illustrate both the value of this chemistry and the difficulty of translation [1,2]. The halichondrin B-eribulin lineage discussed below is particularly informative: a potent natural-product parent and its clinically used synthetic analogue are chemically related, but their biological evidence and manufacturing histories are not interchangeable. Computational findings should be interpreted within such development histories rather than treated as substitutes for pharmacology, formulation, or process development.
Computational prioritization can reduce the number of compounds taken forward when isolation is costly and material is scarce. Docking, molecular dynamics (MD), quantitative structure-activity relationship (QSAR) modeling, target prediction, machine learning, and generative design offer complementary approaches [4,5,6]. Their usefulness nevertheless depends on data quality and the decision being supported. Biased datasets, analogue leakage between training and test sets, uncertain binding-site structures, and uncalibrated predictions can inflate apparent performance. Marine chemotypes may be poorly represented in training data, making applicability-domain assessment especially important.
Supply creates a second bottleneck that is partly independent of biological evidence: potency cannot compensate for material that cannot be obtained again. Discovery assays may consume micrograms or milligrams, whereas formulation, toxicology, clinical development, and manufacture can require substantially larger quantities. Wild collection may be unsuitable for sustained demand, particularly for slow-growing or ecologically sensitive organisms. Total synthesis, semisynthesis, aquaculture, fermentation, symbiont cultivation, and heterologous expression offer alternative routes, but each has molecule- and producer-specific limitations [7,8,9].
Reviewing biological evidence and supply separately can conceal important mismatches. An untested docking hit, an animal-active mixture of uncertain composition, a cellular result dependent on one isolation, and a licensed synthetic analogue represent different development situations. Describing all of them as ‘promising leads’ obscures the exact material, the evidence supporting it, and the route available to reproduce the next experiment.
This review examines computational practice, proposes a preliminary two-axis framework, and applies it to deliberately contrasting lineages. The cases are illustrative rather than representative and cannot establish prevalence. The framework does not estimate therapeutic value; it makes the decision record explicit: what material was tested, which stage was documented, how the material was obtained, what computation changed, and whether the demonstrated route can meet the next defined demand.
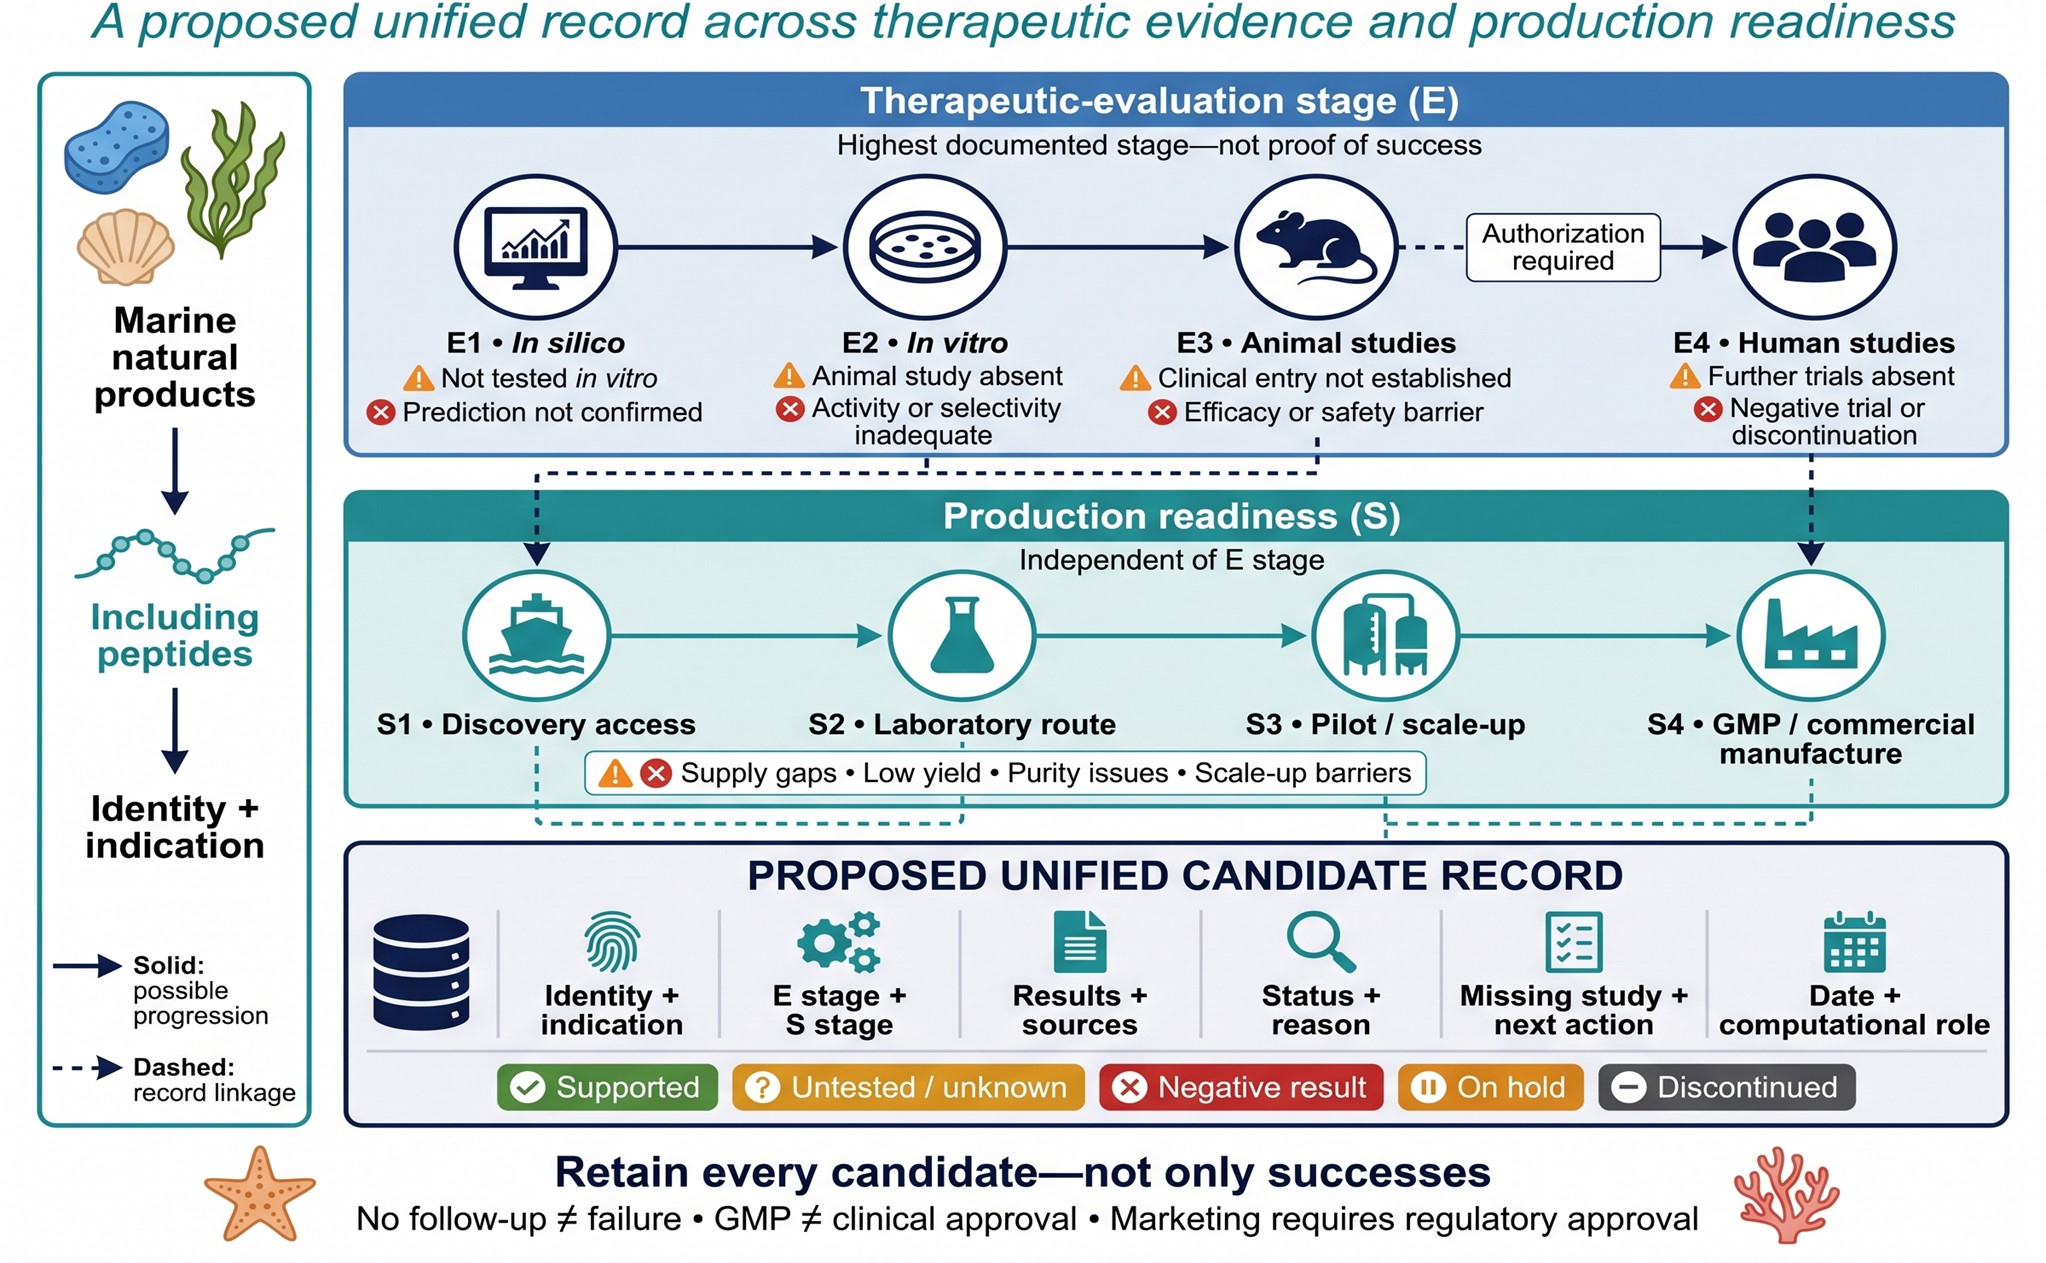
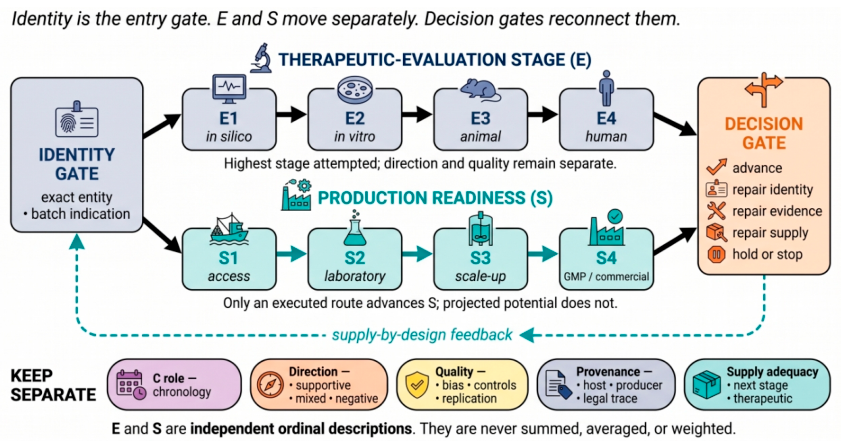
Figure 1.
Linked-record framework. Identity is the entry gate. Therapeutic-evaluation stage (E) and production readiness (S) advance on parallel, independent tracks and reconnect at explicit decision gates. Computational role, evidence direction, quality, provenance, and scenario-specific supply adequacy remain separate attributes. Supply-by-design returns route constraints to prioritization.
Figure 1.
Linked-record framework. Identity is the entry gate. Therapeutic-evaluation stage (E) and production readiness (S) advance on parallel, independent tracks and reconnect at explicit decision gates. Computational role, evidence direction, quality, provenance, and scenario-specific supply adequacy remain separate attributes. Supply-by-design returns route constraints to prioritization.
2. Review Approach and Analytical Unit
2.1. Critical-Review Design and Search Approach
This article is a structured critical narrative review, not a systematic or scoping review. No protocol was registered, screening was not performed in duplicate, and study frequencies were not calculated. SANRA domains provide a reporting reference for the rationale, aims, search description, referencing, scientific reasoning, and presentation of relevant outcomes; their use does not validate the proposed E/S/C framework.
Targeted literature discovery covered 1 January 2015 to 9 August 2026. PubMed was searched for marine-source terms combined with computational terms. The main query is shown in Table 1. We also searched publisher sites and Crossref metadata. Backward and forward citation chasing was used for key studies. Historical lineage records had no date limit. These records included original isolation, biological testing, synthesis, production, regulatory documents, and mechanism studies.
The search was used for concept discovery and source verification. It was not treated as a screened corpus. We therefore report no record count or PRISMA flow. English-language full texts were prioritized. Reviews supplied context. Primary sources supported case classifications. Current regulatory claims were checked against official sources.
Cases were selected for contrast rather than representativeness. Eligibility required a named entity, derivative, or described mixture; a therapeutic claim or development lineage; and primary evidence supporting at least one framework attribute. The selected cases span a mature natural-product-to-drug lineage, computation-guided isolation, recent antiviral and anticancer investigations, and an identity-limited mixture. This purposive selection illustrates different decision problems but cannot quantify their frequency in the wider literature.
2.2. Exact Entity-Indication Pair as the Unit of Analysis
The analytical unit is an exact entity-indication pair. A stereochemically defined molecule, derivative, and mixture require separate records, and therapeutic evidence is not transferred between constituents, congeners, parent-derivative pairs, or indications. Production evidence may inform more than one indication only when the chemical identity and relevant quality specification are demonstrably the same; demand and formulation suitability must still be reassessed for each scenario. Chemical lineage links provide context but do not confer shared development status.
An identity threshold precedes classification. A named molecule must be identifiable and traceable between biological and production records. A mixture constitutes its own entity and requires a reproducible composition or batch specification. When materials cannot be matched adequately, the experiment can still be described, but a joint E×S coordinate is withheld. This prevents apparently mature records from being assembled from incompatible test articles.
2.3. Extraction and Judgment
Case records capture entity and indication, collection host, producer evidence, computational method and chronology, biological model, exposure, controls, outcomes, and evidence direction. Production fields include route, isolated output or yield, identity, purity, and batch evidence. Regulatory status and the next decision gate are recorded separately. Each assignment represents the highest stage directly documented in the sources reviewed, rather than a claim that all relevant literature has been retrieved. Missing information is distinguished from a demonstrated absence and labeled as not reported, uncertain, not assessable, or not applicable, as appropriate.
2.4. Classification Procedure and Planned Validation
One reviewer created the current case records. Each field was linked to a primary source. Ambiguous assignments were resolved conservatively. A level was withheld when the identity threshold failed. The framework has not yet been tested between independent reviewers. It is therefore described as preliminary.
Independent reliability testing is a proposed next step, not a completed or registered validation study. Reviewers with complementary expertise should classify a deliberately varied sample independently using a frozen coding manual; the sample size should be justified by the intended precision of agreement estimates. Weighted agreement measures with confidence intervals may be used for the ordinal E and S axes, while categorical agreement should be examined for C, evidence direction, and supply adequacy. Disagreements should be analyzed by cause, including identity mismatch, unclear chronology, and missing production information, before the framework is presented as a validated tool.
3. Chemical, Provenance, and Data Foundations
3.1. Chemical Complexity and Source Attribution
Marine natural products occupy chemical space that is simultaneously valuable and difficult to model. Large macrocycles and polyethers can have many low-energy conformers. Dense stereochemistry makes two-dimensional similarity an incomplete proxy for recognition. Halogenation and uncommon heterocycles may be poorly represented in training data. Peptides can sit outside standard small-molecule assumptions, while salts, tautomers, protonation states, and stereochemical annotations are inconsistently standardized across repositories. These issues affect docking preparation, descriptor calculation, model transferability, and compound matching.
Provenance data are similarly layered. A field record may identify a collection site and a host taxon without establishing the biosynthetic producer. Even a strong host association may vary geographically with the microbiome. Conversely, a biosynthetic gene cluster identified in a symbiont does not by itself establish a scalable production host. A useful record should therefore distinguish collection host, inferred or demonstrated biosynthetic producer, geographic and permit metadata, voucher or strain identifiers, and the route by which the evaluated batch was obtained.
Recent work illustrates that computational methods can also help correct provenance. A structure-based deep-learning framework was developed to identify marine-natural-product misannotations arising from host-microbe symbiosis [10]. Such approaches may improve databases, but predicted reassignment should remain separate from demonstrated biosynthesis. Provenance confidence is therefore an attribute in our framework, not a substitute for production readiness.
3.2. Databases, Spectra, and Traceability
The Comprehensive Marine Natural Products Database (CMNPD) integrates structures with taxonomic, geographic, biological, and physicochemical information and contained more than 31,000 compounds at publication [11]. The Natural Products Atlas provides an open, organism-centered resource for microbial natural products [12]. Global Natural Products Social Molecular Networking (GNPS) enables community sharing and spectral networking, helping investigators dereplicate known metabolites and connect related features before exhaustive isolation [13]. These resources serve complementary purposes. None guarantees that a database structure is linked to a verified producing organism, a physical sample, an assay-ready quantity, or a reproducible production route.
Traceability can be lost during modeling. Standardization may remove stereochemical or salt information. Deduplication can collapse distinct provenance records. Fragment-based generation can retain a substructure while severing its link to the source. Marine-FL used a marine database to construct and grow fragments as a computational proof of concept [14]. Its generated candidates are best described as marine-inspired. A natural-product claim needs a traceable lineage and experimental support. This distinction is not semantic. Access obligations, ecological claims, and supply strategies differ between a recovered natural product and a new synthetic design.
Mass-spectrometry networking can strengthen traceability when paired with isolation. Feature-based molecular networking links chromatographic features, MS/MS similarity, relative abundance, and sample metadata. Annotation confidence nevertheless varies from an exact reference-spectrum match to a class-level inference. A network node is not an isolated compound. The highest-value workflow connects the computational or spectral nomination to a purified material, orthogonal structural evidence, a quantified yield, and a registered sample or spectrum.
Analytical artifacts are another source of false novelty. Reactive solvents, media components, and work-up conditions can create compounds that were not present in the living system. A recent Marine Drugs review showed how artifacts can still have value when their origin is recognized and tested [15]. The lesson is simple. Structure, batch history, and formation pathway must stay linked.
3.3. Dataset bias and Validation Design
Public molecular-machine-learning benchmarks such as MoleculeNet improved comparability across tasks [16]. Yet random train-test splitting can place close analogues in both sets, inflating performance. Scaffold-aware and temporal partitions better approximate the intended use on new chemistry, although they often yield lower scores. Learned molecular representations also vary substantially with architecture, pretraining, data scale, and endpoint [17]. For a marine application, reporting should include deduplication rules, stereochemical handling, split logic, similarity between training and test compounds, endpoint provenance, missing-data treatment, class balance, calibration, uncertainty, and the applicability domain.
Negative data are a special problem. Natural-product reports disproportionately contain active compounds, while inactive fractions and failed re-isolations remain unpublished. A model trained on such data may learn reporting practices rather than biological causality. External validation should use an independently generated set rather than a random holdout from the same curation pipeline. Prospective validation is stronger still: the model is frozen, compounds are nominated, and experiments are performed after nomination. Without a timestamped sequence, a computational analysis conducted on an already known active molecule is assessment or rationalization, not computation-enabled discovery.
4. Computational Prioritization: Capabilities and Failure Modes
4.1. Machine Learning, Structure-Based Computation, and Experimental Structure
Machine learning and conventional computational chemistry should not be conflated. QSAR may use conventional statistical models or machine-learning methods; learned molecular representations, graph neural networks, deep classifiers, learned scoring functions, and generative models are examples of explicitly data-driven approaches. Graph architectures operate on atoms and bonds, but their performance still depends on task-relevant data and validation [18]. Conventional docking, MD, and approximate binding free-energy calculations do not by themselves make a study ‘AI-enabled’. Experimental structures from X-ray crystallography, NMR, or cryogenic electron microscopy provide a different evidence class. AlphaFold and related systems expand access to protein models [19], but local binding-site uncertainty must be evaluated rather than assumed equivalent to a well-resolved experimental structure.
The distinction matters for both claims and decisions. A machine-learning classifier can rank a database without specifying a binding pose. Docking can propose a pose without learning from task-specific examples. MD can test the stability of a starting complex but does not rescue an incorrect pose or prove binding. A property-prediction portal can support triage but does not supply measured absorption, distribution, metabolism, excretion, or toxicity. ADMETlab 3.0 illustrates the speed and breadth of current prediction tools [20]; its outputs remain predictions whose relevance depends on the chemical domain and endpoint.
4.2. Docking and Molecular-Dynamics Quality Control
Docking is widely used for inexpensive, scalable prioritization, but its outputs require careful interpretation. Scores are method-dependent estimates rather than measured binding free energies, and small differences need not imply meaningful affinity differences. Benchmarking has exposed limitations in affinity ranking across diverse systems [21]. Receptor state, missing residues, cofactors, protonation, tautomers, waters, ligand stereochemistry, and search-region definition should be reported. Validation should include known ligands and, where suitable, relevant inactive compounds or decoys.
Redocking assesses whether a protocol can reproduce a known pose; it does not validate affinity ranking or establish biological activity. A pose RMSD around 2 Å is a commonly used reference point, not a universal pass-fail threshold. PoseBusters further shows why geometric and chemical plausibility must be checked independently of a favorable score [22]. Contact diagrams alone are insufficient to validate a binding-mode claim.
MD can examine the behavior of a proposed complex under a specified model, but a stable backbone RMSD or persistent contact does not prove binding, selectivity, or efficacy. Reports should specify force fields, ligand parameterization, protonation, solvent and ions, equilibration, production length, replicate trajectories, and convergence checks. MM/PBSA and MM/GBSA estimates can support comparisons within suitable series but remain sensitive to initial poses, sampling, dielectric assumptions, and entropy treatment; they should not be presented as measured affinities.
4.3. Prospective Machine Learning and Causal Contribution
A prospective claim requires more than a favorable retrospective ranking. Outside the marine field, a deep-learning model nominated halicin before experimental testing [23]. This illustrates the importance of freezing the model and candidate universe, recording nominations before results are available, using a meaningful comparator, and reporting unsuccessful as well as successful selections. It does not establish that the same performance will transfer to marine chemical space.
Computational analyses of known marine metabolites can generate useful hypotheses without constituting computational discovery. A deep-learning and docking workflow screened CMNPD for HIF-1α pathway activators but did not report prospective wet-laboratory validation of its nominations [24]. A virtual-screening study of chloroethylagelastatin A investigated a ribosomal mechanism after therapeutic activity was known [25]. The relevant distinction is the decision changed by computation and its timing, not whether computational methods appear in the study.
Label quality is equally important. Rabelo and colleagues used LightGBM to classify natural products using spectral descriptors, reporting a test-set AUC of 0.851 [26]. The large modeled dataset used activity classes derived from docking-based estimates rather than measured IC50 values. In the smaller comparison set of 172 compounds, docking scores correlated weakly with experimental pIC50 (R = 0.32). These findings illustrate prediction of a computational proxy, not direct experimental confirmation of PD-L1 inhibition by the nominated compounds; the classification result alone does not support E2.
Leakage control also needs more than a random split. DataSAIL showed how similarity across training and test partitions can inflate biomedical machine-learning performance [27]. Recent out-of-distribution evaluations reached the same broad conclusion. Strong in-distribution scores do not ensure robust performance on new chemical space [28]. Marine studies should report the nearest training analogues for each nominated compound. Scaffold, cluster, and temporal sensitivity analyses are preferable when the data permit them.
4.4. Recent Marine Examples and What They Establish

Table 2.
Recent 2025-2026 computational and marine-natural-product examples, with claim-limiting features.
Table 2.
Recent 2025-2026 computational and marine-natural-product examples, with claim-limiting features.
| Study | Computational role | Physical test article | Wet-lab status | Main limitation | Framework lesson |
|---|---|---|---|---|---|
| [10] | Deep learning for host-microbe misannotation | Database structures | No therapeutic test required | Predicted provenance is not demonstrated biosynthesis | Keep provenance confidence outside S |
| [14] | Fragment construction and growth | Generated designs | Computational proof of concept | Marine origin can be severed during generation | Call outputs marine-inspired unless lineage is traceable |
| [26] | LightGBM classification | Natural-product structures | No direct confirmation of ranked records | Large labels were docking-derived; seed experimental/docking correlation was weak | A model can learn a proxy rather than biology |
| [29] | Machine learning, docking, and MD | Isolated sea-star steroid | SARS-CoV-2 in vitro test | Computational chronology and final production fields are incomplete | C-NR / E2 / S1; reconcile reported IC50 values |
| [30] | Docking and cell testing; chronology not established | Reported purified cynthichlorine; final assay-batch specification requires clarification | Five cancer cell lines | Final isolated mass, quantitative purity, and chronology are unclear | Provisional C-NR / E2 / S1; withhold coordinate if batch identity cannot be reconciled |
| [31] | Network pharmacology and enrichment | Gukulenin A plus olaparib | Ovarian-cancer cell tests | Result-to-computation chronology is not sufficiently established for C3 | C-NR / E2; production updated to S2 by later synthesis [32] |
| [27] | Similarity-aware data splitting | Benchmark datasets | Method validation | Random splits can leak related entities | Report split logic and nearest analogues |
| [28] | Out-of-distribution evaluation | Benchmark datasets | Method validation | In-domain scores can fail on new chemistry | Report applicability domain and OOD tests |
Notes: Rows describe method use and reporting limits. They do not rank study quality. C, E, and S assignments are made only where the exact material and chronology permit them.
The selected 2025-2026 reports illustrate heterogeneous computational roles and limits on interpretation [29,30]. Their evidence cannot be used to estimate the proportion of studies reaching E1, E2, or prospective experimental validation. Instead, they show why therapeutic testing, computational chronology, and production reporting must be inspected separately. Incomplete reporting limits classification; it does not by itself demonstrate that computation has failed or that an unreported production route does not exist.
4.5. A minimum Reporting Standard for Computational Prioritization
A decision-grade report should define the candidate universe and access date, structure-standardization rules, stereochemical treatment, target provenance, and binding-site quality. It should identify the model version, training data, split assignments, applicability domain, uncertainty, calibration, and relevant baselines. A dated record must establish whether each contribution preceded or followed the result it is claimed to influence. Complete nomination lists, including failures, should connect database entries to physical samples, spectra, and assay batches; docking and simulation parameters must be reproducible.
4.6. Target Validity, Endpoint Quality, and Multi-Objective Selection
Computational sophistication cannot rescue a weak therapeutic question. Target selection should separate disease causality, pathway association, tractability, and assayability. A model may rank ligands for a protein that is not causal. The protein may also be redundant or inaccessible in the relevant tissue. Disease subtypes can use it differently. The acanthomanzamine case shows this problem. Viral-entry biology changed the relevance of the proposed host-protease target.
Endpoint quality sets a ceiling on model quality. Incompatible assays should not be merged into one activity label without justification. Species, cell lines, exposure times, and censoring matter. Continuous endpoints should keep units and assay context. Classification thresholds need a biological or decision rationale. Proxy labels must be named as proxies. They do not support claims of clinical efficacy.
Prospective selection is usually multi-objective. Potency can conflict with selectivity, solubility, stability, or route feasibility. Ecological burden may also change the decision. A transparent Pareto set is often more useful than one rank. Uncertainty should affect action. A high but uncertain prediction may be selected to gain information. A moderate and well-supported candidate may be selected for efficient confirmation. Active learning can help. It requires rapid assays and the return of both positive and negative results.
The baseline must match the claim. Database triage should be compared with random selection, similarity search, established docking, or expert prioritization under the same testing budget. Enrichment calculated after exclusions is not a prospective success rate. Generative designs need more than validity and novelty. They need a route review, synthesis, identity confirmation, and experimental comparison with source scaffolds.
5. A Two-Axis Evaluation-and-Production Framework
5.1. Design Principles
The framework separates biological evaluation, demonstrated production capability, computational contribution, and adequacy for a defined supply scenario. E and S are independent ordinal descriptors and are not summed, averaged, weighted, or converted into a readiness score. Their coordinate is descriptive rather than promotional. Evidence direction, study quality, effect size, replication, safety, provenance, and uncertainty remain necessary accompanying attributes.
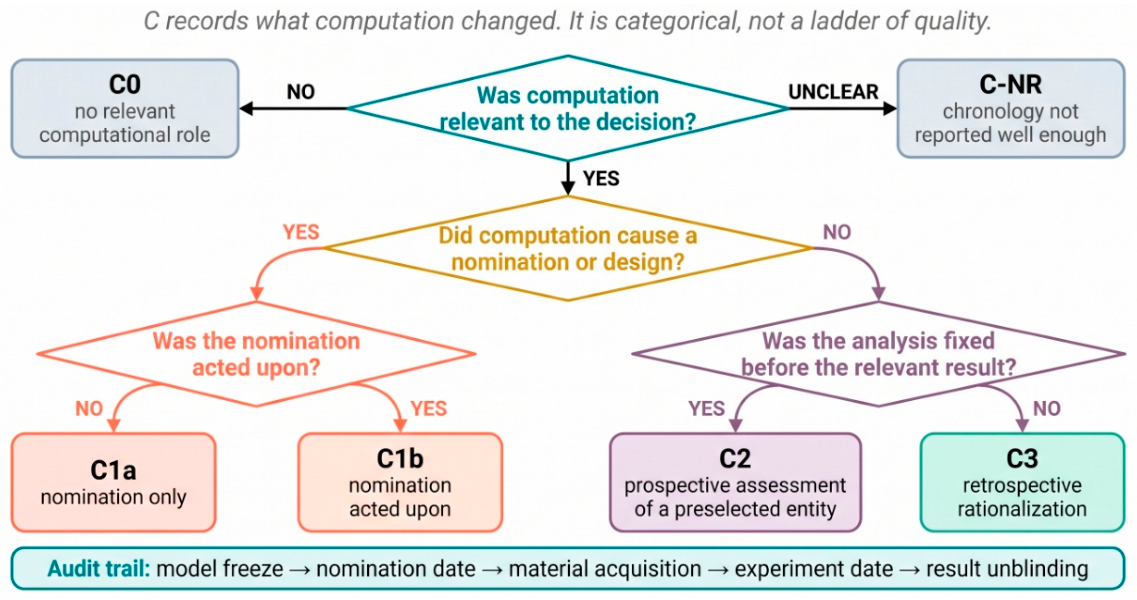
E and S may change independently. A compound can reach an animal model while still depending on a limited isolation, whereas a well-characterized laboratory synthesis may precede therapeutic evaluation. Figure 1 presents the linked-record concept, Figure 2 defines computational contribution by chronology, and Figure 3 maps the illustrative cases. A change on one axis does not imply a change on the other.
5.2. Operational Definitions
Table 3.
Operational definitions for therapeutic-evaluation stage (E), production readiness (S), and computational contribution (C).
Table 3.
Operational definitions for therapeutic-evaluation stage (E), production readiness (S), and computational contribution (C).
| Field | Code | Label | Operational rule |
|---|---|---|---|
| Therapeutic-evaluation stage | E1 | In silico | Only computational evaluation is documented for the exact entity-indication pair in the reviewed sources. |
| E2 | In vitro | Controlled in vitro test of the exact entity for the stated indication-relevant hypothesis. | |
| E3 | Animal | Test of the exact entity in a relevant animal model for the same indication. | |
| E4 | Human | Documented interventional administration to human participants for the same indication. Registration alone is insufficient. | |
| Production readiness | S1 | Discovery access | Exact entity was physically obtained. The record does not meet every S2 requirement. |
| S2 | Laboratory route | Executed laboratory route reporting starting material, key conditions, isolated output or yield, identity, and purity or analytical fitness. Does not establish scale-up or scenario-specific adequacy. | |
| S3 | Pilot / scale-up | Executed pilot or scale-up route. Repeat batches and relevant process controls are documented. | |
| S4 | GMP / commercial | Applicable GMP manufacture or established commercial production is documented. | |
| NR | Not classifiable | Available evidence cannot support S1-S4. | |
| Computational contribution | C0 | No relevant role | Computation did not affect the decision under review. |
| C1a | Nomination only | A frozen computation caused a nomination, but the nomination was not acted upon experimentally. | |
| C1b | Action caused | A frozen computation caused isolation, purchase, synthesis, design, or testing. | |
| C2 | Prospective assessment | Computation assessed a preselected entity before its relevant result was known. | |
| C3 | Retrospective rationale | Computation interpreted a relevant result after it was known. | |
| C-NR | Chronology unclear | Reporting is insufficient to assign the computational contribution. |
Notes: E and S are independent ordinal descriptors and are never summed or averaged. E records the highest stage documented in the reviewed sources, not evidence strength. C is categorical and non-ordinal. Therapeutic status is not inherited between different test articles or indications. A verified production route may support multiple indication-specific records only when chemical identity and relevant quality specifications match.
E records the highest therapeutic-evaluation stage documented for the exact entity-indication pair in the reviewed sources: E1, computational evaluation only; E2, controlled in vitro testing; E3, testing in a relevant animal model; and E4, documented interventional administration to human participants. Trial registration alone is insufficient for E4. For E2-E4, the model, exposure, outcome, and controls must be interpretable. Negative or mixed results can establish a stage; higher E therefore does not imply stronger evidence, favorable efficacy, or regulatory approval.
S1 indicates physical access to the exact entity without sufficient reporting to satisfy S2. S2 requires an executed laboratory route with starting material, key conditions, isolated output or yield, analytical identity, and purity or analytical fitness appropriate to the experiment. It does not establish independent reproducibility, pilot manufacture, or adequate supply for a new scenario. S3 requires executed pilot or scale-up production with repeat batches and relevant process controls. S4 requires documented applicable GMP manufacture or established commercial production. NR is reserved for evidence insufficient even to establish S1; scarcity alone is not NR.
C describes a particular computational contribution, not a permanent molecular property. C0 denotes no relevant computational role in the specified decision. C1a denotes a computational nomination not yet acted upon, and C1b denotes a nomination that led to isolation, purchase, synthesis, design, or testing. C2 is prospective assessment of an independently preselected entity; C3 is interpretation after the relevant result was known. C-NR is used when reporting does not establish that chronology. These categories are non-ordinal. ‘AI-enabled’ should be reserved for genuine AI or machine-learning methods; docking and MD alone do not justify that designation.
Figure 2.
Chronology-based assignment of computational contribution. C records what computation changed and is categorical, not ordinal. A dated audit trail distinguishes nomination-only work (C1a), nominations acted upon (C1b), prospective assessment of a preselected entity (C2), retrospective rationalization (C3), no relevant computational role (C0), and insufficiently reported chronology (C-NR).
Figure 2.
Chronology-based assignment of computational contribution. C records what computation changed and is categorical, not ordinal. A dated audit trail distinguishes nomination-only work (C1a), nominations acted upon (C1b), prospective assessment of a preselected entity (C2), retrospective rationalization (C3), no relevant computational role (C0), and insufficiently reported chronology (C-NR).
5.3. Evidence Direction, Provenance, and Scenario-Specific Supply
Evidence direction is supportive, mixed, negative, or not efficacy-evaluable. “Supportive” does not mean replicated or clinically meaningful. Study quality is also separate. Provenance records the collection host and the level of confidence in the true producer. This keeps biological origin out of the S scale.
Supply adequacy is not an intrinsic label. It depends on the route, required mass, time, quality, and risk tolerance. Two scenarios should be recorded. The first is the next development stage. The second is projected therapeutic use. Each is labeled adequate, inadequate, uncertain, not assessable, or not applicable. Assumptions must be stated. The approximate requirement is:
Required mass = (per-unit requirement × number of units × administrations × overage factor) / usable-product fraction.
For an in vitro program, the per-unit amount can be concentration multiplied by assay volume, with units accounting for wells, repeats, confirmatory assays, and controls. For an animal study, it can be dose per kilogram multiplied by body mass. Overage should cover additional sampling and contingency requirements not already represented elsewhere. The usable-product fraction should account for specified material losses between the chosen starting quantity and administered material. The same purification, release, or formulation loss must not be counted in both factors.
One hypothetical next-stage example shows how to apply the equation. Assume a 10 mg/kg dose in 25 g mice. Ten animals receive ten administrations. Use a 1.20 overage factor and a usable-product fraction of 0.85. The required drug-substance mass is 35.3 mg. This is a planning example, not a recommendation for any case in this Review. The example is useful because it converts “enough material” into a testable quantity. The result should then be compared with an executed route and its batch quality.
6. Contrasting Case Lineages
6.1. Halichondrin B and Eribulin: Lineage Without Status Inheritance
Halichondrin B is a complex polyether macrolide. It was associated with the sponge Halichondria okadai. Early work reported activity in murine P388 leukemia and B16 melanoma models [33]. The true producer remains unresolved. “Sponge-associated” is therefore the safer term. A landmark total synthesis established chemical access [34]. It did not make the parent a practical commercial product.
Historical scarcity makes the scale mismatch clear. An official NIH technology-transfer account describes the discovery and development lineage [35]. A supply review reports about 300 mg from one metric ton of sponge [7]. That nominal recovery is 0.3 mg/kg. At that rate, 10 g would require about 33,300 kg of wet sponge. This simple calculation excludes batch variation, purification loss, retention samples, and ecological limits. It is not a patient-dose forecast. It shows why discovery access does not equal development adequacy.
For halichondrin B in the murine P388 leukemia model, the reviewed animal evidence supports E3 and the executed total synthesis supports S2 [33,34]. These sources do not establish pilot or commercial manufacture of the parent. C0 refers to the original nomination considered here, and evidence direction is supportive in that model. Historical wild-harvest limitations motivated alternative supply and derivative strategies; eribulin’s later status is recorded separately.
Eribulin mesylate is a synthetic analogue, not a manufactured batch of halichondrin B. In EMBRACE, eribulin improved overall survival relative to treatment of physician’s choice in heavily pretreated locally recurrent or metastatic breast cancer [36]. The US prescribing information lists metastatic breast cancer and unresectable or metastatic liposarcoma, each subject to specified prior-treatment conditions [37]. A manufacturing account documents commercial process chemistry [38]. These distinct sources support clinical evaluation, labeled use, and production, respectively.
For metastatic breast cancer, eribulin is classified E4/S4, with supportive human evidence and C0 for the original nomination considered here. Commercial manufacture establishes an available therapeutic supply route, but it does not demonstrate adequacy for every quantity, deadline, location, or interruption scenario. Post-approval safety, process control, stability, and supply continuity remain relevant. The halichondrin B-eribulin relationship shown in Figure 3 is chemical lineage, not inheritance of E4 or S4 status.
6.2. (+)-Aeroplysinin-1: Computation Connected to Targeted Isolation
Lever and colleagues linked virtual screening to targeted isolation [39]. They screened 633 Verongiida compounds against 19 MRSA targets and combined docking with network analysis; GNPS feature-based molecular networking then helped target chemistry in Pseudoceratina durissima. This reported connection between prioritization and experimental action supports C1b. Because the relevant methods were docking and molecular networking, ‘computation-enabled’ is more precise than ‘AI-enabled’.
The study processed 179.8 g wet sponge material (27 g dry material) and reported approximately 7.2 mg of (+)-aeroplysinin-1 across isolated fractions. Spectroscopic identification and reported purity above 95% by proton NMR support interpretation of the test material. The reported anti-MRSA minimum inhibitory concentration was 32 μg/mL under the study’s inhibition criterion, not below 32 μg/mL [39]. These data support E2 and a quantified laboratory isolation meeting S2, without establishing scale-up.
The result goes beyond an untested docking nomination but does not establish animal efficacy or a scalable process. Evidence direction is supportive in vitro. Both supply scenarios remain not assessable without a defined demand, timing, and quality requirement. Further development would require orthogonal antibacterial confirmation, selectivity and resistance studies, relevant exposure, animal evaluation, and a replenishable production route.
6.3. 5α-Cholesta-9(11)-en-3β,20β-diol from Acanthaster Planci
A 2025 study examined 5α-cholesta-9(11)-en-3β,20β-diol from Acanthaster planci using isolation, antiviral assays, and computational analyses. It reported approximately 85% inhibition at 5 ng/μL and an IC50 of 5.86 μM. Elsewhere, its fitted value of 2.23 ng/μL corresponds to approximately 5.54 μM using the stated molecular mass. This internal numerical discrepancy should be retained as a source limitation rather than silently resolved by selecting one estimate.
The antiviral assay supports E2 with a supportive in vitro direction, but not established animal exposure or a confirmed molecular mechanism. The reported main-protease redocking RMSD of 3.10 Å exceeded the study’s stated 2 Å criterion. This weakens the pose-based interpretation without negating the separate antiviral assay; whole-virus inhibition and direct main-protease engagement are different endpoints.
The report does not establish whether machine learning caused isolation or testing, so computational contribution is C-NR. Extraction and structural characterization establish physical access. However, the reviewed reporting does not clearly establish the final isolated output and quantitative purity needed for a defensible S2 assignment; S1 is retained pending clarification [29]. Missing production information is not evidence that a laboratory route cannot be developed.
Next-stage and therapeutic supply are not assessable. Harvesting A. planci may appear attractive where population control occurs. That does not establish a production route. Availability, variability, ecology, governance, and the true producer remain unresolved. The next gates are independent replication, target engagement, selectivity, exposure, quantified re-isolation, and route development.
6.4. Acanthomanzamine C: Target Biology and Validation Lag Behind Ranking
Acanthomanzamine C was isolated from Acanthostrongylophora ingens [40]. A 2023 study screened 137 Indonesian marine-invertebrate-associated compounds [41]. It used docking, predicted ADMET properties, and 100 ns MD simulations. The targets were TMPRSS2 and the Omicron spike protein. Acanthomanzamine C was prioritized. The record is C1a because the nomination was not acted upon experimentally. The methods were not demonstrably AI-enabled.
No antiviral wet-laboratory test was reported. The level is E1. Direction is not efficacy-evaluable. Docking contacts and stable trajectories do not prove entry inhibition. Biological context also matters. Omicron BA.1 used TMPRSS2 less efficiently than earlier variants [42]. Variant dependence and airway-cell context should be resolved before further development.
Original isolation establishes access to acanthomanzamine C [40], while the antiviral nomination is supported by the later computational study [41]. These sources support S1 and E1 for the specified antiviral hypothesis, respectively; they do not establish a replenishable route or antiviral efficacy. Both supply scenarios remain not assessable. The next informative step is controlled testing of the exact compound in a relevant entry or antiviral assay, with cytotoxicity controls, appropriate variants and cell types, and a parallel assessment of quantified material access.
6.5. Cynthichlorine: Extraction Evidence Does Not Settle Computational Chronology
A 2025 study investigated cynthichlorine from the ascidian Cynthia savignyi, comparing maceration and Soxhlet extraction, reporting chromatographic purification and spectroscopic characterization, and testing five cancer cell lines [30]. U87-MG cells had the lowest reported IC50. Docking explored possible targets, including NM23-H2. The extraction and purification claims should be reported as such rather than treating the study as testing only an unspecified crude extract.
The reported U87-MG result supports an E2 anticancer record, provisionally linked to the named test article, with a supportive in vitro direction. It does not establish target engagement or animal efficacy. Although extraction yields and purification are described, the reviewed report does not clearly resolve the mass and quantitative purity of the final bioassayed preparation. S1 is therefore retained conservatively pending analytical clarification. If identity cannot be linked across the biological and production preparations, the joint coordinate must instead be withheld.
Section order does not establish when computation occurred relative to the relevant biological result. In the absence of an auditable chronology, C-NR is preferable to C2 or C3. The next gate is an identity-controlled repeat with quantitative purity, non-malignant controls, target-engagement experiments, and a defined mass requirement.
6.6. Gukulenin A: Separating Combination Evidence from Production Updates
Gukulenin A is a sponge-associated bis-tropolone tetraterpenoid. A 2025 Marine Drugs study tested it with olaparib in ovarian-cancer cells [31]. Mildly cytotoxic gukulenin A sensitized cells to the PARP inhibitor. The study linked the effect to ferroptosis, lipid peroxidation, and oxidative-stress pathways. Network pharmacology and enrichment analyses were used to support the mechanistic interpretation.
The combination study supports E2 for the gukulenin A-olaparib sensitization hypothesis, with a supportive in vitro direction [31]. Network analysis contributes mechanistic hypotheses but does not demonstrate that computation caused compound selection. Because a retrospective C3 assignment requires evidence that the relevant result was already known, C-NR is retained unless that chronology can be confirmed. Single-agent animal evidence is not transferred to the combination record.
Production classification must incorporate later route evidence, not only the combination paper. Gupta and colleagues reported an enantioselective total synthesis of (−)-gukulenin A in 2025, with 24 steps and 2.5% overall yield from commercial reagents [32]. This supports an update from discovery access to a documented laboratory route (S2), not pilot manufacture or guaranteed supply. Biological E2 status for olaparib sensitization remains separate. Both supply scenarios require defined demand, quality, timing, and route-output assumptions before adequacy can be assessed.
6.7. Meridianins: Why Mixtures Cannot Lend Maturity to Individual Compounds
Meridianins are indole alkaloids associated with the tunicate Aplidium meridianum. A 2020 study combined computational analyses of individual meridianins with biological testing of mixtures in work on glycogen synthase kinase 3β and neuronal structural plasticity [43]. A subsequent study administered a meridianin mixture intracerebroventricularly in the 5xFAD Alzheimer disease mouse model and reported beneficial cognitive and neuropathological outcomes, alongside impaired spontaneous alternation in wild-type animals [44]. Those experiments concern mixtures, not evidence automatically attributable to every modeled congener.
An animal experiment with a mixture does not establish E3 for each constituent. Linking the earlier in vitro mixture to the later administered mixture also requires adequate composition and batch specifications. Because the reviewed evidence does not establish that comparability confidently, the animal experiment is described but a joint E×S coordinate is withheld. Direction is mixed because disease-model benefits coexist with a wild-type behavioral concern. Computational contribution remains C-NR for the unmatched entity-specific record.
The next gate is chemical before it is computational: define and reproduce the administered mixture or test isolated congeners individually and in specified combinations. Subsequent studies should compare systemic and central routes, establish exposure, include wild-type safety endpoints, and connect kinase engagement to the behavioral phenotype. This vignette is deliberately placed outside the matrix in Figure 3. Withholding a coordinate is more informative than creating precision from incompatible materials.
6.8. Cross-Case Synthesis
Table 4.
Cross-case evidence, production stage, and computational contribution.
| Entity-indication | Exact evaluated material | C | E | S | Direction | Primary basis |
|---|---|---|---|---|---|---|
| Halichondrin B—P388 leukemia | Defined parent natural product | C0 | E3 | S2 | Supportive | Murine activity; executed total synthesis [33,34] |
| Eribulin—metastatic breast cancer | Eribulin mesylate | C0 | E4 | S4 | Supportive | Phase 3 trial; label; commercial manufacture [36,37,38] |
| (+)-Aeroplysinin-1—MRSA | Purified (+)-aeroplysinin-1 | C1b | E2 | S2 | Supportive | Prospective virtual screen, targeted isolation, in vitro test [39] |
| Sea-star steroid—SARS-CoV-2 | 5α-Cholesta-9(11)-en-3β,20β-diol | C-NR | E2 | S1 | Supportive | Isolated compound and antiviral assay [29] |
| Acanthomanzamine C—SARS-CoV-2 | Named isolated congener | C1a | E1 | S1 | Not efficacy-evaluable | Isolation [40]; subsequent antiviral computational nomination [41] |
| Cynthichlorine—U87-MG cell growth inhibition | Reported cynthichlorine; assay-batch identity/purity linkage requires confirmation | C-NR | E2* | S1 | Supportive | Cell testing and reported purification [30]; coordinate conditional on identity linkage |
| Gukulenin A—olaparib sensitization | Gukulenin A plus olaparib | C-NR | E2 | S2 | Supportive | Combination cell testing [31]; later total synthesis [32] |
| Meridianin mixture—Alzheimer model | Composition/batch link insufficient | C-NR | — | — | Mixed | Mixture-based in vitro and animal records not confidently batch-matched [43,44] |
Notes: Each row is an exact entity-indication record. The highest E stage documented in the reviewed sources is reported even when evidence is negative or mixed. A withheld coordinate is not a low score; it signals failure of the identity threshold. For halichondrin B and eribulin, C0 refers only to the original nomination and development pathway; it is not a permanent property of the lineage. * Provisional cynthichlorine identity linkage; —, coordinate withheld.
Table 5.
Cross-case provenance, route/time basis, scenario-specific supply adequacy, and next decision gate.
Table 5.
Cross-case provenance, route/time basis, scenario-specific supply adequacy, and next decision gate.
| Entity-indication | Next-stage supply | Therapeutic supply | Provenance | Route/time basis and main gap | Key next gate |
|---|---|---|---|---|---|
| Halichondrin B—P388 leukemia | Not defined for this historical comparison | Historically inadequate—wild harvest | Sponge-associated; producer unresolved | Historical wild isolation; laboratory synthesis documented, but pilot/commercial output not established in the reviewed sources | Keep parent and derivative status separate |
| Eribulin—metastatic breast cancer | Not applicable—licensed indication | Commercial route established; adequacy is scenario-dependent | Fully synthetic analogue | Commercial synthesis documented; no demand/location/time-specific adequacy assessment | Post-approval safety and process control |
| (+)-Aeroplysinin-1—MRSA | Not assessable | Not assessable | Sponge-associated; producer unresolved | 2022 laboratory isolation; no defined demand or scalable route | Orthogonal tests, animal exposure, replenishable route |
| Sea-star steroid—SARS-CoV-2 | Not assessable | Not assessable | Sea-star-associated; producer unresolved | 2025 discovery isolation; chronology, yield, and purity incomplete | Replicate assay; quantify route; test engagement |
| Acanthomanzamine C—SARS-CoV-2 | Not assessable | Not assessable | Sponge-associated; producer unresolved | 2014 discovery isolation; no antiviral test or replenishment data | Variant-relevant assay and quantified access |
| Cynthichlorine—U87-MG cell growth inhibition | Not assessable | Not assessable | Ascidian-associated; producer unresolved | 2025 extraction and purification report; final assay-batch mass, purity, and chronology need reconciliation | Identity-controlled repeat and target engagement |
| Gukulenin A—olaparib sensitization | Not assessable | Not assessable | Sponge-associated; producer unresolved | Laboratory total synthesis reported in 2025; scale-up, repeat-batch supply, and defined demand remain unestablished | Confirm synergy, exposure, safety, and scenario-specific route output |
| Meridianin mixture—Alzheimer model | Not assessable | Not assessable | Tunicate-associated mixture | Reviewed 2020/2022 mixture records do not establish batch comparability sufficiently for a joint coordinate | Specify mixture or test congeners |
Notes: Supply adequacy is scenario-specific. “Not assessable” means that demand, route output, quality, or time assumptions are missing. It must not be converted to adequate or inadequate without new evidence.
Figure 3.
Illustrative entity-indication records on independent therapeutic-evaluation (E) and production (S) axes. Each cell denotes a category, not a continuous score; C labels describe non-ordinal computational contributions. Halichondrin B and eribulin are linked chemically but do not share status. Gukulenin A is shown at E2/S2 for the combination hypothesis and later documented laboratory synthesis. The cynthichlorine coordinate is provisional pending test-article reconciliation. The meridianin mixture is shown separately because the reviewed batch information does not support a joint coordinate. Case selection is purposive and does not estimate prevalence.
Figure 3.
Illustrative entity-indication records on independent therapeutic-evaluation (E) and production (S) axes. Each cell denotes a category, not a continuous score; C labels describe non-ordinal computational contributions. Halichondrin B and eribulin are linked chemically but do not share status. Gukulenin A is shown at E2/S2 for the combination hypothesis and later documented laboratory synthesis. The cynthichlorine coordinate is provisional pending test-article reconciliation. The meridianin mixture is shown separately because the reviewed batch information does not support a joint coordinate. Case selection is purposive and does not estimate prevalence.
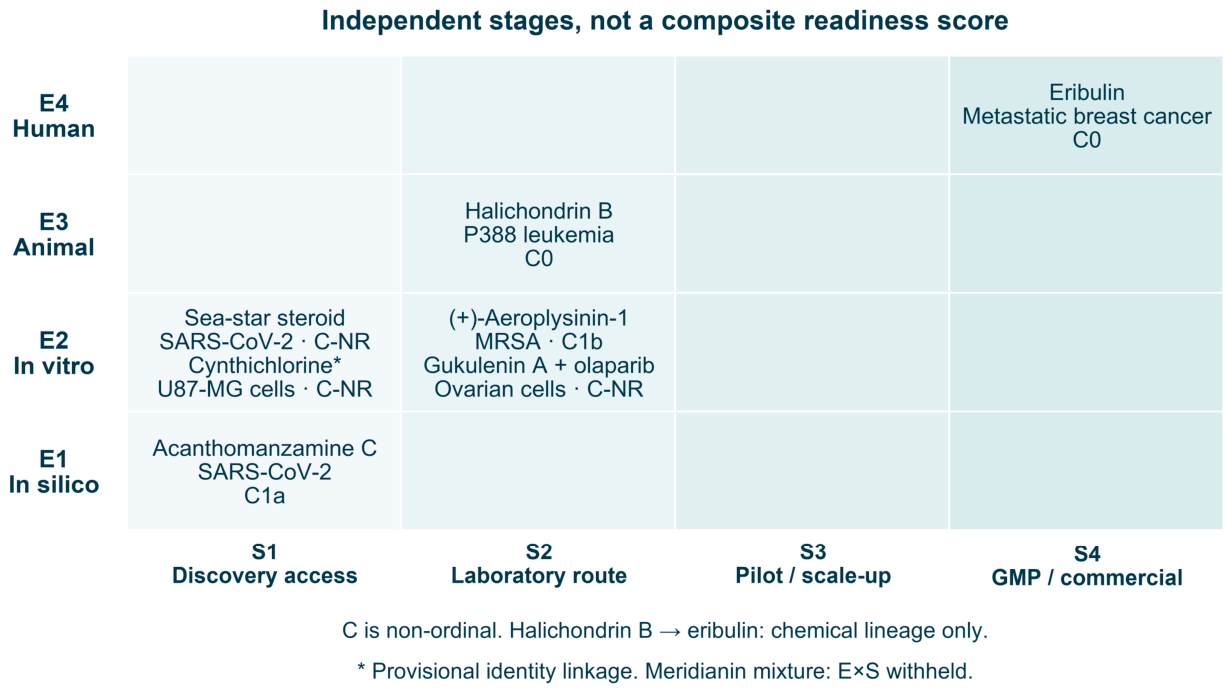
The illustrative cases expose different bottlenecks rather than establish their prevalence. Eribulin occupies the high-E/high-S region and demonstrates the contribution of medicinal and process chemistry within one lineage. This does not show that derivatives generally outperform their natural-product parents. The parent-analogue distinction remains essential to interpreting both biological evidence and supply.
(+)-Aeroplysinin-1 connects computational prioritization to isolation and testing (C1b/E2/S2), whereas acanthomanzamine C remains a computational antiviral nomination (C1a/E1/S1). The gukulenin A case illustrates how a new synthesis can update S without advancing the combination-specific E stage. For the sea-star steroid and cynthichlorine, chronology and analytical reporting constrain interpretation. Meridianin mixtures illustrate why an animal experiment alone cannot resolve an identity mismatch. These differences cannot be represented faithfully by one maturity ranking.
7. Supply-by-Design and Development Gates
7.1. Production Strategies Should Follow the Molecule and Producer
No production route is universally superior. Total synthesis can provide identity control and analogue access, but step count, stereochemical complexity, convergence, hazardous reagents, purification, and overall yield constrain practicality. Semisynthesis is useful when an accessible precursor is available; trabectedin is an instructive example [8]. Fermentation depends on a producer that grows and expresses the pathway under controlled conditions. Heterologous expression may overcome cultivation limits, but biosynthetic-cluster complexity, precursor supply, enzyme maturation, toxicity, regulation, and host compatibility can limit output [45]. Aquaculture may reduce dependence on wild collection, although growth rate, disease, environmental footprint, metabolite variability, and permitting remain relevant [46].
Recent work has framed these options as a connected supply portfolio. The route may combine cultivation, fermentation, semisynthesis, total synthesis, and process intensification [9]. Route choice should be evidence-led. It should not be based on source prestige or novelty alone.
Route selection should start with the required material and a clearly bounded demand model. Even a potent agent may need substantial quantities for standards, impurity qualification, toxicology, stability, and formulation. Conversely, a low-output route may suffice for a narrowly defined experiment. Production maturity and supply adequacy therefore answer different questions: what capability has been demonstrated, and can that capability deliver the specified amount at the required quality and time?
7.2. Integrated Gates
At E1, the gate should require a frozen nomination, applicability-domain assessment, physical-sample traceability, and an assay and supply plan. A candidate that cannot be obtained in sufficient quality should not consume repeated modeling effort. At E2, orthogonal biological confirmation should be paired with identity, purity, stability, and a quantified route. For target-based claims, biochemical binding or engagement and a cellular mechanism should agree. At E3, exposure, formulation, tolerability, sex and model relevance, dose-response, and prespecified endpoints should be supported by a route capable of supplying repeat studies and toxicology. Before E4, good laboratory practice toxicology, chemistry-manufacturing-controls information, stability, release specifications, and clinical supply become essential. These are not rigid universal checklists, but they show how E and S gates interact.
Supply-by-design also changes computational objectives. A ranking model can include synthetic accessibility, precursor availability, fermentation potential, anticipated purification complexity, ecological burden, and provenance confidence as decision variables. Such attributes should not be collapsed into a single opaque score. Multi-objective or Pareto analysis can reveal trade-offs: a slightly less potent candidate with a robust route may be preferable to a nominally stronger compound with no replenishable source. The assumptions and weights remain decisions for the program, not facts learned automatically from sparse data.
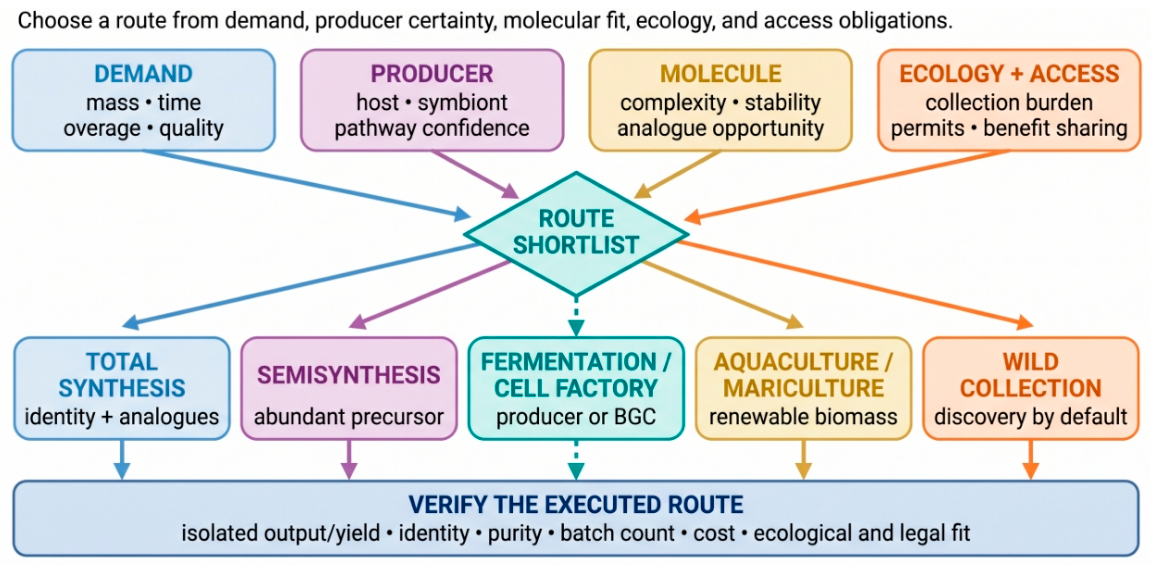
Figure 4.
Supply-by-design. Demand, producer confidence, molecular fit, ecology, and access obligations shape a route shortlist before a candidate is fixed. Route choice remains provisional until the executed route is verified for output, identity, purity, batch evidence, cost, and ecological and legal fit.
Figure 4.
Supply-by-design. Demand, producer confidence, molecular fit, ecology, and access obligations shape a route shortlist before a candidate is fixed. Route choice remains provisional until the executed route is verified for output, identity, purity, batch evidence, cost, and ecological and legal fit.
7.3. Reproducibility and Reporting Priorities
For computation, share standardized structures, model versions, code or sufficient parameters, split assignments, uncertainty, and complete nomination lists. For biology, identify the exact batch, report controls and negative results, and use orthogonal assays. For production, report starting material, route, output, yield basis, analytical identity, quantitative purity, batch count, variability, and the mass needed for the next gate. For provenance, include host voucher, collection coordinates at an appropriate level of sensitivity, permits, strain or metagenome identifiers, and confidence in the biosynthetic producer. These fields enable future reclassification without forcing authors to speculate.
7.4. How the Framework Can Be Used in Practice
The framework is intended as a compact record attached to a nomination or review, not as a substitute for disciplinary assessment. A research team can complete one row per entity-indication pair at a portfolio meeting. Reviewers can then ask whether the assigned stage follows from the cited primary evidence and whether missing supply fields change the interpretation. Funders can identify projects in which a modest process-chemistry investment would unlock decisive biology, or conversely projects in which repeated in silico work is accumulating without physical access.
Records should be versioned as evidence accumulates. New results can alter direction without changing E; a relevant animal study can support E3; and a quantified synthesis can establish S2 without changing biological status. The gukulenin A synthesis provides an example of the latter update. Improved chronology may resolve C-NR, while revised identity evidence can invalidate a previously assigned coordinate. Retaining earlier records and field-level citations makes these changes auditable.
Decision rules should be prespecified for high-stakes comparisons. For example, a program might require at least E2, a supportive orthogonal assay, S2, and adequate next-stage supply before animal advancement. Another program may deliberately accept S1 for a uniquely informative mechanistic probe while funding route development in parallel. The framework does not decide which policy is correct. It makes the exception and its consequences visible. Importantly, “not assessable” should trigger a data request or a small enabling experiment rather than being silently converted to “adequate.”
Table 6.
Stage-gate checklist for linking biological evidence to a defined supply plan.
| Decision gate | Biology | Identity and quality | Production and demand | Minimum decision record |
|---|---|---|---|---|
| E1 → E2 | Frozen hypothesis; relevant assay; controls | Exact structure or specified mixture; sample traceability | Assay mass; route to test material; overage | Timestamped nomination and planned test |
| E2 → E3 | Orthogonal confirmation; selectivity; target engagement | Batch identity; quantitative purity; stability | Executed S2 route; animal and formulation mass balance | Direction, uncertainty, exposure plan, supply adequacy |
| E3 → E4 | Dose-response; exposure; tolerability; prespecified endpoints | Release tests; impurity profile; formulation | Repeat batches; scale-up; toxicology and clinical demand | Integrated pharmacology and CMC package |
| E4 / lifecycle | Human benefit-risk; subgroup and safety follow-up | Validated release and stability controls | GMP continuity; change control; cost and resilience | Regulatory, manufacturing, and safety record |
| Identity threshold fails | Describe result only | Do not assign named constituents | Do not infer route across unmatched batches | Withhold E×S coordinate; request chemical reconciliation |
Notes: This checklist is a reporting aid. Program-specific thresholds should be prespecified. CMC, chemistry, manufacturing, and controls; GMP, good manufacturing practice.
A digital implementation could store E, S, and C as controlled terms. Narrative evidence, dates, documents, batch identifiers, and assumptions should remain attached. Automated suggestions may help populate records. Final assignments still require human verification across chemistry, pharmacology, computation, and process development. Disagreement should be preserved with reasons. Forced consensus can hide the uncertainty that the record is meant to expose.
8. Sustainability, Access, and Governance
The ethics of marine drug discovery cannot be reduced to avoiding endangered organisms. Collection can affect habitats and associated communities even when the host is locally abundant. Repeated sampling of slow-growing sponges, corals, or tunicates may be incompatible with therapeutic-scale demand. A responsible program should define collection ceilings, prefer non-destructive or cultured sources where feasible, assess population recovery, and treat wild biomass as a discovery input rather than a default manufacturing feedstock.
Legal provenance should be recorded at collection and remain traceable through data and chemical transformations. The Nagoya Protocol provides an access-and-benefit-sharing framework whose application depends on relevant national implementation and the circumstances of access [47]. The BBNJ Agreement entered into force on 17 January 2026 and addresses, among other matters, marine genetic resources of areas beyond national jurisdiction and associated digital sequence information. These instruments should not be treated as interchangeable, and their applicability requires case-specific assessment.
Computational workflows introduce governance questions of their own. Database entries can detach sequence or structure data from permits, provider communities, and original samples. Models trained on digital sequence information may generate commercial hypotheses far from the site of collection. Traceability fields should therefore persist through database export, model training, fragment generation, analogue design, and deposition. Compliance is jurisdiction- and fact-specific and requires appropriate legal expertise; a manuscript framework cannot determine obligations. It can, however, make missing provenance visible before a program becomes difficult to unwind.
9. Limitations and Validation Agenda
This critical narrative review is not systematic. Targeted discovery, metadata checks, publisher sources, and citation chaining cannot ensure exhaustive retrieval, particularly for chemistry and industrial process literature outside biomedicine. The purposively selected cases cannot estimate how often marine computational studies reach particular E, S, or C categories. Public reporting may omit confidential production data and unsuccessful experiments; older sources may lack modern analytical detail. Accordingly, each classification describes the reviewed evidence at a stated time and can change when additional sources become available.
The framework is preliminary and has not undergone formal inter-rater validation. Boundary judgments, especially S1 versus S2 and C1 versus C2, may reveal ambiguities when applied by independent users. Reliability should be tested on a larger, preregistered set by reviewers with complementary pharmacology, natural-products chemistry, process, computational, and regulatory expertise. Disagreements should be analyzed to refine definitions rather than hidden in consensus. Predictive validity could then be studied prospectively: do explicit E/S/C records and scenario-specific supply estimates improve replication, reduce failed advancement, or change nomination decisions?
The axes deliberately sacrifice some detail for interpretability. E4 combines early and late human interventional exposure, so phase, design, direction, and regulatory status must remain separate fields. S4 combines GMP and established commercial manufacture, which should be described in accompanying text. Neither axis encodes potency, therapeutic index, clinical effect size, novelty, cost of goods, market size, ecological value, or probability of success. A coordinate is not an investment recommendation.
Several supply judgments remain not assessable because demand, final output, quality, or timing is insufficiently specified in the reviewed sources. This uncertainty should prompt targeted clarification rather than an inference of either adequacy or impossibility. Provisional and withheld coordinates make identity limitations explicit. Better reporting and independent application are necessary to determine whether the framework improves decisions rather than merely reorganizes existing information.
10. Conclusions
Computational prioritization can make marine invertebrate-associated chemistry more tractable, but it does not remove the need for exact identity, prospective chronology, experimental confirmation, and reproducible supply. Machine learning, docking, MD, and molecular networking have different evidentiary roles and should be named accurately. A favorable prediction advances a candidate to a test queue; it does not establish activity, mechanism, or manufacturability.
The proposed framework records therapeutic-evaluation stage and production readiness as separate ordinal axes for each exact entity-indication pair. Computational contribution, evidence direction, provenance, and scenario-specific supply adequacy remain separate. Applied to contrasting lineages, the framework exposes problems that a “promising lead” label conceals. A parent does not inherit a derivative’s manufacturing success. A mixture does not lend evidence to named constituents. Discovery isolation does not show scalable supply. Retrospective modeling is not AI-enabled discovery.
Supply-by-design is the practical implication: nomination should connect a biological hypothesis to a defined test article, an explicit next-stage mass requirement, a plan for batch reproduction, and a traceable production route. Ecological and access considerations belong in the same decision record. Although the framework requires independent validation, separating these claims can help identify the next informative experiment and the production work required to make it possible.
Author Contributions
YL, YL, MS, BH, JW, SZH, and MZN wrote the manuscript. All authors contributed to the final version of the manuscript and approved the submitted version.
Funding
This work was supported by the Natural Science Foundation of Heilongjiang Province (Grant NO.QC2025H016), Basic Scientific Research Business Expenses of Heilongjiang Province (2025-KYYWF-ZR0869), and Science and Technology Guidance Project of the Science and Technology Bureau of Mudanjiang (HA25BR087).
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
No new data were created or analyzed in this study.
Acknowledgments
During the preparation of this work, the authors used DeepSeek to improve the language and readability of the manuscript. After using this tool, the authors reviewed and edited the content as needed and take full responsibility for the content of the published article.
Conflicts of Interest
The authors declare no competing interests.
References
- Molinski, T. F.; Dalisay, D. S.; Lievens, S. L.; Saludes, J. P. Drug development from marine natural products. Nat. Rev. Drug Discov. 2009, 8, 69–85. [Google Scholar] [CrossRef] [PubMed]
- Gerwick, W. H.; Moore, B. S. Lessons from the past and charting the future of marine natural products drug discovery and chemical biology. Chem. Biol. 2012, 19, 85–98. [Google Scholar] [CrossRef] [PubMed]
- Wilson, M. C.; Mori, T.; Ruckert, C.; Uria, A. R.; Helf, M. J.; Takada, K.; Gernert, C.; Steffens, U. A.; Heycke, N.; Schmitt, S.; Rinke, C.; Helfrich, E. J.; Brachmann, A. O.; Gurgui, C.; Wakimoto, T.; Kracht, M.; Crusemann, M.; Hentschel, U.; Abe, I.; Matsunaga, S.; Kalinowski, J.; Takeyama, H.; Piel, J. An environmental bacterial taxon with a large and distinct metabolic repertoire. Nature 2014, 506, 58–62. [Google Scholar] [CrossRef] [PubMed]
- Pereira, F.; Aires-de-Sousa, J. Computational Methodologies in the Exploration of Marine Natural Product Leads. Mar. Drugs 2018, 16, 236. [Google Scholar] [CrossRef] [PubMed]
- Sadybekov, A. V.; Katritch, V. Computational approaches streamlining drug discovery. Nature 2023, 616, 673–685. [Google Scholar] [CrossRef] [PubMed]
- Paerhati, Y.; Aikebaier, A.; Dilimulati, D.; Baishan, A.; Yusufujiang, N.; Qiu, X.; Wusiman, Y.; Zhou, W. Rethinking Nature's Pharmacy: AI Era and Natural Product Drug Discovery. Pharmaceuticals 2026, 19, 301. [Google Scholar] [CrossRef] [PubMed]
- Gomes, N. G.; Dasari, R.; Chandra, S.; Kiss, R.; Kornienko, A. Marine Invertebrate Metabolites with Anticancer Activities: Solutions to the "Supply Problem". Mar. Drugs 2016, 14, 98. [Google Scholar] [CrossRef] [PubMed]
- Cuevas, C.; Francesch, A. Development of Yondelis (Trabectedin, ET-743). A Semisynth. Process Solves Supply Probl. 2009, 26, 322–337. [Google Scholar] [CrossRef] [PubMed]
- Martinez, H.; Santos, M.; Pedraza, L.; Testera, A. M. Advanced Technologies for Large Scale Supply of Marine Drugs. Mar. Drugs 2025, 23, 69. [Google Scholar] [CrossRef] [PubMed]
- Tian, X.; Lyu, C.; Zhou, Y.; Zhang, L.; Fan, A.; Liu, Z. A Structure-Based Deep Learning Framework for Correcting Marine Natural Products' Misannotations Attributed to Host-Microbe Symbiosis. Mar. Drugs 2026, 24. [Google Scholar] [CrossRef] [PubMed]
- Lyu, C.; Chen, T.; Qiang, B.; Liu, N.; Wang, H.; Zhang, L.; Liu, Z. CMNPD: a comprehensive marine natural products database towards facilitating drug discovery from the ocean. Nucleic Acids Res. 2021, 49, D509–D515. [Google Scholar] [CrossRef] [PubMed]
- van Santen, J. A.; Jacob, G.; Singh, A. L.; Aniebok, V.; Balunas, M. J.; Bunsko, D.; Neto, F. C.; Castano-Espriu, L.; Chang, C.; Clark, T. N.; Cleary Little, J. L.; Delgadillo, D. A.; Dorrestein, P. C.; Duncan, K. R.; Egan, J. M.; Galey, M. M.; Haeckl, F. P. J.; Hua, A.; Hughes, A. H.; Iskakova, D.; Khadilkar, A.; Lee, J. H.; Lee, S.; LeGrow, N.; Liu, D. Y.; Macho, J. M.; McCaughey, C. S.; Medema, M. H.; Neupane, R. P.; O'Donnell, T. J.; Paula, J. S.; Sanchez, L. M.; Shaikh, A. F.; Soldatou, S.; Terlouw, B. R.; Tran, T. A.; Valentine, M.; van der Hooft, J. J. J.; Vo, D. A.; Wang, M.; Wilson, D.; Zink, K. E.; Linington, R. G. The Natural Products Atlas: An Open Access Knowledge Base for Microbial Natural Products Discovery. ACS Cent. Sci. 2019, 5, 1824–1833. [Google Scholar] [CrossRef] [PubMed]
- Wang, M.; Carver, J. J.; Phelan, V. V.; Sanchez, L. M.; Garg, N.; Peng, Y.; Nguyen, D. D.; Watrous, J.; Kapono, C. A.; Luzzatto-Knaan, T.; Porto, C.; Bouslimani, A.; Melnik, A. V.; Meehan, M. J.; Liu, W. T.; Crusemann, M.; Boudreau, P. D.; Esquenazi, E.; Sandoval-Calderon, M.; Kersten, R. D.; Pace, L. A.; Quinn, R. A.; Duncan, K. R.; Hsu, C. C.; Floros, D. J.; Gavilan, R. G.; Kleigrewe, K.; Northen, T.; Dutton, R. J.; Parrot, D.; Carlson, E. E.; Aigle, B.; Michelsen, C. F.; Jelsbak, L.; Sohlenkamp, C.; Pevzner, P.; Edlund, A.; McLean, J.; Piel, J.; Murphy, B. T.; Gerwick, L.; Liaw, C. C.; Yang, Y. L.; Humpf, H. U.; Maansson, M.; Keyzers, R. A.; Sims, A. C.; Johnson, A. R.; Sidebottom, A. M.; Sedio, B. E.; Klitgaard, A.; Larson, C. B.; P, C. A. B.; Torres-Mendoza, D.; Gonzalez, D. J.; Silva, D. B.; Marques, L. M.; Demarque, D. P.; Pociute, E.; O'Neill, E. C.; Briand, E.; Helfrich, E. J. N.; Granatosky, E. A.; Glukhov, E.; Ryffel, F.; Houson, H.; Mohimani, H.; Kharbush, J. J.; Zeng, Y.; Vorholt, J. A.; Kurita, K. L.; Charusanti, P.; McPhail, K. L.; Nielsen, K. F.; Vuong, L.; Elfeki, M.; Traxler, M. F.; Engene, N.; Koyama, N.; Vining, O. B.; Baric, R.; Silva, R. R.; Mascuch, S. J.; Tomasi, S.; Jenkins, S.; Macherla, V.; Hoffman, T.; Agarwal, V.; Williams, P. G.; Dai, J.; Neupane, R.; Gurr, J.; Rodriguez, A. M. C.; Lamsa, A.; Zhang, C.; Dorrestein, K.; Duggan, B. M.; Almaliti, J.; Allard, P. M.; Phapale, P.; Nothias, L. F.; Alexandrov, T.; Litaudon, M.; Wolfender, J. L.; Kyle, J. E.; Metz, T. O.; Peryea, T.; Nguyen, D. T.; VanLeer, D.; Shinn, P.; Jadhav, A.; Muller, R.; Waters, K. M.; Shi, W.; Liu, X.; Zhang, L.; Knight, R.; Jensen, P. R.; Palsson, B. O.; Pogliano, K.; Linington, R. G.; Gutierrez, M.; Lopes, N. P.; Gerwick, W. H.; Moore, B. S.; Dorrestein, P. C.; Bandeira, N. Sharing and community curation of mass spectrometry data with Global Natural Products Social Molecular Networking. Nat. Biotechnol. 2016, 34, 828–837. [Google Scholar] [CrossRef] [PubMed]
- Gomez, M. C.; Rajendran, K.; Tayo, L. L. Unlocking the potential of marine natural product fragments for rational anticancer drug design: a computational approach. Sci. Rep. 2026, 16. [Google Scholar] [CrossRef] [PubMed]
- Butler, M. S.; Capon, R. J. Extracting Value from Marine and Microbial Natural Product Artifacts and Chemical Reactivity. Mar. Drugs 2025, 24. [Google Scholar] [CrossRef] [PubMed]
- Wu, Z.; Ramsundar, B.; Feinberg, E. N.; Gomes, J.; Geniesse, C.; Pappu, A. S.; Leswing, K.; Pande, V. MoleculeNet: a benchmark for molecular machine learning. Chem. Sci. 2018, 9, 513–530. [Google Scholar] [CrossRef] [PubMed]
- Yang, K.; Swanson, K.; Jin, W.; Coley, C.; Eiden, P.; Gao, H.; Guzman-Perez, A.; Hopper, T.; Kelley, B.; Mathea, M.; Palmer, A.; Settels, V.; Jaakkola, T.; Jensen, K.; Barzilay, R. Analyzing Learned Molecular Representations for Property Prediction. J. Chem. Inf. Model 2019, 59, 3370–3388. [Google Scholar] [CrossRef] [PubMed]
- Zhang, O.; Lin, H.; Zhang, X.; Wang, X.; Wu, Z.; Ye, Q.; Zhao, W.; Wang, J.; Ying, K.; Kang, Y.; Hsieh, C. Y.; Hou, T. Graph Neural Networks in Modern AI-Aided Drug Discovery. Chem. Rev. 2025, 125, 10001–10103. [Google Scholar] [CrossRef] [PubMed]
- Jumper, J.; Evans, R.; Pritzel, A.; Green, T.; Figurnov, M.; Ronneberger, O.; Tunyasuvunakool, K.; Bates, R.; Zidek, A.; Potapenko, A.; Bridgland, A.; Meyer, C.; Kohl, S. A. A.; Ballard, A. J.; Cowie, A.; Romera-Paredes, B.; Nikolov, S.; Jain, R.; Adler, J.; Back, T.; Petersen, S.; Reiman, D.; Clancy, E.; Zielinski, M.; Steinegger, M.; Pacholska, M.; Berghammer, T.; Bodenstein, S.; Silver, D.; Vinyals, O.; Senior, A. W.; Kavukcuoglu, K.; Kohli, P.; Hassabis, D. Highly accurate protein structure prediction with AlphaFold. Nature 2021, 596, 583–589. [Google Scholar] [CrossRef] [PubMed]
- Fu, L.; Shi, S.; Yi, J.; Wang, N.; He, Y.; Wu, Z.; Peng, J.; Deng, Y.; Wang, W.; Wu, C.; Lyu, A.; Zeng, X.; Zhao, W.; Hou, T.; Cao, D. ADMETlab 3.0: an updated comprehensive online ADMET prediction platform enhanced with broader coverage, improved performance, API functionality and decision support. Nucleic Acids Res. 2024, 52, W422–W431. [Google Scholar] [CrossRef] [PubMed]
- Warren, G. L.; Andrews, C. W.; Capelli, A. M.; Clarke, B.; LaLonde, J.; Lambert, M. H.; Lindvall, M.; Nevins, N.; Semus, S. F.; Senger, S.; Tedesco, G.; Wall, I. D.; Woolven, J. M.; Peishoff, C. E.; Head, M. S. A critical assessment of docking programs and scoring functions. J. Med. Chem. 2006, 49, 5912–5931. [Google Scholar] [CrossRef] [PubMed]
- Buttenschoen, M.; Morris, G. M.; Deane, C. M. PoseBusters: AI-based docking methods fail to generate physically valid poses or generalise to novel sequences. Chem. Sci. 2024, 15, 3130–3139. [Google Scholar] [CrossRef] [PubMed]
- Stokes, J. M.; Yang, K.; Swanson, K.; Jin, W.; Cubillos-Ruiz, A.; Donghia, N. M.; MacNair, C. R.; French, S.; Carfrae, L. A.; Bloom-Ackermann, Z.; Tran, V. M.; Chiappino-Pepe, A.; Badran, A. H.; Andrews, I. W.; Chory, E. J.; Church, G. M.; Brown, E. D.; Jaakkola, T. S.; Barzilay, R.; Collins, J. J. A Deep Learning Approach to Antibiotic Discovery. Cell 2020, 180, 688–702 e13. [Google Scholar] [CrossRef] [PubMed]
- Neelakandan, A. R.; Rajanikant, G. K. A deep learning and docking simulation-based virtual screening strategy enables the rapid identification of HIF-1α pathway activators from a marine natural product database. J. Biomol. Struct. Dyn. 2024, 42, 629–651. [Google Scholar] [CrossRef] [PubMed]
- Caulfield, T. R.; Hayes, K. E.; Qiu, Y.; Coban, M.; Seok Oh, J.; Lane, A. L.; Yoshimitsu, T.; Hazlehurst, L.; Copland, J. A.; Tun, H. W. A Virtual Screening Platform Identifies Chloroethylagelastatin A as a Potential Ribosomal Inhibitor. Biomolecules 2020, 10. [Google Scholar] [CrossRef] [PubMed]
- Rabelo, H.; Tsimiante, A.; Binev, Y.; Pereira, F. A Chemoinformatics Investigation of Spectral and Quantum Chemistry Patterns for Discovering New Drug Leads from Natural Products Targeting the PD-1/PD-L1 Immune Checkpoint, with a Particular Focus on Naturally Occurring Marine Products. Mar. Drugs 2025, 23, 247. [Google Scholar] [CrossRef] [PubMed]
- Joeres, R.; Blumenthal, D. B.; Kalinina, O. V. Data splitting to avoid information leakage with DataSAIL. Nat. Commun. 2025, 16, 3337. [Google Scholar] [CrossRef] [PubMed]
- Fooladi, H.; Vu, T. N. L.; Mathea, M.; Kirchmair, J. Evaluating Machine Learning Models for Molecular Property Prediction: Performance and Robustness on Out-of-Distribution Data. J. Chem. Inf. Model 2025, 65, 9871–9891. [Google Scholar] [CrossRef] [PubMed]
- Abd El Hafez, M. S. M.; Maiyza, A. I.; Hassan, H. A.; Osama, S.; Seadawy, M. G.; El Demellawy, M. A.; Ghareeb, D. A. Analytical and machine learning approaches identify a sea star steroid with promising activity for COVID-19 therapeutic development. Sci. Rep. 2025, 15, 35013. [Google Scholar] [CrossRef] [PubMed]
- Abdoul-Latif, F. M.; Mohamed, H.; Houmed Aboubaker, I.; Saoudi, O.; Ainane, A.; Ali, A. M.; Cacciatore, S.; Zerbini, L. F.; Abourriche, A.; Ainane, T. Cynthichlorine Extracted from Ascidian Cynthia savignyi from Djibouti: Optimization of Extraction, In Vitro Anticancer Profiling, and In Silico Approach. Mar. Drugs 2025, 23. [Google Scholar] [CrossRef] [PubMed]
- Kim, J. H.; Rho, J. R.; Choi, J. H. Marine Sponge-Derived Gukulenin A Sensitizes Ovarian Cancer Cells to PARP Inhibition via Ferroptosis Induction. Mar. Drugs 2025, 23, 138. [Google Scholar] [CrossRef] [PubMed]
- Gupta, V.; Wang, Z.; Combs, J. B.; Wright, T.; Chen, L.; Lin, B.; Holmes, R.; Qin, B.; Oh, J.; Crawford, J. M.; Herzon, S. B. Three-component assembly and structure-function relationships of (−)-gukulenin A. Science 2025, 390, eaea9310. [Google Scholar] [CrossRef] [PubMed]
- Hirata, Y.; Uemura, D. Halichondrins - antitumor polyether macrolides from a marine sponge. Pure Appl. Chem. 1986, 58, 701–710. [Google Scholar] [CrossRef]
- Aicher, T. D.; Buszek, K. R.; Fang, F. G.; Forsyth, C. J.; Jung, S. H.; Kishi, Y.; Matelich, M. C.; Scola, P. M.; Spero, D. M.; Yoon, S. K. Total synthesis of halichondrin B and norhalichondrin B. J. Am. Chem. Soc. 2002, 114, 3162–3164. [Google Scholar]
- Health, N. I. o.; Transfer, O. o. T. Development of Eribulin, a Potent Anti-Cancer Agent, from a Marine Sponge. National Institutes of Health, Office of Technology Transfer. Available online: https://www.techtransfer.nih.gov/kudo/development-of-eribulin-a-potent-anti-cancer-agent-from-a-marine-sponge (accessed on 9 August 2026).
- Cortes, J.; O’Shaughnessy, J.; Loesch, D. Eribulin Monotherapy versus Treatment of Physician’s Choice in Patients with Metastatic Breast Cancer (EMBRACE): A Phase 3 Open-Label Randomised Study. Lancet 2011, 377, 914–923. [Google Scholar] [CrossRef] [PubMed]
- Eisai Inc. HALAVEN (eribulin mesylate) injection: Prescribing information. Available online: https://dailymed.nlm.nih.gov/dailymed/lookup.cfm?setid=31ce4750-ded5-4a0b-95e9-f229fa6bc822.
- Fang, F.; Austad, B.; Calkins, T.; Chase, C.; Horstmann, T.; Hu, Y.; Lewis, B.; Niu, X.; Noland, T.; Orr, J.; Schnaderbeck, M.; Zhang, H.; Asakawa, N.; Asai, N.; Chiba, H.; Hasebe, T.; Hoshino, Y.; Ishizuka, H.; Kajima, T.; Kayano, A.; Komatsu, Y.; Kubota, M.; Kuroda, H.; Miyazawa, M.; Tagami, K.; Watanabe, T. Commercial Manufacture of Halaven®: Chemoselective Transformations En Route to Structurally Complex Macrocyclic Ketones. Synlett 2013, 24, 333–337. [Google Scholar] [CrossRef]
- Lever, J.; Kreuder, F.; Henry, J.; Hung, A.; Allard, P. M.; Brkljaca, R.; Rix, C.; Taki, A. C.; Gasser, R. B.; Kaslin, J.; Wlodkowic, D.; Wolfender, J. L.; Urban, S. Targeted Isolation of Antibiotic Brominated Alkaloids from the Marine Sponge Pseudoceratina durissima Using Virtual Screening and Molecular Networking. Mar. Drugs 2022, 20, 554. [Google Scholar] [CrossRef] [PubMed]
- Furusato, A.; Kato, H.; Nehira, T.; Eguchi, K.; Kawabata, T.; Fujiwara, Y.; Losung, F.; Mangindaan, R. E.; de Voogd, N. J.; Takeya, M.; Yokosawa, H.; Tsukamoto, S. Acanthomanzamines A-E with new manzamine frameworks from the marine sponge Acanthostrongylophora ingens. Org. Lett. 2014, 16, 3888–3891. [Google Scholar] [CrossRef] [PubMed]
- Rizka Nurcahyaningtyas, H.; Irene, A.; Tri Wibowo, J.; Yunovilsa Putra, M.; Yanuar, A. Identification of potential Indonesian marine invertebrate bioactive compounds as TMPRSS2 and SARS-CoV-2 Omicron spike protein inhibitors through computational screening. Arab J. Chem. 2023, 16, 104984. [Google Scholar] [CrossRef] [PubMed]
- Meng, B.; Abdullahi, A.; Ferreira, I.; Goonawardane, N.; Saito, A.; Kimura, I.; Yamasoba, D.; Gerber, P. P.; Fatihi, S.; Rathore, S.; Zepeda, S. K.; Papa, G.; Kemp, S. A.; Ikeda, T.; Toyoda, M.; Tan, T. S.; Kuramochi, J.; Mitsunaga, S.; Ueno, T.; Shirakawa, K.; Takaori-Kondo, A.; Brevini, T.; Mallery, D. L.; Charles, O. J.; Collaboration, C.-N. B. C.-; Genotype to Phenotype Japan, C.; Ecuador, C. C.; Bowen, J. E.; Joshi, A.; Walls, A. C.; Jackson, L.; Martin, D.; Smith, K. G. C.; Bradley, J.; Briggs, J. A. G.; Choi, J.; Madissoon, E.; Meyer, K. B.; Mlcochova, P.; Ceron-Gutierrez, L.; Doffinger, R.; Teichmann, S. A.; Fisher, A. J.; Pizzuto, M. S.; de Marco, A.; Corti, D.; Hosmillo, M.; Lee, J. H.; James, L. C.; Thukral, L.; Veesler, D.; Sigal, A.; Sampaziotis, F.; Goodfellow, I. G.; Matheson, N. J.; Sato, K.; Gupta, R. K. Altered TMPRSS2 usage by SARS-CoV-2 Omicron impacts infectivity and fusogenicity. Nature 2022, 603, 706–714. [Google Scholar] [CrossRef] [PubMed]
- Llorach-Pares, L.; Rodriguez-Urgelles, E.; Nonell-Canals, A.; Alberch, J.; Avila, C.; Sanchez-Martinez, M.; Giralt, A. Meridianins and Lignarenone B as Potential GSK3beta Inhibitors and Inductors of Structural Neuronal Plasticity. Biomolecules 2020, 10. [Google Scholar] [CrossRef] [PubMed]
- Rodriguez-Urgelles, E.; Sancho-Balsells, A.; Chen, W.; Lopez-Molina, L.; Ballasch, I.; Del Castillo, I.; Avila, C.; Alberch, J.; Giralt, A. Meridianins Rescue Cognitive Deficits, Spine Density and Neuroinflammation in the 5xFAD Model of Alzheimer's Disease. Front Pharmacol. 2022, 13, 791666. [Google Scholar] [CrossRef] [PubMed]
- Xu, Y.; Du, X.; Yu, X.; Jiang, Q.; Zheng, K.; Xu, J.; Wang, P. Recent Advances in the Heterologous Expression of Biosynthetic Gene Clusters for Marine Natural Products. Mar. Drugs 2022, 20. [Google Scholar] [CrossRef] [PubMed]
- Lin, H. Y.; Tsai, T. N.; Hsu, K. C.; Hsu, Y. M.; Chiang, L. C.; El-Shazly, M.; Chang, K. M.; Lin, Y. H.; Tu, S. Y.; Lin, T. E.; Du, Y. C.; Liu, Y. C.; Lu, M. C. From Sea to Science: Coral Aquaculture for Sustainable Anticancer Drug Development. Mar. Drugs 2024, 22, 323. [Google Scholar] [CrossRef] [PubMed]
- Diversity, S. o. t. C. o. B. Nagoya Protocol on Access to Genetic Resources and the Fair and Equitable Sharing of Benefits Arising from Their Utilization; United Nations: Montreal, Canada; United Nations, 2011. [Google Scholar]
Table 1.
Targeted literature-discovery and source-verification approach.
| Source | Coverage | Search or verification route | Purpose |
|---|---|---|---|
| PubMed | 1 Jan 2015-9 Aug 2026 | (marine OR sponge OR tunicate OR mollusc OR cnidarian OR echinoderm) AND (machine learning OR artificial intelligence OR virtual screening OR docking OR molecular dynamics OR QSAR OR molecular networking) AND (natural product OR metabolite) | Recent computational and translational studies |
| Publisher sites and Crossref | Same period | Title, DOI, issue, author, and full-text verification for records found by targeted searching | Resolve metadata and check methods |
| Backward and forward citations | No date limit for lineages | Original isolation, synthesis, pharmacology, process, mechanism, and review records | Reconstruct chronology and production history |
| Official sources | Current to 9 Aug 2026 | Regulatory labels, treaty status, and public technology-transfer records | Verify changeable status claims |
Notes: The search supported a structured critical Review. It was not used as a screened corpus. No prevalence estimate or PRISMA flow is claimed.
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (http://creativecommons.org/licenses/by/4.0/).
Copyright: This open access article is published under a Creative Commons CC BY 4.0 license, which permit the free download, distribution, and reuse, provided that the author and preprint are cited in any reuse.