

Submitted:
12 September 2026
Posted:
14 September 2026
You are already at the latest version
Abstract
Background/Objectives: Accurate prediction of complex traits from high-dimensional genomic markers remains difficult in plant breeding. Linear models have limited capacity for non-linear interactions, and many deep learning models scale poorly on long marker sequences. This study introduces BiMSGP, a bidirectional Mamba-based model for scalable genomic prediction. Methods: BiMSGP extends a selective state space model with forward and backward processing so that each marker can integrate sequence context from both directions while retaining linear computational complexity; this is a modeling device for long-range marker dependencies, not a demonstration of biological epistasis. Regression was evaluated on Wheat599, Wheat2000, and SoyBase, and classification on SoyBase, using 10-fold cross-validation with shared fold assignments. Ablation studies compared bidirectional and unidirectional stacks and different depths. Pairwise tests on the same folds were used to separate numerical rank from statistical significance. Results: BiMSGP attained the numerically highest Pearson correlation coefficient (PCC) in all four Wheat599 environments, six of eight Wheat2000 traits, and five of seven quantitative SoyBase traits. Several of these numerical ranks were not statistically significant against the strongest baseline; GBLUP was significantly better for SoyBase oil content. Shallow bidirectional designs had higher mean PCC than deeper and unidirectional variants. Training cost was higher than that of lightweight baselines on larger datasets, but inference remained in the millisecond range. Conclusions: Bidirectional selective state space modeling offers a practical accuracy–efficiency trade-off for genomic prediction under within-dataset cross-validation. Evaluation in independent populations, years, or environments remains future work.
Keywords:
BiMSGP
; bidirectional Mamba
; selective state space model
; genomic prediction
; complex traits
; plant breeding
; genomic selection
1. Introduction
Accurately predicting complex phenotypic traits from genomic data is a central challenge in plant breeding and genetics, with significant implications for accelerating genetic gain and improving crop productivity [1,2,3,4,5,6]. Genomic prediction (GP) uses genome-wide markers to estimate breeding values or phenotypic outcomes before all candidates are phenotyped. Its practical application is complicated by the high-dimensional, low-sample-size structure of many breeding datasets, in which the number of markers greatly exceeds the number of individuals [7,8,9,10].
Traditional statistical approaches, such as genomic best linear unbiased prediction (GBLUP) and ridge-regression BLUP, are computationally efficient and remain strong baselines [11,12,13]. Their predominantly additive formulations, however, can have limited capacity to represent non-linear effects and interactions that contribute to complex traits [14,15]. Comparative studies have consequently explored machine- and deep-learning alternatives, while also showing that performance depends strongly on trait architecture, sample size, and model tuning [9,16,17]. Convolutional models such as DeepGS and DLGWAS learn local marker patterns, and newer systems including DNNGP, SoyDNGP, and DeepCCR extend deep genomic prediction to multi-omics, soybean, and large rice populations [6,18,19,20,21]. Fixed local receptive fields and the cost of modeling long marker sequences nevertheless remain important constraints.
Long-range sequence models have demonstrated the value of integrating distant genomic context, from hybrid convolutional–recurrent networks and long-context regulatory models to genomic language models [22,23,24]. State space models provide another route to long-context modeling: HiPPO and S4 established efficient structured-memory formulations, and Mamba introduced input-dependent selective state spaces with linear sequence complexity [25,26,27,28]. Building on this foundation, we propose BiMSGP (Bidirectional Mamba-based model for Scalable and Accurate Genomic Prediction), a bidirectional Mamba architecture specifically designed for plant genomic prediction.
By processing genomic marker sequences in both forward and backward directions, BiMSGP enables each marker to incorporate contextual information from both sides of the sequence. This bidirectional scan can help the model use long-range marker dependencies; it is not direct evidence of biological epistasis between distant loci. The model retains the linear-complexity scan of Mamba.
The main contributions of this work are as follows:
- 1.
- We propose BiMSGP, a bidirectional Mamba-based architecture tailored for genomic prediction. Ablation studies on Wheat599 show that shallow bidirectional stacks outperform deeper and unidirectional variants. The main comparison tables report the residual-on configuration; a residual-off ablation reached a higher mean PCC on that panel and was not substituted into the main tables.
- 2.
- We evaluate BiMSGP on three datasets of increasing scale using within-dataset 10-fold cross-validation: Wheat599 (599 accessions and 1,279 markers), Wheat2000 (2,000 accessions and 33,709 markers), and SoyBase (trait-specific n up to 15,878 accessions and 42,195 SNPs in the processed matrix). We report numerical ranks together with paired fold-wise tests and do not interpret small PCC differences as significant advantages.
- 3.
- We analyze the accuracy–efficiency trade-off of BiMSGP. The model has far more parameters than lightweight baselines (42M versus 81K for DeepGS on Wheat599) and a higher training cost on Wheat2000 and SoyBase; millisecond-scale inference is the operational advantage after a model has been trained.
The remainder of this paper is organized as follows. Section 2 details the BiMSGP architecture, evaluation metrics, and experimental setup. Section 3 presents the main experimental results, ablation studies, and computational efficiency analysis. Section 4 discusses the key findings, limitations, and implications. Finally, Section 5 concludes the paper and outlines future research directions.
2. Materials and Methods
This section details the datasets, data preprocessing procedures, model architecture, implementation details, and evaluation framework used in the development and assessment of the proposed BiMSGP model.
2.1. Datasets and Preprocessing
BiMSGP was evaluated on three publicly available genomic datasets (Table 1):
- Wheat2000: 2,000 Iranian bread wheat lines with 33,709 DArT markers and eight quantitative traits (Grain Length (GL), Grain Width (GW), Grain Hardness (GH), Thousand Kernel Weight (TKW), Test Weight (TW), Sodium Dodecyl Sulphate Sedimentation (SDS), Grain Protein (GP), and Plant Height (PHT)) [18,30].
- SoyBase: a soybean panel derived from the public SoyDNGP/SoyBase resources [20,31]. Gao et al. reported 13,784 accessions and 32,032 SNPs after their complete-case and marker-intersection filters. The processed genotype table used in this study contained 15,878 genotyped accessions and 42,195 SNP columns; we did not restrict the main tables to that 13,784 × 32,032 subset. After excluding accessions with missing values of the target phenotype, sample sizes ranged from 14,485 (Yield) to 15,878 (oil and protein). Seven quantitative traits (Plant Height (Hgt), Oil Content (Oil), Protein Content (Protein), Hundred-seed Weight (SdWgt), Flowering Date (R1), Maturity Date (R8), Yield) and four categorical traits (Flower Color (FC), Pubescence Density (P_DENS), Pod Color (POD), Stem Termination (ST)) were analyzed.
SNP markers (SoyBase) were encoded as {0, 1, 2}, representing the number of minor-allele copies. DArT markers in Wheat599 and Wheat2000 were encoded as binary values (0 = absence, 1 = presence). No additional marker selection was applied beyond the source quality-control procedures described below. Within each training fold, marker values were standardized with scikit-learn StandardScaler fitted on the training partition only and applied to the held-out partition (bimsgp/train.py). Phenotypes for regression were likewise standardized to zero mean and unit variance within each training fold; metrics were reported after inverse transformation to the original scale.
The Wheat599 matrix used for both the main tables and the ablation studies contains 1,279 markers. The source panel comprised 1,447 DArT markers; markers with minor allele frequency below 0.05 were removed and missing genotypes were imputed by sampling from the marginal Bernoulli distribution, following Crossa et al. [29] and Wang et al. [6]. No second, different imputation (for example, population-mean imputation) was applied at training time. Wheat2000 retained 33,709 DArT markers after the quality control of Ma et al. [18]. For SoyBase, genotypes were read from the processed marker table (geno-big.parquet; 15,878 rows and 42,195 SNP columns) without applying the 32,032-SNP intersection or 13,784-accession complete-case filter of Gao et al. Samples with missing values of the target phenotype were then excluded, giving the trait-specific n in Table 1. No additional genotype imputation was applied in the training scripts. The public code expects these already-processed matrices (Geno.csv / wheat_GS_v2.RData / geno-big.parquet); scripts that rebuild the 1,279-marker Wheat599 table or the 42,195-column SoyBase table from raw public downloads are not included in the released tree.
Markers were arranged as a one-dimensional sequence in the column order of the source genotype matrices. Wheat599 columns are DArT identifiers (for example, wPt and c names) and do not include chromosome or physical-position annotation, so the sequence is not guaranteed to follow genomic coordinates. Wheat2000 followed the column order of the genotype matrix in the public wheat_GS_v2.RData object. SoyBase SNPs followed the column order of the processed genotype table. Concatenating markers across chromosomes, or using an unsorted marker list, places the last marker of one group next to the first marker of the next; such junctions are artifacts of serialization rather than biological adjacency. Figure 1 is an abstract schematic of this marker sequence and does not depict chromosome boundaries.
Class counts and proportions for the four SoyBase categorical traits are given in Table 2. Stem termination (ST) is the most imbalanced (class S: 8.1%), which is why balanced accuracy is reported alongside overall accuracy.
2.2. BiMSGP Model Architecture
The proposed BiMSGP model adopts a bidirectional selective state space modeling approach to effectively capture long-range dependencies among genomic markers while maintaining computational efficiency.
2.2.1. Background on Mamba Architecture
The Mamba model [27] is a recent state space model (SSM) designed as an efficient alternative to Transformers for modeling long sequences. Unlike Transformers, which suffer from quadratic computational complexity with respect to sequence length, Mamba achieves linear time and memory complexity through a selective state space mechanism.
Specifically, Mamba is based on a structured state space model (S4) [26] with the following key innovations:
- Selective State Space: The model parameters (A, B, C matrices) are made input-dependent, allowing the network to dynamically focus on relevant parts of the sequence while filtering out noise. This is particularly beneficial for high-dimensional genomic marker data where only a subset of markers may be strongly associated with the target trait.
- Hardware-aware Algorithm: Mamba employs a parallel scan algorithm that enables efficient GPU-parallel computation, significantly improving training and inference speed compared to standard SSMs.
- Linear Complexity: For a sequence of M markers, Mamba has time and memory complexity, making it particularly suitable for genomic data with tens of thousands of markers (– in our experiments).
In standard Mamba, information flows only in one direction (forward). To better capture long-range bidirectional dependencies among SNP markers, we propose BiMSGP, which extends Mamba into a bidirectional architecture.
2.2.2. Overall Framework
As illustrated in Figure 1(A), BiMSGP consists of an embedding layer, bidirectional Mamba stacks, and a decoder head. The marker sequence is embedded, processed in the forward and reverse directions, concatenated, and decoded to a trait prediction. Figure 1(B) shows the same pipeline in more detail: a linear embedding maps each marker to , residual Mamba blocks (when used) run on the original and flipped sequences, the two representations are concatenated, and a lightweight MLP decoder produces the output. Chromosome boundaries are not marked; the figure is an abstract marker sequence in source-file column order.
2.2.3. Input and Embedding Layer
The input to BiMSGP is a matrix of genomic markers with shape , where B is the batch size and M is the number of markers (sequence length). Each genomic marker is initially treated as a univariate feature.
A linear embedding layer projects the input from 1 dimension to the model dimension :
This produces an embedded representation of shape that serves as input to the subsequent bidirectional Mamba stacks. The embedding layer allows the model to learn a richer representation of the genomic markers before processing them through the state space layers.
2.2.4. Bidirectional Mamba Stacks
The core of BiMSGP is the bidirectional Mamba architecture, which processes the marker sequence in both forward and backward directions to capture long-range dependencies from both ends.
For the forward path, the sequence passes through a stack of Mamba layers with residual connections and layer normalization:
where L is the number of layers in the stack. In our experiments, we typically set L to 1 or 2, as deeper stacks did not yield further improvements according to the ablation studies.
For the backward path, the sequence is first flipped, processed by an identical Mamba stack, and then flipped back:
In configurations with residual connections, a residual connection and layer normalization are applied after each Mamba layer to stabilize training; the ablation study also evaluates configurations without residual connections.
2.2.5. Feature Fusion and Decoder Head
The forward and backward features are concatenated along the feature dimension:
After a final layer normalization, the fused representation is flattened and passed through a lightweight decoder head:
Two decoder heads are used (bimsgp/model.py). Wheat599 and Wheat2000 use the wide head (three linear layers; first dropout at least 0.15). SoyBase uses the compact head (two linear layers; dropout ). Let for bidirectional models.
The Wheat (wide) decoder is
The SoyBase (compact) decoder is
Here, denotes the task-specific output dimension: one output is used for regression, whereas classification uses the configured number of output logits. This design enables BiMSGP to effectively model complex non-linear marker–trait associations from both directions while keeping the model computationally tractable.
2.2.6. Implementation Details
The model was implemented in PyTorch using the official mamba-ssm library. All experiments were conducted on Ubuntu Linux systems with NVIDIA GPUs, including A100 GPUs with 40 GB or 80 GB of memory, an RTX 3090, and an RTX 4090.
Unless otherwise stated, the main-table configuration (Table 3, Table 4, Table 5 and Table 6) used BiMSGP with , , bidirectional Mamba layer per direction, residual connections and layer normalization after each Mamba block, AdamW (learning rate , weight decay ), ReduceLROnPlateau (patience 10, factor 0.5), and a maximum of 100 epochs. Wheat599 and Wheat2000 used the wide decoder and batch size 8. SoyBase quantitative traits used the compact decoder and batch size 32, except oil and R8, which used and 20 epochs. SoyBase classification used the compact decoder and batch size 1. Decoder dropout is 0.15 then 0.1 in the wide head and 0.1 in the compact head. The released trainer (bimsgp/train.py) runs in FP32; mixed precision (FP16) was used in the original internal runs but is not implemented in the public script (no autocast/GradScaler). This residual-on Wheat599 setting is the configuration reported in Table 3 (42.0M parameters; Environment 1 mean PCC ). Ablation experiments on Wheat599 Environment 1 additionally evaluated residual-off and depth/dimension variants; removing residual connections at increased mean PCC to (Table 8), but that variant was not substituted into the main comparison tables. For regression, continuous phenotypes were standardized to zero mean and unit variance within each training fold.
2.3. Competing Methods
To evaluate BiMSGP, we compared it against four widely used genomic prediction methods: GBLUP, DeepGS, DNNGP, and SoyDNGP. Brief descriptions of each method are provided below.
2.3.1. GBLUP
Genomic best linear unbiased prediction (GBLUP) is one of the most widely adopted linear mixed model approaches for genomic selection [11,12]. It replaces the traditional pedigree-based relationship matrix with a genomic relationship matrix (GRM) constructed from genome-wide markers. The model can be expressed as:
where is the vector of phenotypes, represents fixed effects, is the vector of genomic breeding values with , is the GRM, and is the residual error. GBLUP assumes additive genetic effects and has low computational cost, making it a strong baseline for genomic prediction across various species.
2.3.2. DeepGS
DeepGS is a deep learning-based method for genomic prediction that utilizes a deep convolutional neural network (CNN) to extract hidden features directly from raw genotypic data [18]. The model treats SNP markers as a one-dimensional sequence and applies convolutional layers, pooling, and fully connected layers to learn complex non-linear patterns. DeepGS was one of the early attempts to apply deep learning to genomic selection and has demonstrated improved performance over traditional linear models on several crop datasets by capturing non-linear and non-additive marker effects.
2.3.3. DNNGP
Deep Neural Network Genomic Prediction (DNNGP) is a deep learning framework specifically designed for integrating multi-omics data in plant genomic prediction [6]. It employs a hierarchical multilayer neural network with batch normalization, ReLU activation, and early stopping to mitigate overfitting. DNNGP can handle various types of omics data and dynamically learns feature representations from raw inputs. It has shown competitive or superior performance compared to GBLUP and other deep learning methods, particularly on large-scale breeding datasets, while maintaining reasonable computational efficiency.
2.3.4. SoyDNGP
SoyDNGP is a soybean-specific deep learning framework for genomic prediction [20]. It converts standard VCF files into 3D tensor inputs and employs a convolutional neural network (CNN) architecture optimized for soybean breeding traits. The model is designed to be web-accessible and user-friendly, focusing on capturing complex patterns in high-dimensional SNP data for traits such as yield, oil content, and protein content. SoyDNGP has demonstrated strong performance on large soybean panels and serves as a specialized competitor for legume genomic prediction tasks.
2.4. Evaluation Metrics
To rigorously assess the predictive performance of BiMSGP and competing methods, we employed multiple complementary evaluation metrics suitable for both regression and classification tasks in genomic prediction.
For all quantitative traits (regression tasks), the primary metric was the Pearson correlation coefficient (PCC) between predicted and observed phenotypic values, which measures the strength of the linear relationship and is widely used in genomic selection studies because it is invariant to scale. We also reported the root mean squared error (RMSE) and mean absolute error (MAE) to evaluate the accuracy of absolute predictions:
where n is the number of evaluated samples, and are the observed and predicted values, respectively, and , denote their means.
All regression metrics were computed on the original (unstandardized) phenotypic scale after inverse transformation.
For the four categorical traits in the SoyBase dataset (flower color (FC), pubescence density (P_DENS), pod color (POD), and stem termination (ST)), we used classification accuracy and balanced accuracy as the main metrics. Accuracy is the proportion of correctly classified samples:
where is the indicator function. Balanced accuracy is particularly suitable for potentially imbalanced classes and is calculated as the average of recall across all classes:
where C is the number of classes, and are the true positives and false negatives for class c, respectively.
All performance metrics were evaluated using 10-fold cross-validation. Regression used scikit-learn KFold (10 splits, shuffle, random_state=42). SoyBase classification used StratifiedKFold with the same split count and seed. Within each task, BiMSGP and the baseline methods shared those fold assignments so that methods could be compared on identical held-out partitions. For neural-network models, the held-out test partition of each fold was scored at every epoch, and the checkpoint with the highest test PCC (regression) or balanced accuracy (classification) was retained. No inner validation split was created inside the training partition; hyperparameters listed above were fixed rather than re-tuned on the test fold, but epoch selection did use the test partition. This historical protocol can produce an optimistic bias relative to nested cross-validation, in which early stopping would use only data from the training partition. Reported neural-network accuracies should therefore be interpreted as an upper bound under this protocol. GBLUP has no epoch-wise checkpointing and is not subject to the same selection step.
Pairwise differences in PCC were tested on the ten shared folds with a two-sided paired t-test and a two-sided Wilcoxon signed-rank test. We report the mean difference, a 95% confidence interval, Cohen’s paired effect size , and both p-values (Appendix Table A1–Table A3). Boldface in the main tables marks the numerically highest mean only and does not imply statistical significance. P-values are unadjusted for the number of trait-by-method contrasts. Fold-level scores were not archived for Wheat599 SoyDNGP or for SoyBase SoyDNGP, so those comparisons remain descriptive (mean ± SD only).
3. Results
In this section, we evaluate the proposed BiMSGP model against GBLUP [12], DeepGS [18], DNNGP [6], and SoyDNGP [20] on Wheat599 [6], Wheat2000 [18,30], and SoyBase [20,31]. All three datasets were used for regression, whereas classification was evaluated only on SoyBase; all evaluations used 10-fold cross-validation with shared fold assignments. We distinguish numerically highest mean PCC from statistically significant paired differences (Appendix Table A1–Table A3). We then report ablation studies and computational cost.
3.1. Performance on Wheat599 Dataset
The Wheat599 dataset consists of 599 historical wheat lines genotyped with 1,279 DArT genomic markers (after quality control and imputation) across four agroclimatic mega-environments [6]. Phenotypic values in each environment were standardized to a zero mean and unit variance. Predictive performance was assessed using 10-fold cross-validation, with the Pearson correlation coefficient (PCC) as the primary metric and root mean squared error (RMSE) as a secondary metric.
BiMSGP had the numerically highest mean PCC in all four environments (Table 3 and Figure 2). In Environment 1, the mean PCC was 0.6198 ± 0.0708 (RMSE 0.8038 ± 0.0591), compared with 0.5720 ± 0.0763 for DeepGS, 0.5543 ± 0.1015 for DNNGP, 0.5234 ± 0.0798 for GBLUP, and 0.5225 ± 0.1209 for SoyDNGP. Paired tests on the shared folds (Table ) supported a BiMSGP advantage over GBLUP in all four environments (). Versus DeepGS, the Environment 1 and Environment 3 differences were significant ( and ), whereas Environments 2 and 4 were not ( for both). Versus DNNGP, Environments 1, 2, and 4 were significant, but Environment 3 was not (). SoyDNGP fold-level scores were not archived for Wheat599, so that comparison remains descriptive.
3.2. Performance on Wheat2000 Dataset
To assess scalability with a larger sample size and more markers, BiMSGP was evaluated on the Wheat2000 dataset, which consists of 2,000 Iranian bread wheat landraces genotyped with 33,709 DArT markers retained after quality control. Eight agronomic traits were analyzed: grain hardness (GH), grain length (GL), grain protein (GP), grain width (GW), plant height (PHT), sodium dodecyl sulphate sedimentation (SDS), thousand kernel weight (TKW), and test weight (TW).
As shown in Table 4 and Figure 3, BiMSGP had the numerically highest mean PCC for six of eight traits (GH, GL, GP, SDS, TKW, and TW). DeepGS had a slightly higher mean PCC for grain width (0.7500 ± 0.0331 versus 0.7464 ± 0.0384) and plant height (0.3279 ± 0.0617 versus 0.3212 ± 0.0674); neither difference was significant (GW ; PHT ; Table ). None of the six numerical BiMSGP ranks versus DeepGS was statistically significant (all ), including close contrasts such as TKW (PCC , ). Versus GBLUP, BiMSGP was significantly higher for GH, GL, GW, TKW, and TW, but not for GP, SDS, or PHT. Versus DNNGP and SoyDNGP, BiMSGP was significantly higher for all eight traits.
3.3. Performance on Soybean Dataset (SoyBase)
We further evaluated BiMSGP on the larger SoyBase panel using the same within-dataset 10-fold protocol (trait-specific n of 14,485–15,878 and 42,195 SNPs in the processed matrix). Seven quantitative traits (plant height (Hgt), oil content (Oil), protein content (Protein), hundred-seed weight (SdWgt), flowering date (R1), maturity date (R8), and yield (Yield)) and four categorical traits (flower color (FC), pubescence density (P_DENS), pod color (POD), and stem termination (ST)) were analyzed. For quantitative traits, performance was measured by PCC and RMSE; for classification, accuracy and balanced accuracy were reported.
As shown in Table 5 and Figure 4, BiMSGP had the numerically highest mean PCC on five of seven quantitative traits: Hgt (0.8141 ± 0.0135), SdWgt (0.9201 ± 0.0073), R1 (0.6821 ± 0.0114), R8 (0.7846 ± 0.0176), and yield (0.7900 ± 0.0093). GBLUP had a higher mean PCC for oil (0.8825 versus 0.8816) and protein (0.7182 versus 0.7171). Paired tests (Table ) showed that GBLUP was significantly better for oil (PCC , ), whereas the protein difference was not significant (). BiMSGP was significantly higher than GBLUP for Hgt, SdWgt, R1, and R8; the yield difference versus GBLUP and DeepGS was not significant ( and ). Versus DeepGS, only Hgt, R1, and R8 were significant; SdWgt, oil, protein, and yield were not.
For the classification tasks (Table 6 and Figure 5), BiMSGP was competitive but was not the top method on every metric. SoyDNGP attained the highest accuracy and balanced accuracy on the binary traits FC and P_DENS, while DeepGS performed best on the three-class trait ST. BiMSGP had the highest balanced accuracy on POD (0.8497 ± 0.0123). Class proportions (Table 2) show substantial imbalance, especially for ST (class S: 8.1%), which is consistent with the gap between overall accuracy (0.8179) and balanced accuracy (0.6695) for that trait. Fold-level classification scores were not archived for all methods, so these ranks are descriptive.
Overall, BiMSGP was competitive for both regression and classification under within-dataset 10-fold cross-validation. Numerical rank over GBLUP or DeepGS should not be read as a uniform significant advantage, particularly for SoyBase oil and protein and for most Wheat2000 traits versus DeepGS.
3.4. Ablation Studies on Model Architecture
To systematically evaluate the contribution of key components in the proposed Mamba-based genomic prediction framework, we performed a comprehensive set of ablation experiments on the Wheat599 dataset. This dataset comprises 599 historical wheat lines from the CIMMYT Global Wheat Program [29], genotyped with 1,447 DArT markers. After removing markers with minor allele frequency below 0.05 and imputing missing values with samples from the marginal Bernoulli distribution (as described in [29]), 1,279 markers remained. This is the same processed matrix used in Table 3; no alternative population-mean imputation was applied at training time. Phenotypic values for Environment 1 were standardized to zero mean and unit variance (mean ± standard deviation: ±). All ablation configurations were trained under identical optimization settings: learning rate , weight decay , 100 epochs, and batch size 16. Performance was assessed via 10-fold cross-validation using Pearson correlation coefficient (PCC, higher is better), root mean squared error (RMSE), and mean absolute error (MAE).
The ablation study examined five main factors: (i) presence/absence of residual connections, (ii) number of layers (L), (iii) model dimension (), (iv) state dimension (), and (v) architectural variants (standard bidirectional Mamba vs. forward-only, backward-only, and sum-pooling variants).
Table 7 summarizes the computational cost of different configurations. Trainable parameter counts ranged from approximately 21M (smallest model) to 673M (largest), while average training time for 100 epochs varied from 0.96 minutes (lightweight forward Mamba) to 8.28 minutes (large model). Inference time per sample remained efficient (1.64–1.98 ms) across all configurations.
Table 8 reports results for the effect of residual connections and layer depth (fixed , ). Removing residual connections consistently yielded a modest but stable improvement in PCC across all layer counts, with no degradation in RMSE or MAE. Performance was optimal with shallow architectures (–4), while increasing depth to produced a slight decline, suggesting that deeper Mamba stacks may introduce unnecessary complexity for this genomic prediction task.
Table 9 isolates the impact of model dimension, state dimension, and directional variants (all with ). Increasing from 32 to 128 improved PCC, with the peak at (PCC ±). Further scaling to yielded comparable performance at substantially higher computational cost (parameters increased ∼4×, from 168M to 673M). The state dimension performed marginally better than 16 or 64. Among directional variants, the standard bidirectional Mamba had a higher mean PCC than forward-only, backward-only, and sum-pooling configurations, indicating that bidirectional scanning is useful for using marker context from both directions.
Overall, the Wheat599 Environment 1 ablations support shallow bidirectional stacks over deeper or unidirectional variants. Residual-off reached mean PCC versus with residuals (Table 8); a similar mean PCC of also appeared for residual-on at (Table 9). Neither peak was used as the main-table configuration. The published comparisons use residual-on and (Environment 1 mean PCC ).
3.5. Computational Efficiency
We evaluated the computational efficiency of BiMSGP on the Wheat599 dataset (, ), which represents a typical small-to-medium-scale genomic prediction scenario. Training time is reported for 100 epochs for the neural-network models, whereas GBLUP time is reported per cross-validation fold.
Dashes for GBLUP indicate that it is not a neural network: there is no comparable trainable-parameter count, training is reported per cross-validation fold rather than per 100 epochs, and a separate per-sample neural inference time was not recorded. As shown in Table 10, BiMSGP used approximately 42 million parameters and 1.52 minutes for 100 epochs on Wheat599, compared with 81K parameters and 0.40 minutes for DeepGS and 10.4M parameters and 0.48 minutes for DNNGP. The Environment 1 mean PCC was numerically higher (0.6198 versus 0.5720 for DeepGS). Inference remained fast at 1.7 ms per sample.
Training times on Wheat2000 and SoyBase were much longer (Appendix B, Table A1): about 174 minutes per 100 epochs on Wheat2000 (1.105 billion parameters) and 462 minutes on SoyBase (691 million parameters), versus minutes for DeepGS. This training cost is a real practical constraint. Millisecond inference is the advantage after a model has been trained, not a claim that BiMSGP is cheaper to fit.
4. Discussion
The results indicate that BiMSGP is a competitive bidirectional Mamba-based model for genomic prediction under within-dataset 10-fold cross-validation. Model ranking depended on the crop, trait, and baseline, which is consistent with broader benchmarking evidence that no single algorithm is universally best [8,9,16,17]. Bidirectional scanning lets each marker use context from both directions and may help the model use long-range marker dependencies; the experiments do not demonstrate biological epistasis between distant loci.
On Wheat599, BiMSGP had the numerically highest mean PCC in all four environments, with the largest contrast in Environment 1 (0.6198 versus 0.5720 for DeepGS). Paired tests supported an advantage over GBLUP in every environment, but not every contrast with DeepGS or DNNGP was significant. With , fold-to-fold variation is large, so overlapping intervals should be interpreted cautiously.
On Wheat2000 (, ), BiMSGP had the numerically highest mean PCC on six of eight traits. Versus DeepGS, none of those six differences was significant, and DeepGS was numerically higher for GW and PHT. Versus GBLUP, several grain-related traits were significant, whereas GP, SDS, and PHT were not. These results support scalability of the architecture to tens of thousands of markers, but they do not support a claim of uniform superiority over strong convolutional or additive baselines.
On SoyBase, GBLUP remained a strong additive baseline. It was significantly better than BiMSGP for oil () and numerically better for protein (). BiMSGP was significantly higher than GBLUP for Hgt, SdWgt, R1, and R8, while yield was not significant versus GBLUP or DeepGS. Classification performance was competitive rather than uniformly best, and ST in particular is imbalanced. These evaluations are within-dataset cross-validation, not prediction into an independent population, year, or environment.
Ablation studies on Wheat599 Environment 1 showed that bidirectional processing had a higher mean PCC than unidirectional and sum-pooling variants, and that shallow stacks ( or ) with moderate were sufficient. Removing residual connections gave a modest further gain (mean PCC 0.6387 versus 0.6191 at ); the main tables used the residual-on configuration.
Computationally, BiMSGP is expensive to train relative to DeepGS (42M versus 81K parameters on Wheat599; 174 and 462 minutes per 100 epochs on Wheat2000 and SoyBase). That training cost is a genuine limitation for routine refitting. Millisecond inference is the benefit after a model has been trained.
Several additional limitations should be noted. First, epoch selection used the test partition of each fold, which can inflate neural-network accuracies relative to nested cross-validation. Second, marker order followed source-file column order; chromosome junctions in the serialized sequence are not biological adjacencies. Third, the study does not include multi-omics inputs or independent-population validation. Future work should include nested evaluation, independent breeding populations or environments, model compression, and multi-trait or genotype-by-environment extensions [14,32].
5. Conclusions
BiMSGP is a bidirectional Mamba-based model for genomic prediction of complex plant traits. Bidirectional scanning lets each marker use sequence context from both directions while retaining linear complexity; this is a modeling device for long-range marker dependencies, not a demonstration of biological epistasis. Under within-dataset 10-fold cross-validation, BiMSGP was numerically strongest for many quantitative traits and competitive for SoyBase categorical traits, but several close comparisons with DeepGS or GBLUP were not statistically significant, and GBLUP was significantly better for SoyBase oil. Shallow bidirectional configurations with moderate model dimensions had higher mean PCC than deeper or unidirectional alternatives.
Training BiMSGP is substantially more expensive than lightweight baselines; millisecond inference is the operational advantage after training. Independent-population or multi-environment evaluation, nested cross-validation, and model compression are important next steps.
Patents
The authors have filed a patent application related to the BiMSGP model proposed in this manuscript, which has been accepted for examination. The filing does not prevent academic use or public release of the research code and experiment settings.
Author Contributions
Conceptualization: Xu Liu and Qingjie Liu; Methodology: Xu Liu, and Qingjie Liu; Validation: Xinwei Yao, Jinyan Ma, and Huilin Cheng; Resources: Huahao Zhou; Data curation: Xu Liu and Songyang Huai; Writing—review and editing: Xu Liu and Songyang Huai; Supervision: Xu Liu; Project administration: Jinyan Ma, Qingjie Liu, and Licong Ding; Funding acquisition: Huahao Zhou. All authors have read and agreed to the published version of the manuscript.
Funding
This research was funded by the Central-Local Collaborative Project “High-Performance Brain-inspired Computer and Applications” (Grant No. 2025YFG0100600).
Institutional Review Board Statement
Not applicable. This study used publicly available plant genomic and phenotypic datasets and did not involve humans or animals.
Informed Consent Statement
Not applicable.
Data Availability Statement
The datasets analyzed in this study are publicly available from the original publications and repositories cited in the Materials and Methods section. The released research tree provides the trainer, JSON configs, fold-export helpers, and fold-wise metrics. Regression used KFold and SoyBase classification used StratifiedKFold (n_splits=10, shuffle=True, random_state=42). The public code reads already-processed genotype matrices; scripts that rebuild the 1,279-marker Wheat599 table or the 42,195-column SoyBase table from raw downloads are not included. The patent application related to BiMSGP does not restrict academic release of the implementation.
Acknowledgments
The authors thank the researchers and institutions that made the Wheat599, Wheat2000, and SoyBase datasets publicly available.
Conflicts of Interest
The authors have filed a patent application related to the BiMSGP model described in this manuscript. The patent does not restrict independent academic reproduction of the method or release of the research implementation. The authors declare no other conflicts of interest. The funders had no role in the design of the study; in the collection, analyses, or interpretation of data; in the writing of the manuscript; or in the decision to publish the results.
Abbreviations
| Abbreviation | Definition |
| BiMSGP | Bidirectional Mamba-based Genomic Prediction |
| Mamba | Selective State Space Model |
| SSM | State Space Model |
| SNP | Single Nucleotide Polymorphism |
| DArT | Diversity Arrays Technology |
| PCC | Pearson Correlation Coefficient |
| RMSE | Root Mean Squared Error |
| MAE | Mean Absolute Error |
| GBLUP | Genomic Best Linear Unbiased Prediction |
| DeepGS | Deep Genomic Selection |
| DNNGP | Deep Neural Network Genomic Prediction |
| SoyDNGP | Soybean Deep Neural Network Genomic Prediction |
| CV | Cross-Validation |
Appendix A. Paired Fold-Wise Tests
Table A1–Table A3 report paired comparisons of BiMSGP versus competing methods on the ten shared cross-validation folds. Positive PCC means BiMSGP had the higher mean PCC. P-values are unadjusted. SoyDNGP fold-level scores were unavailable for Wheat599 and for SoyBase quantitative traits.

Table A1.
Paired fold-wise comparisons of BiMSGP versus competing methods on Wheat599 (Pearson correlation coefficient, 10 shared folds). PCC is BiMSGP minus the comparator. is from a two-sided paired t-test; is from a two-sided Wilcoxon signed-rank test. Cohen’s is the paired effect size (mean difference / SD of differences). Significance stars refer to : * , ** , *** ; ns, not significant. SoyDNGP fold-level scores were not archived for this dataset.
Table A1.
Paired fold-wise comparisons of BiMSGP versus competing methods on Wheat599 (Pearson correlation coefficient, 10 shared folds). PCC is BiMSGP minus the comparator. is from a two-sided paired t-test; is from a two-sided Wilcoxon signed-rank test. Cohen’s is the paired effect size (mean difference / SD of differences). Significance stars refer to : * , ** , *** ; ns, not significant. SoyDNGP fold-level scores were not archived for this dataset.
| Trait | Comparator | PCC | 95% CI | Sig. | |||
|---|---|---|---|---|---|---|---|
| Env1 | DeepGS | +0.0478 | [+0.0029, +0.0926] | 0.039 | 0.037 | 0.76 | * |
| DNNGP | +0.0655 | [+0.0048, +0.1261] | 0.037 | 0.049 | 0.77 | * | |
| GBLUP | +0.0964 | [+0.0640, +0.1288] | 0.002 | 2.13 | *** | ||
| Env2 | DeepGS | +0.0538 | [-0.0087, +0.1164] | 0.083 | 0.131 | 0.62 | ns |
| DNNGP | +0.0441 | [+0.0076, +0.0806] | 0.023 | 0.027 | 0.86 | * | |
| GBLUP | +0.0445 | [+0.0177, +0.0713] | 0.004 | 0.004 | 1.19 | ** | |
| Env3 | DeepGS | +0.0574 | [+0.0080, +0.1068] | 0.027 | 0.027 | 0.83 | * |
| DNNGP | +0.0268 | [-0.0107, +0.0643] | 0.141 | 0.193 | 0.51 | ns | |
| GBLUP | +0.0649 | [+0.0243, +0.1056] | 0.006 | 0.010 | 1.14 | ** | |
| Env4 | DeepGS | +0.0579 | [-0.0092, +0.1250] | 0.083 | 0.131 | 0.62 | ns |
| DNNGP | +0.0713 | [+0.0298, +0.1128] | 0.004 | 0.004 | 1.23 | ** | |
| GBLUP | +0.1128 | [+0.0614, +0.1642] | 0.002 | 1.57 | *** |
Table A2.
Paired fold-wise comparisons of BiMSGP versus competing methods on Wheat2000 (PCC, 10 shared folds). Notation as in Table A1.
Table A2.
Paired fold-wise comparisons of BiMSGP versus competing methods on Wheat2000 (PCC, 10 shared folds). Notation as in Table A1.
| Trait | Comparator | PCC | 95% CI | Sig. | |||
|---|---|---|---|---|---|---|---|
| GH | DeepGS | +0.0016 | [-0.0056, +0.0088] | 0.629 | 0.770 | 0.16 | ns |
| DNNGP | +0.2743 | [+0.2348, +0.3137] | 0.002 | 4.98 | *** | ||
| GBLUP | +0.0149 | [+0.0094, +0.0203] | 0.002 | 1.96 | *** | ||
| SoyDNGP | +0.1766 | [+0.1370, +0.2161] | 0.002 | 3.19 | *** | ||
| GL | DeepGS | +0.0087 | [-0.0018, +0.0192] | 0.093 | 0.105 | 0.59 | ns |
| DNNGP | +0.2903 | [+0.2553, +0.3253] | 0.002 | 5.93 | *** | ||
| GBLUP | +0.0240 | [+0.0188, +0.0292] | 0.002 | 3.30 | *** | ||
| SoyDNGP | +0.1090 | [+0.0874, +0.1306] | 0.002 | 3.61 | *** | ||
| GP | DeepGS | +0.0055 | [-0.0082, +0.0192] | 0.385 | 0.432 | 0.29 | ns |
| DNNGP | +0.1295 | [+0.0880, +0.1710] | 0.002 | 2.23 | *** | ||
| GBLUP | +0.0024 | [-0.0056, +0.0105] | 0.511 | 0.625 | 0.22 | ns | |
| SoyDNGP | +0.1039 | [+0.0904, +0.1174] | 0.002 | 5.52 | *** | ||
| GW | DeepGS | -0.0036 | [-0.0115, +0.0042] | 0.325 | 0.432 | -0.33 | ns |
| DNNGP | +0.2096 | [+0.1834, +0.2358] | 0.002 | 5.72 | *** | ||
| GBLUP | +0.0082 | [+0.0026, +0.0138] | 0.009 | 0.014 | 1.05 | ** | |
| SoyDNGP | +0.1337 | [+0.0860, +0.1815] | 0.002 | 2.00 | *** | ||
| PHT | DeepGS | -0.0068 | [-0.0272, +0.0137] | 0.473 | 0.492 | -0.24 | ns |
| DNNGP | +0.0901 | [+0.0596, +0.1205] | 0.002 | 2.12 | *** | ||
| GBLUP | -0.0024 | [-0.0199, +0.0152] | 0.767 | 0.922 | -0.10 | ns | |
| SoyDNGP | +0.0964 | [+0.0481, +0.1447] | 0.001 | 0.006 | 1.43 | ** | |
| SDS | DeepGS | +0.0116 | [-0.0064, +0.0296] | 0.179 | 0.232 | 0.46 | ns |
| DNNGP | +0.1897 | [+0.1516, +0.2278] | 0.002 | 3.56 | *** | ||
| GBLUP | +0.0068 | [-0.0023, +0.0160] | 0.126 | 0.131 | 0.53 | ns | |
| SoyDNGP | +0.1826 | [+0.1353, +0.2300] | 0.002 | 2.76 | *** | ||
| TKW | DeepGS | +0.0008 | [-0.0081, +0.0098] | 0.837 | 0.922 | 0.07 | ns |
| DNNGP | +0.2507 | [+0.2212, +0.2803] | 0.002 | 6.08 | *** | ||
| GBLUP | +0.0151 | [+0.0060, +0.0242] | 0.005 | 0.004 | 1.18 | ** | |
| SoyDNGP | +0.0968 | [+0.0650, +0.1286] | 0.002 | 2.18 | *** | ||
| TW | DeepGS | +0.0042 | [-0.0121, +0.0205] | 0.575 | 0.695 | 0.18 | ns |
| DNNGP | +0.1966 | [+0.1667, +0.2265] | 0.002 | 4.71 | *** | ||
| GBLUP | +0.0149 | [+0.0032, +0.0266] | 0.018 | 0.020 | 0.91 | * | |
| SoyDNGP | +0.1373 | [+0.0796, +0.1951] | 0.002 | 1.70 | *** |
Table A3.
Paired fold-wise comparisons of BiMSGP versus competing methods on SoyBase quantitative traits (PCC, 10 shared folds). Notation as in Table A1. SoyDNGP fold-level scores were not archived for these traits.
Table A3.
Paired fold-wise comparisons of BiMSGP versus competing methods on SoyBase quantitative traits (PCC, 10 shared folds). Notation as in Table A1. SoyDNGP fold-level scores were not archived for these traits.
| Trait | Comparator | PCC | 95% CI | Sig. | |||
|---|---|---|---|---|---|---|---|
| Hgt | DeepGS | +0.0068 | [+0.0019, +0.0116] | 0.011 | 0.014 | 1.00 | * |
| DNNGP | +0.0257 | [+0.0183, +0.0331] | 0.002 | 2.48 | *** | ||
| GBLUP | +0.0064 | [+0.0036, +0.0091] | 0.004 | 1.64 | *** | ||
| Oil | DeepGS | +0.0011 | [-0.0000, +0.0023] | 0.058 | 0.064 | 0.68 | ns |
| DNNGP | +0.0077 | [+0.0058, +0.0096] | 0.002 | 2.90 | *** | ||
| GBLUP | -0.0010 | [-0.0018, -0.0002] | 0.025 | 0.020 | -0.85 | * | |
| Protein | DeepGS | +0.0070 | [-0.0002, +0.0143] | 0.056 | 0.084 | 0.69 | ns |
| DNNGP | +0.0210 | [+0.0127, +0.0293] | 0.002 | 1.82 | *** | ||
| GBLUP | -0.0011 | [-0.0078, +0.0055] | 0.706 | 0.492 | -0.12 | ns | |
| SdWgt | DeepGS | +0.0014 | [-0.0002, +0.0030] | 0.076 | 0.105 | 0.63 | ns |
| DNNGP | +0.0084 | [+0.0058, +0.0110] | 0.002 | 2.31 | *** | ||
| GBLUP | +0.0033 | [+0.0022, +0.0045] | 0.004 | 2.14 | *** | ||
| R1 | DeepGS | +0.0186 | [+0.0028, +0.0345] | 0.026 | 0.002 | 0.84 | * |
| DNNGP | +0.0173 | [+0.0119, +0.0227] | 0.002 | 2.29 | *** | ||
| GBLUP | +0.0067 | [+0.0001, +0.0134] | 0.047 | 0.131 | 0.73 | * | |
| R8 | DeepGS | +0.0085 | [+0.0031, +0.0139] | 0.006 | 0.002 | 1.13 | ** |
| DNNGP | +0.0160 | [+0.0114, +0.0207] | 0.002 | 2.46 | *** | ||
| GBLUP | +0.0091 | [+0.0059, +0.0124] | 0.002 | 1.99 | *** | ||
| Yield | DeepGS | +0.0025 | [-0.0015, +0.0065] | 0.193 | 0.193 | 0.45 | ns |
| DNNGP | +0.0156 | [+0.0136, +0.0176] | 0.002 | 5.65 | *** | ||
| GBLUP | +0.0039 | [-0.0005, +0.0082] | 0.074 | 0.105 | 0.64 | ns |
Appendix B. Computational Efficiency on Larger Datasets
Training times on Wheat2000 and SoyBase were substantially longer than on Wheat599, primarily because of BiMSGP’s parameter count (1.105 billion on Wheat2000 and 691 million on SoyBase, compared with 42 million on Wheat599 and 81K for DeepGS on Wheat599). This capacity may help represent long marker sequences, but it is a real training-cost disadvantage.
Detailed results are presented in Table A4. On Wheat2000, BiMSGP required approximately 174 minutes for 100 epochs, and on SoyBase approximately 462 minutes, versus under 10 minutes for DeepGS on those panels. Inference remained in the millisecond range, which is relevant after a model has already been trained rather than as a substitute for the training cost.
In future work, we plan to explore shallower network architectures to reduce the parameter count and training time while aiming to preserve the predictive advantages of the current BiMSGP model.
Table A4.
Computational efficiency comparison of BiMSGP and competing methods across three datasets.
Table A4.
Computational efficiency comparison of BiMSGP and competing methods across three datasets.
| Dataset | Model | Parameter count | Training Time | Inference Time |
|---|---|---|---|---|
| (100 epochs) | (per sample) | |||
| Wheat599 (n=599, m=1,279) |
BiMSGP | 42M | 1.52 min | 1.7 ms |
| DeepGS | 81K | 0.40 min | 1.1 ms | |
| DNNGP | 10.4M | 0.48 min | 1.3 ms | |
| SoyDNGP | 18.1M | 0.80 min | 1.4 ms | |
| GBLUP | – | <0.1 s/fold | – | |
| Wheat2000 (n=2,000, m=33,709) |
BiMSGP | 1.105B | 174 min | 11.9 ms |
| DeepGS | 8.6M | 0.98 min | 0.63 ms | |
| DNNGP | 276M | 5.3 min | 0.87 ms | |
| SoyDNGP | 18.1M | 2.8 min | 0.73 ms | |
| GBLUP | – | 0.2 s/fold | – | |
| SoyBase (trait-specific –; 42,195 SNPs) |
BiMSGP | 691M | 462 min | 4.9 ms |
| DeepGS | 21.6M | 9 min | 0.5 ms | |
| DNNGP | 346M | 37–43 min | 0.6 ms | |
| SoyDNGP | 18.4M | 80 min | 3 ms | |
| GBLUP | – | 6–7 s/fold | ≈4 ms |
References
- Meuwissen, T.H.E.; Hayes, B.J.; Goddard, M.E. Prediction of Total Genetic Value Using Genome-Wide Dense Marker Maps. Genetics 2001, 157, 1819–1829. Available online: https://academic.oup.com/genetics/article-pdf/157/4/1819/42032331/genetics1819.pdf. [CrossRef] [PubMed]
- Jannink, J.L.; Lorenz, A.J.; Iwata, H. Genomic selection in plant breeding: From theory to practice. Brief. Funct. Genom. 2010, 9, 166–177. [Google Scholar] [CrossRef] [PubMed]
- Desta, Z.A.; Ortiz, R. Genomic selection: Genome-wide prediction in plant improvement. Trends Plant Sci. 2014, 19, 592–601. [Google Scholar] [CrossRef]
- Crossa, J.; Pérez-Rodríguez, P.; Cuevas, J.; Montesinos-López, O.; Jarquín, D.; de los Campos, G.; Burgueño, J.; González-Camacho, J.M.; Pérez-Elizalde, S.; Beyene, Y.; et al. Genomic Selection in Plant Breeding: Methods, Models, and Perspectives. Trends Plant Sci. 2017, 22, 961–975. [Google Scholar] [CrossRef] [PubMed]
- Bhat, J.A.; Ali, S.; Salgotra, R.K.; Mir, Z.A.; Dutta, S.; Jadon, V.; Tyagi, A.; Mushtaq, M.; Jain, N.; Singh, P.K.; et al. Genomic Selection in the Era of Next Generation Sequencing for Complex Traits in Plant Breeding. Front. Genet. 2016, 7. [Google Scholar] [CrossRef] [PubMed]
- Wang, K.; Abid, M.A.; Rasheed, A.; Crossa, J.; Hearne, S.; Li, H. DNNGP, a deep neural network-based method for genomic prediction using multi-omics data in plants. Mol. Plant Celebrating 15 Years of Publication Special Issue. 2023, 16, 279–293. [Google Scholar] [CrossRef] [PubMed]
- Danilevicz, M.F.; Gill, M.; Anderson, R.; Batley, J.; Bennamoun, M.; Bayer, P.E.; Edwards, D. Plant Genotype to Phenotype Prediction Using Machine Learning. Front. Genet. 2022, 13. [Google Scholar] [CrossRef] [PubMed]
- Grinberg, N.F.; Orhobor, O.I.; King, R.D. An Evaluation of Machine-learning for Predicting Phenotype: Studies in Yeast, Rice, and Wheat. bioRxiv. 2018. Available online: https://www.biorxiv.org/content/early/2018/03/22/105528.full.pdf. [CrossRef]
- Azodi, C.B.; Bolger, E.; McCarren, A.; Roantree, M.; de los Campos, G.; Shiu, S.H. Benchmarking Parametric and Machine Learning Models for Genomic Prediction of Complex Traits. G3 Genes Genomes Genet. 2019, 9, 3691–3702. [Google Scholar] [CrossRef] [PubMed]
- Uffelmann, E.; Huang, Q.Q.; Munung, N.S.; de Vries, J.; Okada, Y.; Martin, A.R.; Martin, H.C.; Lappalainen, T.; Posthuma, D. Genome-wide association studies. Nat. Rev. Methods Primers 2021, 1, 59. [Google Scholar] [CrossRef]
- VanRaden, P. Efficient Methods to Compute Genomic Predictions. J. Dairy Sci. 2008, 91, 4414–4423. [Google Scholar] [CrossRef] [PubMed]
- Clark, S.A.; van der Werf, J. Genomic Best Linear Unbiased Prediction (gBLUP) for the Estimation of Genomic Breeding Values. In Genome-Wide Association Studies and Genomic Prediction; Humana Press: Totowa, NJ, 2013; pp. 321–330. [Google Scholar] [CrossRef] [PubMed]
- Endelman, J.B. Ridge Regression and Other Kernels for Genomic Selection with R Package rrBLUP. Plant Genome 2011, 4. Available online: https://acsess.onlinelibrary.wiley.com/doi/pdf/10.3835/plantgenome2011.08.0024. [CrossRef]
- van Eeuwijk, F.A.; Bink, M.C.; Chenu, K.; Chapman, S.C. Detection and use of QTL for complex traits in multiple environments. Curr. Opin. Plant Biol. 2010, 13, 193–205. [Google Scholar] [CrossRef] [PubMed]
- Poland, J.; Rutkoski, J. Advances and Challenges in Genomic Selection for Disease Resistance. Annu. Rev. Phytopathol. 2016, 54, 79–98. [Google Scholar] [CrossRef]
- Bellot, P.; de los Campos, G.; Pérez-Enciso, M. Can Deep Learning Improve Genomic Prediction of Complex Human Traits? Genetics 2018, 210, 809–819. [Google Scholar] [CrossRef] [PubMed]
- Pérez-Enciso, M.; Zingaretti, L.M. A Guide on Deep Learning for Complex Trait Genomic Prediction. Genes 2019, 10, 553. [Google Scholar] [CrossRef] [PubMed]
- Ma, W.; Qiu, Z.; Song, J.; Li, J.; Cheng, Q.; Zhai, J.; Ma, C. A deep convolutional neural network approach for predicting phenotypes from genotypes. Planta 2018, 248, 1307–1318. [Google Scholar] [CrossRef] [PubMed]
- Liu, Y.; Wang, D.; He, F.; Wang, J.; Joshi, T.; Xu, D. Phenotype Prediction and Genome-Wide Association Study Using Deep Convolutional Neural Network of Soybean. Front. Genet. 2019, 10. [Google Scholar] [CrossRef] [PubMed]
- Gao, P.; Zhao, H.; Luo, Z.; Lin, Y.; Feng, W.; Li, Y.; Kong, F.; Li, X.; Fang, C.; Wang, X. SoyDNGP: A web-accessible deep learning framework for genomic prediction in soybean breeding. Brief. Bioinform. 2023, 24, bbad349. [Google Scholar] [CrossRef] [PubMed]
- Ma, X.; Wang, H.; Wu, S.; Han, B.; Cui, D.; Liu, J.; Zhang, Q.; Xia, X.; Song, P.; Tang, C.; et al. DeepCCR: Large-scale genomics-based deep learning method for improving rice breeding. Plant Biotechnol. J. 2024, 22, 2691–2693. Available online: https://onlinelibrary.wiley.com/doi/pdf/10.1111/pbi.14384. [CrossRef]
- Quang, D.; Xie, X. DanQ: A hybrid convolutional and recurrent deep neural network for quantifying the function of DNA sequences. Nucleic Acids Res. 2016, 44, e107–e107. Available online: https://academic.oup.com/nar/article-pdf/44/11/e107/19695521/gkw226.pdf. [CrossRef] [PubMed]
- Avsec, Ž.; Agarwal, V.; Visentin, D.; Ledsam, J.R.; Grabska-Barwinska, A.; Taylor, K.R.; Assael, Y.; Jumper, J.; Kohli, P.; Kelley, D.R. Effective gene expression prediction from sequence by integrating long-range interactions. bioRxiv. 2021. Available online: https://www.biorxiv.org/content/early/2021/04/08/2021.04.07.438649.full.pdf. [CrossRef]
- Ji, Y.; Zhou, Z.; Liu, H.; Davuluri, R.V. DNABERT: Pre-Trained Bidirectional Encoder Representations from Transformers Model for DNA-Language in Genome. Bioinformatics 2021, 37, 2112–2120. [Google Scholar] [CrossRef] [PubMed]
- Gu, A.; Dao, T.; Ermon, S.; Rudra, A.; Re, C. HiPPO: Recurrent Memory with Optimal Polynomial Projections, 2020. arXiv arXiv:cs.LG/2008.07669.
- Gu, A.; Goel, K.; Ré, C. Efficiently Modeling Long Sequences with Structured State Spaces, 2022. arXiv arXiv:cs.LG/2111.00396.
- Gu, A.; Dao, T. Mamba: Linear-Time Sequence Modeling with Selective State Spaces. arXiv 2024, arXiv:cs.LG/2312.00752. [Google Scholar]
- Dao, T.; Gu, A. Transformers are SSMs: Generalized Models and Efficient Algorithms Through Structured State Space Duality. arXiv 2024, arXiv:cs.LG/2405.21060. [Google Scholar]
- Crossa, J.; Campos, G.d.l.; Pérez, P.; Gianola, D.; Burgueño, J.; Araus, J.L.; Makumbi, D.; Singh, R.P.; Dreisigacker, S.; Yan, J.; et al. Prediction of Genetic Values of Quantitative Traits in Plant Breeding Using Pedigree and Molecular Markers. Genetics 2010, 186, 713–724. [Google Scholar] [CrossRef] [PubMed]
- Crossa, J.; Jarquín, D.; Franco, J.; Pérez-Rodríguez, P.; Burgueño, J.; Saint-Pierre, C.; Vikram, P.; Sansaloni, C.; Petroli, C.; Akdemir, D.; et al. Genomic Prediction of Gene Bank Wheat Landraces. G3 Genes Genomes Genet. 2016, 6, 1819–1834. [Google Scholar] [CrossRef] [PubMed]
- Grant, D.; Nelson, R.T.; Cannon, S.B.; Shoemaker, R.C. SoyBase, the USDA-ARS soybean genetics and genomics database. Nucleic Acids Res. 2010, 38, D843–D846. [Google Scholar] [CrossRef] [PubMed]
- Murcray, C.E.; Lewinger, J.P.; Conti, D.V.; Thomas, D.C.; Gauderman, W.J. Sample size requirements to detect gene-environment interactions in genome-wide association studies. Genet. Epidemiol. 2011, 35, 201–210. Available online: https://onlinelibrary.wiley.com/doi/pdf/10.1002/gepi.20569. [CrossRef]
Figure 1.
Bidirectional Mamba-based architecture of the proposed BiMSGP model. (A) High-level view showing the bidirectional design with embedding and decoder. (B) Detailed implementation including the embedding layer, forward and backward Mamba stacks, feature concatenation, and decoder head. The input is an abstract one-dimensional marker sequence in source-file column order; chromosome boundaries are not shown and inter-chromosome (or otherwise unsorted) junctions are serialization artifacts rather than biological adjacency.
Figure 1.
Bidirectional Mamba-based architecture of the proposed BiMSGP model. (A) High-level view showing the bidirectional design with embedding and decoder. (B) Detailed implementation including the embedding layer, forward and backward Mamba stacks, feature concatenation, and decoder head. The input is an abstract one-dimensional marker sequence in source-file column order; chromosome boundaries are not shown and inter-chromosome (or otherwise unsorted) junctions are serialization artifacts rather than biological adjacency.
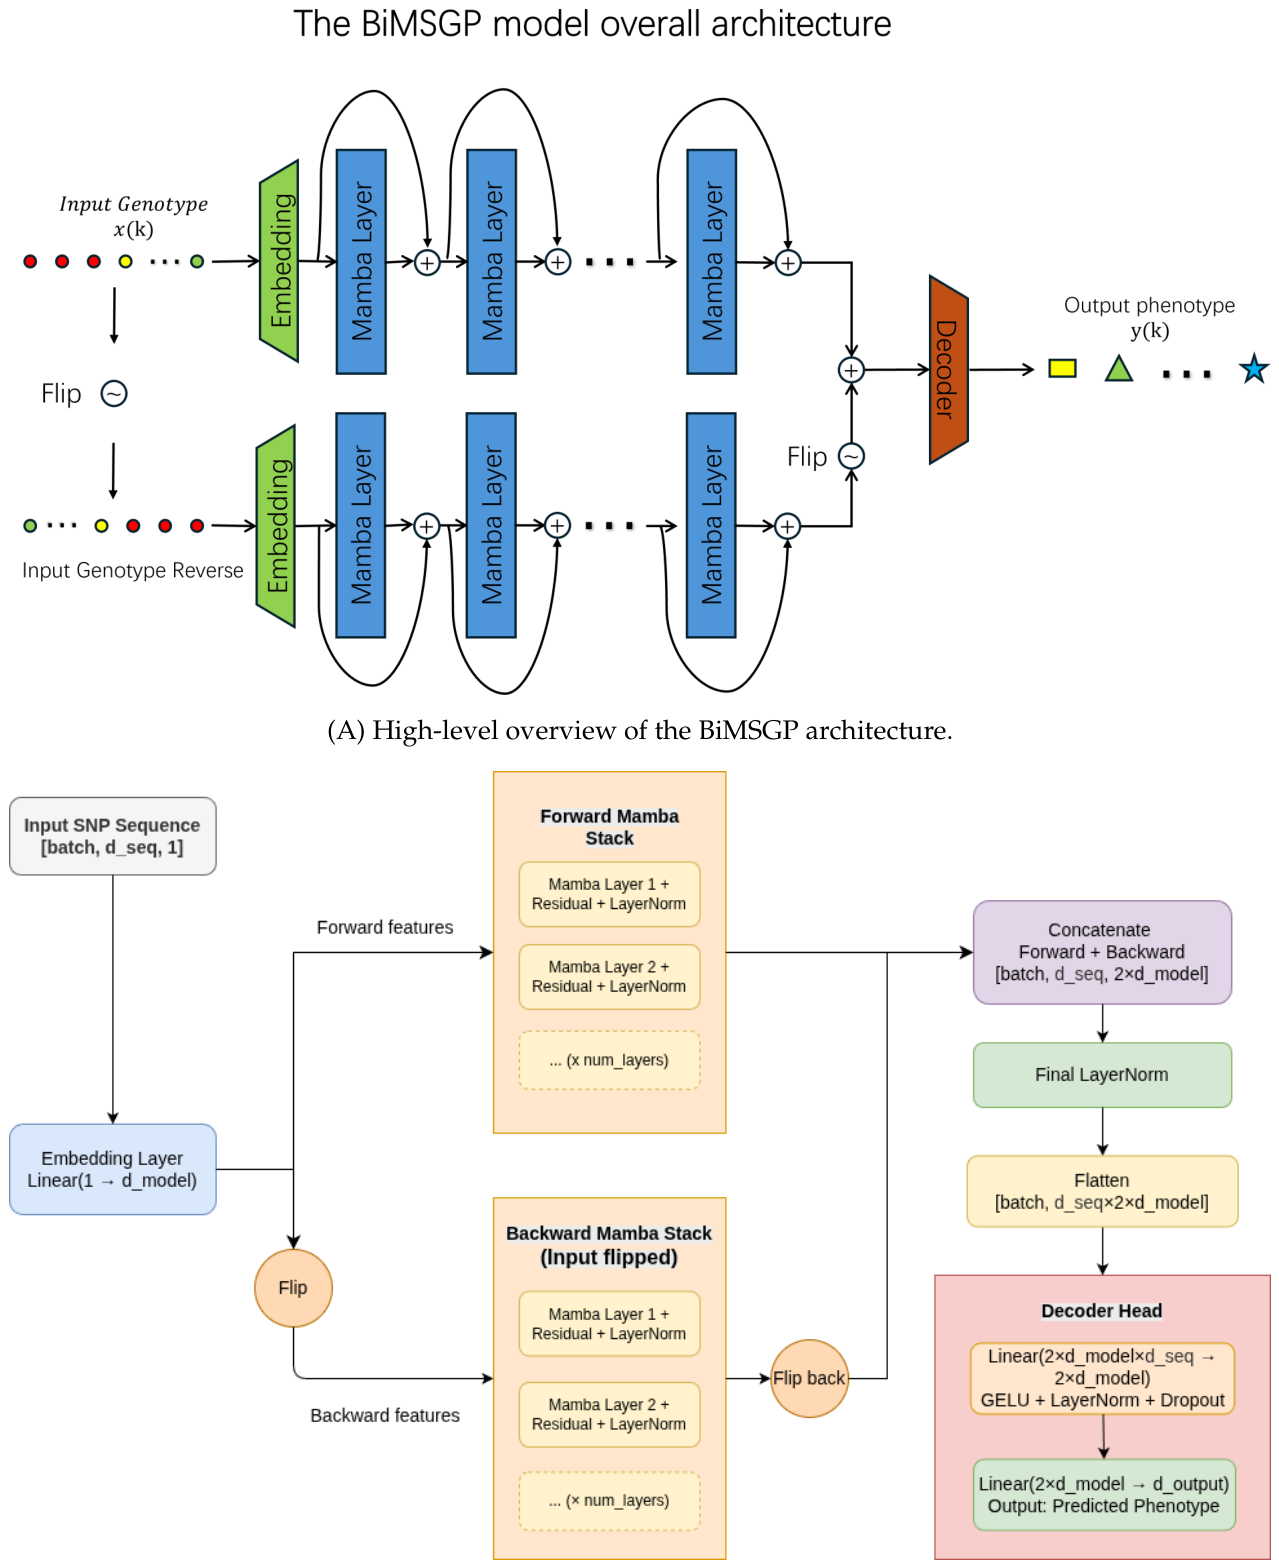
Figure 2.
Predictive performance (Pearson correlation coefficient) of BiMSGP and four baseline methods on the Wheat599 dataset across four environments. Bars show mean PCC over 10 folds; numerical rank is not equivalent to statistical significance.
Figure 2.
Predictive performance (Pearson correlation coefficient) of BiMSGP and four baseline methods on the Wheat599 dataset across four environments. Bars show mean PCC over 10 folds; numerical rank is not equivalent to statistical significance.
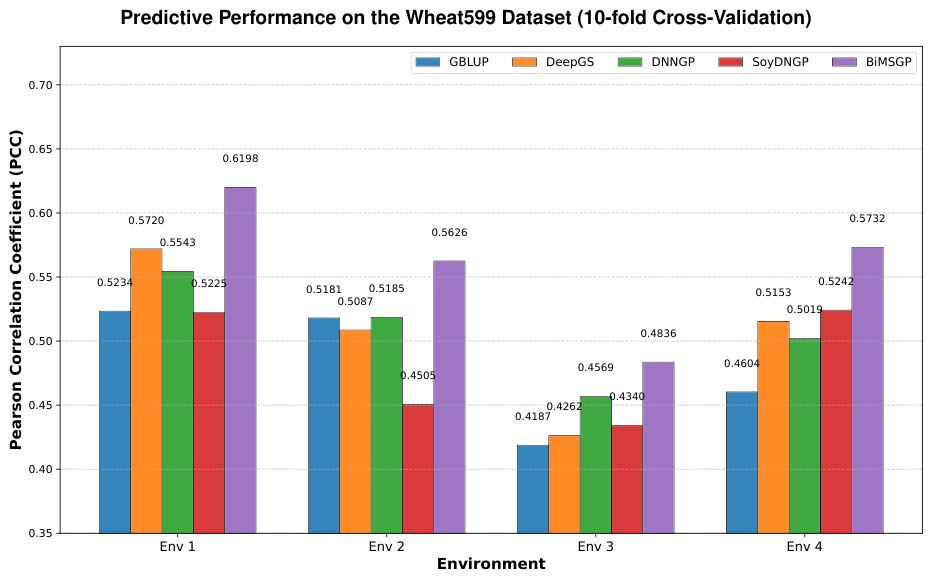
Figure 3.
Predictive performance (PCC) of different methods on the Wheat2000 dataset across eight agronomic traits. Bars show mean PCC over 10 folds; numerical rank is not equivalent to statistical significance.
Figure 3.
Predictive performance (PCC) of different methods on the Wheat2000 dataset across eight agronomic traits. Bars show mean PCC over 10 folds; numerical rank is not equivalent to statistical significance.
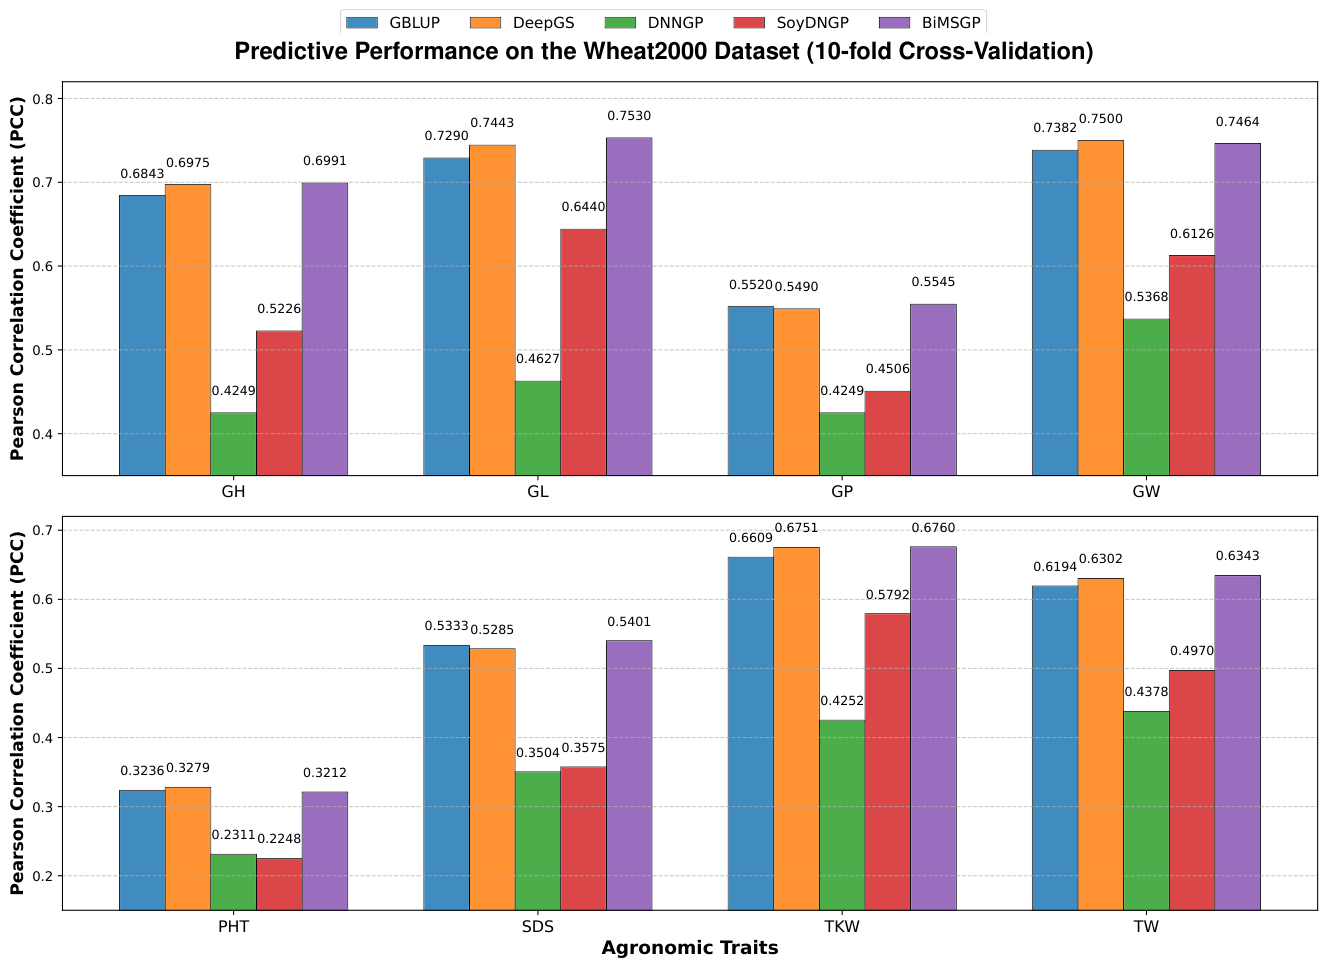
Figure 4.
Predictive performance (PCC) of different methods on soybean quantitative traits using 10-fold cross-validation. The figure is split into top four traits (upper panel) and bottom three traits (lower panel). Bars show mean PCC over 10 folds; numerical rank is not equivalent to statistical significance.
Figure 4.
Predictive performance (PCC) of different methods on soybean quantitative traits using 10-fold cross-validation. The figure is split into top four traits (upper panel) and bottom three traits (lower panel). Bars show mean PCC over 10 folds; numerical rank is not equivalent to statistical significance.
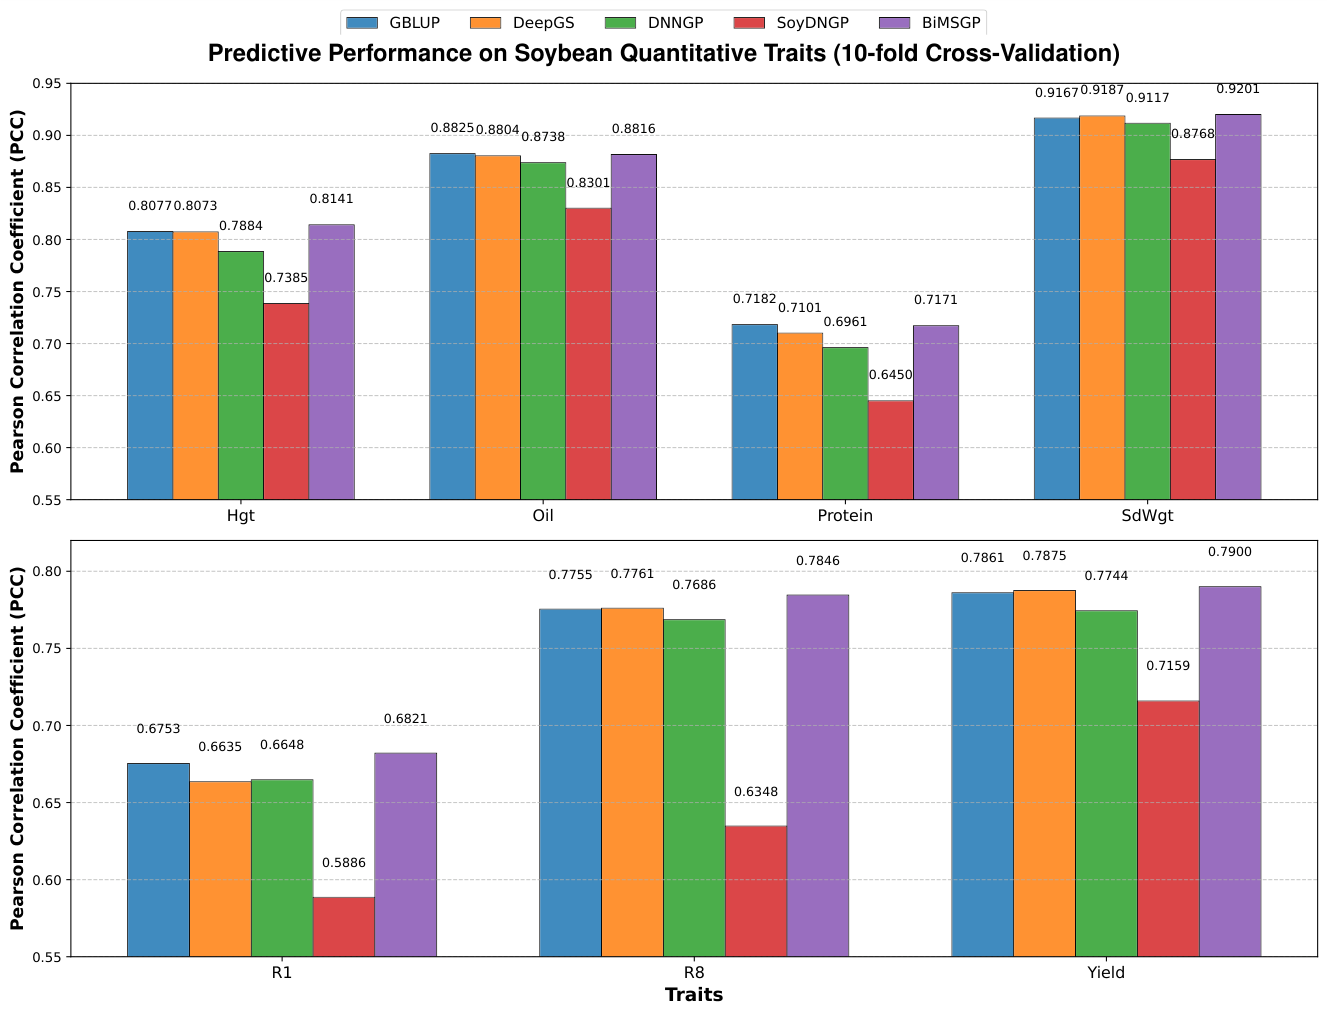
Figure 5.
Balanced accuracy of different methods on soybean categorical traits using 10-fold cross-validation. Bars show mean balanced accuracy over 10 folds; numerical rank is not equivalent to statistical significance.
Figure 5.
Balanced accuracy of different methods on soybean categorical traits using 10-fold cross-validation. Bars show mean balanced accuracy over 10 folds; numerical rank is not equivalent to statistical significance.
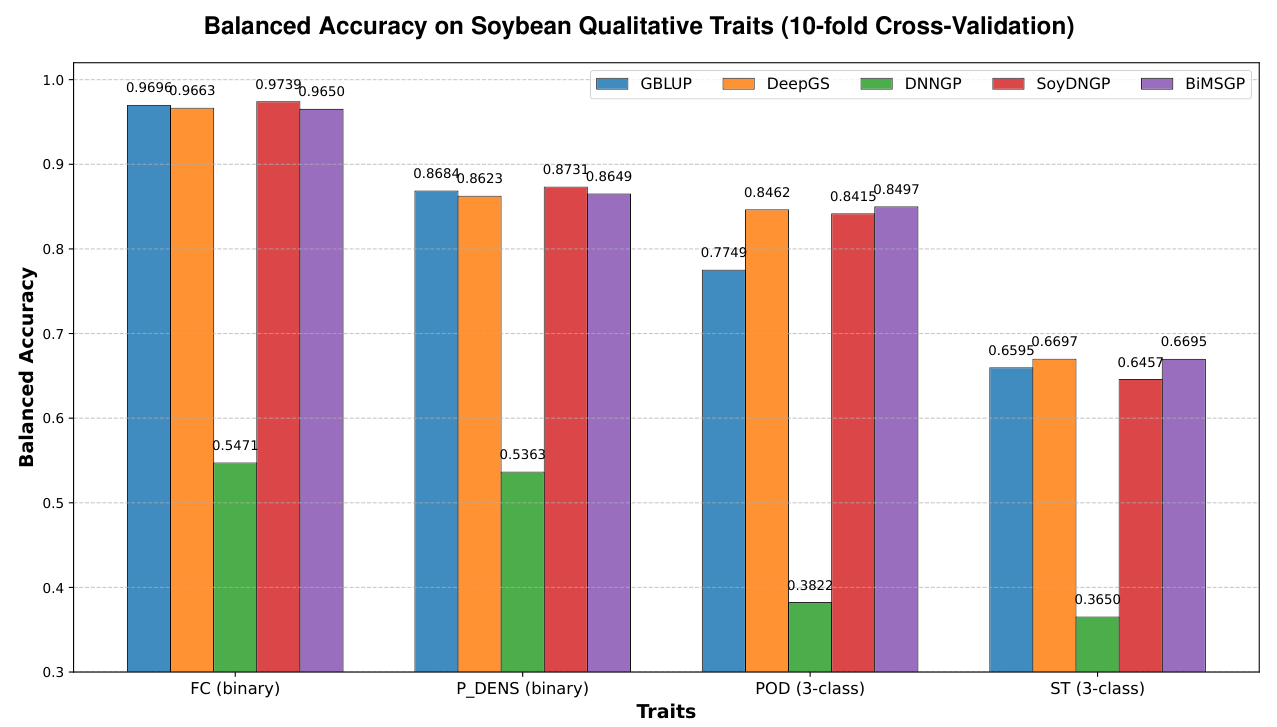
Table 1.
Summary of the datasets used in this study. SoyBase n is the trait-specific complete-case count among 15,878 genotyped accessions in the processed 42,195-SNP matrix, not the 13,784 × 32,032 panel of Gao et al. Categorical class counts are in Table 2.
Table 1.
Summary of the datasets used in this study. SoyBase n is the trait-specific complete-case count among 15,878 genotyped accessions in the processed 42,195-SNP matrix, not the 13,784 × 32,032 panel of Gao et al. Categorical class counts are in Table 2.
| ID | Name | Sample Size | Markers | Traits | Marker Type |
|---|---|---|---|---|---|
| 1 | Wheat599 | 599 | 1,279 | GY (Env1, Env2, Env3, Env4) | DArT |
| 2 | Wheat2000 | 2,000 | 33,709 | GL, GW, GH, TKW, TW, SDS, GP, PHT | DArT |
| 3 | SoyBase | 14,485–15,878 | 42,195 | Categorical: FC, P_DENS, POD, ST | SNP |
| Quantitative: Hgt, Oil, Protein, SdWgt, R1, R8, Yield |
Table 2.
Class counts for SoyBase categorical traits after excluding accessions with missing labels. Proportions are within each trait.
Table 2.
Class counts for SoyBase categorical traits after excluding accessions with missing labels. Proportions are within each trait.
| Trait | Classes | n | Class counts | Majority (%) |
|---|---|---|---|---|
| FC | W / P (binary) | 15,731 | W: 4,844; P: 10,887 | 69.2 |
| P_DENS | Ssp / N (binary) | 15,697 | Ssp: 5,720; N: 9,977 | 63.6 |
| POD | Tn / Br / Bl (3-class) | 15,490 | Tn: 3,863; Br: 9,821; Bl: 1,806 | 63.4 |
| ST | N / S / D (3-class) | 15,164 | N: 5,907; S: 1,225; D: 8,032 | 53.0 |
Table 3.
Predictive performance on the Wheat599 dataset across four environments. Values are mean PCC ± standard deviation (SD), with RMSE ± SD shown below, over 10-fold cross-validation. Boldface marks the numerically highest mean PCC and lowest mean RMSE; it does not imply statistical significance (Table ). Full BiMSGP settings, including the wide decoder and batch size 8, are in Section 2 (Implementation Details). PCC values are shown in normal font (top), while RMSE values are shown in smaller font (bottom) in each cell.
Table 3.
Predictive performance on the Wheat599 dataset across four environments. Values are mean PCC ± standard deviation (SD), with RMSE ± SD shown below, over 10-fold cross-validation. Boldface marks the numerically highest mean PCC and lowest mean RMSE; it does not imply statistical significance (Table ). Full BiMSGP settings, including the wide decoder and batch size 8, are in Section 2 (Implementation Details). PCC values are shown in normal font (top), while RMSE values are shown in smaller font (bottom) in each cell.
| Method | Env 1 | Env 2 | Env 3 | Env 4 |
|---|---|---|---|---|
| GBLUP | 0.5234 ± 0.0798 0.8521 ± 0.0419 |
0.5181 ± 0.0746 0.8533 ± 0.0902 |
0.4187 ± 0.0906 0.9076 ± 0.1335 |
0.4604 ± 0.0911 0.8855 ± 0.0960 |
| DeepGS | 0.5720 ± 0.0763 0.8220 ± 0.0668 |
0.5087 ± 0.1145 0.8757 ± 0.0766 |
0.4262 ± 0.0977 0.9306 ± 0.1393 |
0.5153 ± 0.1137 0.8765 ± 0.1242 |
| DNNGP | 0.5543 ± 0.1015 0.8397 ± 0.0641 |
0.5185 ± 0.0897 0.8868 ± 0.0829 |
0.4569 ± 0.0750 0.9265 ± 0.1127 |
0.5019 ± 0.1112 0.9144 ± 0.1060 |
| SoyDNGP | 0.5225 ± 0.1209 0.9927 ± 0.2207 |
0.4505 ± 0.1036 0.9876 ± 0.1200 |
0.4340 ± 0.1143 1.0875 ± 0.4172 |
0.5242 ± 0.0704 0.9315 ± 0.1146 |
| BiMSGP |
0.6198 ± 0.0708 0.8038 ± 0.0591 |
0.5626 ± 0.0834 0.8693 ± 0.0872 |
0.4836 ± 0.0701 0.9456 ± 0.1458 |
0.5732 ± 0.1079 0.8485 ± 0.0974 |
Table 4.
Predictive performance on the Wheat2000 dataset for eight agronomic traits. Values are mean PCC ± SD, with RMSE ± SD shown below, over 10-fold cross-validation. Boldface marks numerical rank only (Table ). Full BiMSGP settings, including the wide decoder and batch size 8, are in Section 2 (Implementation Details). PCC values are shown in normal font (top), while RMSE values are shown in smaller font (bottom) in each cell.
Table 4.
Predictive performance on the Wheat2000 dataset for eight agronomic traits. Values are mean PCC ± SD, with RMSE ± SD shown below, over 10-fold cross-validation. Boldface marks numerical rank only (Table ). Full BiMSGP settings, including the wide decoder and batch size 8, are in Section 2 (Implementation Details). PCC values are shown in normal font (top), while RMSE values are shown in smaller font (bottom) in each cell.
| Method | GH | GL | GP | GW |
|---|---|---|---|---|
| GBLUP | 0.6843 ± 0.0398 0.7347 ± 0.0378 |
0.7290 ± 0.0451 0.6888 ± 0.0470 |
0.5520 ± 0.0364 0.8333 ± 0.0352 |
0.7382 ± 0.0377 0.6778 ± 0.0647 |
| DeepGS | 0.6975 ± 0.0416 0.7224 ± 0.0421 |
0.7443 ± 0.0424 0.6728 ± 0.0487 |
0.5490 ± 0.0368 0.8642 ± 0.0905 |
0.7500 ± 0.0331 0.6679 ± 0.0592 |
| DNNGP | 0.4249 ± 0.0658 0.9876 ± 0.0299 |
0.4627 ± 0.0480 0.9902 ± 0.0770 |
0.4249 ± 0.0490 0.9952 ± 0.0358 |
0.5368 ± 0.0635 0.9756 ± 0.0497 |
| SoyDNGP | 0.5226 ± 0.0709 0.8742 ± 0.0456 |
0.6440 ± 0.0494 0.7738 ± 0.0465 |
0.4506 ± 0.0349 0.9179 ± 0.0576 |
0.6126 ± 0.0668 0.8272 ± 0.0736 |
| BiMSGP |
0.6991 ± 0.0420 0.7145 ± 0.0389 |
0.7530 ± 0.0434 0.6563 ± 0.0433 |
0.5545 ± 0.0340 0.8481 ± 0.0547 |
0.7464 ± 0.0384 0.6655 ± 0.0668 |
| Method | PHT | SDS | TKW | TW |
|---|---|---|---|---|
| GBLUP | 0.3236 ± 0.0769 0.9440 ± 0.0527 |
0.5333 ± 0.0411 0.8459 ± 0.0334 |
0.6609 ± 0.0296 0.7544 ± 0.0409 |
0.6194 ± 0.0611 0.7855 ± 0.0436 |
| DeepGS |
0.3279 ± 0.0617 0.9474 ± 0.0473 |
0.5285 ± 0.0435 0.8536 ± 0.0347 |
0.6751 ± 0.0313 0.7400 ± 0.0393 |
0.6302 ± 0.0632 0.7805 ± 0.0457 |
| DNNGP | 0.2311 ± 0.0459 0.9974 ± 0.0627 |
0.3504 ± 0.0599 0.9956 ± 0.0428 |
0.4252 ± 0.0554 0.9911 ± 0.0358 |
0.4378 ± 0.0468 0.9806 ± 0.0543 |
| SoyDNGP | 0.2248 ± 0.0527 0.9901 ± 0.0723 |
0.3575 ± 0.0586 0.9937 ± 0.0987 |
0.5792 ± 0.0590 0.8314 ± 0.0545 |
0.4970 ± 0.0906 0.9344 ± 0.1261 |
| BiMSGP | 0.3212 ± 0.0674 0.9592 ± 0.0502 |
0.5401 ± 0.0353 0.8504 ± 0.0368 |
0.6760 ± 0.0327 0.7476 ± 0.0423 |
0.6343 ± 0.0520 0.7763 ± 0.0389 |
Table 5.
Predictive performance on soybean quantitative traits. Values are mean PCC ± SD, with RMSE ± SD shown below, over 10-fold cross-validation. Boldface marks numerical rank only (Table ). Full BiMSGP settings, including the compact decoder, batch size 32, and oil/R8 for 20 epochs, are in Section 2 (Implementation Details). PCC values are shown in normal font (top), while RMSE values are shown in smaller font (bottom) in each cell.
Table 5.
Predictive performance on soybean quantitative traits. Values are mean PCC ± SD, with RMSE ± SD shown below, over 10-fold cross-validation. Boldface marks numerical rank only (Table ). Full BiMSGP settings, including the compact decoder, batch size 32, and oil/R8 for 20 epochs, are in Section 2 (Implementation Details). PCC values are shown in normal font (top), while RMSE values are shown in smaller font (bottom) in each cell.
| Method | Hgt | Oil | Protein | SdWgt |
|---|---|---|---|---|
| GBLUP | 0.8077 ± 0.0131 17.3797 ± 0.4693 |
0.8825 ± 0.0076 1.2277 ± 0.0218 |
0.7182 ± 0.0105 1.9667 ± 0.0633 |
0.9167 ± 0.0068 2.1764 ± 0.0764 |
| DeepGS | 0.8073 ± 0.0152 17.6109 ± 0.7131 |
0.8804 ± 0.0082 1.2546 ± 0.0337 |
0.7101 ± 0.0100 2.0057 ± 0.0529 |
0.9187 ± 0.0069 2.2147 ± 0.0522 |
| DNNGP | 0.7884 ± 0.0189 18.2717 ± 0.5506 |
0.8738 ± 0.0073 1.2883 ± 0.0287 |
0.6961 ± 0.0122 2.0486 ± 0.0605 |
0.9117 ± 0.0075 2.2663 ± 0.0709 |
| SoyDNGP | 0.7385 ± 0.0187 31.8739 ± 6.3753 |
0.8301 ± 0.0117 7.4110 ± 1.4514 |
0.6450 ± 0.0122 13.2460 ± 2.4886 |
0.8768 ± 0.0071 11.4385 ± 2.1095 |
| BiMSGP |
0.8141 ± 0.0135 17.3879 ± 0.6601 |
0.8816 ± 0.0078 1.2456 ± 0.0236 |
0.7171 ± 0.0107 2.0118 ± 0.0731 |
0.9201 ± 0.0073 2.1498 ± 0.0871 |
| Method | R1 | R8 | Yield |
|---|---|---|---|
| GBLUP | 0.6753 ± 0.0095 45.1964 ± 0.5061 |
0.7755 ± 0.0184 38.2370 ± 1.2049 |
0.7861 ± 0.0127 0.4582 ± 0.0108 |
| DeepGS | 0.6635 ± 0.0254 46.3535 ± 1.4084 |
0.7761 ± 0.0154 38.5956 ± 0.9967 |
0.7875 ± 0.0120 0.4621 ± 0.0149 |
| DNNGP | 0.6648 ± 0.0129 46.1224 ± 0.8387 |
0.7686 ± 0.0151 38.9624 ± 0.8739 |
0.7744 ± 0.0084 0.4738 ± 0.0075 |
| SoyDNGP | 0.5886 ± 0.0180 41.6439 ± 11.2156 |
0.6348 ± 0.2311 38.7465 ± 16.2311 |
0.7159 ± 0.0197 0.6253 ± 0.04853 |
| BiMSGP |
0.6821 ± 0.0114 45.5045 ± 0.9148 |
0.7846 ± 0.0176 37.9279 ± 1.1924 |
0.7900 ± 0.0093 0.4600 ± 0.0090 |
Table 6.
Classification performance on soybean categorical traits. Values are mean accuracy ± SD, with balanced accuracy ± SD shown below, over 10-fold StratifiedKFold cross-validation. Boldface marks numerical rank only. Full BiMSGP settings, including the compact decoder and batch size 1, are in Section 2 (Implementation Details). Accuracy values are shown in normal font (top), while balanced accuracy values are shown in smaller font (bottom) in each cell.
Table 6.
Classification performance on soybean categorical traits. Values are mean accuracy ± SD, with balanced accuracy ± SD shown below, over 10-fold StratifiedKFold cross-validation. Boldface marks numerical rank only. Full BiMSGP settings, including the compact decoder and batch size 1, are in Section 2 (Implementation Details). Accuracy values are shown in normal font (top), while balanced accuracy values are shown in smaller font (bottom) in each cell.
| Method | FC (binary) | P_DENS (binary) | POD (3-class) | ST (3-class) |
|---|---|---|---|---|
| GBLUP | 0.9749 ± 0.0046 0.9696 ± 0.0062 |
0.8815 ± 0.0090 0.8684 ± 0.0095 |
0.8473 ± 0.0079 0.7749 ± 0.0111 |
0.7090 ± 0.0122 0.6595 ± 0.0220 |
| DeepGS | 0.9718 ± 0.0032 0.9663 ± 0.0055 |
0.8732 ± 0.0088 0.8623 ± 0.0128 |
0.8714 ± 0.0088 0.8462 ± 0.0141 |
0.8203 ± 0.0093 0.6697 ± 0.0222 |
| DNNGP | 0.7198 ± 0.0832 0.5471 ± 0.1413 |
0.6575 ± 0.0658 0.5363 ± 0.1089 |
0.6575 ± 0.0707 0.3822 ± 0.1465 |
0.5624 ± 0.0930 0.3650 ± 0.0905 |
| SoyDNGP |
0.9775 ± 0.0033 0.9739 ± 0.0038 |
0.8838 ± 0.0072 0.8731 ± 0.0103 |
0.8904 ± 0.0104 0.8415 ± 0.0162 |
0.7973 ± 0.0131 0.6457 ± 0.0201 |
| BiMSGP | 0.9704 ± 0.0027 0.9650 ± 0.0043 |
0.8755 ± 0.0062 0.8649 ± 0.0077 |
0.8717 ± 0.0063 0.8497 ± 0.0123 |
0.8179 ± 0.0073 0.6695 ± 0.0220 |
Table 7.
Computational cost of different BiMSGP configurations on the Wheat599 dataset. Training time is reported for 100 epochs.
Table 7.
Computational cost of different BiMSGP configurations on the Wheat599 dataset. Training time is reported for 100 epochs.
| Configuration | Parameter count | Training Time (100 epochs) | Inference Time (per sample) |
|---|---|---|---|
| Lightweight Forward Mamba (L=1, d=64) | 21.0M | 0.96 min | 1.89 ms |
| Mamba (L=1, d=64) | 42.0M | 1.22 min | 1.64 ms |
| Mamba (L=2, d=64) | 42.1M | 1.64 min | 1.81 ms |
| Mamba (L=2, d=128) | 168.4M | 3.17 min | 1.86 ms |
| Mamba (L=2, d=256) | 673.1M | 8.28 min | 1.98 ms |
Table 8.
Ablation results for residual connections and number of layers (, ). Values are mean PCC, RMSE, and MAE ± SD over 10-fold cross-validation. The best value for each metric is shown in bold.
Table 8.
Ablation results for residual connections and number of layers (, ). Values are mean PCC, RMSE, and MAE ± SD over 10-fold cross-validation. The best value for each metric is shown in bold.
| Variant | Layers | Residual | Avg. PCC | Avg. RMSE | Avg. MAE |
|---|---|---|---|---|---|
| Mamba (no res) | 1 | No | 0.6387 ± 0.0736 | 0.7783 ± 0.0557 | 0.5978 ± 0.0516 |
| Mamba (no res) | 2 | No | 0.6378 ± 0.0676 | 0.7765 ± 0.0477 | 0.5964 ± 0.0461 |
| Mamba (no res) | 4 | No | 0.6374 ± 0.0651 | 0.7738 ± 0.0620 | 0.6041 ± 0.0479 |
| Mamba (no res) | 10 | No | 0.6321 ± 0.0734 | 0.7938 ± 0.0444 | 0.6144 ± 0.0458 |
| Mamba | 1 | Yes | 0.6191 ± 0.0708 | 0.7921 ± 0.0479 | 0.6076 ± 0.0398 |
| Mamba | 2 | Yes | 0.6295 ± 0.0772 | 0.7865 ± 0.0607 | 0.6027 ± 0.0492 |
| Mamba | 4 | Yes | 0.6271 ± 0.0834 | 0.7995 ± 0.0662 | 0.6131 ± 0.0467 |
| Mamba | 10 | Yes | 0.6259 ± 0.0707 | 0.7962 ± 0.0647 | 0.6133 ± 0.0562 |
Table 9.
Ablation results for model dimension, state dimension, and architectural variants (fixed ). Values include trainable parameters and mean PCC, RMSE, and MAE ± SD over 10-fold cross-validation. The best value for each metric is shown in bold.
Table 9.
Ablation results for model dimension, state dimension, and architectural variants (fixed ). Values include trainable parameters and mean PCC, RMSE, and MAE ± SD over 10-fold cross-validation. The best value for each metric is shown in bold.
| Variant | Parameter count | Avg. PCC | Avg. RMSE | Avg. MAE | ||
|---|---|---|---|---|---|---|
| Mamba | 32 | 64 | 10.6M | 0.6197 ± 0.0774 | 0.7960 ± 0.0560 | 0.6131 ± 0.0441 |
| Mamba | 64 | 64 | 42.1M | 0.6295 ± 0.0772 | 0.7865 ± 0.0607 | 0.6027 ± 0.0492 |
| Mamba | 128 | 64 | 168.4M | 0.6387 ± 0.0835 | 0.7867 ± 0.0760 | 0.6005 ± 0.0543 |
| Mamba | 256 | 64 | 673.1M | 0.6364 ± 0.0663 | 0.7906 ± 0.0754 | 0.6040 ± 0.0493 |
| Mamba | 64 | 16 | 42.1M | 0.6242 ± 0.0829 | 0.7919 ± 0.0616 | 0.6029 ± 0.0506 |
| Mamba | 64 | 32 | 42.1M | 0.6337 ± 0.0665 | 0.7803 ± 0.0479 | 0.5932 ± 0.0314 |
| ForwardMamba | 64 | 64 | 21.1M | 0.6215 ± 0.0742 | 0.8052 ± 0.0652 | 0.6121 ± 0.0420 |
| BackwardMamba | 64 | 64 | 21.1M | 0.6224 ± 0.0767 | 0.7997 ± 0.0528 | 0.6064 ± 0.0400 |
| Mamba (sum) | 64 | 64 | 21.2M | 0.6232 ± 0.0834 | 0.7985 ± 0.0737 | 0.6092 ± 0.0596 |
Table 10.
Computational efficiency comparison on the Wheat599 dataset. Training time is reported for 100 epochs.
Table 10.
Computational efficiency comparison on the Wheat599 dataset. Training time is reported for 100 epochs.
| Model | Parameter count | Training Time (100 epochs) | Inference Time (per sample) |
|---|---|---|---|
| BiMSGP | 42M | 1.52 min | 1.7 ms |
| DeepGS | 81K | 0.40 min | 1.1 ms |
| DNNGP | 10.4M | 0.48 min | 1.3 ms |
| SoyDNGP | 18.1M | 0.80 min | 1.4 ms |
| GBLUP | – | <0.1 s/fold | – |
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (http://creativecommons.org/licenses/by/4.0/).
Copyright: This open access article is published under a Creative Commons CC BY 4.0 license, which permit the free download, distribution, and reuse, provided that the author and preprint are cited in any reuse.