

Submitted:
03 September 2026
Posted:
04 September 2026
You are already at the latest version
Abstract
Driven by the common entropy formalism in statistical physics and information theory here we show that methods developed for the analysis of molecular conformational ensembles may be successfully used for classification. Entropy is estimated using the k-th nearest neighbour method combined with the Maximum Information Spanning Tree method to account for the mutual informations between variables. This formalism is used to classify new samples using their estimated cross-entropy with the training set. The method is tested using diverse datasets and the results obtained are comparable to those obtained by machine learning methods, or better when the number of samples is small. The methods described here have the advantage, compared to other classification methods, of directly linking variables and pairs of variables to the assigned class, a valuable feature when aiming at identifying causative relationships between features and classes (e.g. the relationship between genes and diseases).
Keywords:
entropy
; kth nearest neighbour method
; cross-entropy
; classification
1. Introduction
Statistical physics aims at linking macroscopic properties of matter with the physics of its components. In this process fundamental laws of physics are coupled with the laws of probability to derive macroscopic properties through suitable averages over the degrees of freedom of the entities which constitute the system.
Since its inception, with kinetic theory in the mid-eighteenth century, and later with the work of Boltzmann [1] and Gibbs [2], statistical physics made it possible to describe even the most elusive thermal quantity, entropy, in terms of averages over microscopic coordinates. The direct computation of entropy for molecular system is performed by techniques which use different methods to consider the probability density function (pdf). Such methods may be parametric, based on the expected behaviour of molecules, e.g. treated as a collection of independent harmonic oscillators, or non-parametric. The latter may be straighforwardly used for estimation of entropy for any pdf.
The same formula used by Boltzmann for entropy, save for a multiplicative constant, was independently obtained by Shannon in his mathematical theory of information and, following a suggestion by von Neumann, was also named entropy [3]. The fact that quantities defined in so different contexts and formalisms happen to coincide is far from expected, but also far from being casual. Indeed, the interpretation of entropy as a measure of the average information gained upon knowledge of one symbol of the message is translated immediately into the average information gained upon knowledge of one microstate instead of the macrostate of a system. In other words the macrostate plays the role of the unknown symbol and the microstate plays the role of the specific symbol.
The connection between statistical physics, in particular entropy, and information theory is therefore strongly rooted in the concept of information.
The same concept underpins classification by machine learning (ML), where training, testing and predictions are performed using the consolidated framework of information theory. Since cross-entropy is the criterion by which most often classification is performed in ML it is natural to wonder whether the tools used for entropy calculation in molecular systems can be borrowed and applied to more general classification problems.
The idea is not unheard of, indeed early methodology developments in the field of ML were driven by analogies with physical systems. In many, but not all, cases the statistical properties of such systems were used.
A physical system is represented by generalized coordinates and by interaction energy parameters. Prototypical of the relationship between physical systems and ML are Hopfield networks [4] where the input and output of a ML task are mapped to the states of the network cells, which may assume only two values () and the learning machine is mapped to the set of couplings of a fully connected Ising model. Such physical model starting from any input evolves towards the states it was trained on. If part of the input represents the features and another part represents the output, Hopfield networks are able to perform classification.
Statistical physics was very early applied to a similar model (named "Boltzmann machine") where the strengths of the connections of the Ising model are modified as to obtain for random input the same Boltzmann distribution as for the training set [5]. In the latter scenario the cross-entropy (or Kullback-Leibler divergence) is a measure of how well the network reproduces the input underlying distribution.
The conformational entropy of molecules may be estimated by a variety of methods [6,7], some of which may be used for different problems under reasonable assumptions concerning the data. Here we use non-parametric methods for entropy estimation developed in the fields of statistical sciences [8,9] and molecular sciences [10,11,12] for classification. We consider each label of the data as identifying a macrostate and each unlabelled sample as a microstate of a system. Then, for each sample, we estimate the entropy that would results from the sample being assigned to each possible label. Finally the corresponding minimum entropy label is assigned to the sample.
For the above task we use the methods of kth nearest neighbour entropy (kNNe) estimation and the maximum information spanning tree. The entropy is obviously an ensemble property, but the kNNe method allows to estimate the entropy from each sample.
Compared to ML classification the method has the advantage of being readily intepretable and applicable even when the number of samples is extremely low. The results presented here show that the performance of the method is comparable to more complex approaches like multilayer perceptrons or support vector machines.
2. Results and Discussion
2.1. Analysis of the MNIST Dataset
The discretization of pixel intensities in the MNIST dataset prevents the application of kNNe method because many distances between intensities are 0. For this reason we turn to histogram analysis. It is worth mentioning also that the large number of samples and the low dimensionality (1 and 2) of the spaces considered in the kNNe-MIST analysis make histogramming a much more efficient method to estimate entropy. Therefore, for each of the ten classes (k) of the MNIST dataset the probability distribution function for each pixel (i) was estimated as a histogram with constant probability in each bin j of width :
where
and
The Kullback-Leibler divergence between the probability distribution of the same pixel i in different classes k and l, and was approximated as:
An example of entropy based analysis of the MNIST training set is reported in Figure 1. Information relative to the classes 0 and 1, which are very easy to distinguish, and the two most confounded classes 3 and 8, and 4 and 9. The two left-most panels display the entropy of the pixels obtained from the distribution in the train dataset, for the corresponding classes. The right-most panels display the non-symmetric Kullback-Leibler divergences of the pixels in the two distributions.
In the kNNe classification the pixels showing the highest Kullback-Leibler divergence are those who are the most important for classification.
A simple application of the method achieves 0.850 accuracy. The accuracy is comparable to that obtainable with linear modeling and fitting classes as one-hot vectors (0.860). The difference with linear modeling is that here cross-entropy is explicitly estimated and provides the criterion for classification. Moreover this is easily extendible, for instance by considering more refined model for the probability density. Indeed, when only pairs of pixels are considered, the mutual information can be estimated by two-dimensional histograms and the entropy estimated by the upper bound provided by the MIST approach. When this is done on the MNIST dataset an accuracy of 0.934 is achieved. Consideration of pairs of features and their mutual information leads therefore to a significant increase of accuracy of 0.084.
In order to check whether the correlations among pixels could be accounted by linear modeling we also used SVD to reduce the dimensionality by projecting the data on the first principal components. The accuracy tends to level off at an accuracy of 0.854 at about 100 components. Therefore, reducing the dimensionality does not improve dramatically the accuracy.
It is also interesting to compare standard kNN classification with kNNe classification on the MNIST dataset to highlight similarities and differences. For this we consider the accuracy of the classification using increasing values of k. For the standard kNN method, the class is assigned based on the most represented class within the first k neighbours. For the kNNe entropy-based classification we estimate the entropy of each sample for each class considering the k-th nearest neighbour in the 784-dimensional space of pixel intensities (the procedure is referred to as JOINT-kNNe). So, for the first nearest neighbour standard kNN and kNNe entropy-based classification produce exactly the same classification. When k increases however the accuracy of standard kNN classification decreases rapidly whereas kNNe entropy-based slightly increases for the first k’s and decreases much slowlier (Figure 2). It is apparent that, notwithstanding the similarities, the two approaches are different. In the case of standard kNN classification the first k nearest neighbours are taken independently of their class, whereas in kNNe entropy-based classification for each class the first k nearest neighbours belonging to that class are considered. For this reason the two approaches essentially coincide for the first nearest neighbour, but they differ for all choices of .
2.2. Analysis of CuMiDa Datasets
2.2.1. Benchmark
CuMiDa datasets provide a good benchmark for the kNNe approach in several respects. First, the datasets contain a small number of samples, sometimes just six samples for class. In such scenario ML methods are prone to overfitting. Second, singling out which genes and which pairs of genes most contribute to classification provides valuable information not available or only indirectly available with ML methods. The genomic analysis of the results is out of the scope of the present work, but we remark that interpretability is a valuable feature of the method proposed here.
To assess the performance of the kNNe classifier, we take advantage of the metrics presented with the data on the CuMiDa website (URL: https://sbcb.inf.ufrgs.br/cumida).
The entropy-based classifier achieves accuracies that are broadly comparable to, and in several cases higher than, those reported for standard machine-learning classifiers such as classical kNN, Multi Layer Perceptron (MLP), Random Forests (RF), and Support Vector machine (SVM).
Since the datasets contain a different number of samples and classes, we found it useful to sort the datasets by the average number of samples per class, in order to check possible trends in the results.
Only 69 out of the 78 datasets from CuMiDa could be used because some contained only one class or had a samples-per-class ratio less than six.
Figure 3 compares the four aforementioned methods with our MIST-kNNe model. The comparison was performed using 80 features, since this dimensionality yielded the best average performance after feature reduction based on ANOVA and Logistic Regression.
The results show that MIST-kNNe achieves higher accuracy than the other methods in most cases, particularly as the number of samples per class decreases. The only consistently competitive method is SVM, which performs slightly better than MIST-kNNe in the leftmost region of the plots, corresponding to datasets with a large number of samples and a limited number of classes.
It should be noted that the accuracy values reported by CuMiDa refer to the application of machine-learning methods without reducing the number of genes. Therefore, the comparison of the reference point with our MIST-kNNe model is also influenced by this methodological difference. As a matter of fact, as discussed in the Feature Dependencies section, dimensionality reduction is an unavoidable step when applying MIST. Indeed, it is particularly evident that when the effective number of training samples per class decreases, namely in the regime where density estimation is intrinsically more difficult and overfitting may more severely affect conventional classifiers, kNNe classification, combined with hybrid-embedded feature selection, is more accurate than standard machine-learning classifiers.
2.2.2. Features Dependencies
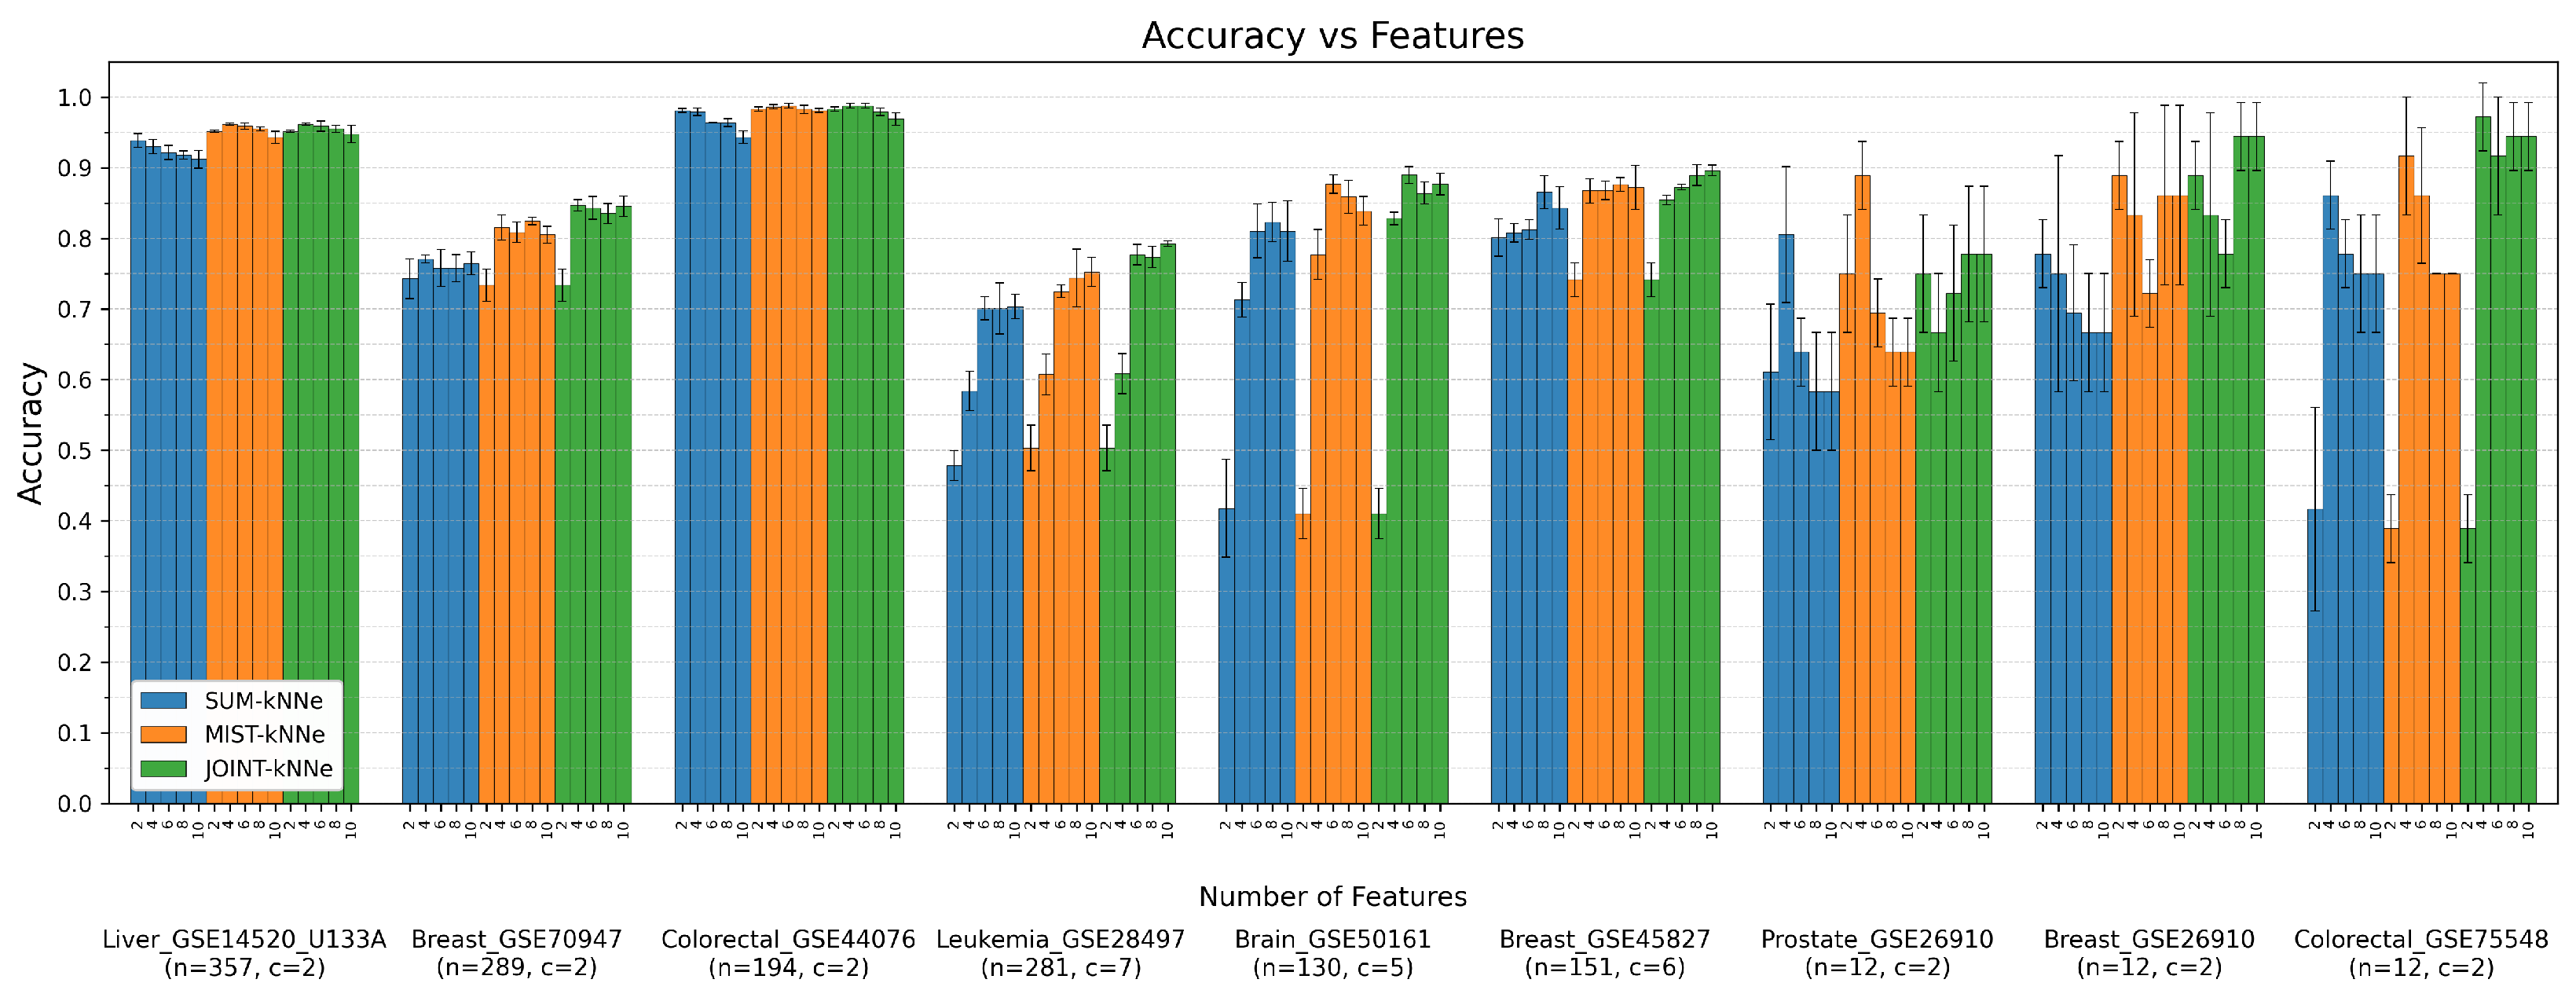
We thoroughly investigated the effect of dimensionality reduction across the 69 datasets. Working directly with tens of thousands of features can be problematic for classical machine-learning methods because of the noise introduced by numerous genes. For proper comparison we therefore tested our method using both the original feature sets and reduced subsets of features. The full-features approach was impractical for the MIST algorithm due to the extremely large matrix required for pairwise MI estimation. Consequently, only the SUM-kNNe and JOINT-kNNe analyzes were performed using the complete feature sets. By contrast, dimensionality reduction allowed us to apply MIST and evaluate its performance as the number of retained features increased from 20 to 100.
To provide a clear graphical representation of these results (Figure 4), we selected a representative subset of nine datasets according to three criteria: three datasets with a large number of samples and only two classes, three datasets with a large number of samples and multiple classes, and three datasets with a limited number of samples. The complete CSV file containing the results for all 69 datasets is available in the supplementary materials.
In multiclass datasets such as Leukemia GSE28497 and Brain GSE50161, MIST-kNNe and JOINT-kNNe systematically improve over the purely marginal SUM-kNNe estimate, reaching accuracies of up to and , respectively. By contrast, on the same datasets, SUM-kNNe achieves lower accuracy and is more sensitive to the number of selected features. The dependence on dimensionality appears to be dataset-specific. In some cases, such as Breast GSE45827, increasing the number of selected features improves the classification accuracy of SUM-kNNe, even beyond that achieved by MIST-kNNe. However, more often, using more than 40 features degrades the performance of SUM-kNNe. This suggests that non-informative or redundant variables can introduce noise unless feature dependencies are explicitly taken into account. The MIST protocol often mitigates this effect by incorporating pairwise mutual-information terms. However, the improvement over SUM-kNNe is not universal, indicating that the relevance of gene-gene dependencies varies substantially across datasets, even under the same feature-selection procedure.
Looking at the last bar of each SUM-kNNe and JOINT-kNNe analysis, representing the complete set of features, it is apparent that the first three datasets can be well classified despite the inclusion of noisy features, which only slightly lowered the accuracy compared to the reduced feature sets. By contrast, when the number of classes increases or the number of samples decreases, the impact of the noise makes the accuracy drop by several percent points, particularly in the SUM-kNNe approach, except for Breast GSE45827.
We analyzed the same group of datasets using Random Forests, instead of ANOVA, pre-filtering followed by Logistic Regression for feature selection. The accuracy achieved was highly comparable to that of the previous approach; however, the computational cost increased substantially, particularly when using 10,000 trees. Consequently, we opted not to pursue this method further.
Despite the initial premise regarding the use of feature extraction (versus feature selection) on tumor gene expression datasets, we nevertheless decided to test its effectiveness. The graph in Figure 5 shows the results of the analyses performed on the same group of datasets also used with feature selection. The first evident aspect is the different range of features used. With SVD, having more than 10 components led to a drastic drop in accuracy, whereas varying the number of components in a range between 2 and 10 yielded results at least comparable to those obtained with ANOVA + Logistic Regression. Comparing Figure 4 and Figure 5, it can be seen that, on average, the accuracy level achieved with feature extraction is lower than that achieved with feature selection. On the datasets with many samples and only 2 classes, this difference is not too marked, whereas as the number of classes increases and the number of samples decreases, the performance drops significantly, both in terms of accuracy and mean error, in some cases becoming even worse than the full-features approach.It must be said, however, that SVD provides an advantage in terms of computational speed, mainly due to the low complexity of obtaining the matrix factorization and the use of a number of features an order of magnitude lower than that required by feature selection.
JOINT-kNNe is frequently the best-performing protocol. This result was not obvious a priori, since JOINT-kNNe could have been expected to suffer more severely from the curse of dimensionality, with distances increasing relevantly as the number of features grows. Nevertheless, this gain comes at the cost of reduced interpretability. In contrast, MIST-kNNe provides a sparse representation of the dominant mutual-information links between genes, an aspect that is particularly relevant in oncological applications, where both predictive accuracy and biological interpretability must be considered.
3. Materials and Methods
3.1. Entropy Estimation
We assume samples x of a mutivariate variable X are randomly drawn by M sources (classes) with probability density functions , and probabilities , respectively. We refer to the general distribution as .
The entropy of the distribution is [13]:
where is the entropy due to class distribution and is the entropy of the distribution of samples in class m.
We consider now the estimation of entropy from n samples. This is expressed as an average over the samples. The entropy term is estimated by the standard formula using Miller-Madow correction [14]:
The entropy terms are estimated using the k-th nearest neighbour method [8,9,12]:
where is the volume of a ball with radius equal to the distance of the k-th nearest neighbour of class m from the i-th sample in class m.
Classification amounts to assigning (deterministically or not) to a new sample x the class l, which may be different from its true class, say t.
The rule by which classification, based on training examples, is performed, establishes a distribution which will be in general different from the true (unknown) distribution .
The sum of Equations 12 and 10 provide, as shown above, an unbiased estimator of the quantity , which is in general different from the entropy of the true and estimated distribution and , but also from the entropy of the distribution because samples are drawn from the true distribution , as indicated by the subscript at the average brackets. The distributions and are actually the same when the classifier assigns to each sample x the class m with the same probability.
The expected change in the estimated entropy, with respect to the unknown true entropy, estimated by Equations 10 and 12 is given by:
The last line is the Kullback Leibler distance between the probability distributions and , which is greater than zero by the Information Theorem, i.e.:
with the equal sign holding if and only if [13].
The latter inequality provides a criterion to assign the class to a new sample, by choosing the class providing the smaller positive change in the estimated entropy.
The reference is estimated using Equations 10 and 12. Since is equal for all possible class assignments we just need to choose the assignment l which minimizes the entropy estimate associated with the new sample, i.e.:
For the sake of completeness it should be noted that assigning a new sample to class l would also result in a change of the estimate of the entropy based on the sole training set. Using Equation 16 is however extremely convenient because neighbours of the train samples are not recomputed. No sizable difference was observed in our tests using Equation 16 compared to recalculating nearest neigbours for the training set.
Throughout this paper we will refer to kNN entropy-based classification as to kNNe classification.
For multidimensional spaces kNNe may be applied under the approximation that all variables are independent and therefore the entropy is just the sum of each variable pdf entropy, which is referred to as SUM-kNNe. Alternatively, we refer to JOINT-kNNe when considering the euclidean distances in the multidimensional space.
3.2. Maximum Information Spanning Tree
In high dimensional spaces the kNNe method, as described above, faces the problem that the distances on which the method is based on, result from the combination of informative and much less informative variables. For this reason the straightforward application of the method, which we named JOINT-kNNe may be inappropriate. For this reason other approximate ways to estimate the entropy of multivariate pdfs have been proposed. In the field of molecular conformational ensembles two main approaches based on mutual information have been used: (i) a mutual information expansion (MIE), truncated at pairwise mutual informations, which has demonstrated its potential for torsional variables [15,16,17], but suffers from quadratic growth of terms, many of which are just adding noise; and (ii) the maximum information spanning tree (MIST) method, proposed by Tidor and collaborators [18,19], which also accounts for mutual information between variables. The MIST approach considers pairwise mutual information and constructs a tree corresponding to a chain of conditional entropies, yielding the lowest upper bound on the entropy that can be obtained from mutual information involving at most two variables. In the approach for an n-dimensional space, only mutual informations are taken into consideration. This approach has also been extended to group variables and evaluate the mutual information between pairs of groups [20]. The entropy-based classification method using the kNN method to estimate univariate entropies and pairwise mutual information is referred to as MIST-kNNe.
3.3. Choice of the Neighbourhood
The choice of k is crucial as it effectively represents the only tunable parameter in the k-th nearest neighbour entropy estimation. It is well known that choosing a small value of k provides stronger support for the assumption that the density of neighbours is uniform within the hyper-sphere (or ball) volume. On the other hand, this choice leads to greater variance of the entropy estimate. [12].
An alternative is to choose a larger value of k. In this case, the entropy estimates obtained for different points of the distribution tend to become more uniform, due to reduced variance. However, this introduces a bias, since the distribution within the ball with large radius may not be homogeneous, thus reducing the validity of the underlying assumption. Moreover rendering uniform a non-uniform density results in larger entropy.
To mitigate the above issue, we adopted an intermediate approach: entropy was estimated for several values of k (from 1 to 5), and the median of the resulting estimates was then used, in order to limit the influence of possible outliers.
3.4. Datasets
3.4.1. Randomized MNIST
Since its original assembly by LeCun et al. [21] the MNIST dataset has become a standard benchmark for testing ML classification algorithms. The dataset consists of 60000 28x28 pixel images representing hand-written digits, converted to arrays of 784 integers in the range 0 to 255. If the indices of the pixels are randomized the correlations among the pixels cannot be derived by their indices anymore. Algorithms specific for images, like rotations, distortions, convolutions, etc. cannot be applied in a straightforward way on the randomized MNIST dataset, and we are left with the more general problem of classifying a set of 784-integer arrays into one of ten classes. The choice of randomizing the array components’ indices adopted in the present work, stems from the requirement to test a general and not image-specific classification method, thus not using knowledge that the arrays represent images. On the other hand reordering the indices allows for easy visualization of the contributions of single pixel to classification of digits or their diasmbiguation.
The set is characterized by a limited number of features, i.e. the 784 pixels, and by a large number of training examples (60000) and a moderate set of classes (10).
Also it is worth noting that there are always many pixels contributing information able to discriminate among different classes, i.e. whose probability distributions differ significantly between different classes.
For the same set a large number of classifiers has been tested and results are reported in the original paper by LeCun et al. [21].
3.4.2. CuMiDa
The Curated Microarray Database (CuMiDa) [22] is a database of 78 hand-curated microarray data sets selected from more than 30,000 microarray experiments from the Gene Expression Omnibus [23]. The sets were selected for different cancer subtypes of colorectal, gastric, pancreatic, liver, bladder, lung, throat, renal, brain, prostate, ovary, leukemia, and breast cancers. The experiment were chosen in such a way that no interference (e.g. by drugs, miRNA, siRNA, engineered mutations, etc.) with the expression levels of the cells was performed during the experiments and that at least six samples were present in the set.
The work describing CuMiDa reports further details and classification accuracies obtained by different classifiers, which are used in the present work for comparison with the methods presented in this work [22].
3.5. System Dimensionality Reduction
General classification tasks pose a significant challenge because datasets may contain a small number of samples versus a massive number of features. Many of the features may be irrelevant or redundant and their consideration into algorithms may result in overfitting or noise addition. For these reasons, besides the ensuing reduction in computational cost, the reduction of system dimensionality is typically performed as a pre-processing step in classification pipelines.
The ways to achieve this tasks are subject of a wide research area. Here, we use feature extraction by projecting over the first principal components, and feature selection ranging from the simple between-class variance method to more accurate Random Forests (RF), followed by Logistic Regression in order to obtain hybrid-embedded filter methods. The latter methods are also used as classification methods, but here they are used only for feature selection.
The implemented pipeline within the main execution script evaluates these classification algorithms using a Stratified K-Fold cross-validation as implemented in the python software Scikit-learn [24]. To prevent data leakage, feature selection is performed using exclusively the training data during each fold before proceeding to classification of the test set cases.
3.5.1. Feature Reduction
- SVD
Singular Value Decomposition [25] was used as a feature extraction method to project the original data onto a lower-dimensional space. Given a centered data matrix , containing n samples and p features, its reduced SVD can be written as
where and have orthonormal columns, , and contains the singular values ordered as .
For centered data, the connection with Principal Component Analysis (PCA) follows from
so that the columns of V are the principal directions and the variance associated with component i is . The fraction of the total variance accounted for by the first components is therefore
Dimensionality reduction was performed by retaining the first right singular vectors and projecting the samples as
Within each cross-validation fold, centering and SVD were determined exclusively from the training data, and the corresponding transformation was subsequently applied to the test data, thus preventing data leakage.
Although SVD efficiently reduces the dimensionality of high-dimensional data, each resulting component is a linear combination of the original features and therefore does not retain a direct correspondence with individual variables. For this reason, here feature selection was generally preferred for the CuMiDa datasets. Retaining the original variables allows the information relevant for classification to be associated directly with individual genes and, in the MIST analysis, with specific pairs of genes, thus preserving the biological interpretability of marginal and pairwise contributions.
3.5.2. Feature Selection
- ANOVA
Analysis of variance (ANOVA) [26] was used as a univariate filter to rank the original features according to their ability to discriminate among the classes. For each feature j, the mean value within each class c was compared with the global mean . The between-class and within-class sums of squares were computed as
where is the number of samples in class c. The final score assigned to feature j was the standard one-way ANOVA F-score,
Features with larger values were considered more informative, since they display large separation between class means compared to the dispersion within each class. The features were ranked by decreasing , and the first features were retained for the subsequent entropy-based classification step. The ranking was computed independently within each training fold, before retaining the same selected feature subset to the corresponding test fold.
- Random Forests
For Random Forests (RF) [27] the columns in the train dataset are randomly resampled to provide a large number (we tested 1000 or 10000) of different datasets on each of which a decision tree is built. The split at each decision tree is performed taking randomly into account only a subset of features (we used the square root of the total number of samples). The criterion employed to choose the splitting feature and the splitting threshold is the class entropy of the feature, i.e. for feature j:
where
For each chosen feature the optimal threshold for splitting is found and the feature and threshold leading to the largest reduction () in entropy between the parent node and the nodes resulting from splitting is chosen, i.e.:
Note that at the descending nodes the entropy is weigthed by the fraction of samples at the node.
Features are finally ranked by importance by summing the normalized decrease in entropy at all nodes using each feature. The decrease in entropy represents the information gain at each node. The importance of feature j is computed as:
The features are selected up to a chosen importance threshold in order to retain a fixed number of features.
- Random Forests/ANOVA + Logistic Regression
To power up the feature selection, two hybrid-embedded methods have been included. The initial set of features has been pre-filtered using Random Forests or ANOVA, in order to retain 0.01 of the features. The latter features were further filtered using Logistic regression. Logistic regression [28] is applied using an elastic net regularized with mixing coefficient 0.5. The importance of feature j is finally computed as:
where is the coefficient of the Logistic Regression, in the case when there are only two classes or as:
where c runs over the classes and is the Logistic Regression coefficient of feature j for the binary Logistic Regression where class c is singled out from the other ones.
4. Conclusions
The k-th nearest neighbour method for entropy estimation (kNNe), developed in the context of entropy estimation for molecular conformational ensembles, has been applied to the task of classification. The method enable to estimate the entropy from each sample. The estimated cross-entropy with the pdf of train samples of each class is used to classify test samples.
The results obtained on diverse datasets, with largely different number of samples and classes, show that the method is comparable with ML methods, especially when the number of samples is small, a situation where methdos based on a large number of tunable parameters are expected to be prone to overfitting.
For practical application of the method, in particular the application of MIST, which requires the mutual informations of all pairs of features, it is necessary to reduce the dimensionality of the samples. In the cases considered here a simple ANOVA analysis gave results similar to those obtained using a computationally more intense method like Random Forests. Feature selection and the choice of MIST for taking into account mutual informations, versus other entropy approximation methods, was motivated by the need of highlighting the contribution of relevant features over noisy irrelevant features.
The main advantage of the kNNe method with respect to other classification methods resides in the straightforward theoretically grounded linkage of features with the assigned class, which makes the method useful not only for classifying samples, but also to identify most relevant features (and pairs of features) of the sample. The method is therefore fully interpretable, making it a useful alternative or a complementary tool to esisting ones, for classification.
Supplementary Materials
The following supporting information can be downloaded at the website of this paper posted on Preprints.org and is also available at https://github.com/federicovello18-droid/Entropy-Classification/blob/main/supplementary_files.zip. The CSV files contain the classification results obtained across all 69 analyzed CuMiDa datasets. One file contains the results obtained using ANOVA + Logistic Regression for feature selection, alongside the full-feature analysis, while the other contains the results following feature extraction via SVD. Each row corresponds to a specific number of features and reports all the parameters used for the analysis, including the actual number of features and the effective range of k. In addition to the average accuracy computed over three repetitions, Cohen’s Kappa is also provided as an evaluation metric (which is not reported in the main manuscript)
Author Contributions
Conceptualization, F.V., S.F. and F.F.; methodology, F.V., S.F. and F.F.; software, F.V.; validation, F.V. and F.F.; formal analysis, F.V., S.F. and F.F.; writing—original draft preparation, F.V. and F.F.; writing—review and editing, F.V., S.F. and F.F.; visualization, F.V. and F.F.; supervision, S.F. and F.F.; funding acquisition, F.F. All authors have read and agreed to the published version of the manuscript.
Funding
This research was partially funded by the European Union through the European Social Fund Plus (ESF+), the Italian Republic, and the Region of Friuli Venezia Giulia, within the framework of the Regional Programme (PR) Programma Specifico 20/24 FSE+ 2021/2027, under Project/Grant No. G23C25000620008.
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable
Data Availability Statement
The data analysed in this study are available in Hugging Face Datasets at URL: https://huggingface.co/datasets/ylecun/mnist and in CuMiDa Database at URL: and https://sbcb.inf.ufrgs.br/cumida.
Acknowledgments
The authors would like to express their gratitude to Claudia Vello for providing essential advice on ML methodologies at the start of this project. The authors thank Rino Esposito and Miguel Angel Soler for useful discussion.
Conflicts of Interest
The authors declare no conflicts of interest.
Abbreviations
The following abbreviations are used in this manuscript:
| probability density function | |
| kNNe | k-th nearest neighbour entropy estimation |
| MIST | Maximum Information Spanning Tree |
| SUM-kNNe | k-th nearest neighbour entropy estimation using the sum of single variable entropies. |
| MI | mutual information |
| MIST-kNNe | k-th nearest neighbour entropy estimation using the sum of single variable entropies and the mutual informations corresponding to edges in the MIST. |
| JOINT kNNe | k-th nearest neighbour entropy estimation applied in the multidimensional space of all variables |
| MIE | mutual information expansion |
| MNIST | modified National Institute of Standards and Technology |
| CuMiDa | Curated Microarray Database |
| SVD | singular value decomposition |
| PCA | principal component analysis |
| ANOVA | analysis of variance |
| kNN | k nearest neighbours method for classification |
| SVM | support vector machine |
| RF | random forests |
| MLP | multilayer perceptron |
| ML | machine learning |
References
- Sharp, K.; Matschinsky, F. Translation of Ludwig Boltzmann’s Paper “On the Relationship between the Second Fundamental Theorem of the Mechanical Theory of Heat and Probability Calculations Regarding the Conditions for Thermal Equilibrium” Sitzungberichte der Kaiserlichen Akademie der Wissenschaften. Mathematisch-Naturwissen Classe. Abt. II, LXXVI 1877, pp 373-435 (Wien. Ber. 1877, 76:373-435). Reprinted in Wiss. Abhandlungen, Vol. II, reprint 42, p. 164-223, Barth, Leipzig, 1909. Entropy 2015, 17, 1971–2009. [CrossRef]
- Gibbs, J.W. Elementary principles in statistical mechanics: developed with especial reference to the rational foundations of thermodynamics; C. Scribner’s sons, 1902.
- Shannon, C.E. A mathematical theory of communication. The Bell system technical journal 1948, 27, 379–423.
- Hopfield, J.J. Neural networks and physical systems with emergent collective computational abilities. Proceedings of the national academy of sciences 1982, 79, 2554–2558. [CrossRef]
- Ackley, D.H.; Hinton, G.E.; Sejnowski, T.J. A learning algorithm for Boltzmann machines. Cognitive science 1985, 9, 147–169. [CrossRef]
- Polyansky, A.A.; Zubac, R.; Zagrovic, B. Estimation of conformational entropy in protein-ligand interactions: a computational perspective. Methods Mol. Biol. 2012, 819, 327–353. [CrossRef]
- Suarez, D.; Diaz, N. Direct methods for computing single-molecule entropies from molecular simulations. WIREs Comput Mol Sci 2015, 5, 1–26. [CrossRef]
- Kozachenko, L.F.; Leonenko, N.N. Sample estimates of entropy of a random vector. Problems in Inform Transm 1987, 23, 95–101.
- Singh, H.; Misra, N.; Hnizdo, V.; Fedorowicz, A.; Demchuk, E. Nearest neighbor estimate of entropy. Am J Math Manag Sci 2003, 23, 301–321. [CrossRef]
- Fogolari, F.; Corazza, A.; Fortuna, S.; Soler, M.A.; VanSchouwen, B.; Brancolini, G.; Corni, S.; Melacini, G.; Esposito, G. Distance-based configurational entropy of proteins from molecular dynamics simulations. PLoS ONE 2015, 10, e0132356. [CrossRef]
- Fogolari, F.; Dongmo Foumthuim, C.J.; Fortuna, S.; Soler, M.A.; Corazza, A.; Esposito, G. Accurate Estimation of the Entropy of Rotation–Translation Probability Distributions. J Chem Theory Comput 2016, 12, 1–8. [CrossRef]
- Fogolari, F.; Borelli, R.; Dovier, A.; Esposito, G. The k th nearest neighbor method for estimation of entropy changes from molecular ensembles. Wiley Interdisciplinary Reviews: Computational Molecular Science 2024, 14, e1691.
- Cover, T.M.; Thomas, J.A. Elements of information theory; Wiley: New York, 1991.
- Miller, G. Note on the bias of information estimates. Information theory in psychology: Problems and methods, B 1955, pp. 95–100.
- Killian, B.J.; Yundenfreund Kravitz, J.; Gilson, M.K. Extraction of configurational entropy from molecular simulations via an expansion approximation. J Chem Phys 2007, 127, 024107. [CrossRef]
- Hnizdo, V.; Tan, J.; Killian, B.J.; Gilson, M.K. Efficient calculation of configurational entropy from molecular simulations by combining the mutual-information expansion and nearest-neighbor methods. J Comput Chem 2008, 29, 1605–1614. [CrossRef]
- Fenley, A.T.; Killian, B.J.; Hnizdo, V.; Fedorowicz, A.; Sharp, D.S.; Gilson, M.K. Correlation as a Determinant of Configurational Entropy in Supramolecular and Protein Systems. J Phys Chem B 2014, 118, 6447–6455. [CrossRef]
- King, B.M.; Tidor, B. MIST: Maximum Information Spanning Trees for dimension reduction of biological data sets. Bioinformatics 2009, 25, 1165–1172. [CrossRef]
- King, B.M.; Silver, N.W.; Tidor, B. Efficient calculation of molecular configurational entropies using an information theoretic approximation. J Phys Chem B 2012, 116, 2891–2904. [CrossRef]
- Fogolari, F.; Maloku, O.; Dongmo Foumthuim, C.J.; Corazza, A.; Esposito, G. PDB2ENTROPY and PDB2TRENT: Conformational and Translational–Rotational Entropy from Molecular Ensembles. J Chem Inf Model 2018, 58, 1319–1324.
- LeCun, Y.; Bottou, L.; Bengio, Y.; Haffner, P. Gradient-based learning applied to document recognition. Proceedings of the IEEE 1998, 86, 2278–2324.
- Feltes, B.C.; Chandelier, E.B.; Grisci, B.I.; Dorn, M. CuMiDa: An extensively curated microarray database for benchmarking and testing of machine learning approaches in cancer research. Journal of Computational Biology 2019, 26, 376–386. [CrossRef]
- Clough, E.; Barrett, T. The gene expression omnibus database. In Statistical genomics: methods and protocols; Springer, 2016; pp. 93–110.
- Pedregosa, F.; Varoquaux, G.; Gramfort, A.; Michel, V.; Thirion, B.; Grisel, O.; Blondel, M.; Prettenhofer, P.; Weiss, R.; Dubourg, V.; et al. Scikit-learn: Machine Learning in Python. Journal of Machine Learning Research 2011, 12, 2825–2830.
- Golub, G.H.; Van Loan, C.F. Matrix computations, 3rd ed.; JHU press: Baltimore, 2013.
- Ross, S.M. Introductory Statistics, 3rd ed.; Elsevier: Amsterdam, 1982.
- Hastie, T.; Tibshirani, R.; Friedman, J.H.; Friedman, J.H. The elements of statistical learning: data mining, inference, and prediction, 2nd ed.; Springer: Amsterdam, 2009.
- Goodfellow, I.; Bengio, Y.; Courville, A.; Bengio, Y. Deep learning; MIT press: Cambridge, 2016.
Figure 1.
Pixel class entropies and Kullback-Leibler divergences between classes. Starting from the top, rows refer to classes 0 and 1, 3 and 8, 4 and 9, respectively.
Figure 1.
Pixel class entropies and Kullback-Leibler divergences between classes. Starting from the top, rows refer to classes 0 and 1, 3 and 8, 4 and 9, respectively.
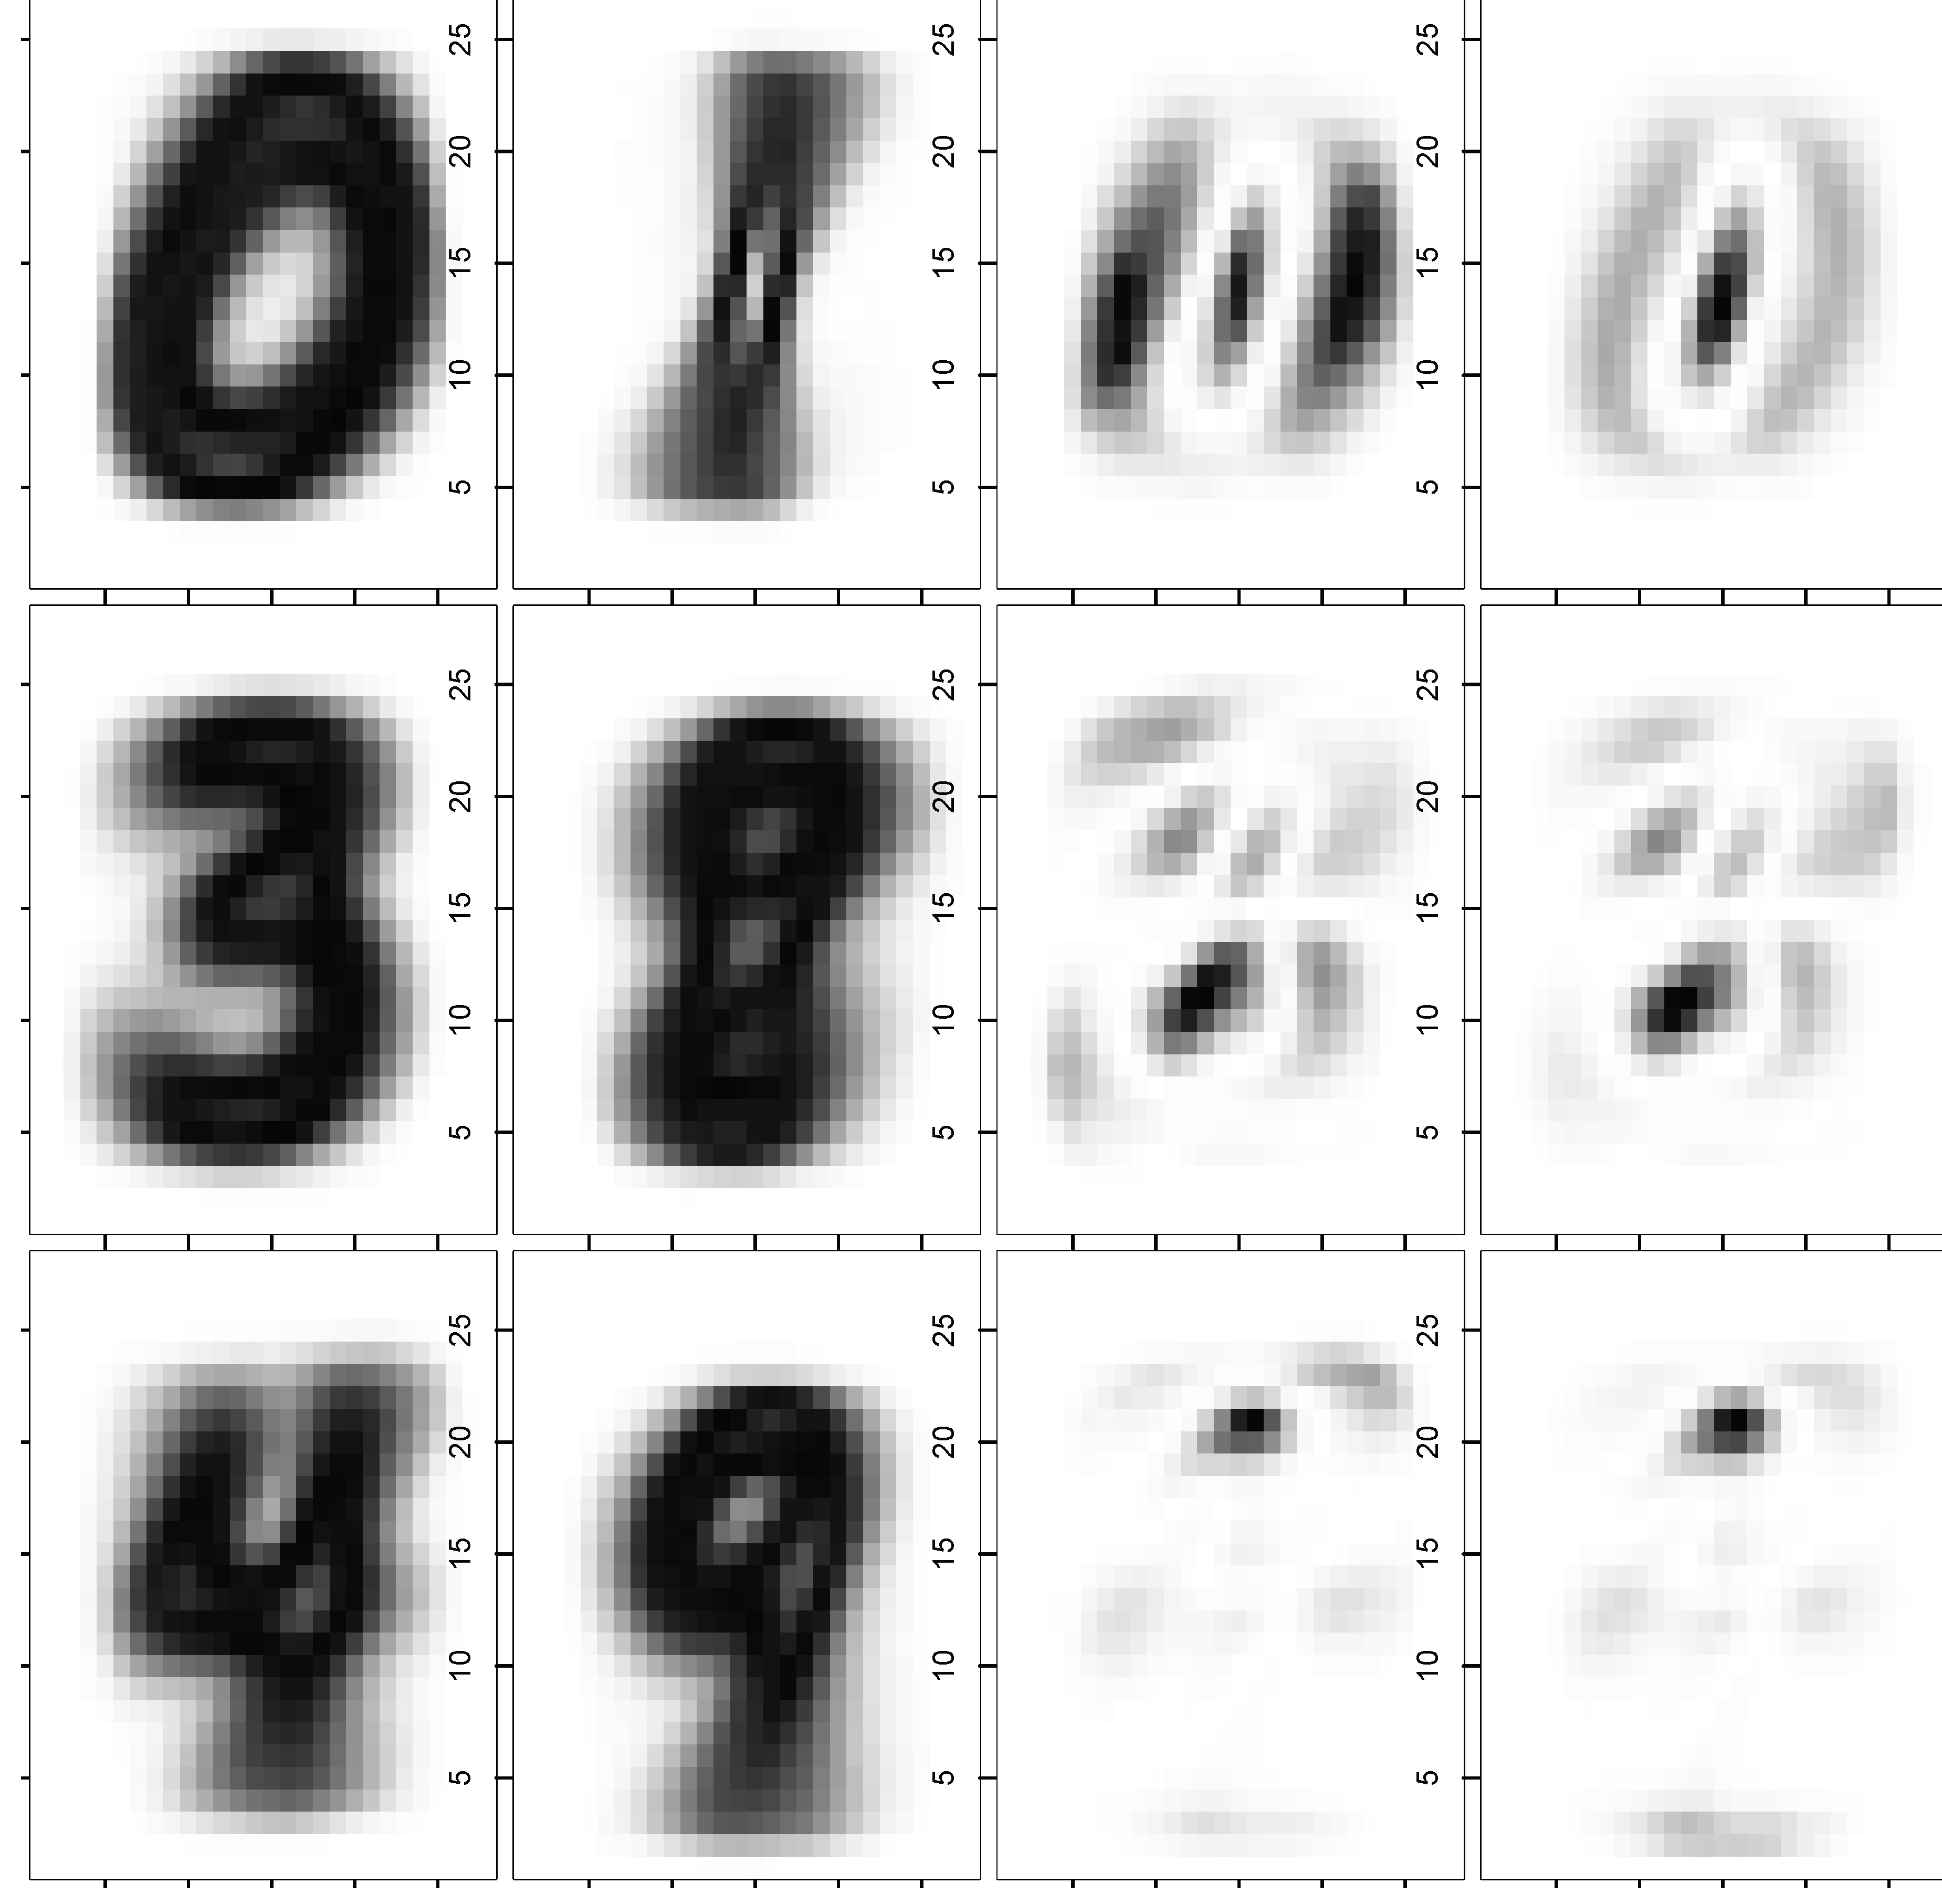
Figure 2.
Accuracy of standard kNN and kNNe entropy-based classification.
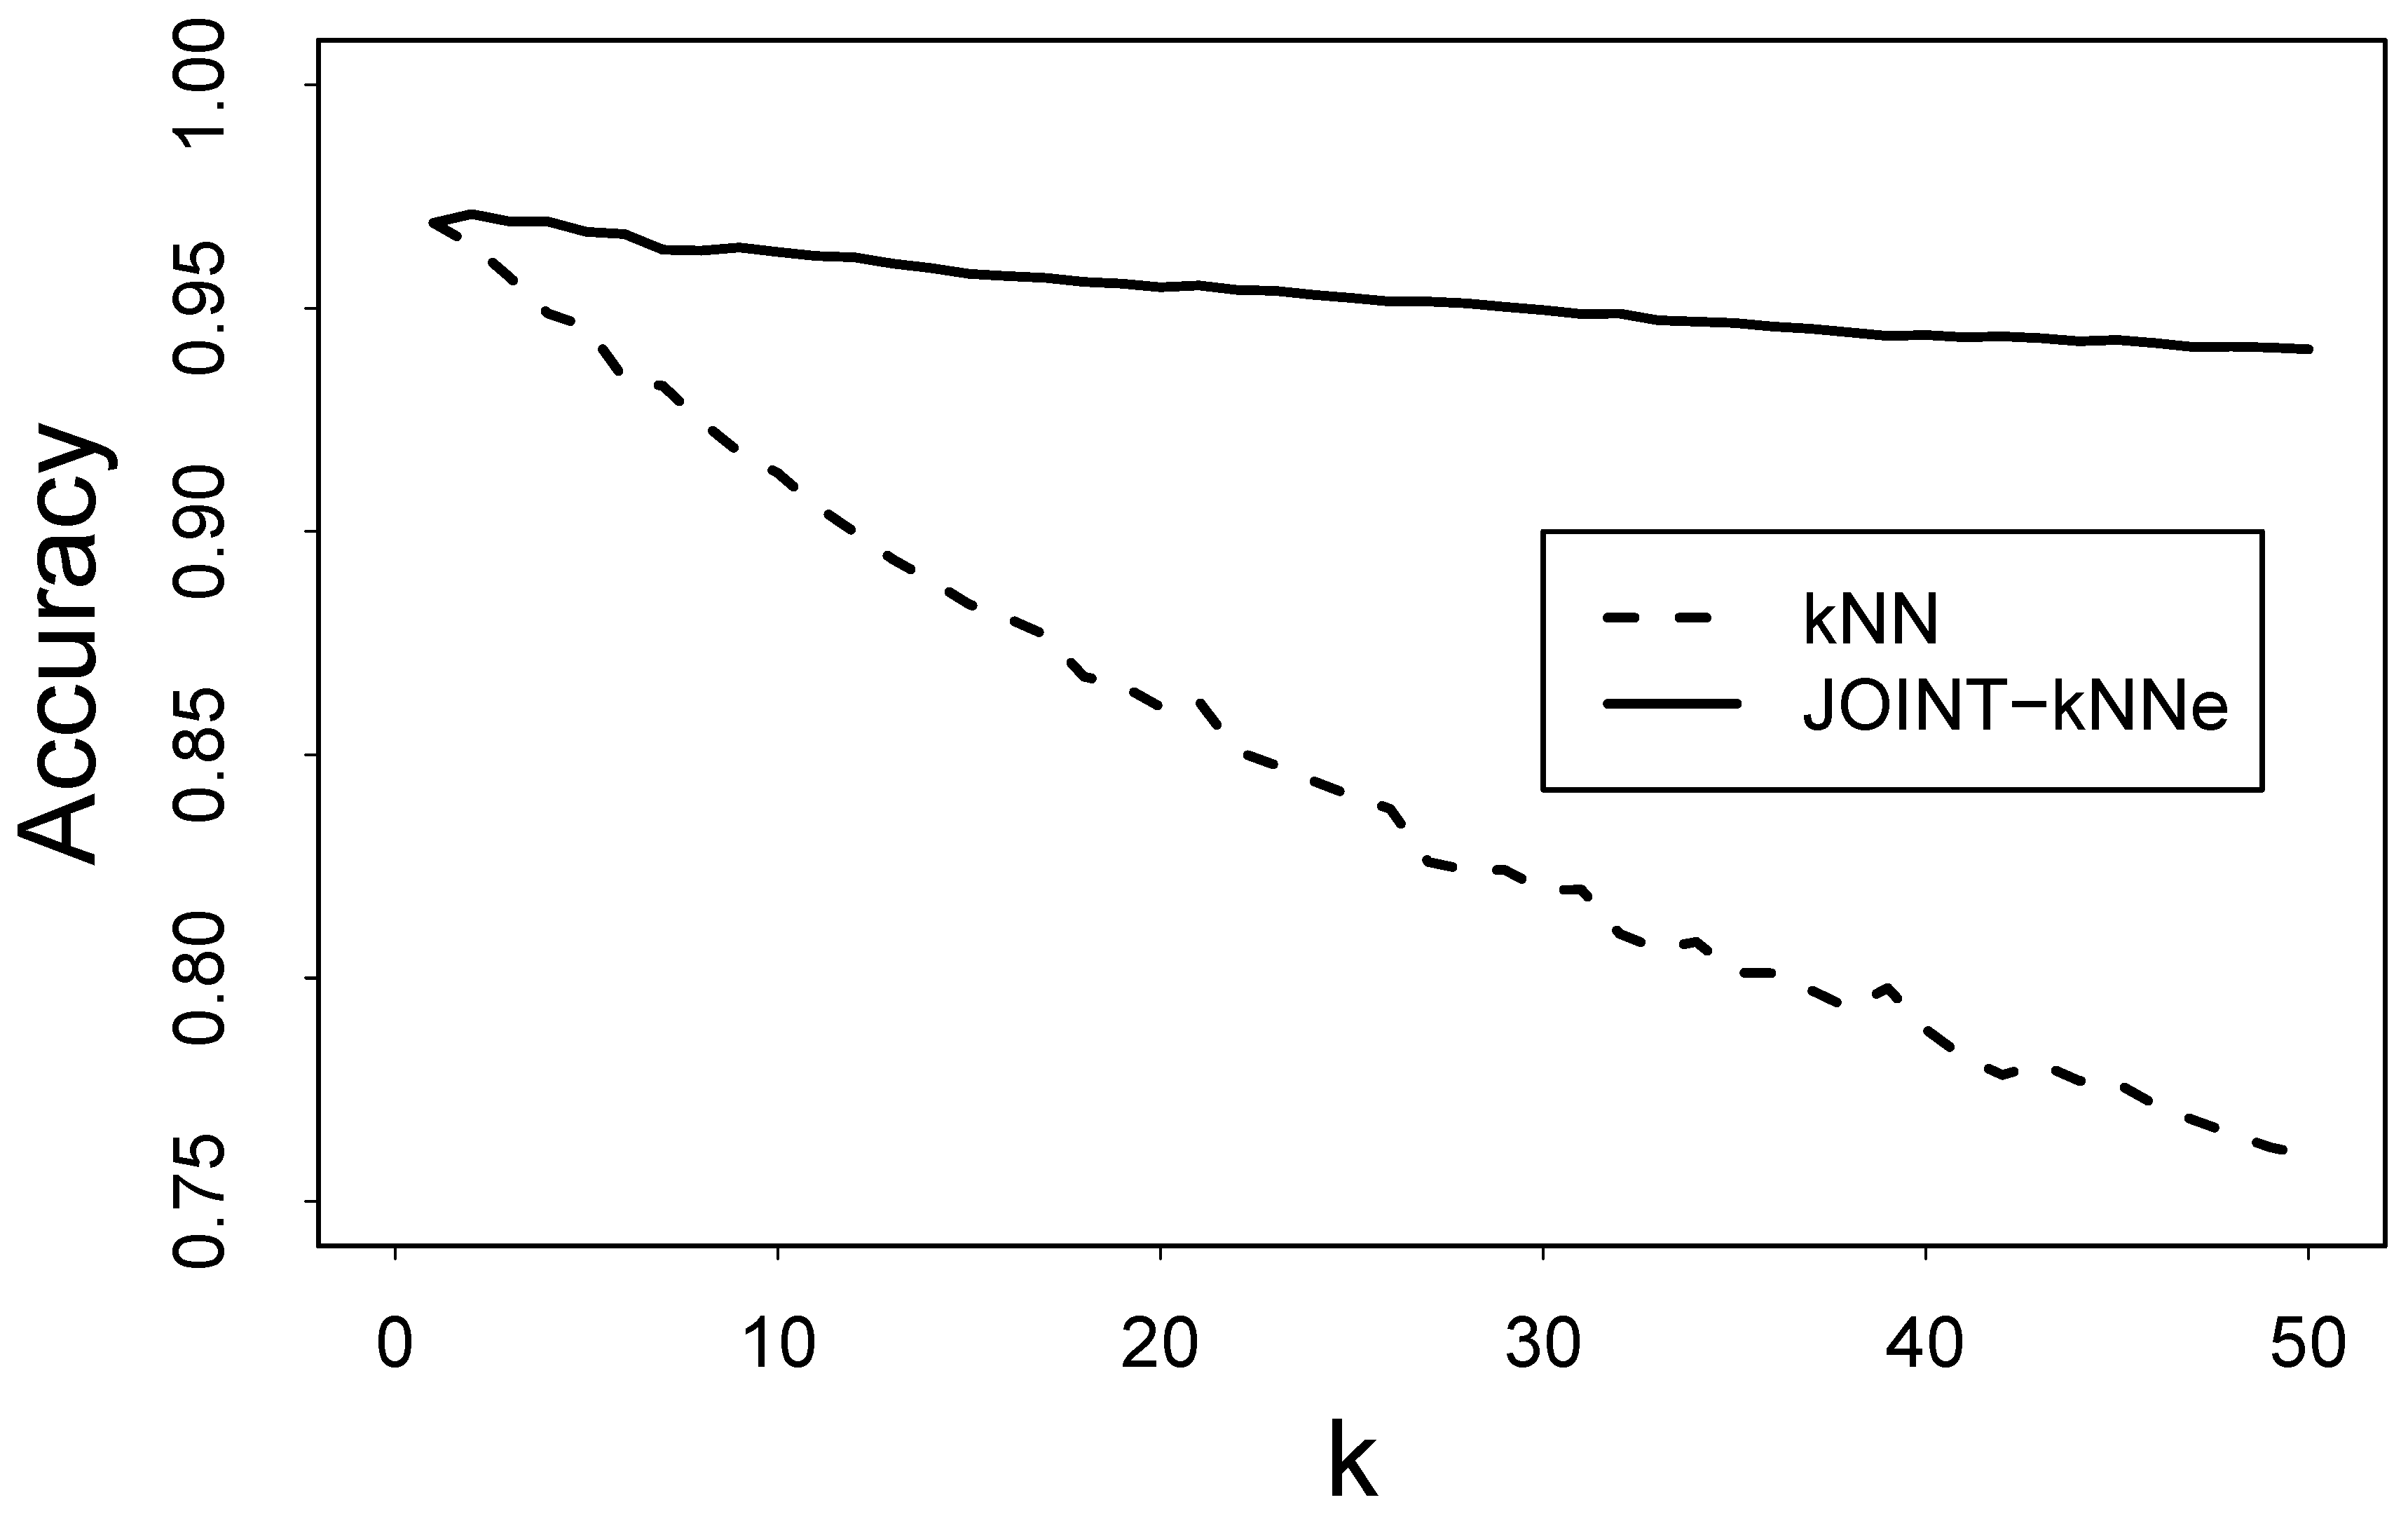
Figure 3.
Benchmark of four ML methods presented by CuMiDa. Each graph represent the confront between MIST-kNNe model and a ML algorithm among kNN, MLP, RF, and SVM.
Figure 3.
Benchmark of four ML methods presented by CuMiDa. Each graph represent the confront between MIST-kNNe model and a ML algorithm among kNN, MLP, RF, and SVM.
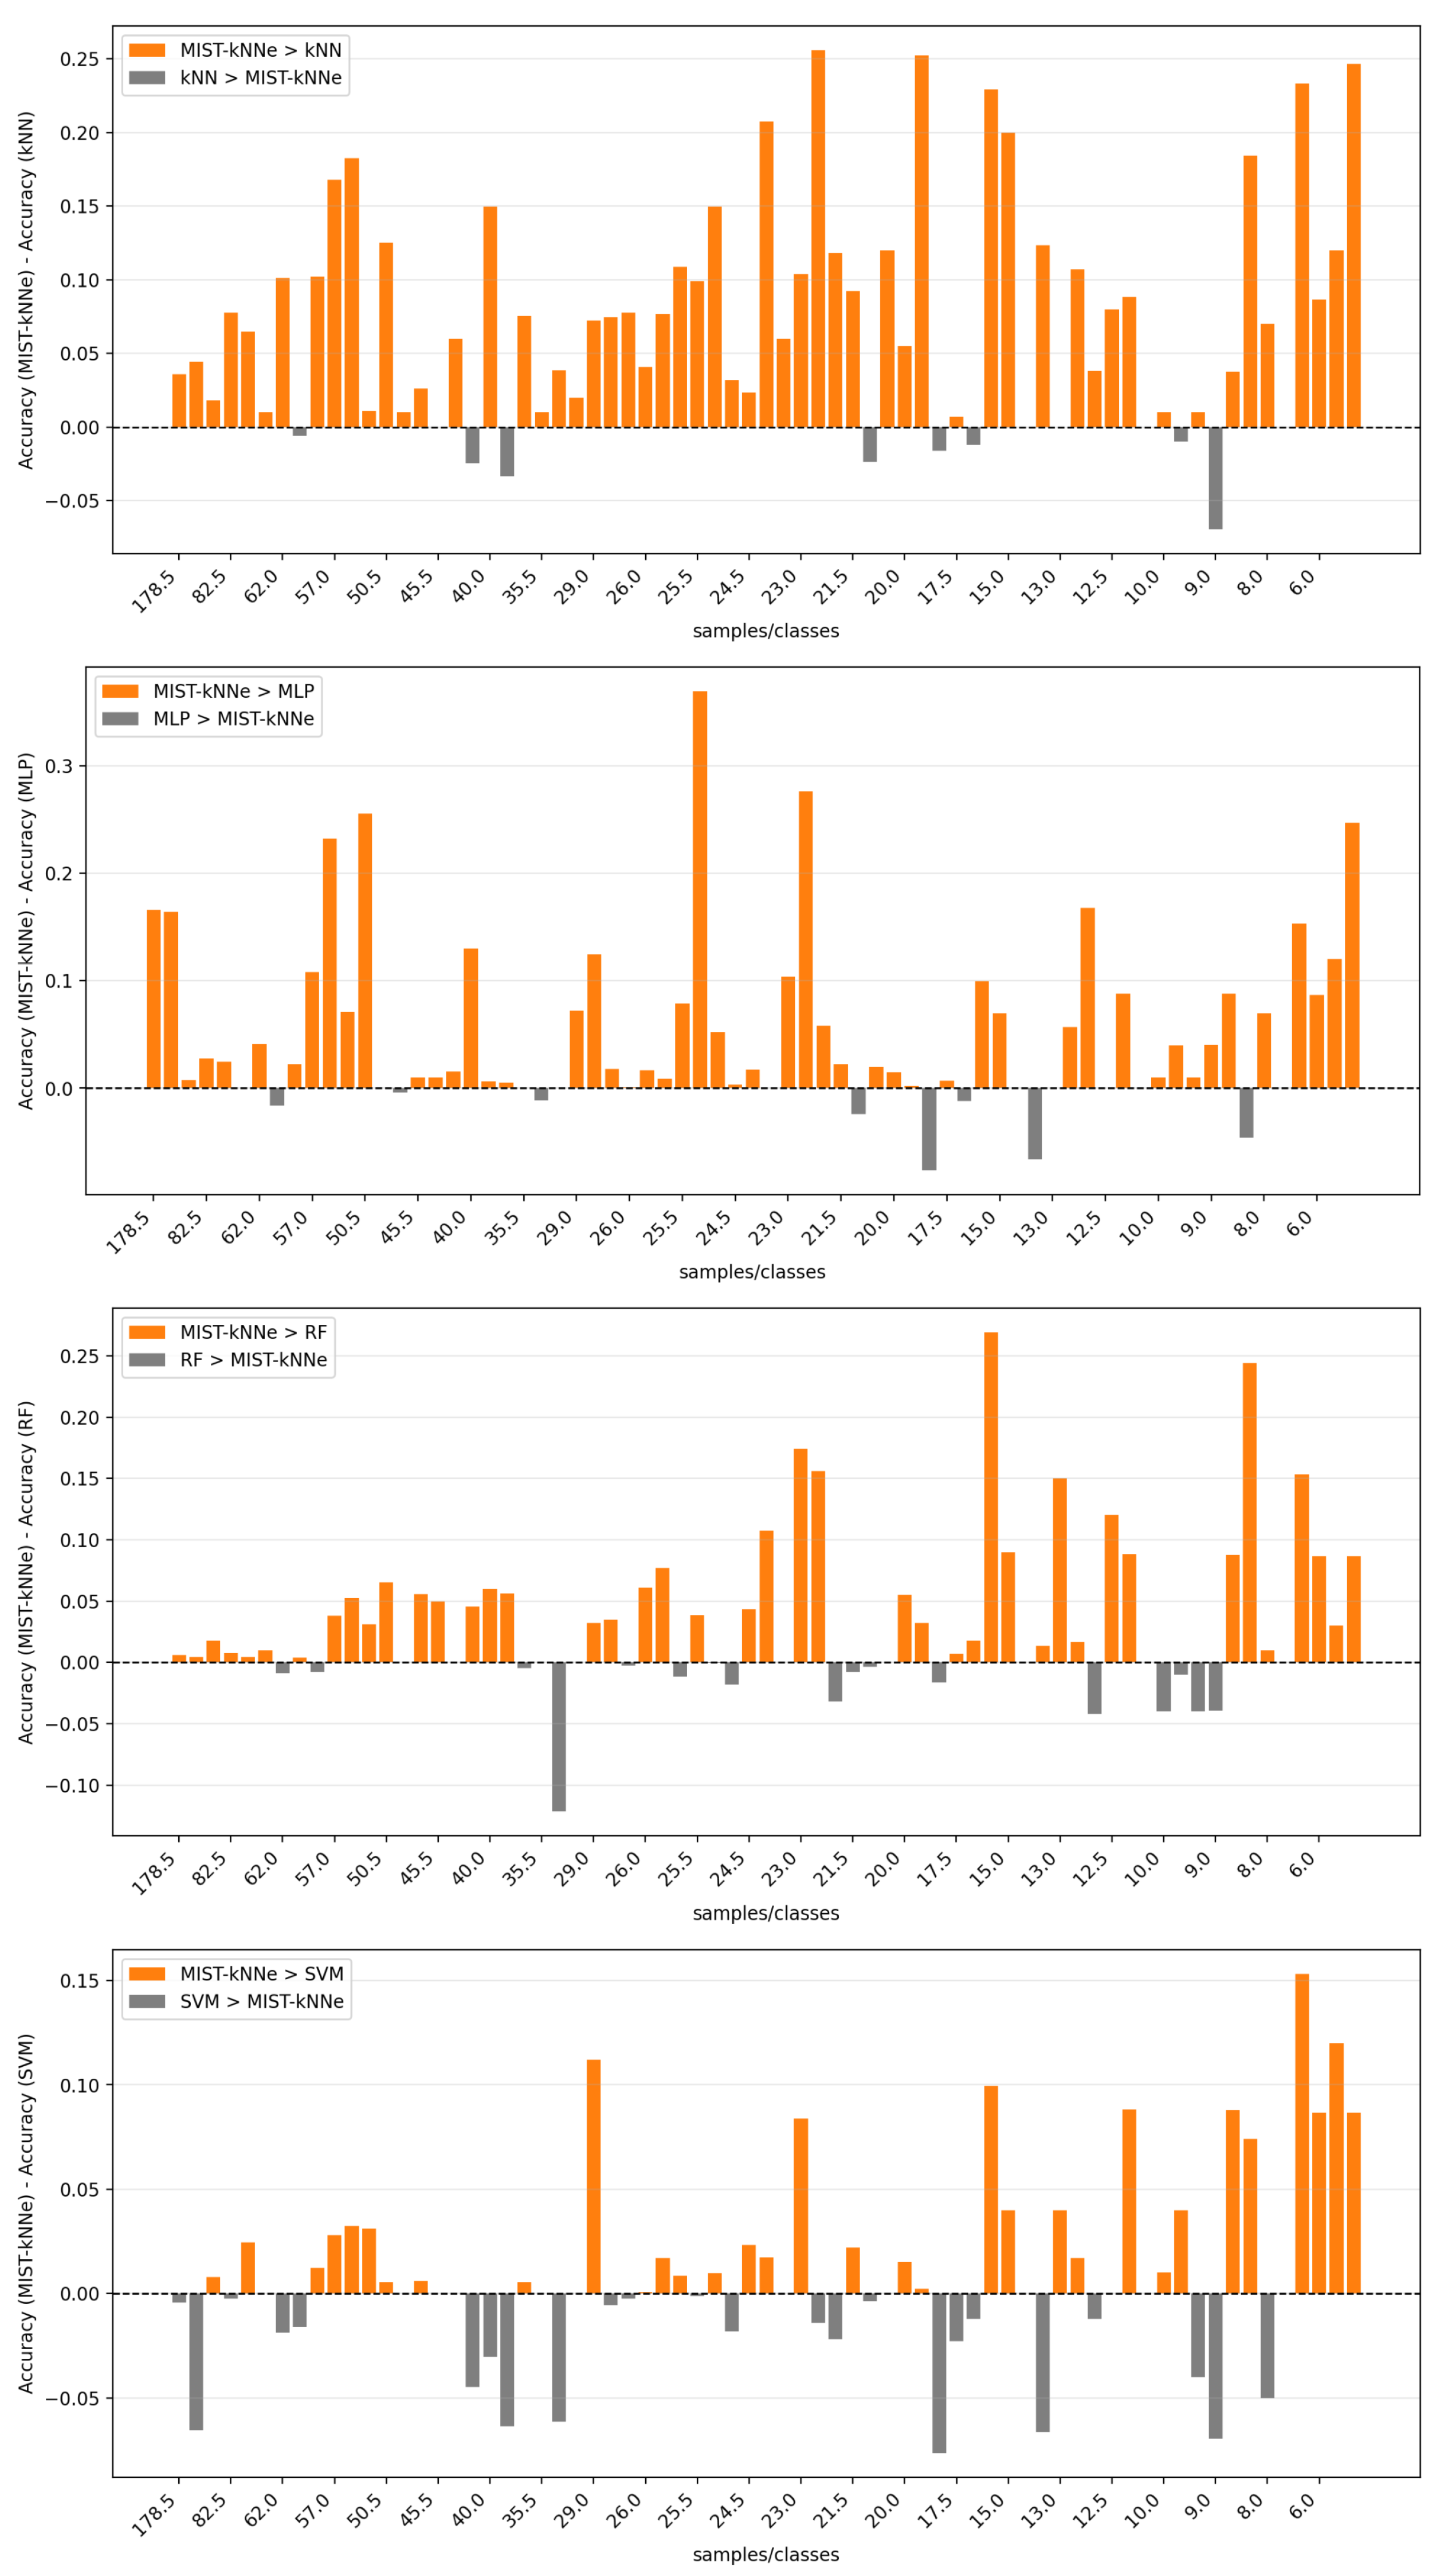
Figure 4.
Accuracy vs number of features obtained via ANOVA + Logistic Regression filtering. SUM-kNNe refers to sum of marginal entropy, MIST-kNNe refers to pipeline including pairwise MI through MIST, JOINT-kNNe refers to multivariate entropy estimation.
Figure 4.
Accuracy vs number of features obtained via ANOVA + Logistic Regression filtering. SUM-kNNe refers to sum of marginal entropy, MIST-kNNe refers to pipeline including pairwise MI through MIST, JOINT-kNNe refers to multivariate entropy estimation.
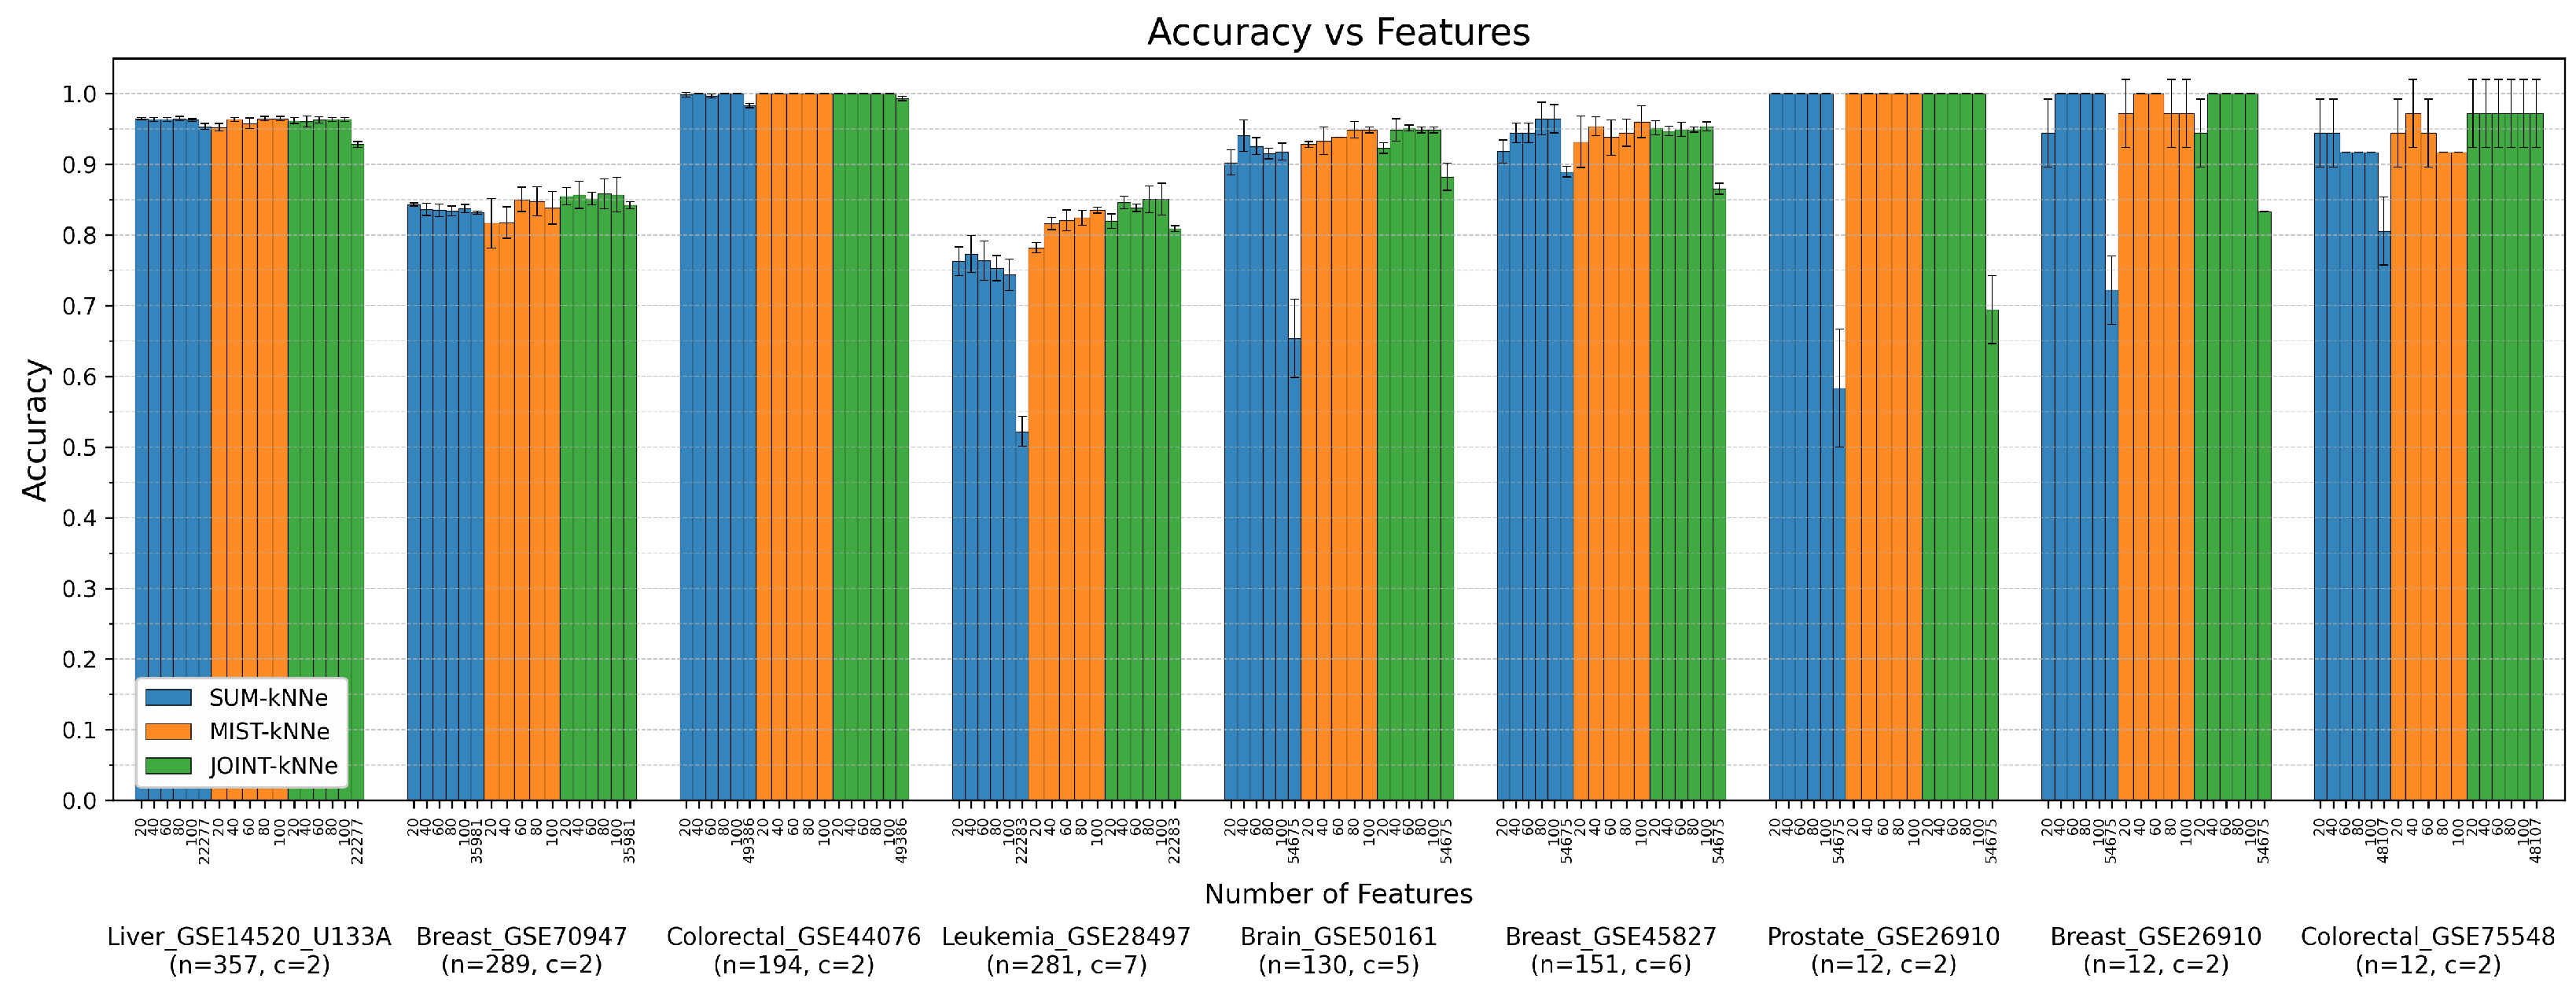
Figure 5.
Accuracy vs number of features (principal components) obtained via SVD. SUM-kNNe refers to sum of marginal entropy, MIST-kNNe refers to pipeline including pairwise MI through MIST, JOINT-kNNe refers to multivariate entropy estimation.
Figure 5.
Accuracy vs number of features (principal components) obtained via SVD. SUM-kNNe refers to sum of marginal entropy, MIST-kNNe refers to pipeline including pairwise MI through MIST, JOINT-kNNe refers to multivariate entropy estimation.
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (http://creativecommons.org/licenses/by/4.0/).
Copyright: This open access article is published under a Creative Commons CC BY 4.0 license, which permit the free download, distribution, and reuse, provided that the author and preprint are cited in any reuse.