
Submitted:
14 August 2026
Posted:
14 August 2026
You are already at the latest version
Abstract
People often recognize spoken words more accurately and more quickly than written words. From the perspective of active inference under the free-energy principle, the present study develops a formal account of this speaking-over-writing advantage in production-modality retrieval. We modeled retrieval under spoken and written production-modality states, together with the selection of an early or late response policy according to its expected sensory consequences. University students spoke or wrote words presented on a computer screen and later judged the modality in which each word had been produced. Responses were followed by explicit visual feedback indicating whether each judgment was correct or incorrect, thereby providing an observable sensory consequence of the recognition response. Response times were implemented as early and late policies within a partially observable Markov decision process (POMDP). The model included modality-specific likelihood parameters linking response timing to feedback outcomes. Spoken words were identified more quickly and accurately than written words, and early responding was more strongly associated with correct feedback under the speaking state than under the writing state. Bayesian model selection favored the POMDP over a simpler linear model estimated using Variational Laplace, indicating that the POMDP provided a better balance of fit and complexity. These findings show how production modality, response timing, and expected sensory consequences can be represented within a common generative framework. The framework provides a basis for future extensions that model uncertainty about production modality, preserve continuous response timing, incorporate learning across trials, and compare active-inference accounts with alternative models of recognition memory.
Keywords:
active inference
; free-energy principle
; Markov decision process
1. Introduction
Imagine meeting someone for the first time and learning their name: Ana. During the encounter, the person says the name aloud: “Nice to meet you, Ana.” Speaking creates a production episode that includes multiple contextual features (CF), such as hearing one’s own voice with a particular pronunciation or phonetic profile, executing the corresponding articulatory movements, and producing the name within a specific social context. What appears to be a simple social convention illustrates a broader principle in cognitive psychology: memory is shaped not only by the item to be remembered, but also by the contextual features (CF) generated during encoding (1, 2)., including the fact that the item was spoken aloud.
One week later, the person encounters the same individual and must retrieve the name. In doing so, they may partially reinstate the earlier production episode, including the memory that they had spoken the name aloud during the initial encounter. This reinstated production-modality context may facilitate retrieval of the name “Ana.” The person must then evaluate possible response policies or actions: saying the name immediately—“Hi, Ana”—or hesitating and waiting for additional evidence. An immediate response may elicit approving feedback, such as a smile or warm reply, if the name is correct; if it is incorrect, it may instead elicit confusion or correction
Although the person may strongly believe that the retrieved name is correct, its correctness is not directly observable. It must instead be inferred from sensory observations. In this example, the relevant observation is the other person’s response. A smile provides sensory evidence that the person, acting as an active-inference agent [1], can use to update their belief that the retrieved name was correct. Conversely, confusion or correction provides evidence that the retrieval was inaccurate. Approving feedback therefore matters because it serves as an observable consequence of an otherwise hidden state: whether the retrieved name is correct (Figure 1).
The introductory real-life example reflects the well-established finding that word-recognition accuracy is higher for words that participants produce aloud than for words they read silently [2,3,4,5,6,7,8,9,10,11,12,13,14,15,16,17,18,19,20]. Most experiments examining this phenomenon use a two-stage task. During the production stage, participants either read words aloud or read them silently. During the subsequent retrieval stage, previously presented words are intermixed with novel lures, and participants judge whether each item appeared during the production stage.
Enhanced recognition is not limited to words spoken aloud. Writing a word can also improve its subsequent recognition [18]. Crucially, this benefit is typically weaker than that associated with speaking the word aloud [5,14,16,18]. This pattern gives rise to a speaking-over-writing advantage, whereby spoken words are generally recognized more accurately than written words.
Contemporary theoretical neurobiology, particularly active-inference accounts, proposes that cognition and action are organized partly around their anticipated sensory consequences [1,21,22,23]. On this view, an agent does not select an action solely on the basis of currently available evidence, but also according to what the action is expected to make observable. In the introductory example, retrieving the name “Ana” is therefore not only a matter of reinstating information about the earlier production episode. It is also embedded in the evaluation of a possible action—saying the name—and of the sensory consequences expected to follow from that action, such as a smile, a warm response, confusion, or correction.
The present account applies this active-inference assumption specifically to the retrieval of production-modality traces. When a participant infers that a word was previously spoken or written, that inference provides evidence about whether the item was encountered before. However, the functional significance of the trace also depends on how it informs the selection of a recognition response expected to produce a preferred observation, such as feedback confirming that the judgment was correct. Retrieval is therefore treated not as an isolated reconstruction of the encoding episode, but as part of an action-oriented inferential process in which beliefs about prior production and beliefs about future sensory consequences jointly contribute to recognition-policy evaluation.
The above general account can be applied to provide a preliminary formalization of the speaking-over-writing advantage of word retrieval. Specifically, spoken and written production-modality traces may differ in the reliability or precision, with which they support this process. A spoken trace may provide more distinctive or diagnostically informative evidence because it includes auditory and articulatory information, whereas a written trace may rely more heavily on visuomotor and orthographic information. A more precise spoken trace would support stronger beliefs about the earlier production modality and, consequently, greater confidence in selecting a recognition policy expected to yield confirming sensory feedback. From this perspective, the speaking-over-writing advantage can be characterized as a difference in the precision with which spoken and written production-modality traces inform recognition-policy selection in relation to the sensory consequences expected from responding.
1.1. The Current Work
The present paper pursues a specific theoretical objective: to develop a formal, yet preliminary, active-inference model, implemented as a partially observable Markov decision process (POMDP), of the speaking-over-writing advantage in the retrieval of individually produced words. The model characterizes how production-modality CF are reinstated during retrieval, how their precision contributes to belief updating about the encoding episode, and how these beliefs inform recognition-response policies through their expected sensory consequences.
This modeling work is intentionally narrow. It does not aim to explain every way in which CF enhance memory retrieval. Instead, it formalizes one specific component of this process: how spoken and written production-modality traces, as elements within a broader set of CF, guide retrieval within an active-inference framework [24,25,26,27,28,29]. In this framework, explicit feedback provides the sensory evidence through which beliefs about the appropriateness of the selected response can subsequently be updated.
The remainder of the manuscript is organized as follows. First, we briefly introduce the experimental task we used to instantiate the POMDP. Second, we describe the model specification and its mathematical formulation. Third, we report descriptive statistical analyses confirming the speaking-over-writing advantage elicited by the task, followed by the POMDP parameter estimates obtained by fitting the model to the collected data.
1.1.1. Word-Production and Retrieval Task That Instantiates the POMDP
The task (see Materials and Methods for details) comprised production and retrieval stages (Figure 2). During the production stage, participants spoke or wrote blocks of words presented on a computer screen. During the subsequent retrieval stage, previously produced words were presented again, and participants indicated whether each word had originally been spoken or written.
After each judgment, participants received explicit visual feedback indicating whether their response was correct or incorrect. This feedback constituted an observable sensory consequence of the recognition response. Correct feedback represented a preferred outcome, whereas incorrect feedback represented an outcome to be avoided. The task therefore allowed recognition behavior to be modeled not only in terms of beliefs about the earlier production modality, but also in terms of the sensory outcomes that different responses were expected to generate.
A further feature of the task was that participants were free to determine when to respond after the retrieval prompt appeared. Response time therefore indexed when participants acted on their current belief about the production modality. In the discrete POMDP, this temporal aspect of behavior had to be represented as a choice between a finite set of response-timing policies. The theoretical rationale for this representation follows from the distinction in active-inference formulations between continuous-state/action and discrete-state/action models [24,25,30]. Continuous-time formulations are suited to modeling continuously evolving states and movements, whereas discrete-time formulations represent inference over a finite set of hidden states, observations, actions, and policies. In the present model, the theoretically relevant quantity was not the continuous motor execution of the response itself, but the policy governing when participants committed to and expressed their belief that a word had previously been spoken or written.
To instantiate these alternative temporal policies, response times were classified separately for each participant after collapsing across the speaking and writing conditions. Each participant’s median response time served as the threshold: responses equal to or below the median were coded as enactments of the early-response policy, whereas responses above the median were coded as enactments of the late-response policy. These policies represented acting relatively early on the current belief about production modality or delaying the response before committing to that belief. The participant-specific threshold expressed policy timing relative to each participant’s own response distribution rather than imposing a common absolute cutoff across participants.
A continuous-action formulation would instead be more appropriate for modeling the evolving motor dynamics through which a selected policy is executed, such as hand trajectories, keypress dynamics, speech articulation, or other continuously unfolding movements. Note, therefore, that the early–late classification was introduced to define the two temporal policies available to the agent within the discrete POMDP, rather than merely to simplify a continuous response-time measure.
In summary, the memory-phase of the task thus involved two related inferential components. First, participants formed a belief about whether the probe word had previously been spoken or written. Second, they selected when to act on that belief, with early and late responding represented as alternative policies associated with different expected feedback outcomes. Recognition accuracy and response timing were therefore treated jointly as observable expressions of the latent decision process underlying retrieval [31]. Within this framework, the central computational question is whether the speaking-over-writing advantage can be characterized by differences in the precision of the mapping from production-modality and response-timing states to feedback outcomes. Specifically, we examine whether early and late response policies differ in how reliably they are associated with correct feedback under spoken and written production-modality states. If spoken production supports a more precise retrieval trace than written production, an early response under the spoken state should be more strongly associated with correct feedback than an early response under the written state.
The following section describes the POMDP architecture through which production-modality states, response-timing policies, feedback observations, and their likelihood mappings are formally represented.
1.1.2. Partially Observable Markov Decision Process
In active inference, policy selection is guided by expected free energy, which evaluates policies according to the outcomes they are expected to generate. Expected free energy includes a pragmatic component, related to attaining preferred outcomes, and an epistemic component, related to reducing uncertainty. In the present model, correct feedback constitutes a preferred outcome, whereas incorrect feedback constitutes an outcome to be avoided. Feedback also provides sensory evidence about the response generated under the current production-modality state. Participants are therefore represented as active-inference agents who select response-timing policies according to the feedback outcomes those policies are expected to produce when retrieving words that were previously spoken or written.
We formalized this process using a two-timestep POMDP model [24,25]. The model represents the participant as an agent who selects a response-timing policy and subsequently updates beliefs after observing feedback. It specifies the hidden states, observable outcomes, likelihood mappings, preferences, policies, and state transitions required to represent this process. The production-modality state corresponds to the modality in which the probe word was encoded: speaking or writing. The agent selects either an early-response or a late-response policy and then observes correct or incorrect feedback. The central computational question is whether the mapping between response timing and feedback differs across the speaking and writing production-modality states. Figure 3 presents the POMDP specification as a factor graph.
The model contains two hidden-state factors. The first factor represents response state and comprises three states: no response, early response, and late response. This factor is action dependent because the selected policy determines the transition from the no-response state at the first timestep to either the early-response or late-response state at the second timestep. These policy-dependent transitions are encoded in the (B{1}(:,:,1) matrix. The second hidden-state factor represents production modality and comprises two states: speaking and writing. This factor indicates the modality in which the current probe word was originally produced. In the present implementation, the production-modality state is determined by the trial structure and remains stable across the two timesteps. Its transitions are encoded in the B{1}(:,:,2) matrix.
The model includes one outcome modality, represented by the A{1}(:,:,1) matrix, with three possible observations: no feedback, incorrect feedback, and correct feedback. Feedback is generated by the joint configuration of the response state and the production-modality state. At the first timestep, the agent occupies the no-response state and observes no feedback, regardless of whether the production-modality state is speaking or writing. At the second timestep, the agent occupies either the early-response or late-response state and observes correct or incorrect feedback.
The agent’s problem is therefore to select the response-timing policy expected to generate the preferred feedback outcome under the current production-modality state. Under the speaking state, an early response generates correct feedback with probability (CorrS), whereas a late response generates correct feedback with probability (1-CorrS). Under the writing state, an early response generates correct feedback with probability (CorrW), whereas a late response generates correct feedback with probability (1-CorrW).
The parameters (CorrS) and (CorrW) quantify the precision of the likelihood mapping from the joint configuration of production modality and response state to feedback. More specifically, they determine how reliably early, relative to late response state predicts correct feedback under the speaking and writing states. The speaking-over-writing advantage is therefore represented as a condition-specific difference in these likelihood parameters. If speaking supports earlier and more confident retrieval than writing, early response state should map more strongly onto correct feedback in the speaking state than in the writing state. Formally, this prediction corresponds to .
Preferences over feedback observations are encoded in the C{1} matrix. No-feedback observations are assigned neutral preference, incorrect feedback is avoided at the second timestep, and correct feedback is preferred at the second timestep. The two possible response timings are encoded as shallow policies in the (U) matrix, with one policy producing an early response and the other producing a late response.
The model additionally specifies parameters governing policy selection and action execution. The inverse policy-precision parameter is fixed at beta = 1, allowing expected differences among policies to exert a relatively strong influence on policy selection. The action-precision parameter is fixed at alpha = 16, producing relatively consistent execution of the selected response policy.
1.1.3. Formal Decomposition of Policy Belief Updating
We next decompose the posterior probability of selecting a response-timing policy, ), in terms of variational free energy and precision-weighted expected free energy. Because the agent expects feedback at the second timestep, response timing is selected by sampling from a posterior distribution over policies after the no-feedback observation at the first timestep. This distribution is expressed as:
Here, denotes the posterior probability of selecting response-timing policy . The term denotes the policy-specific variational free energy associated with observations already available. The term denotes the expected free energy of future feedback observations under that policy. The parameter denotes policy precision and controls the extent to which differences in expected free energy influence policy selection.
Accordingly, evaluates how well a policy explains observations that have already occurred, whereas evaluates the expected pragmatic and epistemic value of observations that may occur in the future. Policies with lower variational and expected free energy are assigned higher posterior probability.
In the present two-timestep model, before correct or incorrect feedback is observed, is determined primarily by the no-feedback observation and the production-modality state. Because both the early- and late-response policies are associated with no feedback at the first timestep, variational free energy provides little basis for distinguishing between them at that point. Initial policy selection is therefore driven mainly by expected free energy: the agent evaluates whether responding early or late is expected to generate the preferred outcome of correct feedback at the second timestep.
1.1.4. Pragmatic and Epistemic Decomposition of Expected Free Energy
For a response-timing policy, , expected free energy may be written as:
Expected free energy can be decomposed into pragmatic and epistemic components. The pragmatic component evaluates whether a policy is expected to generate preferred observations, whereas the epistemic component evaluates whether it is expected to reduce uncertainty about hidden states. In the present model, the pragmatic value of a policy depends on its probability of generating correct rather than incorrect feedback.
Feedback may also have epistemic value insofar as it reduces uncertainty about hidden states. In the present implementation, however, this information gain applies primarily to the response state rather than to the production-modality state. Production modality is fixed by the trial structure and is therefore already strongly constrained. Correct or incorrect feedback consequently provides little additional information about whether the word was spoken or written. By contrast, because feedback depends on the response state, it can sharpen posterior beliefs about whether the observed outcome was generated under an early- or late-response state.
1.1.5. Variational Free Energy and Variational Message Passing During Belief Updating
Although variational free energy has limited policy-discriminating value at the first timestep, it becomes important after feedback is observed. Once the agent has selected a response-timing policy and received correct or incorrect feedback, it must update its beliefs to account for that observation. This updating is implemented through marginal message passing [24,32], with variational free energy supplying the objective function:
Minimizing variational free energy reduces the divergence between the approximate posterior, q(s), and the Bayesian posterior, . In the present model, this means that, after feedback is observed, beliefs about the response state are updated so that they better explain the feedback under the current production-modality state.
In summary, evaluates response-timing policies prospectively, before feedback is observed, according to their expected pragmatic and epistemic consequences. By contrast, evaluates how well a policy and its associated hidden states explain observations that have already occurred. At the first timestep, both policies predict no feedback, and therefore provides little discrimination between them. At the second timestep, after correct or incorrect feedback is observed, variational free energy supports retrospective belief updating by evaluating how well the inferred response state accounts for the observed outcome.
2. Materials and Methods
2.1. Participants
Under laboratory conditions, 16 undergraduate students (6 biological males and 10 biological females; M age = 22.5, SD = 6.22) from Brandon University were recruited via campus advertisements. Sample size estimation was based on sequential analysis and optional stopping [33,34]. Participation was voluntary, and all individuals provided written informed consent prior to the initiation of the experiment. All participants received a $50 gift card as compensation for their time. The study was approved by the Brandon University Research Ethics Committee.
2.1.1. Optional Stopping for Sample Size Definition
After data had been collected from the first 10 participants, we fitted Bayesian ANCOVA models to the response time and accuracy data, with condition as a fixed effect, participant as a random effect, and word frequency as a covariate. We specified a stopping criterion of BF₁₀ > 10, indicating strong evidence [35] for higher accuracy and faster response time in the speaking condition than in the writing condition. We had planned to continue data collection one participant at a time, recomputing BF₁₀ after each addition until this threshold was reached. However, the criterion was already satisfied with the initial 10 participants. We nevertheless increased the sample by 50% and recruited one additional participant to maintain counterbalancing, yielding a final sample of 16 participants.
2.2. Stimuli
Our stimuli consisted of an experimental word list of 180 nouns with the highest academic frequency selected from the Strathy Corpus of Canadian English [36]. For each participant, the order of the 180 words was randomized, and the list was split into two sublists (one per condition) of 90 words each. This randomized order was used to assign each word, without replacement, to a language condition (writing or speaking). Nine block lists of 20 words each were then created, with words randomly drawn from the speaking and writing sublists (10 words per condition).
2.3. Procedure and Software
Participants were seated at a computer and wore noise-cancelling headphones throughout the experiment. Each participant completed nine blocks, each consisting of a language production phase followed by a memory phase (Figure 2). After completing each block, participants took a break and were free to decide when to begin the next block by pressing the space bar. The experiment began with four familiarization trials (two per condition). In the production phase of each block, participants were presented with 20 words for 5 s each, displayed either in red ink (speaking condition) or green ink (writing condition)—counterbalanced across participants. The color of the word cued participants to either speak or type the word. Each word presentation was preceded by a “be prepared” slide displayed for 4.5 s. After completing the language production phase, participants performed the memory phase using the same words presented during the production phase. A memory trial began with a blank screen (5 s) serving as fixed inter stimulus interval, followed by a probe word (5 s, unless a response was recorded), and feedback screen (“correct,” “incorrect,” or “no response recorded”, 5 s). Probe words were displayed in black ink on a white background. The task was built using PsychoPy, which recorded accuracy, response time, and word production. Accuracy of word production (i.e., whether the participant actually spoke or wrote the target word was confirmed via PsychoPy output (for written registers) and spectrogram analysis (for spoken registers). For basic statistical analysis, we used JASP [37]. For modeling, we used SPM12 (http://www.fil.ion.ucl.ac.uk/spm/) and modified scripts provided by Smith, et al. [24] and Smith, et al. [38].
3. Results
3.1. Behavioral Results
Table 1 summarizes the behavioral results. Mean RT was shorter in the speaking than in the writing condition. Similarly, the mean proportion of correct responses was higher in the speaking than in the writing condition. Bayesian ANCOVA models confirmed these differences and ruled out an effect of word frequency (i.e., the model including the covariate received less support, BF₁₀ = 1390, than the model without the covariate, BF₁₀ = 3899; Figure 4). A similar Bayesian ANCOVA model confirmed the accuracy difference and again ruled out an effect of word frequency (BF₁₀ = 325 vs. BF₁₀ = 59, respectively; Figure 4). We further fit a third ANCOVA model to confirm that the RT difference between conditions remained after discretization (BF₁₀ = 3948); the model including word frequency as a covariate was less supported by the data (BF₁₀ = 335; Figure 4).
3.2. Computational Model Results
3.2.1. Model Parameter Estimates and Parametric Empirical Bayes (PEB)
Table 2 shows the subject-level parameter estimates of the POMDP model. The mean parameter estimate for CorrS was 0.53 (SD = 0.04), whereas the mean parameter estimate for CorrW was 0.47 (SD = 0.04). We performed PEB to assess group level effects. The results showed group-level effects for both the CorrS and CorrW (with posterior probability exceeding .99, Figure 5). A posterior contrast confirmed that the CorrS parameter was greater than the CorrW parameter, μ = 0.258, SD = 0.075, P(CorrS − CorrW > 0) = .9997. The 95% credible interval for the contrast was [0.111, 0.405]. Thus, feedback precision or feedback-related evidence was substantially greater in the speaking condition than in the writing condition.
While model results showed higher likelihood precision for early responses in the speaking condition than in the writing condition, they also allowed us to examine a secondary model-derived contrast: the relative correctness of the best-supported response-timing policy in each production-modality state. In the present model, the best-supported policy under the speaking state is early responding, whereas the best-supported policy under the writing state is late responding. Therefore, from Table 2, we computed the difference between the model-implied probability of correct feedback for early responding under speaking and the model-implied probability of correct feedback for late responding under writing:
This quantity does not correspond to the raw behavioral accuracy difference shown in Table 1. Rather, it indexes whether the policy favored under speaking yields a higher model-implied probability of correct feedback than the policy favored under writing. Heuristically, because the active-inference agent selects the response-timing policy expected to generate the preferred outcome, namely correct feedback, this contrast asks whether the best-supported speaking policy produces better expected feedback than the best-supported writing policy.
A Bayesian one-sample t-test of this contrast showed that the speaking-favored policy had slightly higher model-implied correctness than the writing-favored policy, , . The 95% credible interval for the contrast was ,0.003]. Although this difference is numerically small, the Bayes factor indicates strong evidence [35] that the contrast is reliably positive. This result should therefore be interpreted as a policy-conditioned, speaking-over-writing correctness advantage, whereas the primary computational signature of the speaking-over-writing advantage remains the contrast .
3.2.2. Pragmatic Values and Posterior Probabilities Across Response-Timing Policies
Using the group-level likelihood estimates, and , we computed the expected pragmatic value of each response-timing policy as the expected preference for feedback outcomes. Because correct feedback was assigned and incorrect feedback was assigned , the pragmatic value of a policy was . Under speaking, early responding had pragmatic value , whereas late responding had pragmatic value . Under writing, this pattern reversed: early responding had pragmatic value , whereas late responding had pragmatic value . Thus, the adaptive policy had a pragmatic advantage of in each production-modality state. After precision-weighting by , these values yielded posterior policy probabilities of approximately and in the speaking condition, with the reverse pattern in the writing condition. This shows that the group-level likelihood parameters produce a systematic pragmatic bias toward early responding under speaking and late responding under writing.
3.2.3. Post-Hoc Analysis of Model Complexity
The POMDP embodies the theoretical construct of a hidden contextual cause of retrieval, operationalized as production-modality-specific policy-feedback precision. Does the additional mechanistic structure introduced by the active-inference POMDP improve the explanation of the data sufficiently to justify its greater complexity? If the increased complexity did not add explanatory value, then a simpler descriptive model should provide a better account of the data once model complexity was taken into account. To answer this question, we compared the POMDP model against a simpler linear model addressing the effect of condition and accuracy on response time under Variational Laplace [39]. Crucially, Variational Laplace allows for the comparison of models with different likelihood functions using Bayesian model selection and variational free energy. Therefore, we adjudicated between the active inference model and the linear model based on their free energies. Bayesian model selection supported the POMDP, yielding a protected exceedance probability of 0.99 and a Bayesian omnibus risk (BOR) of less than 0.001.
4. Discussion
The present study developed a formal active-inference account of the speaking-over-writing advantage in the retrieval of the production modality of individual words. The model represented speaking and writing as contextual states that altered the expected sensory consequences of alternative response-timing policies. Behaviorally, participants identified the production modality of spoken words earlier and more accurately than that of written words. Within the POMDP, this pattern was expressed as a production-modality-specific difference in the likelihood mapping from response timing to feedback: early responding was more strongly associated with correct feedback under the speaking state than under the writing state.
The principal computational result was the group-level difference between the (CorrS) and (CorrW) parameters. (CorrS) quantified the model-implied probability that an early response would generate correct feedback under the speaking state, whereas (CorrW) quantified the corresponding probability under the writing state. The posterior contrast indicated that (CorrS) was greater than (CorrW). In the context of the present model, this contrast constitutes the primary computational expression of the speaking-over-writing advantage.
Based on the POMDP architecture, production modality was not modeled as a state that the agent had to discover during each trial. Instead, the speaking or writing state provided the contextual condition under which the consequences of early and late responding were evaluated. The production-modality state was therefore important because it determined the likelihood mapping between response timing and feedback. Feedback, in turn, supplied observable sensory evidence about the response generated under that contextual state.
Because correct feedback was preferred and incorrect feedback was avoided, policies expected to generate correct feedback received greater posterior support. When (CorrS>.5), an early response is more likely than a late response to generate correct feedback under the speaking state. Conversely, when (CorrW<.5), a late response is more likely than an early response to generate correct feedback under the writing state. The model therefore characterizes the faster recognition of spoken words as a difference in the expected reliability of early and late responding across production modalities. It does not imply that response timing itself causes accurate retrieval. Rather, response timing is treated as an observable expression of when participants acted on their current beliefs about the earlier production episode.
This formulation speaks to the role assigned to sensory consequences. In the real-life example introduced at the beginning of the paper, the correctness of a retrieved name is not directly observable. What becomes observable is the consequence of saying the name, such as a smile, a smooth continuation of the interaction, confusion, or correction. The expected response of the other person can therefore contribute to the evaluation of whether and when to act on the retrieved name. This does not mean that social approval is sought independently of retrieval accuracy. Instead, approving feedback is informative because, in that context, it is expected to follow an accurate response.
The experimental task instantiated a simplified version of this relationship. Participants acted on a belief about whether a word had previously been spoken or written and subsequently received explicit feedback indicating whether their judgment was correct. Correct feedback was therefore the observable consequence associated with an accurate recognition response. Within the scope of the present model, the production-modality context and the expected feedback outcome jointly constrained the relative support for early and late response policies. The model thus offers a formal characterization of how spoken and written contextual traces may differ in the precision with which they inform temporally expressed recognition decisions.
4.1. Relation to the Comparison Model
The linear model described associations among production condition, response accuracy, and response time. It therefore addressed whether speaking and writing were associated with different behavioral outcomes. The POMDP addressed a different, more specific question by representing the task as a sequence in which a production-modality state contextualized the selection of an early or late response policy and the subsequent observation of feedback.
The comparison speaks to two approaches that differ in explanatory scope. The linear model summarized relations among observed variables, whereas the POMDP made explicit a proposed latent structure connecting production modality, response timing, expected feedback, and belief updating. Bayesian model selection favored the POMDP over the particular linear model considered here, suggesting that this additional structure provided a better balance of model fit and complexity within the present comparison.
Accordingly, the contribution of the POMDP lies primarily in formalization and model complexity worthiness. It translates the verbal proposal that spoken and written production traces may differentially inform action into a generative model with explicit states, policies, observations, preferences, and likelihood mappings. This formalization makes the proposal quantitatively evaluable and identifies the (CorrS-CorrW) contrast as its central parameter-level implication. Note, however, that support relative to one linear comparison model does not establish that the POMDP is superior to all plausible accounts of recognition memory or response timing.
4.2. Production Modality, Precision, and Feedback
The (CorrS) and (CorrW) parameters refer to likelihood precision, in the restricted sense represented by the model. They quantify the reliability with which the joint configuration of response timing and production modality maps onto feedback. They should therefore be described more precisely as policy-outcome or feedback-related likelihood parameters, rather than as direct measures of the strength of the memory trace, subjective confidence, or neural precision.
The finding that (CorrS) exceeded (CorrW) is compatible with the proposal developed in the introduction that spoken and written production-modality traces differ in how reliably they support recognition-policy selection. Spoken production provides auditory and articulatory contextual information in addition to the visual characteristics of the word. Written production instead provides orthographic, visual, and motor contextual information. Notably, the present results are consistent with spoken contextual information supporting a more reliable association between early responding and correct feedback. Nevertheless, the model does not separately estimate the contribution of auditory, articulatory, visual, orthographic, or motor features. It therefore cannot determine which specific features account for the observed difference.
The findings also speak to active-inference accounts in which precision modulates the influence of sensory evidence on beliefs [25,26,27,29]. Specifically, more reliable likelihood mappings produce more differentiated beliefs about the consequences of alternative policies. In the context of the present task, the estimated mappings suggest that the expected consequences of early and late responding differed more clearly under the speaking state than under the writing state. This interpretation concerns precision within the formal model and should not be taken as direct evidence of attentional gain, neural precision, or a particular physiological mechanism.
4.3. Group-Level Pattern and Individual Variability
At the group level, most participants showed the expected (CorrS>CorrW) pattern, although the magnitude and direction of the contrast varied across individuals. A small number of participants showed approximately balanced or reversed parameter profiles. These observations suggest that the group-level tendency was not expressed identically by every participant.
Interestingly, such variability may eventually prove useful for studying individual differences in how spoken and written contextual information supports retrieval. At present, however, this interpretation should be considered preliminary. The sample was not designed to identify stable participant subtypes, and the study did not include repeated testing or a formal assessment of parameter reliability. Reversed or attenuated profiles could reflect meaningful differences in production strategy, writing experience, confidence, or response style, but they could also reflect sampling variability or limited information at the individual level. Our interpretation, therefore, suggests a future research direction.
Furthermore, the distinction between group effects and individual reliability is particularly relevant in light of the reliability paradox [40]. A robust experimental effect at the group level does not necessarily provide a reliable measure of individual differences. Model-derived parameters may offer advantages over raw difference scores when they successfully isolate a stable latent process, but this possibility must be demonstrated rather than assumed. In the present study, (CorrS) and (CorrW) are best regarded as theoretically interpretable candidate parameters for future reliability research.
4.4. Scope of the Interpretation in the Context of Discourse Production
The present task examined source recognition for individually produced words. It was not designed to address the broader cognitive or epistemic functions of speaking and writing [41,42,43]. Writing is typically slower than speaking and may support greater elaboration, externalization, revision, and development of knowledge [44,45]. These properties may be advantageous in tasks involving sentence production, conceptual organization, learning, or long-term knowledge construction, even though writing was associated here with slower and less accurate recognition of the production modality of individual words.
The speaking-over-writing advantage observed in this task should therefore not be interpreted as a general cognitive superiority of speaking over writing at the discourse level. It is specific to the retrieval of how isolated words were produced under the present experimental conditions. Future studies could examine whether the same parameter pattern is observed when participants produce sentences, extended discourse, or semantically integrated material. Such tasks may reveal different relations among production modality, response timing, and expected outcomes.
The present modeling approach could also be adapted to the broader recognition advantage observed when produced items are compared with silently read items, often termed the production effect [2,14]. Such an extension would require a task and model architecture different from those examined here. The present model concerns source judgments between speaking and writing and represents production modality as a contextual state that constrains the expected consequences of early and late responding. A produced-versus-silent recognition model would instead need to represent whether an item had been produced, how production-related contextual features distinguish studied items from lures, and how those features contribute to old–new recognition judgments. The present findings therefore do not directly explain this broader phenomenon. Rather, the model provides a formal element—context-dependent mappings among retrieved features, response policies, and feedback—that could be examined in a task designed specifically for that purpose.
Extending the model in this direction could also permit constructive comparison with established computational accounts of recognition memory. Global-matching models such as MINERVA 2 [15] and REM [8] formalize recognition in terms of the similarity between retrieval cues and stored traces, whereas distinctiveness-based accounts emphasize the diagnostic value of features generated during production. An active-inference formulation could complement these approaches by representing how retrieved contextual evidence informs action selection in relation to expected sensory consequences. Future work could examine whether these frameworks provide compatible, partially overlapping, or distinct descriptions of produced-versus-read recognition when evaluated using comparable behavioral data. The present study should therefore be viewed as a restricted foundation for such future comparisons, rather than as a model of the production effect itself.
4.5. Limitations to be Addressed in Future Studies
While the present results open a new research avenue in the area of language production and active inference, several limitations need to be addressed in future studies.
First, based on the participant homogeneity and sample size, the robustness and generalizability of the results are limited to comparable participants and comparable experimental conditions.
Second, continuous response times were represented as early and late response policies. This distinction was introduced to instantiate alternative temporal policies within the discrete POMDP architecture, rather than simply as a convenient statistical reduction. Nevertheless, assigning responses to two policy classes necessarily omits variation within each class. Future work should compare the present formulation with models that retain continuous response times or represent a greater number of temporally extended policies.
Third, the model contained only two timesteps and two response-timing policies. This intentionally minimal architecture captures the decision to act relatively early or to delay responding, but it does not specify the processes occurring during the delay. A later response could reflect uncertainty, hesitation, additional retrieval operations, motor preparation, or other processes. A richer model could include additional timesteps and an explicit wait policy, allowing the consequences of continued sampling or delayed commitment to be examined without assuming that later responses necessarily reflect evidence accumulation.
Fourth, feedback was represented within each trial as an observation generated by the joint configuration of production modality and response timing. In the experimental task, however, feedback may also have influenced expectations across trials. The current model does not estimate such learning. A hierarchical or temporally extended model could allow participants to update beliefs about the reliability of early and late responding over the course of the experiment.
Fifth, the production-modality state was fixed by the trial structure. The model therefore characterizes how the speaking or writing context changes expected policy outcomes, but it does not model the initial reconstruction or inference of production modality itself. A more complete source-memory model could represent uncertainty over whether the probe had been spoken or written and examine how modality-specific contextual evidence contributes to resolving that uncertainty.
Sixth, the model did not separately represent recognition accuracy and response timing as distinct outcome modalities. Instead, feedback was generated from their modeled relationship under the production-modality state. Although this architecture served the present theoretical objective, alternative formulations could model the recognition choice, response latency, confidence, and feedback as separate but interacting observations.
Finally, the model was compared with a relatively simple linear alternative. The model-selection result therefore provides evidence only within the tested comparison set. Future work should compare the present POMDP with other plausible generative accounts, including global-matching models, source-memory models, sequential-sampling models, and active-inference models with continuous or more deeply structured temporal policies.
5. Conclusions
The present study provides a preliminary formal account of the speaking-over-writing advantage in retrieving the production modality of individually produced words. Behaviorally, participants identified spoken production more quickly and accurately than written production. Within the POMDP, this advantage was expressed as a stronger association between early responding and correct feedback under the speaking state than under the writing state. The positive (CorrS-CorrW) contrast therefore constitutes the primary computational signature of the empirical pattern within the present model.
By representing production modality as a contextual state, response timing as policy selection, and correct or incorrect feedback as an observable sensory consequence, the model connects the behavioral pattern to an explicit inferential architecture. The results do not establish this architecture as a complete or unique explanation of the speaking-over-writing advantage. Rather, they show that an intentionally minimal active-inference model can formalize how spoken and written production contexts may differentially constrain the expected consequences of acting relatively early or late on a recognition belief.
This framework provides a basis for further comparison with alternative models and for extensions that represent uncertainty about production modality, continuous response timing, learning across trials, and richer forms of linguistic production. In this sense, the present contribution is a focused first step toward modeling how production-modality context and expected sensory consequences jointly contribute to recognition behavior.
Author Contributions
Conceptualization, A.S., and R.L.; methodology, R.L, O.O.; software, R.L.; formal analysis, R.L.; investigation, O.O, R.L; resources, R.L.; writing—original draft preparation, A.S., O.O, R.L; writing—review and editing, A.S., O.O, and R.L.; supervision, R.L.; funding acquisition, R.L. All authors have read and agreed to the published version of the manuscript.
Funding
This research was funded by the Social Sciences and Humanities Research Council, Insight Development Grant 430-2024-00727.
Institutional Review Board Statement
The study was conducted in accordance with the Declaration of Helsinki, and approved by Brandon University Research Ethics Committee (protocol code 23412, October 2, 2024).
Informed Consent Statement
Informed consent was obtained from all subjects involved in the study.
Data Availability Statement
Modeling scripts and raw data files can be downloaded from the Writing-brain laboratory website https://people.brandonu.ca/limongir/home/the-writing-brain-laboratory/.
Conflicts of Interest
All authors declare no conflict of interest.
References
- Friston, K.J.; Salvatori, T.; Isomura, T.; Tschantz, A.; Kiefer, A.; Verbelen, T.; Koudahl, M.; Paul, A.; Parr, T.; Razi, A.; et al. Active Inference and Intentional Behavior. Neural Comput. 2025, 37, 666–700. [Google Scholar] [CrossRef] [PubMed]
- MacLeod, C.M.; Gopie, N.; Hourihan, K.L.; Neary, K.R.; Ozubko, J.D. The production effect: delineation of a phenomenon. J. Exp. Psychol. Learn Mem. Cogn. 2010, 36, 671–685. [Google Scholar] [CrossRef] [PubMed]
- Fawcett, J.M.; Roberts, B.R.T.; Hu, S.; Thoms, C.W.J.; MacLeod, C.M.; Willoughby, H. Preparing to produce (without production) is sufficient to elicit a behavioral and pupillometric production effect. PsyArXiv 2025. [Google Scholar] [CrossRef]
- Mama, Y. The Production Effect in Implicit Memory. Exp. Psychol. 2024, 71, 298–311. [Google Scholar] [CrossRef] [PubMed]
- Kelly, M.O.; Ensor, T.M.; MacLeod, C.M.; Risko, E.F. The prod eff: Partially producing items moderates the production effect. Psychon. Bull. Rev. 2024, 31, 373–379. [Google Scholar] [CrossRef] [PubMed]
- Caplan, J.B.; Guitard, D. A Feature-Space Theory of the Production Effect in Recognition; Hogrefe Publishing, 2024; Volume 71, pp. 64–82. [Google Scholar]
- Wakeham-Lewis, R.M.; Ozubko, J.; Fawcett, J.M. Characterizing production: the production effect is eliminated for unusual voices unless they are frequent at study. Memory 2022, 30, 1319–1333. [Google Scholar] [CrossRef] [PubMed]
- Kelly, M.O.; Ensor, T.M.; Lu, X.; MacLeod, C.M.; Risko, E.F. Reducing retrieval time modulates the production effect: Empirical evidence and computational accounts. J. Mem. Lang. 2022, 123, 104299. [Google Scholar] [CrossRef]
- Gionet, S.; Guitard, D.; Saint-Aubin, J. The Production Effect Interacts With Serial Positions. Exp. Psychol. 2022, 69, 12. [Google Scholar] [CrossRef] [PubMed]
- Cyr, V.; Poirier, M.; Yearsley, J.M.; Guitard, D.; Harrigan, I.; Saint-Aubin, J. The production effect over the long term: Modeling distinctiveness using serial positions. J. Exp. Psychol. Learn. Mem. Cogn. 2022, 48, 1797–1820. [Google Scholar] [CrossRef] [PubMed]
- Saint-Aubin, J.; Yearsley, J.M.; Poirier, M.; Cyr, V.; Guitard, D. A model of the production effect over the short-term: The cost of relative distinctiveness. J. Mem. Lang. 2021, 118, 104219. [Google Scholar] [CrossRef]
- Mama, Y.; Icht, M. Production Effect in Adults With ADHD With and Without Methylphenidate (MPH): Vocalization Improves Verbal Learning. J. Int. Neuropsychol. Soc. JINS 2019, 25, 230–235. [Google Scholar] [CrossRef] [PubMed]
- Mama, Y.; Fostick, L.; Icht, M. The impact of different background noises on the Production Effect. Acta Psychol. 2018, 185, 235–242. [Google Scholar] [CrossRef] [PubMed]
- MacLeod, C.M.; Bodner, G.E. The Production Effect in Memory. Curr. Dir. Psychol. Sci. 2017, 26, 390–395. [Google Scholar] [CrossRef]
- Jamieson, R.K.; Mewhort, D.J.K.; Hockley, W.E. A computational account of the production effect: Still playing twenty questions with nature. Can. J. Exp. Psychol. Rev. Can. De Psychol. Expérimentale 2016, 70, 154–164. [Google Scholar] [CrossRef] [PubMed]
- Bodner, G.E.; Jamieson, R.K.; Cormack, D.T.; McDonald, D.L.; Bernstein, D.M. The production effect in recognition memory: Weakening strength can strengthen distinctiveness. Can. J. Exp. Psychol. 2016, 70, 93–98. [Google Scholar] [CrossRef] [PubMed]
- Icht, M.; Mama, Y.; Algom, D. The production effect in memory: multiple species of distinctiveness. Front Psychol. 2014, 5, 886. [Google Scholar] [CrossRef] [PubMed]
- Forrin, N.D.; MacLeod, C.M.; Ozubko, J.D. Widening the boundaries of the production effect. Mem. Cogn. 2012, 40, 1046–1055. [Google Scholar] [CrossRef] [PubMed]
- MacLeod, C.M. I said, you said: The production effect gets personal. Psychon. Bull. Rev. 2011, 18, 1197–1202. [Google Scholar] [CrossRef] [PubMed]
- Ozubko, J.D.; Macleod, C.M. The production effect in memory: evidence that distinctiveness underlies the benefit. J. Exp. Psychol. Learn Mem. Cogn. 2010, 36, 1543–1547. [Google Scholar] [CrossRef] [PubMed]
- Friston, K.J.; FitzGerald, T.; Rigoli, F.; Schwartenbeck, P.; Pezzulo, G. Active Inference: A Process Theory. Neural Comput. 2016, 23, 1–49. [Google Scholar] [CrossRef] [PubMed]
- Friston, K. The free-energy principle: a unified brain theory? Nat. Rev. Neurosci. 2010, 11, 127–138. [Google Scholar] [CrossRef] [PubMed]
- Friston, K. The free-energy principle: a rough guide to the brain? Trends Cogn. Sci. 2009, 13, 293–301. [Google Scholar] [CrossRef] [PubMed]
- Smith, R.; Friston, K.J.; Whyte, C.J. A step-by-step tutorial on active inference and its application to empirical data. J. Math. Psychol. 2022, 107, 102632. [Google Scholar] [CrossRef] [PubMed]
- Parr, T.; Pezzulo, G.; Friston, K.J. Active Inference: The Free Energy Principle in Mind, Brain, and Behavior; MIT Press: Cambridge, MA, 2022. [Google Scholar]
- Parr, T.; Friston, K.J. Attention or salience? Curr. Opin. Psychol. 2019, 29, 1–5. [Google Scholar] [CrossRef] [PubMed]
- Parr, T.; Friston, K.J. Working memory, attention, and salience in active inference. Sci. Rep. 2017, 7, 14678. [Google Scholar] [CrossRef] [PubMed]
- Auksztulewicz, R.; Friston, K. Attentional Enhancement of Auditory Mismatch Responses: a DCM/MEG Study. Cereb. Cortex 2015, 25, 4273–4283. [Google Scholar] [CrossRef] [PubMed]
- Feldman, H.; Friston, K.J. Attention, uncertainty and free-energy. Front Hum. Neurosci. 2010, 4, 1–23. [Google Scholar] [CrossRef] [PubMed]
- Da Costa, L.; Parr, T.; Sajid, N.; Veselic, S.; Neacsu, V.; Friston, K. Active inference on discrete state-spaces: A synthesis. J. Math. Psychol. 2020, 99, 102447. [Google Scholar] [CrossRef] [PubMed]
- Ratcliff, R. A theory of memory retrieval. Psychol. Rev. 1978, 85, 59–108. [Google Scholar] [CrossRef]
- Parr, T.; Markovic, D.; Kiebel, S.J.; Friston, K.J. Neuronal message passing using Mean-field, Bethe, and Marginal approximations. Sci. Rep. 2019, 9, 1–18. [Google Scholar] [CrossRef] [PubMed]
- Rouder, J.N. Optional stopping: No problem for Bayesians. Psychon. Bull. Rev. 2014, 21, 301–308. [Google Scholar] [CrossRef] [PubMed]
- Tendeiro, J.N.; Kiers, H.A.L.; van Ravenzwaaij, D. Worked-out examples of the adequacy of Bayesian optional stopping. Psychon. Bull. Rev. 2022, 29, 70–87. [Google Scholar] [CrossRef] [PubMed]
- Jeffreys, H. Theory of Probability; Oxford University Press: Oxford, 1961. [Google Scholar]
- Unit, S.L. Strathy Corpus of Canadian English; 2024. [Google Scholar]
- Team, J. JASP (Version 0.18) [Computer software]. 2024. Available online: https://jasp-stats.org/.
- Smith, R.; Kuplicki, R.; Feinstein, J.; Forthman, K.L.; Stewart, J.L.; Paulus, M.P.; Tulsa, i.; Khalsa, S.S. A Bayesian computational model reveals a failure to adapt interoceptive precision estimates across depression, anxiety, eating, and substance use disorders. PLoS Comput. Biol. 2020, 16, e1008484. [Google Scholar] [CrossRef] [PubMed]
- Zeidman, P.; Friston, K.; Parr, T. A primer on Variational Laplace (VL). Neuroimage 2023, 279, 120310. [Google Scholar] [CrossRef] [PubMed]
- Haines, N.; Kvam, P.D.; Irving, L.; Smith, C.T.; Beauchaine, T.P.; Pitt, M.A.; Ahn, W.-Y.; Turner, B.M. A tutorial on using generative models to advance psychological science: Lessons from the reliability paradox. Psychol. Methods 2025. [Google Scholar] [CrossRef] [PubMed]
- Limongi, R.; Peters, A.; Silva, A.M. An active-inference model of the effect of epistemic writing on long-term memory consolidation. Conference Paper Presented at SIG Writing 2024, Paris, France, 2024. [Google Scholar]
- Silva, A.M.; Limongi, R. Writing to Learn Increases Long-term Memory Consolidation: A Mental-chronometry and Computational-modeling Study of “Epistemic Writing”. J. Writ. Res. 2019, 11, 211–243. [Google Scholar] [CrossRef]
- Silva, A.M.; Limongi, R. La Escritura Epistémica en Contextos Académico Profesionales: Desafíos de Investigación Educativa, Cognitiva y Neurocientífica. Rev. Educ. Super. Y Soc. (ESS) 2017, 1, 41–58. [Google Scholar]
- Biber, D. Variation across speech and writing; Cambridge University Press: Cambridge, UK, 1988. [Google Scholar]
- Baaijen, V.M.; Galbraith, D. Discovery Through Writing: Relationships with Writing Processes and Text Quality. Cogn. Instr. 2018, 36, 199–223. [Google Scholar] [CrossRef]
Figure 1.
Everyday example of production-modality retrieval as policy evaluation. The equation on the right represents the posterior probability of selecting a response policy, as described in Section 1.2.
Figure 1.
Everyday example of production-modality retrieval as policy evaluation. The equation on the right represents the posterior probability of selecting a response policy, as described in Section 1.2.
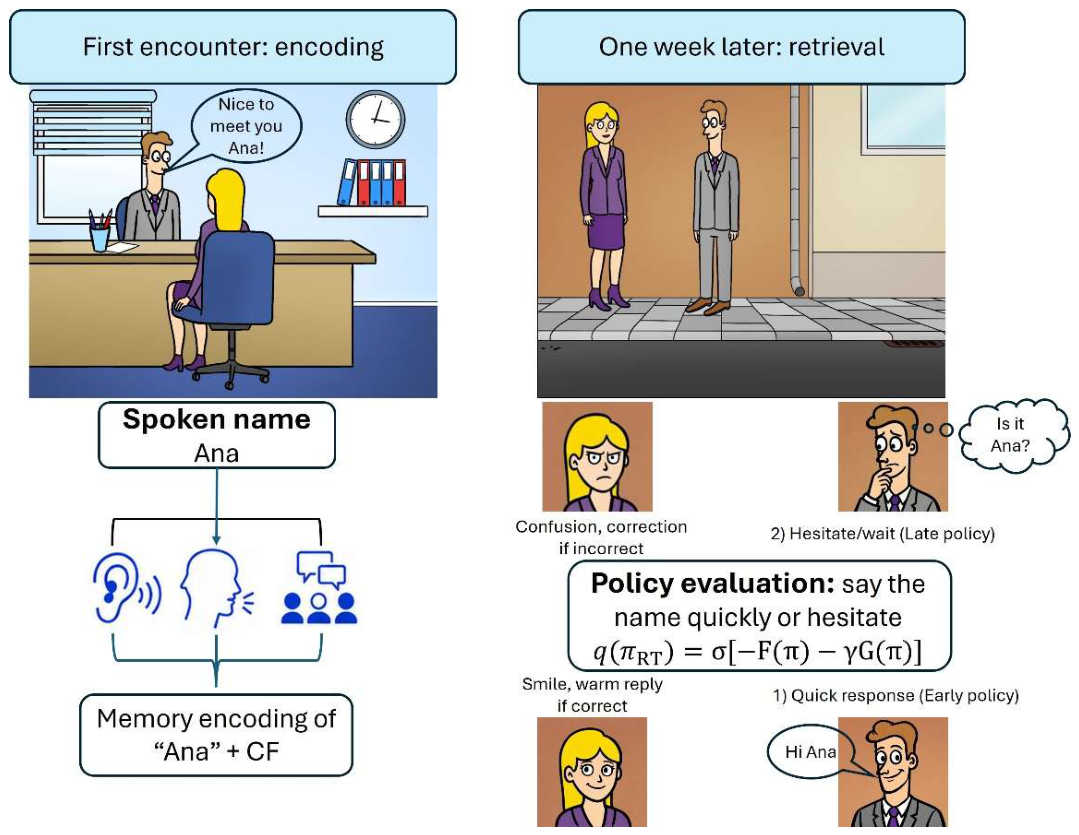
Figure 2.
Experimental task block. Participants performed 9 blocks of 20 trials in two phases: language production phase and memory phase. As shown in the production phase, the language modality was cued by the word color (speaking in red, writing in green) counterbalanced across participants. In the memory phase, participants responded by pressing relevant keys whether the word was spoken or written (colored buttons do not represent the actual response keys which where “S” for speaking and “W” for writing). Participants observed feedback at the time of response. A partially observable Markov decision process model (POMDP) instantiates the two timesteps corresponding to the memory phase. In the model, see text for details, the response state transition (from no response at timestep one to early or late response state at timestep 2) is dictated by the B matrix. The A matrix expresses the likelihood of observing no-feedback, incorrect, or correct feedback at each timestep.
Figure 2.
Experimental task block. Participants performed 9 blocks of 20 trials in two phases: language production phase and memory phase. As shown in the production phase, the language modality was cued by the word color (speaking in red, writing in green) counterbalanced across participants. In the memory phase, participants responded by pressing relevant keys whether the word was spoken or written (colored buttons do not represent the actual response keys which where “S” for speaking and “W” for writing). Participants observed feedback at the time of response. A partially observable Markov decision process model (POMDP) instantiates the two timesteps corresponding to the memory phase. In the model, see text for details, the response state transition (from no response at timestep one to early or late response state at timestep 2) is dictated by the B matrix. The A matrix expresses the likelihood of observing no-feedback, incorrect, or correct feedback at each timestep.
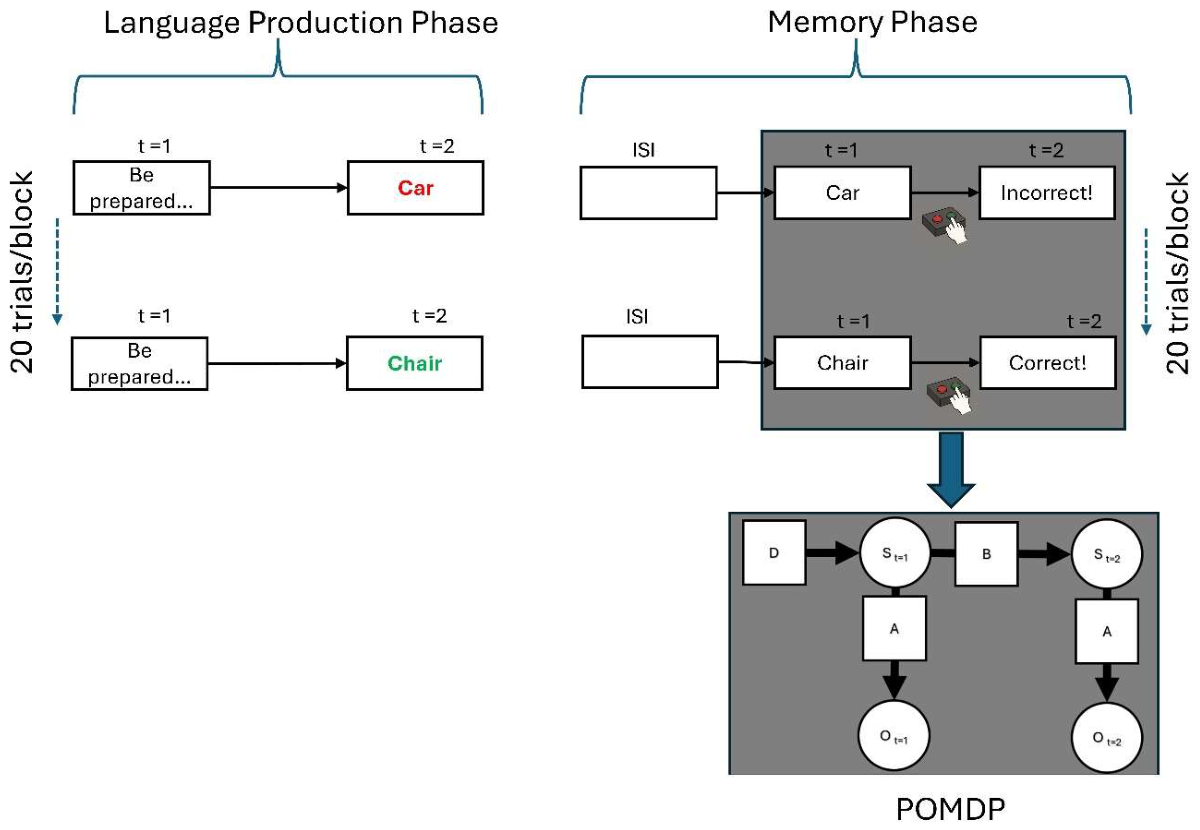
Figure 3.
Factor graph of the POMDP model. CorrS (Correct-speaking parameter), CorrW (Correct-writing parameter). D matrix represents beliefs at the beginning of a trial. A matrix represents the state-outcome mappings. The B matrix represents Markovian transitions (policy-dependent state-transition probabilities). The C matrix encodes preferred observations (note that at t=2 correct feedback is slightly preferred to incorrect feedback).
Figure 3.
Factor graph of the POMDP model. CorrS (Correct-speaking parameter), CorrW (Correct-writing parameter). D matrix represents beliefs at the beginning of a trial. A matrix represents the state-outcome mappings. The B matrix represents Markovian transitions (policy-dependent state-transition probabilities). The C matrix encodes preferred observations (note that at t=2 correct feedback is slightly preferred to incorrect feedback).
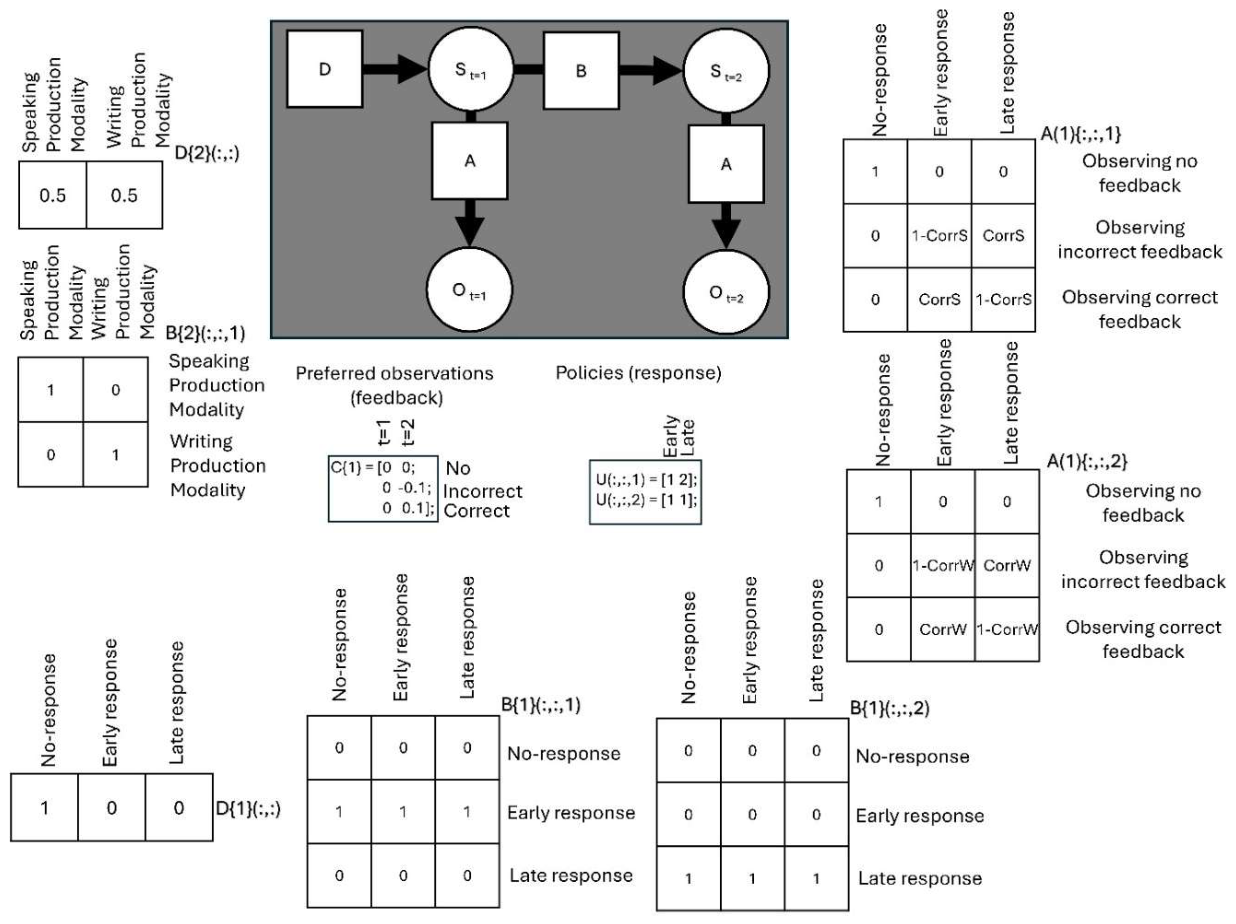
Figure 4.
Parameter estimates of Bayesian ANCOVA models. Effect of condition on RT (top left), effect of condition on response (word memory retrieval) accuracy (top right). Difference in RT held after discretization (bottom left). Bottom right panel shows the group-mean proportions of early (discretized) responses in the speaking and writing conditions, mirroring the behavioral pattern of the raw RTs.
Figure 4.
Parameter estimates of Bayesian ANCOVA models. Effect of condition on RT (top left), effect of condition on response (word memory retrieval) accuracy (top right). Difference in RT held after discretization (bottom left). Bottom right panel shows the group-mean proportions of early (discretized) responses in the speaking and writing conditions, mirroring the behavioral pattern of the raw RTs.
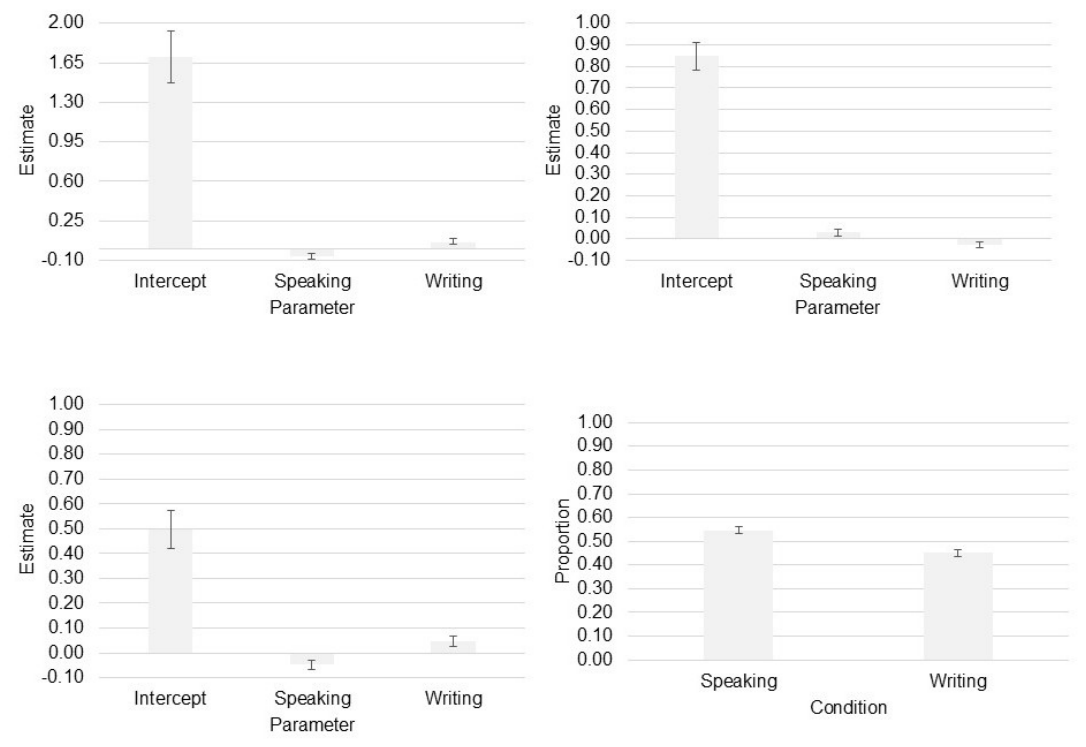
Figure 5.
Group-level PEB results for likelihood parameters. Left, panel A shows the second-level PEB design matrix used to estimate group-level effects across participants. The model included one second-level covariate, corresponding to the group mean, two first-level DCM parameters, and 16 subjects. Panel B shows the posterior covariance structure for the two first-level parameters included in the PEB model. Panel C shows the estimated group-level posterior parameters. Right, AccDiff (policy-conditioned speaking-over-writing correctness advantage).
Figure 5.
Group-level PEB results for likelihood parameters. Left, panel A shows the second-level PEB design matrix used to estimate group-level effects across participants. The model included one second-level covariate, corresponding to the group mean, two first-level DCM parameters, and 16 subjects. Panel B shows the posterior covariance structure for the two first-level parameters included in the PEB model. Panel C shows the estimated group-level posterior parameters. Right, AccDiff (policy-conditioned speaking-over-writing correctness advantage).
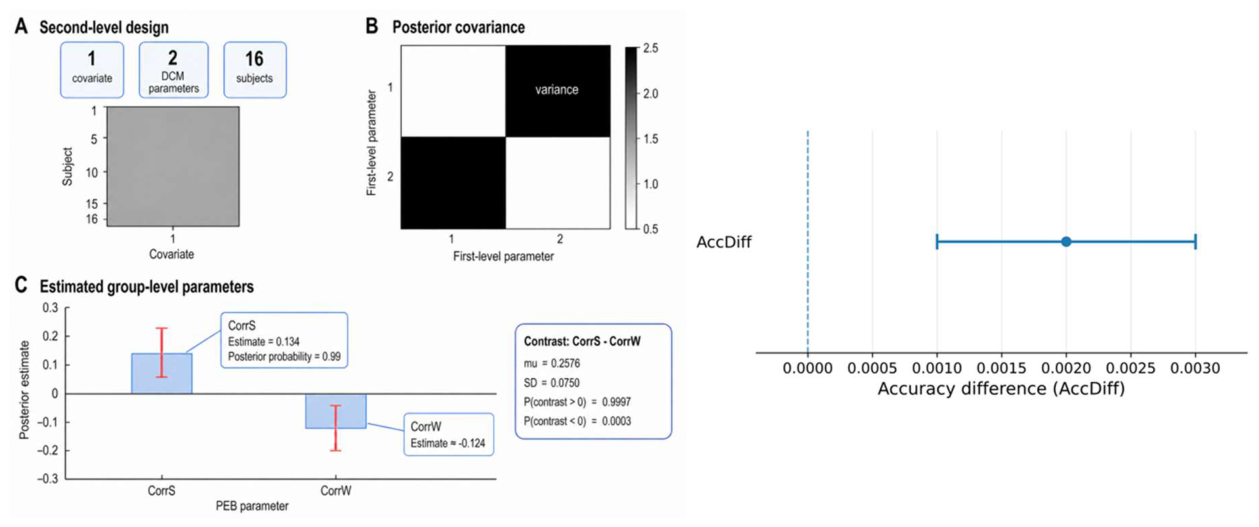

Table 1.
Descriptive Statistics.
| Speaking (M ± SD) | Writing (M ± SD) | |
|---|---|---|
| Number of Trials | 82.50 ± 8.76 | 82.94 ± 8.07 |
| RT (s) | 1.64 ± 0.38 | 1.77 ± 0.40 |
| Proportion Correct | 0.88 ± 0.07 | 0.81 ± 0.12 |
| Proportion Incorrect | 0.12 ± 0.07 | 0.19 ± 0.12 |
Note. Values represent subject-level means (M) and standard deviations (SD).
Table 2.
Parameter estimates of the POMDP model.
| Participant | CorrS | CorrW | AccDiff |
|---|---|---|---|
| 001 | 0.4916 | 0.5108 | 0.0025 |
| 002 | 0.6014 | 0.3961 | -0.0025 |
| 003 | 0.5413 | 0.4616 | 0.0030 |
| 004 | 0.5403 | 0.4646 | 0.0048 |
| 005 | 0.5464 | 0.4586 | 0.0050 |
| 006 | 0.5210 | 0.4794 | 0.0004 |
| 007 | 0.5360 | 0.4656 | 0.0016 |
| 008 | 0.5210 | 0.4789 | -0.0001 |
| 009 | 0.5511 | 0.4497 | 0.0007 |
| 010 | 0.5588 | 0.4452 | 0.0040 |
| 011 | 0.5362 | 0.4657 | 0.0019 |
| 012 | 0.4112 | 0.5936 | 0.0047 |
| 013 | 0.5137 | 0.4896 | 0.0032 |
| 014 | 0.5352 | 0.4693 | 0.0045 |
| 015 | 0.5483 | 0.4536 | 0.0019 |
| 016 | 0.5611 | 0.4389 | -0.0001 |
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (http://creativecommons.org/licenses/by/4.0/).
Copyright: This open access article is published under a Creative Commons CC BY 4.0 license, which permit the free download, distribution, and reuse, provided that the author and preprint are cited in any reuse.