

Submitted:
16 October 2026
Posted:
19 October 2026
You are already at the latest version
Abstract
Chile represents the southern limit of the historical diversification of maize in the Americas. Across its pronounced latitudinal and altitudinal gradients, centuries of farmer selection, seed exchange, and adaptation to contrasting environments gave rise to a distinctive set of local races. These races are now conserved in the national collection maintained by INIA. Despite its value as a reservoir of adaptive diversity, this germplasm has remained poorly characterized: previous molecular studies were limited to specific groups or to a few accessions within continental surveys. This study aimed to characterize, for the first time at the genome-wide level, the genetic diversity, population structure, and linkage disequilibrium of the collection, and to establish a representative core collection. 1,157accessions were genotyped as DNA bulks using 20,956 DArTseq SNP markers. The main genetic division followed ecogeographic rather than racial boundaries. It separated a genetically homogeneous northern Andean group of floury maize from a more diverse and admixed central-southern complex. At finer resolution, groups associated with specific races emerged, while some traditionally distinguished races were genetically indistinguishable. Landraces harbored allelic variation largely absent from breeding materials, confirming their role as the main reservoir of diversity in the collection. Genetic inference also allowed accessions with incomplete passport data to be classified. A stratified core collection (n=231 accessions) retained virtually all the genetic diversity, racial representation, and geographic range of the full collection in a fraction of its size. It offers a manageable resource for conservation, characterization, and pre-breeding. These results provide the first genomic framework for the conservation and use of Chilean maize diversity.
Keywords:
Zea mays
; landraces
; DArTseq
; DNA pools
; ex situ conservation
; core collection
; ecogeographic differentiation
; genebank
1. Introduction
Maize (Zea mays L.) is one of the world's major crops and one of the most genetically and phenotypically diverse cultivated species. It was domesticated approximately 9,000 years ago in southwestern Mexico from Zea mays ssp. parviglumis and subsequently dispersed throughout the Americas, diversifying through human selection and adaptation to contrasting environments [1]. Archaeological and genomic evidence indicates that maize reached South America relatively early in its domestication history and diversified further through complex dispersal processes, gene flow, and adaptation to diverse environments and agricultural systems [2,3].
The southward expansion of maize eventually brought the crop into the highly heterogeneous environments of Chile. Archaeobotanical and isotopic evidence documents a long history of maize cultivation and consumption in pre-Hispanic Chile, with increasing importance in agricultural societies of central Chile [4,5]. Cultivation extends across pronounced latitudinal and altitudinal gradients, from extremely arid northern environments to Mediterranean and temperate rainy conditions farther south. Farmer selection, seed exchange, geographic differentiation, and environmental pressures may have contributed to the maintenance and differentiation of local populations. These landraces are represented in the Chilean national maize germplasm collection, alongside improved and advanced breeding materials, including those developed by the Instituto de Investigaciones Agropecuarias (INIA) during the second half of the twentieth century.
Previous molecular studies of Chilean maize have focused on specific germplasm groups or included few Chilean accessions in broader continental surveys [6,7,8]. In contrast, recent SNP-based studies have substantially expanded our understanding of maize genetic diversity elsewhere in the Americas. Genome-wide analyses have revealed genetic differentiation associated with highland adaptation in Mesoamerican and South American maize [9], dispersal history and endosperm type in South American lowland germplasm [10], and genetic structure among highland and lowland landraces from southern South America [11]. More recently, genotyping-by-sequencing of 423 Peruvian accessions revealed genetic diversity and population structure among highland maize races [12]. Despite these advances, the Chilean national maize germplasm collection remains uncharacterized using genome-wide SNP data.
Characterizing this diversity is important for both germplasm conservation and utilization. Landraces may retain variation underrepresented in modern breeding germplasm, and genome-wide studies have demonstrated their potential to broaden the genetic base available for maize improvement [13,14]. In South America, genomic information has also helped resolve relationships among landraces and support the conservation and utilization of locally adapted germplasm [10,11].
High-throughput SNP genotyping enables the characterization of large germplasm collections. Reduced-representation sequencing approaches such as DArTseq [15] generate large numbers of genome-wide markers and have been successfully applied to maize genetic resources, including South American landraces [10]. Genotyping DNA pools provides an efficient strategy for characterizing landrace diversity at the population level [16].
Here, we used DArTseq SNP genotyping to characterize the Chilean national maize germplasm collection conserved by INIA. Our objectives were to (i) assess the extent and distribution of genetic diversity; (ii) determine population structure and genetic relationships among accessions and germplasm groups; (iii) characterize patterns of linkage disequilibrium; and (iv) establish a representative core collection capturing the genetic diversity of the broader collection. The resulting characterization provides a genetic framework for conservation, management, and future use in maize research and breeding.
2. Results
2.1. Distribution of SNP Markers Across the Genome
Of the 20,956 quality-filtered SNP markers, 11,698 (55.8%) were anchored to the 10 maize nuclear chromosomes using B73 RefGen_v4 reference genome, while 9,179 (43.8%) could not be uniquely aligned and were classified as unknown. The remaining markers comprised 72 SNPs (0.3%) not anchored to any nuclear chromosome and 7 (<0.1%) mapped to the mitochondrial genome. None mapped to the chloroplast genome (Figure 1). Of the 9,258 markers that could not be assigned to one of the ten nuclear chromosomes, 72 aligned to unplaced B73 RefGen_v4 scaffolds not yet integrated into the ten pseudomolecules, while the remaining 9,179 had no reported alignment position in the reference assembly.
The number of chromosome-anchored markers ranged from 785 on chromosome 10 to 1,972 on chromosome 1. Marker density in 1 Mb windows was heterogeneous within chromosomes, with regions of reduced or absent coverage interspersed among regions of higher density.
Across all markers, mean MAF, GD, Ho, and Shannon–Wiener index (H) were 0.178, 0.253, 0.270, and 0.398, respectively, with 5.7% missing data (Table 1). For the 11,698 chromosome-anchored SNPs, diversity statistics were broadly consistent across chromosomes: MAF ranged from 0.154 (chromosome 4) to 0.173 (chromosome 9), GD from 0.227 to 0.246, H from 0.367 to 0.389, and missing data from 5.81% to 6.70% (Figure S1, Table S1). These chromosome-anchored markers were slightly less diverse and had slightly more missing data than the 9,258 SNPs that could not be anchored to a chromosome (mean MAF = 0.198, GD = 0.274, H = 0.425, missing data = 5.09%); because the genome-wide means reported in Table 1 are computed across all 20,956 SNPs, they fall just outside the per-chromosome range reported here.
Diversity was compared between 938 landraces and 172 breeding materials using all 20,956 SNPs; the 47 accessions of unknown population type were excluded (Table 1). Landraces had a higher proportion of heterozygous calls (0.292 vs. 0.123), but a smaller difference in GD (0.254 vs. 0.227). The GD of the entire collection (0.253) was close to that of landraces, while breeding materials retained substantial allelic diversity despite their lower proportion of heterozygous calls. MAF and H were also higher in landraces (0.180 vs. 0.158 and 0.400 vs. 0.362, respectively), whereas missing data were higher in breeding materials (14.2% vs. 4.2%).
Alternative alleles were shared between landraces and breeding materials at 20,496 loci (97.8%). At 459 loci (2.2%), the alternative allele occurred exclusively in landraces, compared with one locus (<0.1%) exclusive to breeding materials. Thus, landraces contained allelic variation absent from the breeding-material subset.
Private alleles were assessed for each of the 22 standard races, using 758 landrace accessions (100 of unknown race and 80 of non-standard classification were excluded). Race sample sizes ranged from one accession in Marcame to 111 in Camelia. Alternative alleles occurred in two or more races at 20,951 loci (99.98%) and were absent from all races at one locus (<0.01%). Four loci carried race-private alleles: one locus each in Camelia (carried by LP243 and LP1159), Curagua (LP13), Morocho Blanco (LP804), and Capio Chileno Grande (LP201 and LP209). No private alleles were detected in the remaining 18 races.
2.2. Linkage Disequilibrium Decay
Pairwise linkage disequilibrium (r²) was estimated for 105,700 SNP pairs separated by ≤1 Mb, using the 11,698 chromosome-anchored markers in the 938 landrace accessions. The unbinned distribution showed rapid LD decay with physical distance, approaching background levels within the shortest intervals examined (Figure S2).
Variable-width binning confirmed this pattern (Table S2). Mean r² was 0.052 in the first interval (≤100 bp), already below the 0.10 threshold, and declined to approximately 0.013 beyond 500 kb. The overall mean across all pairs was 0.016. Because mean r² was below 0.10 in the shortest interval, the decay distance could only be resolved to an upper bound of 100 bp.
All ten chromosomes had mean r² below 0.10 in the first 100 bp interval, with no detectable differences in decay distance at this resolution (Figure 2). Chromosome 9 showed comparatively higher mean r² at intermediate distances (5–40 kb), but all chromosomes converged toward similar background levels of approximately 0.01–0.02 beyond 40 kb.
2.3. Structure analysis
The ΔK distribution showed a clear primary peak at K = 2 (ΔK ≈ 15,685), with smaller secondary peaks at K = 6 (ΔK ≈ 5,044) and K = 8 (ΔK ≈ 2,728), indicating hierarchical genetic structure (Figure S3). Results are presented first for K = 2, the broadest level detected.
At K = 2, 184 accessions (15.9%) were assigned to Group 1 and 534 (46.2%) to Group 2 using Q ≥ 0.80. The remaining 439 accessions (37.9%) were classified as admixed (Figure 3A, Table S3A).
K2-Group 1 (n = 184), hereafter the northern Andean group, included 12 races, none accounting for more than ~13% of its accessions. The most frequent were Capio Chileno Grande (n = 24), Choclero (n = 17), Harinoso Tarapaqueño (n = 16), and Capio Chileno Chico (n = 16); 11 accessions were racially unclassifiable and 71 lacked racial classification. Among accessions with available passport data, 86% were collected in Arica y Parinacota, Tarapacá, and Antofagasta Regions, at a mean elevation of 2,656 m (range: 91–3,660 m; median: 2,857 m). Among the 141 accessions with morphological records, 89% had floury grain, 92% white endosperm, and 77% white cobs.
K2-Group 2 (n = 534) was most frequently represented by Ocho Corridas (n = 81), Diente de Caballo (n = 73), Camelia (n = 58), Cristalino Chileno (n = 51), and Araucano (n = 27). Among accessions with passport data, 77.4% were from Metropolitana, O’Higgins, Maule, Ñuble, Biobío and Araucanía Regions, at a mean elevation of 293 m (range: 0–2,518 m; median: 179 m). Among the 367 accessions with morphological records, ears were mainly cylindrical-conical (49%) or cylindrical (47%), grain texture was predominantly corneous/flint (56%), endosperm was most frequently orange (51%), and pericarp was predominantly colorless (98%). Breeding materials were more frequent in K2-Group 2 (23.2%, n = 124) than in K2-Group 1 (8.2%, n = 15). Mean within-group MRD was lower in K2-Group 1 than in K2-Group 2 (0.085 vs. 0.199).
At K = 6, Q ≥ 0.80 assigned accessions to only four groups and left 904 accessions (78.1%) classified as admixed. K6-Group 2 and K6-Group 6 had maximum Q values of 0.671 and 0.565, respectively (Figure 3B). Applying Q > 0.50 allowed assignments to all six groups and reduced the admixed set to 566 accessions (48.9%) (Table S3B). The resulting groups differed in racial composition, geographic distribution, and grain morphology:
- K6-Group 5 (n = 169) closely corresponded to the northern Andean group at K = 2. Among accessions with passport data, 92.0% were recorded in Arica y Parinacota, Tarapacá, and Antofagasta regions, at a mean elevation of 2,670 m. Grain was predominantly floury (90%) with white endosperm (93%).
- K6-Group 2 (n = 47) was dominated by Camelia (87%); its accessions were mainly from Coquimbo and Valparaíso Regions and have corneous grain (100%) and predominantly orange endosperm (97%).
- K6-Group 3 (n = 101) was dominated by Choclero (70%), with most accessions from Valparaíso and Metropolitana Regions and mixed grain characteristics (58% floury).
- K6-Group 4 (n = 205), the largest cluster, included Diente de Caballo (34%) and many accessions with unclassified or missing racial data. Accessions in Group 4 were collected mainly from the Metropolitana Region to the Maule Region and had semi-corneous grain (57%) and yellow endosperm (57%).
- K6-Group 6 (n = 12), the smallest cluster, was dominated by Ocho Corridas (92%). All accessions with passport data (n = 11) were from the southern Biobío and Araucanía Regions and grain was predominantly corneous (91%) with orange endosperm (91%).
- K6-Group 1 (n = 57) lacked a clear racial or geographic association. Morphological records were missing for 75% of its accessions, and breeding materials of undocumented origin predominated (72%, n = 41).
2.4. Hierarchical Cluster Analysis
Ward’s hierarchical clustering of the MRD matrix divided the 1,157 accessions into three main clusters—A (n = 290), B.1 (n = 610), and B.2 (n = 257)—and six subclusters: A.1 (n = 124), A.2 (n = 166), B.1.1 (n = 295), B.1.2 (n = 315), B.2.1 (n = 44), and B.2.2 (n = 213) (Figure 4).
Clustering corresponded closely with STRUCTURE assignments and PCoA ordination. At the three-cluster level, Cluster A contained all accessions assigned to STRUCTURE K2-Group 1 and none assigned to K2-Group 2, while clusters B.1 and B.2 corresponded exclusively to subdivisions within STRUCTURE K2-Group 2. At the six-cluster level, all accessions in subcluster A.2 were assigned to STRUCTURE K6-Group 5, and 91% of those in subcluster B.2.1 were assigned to K6-Group 1. Cluster A had the most negative mean PC1 value (−0.0040) among the three main clusters, congruent with its distinct position along the first PCoA axis.
Across 100 locus-resampling bootstrap replicates, pairwise co-clustering stability was 99.4% and 100.0% for the two K = 2 STRUCTURE groups (Table S4). At K = 6, stability was 96.6% for the northern floury group, 93.1% for Ocho Corridas, and 85.4% for Choclero,78.5% for Camelia, and 74.9% for the Diente de Caballo group. The group associated with undocumented breeding materials showed lower stability (53.3%), in agreement with its heterogeneous genetic composition.
2.5. Principal Coordinates Analysis (PCoA)
The first three principal coordinates explained 11.18%, 5.81%, and 2.41% of the total genetic variation, respectively. All pairwise combinations were plotted, with accessions colored by their STRUCTURE assignments at K = 6 (Figure 5).
The ordination corresponded closely with the STRUCTURE groups. The northern Andean floury-grain group (K6-Group 5) was clearly separated along PC1 (mean = −0.0052). K6-Group 1, K6-Group 6, and K6-Group 4—undocumented breeding materials, Ocho Corridas, and Diente de Caballo, respectively—occupied the opposite extreme with mean PC1 values of 0.0032, 0.0023, and 0.0019, while K6-Group 2 (Camelia) was near the center (0.0007). K6-Group 3 (Choclero) occupied an intermediate position (mean PC1 = −0.0026): 52% of its accessions fell between the ranges of K6-Group 5 and the remaining groups, 46% overlapped with K6-Group 5, and only 2% with the other groups (Figure 5). Accessions classified as Choclero by race (n = 114, including 25 breeding materials) likewise had an intermediate mean PC1 (−0.0019), between the northern races (−0.0053 to −0.0051) and the main central-southern races (0.0008 to 0.0021). This intermediate position was not observed along PC2 or PC3. K6-Group 1 separated distinctly along PC3 (mean = −0.0028). Admixed accessions occupied intermediate positions, consistent with their mixed ancestry.
PC1 was correlated with elevation (r = −0.82) and latitude (r = −0.83; n = 697 accessions with coordinates; p < 0.001 in both cases), reflecting the geographic and altitudinal gradient between the northern Andean highlands and central-southern valleys (Figure S5). In contrast, PC3 showed no association with elevation (r = 0.03), in accordance with its separation of breeding materials of undocumented provenance (K6-Group 1).
2.6. Population Distances
Pairwise FST was estimated among STRUCTURE groups at K = 2 and K = 6 and hierarchical clusters at the three- and six-cluster levels (HC-C3 and HC-C6), using the pool-size-weighted allele-frequency approach.
At K = 2, FST between STRUCTURE Groups 1 and 2 was 0.072 (Table 2). Among HC-C3 clusters, comparisons involving Cluster A showed greater differentiation (0.047–0.076) than B.1–B.2 (0.013), with the highest value for A–B.2 (0.076) (Table S5).
At K = 6, FST ranged from 0.012 between Groups 4 and 6 to 0.201 between Group 1 (undocumented breeding materials) and Group 5 (northern floury group). The second-highest value was between Group 4 (Diente de Caballo) and Group 5 (0.126). In agreement with its intermediate PCoA position, Group 3 was the least differentiated from Group 5 (FST = 0.051), compared with 0.091–0.201 for the other groups. Its differentiation from Groups 2, 4, and 6 was similarly low (0.049–0.053). Among HC-C6 subclusters, FST ranged from 0.008 for B.1.1–B.1.2 to 0.208 for A.2–B.2.1, following a pattern aligned with STRUCTURE (Table S5).
AMOVA detected significant differentiation in all three groupings tested (p ≤ 0.001). At K = 2, differences between groups accounted for 43.5% of total genetic variance, with 56.5% among accessions within groups. At K = 6 (Q > 0.50), these proportions were 40.4% and 59.6%, respectively. Pairwise AMOVA among the 22 standard landrace races (231 comparisons) revealed significant differentiation in 192 pairs (83.1%) after correction for multiple testing (FDR, q < 0.05), with ΦST values ranging up to 0.772 (median 0.227) (Table S6). Of the 39 non-significant comparisons, 38 involved at least one race represented by fewer than 15 accessions. The only non-significant comparison between two races with at least 15 accessions each was Capio Chileno Chico vs. Capio Chileno Grande (ΦST = 0.011; q = 0.122). Four races (Araucano, Camelia, Cristalino Chileno and Diente de Caballo) were significantly differentiated from all other races.2.7. Inference of Population Type and Race for Unclassified Accessions.
Population type and race were inferred for the 46 accessions of unknown population type using the MRD-based k-nearest-neighbor approach (Table S7 and Table S8). Population-type assignments were classified as high confidence for 44 accessions (93.4%), medium confidence for 2 (4.3%), and low confidence for 1 (2.1%). Across all confidence levels, 39 accessions (84.7%) were classified as landraces and 7 (15.2%) as breeding materials.
Race assignments were less confident among the 40 proposed landraces: 11 (27.5%) received high-confidence assignments, 22 (55.0%) medium-confidence assignments, and 7 (17.5%) low-confidence assignments. Among high-confidence assignments, eight were assigned to Diente de Caballo and one each to Camelia, Harinoso Tarapaqueño, and Maíz de Rulo. Across all confidence levels, Diente de Caballo was proposed for 22 of the 40 accessions. All medium-confidence assignments were consistent across k values but supported by fewer than 7 of the 10 nearest neighbors. The four Banco Base accessions, XBB29–XBB32, were consistently assigned to Harinoso Tarapaqueño across all k values, with high confidence for XBB32 and medium confidence for the other three.
2.8. Core Collection
The core collection comprised 231 accessions: 195 in the landrace stratum (187 landraces and 8 accessions of unknown type inferred as landraces) and 36 in the breeding-material stratum (34 breeding materials and 2 accessions of unknown type) (Table S9). All 41,912 alleles detected in the entire collection were retained. Mean GD and PIC were 0.242 and 0.201, respectively, representing 95.9% and 96.5% of the full-collection values (0.253 and 0.208). Within strata, the landrace core retained 95.3% of GD and 95.9% of PIC, while the breeding-material core retained 100.0% and 99.9%, respectively.
All 22 standard races were represented. Thirteen included accessions selected during optimization in addition to their forced representative, most frequently Camelia (25 accessions), Curagua (23), Choclero (22 plus 1 unknown inferred as Choclero-medium confidence), Araucano (21), and Diente de Caballo (14 plus 3 unknown inferred as Diente de Caballo–medium confidence). Nine races were represented only by their forced accession: Capio Chileno Chico, Chutucuno, Harinoso Tarapaqueño, Limeño, Marcame, and Polulo, whose accessions were all assigned to the northern Andean group, together with Morocho Amarillo, Negrito Chileno, and Semanero. The four race-private alleles were retained, each carried by at least one accession of its own race.
The core covered 98.4%, 99.6%, and 100.0% of the ranges of PC1, PC2, and PC3, with core/collection variance ratios of 0.64, 0.92, and 1.02, respectively. The lower PC1 variance ratio reflects the reduced representation of the northern Andean group (STRUCTURE Group 1, K = 2; 6.1% of the core vs. 15.9% of the collection), half of whose core accessions were forced race representatives. The distribution of core accessions within the genetic space of the collection is shown in Figure 6.
The core included accessions from all 14 regions represented in the collection (Table S9). Among accessions with geographic coordinates, it covered the complete latitudinal (18.2°S–42.3°S) and longitudinal (67.9°W–73.7°W) ranges and nearly the entire altitudinal range (27–3,660 m a.s.l.). Median latitude and elevation (35.5°S and 207 m) were close to those of the collection (35.3°S and 237 m). The largest regional contributions were Metropolitana (47 accessions), Valparaíso (23), La Araucanía (21), and Maule (20). Arica y Parinacota, Tarapacá, and Antofagasta together accounted for 13.3% of core accessions with regional data, compared with 17.7% in the collection. Arica y Parinacota (2.8% vs. 5.6%) and Tarapacá (4.4% vs. 8.0%) had lower representation, whereas Antofagasta had higher representation (6.1% vs. 4.1%). Eight of the 24 core accessions from these regions were forced race representatives.
Of the 36 breeding materials in the core, 28 had detailed passport records. These comprised 13 inbred lines derived from Chilean races—six Diente de Caballo, four Choclero, and three Camelia—one racial composite, eight advanced lines from the INIA La Platina breeding program, three segregating lines, and three international inbred lines introduced through the USDA-ARS North Central Regional Plant Introduction Station. The latter, Mo17, Oh43, and TZI 18, represented three of the five international lines present in the collection.
3. Discussion
3.1. The Chilean Maize Collection Within a Continental Framework of Racial Diversity
Chilean maize diversity reflects a broad environmental and cultural setting. The country spans over 30° of latitude and encompasses desert, semi-arid, Mediterranean, temperate rainy, and maritime climates, with maize cultivated across most of these environments. This climatic breadth is complemented by an altitudinal gradient of cultivation extending from sea level to above 3,000 m. Historically, Atacameño, Diaguita, and Mapuche communities developed diverse culinary uses for maize, including roasted green ears, popcorn, fermented chicha, and lye-cooked muti [17,18]. This environmental and cultural breadth is reflected in the present collection, which represents 22 of the 23 Chilean races, from Harinoso Tarapaqueño and Capio Chileno Grande of the northern altiplano to the temperate, lowland-adapted Araucano and Ocho Corridas of south-central Chile.
The formal racial classification of Chilean maize began with the 19 provisional races described by Timothy et al. [17] and was subsequently refined, with 23 races recognized by Paratori et al. [19]. This national classification can also be viewed within the broader continental framework developed by Goodman and Bird [20]. Their analysis placed Chilean races in several racial complexes rather than a single cohesive group, providing a historical perspective on their differing affinities within Latin American maize. For example, Camelia, together with Curagua Grande, Cristalino, Araucano, and Dentado Comercial, was classified within the "Southern South American Races," a complex resulting from the introduction and admixture of North American, European, and Mexican germplasm into southern Brazil, Uruguay, Argentina, and Chile; a pattern consistent with the historically documented introduction of exotic germplasm into Chilean breeding material [17].
Choclero, by contrast, was included in the Cravos group together with the Brazilian race Dente Riograndense Rugoso and the composite entry Cravo, which comprised Cravo Riograndense and Cravo Paulista. In describing this group, Goodman and Bird [20] noted its resemblance to the narrow-kernelled, shoepeg maize formerly cultivated in the southern United States and its historical presence in southern Brazil. They hypothesized that these corns originated partly from the Mexican race Pepitilla. This proposed relationship offers a historical context for Choclero’s distinct, intermediate genetic position relative to the other central-southern races in the present study. It remains a hypothesis, however, and does not establish Choclero’s ancestry or an independent introduction into Chile.
Capio Chileno Chico and Capio Chileno Grande were both placed by Goodman and Bird [20] within the central Andean complex, but remained separate entries under the authors’ minimum-distance criterion of 1.0. Their historical separation contrasts with the pairwise AMOVA in the present study, which detected no statistically significant genetic differentiation between them. Thus, the morphological distinction retained in the earlier classification was not accompanied by differentiation at the SNP markers examined here.
This continental perspective provides historical context for the primary genetic division recovered in the present study, between a distinct northern Andean group and a more admixed central-southern complex. This pattern is consistent with the heterogeneous composition of Chilean maize germplasm described in historical classifications and accounts of germplasm introductions and admixture.
3.2. Ecogeographic, Not Racial, Basis for the Primary Genetic Division
The primary division detected at K = 2 followed ecogeographic patterns more closely than racial classification. The northern Andean group comprised 184 accessions from 12 races, none accounting for more than 13% of its composition. Despite this racial diversity, accessions with available passport data were concentrated in the northernmost regions of Chile (86%), at a mean elevation of 2,656 m. Morphological records likewise showed predominantly floury grain (89%) and white endosperm (92%). The central-southern group (n = 534), in contrast, was dominated by Ocho Corridas, Diente de Caballo, Camelia, Cristalino Chileno, and Araucano, with a lower mean elevation (293 m) and predominantly corneous grain and most frequently orange endosperm. The PCoA supported this division: PC1, which most clearly separated the groups, was strongly correlated with elevation (r = −0.82) and latitude (r = −0.83).
Earlier work on Chilean maize provides a complementary perspective on some of these racial affinities. Campbell et al. [18] analyzed grain samples from 306 Chilean lowland accessions using near-infrared transmittance spectroscopy (NITS), which captures chemical and physical grain properties rather than DNA variation. Their principal component analysis grouped Diente de Caballo, Camelia, Cristalino Chileno, and Semanero in one region of the ordination, and Araucano and Ocho Corridas in another. For the latter pair, the authors interpreted spectral similarity as suggesting similar grain characteristics despite contrasting ear shapes. Several Choclero accessions were positioned relatively far from the origin of the NITS-based PCA plot, and the authors also reported distinctive spectral patterns for this race. These observations complement the morphological relationships described by Goodman and Bird [20] and the genomic affinities recovered here. Because the NITS study examined lowland accessions, this correspondence concerns relationships within that germplasm rather than a direct test of the Andean–central-southern division.
The distinction between racial identity and genomic structure also appears in other American maize collections. In Mexico, Arteaga et al. [21] found that genomic variation was better explained by the interaction of altitude and latitude than by race. Caldu-Primo et al. [22] could distinguish the five Mexican races examined only after selecting highly differentiated SNPs, whereas the complete marker set did not clearly separate them. In the Peruvian Andes, Arbizu et al. [12] reported that races did not form monophyletic groups, with genetic clusters more closely related to the chronological and geographic origins of the germplasm. These studies show that morphological racial distinctions do not consistently correspond to the principal patterns of genomic variation. In the Chilean collection, the strongest pattern was the geographic and altitudinal contrast between northern Andean and central-southern accessions.
Within this broader pattern, Choclero occupied an intermediate position along PC1 between the northern floury group and the remaining central-southern groups. Two historical scenarios could account for this position, and they need not be mutually exclusive. Choclero may indicate gene flow or shared ancestry between northern and central-southern maize, or it may have a distinct introduction and diversification history. Its marked spectral differentiation in Campbell et al. [18] and its placement in the Cravos group by Goodman and Bird [20], discussed in section 3.1, provide context for the second possibility. Neither observation establishes its ancestry, however. Distinguishing these scenarios requires broader comparative analyses that include Chilean germplasm and potentially related Mesoamerican and South American populations.
3.3. Higher Genetic Diversity in Landraces Reflects Both Biological Signal and Sampling Design
Landraces showed higher genetic diversity than breeding materials across all indices examined, although the magnitude of this difference depended strongly on the metric considered. Previous studies have highlighted maize landraces as sources of allelic variation not fully represented in breeding materials [7,23]. The contrast was also evident in allele distribution: among the 20,956 SNPs analyzed, 459 alternative alleles (2.2%) were detected exclusively in landraces, compared with only one in breeding materials. These results indicate that landraces constitute the principal reservoir of genetic variation within the collection and contain allelic variation not detected in its improved germplasm.
The contrast between metrics clarifies the nature of this difference. Heterozygous calls were more than twice as frequent in landraces as in breeding materials (0.292 vs. 0.123), whereas frequency-based indices were only 10–14% higher in landraces (GD, 0.254 vs. 0.227; Shannon, 0.400 vs. 0.362; MAF, 0.180 vs. 0.158). In a pooled-DNA design, a heterozygous call indicates polymorphism within a bulk, whereas frequency-based indices mainly show diversity among accessions. The large difference in Ho therefore largely indicates the greater internal homogeneity of breeding materials, many of them inbred lines or derived from them, instead of an equivalent loss of allelic diversity, consistent with the 97.8% of SNPs shared between germplasm types. For the same reason, Ho from DNA bulks should not be interpreted as individual heterozygosity, and its exceeding GD in landraces reflects within-bulk polymorphism rather than an excess of heterozygous individuals.
Part of the remaining difference, however, may reveal variation in sampling and genotyping performance. Breeding material accessions were represented by smaller DNA bulks on average (21.0 plants) than landraces (26.4 plants, with most represented by 30 plants) and showed a higher proportion of missing genotype calls (14.2% vs. 4.2%). Smaller bulks may reduce the representation of within-accession allelic variation and, together with differences in sequencing coverage, could contribute to lower diversity estimates, particularly for Ho, which depends directly on the detection of both alleles within each bulk. Therefore, although the consistently higher diversity and greater number of exclusive alleles in landraces support a biological difference between germplasm types, its magnitude should be interpreted with some caution, and frequency-based indices such as GD provide a more appropriate basis for comparing diversity between germplasm groups in pooled genotyping designs. A comparable pattern was observed between the 11,698 chromosome-anchored SNPs and the 9,258 markers that could not be anchored, the latter showing higher diversity and less missing data — plausibly because unanchored probes originate from repetitive or structurally complex genomic regions that remain less fully resolved in the B73 reference assembly [24].
The diversity observed in the Chilean collection is broadly consistent with SNP-based estimates reported for American maize landraces. Gene diversity values of approximately 0.31 were reported for Mexican landraces genotyped with the MaizeSNP50 array [21], whereas values of 0.33–0.36 have recently been reported for Peruvian highland maize using GBS [12,25]. Direct numerical comparisons should nevertheless be treated cautiously because these studies differ in diversity metrics, marker platforms, filtering criteria, and sampling strategies. Higher diversity estimates obtained with SSR markers in American maize collections (e.g., [6]) are also expected given the greater per-locus information content of multiallelic microsatellites relative to biallelic SNPs.
Guo et al. [26] provide an additional comparison based on pooled leaf tissue from multiple plants per accession and reduced-representation SNP genotyping. Their analysis of 244 Chinese maize landraces using SLAF-seq retained 144,650 SNPs after filtering (MAF > 0.05 and missing data < 50%) and yielded mean heterozygosity and Shannon index values of 0.15 and 0.50, respectively, compared with 0.292 and 0.400 in the Chilean landraces. However, differences in sequencing platform, bulk size, marker filtering, and particularly the higher missing-data rate reported by Guo et al. (0.44) preclude a direct biological interpretation of these numerical differences. Overall, comparisons across studies support substantial genetic diversity in the Chilean landraces, while emphasizing that diversity estimates obtained from pooled SNP data should be interpreted in the context of the specific sampling and genotyping strategy used.
3.4. Racial Differentiation and Private Alleles
Among the 22 standard races, only four of the 20,956 SNPs carried race-private alleles. This scarcity should be interpreted in light of marker filtering and unequal race representation. Because the MAF ≥ 0.01 filter was applied to the entire panel (2,314 allele copies), a minor allele required approximately 24 copies to be retained. Consequently, the eight races represented by fewer than 12 accessions (33 accessions in total) could not reach this threshold on their own, reducing the probability of detecting private alleles regardless of their genetic distinctiveness. This is in accordance with sampling theory showing that the detection and retention of rare alleles are strongly dependent on sample size [27].
Despite the scarcity of private alleles, pairwise differentiation revealed considerable race-level structure: 196 of the 231 race comparisons (84.8%) were significant (p < 0.05), and Araucano, Camelia, Cristalino Chileno, Diente de Caballo, Maíz de Rulo, and Ocho Corridas differed significantly from nearly all other races. Among the non-significant comparisons, Capio Chileno Chico versus Capio Chileno Grande was particularly informative because both races had comparatively adequate representation (n = 16 and 26, respectively) but showed negligible differentiation (ΦST = 0.005, p = 0.155). As these races are traditionally distinguished primarily by ear and kernel size, their genomic similarity suggests that their morphological differentiation may not correspond to substantial genome-wide differentiation. Most other non-significant comparisons involved at least one race represented by fewer than 15 accessions, making limited statistical power an important consideration.
The influence of marker selection and sampling on racial differentiation has also been observed in Mexican maize, where races that were poorly separated using the complete SNP dataset became distinguishable using highly differentiated markers [22]. At the aggregate level, AMOVA attributed 22.7% of total genetic variance in the Chilean collection to differences among races, compared with 4.52% reported for Peruvian highland maize [12]. Although this indicates race-level structure in the Chilean collection, direct numerical comparison should consider differences in sampling, marker systems, and analytical approaches among studies.
3.5. Rapid Linkage Disequilibrium Decay in the Chilean Maize Landrace Collection
LD in the Chilean landraces declined rapidly, with mean r² already below 0.10 in the first 100 bp interval. This places an upper bound on the decay distance, but the available marker resolution did not allow a more precise estimate. The observed pattern nevertheless indicates that LD extends over relatively short physical distances in this germplasm.
Rapid decay has also been reported in other diverse maize panels. Tenaillon et al. [28], using sequence data from exotic landraces and U.S. inbred lines, found that intragenic LD generally declined within approximately 100–200 bp. Guo et al. [26] reported a decay distance of 0.98 kb at r² = 0.10 for a panel comprising 244 Chinese landraces and seven reference inbred lines. These studies provide context for the short-distance LD observed here, although differences in sampling, genotyping platforms, marker density, and estimation methods limit direct numerical comparisons.
The Chilean pattern is in agreement with the predominantly outcrossing mating system of maize, in which repeated recombination and gene flow can reduce associations between neighboring loci. It may also reflect the historical processes of gene flow, recombination, and diversification represented in the collection. LD patterns alone, however, cannot establish the relative contribution of these processes.
From a practical perspective, rapid LD decay has to be considered in future studies using this germplasm, e.g. genome-wide association studies. Short-distance LD means that each marker represents a comparatively small surrounding genomic region. Detecting associations with traits of interest would therefore likely require denser marker coverage than that used to characterize diversity and population structure. The present findings can inform marker-density decisions for such studies, while the unresolved decay distance limits how precisely those requirements can be specified.
3.6. Genetic Inference as a Tool for Resolving Incomplete Passport Data
Incomplete passport records limit the characterization and use of conserved germplasm. In the Chilean collection, 47 accessions lacked population-type classification, including long-conserved Banco Base materials identified by XBB codes. Genetic nearest-neighbor inference provided high-confidence population-type assignments for 44 accessions (93.6%). Across all confidence levels, 40 were classified as landraces (85.1%) and seven as breeding materials (14.9%). Race assignments were less conclusive: only 11 of the 40 proposed landraces (27.5%) received a high-confidence assignment. This contrast suggests that genomic information was more effective for resolving broad germplasm categories than individual races, consistent with the unequal representation of some races in the collection.
These findings illustrate how genomic characterization can complement passport and phenotypic information, an application emphasized in genebank research [29] and increasingly relevant to the characterization and use of maize collections [12]. Its value lies in providing additional evidence for accessions whose documentary history is incomplete.
The XBB29–XBB32 accessions provide a specific example. All ten nearest neighbors supported their classification as landraces, and this assignment remained consistent across the three k values. Their proposed race was likewise consistently Harinoso Tarapaqueño, although only XBB32 reached high confidence at that level. The analysis therefore provided strong support for population type and a plausible racial affiliation for these long-conserved materials. Such assignments can guide documentary and morphological curation, but should remain working classifications subject to evaluation as additional passport, morphological, or genomic evidence becomes available.
3.7. Composition and Representativeness of the Core Collection
The core collection combined SNP-based optimization with stratification by population type and mandatory inclusion of one accession per standard race. These complementary criteria balanced the capture of genetic variation with the retention of distinct germplasm components, including races that might otherwise have been omitted because of their limited representation. This approach is consistent with recommendations to combine grouping criteria with genetic information when constructing core collections [27,30] and with marker-based stratified sampling strategies evaluated in maize [31].
Representativeness was also assessed through the coverage of the collection’s genetic space in the PCoA. Comparing the ranges retained along the first three coordinates provided a criterion for selecting among the tested core configurations. Their broad coverage indicates that the selected subset retained the extent of variation described by these coordinates, although it does not imply that the density of the original point cloud was reproduced. Retention of GD and PIC, neither used as an optimization objective, provided complementary evidence of the core’s representativeness.
The lower proportion of northern Andean accessions in the core is consistent with the comparatively homogeneous genetic composition of this group, while mandatory race representatives preserved its racial coverage. Within the breeding-material stratum, the core retained both germplasm derived from Chilean races and introduced international lines. These features support the value of combining genetic optimization with explicit representation criteria to obtain a manageable subset that preserves the collection’s principal components of diversity.
3.8. Conservation Value and Breeding Use of the Collection
The Chilean maize collection maintains germplasm that has contributed to national breeding. Since the early 1970s, Chilean maize germplasm has supported the development of open-pollinated varieties and hybrids, including Choclero Platina, MA-3, MA-4, MA-6, MA-7, INIA-8, INIA-9, INIA 140, INIA 150, INIA 160, Choclero INIA 110, and Camelia INIA 145 [32,33,34,35]. These examples connect the diversity maintained in traditional maize populations with its practical application in crop improvement.
This contribution developed alongside a significant transformation of maize production in Chile. By the late 1980s, approximately 85% of the maize area was planted with hybrid seed. Open-pollinated varieties such as Camelia, Curagua, Ocho Corridas, and Araucano nevertheless remained in cultivation, although some were already considered scarce in the main maize-producing regions [36,37]. Conservation therefore preserves access to germplasm that became less prominent in commercial agriculture. Its potential remains relevant in a broader continental context, where only a fraction of Latin American maize racial diversity has historically been incorporated into breeding programs [20].
The genomic characterization presented here provides a basis for more informed management of these resources. Information on genetic differentiation and relationships among accessions can support conservation decisions by identifying distinct components of the collection and guiding the selection of material for further evaluation. The core collection translates this information into a manageable subset, combining broad genetic representation with the retention of all standard races. It thus offers a practical starting point for organizing phenotypic characterization and pre-breeding activities while maintaining access to the wider diversity conserved in the full collection.
The breeding materials add a further link between conservation and use. They include inbred lines derived from Chilean races, reflecting the historical incorporation of local germplasm into breeding, together with international lines that broaden the genetic backgrounds available. Their inclusion in the core brings these complementary resources into the same evaluation framework. Although genomic diversity alone does not establish agronomic value, it can guide the choice of genetically distinct material for assessing traits of interest, supporting both conservation planning and the exploration of the collection’s value for breeding programs.
4. Materials and Methods
4.1. Plant Material
The Chilean national maize germplasm collection is maintained by the Instituto de Investigaciones Agropecuarias (INIA) at the INIA La Platina Germplasm Bank, with a safety duplicate at the INIA Vicuña Base Germplasm Bank. It comprises 1,519 accessions: 1,468 from Chile, 21 from other countries, and 30 of unknown origin. By germplasm type, these include 975 landraces, 448 breeding materials, and 96 accessions of unknown type. A total of 1,303 accessions were selected for genotyping.
4.2. Plant Sampling and DNA Extraction
Seeds from 1,303 maize accessions were sent to the Genetic Analysis Service for Agriculture (SAGA) at the International Maize and Wheat Improvement Center (CIMMYT), Mexico, for DNA extraction and genotyping. For each accession, 30 seeds were germinated under greenhouse conditions, and leaf tissue was collected after two weeks by pooling material from the available seedlings. The number of individuals contributing to each bulk ranged from 1 to 30 plants (Table S9). Thirty-plant bulks accounted for approximately 64% of the panel and single-plant samples for 0.5%. Samples were lyophilized, and genomic DNA was extracted in 96-well plate format using the CIMMYT modified cetyltrimethylammonium bromide (CTAB) protocol [38]. DNA quality and concentration were assessed by electrophoresis on 1% agarose gels. Of the 1,303 accessions submitted, 133 were not genotyped because of germination failure or low DNA quality.
4.3. DArTseq Genotyping
A total of 1,170 accessions were successfully genotyped using high-density DArTseq at SAGA (CIMMYT), generating approximately 2 million sequencing reads per accession. For library preparation, 25 μL of genomic DNA at 100 ng/μL per accession underwent complexity reduction using PstI and HpaIII restriction enzymes. The resulting fragments were ligated to adapters containing sample-specific barcodes for accession identification after sequencing. Fragments were then amplified by PCR, and equimolar amounts of the PCR products were pooled to prepare sequencing libraries. The libraries were purified, quantified, and sequenced on an Illumina NovaSeq 6000 platform (Illumina Inc., San Diego, CA, USA) according to the DArTseq protocol (Diversity Arrays Technology sequencing) [15,39,40,41]
4.3.1. Raw Read Quality Control and Variant Calling
Raw DArTseq reads were processed by the SAGA bioinformatics platform (CIMMYT) using its standard workflow. Reads were assessed for quality, trimmed to remove adapters and low-quality bases, and demultiplexed using sample-specific barcodes. Variant calling was performed with the proprietary reference-independent DArTsoft14 pipeline, which generates SNP and SilicoDArT markers [42]; only SNPs were used in this study. SNP-containing sequence tags were then aligned to the maize B73 RefGen_v4 genome [24] using Bowtie2, and markers without a unique alignment were retained as unmapped.
4.3.2. Quality Filtering Criteria
Following variant calling, SAGA (CIMMYT) delivered a processed marker matrix comprising 109,824 SNPs. Additional filtering was performed in R using dartR to obtain a high-confidence dataset for genetic diversity analyses. Markers with ≥20% missing data or a minor allele frequency (MAF) <0.01 were excluded, as were accessions with ≥25% missing data across loci. No filtering based on Hardy–Weinberg equilibrium was applied because deviations are expected from population subdivision, partial inbreeding, and pooled sampling, and filtering could remove informative biological signals instead of technical artifacts.
After filtering, the dataset comprised 20,956 unimputed SNPs from 1,157 accessions (13 of the 1,170 genotyped accessions were removed for exceeding the missing data threshold): 938 landraces representing 22 of the 23 Chilean maize races, 172 breeding materials, and 47 accessions of unknown germplasm type. Regarding geographical origin, 1,116 accessions (96.5%) originated from Chile, 16 from the United States, one from Mexico, and one from Nigeria; 23 had unknown origin. The study panel represents the broad geographical distribution of the national collection and includes accessions collected in Chile between 1939 and 2020. The geographical distributions of the national collection and study panel are shown in Figure 7, and detailed passport and germplasm information is provided in Table S9.
4.4. Genetic Diversity Analysis
Marker-level genetic diversity was assessed across the 20,956 quality-filtered SNPs using R [43]. Minor allele frequency (MAF), gene diversity (GD), proportion of heterozygous calls (Ho), the Shannon–Wiener diversity index (H), and the percentage of missing data were calculated for each marker. H and GD were calculated as:
and
respectively, where pi is the frequency of the ith allele at a given locus. These parameters were calculated for the entire collection and separately for the landrace and breeding-material subsets, with mean values obtained across loci for each group.
Private alleles were identified among the 22 standard races within the landrace subset, using passport information for racial assignments. An allele was considered private when detected in one or more accessions of a race and absent from all accessions of the other 21 races. Landraces of unknown or non-standard race and breeding materials were excluded. Counts were obtained without correction for unequal race sample sizes, and detection was conditional on the marker filtering criteria applied to the entire collection.
4.5. Linkage Disequilibrium (LD) Analysis
Linkage disequilibrium (LD) was estimated among the 938 landrace accessions using the 11,698 SNPs with valid physical positions on B73 RefGen_v4, out of the 20,956 quality-filtered markers. The analysis was restricted to landraces to reduce the effect of genetic differentiation between germplasm types on LD estimates, given their potentially different allele frequencies and breeding histories. Pairwise LD (r²) was calculated in Python (v3.12.3; NumPy v2.4.4 and SciPy v1.17.1). Only SNP pairs located on the same chromosome and separated by ≤1 Mb were considered.
The relationship between pairwise r² and physical distance was initially examined to determine the scale of LD decay and define a variable-width binning scheme. Narrower intervals were used at short distances, where r² declined most strongly, and wider intervals at greater distances, where it approached background levels. Mean r² was calculated for all SNP pairs within each distance bin. For descriptive purposes, LD decay was defined as the physical distance at which mean r² first decreased below 0.10.
4.6. Population Structure
Population structure was assessed using STRUCTURE v2.3.4 [44], under an admixture model with correlated allele frequencies and no prior population information. Although computationally demanding for large genome-wide datasets, STRUCTURE was selected for its full Markov chain Monte Carlo (MCMC) estimation of accession admixture proportions and the ability to assess solution consistency across independent runs [45]. Values of K from 1 to 22 were tested, with 10 independent runs per K, each comprising 10,000 burn-in iterations followed by 20,000 MCMC iterations. Evanno’s ΔK method [46], implemented in STRUCTURE HARVESTER [47], was used to identify the most likely number of genetic clusters.
For the K values corresponding to the primary and secondary ΔK peaks, accession assignments were based on the run with the highest log-likelihood among the 10 replicates. At K = 2, accessions with a membership coefficient (Q) ≥ 0.80 for a single cluster were assigned to that cluster; the remainder were classified as admixed. At K = 6, because members of some clusters did not reach Q ≥ 0.80, accessions were assigned to the cluster with the highest membership coefficient if Q > 0.50; the remainder were classified as admixed.
4.7. Genetic distance and clustering
Pairwise Rogers’ modified genetic distance (MRD [48]) was calculated across the 20,956 quality-filtered SNPs in BIO-R v3.2 [49]. Hierarchical cluster analysis was performed using Ward’s minimum variance method ([50,51]; hclust(), R, method = “ward.D2”). The dendrogram was cut into three and six groups for comparison with STRUCTURE at K = 2 and K = 6, respectively. At K = 2, correspondence was assessed by mapping assignments because the two approaches yielded different numbers of groups. The dendrogram was visualized as a circular cladogram in Python (Matplotlib), with branches colored by STRUCTURE group only where all descendant accessions shared the same assignment.
Cluster robustness was assessed by a locus-resampling bootstrap implemented independently in Python (NumPy; SciPy). In each of 100 replicates, the 20,956 SNPs were resampled with replacement, converted to allele dosage (0, 0.5, 1; missing calls imputed by locus mean), and used to recompute the pairwise distance matrix and Ward dendrogram (scipy.cluster.hierarchy.linkage, method = “ward”). Each bootstrap dendrogram was cut into three or six clusters (scipy.cluster.hierarchy.fcluster, criterion = “maxclust”). For accession pairs sharing a STRUCTURE group at the corresponding K, stability was measured as the percentage of replicates in which they remained together. This co-clustering measure was used instead of node-support statistics, which are poorly suited to datasets exceeding 1,000 accessions.
4.8. Principal Coordinates Analysis (PCoA)
Principal coordinates analysis (PCoA) was performed on the pairwise Rogers’ modified genetic distance (MRD) matrix to visualize genetic relationships among accessions. The proportion of variation represented by each principal coordinate was calculated in GenAlEx 6.51b2 [52]. Accessions were plotted along the first three principal coordinates, and their distribution was compared with the groups identified by STRUCTURE and Ward’s hierarchical cluster analysis.
4.9. Population Distances
Genetic differentiation among STRUCTURE groups was assessed using pairwise FST, which quantifies the proportion of total genetic variation attributable to differentiation among groups [53]. A study-specific variance-partitioning procedure accommodated the pooled samples of 1–30 plants per accession. SNP calls were converted to dosage values of 0, 0.5, or 1 and used as operational proxies for bulk-level allele frequencies. Accessions were weighted by the number of plants contributing to each bulk when calculating allele-frequency variance among and within groups:
where p denotes the bulk-level allele-frequency and pˉ is the weighted mean allele frequency across all bulks. The procedure was implemented in Python (v3.12.3; NumPy) across all 20,956 quality-filtered SNPs and also applied to hierarchical clusters to compare differentiation between the two clustering approaches.
Analysis of Molecular Variance (AMOVA [54]) was performed for STRUCTURE groups at K = 2 (Q ≥ 0.80; n = 718) and K = 6 (Q > 0.50; n = 591), and for the 22 standard races within the landrace subset (n = 758). Admixed accessions were excluded from the STRUCTURE-based analyses. AMOVA was implemented in Python (v3.12.3; NumPy v2.4.4), using squared pairwise MRD to partition variation among groups and among accessions within groups and calculate ΦST. This analysis did not incorporate bulk-size weighting; its estimates therefore complement, but are not directly comparable in magnitude to, the weighted FST estimates.
Statistical significance of the among-group variance component was assessed by comparing the observed ΦST against a null distribution generated from 999 random permutations of group labels among accessions, with the resulting p-value corresponding to the proportion of permuted ΦST values equal to or exceeding the observed value (including the observed value itself). Pairwise differentiation between races (231 comparisons) was assessed within the same AMOVA framework, with significance determined by 9,999 permutations per pair; p-values were adjusted for multiple testing using the false discovery rate (FDR) procedure of Benjamini and Hochberg, [55].
4.10. Inference of Population Type and Race for Unclassified Accessions
Population type and race were inferred for the 47 accessions of unknown population type using the pairwise MRD matrix calculated in BIO-R. For each unclassified accession, accessions of known population type were ranked by increasing MRD (numpy.argsort), and population type was assigned by majority vote among the k nearest neighbors. Race inference was performed only for accessions proposed as landraces, using the same neighbor set. Neighbors recorded as “Unknown” or “No Clasificable” for race were retained but did not contribute race votes; support was therefore always expressed relative to k.
The procedure was repeated with k = 3, 5, and 10. Confidence was determined by two criteria: consistency of the proposed category across all three k values and support from at least 70% of the neighbors at k = 10. Assignments meeting both criteria were classified as high confidence, those meeting one as medium confidence, and those meeting neither as low confidence and interpreted cautiously. Support from fewer than two neighbors at k = 10 resulted in low confidence regardless of the other criteria. When assignments differed across k values, the category supported at k = 10 was retained.
4.11. Development of the Core Collection
A core collection of 231 accessions (20% of the collection [31] was developed from the 1,157 genotyped accessions using the R package corehunter (Core Hunter 3 [56]), based on the 20,956 quality-filtered SNPs in biparental format. Sampling was stratified by population type, with the 47 accessions of unknown type assigned according to their k-NN inferred classification. Core positions were allocated proportionally: 195 from the landrace stratum (978 accessions) and 36 from the breeding-material stratum (179 accessions). Core Hunter was run independently within each stratum.
One accession per standard race was forced into the landrace core using the always.selected option to ensure representation of all 22 races. Representatives were chosen by passport status (typical > similar > mixed > hybrid) and then by the lowest mean MRD to other accessions of the same race. Ties were resolved by the lowest proportion of missing data.
Two objectives were combined: Coverage (CV), which maximizes the proportion of alleles retained, and Accession-to-Nearest-Entry distance (AN; Modified Rogers distance), which minimizes the distance between each accession of the collection and its closest accession in the core. Objectives were normalized and weighted 0.3 for CV and 0.7 for AN. This configuration provided the most complete overall coverage of the first three PCoA coordinate ranges among four configurations tested: CV/EN (Entry-to-Nearest-Entry distance) 0.7/0.3, CV/AN 0.3/0.7, CV/AN/EN 0.2/0.4/0.4, and CV/AN 0.5/0.5. Searches were run with a fixed random seed and terminated after 2,000 steps without improvement.
Retained genetic diversity was evaluated using polymorphic information content (PIC) and Nei’s gene diversity (GD), neither included as an optimization objective. Both indices were averaged across the 20,956 SNPs and compared between the core and the entire collection
5. Conclusions
This study provides the first genomic characterization of the Chilean national maize germplasm collection, revealing substantial genetic diversity preserved in both landraces and breeding materials. The primary genetic division of the collection separates the floury maize of the northern Andean highlands from the germplasm of the central-southern regions, reflecting the ecogeographic gradients of the country rather than traditional racial classification. At a finer scale, genetic groups were associated with specific races, geographic origins and grain types, and most races were genetically differentiated, while extensive admixture among several central Chilean races points to a history of gene flow and farmer-mediated seed exchange. Beyond describing this diversity, the genomic data strengthened the management of the collection, allowing the classification of accessions lacking passport information and the development of a stratified core collection that captures the allelic, racial and geographic diversity of the national collection in a manageable number of accessions. Together, these results establish the basis for using Chilean maize germplasm in diverse environmental, nutritional and breeding contexts, laying the foundation for the conservation and sustainable utilization of the genetic diversity of national maize.
Supplementary Materials
The following supporting information can be downloaded at: Preprints.org, Figure S1: Mean diversity statistics per chromosome for chromosome-anchored SNP markers; Table S1: Mean diversity statistics per chromosome for chromosome-anchored SNP markers; Figure S2: Unbinned distribution of pairwise linkage disequilibrium (r²) as a function of physical distance among landrace accessions; Table S2: Mean pairwise r² by physical distance interval in the landrace subset; Figure S3: Determination of the most likely number of genetic clusters (K) in the Chilean maize collection; Table S3: (a) Passport information and STRUCTURE-based genetic cluster assignment (K = 2 and K = 6) for all 1,157 accessions; (b) Composition of STRUCTURE K = 6 clusters at Q > 0.50; Table S4: Pairwise co-clustering stability of STRUCTURE genetic groups across 100 locus-resampling bootstrap replicates; Figure S4: Principal coordinates analysis (PCoA) of the 1,157 accessions colored by race, population type, and country of origin; Figure S5: Relationship between the first principal coordinate (PC1) and the elevation and latitude of the collection sites; Table S5: Pairwise FST among hierarchical clusters (HC-C3 and HC-C6); Table S6. Pairwise genetic differentiation (ΦST) among the 22 standard landrace race; Table S7: Inferred population type by k-nearest-neighbor majority vote (k = 3, 5, 10); Table S8: Inferred race by k-nearest-neighbor majority vote (k = 3, 5, 10); Table S9: Passport data of the 1,157 genotyped accessions of the Chilean maize germplasm collection, including DNA bulk size and core collection membership.
Author Contributions
Conceptualization, E.S.; methodology, E.S. and G.V.; validation, C.P. and G.V.; formal analysis, V.S., M.G. and E.S.; investigation, E.S.; resources, E.S., C.P. and G.V.; data curation, E.S., G.V. and C.P.; writing—original draft preparation, E.S.; writing—review and editing, E.S., M,G., C.P. and G.V.; visualization, E.S., V.S. and M.G.; supervision, E.S.; project administration, E.S. and C.A; funding acquisition, E.S. All authors have read and agreed to the published version of the manuscript.
Funding
This research was funded by ANID – Fondo Nacional de Desarrollo Científico y Tecnológico (FONDECYT de Iniciación - grant number 11200894), ANID – Fomento a La Vinculación Internacional para Instituciones de Investigación (FOVI - grant number 220099) and Subsecretaría del Ministerio de Agricultura (Subsecretaría MINAGRI - grant number 501453-70).
Data Availability Statement
The datasets generated and analyzed during the current
study are available from the corresponding author upon reasonable request.
Acknowledgments
During the preparation of this manuscript, the authors used Claude (Anthropic) for assistance in writing and debugging R and Python scripts for data analysis, improving the visual presentation of figures, and editing the English text. The authors have reviewed and edited the output and take full responsibility for the content of this publication.
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Matsuoka, Y.; Vigouroux, Y.; Goodman, M.M.; Sánchez, G. J.; Buckler, E.; Doebley, J. A single domestication for maize shown by multilocus microsatellite genotyping. Proc. Natl. Acad. Sci. U S A 2002, 99(9), 6080–6084. [Google Scholar] [CrossRef] [PubMed]
- Kistler, L.; Maezumi, S.Y.; de Souza, J.G.; Przelomska, N.A.S.; Costa, F.M.; Smith, O.; et al. Multiproxy evidence highlights a complex evolutionary legacy of maize in South America. Science 2018, 362(6420), 1309–1313. [Google Scholar] [CrossRef] [PubMed]
- Kistler, L.; Thakar, H.B.; VanDerwarker, A.M.; Domic, A.; Bergström, A.; George, R.J.; et al. Archaeological Central American maize genomes suggest ancient gene flow from South America. Proc. Natl. Acad. Sci. U S A 2020, 117(52), 33124–33129. [Google Scholar] [CrossRef] [PubMed]
- Falabella, F.; Planella, M.T.; Tykot, R.H. El maíz (Zea mays) en el mundo prehispánico de Chile central. Lat. Am. Antiq. 2008, 19, 25–46. [Google Scholar] [CrossRef]
- Tykot, R.H.; Falabella, F.; Planella, M.T.; Aspillaga, E.; Sanhueza, L.; Becker, C. Stable isotopes and archaeology in central Chile: Methodological insights and interpretative problems for dietary reconstruction. Int. J. Osteoarchaeol. 2009, 19(2), 156–170. [Google Scholar] [CrossRef]
- Vigouroux, Y.; Glaubitz, J.C.; Matsuoka, Y.; Goodman, M.M.; Sánchez, G. J.; Doebley, J. Population structure and genetic diversity of New World maize races assessed by DNA microsatellites. Am. J. Bot. 2008, 95(10), 1240–1253. [Google Scholar] [CrossRef] [PubMed]
- Salazar, E.; González, M.; Araya, C.; Mejía, N.; Carrasco, B. Genetic diversity and intra-racial structure of Chilean Choclero corn (Zea mays L.) germplasm revealed by simple sequence repeat markers (SSRs). Sci. Hortic. 2017, 225, 620–629. [Google Scholar] [CrossRef]
- Bedoya, C.A.; Dreisigacker, S.; Hearne, S.; Franco, J.; Mir, C.; Prasanna, B.M.; et al. Genetic diversity and population structure of native maize populations in Latin America and the Caribbean. PLoS ONE 2017, 12(4), e0173488. [Google Scholar] [CrossRef] [PubMed]
- Takuno, S.; Ralph, P.; Swarts, K.; Elshire, R.J.; Glaubitz, J.C.; Buckler, E.S.; et al. Independent molecular basis of convergent highland adaptation in maize. Genetics 2015, 200, 1297–1312. [Google Scholar] [CrossRef] [PubMed]
- Costa, F.M.; Silva, N.C.A.; Vidal, R.; Clement, C.R.; Freitas, F.O.; Alves-Pereira, A.; et al. Maize dispersal patterns associated with different types of endosperm and migration of indigenous groups in lowland South America. Ann. Bot. 2022, 129, 737–751. [Google Scholar] [CrossRef] [PubMed]
- Dominguez, P.G.; Gutierrez, A.V.; Fass, M.I.; Filippi, C.V.; Vera, P.; Puebla, A.; et al. Genome-wide diversity in lowland and highland maize landraces from southern South America: Population genetics insights to assist conservation. Evol. Appl. 2024, 17, e70047. [Google Scholar] [CrossRef] [PubMed]
- Arbizu, C.I.; Bazo-Soto, I.; Flores, J.; Ortiz, R.; Blas, R.; García-Mendoza, P.J.; et al. Genotyping by sequencing reveals the genetic diversity and population structure of Peruvian highland maize races. Front Plant Sci. 2025, 16, 1526670. [Google Scholar] [CrossRef] [PubMed]
- Hölker, A.C.; Mayer, M.; Presterl, T.; Bolduan, T.; Bauer, E.; Ordas, B.; et al. European maize landraces made accessible for plant breeding and genome-based studies. Theor. Appl. Genet. 2019, 132, 3333–3345. [Google Scholar] [CrossRef] [PubMed]
- Arca, M.; Gouesnard, B.; Mary-Huard, T.; Le Paslier, M.C.; Bauland, C.; Combes, V.; et al. Genotyping of DNA pools identifies untapped landraces and genomic regions to develop next-generation varieties. Plant Biotechnol. J. 2023, 21, 1123–1139. [Google Scholar] [CrossRef] [PubMed]
- Sansaloni, C.; Petroli, C.; Jaccoud, D.; Carling, J.; Detering, F.; Grattapaglia, D.; et al. Diversity Arrays Technology (DArT) and next-generation sequencing combined: Genome-wide, high throughput, highly informative genotyping for molecular breeding of Eucalyptus. BMC Proc. 2011, 5 (Suppl 7), P54. [Google Scholar] [CrossRef]
- Arca, M.; Mary-Huard, T.; Gouesnard, B.; Bérard, A.; Bauland, C.; Combes, V.; et al. Deciphering the genetic diversity of landraces with high-throughput SNP genotyping of DNA bulks: Methodology and application to the maize 50K array. Front Plant Sci. 2021, 11, 568699. [Google Scholar] [CrossRef] [PubMed]
- Timothy, D.H.; Peña, V. B.; Ramírez, E. R.; Brown, W.L.; Anderson, E. 1961. Races of maize in Chile. Publication 847. National Academy of Sciences–National Research Council: Washington (DC). [Google Scholar]
- Campbell, M.R.; Anih, E.; Conatser, C.; Grau-Saavedra, B.; Pollak, L.M. Development of a core subset of Chilean lowland subtropical and temperate maize (Zea mays L.) populations using near infrared transmittance spectroscopy. Plant Genet Resour. Newsl. 2006, 148, 1–9. [Google Scholar]
- Paratori, O.; Sbarbaro, R.; Villegas, C. Catálogo de recursos genéticos de maíz de Chile. In Boletín Técnico No. 165.; INIA, Estación Experimental La Platina: Santiago (Chile), 1990; p. 210 p. [Google Scholar]
- Goodman, M.M.; Bird, R.M. The races of maize IV: Tentative grouping of 219 Latin American races. Econ. Bot. 1977, 31, 204–221. [Google Scholar] [CrossRef]
- Arteaga, M.C.; Moreno-Letelier, A.; Mastretta-Yanes, A.; Vázquez-Lobo, A.; Breña-Ochoa, A.; Moreno-Estrada, A.; et al. Genomic variation in recently collected maize landraces from Mexico. Genom. Data 2016, 7, 38–45. [Google Scholar] [CrossRef] [PubMed]
- Caldu-Primo, J.L.; Mastretta-Yanes, A.; Wegier, A.; Piñero, D. Finding a needle in a haystack: Distinguishing Mexican maize landraces using a small number of SNPs. Front Genet. 2017, 8, 45. [Google Scholar] [CrossRef] [PubMed]
- Warburton, M.L.; Reif, J.C.; Frisch, M.; Bohn, M.; Bedoya, C.; Xia, X.C.; et al. Genetic diversity in CIMMYT nontemperate maize germplasm: Landraces, open pollinated varieties, and inbred lines. Crop Sci. 2008, 48, 617–624. [Google Scholar] [CrossRef]
- Jiao, Y.; Peluso, P.; Shi, J.; Liang, T.; Stitzer, M.C.; Wang, B.; et al. Improved maize reference genome with single-molecule technologies. Nature 2017, 546, 524–527. [Google Scholar] [CrossRef] [PubMed]
- García-Mendoza, P.J.; Saldaña, C.L.; Pérez-Almeida, I.B.; Prieto-Rosales, G.P.; Medina-Castro, D.E.; Taramona-Ruíz, L.A.; et al. Genetic diversity and population structure of maize landraces from Huancavelica and Cajamarca provinces of Peru using SNP markers. Plant Genet Resour. 2025, 23, 262–270. [Google Scholar] [CrossRef]
- Guo, R.; Li, T.; Zhang, Q.; Wang, J.; Guo, J.; Wang, L.; et al. Genetic and molecular characterization of maize landraces from Central China. Agronomy 2024, 14(6), 1278. [Google Scholar] [CrossRef]
- Marshall, D.R.; Brown, A.H.D. Optimum sampling strategies in genetic conservation. In Crop genetic resources for today and tomorrow; Frankel, O.H., Hawkes, J.G., Eds.; Cambridge University Press: Cambridge (UK), 1975; pp. 53–80. [Google Scholar]
- Tenaillon, M.I.; Sawkins, M.C.; Long, A.D.; Gaut, R.L.; Doebley, J.F.; Gaut, B.S. Patterns of DNA sequence polymorphism along chromosome 1 of maize (Zea mays ssp. mays L.). Proc. Natl. Acad. Sci. U S A 2001, 98, 9161–9166. [Google Scholar] [CrossRef] [PubMed]
- Mascher, M.; Schreiber, M.; Scholz, U.; Graner, A.; Reif, J.C.; Stein, N. Genebank genomics bridges the gap between the conservation of crop diversity and plant breeding. Nat. Genet. 2019, 51, 1076–1081. [Google Scholar] [CrossRef] [PubMed]
- van Hintum, ThJL; Brown, A.H.D.; Spillane, C.; Hodgkin, T. Core collections of plant genetic resources. In IPGRI Technical Bulletin No. 3.; International Plant Genetic Resources Institute: Rome (Italy), 2000. [Google Scholar]
- Franco, J.; Crossa, J.; Warburton, M.L.; Taba, S. Sampling strategies for conserving maize diversity when forming core subsets using genetic markers. Crop Sci. 2006, 46, 854–864. [Google Scholar] [CrossRef]
- Paratori, O. Camelia-INIA 145, un nuevo cultivar de maíz. Agric. Téc 1986, 46, 531. [Google Scholar]
- Paratori, O.; Villegas, C. Híbridos comerciales de maíz. IPA La. Platina 1984, 23, 55–56. [Google Scholar]
- Sbarbaro, R. Etapas para la obtención de un híbrido de maíz. IPA La. Platina 1989, 56, 7–11. [Google Scholar]
- Paratori, O.; Altamirano, S. (Eds.) El cultivo del maíz; Instituto de Investigaciones Agropecuarias, Centro Regional de Investigación La Platina: Santiago (Chile), 1995; ISBN 956-7016-04-6. [Google Scholar]
- Paratori, O.; Villegas, C. Híbridos y producción de maíz. Investig. Prog. Agropecu. La. Platina 1987, 42, 7–13. [Google Scholar]
- Chiron, C. Agriculture familiale et conservation des variétés traditionnelles: Le cas du maïs chilien. undergraduate thesis, ISTOM—École Supérieure d'Agro-Développement International, Angers (France), 2023. [Google Scholar]
- International Maize and Wheat Improvement Center (CIMMYT). Laboratory protocols: CIMMYT Applied Molecular Genetics Laboratory, 3rd ed.; CIMMYT: Mexico City (Mexico), 2005. [Google Scholar]
- Cruz, V.M.; Kilian, A.; Dierig, D.A. Development of DArT marker platforms and genetic diversity assessment of the US collection of the new oilseed crop lesquerella and related species. PLoS ONE 2013, 28;8(5), e64062. [Google Scholar] [CrossRef]
- Yang, X.; Ren, R.; Ray, R.; Xu, J.; Li, P.; Zhang, M.; Liu, G.; Yao, X.; Kilian, A. Genetic diversity and population structure of core watermelon (Citrullus lanatus) genotypes using DArTseq-based SNPs. Plant Genet. Resour. 2016, 14(3), 226–33. [Google Scholar] [CrossRef]
- Baloch, F.S.; Alsaleh, A.; Shahid, M.Q.; Çiftçi, V.; E. Sáenz de Miera, L.; Aasim, M.; Nadeem, M.A.; Aktaş, H.; Özkan, H.; Hatipoğlu, R. A whole genome DArTseq and SNP analysis for genetic diversity assessment in durum wheat from central fertile crescent. PLoS ONE 2017, 18;12(1), e0167821. [Google Scholar] [CrossRef] [PubMed]
- Sansaloni, C.; Franco, J.; Santos, B.; Percival-Alwyn, L.; Singh, S.; Petroli, C.; et al. Diversity analysis of 80,000 wheat accessions reveals consequences and opportunities of selection footprints. Nat. Commun. 2020, 11, 4572. [Google Scholar] [CrossRef] [PubMed]
- R Core Team. R: A language and environment for statistical computing; R Foundation for Statistical Computing: Vienna (Austria), 2024; Available online: https://www.R-project.org/.
- Pritchard, J.K.; Stephens, M.; Donnelly, P. Inference of population structure using multilocus genotype data. Genetics 2000, 155(2), 945–959. [Google Scholar] [CrossRef] [PubMed]
- Chhatre, V.E.; Emerson, K.J. StrAuto: Automation and parallelization of STRUCTURE analysis. BMC Bioinform. 2017, 18, 192. [Google Scholar] [CrossRef] [PubMed]
- Evanno, G.; Regnaut, S.; Goudet, J. Detecting the number of clusters of individuals using the software STRUCTURE: A simulation study. Mol. Ecol. 2005, 14(8), 2611–2620. [Google Scholar] [CrossRef] [PubMed]
- Earl, D.A.; vonHoldt, B.M. STRUCTURE HARVESTER: A website and program for visualizing STRUCTURE output and implementing the Evanno method. Conserv Genet Resour. 2012, 4(2), 359–361. [Google Scholar] [CrossRef]
- Wright, S. Evolution and the genetics of populations. In Variability within and among natural populations; University of Chicago Press: Chicago (IL), 1978; Vol. 4. [Google Scholar]
- Pacheco-Gil, R.A.; Alvarado, G.; Rodríguez, F.; Burgueño, J. BIO-R (Biodiversity analysis with R for Windows), version 3.2. CIMMYT Research Data & Software Repository Network. 2016. Available online: https://hdl.handle.net/11529/10820.
- Ward, J.H. Hierarchical grouping to optimize an objective function. J. Am. Stat. Assoc. 1963, 58(301), 236–244. [Google Scholar] [CrossRef]
- Murtagh, F.; Legendre, P. Ward's hierarchical agglomerative clustering method: Which algorithms implement Ward's criterion? J. Classif. 2014, 31, 274–295. [Google Scholar] [CrossRef]
- Peakall, R.; Smouse, P.E. GenAlEx 6.5: Genetic analysis in Excel. Population genetic software for teaching and research—An update. Bioinformatics 2012, 28, 2537–2539. [Google Scholar] [CrossRef] [PubMed]
- Weir, B.S. Genetic data analysis II: Methods for discrete population genetic data; Sinauer Associates: Sunderland (MA), 1996; p. 445 p. [Google Scholar]
- Excoffier, L.; Smouse, P.E.; Quattro, J.M. Analysis of molecular variance inferred from metric distances among DNA haplotypes: Application to human mitochondrial DNA restriction data. Genetics 1992, 131(2), 479–491. [Google Scholar] [CrossRef] [PubMed]
- Benjamini, Y.; Hochberg, Y. Controlling the false discovery rate: A practical and powerful approach to multiple testing. J. R Stat. Soc. Ser. B Stat. Methodol. 1995, 57(1), 289–300. [Google Scholar] [CrossRef]
- De Beukelaer, H.; Davenport, G.F.; Fack, V. Core Hunter 3: Flexible core subset selection. BMC Bioinform. 2018, 19, 203. [Google Scholar] [CrossRef]
Figure 1.
Density distribution of quality-filtered SNP markers across maize chromosomes (1 Mb bins) (A), and number of SNP markers by genome location category (B).
Figure 1.
Density distribution of quality-filtered SNP markers across maize chromosomes (1 Mb bins) (A), and number of SNP markers by genome location category (B).
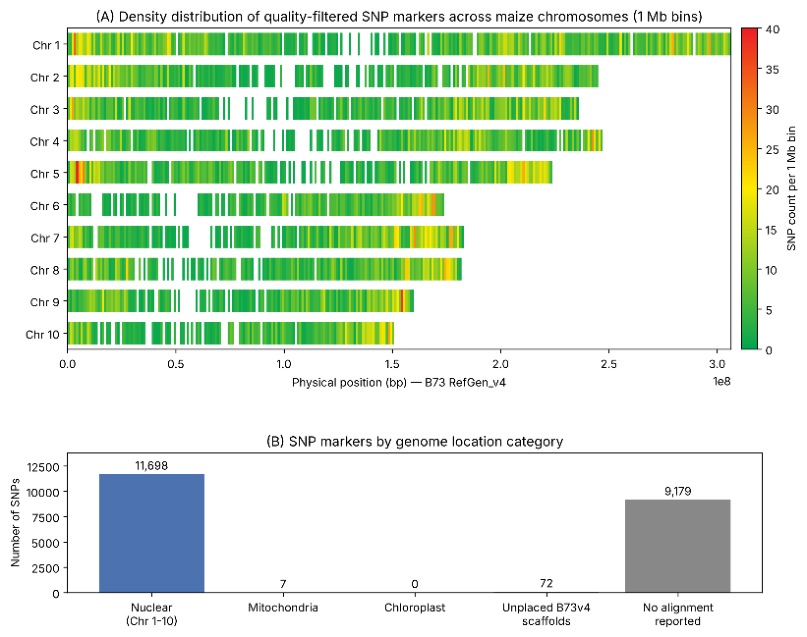
Figure 2.
Linkage disequilibrium (LD) decay by chromosome in the landrace subset (n = 938), based on pairwise r² between SNP markers within 1 Mb of physical distance.
Figure 2.
Linkage disequilibrium (LD) decay by chromosome in the landrace subset (n = 938), based on pairwise r² between SNP markers within 1 Mb of physical distance.
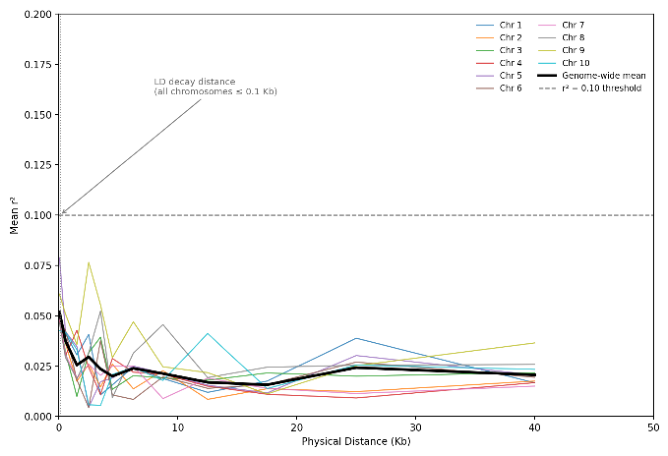
Figure 3.
Population structure of the maize germplasm collection inferred using STRUCTURE. (A) K = 2. (B) K = 6. Each vertical bar represents one accession, and colors indicate the estimated membership coefficient (Q) for each inferred genetic cluster.
Figure 3.
Population structure of the maize germplasm collection inferred using STRUCTURE. (A) K = 2. (B) K = 6. Each vertical bar represents one accession, and colors indicate the estimated membership coefficient (Q) for each inferred genetic cluster.
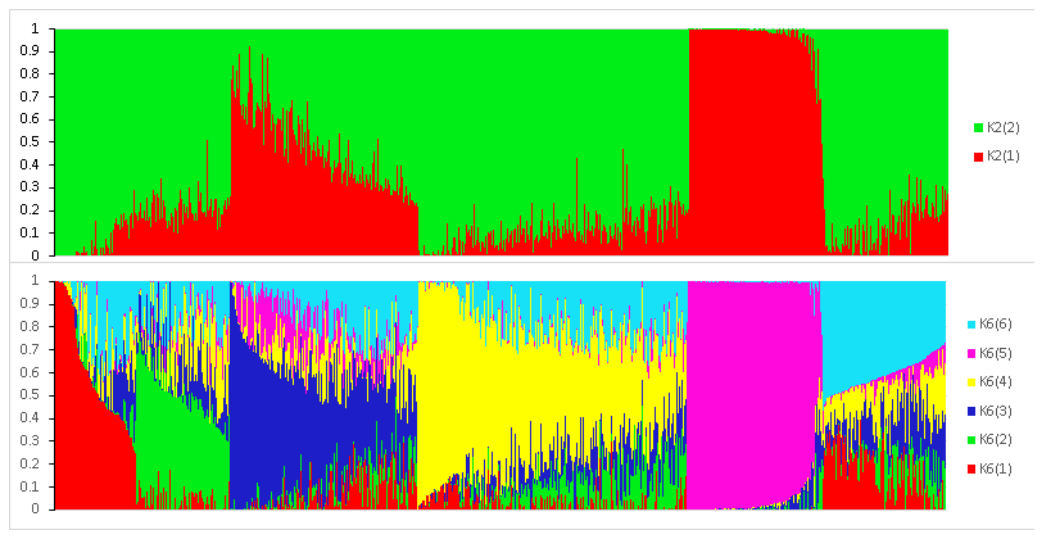
Figure 4.
Hierarchical dendrogram of the maize panel analyzed in this study, with branches colored according to genetic cluster membership inferred by STRUCTURE at K = 2 and K = 6. A branch is colored only when all descendant accessions belong to the same genetic cluster; branches revert to grey when they merge with accessions assigned to a different cluster or with admixed accessions.
Figure 4.
Hierarchical dendrogram of the maize panel analyzed in this study, with branches colored according to genetic cluster membership inferred by STRUCTURE at K = 2 and K = 6. A branch is colored only when all descendant accessions belong to the same genetic cluster; branches revert to grey when they merge with accessions assigned to a different cluster or with admixed accessions.
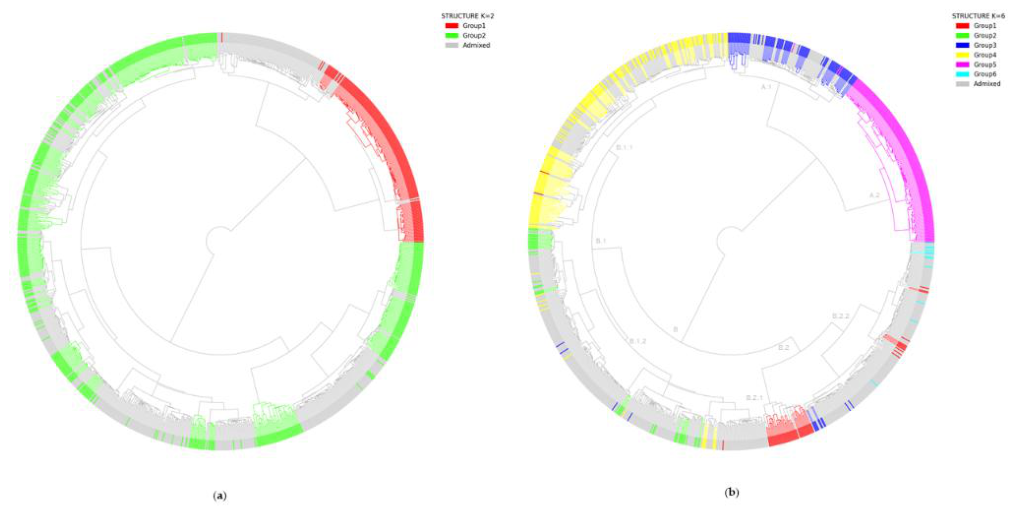
Figure 5.
Principal coordinates analysis (PCoA) based on Rogers' modified genetic distance, showing pairwise combinations of the first three principal coordinates. Colors indicate the genetic clusters identified through STRUCTURE analysis at K = 6 (Q > 0.50), admixed group in grey.
Figure 5.
Principal coordinates analysis (PCoA) based on Rogers' modified genetic distance, showing pairwise combinations of the first three principal coordinates. Colors indicate the genetic clusters identified through STRUCTURE analysis at K = 6 (Q > 0.50), admixed group in grey.
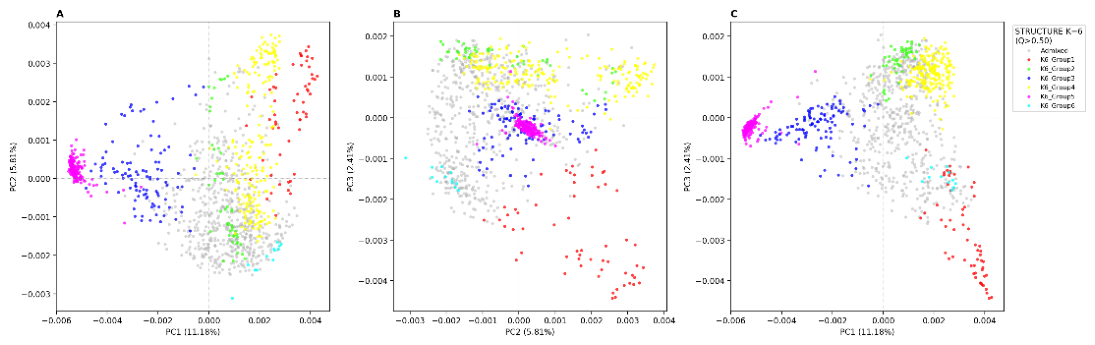
Figure 6.
Principal coordinates analysis (PCoA) based on Rogers' modified genetic distance, showing the 231 accessions of the stratified core collection (colored symbols) within the entire germplasm collection (n = 1,157; grey dots). Blue: landraces (n = 173) and red: breeding materials (n = 36) selected by Core Hunter 3; green triangles: race representatives forced into the core (n = 22).
Figure 6.
Principal coordinates analysis (PCoA) based on Rogers' modified genetic distance, showing the 231 accessions of the stratified core collection (colored symbols) within the entire germplasm collection (n = 1,157; grey dots). Blue: landraces (n = 173) and red: breeding materials (n = 36) selected by Core Hunter 3; green triangles: race representatives forced into the core (n = 22).
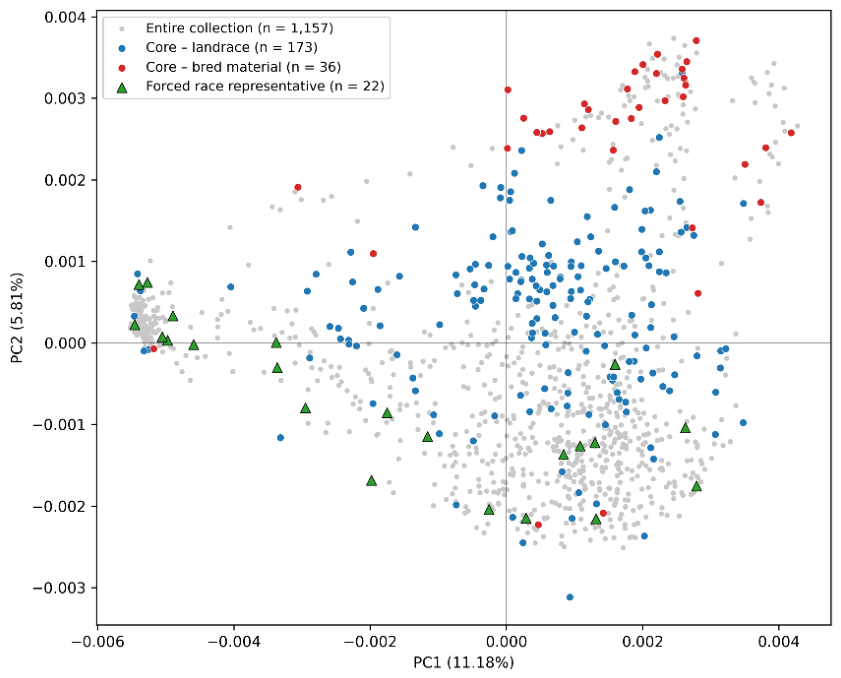
Figure 7.
Geographic distribution of the Chilean national maize germplasm collection and the genotyped study panel. Genotyped panel (blue), accessions not genotyped (light gray), sites containing both genotyped and non-genotyped accessions (blue–gray). Circle size is proportional to the number of accessions recorded at each collection site (1–4, 5–9, or ≥10 accessions).
Figure 7.
Geographic distribution of the Chilean national maize germplasm collection and the genotyped study panel. Genotyped panel (blue), accessions not genotyped (light gray), sites containing both genotyped and non-genotyped accessions (blue–gray). Circle size is proportional to the number of accessions recorded at each collection site (1–4, 5–9, or ≥10 accessions).
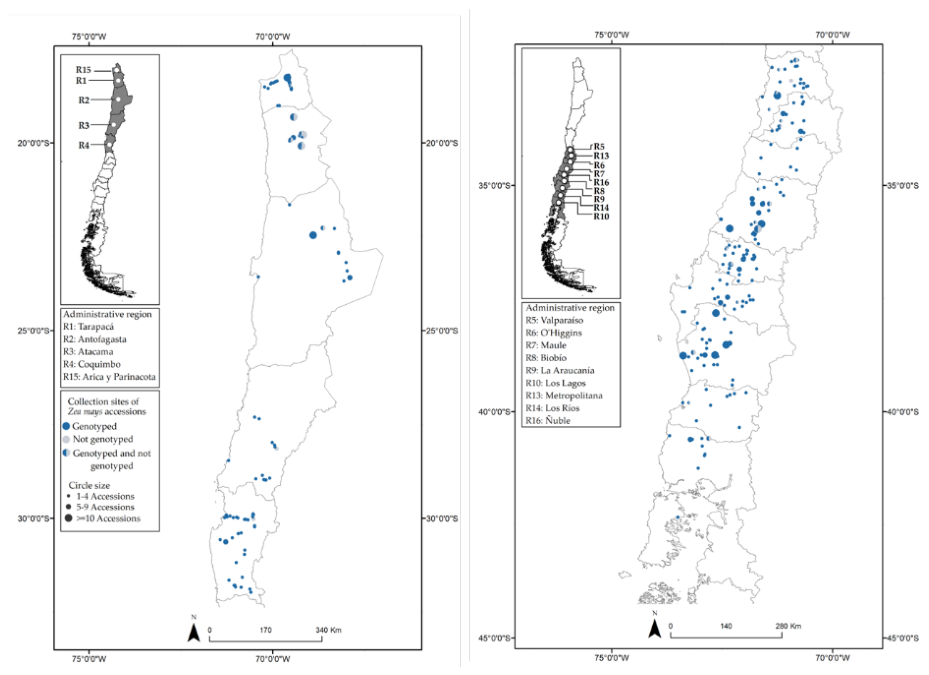

Table 1.
Genetic diversity statistics of the quality-filtered SNP dataset (n = 20,956 SNPs) for the entire germplasm collection and for the landrace and breeding material subsets.
Table 1.
Genetic diversity statistics of the quality-filtered SNP dataset (n = 20,956 SNPs) for the entire germplasm collection and for the landrace and breeding material subsets.
| Metric | Overall (n = 1,157) | Landrace (n = 938) | Breeding Material (n = 172) |
| Minor allele frequency (MAF) | 0.178 | 0.180 | 0.158 |
| Gene Diversity (GD) | 0.253 | 0.254 | 0.227 |
| Heterozygous calls (Ho) | 0.270 | 0.292 | 0.123 |
| Shannon-Wiener index (H) | 0.398 | 0.400 | 0.362 |
| Missing data (%) | 5.7 | 4.2 | 14.2 |
Table 2.
Pairwise FST among genetic groups identified through STRUCTURE analysis (K = 2 and K = 6), estimated using a pool-size-weighted allele frequency variance approach.
Table 2.
Pairwise FST among genetic groups identified through STRUCTURE analysis (K = 2 and K = 6), estimated using a pool-size-weighted allele frequency variance approach.
| K = 2 | |||||
| Group 1 | Group 2 | N₁ | N₂ | FST | |
| Group 1 | Group 2 | 184 | 534 | 0.072 | |
| K = 6 | |||||
| Group 2 | Group 3 | Group 4 | Group 5 | Group 6 | |
| Group 1 | 0.080 | 0.117 | 0.038 | 0.201 | 0.044 |
| Group 2 | — | 0.052 | 0.017 | 0.103 | 0.042 |
| Group 3 | — | — | 0.053 | 0.051 | 0.049 |
| Group 4 | — | — | — | 0.126 | 0.012 |
| Group 5 | — | — | — | — | 0.091 |
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.
Copyright: This open access article is published under a Creative Commons CC BY 4.0 license, which permit the free download, distribution, and reuse, provided that the author and preprint are cited in any reuse.