

Submitted:
11 October 2026
Posted:
13 October 2026
Read the latest preprint version here
Abstract
Live data migration across geographic regions in Internet-scale cloud services requires distributed locking—but a dedicated lock service adds infrastructure, a lock lookup on the request path, and an atomicity gap between lock release and location cutover. We describe an architectural alternative: embedding lock metadata in the routing records that services already read on every user request. The coordination primitives are standard—fencing tokens, leases, and conditional writes; what changes is where lock state lives. Deployed at a large-scale real-time messaging platform processing 6–10 million migrations per day, this placement lets lock checks ride the existing routing lookup, adding one point read only for the small, transient set of resources holding an active lock; it makes location swap and lock release a single atomic database write; and it propagates locks by passive cache expiry rather than active invalidation. Write-lock duration—the only user-impacting phase—holds at p99 under 20 seconds. We compare the design architecturally with Chubby, ZooKeeper, Redlock, and DynamoDB Lock Client, separate measured from inferred benefits, and discuss where infrastructure-embedded coordination applies.
Keywords:
distributed locking
; live data migration
; routing metadata
; cache convergence
; cloud computing
; data sovereignty
; coordination protocols
1. Introduction
Data sovereignty regulations increasingly require Internet-scale cloud services to move user data across geographic data centers while the service remains available. In a real-time messaging platform—where hundreds of millions of users exchange messages, share media, and collaborate daily—this means migrating live conversations across regions without perceptible disruption. Each migration requires coordinated locking: writes must be blocked during final synchronization, deletes must be intercepted during bulk copy, and concurrent migration attempts on the same resource must be prevented.
The conventional approach is a centralized lock service such as Chubby[1] or ZooKeeper.[2] Effective for many coordination workloads, it has three drawbacks for live migration at Internet scale. Additional infrastructure: a lock service needs its own deployment, monitoring, capacity planning, and on-call rotation, and becomes a shared dependency. A lookup on the request path: a service cannot know whether a resource is migrating without asking, so it must check the lock on any operation that could be affected—overhead paid continuously for a condition affecting a tiny fraction of resources. Atomicity gap: switching the routing location and releasing locks are separate actions, so a crash between them leaves a partial cutover—location changed but locks still held, or the reverse—requiring manual repair.
Every resource-owning service in our platform already maintains a routing database: a per-resource document, in a globally distributed store, giving the location of the resource’s data, resolved by every user request. We extended this document to carry lock state. Because the lock now lives where routing already lives, checking it costs no extra lookup unless a lock is active, releasing it and switching location is a single atomic write, and its correctness rests on token and version validation rather than synchronized clocks. The mechanism is the production locking substrate for residency-driven migration across the platform’s resource-owning services.
We do not propose a new coordination primitive: fencing tokens, leases, and conditional writes are well established. The contribution is architectural—where lock state lives—together with the consequences of that placement, documented at production scale: (1) a routing-embedded lock architecture in which lock and routing metadata share one database document, so enforcement needs no separate lookup and cutover is one atomic write; (2) a lock lifecycle—token-gated operations, lease-based expiry with bounded renewal, and passive cache convergence—with its timing parameters and their rationale; and (3) a production evaluation that separates what is measured (lock durations, reliability, the cost of a lock read) from what is inferred (the comparison with a lock-service baseline), with a failure-mode analysis.
2. System Model and Background
We first establish the system context, the migration process that needs locking, and the consistency, caching, and failure assumptions; all numbers reported later come from this production deployment.
2.1. Platform and Routing Model
The messaging platform is built as many independently owned microservices—thread metadata, message stores (hot and cold tiers), access-control lists, media, reactions, and notification preferences are each owned by a different team and backed by different storage. A single logical entity, such as a conversation, is therefore spread across services rather than held in one place.
To route each user request to the region that currently holds an entity’s data, every resource-owning service maintains a routing database: one location document per resource, keyed by resource identifier, holding the entity’s geographic location. This document is backed by Azure Cosmos DB, globally replicated across 12 or more regions, and is resolved on every user request through a shared routing library that each service links at build time. Ordinary point reads of this document are served from a local-region replica; Cosmos DB’s published SLA guarantees read latency under 10 ms at the 99th percentile and typically 4 ms at the median.[3] This per-request routing lookup is the infrastructure our design reuses.
The location document points to the storage account holding all of a resource’s data, which for a conversation spans several collections—metadata, hot and cold message stores, the participant roster, and per-user consumption state—and one user operation typically touches several. Because every operation resolves the location document before reaching any collection, a lock embedded in that one document applies uniformly to the whole resource, however many stores its data occupies.
2.2. Migration Process and the Need for Locking
Data-residency regulation requires moving an entity’s data between regions while it stays live. Migration runs four ordered phases, summarized here so the paper is self-contained; the orchestration driving them is companion work.[4,5]
- 1.
- Pre-lock (convergence). Migration intent is recorded and the system waits for caches to converge (§2.4) before any user-visible restriction takes effect.
- 2.
- Hard-delete lock. Historical data is bulk-copied to the target while physical deletes are intercepted (converted to tombstones) so that a delete during copy is not lost.
- 3.
- Write lock. Writes are briefly frozen while the small remaining delta is copied, so source and target agree at cutover.
- 4.
- Atomic cutover. The entity’s active location switches to the target and all locks release together.
2.3. Consistency Requirements
Correctness for migration means three things. Mutual exclusion: at most one migration may hold and advance the lock for a given entity. No lost updates: no write or delete may slip through to the source region once the corresponding lock phase is in force across the fleet. Atomic cutover: the routing location and the lock state must change together—there must be no observable state in which the location has switched but locks remain, or vice versa. Reads are never blocked in any phase; only writes and deletes are affected, and only briefly.
2.4. Caching and Replication Model
Because the location document is read on every request, services cache it in multiple tiers—for example an edge cache, a regional cache, and a service-local cache—each with its own time-to-live (TTL). TTLs differ by service: one service in our platform uses a maximum tier TTL of 2 hours, another 4 hours. The routing database has a single write region, with read replicas elsewhere, and is configured for bounded-staleness consistency, so a replica’s lag behind the write region has an upper bound enforced by the database.[3] Each resource-owning service configures that bound, trading data freshness against cost; our chat location database uses 5 minutes (§4.1). These two quantities—the maximum cache TTL and the bounded replication lag—are what the convergence phase depends on (§4).
2.5. Failure and Clock Assumptions
We assume a standard crash-recovery model: services and the orchestrator may crash or be taken out of rotation at any time, messages may be lost, and network partitions may occur. In our environment these are not rare events—the orchestrator runs as a durable workflow across 300 or more host machines that the cloud infrastructure continuously recycles during deployments and scaling.
Crucially, the design makes no assumption of a synchronized global clock. Leases are coarse (hours for the copy phases, minutes for the write phase), so clock drift of seconds is immaterial; correctness comes from token validation and atomic conditional writes (§3), not from comparing timestamps across machines.
2.6. Store-Level Movement vs. Cross-Service Coordination
Managed stores already replicate and move data across regions—our platform relies on Cosmos DB multi-region replication,[6] and Nomad[7] and Albatross[8] migrate data within one storage system. But an entity’s data spans many independently owned stores, and no single store owns all of it. Each service moves its own bytes; what must be coordinated across services is the locking and cutover—preventing concurrent migrations, intercepting deletes, freezing writes, and switching location atomically. That coordination is this paper’s problem.
3. Design: Routing-Embedded Locks
3.1. Location Document Schema
We extend the location document introduced in §2.1—a single per-resource document supporting point reads and atomic conditional writes—to carry lock metadata alongside its location metadata (Figure 1):
Figure 1.
The location document stores routing and lock state in the same database document. The primary section contains the active location and any migration locks. The secondary section is created during migration to hold the target location and prevent premature writes to the target.
Figure 1.
The location document stores routing and lock state in the same database document. The primary section contains the active location and any migration locks. The secondary section is created during migration to hold the target location and prevent premature writes to the target.
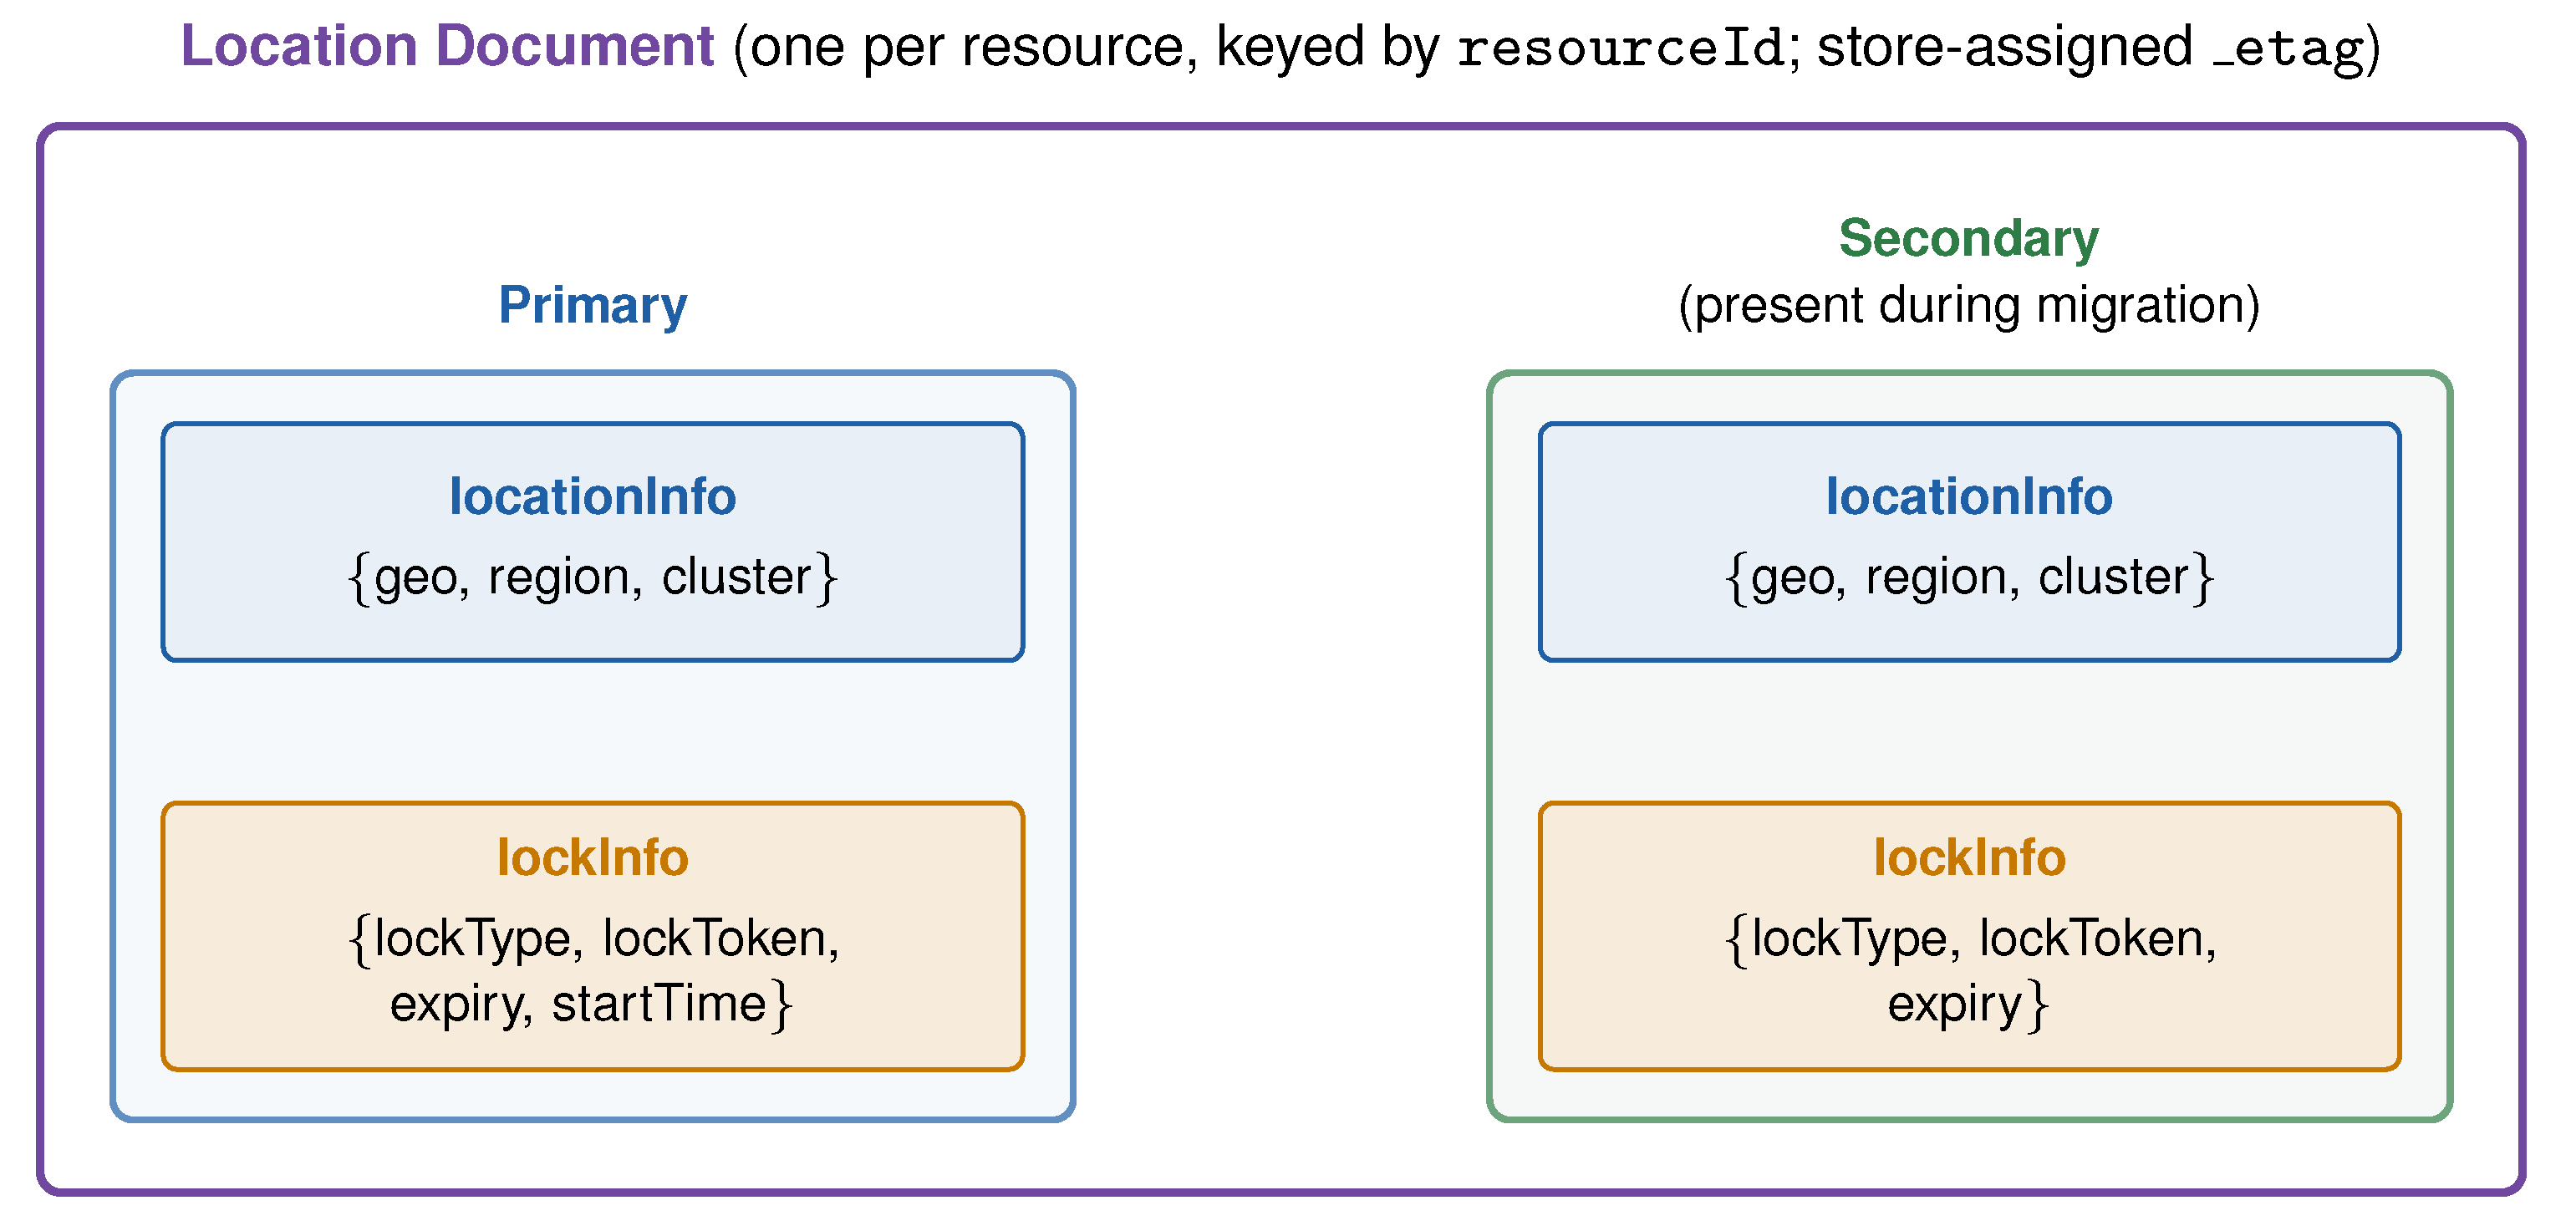
This co-location is the core design decision. Because lock state and location state reside in the same document: (a) a routing lookup carries lock state at no extra call—for resources without an active lock, checking it needs no additional read; (b) the location swap and lock release can be performed as a single atomic write; and (c) every lock mutation is guarded by the document’s ETag. An ETag is an opaque version identifier that the database regenerates on every successful write to a document. A writer supplies the ETag it last read as an if-match condition; the write commits only if the current ETag still matches, and is otherwise rejected atomically (HTTP 412).[9] Because all writes execute in the single write region (§2.4), the check runs against the authoritative copy, never a stale replica: an ETag-conditional write is a compare-and-swap on the whole document, versioned by the store, not by any client clock.
3.2. Lock Enforcement on the Routing Path
When a service receives a user request, it resolves the location document through the shared routing library, which returns the current lock state with the location. The service then allows or denies the operation—blocking writes during a write lock, converting deletes to tombstones during a hard-delete lock. No separate lock-check call exists; enforcement is a by-product of the routing lookup.
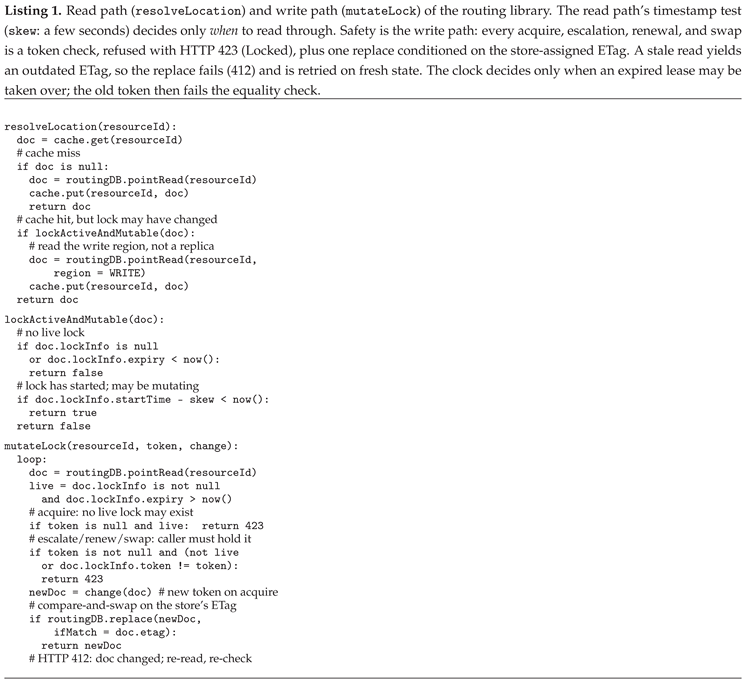
The library returns cached records where it safely can. On a cache miss it performs a point read, returning location and lock state together, and populates the cache. On a cache hit it returns the cached record, unless that record carries an active, currently mutable lock (non-expired, start time passed within a small clock-skew margin); then it reads through to the write region, never a read replica, because the orchestrator may have changed the lock since caching. That read-through is the entire residual overhead, confined to the small, transient set of resources with an in-flight lock (Listing 1).
3.3. Token-Gated Operations
When the orchestrator acquires a pre-lock, the routing library issues a lock token stored in the location document. That token is required for every later operation—escalating to hard-delete lock, to write lock, renewing expiry, and the final swap. While a valid (non-expired) lock exists, the library rejects any mutation without the matching token before it reaches the database (Listing 1), so only the orchestrator instance that began the migration can advance or complete it.
This is the fencing-token pattern Kleppmann[10] recommends for preventing stale lock holders from corrupting state, except that enforcement lives in the shared routing library every service embeds. Because the library is the only path to the routing database, the fencing check cannot be accidentally omitted: it is infrastructural rather than contractual.
3.4. Two-Layer Enforcement
Enforcement splits across two layers. The shared routing library persists lock state, controls valid transitions (pre-lock → hard-delete → write lock), enforces token ownership, and reports lock state; the resource-owning service allows or denies user operations per that state. Because the library is linked into every service, no service can resolve a route without receiving lock state or mutate the document without a valid token—the safety boundary is uniform. The split also keeps each layer simple: the library knows only lock states and their legal transitions, and each service only which of its operations are writes or deletes.
4. Lock Lifecycle
A migration progresses through four lock phases with escalating severity.[5] All phases use the same lock token issued during pre-lock.

Table 1.
Lock phases, configured expiry, and enforcement. Expiry is a liveness timeout; actual hold times are shorter. Reads are never blocked.
Table 1.
Lock phases, configured expiry, and enforcement. Expiry is a liveness timeout; actual hold times are shorter. Reads are never blocked.
| Lock Phase | Configured Expiry | User Impact | Enforcement Behavior |
|---|---|---|---|
| Pre-lock | 48h + convergence delay | None | Prevents concurrent migration; marks routing dirty |
| Hard-delete lock | 6h (renewable) | None visible | Service converts physical deletes to tombstones |
| Write lock | 5 min | Writes return retriable errors | Service blocks write operations |
| Swap + unlock | Instantaneous | None | Single atomic database write |
4.1. Phase 1: Pre-Lock with Passive Cache Convergence
The orchestrator requests a pre-lock (typically 48 hours). The service generates a lock token, marks the document migration-in-progress, and computes a convergence delay = maximum cache TTL across its tiers + database replication bound, returning the token, that delay (as the lock’s start time), and an expiry. The orchestrator then waits that delay plus a ∼10-minute safety buffer on a durable timer, and never less than the replication bound. The total varies by service (about 1–4 hours) and ensures that before stronger locks begin, every cache tier has expired its stale entry and re-fetched the now-dirty document.
Figure 2.
Passive cache convergence. After pre-lock, the orchestrator waits out the maximum cache TTL, the bounded replication lag (∼5 min), and a ∼10-minute safety buffer; all caches then re-fetch the dirty-flagged document with no active invalidation.
Figure 2.
Passive cache convergence. After pre-lock, the orchestrator waits out the maximum cache TTL, the bounded replication lag (∼5 min), and a ∼10-minute safety buffer; all caches then re-fetch the dirty-flagged document with no active invalidation.
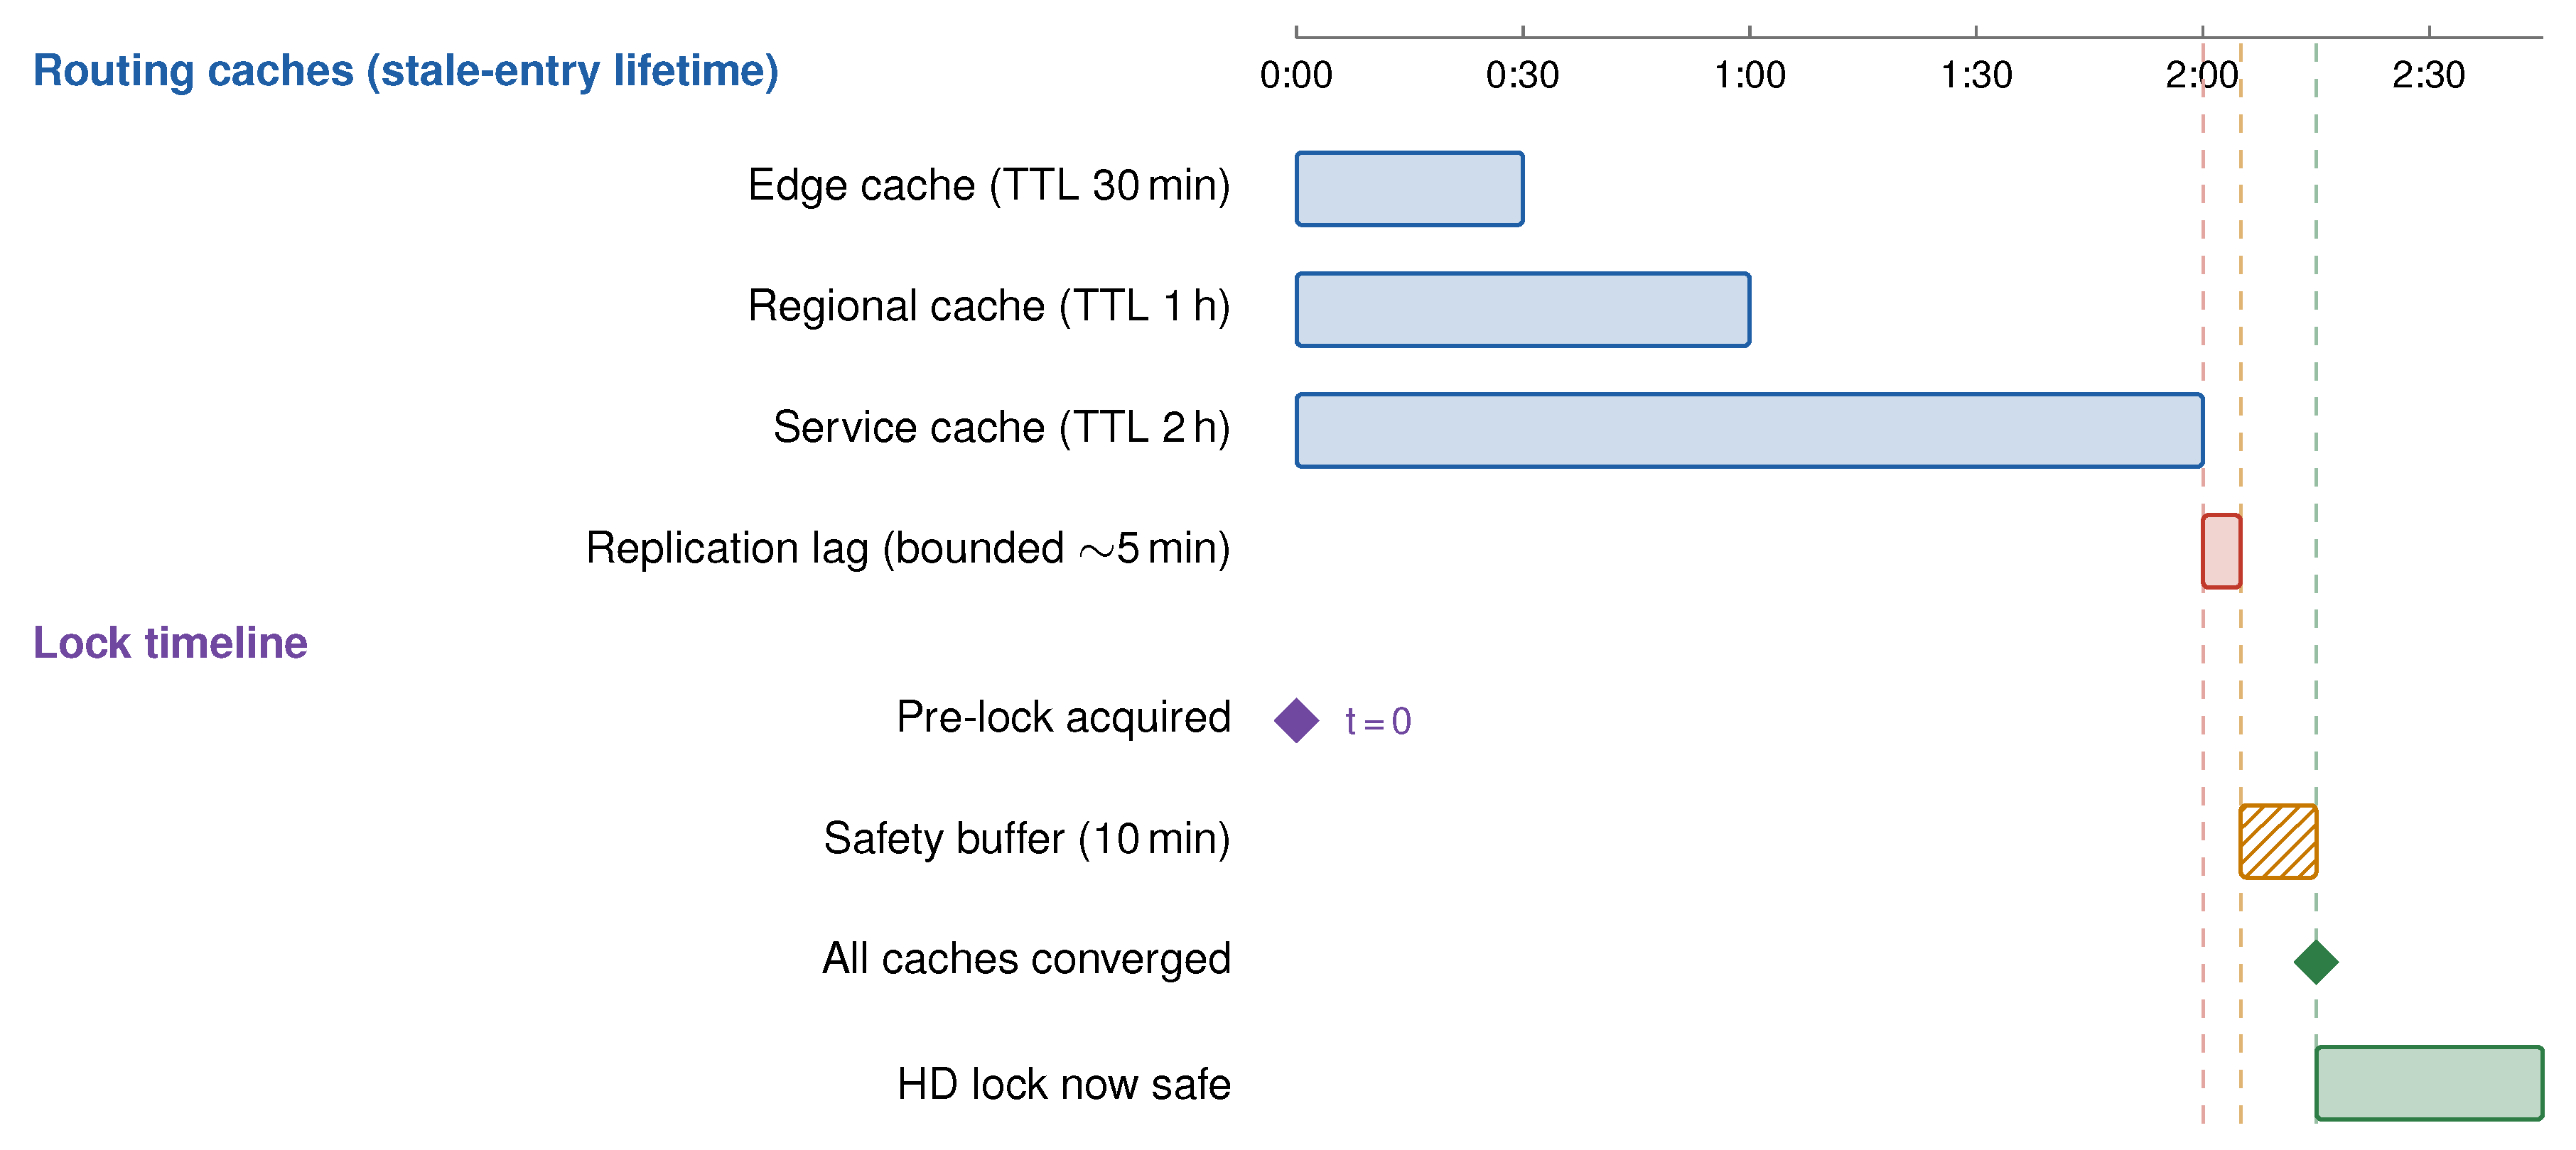
Why passive convergence, not active invalidation? At Internet scale, discovering every cache instance with certainty is impossible—services run across dozens of clusters with independent cache, edge, and CDN tiers—and an invalidation that misses even one creates a correctness gap: that stale cache could admit a write to the source during bulk copy. Passive expiry depends only on configuration: if the maximum TTL across tiers is T, then T plus a buffer after marking the document dirty, all caches have converged, regardless of runtime topology. We accept 1–4 hours of latency in this zero-user-impact phase for that guarantee—an instance of Vogels’s observation that eventual consistency suffices when staleness is bounded and tolerable.[11]
How the timing values were chosen. The replication bound is a per-service setting that trades freshness against cost: a tighter bound raises the store’s cost. Our chat location database uses 5 minutes, chosen through extensive production experimentation to keep cost relatively low; it is an example, not a design constant. The ∼10-minute buffer is engineering judgment, not an optimum. At about twice the replication bound, it absorbs requests in flight when the document was marked dirty, seconds of clock skew between the service that computes the start time and the orchestrator that waits on it, and durable-timer jitter. It costs at most about 15% of a 1–4-hour phase with no user impact, and monitoring (§5.4) has not shown it to be insufficient.
4.2. Phases 2–3: Hard-Delete and Write Locks
The orchestrator escalates to a hard-delete lock (same token) for the historical copy, then a write lock (same token) for the brief delta catch-up. During the write lock, writes receive retriable HTTP 423 (Locked) errors that client SDKs retry after a brief backoff, making the interruption transparent to most users. Each lock type has its own expiry, but none can outlive the pre-lock, which acts as the parent lease bounding the whole migration. The orchestrator periodically renews the hard-delete lock, and the service enforces a maximum pre-lock duration, so a migration that overruns fails for investigation rather than renewing indefinitely; this is rare.
4.3. Phase 4: Atomic Swap + Unlock
The orchestrator calls the swap API, and the service performs a single ETag-conditional point-write (Listing 1) that atomically: (a) updates locationInfo to the target region; (b) clears lockInfo, releasing all locks at once; and (c) locks the secondary location to prevent premature writes to the target before caches converge on it.
Figure 3.
Atomic swap and lock release. One database replace operation simultaneously changes the primary location and clears all lock state. ETag-based optimistic concurrency prevents conflicting writes.
Figure 3.
Atomic swap and lock release. One database replace operation simultaneously changes the primary location and clears all lock state. ETag-based optimistic concurrency prevents conflicting writes.
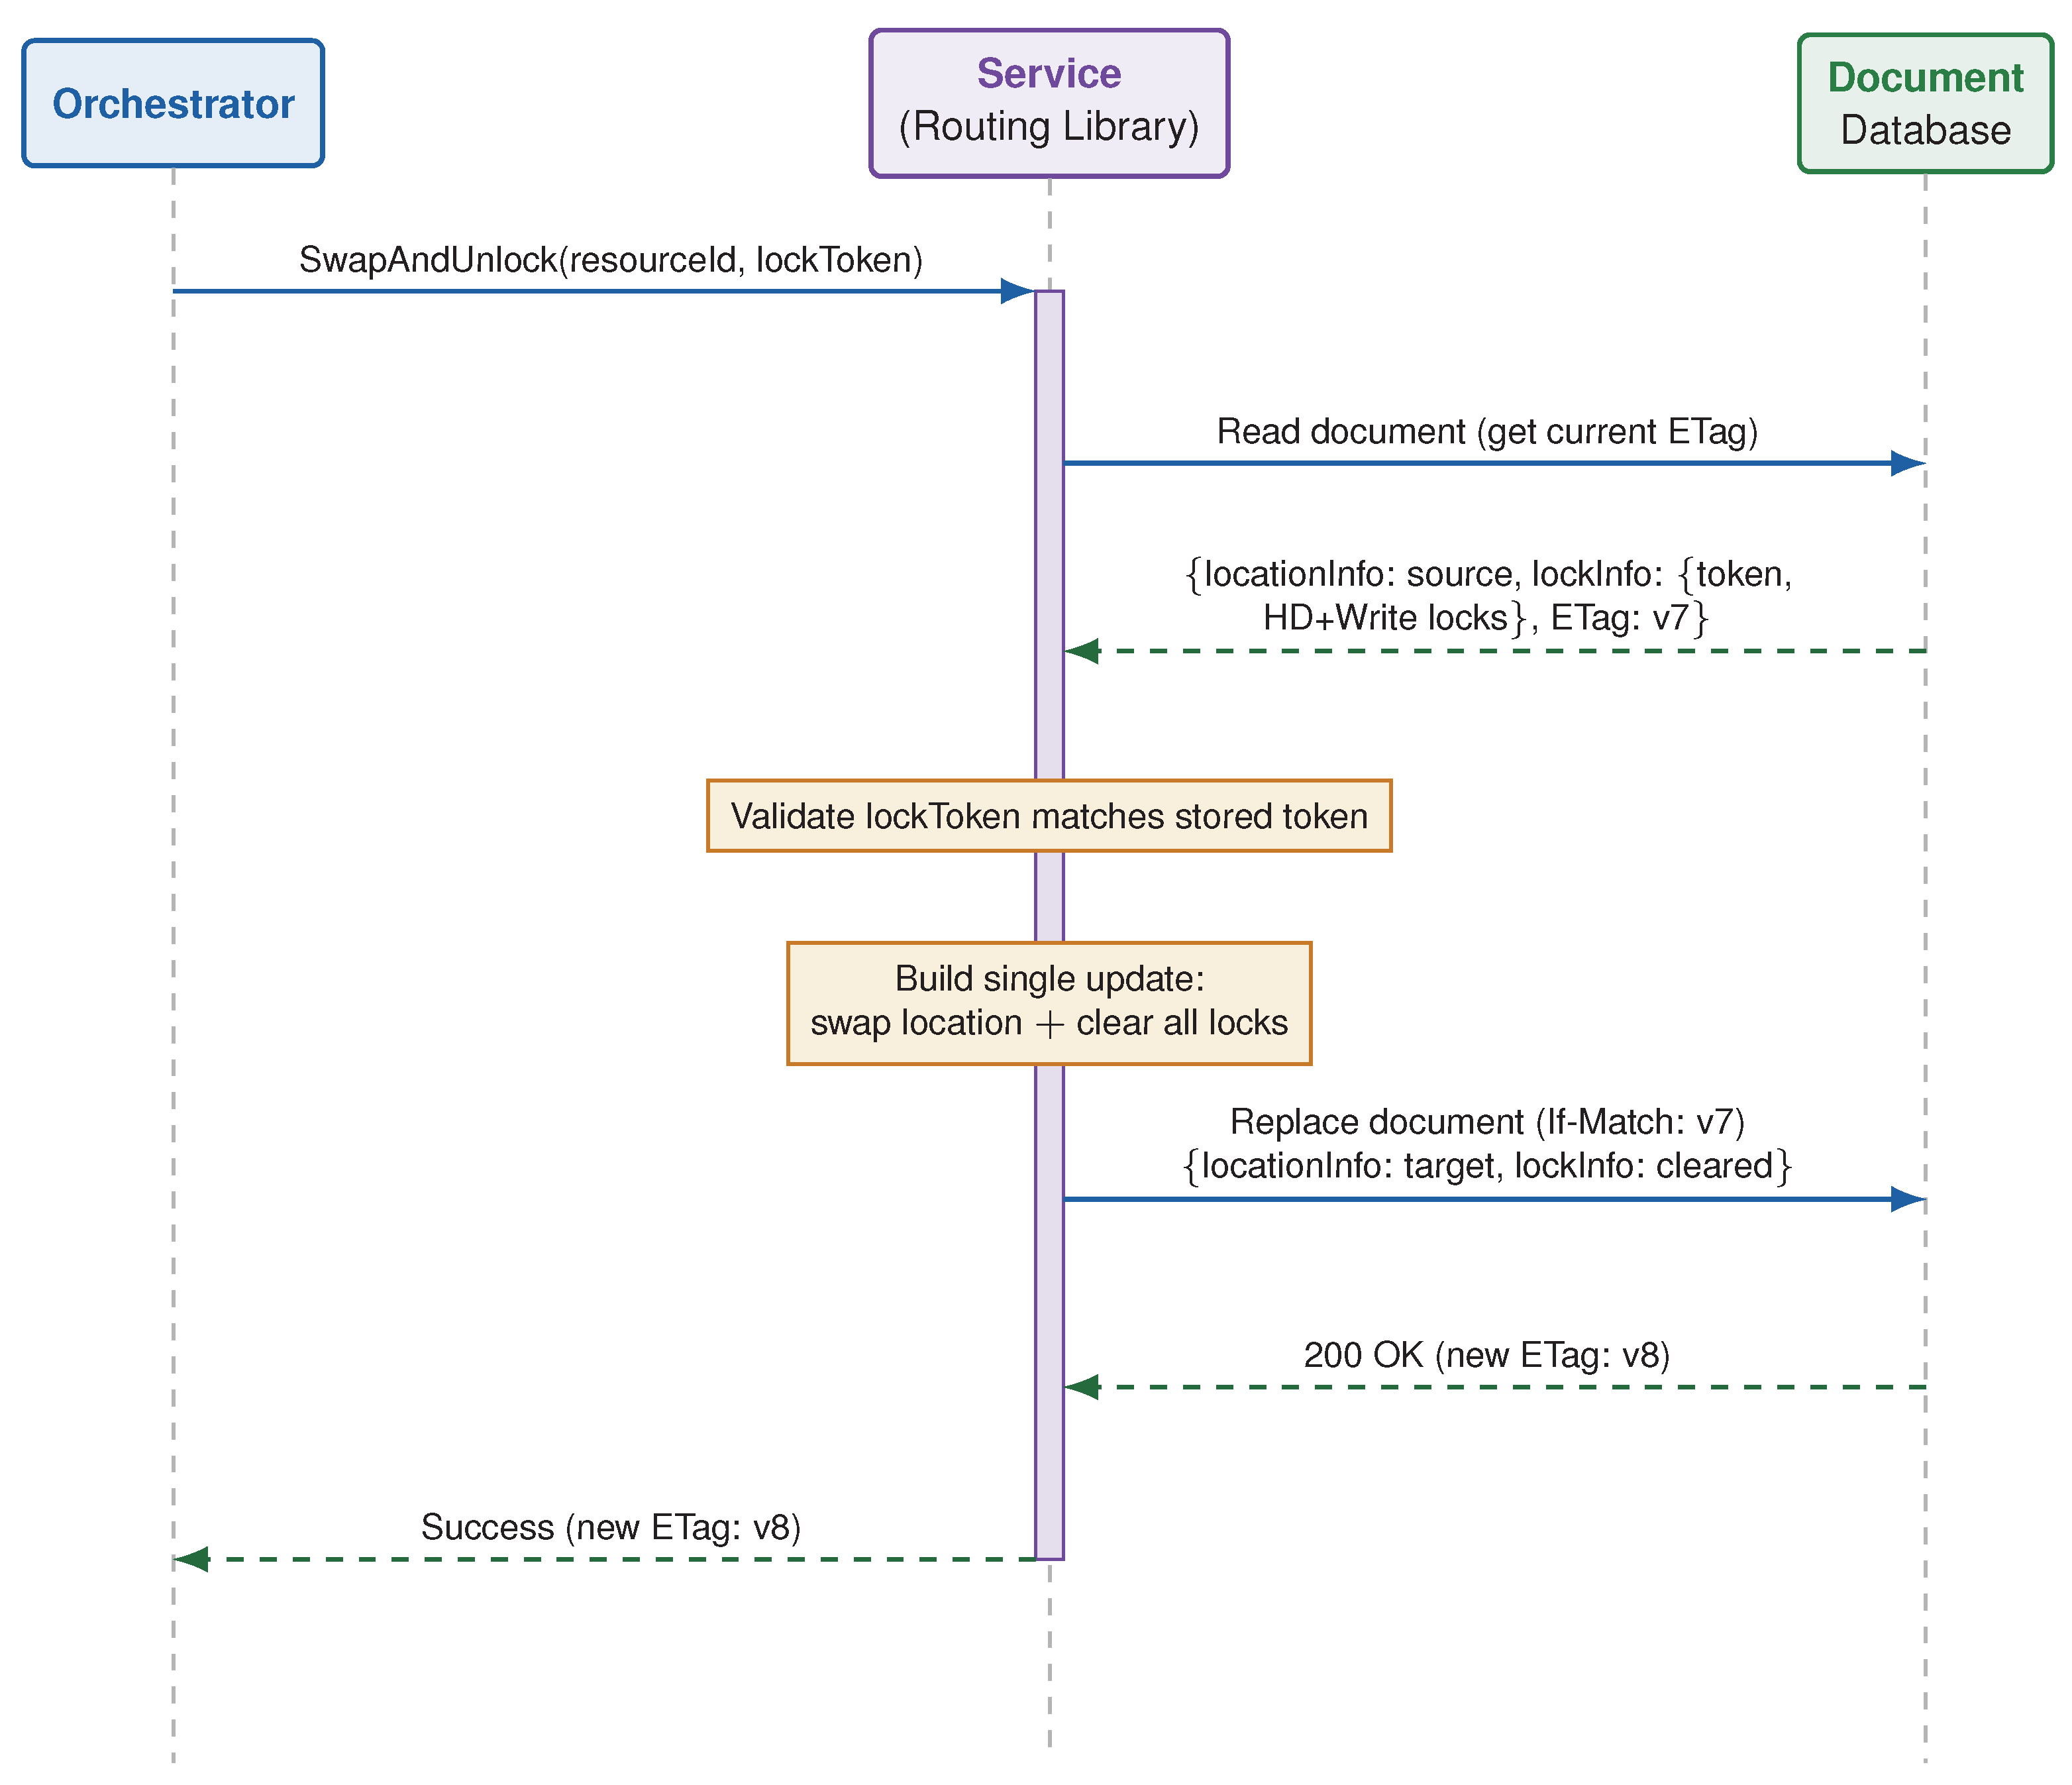
Because location and lock state share one document, partial cutover is impossible by construction: if the write succeeds, both changed; if it fails, neither did. This was a day-one design decision, not a post-incident fix, and it eliminates a failure class inherent to storing lock and routing state separately.
5. Evaluation
5.1. Methodology and Deployment Status
The mechanism is deployed in production, not a prototype (§1). We evaluate it using production telemetry over a 30-day window, aggregated from structured logs across regions. A controlled multi-system benchmark is not feasible on a live platform of this scale, so we combine reliability telemetry (§5.2), a latency analysis that separates the measured cost of a lock read from the inferred comparison with a lock-record baseline (§5.3), and a failure-mode analysis under the environment’s continuous, uncontrolled fault load (§5.4).
5.2. Reliability and Scale
The system processes 6–10 million migrations per day. The write-lock phase—the only user-impacting phase—holds for a median of 13 seconds (p75: 15s, p99: 19s), well under the configured 5-minute safety expiry. First-attempt migration success is 99.9%; the remainder complete on automatic retry, so no migration was left permanently failed during the window. Across the 30-day observation window we observed no partial-cutover incidents and no orphaned locks. Lock expiry before migration completion occurred in fewer than 0.1% of migrations, triggering automatic retry with a fresh lock.
All participating resource-owning services (the number has nearly doubled since launch) use the shared routing library, and none has implemented custom lock-enforcement logic.
5.3. Latency: Measured Cost, Inferred Comparison
What we measure. Our only lock-specific read is the read-through in Listing 1: a cached record carrying an active, started lock triggers one point read of the location document from the write region (2 request units), which service-side telemetry shows at ∼50 ms p99—the in-region Cosmos DB read itself is under 10 ms p99 per its SLA,[3] the rest network latency to the write region and service-side processing. Without such a lock, no lock-specific read occurs.
What we infer. Routing-embedded locking was this platform’s design from launch, so no earlier lock service exists to measure against, and deploying one on the live request path solely as a benchmark was not feasible. The read-through is, however, an in-situ proxy for the closest realistic baseline—a lock record in a dedicated table of the same store, as in the DynamoDB Lock Client:[12] the same point read against the same store, write region, and client stack. That baseline pays this read on every operation that might touch a migrating resource, since the service cannot know in advance which do; ours pays it only for resources already holding a lock. If a fraction f of operations target locked resources, the baseline performs about times as many lock reads; the two converge as f approaches 1. As an illustration only, if 1% of operations targeted locked resources, the baseline would perform about a hundred times as many lock reads as our design. We do not estimate the cost for consensus-based services, which add a hop to a separate cluster.
We therefore claim a structural reduction in critical-path lock reads whose per-read cost is measured. We do not claim a measured end-to-end latency or resource-usage improvement over a deployed alternative, which this evaluation cannot provide (§5.6).
5.4. Correctness Under Failure
Correctness rests on one invariant enforced inside the routing library: every mutation of the lock state is a single conditional write presenting both the current lock token and the document’s ETag. Only the token holder can advance or release the lock, and a new token is issued only after the previous lease expires or is released. Table 2 traces how this invariant, with lease expiry and the durable-workflow model, handles the failure classes a distributed lock must survive.
Table 2.
Failure classes and the properties that handle them, corroborated by production telemetry and testing rather than controlled fault injection. Host loss, deployments, and failovers occur continuously in our environment, so 30 days without a partial cutover is sustained evidence.
Table 2.
Failure classes and the properties that handle them, corroborated by production telemetry and testing rather than controlled fault injection. Host loss, deployments, and failovers occur continuously in our environment, so 30 days without a partial cutover is sustained evidence.
| Failure | Guaranteed behavior | Why |
|---|---|---|
| Orchestrator crash mid-migration | Migration resumes with no manual action; impact bounded by lease | The orchestrator is a durable workflow that resumes on any of 300+ machines from its last checkpoint, token persisted. A crash during the write lock lets the short lease auto-release, so writes resume. |
| Database failure / regional failover | No partial cutover; migration retries | Cutover is one atomic conditional write. The durable workflow retries transient failures against a healthy write region. Lock durability equals routing durability; no separate store can desynchronize. |
| Network partition / split-brain | No two writers can both mutate a lock | The replicated store, not an application node, holds the record. A mutation needs the matching token and ETag in one compare-and-swap, so a second writer loses and retries. |
| Concurrent migration attempts | Exactly one proceeds; others abort cleanly | Pre-lock is itself exclusive: a request finding an unexpired lock under another token gets HTTP 423; of two simultaneous requests, the loser’s ETag-conditional write fails (412) and its re-read finds the winner’s lock. The loser aborts before any destructive action. Observed at <0.1% of migrations, failing as designed. |
| Stale cache during bulk copy | No write reaches the source after its lock is in force | The convergence wait (§4.1) exceeds the declared maximum cache TTL plus the bounded replication lag, so every cache tier has re-read the locked document before stronger locks begin. |
| Lease expiry before completion | No stale holder can act; resource becomes migratable again | An expired lease invalidates its token; a slow orchestrator that resumes finds its token rejected.[10] A fresh migration re-drives from a consistent source. |
| Mixed service versions during rollout | No version can bypass enforcement | The token+ETag invariant lives entirely in the shared library and has been stable since launch; compatibility tests and a schemaVersion field make rollout safe. |
What five minutes of staleness does—and does not—allow. A replica may serve lock state that is stale by up to the configured bound—5 minutes here. That affects visibility—when a reader learns of a lock—not exclusion. Every acquisition is a write evaluated in the single write region against the current ETag; a writer acting on a stale read presents an outdated ETag, its write fails (412), and once its re-read reflects the live lock it is refused (423). Staleness can thus cause an orchestrator to attempt a conflicting acquisition, never to complete one. The visibility gap is closed in two ways. Pre-lock restricts no user operation until the convergence wait, which covers the replication bound, has elapsed. And once a document carries a lock, the routing library reads it only from the write region, never a replica, so enforcement never acts on lagging lock state. The orchestrator’s confirmation of each new lock is only an extra safeguard. One benign race remains: an orchestrator whose location read was stale may pre-lock a resource another instance has just swapped and released, so it re-reads the location after pre-lock and drops resources already at the target.
Is Table 2 exhaustive? Not formally. Its rows cover the faults admitted by the model in §2.5—crash, failover, message loss and partition, concurrency, staleness, lease timing, and version skew. Faults outside that model are not covered: Byzantine behavior, a bug in the routing library itself, the store violating its ETag or staleness guarantees, and operator force-release (§8), which is guarded procedurally by multi-level approval.
How correctness was checked. We have not applied formal methods such as TLA+; a machine-checked model of the token+ETag protocol is future work. Validation is empirical. Before release, each lock type was placed on test resources under generated production-style read, write, and delete traffic, checking that every operation was allowed, blocked, or tombstoned as the phase prescribes. In production, continuous synthetic probes repeat the cycle—acquire a lock, wait out convergence, confirm the lock on the read path, drive simulated reads and writes, and assert the outcomes—so an enforcement regression surfaces as a probe failure rather than a data anomaly. Testing shows correct behavior on the cases exercised, not the absence of bugs; confining safety to one invariant keeps that case space small.
Validating the convergence bound. The one property depending on external bounds rather than the token/ETag invariant is passive convergence, so we treat those bounds as measured, declared, and monitored. Each service measures its cache-tier expiry and replication lag—it alone knows its cache topology—and declares their sum as the convergence delay; the store enforces the configured replication ceiling (5 minutes here). The orchestrator adds its buffer and monitors the declared delay against the actual pre-lock-to-hard-delete interval on every migration. Across the window this stayed within the declared bound plus buffer, with no stale-cache write to a source region detected.
5.5. Architectural Comparison
Table 3 compares routing-embedded locking with established approaches on the properties that motivated the design. The comparison is structural, not a benchmark.
Table 3.
Comparison with distributed lock approaches. A dedicated lock record can also be updated atomically; what differs is that our swap-and-release acts on the routing document already read on every request.
Table 3.
Comparison with distributed lock approaches. A dedicated lock record can also be updated atomically; what differs is that our swap-and-release acts on the routing document already read on every request.
| Property | Routing-Embedded (Ours) | Chubby[1] | ZooKeeper[2] | Redlock[13] | DynamoDB Lock[12] | Generic DB lease[14] |
|---|---|---|---|---|---|---|
| Additional infrastructure | None | Paxos cells | ZK ensemble | Redis instances | Dedicated table | Dedicated table |
| Lock-check latency | No extra read unless a lock is active; then one point read | Separate RPC | Separate RPC | Separate call | Separate read | Separate read |
| Atomic swap + unlock | Yes—in the routing document already on the read path | No | No | No | Only via a separate lock record | Only via a separate lock record |
| Fencing token | Yes (library-enforced) | Yes (sequencer) | Must build | Controversial[15] | Yes (record version) | Via version |
| Clock assumption | None (token/ETag) | None | None | Bounded skew[15] | None | Bounded (lease) |
5.6. Threats to Validity
All metrics are from a single messaging platform; generalization requires further study. The comparison in §5.3 is inferred from a measured proxy and the one in §5.5 is architectural; neither is a head-to-head benchmark, and no before/after comparison exists because no earlier lock service ran on this platform. Operational benefits—no separate service to deploy, monitor, or staff—are structural, and we do not quantify them against a counterfactual. The failure analysis rests on the environment’s continuous, uncontrolled fault load, telemetry, and testing (§5.4), not on controlled fault injection or formal verification. Finally, the shared routing library is a single point of correctness—a bug would propagate to every service at once—mitigated by its narrow API surface, compatibility testing, and staged rollout.
6. Discussion
6.1. Applicability Beyond Messaging
The routing-embedded locking pattern applies whenever three conditions hold:
- 1.
- Per-resource routing already exists: a per-entity routing record is resolved on every request; that record is the embedding point for lock metadata.
- 2.
- Lock granularity matches routing granularity: the entity that must be locked is the entity whose routing record is resolved; if locking needs a finer or coarser unit than the routing record, a separate mechanism may be necessary.
- 3.
- Atomic state transition is needed: cutover must change location and release locks together, which co-location makes atomic by construction.
These conditions arise beyond messaging—in content delivery (per-asset routing), multi-tenant SaaS (per-tenant shard routing), and e-commerce (per-merchant regional routing).
6.2. Infrastructure-Embedded Coordination as a Design Principle
Our experience suggests a broader principle: before building new coordination infrastructure, examine what already sits on your critical path—DNS, service-mesh routing, configuration lookups, tenant resolution, shard mapping. This aligns with Helland’s argument[16] that Internet-scale systems should coordinate at the entity level rather than through global mechanisms.
6.3. Where the Complexity Goes
Removing a separate lock service does not remove the complexity of locking; it relocates it into the routing library and store. The library now owns lock-state transitions, token validation, and the atomic swap, and must keep them correct for every service that links it. A routing anomaly and a locking anomaly can now share a root cause in one document. And the routing database inherits lock traffic it did not carry before (the read amplification in §8).
We accept this for three reasons specific to our setting. First, routing and locking already share an availability requirement, a consistency model, and an operational team, so co-locating them crosses no ownership or reliability boundary. Second, concentrating enforcement turns “every service must implement locking correctly” into “one audited component does”—fewer places for a correctness bug in a fleet of independently owned services. Third, the library’s API is narrow and its token/ETag invariant unchanged since launch. Coupling also does not prevent verifying the lock layer on its own: its API can be exercised directly, as the synthetic probes do (§5.4). Where routing and locking differ in consistency needs, owners, or lifecycles, a separate lock service remains the better choice.
6.4. Alternatives Considered
Two alternatives deserve mention. The first is piggybacking coordination on an explicit lock acquisition, a standard technique for eliminating round-trips. Our design applies the same idea one step earlier—to the routing read that every request already performs—so even operations that never acquire a lock observe lock state without a separate lock lookup. The second, delegating migration to the underlying store, is set aside in §2.6.
7. Related Work
Consensus-based lock services. Chubby[1] is a Paxos-based lock service built as general-purpose coordination infrastructure; ZooKeeper[2] provides locks via ephemeral znodes with session-based auto-release. Both are standalone services. Rather than adding one, we embed coordination metadata in infrastructure already on the request path.
Redis-based distributed locks. Sanfilippo[13] proposed Redlock across multiple Redis instances; Kleppmann[15] showed its correctness depends on timing assumptions violated by clock skew and pauses. Our lock token is validated against stored state on every mutation, and convergence depends on a configured TTL bound, not clock synchronization.
Fencing tokens. Kleppmann[10] recommends fencing tokens that downstream services must validate. Our lock token realizes this pattern, with the check embedded in the shared library rather than left to each caller (§3.3).
Leases and database-backed locks. Gray and Cheriton[14] introduced the lease, a time-bounded grant whose lapse costs performance, not correctness. Our lock expiry is a lease in this sense, and passive convergence is a lease-style argument applied to caches. The DynamoDB Lock Client[12] is the closest analog—database-backed, lease-based, with heartbeat renewal. What differs is where the lease lives. A conventional database lease or conditional-write lock keeps lock state in a dedicated record, so verifying it costs a separate read. Ours lives in the routing document every request already reads, so verification needs no extra read unless a lock is active, and cutover and release are one atomic write.
Live migration. Clark et al.[17] pioneered pre-copy live migration of virtual machines. Albatross[8] migrates live databases in shared-storage settings, and Nomad[7] migrates data across data centers using storage overlays. All operate within one storage system’s authority. Our problem is coordinating locks and cutover across independently owned services with heterogeneous storage, where no single system has that authority (§2.6).
Distributed mutual exclusion. Building on Lamport’s foundations,[18] our lock token provides mutual exclusion, lease expiry provides liveness, and the atomic swap rules out partial transitions.
Companion work. This paper is self-contained. Two companion articles under review treat the surrounding system: the four-phase lifecycle from the standpoint of perceived downtime[5] and the contract-based orchestration that invokes the lock and swap operations.[4] Neither is needed for this paper’s correctness or evaluation.
Data sovereignty. Opara-Martins et al.[19] survey data-residency challenges in cloud computing; our locking mechanism is one component of satisfying them through live migration.
8. Lessons Learned
Design lock durations for the failure case. Our initial design used a fixed 7–10 day pre-lock with no renewal. When a migration bug caused failures, resources were stuck behind locks for days with no way to retry—the safety mechanism became the problem. The current 48-hour leases with bounded renewal and a service-enforced maximum (§4) were the response, later joined by admin tooling with multi-level approval to force-release stuck locks. The lock duration that matters most is how long a failed migration blocks retries.
Extend existing infrastructure before building new infrastructure. The routing database and shared library already existed in every service. Extending their schema and API with lock operations gave us routing-path enforcement, atomic cutover, and uniform safety with no new infrastructure, dependencies, or on-call burden. The marginal cost was a schema change and a library update—in our experience far less than operating a dedicated lock service, although we have not measured that difference (§5.6).
Anticipate read amplification in shared databases. During large migrations, the orchestrator makes millions of API calls, each requiring a location document read from the database. These reads created partition hotspots, degrading performance for unrelated resources sharing the same physical database partition. We resolved this with an ETag-based optimization: because the lock guarantees the orchestrator is the sole writer, the service can safely use a cached document when the ETag matches—reducing routing-database reads during migration by approximately 90% without risking stale data.
9. Conclusion
The contribution is architectural rather than a new coordination primitive: routing infrastructure that already exists on every request path can carry lock metadata, so enforcement needs no separate service and, for requests to resources without an active lock, no additional lookup. Co-locating lock and location state yields routing-path enforcement, atomic cutover, and uniform safety across all participating services. In production, the write-lock phase—the only user-impacting window—holds at p99 under 20 seconds across 6–10 million daily migrations, with zero partial-cutover incidents in the observation window. The reduction in lock reads relative to a lock-service baseline is structural and inferred from a measured proxy, not benchmarked head-to-head.
The pattern applies wherever per-entity routing records are resolved on every request and migration needs locking at the same granularity. More broadly, existing request-path infrastructure is worth examining before building dedicated coordination services.
Acknowledgments
The authors used GitHub Copilot (powered by large language models) to assist with drafting and editing. All technical content, system design, production data, and architectural decisions originate from the authors’ engineering work; the authors reviewed and take full responsibility for all content. Aggregated, non-personally-identifiable production metrics are shared with organizational approval.
Conflicts of Interest
All authors are employees of Microsoft Corporation, which operates the production system described in this paper. The authors declare no other conflicts of interest.
References
- Burrows, M. The Chubby lock service for loosely-coupled distributed systems. Proc. 7th USENIX Symp. Operating Syst. Des. Implement. (OSDI), Seattle, WA, USA, Nov. 2006; pp. 335–350. [Google Scholar]
- Hunt, P.; Konar, M.; Junqueira, F. P.; Reed, B. ZooKeeper: Wait-free coordination for Internet-scale systems. Proc. USENIX Annu. Tech. Conf. (ATC), Boston, MA, USA, Jun. 2010; pp. 145–158. [Google Scholar]
- Microsoft. “Consistency levels in Azure Cosmos DB,” Microsoft Learn. Available online: https://learn.microsoft.com/azure/cosmos-db/consistency-levels (accessed on Oct. 8 2026).
- Roy, D.; Mulye, S.; Govindarajan, N.; Rajeevalochanam, J. “Moving live data across the continuum: Contract-based migration when no service knows the full graph,” submitted to IEEE Softw. 2026. Preprint, doi: 10.20944/preprints202610.0226.v1; Available online: https://www.preprints.org/manuscript/202610.0226.
- Roy, D.; Mulye, S.; Govindarajan, N.; Rajeevalochanam, J. “Live cross-region data migration without perceived downtime: A four-phase protocol for multi-service cloud systems,” submitted to IEEE Access. 2026. Preprint, doi: 10.20944/preprints202610.0828.v1; Available online: https://www.preprints.org/manuscript/202610.0828.
- Singh, S. “Powering real-time messaging at scale with Azure Cosmos DB,” Azure Cosmos DB Blog, 2025. Available online: https://devblogs.microsoft.com/cosmosdb/powering-real-time-messaging-at-scale-with-azure-cosmos-db/ (accessed on Oct. 8 2026).
- Tran, N.; Aguilera, M. K.; Balakrishnan, M. Online migration for geo-distributed storage systems. Proc. USENIX Annu. Tech. Conf. (ATC), Portland, OR, USA, Jun. 2011. [Google Scholar]
- Das, S.; Nishimura, S.; Agrawal, D.; El Abbadi, A. Albatross: Lightweight elasticity in shared storage databases for the cloud using live data migration. Proc. VLDB Endow. 2011, vol. 4(no. 8), 494–505. [Google Scholar]
- Microsoft. “Database transactions and optimistic concurrency control in Azure Cosmos DB,” Microsoft Learn. Available online: https://learn.microsoft.com/azure/cosmos-db/database-transactions-optimistic-concurrency (accessed on Oct. 8 2026).
- Kleppmann, M. Designing Data-Intensive Applications; O’Reilly: Sebastopol, CA, USA, 2017; Volume ch. 8. [Google Scholar]
- Vogels, W. Eventually consistent. Commun. ACM 2009, vol. 52(no. 1), 40–44. [Google Scholar] [CrossRef]
- Amazon Web Services, “Amazon DynamoDB lock client,” GitHub repository. Available online: https://github.com/awslabs/amazon-dynamodb-lock-client (accessed on Oct. 8 2026).
- Sanfilippo, S. “Distributed locks with Redis,” Redis Documentation. Available online: https://redis.io/docs/latest/manual/patterns/distributed-locks/ (accessed on Oct. 8 2026).
- Gray, C. G.; Cheriton, D. R. Leases: An efficient fault-tolerant mechanism for distributed file cache consistency. Proc. 12th ACM Symp. Operating Syst. Princ. (SOSP), Litchfield Park, AZ, USA, Dec. 1989; pp. 202–210. [Google Scholar]
- Kleppmann, M. “How to do distributed locking,” Feb. 8, 2016. Available online: https://martin.kleppmann.com/2016/02/08/how-to-do-distributed-locking.html (accessed on Oct. 8 2026).
- Helland, P. Life beyond distributed transactions: An apostate’s opinion. Proc. 3rd Biennial Conf. Innov. Data Syst. Res. (CIDR), Asilomar, CA, USA, Jan. 2007; pp. 132–141. [Google Scholar]
- Clark, C.; et al. Live migration of virtual machines. Proc. 2nd USENIX Symp. Netw. Syst. Des. Implement. (NSDI), Boston, MA, USA, May 2005; pp. 273–286. [Google Scholar]
- Lamport, L. Time, clocks, and the ordering of events in a distributed system. Commun. ACM 1978, vol. 21(no. 7), 558–565. [Google Scholar] [CrossRef]
- Opara-Martins, J.; Sahandi, R.; Tian, F. Critical analysis of vendor lock-in and its impact on cloud computing migration: A business perspective. J. Cloud Comput. 2016, vol. 5(no. 1), Art. no. 4. [Google Scholar] [CrossRef]
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (http://creativecommons.org/licenses/by/4.0/).
Copyright: This open access article is published under a Creative Commons CC BY 4.0 license, which permit the free download, distribution, and reuse, provided that the author and preprint are cited in any reuse.