

Submitted:
26 September 2026
Posted:
30 September 2026
You are already at the latest version
Abstract
This paper specifies the Planetary Health Axis System (PHAS), An active learning framework integrating data, large language models, and human experts for planetary health. The system is a pipeline of eight stages: (1) leakage-free preprocessing, mixture-of-experts imputation, and credibility-weighted data integration; (2) extraction of a dynamic, context-dependent knowledge prior from the scientific literature by a domain-tuned large language model; (3) nIDE non-invertible, asymmetric dimensionality expansion with median-kernel aggregation; (4) SCGL conditional structural graph learning on the lifted representation under a generalized-sparse, locally-dense, hub-mediated structure with acyclicity; (5) an active-learning, human-in-the-loop closure that converts learned structure into staged, verifiable queries; (6) non-discounted long-run-average optimal control subject to generalized planetary-boundary constraints, yielding KKT shadow prices and propagated top-level weights; (7) numerical solution by relative-value or policy iteration, with evaluation of the current state against the constrained optimum; and (8) full-system path/flux attribution together with unconditional and conditional distributional extrapolation. Together, the eight stages form a coupled estimation-and-control procedure that converts heterogeneous planetary-health evidence into verifiable structure and, ultimately, into boundary-respecting, decision-facing policies.
Keywords:
planetary health
; active learning
; structural graph learning
; large language models
; constrained optimal control
1. Introduction
Human civilization is now operating measurably outside the environmental conditions under which it developed. The planetary-boundaries framework identified nine interacting Earth-system processes whose transgression risks abrupt, potentially irreversible change at planetary scale [1,2]; the most recent assessment concludes that six of the nine boundaries have already been crossed, with interactions among boundaries amplifying the overall risk beyond the sum of the individual transgressions [3,4]. In parallel, the Rockefeller Foundation–Lancet Commission institutionalized planetary health as a transdisciplinary field concerned with the health of human civilization and the state of the natural systems on which it depends [5], extending the health-centric One Health perspective toward the political, economic, and technological systems that mediate ecological outcomes [6]. Subsequent work has embedded justice considerations into Earth-system boundaries [7] and documented that, at present, no country meets the basic social thresholds for its citizens without exceeding biophysical boundaries [8]. The human-development measurement tradition has likewise converged on the same diagnosis: the Human Development Report 2020 frames the Anthropocene as the next frontier of human development [9]. The problem this appendix addresses is therefore not the absence of warning or of indicators, but the absence of an analytical architecture capable of turning the accumulated evidence into coherent, forward-looking, decision-grade structure.
Three limitations of the existing analytical toolkit motivate the construction. First, the dominant measurement frameworks are retrospective: they report where the system has been, not where current decisions drive it. Second, the frameworks that do look forward—notably integrated assessment models and the sustainable-development-pathway literature—have made substantial progress in quantifying climate–development synergies and trade-offs [10,11], and recent modelling studies have begun to project planetary-boundary transgression under concrete mitigation scenarios [12]; yet in these frameworks the boundaries typically enter as scenario diagnostics or aspirational targets rather than as constraints embedded in the operating logic of the decision problem itself. Third, the standard economic machinery of intertemporal evaluation discounts the future at rates that render catastrophes a century away nearly negligible in present value—a practice long recognized as indefensible for existential and intergenerational stakes [13]. A framework adequate to planetary health must therefore be (i) forward-looking and control-theoretic rather than purely descriptive, (ii) able to treat planetary boundaries as dynamic, risk-graded constraints inside the optimization, and (iii) intergenerationally neutral in its objective.
What has changed is the computational substrate. Artificial-intelligence methods have matured to the point of materially altering what is feasible in scientific modelling [14]: machine learning is being applied across climate mitigation and adaptation domains [15], deep learning has begun to fuse with process understanding in Earth-system science [16], and large language models built on the transformer architecture [17,18] can now extract and organize knowledge from scientific corpora at a scale no manual review could match. At the same time, the governance literature is unambiguous that such systems must operate under human oversight, with reinforcement learning from human feedback providing one concrete alignment mechanism [19] and with commission-level analyses calling for dedicated governance of AI in health [20]; open-science principles such as FAIR data stewardship supply the complementary norms of transparency and reproducibility [21]. A companion commentary articulates the scientific and governance case for AI-enabled planetary-health assessment in these terms [22]. The present document supplies the mathematical specification of one such system.
Realizing this program requires integrating several methodological literatures that have so far developed largely in isolation. Global country–year indicator panels are incomplete, heterogeneous, and of uneven quality, so the data layer draws on the statistical theory of missing data [23] and on mixture-of-experts architectures, in which gated combinations of specialized models outperform any single imputer [24]. Turning a harmonized panel into directed structure engages the theory of causal graphical models [25,26] and, at the scale required here, continuous formulations of structure learning in which acyclicity is enforced by a smooth algebraic penalty rather than combinatorial search [27], combined with group-structured sparsity penalties that respect the block organization of real systems [28] and with kernel-based representations that give nonlinear mechanisms linear coordinates [29]. Closing the loop between automated discovery and human knowledge is the province of active learning, in which the algorithm—not the annotator—selects which queries are most informative [30]. The decision layer rests on the theory of Markov decision processes under the long-run average criterion [31] and on constrained Markov decision processes, which supply exactly the formalism in which planetary boundaries become feasibility restrictions on policies [32], solved by the value- and policy-iteration machinery of modern reinforcement learning [33]. Constraint economics enters through the Karush–Kuhn–Tucker conditions, whose multipliers admit the shadow-price reading used throughout [34], and boundary risk is measured with functionals in the spirit of coherent and convex risk measures [35].
This appendix specifies the Planetary Health Axis System (PHAS), an eight-stage pipeline that assembles these components into one coupled estimation and control procedure: leakage-free preprocessing with credibility-weighted mixture-of-experts imputation (Section 3); a domain-tuned large language model that converts the literature corpus into a dynamic, context-dependent probabilistic prior (Section 4); non-invertible, asymmetric dimensionality expansion with median-kernel aggregation (Section 5); conditional structural graph learning under generalized-sparse, locally-dense, hub-mediated structure with acyclicity (Section 6); an active-learning, human-in-the-loop closure converging to a tripartite data–literature–expert consensus knowledge set (Section 7); non-discounted long-run-average optimal control under generalized planetary-boundary gauge constraints, yielding KKT shadow prices and propagated top-level weights (Section 8); certified numerical solution and evaluation of the current state against the constrained optimum (Section 9); and full-system path/flux attribution with unconditional and conditional distributional extrapolation (Section 10). Throughout, identified structure is reported as quasi-causal: the machinery supports directed, lag-consistent structural associations, while a causal reading is licensed only under the additional assumptions collected in Section A. Section 2 fixes terminology and global objects and presents the master pipeline; Section 3, Section 4, Section 5, Section 6, Section 7, Section 8, Section 9 and Section 10 specify the eight steps, each with its own notation, mathematical formulation, algorithmic role, and interface; the appendix concludes with a consolidated assumption list and a symbol table.
2. Overview and Master Pipeline
2.1. Terminology and Scope
The following terminology is fixed once and used uniformly throughout the appendix.
- (T1)
- System name. PHAS denotes the Planetary Health Axis System, the integrated-modeling and stochastic-control system specified here.
- (T2)
- Lifting layer. The dimensionality-expansion layer is written nIDE (non-invertible/asymmetric dimensionality expansion; Definition 9).
- (T3)
- Graph-learning layer. The graph-learning layer is written SCGL (structural causal graph learning; Section 6).
- (T4)
- Causal language. All identification outputs are described as quasi-causal or as structural associations. Neither the nIDE lifting nor the LLM prior, alone or jointly, guarantees physical causation; a causal reading is licensed only under the explicit additional assumptions stated in Section 6 and collected in Section A.
2.2. Global Objects
The following objects are used across all eight steps and are fixed here once.
Definition 1
(Index sets and panel object). Let be the set of countries or macro-regions, the set of annual time indices, and the set of original indicator indices. The raw country–year panel is the pair with
where is the observation mask. A conditioning context aggregates country, regime, scenario, and exogenous covariate information available at time t. The literature corpus is .
Definition 2
(State, action, and policy). The aggregate planetary-health state at time t is , containing wealth, health, technology/knowledge, renewable and nonrenewable resource, and planetary-health coordinates together with the context . The action (control) at time t is , constrained to an admissible set . A (stationary) policy is a measurable map with ; Π denotes the class of admissible policies. The controlled transition kernel is , and denotes expectation under the law induced by π from .
2.3. Master Algorithm
Master pipeline (PHAS). Inputs: the raw panel , the corpus , an expert pool, an admissible policy class , a scenario generator, and validation partitions. Outputs: coherent indicators, dynamic priors, the median-kernel representation, the conditional structural graph, the controlled simulator, the optimal policy and gain, top-level and propagated weights, distance and boundary-risk metrics, jointly normalized path–flux tables, and forecast distributions.
- Stage 1.
- Preprocessing and integration (Step 1). Build ; harmonize and normalize without future leakage, ; generate Bundle-T imputations by a mixture-of-experts gate; iterate the credibility-weighted impute–model–verify–reimpute loop to convergence. Output: completed panel , credibility weights q.
- Stage 2.
- Domain-tuned quasi-LLM prior (Step 2). Extract directional, lagged, contextual claims from ; form the prior edge/lag probabilities , the prior graph score , and the reverse-query operator ; maintain the dynamic prior recursion .
- Stage 3.
- nIDE lifting (Step 3). Apply the non-invertible, asymmetric lifting ; aggregate feature views into median kernels and the lifted representation .
- Stage 4.
- SCGL graph identification (Step 4). Learn the conditional directed graph on the lifted representation under generalized-sparse/locally-dense structure with acyclicity and prior regularization.
- Stage 5.
- Active-learning closure (Step 5). Run the staged query progression (data → model/ adversarial → human expert) with acquisition functional and binary Bayesian posterior updates; converge to the tripartite knowledge set ; re-inject accepted hypotheses as anchors.
- Stage 6.
- Non-discounted optimal control (Step 6). Estimate the controlled transition kernel on the lifted representation and solve the constrained long-run-average problem with over the feasible policy class induced by the generalized planetary-boundary constraints; derive KKT shadow prices and top-level weights.
- Stage 7.
- Numerical implementation and evaluation (Step 7). Compute by relative value iteration or fitted policy iteration with constraint handling and convergence diagnostics; evaluate the utility gap , the weighted state distance , boundary-risk distances , the first-passage time , and the bounded reporting score.
- Stage 8.
- Path/flux outputs and extrapolation (Step 8). Enumerate the full path set in the time-unrolled conditional graph; compute jointly normalized fluxes ; generate unconditional and conditional (policy-, scenario-, and future-value-conditioned) distributional extrapolations with dynamically updated priors; report policy-portfolio output distributions.
Validation (simulated missingness, blocked time/country tests, graph and path recovery, calibration, boundary behavior, and expert ablation) accompanies all stages and is stated in Section 3, Section 7, and Section 9.
Inputs, Intermediate Objects, and Outputs
The input list of the master pipeline separates three kinds of ingredients. The raw panel and the literature corpus are the empirical ingredients: the former carries the observed country–year indicator values together with the observation mask, and the latter carries the accumulated textual knowledge that the quasi-LLM of Step 2 converts into probabilistic structure. The expert pool, the admissible policy class , and the scenario generator are the structural ingredients: they delimit who may be queried in the active-learning closure, which controls are implementable, and which exogenous futures the system is evaluated against. The validation partitions are the epistemic ingredient: they fix which part of the panel fits parameters and which parts are reserved for verification, making the leakage-free discipline of Step 1 operational. The intermediate objects are exactly those passed along the arrows of the interface map: the completed panel and the credibility weights q, the prior field together with the reverse-query operator , the median-kernel representation , the conditional structural graph , and the consensus knowledge set . Each intermediate object is at once an output of its producing step and an input of every later step that consumes it, and the producing step always precedes the consuming step in the linear order of the pipeline.
Convergence Loops and Downstream Dependencies
Two convergence loops are the only points at which the otherwise linear pipeline revisits earlier computations. The first is the credibility-weighted impute–model–verify–reimpute loop of Step 1, which iterates model training, held-out verification, and credibility updating until the stopping tolerances of Definition 5 hold. The second is the active-learning closure of Step 5, which iterates hypothesis acquisition, staged verification, and anchor re-injection until the joint state of graph, credibility weights, and knowledge set stabilizes under the composite tolerance . The downstream dependencies are explicit: the credibility weights q produced by Step 1 enter the data-fit term of the SCGL objective in Step 4; the prior field produced by Step 2 is lifted to kernel level in Step 3 and enters the prior regularization of Step 4; the graph supplies the transition structure estimated in Step 6, the hypotheses verified in Step 5, and the time-unrolled graph traversed in Step 8; and the feedback of Step 5 together with the validation outcomes of Step 7 re-enter the dynamic prior recursion of Step 2, so the prior consumed by later passes reflects everything the system has already verified. The eight steps thus form one coupled estimation and control procedure rather than a sequence of independent modules.
| Algorithm 1: Full-system PHAS algorithm (master pipeline, Steps 1–8) |
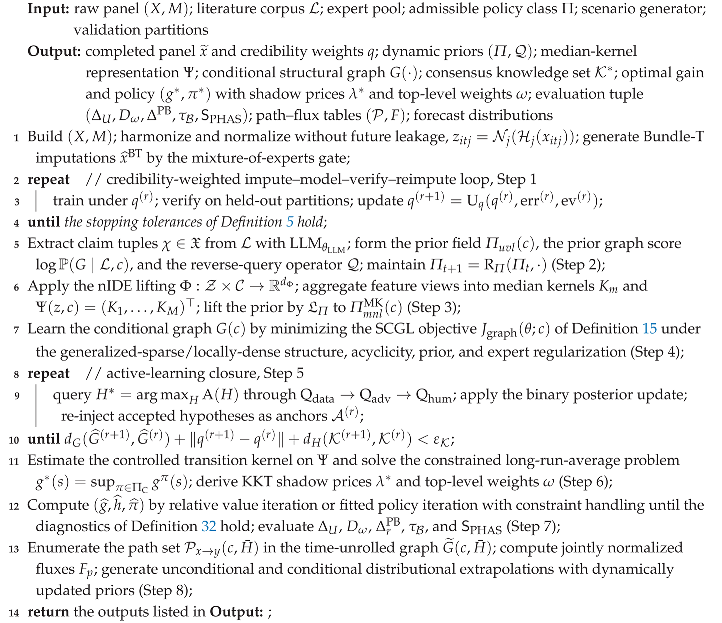 |
Remark 1
(Interface map). The data flow of the master pipeline is
Each step below states its own domain/codomain precisely in its Interface subsection.
3. Step 1: Input Preprocessing and Iterative Data Integration
Overview of the Preprocessing Pipeline
Step 1 is the entry point of the master pipeline and has a single responsibility: to turn the raw panel and the corpus into a harmonized, completed, and quality-annotated evidence object that every later step can consume without further data curation. Four constructions follow in a fixed order. First, harmonization and normalization (Definition 3) place all indicators on comparable footing under a strict no-future-leakage discipline. Second, the Bundle-T mixture-of-experts imputer (Definition 4) fills the entries flagged as missing by the observation mask, using a gated convex combination of four complementary experts. Third, the credibility-weighted iterative loop (Definition 5) couples imputation quality to model quality: training, held-out verification, and credibility updating are repeated until three stopping tolerances hold at once. Fourth, the full-input retention principle (Definition 6 and Proposition 1) fixes what the step does not do: it performs no a-priori variable selection, deferring all filtering to the learned structure.
3.1. Notation
Within this section: is a raw indicator value; its observation indicator (Definition 1); a per-indicator harmonization map; a per-indicator normalization map; the harmonized indicator; the index set of imputation experts (local time-series, local factor, global spline, clustered global factor); the gate weight of expert ; the expert-e imputation; the completed panel; the credibility weight; a generic model parameter vector; a per-indicator loss; the outer iteration counter of the credibility loop; the held-out error profile; the validation evidence profile; the credibility update map; stopping tolerances.
3.2. Mathematical Formulation
Definition 3
(Leakage-free harmonization and normalization). The harmonized indicator is
where resolves units, definitions, and cross-dataset definitional discrepancies for indicator j, and is a monotone normalization whose parameters are fit only on the training partition of ; all validation and test partitions are transformed with frozen parameters (no future leakage).
Definition 4
(Bundle-T mixture-of-experts imputer). For each missing entry ( with ), the Bundle-T prediction is the gated convex combination
where the gate γ is selected by folding cross-validation, and the completed panel is
Both the completed panel and the observed-only subpanel are retained for downstream use.
Definition 5
(Credibility-weighted iterative loop). Given credibility weights , model training at outer iteration r minimizes the weighted loss
followed by the credibility update
where is the per-entry held-out error profile and the verification evidence (simulated-missingness recovery, blocked time/country tests). The map is required to be monotone decreasing in held-out error: entries whose predictions verify well do not lose credibility. The loop stops at the first r for which
with graph distance as defined in Section 6; all tolerances are positive. Credibility is therefore a convergence product of the loop, not an a-priori input.
Definition 6
(Full-input retention and model-selected filtering). Let denote the union of all obtainable country–year series and ontology entities. The integration map retains the full evidence object,
i.e. no a-priori variable selection is performed at integration time. For a query specification (target variables, precision requirement), the problem-conditioned projection
extracts a local sub-network around the query variables. Writing for the complementary mechanisms, the map also returns a mixture-factor reduction , so that the query-facing representation is the ordered pair .
Proposition 1
(Full-input, then model-selected filtering). Under Definition 6, (i) integration completeness holds: ; and (ii) selection is deferred to the learned structure: every query induces an explicit sub-network and a residual representation of . Hence no information available at integration time is discarded before the model itself performs selection.
3.3. Algorithmic Role
Step 1 converts heterogeneous public statistical data and literature-derived knowledge into a single harmonized, completeness-audited panel with data-driven credibility weights. Imputation is performed by a mixture of complementary experts whose gate is selected by cross-validation; the credibility loop couples data quality to model quality so that weakly defined observations are down-weighted only insofar as they fail verification, in line with the design principle that selection is the model’s task, not the curator’s.
3.4. Interface
Inputs: raw panel over ; corpus (shared with Step 2); validation partitions. Outputs: harmonized panel ; completed panel ; credibility weights q; the retained full evidence object passed unfiltered to Steps 2–4; query projections used by Steps 4, 6, and 8.
Validation Logic and Downstream Interface
The validation logic of Step 1 is distributed across the constructions rather than collected in a single test. The normalization discipline guarantees that evaluation partitions are never contaminated by fitting; the gate of the Bundle-T imputer is selected by folding cross-validation, so the imputation machinery is itself validated; the credibility loop verifies every entry against held-out error, simulated-missingness recovery, and blocked time/country tests; and the stopping rule requires stability not only of the loss and the predictions but also of the identified graph, so the data layer is declared converged only when its downstream structural consequences have stabilized. The interface statement enumerates what later steps may assume: Steps 2 through 4 receive the full evidence object unfiltered, with the corpus shared with Step 2; Step 3 receives the harmonized and completed panels together with the credibility weights; Step 4 consumes the weights inside its data-fit term; and the query projections serve Steps 4, 6, and 8 whenever a query-facing local representation is required. Nothing beyond these listed objects crosses the boundary of the step.
4. Step 2: Domain-Tuned LLM as a Dynamic Knowledge Prior
Overview of the Quasi-LLM Prior Step
Step 2 supplies the pipeline with its second stream of evidence: accumulated scientific knowledge, extracted from the literature corpus and rendered as probabilistic structure rather than as fixed assertions. Definition 7 constructs the static objects: the extraction map realized by the domain-tuned quasi-LLM, the claim set , the prior edge probabilities , the prior graph score , and the association skeleton . Definition 8 constructs the dynamic objects: the recursion that keeps the prior current as data, feedback, and validation outcomes accumulate, and the reverse-query operator that translates model findings back into verifiable statements. The guiding idea is that the quasi-LLM is treated as an instrument whose readings are calibrated, aggregated, and subsequently verified, never as an authority whose output enters the graph directly. Every object produced here is consumed elsewhere: the prior field and skeleton feed the prior regularization of Step 4 through the prior-lifting map of Step 3, and the reverse queries feed the staged verification of Step 5.
4.1. Notation
Within this section: is the literature corpus; a claim tuple is , where are variables, a direction/sign, a lag, a context, e evidence metadata, and a calibrated confidence; is the set of extracted claims; a directed graph; the indicator that edge acts at lag l; the prior edge probability; the claim-confidence aggregation functional; the skeleton threshold; the quasi-LLM parameter vector; the data evidence; the dynamic-prior update map; the feedback available after round t (expert responses and validation outcomes); the reverse-query operator; a hypothesis set (formalized in Step 5).
4.2. Mathematical Formulation
Definition 7
(Claim extraction and prior graph score). The domain-tuned quasi-LLM (a “quasi large language model”, i.e. an LLM with domain-specific modification) realizes a measurable extraction map
with parameter vector . The joint graph score is
and the prior factorizes over edges and lags as
where the prior edge probability is aggregated from the confidences of the consistent claims by an aggregation functional,
and the factorized form additionally assumes that the edge–lag indicators are conditionally independent given . The prior supplies three objects: the association skeleton, defined with a threshold ,
the time-asynchrony structure (lag prior), and the reverse-query interface below.
Definition 8
(Dynamic prior recursion and reverse query). The prior is a stochastic process on contexts, updated by
where is the new data evidence and aggregates expert feedback (Step 5) and validation outcomes (Step 7). The reverse-query operator maps model findings back to verifiable statements,
where contains hypotheses about edges, lags, context-dependent relations, paths, flux rankings, functional forms, or boundary mechanisms. This closes a cyclic verification loop: extracted priors constrain learning (Step 4), learned structure generates queries, and query answers re-enter .
4.3. Algorithmic Role
Step 2’s domain-tuned quasi-LLM injects accumulated scientific knowledge into the pipeline as a probabilistic, context-dependent, and dynamically updated prior rather than as fixed structure. Its comparative advantage is short-range concrete and ultra-long-range abstract relations; its known weakness (hallucination) is controlled downstream by the credibility loop of Step 1, the data fit of Step 4, and the adversarial/expert queries of Step 5.
Interface and Consumption of the Prior Objects
The prior objects enter the rest of the pipeline as follows. To Step 3, the step promises the variable-level prior objects that the prior-lifting map transports to median-kernel level as the kernel-level prior field and the lifted skeleton . To Step 4, the step promises the prior regularization term , through which the prior enters the SCGL objective as one additive penalty among several, weighted by a coefficient and therefore unable to override the data fit by construction. To Step 5, the step promises the reverse queries , which populate the candidate-hypothesis pool that the acquisition functional ranks. In return, the step receives anchors and expert feedback from Step 5 and validation outcomes from Step 7, which enter the recursion and keep the prior synchronized with everything the system has verified. The quasi-LLM prior is thus neither a fixed constraint nor a one-time initialization but a maintained, context-conditioned, dynamically updated probabilistic summary of accumulated knowledge, embedded in and subordinate to the empirical and human verification machinery of the remaining steps.
4.4. Interface
Inputs: corpus ; indicator dictionary and harmonized panel from Step 1; anchors and expert feedback from Step 5; validation outcomes from Step 7. Outputs: claim set ; skeleton ; prior field and its recursion ; reverse queries feeding Step 5; the variable-level prior objects that the prior-lifting map of Definition 12 transports to median-kernel level, where they enter the prior regularization term used by Step 4.
5. Step 3: nIDE Lifting and Median Kernels
Purpose and position of the lifting layer.
Step 3 is the representational hinge of the Planetary Health Axis System (PHAS). Steps 1 and 2 deliver a harmonized, completeness-audited panel and a probabilistic, context-dependent structural prior; Step 4 will learn directed conditional structure; and Steps 6–8 will control and attribute along that structure. None of these operations is stated on the raw indicators, because the mechanisms PHAS must represent—lagged responses, asymmetric rises and declines, threshold crossings, context dependence, and directed source–target transformations—do not share coordinates in the original indicator space. Compressing the panel into a small number of latent scores would force heterogeneous mechanisms onto common axes, where a downstream linear operator could no longer separate them. The nIDE layer takes the opposite route: it expands the harmonized state into the high-dimensional tuple , giving each candidate mechanism its own coordinate, and then aggregates the resulting views into the median-kernel representation on which all subsequent structure learning runs.
The harmonized panel , the completed panel , and the credibility weights q from Step 1 are first assembled, together with the skeleton and lag sets from Step 2, which restrict the candidate view sets. The dictionary views are then evaluated pointwise over panel rows and contexts, the views are grouped into view sets and aggregated into kernels , the attribute sets are recorded, and only then is the prior lifted to kernel level. What is passed to Step 4 is not a bare feature matrix but the tuple of representation, kernel naming, attribute sets, and lifted prior field, each component consumed by a different term of the graph objective. The attached checks are structural rather than numerical: every view set must be nonempty, the first-pass dictionary must contain no block summaries, and the attribute map must cover every kernel the prior is expected to inform.
5.1. Notation
Within this section: is the harmonized indicator space (a point collects ); the lifting dimension; the r-th lifted feature view, ; the lifted trajectory; the view set of median kernel m; the number of median kernels; the view-set feature vector of kernel m (a vector, not a scalar); the attribute set of original indicators generating kernel m; the prior-lifting map; the kernel-level prior edge probability.
5.2. Mathematical Formulation
Definition 9
(nIDE lifting). The nIDE (non-invertible/asymmetric dimensionality expansion) layer is a map
satisfying two structural properties:
- (nIDE1)
- Asymmetry (directedness). For ordered variable pairs , the directed source–target transforms obey in general, so that directional information survives lifting.
- (nIDE2)
- Non-invertibility. There is no map with for all : distinct original states may share one lifted representation. Formally, the fiber is non-singleton in general.
Asymmetry, Non-Invertibility, and Fibers
The two properties of Definition 9 are the design content of nIDE, and each answers a specific failure of conventional feature construction. Asymmetry, property (nIDE1), requires the directed source–target transforms to differ across orientations: and are different functions in general. Without this property, any directional statement made downstream would be manufactured by regularization rather than supported by representation: Step 4 orients edges, Step 8 orients paths, and both inherit direction from the lifting. With (nIDE1) in force, the lifted coordinates already encode which variable plays the source role and which the target role, so orientation is a property of the data representation rather than of the penalty structure. A directed transform whose two orientations coincide throughout the panel is a candidate mislabeled view, and systematic coincidence would strip the downstream graph of representational support for direction.
Non-invertibility, property (nIDE2), states that the fiber is non-singleton in general: distinct original state–context pairs may share one lifted representation. This collapse is deliberate. The many-to-one character of is precisely what makes the lifted object insensitive to fine distinctions that the dictionary does not encode, and it is the representational basis of the robustness that median aggregation later reinforces. The cost is that no inverse exists: the original state cannot be recovered from , and every interpretation of lifted objects is routed through the attribute sets rather than through inversion. Non-invertibility also delimits what Step 3 can claim: collapsing states into shared representations is aggregation, not identification; it neither creates nor destroys causal content, consistently with the quasi-causal qualification of Remark 3. Treating a non-singleton fiber as if its members were the same underlying configuration would conflate representational equivalence with physical equivalence.
Definition 10
(Feature dictionary). The following standard dictionary instantiates : lagged levels and differences for ; asymmetric rise/decline transforms and ; polynomial and interaction terms of bounded degree; context interactions ; threshold and tail indicators with thresholds ; and directed source–target transformations . Block summaries are deliberately excluded from this first-pass dictionary to avoid a circular dependence on the SCGL block partition of Section 6; the construction is explicitly two-stage: (i) SCGL is run on the first-pass dictionary and returns a provisional partition ; (ii) a single optional second lifting pass augments the dictionary with block summaries over and SCGL is re-run once on the augmented representation. No iterated co-estimation of dictionary and partition is used, so the interface is acyclic.
Dictionary Design and the Two-Stage Construction
Each family of the first-pass dictionary in Definition 10 supplies one representational capability used downstream. Lagged levels and differences encode temporal dependence at exactly the lags that the Step 2 lag prior marks as plausible; the asymmetric rise and decline transforms and give concrete content to property (nIDE1) by treating increases and decreases as distinct mechanisms; polynomial and interaction terms of bounded degree supply the denseness hypothesis of Proposition 2; context interactions make the lifted representation context-dependent, which is what the conditioning map of Step 4 ultimately consumes; threshold and tail indicators expose crossings of the levels , the same type of event that the boundary evaluation of Step 7 formalizes; and the directed source–target transformations carry orientation.
Block summaries are excluded from the first pass for a structural reason: a block summary is defined relative to a block partition, while the block partition is an output of Step 4, which consumes the dictionary. Putting block summaries into the first-pass dictionary would make the dictionary depend on its own downstream product. The two-stage construction resolves this circularity by sequencing rather than by co-estimation. In the first stage, SCGL is run on the first-pass dictionary and returns the provisional partition ; in the second, optional stage, the dictionary is augmented once with block summaries computed over that provisional partition, and SCGL is re-run once on the augmented representation. The first-pass representation is therefore computed completely before any block summary exists, passed to Step 4, which returns the provisional partition; only then is the single augmentation pass decided. The augmentation is applied at most once, and no iterated alternation between dictionary and partition is used, which avoids partition drift under repeated re-augmentation in which dictionary and partition chase each other; the acyclic interface keeps the provisional and final partitions separately interpretable.
Definition 11
(Median kernels and the lifted representation). Each median kernel carries one aspect of an indicator’s nonlinear complexity. For each , the median kernel is the coordinate-wise median of its view-set feature vector,
Coherent indicators generate the median kernels through an attribute flow; this is formalized as the attribute map together with the aggregation , without asserting any architecture. Each kernel is named by the pattern (PHAS level ℓ, identifier j). If a positive-semidefinite kernel is separately verified on a view set, one may additionally define
absent such verification, is used strictly as a robust lifted feature (cf. Section A).
Median Kernels as Robust Aggregates; The Attribute Sets
Each median kernel carries one aspect of an indicator’s nonlinear complexity; the coordinate-wise median of Definition 11 is one instantiation of that role. Two features of the construction deserve emphasis. First, the object being aggregated is the view-set feature vector , a vector indexed by the view set , not a scalar: kernel m summarizes a whole family of views of one aspect, and the coordinate-wise median is the point at which disagreement among those views is absorbed. Because the median is insensitive to any single coordinate, no individual transform—a particular lag choice, a particular threshold, a particular orientation—can dominate the kernel; this is the precise sense in which median aggregation provides robustness to any single transform. Second, the aggregation is anchored to the original indicators through the attribute flow, recorded as the attribute map . The attribute sets are not auxiliary metadata: they are the transport vehicle of the prior lifting of Definition 12 and the interpretive substitute for the inversion that non-invertibility rules out. Kernels are named by the pattern by level and identifier slots.
The optional inner-product construction is conditioned on separate verification of positive semidefiniteness on the view set; absent that verification, is used strictly as a robust lifted feature and no kernel geometry is invoked. To form , one computes for each view set and aggregates coordinate-wise. Within-view-set dispersion is the diagnostic: transient disagreement among views is exactly what the median absorbs, systematic disagreement exposes a dictionary assigning unlike mechanisms to one aspect, and a singleton view set forfeits the aggregation rationale and is a plain feature rather than a robust aggregate.
Definition 12
(Prior lifting from variables to median kernels). The LLM prior of Step 2 is stated at the level of original variables, while SCGL (Step 4) learns the graph at the level of median kernels. The prior-lifting map connects the two levels: using the attribute-flow sets , variable-level claims and edges are transported to kernel-level objects by
with the same aggregation functional as in Definition 7, and the lifted skeleton is
with the same threshold . The kernel-level prior field and skeleton are the objects consumed by the prior regularizer of Step 4; claims whose attribute map assigns them to no view set are retained at variable level and do not enter the kernel-level prior.
Transporting the Prior from Variables to Kernels
Definition 12 resolves a level mismatch that is easy to overlook. The Step 2 prior is stated over original variables, because claims in the corpus are phrased over original indicators; SCGL, however, learns the graph over median kernels. The prior-lifting map connects the two levels using exactly one structural object already available: the attribute sets . A claim tuple contributes to the kernel-level entry precisely when its source variable is attributed to kernel m and its target variable to kernel n at lag l, and the confidences of all such claims are combined by the same aggregation functional used at variable level, under the same skeleton threshold . Reusing the same functional and threshold keeps the lifted field comparable in kind to the variable-level field: no new aggregation logic is introduced, and is the kernel-level image of the same topological-prior idea.
Claims whose attribute map assigns them to no view set are retained at variable level and do not enter the kernel-level prior; the lifting is a transport of whatever the attribute sets reach, not a completion of what they miss. One fixes the attribute map first, then evaluates over kernel pairs and lags, then thresholds to form the skeleton, and passes both objects to the prior regularizer of Step 4. The natural diagnostic is coverage: kernel pairs that are richly populated with attributed variables but carry an empty lifted prior expose gaps in claim coverage or in attribute assignment, while a lifted skeleton that is nearly complete erodes the selectivity that the prior regularizer is supposed to exercise. In both directions the outcome is the same: the regularizer stops discriminating, either because it has nothing to say or because it says everything at once.
Proposition 2
(Universal lifting). Suppose the feature algebra generated by is dense in for compact (Stone–Weierstrass-type denseness of polynomial bases). Then for every continuous target and every tolerance there exist a finite feature subset and coefficients w such that
Consequently any continuous nonlinear transition map admits an arbitrarily accurate linear representation on the lifted space: nonlinear complexity is converted into high-dimensional linear complexity.
What the universal-lifting statement licenses.
Proposition 2 is a license, not a procedure. Its hypothesis—denseness of the feature algebra generated by in the continuous functions on a compact , a Stone–Weierstrass-type property supported by the polynomial family of the dictionary—yields uniform approximation of any continuous target f by a linear readout with coefficients w. The design content is the conversion stated in the accompanying remark: nonlinear complexity in the original variables becomes high-dimensional linear complexity in the lifted variables. This is what allows Step 4 to state the conditional dynamics with coefficient matrices acting linearly on , and Step 7 to fit the value representation , without in-principle loss of expressiveness: whatever continuous mechanism exists in the original state can be represented by linear operators on the lifted coordinates, with expressiveness carried by the lifting rather than by the downstream model class.
Three things the proposition does not assert deserve equal emphasis. It is an existence statement: the coefficient vector w is guaranteed but is not computed anywhere in Step 3, and no algorithm for finding it is specified. It carries no rate: nothing is said about how large a feature subset a given tolerance demands, and no bound on is asserted. It is also silent on identification and causation: approximability by a linear readout says nothing about whether learned coefficients reflect structural mechanisms, which is why the quasi-causal qualification of Remark 3 remains necessary after lifting. The hypothesis would fail under expressive starvation—a dictionary too poor to represent the mechanisms of interest in linearly separable coordinates; the denseness hypothesis rests on the polynomial and interaction family, so removing that family would vacate the license.
Remark 2
(Nonlinear-to-linear lifting). Proposition 2 formalizes the design statement that nIDE turns “nonlinear complexity” into “high-dimensional linear complexity”: downstream Steps 4 and 6 operate on Ψ with linear operators, while expressiveness is carried by the lifting. The accompanying motivation—that a describable world is necessarily “generalized sparse, locally dense”—is formalized as a learnability structure in Step 4 (Definition 14), not assumed here.
5.3. Algorithmic Role
Step 3 produces the representation on which all subsequent structure learning and control estimation runs. Median aggregation across asymmetric views provides robustness to any single transform; non-invertibility is retained by design and is not claimed to identify causation (Remark 3, Step 4).
5.4. Interface
Inputs: harmonized/completed panel , and credibility weights q from Step 1; prior skeleton and lag sets from Step 2 (used to restrict candidate view sets). Outputs: the lifted representation and trajectories ; the kernel index set with naming pattern ; the attribute sets ; the lifted kernel-level prior field and skeleton ; feature metadata required by the graph prior of Step 4.
6. Step 4: SCGL Conditional Structural Graph Identification
Operating Logic of the Graph-Identification Step
Step 4 is the point at which the lifted representation becomes structure. Its inputs are the lifted trajectories from Step 3, the lifted kernel-level prior field and skeleton transported by , the credibility weights q from Step 1, and—on later outer iterations—the anchors accepted in Step 5. Its output is the conditional directed graph , stored as the adjacency and coefficient structure together with the block partition and the hub set . Three downstream consumers draw on this single object: Step 5 receives candidate hypotheses for staged verification, Step 6 receives the transition structure on which the controlled kernel is estimated, and Step 8 receives the time-unrolled graph on which paths and fluxes are computed. This triple consumption is why the section describes Step 4 as the system’s gross engine: every decision-facing quantity in PHAS passes through the identified graph.
The lifted trajectories and their contexts are organized as the regression structure of Definition 13; candidate edges are then restricted by the skeleton and the lag set, so that the prior enters as a restriction of the search space before it enters as a penalty; the objective of Definition 15 is minimized under the credibility weights; the block partition and hub set are extracted from the solution; and only then is identification quality assessed through the graph distance of Definition 16. What is checked at the end of the pass is not only fit but structure: the contemporaneous matrix must admit a topological order, cross-block factor ranks must remain small relative to block sizes, and cross-block edges must be hub-mediated, each check corresponding to one clause of the formulation.
6.1. Notation
Within this section: is the node set of median kernels; the lag set; the conditional directed graph at context c; the lag-l coefficient matrix, with contemporaneous matrix ; an innovation; a partition of into blocks; the proxy/hub set; a low-rank cross-block factorization; the graph parameter collection; regularization coefficients; the adjacency indicator of under c; .
6.2. Mathematical Formulation
Definition 13
(Conditional lifted dynamics). The canonical lifted dynamic model is
where the contemporaneous matrix satisfies the acyclicity constraint
equivalently the directed graph of is a DAG; lagged edges are forward edges in the time-unrolled graph of Section 10, so the full dynamic structure is acyclic by construction.
Contemporaneous Versus Lagged Edges; Adjacency and Parents
Definition 13 separates two channels of influence that play different logical roles. The contemporaneous matrix collects same-period dependencies among kernels; the lagged matrices , , collect cross-time dependencies. The asymmetry between them is the acyclicity constraint: must be invertible and nilpotent up to a topological order, equivalently the directed graph of is a directed acyclic graph. Lagged edges need no such restriction because they are forward edges in the time-unrolled graph of Section 10: time order already prevents recirculation, so the full dynamic structure is acyclic by construction. The innovation condition on records that, given the lifted past and the context, the residual carries no predictable component; it is a definition of what the matrices are asked to absorb, not an assumption about the world.
The adjacency indicator and the parent set are the bookkeeping objects of this structure: records the presence of an edge under context c, and collects the parents of v, the variables on which the conditional model of v is conditioned. Parent sets interface the graph with every conditional statement made downstream, from the local sub-networks of the Step 1 query projection to the path enumeration of Step 8. The contemporaneous matrix is estimated under the acyclicity restriction and the lagged matrices over the lag set ; parent sets are then read off the solution, and the existence of a topological order is checked, whose failure is exactly cyclicity. A contemporaneous cycle makes the resolvent-type recursion of Step 8 ill-posed, because the forward propagation through presupposes invertibility, so acyclicity is an operational precondition for attribution, not an aesthetic restriction; and systematic residual structure at lags outside , visible against the lag prior, indicates a lag set drawn too narrowly.
Definition 14
(Generalized sparse/locally dense structure). The node set admits a partition such that
- GS1
- Local density. Within-block connectivity is dense or low-rank: may be nonzero for a dense set of pairs , or admits a low-rank factorization.
- GS2
- Generalized sparsity. Cross-block connectivity is sparse and hub-mediated: cross-block edges are incident to the hub set , and for blocks the cross-block coefficient submatrix admits
The effective influencer set of a node v is therefore its own block’s variables plus the hub proxies of other blocks, which formalizes the design principle of “own-domain variables plus proxy variables.”
Generalized Sparsity, Local Density, and the Hub-Mediated Low-Rank Structure
Definition 14 encodes the learnability structure that the Step 3 remark announced: a describable system is taken to be generalized sparse and locally dense. Clause (GS1) permits within-block connectivity to be dense, or the within-block coefficient submatrix to admit a low-rank factorization: mechanisms that belong together are allowed to interact richly. Clause (GS2) disciplines everything that crosses block boundaries: cross-block edges are incident to the hub set , and the cross-block submatrix admits the factorization with inner dimension much smaller than either block size. The consequence stated in the definition—that the effective influencer set of a node is its own block’s variables plus the hub proxies of other blocks—is the formal version of the design principle of own-domain variables plus proxy variables: a kernel is modeled by the mechanisms it belongs to and by a small number of proxies summarizing the rest of the system. The hub set is therefore not an auxiliary list but the carrier of all inter-domain influence.
This structure also closes the loop opened in Step 3: the provisional partition returned to the dictionary’s second stage is exactly this partition estimated on the first-pass representation. Blocks, hubs, and factor ranks are extracted from the fitted coefficient matrices and then audited against both clauses. Factor ranks comparable to block dimensions indicate that two putative blocks have not actually separated: generalized sparsity fails between them, and the partition is misdrawn rather than the factorization rich. Cross-block edges that bypass the hub set contradict (GS2) and flag hub nodes misassigned to ordinary blocks. A block with neither internal density nor low-rank structure exposes an over-split partition, in which a single mechanism has been fragmented across blocks. Each diagnostic is structural and local: it identifies which clause fails and where, without requiring a reference graph.
Definition 15
(SCGL objective). The conditional graph is estimated by
where is a (quasi-)likelihood or least-squares fit of Definition 13 under credibility weights q; and encode Definition 14 (e.g. group-structured/hierarchical penalties); the prior term is , evaluated with the lifted kernel-level prior field of Definition 12 (the factorized edge form of Definition 7, applied at kernel level); and penalizes deviation from anchors accepted in Step 5. A standard smooth acyclicity penalty is
with iff the graph of B is acyclic.
The Five Terms of the Graph Objective and What Each One Buys
The objective of Definition 15 is a sum of a data term and five regularization contributions, and each term answers a distinct failure of unconstrained fitting. The data term is a (quasi-)likelihood or least-squares fit of the lifted dynamics under the credibility weights q: it ties the graph to the panel and ensures that entries down-weighted by the Step 1 loop exert correspondingly less pull on the structure. The sparsity regularizer , weighted by , implements the edge-level side of generalized sparsity; the block regularizer , weighted by , implements the block side, with group-structured or hierarchical penalties. The acyclicity term replaces a combinatorial constraint by the differentiable function , which vanishes exactly when the graph of B is acyclic; this is what makes constrained optimization over contemporaneous structures computable. The prior term is evaluated with the lifted kernel-level prior field, applying the factorized edge form at kernel level; it pulls the solution toward structure the corpus supports, with strength set by the coefficient . The expert term , weighted by , penalizes deviation from anchors accepted in Step 5, so verified human knowledge enters at the same level as learned structure.
The operational reading is a division of labor among inputs: panel and credibility weights feed the data term, the lifted prior field feeds the prior term, anchors feed the expert term, and the two structural penalties encode Definition 14. Each term also supplies a diagnostic. The residual profile of exposes lack of fit; the magnitude of exposes near-cyclic contemporaneous structure even when the constraint appears to hold; persistent disagreement between data term and prior term at a kernel pair exposes a prior–data conflict, which is precisely the material routed to Step 5 as candidate hypotheses; and pressure of the expert term is by construction localized at anchors. An overweighted prior term reproduces the literature rather than learning from the panel, an underweighted acyclicity term admits the cycles that break the Step 8 recursion, and over-aggressive sparsity severs the hub mediation that (GS2) requires.
Definition 16
(Graph distance and conditional subgraphs). Graph-identification quality is measured by a graph distance against held-out or simulated reference structure (e.g. structural Hamming or edit-distance-based). The conditioning map is estimated jointly over contexts, so that for contexts the local subgraphs of Definition 6 may differ: the identified mechanism from source to target variables is context-dependent.
Graph Distance and Conditional Subgraphs
Definition 16 supplies the quality notion used across the pipeline. The graph distance measures identification quality against a held-out or simulated reference structure , with structural-Hamming or edit-distance-based realizations. One distance notion serves three different control loops: the credibility loop of Step 1 stops when consecutive graphs stabilize under , the active-learning outer loop of Step 5 includes in its joint convergence criterion, and Step 8 scores long-horizon graph recovery with the same object. Reusing a single distance is what makes the three stabilization statements comparable.
The second half of the definition is the conditioning statement. The map is estimated jointly over contexts rather than context by context, and the local subgraphs and produced by the query projection of Definition 6 may differ: the identified mechanism from source to target variables is context-dependent. This is the formal content behind the conditional extrapolation of Step 8, where the simulated path is driven by rather than by a frozen graph. The distance is evaluated wherever a reference exists—simulated benchmarks where the truth is known by construction, or held-out structure—and the conditioning map is audited by comparing subgraphs across qualitatively distinct contexts. Subgraphs that coincide across such contexts indicate that the conditioning channel has collapsed, that is, the context interactions of the dictionary carry no weight in the fitted matrices; large distance against simulated references exposes estimation error and localizes it to the edges and blocks where the distance is incurred; and oscillation of consecutive graphs, rather than convergence, is precisely what the stopping criteria of Steps 1 and 5 are built to detect.
Remark 3
(Quasi-causal status of the output). The learned is a quasi-causal (structural-association) object: temporal ordering (lag structure) plus sparse/locally-dense regularization and literature priors support directed, lag-consistent associations at long horizons and large scales. A causal interpretation requires additional explicit assumptions—no relevant hidden confounding, invariance across regimes, validated structural equations, or interventional evidence—none of which is delivered by nIDE or by the LLM prior alone. All downstream statements that use inherit this qualification (Section A).
The Quasi-Causal Reading and Its Downstream Discipline
Remark 3 fixes the interpretive status of everything Step 4 produces. The learned graph is a quasi-causal object: temporal ordering through the lag structure, sparse and locally dense regularization, and corpus-derived priors jointly support directed, lag-consistent structural associations at the long horizons and large scales at which PHAS operates. What they do not deliver is physical causation. A causal reading is licensed only under additional explicit assumptions—no relevant hidden confounding, invariance across regimes, validated structural equations, or interventional evidence—and neither the nIDE lifting nor the Step 2 prior, alone or jointly, supplies any of them. The qualification is inherited, not local: the transition structure consumed by Step 6, the hypotheses verified in Step 5, and the paths and fluxes computed in Step 8 all carry the same status, as collected in Section A.
This has direct consequences. Every statement derived from is reported as a structural association unless the additional assumptions are explicitly invoked for the case at hand; the active-learning closure of Step 5 is the pipeline’s instrument for moving selected hypotheses toward stronger status through staged verification, and the anchors it returns are the only channel through which verified knowledge re-enters the graph objective. In particular, normalized flux shares or parent sets should not be read as the effects of physical interventions without confounding control, invariance, or interventional evidence. Temporal precedence plus regularization plus prior support is a strong basis for directing attention and structuring control experiments; the remark records that it is not, by itself, a basis for causal claims.
6.3. Algorithmic Role
Step 4 is the system’s “gross engine”: it condenses the lifted representation into a conditional directed graph with block/hub structure, stored as adjacency and coefficient matrices, which (i) supplies the controlled transition model of Step 6, (ii) generates the hypotheses verified in Step 5, and (iii) carries the path/flux computations of Step 8. The emergent low-rank cross-block structure corresponds to the -rank factorization of Definition 14.
6.4. Interface
Inputs: lifted trajectories from Step 3; lifted kernel-level priors and skeleton from Step 3 (lifted from the Step 2 variable-level prior by ); credibility weights q from Step 1; anchors from Step 5 (on later iterations). Outputs: conditional graph with matrices ; block partition and hub set ; candidate hypotheses handed to Step 5; transition structure handed to Step 6; time-unrolled graph handed to Step 8.
7. Step 5: Active-Learning Human-in-the-Loop Closure
7.1. Notation
Within this section: is the candidate-hypothesis pool at outer iteration r; a single hypothesis (concerning an edge, lag, context-dependent relation, path, flux ranking, functional form, or boundary-sensitive mechanism); the acquisition utility; its components and the corresponding weights; the binary expert response; the posterior belief after evidence set ; the three query channels; the data-supported, literature/model-supported, and expert-validated knowledge sets; the anchor set.
7.2. Mathematical Formulation
Definition 17
(Boolean-question decomposition). The inferred graph is decomposed for expert consumption by the chain
where is a local linear effects matrix (first-order expansion of the lifted dynamics around a reference context), its subfield submatrices, expert-answerable Boolean propositions, the verification result, and an optional expert modification. The expert role is verify and modify, not directly measure.
Interpretation of the Boolean-Question Decomposition
Definition 17 converts a learned graph into questions that experts can answer without being asked to estimate numerical effects. The map summarizes the conditional dynamics by the local effects object , separates that description into subfield matrices, and turns the relevant entries into Boolean propositions . The local matrix is an explanatory interface, not a replacement for the nonlinear representation learned through nIDE and SCGL. A proposition may ask whether an edge, lag, context-dependent relation, path, flux ordering, functional form, or boundary mechanism is supported. The response records verification, while permits an expert to replace an incorrectly stated proposition by a corrected one.
The division of labor is deliberate. Automated learning selects the question because it knows which relations are statistically or decision-relevant; the expert verifies or modifies that proposition because judgment is most valuable where the model is sparse, extrapolative, or artifact-prone. Experts are not asked to supply coefficients or an alternative graph. An affirmative answer does not by itself establish physical causation, and a negative answer need not discard all model evidence: it enters the posterior update, possibly together with a modified proposition. An ambiguous question is refined rather than treated as evidence either for or against the relation. The subfield stage also controls the cognitive scope of review: an expert sees the local mechanism and its immediate context, while the full conditional graph remains the object stored and updated by the system. This makes the query interpretable without fragmenting the underlying model. The optional modification field is equally important: it allows rejection of an imprecise formulation to become usable knowledge, since the corrected mechanism can re-enter candidate generation rather than leaving only a negative binary response.
Definition 18
(Acquisition utility and staged queries). The next hypothesis queried maximizes
with component weights () and components measuring inferential uncertainty, control relevance (sensitivity of , Step 6), boundary relevance (sensitivity of , Step 7), novelty relative to , and query cost. Verification proceeds in three stages of increasing cost:
so that human queries are reserved for hypotheses surviving data and adversarial screening (a hypothesis-filtering funnel over causal links, spurious correlations, missing variables, overfitting, and noise artifacts).
Acquisition Components and Weights
Definition 18 makes query selection an explicit allocation problem. The uncertainty component favors propositions whose resolution would most reduce structural ambiguity; favors those that could change the constrained gain or action; favors those affecting boundary risk; favors information not already present in ; and subtracts the burden of obtaining an answer. The argmax therefore selects the hypothesis with the greatest expected epistemic and decision value net of cost, not merely the most uncertain hypothesis.
The nonnegative weights determine the priority assigned to these motives. A larger control weight directs effort toward policy-relevant mechanisms, while a larger boundary weight directs it toward constraints and tail outcomes. A zero weight suppresses the corresponding motive. If several hypotheses maximize , the definition identifies the maximizing set and leaves tie selection unspecified. If all remaining values are negative after cost, acquisition still ranks the least unfavorable candidate, but the outer convergence rule decides whether another query should occur. This separates the question “which hypothesis is next” from the question “should querying continue.”
The Staged Query Funnel
The progression from to and then to orders verification by increasing elicitation cost. Held-out data first test empirical support. Adversarial checking then asks whether the relation can be explained by spurious correlation, omitted variables, overfitting, unstable lag selection, or noise. Human review is reserved for hypotheses that remain consequential after those screens. A human answer is therefore the final stage of accumulated testing, not an isolated substitute for evidence. A hypothesis rejected early need not consume expert effort; one that reaches an expert carries the preceding evidence. A failed hypothesis may return only as a revised proposition generated by new data, changed context, or expert modification. The funnel therefore protects both statistical discipline and expert time. It does not rank the channels as independent verdicts; it orders them so that inexpensive falsification occurs before costly elicitation, and so that the final human response is interpreted conditional on the evidence that allowed the proposition to advance. The acquisition score remains active throughout: survival of a screen does not guarantee human review unless the hypothesis continues to offer sufficient value relative to its cost and to competing candidates.
Definition 19
(Binary posterior update). A query answer updates the belief in H by
where the response likelihoods encode channel-specific reliability. Accepted hypotheses ( above an acceptance threshold) become anchors and re-enter future candidate pools:
Posterior Updating and Re-Entry of Accepted Hypotheses
Definition 19 updates the prior belief by comparing how likely the observed answer is under H and under its negation. Channel-specific likelihoods encode the different error modes of empirical checks, adversarial checks, and expert responses. An answer raises belief only when it is more expected under the hypothesis than under its negation; consequently, the same response can be informative from one channel and weakly informative from another. This preserves the distinction between absence of evidence and evidence of absence.
The acceptance threshold converts posterior belief into an anchor. An accepted hypothesis enters and the knowledge state , after which new candidates are generated from accepted knowledge and updated evidence. The anchor can then constrain the next SCGL iteration through the expert regularizer and can also enter the dynamic prior recursion of Step 2. It therefore influences both graph learning and the generation of later hypotheses. A posterior below threshold remains informative but non-binding; one above threshold becomes operationally accepted. Expert modification creates a corrected proposition whose belief is assessed separately. Anchors are not made irreversible by definition: later evidence can change the accepted hypothesis set through the same update machinery. Because the likelihoods may depend on boundary sensitivity, expert evidence can be given a different operational role for tail mechanisms than for routine relations. This reflects where expert judgment is most discriminating without changing the binary form of the update or introducing a separate decision rule.
Definition 20
(Tripartite knowledge convergence). Let denote hypotheses supported by data queries, those consistent with the literature/model prior (Step 2), and those validated by experts. The operational consensus set is
and the outer loop is declared converged when, with tolerance ,
where is a symmetric-difference metric on hypothesis sets. The three knowledge sources play asymmetric roles: the AI prior covers short-range concrete and ultra-long-range abstract relations, well-defined data support local verification, and experts regularize against hallucination at the distributional tails.
Tripartite Consensus and Stabilization
Definition 20 distinguishes empirical support , literature/model support , and expert validation . Their intersection is conservative: consensus requires all three forms of support, so strength in one channel cannot compensate for failure in another. If the intersection is empty for competing propositions, the correct conclusion is absence of consensus rather than selection by an informal preference rule.
Convergence is assessed on the joint learning state. Graph distance compares successive SCGL outputs, the credibility-weight norm compares data-quality assessments, and compares accepted hypothesis sets. The combined movement must be below . Stability of only one component is insufficient, and a large change in any component can prevent stopping. The criterion is a practical stabilization certificate, not a proof that true structure has been recovered or a claim about convergence rate.
The fixed-point interpretation is that another pass through integration, prior updating, nIDE lifting, SCGL identification, and query closure returns nearly the same graph, credibility weights, and knowledge set. At that point additional queries are expected to yield only local refinement. The Planetary Health Axis System therefore stops when empirical fit, prior consistency, expert-validated knowledge, and credibility have stabilized jointly. The three knowledge channels retain asymmetric roles: data verify local support, the literature/model prior connects short-range and highly abstract relations, and experts are especially important where distributional tails or model artifacts make automated verification fragile. Consensus is consequently a closure rule, not an assertion that the channels are interchangeable.
Remark 4
(Tripartite convergence as a fixed point). Definition 20 expresses the “three-way convergence” design as stabilization of the joint state under the composed update defined by Steps 1–5; operationally the system stops at an approximate fixed point . No convergence rate is claimed.
7.3. Algorithmic Role
Step 5 closes the loop between automated structure discovery and human knowledge. The algorithm—not the human—selects which intermediate conclusions are queried, which avoids guided/leading error; binary feedback is fed back into the prior recursion of Step 2 and the expert regularizer of Step 4, so expert knowledge enters at the most discriminative elements. Heterogeneity in expert reliability (expert feedback helps tail/extreme cases more than routine cases) is represented by allowing the reliability likelihoods of Definition 19 to depend on the hypothesis’s boundary sensitivity .
7.4. Interface
Inputs: candidate hypotheses from Steps 2 and 4; held-out data partitions from Step 1; expert pool. Outputs: validated knowledge ; anchors ; expert regularizer for Step 4; feedback for the prior recursion of Step 2; updated posterior beliefs used in the prior field .
8. Step 6: Non-Discounted Optimal-Control Theory
8.1. Notation
Within this section: , , as in Definition 2; the single-period welfare/utility (an extension of an HDI-type aggregate over health, wealth/knowledge, and planetary-health coordinates); an exogenous scenario realization with ; the index set of generalized planetary-boundary (g-PB) constraints; the r-th boundary-shortfall risk gauge with boundary level , shortfall exponent , and risk budget ; the associated multiplier; the feasible policy class; the current (evaluation) policy; the policy, unconstrained-optimal, and constrained-optimal long-run average gains; h the relative value function; a top-level preference parameter; top-level sensitivities and normalized weights; the nonnegative penetration coefficient; occupation measures; the barycenter (or a distinguished mode) of ; the nonrenewable boundary consumption; the boundary savings attributable to current and future technological progress. The symbols (top-level weight tuple and perpetual condition) and (CES aggregates) are section-local notation used only inside Definition 28.
8.2. Mathematical Formulation
Definition 21
(Long-run average criterion). For a policy and initial state s, the long-run average gain is
Two optimal gains are distinguished and defined separately in Definition 23: the unconstrained value and the constrained value ; the symbol without a subscript always denotes the constrained value. The time-average normalization removes the divergence that afflicts undiscounted sums, while the absence of a discount factor means distant outcomes retain non-vanishing weight: the criterion is intergenerationally neutral by construction.
Meaning of the Long-Run Average Criterion
Definition 21 evaluates a policy by the average utility generated over an indefinitely long stochastic trajectory. Division by horizon length prevents the objective from diverging merely because time accumulates, while expectation accounts for the transitions induced by the policy. The lim inf form remains defined when finite-horizon averages oscillate and agrees with the ordinary limit when that limit exists. The decision question is which policy sustains the best long-run welfare level, not which policy produces a temporary improvement.
Non-discounting is a substantive choice. Recurring or persistent changes in health, wealth, knowledge, technology, and planetary health retain weight in the limiting average regardless of when they begin; initial transients become negligible. The criterion is intergenerationally neutral because an outcome is not assigned smaller weight solely for occurring later. This does not make present feasibility irrelevant: feasibility is imposed through the action sets and g-PB constraints rather than through time preference.
The unconstrained value optimizes over , whereas optimizes over the smaller feasible class . Hence the constrained value cannot exceed the unconstrained value. The unadorned always denotes the constrained target, ensuring that performance achieved by violating a boundary is not mistaken for the PHAS optimum. The contrast with a discounted criterion is structural rather than numerical: discounting multiplies continuation consequences by a factor below one, whereas the average criterion evaluates persistent consequences symmetrically across time. The finite-horizon average is useful for computation, but only its limiting behavior defines the objective used here. Consequently, a policy that sacrifices a bounded early interval to establish a superior persistent regime can be preferred, while a policy with an impressive transient followed by inferior recurrent behavior is not rewarded for that transient in the limit.
Remark 5
(Choice of the lim inf form). Notation-level variants of the long-run average objective place the expectation inside the time average, start the summation at , or—in a finite-horizon contrast against discounting—omit the limit. These differences are immaterial: the placement of is immaterial by linearity; the versus and T versus indexing differences vanish as ; and the finite-horizon version is a contrast device, not the PHAS objective. This appendix adopts the lim inf form with , which is well defined even when the ordinary limit fails to exist and coincides with the plain-limit expression whenever that limit exists.
Remark 6
(Structural contrast with discounting). Let be a per-period discount factor and the discounted value. The first-order conditions of the discounted and time-average problems differ structurally only in the factor β multiplying the continuation-value term; under , future constraint-relevant losses are geometrically down-weighted. This mechanism produces a systematic overdraft of the long-run attainable welfare ceiling under discounted optima, and the non-discounted optimum carries a higher implicit price of nonrenewable resources and a larger relative investment share in technology production. These comparative statements are recorded here as qualitative claims; the formal content used downstream is only the order statement for any feasible β-discounted optimal policy evaluated under the average criterion.
Definition 22
(g-PB gauge: design desiderata and operational shortfall construction). For each , the generalized planetary-boundary (g-PB) gauge is axiomatized by three properties. Because the triple is mutually incompatible (see below), the properties are retained here only as design desiderata on a putative functional of (random) boundary-relevant welfare variables X:
- (gPB1)
- Positive superhomogeneity: for all , with exponent (nonlinear risk amplification near the boundary);
- (gPB2)
- Translation property: for every constant a;
- (gPB3)
- Monotonicity: implies .
Incompatibility. Already on constant variables the desiderata cannot hold jointly: (gPB1) forces for all , hence ; then (gPB2) applied to gives for all , while (gPB1) gives . The two imply for all , and letting forces , so the putative gauge is not finite-real-valued. Hence no finite functional on a space containing the constants satisfies all three, and the axiom triple is retained as design guidance only.
Operational gauge. The g-PB gauge used everywhere in this appendix is the boundary-shortfall functional
where is the boundary level of constraint r and X the boundary-relevant welfare variable. Relative to the design desiderata: (gPB1) is retained in restricted form —as a functional of the shortfall , is positively homogeneous of degree (scaling scales ), which preserves the intended nonlinear risk-amplification content; (gPB2) is replaced by antitonicity in constants: is nonincreasing in a and equals 0 once ; (gPB3) is retained exactly, and for the gauge is additionally convex in X, which is the structure actually used in the constraint duality of Definition 24. Because the exponent exceeds one, remains a generalized (shortfall) risk gauge rather than a coherent risk measure. The state–action evaluation is , where is the one-step-ahead boundary-relevant variable induced by ; the state-level boundary risk under an explicit evaluation policy is defined in Definition 33.
Operational Interpretation of the g-PB Shortfall Gauge
Definition 22 separates ideal design desiderata from the implementable risk functional. The three desiderata express nonlinear amplification, responsiveness to improvements, and monotonicity, but they cannot hold jointly on a finite functional over constants. The desiderata are therefore retained as guidance, and expected powered shortfall is used as the operational gauge .
Only outcomes below contribute to the shortfall of X. Because , deeper shortfall is amplified nonlinearly. The expectation combines the likelihood and severity of adverse outcomes, so the gauge is more than an indicator that a breach is possible. It can be positive even when the expected value of X lies above , since tail outcomes may still cross the boundary; it is zero when shortfall is absent almost surely.
The retained properties govern interpretation. Monotonicity ensures that improving X cannot increase risk. Convexity supports the constraint duality used later. Restricted homogeneity applies to the shortfall itself, while antitonicity in constants means that a uniform improvement weakly reduces risk and can eliminate it. Evaluated as , the gauge is a one-step restriction on action choice: the state and action induce the next boundary-relevant variable, and feasibility is assessed under that conditional uncertainty. It is not a penalty added after optimization. The distinction between state–action and state-level evaluation is also material. The former asks whether a proposed action is admissible; the latter audits risk under an explicit current policy. This prevents the same gauge symbol from being read as an unconditional property of a state when its value actually depends on the action or policy under assessment. The shortfall form also gives a clear boundary case: improvements above the boundary do not create a negative risk offset for the same constraint, so favorable outcomes cannot mask a separate adverse shortfall within the expectation.
Definition 23
(Feasible set and constrained problem). With a risk budget for boundary r ( is the hard boundary; a risk-tolerant reading), the g-PB-feasible action set at state s is
where is the feasible policy class. The constrained optimal gain—the only used downstream—is
where is the unconstrained optimal gain, recorded here only to disambiguate the two suprema and not used in any downstream statement. The constraint family aggregates the planetary boundaries, their interaction-induced higher-dimensional constraints, and social-health-induced boundaries; only the index-set form is used here.
Feasible Actions, Feasible Policies, and the Two Suprema
Definition 23 constructs feasibility at every state. The set contains the actions available in the underlying control problem, while retains only those satisfying every boundary budget in . An action can therefore be practically available yet inadmissible for PHAS because it creates excessive shortfall risk. A feasible policy in must select such a constrained action at every state, so feasibility is a property of the entire policy rule.
A zero gives the hard-boundary reading, while a positive budget allows a degree of shortfall risk. The common index-set interface lets planetary, interaction-induced, and social-health restrictions enter the same optimization framework without changing the control theory. Maximization over asks what is attainable without boundary restrictions; maximization over asks what is attainable under them. Their ordering expresses the cost of feasibility without placing a separate penalty in utility. The values coincide when an unconstrained optimizer is already feasible. Nonempty constrained action sets are required for the Bellman maximization to have a feasible solution at each state. If the underlying admissible set is empty, the control problem itself is undefined; if only the constrained set is empty, the boundary requirements are mutually incompatible with every available action at that state. That regime is excluded through regularity rather than assigned an artificial value.
Assumption 1
(Standard regularity for the average-reward problem). The state space is a Borel subset of a complete separable metric space; is nonempty, compact, and continuous in s; U is bounded and continuous; the kernel is weakly continuous; and the controlled process admits a solution to the average-reward optimality equation (e.g. a standard ergodicity/unichain or Lyapunov-type condition holds). These are standard sufficient conditions.
Role of the regularity assumptions
Assumption 1 supplies the analytical environment in which the average-reward problem is well posed. Measurability supports policies and kernels; compactness and continuity of support existence and stability of maximizers; bounded continuous utility and weakly continuous transitions keep expectations well behaved; and an ergodicity, unichain, or Lyapunov-type condition stabilizes long-run behavior.
These conditions are not substantive planetary assumptions. They are standard sufficient regularity for the Bellman equation, a stationary optimal policy, and the later numerical methods. If they fail, the formal objective may still be stated, but existence, uniqueness, and convergence are no longer guaranteed by this assumption. The assumption also explains why stationarity is meaningful: the process must mix sufficiently that persistent behavior, rather than an indefinitely influential transient, determines the gain. This is the analytical counterpart of the long-run decision interpretation.
Proposition 3
(Average-reward Bellman equation). Under Assumption 1 there exist a constant and a measurable relative value function such that
with the normalization (anchoring) condition at a fixed reference state (the pair is otherwise identified only up to an additive constant in ). Any stationary policy in attaining the maximum for all s is average-reward optimal within .
Interpretation of the Bellman Equation
Proposition 3 balances immediate utility against continuation position. For each feasible action at state s, measures current welfare and the expectation of measures the relative value of the state reached next. The maximum over selects the action with the best immediate-plus-continuation value under all boundary restrictions. The constant is the average gain subtracted each period so that the relative value remains finite.
The function is not a second utility. It records whether a state is favorable or unfavorable relative to the reference configuration after average performance has been removed. Its additive normalization fixes a representation but does not alter action comparisons, the optimal policy, or the gain. A stationary policy attaining the maximum everywhere is optimal within . Thus an attractive current action can be rejected if it leads to a poor constrained continuation state, while a costly current action can be selected if it preserves feasibility or improves future position. The equation is evaluated state by state, but stationarity links those local choices into one policy. A rule that attains the maximum only on a subset of states does not satisfy the proposition’s optimality conclusion on the remaining states. The integral also clarifies the role of uncertainty: an action is evaluated by the full distribution of continuation states it induces, not by a single most likely outcome. Boundary feasibility is checked before that continuation value is compared, so high expected value cannot excuse an infeasible action.
Definition 24
(KKT system and shadow prices; under a constraint qualification). Assume U and each are differentiable in a, and impose the following constraint qualification: at every state s there exists an action with for all (Slater-type strict feasibility); the maximizer of the Bellman right-hand side of Proposition 3 lies in ; and the active-constraint gradients at satisfy the Mangasarian–Fromovitz constraint qualification (MFCQ). Define the one-period Lagrangian
Under the constraint qualification, the Karush–Kuhn–Tucker conditions are necessary at :
The multiplier is the shadow price of boundary r: the marginal long-run-average welfare gained by relaxing the risk budget , equivalently the welfare cost of tightening it by the same infinitesimal amount. With the Lagrangian sign convention above, the envelope relation is
wherever is differentiable in —justified, for instance, under the constraint qualification together with strict concavity of the reduced one-period problem; outside that differentiable regime retains only a subgradient/sensitivity-bound interpretation. Without the constraint qualification the KKT system need not characterize the constrained optimum, and no shadow-price reading is claimed.
KKT Conditions and the Shadow-Price Interpretation
Definition 24 treats the Bellman maximization at each state as a constrained one-period problem. The Lagrangian combines current utility and expected continuation value, subtracts the gain, and prices each boundary excess through a nonnegative multiplier. Stationarity says that at an interior maximizer the marginal benefit of changing the action equals the marginal boundary cost. Primal feasibility requires all gauge constraints to hold; multiplier nonnegativity reflects the fact that relaxing a budget cannot lower the constrained maximum.
Complementary slackness connects prices to active constraints. A slack constraint has zero multiplier and no local effect. A positive multiplier indicates a binding constraint whose budget restricts the optimum at the margin. A binding constraint with zero multiplier is a degenerate case of zero local sensitivity, not an absent constraint.
Under the stated differentiability and envelope conditions, is the marginal gain in long-run average welfare from relaxing , or equivalently the marginal welfare cost of tightening it. It is an internal price of boundary stringency at the state. Slater-type feasibility, interiority of the maximizer, and MFCQ make this first-order characterization valid. Without them, the optimum may occur at a kink or boundary, multipliers may fail to exist, and only a subgradient or sensitivity-bound interpretation remains. Shadow prices therefore carry their stated meaning only under the regularity that supports them. They are state-dependent because the marginal cost of a boundary budget can vary with current conditions and available actions. They also concern infinitesimal budget changes; a large relaxation can alter the active-constraint set, the policy, and the continuation value, so the local derivative is not a global valuation of eliminating the boundary. The multiplier vector is therefore read jointly with the constraint residuals. A positive price identifies where feasibility is expensive at the margin, while the residual identifies which restrictions are actually binding at the selected action.
Definition 25
(Dual gap and order-preserving state distance). Because the ultimate target has no closed-form expression, “maximize performance” is replaced by “minimize distance to the optimal state.” Let denote the current (evaluation) policy under assessment; its long-run average gain is the quantity of Definition 21 evaluated at (the current policy is not required to be feasible or optimal, so the gap below also reflects any infeasibility). The utility (dual) gap at state s is
a difference of two long-run average gains (never of a gain against a single-period utility). It is nonnegative whenever ; if the current policy is infeasible, may be negative and the sign itself reports that unconstrained outperformance relative to the constrained optimum. With occupation measures on and optimal stationary law (optimal occupation measure) , define the optimal reference state directly from as its barycenter
replaced by a distinguished mode of when the barycenter is not meaningful for the state geometry. The weighted state distance to the optimal stationary law is
where is a component distance and the weights are those of Definition 26. Under the stated convexity and monotonicity assumptions, we impose the surrogate condition that there exists a nondecreasing map such that on the evaluated state set. Consequently the map from to is order-preserving,
so that state-space distance is a valid surrogate for the unobservable optimality gap.
Utility Gap, Optimal Stationary Law, and Distance Surrogate
Definition 25 compares the constrained optimal gain with the long-run gain of the current evaluation policy. For feasible , the utility gap is nonnegative and measures sustained welfare forgone. If the current policy is infeasible, the difference may be negative because it can outperform the constrained optimum by using excluded actions; the sign must therefore be interpreted together with feasibility and boundary risk.
The optimal stationary law describes the long-run distribution of state–action pairs under the optimal policy rather than a single terminal point. Its state barycenter supplies a reference when averaging is meaningful; otherwise a distinguished mode is used. The weighted distance aggregates componentwise distances from the current state to that reference, with larger weights giving coordinates greater reporting influence.
The imposed nondecreasing map makes distance an order-preserving surrogate for the utility gap on the evaluated state set: greater weighted distance cannot correspond to a smaller gap. If the current policy is feasible and optimal, both quantities can vanish. Equal distances do not imply identical mechanisms, only the same reported ordering through the surrogate. If the order-preserving condition fails, distance remains descriptive but cannot be used as a substitute for the utility gap. The construction also explains why the reference is a stationary law: long-run optimality concerns recurrent behavior, so the relevant target is where the optimally controlled process spends its time. The barycenter or distinguished mode is a reporting summary of that law, not an additional optimization variable. This treatment accommodates optimal processes that cycle, mix among regimes, or visit several favorable regions. In such cases, proximity to every visited point is not required; the evaluated state is compared with the stated summary of the long-run law, and the surrogate condition supplies the reported ordering.
Definition 26
(Top-level weights and propagation). Let collect the top-level preference parameters of U (target-preference intensities over health, wealth/knowledge, technology accumulation, and the planetary-health coordinates). The KKT conditions of the single-period problem family determine the top-level weights; an explicit weight formula is recorded in Definition 28(i). The following envelope-derivative construction is the alternative used in this appendix. Where the envelope derivative exists (cf. Definition 24), define the raw top-level sensitivities and nonnegative normalized weights by
provided ; if all raw sensitivities are nonpositive, a predeclared fallback weight vector on the simplex is used. Weights propagate down the conditional graph along the penetration structure of Definition 14: for the transmitted share is with nonnegative penetration coefficients satisfying , followed by renormalization within each level (a downward broadcast / upward aggregation closed loop).
Top-Level Sensitivities, Normalized Weights, and Propagation
Definition 26 obtains reporting weights from the constrained optimum. Each sensitivity is the envelope response of to the corresponding preference parameter in , after optimal adjustment rather than with actions held fixed. Positive-part projection excludes negative weights, and normalization places the result on the simplex. If all projected sensitivities vanish, the ratio is undefined and the predeclared fallback vector is used.
Propagation then distributes top-level importance through the SCGL graph. The coefficient gives the share of the weight at u transmitted to its influencing node v under context c. Nonnegativity and the stated summation make this an allocation of influence, not a signed causal effect. Renormalization supports the downward broadcast and upward aggregation loop, linking preferences at the optimum to the mechanisms that produce top-level outcomes. The weights are therefore comparative decision quantities. They indicate how local mechanisms contribute to valued outcomes under the identified structure, but they do not by themselves prove that changing one node will produce the same proportional change in welfare.
Definition 27
(Technology-accumulation equilibrium; equality form and operational relaxation). Let denote the nonrenewable-boundary consumption in period t, and , the nonrenewable-boundary savings attributable, respectively, to current technological progress and to the future progress enabled by current investment. The technology-accumulation equilibrium is stated as the equality
i.e. the boundary consumed in the current period is exactly covered by the boundary saved through current and future technology. As a constraint inside the feasible-set construction of Definition 23 it enters in the relaxed inequality form
so that over-saving is feasible while under-saving is not. Measurement of and is left unspecified; the constraint is an element of .
Technology Equilibrium and Its Operational Relaxation
Definition 27 treats technology accumulation as boundary accounting. Current nonrenewable-boundary consumption is compared with savings from technology already operative and savings from future progress enabled by current investment. The equality form requires exact balance: boundary use is fully covered by current and enabled future savings.
The operational inequality requires savings to be at least consumption. Over-saving is feasible, while under-saving is not, so exact equality need not be forced. The condition belongs to the g-PB family and enters feasible-action construction in the same way as other boundary restrictions. Its two savings terms distinguish immediate technological substitution from the enabling effect of present accumulation; the definition specifies when technology can relieve pressure on the nonrenewable boundary. If savings exceed consumption, the slack does not authorize use of a different boundary budget unless the model separately connects those constraints. The condition is one member of the family in and does not override the simultaneous feasibility requirement for the others.
Definition 28
(Supplemental theory: top-level weight tuple, perpetual condition, and CES aggregates; adapted section-local notation). The following theory components are recorded in adapted notation. All symbols introduced in this definition aresection-local; where a symbol would collide with appendix-wide notation it has been renamed.
- (i)
- Top-level weight tuple. With the target-preference intensities over health, wealth/knowledge, and technology accumulation; the implicit price of the nonrenewable resource (the subscript a refers to that resource, not to the action ); a time-preference-related parameter; and a scale constant, the top-level weight tuple iswhere are the health and wealth/knowledge state coordinates (section-local notation, distinct from the relative value function h). The envelope-derivative weights of Definition 26 are the alternative to this form.
- (ii)
- Perpetual condition. With accumulation coefficients over the health, wealth/knowledge, and education/technology inputs , the perpetual (civilizational sustainability) condition isi.e. the implicit-price-weighted composite accumulation must cover time-preference decay. It is recorded as supplemental theory and does not enter the operational constructions of Steps 6–8.
- (iii)
- CES planetary-health and production aggregates. The four health dimensions (human, species, environmental, social) are aggregated into a planetary-health index, and the planetary-health-friendly () and planetary-health-destructive () technology outputs into final output, both in constant-elasticity-of-substitution form:with on the unit simplex and the CES parameters (section-local; the production weights are denoted to avoid collision with the top-level weights ). These aggregates supply the functional-form content behind the utility U and the four health coordinates of the state ; they are supplemental theory.
Supplemental Weight, Perpetual, and CES Formulations
Definition 28 records auxiliary forms without replacing the operational constructions. The top-level weight tuple expresses relative preference through ratios involving health, wealth or knowledge, technology accumulation, scale, time-preference-related terms, and the implicit price of the nonrenewable resource. Its interpretation is comparative rather than numerical. The section-local h and w are state coordinates, distinct from the relative value function h, and the envelope-derivative weights remain the alternative used throughout.
The perpetual condition requires the implicit-price-weighted composite accumulation to cover the stated decay term. It is supplemental sustainability theory and does not alter the Bellman equation, KKT system, or evaluation functionals unless separately incorporated into the declared constraint family.
The CES aggregates combine the four health dimensions and the friendly and destructive technology outputs through nonnegative simplex weights and substitution parameters below one. These forms clarify how multidimensional planetary health and differentiated technology output can enter the utility and state coordinates, and they leave the operational gain, constraints, weights, and policy definitions unchanged. In decision terms, the CES forms state how substitutable the included dimensions are and how their relative shares enter composites. The simplex condition makes the shares comparable, while the section-local scope prevents the auxiliary production weights from being confused with the top-level weights used elsewhere.
8.3. Algorithmic Role
Step 6 supplies the normative core of PHAS: it converts the learned dynamics (Step 4) into a controlled stochastic system, defines the intergenerationally neutral objective, encodes planetary, One-Health, and social-health boundaries as gauge constraints, and produces the shadow prices and weights that make “distance to the optimal state” a computable, order-preserving surrogate for the unobservable optimality gap. The outputs are exactly the quantities evaluated numerically in Step 7 and decomposed into paths in Step 8.
8.4. Interface
Inputs: conditional graph and lifted transition structure from Step 4 (used to estimate ); validated anchors from Step 5; utility construction U and gauge family . Outputs: gain and relative value ; optimal policy ; shadow prices ; top-level weights and penetration structure; dual gap and distance ; occupation measure ; all passed to Steps 7 and 8.
9. Step 7: Numerical Implementation and Current-State-to-Optimum Evaluation
9.1. Notation
Within this section: is the Bellman operator; the n-th iterate of the relative value function; the gauge reference state; the parameter vector of the fitted value representation ; the n-th policy in policy iteration; and the transition operator under ; a stepsize sequence; the first-passage time into the boundary-violation set ; the bounded reporting score; a constraint-restoration map onto the feasible set.
9.2. Mathematical Formulation
Definition 29
(Bellman operator and relative value iteration). Define
Relative value iteration generates
so that enforces the normalization condition of Proposition 3. Under Assumption 1, standard average-reward theory gives and (up to the additive constant fixed by the gauge).
Role of the Bellman Operator in the Implementation
The Bellman operator of Definition 29 is the computational bridge between the constrained optimality theory of Step 6 and any executable numerical scheme. Each application of performs one complete one-step lookahead: for every state s it re-solves the constrained static problem over the feasible set , prices each admissible action by the sum of the immediate utility and the expected continuation value under the controlled kernel, and returns the best attainable total. Because the maximization ranges over , every evaluation of the operator inherits the boundary constraints of Definition 23: feasibility is built into each backup rather than imposed afterward. The expectation is taken against the transition law estimated on the lifted representation of Steps 3–4, supplied in practice by quadrature, Monte Carlo sampling from the controlled simulator, or exact enumeration on a finite grid.
What Relative Value Iteration Computes
Relative value iteration maintains two objects at each sweep: the relative value function and the scalar gain estimate . The subtraction of the operator’s value at the gauge state removes the additive indeterminacy inherent in the average-reward criterion, enforcing the normalization condition of Proposition 3 at every iterate rather than only in the limit. The pinned quantity is then read as the transient advantage of starting at s rather than at the gauge state under optimal continuation, while is the running estimate of the best long-run average utility. One sweep is a full Bellman backup followed by re-centering, repeated until the diagnostics of Definition 32 accept the iterate. Under Assumption 1, standard average-reward theory guarantees that the gain estimates converge to and the relative values converge to up to the constant fixed by the gauge, so the procedure outputs a candidate optimal gain and a candidate relative value function from which a greedy feasible policy can be extracted.
Definition 30
(Policy iteration). Policy iteration alternates evaluation and improvement:
where the evaluation equation is the Poisson equation of the Markov chain under , solved up to the gauge constant. Constraint feasibility is enforced at the improvement step by maximizing over ; when exact projection is unavailable, a restoration map or the penalized Lagrangian of Definition 24 is used.
Evaluation as a Linear Solve
The evaluation half-step of Definition 30 treats the current policy as fixed and asks what long-run performance it delivers. With the policy frozen, the induced state process is a single Markov chain, and the evaluation equation is the Poisson equation of that chain: a linear system in the pair , with the gauge condition at selecting one member of the affine family of solutions. This half-step requires no maximization; it is a solve, exact on a discretization or approximate by least-squares projection onto the fitted representation of Definition 31. Its output is the gain of the incumbent policy and the relative value function used by the improvement step.
Improvement and Constraint Restoration
The improvement half-step re-solves, at every state, a one-step constrained problem in which plays the role of continuation value. Feasibility is enforced at the point of maximization by restricting to ; where an exact constrained maximizer is unavailable, the restoration map or the penalized Lagrangian of Definition 24 supplies an implementable surrogate. The alternating structure separates the two difficulties of the problem: evaluation handles the stochastic dynamics for a fixed decision rule, while improvement handles the static constrained optimization for fixed valuations. One round of policy iteration is more expensive than a single Bellman backup because of the embedded linear solve, but it typically requires far fewer rounds; the choice between the two schemes is left open, and both are judged by the same diagnostics before any output is accepted.
Definition 31
(Fitted high-dimensional value representation). For large , the relative value is represented on the lifted basis of Step 3:
with θ fitted by any of the standard routes: projected Bellman (fixed-point) equations with the projection onto the span of Ψ; least-squares policy evaluation; temporal-difference updates with ; or sampled fitted policy iteration. The estimate is updated by the running average of U along simulated or observed trajectories.
Why a FITTED Representation is Needed
The state coordinates of the Planetary Health Axis System are median-kernel coordinates on a high-dimensional, effectively continuous space, so storing as a table is not feasible. Definition 31 replaces function storage by the parameter vector and evaluates the approximate relative value through the lifted basis constructed in Step 3. Because the basis is context-dependent, the same fitted representation carries the conditional structure identified by the SCGL step: changing the context changes the features through which is evaluated, without re-specifying the representation.
Fitting Routes and Temporal-Difference Updates
The definition records several standard fitting routes, all of which approximate the same optimality content. The projected Bellman route seeks a parameter whose image under , once projected back onto the span of , reproduces the current approximation; least-squares policy evaluation solves the projected Poisson equation for a fixed policy; sampled fitted policy iteration interleaves the two. The temporal-difference route is a one-sample stochastic approximation to the Bellman residual along realized or simulated trajectories: the error compares the realized immediate utility plus the successor value, centered by the running gain estimate , against the current value estimate, and the parameter is moved along the gradient of at the visited state by the stepsize . The gain estimate is the running average of realized utility, so no separate gain computation is required. Whichever route is used, the fitted object is accepted only after passing the diagnostics of Definition 32, which are stated for the iterate, not for the approximation architecture.
Definition 32
(Convergence diagnostics). Iteration stops when the following diagnostics hold jointly: Bellman residual ; span contraction , where ; gain stabilization ; policy stabilization for a policy distance ; and constraint residuals on a validation grid.
Diagnostics as Acceptance Certificates
Definition 32 is the acceptance gate of the numerical step: an iterate is promoted to the reported triple only when the five checks hold jointly. The Bellman residual, measured in the supremum norm, certifies that the iterate approximately satisfies the optimality equation everywhere rather than on average; an iterate failing this check does not approximately solve the problem and is rejected however stable the other sequences appear. The span contraction check detects residual oscillation that the gain sequence cannot reveal: it certifies that the iterates are settling rather than cycling, a pathology particular to the average-reward setting. Gain stabilization certifies that the scalar estimate has stopped moving; it is the weakest of the checks and is never sufficient alone, because a flat gain sequence can coexist with a drifting relative value function. Policy stabilization, expressed through the policy distance , certifies that the extracted decisions no longer change; it may hold before the residual tolerance is met when improvement flips among near-optimal actions, and conversely, so the two checks are complementary. Finally, the constraint-residual check evaluates the positive part of the excess of each risk gauge over its budget on a validation grid, certifying that the candidate policy respects the boundary constraints at states not used to fit it: feasibility is verified out of sample. When the joint gate fails, the diagnostics indicate the remedy only by elimination—continue iterating, change the solver or fitting route, enrich the representation, or revisit the modeling assumptions; they certify or reject an iterate, they never repair one, and no output of Step 7 is reported without passing them.
Definition 33
(Evaluation functionals: gap, distances, first passage). The evaluation layer reports four families of quantities. Throughout, the state-level boundary risk is the gauge of Definition 22 evaluated at the explicit current (evaluation) policy,
so that every state-level risk statement carries an explicit policy/action.
- (E1)
- Utility gap:, the difference between the constrained optimal gain and the long-run gain of the current policy (Definition 25).
- (E2)
- Weighted state distance: relative to the barycenter of the optimal stationary law, order-preserving relative to under the assumptions of Definition 25.
- (E3)
- Boundary-risk (safe-operating-space) distance: , the risk-budget slack of boundary r at s under ; the multi-boundary profile is . The distance is the gauge-distance reading of the same slack profile (the terminology is retained; its exact relation to the slack profile is not further specified).
- (E4)
- Time distance / first passage: with the boundary-violation set and the trajectory under ,the time-to-criticality at the current policy; up-/down-crossing analyses of the slack processes are the standard first-passage tools applied here.
From a Certified Solution to Evaluation
Once the solver output is certified, Definition 33 converts it into four families of quantities that answer, in different units, the question of how far the current configuration is from the best attainable long-run configuration. The utility gap is computed by evaluating the current policy with the same machinery—a Poisson solve or a trajectory average under —and subtracting the resulting gain from the constrained optimal gain. It is measured in utility units per unit time, is nonnegative by construction, and vanishes exactly when the current policy attains the constrained optimum. The weighted state distance relocates the comparison into state space: coordinatewise distances between the current coordinates and the barycenter of the optimal stationary law are combined with the weights of Definition 26, and under the assumptions of Definition 25 the result is order-preserving relative to the utility gap, so it is a state-space proxy that moves in the same direction as the utility loss while additionally indicating where, in coordinates, the shortfall lies.
Boundary Slack and First Passage
The boundary-risk family reports the slack profile , where each component is the risk budget minus the state-level risk evaluated at the explicit current policy: positive slack is headroom and negative slack is violation, so the profile records which boundaries bind, which are breached, and which are satisfied. The distance is the gauge-distance reading of the same slack profile. The first-passage family adds the time dimension: with the boundary-violation set defined from the same gauges, the time-to-criticality is the first entry time of the trajectory under into . It is computed as a stopping-time statistic over simulated or observed trajectories and is reported as a distribution, not a single number; up-crossing and down-crossing analyses of the slack processes are the standard first-passage tools applied to estimate it. Because every state-level risk statement carries an explicit policy and action, all four families are functions of the pair and change when the evaluation policy changes. The four families are deliberately reported in their own units—utility, state distance, boundary slack, and time—and are collapsed only through the reporting score of Definition 34.
Definition 34
(Bounded reporting score). The PHAS reporting score is any fixed, strictly decreasing map applied to the gap/distance,
where the interval is the reporting scale (upper endpoint: the optimal expected ultimate target attainable from a fully benign reference state; lower endpoint: expected civilizational failure). The specific map is versioned.
Interpretation of the Reporting Score
The score of Definition 34 is a composition of a fixed, strictly decreasing map with the weighted state distance, and its computational content is therefore trivial once has been certified: all modeling content lies upstream. The interval is the reporting scale; the upper endpoint carries the interpretation of the optimal expected ultimate target attainable from a fully benign reference state, and the lower endpoint carries the interpretation of expected civilizational failure. Strict monotonicity makes the score deteriorate exactly when the distance to the optimal reference increases, inheriting the order-preserving property of relative to the utility gap. Because the map is versioned, scores are comparable across states and times under a fixed version; cross-version comparison requires the versioning record. The score is a communication layer over the evaluation functionals and introduces no estimation problem of its own.
9.3. Algorithmic Role
Step 7 turns the theory of Step 6 into computable objects: a stabilized , diagnostics certifying the solve, and the evaluation functionals that answer “how far is the current configuration from the best attainable long-run configuration” in utility, state, boundary, and time units. The transformed stationary (ergodic) process generated by is the object simulated in Step 8.
9.4. Interface
Inputs: from Step 6; controlled kernel estimated on from Steps 3–4; anchors and validation partitions. Outputs: numerical with convergence certificates; evaluation tuple ; the optimal stationary process for Step 8.
10. Step 8: Path/Flux Outputs and Unconditional and Conditional Extrapolation
10.1. Notation
Within this section: are source and target nodes (median kernels or aggregate state coordinates); a horizon; the time-unrolled DAG of over ; a directed path; the full admissible path set; the coefficient of edge e in ; the raw path gain; the full-system source-to-target response; the normalized path flux; the information filtration at time t; a scenario realization with scenario measure ; a vector of prescribed future values for a variable subset S; particle weights; on the simplex the portfolio weights; component policies; the portfolio policy; a submodel parameter with prior (both section-local); C a copula.
10.2. Mathematical Formulation
Definition 35
(Time-unrolled graph and full path set). The time-unrolled graph has node set and edges whenever ; it is acyclic in the time direction by construction. The full admissible path set from x to y at horizon under context c is
What Time-Unrolling Computes
The time-unrolled graph of Definition 35 converts the lagged conditional dynamics of Step 4 into a static object on which path questions become finite reachability questions. Each node is a copy of a median kernel (or aggregate state coordinate) at a time index within the horizon , and an edge exists exactly when the corresponding coefficient is nonzero, so the edge set is read off directly from the context-indexed coefficient matrices produced by the SCGL step. Because every edge advances the time index, the unrolled graph is acyclic in the time direction by construction, even when the original conditional graph contains feedback cycles; dynamics with reciprocal influence become feed-forward structure on the unrolled object. The computational consequence is that enumeration, reachability, and path-sum operations over the horizon are finite directed acyclic graph operations, and the identification-stage acyclicity penalty does not conflict with cycles in the estimated dynamics.
Full Path Enumeration
The admissible path set collects every simple directed path in the unrolled graph from the source copy to any target copy with . Simplicity excludes revisits of a node–time copy, the horizon bound guarantees finiteness, and enumeration is a standard traversal on the unrolled directed acyclic graph. The set is context-conditioned: it is computed from and at the context of the query, so different contexts yield different path sets. It is the index set over which the response recursion of Definition 36 is decomposed and over which the flux accounting of Proposition 4 is performed in one pass. Its practical size is governed by the conditional sparsity of the estimated coefficients and by the horizon.
Definition 36
(Local path gain and full-system response). Under a source perturbation of magnitude at , the full-system response is computed by forward recursion of the lifted dynamics of Definition 13:
with accumulated to the target horizon. In a local linearization, the raw gain of path p is the product of edge coefficients,
The linear product form is a first-order sensitivity along the path; the recursive definition of is primary and remains valid under nonlinearity.
Recursive Full-System Response
The full-system response of Definition 36 answers the question: if the source node x is perturbed by the magnitude at time zero, what is the induced displacement at the target node y by the target horizon, after the perturbation has propagated through the entire system? The computation is a forward recursion of the lifted dynamics initialized at : at each time index the contemporaneous block resolves within-period simultaneity among the coordinates, and the lag terms accumulate the delayed influences arriving from earlier times. The response is then read as the y-coordinate of the propagated displacement. The recursion is the primary object because it is defined on the dynamics themselves: it depends on no path decomposition and remains meaningful under nonlinearity, where propagation follows the lifted recursion of Definition 13 rather than a linear product rule.
Raw Path Gains as First-Order Sensitivities
The raw path gain attaches a single number to each enumerated path: the source magnitude multiplied by the product of edge coefficients along the path. It is a local linearization—a first-order sensitivity along the path. Its computational value is decompositional: it converts the aggregate response into pathwise summands whose signs and magnitudes can be tabulated, ranked, and audited. The sign of a raw gain is inherited from the product of signed edge coefficients, and nothing in the construction suppresses mixed signs across the path set. When the linearization is inappropriate, the raw gains are discarded while the recursive response remains the reported system-level quantity.
Proposition 4
(Exact path expansion, additive signed attribution, and normalized flux shares). Fix and write . The statement separates three logically distinct objects.
- (F1)
- Exact path expansion. In the locally linear regime of Definition 36, the resolvent recursion of the time-unrolled DAG expands exactly over the path set (path-sum expansion of terms): with the truncation/linearization residual ,where when the linearization is exact and the horizon covers every contributing path, and otherwise collects the neglected higher-order/truncated-path terms. This is an exact expansion statement, not an attribution normalization.
- (F2)
-
Additive signed attribution. The raw signed contribution of path p isThe family is additive and signed by construction and exhausts the response up to the residual, ; no normalization is applied, mixed signs are carried as-is, and no denominator condition is needed.
- (F3)
-
Normalized shares (conditional definition). Only when the total raw gain is nonzero,define the jointly normalized flux shareThe adding-up is a construction identity for the shares; whenever (i.e. ) normalization rescales the raw contributions, so individual are relative shares of the response, not absolute path contributions, and no identity between and is claimed. When (exact signed cancellation) the normalized share is undefined and only the raw decomposition of (F2) is reported. For mixed-sign path gains, the absolute-share signed variant, defined whenever ,retains each path’s sign and exhausts the response magnitude,but satisfies in general (signed cancellation is not preserved); it coincides with when all path gains are nonnegative and differs from only by a global sign when all path gains are nonpositive.
In all three families the computation is performed once over the whole path set, which eliminates the double counting produced by one-path-at-a-time attribution and is the one-shot full-system estimation principle.
Three Logically Distinct Accounting Objects
Proposition 4 separates statements easily conflated in reporting. Part (F1), the exact path expansion, is a statement about the resolvent algebra of the unrolled directed acyclic graph: in the locally linear regime the recursive response expands exactly as the sum of raw gains over the full path set plus the residual , which vanishes when the linearization is exact and the horizon covers every contributing path, and otherwise collects the neglected higher-order and truncated-path terms. It is an expansion statement, not an attribution normalization. Part (F2), the additive signed attribution, reports the raw gains themselves as the decomposition: the family is additive and signed by construction, exhausts the response up to the residual, requires no denominator condition of any kind, and carries mixed signs as they arise. This is the fallback decomposition and the audit-grade one, because it is defined in every configuration. Part (F3), the normalized shares, is a conditional definition: only when the total raw gain is nonzero are the shares formed, rescaling the raw gains so that they sum to the full-system response. The adding-up over the path set is then a construction identity of the shares, and whenever the residual is nonzero the shares are relative shares of the response rather than absolute path contributions; no identity between and is claimed.
Mixed-Sign and Zero-Denominator Discipline
The conditional definition is the mechanism that prevents meaningless output. When through exact signed cancellation, any normalized share would divide by zero, so the shares are declared undefined and only the raw decomposition of (F2) is reported; an undefined share is not silently replaced by a rescaled or absolute variant. For mixed-sign path gains, the absolute-share signed variant is defined whenever the sum of absolute raw gains is positive: it retains each path’s sign and exhausts the response magnitude, but its signed sum does not recover the response in general, since signed cancellation is not preserved. The variant coincides with when all raw gains are nonnegative and differs from it only by a global sign when all are nonpositive. All three families are computed once over the whole path set, and this one-shot full-system computation eliminates the double counting produced by one-path-at-a-time attribution.
Remark 7
(Policy output as configuration on the flux network). Because intervention on acts on the entire flux-carrying network rather than on a single path, the PHAS policy object is a portfolio: a vector of intensities over named intervention classes, evaluated through the fluxes they modulate. This is the formal reason the system output is a policy package, not a single recommendation.
Definition 37
(Unconditional extrapolation). With scenario/policy uncertainty integrated out, the unconditional predictive law of the future trajectory is
where is the scenario/policy measure. Trajectories are generated by recursive sampling from on the lifted representation.
What Unconditional Extrapolation Computes
Definition 37 produces the predictive law of the future trajectory given the information filtration when neither a policy nor a scenario is pinned down: policy and scenario uncertainty is integrated out against the scenario/policy measure . The integral is evaluated by Monte Carlo: policy–scenario pairs are drawn from the conditional scenario measure, and each draw generates a trajectory by recursive sampling from the controlled transition law on the lifted representation. The output is a distribution over trajectories, not a point forecast; downstream summaries—moments, quantiles, tail functionals—are computed from the simulated ensemble. The scenario measure encodes current beliefs about which policies and exogenous realizations will occur. The unconditional law is the descriptive reporting object and the reference against which the conditioned forecasts of Definition 38 are contrasted.
Definition 38
(Conditional extrapolation). Three conditioning modes are supported.
- (C1)
- Policy- and scenario-conditioned: with exogenous policy π and scenario ξ,is generated by recursive sampling under the intervened kernel, with the conditional graph and prior co-evolving along the simulated path:where the simulated evidence, context, and feedback are induced by ; i.e. the prior field is dynamic: each realized scenario updates the next stage’s structural prior rather than mapping anomalies through a fixed function.
- (C2)
- Conditioned on prescribed future variable values: for target subset S and prescribed values , simulated trajectories are weighted byfollowed by normalized resampling (standard posterior trajectory weighting).
- (C3)
- Dynamic-prior consistency: both modes share the recursion of (C1), so conditional extrapolation is always driven by the current conditional graph , not by a static graph.
Policy- and Scenario-Conditioned Forecasts
Mode (C1) of Definition 38 answers the interventional question: what happens if a specified policy is imposed and a specified scenario unfolds? The intervention operator replaces the policy argument of the transition law, trajectories are generated by recursive sampling under the intervened kernel, and two objects co-evolve along each simulated path: the conditional graph is re-evaluated at the simulated context at every stage, and the prior field is advanced by the recursion of Step 2 driven by the simulated evidence, context, and feedback induced by the realized states and scenario draws. This is the dynamic-prior property: each realized scenario updates the next stage’s structural prior rather than mapping anomalies through a fixed function, so forecasts under a novel regime are governed by the structure the regime itself induces, not by a frozen historical graph.
Conditioning on Prescribed Future Values
Mode (C2) reverses the direction of the query: rather than asking what a policy will cause, it asks which futures are compatible with prescribed values for a target subset S of variables. Simulated trajectories are weighted by the likelihood of the prescribed values under the trajectory, policy, scenario, and context, and the weights are normalized and resampled by standard posterior trajectory weighting. The result is an ensemble concentrated on paths that realize the prescribed outcomes, from which the pathways and intermediate states leading to those outcomes can be read off. Weight degeneracy—ensembles in which few trajectories carry most of the mass—is a computational hazard of this mode. Mode (C3) records that both conditioning modes share the co-evolution recursion of (C1): conditional extrapolation is always driven by the current conditional graph , so no conditional forecast is ever produced from a static graph.
Definition 39
(Policy portfolio and distributional reporting). For component policies and weights , , , the portfolio policy is the mixture (mixing over policy realizations). The policy lab reports, for each α, the induceddistributionsof
together with trajectory moments, quantiles, and tail functionals (VaR/CTE-type) of the state coordinates, since boundary-breach risk concentrates in the tails. Long-horizon forecast quality is scored by a time-decay loss with horizon weights , and graph-identification quality by the graph distance of Definition 16.
Portfolios and Distributional Reporting
Definition 39 formalizes the observation that intervention on a source-to-target pair acts on the entire flux-carrying network, so the decision-facing object is a portfolio rather than a single recommendation. The portfolio policy mixes the component policies with weights (mixing over policy realizations); each candidate portfolio is evaluated by simulation through the certified solver output of Step 7 and the extrapolation machinery of this section. The policy lab reports, for each weight vector, the induced distributions of the long-run gain , the weighted state distance , the first-passage time , and the fluxes , together with trajectory moments, quantiles, and tail functionals of the VaR/CTE type for the state coordinates, since boundary-breach risk concentrates in the tails rather than in the means. Long-horizon forecast quality is scored by the time-decay loss with horizon weights , and graph-identification quality by the graph distance of Definition 16. Distributional reporting makes portfolios comparable: equal expected gains can be separated by first-passage tails and flux profiles, and the trade-off surface over is the deliverable.
Submodel Coupling
The submodel layer consumes the main pipeline rather than paralleling it. Sub-models of the PSM family take main-model outputs as priors on their section-local parameter and are re-adjusted by Bayesian posterior updating against their own observations, so information flows one way from the system-level objects into the submodel layer, which remains a downstream application, not a separate mechanism. Where joint severity–exposure–vulnerability dependence is required, it is represented by the copula C through the marginals of the three coordinates, with the copula left unspecified; nothing in the main pipeline depends on a particular copula family.
Remark 8
(Submodel coupling; SEV layer). Sub-models (the PSM family) consume main-model outputs as priors and are re-adjusted by Bayesian posterior updating, with section-local submodel parameter and prior . Joint severity–exposure–vulnerability dependence, where used, is represented by a copula with C unspecified. These layers are downstream applications of Steps 1–8, not separate mechanisms.
10.3. Algorithmic Role
Step 8 exposes the system’s decision-facing products: complete pathway sets with jointly normalized fluxes for arbitrary source–target pairs, and forecast distributions under unconditional, policy/scenario-conditioned, and future-value-conditioned regimes, with dynamic priors. It is the readout layer through which the control solution of Steps 6–7 and the identified structure of Steps 3–5 become actionable.
10.4. Interface
Inputs: conditional graph and coefficients from Step 4; prior recursion from Step 2; controlled simulator, optimal policy, and evaluation functionals from Steps 6–7; scenario generator; query specifications from Step 1. Outputs: path sets and flux tables ; forecast distributions (unconditional and conditional); policy-portfolio distribution reports; submodel priors for the PSM layer. These outputs terminate the master pipeline of Section 2.3.
Acknowledgments
The authors declare that this technical document describes the technical specification of the PHAS system as of version V1.4.13 (April 2026), and that its models, specifications, and contents are subject to change as the PHAS system is upgraded. Many of the key technical details presented herein will be published separately as rigorous theoretical and technical articles through peer review, and this document will cite them in accordance with academic standards. This document remains a preprint; some of its explanatory passages were completed with the assistance of AI, which was used to polish the language of explanatory and descriptive passages, to correct grammar, and to improve readability. The three authors contributed equally to this work. We thank the entire PHAS working group and the PHAS expert panel for their contributions; some of their members will be added to the author list as the project progresses.
Appendix A. Consolidated List of Assumptions
The following items collect the explicit assumptions required for the mathematics to hold together with the standard constructions whose concrete form is left open.
- (A1)
- Causal status. All identified structure is quasi-causal (structural association). Causal interpretation requires temporal ordering plus additional assumptions such as no relevant hidden confounding, cross-regime invariance, interventional validation, or validated structural equations (Remark 3).
- (A2)
- Median kernels. The coordinate-wise median over view sets instantiates the kernels’ role; attribute-flow generation is recorded through the attribute sets (Definition 11). Positive-semidefinite kernel properties are used only when separately verified.
- (A3)
- g-PB gauge. The design axiom triple (gPB1)–(gPB3) is mutually incompatible on constant variables and is retained only as design desiderata; the operational gauge is the boundary-shortfall functional , , with (gPB1) retained in restricted (shortfall-homogeneity) form, (gPB2) replaced by antitonicity in constants, and (gPB3) retained exactly (Definition 22).
- (A4)
- Average-reward regularity. Existence of solutions to the optimality equation rests on standard compactness/continuity/ergodicity conditions (Assumption 1).
- (A5)
- Constraint qualification. The KKT system and the shadow-price/envelope reading are conditional on Slater-type strict feasibility, MFCQ at the maximizer, and differentiability (Definition 24).
- (A6)
- Optimal reference. The optimal reference is the optimal stationary law , represented by its barycenter (or a distinguished mode when the barycenter is not meaningful); no unique optimal state is assumed (Definition 25).
- (A7)
- Feature dictionary. The nIDE dictionary of Definition 10 is a standard construction. The dependence between the dictionary and the SCGL block partition is resolved by an explicit two-stage construction (first-pass dictionary without block summaries; one optional augmented second pass), not by co-estimation.
- (A8)
- Graph-learning penalties. The smooth acyclicity penalty and the group-structured penalties of Definition 15 are standard constructions.
- (A9)
- Active-learning internals. The acquisition utility components , their weights , response likelihoods, acceptance thresholds, hypothesis-set metric , and stopping tolerance are left unspecified (Definitions 18–20).
- (A10)
- Credibility loop. The update map , its monotonicity requirement, and the stopping tolerances are left unspecified (Definition 5).
- (A11)
- Numerical solver. Relative value iteration, policy iteration, fitted representations on , constraint restoration, and convergence diagnostics of Section 9 are standard constructions.
- (A12)
- Path gains and fluxes. The linear product gain is a first-order approximation; the recursive full-system response is the primary object (Definition 36). Proposition 4 separates the exact path expansion (with residual ) from the additive signed attribution and from the normalized shares , which are defined only under explicit nonzero-denominator conditions and are relative shares whenever .
- (A13)
- Prior aggregation and lifting. The claim-confidence aggregation functional , the conditional independence of edge–lag indicators underlying the factorized prior, the skeleton threshold , and the prior-lifting map from variables to median kernels are left unspecified (Definitions 7 and 12).
- (A14)
- Supplemental theory. The top-level weight tuple, perpetual condition, and CES aggregates of Definition 28 are recorded in adapted section-local notation and do not enter the operational constructions, which use the alternative weights of Definition 26.
- (A15)
- Extrapolation internals. The scenario measure , the trajectory-weighting likelihood for future-value conditioning, the time-decay weights , and the copula C of the SEV layer are left unspecified (Section 10).
- (A16)
- Reporting scale. The reporting score takes values in (Definition 34); the monotone map is versioned, and the endpoints carry interpretations.
Appendix B. Symbol Table
Symbols are globally consistent unless explicitly marked section-local; the main section-local families are (generic/fitted parameter vectors in Steps 1, 4, 7), (claim sign in Step 2; TD error in Step 7; perturbation magnitude in Step 8), (MoE gate weights in Step 1; shortfall exponent in Step 6; time-preference parameter in Definition 28), (mixture-factor residual in Step 1; claim confidence in Step 2), (scaling scalar in (gPB1); stepsize in Step 7), w (lifting coefficients in Step 3; acquisition weights in Step 5; wealth coordinate in Definition 28), and the full section-local notation sets of Definition 28. Section-local base-letter families also include M (observation mask globally; number of median kernels in Step 3), (edge set, association skeleton, or active-learning evidence set, disambiguated by indices/context), (harmonization map, hypothesis pool, or hub set), and (imputation-expert index set or knowledge set). The policy class is ; the LLM prior field is (renamed to avoid collision); penetration coefficients are ; the projection onto is .
| Meaning | ||
| Global index sets and panel | ||
| country/region, annual time, and indicator index sets | 1 | |
| variable/node set (original variables in Step 2; median kernels after lifting) | 4 | |
| context space; conditioning context at t | 1 | |
| literature corpus | 1 | |
| lag set | 4 | |
| raw indicator value; observation indicator in | 1 | |
| raw panel and observation mask | 1 | |
| set indicator (constants ) | 1 | |
| state space; action space | 2 | |
| planetary-health state; action/control | 2 | |
| admissible action set at s | 2 | |
| policy; admissible policy class | 2 | |
| controlled transition kernel; induced expectation | 2 | |
| Step 1: preprocessing and integration | ||
| per-indicator harmonization; normalization (training-partition fit) | 3 | |
| harmonized/normalized indicator | 3 | |
| imputation-expert index set | 3 | |
| MoE gate weight; expert-e imputation | 4 | |
| Bundle-T imputation; completed panel | 4 | |
| credibility weight | 5 | |
| credibility-weighted training loss | 5 | |
| per-indicator loss; generic (section-local) parameter vector | 5 | |
| held-out error profile; validation evidence at iteration r | 5 | |
| credibility update map (monotone in held-out error) | 5 | |
| stopping tolerances (loss, graph, prediction) | 5 | |
| graph distance | 16 | |
| full evidence universe; integration map | 6 | |
| query specification; problem-conditioned projection | 6 | |
| complementary mechanism subgraph; mixture-factor reduction map | 6 | |
| explicit sub-network; implicit mixture-factor residual | 6 | |
| Step 2: domain-tuned LLM prior | ||
| claim tuple : variables, sign (section-local ), lag, context, evidence, confidence | 7 | |
| extracted claim set; quasi-LLM parameter vector | 7 | |
| domain-tuned quasi-LLM claim-extraction map | 7 | |
| edge–lag indicator | 7 | |
| prior probability of edge at lag l under c (field renamed to avoid collision with the policy class ) | 7 | |
| claim-confidence aggregation functional; skeleton threshold | 7 | |
| association skeleton (topological prior) | 7 | |
| data evidence | 7 | |
| dynamic prior update map | 8 | |
| feedback (expert responses, validation outcomes) after t | 8 | |
| reverse-query operator into the hypothesis space | 8 | |
| Step 3: nIDE lifting and median kernels | ||
| harmonized indicator space; lifting dimension | 9 | |
| nIDE lifting map; r-th feature view | 9 | |
| directed source–target transform (asymmetric) | 9 | |
| view set of kernel m; number of median kernels | 11 | |
| view-set feature vector (vector, not scalar) | 11 | |
| median-kernel feature; coordinate-wise median of | 11 | |
| attribute-flow set of original indicators generating kernel m | 11 | |
| threshold levels in dictionary indicators (section-local) | 10 | |
| prior-lifting map; lifted kernel-level prior edge probability | 12 | |
| lifted kernel-level association skeleton | 12 | |
| lifted representation; lifted trajectory | 11 | |
| kernel naming pattern (level ℓ, identifier j) | 11 | |
| PSD kernel on view sets, only if separately verified | 11 | |
| w | coefficient vector in the universal-lifting statement | 2 |
| Step 4: SCGL conditional graph | ||
| conditional directed graph | 13 | |
| lag-l coefficient matrix; contemporaneous (DAG) matrix | 13 | |
| lifted-dynamics innovation | 13 | |
| adjacency indicator; parent set under c | 6 | |
| node partition; block b; number of blocks | 14 | |
| proxy/hub node set | 14 | |
| low-rank cross-block factorization; inner dimension | 14 | |
| graph objective; data-fit term | 15 | |
| sparsity; block-structure regularizer | 15 | |
| acyclicity; prior (lifted field ) regularizer | 15 | |
| expert-anchor regularizer | 15 | |
| regularization coefficients (sparsity, block, prior, expert, acyclicity) | 15 | |
| smooth acyclicity function (standard construction) | 15 | |
| reference graph for graph-distance evaluation | 16 | |
| Step 5: active-learning closure | ||
| candidate-hypothesis pool; single hypothesis | 7 | |
| acquisition utility | 18 | |
| acquisition components and their weights, (section-local w) | 18 | |
| data, adversarial-self, human-expert query channels | 18 | |
| expert Boolean response; posterior belief in H | 19 | |
| evidence set after iteration r | 19 | |
| local linear effects matrix; subfield submatrix | 17 | |
| subfield index set; Boolean proposition; expert modification | 17 | |
| Boolean-question decomposition maps; query index set | 17 | |
| anchor set; candidate-pool regeneration map | 19 | |
| data-, literature/model-, expert-supported knowledge sets | 20 | |
| tripartite consensus knowledge set | 20 | |
| hypothesis-set metric; convergence tolerance | 20 | |
| composed HITL update (fixed-point view) | 7 | |
| Step 6: non-discounted control | ||
| single-period welfare/utility | 21 | |
| exogenous scenario realization | 8 | |
| long-run average gain of policy | 21 | |
| constrained optimal gain (always the meaning of ); unconstrained optimal gain (disambiguation only) | 23 | |
| current (evaluation) policy; its long-run gain | 25 | |
| discount factor; discounted-optimal policy (contrast only) | 8 | |
| g-PB constraint index set | 23 | |
| boundary-shortfall risk gauge ; boundary level; shortfall exponent | 22 | |
| risk budget (0 = hard boundary) | 23 | |
| state–action gauge; state-level gauge at the explicit policy (Definition 33) | 22 | |
| scaling scalar in desideratum (gPB1) (section-local) | 22 | |
| g-PB-feasible action set; feasible policy class | 23 | |
| relative value function; normalization reference state | 3 | |
| one-period Lagrangian (under the stated constraint qualification) | 24 | |
| relint | relative interior (constraint qualification) | 24 |
| shadow price of boundary r; envelope relation where differentiable | 24 | |
| occupation measures; barycenter (or distinguished mode) of the optimal stationary law | 25 | |
| nondecreasing surrogate map from state distance to utility gap | 25 | |
| utility (dual) gap , a difference of long-run gains | 25 | |
| weighted state-to-optimum distance; component distance | 25 | |
| preference parameter; raw sensitivity; normalized top-level weight (alternative to the weight tuple) | 26 | |
| positive part; nonnegative penetration coefficient | 26 | |
| nonrenewable-boundary consumption; current/future technology savings (equality form; operational relaxation ≤) | 27 | |
| top-level-weight preference intensities; implicit nonrenewable price (section-local notation) | 28 | |
| time-preference parameter; scale constant (section-local, renamed from , a) | 28 | |
| perpetual-condition accumulation coefficients (section-local notation) | 28 | |
| health/wealth/education coordinates (section-local notation) | 28 | |
| CES planetary-health index; production aggregate (section-local notation, adapted) | 28 | |
| CES simplex weights (production weights renamed from ; section-local) | 28 | |
| CES parameters, health dimensions and technology outputs (section-local) | 28 | |
| Step 7: numerical implementation and evaluation | ||
| Bellman operator; iterates of relative value and gain | 29 | |
| transition operator; expected reward under | 30 | |
| fitted value representation on the lifted basis | 31 | |
| projection onto ; gain estimate | 31 | |
| TD error (section-local ); stepsize | 31 | |
| span functional | 32 | |
| Bellman/span/gain/constraint tolerances; policy distance | 32 | |
| constraint-restoration map | 30 | |
| boundary risk-budget slack under | 33 | |
| multi-boundary slack profile | 33 | |
| Safe Operating Space distance reading of the slack profile | 33 | |
| boundary-violation set; first-passage time | 33 | |
| bounded reporting score in ; fixed monotone map | 34 | |
| Step 8: paths, fluxes, extrapolation | ||
| path/forecast horizon | 35 | |
| time-unrolled DAG over | 35 | |
| directed path of length | 35 | |
| full admissible source-to-target path set | 35 | |
| source-perturbation magnitude (section-local ); unit vector at node x | 36 | |
| coefficient of edge e in | 36 | |
| full-system source-to-target response | 36 | |
| raw (local linear) path gain; truncation/linearization residual of the path expansion (Proposition 4) | 36 | |
| additive signed attribution ; total raw gain | 4 | |
| normalized flux share (only when ); absolute-share signed variant (only when ) | 4 | |
| information filtration | 37 | |
| scenario/policy measure | 37 | |
| exogenous-policy intervention operator | 38 | |
| co-evolving conditional graph and dynamic prior along a simulation | 38 | |
| prescribed future values; normalized trajectory weight | 38 | |
| simplex portfolio weights | 39 | |
| portfolio policy; component policy | 39 | |
| time-decay loss; horizon weights | 39 | |
| submodel parameter; submodel prior (both section-local) | 10 | |
| copula; joint severity–exposure–vulnerability law | 10 | |
References
- Rockström, J.; Steffen, W.; Noone, K.; Persson, Å.; Chapin, F.S.; Lambin, E.F.; Lenton, T.M.; Scheffer, M.; Folke, C.; Schellnhuber, H.J.; et al. A safe operating space for humanity. Nature 2009, 461, 472–475. [Google Scholar] [CrossRef] [PubMed]
- Steffen, W.; Richardson, K.; Rockström, J.; Cornell, S.E.; Fetzer, I.; Bennett, E.M.; Biggs, R.; Carpenter, S.R.; de Vries, W.; de Wit, C.A.; et al. Planetary boundaries: Guiding human development on a changing planet. Science 2015, 347, 1259855. [Google Scholar] [CrossRef] [PubMed]
- Richardson, K.; Steffen, W.; Lucht, W.; Bendtsen, J.; Cornell, S.E.; Donges, J.F.; Drüke, M.; Fetzer, I.; Bala, G.; von Bloh, W.; et al. Earth beyond six of nine planetary boundaries. Sci. Adv. 2023, 9, eadh2458. [Google Scholar] [CrossRef] [PubMed]
- Lade, S.J.; Steffen, W.; de Vries, W.; Carpenter, S.R.; Donges, J.F.; Gerten, D.; Hoff, H.; Newbold, T.; Richardson, K.; Rockström, J. Human impacts on planetary boundaries amplified by Earth system interactions. Nat. Sustain. 2020, 3, 119–128. [Google Scholar] [CrossRef]
- Whitmee, S.; Haines, A.; Beyrer, C.; Boltz, F.; Capon, A.G.; de Souza Dias, B.F.; Ezeh, A.; Frumkin, H.; Gong, P.; Head, P.; et al. Safeguarding human health in the Anthropocene epoch: Report of The Rockefeller Foundation–Lancet Commission on planetary health. The Lancet 2015, 386, 1973–2028. [Google Scholar] [CrossRef] [PubMed]
- Myers, S.S. Planetary health: Protecting human health on a rapidly changing planet. The Lancet 2017, 390, 2860–2868. [Google Scholar] [CrossRef] [PubMed]
- Rockström, J.; Gupta, J.; Qin, D.; Lade, S.J.; Abrams, J.F.; Andersen, L.S.; Armstrong McKay, D.I.; Bai, X.; Bala, G.; Bunn, S.E.; et al. Safe and just Earth system boundaries. Nature 2023, 619, 102–111. [Google Scholar] [CrossRef] [PubMed]
- O’Neill, D.W.; Fanning, A.L.; Lamb, W.F.; Steinberger, J.K. A good life for all within planetary boundaries. Nat. Sustain. 2018, 1, 88–95. [Google Scholar] [CrossRef]
- United Nations Development Programme. Human Development Report 2020: The Next Frontier—Human Development and the Anthropocene; United Nations Development Programme: New York, 2020. [Google Scholar]
- Soergel, B.; Kriegler, E.; Weindl, I.; Rauner, S.; Dirnaichner, A.; Ruhe, C.; Hofmann, M.; Bauer, N.; Bertram, C.; Bodirsky, B.L.; et al. A sustainable development pathway for climate action within the UN 2030 Agenda. Nat. Clim. Change 2021, 11, 656–664. [Google Scholar] [CrossRef]
- Soergel, B.; Rauner, S.; Daioglou, V.; Weindl, I.; Mastrucci, A.; Carrer, F.; Kikstra, J.S.; Ambrósio, G.; Aguiar, A.P.D.; Baumstark, L.; et al. Multiple pathways towards sustainable development goals and climate targets. Environ. Res. Lett. 2024, 19, 124009. [Google Scholar] [CrossRef]
- Beier, F.D.; Dietrich, J.P.; Heinke, J.; Abrahão, G.M.; von Jeetze, P.; Bodirsky, B.L.; Crawford, M.; Humpenöder, F.; Merfort, L.; Weindl, I.; et al. Planetary boundaries under a land-based climate change mitigation scenario with a food demand transformation: A modelling study. Lancet Planet. Health 2025, 9, 101249. [Google Scholar] [CrossRef] [PubMed]
- Stern, N. The Economics of Climate Change: The Stern Review; Cambridge University Press: Cambridge, 2007. [Google Scholar]
- Wang, H.; Fu, T.; Du, Y.; Gao, W.; Huang, K.; Liu, Z.; Chandak, P.; Liu, S.; Van Katwyk, P.; Deac, A.; et al. Scientific discovery in the age of artificial intelligence. Nature 2023, 620, 47–60. [Google Scholar] [CrossRef] [PubMed]
- Rolnick, D.; Donti, P.L.; Kaack, L.H.; Kochanski, K.; Lacoste, A.; Sankaran, K.; Ross, A.S.; Milojevic-Dupont, N.; Jaques, N.; Waldman-Brown, A.; et al. Tackling climate change with machine learning. ACM Comput. Surv. 2022, 55, 1–96. [Google Scholar] [CrossRef]
- Reichstein, M.; Camps-Valls, G.; Stevens, B.; Jung, M.; Denzler, J.; Carvalhais, N.; Prabhat. Deep learning and process understanding for data-driven Earth system science. Nature 2019, 566, 195–204. [Google Scholar] [CrossRef]
- Vaswani, A.; Shazeer, N.; Parmar, N.; Uszkoreit, J.; Jones, L.; Gomez, A.N.; Kaiser; Polosukhin, I. Attention is all you need. In Proceedings of the Advances in Neural Information Processing Systems 30 (NeurIPS 2017), 2017; pp. 5998–6008. [Google Scholar]
- Brown, T.B.; Mann, B.; Ryder, N.; Subbiah, M.; Kaplan, J.; Dhariwal, P.; Neelakantan, A.; Shyam, P.; Sastry, G.; Askell, A.; et al. Language models are few-shot learners. In Proceedings of the Advances in Neural Information Processing Systems 33 (NeurIPS 2020), 2020; pp. 1877–1901. [Google Scholar]
- Ouyang, L.; Wu, J.; Jiang, X.; Almeida, D.; Wainwright, C.L.; Mishkin, P.; Zhang, C.; Agarwal, S.; Slama, K.; Ray, A.; et al. Training language models to follow instructions with human feedback. In Proceedings of the Advances in Neural Information Processing Systems 35 (NeurIPS 2022), 2022; pp. 27730–27744. [Google Scholar]
- Kickbusch, I.; Piselli, D.; Agrawal, A.; Balicer, R.; Banner, O.; Adelhardt, M.; et al. The Lancet and Financial Times Commission on governing health futures 2030: Growing up in a digital world. The Lancet 2021, 398, 1727–1776. [Google Scholar] [CrossRef] [PubMed]
- Wilkinson, M.D.; Dumontier, M.; Aalbersberg, I.J.; Appleton, G.; Axton, M.; Baak, A.; Blomberg, N.; Boiten, J.W.; da Silva Santos, L.B.; Bourne, P.E.; et al. The FAIR Guiding Principles for scientific data management and stewardship. Sci. Data 2016, 3, 160018. [Google Scholar] [CrossRef] [PubMed]
- Chen, E.; et al. AI for science: Decoding complexity for planetary health. The Lancet 2026, 408, 599–600. [Google Scholar] [CrossRef] [PubMed]
- Little, R.J.A.; Rubin, D.B. Statistical Analysis with Missing Data, 2 ed.; John Wiley & Sons: Hoboken, NJ, 2002. [Google Scholar]
- Jacobs, R.A.; Jordan, M.I.; Nowlan, S.J.; Hinton, G.E. Adaptive mixtures of local experts. Neural Comput. 1991, 3, 79–87. [Google Scholar] [CrossRef] [PubMed]
- Pearl, J. Causality: Models, Reasoning, and Inference, 2 ed.; Cambridge University Press: Cambridge, 2009. [Google Scholar]
- Spirtes, P.; Glymour, C.; Scheines, R. Causation, Prediction, and Search, 2 ed.; MIT Press: Cambridge, MA, 2000. [Google Scholar]
- Zheng, X.; Aragam, B.; Ravikumar, P.; Xing, E.P. DAGs with NO TEARS: Continuous optimization for structure learning. In Proceedings of the Advances in Neural Information Processing Systems 31 (NeurIPS 2018), 2018; pp. 9472–9483. [Google Scholar]
- Yuan, M.; Lin, Y. Model selection and estimation in regression with grouped variables. J. R. Stat. Soc. Ser. B (Statistical Methodology) 2006, 68, 49–67. [Google Scholar] [CrossRef]
- Schölkopf, B.; Smola, A.J. Learning with Kernels: Support Vector Machines, Regularization, Optimization, and Beyond; MIT Press: Cambridge, MA, 2002. [Google Scholar]
- Settles, B. Active Learning Literature Survey. Technical Report 1648; Department of Computer Sciences, University of Wisconsin–Madison, 2009.
- Puterman, M.L. Markov Decision Processes: Discrete Stochastic Dynamic Programming; John Wiley & Sons: New York, 1994. [Google Scholar]
- Altman, E. Constrained Markov Decision Processes; Chapman and Hall/CRC: Boca Raton, FL, 1999. [Google Scholar]
- Sutton, R.S.; Barto, A.G. Reinforcement Learning: An Introduction, 2 ed.; MIT Press: Cambridge, MA, 2018. [Google Scholar]
- Kuhn, H.W.; Tucker, A.W. Nonlinear programming. In Proceedings of the Proceedings of the Second Berkeley Symposium on Mathematical Statistics and Probability, Berkeley, CA, 1951; pp. 481–492. [Google Scholar]
- Artzner, P.; Delbaen, F.; Eber, J.M.; Heath, D. Coherent measures of risk. Math. Financ. 1999, 9, 203–228. [Google Scholar] [CrossRef]
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (http://creativecommons.org/licenses/by/4.0/).
Copyright: This open access article is published under a Creative Commons CC BY 4.0 license, which permit the free download, distribution, and reuse, provided that the author and preprint are cited in any reuse.