

Submitted:
16 September 2026
Posted:
17 September 2026
You are already at the latest version
Abstract
Plant pangenomics has rapidly changed the way genetic diversity is represented and studied. During the last three years, advances in long-read sequencing, chromosome-scale genome assembly, structural-variant discovery, graph genomes, haplotype-resolved assemblies and super-pangenomes have demonstrated that a single reference genome is insufficient to describe the genetic diversity of crop species. Today the current challenges in plant pangenomics is the transformation of the pangenomics based information into gleanable resources, which could be biologically interpreted and useful for plant improvement. Pangenomics has been predominantly descriptive "catalogue of variation" paradigm and transformed toward a functional and predictive pangenomics framework integrating structural variation, regulatory sequences, transcriptomics, epigenomics, phenomics and artificial intelligence. This transition is particularly important for complex and polyploid crops, where conventional reference-based approaches remain inadequate. Super-pangenomes that incorporate wild relatives provide an important opportunity to recover genetic diversity lost during domestication. To achieve, pangenomes and super-pangenomes, computational scalability, functional validation, standardization and equitable access remain major challenges. In this paper, we present computational approaches to the pangenomics and introduce computational end to end scalabale pangenomic workflow and panscape, which serves a single standalone tool for all pangenomic needs.
Keywords:
plant pangenomics
; graph genome
; structural variation
; crop improvement
; super-pangenome
; structural variants
; precision breeding
; multi-omics
; genomic selection
1. Introduction
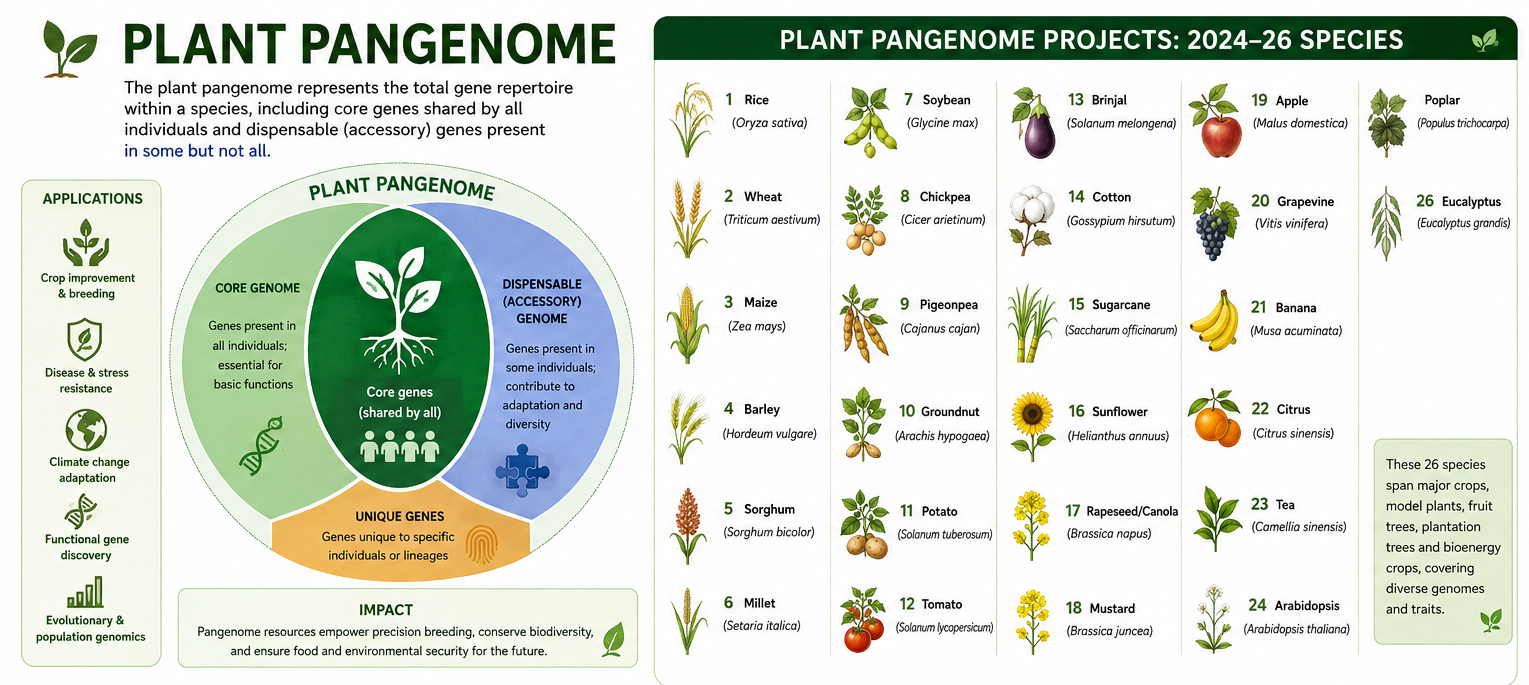
For decades, plant genomics has been organized around a simple concept: identify a representative reference genome and map genetic variation against it. This strategy has generated enormous advances in plant biology and crop improvement. However, the assumption that one genome can adequately represent a species is increasingly difficult to defend owing to the diversity across plant genomes. Variation extends far beyond single-nucleotide polymorphisms (SNPs) to include insertions, deletions, duplication's, inversions, copy-number changes, transposable elements, presence/absence variation and highly divergent haplotypes (Cochetel et al. 2026). Some of these variants can involve genes or regulatory regions that are completely absent from the commonly used reference genome. Thus, pangenome quality should be evaluated using multiple criteria, including genetic diversity, assembly quality, functional annotation, and phenotype integration, rather than genome number alone (Kaur et al. 2024).. Plant pangenomics emerged as a response to this limitation. Rather than representing a species by one genome, a pangenome attempts to capture genomic diversity across multiple individuals. Plant pangenomics has become an essential framework for capturing genetic diversity beyond a single reference genome, including presence–absence variation (PAV), structural variation (SV), copy-number variation, repetitive sequences, and divergent genomic regions. Advances in long-read sequencing and chromosome-scale assembly have enabled high-quality pangenomes and increasingly sophisticated graph-based representations, supporting studies of adaptation, domestication, disease resistance, and agronomic traits (Kaur et al. 2024, Cochetel et al. 2026) (Figure 1, 2). Recent developments in long-read sequencing and genome assembly have made it possible to construct increasingly complete and haplotype-resolved genome resources. Graph-based approaches have further expanded this concept by allowing alternative genomic sequences to be represented within a unified structure. Current approaches include reference-guided graph construction using Minigraph and Minigraph-Cactus (Hickey et al. 2024), and reference-unbiased construction using PGGB. Minigraph is computationally efficient and well suited for large-scale detection of structural and presence–absence variation, but its reference dependence can introduce bias and its original implementation has limited resolution for small variants. Minigraph-Cactus combines efficient structural-variant graph construction with base-level whole-genome alignment, enabling representation of SNPs, small indels, and large SVs and therefore providing a strong balance between resolution and scalability. PGGB (Garrison et al. 2024), based on all-versus-all whole-genome alignment, minimizes reference bias and is particularly valuable for highly divergent genomes, although it requires substantially greater computational and memory resources. Downstream tools such as VG (Garrison et al. 2018) and ODGI (Guarracino et al. 2022) support graph analysis, while SyRI (Goel et al. 2019) and SVIM-asm (Heller and Vingron 2020) can provide independent SV detection and validation. Overall, plant pangenomics is shifting from genomic cataloguing toward pangenome-assisted breeding, enabling discovery and deployment of favourable alleles and haplotypes through integration with transcriptomic, phenotypic, and other multi-omics data. Major challenges remain for large, repetitive, heterozygous, and polyploid genomes, particularly in graph scalability, standardization, storage, and reproducible analysis.

Table 1.
Comparative analysis of pangenome software and panscape.
| Feature | panscape | PGGB | Minigraph-Cactus | Minigraph | Panaroo |
| Primary purpose | Integrated pangenomic workflow | Reference-free pangenome graph construction | Pangenome graph construction | Fast pangenome graph construction | Gene-centric bacterial pangenomics |
| Language / implementation | Rust | Pipeline integrating multiple tools | Cactus + Minigraph ecosystem | C/C++-based tool | Python |
| Raw FASTQ/FASTA processing | Yes | Limited; mainly sequence preparation | Not primary focus | Not primary focus | Primarily assembled genomes/annotations |
| Motif searching | Yes | No | No | No | No |
| Read filtering/clipping | Yes | No | No | No | No |
| PAF analysis | Yes | Uses PAF internally | Yes, through components | Yes | Not its main focus |
| GFA graph analysis | Yes | Core function | Core function | Core function | GML-based gene graph |
| Genome annotation | Yes | Limited/downstream | Limited/downstream | Limited | Core function |
| VCF analysis | Yes | Yes, through vg-related workflow | Yes | Yes/downstream | Not primary |
| Ancestral-state analysis | Yes | Not a primary feature | Not a primary feature | Not a primary feature | Limited |
| Read database | Yes | No | No | No | No |
| Integrated single executable | Yes | No; multiple components | No; multiple components | More focused | Primarily pipeline/software |
| Main strength | Breadth and integration | High-quality reference-free graphs | Complex, scalable genome graphs | Computational efficiency | Gene presence/absence and bacterial genomes |
2. Pangenomics Software: State of Art of Pangenome Detection Algorithms
Pangenomics aims to characterize the entire set of genes and sequence variations within a species or population, moving beyond the limitations of single reference genomes which often suffer from reference bias (Bao and Weigel 2025). The field has seen a rapid expansion of software tools designed to handle the increasing volume of high-quality assemblies and long-read sequencing data (Bao and Weigel 2025, Andreace et al. 2023). Graph-based pangenomes, which represent genomic variation as nodes and edges, have become the primary focus of development, allowing for more accurate mapping and variant calling, particularly for structural variants (Hickey et al. 2019, Eizenga et al. 2020).
Pangenome software has been well established from graph construction to remapping and downstream analysis. Graph pangenomes represent an important technological development because they provide a framework for representing alternative genomic sequences. Unlike a linear reference, a graph can contain multiple allelic paths and divergent genomic regions. This makes graph-based approaches particularly attractive for species with substantial structural variation. Among graph construction, variation graphs, de Bruijn graphs and genome-graph frameworks have been widely exploited for pangenome construction. The VG toolkit is a versatile framework for constructing variation graphs from VCF files or assembly alignments (Hickey et al. 2019). Alognside, Minigraph utilizes approximate mapping to a backbone genome to add large structural variants (>50 bp) (Bao and Weigel 2025, Andreace et al. 2023). Minigraph-Cactus (Hickey et al. 2024) and PGGB (Pangenome Graph Builder) employ base-level alignments to create more comprehensive representations that include small variants and precise breakpoints (Bao and Weigel 2025, Andreace et al. 2023, Crysnanto et al. 2022). The VG toolkit demonstrated strong SV-genotyping performance across several benchmarks and outperformed several conventional SV genotypers in many evaluated datasets, although performance relative to other graph-based methods such as Paragraph was dataset-dependent (Hickey et al. 2020). Minigraph-Cactus combines Minigraph's computationally efficient structural-variant skeleton with Cactus-based base-level alignment, enabling the representation of SNPs, small indels, and larger structural variants within a unified graph. Although Minigraph-Cactus can resolve certain complex and nested structural variants in plant genomes, highly repetitive regions such as satellite arrays, centromeres, and telomeres remain challenging for the approach (Hickey et al. 2024). Recent plant studies nevertheless demonstrate its utility for resolving specific complex transposable-element-associated structural variants.This TE-aware handling matters a lot for crops like sorghum, where repeat content constitutes roughly 61% of the genome and significantly influences structural variant landscapes.(Figure 2). Tools like Bifrost and Cuttlefish focus on constructing compacted and colored DBGs, which are highly efficient for storage and querying of large genomic datasets (Outten and Wareen 2021, Andreace et al. 2023). mdbg uses minimizer-space DBGs to achieve extremely fast construction and low memory usage, though it may discard small variants (Andreace et al. 2023). pangene identifies gene-level variations like orientation and copy-number changes by constructing gene graphs from protein sequences (Li et al. 2024).
One of the strongest arguments for pangenomics is that biologically important variation is not restricted to SNPs. Structural variants can alter gene dosage, gene structure, regulatory regions and genome organization. Presence/absence variation can also determine whether an individual carries entire genes or genomic regions that are missing from another genotype. Despite this importance, many conventional breeding pipelines remain strongly SNP-centric. In our view, this represents a major mismatch between the complexity of plant genomes and the tools routinely used for crop improvement.Efficiently mapping reads to a pangenome graph and calling variants are critical tasks for population genomics. VG Giraffe is a state-of-the-art mapper for human-scale pangenomes, achieving speeds comparable to linear mappers while improving variant calling (Chang et al. 2025). GraphAligner (Rautiainen and Marschall (2020)) excels in long-read sequence-to-graph alignment using a minimizer-based seeding strategy (Chang et al.2025, Outten and Warren 2021). HISAT2 employs a Hierarchical Graph FM index for graph-based alignment of sequencing reads (Kim et al. 2019). Comparative benchmarking has also evaluated HISAT2 alongside VG and other graph-based mappers (Grytten et al. 2020). PanGenie (Elber et al. 2022) and KAGE (Grytten et al. 2022) utilize k-mer comparisons to haplotypes for rapid genotyping with reduced bias (Mun et al., 2023, Singh et al. 2022). rowbowt introduces a marker array approach that is faster and less memory-intensive than previous methods like BayesTyper (Crysnanto et al. 2022). GraphTyper realigns reads to variation subgraphs for population-scale genotyping(Eggertsson et al. 2017). Annotation of the pangenome holds the key for the functional importance of the pangenomes and to eluciddate the functional convergence and divergence of the pangenome. Tools such as ggCaller integrates gene prediction and pangenome clustering using DBGs, offering a ~50x speed increase over traditional workflows like Prokka/Roary (Horsfield et al. 2023). GrAnnoT and PPanG are specialized for annotation transfer and nucleotide-level visualization of genomic variations within graph-based browsers (Marthe et al. 2025, Liu et al., 2024).
Comparative studies reveal significant trade-offs between speed, memory, and graph complexity. mdbg is reported as the fastest construction tool with the lowest memory footprint, followed by Bifrost (Andreace et al. 2023). In contrast, PGGB and Minigraph-Cactus are more computationally demanding; PGGB has been noted to fail on very large datasets due to high resource requirements (Andreace et al. 2023). vg Giraffe is over an order of magnitude faster than GraphAligner for long reads (Chang et al. 2025). rowbowt consistently outperforms PanGenie and BayesTyper in terms of speed and memory efficiency (Crysnanto et al. 2022). Tools such as ggCaller integrate gene prediction and pangenome clustering using de Bruijn graphs. In benchmarks against a Prokka + Panaroo workflow, ggCaller substantially reduced runtime, although the magnitude of the speed-up depended on dataset size and population diversity (Horsfield et al. 2023).
The next major limitation is functional interpretation. Identifying a genomic sequence is not equivalent to understanding its biological function. The growing number of novel genes, structural variants and regulatory regions identified through pangenomics creates a new problem: functional annotation is becoming a bottleneck.This suggests that the future of pangenomics should involve integration with multiple layers of biological information.Graph-based methods can improve mapping accuracy and variant detection for genomic regions containing substantial sequence diversity, particularly for complex structural variants, although performance depends on graph construction, graph complexity, sequencing technology, and the downstream analysis method. The VG toolkit demonstrates superior SV genotyping accuracy compared to tools like SVTyper and Paragraph (Hickey et al. 2019). Minigraph-Cactus and PGGB can capture substantially more small variation than Minigraph's approximate-mapping approach; Crysnanto et al. (2022) reported approximately 40% more small variations in base-level-alignment graphs. Consistent with this observation, Leonard et al. (2023) found that PGGB and Cactus accurately represented assembly-derived small variants in a bovine super-pangenome. vg shows higher sensitivity for short-read mapping on reads containing variants compared to HISAT2 and linear mappers (Grytten et al. 2019, Outten and Warren 2021).
In this opinion, plant pangenomics is now approaching an important turning point. The central question should no longer be simply "How can we construct a larger pangenome?" Instead, it should be "How can we convert pangenomic diversity into biological knowledge and breeding value?" Artificial intelligence (AI) and machine learning are increasingly being incorporated into genomic prediction and biological interpretation. Pangenomes provide potentially valuable input data for these approaches because they capture a broader range of genetic variation. AI could help prioritize candidate variants, predict functional consequences, identify genotype–phenotype relationships and improve genomic selection models (Kaur et al. 2024). Nevertheless, we argue against treating AI as a solution to the fundamental challenges of pangenomics.
Artificial intelligence and machine learning may further support variant prioritization, functional prediction, genotype–phenotype modeling, and genomic selection, but their effectiveness will depend on high-quality, representative genomic and phenotypic datasets and should complement rather than replace biological validation. Major challenges remain, particularly the computational complexity of large, repetitive, and polyploid plant genomes, graph scalability, functional validation of novel genes and SVs, inconsistent assembly and annotation pipelines, and the lack of standardized approaches for pangenome construction, variant representation, nomenclature, and phenotype metadata. Thus, pangenome quality should be evaluated not solely by the number of genomes included, but also by sampling breadth, assembly completeness, representation of genomic variation, annotation quality, and the extent to which the resource supports downstream functional and phenotypic analyses (Loegler et al. 2026; Heuermann et al. 2026). Ultimately, the next generation of plant pangenomics should establish a pan-genome-to-phenome infrastructure that connects diverse germplasm and haplotype-resolved genomes to graph-based variation, multi-omics, phenotyping, causal variant discovery, genomic prediction, genome editing, and precision breeding, transforming the pangenome from a catalogue of genomic diversity into a predictive biological and breeding platform.
References
- Bao, Z.; Weigel, D. Complexity welcome: Pangenome graphs for comprehensive population genomics. Quant Plant Biol 2025, 1–34. [Google Scholar] [CrossRef]
- Kaur, H.; Shannon, L.M.; Samac, D.A. A stepwise guide for pangenome development in crop plants: An alfalfa (Medicago sativa) case study. BMC Genomics 2024, 25, 1. [Google Scholar] [CrossRef]
- Outten, J.; Warren, A.S. Methods and developments in graphical pangenomics. J Indian Inst Sci 2021, 101, 1–14. [Google Scholar] [CrossRef] [PubMed]
- Tonkin-Hill, G.; MacAlasdair, N.; Ruis, C.; Weimann, A.; Horesh, G.; Lees, J.A.; Gladstone, R.A.; Lo, S.; Beaudoin, C.; Floto, R.A.; Frost, S.D.W.; Corander, J.; Bentley, S.D.; Parkhill, J. Producing polished prokaryotic pangenomes with the Panaroo pipeline. Genome Biol 2020, 21, 180. [Google Scholar] [CrossRef] [PubMed]
- Ebler, J.; Ebert, P.; Clarke, W. E. Pangenome-based genome inference allows efficient and accurate genotyping across a wide spectrum of variant classes. Nature Genetics 2022, 54, 518–525. [Google Scholar] [CrossRef] [PubMed]
- Cochetel, N. From structural pangenomes to functional panomics in plants. Mol Biol Evol 2026, 43. [Google Scholar] [CrossRef] [PubMed]
- Hickey, G.; Monlong, J.; Ebler, J.; Novak, A.M.; Eizenga, J.M.; Gao, Y.; Human Pangenome Reference Consortium; Marschall, T.; Li, H.; Paten, B. Pangenome graph construction from genome alignments with Minigraph-Cactus. Nat Biotechnol 2024, 42, 663–673. [Google Scholar] [CrossRef] [PubMed]
- Heller, D.; Vingron, M. SVIM-asm: structural variant detection from haploid and diploid genome assemblies. Bioinformatics 2020, 36, 5519–5521. [Google Scholar] [CrossRef] [PubMed]
- Garrison, E.; Guarracino, A.; Heumos, S.; Villani, F.; Bao, Z.; Tattini, L.; Hagmann, J.; Vorbrugg, S.; Marco-Sola, S.; Kubica, C.; Ashbrook, D.G.; Thorell, K.; Rusholme-Pilcher, R.L.; Liti, G.; Rudbeck, E.; Nahnsen, S.; Yang, Z.; Moses, M.N.; Nobrega, F.L.; Wu, Y.; Chen, H.; de Ligt, J.; Sudmant, P.H.; Prins, P. Building pangenome graphs. Nat Methods 2024, 21, 2008–2012. [Google Scholar] [CrossRef] [PubMed]
- Garrison, E.; Sirén, J.; Novak, A.M.; Hickey, G.; Eizenga, J.M.; Dawson, E.T.; Jones, W.; Garg, S.; Markello, C.; Lin, M.F.; Paten, B.; Durbin, R. Variation graph toolkit improves read mapping by representing genetic variation in the reference. Nat Biotechnol 2018, 36, 875–879. [Google Scholar] [CrossRef] [PubMed]
- Goel, M.; Sun, H.; Jiao, W.B.; Schneeberger, K. SyRI: finding genomic rearrangements and local sequence differences from whole-genome assemblies. Genome Biol 2019, 20, 277. [Google Scholar] [CrossRef]
- Guarracino, A.; Heumos, S.; Nahnsen, S.; Prins, P.; Garrison, E. ODGI: understanding pangenome graphs. Bioinformatics 2022, 38, 3319–3326. [Google Scholar] [CrossRef] [PubMed]
- Grytten, I.; Dagestad Rand, K.; Sandve, G.K. KAGE: fast alignment-free graph-based genotyping of SNPs and short indels. Genome Biology 2022, 23, 209. [Google Scholar] [CrossRef]
- Horsfield, S.T.; Tonkin-Hill, G.; Croucher, N.J.; Lees, J.A. Accurate and fast graph-based pangenome annotation and clustering with ggCaller. Genome Research 2023, 33, 1622–1637. [Google Scholar] [CrossRef] [PubMed]
- Hickey, G. Genotyping structural variants in pangenome graphs using the vg toolkit. bioRxiv 2019, 654566. [Google Scholar] [CrossRef]
- Mun, T.; Vaddadi, N.; Langmead, B. Pangenomic genotyping with the marker array. Algorithms Mol Biol 2023, 18, 1. [Google Scholar] [CrossRef] [PubMed]
- Crysnanto, D.; Leonard, A.; Pausch, H. Comparison of methods for building pangenome graphs; Proceedings/Conference publication, 2022; p. 252. [Google Scholar] [CrossRef] [PubMed]
- Andreace, F.; Lechat, P.; Dufresne, Y.; Chikhi, R. Construction and representation of human pangenome graphs. bioRxiv 2023. [Google Scholar] [CrossRef]
- Chang, X. Rapid, accurate long- and short-read mapping to large pangenome graphs with vg Giraffe. bioRxiv 2025. [Google Scholar] [CrossRef] [PubMed]
- Leonard, A.S.; Crysnanto, D.; Mapel, X.M.; Bhati, M.; Pausch, H. Graph construction method impacts variation representation and analyses in a bovine super-pangenome. Genome Biol 2023, 24, 1. [Google Scholar] [CrossRef] [PubMed]
- Kim, D.; Paggi, J.M.; Park, C. Graph-based genome alignment and genotyping with HISAT2 and HISAT-genotype. Nature Biotechnology 2019, 37, 907–915. [Google Scholar] [CrossRef] [PubMed]
- Eizenga, J.M. Pangenome graphs. Annu Rev Genomics Hum Genet 2020. [Google Scholar] [CrossRef] [PubMed]
- Grytten, I.; Rand, K.D.; Nederbragt, A.J.; Sandve, G.K. Assessing graph-based read mappers against a baseline approach highlights strengths and weaknesses of current methods. BMC Genomics 2020, 21, 282. [Google Scholar] [CrossRef] [PubMed]
- Jayakodi, M.; Schreiber, M.; Stein, N.; Mascher, M. Building pan-genome infrastructures for crop plants and their use in association genetics. DNA Res 2021, 28, 1. [Google Scholar] [CrossRef] [PubMed]
- Singh, V.; Pandey, S.; Bhardwaj, A. From the reference human genome to human pangenome: Premise, promise and challenge. Front Genet 2022, 13. [Google Scholar] [CrossRef] [PubMed]
- Nyaga, D.M.; Zaied, R.E.; Silander, O.; Black, M.A.; O’Sullivan, J.M. Beyond single references: Pangenome graphs and the future of genomic medicine. Front Genet 2025, 16. [Google Scholar] [CrossRef] [PubMed]
- Li, H.; Marin, M.; Farhat, M.R. Exploring gene content with pangene graphs. arXiv 2024. [Google Scholar] [CrossRef]
- Eggertsson, H.P. Graphtyper enables population-scale genotyping using pangenome graphs. Nat Genet 2017, 49, 1654–1660. [Google Scholar] [CrossRef] [PubMed]
- Liu, M. PPanG: A precision pangenome browser enabling nucleotide-level analysis of genomic variations in individual genomes and their graph-based pangenome. BMC Genomics 2024, 25. [Google Scholar] [CrossRef] [PubMed]
- Marthe, N.; Zytnicki, M.; Sabot, F. GrAnnoT, a tool for efficient and reliable annotation transfer through pangenome graph. bioRxiv 2025. [Google Scholar] [CrossRef]
- Rautiainen, M.; Marschall, T. GraphAligner: rapid and versatile sequence-to-graph alignment. Genome Biology 2020, 21, 253. [Google Scholar] [CrossRef] [PubMed]
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (http://creativecommons.org/licenses/by/4.0/).
Copyright: This open access article is published under a Creative Commons CC BY 4.0 license, which permit the free download, distribution, and reuse, provided that the author and preprint are cited in any reuse.