

Submitted:
18 August 2026
Posted:
19 August 2026
You are already at the latest version
Abstract
Remote electroencephalography (EEG) systems require compact representations robust to communication noise. We evaluated whether task-oriented residual refinement of filter bank common spatial pattern (FBCSP) features compressed by principal component analysis (PCA) improves four-class motor imagery (MI) decoding without increasing the transmitted dimension. BNCI2014-001 was assessed in nine subjects using bidirectional subject-specific cross-session evaluation. The methods transmitted K∈{16,32,64} real values through additive white Gaussian noise (AWGN) at seven signal-to-noise ratios (SNRs) and a noise-free reference; a classifier-only control was evaluated at K=32. Balanced accuracy was averaged over 20 paired noise realizations per noisy condition. At K=32, the proposed method achieved 41.10%, 49.46%, and 56.15% at −10, −5, and 0 dB, compared with 38.63%, 46.28%, and 53.26% for conventional FBCSP–PCA transmission. Eight of the 24 primary comparisons remained significant after Holm correction, all at −10, −5, or 0 dB. The classifier-only control closely matched the conventional system, whereas the reconstruction-oriented representation remained near chance. Overall, baseline-preserving task-oriented refinement improved MI decision robustness under severe AWGN without increasing the number of transmitted values.
Keywords:
electroencephalography
; brain–computer interface
; motor imagery
; semantic communication
; task-oriented communication
; filter bank common spatial pattern
; additive white Gaussian noise
; remote classification
1. Introduction
In a goal-directed sensing system, information acquires practical value through the decision or action it enables. Classical communication theory established how a signal generated at one point can be represented and recovered reliably at another, largely without assigning value to the meaning of the transmitted content [1]. In many sensing systems, however, the measured samples are not the final objective; they are an intermediate description from which a receiver must infer a state, recognize an event, or select an action. If the receiver only needs a particular decision, reproducing every source sample with equal fidelity may be neither necessary nor the most effective use of a constrained message. This observation motivates semantic and task-oriented communication, in which the transmitted representation is judged by its usefulness for the receiver’s goal rather than solely by symbol-level or waveform-level similarity [2,3]. For such applications, the design question can therefore shift from how accurately can the source be reconstructed? to which information must survive the link for the intended decision to remain correct?
Electroencephalography (EEG) provides a compelling setting for this question. EEG non-invasively measures electrical potentials at the scalp with high temporal resolution, and brain–computer interfaces (BCIs) use these recordings to create pathways for communication and control that do not depend on conventional muscular output [4,5]. Motor imagery (MI), in which a person imagines a movement without executing it, is one of the principal EEG–BCI paradigms. Its discriminative information is distributed across electrodes, frequency ranges, and time, while the measured signals are affected by low signal amplitudes, background activity, artifacts, and substantial variation between people and recording sessions [5,6]. Wearable and wireless EEG systems permit acquisition away from a fixed laboratory workstation and can separate the sensing device from the computing resource that interprets its data [7]. Such separation creates a communication problem in addition to the decoding problem: the acquisition side must construct a fixed-dimensional representation from each EEG trial, the communication link may disturb that representation, and a classifier at the remote side must still identify the intended MI class. When the communication signal-to-noise ratio (SNR) is low, the added disturbance is large relative to the transmitted signal, so information that supports a reliable local decision may not remain equally reliable after transmission.
Established MI pipelines provide strong foundations for constructing compact EEG messages. Common spatial patterns (CSP) identify weighted combinations of electrodes whose variances discriminate between imagined movements [8]. The filter bank common spatial pattern (FBCSP) method extends this principle across multiple frequency bands and remains an important reference for MI decoding [5,9,10]. Its features can be further reduced by principal component analysis (PCA) to a prescribed dimension. In parallel, convolutional networks and compact architectures such as EEGNet have demonstrated that temporal and spatial EEG representations can be learned directly from data [11,12]. These advances have primarily addressed representation quality when acquisition and decision making form a local processing chain. A compact representation that separates MI classes without channel noise is not necessarily arranged to preserve that separation under additive disturbance. Training a remote classifier on noisy features can adapt its decision boundaries, but it cannot change the message constructed at the acquisition side.
Learned EEG representations introduce a further design choice: which information should compression preserve? Autoencoders retain information needed to reconstruct the input waveform, whereas supervised decoders emphasize variations predictive of the task label; suitably designed autoencoder features can nevertheless support MI decoding [13]. Compact convolutional networks, large-scale pretrained encoders, and recent task-independent, topographic, multimodal, and hybrid approaches have broadened EEG representation learning beyond predetermined handcrafted descriptors [12,14,15,16,17,18,19]. However, waveform reconstruction and task preservation are not equivalent: a component can contribute substantially to reconstruction error while providing little class information, whereas a low-energy pattern may be essential for classification [20]. These advances therefore do not by themselves determine which representation should be transmitted through a noisy link under a fixed message size.
Task-oriented semantic communication addresses this problem by constructing a message according to its usefulness for the receiver task rather than solely according to source-reconstruction fidelity. Differentiable channel models permit message construction and receiver decision making to be optimized jointly under the disturbances expected during transmission [21,22,23]. Here, semantic refers specifically to information optimized for MI classification; it does not imply linguistic meaning, recovery of thought content, or a neurophysiological claim about how the brain represents semantics. Neural applications include semantic communication for multi-brain robot control [24], cross-modal visual-perception communication in the EidetiCom preprint [25], and task-agnostic EEG representations evaluated under uncoded noisy links across several cognitive tasks [26]. Robustness and security have also been studied for EEG-based brain-to-brain communication under adversarial perturbations [27]. Together, these studies establish an emerging connection between neural decoding and communication-aware representation design.
The remaining question is whether a strong conventional MI representation can be refined, rather than replaced, to improve remote decisions after noisy transmission. A controlled answer requires matched message dimension and power, exclusion of the held-out test session from subject-level preprocessing and model selection, a classifier-only control separating message refinement from receiver training, and a reconstruction baseline contrasting waveform with decision preservation. Prior studies do not examine this combination for baseline-preserving FBCSP–PCA refinement under matched real-valued channel uses.
We therefore formulate MI decoding as remote classification of a compact vector transmitted through an additive white Gaussian noise (AWGN) link, with K denoting real-valued channel uses rather than bits or a complete wireless protocol. The proposed transmitter learns a bounded residual correction to FBCSP–PCA features, initialized to reproduce and constrained to remain near the conventional system. We compare it with conventional FBCSP–PCA transmission, reconstruction-oriented autoencoder transmission, and a classifier-only control under matched conditions.
The main contributions of this study are as follows:
- 1.
- We formulate and evaluate a remote EEG classification framework in which alternative representations are compared in terms of downstream MI classification while transmitting the same number of power-normalized real values through the same noisy link.
- 2.
- We introduce a baseline-preserving semantic transmitter that learns a bounded, task-oriented residual refinement of FBCSP–PCA features, retaining the established conventional representation as its starting point rather than replacing it with an unconstrained latent space.
- 3.
- We compare the proposed method with conventional feature transmission, an autoencoder-based reconstruction baseline, and a classifier-only control. These comparisons separate changes to the message from receiver-only training and contrast task-oriented learning with waveform reconstruction.
- 4.
- We evaluate the approaches using subject-specific bidirectional cross-session testing, matched numbers of real-valued channel uses under the adopted AWGN model, paired channel realizations, and subject-level statistical inference with family-wise error-rate correction.
2. Materials and Methods
2.1. EEG Dataset
The study was conducted on BNCI2014-001, also known as BCI Competition IV Dataset 2a [28,29,30,31]. The dataset contains EEG recordings from nine subjects who performed four MI tasks: imagining movements of the left hand, the right hand, both feet, or the tongue. Each subject completed two recording sessions on different days. A session comprised six runs, and each run contained 48 trials, with the four tasks represented equally. EEG was recorded from 22 scalp electrodes at 250 Hz. The three accompanying electrooculographic (EOG) channels were not used. The complete dataset therefore contained 576 trials per subject and 5184 trials in total before trials marked as artifactual by the data provider were removed.
The two sessions enabled cross-session evaluation, in which a system fitted using one recording day was evaluated on the other. The following subsections define the remote classification problem and then describe the transmitted representations, data preparation, model training, and evaluation.
2.2. Remote EEG Classification as a Communication Problem
We considered a situation in which EEG is recorded at one location, whereas the final MI decision is made at another. For example, a wearable EEG device may collect a trial near the user, while a separate computer performs the classification. Sending the complete trial would require transferring thousands of EEG samples for every decision. The acquisition side therefore replaces the trial with a much shorter numerical message and passes it to the remote processing side. The scientific question is whether the construction of this message determines how reliably the remote computer can identify the intended MI class when the transferred values are disturbed by noise. In this study, communication refers specifically to this transfer of information between the two sides.
The system contains three consecutive stages. First, a software block at the acquisition side converts one EEG trial into a vector containing K real numbers. We call this algorithm the transmitter, and its K-dimensional output is the message for that trial. Second, the vector passes through an abstract link between the acquisition and remote sides, termed the communication channel. This must not be confused with an EEG channel: an EEG channel is the signal measured by one electrode, whereas the communication channel is the path over which the message is transferred. Third, a software block at the remote side receives the vector and assigns it to one of the four MI classes. We call this block the receiver. Thus, transmission denotes the passage of one message vector from the transmitter to the receiver for an EEG trial.
We represent one EEG trial by a real-valued matrix , where is the set of real numbers, C is the number of EEG electrodes, and T is the number of temporal samples. The number of values to be transmitted is denoted by K, and denotes the representation method operating at the acquisition side. The transmitter output is
The value K is the communication load considered in this study, with . In the adopted real-valued channel model, each transmitted scalar occupies one real-valued channel use; consequently, a K-dimensional vector requires K such channel uses. To avoid confusion with the 22 EEG electrode channels, the results are reported primarily as the number of transmitted values.
The numerical scale of a transmitted vector determines the relative effect of a fixed noise level. Without normalization, a method could obtain an artificial advantage by producing values with larger amplitudes. We denote the rescaled vector by and apply per-vector power normalization:
where is the Euclidean norm and prevents numerical instability when the norm is zero or very small. For , Equation (2) makes the mean squared value of the K transmitted numbers equal to one. The same normalization is applied to every method before transmission.
The communication link is represented by an AWGN model. We denote the added noise by , its variance by , and the vector available at the remote side by . The communication model is
where is the identity matrix. The SNR controls the size of the disturbance relative to the normalized transmitted vector. A high SNR corresponds to weak corruption, whereas a low SNR corresponds to strong corruption. SNR is expressed in decibels (dB). Because Equation (2) sets the mean squared transmitted value to one, the noise variance is
Finally, let denote the classifier at the remote side and its predicted MI label. The receiver operation is
The experiment concerns the reliability of this class decision after corruption of the compact vector. It does not simulate a particular wireless standard, modulation scheme, quantizer, error-correcting code, or transmission rate. Accordingly, K measures the number of real values transferred per EEG trial, neither a number of bits nor a bit rate. The next subsection defines how the three transmitters construct their messages.
2.3. Transmitted EEG Representations
Three approaches construct the vector in Equation (1). The conventional approach summarizes MI activity with established spatial and spectral features. The reconstruction-oriented approach produces a vector designed to retain enough information to recover the original EEG waveform. The proposed semantic approach instead produces a vector designed to retain the information needed for the MI decision. For a given value of K, all approaches send exactly K real numbers, undergo the same power constraint in Equation (2), and are disturbed according to the same communication model in Equation (3). Their comparison therefore tests how the content of an equally sized transmitted vector affects remote classification.
All approaches use the same receiver: a fully connected layer, an exponential linear unit activation, dropout with probability 0.25, and a four-unit softmax output layer. Holding this architecture constant prevents receiver capacity from being confounded with representation quality.
2.3.1. Conventional FBCSP Representation
The conventional transmitter uses FBCSP, a standard method for MI EEG decoding [9]. The 8–30 Hz MI range is divided into five subbands: 8–12, 12–16, 16–20, 20–24, and 24–30 Hz. Within each band, CSP filters are constructed separately for each class against the remaining three classes. Four spatial components are retained for every one-versus-rest (OVR) problem, and the logarithm of the average signal power of each retained component is calculated. The five bands, four class comparisons, and four components yield features per trial.
Within each OVR problem, CSP used covariance matrices estimated from concatenated trials, Ledoit–Wolf regularization [32], no trace normalization, and mutual-information component ordering. After training-set standardization, PCA using full singular value decomposition reduced the 80 features to the selected value of K. Let denote this PCA output before communication normalization. The power-normalized conventional vector is
where denotes Equation (2). The vector , whose mean squared value is one, forms the conventional message sent through the communication channel.
2.3.2. Reconstruction-Oriented Representation
The reconstruction transmitter is a convolutional autoencoder. Its encoder compresses an 8–30 Hz EEG trial into a K-dimensional latent vector, while its decoder reconstructs the standardized trial from the noisy latent representation. Reconstruction training therefore encourages the transmitted vector to retain waveform information. After training, the decoder is discarded and the encoded vector is passed to the common receiver. Exact layer dimensions are reported in Table 1.
2.3.3. Proposed Residual Semantic Representation
The proposed approach begins with the normalized conventional vector in Equation (6). A residual transformation , comprising layer normalization and two fully connected layers separated by a Gaussian error linear unit, produces a bounded correction. With residual scale , the transmitted semantic vector is
The model used hidden width and residual scale , fixed across subjects, cross-session directions, communication loads, and test conditions. Because the hyperbolic tangent lies between and 1, each pre-normalization correction component is bounded in magnitude by . No subject-specific or communication-condition-specific selection of these values was performed.
The final layer of is initialized with zero weights and biases, and the semantic receiver is initialized from the corresponding trained conventional receiver. Before semantic training, Equation (7) therefore yields , and the complete semantic system reproduces the corresponding conventional system. Semantic learning begins from this baseline-preserving state rather than from an unrelated representation and classifier.
2.3.4. Classifier-Only Control
A classifier-only control was evaluated at to distinguish modification of the transmitted vector from additional receiver training. Its conventional vector remained fixed, and only the receiver parameters were updated. In the figures, this condition is labeled Receiver-only.
Figure 1 consolidates the three representation paths within the common communication system.
Table 1 summarizes the learned components; Conv1D denotes a one-dimensional convolution and TConv1D a one-dimensional transposed convolution.
These representations were evaluated using the common cross-session protocol described next.
2.4. Cross-Session Experimental Design and Input Preparation
2.4.1. Session and Run Partitioning
All analyses were subject-specific: data from different subjects were never combined to fit a representation or classifier. For each subject, the two recording sessions were used in both possible directions. In the first direction, Session 1 supplied the training and validation data, while Session 2 was the held-out test session. In the second direction, their roles were reversed. This produced two cross-session evaluations per subject and ensured that every final prediction concerned a recording day not used to fit or select the corresponding model.
Within the source session, five complete acquisition runs formed the training set used to fit preprocessing transformations and model parameters. The remaining complete run formed the validation set used to select the retained model state. The validation run was chosen deterministically with split seed 2026, with the requirement that all four classes were present in both sets. Keeping runs intact prevented trials from the same recording block from appearing in both training and validation. The opposite session was reserved exclusively as the test set.
The data partition was established before any data-dependent operation was fitted. Within this partition, the signals and method-specific inputs were prepared as follows.
2.4.2. Signal Preprocessing and Method-Specific Inputs
The dataset was accessed with version 1.5.0 of the Mother of All BCI Benchmarks (MOABB) and processed through its MNE-Python-based paradigm interface [30,31]. We specified the filtering, resampling, and epoching parameters; the MOABB/MNE-Python pipeline executed these signal operations and returned the trial arrays together with their session, run, class, and artifact annotations from the source files.
Signals were resampled from 250 to 160 Hz. Each trial covered the 3.5-s interval s after the MI cue. Removing the first 0.5 s reduced the contribution of the immediate visual cue response and retained sustained MI activity. Consequently, every 8–30 Hz trial used by the reconstruction-oriented approach contained 22 EEG electrodes and 560 temporal samples, or 12,320 signal values. For the conventional and semantic approaches, the same interval was extracted separately in the five frequency bands defined in Section 2.3.1.
Trials carrying an artifact flag in the original BNCI2014-001 source files were identified through an explicit audit that mapped the provider’s flags to the MOABB trial metadata using subject, session, run, within-run trial order, and class label. Flagged trials were excluded before model fitting or evaluation. This removed 488 of the original 5184 trials and retained 4696 trials. No additional automated amplitude-based rejection criterion was introduced, and the same retained trials were used by all three methods.
All data-dependent operations were estimated from the training set only. For the reconstruction-oriented approach, each EEG electrode was standardized using its mean and standard deviation over the training trials and temporal samples; these same values were then applied to the validation and test sets. For the conventional and semantic approaches, the CSP spatial filters, the standardizer for the 80 FBCSP features, and the PCA transformation were fitted only to the training trials and then applied unchanged to validation and test trials. The resulting PCA vectors were power-normalized as specified in Equation (6). Once these leakage-free inputs had been prepared, the learned components were trained while being exposed to the communication disturbances defined earlier.
2.5. Model Training and Selection
Learned components expected to operate with noise-corrupted vectors were exposed to such disturbances during training. Accordingly, the AWGN operation in Equation (3) remained active during training. For each training example, an SNR was sampled from .
This procedure allowed one model to operate across several noise levels instead of fitting a separate model for each SNR. Three deterministic repetitions used seeds 2026, 2027, and 2028. For the semantic and classifier-only models, a distinct initialization seed was deterministically derived for every subject, cross-session direction, communication load, and repetition seed before model construction. Training-batch order and the two semantic training stages were also controlled by deterministic seeds.
Classification models were learned using categorical cross-entropy, which measures disagreement between the predicted class probabilities and the known MI label. The criterion used to assess predictions on the validation set was balanced accuracy. For a class c, let denote its correctly recognized trials and its missed trials. Balanced accuracy was defined as the mean class-specific recognition rate:
Balanced accuracy therefore gives the same weight to every MI class.
For the conventional approach, the common receiver classifier was trained from noisy FBCSP–PCA vectors. The SNR of each example was sampled uniformly from . At the end of every epoch, balanced accuracy was calculated on the validation set at all seven noisy SNRs, using one fixed disturbance, the same generated noise values at every epoch, for each SNR. The retained parameter state was the one with the highest mean balanced accuracy across these seven conditions.
For the reconstruction-oriented approach, the encoder and decoder were first trained together. The power-normalized reconstruction-oriented vector was corrupted at an SNR sampled uniformly from , and the decoder attempted to recover the standardized EEG trial. The training objective was mean squared error, calculated as the average squared difference between corresponding samples of the original and reconstructed trials. Model selection used the mean reconstruction error across the seven noisy SNRs on the validation set. The selected encoder was then fixed, the decoder was removed, and the common receiver classifier was trained and selected from the noisy reconstruction-oriented vectors in the same manner as the conventional receiver.
The semantic transmitter was optimized to retain correct decisions across several noise conditions while remaining close to its conventional starting point. Five quantities were defined for this purpose. First, was the cross-entropy obtained from the semantic vector without added noise. Second, was the mean cross-entropy from two independently disturbed copies of each vector, where the SNR of each copy was sampled from dB. Third, was the cross-entropy from one additional disturbed copy whose SNR was sampled from the complete set . Fourth, the anchor term was
It penalized unnecessary departure of the semantic vector from the normalized conventional vector . Fifth, encouraged the semantic system to preserve the class-probability structure produced by a fixed copy of the conventional system. To obtain this term, the output scores of both systems were divided by a temperature before conversion to probabilities. This operation produces flatter probability distributions and exposes similarities among the non-selected classes. Let and denote the resulting conventional and semantic probabilities for class c. The probability-preservation term was the temperature-scaled Kullback–Leibler divergence [33]:
Having defined all five quantities, the semantic training objective was
The weights prioritized clean and severe-noise classification, retained exposure to the complete noisy SNR range, and constrained departure from the conventional representation and its class-probability structure. They were selected during exploratory method development and then held fixed throughout the reported all-nine-subject execution; they were not adapted separately by subject, direction, communication load, or test condition.
For each of the three classification terms, the target that would ordinarily assign all probability to the correct class was replaced by a slightly smoothed target distribution with smoothing factor 0.02. This label-smoothing operation reduced absolute confidence in a single class during optimization. Training then proceeded in two stages. The receiver was fixed during the first stage, so only the residual transformation learned to modify the FBCSP–PCA vector; this stage is termed residual warm-up. During the second stage, termed joint refinement, the residual transformation and receiver were refined together, using a smaller learning rate for the receiver.
At each epoch, semantic validation used three fixed noise realizations at every SNR in and a noise-free condition in which . Let denote validation balanced accuracy at SNR q, and let denote validation balanced accuracy without communication noise. The semantic model-selection score U emphasized the two most difficult conditions:
A parameter state was eligible for selection only if its balanced accuracies at 0 dB and in the noise-free condition were no more than 0.01 (one percentage point) below those of the corresponding conventional model. Because the semantic system was initialized to reproduce the conventional system, an unchanged conventional state was eligible from the start; a semantic refinement was retained only when it satisfied this preservation condition.
The classifier-only control used the same clean, severe-noise, mixed-noise, and probability-preservation terms but omitted , because its transmitted vector remained fixed. It was selected using the same score and preservation condition as the semantic model.
Table 2 summarizes the optimization settings. During semantic and classifier-only training, any gradient vector with a norm above 5 was rescaled to have norm 5, preventing an unusually large parameter update from destabilizing optimization.
For the Adam and AdamW stages, weight decay was and batch size was 32. An improvement smaller than was ignored. Training was stopped when the relevant model-selection criterion did not improve for 30 consecutive epochs; this waiting interval is the early-stopping patience. The learning rate was halved after 10 epochs without improvement, down to . Semantic joint refinement and the classifier-only control used an early-stopping patience of 40 epochs. Only the parameter state selected from the source session was subsequently applied to the held-out test session.
2.6. Evaluation and Statistical Analysis
Each selected model was evaluated on the held-out test session at every noisy SNR in , together with a noise-free condition. At every noisy SNR, 20 independently generated disturbances were applied to each test trial. The same deterministic disturbances were used for corresponding methods so that paired methods were compared under identical communication conditions. The noise-free condition was evaluated once per test trial.
Balanced accuracy from Equation (8) was the classification outcome, whereas K quantified the communication load. At each noisy SNR, balanced accuracy was first averaged across the 20 noise realizations. The noise-free score was used directly. For every subject, method, value of K, and test condition, results were then averaged across the three deterministic repetitions and the two cross-session directions. This produced one value per subject for every experimental condition. Subjects, rather than individual trials, directions, repetitions, or noise realizations, were treated as the independent units of group analysis.
Group values are reported as the mean across the nine subjects with two-sided 95% confidence intervals based on the t distribution. Method comparisons were performed on paired subject-level differences. The normality of each set of differences was examined with the Shapiro–Wilk test [34]. A paired t-test was used when the Shapiro–Wilk p-value was at least 0.05; otherwise, the Wilcoxon signed-rank test was used [35]. All tests were two-sided, and confidence intervals were unadjusted descriptive intervals.
Holm’s procedure controlled the family-wise error rate within the defined families of comparisons [36]. The primary family compared the proposed semantic approach with the conventional FBCSP–PCA approach across three values of K and eight test conditions, giving 24 tests. Two further 24-test families compared the semantic approach with the reconstruction-oriented approach and the conventional approach with the reconstruction-oriented approach. At , two eight-test families compared the semantic approach with the classifier-only control and the classifier-only control with the conventional approach. Holm-adjusted p-values below 0.05 were considered statistically significant. For every comparison, the mean paired difference, its 95% confidence interval, the number of subjects favoring either method, the unadjusted p-value, and the Holm-adjusted p-value were retained.
3. Results
The final analysis contained every defined condition for each method; as specified above, the classifier-only control was evaluated only at . No subject-level result was missing. For concise reporting, the , , and 0 dB conditions are referred to as the low-SNR region.
3.1. Classification Performance Across Channel Conditions and Transmission Budgets
Figure 2 presents the group results at . At , , and 0 dB, the proposed semantic approach obtained mean balanced accuracies of 41.10%, 49.46%, and 56.15%, respectively, compared with 38.63%, 46.28%, and 53.26% for the conventional FBCSP–PCA approach. The classifier-only control obtained 38.66%, 46.32%, and 53.31% at the same conditions. The corresponding values for the reconstruction-oriented approach were 25.81%, 26.47%, and 27.07%. At 20 dB, the semantic and conventional group means were 60.65% and 59.87%, respectively; in the noise-free condition, they were 60.71% and 59.98%.
Figure 3 extends the comparison across all transmission budgets. At dB, semantic balanced accuracy increased from 46.30% at to 52.22% at , while conventional accuracy increased from 43.55% to 48.73%. In the noise-free condition, semantic and conventional performance was similar across budgets, ranging from 59.58% to 60.71% and from 58.38% to 60.39%, respectively.
3.2. Primary Comparison with Conventional FBCSP–PCA Transmission
The mean semantic-minus-conventional difference was positive in all nine low-SNR budget–SNR combinations (Figure 4; Table 3). All nine subjects favored the semantic approach in eight combinations; at and 0 dB, eight of nine favored it.
After Holm correction across the 24 defined semantic-versus-conventional comparisons, eight conditions had : , , and 0 dB for and , and and dB for . The , 0-dB difference was 2.36 percentage points (95% confidence interval, 0.86 to 3.87), with . None of the 15 comparisons at 5, 10, 15, or 20 dB or in the noise-free condition had . In the noise-free condition, the mean semantic-minus-conventional differences were 1.20, 0.73, and percentage points for , , and , respectively.
3.3. Reconstruction-Oriented and Classifier-Only Comparisons
Across all budgets and test conditions, reconstruction-oriented balanced accuracy ranged from 25.35% to 28.79% (Figure 2 and Figure 3). The semantic approach exceeded it for every subject and condition; all 24 comparisons had . Conventional FBCSP–PCA also exceeded reconstruction-oriented transmission in all 24 comparisons, each with .
At , classifier-only and conventional means differed by less than 0.08 percentage points in every condition, with no significant comparison after Holm correction. The semantic approach exceeded the classifier-only control at , , and 0 dB for all nine subjects, and all three comparisons remained significant after correction (Table 4). No other test condition reached the adjusted significance threshold.
3.4. Subject-Level Consistency
Figure 5 shows the paired differences for every subject and low-SNR condition. Of the 81 subject–budget–SNR cells, 80 favored the semantic approach; the only negative difference was percentage points for Subject 9 at and 0 dB.
4. Discussion
4.1. Principal Findings
Under matched message dimension, power normalization, test trials, and AWGN realizations, task-oriented residual refinement improved balanced accuracy primarily at low SNR. Eight of the 24 semantic-versus-conventional comparisons remained significant after Holm correction, with gains of 1.79–3.49 percentage points; no comparison at 5 dB or above remained significant. The classifier-only control closely reproduced conventional performance, whereas the reconstruction-oriented representation remained near chance. Together, these results associate the observed low-SNR advantage with refinement of the transmitted representation rather than receiver retraining alone.
This study did not seek to benchmark state-of-the-art MI classifiers or maximize absolute accuracy. Its purpose was to isolate how three compact transmission strategies affect remote classification under matched communication conditions, with a classifier-only system as a control. More elaborate architectures could improve absolute decoding performance, but that is a separate question. Compact models were chosen to support reproducibility and extension to other EEG datasets and paradigms. Because computational efficiency was neither optimized nor evaluated, runtime, memory, and operation-count comparisons are outside the present scope.
4.2. Interpretation of the Low-SNR Benefit
The semantic objective prioritized the downstream MI decision over faithful recovery of the original EEG waveform, following the task-oriented view that a message is valued by its usefulness for the receiver task rather than solely by sample- or symbol-level fidelity [21,22,23]. The present method applies that principle conservatively by beginning with FBCSP–PCA, an established spatial–spectral representation for MI decoding, and learning only a bounded correction [5,9].
After FBCSP and PCA, the conventional mapping remains fixed; noise-aware receiver training can alter only the decision boundary. Semantic training can also modify the representation while observing noisy instances. Its emphasis on and dB promotes robustness under severe disturbance, whereas the anchor and distillation terms limit departure from the conventional solution.
A plausible explanation is that the residual transformation rearranged the compact FBCSP–PCA vectors so that task-relevant class distinctions were less vulnerable to the additive perturbations encountered during training. Such a rearrangement may increase class margins at vulnerable decision boundaries or distribute class-relevant evidence more robustly across the K transmitted components. This interpretation is consistent with the paired low-SNR gains and with task-oriented communication studies in other data modalities, where representations optimized for the receiver task retained greater utility under restrictive or noisy links [20,22,23].
The reduction of the difference at favorable SNRs is equally informative. When little or no communication noise was added, the conventional representation was already near its performance plateau, leaving less scope for channel-aware refinement. Moreover, zero initialization of the residual path, the anchor loss, the distillation loss, and the preservation condition were designed to retain the conventional solution when a change was unnecessary. The concentration of the gain at low SNR is therefore consistent with both the training priorities and the baseline-preserving construction.
4.3. Evidence from the Comparison Methods
The classifier-only control isolates receiver adaptation from message refinement. Its close agreement with conventional performance, together with the semantic method’s significant low-SNR advantage over this control, indicates that additional receiver optimization alone did not account for the gain at .
The reconstruction comparison addresses a different objective. Mean-squared error weights samplewise waveform deviations irrespective of their relevance to the MI decision, whereas a task-oriented loss can prioritize variations that affect the class prediction. Its near-chance performance is therefore consistent with a mismatch between reconstruction fidelity and decision relevance [20,22]. Because this system also differed in architecture and input representation, the result concerns the tested complete implementation rather than reconstruction learning generally; suitably designed autoencoder features can support MI decoding [13].
Increasing K generally raised balanced accuracy for both the conventional and semantic approaches at low SNR, but the semantic-minus-conventional difference did not increase monotonically with K. These are separate effects: sending more real values supplied a larger representation to both methods, whereas task-oriented refinement altered the content of a representation at a fixed size. The within-budget comparisons therefore show that the semantic gains were not obtained by transmitting a longer vector.
4.4. Across-Subject Consistency
Positive semantic-minus-conventional differences in 80 of the 81 low-SNR subject–budget–SNR cells show that the group effect was broadly distributed rather than driven by a small number of individuals. The eight significant group-level gains ranged from 1.79 to 3.49 percentage points. Their practical importance will depend on application-specific factors such as error cost and decision rate, while the present cross-session result establishes that the improvement persisted when subject-specific fitting and checkpoint selection used a different recording day from evaluation.
4.5. Study Scope and Future Directions
The findings apply to a subject-specific cross-session analysis of one four-class MI dataset under a controlled analog AWGN model. This design isolates task-oriented message refinement under matched dimension and power, but equal K denotes equal real-valued vector dimension rather than equal digital bit rate, latency, or energy. The reconstruction result likewise pertains to the tested convolutional autoencoder. Because method development and final evaluation used BNCI2014-001, the reported comparisons provide internal cross-session evidence rather than independent confirmation. Moreover, although repeated model seeds and channel realizations stabilized within-subject estimates, the inferential sample remained nine subjects, limiting precision and the power of assumption checks and multiplicity-adjusted tests.
Applying the fixed procedure to an independent MI dataset would test whether the low-SNR advantage transfers beyond the present recordings. Introducing quantization and a representative fading or interference model would connect the real-valued AWGN abstraction to a practical link. Budget-matched raw or conventionally compressed EEG, a supervised neural transmitter, and a compact ablation of the residual objective would further clarify how the proposed refinement compares with alternative message designs and which components contribute most to its performance.
5. Conclusions
Within the evaluated cross-session AWGN setting, baseline-preserving task-oriented refinement of FBCSP–PCA features improved MI decoding at low SNR without increasing the transmitted dimension. At , its advantage over the classifier-only control associated the gain with refinement of the message itself rather than additional receiver optimization alone. The near-chance result of the tested reconstruction system is consistent with the distinction between waveform preservation and decision preservation under this compact bottleneck. These findings support the potential of task-oriented residual refinement for protecting remote EEG decisions under the evaluated low-SNR conditions and motivate validation on independent datasets and more practical communication models.
Author Contributions
Conceptualization, H.A.; methodology, H.A.; software, H.A.; validation, H.A. and L.M.; formal analysis, H.A.; investigation, H.A.; resources, H.A. and L.M.; data curation, H.A.; writing—original draft preparation, H.A.; writing—review and editing, H.A. and L.M.; visualization, H.A.; supervision, L.M.; project administration, H.A. and L.M. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Institutional Review Board Statement
Not applicable to this secondary analysis, which used only deidentified, publicly available EEG recordings and enrolled no new participants.
Informed Consent Statement
Not applicable to the present secondary analysis; no new participants were enrolled.
Data Availability Statement
BNCI2014-001 (BCI Competition IV Dataset 2a) is publicly available from the BNCI Horizon 2020 repository (https://bnci-horizon-2020.eu/database/data-sets) and can be downloaded programmatically through MOABB under the identifier BNCI2014_001. The complete analysis code and frozen publication results are publicly available at https://github.com/HosseinAhmadi63/Semantic-EEG-Communication.
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Shannon, C.E. A Mathematical Theory of Communication. Bell Syst. Tech. J. 1948, 27, 379–423. [Google Scholar] [CrossRef]
- Calvanese Strinati, E.; Barbarossa, S. 6G Networks: Beyond Shannon Towards Semantic and Goal-Oriented Communications. Comput. Netw. 2021, 190, 107930. [Google Scholar] [CrossRef]
- Gündüz, D.; Qin, Z.; Aguerri, I.E.; Dhillon, H.S.; Yang, Z.; Yener, A.; Wong, K.K.; Chae, C.B. Beyond Transmitting Bits: Context, Semantics, and Task-Oriented Communications. IEEE J. Sel. Areas Commun. 2023, 41, 5–41. [Google Scholar] [CrossRef]
- Wolpaw, J.R.; Birbaumer, N.; McFarland, D.J.; Pfurtscheller, G.; Vaughan, T.M. Brain–Computer Interfaces for Communication and Control. Clin. Neurophysiol. 2002, 113, 767–791. [Google Scholar] [CrossRef] [PubMed]
- Lotte, F.; Bougrain, L.; Cichocki, A.; Clerc, M.; Congedo, M.; Rakotomamonjy, A.; Yger, F. A Review of Classification Algorithms for EEG-Based Brain–Computer Interfaces: A 10 Year Update. J. Neural Eng. 2018, 15, 031005. [Google Scholar] [CrossRef] [PubMed]
- Saha, S.; Baumert, M. Intra- and Inter-Subject Variability in EEG-Based Sensorimotor Brain–Computer Interface: A Review. Front. Comput. Neurosci. 2020, 13, 87. [Google Scholar] [CrossRef] [PubMed]
- Lin, C.T.; Wang, Y.; Chen, S.F.; Huang, K.C.; Liao, L.D. Design and Verification of a Wearable Wireless 64-Channel High-Resolution EEG Acquisition System with Wi-Fi Transmission. Med. Biol. Eng. Comput. 2023, 61, 3003–3019. [Google Scholar] [CrossRef] [PubMed]
- Ramoser, H.; Müller-Gerking, J.; Pfurtscheller, G. Optimal Spatial Filtering of Single Trial EEG During Imagined Hand Movement. IEEE Trans. Rehabil. Eng. 2000, 8, 441–446. [Google Scholar] [CrossRef] [PubMed]
- Ang, K.K.; Chin, Z.Y.; Zhang, H.; Guan, C. Filter Bank Common Spatial Pattern (FBCSP) in Brain-Computer Interface. In Proceedings of the 2008 IEEE International Joint Conference on Neural Networks, Hong Kong, 2008; pp. 2391–2398. [Google Scholar] [CrossRef]
- Ang, K.K.; Chin, Z.Y.; Wang, C.; Guan, C.; Zhang, H. Filter Bank Common Spatial Pattern Algorithm on BCI Competition IV Datasets 2a and 2b. Front. Neurosci. 2012, 6, 39. [Google Scholar] [CrossRef] [PubMed]
- Schirrmeister, R.T.; Springenberg, J.T.; Fiederer, L.D.J.; Glasstetter, M.; Eggensperger, K.; Tangermann, M.; Hutter, F.; Burgard, W.; Ball, T. Deep Learning with Convolutional Neural Networks for EEG Decoding and Visualization. Hum. Brain Mapp. 2017, 38, 5391–5420. [Google Scholar] [CrossRef] [PubMed]
- Lawhern, V.J.; Solon, A.J.; Waytowich, N.R.; Gordon, S.M.; Hung, C.P.; Lance, B.J. EEGNet: A Compact Convolutional Neural Network for EEG-Based Brain–Computer Interfaces. J. Neural Eng. 2018, 15, 056013. [Google Scholar] [CrossRef] [PubMed]
- Mammone, N.; Ieracitano, C.; Adeli, H.; Morabito, F.C. AutoEncoder Filter Bank Common Spatial Patterns to Decode Motor Imagery From EEG. IEEE J. Biomed. Health Inform. 2023, 27, 2365–2376. [Google Scholar] [CrossRef] [PubMed]
- Jiang, W.B.; Zhao, L.M.; Lu, B.L. Large Brain Model for Learning Generic Representations with Tremendous EEG Data in BCI. In Proceedings of the Twelfth International Conference on Learning Representations, 2024. [Google Scholar]
- Ahmadi, H.; Mesin, L. Universal Semantic Feature Extraction from EEG Signals: A Task-Independent Framework. J. Neural Eng. 2025, 22, 036003. [Google Scholar] [CrossRef] [PubMed]
- Ahmadi, H.; Mesin, L. Decoding Visual Imagination and Perception from EEG via Topomap Sequences. In Proceedings of the 2025 47th Annual International Conference of the IEEE Engineering in Medicine and Biology Society (EMBC), Copenhagen, Denmark, 2025; pp. 1–7. [Google Scholar] [CrossRef] [PubMed]
- Ahmadi, H.; Impagnatiello, M.; Mesin, L. Semantic Latent Geometry Reveals Imagination–Perception Structure in EEG. Appl. Sci. 2026, 16, 661. [Google Scholar] [CrossRef]
- Ahmadi, H.; Santamaria Vazquez, E.; Mesin, L.; Hornero, R. Semantic-Aware Decoding of Covert Inner Speech: A Multimodal EEG–EMG–Audio Framework. SSRN Posted. 2026. [Google Scholar] [CrossRef]
- Ahmadi, H.; Costa, P.; Mesin, L. A Novel Hierarchical Binary Classification for Coma Outcome Prediction Using EEG, CNN, and Traditional ML Approaches. TechRxiv preprint, Version 1, 2024. Posted. 21 November 2024. [CrossRef]
- Diao, Y.; Zhang, Y.; She, C.; Zhao, P.G.; Li, E.L. Aligning Task- and Reconstruction-Oriented Communications for Edge Intelligence. IEEE J. Sel. Areas Commun. 2025, 43, 2575–2588. [Google Scholar] [CrossRef]
- Xie, H.; Qin, Z.; Li, G.Y.; Juang, B.H. Deep Learning Enabled Semantic Communication Systems. IEEE Trans. Signal Process. 2021, 69, 2663–2675. [Google Scholar] [CrossRef]
- Shao, J.; Mao, Y.; Zhang, J. Learning Task-Oriented Communication for Edge Inference: An Information Bottleneck Approach. IEEE J. Sel. Areas Commun. 2022, 40, 197–211. [Google Scholar] [CrossRef]
- Jankowski, M.; Gündüz, D.; Mikolajczyk, K. Wireless Image Retrieval at the Edge. IEEE J. Sel. Areas Commun. 2021, 39, 89–100. [Google Scholar] [CrossRef]
- Ouyang, J.; Wu, M.; Li, X.; Deng, H.; Jin, Z.; Wu, D.O. NeuroBCI: Multi-Brain to Multi-Robot Interaction Through EEG-Adaptive Neural Networks and Semantic Communications. IEEE Trans. Mob. Comput. 2024, 23, 14622–14637. [Google Scholar] [CrossRef]
- Zheng, L.; Chen, P.; Wang, S. EidetiCom: A Cross-Modal Brain–Computer Semantic Communication Paradigm for Decoding Visual Perception, 2024. arXiv arXiv:cs. [CrossRef]
- Wang, Z.; Li, A.; Xu, G.; Xu, T.; Hu, H. Brain Semantic Communication: Brain Semantics Computation and Robustness Evaluation. In Proceedings of the 2026 Global 6G Conference; IEEE, 2026; pp. 1–6. [Google Scholar] [CrossRef]
- Ahmadi, H.; Kuhestani, A.; Keshavarzi, M.; Mesin, L. Securing Brain-to-Brain Communication Channels Using Adversarial Training on SSVEP EEG. IEEE Access 2025, 13, 14358–14378. [Google Scholar] [CrossRef]
- Brunner, C.; Leeb, R.; Müller-Putz, G.R.; Schlögl, A.; Pfurtscheller, G. BCI Competition 2008 – Graz Data Set A. Institute for Knowledge Discovery and Institute for Human–Computer Interfaces; Accessed. Graz University of Technology, 2008. (accessed on 2 August 2026).
- Tangermann, M.; Müller, K.R.; Aertsen, A.; Birbaumer, N.; Braun, C.; Brunner, C.; Leeb, R.; Mehring, C.; Miller, K.J.; Müller-Putz, G.R.; et al. Review of the BCI Competition IV. Front. Neurosci. 2012, 6, 55. [Google Scholar] [CrossRef] [PubMed]
- Jayaram, V.; Barachant, A. MOABB: Trustworthy Algorithm Benchmarking for BCIs. J. Neural Eng. 2018, 15, 066011. [Google Scholar] [CrossRef] [PubMed]
- Aristimunha, B.; Carrara, I.; Guetschel, P.; Sedlar, S.; Rodrigues, P.; Sosulski, J.; Narayanan, D.; Bjareholt, E.; Barthelemy, Q.; Schirrmeister, R.T.; et al. Mother of All BCI Benchmarks. 2026. [Google Scholar] [CrossRef]
- Ledoit, O.; Wolf, M. A Well-Conditioned Estimator for Large-Dimensional Covariance Matrices. J. Multivar. Anal. 2004, 88, 365–411. [Google Scholar] [CrossRef]
- Kullback, S.; Leibler, R.A. On Information and Sufficiency. Ann. Math. Stat. 1951, 22, 79–86. [Google Scholar] [CrossRef]
- Shapiro, S.S.; Wilk, M.B. An Analysis of Variance Test for Normality (Complete Samples). Biometrika 1965, 52, 591–611. [Google Scholar] [CrossRef]
- Wilcoxon, F. Individual Comparisons by Ranking Methods. Biom. Bull. 1945, 1, 80–83. [Google Scholar] [CrossRef]
- Holm, S. A Simple Sequentially Rejective Multiple Test Procedure. Scand. J. Stat. 1979, 6, 65–70. [Google Scholar] [CrossRef]
Figure 1.
Remote MI-classification framework for the three transmitted representations under AWGN. Each message contains K power-normalized real values; OVR, one-versus-rest.
Figure 1.
Remote MI-classification framework for the three transmitted representations under AWGN. Each message contains K power-normalized real values; OVR, one-versus-rest.
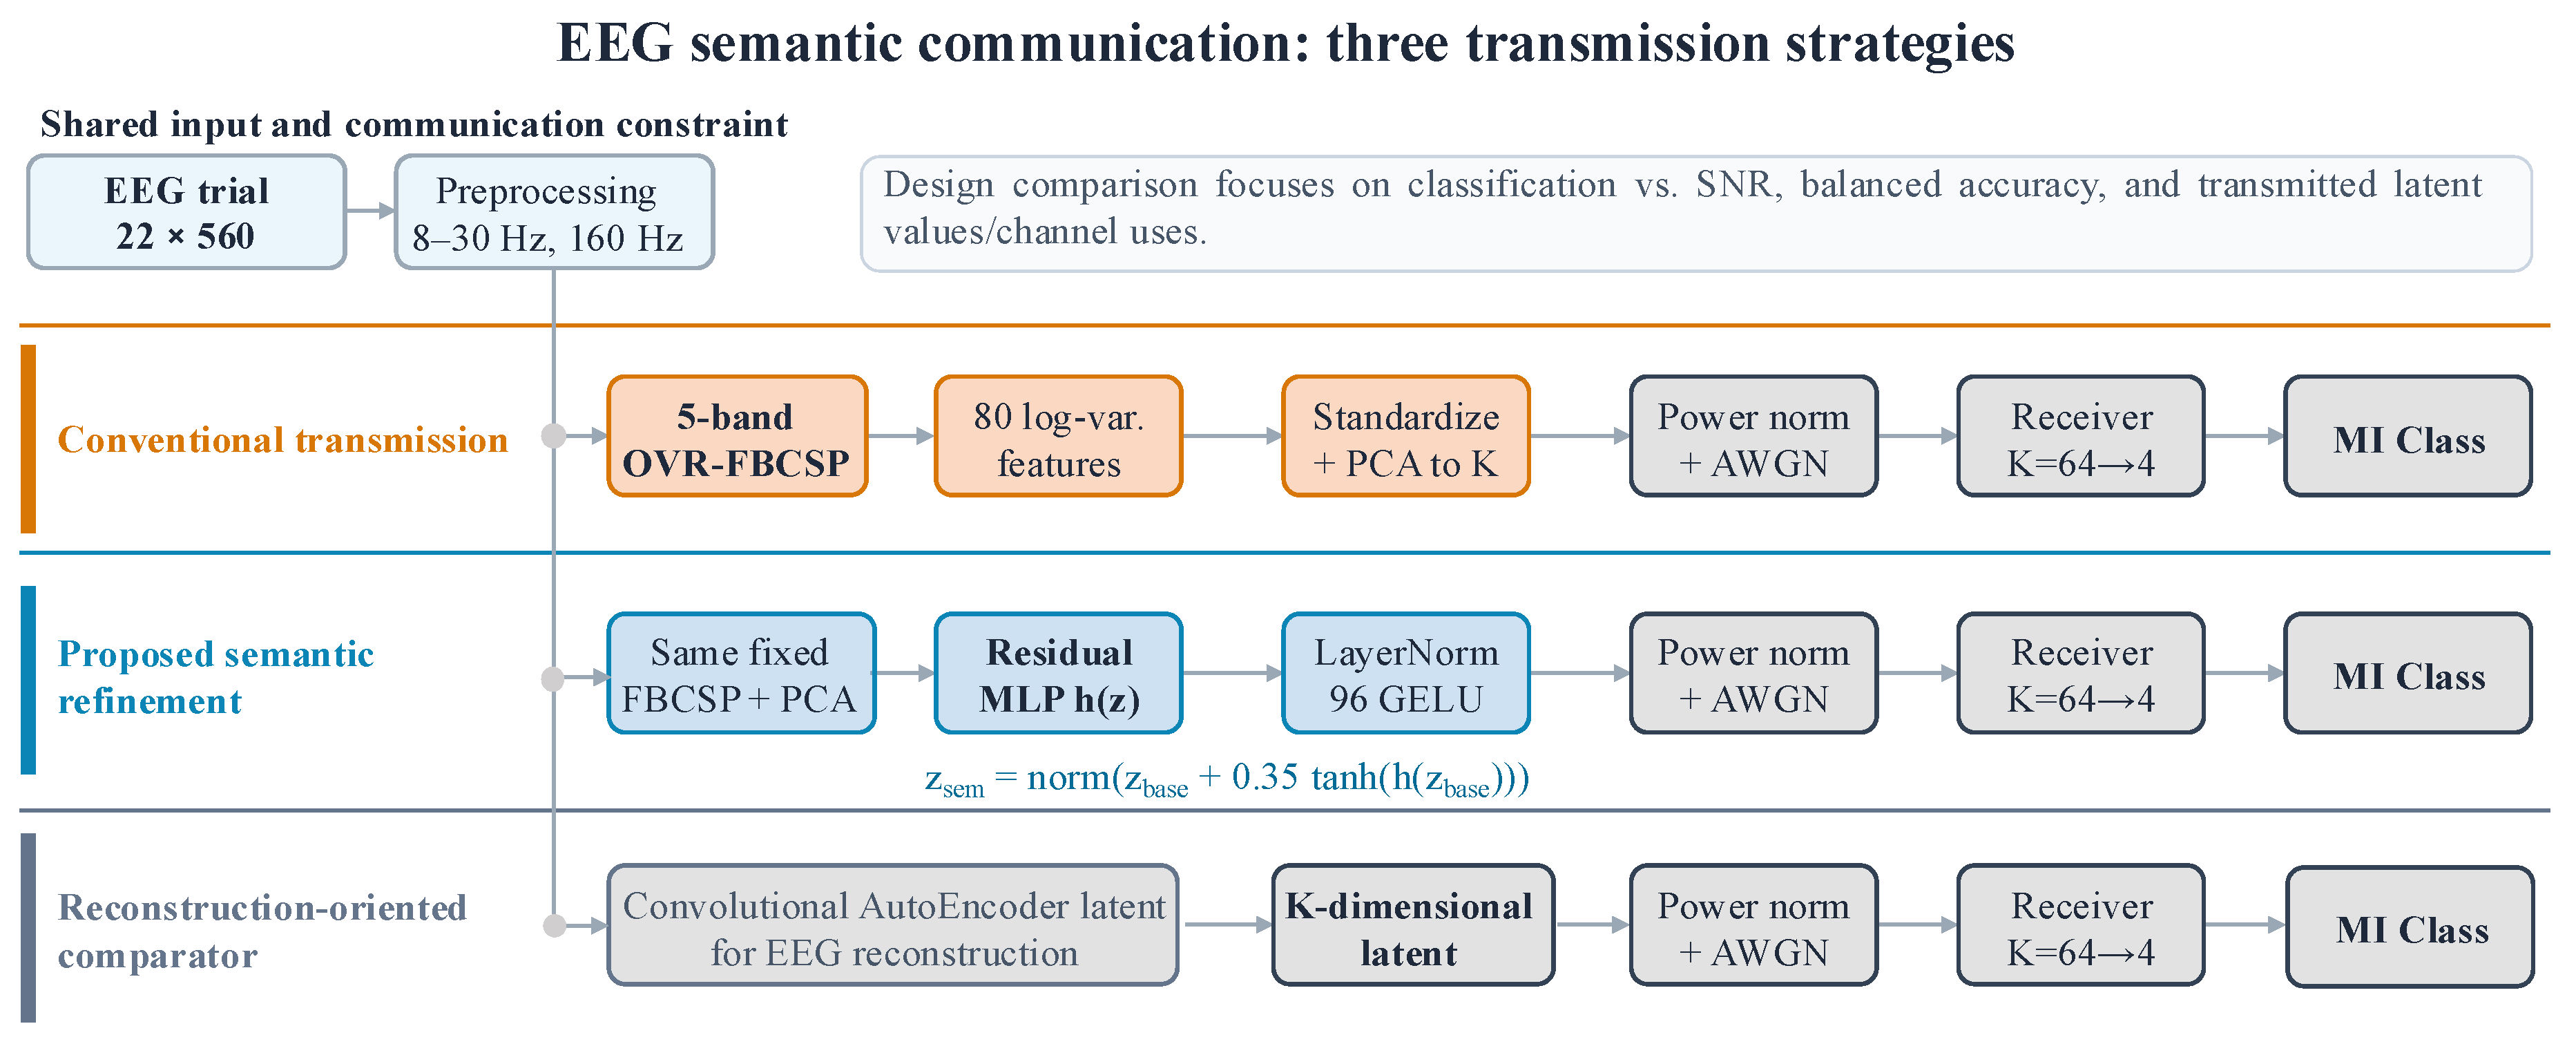
Figure 2.
Balanced accuracy versus SNR at . Shading, 95% confidence intervals for the semantic and FBCSP–PCA curves; Receiver-only, classifier-only control; NF, noise-free; dotted line, chance level.
Figure 2.
Balanced accuracy versus SNR at . Shading, 95% confidence intervals for the semantic and FBCSP–PCA curves; Receiver-only, classifier-only control; NF, noise-free; dotted line, chance level.
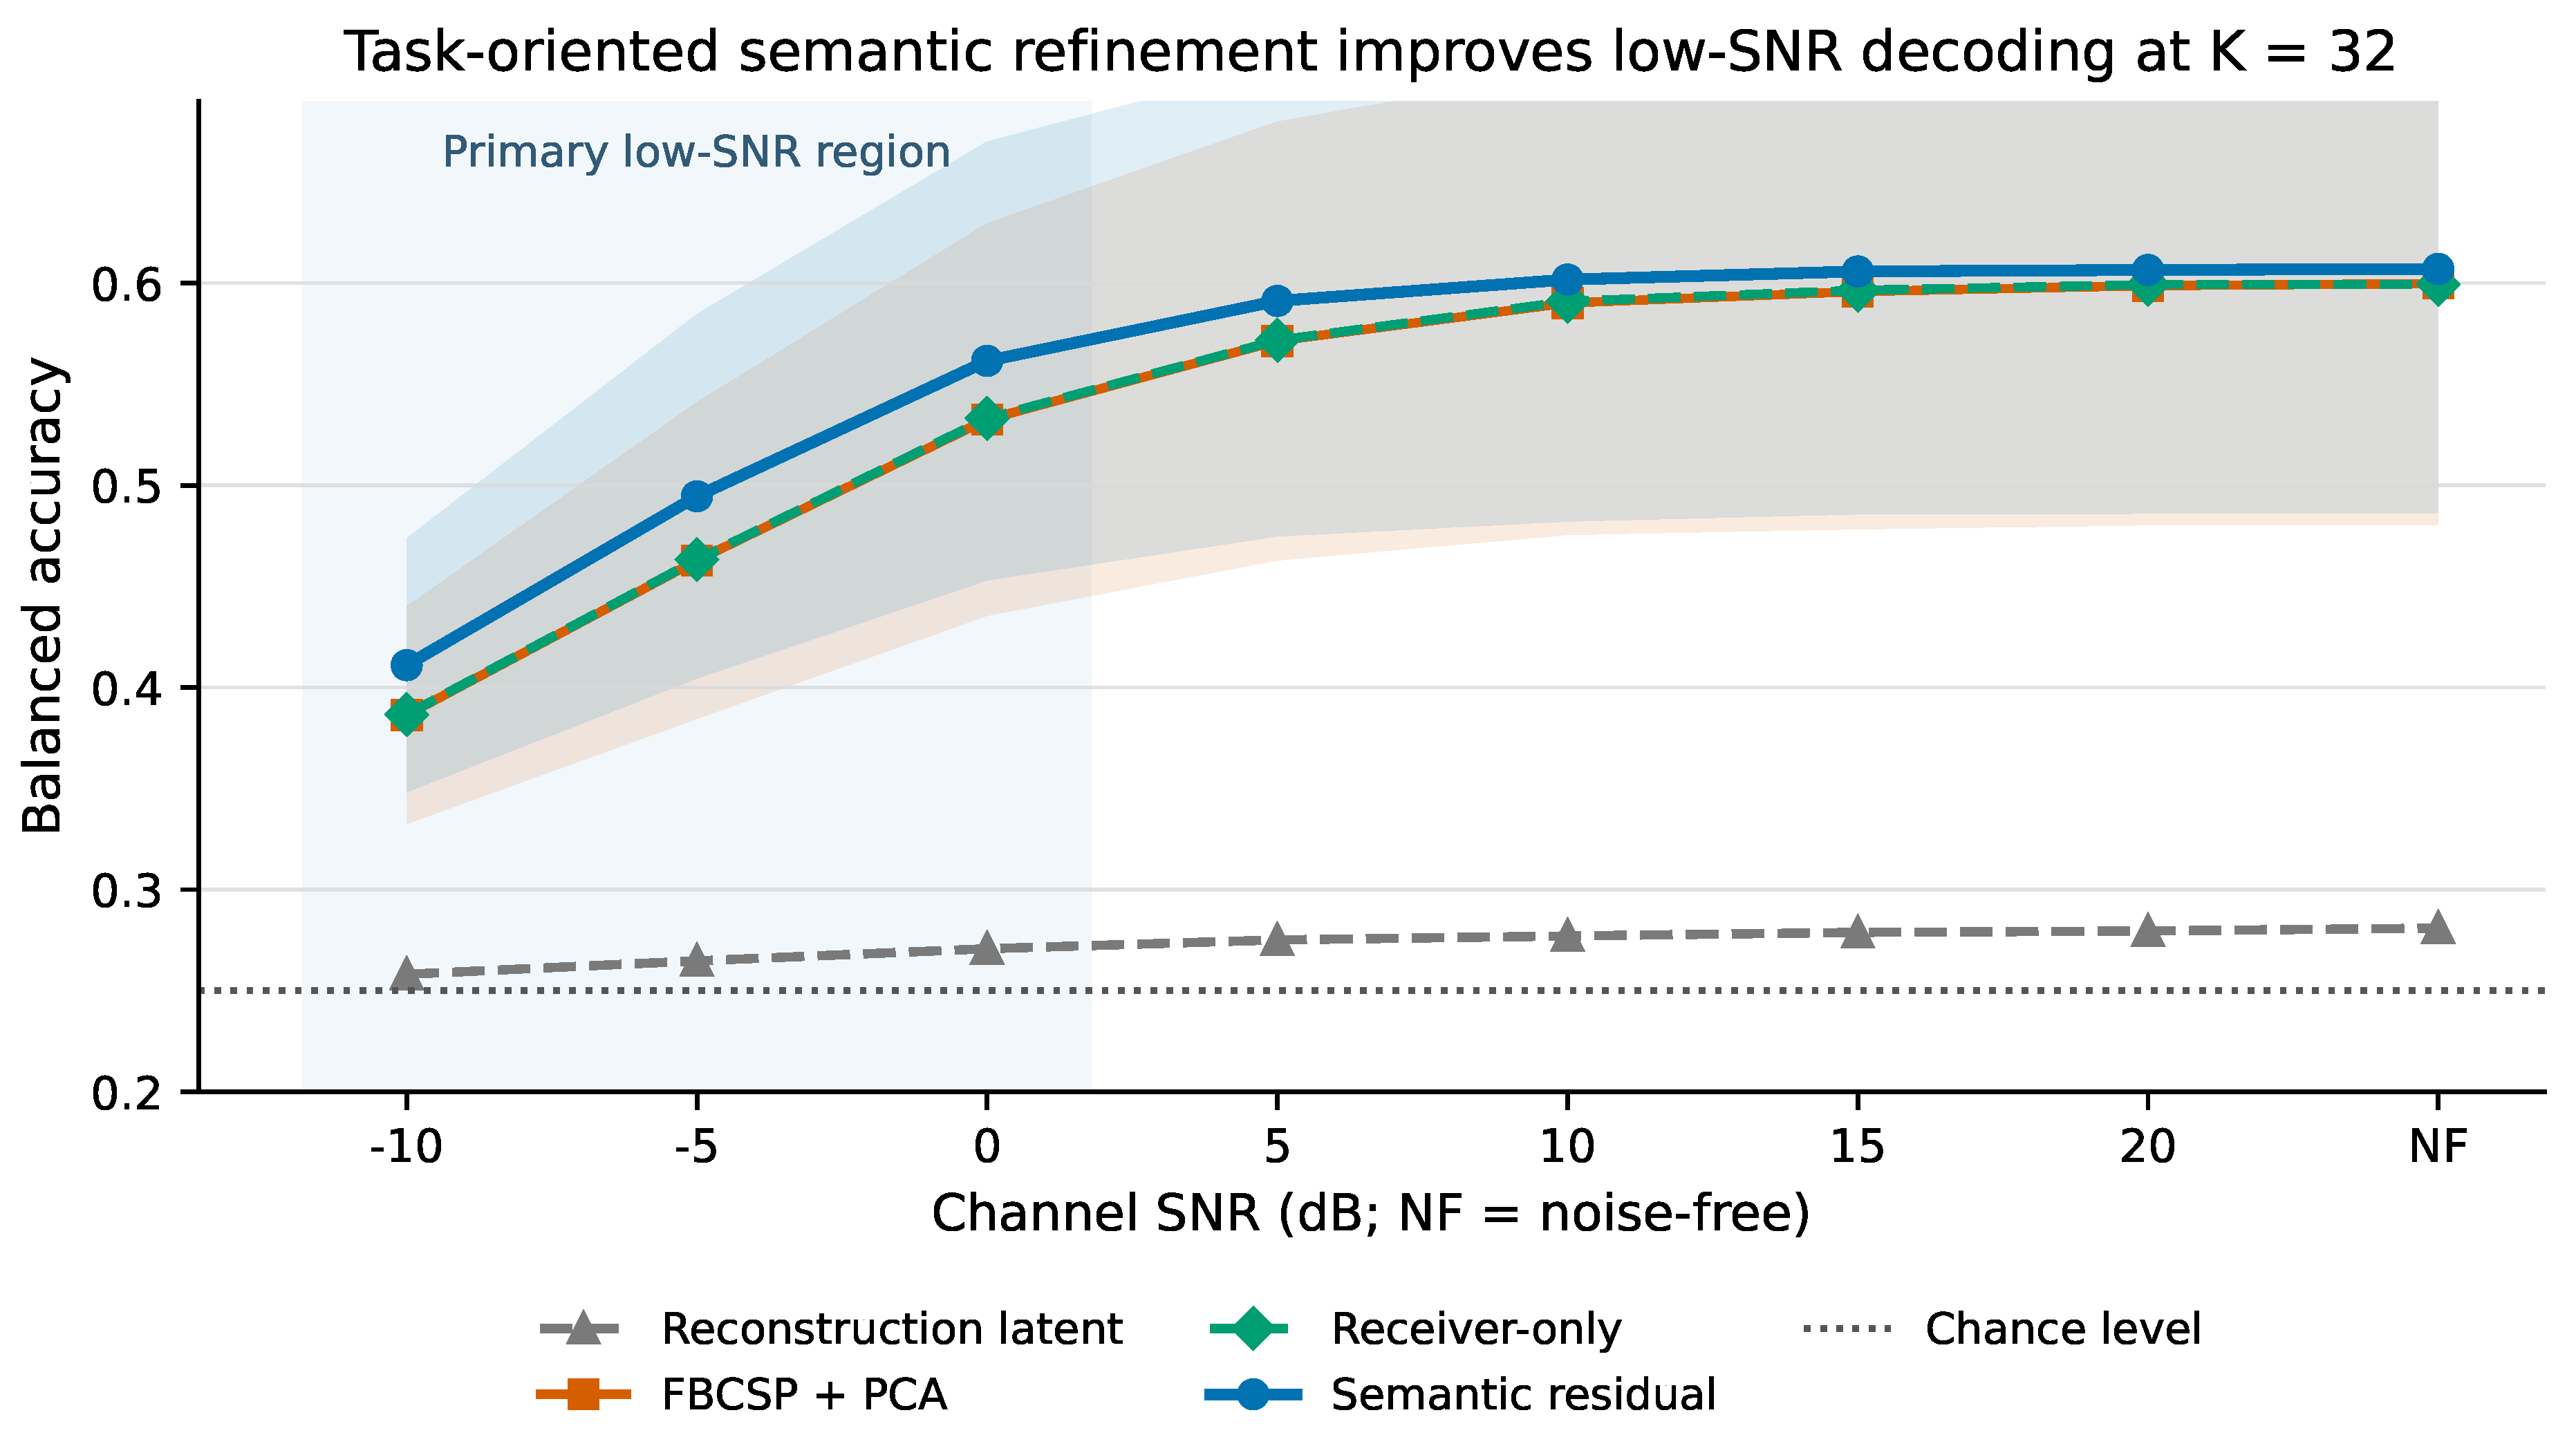
Figure 3.
Balanced accuracy versus SNR for . Shading, 95% confidence intervals for the semantic and FBCSP–PCA curves; NF, noise-free; dotted line, chance level.
Figure 3.
Balanced accuracy versus SNR for . Shading, 95% confidence intervals for the semantic and FBCSP–PCA curves; NF, noise-free; dotted line, chance level.
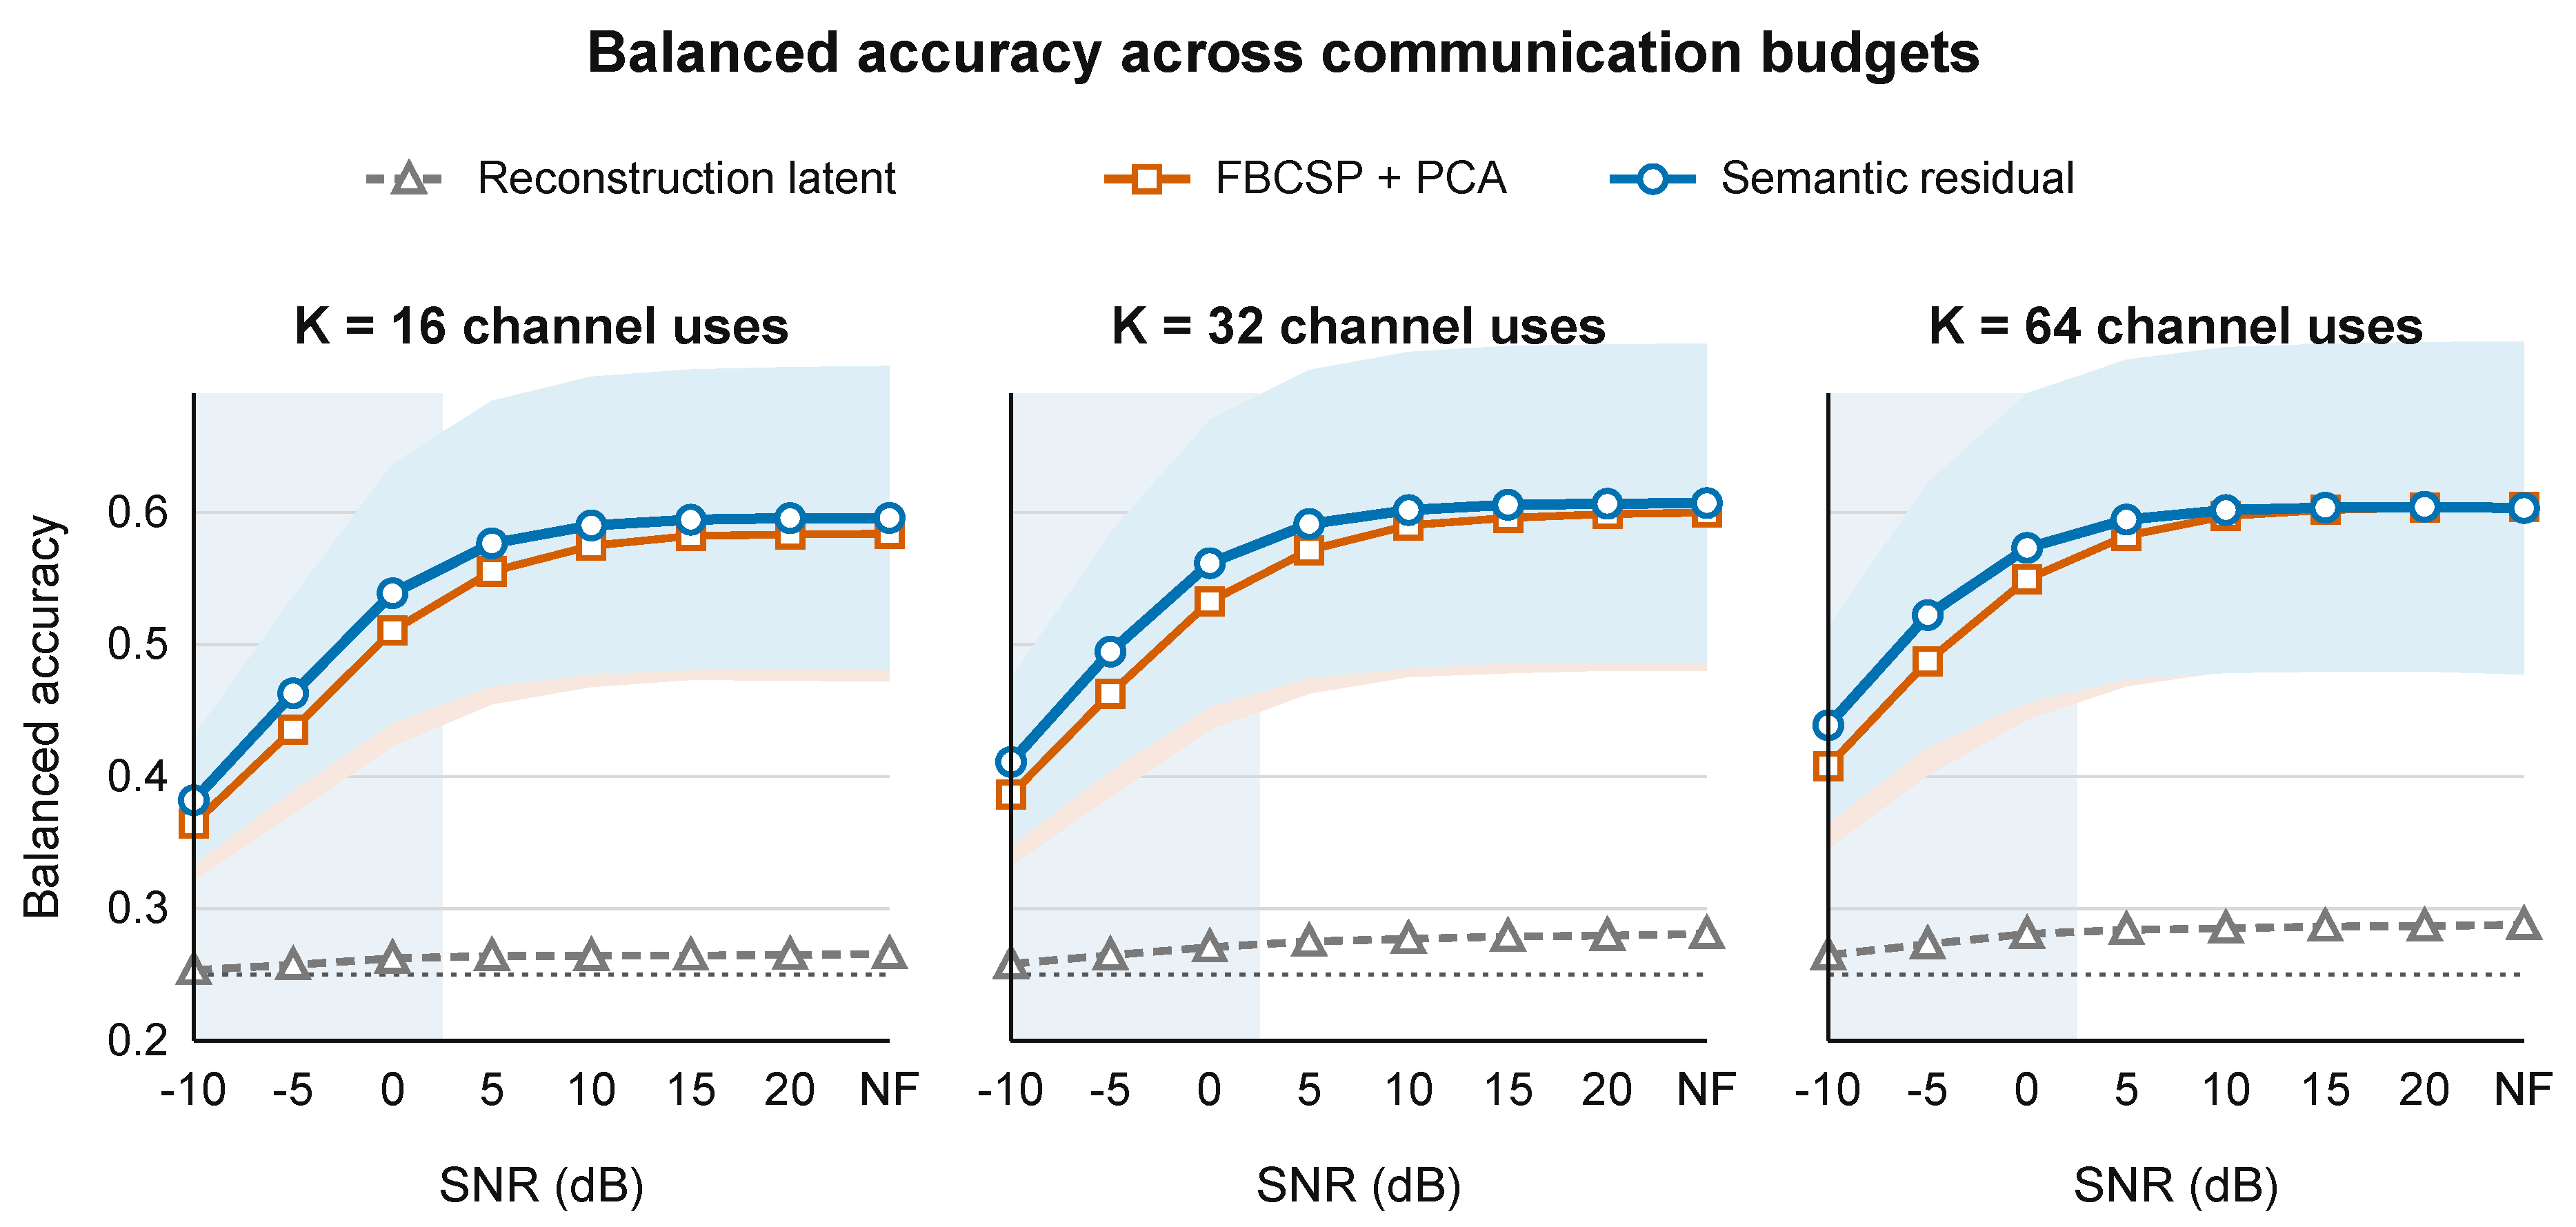
Figure 4.
Semantic-minus-FBCSP–PCA balanced-accuracy difference versus SNR. Shading, unadjusted 95% confidence intervals; asterisks, Holm-adjusted ; NF, noise-free.
Figure 4.
Semantic-minus-FBCSP–PCA balanced-accuracy difference versus SNR. Shading, unadjusted 95% confidence intervals; asterisks, Holm-adjusted ; NF, noise-free.
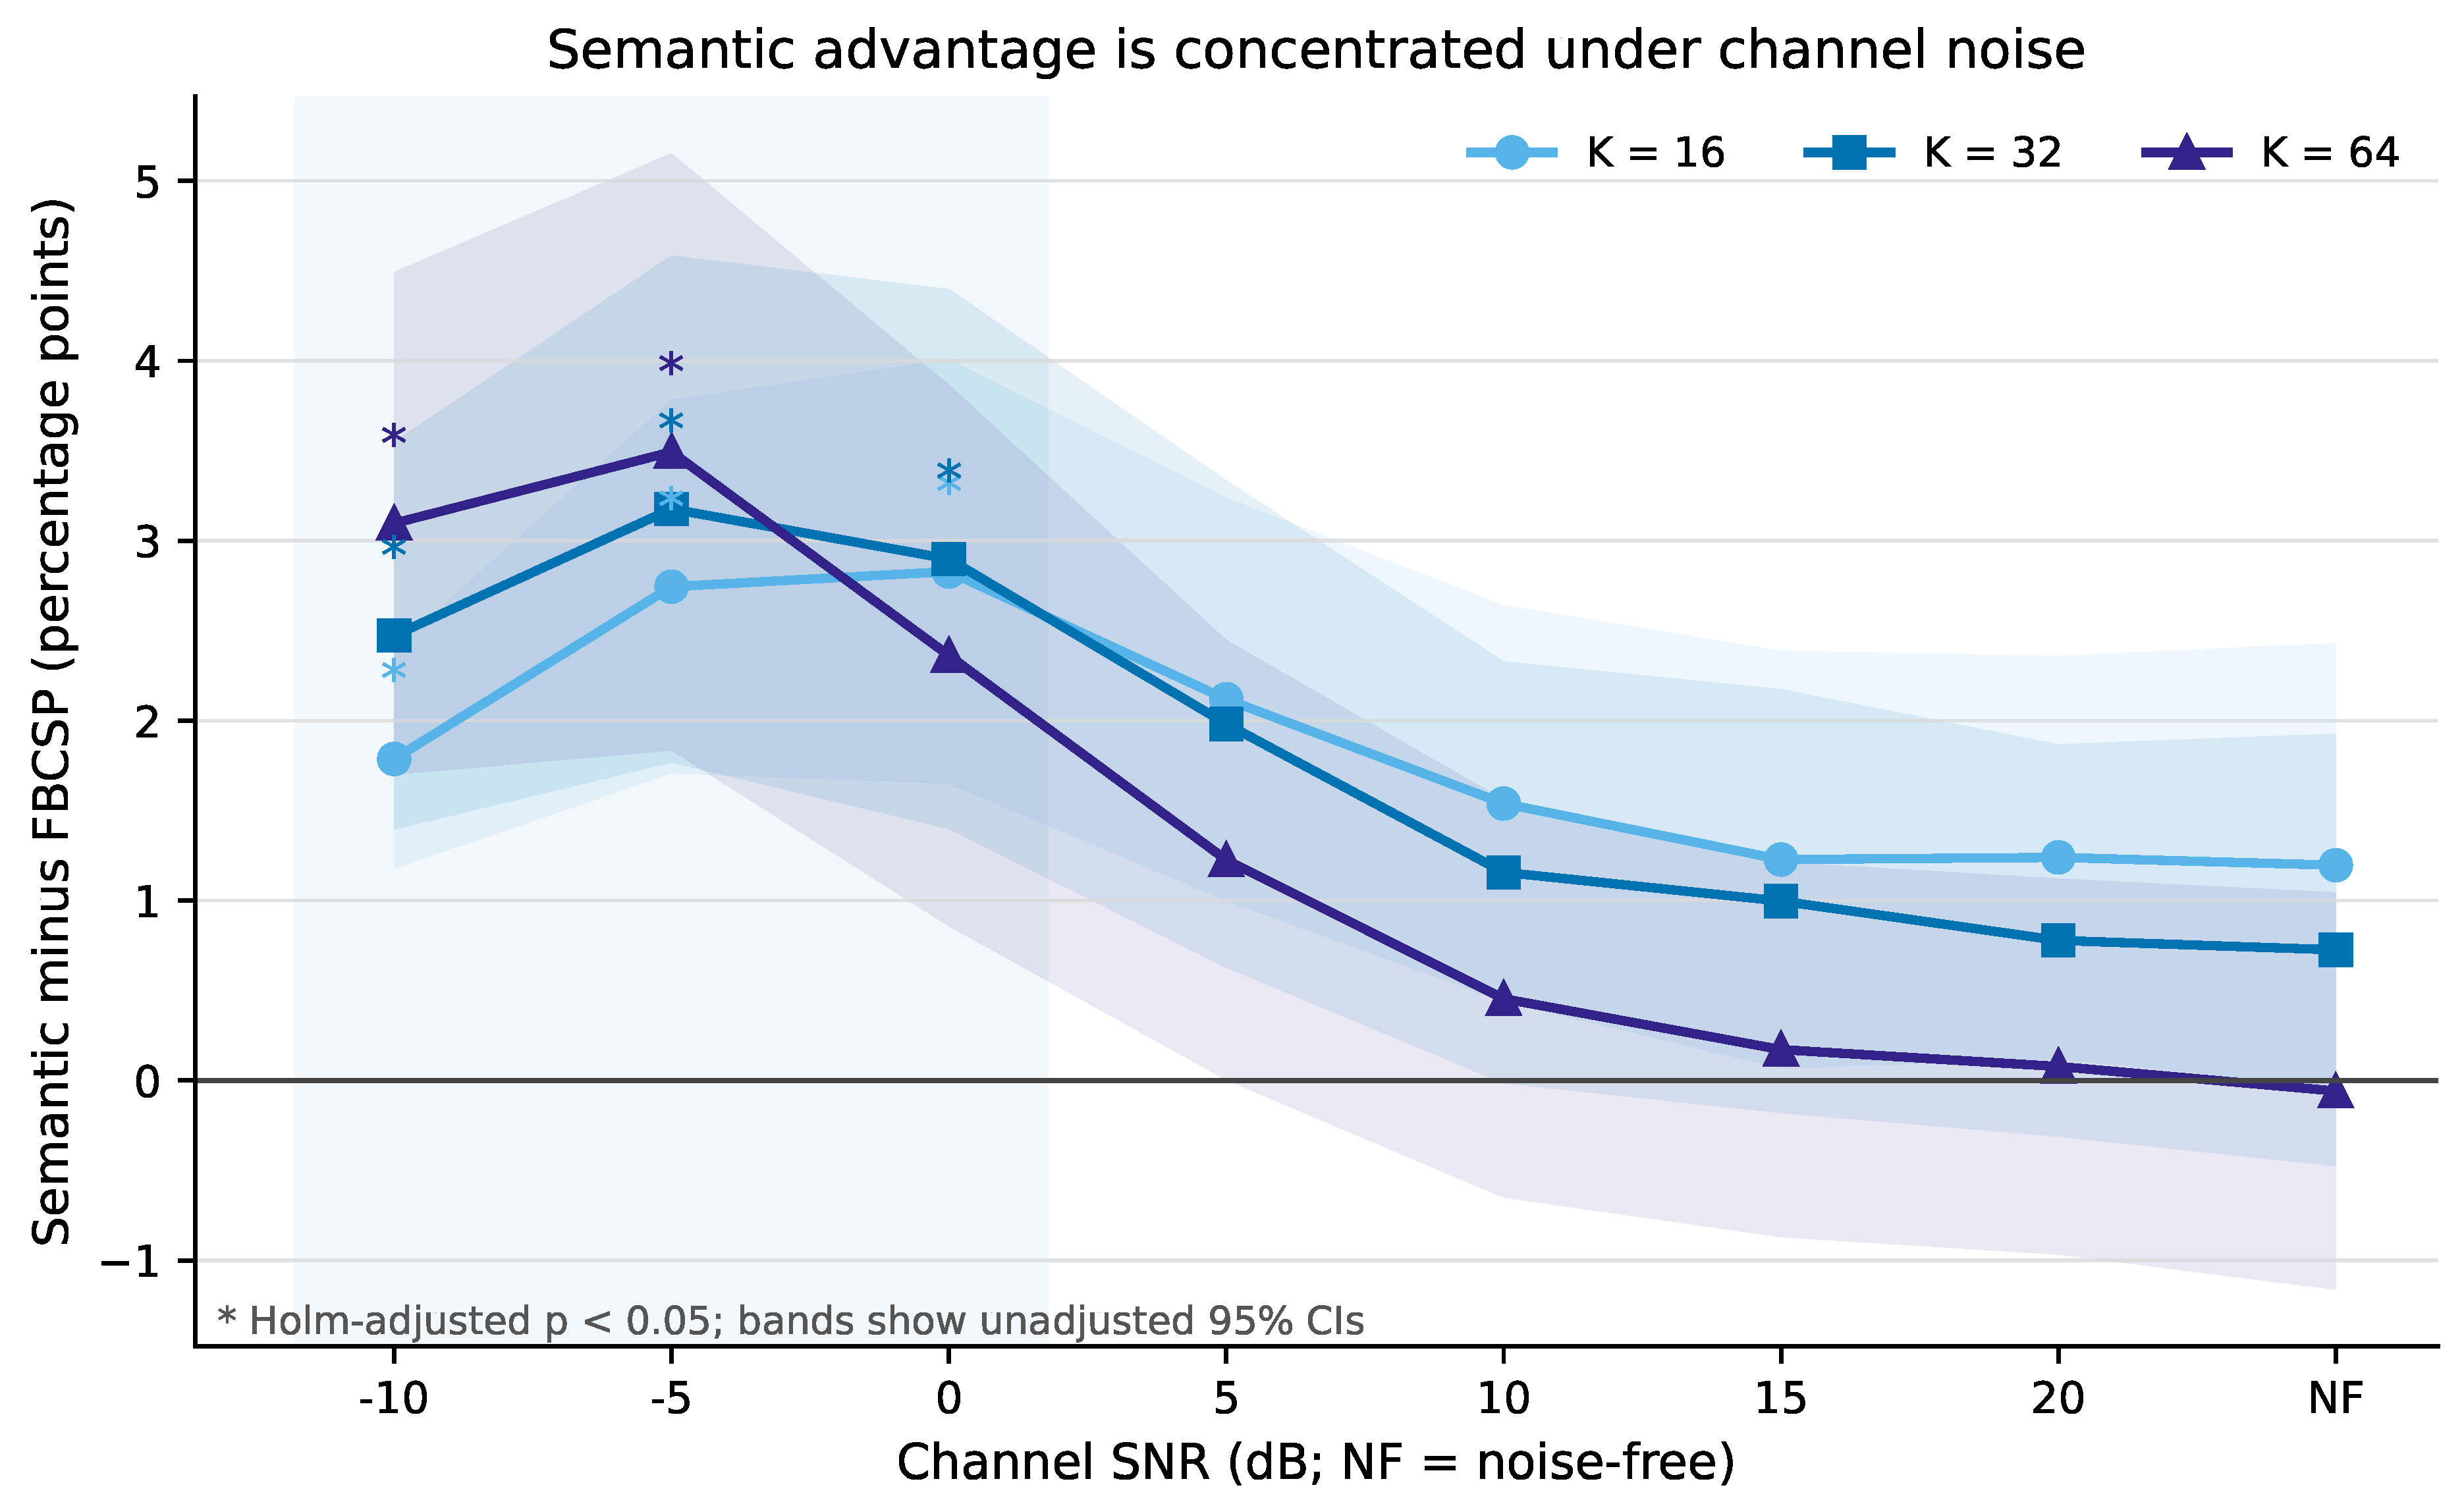
Figure 5.
Subject-level semantic-minus-FBCSP–PCA balanced-accuracy differences at low SNR (percentage points).
Figure 5.
Subject-level semantic-minus-FBCSP–PCA balanced-accuracy differences at low SNR (percentage points).
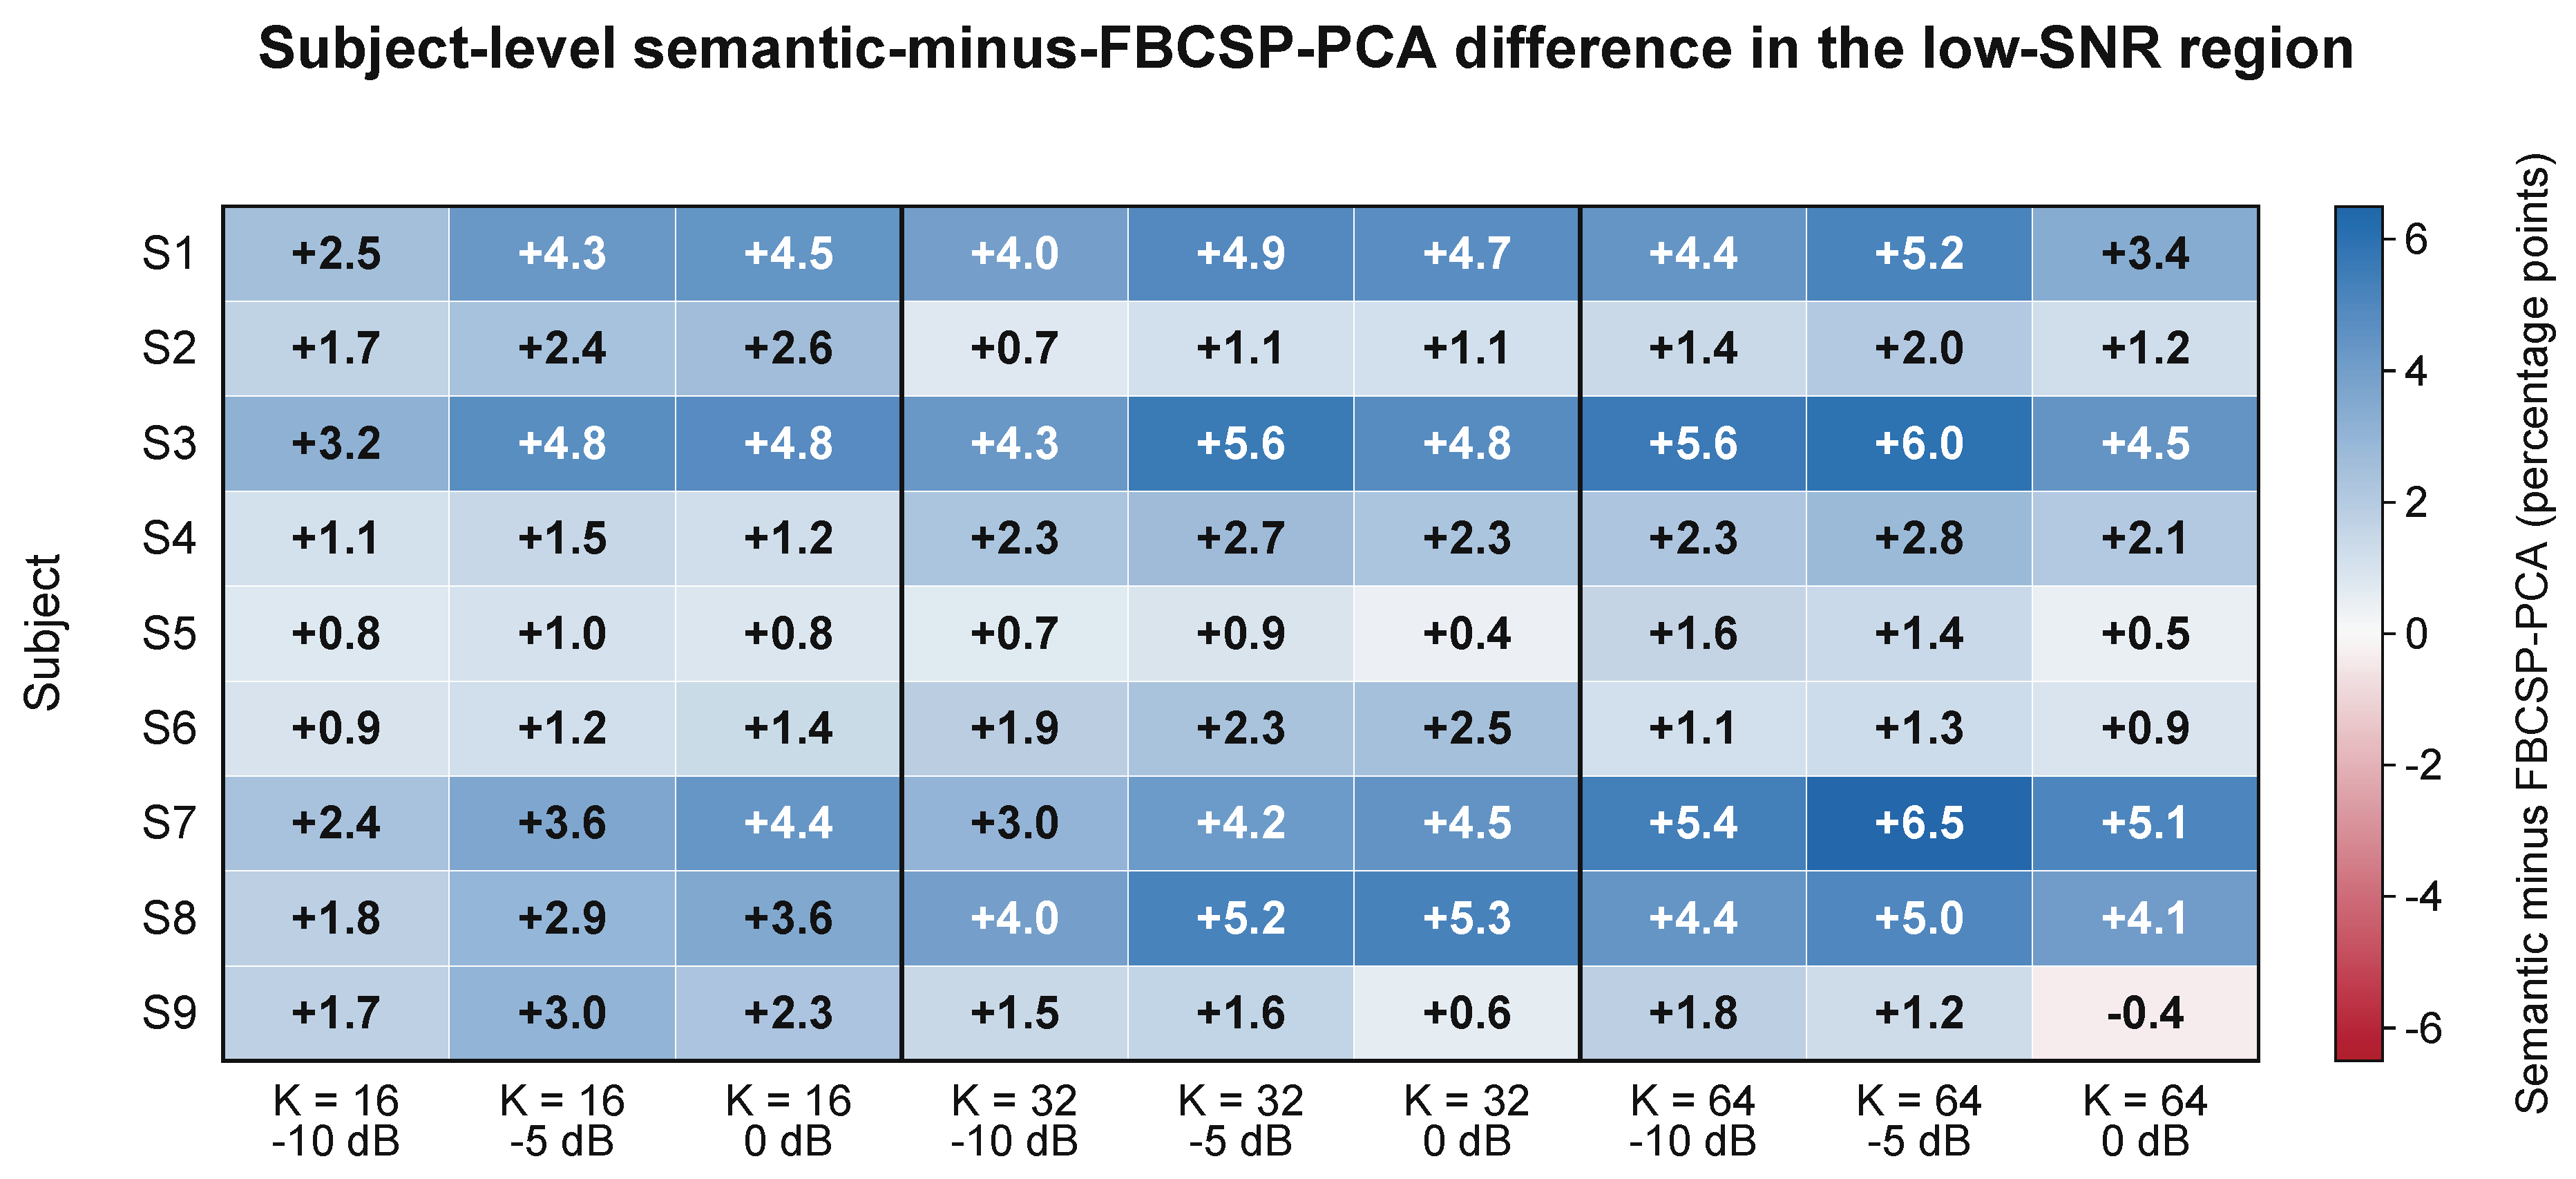

Table 1.
Neural architectures used in the compared methods.
| Component | Architecture |
|---|---|
| Common receiver classifier | Fully connected ; exponential linear unit; dropout 0.25; fully connected . |
| Reconstruction encoder | Conv1D , kernel 15, stride 2, padding 7; Conv1D , kernel 9, stride 2, padding 4; Conv1D , kernel 7, stride 2, padding 3; batch normalization, exponential linear unit, and dropout 0.25 after every convolution; adaptive average pooling to eight positions; fully connected . |
| Reconstruction decoder | Fully connected ; exponential linear unit; TConv1D , kernel 7, stride 2, padding 3, output padding 1; TConv1D , kernel 9, stride 2, padding 4, output padding 1; TConv1D , kernel 15, stride 2, padding 7, output padding 1; batch normalization and exponential linear unit after the first two transposed convolutions. |
| Semantic residual transformation | Layer normalization; fully connected ; Gaussian error linear unit; fully connected , with ; residual scale before final power normalization. |
Table 2.
Optimization and model-selection settings.
| Stage | Optimizer | Learning rate | Maximum epochs | Model-selection criterion |
|---|---|---|---|---|
| Conventional receiver | Adam | 300 | Mean validation balanced accuracy over the seven noisy SNRs. | |
| Reconstruction autoencoder | Adam | 300 | Mean validation reconstruction error over the seven noisy SNRs. | |
| Reconstruction receiver | Adam | 300 | Mean validation balanced accuracy over the seven noisy SNRs. | |
| Semantic residual warm-up | AdamW | 160 | Equation (12), subject to the preservation condition. | |
| Semantic joint refinement | AdamW | residual; receiver | 220 | Equation (12), subject to the preservation condition. |
| Classifier-only control | AdamW | 220 | Equation (12), subject to the preservation condition. |
Table 3.
Low-SNR comparison of semantic and conventional FBCSP–PCA transmission.
| K | SNR | Semantic BA (%) |
FBCSP–PCA BA (%) |
Difference (pp) 95% CI |
Subjects favoring semantic |
|
|---|---|---|---|---|---|---|
| 16 | dB | 38.21 | 36.42 | 1.79 [1.18, 2.40] | 9/9 | |
| 16 | dB | 46.30 | 43.55 | 2.74 [1.71, 3.78] | 9/9 | |
| 16 | 0 dB | 53.88 | 51.05 | 2.83 [1.65, 4.01] | 9/9 | |
| 32 | dB | 41.10 | 38.63 | 2.47 [1.40, 3.55] | 9/9 | |
| 32 | dB | 49.46 | 46.28 | 3.18 [1.77, 4.59] | 9/9 | |
| 32 | 0 dB | 56.15 | 53.26 | 2.90 [1.40, 4.40] | 9/9 | |
| 64 | dB | 43.89 | 40.79 | 3.10 [1.70, 4.49] | 9/9 | |
| 64 | dB | 52.22 | 48.73 | 3.49 [1.83, 5.15] | 9/9 | |
| 64 | 0 dB | 57.31 | 54.95 | 2.36 [0.86, 3.87] | 8/9 | 0.1014 |
Note: BA, balanced accuracy; pp, percentage points; CI, confidence interval. CIs are unadjusted; bold values are below 0.05.
Table 4.
Low-SNR classifier-only control results at .
| Panel A: Semantic minus classifier-only | |||
| SNR | Difference (pp) 95% CI |
Subjects with positive difference |
|
| dB | 2.44 [1.37, 3.51] | 9/9 | |
| dB | 3.14 [1.75, 4.53] | 9/9 | |
| 0 dB | 2.84 [1.35, 4.33] | 9/9 | |
| Panel B: Classifier-only minus FBCSP–PCA | |||
| SNR | Difference (pp) 95% CI |
Subjects with positive difference |
|
| dB | 0.033 [0.005, 0.061] | 7/9 | 0.1974 |
| dB | 0.041 [, 0.0818] | 8/9 | 0.3050 |
| 0 dB | 0.055 [0.005, 0.106] | 6/9 | 0.2468 |
Note: pp, percentage points; CI, confidence interval. CIs are unadjusted; bold values are below 0.05.
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (http://creativecommons.org/licenses/by/4.0/).
Copyright: This open access article is published under a Creative Commons CC BY 4.0 license, which permit the free download, distribution, and reuse, provided that the author and preprint are cited in any reuse.