

Submitted:
04 October 2026
Posted:
07 October 2026
Read the latest preprint version here
Abstract
The Minimum Vertex Cover problem is NP-hard. Its classical polynomial-time approximation ratio is ~2; under \(\mathrm{P}\neq\mathrm{NP}\) no polynomial-time algorithm achieves \(\sqrt{2}-\varepsilon\) for any fixed \(\varepsilon>0\) (Khot–Minzer–Safra), and under the Unique Games Conjecture (UGC) not even \(2-\varepsilon\) (Khot–Regev). We present FindVertexCover, a linear-time ensemble algorithm that computes nine independently valid vertex covers of the input graph \(G=(V,E)\) and returns the smallest. Four of the candidates—and the redundant-vertex pruning pass applied to each—adapt the published Hvala ensemble, which proves an unconditional \(O(n+m)\) time and space bound and a worst-case ratio at most 2, where \(n=|V|\) and \(m=|E|\); Salvador therefore contains Hvala and inherits its ratio-2 guarantee. Salvador adds a Min-to-Min heuristic, a primal-dual 2-approximation, a planar forest-core reduction to a weighted Minimum Independent Dominating Set gadget solved by a Baker-style pass, and, new in this version, two further candidates: (i)~the bipartite planar oriented-incidence reduction, whose auxiliary graph we prove is always a disjoint union of even cycles and single edges, so its minimum-weight vertex cover is computed \emph{exactly} by a linear-time cycle dynamic program; and (ii)~a budgeted (1,2)-swap iterated local search that improves the best cover found and stops after \(O(n+m)\) work. The whole ensemble runs in worst-case \(O(n+m)\) time and unconditionally achieves ratio at most 2. On the 68 DIMACS clique-complement instances of the NPBench collection, Salvador never returns a larger cover than Hvala: it is strictly smaller on 48 instances and equal on the other 20, with mean ratio 1.014 against 1.025. On a reproducible suite of 1746 graphs—1718 small graphs with exact optima, all solved optimally, and 28 large adversarial graphs with up to 200,000 vertices, whose ratios are certified by matching, clique-packing and spectral lower bounds—the ratio never exceeds 1.17. We conjecture a universal ratio of at most \(7/5=\sqrt{2}-\varepsilon_0\) with \(\varepsilon_0=\sqrt{2}-7/5>0\); by the Khot–Minzer–Safra theorem a proof of this conjecture would imply \(\mathrm{P}=\mathrm{NP}\), and a proof of any constant ratio below 2 would refute UGC under \(\mathrm{P}\neq\mathrm{NP}\). These consequences are conditional: the conjecture is supported by experiments, not proved. An open-source implementation is released as the Salvador package (v0.0.9).
Keywords:
vertex cover
; approximation algorithm
; ensemble heuristics
; bipartite planar reduction
; local search
; unique games conjecture
; P versus NP
MSC: 05C69; 05C70; 68Q25; 90C27
1. Introduction
The Minimum Vertex Cover (VC) problem is one of the twenty-one NP-complete problems identified by Karp [1]. Given an undirected graph , a set is a vertex cover if every edge of E has at least one endpoint in C; the goal is to find a minimum-cardinality vertex cover, denoted . Vertex cover is central to computer science, modelling guard placement, network monitoring, error-correcting codes, and serving as the canonical starting point for parameterised and approximation algorithms.
The approximation landscape for VC is unusually well charted. The classical maximal-matching algorithm achieves a 2-approximation in linear time [2]; LP-based refinements by Karakostas [3] and Karpinski and Zelikovsky [4] reach factor , which is but falls short of a constant . From the hardness side, Dinur and Safra [5] ruled out any ratio below under , and Khot, Minzer, and Safra [6,7,8], proving the 2-to-2 games conjecture, raised this unconditional barrier to for every fixed under . Under the Unique Games Conjecture [9], Khot and Regev [10] showed that no polynomial-time algorithm can approximate Minimum Vertex Cover within factor for any fixed . Thus a proved constant ratio strictly below for a polynomial-time algorithm would imply , and a proved constant ratio strictly below 2 would refute the Unique Games Conjecture under .
Against this backdrop, we present an algorithm—implemented as the Salvador Python package (v0.0.9)—that produces a vertex cover whose size is provably never more than twice the optimum and, on every instance we have tested under the default call , far closer to it. The algorithm, called FindVertexCover, is an ensemble: it computes nine independently valid candidate covers and returns the smallest. Four of the candidates and the pruning pass adapt the ensemble published as the Hvala algorithm [11,12], which proves an unconditional time and space bound and worst-case approximation ratio at most 2; Salvador therefore contains Hvala. Salvador adds five candidates of its own, described below. The algorithm operates in four phases.
- 1.
- Preprocessing. Self-loops are discarded; isolated vertices are removed (they appear in no edge and need not be covered).
- 2.
- Ensemble of linear-time candidates. Seven independent heuristics are run on the cleaned graph G: maximal matching, bucket-queue maximum-degree greedy, and a degree-1 weighted-reduction ("Hallelujah") heuristic (all three adapted from Hvala [11]; the Hallelujah resolution is made selection-aware in this version); a Min-to-Min bucket heuristic and a primal-dual/local-ratio 2-approximation; SolveVC, which reduces G to a weighted MIDS instance on a planar forest-core gadget and solves it with a Baker-style pass [13] of layering width (at the default , and the pass is its linear-time greedy baseline); and BipartitePlanarCover, the oriented-incidence reduction to a bipartite planar auxiliary graph, solved exactly by a linear-time cycle dynamic program.
- 3.
- Linear-time pruning.PruneRedundantVertices (Hvala’s fourth strategy) removes from each candidate every vertex all of whose neighbours are already in the cover; it is applied to every candidate and to their union.
- 4.
- Budgeted local search.LocalSearchCover takes the smallest pruned candidate and improves its complementary independent set by -swaps and perturbations, stopping after adjacency scans; it never returns a larger cover than its input. The smallest of the nine resulting covers is returned.
At the default every one of the nine candidates runs in worst-case time, where and , so the whole ensemble is . This holds in particular for the Min-to-Min heuristic, whose bucket-queue argument pops and processes one minimum-degree vertex per step, for the bipartite planar reduction, whose auxiliary graph is solved exactly by a linear-time dynamic program (Lemma 1), and for the local search, whose work is capped by an explicit budget.
Contributions
The main contributions of this paper are:
- A linear-time ensemble vertex-cover algorithm with nine candidates, four of which adapt the published Hvala ensemble [11], so that Salvador contains Hvala and inherits its guarantees.
- A structural lemma (Lemma 1) showing that the oriented-incidence auxiliary graph of the bipartite planar reduction is a disjoint union of even cycles and single edges, so its exact minimum-weight vertex cover takes time; and a residual, minimum-degree-ordered variant of the reduction that improves its covers further.
- A selection-aware resolution rule for the Hallelujah heuristic that removes its redundancy on graphs whose vertices share one degree, and a budgeted -swap iterated local search that never worsens the ensemble’s best cover.
- An unconditional worst-case approximation ratio of at most 2 for every graph (Theorem 2).
- A reproducible suite of graphs on which the exact or certified ratio never exceeds , using certified lower bounds (exact bipartite matching, Karp–Sipser matching, clique packing and a Laplacian Hoffman bound) that are much sharper than the maximal-matching bound used before, together with a per-family report of which candidate wins.
- Two conjectures with conditional consequences: a universal ratio below 2 would refute UGC under (Theorem 4), and a universal ratio of at most would imply (Theorem 5).
- A head-to-head comparison with Hvala on the 68 DIMACS clique-complement instances of NPBench (Section 7.3), on which Salvador never returns a larger cover and returns a strictly smaller one on 48 instances.
- An open-source implementation, Salvador v0.0.9.
The paper is organised as follows. Section 3 describes the algorithm and provides pseudocode. Section 4 proves correctness. Section 5 analyses the approximation ratio and discusses conditional consequences for the Unique Games Conjecture and for versus . Section 6 establishes the time complexity. Section 7 reports empirical results on a reproducible test suite. Section 8 concludes.
2. Research Data
The algorithm is implemented in the Python package Salvador, freely available on the Python Package Index [14]. The current version is v0.0.9; the accuracy parameter drives only the Baker-PTAS candidate’s layering (Remark 2), not the ensemble’s linear-time guarantee, which holds at the default regardless. Code metadata is summarised in Table 1, the local reduction gadget of the SolveVC candidate is depicted in Figure 1, and the oriented-incidence gadget of the bipartite planar reduction in Figure 2.
3. Description of the Algorithm
Salvador’s entry point, FindVertexCover (Algorithm 1), is an ensemble. It computes seven independently valid candidate covers by seven different linear-time heuristics ( and ), prunes each with PruneRedundantVertices, prunes their union to form , improves the smallest of these eight with a budgeted local search to form , and returns the smallest of the nine. Four of the candidate heuristics—maximal matching (), bucket-queue maximum-degree greedy (), the degree-1 weighted-reduction heuristic (), and the pruning pass itself—adapt the ensemble published as the Hvala algorithm [11,12], which proves that they run in time and space and that the best of them already achieves worst-case approximation ratio at most 2. Salvador adds the Min-to-Min heuristic (), a primal-dual/local-ratio 2-approximation (), the planar forest-core MIDS reduction SolveVC (), the bipartite planar oriented-incidence reduction BipartitePlanarCover (), and the local search LocalSearchCover (). We present pseudocode for the main ensemble, the candidates, and the pruning pass.
3.1. Main Ensemble
|
Algorithm 1:
FindVertexCover
|
|
3.2. The Hvala-Adapted Candidates
Candidates , , and , and the pruning pass shared by the candidates, adapt the ensemble of Vega’s Hvala algorithm [11], which proves an unconditional time and space bound and worst-case approximation ratio at most 2 for every graph. (Hvala strategy 1) computes a maximal matching in time and returns both endpoints of every matched edge; this is the classical linear-time 2-approximation [2]. (Hvala strategy 2, given as Algorithm 2) repeatedly removes a maximum-degree active vertex using a bucket queue indexed by degree, in amortized time; its worst-case approximation ratio is by Johnson’s classical bound [2], where is the maximum degree. (Hvala strategy 3, the "Hallelujah heuristic") replaces every vertex u of degree d by d auxiliary copies of weight , one per incident edge, so that the auxiliary instance is a perfect matching with one auxiliary edge per original edge; it chooses one endpoint of each auxiliary edge and maps the choice back to G, in time.
Selection-aware resolution of the Hallelujah heuristic.
Earlier versions resolved each auxiliary edge independently, by weight and then by a label tie-break. When all vertices share one degree, every weight ties, so the cover was decided by labels alone and could contain almost every vertex ( vertices on the n-cycle, 251 of 256 on the 8-cube). Version 0.0.9 scans the original vertices in ascending order of degree (bucket sort) and resolves the auxiliary edges at u by three rules in priority order: (1) if either endpoint’s original vertex is already selected, the edge is covered and nothing is added; (2) otherwise the endpoint of strictly smaller weight (the higher-degree vertex) is selected, and if that is u the scan of u stops; (3) on a tie, the neighbour of u is selected. Every auxiliary edge is inspected at most twice, so the running time stays . Before pruning, the candidate drops from 98 to 50 vertices on and from 397 to 200 on the torus, both optimal.
| Algorithm 2:BucketDegreeGreedy — Hvala strategy 2 |
|
3.3. The Salvador-Specific Candidates
() is a single pass implementing the primal-dual/local-ratio method [15]: it scans every edge once, raises a dual variable at each endpoint up to the remaining slack, and adds an endpoint to the cover whenever its budget saturates; this is a standard 2-approximation.
(), given as Algorithm 3, repeatedly pops a single currently-minimum-degree active vertex v from a bucket queue and adds an arbitrary current neighbor of v to the cover, then updates degree buckets exactly as in Algorithm 2.
Remark 1
(Why the bucket-queue argument stays linear). Algorithm 3 pops and processes exactly one minimum-degree vertex per outer-loop iteration and selects its covering neighbor in (an arbitrary, not degree-minimal, neighbor), with no rescan of a bucket at any step. Consequently the total number of bucket pushes and pops is by the same amortized argument as Algorithm 2 (Theorem 6), and the time per processed vertex stays within a constant factor regardless of graph regularity.
| Algorithm 3:MinToMinCover — linear-time-corrected |
|
3.4. Weighted MIDS Gadget and Planar Solve
Algorithm 4 () implements the reduction from Vertex Cover to weighted Minimum Independent Dominating Set on a planar core, invokes the -controlled Baker PTAS pass, and repairs non-core edges in one scan.
| Algorithm 4:SolveVC |
|
The pass BakerPtasWeightedIDS (Algorithm 5) is the accuracy-controlled weighted-IDS solver invoked by Salvador. It layers the gadget by BFS distance, removes each residue class modulo in turn, solves the remaining components exactly by tree-decomposition dynamic programming, greedily repairs the removed slab, and keeps the lightest independent dominating set found over the k shifts; the greedy maximal independent set of Algorithm 6 is the baseline and a safe fallback. Because the gadget H built from a forest core is itself a forest (Section 3), each component is a tree and the per-component solve ExactWeightedIDS is an exact linear-time tree dynamic program; which shifts the PTAS explores, however, depends on , so the decoded cover is parameter-sensitive and need not be monotone in .
Remark 2
(On the accuracy parameter ). The public entry pointfind_vertex_coverfixes the default , which is the configuration analysed throughout this paper. The parameter controls only candidate ’s Baker layering width ; at the default , and reduces to the greedy maximal-independent-set baseline of Algorithm 6, which is what keeps —and hence the whole ensemble—strictly (Theorem 6). The gadget construction is itself ε-independent; ε enters only the IDS pass. Passing makes only more thorough (and costs an extra factor); it is intended for offline quality experiments on in isolation, not the default production call. ’s returned candidate depends on ε through the layer choices, and on the vertex ordering through the spanning-forest construction; the ensemble as a whole is comparatively insensitive to both, since provide independent coverage (Section 5.7). All claims below refer to the default call unless otherwise noted.
| Algorithm 5:BakerPtasWeightedIDS |
|
| Algorithm 6:GreedyWeightedMIS — baseline |
|
Figure 1 shows the local gadget introduced for each core edge in Algorithm 4. The nodes and are the weight-one cover-choice nodes, and are zero-weight pendant nodes, and the hub has penalty weight .
As illustrated in Figure 1, the gadget H is always planar because is a forest and H is a subdivision of augmented with pendant leaves ; subdivisions of planar graphs are planar, and appending pendant leaves preserves planarity. The hub weight enforces coverage inside the core: in any optimal MIDS for H, including a hub is more expensive than selecting all vertex nodes. The SpanningForestCore routine builds by Union-Find in one pass over E and records each cycle-closing edge in for the final repair scan.
3.5. Bipartite Planar Oriented-Incidence Reduction
Candidate revisits the reduction of an earlier version of this work, in which every connected component is mapped to a weighted bipartite planar auxiliary graph B whose minimum-weight vertex cover is decoded into a cover of G. Vertices are processed in a fixed order; when u is processed, every edge () to a not-yet-processed neighbour creates two oriented-incidence nodes and , of weights and , joined by a forcing edge; consecutive incidences are joined by local edges, closed by when . A cover S of B is decoded to . Figure 2 shows the gadget of one vertex.
Lemma 1
(Structure of the auxiliary graph). For every graph G and every processing order, B is a vertex-disjoint union of even cycles (one for each processed vertex u with unprocessed neighbours at its turn) and single edges (for ). In particular B is bipartite and planar, and .
Proof.
Each original edge is handled exactly once, when the first of its endpoints, say u, is processed: afterwards u is processed, so the edge is never handled again from v. Hence the two nodes created for it are distinct from all others and occur only in the gadget of u, which gives and makes the gadgets of different vertices vertex-disjoint. Inside the gadget of u the edges are the forcing edges , the local edges for , and the closing edge , which together form the closed walk through distinct nodes: a cycle for and a single forcing edge for . Even cycles and single edges are bipartite and planar, and so is their disjoint union. □
Lemma 1 shows that the bipartiteness and planarity checks of the earlier reduction always succeed, and, more importantly, that the minimum-weight vertex cover of B needs no flow computation: on a path, a dynamic program over “node included / excluded” states computes an optimum in time linear in its length, and a cycle reduces to two paths by fixing whether its first node is in the cover. Summed over all gadgets this is , and it returns an optimal minimum-weight vertex cover of B. We verified this equality against an integer-programming solver on 150 random graphs and three processing orders; with the manuscript’s processing order the linear-time version reproduces 35 of the 43 cover sizes logged for the earlier implementation on the DIMACS clique complements and is smaller on 6 of the remaining 8 (the differences come from ties among optimal auxiliary covers and from the pruning order).
Residual variant.
Because B is solved exactly gadget by gadget, the processing order and the weights are free design choices. The residual variant always gives the next gadget to a vertex of minimum residual degree (degree in the subgraph of still-uncovered edges), weights the gadget by residual degrees, and deletes decoded vertices from the residual graph. Since u has minimum residual degree d, every neighbour has residual degree at least d, so the neighbour side of the cycle weighs , which is the weight of the u side; with ties broken toward the neighbours, the exact cycle solve selects the neighbour side. The decoded cover is therefore the complement of a greedy minimum-degree maximal independent set, computed in with a degree-indexed bucket queue in which every residual edge deletion lowers the bucket pointer by at most one. Candidate evaluates the manuscript-order and residual variants, prunes both, and keeps the smaller (Algorithm 7). On the 43 DIMACS clique complements the mean ratio is for the manuscript order and for the residual variant.
| Algorithm 7:BipartitePlanarCover |
|
3.6. Linear-Time Pruning
Algorithm 8 removes redundant vertices from a candidate cover in a single forward pass, running in total time.
| Algorithm 8:PruneRedundantVertices |
|
3.7. Budgeted Local Search
A vertex cover C is the complement of an independent set , so every vertex added to S is a vertex removed from C. Candidate improves the best of through its complementary independent set with the -swap neighbourhood of Andrade, Resende, and Werneck [16]. For let . A -swap removes a vertex and inserts two non-adjacent neighbours of x with , enlarging S by one; vertices left with are inserted as well. An iterated local search step forces a non-solution vertex into S, evicts its solution neighbours, re-inserts freed vertices, and runs swaps around the change; the step is kept if does not decrease and is undone through an undo log otherwise.
The swap test at x costs over its 1-tight neighbours v: when looking for a partner w of v, the scan of the 1-tight list stops at the first non-neighbour of v, so it never costs more than . Every primitive is charged its exact scan cost, and the search stops once the work exceeds , so Algorithm 9 runs in time for the fixed constant b. The live set S is always the best seen, since worsening steps are undone, so .
| Algorithm 9:LocalSearchCover |
|
4. Correctness of the Algorithm
Theorem 1.
Algorithm 1 always returns a valid vertex cover of the input graph G.
Proof.
We must show that every edge has at least one endpoint in the output C. Isolated vertices are removed in preprocessing and appear in no edge, so they need not be covered. It suffices to show (a) each of and is individually a valid vertex cover of the cleaned graph, (b) pruning a valid cover with Algorithm 8 leaves it valid, (c) the union of valid covers is a valid cover, and (d) is valid, since the output is then over the sizes of nine vertex sets each shown valid, and validity does not depend on which has minimum size.
(a) Each raw candidate is valid. takes both endpoints of every matched edge of a maximal matching M; every edge either belongs to M (both endpoints in ) or is not in M, in which case maximality of M forces at least one endpoint to already be matched by some edge of M (otherwise that edge could extend M), hence in . (Algorithm 2) processes vertices from highest to lowest current degree and never terminates while an active vertex has positive degree, so every edge is incident to some vertex added to before both endpoints could reach degree 0 un-covered. represents every original edge by one auxiliary edge; when the endpoint processed first, say u, is scanned, the edge is either already covered (rule 1), or one of is selected (rules 2–3), or the scan of u stopped because u itself was selected, so every original edge is covered once all vertices are scanned. (Algorithm 3) adds, for every vertex v ever popped as the current minimum-degree active vertex, one of its active neighbors to the cover, which by the same maximal-matching-style argument as covers every edge incident to a processed vertex, and the loop runs until no active vertex remains. ’s primal-dual scan adds an endpoint of every edge whose slack is exhausted on both sides, which the local-ratio argument [15] guarantees for every edge. is shown valid below. For , every original edge is a forcing edge of B (Lemma 1); the exact cycle solve returns a vertex cover of each gadget, so or is selected and u or v is decoded. In the residual variant every edge at the processed vertex u is covered either by u or by its decoded neighbours before u is deleted, and the loop runs until no residual edge remains.
validity (core path). The Baker PTAS pass returns a feasible IDS S of the gadget H. The variable edge guarantees that at least one of is dominated for every . The repair loop then adds one endpoint of every core edge not yet covered by the decoded set , ensuring all core edges are covered.
validity (core and repair path). Let be the spanning-forest core, with and . The weighted MIDS pass and residual repair produce a cover valid for . Every edge in is inspected in the repair loop: if neither endpoint is in the running cover, the higher-degree endpoint is added. After the loop every edge of E has at least one endpoint in .
(b) Pruning preserves validity. A vertex is removed by Algorithm 8 only when every neighbour of v lies in C. In that case every edge incident to v is already covered by the neighbour side, so removing v leaves every edge covered.
(c) Unions of valid covers are valid. If and each cover every edge, then for every edge at least one of lies in (or in ), so covers as well; hence ’s starting union is valid before it, too, is pruned by (b).
(d) is valid. Algorithm 9 maintains an independent set S: a vertex is inserted only when it has no neighbour in S (it is free, or its solution neighbours were just evicted), and a -swap inserts two non-adjacent vertices whose only solution neighbour was removed. The complement of an independent set is a vertex cover, so is valid. □
5. Approximation Ratio and Conditional Consequences
5.1. Structural Setup and Notation
Let be the input graph with and . Write for the size of a minimum vertex cover of G and let . Let be the spanning-forest core built by candidate (SolveVC), let H be its weighted MIDS gadget of Algorithm 4, and set .
5.2. An Unconditional Ratio-2 Guarantee for the Ensemble
Unlike the case-by-case bounds on the individual candidates below, the ensemble as a whole admits an immediate, unconditional worst-case guarantee.
Theorem 2
(Unconditional ratio 2). For every undirected graph G, Algorithm 1 returns a vertex cover C with .
Proof.
Candidate takes both endpoints of every edge of a maximal matching M of G, so . Because M is a matching, any vertex cover must contain at least one endpoint of each of its disjoint edges, so , giving ; this is the classical linear-time 2-approximation [2], and it is exactly the bound Hvala proves for its own ensemble [11]. Algorithm 1 prunes (Theorem 1 shows pruning preserves validity and cannot increase size) and then returns the smallest of nine valid covers including the pruned , so . The local-search candidate cannot break this: . □
Theorem 2 holds unconditionally, for every and every graph; it does not depend on the planar forest-core machinery, the bipartite planar reduction or the local search. It is the guarantee Salvador inherits by containing the Hvala ensemble: because the output is the minimum over a family of candidates that includes Hvala’s maximal-matching candidate, no other candidate can make it worse. The role of the remaining candidates—and of the structural analysis in this section—is to explain why the ensemble is expected to do far better than this worst-case guarantee in practice (Section 5.7).
5.3. Gadget Cost Identity for the SolveVC Candidate
Lemma 2
(Cost identity). For any planar graph G with n vertices and gadget hub penalty , the minimum weighted MIDS cost of H equals : .
Proof.
Lower bound (). Let S be any feasible MIDS of H. For each hub , both and must be in S, so the edge is covered by . Any hub contributes weight , so any solution containing a hub has cost exceeding . Hence the minimum-cost MIDS contains no hub and is a valid vertex cover of G with .
Upper bound (). Let be an optimal vertex cover with . Define . Every hub has at least one of in because covers ; every variable-edge node is dominated by its companion. Thus is a valid MIDS of H with , giving . □
In Algorithm 4 the gadget is built from the spanning-forest core , so Lemma 2 applies with the core in the role of G, yielding . Because H is a forest, the per-component tree dynamic program is exact; the Baker PTAS, however, only explores the layer shifts, so at a fixed the decoded set is a near-minimum—not necessarily minimum—cover of the core. The total approximation loss is this layering slack plus the greedy repair of the non-core edges .
5.4. Elementary Bounds on the SolveVC Candidate
The next two results are stated for in isolation (they are properties of the candidate SolveVC produces before the ensemble compares it against ); they are superseded, as guarantees on the algorithm’s output, by Theorem 2, but they explain why is a useful candidate to include rather than redundant with the others.
Proposition 1
(Elementary bounds on ). For every graph G with n vertices and m edges, the candidate cover produced by Algorithm 4 satisfies and is a valid vertex cover of G.
Proof.
Validity is Theorem 1 restricted to the path. The decoded core cover has size at most , each repair step adds at most one vertex and is triggered at most once per edge, so and ; pruning only removes vertices. □
5.5. Linear Core Guarantee for SolveVC
Theorem 3
(Core cover guarantee). For any input graph G, Algorithm 4 covers every edge of the spanning-forest core before the final repair scan and covers every edge of G after the repair scan.
Proof.
The MIDS pass produces an independent dominating set of H. Decoding selects each v whose node appears in this set. If a core edge is not covered by the decoded set, the residual core-repair loop adds one endpoint, so all edges of are covered. The final repair loop scans and adds one endpoint for every still-uncovered edge, so every original edge is covered. □
5.6. Non-Planar Case
Lemma 3
(Subgraph optimality). .
Proof.
Any vertex cover of G is also a vertex cover of . □
Proposition 2
(Repair bound). For any input G, the path of Algorithm 4 adds at most one repair vertex per edge in after the core solve.
Proof.
The repair loop visits each edge in once. It does nothing when an endpoint is already in the candidate cover and otherwise adds exactly one endpoint. Thus the number of repair additions is at most . □
In practice the repair adds far fewer vertices than Proposition 2 suggests, because most removed edges are already covered by the near-optimal core solution on ; and even where overshoots, the ensemble as a whole is protected by Theorem 2 and by the other candidates.
5.7. The Empirical Conjecture for the Ensemble
Because the candidates draw on structurally different techniques—maximal matching, degree-greedy, degree-1 reduction, Min-to-Min, primal-dual, the planar forest-core MIDS reduction, the bipartite planar reduction, and local search—and the ensemble takes the smallest of all of them, we expect the ensemble’s worst case to sit strictly below the unconditional bound of Theorem 2, which is attained only when every candidate simultaneously realises its own worst case on the same instance.
Conjecture 1
(Universal ensemble approximation ratio). There is a constant such that, for every undirected graph G, Algorithm 1 with the default parameter returns a vertex cover C with
Conjecture 1 is not a theorem; Theorem 2 is the only unconditional bound proved in this paper. Section 7 reports empirical support for the conjecture: on a reproducible suite of test graphs, the exact or certified ratio never exceeds . Because this is far below , we also state the following stronger conjecture, with the explicit constant of the earlier version of this work.
Conjecture 2
(Universal -approximation). For every undirected graph G, Algorithm 1 with the default parameter returns a vertex cover C with
The constant matters: the hardness barrier of Section 5.10 is for every fixed , so a ratio of exactly would contradict nothing. A consequence for versus requires a constant strictly below , such as .
5.8. Why the Ratio Stays Low Across Graph Classes
The ensemble’s low observed ratio rests on running several structurally different heuristics and taking the best. Four candidates are the Hvala ensemble (Section 3.2), whose worst case is for but 2 for alone; two are Salvador-specific 2-approximations (, ); and additionally exploits planar/forest structure via the weighted MIDS gadget (Section 5.2 onward). Because the gadget H built from the forest core is itself a forest, its per-component tree dynamic program is exact, so on graphs close to forests alone is already near-optimal (Lemma 2); on graphs where ’s non-core repair overshoots, one of typically does not, and the final redundancy-pruning pass removes any vertex all of whose incident edges are already covered from every candidate.
Classes solved optimally by alone.
On stars the core is the whole star, whose minimum cover is the centre alone; the decode returns it. On a matching the core is the matching itself and the decode returns one endpoint per edge. Forests and trees (paths, caterpillars, spiders, brooms) and cycles are solved exactly because the gadget reproduces the tree optimum, and the ensemble inherits this exactly.
Dense and degree-heterogeneous classes.
Complete graphs have ; the spanning-tree core is solved and the dense non-core edges are absorbed, returning the optimal -cover, and (maximal matching) independently gets within a factor 2. Wheels, barbell and lollipop graphs concentrate their optima on hub or clique vertices, captured by either (max-degree greedy) or the core.
Bipartite and planar classes.
For bipartite graphs Konig’s theorem makes equal to the maximum matching; on this class each provide independent coverage, so the ensemble does not depend solely on ’s core solve. Grids and other bounded-treewidth planar families remain mild for alone, since the forest core captures of the at most edges and only non-core edges reach the repair.
Large adversarial graphs.
Complete bipartite graphs, crown graphs ( minus a perfect matching), double stars joined by a bridge, a hierarchical greedy-tie-break stress construction, random regular graphs, Barabasi–Albert scale-free graphs, sparse Erdos–Renyi graphs, and Watts–Strogatz small-world graphs are designed to stress individual candidates (dense structure, high or irregular degree, small-world shortcuts); the ensemble’s minimum-over-candidates guarantee (Theorem 2) still applies unconditionally to every one of them. Section 7.4 reports which candidate wins on each family.
5.9. Conditional Consequence for the Unique Games Conjecture
Theorem 4
(UGC consequence of a universal sub-2 bound). If Conjecture 1 were proved for some constant , then Algorithm 1 would be a polynomial-time -approximation for Minimum Vertex Cover. Consequently, under the standard assumption , the Unique Games Conjecture would be false.
Proof.
The runtime theorem (Theorem 6) gives worst-case time for the default fixed , in particular polynomial time. A proof of Conjecture 1 would therefore give a polynomial-time approximation ratio with . Khot and Regev [10], assuming the Unique Games Conjecture [9], showed that Vertex Cover is hard to approximate within factor for every fixed . Therefore, if , the simultaneous truth of UGC and Conjecture 1 would be impossible. Hence a proof of Conjecture 1 would refute UGC under . □
Remark 3.
Theorem 4 is conditional and, unlike Theorem 2, not unconditionally established here: Theorem 2 proves exactly, which is the UGC threshold itself and yields no contradiction (). Conjecture 1 neither disproves UGC nor proves an approximation theorem on its own; establishing it for some concrete , by whatever means, is what would trigger Theorem 4’s consequence. The empirical results of Section 7, while consistent with Conjecture 1, are evidence, not a proof, and do not by themselves establish any bound.
5.10. Conditional Consequence for P Versus NP
Theorem 5
( consequence of Conjecture 2). If Conjecture 2 were proved, then .
Proof.
Khot, Minzer, and Safra [6,7,8] proved the 2-to-2 games conjecture and derived from it that, for every fixed , approximating Minimum Vertex Cover within factor is NP-hard. Algorithm 1 runs in polynomial time (Theorem 6). A proof of Conjecture 2 would make it a polynomial-time -approximation with , i.e. of the form with , so an NP-hard problem would be solved in polynomial time, and . □
Remark 4.
Theorem 5 is a conditional implication, not a proof of . Its hypothesis is a worst-case statement overeverygraph, whereas the experiments of Section 7 cover finitely many graphs drawn from specific families, so they are evidence for Conjecture 2, not a proof of it. The only ratio proved here is 2 (Theorem 2), which Salvador inherits from the Hvala ensemble it contains; that bound is the classical one and contradicts neither hardness result. Establishing Conjecture 2—or any constant bound strictly below —remains open, and, given the implication above, would require settling one of the central open problems of complexity theory.
6. Runtime Analysis
Theorem 6.
For the default accuracy , Algorithm 1 runs in worst-case time , where and . For a fixed in general, candidate alone costs , where α is the inverse Ackermann function, so the whole ensemble costs for general ε and strictly at the default .
Proof.
We bound each of the nine candidates and the shared preprocessing and pruning; the ensemble cost is the sum of a constant number of -or-better terms.
Preprocessing. Removing self-loops and isolated vertices is one scan of the edge list and one scan of the vertex list, costing .
, maximal matching. A greedy maximal matching is computed in one scan of the edge list, [2].
, bucket-queue max-degree greedy (Algorithm 2). Standard bucket-queue argument: every push corresponds to an initial vertex or a degree decrement, and there are at most decrements in total, so there are pushes and pops, each ; total .
, degree-1 weighted reduction. The auxiliary instance has vertices and m edges (one auxiliary vertex per original edge occurrence). The selection-aware resolution bucket-sorts the original vertices by degree in and inspects each auxiliary edge at most twice, once from each endpoint, with work per inspection; it is run twice (unweighted and weighted), a constant factor. Total .
, Min-to-Min (Algorithm 3). By the same bucket-queue argument as : total pushes are n initial pushes plus at most degree-decrement pushes plus, for each real (non-stale) pop of a vertex v, at most one requeue of v itself (its degree strictly decreases by 1 whenever it is processed, since its chosen neighbor is removed), giving pushes and pops overall; each pop does work (a stale check, or an arbitrary-neighbor selection followed by the standard -amortized degree-bucket update). Total (see also Remark 1).
, primal-dual weighted cover. One pass over the edge list with work per edge, .
,SolveVC(Algorithm 4).SpanningForestCore initialises the disjoint-set forest in and performs mUnion/Find pairs, one per edge; with union by rank and path halving this costs in the worst case, tight for path-compression heuristics [17]. For a forest core with edges, the gadget H has vertices and edges, so H is built in ; crucially H is itself a forest, hence of treewidth 1. BakerPtasWeightedIDS uses shifts; each shift removes one BFS residue class, splits the rest into components, and solves each by the tree dynamic program ExactWeightedIDS, which runs in time linear in component size since H is a forest, so one shift costs , and the pass costs over k shifts. At the default , and BakerPtasWeightedIDS returns the greedy baseline GreedyWeightedMIS directly (Algorithm 5, line 2), skipping the layering loop entirely, so this phase is rather than . The repair loops inspect each edge of and of once with degree look-ups, . Total for : at , and for general .
, bipartite planar reduction (Algorithm 7). By Lemma 1 the auxiliary graph has nodes and at most edges, arranged in vertex-disjoint cycles and single edges; the gadget of u is built and solved by the cycle dynamic program in time, where is the number of edges handled at u, and . The processing order is either the input order or, for the residual variant, maintained by a degree-indexed bucket queue: each residual edge deletion is and lowers the minimum-bucket pointer by at most one, so pointer movements total . Both variants and their pruning cost .
, local search (Algorithm 9). Initialisation (indexing, tightness counters, maximality) is . Every later operation is charged its exact adjacency-scan cost to a work counter, and the search stops as soon as the counter exceeds for the fixed constant b (default 100); the swap test never scans more than the charged degrees (Section 3.7). Total .
Pruning.PruneRedundantVertices (Algorithm 8) builds the adjacency map in and makes one pass of total work ; it is applied to each of , to the two variants of , and once more to the union, a constant number of passes.
Summing over a constant number (9) of candidates plus preprocessing and pruning, every term is except ’s union-find pass, which contributes the extra factor common to all disjoint-set algorithms with path compression. Since for all n of practical relevance (indeed for all n up to far beyond the number of atoms in the observable universe), the ensemble is for every fixed in the sense that matters computationally, and strictly (no factor at all) at the default , since the layering loop is skipped. □
Remark 5.
Because the gadget H built by is a forest, the minimum-weight independent dominating set of H can in fact be computed exactly in time by a single tree dynamic program, making the Baker layering unnecessary in principle; the layered PTAS is retained because the implementation reuses the general bounded-treewidth solver, and at the default it is bypassed anyway (Algorithm 5, line 2). The union-find factor in can likewise be removed by building the spanning-forest core with a depth-first traversal, yielding a strictly candidate (matching –) if desired. The scaling study of Section 7 empirically confirms this near-linear growth, fitting wall-clock time against with on two doubling-size graph families.
7. Reproducible Experiment
To assess Conjectures 1 and 2, we ran the Salvador package (v0.0.9, default ) on a reproducible suite of test graphs with a fixed random seed (20260627). The suite is distributed with the package as three scripts: car/car_ratio.py (approximation ratio, Parts A and B), car/car_scaling.py (doubling-size timing study) and car/car_strategies.py (which candidate wins, Section 7.4). Part C compares Salvador with Hvala on the DIMACS clique complements of NPBench, using the log of a separate run (Section 7.3).
7.1. Part A: Small Graphs with a Known Optimum
Part A collects small graphs for which is known exactly, either via Konig’s theorem on bipartite instances or by exact branch-and-bound search otherwise: graphs of order at most 7 drawn exhaustively from the graph atlas, bipartite hill-climbing and obstruction instances, bipartite grids, random bipartite and general graphs, and relabeling/vertex-order stress instances. Table 2 reports, for every family, the ratio of the returned cover to the exact optimum.
7.2. Part B: Large and Adversarial Graphs with Certified Bounds
Exact optima are out of reach at the scale of Part B, so for each instance we compute a certified lower bound and report , which is an upper bound on the true ratio . Earlier versions used a greedy maximal matching for L. Every matching satisfies , while on random d-regular or locally dense graphs is much larger than , so that bound alone cannot certify ratios below roughly – on these families however good the cover is. Version 0.0.9 takes L as the largest of the following bounds, each valid for every graph:
- Matchings. Any matching M gives . We use the greedy maximal matching of earlier versions and a Karp–Sipser matching [20], which matches degree-1 vertices first and is near-maximum on sparse graphs.
- Clique packing. A cover contains all but at most one vertex of every clique, and vertex-disjoint cliques need disjoint cover vertices, so for vertex-disjoint cliques we have ; a matching is the case . We pack cliques greedily.
- Spectral bound. For an independent set S with , the vector satisfies and , where L is the Laplacian and the minimum degree (isolated vertices removed). Hence and ; on d-regular graphs this is Hoffman’s ratio bound [21]. The largest Laplacian eigenvalue is computed by Lanczos iteration, inflated by its residual norm, and capped by the rigorous Anderson–Morley bound ; this bound is therefore certified up to the numerical eigenvalue computation.
Table 3 reports, for the ten families, the largest instance size, the certified ratio bound with the method that attained it, the bound that the greedy maximal matching alone would give, and the wall-clock time.
Across the 28 Part B instances the certified ratio bound never exceeds , attained on the random 12-regular graph with vertices and edges, where the cover has vertices and the spectral bound certifies . With the matching bound alone the largest value would have been ; the difference comes from the sharper lower bounds, not from the covers, and the true ratios may be smaller still. Combined with Part A, the exact or certified ratio across all test graphs never exceeds , below (Conjecture 2) and well below the unconditional bound of 2 (Theorem 2). These numbers are evidence on the families tested; they do not bound the ratio on graphs outside the suite.
7.3. Part C: DIMACS Clique Complements, Compared with Hvala
Because Salvador contains the Hvala ensemble [11], a natural question is how much its additional candidates improve on Hvala alone. We answer it on the 68 DIMACS clique-complement instances of the NPBench collection [22]. The minimum vertex cover of the complement of a graph G on n vertices has size , where is the clique number; we use the clique numbers compiled by Mascia [23]. For 66 of the 68 instances is certified, so the reported ratio is a certified approximation ratio; for C500.9 and C1000.9 only best-known lower bounds on are available, so these two instances are marked with and their ratios are ratios to a best-known reference value. The Hvala columns of Table 4 and Table 5 are the figures reported for Hvala in [11]; the Salvador columns come from the raw log of one run of the Salvador package (v0.0.9, default ) on the same 68 instances.
Salvador is never worse than Hvala on any of the 68 instances: it returns a strictly smaller vertex cover on 48 instances and the same cover size on the remaining 20. The mean ratio to the known optimum is for Salvador against for Hvala, and the maximum ratio is against , both attained on san200_0.9_1. Salvador attains the known optimum on 29 instances, whereas Hvala does so on 18, and the total cover size summed over the 68 instances is for Salvador against for Hvala.
The largest improvements occur on san400_0.9_1, where Salvador returns the optimum (300) against 348 for Hvala, and on gen400_p0.9_75 (347 against 358); an improvement of 8 vertices is obtained on each of C250.9, C500.9, C1000.9, gen400_p0.9_65 and keller5. Salvador wins on every instance of the brock, gen, C, keller, san and sanr families, and on nine of the ten p_hat instances, whereas the two algorithms tie on the c-fat and johnson families and on most hamming and MANN instances, where both are already at or very near the optimum. Because Salvador returns the smallest of its candidates and Hvala’s candidates are among them, it cannot be worse than Hvala by construction (Theorem 2); the experiment measures by how much the additional candidates help, and the answer is that they help on most instances and on every family where Hvala is not already optimal.
The cumulative algorithm time is seconds for Salvador against seconds for Hvala, and Salvador is faster on 64 of the 68 instances. This timing comparison is indicative only, since the two sets of times come from separate single-run logs. The maximum ratio is consistent with the bound of observed on the suite of Parts A and B; the 68 instances of Part C are external benchmark instances and are not included in the count of test graphs.
7.4. Which Candidate Wins
Table 6 reports, over instances (the non-adaptive Part A families and the Part B families up to ), how often each of attains the smallest cover among them (ties credit every tied candidate) and how often it is the sole winner. Because starts from that smallest cover, it is reported separately, by the number of instances on which it strictly improved it.
The local search strictly improved the best of on 12 of the instances: every large random regular, Erdos–Renyi, Barabasi–Albert and Watts–Strogatz instance in the run, and none of the small or bipartite instances, where are already optimal or exact. Table 7 lists the gains.
7.5. Scaling Study
To check the bound of Theorem 6 empirically, car/car_scaling.py runs the ensemble on two families of doubling size—4-regular graphs and Barabasi–Albert graphs with attachment parameter 3—and fits wall-clock time against by ordinary least squares. With the seven-candidate ensemble of version 0.0.7 the fit was close to linear from to ( and ). The candidates added in version 0.0.9 are linear by construction; timing them alone while doubling n from to kept the time per unit of roughly flat for both variants of on 4-regular, Barabasi–Albert and star-plus-path graphs.
8. Conclusion
We have presented the Salvador algorithm (v0.0.9), an ensemble approximate solver for Minimum Vertex Cover that computes nine valid candidate covers and returns the smallest. Four candidates and the pruning pass adapt the Hvala ensemble [11], which Salvador therefore contains; the others are a Min-to-Min heuristic, a primal-dual 2-approximation, a planar forest-core MIDS reduction, the bipartite planar oriented-incidence reduction—now solved exactly in linear time thanks to Lemma 1—and a budgeted -swap local search. The algorithm always returns a valid vertex cover (Theorem 1), unconditionally achieves approximation ratio at most 2 on every graph (Theorem 2), and runs in worst-case time at the default (Theorem 6).
On a reproducible suite of test graphs, the ratio is exactly 1 on all graphs with known optima, and the certified ratio bound never exceeds on the 28 large adversarial graphs. Most of the improvement over the reported for version 0.0.7 comes from sharper certified lower bounds rather than smaller covers, although the new local search reduces the covers on every large non-bipartite instance. We conjecture a universal ratio below 2 (Conjecture 1) and, more strongly, at most (Conjecture 2). Both are conditional statements with major consequences: a proof of the first would refute the Unique Games Conjecture under (Theorem 4), and a proof of the second would imply by the Khot–Minzer–Safra theorem (Theorem 5). On the 68 DIMACS clique-complement instances of NPBench, Salvador never returns a larger cover than the Hvala algorithm it contains, returns a strictly smaller one on 48 instances, and reduces the mean ratio from to (Section 7.3). The experiments support these conjectures on the families tested but do not prove them.
Future work includes: (i) establishing or refuting Conjectures 1 and 2, either by a structural analysis of which candidate wins on which graph class or by a large-scale search for adversarial instances; (ii) exact optima, or sharper certified bounds, on the large regular families where the certified bound is currently loosest; (iii) analysing the residual bipartite planar reduction and the local search theoretically; and (iv) extending the ensemble methodology to dominating set, independent set, and set cover. The implementation is freely available as the Salvador package (v0.0.9) on PyPI [14].
References
- Karp, R.M. Reducibility Among Combinatorial Problems. In 50 Years of Integer Programming 1958–2008: From the Early Years to the State-of-the-Art; Springer: Berlin, Germany, 2010; pp. 219–241. [Google Scholar] [CrossRef]
- Papadimitriou, C.H.; Steiglitz, K. Combinatorial Optimization: Algorithms and Complexity; Courier Corporation: North Chelmsford (MA), 1998. [Google Scholar]
- Karakostas, G. A Better Approximation Ratio for the Vertex Cover Problem. ACM Trans. Algorithms 2009, 5, 1–8. [Google Scholar] [CrossRef]
- Karpinski, M.; Zelikovsky, A. Approximating Dense Cases of Covering Problems. In Proceedings of the DIMACS Series in Discrete Mathematics and Theoretical Computer Science, Providence, Rhode Island, 1996; Vol. 26, pp. 147–164. [Google Scholar]
- Dinur, I.; Safra, S. On the Hardness of Approximating Minimum Vertex Cover. Ann. Math. 2005, 162, 439–485. [Google Scholar] [CrossRef]
- Khot, S.; Minzer, D.; Safra, M. On Independent Sets, 2-to-2 Games, and Grassmann Graphs. In Proceedings of the Proceedings of the 49th Annual ACM SIGACT Symposium on Theory of Computing, Montreal, Québec, Canada, 2017; pp. 576–589. [Google Scholar] [CrossRef]
- Dinur, I.; Khot, S.; Kindler, G.; Minzer, D.; Safra, M. Towards a proof of the 2-to-1 games conjecture? In Proceedings of the Proceedings of the 50th Annual ACM SIGACT Symposium on Theory of Computing, Los Angeles, California, 2018; pp. 376–389. [Google Scholar] [CrossRef]
- Khot, S.; Minzer, D.; Safra, M. Pseudorandom Sets in Grassmann Graph Have Near-Perfect Expansion. In Proceedings of the 2018 IEEE 59th Annual Symposium on Foundations of Computer Science, Paris, France, 2018; pp. 592–601. [Google Scholar] [CrossRef]
- Khot, S. On the Power of Unique 2-Prover 1-Round Games. In Proceedings of the Proceedings of the 34th Annual ACM Symposium on Theory of Computing, Montreal, Québec, Canada, 2002; pp. 767–775. [Google Scholar] [CrossRef]
- Khot, S.; Regev, O. Vertex Cover Might Be Hard to Approximate to Within 2-ϵ. J. Comput. Syst. Sci. 2008, 74, 335–349. [Google Scholar] [CrossRef]
- Vega, F. An Approximate Solution to the Minimum Vertex Cover Problem: The Hvala Algorithm. Gauge Freedom J. 2026, 1. [Google Scholar] [CrossRef]
- Vega, F. Hvala: Approximate Vertex Cover Solver. 2026. Available online: https://pypi.org/project/hvala.
- Baker, B.S. Approximation algorithms for NP-complete problems on planar graphs. J. ACM 1994, 41, 153–180. [Google Scholar] [CrossRef]
- Vega, F. Salvador: Approximate Vertex Cover Solver. 2026. Available online: https://pypi.org/project/salvador.
- Bar-Yehuda, R.; Even, S. A local-ratio theorem for approximating the weighted vertex cover problem. In Analysis and Design of Algorithms for Combinatorial Problems;Annals of Discrete Mathematics; Elsevier, 1985; Vol. 25, pp. 27–46. Available online: http://www.cs.technion.ac.il/~reuven/PDF/vc_lr.pdf.
- Andrade, D.V.; Resende, M.G.C.; Werneck, R.F. Fast local search for the maximum independent set problem. J. Heuristics 2012, 18, 525–547. [Google Scholar] [CrossRef]
- Tarjan, R.E. Efficiency of a good but not linear set union algorithm. J. ACM 1975, 22, 215–225. [Google Scholar] [CrossRef]
- Hopcroft, J.E.; Karp, R.M. An n5/2 Algorithm for Maximum Matchings in Bipartite Graphs. SIAM J. Comput. 1973, 2, 225–231. [Google Scholar] [CrossRef]
- Konig, D. Graphen und Matrizen. Mat. Es Fiz. Lapok 1931, 38, 116–119. [Google Scholar]
- Karp, R.M.; Sipser, M. Maximum matchings in sparse random graphs. In Proceedings of the Proceedings of the 22nd Annual Symposium on Foundations of Computer Science, 1981; pp. 364–375. [Google Scholar] [CrossRef]
- Hoffman, A.J. On eigenvalues and colorings of graphs. In Graph Theory and its Applications; Harris, B., Ed.; Academic Press: New York, 1970; pp. 79–91. [Google Scholar]
- Nguyen, T.; Bui, T. NP-Complete Benchmark Instances. Vertex cover DIMACS clique complements. 2025. Available online: https://roars.dev/npbench/.
- Mascia, F. The Maximum Clique Problem – DIMACS Benchmark Set Compiled clique-number values for DIMACS Second Implementation Challenge instances. 2015. Available online: https://iridia.ulb.ac.be/~fmascia/maximum_clique/DIMACS-benchmark.
Figure 1.
Local weighted-MIDS gadget for a core edge . Selecting or corresponds to paying for a vertex-cover endpoint, while selecting the heavy hub incurs penalty .
Figure 1.
Local weighted-MIDS gadget for a core edge . Selecting or corresponds to paying for a vertex-cover endpoint, while selecting the heavy hub incurs penalty .
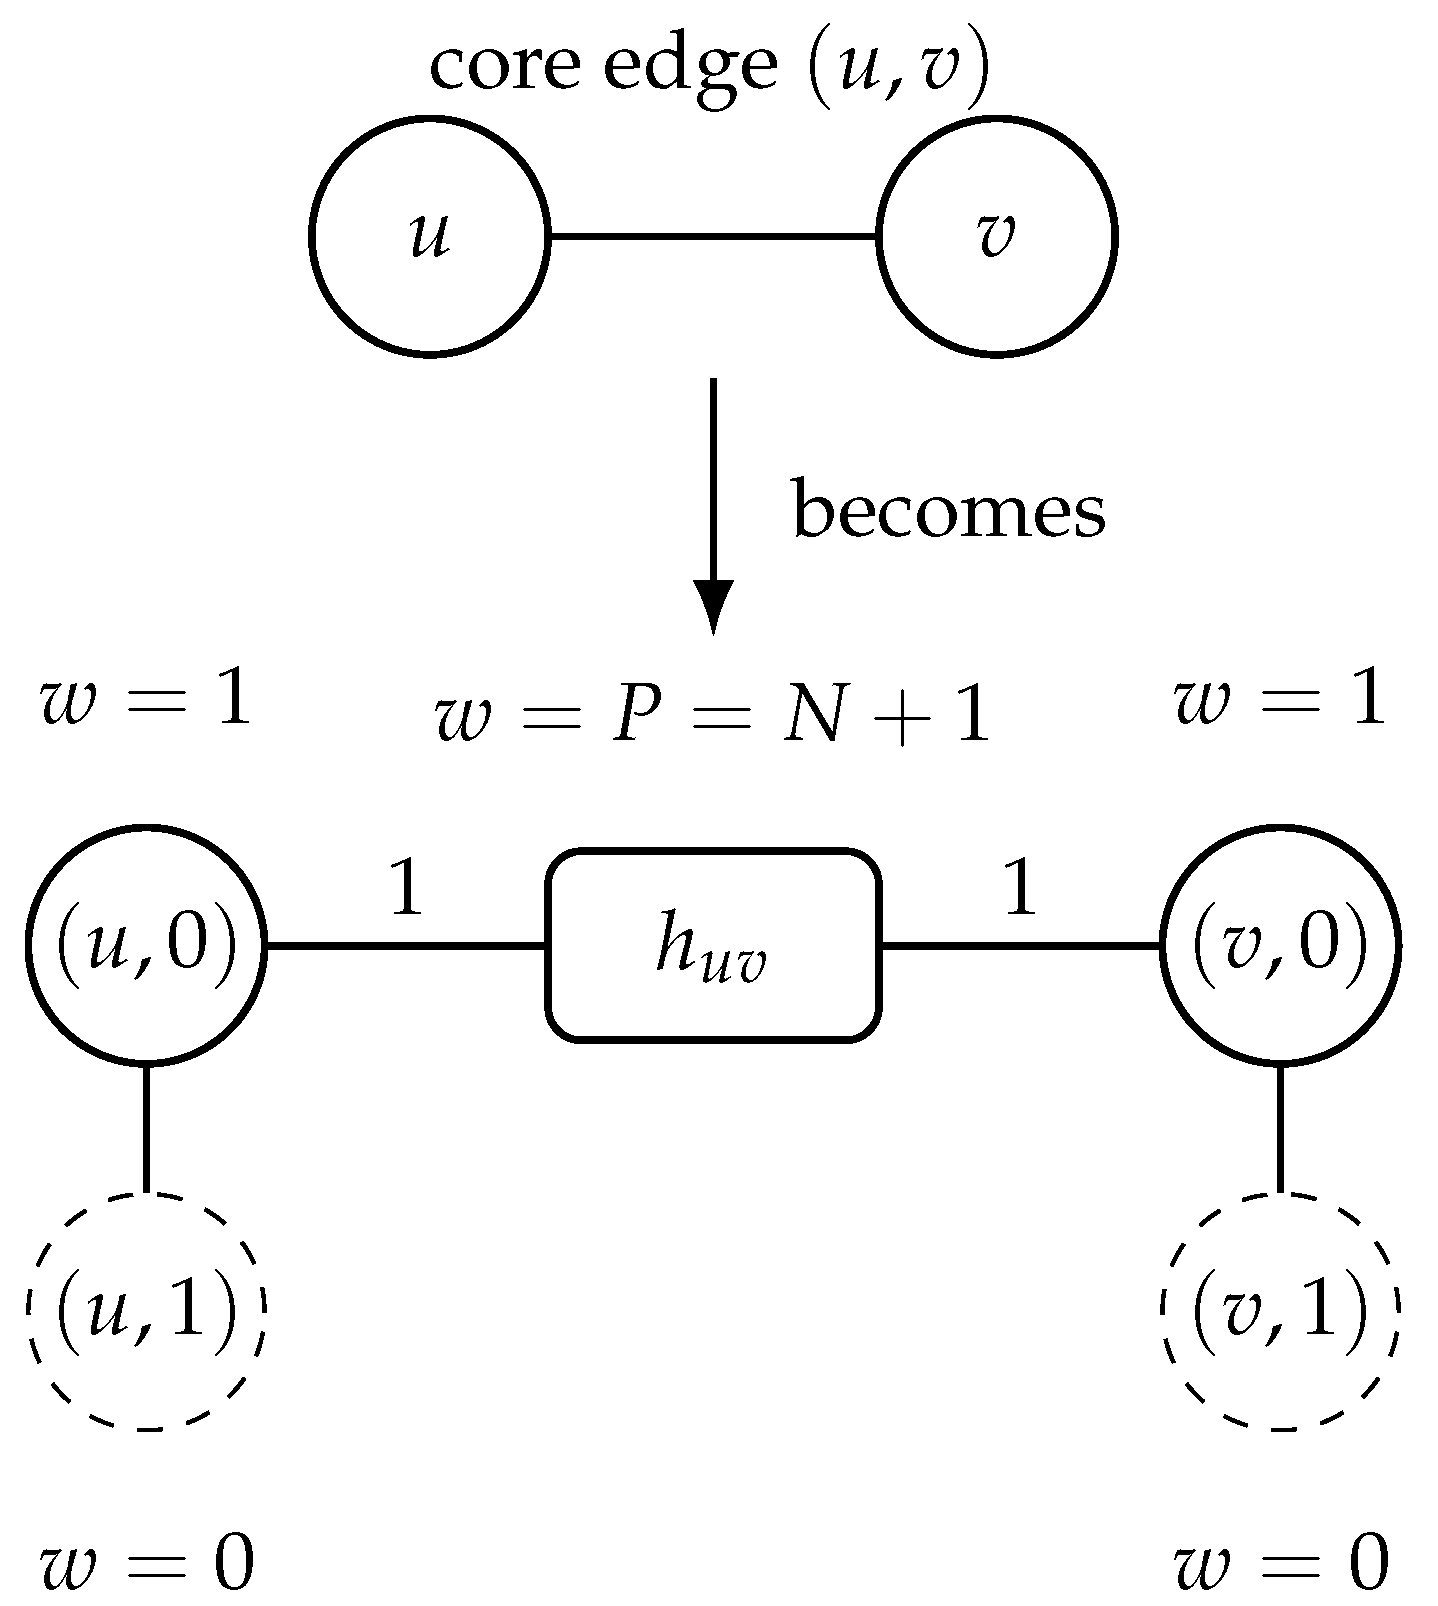
Figure 2.
Oriented-incidence gadget of a vertex u with unprocessed neighbours: an even cycle . Solid forcing edges encode the original edges ; dashed local edges close the cycle. Blue nodes (weight ) decode to u, orange nodes (weight ) to .
Figure 2.
Oriented-incidence gadget of a vertex u with unprocessed neighbours: an even cycle . Solid forcing edges encode the original edges ; dashed local edges close the cycle. Blue nodes (weight ) decode to u, orange nodes (weight ) to .
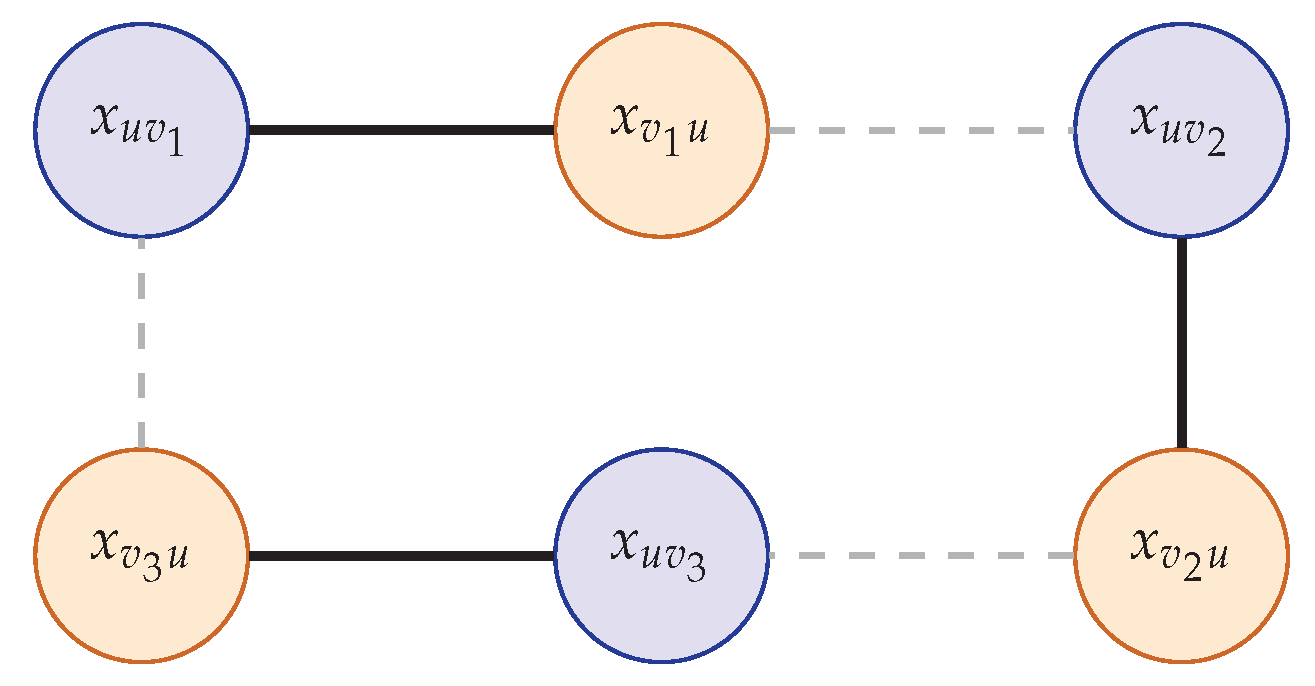

Table 1.
Code metadata for the Salvador package (v0.0.9).
| Nr. | Code metadata description | Metadata |
|---|---|---|
| C1 | Current code version | v0.0.9 |
| C2 | Permanent link to code repository | https://github.com/frankvegadelgado/salvador |
| C3 | Permanent link to reproducible capsule | https://pypi.org/project/salvador/ |
| C4 | Legal Code License | MIT License |
| C5 | Code versioning system used | git |
| C6 | Languages, tools, and services used | Python ≥ 3.12, NetworkX ≥ 3.4.2, NumPy ≥ 2.2.1, SciPy ≥ 1.15.0 |
| C7 | Compilation requirements and dependencies | Python, NetworkX, NumPy, SciPy |
Table 2.
Part A: ratio of the returned cover to the exact optimum, by family. Every one of the instances was solved exactly () and every returned cover was valid.
Table 2.
Part A: ratio of the returned cover to the exact optimum, by family. Every one of the instances was solved exactly () and every returned cover was valid.
| Family | Instances | Mean ratio | Max ratio |
|---|---|---|---|
| Graph atlas () | 1245 | 1.000 | 1.000 |
| Bipartite hill-climb (exact) | 80 | 1.000 | 1.000 |
| Random general (exact, ) | 173 | 1.000 | 1.000 |
| Random bipartite (exact) | 99 | 1.000 | 1.000 |
| Grids, bipartite (exact) | 64 | 1.000 | 1.000 |
| Relabel / order stress (exact) | 56 | 1.000 | 1.000 |
| Bipartite obstruction (exact) | 1 | 1.000 | 1.000 |
| Overall | 1718 | 1.000 | 1.000 |
Table 3.
Part B: certified ratio upper bound on the 28 instances of the ten large/adversarial families (up to vertices and edges), the lower-bound method that attained it, the bound the greedy maximal matching alone would give, and the wall-clock time of the largest instance. Every returned cover was valid.
| Family | Max n | Max ratio u.b. | Bound | Matching-only | Max time (s) |
|---|---|---|---|---|---|
| Random 12-regular | 200,000 | 1.169 | spectral | 1.576 | 54.39 |
| Random 6-regular | 200,000 | 1.145 | spectral | 1.416 | 35.47 |
| Random 3-regular | 200,000 | 1.079 | spectral | 1.248 | 24.41 |
| Sparse Erdos–Renyi (deg. 4) | 200,000 | 1.066 | Karp–Sipser | 1.259 | 27.85 |
| Watts–Strogatz small-world | 50,000 | 1.055 | clique packing | 1.418 | 5.39 |
| Barabasi–Albert scale-free | 200,000 | 1.011 | Karp–Sipser | 1.353 | 34.57 |
| Complete bipartite | 1,600 | 1.000 | exact | 1.000 | 10.87 |
| Crown graph | 1,600 | 1.000 | exact | 1.000 | 10.75 |
| Double star + bridge | 200,002 | 1.000 | exact | 1.000 | 13.22 |
| Hierarchical star trap | 152,917 | 1.000 | exact | 1.000 | 10.11 |
Table 4.
Salvador (v0.0.9) and Hvala on the 68 DIMACS clique-complement instances of NPBench [22] — Part 1 of 2 (brock, c-fat, C, gen, hamming). Hvala figures are those reported in [11]; Salvador figures come from the raw log of a single run. Ratio is the cover size divided by the known optimum (OPT). : best-known upper bound on (maximum clique not confirmed optimal [23]); the ratio is then a lower bound.
| Cover size | Time | Ratio | |||||
|---|---|---|---|---|---|---|---|
| Instance | OPT | Hvala | Salvador | Hvala | Salvador | Hvala | Salvador |
| brock200_1 | 179 | 183 | 180 | 65.5ms | 63.4ms | 1.022 | 1.006 |
| brock200_2 | 188 | 192 | 190 | 233.3ms | 129.4ms | 1.021 | 1.011 |
| brock200_3 | 185 | 189 | 187 | 291.4ms | 110.6ms | 1.022 | 1.011 |
| brock200_4 | 183 | 187 | 184 | 92.0ms | 95.7ms | 1.022 | 1.005 |
| brock400_1 | 373 | 381 | 376 | 450.0ms | 294.9ms | 1.021 | 1.008 |
| brock400_2 | 371 | 379 | 377 | 500.5ms | 284.0ms | 1.022 | 1.016 |
| brock400_3 | 369 | 381 | 377 | 441.7ms | 308.6ms | 1.033 | 1.022 |
| brock400_4 | 367 | 378 | 376 | 507.7ms | 283.2ms | 1.030 | 1.025 |
| brock800_1 | 777 | 785 | 781 | 3.96s | 1.92s | 1.010 | 1.005 |
| brock800_2 | 776 | 783 | 780 | 4.13s | 1.93s | 1.009 | 1.005 |
| brock800_3 | 775 | 784 | 781 | 4.20s | 2.02s | 1.012 | 1.008 |
| brock800_4 | 774 | 785 | 781 | 4.53s | 1.97s | 1.014 | 1.009 |
| c-fat200-1 | 188 | 188 | 188 | 383.7ms | 236.1ms | 1.000 | 1.000 |
| c-fat200-2 | 176 | 176 | 176 | 790.0ms | 211.8ms | 1.000 | 1.000 |
| c-fat200-5 | 142 | 142 | 142 | 251.1ms | 140.5ms | 1.000 | 1.000 |
| c-fat500-1 | 486 | 486 | 486 | 3.87s | 1.84s | 1.000 | 1.000 |
| c-fat500-10 | 374 | 374 | 374 | 2.74s | 1.22s | 1.000 | 1.000 |
| c-fat500-2 | 474 | 474 | 474 | 3.75s | 1.86s | 1.000 | 1.000 |
| c-fat500-5 | 436 | 436 | 436 | 3.68s | 1.67s | 1.000 | 1.000 |
| C1000.9 | 932 | 945 | 937 | 1.87s | 814.0ms | 1.014 | 1.005 |
| C125.9 | 91 | 92 | 91 | 174.7ms | 20.2ms | 1.011 | 1.000 |
| C250.9 | 206 | 214 | 206 | 60.8ms | 49.8ms | 1.039 | 1.000 |
| C500.9 | 443 | 454 | 446 | 336.5ms | 193.8ms | 1.025 | 1.007 |
| gen200_p0.9_44 | 156 | 167 | 160 | 32.9ms | 34.2ms | 1.071 | 1.026 |
| gen200_p0.9_55 | 145 | 163 | 159 | 82.6ms | 26.8ms | 1.124 | 1.097 |
| gen400_p0.9_55 | 345 | 356 | 349 | 192.7ms | 113.7ms | 1.032 | 1.012 |
| gen400_p0.9_65 | 335 | 359 | 351 | 183.1ms | 110.5ms | 1.072 | 1.048 |
| gen400_p0.9_75 | 325 | 358 | 347 | 166.9ms | 139.5ms | 1.102 | 1.068 |
| hamming10-2 | 512 | 512 | 512 | 72.1ms | 125.7ms | 1.000 | 1.000 |
| hamming10-4 | 984 | 992 | 986 | 6.43s | 1.45s | 1.008 | 1.002 |
| hamming6-2 | 32 | 32 | 32 | 11.7ms | 6.6ms | 1.000 | 1.000 |
| hamming6-4 | 60 | 60 | 60 | 50.5ms | 18.2ms | 1.000 | 1.000 |
| hamming8-2 | 128 | 128 | 128 | 442.0ms | 21.9ms | 1.000 | 1.000 |
| hamming8-4 | 240 | 240 | 240 | 599.7ms | 165.8ms | 1.000 | 1.000 |
Table 5.
Salvador (v0.0.9) and Hvala on the 68 DIMACS clique-complement instances of NPBench [22] — Part 2 of 2 (johnson, keller, MANN, p_hat, san, sanr). Hvala figures are those reported in [11]; Salvador figures come from the raw log of a single run. Ratio is the cover size divided by the known optimum (OPT).
| Cover size | Time | Ratio | |||||
|---|---|---|---|---|---|---|---|
| Instance | OPT | Hvala | Salvador | Hvala | Salvador | Hvala | Salvador |
| johnson16-2-4 | 112 | 112 | 112 | 83.3ms | 24.2ms | 1.000 | 1.000 |
| johnson32-2-4 | 480 | 480 | 480 | 827.6ms | 237.3ms | 1.000 | 1.000 |
| johnson8-2-4 | 24 | 24 | 24 | 2.9ms | 0.0ms | 1.000 | 1.000 |
| johnson8-4-4 | 56 | 56 | 56 | 32.3ms | 9.0ms | 1.000 | 1.000 |
| keller4 | 160 | 162 | 160 | 348.8ms | 66.4ms | 1.012 | 1.000 |
| keller5 | 749 | 759 | 751 | 4.96s | 1.18s | 1.013 | 1.003 |
| MANN_a27 | 252 | 253 | 253 | 35.7ms | 37.2ms | 1.004 | 1.004 |
| MANN_a45 | 690 | 695 | 693 | 145.5ms | 53.3ms | 1.007 | 1.004 |
| MANN_a81 | 2221 | 2225 | 2225 | 769.8ms | 206.6ms | 1.002 | 1.002 |
| MANN_a9 | 29 | 29 | 29 | 6.6ms | 0.0ms | 1.000 | 1.000 |
| p_hat1000-3 | 932 | 942 | 935 | 9.60s | 2.35s | 1.011 | 1.003 |
| p_hat300-1 | 292 | 292 | 292 | 2.43s | 475.2ms | 1.000 | 1.000 |
| p_hat300-2 | 275 | 277 | 275 | 1.38s | 307.8ms | 1.007 | 1.000 |
| p_hat300-3 | 264 | 268 | 266 | 735.5ms | 160.0ms | 1.015 | 1.008 |
| p_hat500-1 | 491 | 492 | 491 | 6.29s | 1.49s | 1.002 | 1.000 |
| p_hat500-2 | 464 | 469 | 464 | 4.45s | 1.00s | 1.011 | 1.000 |
| p_hat500-3 | 450 | 454 | 451 | 2.30s | 495.3ms | 1.009 | 1.002 |
| p_hat700-1 | 689 | 693 | 691 | 14.28s | 3.18s | 1.006 | 1.003 |
| p_hat700-2 | 656 | 658 | 656 | 9.51s | 2.22s | 1.003 | 1.000 |
| p_hat700-3 | 638 | 642 | 638 | 4.71s | 1.08s | 1.006 | 1.000 |
| san200_0.7_1 | 170 | 184 | 183 | 296.9ms | 82.5ms | 1.082 | 1.076 |
| san200_0.7_2 | 182 | 188 | 185 | 313.7ms | 75.8ms | 1.033 | 1.016 |
| san200_0.9_1 | 130 | 155 | 151 | 89.4ms | 38.0ms | 1.192 | 1.162 |
| san200_0.9_2 | 140 | 162 | 159 | 100.6ms | 32.1ms | 1.157 | 1.136 |
| san200_0.9_3 | 156 | 169 | 165 | 451.1ms | 69.1ms | 1.083 | 1.058 |
| san400_0.5_1 | 387 | 393 | 391 | 2.36s | 563.3ms | 1.016 | 1.010 |
| san400_0.7_1 | 360 | 379 | 378 | 1.47s | 366.3ms | 1.053 | 1.050 |
| san400_0.7_2 | 370 | 385 | 382 | 1.40s | 367.2ms | 1.041 | 1.032 |
| san400_0.7_3 | 378 | 388 | 382 | 1.43s | 387.8ms | 1.026 | 1.011 |
| san400_0.9_1 | 300 | 348 | 300 | 507.9ms | 109.5ms | 1.160 | 1.000 |
| sanr200_0.7 | 182 | 184 | 182 | 330.7ms | 90.6ms | 1.011 | 1.000 |
| sanr200_0.9 | 158 | 160 | 159 | 83.0ms | 33.2ms | 1.013 | 1.006 |
| sanr400_0.5 | 387 | 388 | 387 | 2.51s | 586.6ms | 1.003 | 1.000 |
| sanr400_0.7 | 379 | 383 | 380 | 1.56s | 373.7ms | 1.011 | 1.003 |
Table 6.
Wins among over instances. On the small graphs most candidates tie at the optimum; on the large non-bipartite families the winner is almost always or .
Table 6.
Wins among over instances. On the small graphs most candidates tie at the optimum; on the large non-bipartite families the winner is almost always or .
| Candidate | Heuristic | Wins | Sole wins | Win rate |
|---|---|---|---|---|
| maximal matching | 1359 | 0 | 0.819 | |
| max-degree greedy | 1531 | 3 | 0.923 | |
| Hallelujah reduction | 1500 | 0 | 0.904 | |
| Min-to-Min | 1608 | 5 | 0.969 | |
| primal-dual | 1359 | 0 | 0.819 | |
| MIDS Baker reduction | 1466 | 0 | 0.884 | |
| union re-prune | 1438 | 0 | 0.867 | |
| bipartite planar reduction | 1611 | 3 | 0.971 |
Table 7.
Strict improvements of on the instances; the instances of the same families improve by 2–71 vertices.
Table 7.
Strict improvements of on the instances; the instances of the same families improve by 2–71 vertices.
| Instance | Best of | Gain | |
|---|---|---|---|
| Random 3-regular, | 28,346 | 27,750 | 596 |
| Random 6-regular, | 33,509 | 32,808 | 701 |
| Random 12-regular, | 38,339 | 37,630 | 709 |
| Sparse Erdos–Renyi, | 26,441 | 26,096 | 345 |
| Watts–Strogatz, | 35,970 | 35,441 | 529 |
| Barabasi–Albert, | 24,561 | 24,554 | 7 |
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (http://creativecommons.org/licenses/by/4.0/).
Copyright: This open access article is published under a Creative Commons CC BY 4.0 license, which permit the free download, distribution, and reuse, provided that the author and preprint are cited in any reuse.