

Submitted:
13 October 2025
Posted:
16 October 2025
You are already at the latest version
Abstract
Deep learning, as a multifaceted computational framework, integrates function approximation, optimization, and statistical learning within a rigorously formulated mathematical landscape. This work systematically develops the theoretical foundations of deep learning through functional analysis, measure theory, and variational calculus, establishing a mathematically exhaustive treatment of deep learning paradigms. We begin with a rigorous problem formulation by defining the risk functional as a mapping between measurable function spaces, analyzing its properties via Fr´echet differentiability and convex functional minimization. The complexity of deep neural networks is examined using VC-dimension theory and Rademacher complexity, characterizing generalization bounds and hypothesis class constraints. The universal approximation properties of neural networks are refined through convolution operators, the Stone-Weierstrass theorem, and Sobolev embeddings, with quantifiable expressivity bounds derived using Fourier analysis and compactness arguments via the Rellich-Kondrachov theorem. The expressivity trade-offs between depth and width are analyzed through capacity measures, spectral representations of activation functions, and energy-based functional approximations. The mathematical structure of training dynamics is developed by rigorously studying gradient flow, stationary points, and Hessian eigenspectrum properties of loss landscapes. The Neural Tangent Kernel (NTK) regime is formalized as an asymptotic linearization of deep learning dynamics, with precise spectral decomposition methods providing theoretical insights into generalization. Generalization bounds are established using PAC-Bayesian techniques, spectral regularization, and information-theoretic constraints, elucidating the stability of deep networks under probabilistic risk formulations. The study extends to advanced deep learning architectures, including convolutional neural networks (CNNs), recurrent neural networks (RNNs), transformers, generative adversarial networks (GANs), and variational autoencoders (VAEs), with rigorous functional analysis of their representational capacities. Optimal transport theory is explored in deep learning through Wasserstein distances, Sinkhorn regularization, and Kantorovich duality, connecting generative modeling to probability space embeddings. Theoretical formulations of game-theoretic deep learning architectures are examined, establishing variational inequalities, equilibrium constraints, and evolutionary stability conditions in adversarial learning paradigms. Reinforcement learning is formalized through stochastic control theory, Bellman operators, and dynamic programming principles, with rigorous derivations of policy optimization strategies. We provide an advanced treatment of optimization techniques, including stochastic gradient descent (SGD), adaptive moment estimation (Adam), and Hessian-based second-order methods, with a focus on spectral regularization and convergence guarantees. The role of information-theoretic constraints in deep learning generalization is further analyzed through rate-distortion theory, entropy-based priors, and variational inference techniques. Metric learning, adversarial robustness, and Bayesian deep learning are rigorously formulated, with explicit derivations of Mahalanobis distances, Gaussian mixture models, extreme value theory, and Bayesian nonparametric priors. Few-shot and zero-shot learning paradigms are examined through meta-learning frameworks, Model-Agnostic Meta-Learning (MAML), and Bayesian hierarchical inference. The mathematical structure of neural network architecture search (NAS) is developed using evolutionary algorithms, reinforcement learning-based policy optimization, and differential operator constraints. Theoretical advancements in kernel regression, deep Kolmogorov methods, and neural approximations of differential operators are rigorously examined, connecting deep learning models to functional approximation in infinite-dimensional Hilbert spaces. The mathematical principles underlying causal inference in deep learning are formulated through structural causal models (SCMs), counterfactual reasoning, domain adaptation, and invariant risk minimization. Deep learning frameworks are analyzed through the lens of variational functionals, tensor calculus, and high-dimensional probability theory. This work presents a mathematically exhaustive, rigorously formulated, and scientifically rigorous synthesis of deep learning theory, bridging fundamental mathematical principles with cutting-edge advancements in neural network research. By unifying functional analysis, information theory, stochastic processes, and optimization into a cohesive theoretical framework, this study serves as a definitive reference for researchers seeking to extend the mathematical foundations of deep learning.
Keywords:
Deep Learning
; Neural Networks
; Universal Approximation Theorem
; Risk Functional
; Measurable Function Spaces
; VC-Dimension
; Rademacher Complexity
; Sobolev Embeddings
; Rellich-Kondrachov Theorem
; Gradient Flow
; Hessian Structure
; Neural Tangent Kernel (NTK)
; PAC-Bayes Theory
; Spectral Regularization
; Fourier Analysis in Deep Learning
; Convolutional Neural Networks (CNNs)
; Recurrent Neural Networks (RNNs)
; Transformers and Attention Mechanisms
; Generative Adversarial Networks (GANs)
; Variational Autoencoders (VAEs)
; Reinforcement Learning
; Stochastic Gradient Descent (SGD)
; Adaptive Optimization (Adam
; RMSProp)
; Function Space Approximation
; Generalization Bounds
; Mathematical Foundations of AI
1. Mathematical Foundations
Deep learning is an algorithmic framework for addressing high-dimensional function approximation tasks. Fundamentally, it is based on the synergy of:
- Functional Approximation: Modeling complex, non-linear functions with neural networks. Functional approximation is one of the building blocks of deep learning, and it lies at the core of how deep learning models, especially neural networks, are able to tackle hard problems. In deep learning, functional approximation means the capability of neural networks to approximate complex, high-dimensional, and non-linear functions that tend to be hard or impossible to model with standard mathematical methods.
- Optimization Theory: Efficiently solving non-convex optimization problems. Optimization theory is a key area of deep learning, as training deep neural networks is really just minimizing the best set of parameters (weights and biases) of a given objective, commonly referred to as the loss function. The objective will usually be some measure of difference between the network outputs and the actual values. Optimization methods control the process of training and decide the extent to which a neural network may learn from data.
- Statistical Learning Theory: Generalization behavior on unseen data. Statistical Learning Theory (SLT) gives the mathematical basis for the generalization behavior of machine learning methods, including deep learning methods. It provides important insights into how models generalize from training data to novel data, and this is very important in making sure that deep learning models are not just correct on the training set but also work well on new, unseen data. SLT assists in solving basic issues like overfitting, bias-variance tradeoff, and generalization error.
The problem can be formalized as:
where X is the input space, Y is the output space, P is the distribution of data, is a loss function, are neural network parameters. This problem entails the integration of various fields, each of which is examined in systematic detail below.
1.1. Problem Definition: Risk Functional as a Mapping Between Spaces
1.1.1. Measurable Function Spaces
A measurable space is the basic building block of measure theory, notated as , in which is an arbitrary but fixed non-empty set called the sample space or underlying set and is a -algebra, that is, a particular class of subsets of capturing the measurability notion. The -algebra , the power set of , holds three axioms, each guaranteeing an essential property of closure with respect to set operations. To start with, is closed under complementation such that for every set , the complement is also in . This ensures the possibility of establishing the "non-occurrence" of measurable events in a mathematically coherent manner. Second, is closed under countable unions: for any countable family , the union is also in , allowing measurable sets to be constructed out of countably infinite operations. De Morgan’s laws subsequently suggest countable intersection closure, since , so that the structure supports conjunctions of countable sets of events. Lastly, the presence of the empty set is an axiom which allows for a null reference point, so that the -algebra is not empty and can be used to express the "impossibility" of some outcomes.
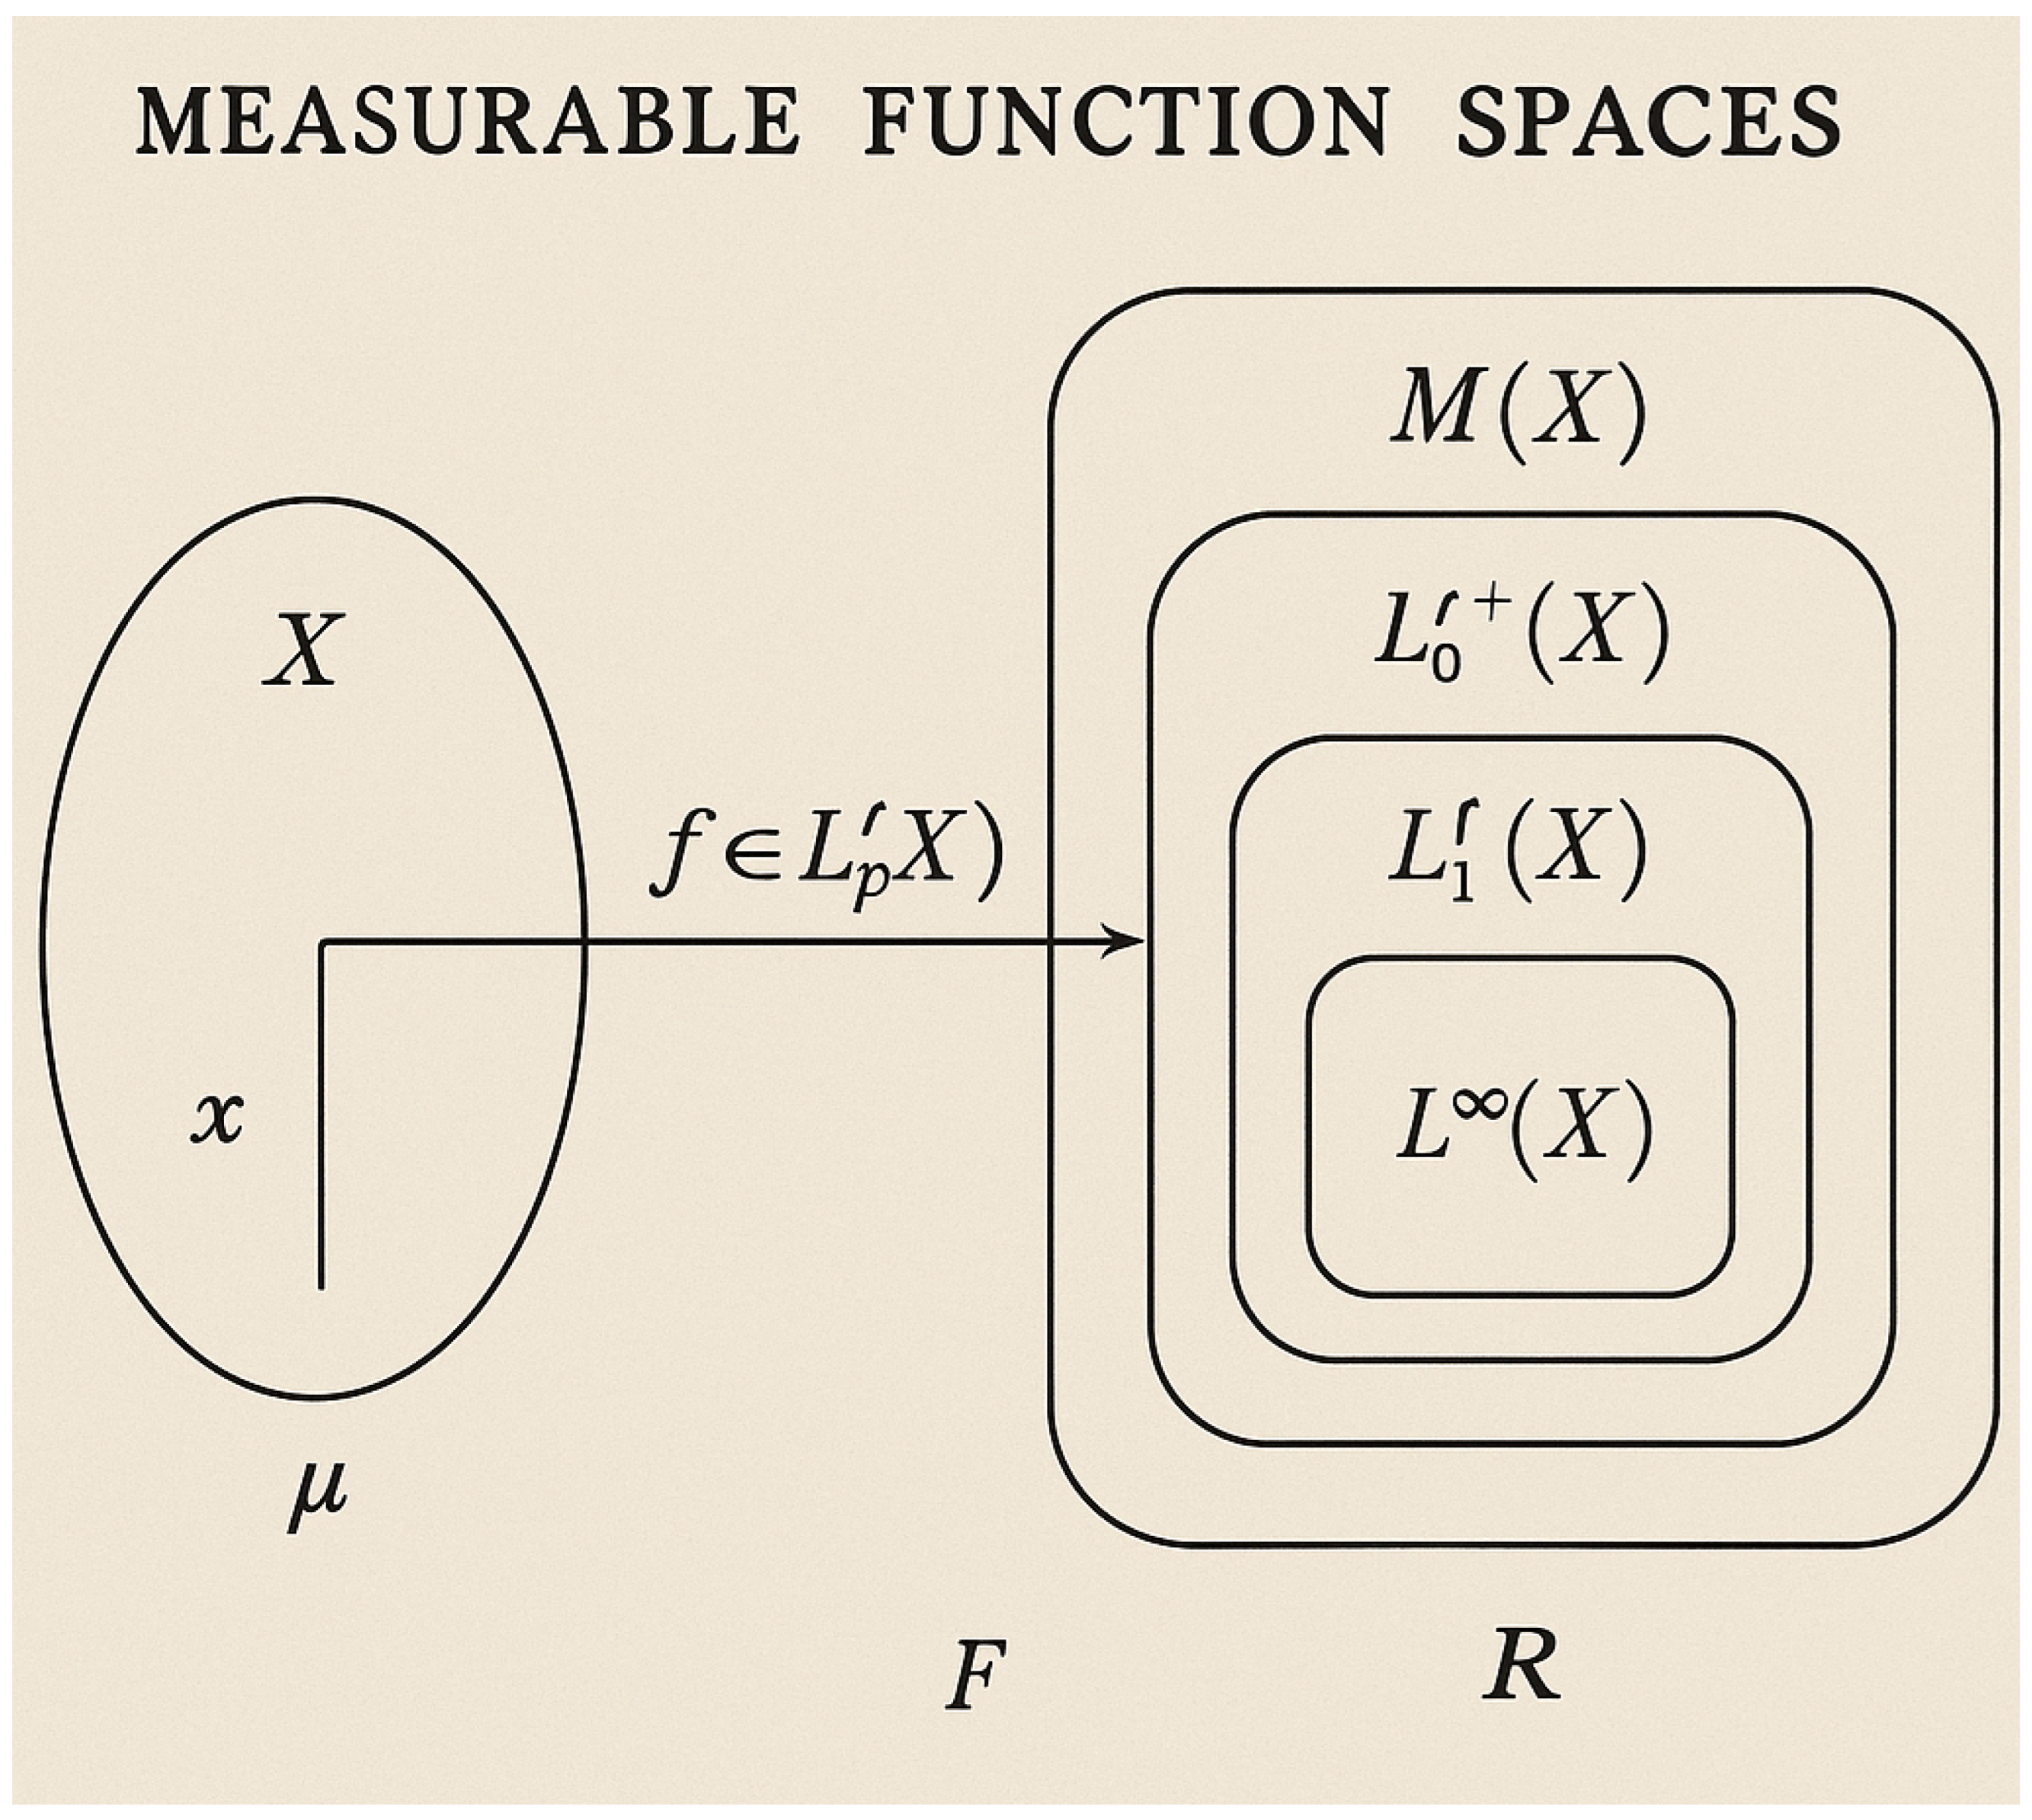
Figure 1.
Measurable Function Spaces
1.1.1.1 Literature Review of Measurable Function Spaces
Rao et. al. (2024) [1] investigated approximation theory within Lebesgue measurable function spaces, providing an analysis of operator convergence. They also established a theoretical framework for function approximation in Lebesgue spaces and provided a rigorous study of symmetric properties in function spaces. Mukhopadhyay and Ray (2025) [2] provided a comprehensive introduction to measurable function spaces, with a focus on Lp-spaces and their completeness properties. They also established the fundamental role of Lp-spaces in measure theory and discussed the relationship between continuous function spaces and measurable functions. Szołdra (2024) [3] examined measurable function spaces in quantum mechanics, exploring the role of measurable observables in ergodic theory. They connected functional analysis and measure theory to quantum state evolution and provided a mathematical foundation for quantum machine learning in function spaces. Lee (2025) [10] investigated metric space theory and functional analysis in the context of measurable function spaces in AI models. He formalized how function spaces can model self-referential structures in AI and provided a bridge between measure theory and generative models. Song et. al. (2025) [4] discussed measurable function spaces in the context of urban renewal and performance evaluation. They developed a rigorous evaluation metric using measurable function spaces and explored function space properties in applied data science and urban analytics. Mennaoui et. al. (2025) [5] explored measurable function spaces in the theory of evolution equations, a key concept in functional analysis. They established a rigorous study of measurable operator functions and provided new insights into function spaces and their role in solving differential equations. Pedroza (2024) [6] investigated domain stability in machine learning models using function spaces. He established a formal mathematical relationship between function smoothness and domain adaptation and uses topological and measurable function spaces to analyze stability conditions in learning models. Cerreia-Vioglio and Ok (2024) [7] developed a new integration theory for measurable set-valued functions. They introduced a generalization of integration over Banach-valued functions and established weak compactness properties in measurable function spaces. Averin (2024) [8] applied measurable function spaces to gravitational entropy theory. He provided a rigorous proof of entropy bounds using function space formalism and connected measure theory with relativistic field equations. Potter (2025) [9] investigated measurable function spaces in the context of Fourier analysis and crystallographic structures. He established new results on Fourier transforms of measurable functions and introduced a novel framework for studying function spaces in invariant shift operators.
1.1.1.2 Analysis of Measurable Function Spaces
Measurable spaces are not merely abstract structures but are the backbone of measure theory, probability, and integration. For example, the Borel -algebra on the real numbers is the smallest -algebra containing all open intervals for . This -algebra is pivotal in defining Lebesgue measure, where measurable sets generalize the classical notion of intervals to include sets that are neither open nor closed. Moreover, the construction of a -algebra generated by a collection of subsets , denoted , provides a minimal framework that includes and satisfies all -algebra properties, enabling the systematic extension of measurability to more complex scenarios. For instance, starting with intervals in , one can build the Borel -algebra, a critical tool in modern analysis.
The structure of a measurable space allows the definition of a measure , a function that assigns a non-negative value to each set in , adhering to two key axioms: and countable additivity, which states that for any disjoint collection , the measure of their union satisfies . This property is indispensable in extending intuitive notions of length, area, and volume to arbitrary measurable sets, paving the way for the Lebesgue integral. A function is then termed -measurable if for every Borel set , the preimage belongs to . This definition ensures that the function is compatible with the -algebra, a necessity for defining integrals and expectation in probability theory.
In summary, measurable spaces represent a highly versatile and mathematically rigorous framework, underpinning vast areas of analysis and probability. Their theoretical depth lies in their ability to systematically handle infinite operations while maintaining closure, consistency, and flexibility for defining measures, measurable functions, and integrals. As such, the rigorous study of measurable spaces is indispensable for advancing modern mathematical theory, providing a bridge between abstract set theory and applications in real-world phenomena.
Let and be measurable spaces. The true risk functional is defined as:
where:
- f belongs to a hypothesis space .
- is a Borel probability measure over , satisfying .
1.1.2. Risk as a Functional
1.1.2.1 Literature Review of Risk as a Functional
Wang et. al. (2025) [11] developed a mathematical risk model based on functional variational calculus and introduced a loss functional regularization framework that minimizes adversarial risk in deep learning models. They also proposed a game-theoretic interpretation of functional risk in security settings. Duim and Mesquita (2025) [12] extended the inverse reinforcement learning (IRL) framework by defining risk as a functional over probability spaces and used Bayesian functional priors to model risk-sensitive behavior. They also introduced an iterative regularized risk functional minimization approach. Khayat et. al. (2025) [13] established functional Sobolev norms to quantify risk in adversarial settings and introduced a functional risk decomposition technique using deep neural architectures. They also provided an in-depth theoretical framework for risk estimation in adversarially perturbed networks. Agrawal (2025) [14] developed a variational framework for risk as a loss functional and used adaptive weighting of loss functions to enhance generalization in deep learning. He also provided rigorous convergence analysis of risk functional minimization. Hailemichael and Ayalew (2025) [15] used control barrier function (CBF) theory to develop risk-aware deep learning models and modeled risk as a functional on dynamical systems, optimizing stability and robustness. They also introduced a risk-minimizing constrained optimization formulation. Nguyen et.al. (2025) [16] developed a functional metric learning approach for risk-sensitive deep models and used convex optimization techniques to derive functional risk bounds. They also established semi-supervised loss functions for risk-regularized learning. Luo et. al. (2025) [17] introduced a geometric interpretation of risk functionals in deep learning models and used integral transform techniques to approximate risk in real-world vision systems. They also developed a functional approach to adversarial robustness.
1.1.2.2 Analysis of Risk as a Functional
The functional is Fréchet-differentiable if:
where denotes the inner product in . In the field of risk management and decision theory, the concept of a risk functional is a mathematical formalization that captures how risk is quantified for a given outcome or state. A risk functional, denoted as , acts as a map that takes elements from a given space X (which represents the possible outcomes or states) and returns a real-valued risk measure. This risk measure, , expresses the degree of risk or the adverse outcome associated with a particular element . The space X may vary depending on the context—this could be a space of random variables, trajectories, or more complex function spaces. The risk functional maps x to , i.e., , where each reflects the risk associated with the specific realization x. One of the most foundational forms of risk functionals is based on the expectation of a loss function , where represents a random variable or state, and quantifies the loss associated with that state. The risk functional can be expressed as an expected loss, written mathematically as:
where is the probability density function of the outcome x, and the integration is taken over the entire space X. In this setup, can be any function that measures the severity or unfavorable nature of the outcome x. In a financial context, could represent the loss function for a portfolio, and would be the probability density function of the portfolio’s returns. In many cases, a specific form of is used, such as , where is the target or expected value. This choice results in the risk functional representing the variance of the outcome x, expressed as:
This formulation captures the variability or dispersion of outcomes around a mean value, a common risk measure in applications like portfolio optimization or risk management. Additionally, another widely used class of risk functionals arises from quantile-based risk measures, such as Value-at-Risk (VaR), which focuses on the extreme tail behavior of the loss distribution. The VaR at a confidence level is defined as the smallest value l such that the probability of exceeding l is no greater than , i.e.,
This defines a threshold beyond which the worst outcomes are expected to occur with probability . Value-at-Risk provides a measure of the worst-case loss under normal circumstances, but it does not provide information about the severity of losses exceeding this threshold. To address this limitation, the Conditional Value-at-Risk (CVaR) is introduced, which measures the expected loss given that the loss exceeds the VaR threshold. Mathematically, CVaR at the level is given by:
This conditional expectation provides a more detailed assessment of the potential extreme losses beyond the VaR threshold. The CVaR is a more comprehensive measure, capturing the tail risk and providing valuable information about the magnitude of extreme adverse events. In cases where the space X represents trajectories or paths, such as in the context of continuous-time processes or dynamical systems, the risk functional is often formulated in terms of integrals over time. For example, consider as a trajectory in the function space , the space of continuous functions on the interval . The risk functional in this case might quantify the total deviation of the trajectory from a reference or target trajectory over time. A typical example could be the total squared deviation, written as:
where represents a reference trajectory and is a norm, such as the Euclidean norm. This risk functional quantifies the total deviation (or energy) of the trajectory from the target path over the entire time interval, and is used in various applications such as control theory and optimal trajectory planning. A common choice for the norm might be , where are the components of the trajectory in . In some cases, the space X of possible outcomes may not be a finite-dimensional vector space, but instead a Banach space or a Hilbert space, particularly when x represents a more complex object such as a function or a trajectory. For example, the space is a Banach space, and the risk functional may involve the evaluation of integrals over this function space. In such settings, the risk functional can take the form:
where is the p-norm, and . For , this risk functional represents the total energy of the trajectory, but other norms can be used to emphasize different types of risks. For instance, the -norm would focus on the maximum deviation of the trajectory from the target path. The concept of convexity plays a significant role in the theory of risk functionals. Convexity ensures that the risk associated with a convex combination of two states and is less than or equal to the weighted average of the risks of the individual states. Mathematically, for , convexity demands that:
This property reflects the diversification effect in risk management, where mixing several states or outcomes generally leads to a reduction in overall risk. Convex risk functionals are particularly important in portfolio theory, where they allow for risk minimization through diversification. For example, if represents the variance of a portfolio’s returns, then the convexity property ensures that combining different assets will result in a portfolio with lower overall risk than the risk of any individual asset. Monotonicity is another important property for risk functionals, ensuring that the risk increases as the outcome becomes more adverse. If is worse than according to some partial order, we have:
Monotonicity ensures that the risk functional behaves in a way that aligns with intuitive notions of risk: worse outcomes are associated with higher risk. In financial contexts, this is reflected in the fact that losses increase the associated risk measure. Finally, in some applications, the risk functional is derived from perturbation analysis to study how small changes in parameters affect the overall risk. Consider as a perturbed trajectory, where is a small parameter, and the Fréchet derivative of the risk functional with respect to is given by:
This derivative quantifies the sensitivity of the risk to perturbations in the system and is crucial in the analysis of stability and robustness. Such analyses are essential in areas like stochastic control and optimization, where it is important to understand how small changes in the model’s parameters can influence the risk profile.
Thus, the risk functional is a powerful tool for quantifying and managing uncertainty, and its formulation can be adapted to various settings, from random variables and stochastic processes to continuous trajectories and dynamic systems. The risk functional provides a rigorous mathematical framework for assessing and minimizing risk in complex systems, and its flexibility makes it applicable across a wide range of domains.
1.2. Approximation Spaces for Neural Networks
The neural network hypothesis space is parameterized as:
To analyze its capacity, we rely on:
- VC-dimension theory for discrete hypotheses.
- Rademacher complexity for continuous spaces:where are i.i.d. Rademacher random variables.
1.2.1. VC-Dimension Theory for Discrete Hypotheses
The VC-dimension (Vapnik-Chervonenkis dimension) is a fundamental concept in statistical learning theory that quantifies the capacity of a hypothesis class to fit a range of labelings of a set of data points. The VC-dimension is particularly useful in understanding the generalization ability of a classifier. The theory is important in machine learning, especially when assessing overfitting and the risk of model complexity.
1.2.1.1 Literature Review of VC-Dimension Theory for Discrete Hypotheses
There are several articles that explore the VC-dimension theory for discrete hypotheses very rigorously. N. Bousquet and S. Thomassé (2015) [18] explored in their paper the VC-dimension in the context of graph theory, connecting it to structural properties such as the Erdős-Pósa property. Yıldız and Alpaydin (2009) [19] in their article computed the VC-dimension for decision tree hypothesis spaces, considering both discrete and continuous features. Zhang et. al. (2012) [20] introduced a discretized VC-dimension to bridge real-valued and discrete hypothesis spaces, offering new theoretical tools for complexity analysis. Riondato and Zdonik (2011) [21] adapted VC-dimension theory to database systems, analyzing SQL query selectivity using a theoretical lens. Riggle and Sonderegger (2010) [22] investigated the VC-dimension in linguistic models, focusing on grammar hypothesis spaces. Anderson (2023) [23] provided a comprehensive review of VC-dimension in fuzzy systems, particularly in logic frameworks involving discrete structures. Fox et. al. (2021) [24] proved key conjectures for systems with bounded VC-dimension, offering insights into combinatorial implications. Johnson (2021) [25] discusses binary representations and VC-dimensions, with implications for discrete hypothesis modeling. Janzing (2018) [26] in his paper focuses on hypothesis classes with low VC-dimension in causal inference frameworks. Ghosh (2024) [907] derived the expressions for fundamental differential operators—namely the gradient, divergence, and curl—as well as the vector gradient of a vector field within curvilinear coordinate systems. This work significantly enhances clarity on the application of the del operator in non-Cartesian contexts, laying a robust foundation for advanced analytical and computational treatments of vector calculus in complex geometries. Hüllermeier and Tehrani (2012) [27] in their paper explored the theoretical VC-dimension of Choquet integrals, applied to discrete machine learning models. The book titled “Foundations of Machine Learning" [28] by Mehryar Mohri, Afshin Rostamizadeh, and Ameet Talwalkar offers a very good foundational discussion on VC-dimension in the context of statistical learning. Another book titled “Learning Theory: An Approximation Theory Viewpoint" by Felipe Cucker and Ding-Xuan Zhou [29] discusses the role of VC-dimension in approximation theory. Yet another book titled “Understanding Machine Learning: From Theory to Algorithms" by Shai Shalev-Shwartz and Shai Ben-David [30] contains detailed chapters on hypothesis spaces and VC-dimension.
1.2.1.2 Analysis of VC-Dimension Theory for Discrete Hypotheses
For discrete hypotheses, the VC-dimension theory applies to a class of hypotheses that map a set of input points to binary output labels (typically 0 or 1). The VC-dimension for a hypothesis class refers to the largest set of data points that can be shattered by that class, where "shattering" means that the hypothesis class can realize all possible labelings of these points.
We shall now discuss the Formal Mathematical Framework. Let X be a finite or infinite set called the instance space, which represents the input space. Consider a hypothesis class H, where each hypothesis is a function . The function h classifies each element of X into one of two classes: 0 or 1. Given a subset
we say that H shatters S if for every possible labeling , there exists some such that for all , we have:
In other words, a hypothesis class H shatters S if it can produce every possible binary labeling on the set S. The VC-dimension is defined as the size of the largest set S that can be shattered by H:
If no set of points can be shattered, then the VC-dimension is 0. Some Properties of the VC-Dimension are
- Shattering Implies Non-empty Hypothesis Class: If a set S is shattered by H, then H is non-empty. This follows directly from the fact that for each labeling , there exists some that produces the corresponding labeling. Therefore, H must contain at least one hypothesis.
- Upper Bound on Shattering: Given a hypothesis class H, if there exists a set of size k such that H can shatter S, then any set of size greater than k cannot be shattered. This gives us the crucial result that:
- Implication for Generalization A central result in the theory of statistical learning is the connection between VC-dimension and the generalization error. Specifically, the VC-dimension bounds the ability of a hypothesis class to generalize to unseen data. The higher the VC-dimension, the more complex the hypothesis class, and the more likely it is to overfit the training data, leading to poor generalization.
We shall now discuss the VC-Dimension and Generalization Bounds (VC Theorem). The VC-dimension theorem (often referred to as Hoeffding’s bound or the generalization bound) provides a probabilistic guarantee on the relationship between the training error and the true error. Specifically, it gives an upper bound on the probability that the generalization error exceeds the empirical error (training error) by more than .
The Vapnik-Chervonenkis (VC) dimension is a fundamental measure of the capacity of a hypothesis class , and it plays a crucial role in understanding the generalization ability of machine learning models, including neural networks. The VC-dimension of a hypothesis class is defined as the largest number m such that there exists a set of m points that can be shattered by . Formally, a set
is shattered by if for every possible binary labeling , there exists a hypothesis such that
The VC-dimension, denoted as , is the supremum of all such m that can be shattered by . For a neural network with W total parameters (weights and biases), the capacity of the hypothesis class induced by the network architecture depends on the activation function. If the activation function is piecewise linear (such as ReLU), then an upper bound for the VC-dimension is given by
This result is derived from combinatorial arguments involving the number of hyperplane arrangements that a neural network can realize in a given input space.
If the activation function is nonlinear (such as sigmoid or tanh), the capacity can increase but remains constrained by the number of parameters. The intuition behind this bound lies in the observation that each neuron introduces a decision boundary in the input space, and the number of such boundaries grows approximately as rather than W due to dependencies among neurons. When considering discrete hypotheses, the hypothesis space is restricted to a finite number of functions. This occurs in scenarios where the weights and biases are quantized to a finite set of values, or where the activation functions themselves take on a finite number of distinct outputs. If there are K possible distinct values for each parameter and there are W parameters, then the total number of possible functions that the network can realize is at most
From the fundamental relationship between the VC-dimension and the number of hypotheses in a finite hypothesis space, we obtain the bound
Applying this result to a neural network with quantized weights and biases, we obtain
Thus, discretization significantly reduces the VC-dimension compared to continuous-valued networks, where the number of hypotheses is effectively infinite due to the continuous range of parameters. For binary networks, where each weight is restricted to two possible values (e.g., ), the bound simplifies further to
Since VC-dimension directly affects the generalization error, its role in neural network theory is formalized through the following uniform convergence bound. If h is chosen from based on an i.i.d. training set of size N, then with probability at least , the true error and the empirical error satisfy the bound
A crucial consequence of this inequality is that for a hypothesis class with a larger VC-dimension, a larger number of training samples is required to achieve the same generalization error. Since discrete neural networks have a lower VC-dimension than their continuous counterparts, they often generalize better given the same training set size, provided the hypothesis class is sufficiently expressive for the problem at hand.
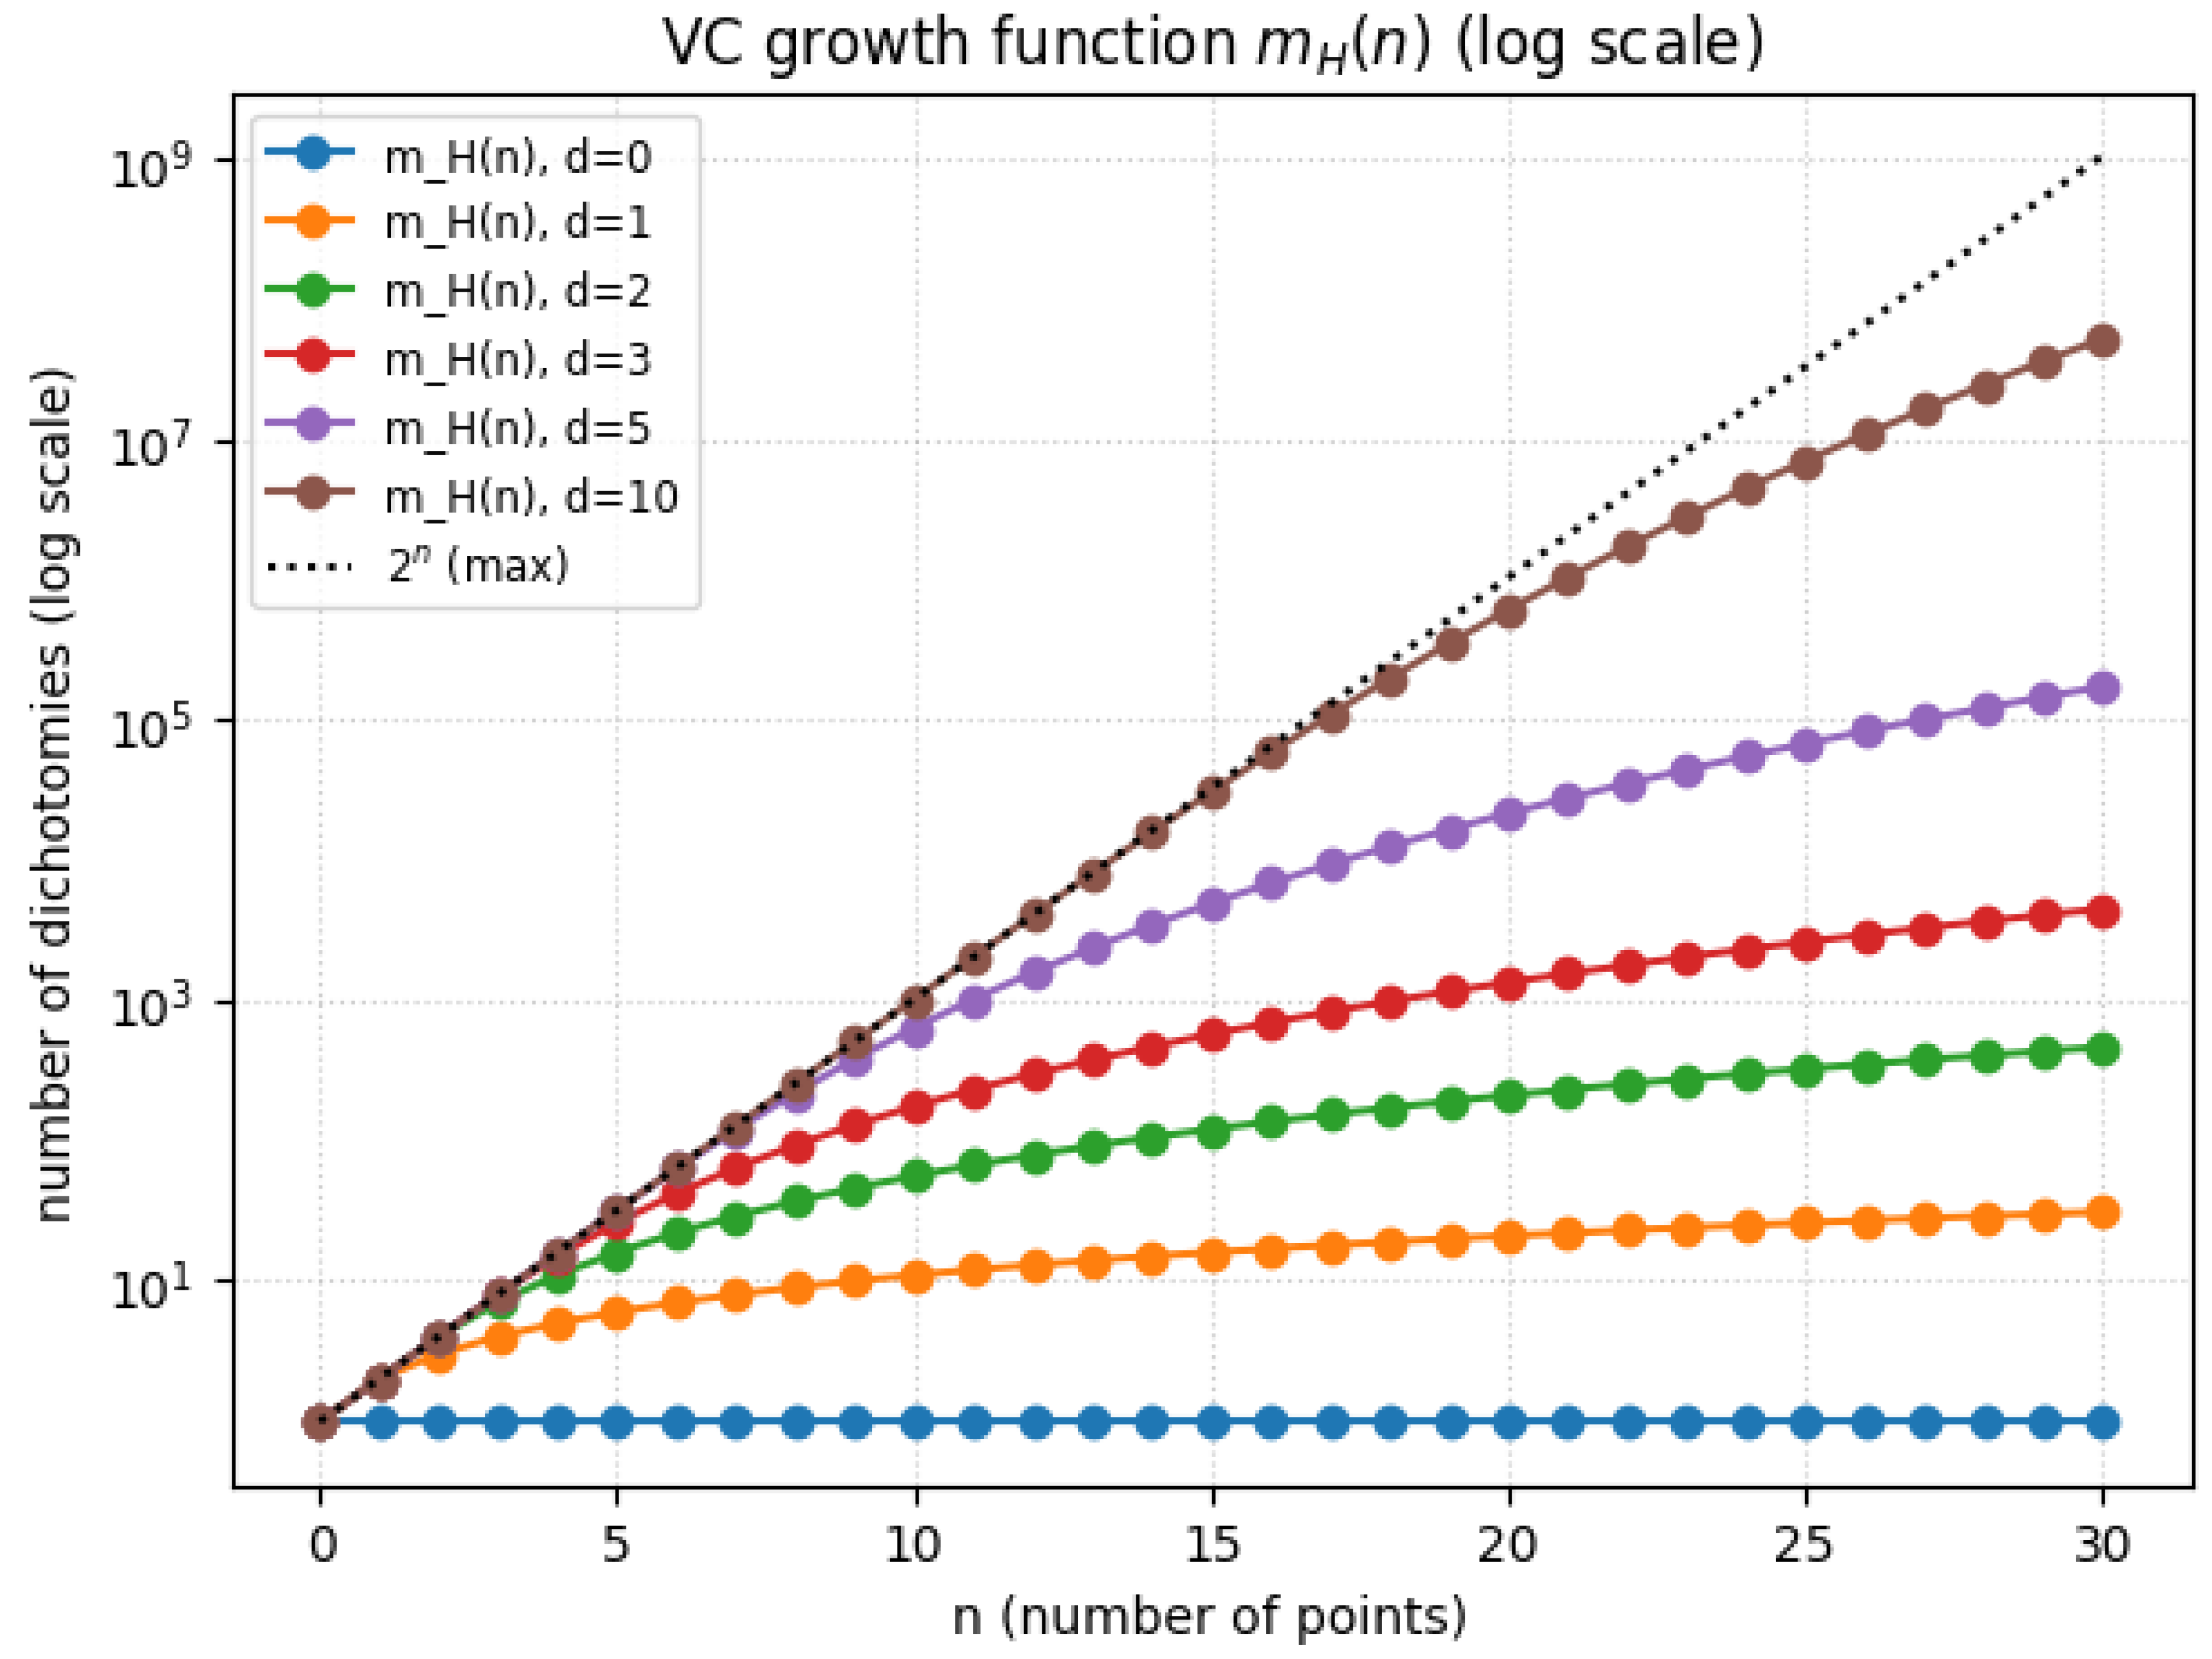
The shattering coefficient, also known as the growth function, plays an essential role in understanding the VC-dimension of neural networks. The shattering coefficient is defined as the maximum number of dichotomies that can realize on any set of m points. If , then can fully shatter an m-point dataset. For neural networks with continuous parameters, the growth function satisfies
For discrete neural networks, where is finite, we obtain the bound
which ensures that the number of realizable functions is significantly smaller than in the continuous case, thereby reducing overfitting potential. The interplay between VC-dimension and structural risk minimization (SRM) further highlights the importance of capacity control in neural networks. Given a hierarchy of hypothesis classes , with increasing VC-dimension, the optimal generalization performance is achieved by choosing the class that minimizes the trade-off between empirical risk and capacity, as given by
For discrete networks, the practical implication of this bound is that models with limited precision weights or constrained architectures tend to generalize better than overparameterized networks with unnecessarily high VC-dimension. From an optimization standpoint, discrete neural networks have a smaller number of local minima in the loss landscape compared to their continuous counterparts. This is because the number of unique parameter configurations is finite, leading to a more structured and potentially more tractable optimization problem. However, the trade-off is that discrete optimization is often NP-hard, requiring specialized techniques such as simulated annealing, evolutionary algorithms, or integer programming methods. Thus, VC-dimension theory provides profound insights into the expressive power, generalization ability, and optimization complexity of neural networks. Discrete neural networks exhibit a reduced VC-dimension compared to their continuous counterparts, leading to potentially better generalization, provided that the model retains sufficient expressivity for the given problem. The trade-off between expressivity and generalization is fundamental to designing efficient neural network architectures that perform well in practice.
Let be the distribution from which the training data is drawn, and let and represent the empirical error and true error of a hypothesis , respectively:
where are i.i.d. (independent and identically distributed) samples from the distribution . For a hypothesis class H with VC-dimension , with probability at least , the following holds for all :
where is bounded by:
This result shows that the generalization error (the difference between the true and empirical error) is small with high probability, provided the sample size n is large enough and the VC-dimension d is not too large. The sample complexity n required to guarantee that the generalization error is within with high probability is given by:
where C is a constant depending on the distribution. This bound emphasizes the importance of VC-dimension in controlling the complexity of the hypothesis class. A larger VC-dimension requires a larger sample size to avoid overfitting and ensure reliable generalization. Some Detailed Examples are:
- Example 1: Linear Classifiers in : Consider the hypothesis class H consisting of linear classifiers in . These classifiers are hyperplanes in two dimensions, defined by:where is the weight vector and is the bias term. The VC-dimension of linear classifiers in is 3. This can be rigorously shown by noting that for any set of 3 points in , the hypothesis class H can shatter these points. In fact, any possible binary labeling of the 3 points can be achieved by some linear classifier. However, for 4 points in , it is impossible to shatter all possible binary labelings (e.g., the four vertices of a convex quadrilateral), meaning the VC-dimension is 3.
- Example 2: Polynomial Classifiers of Degree d: Consider a polynomial hypothesis class in of degree d. The hypothesis class H consists of polynomials of the form:where the are coefficients and . The VC-dimension of polynomial classifiers of degree d in grows as , implying that the complexity of the hypothesis class increases rapidly with both the degree d and the dimension n of the input space.
Neural networks, depending on their architecture, can have very high VC-dimensions. In particular, the VC-dimension of a neural network with L layers, each containing N neurons, is typically , indicating that the VC-dimension grows exponentially with both the number of neurons and the number of layers. This result provides insight into the complexity of neural networks and their capacity to overfit data when the training sample size is insufficient.
The VC-dimension of a hypothesis class is a powerful tool in statistical learning theory. It quantifies the complexity of the hypothesis class by measuring its capacity to shatter sets of points, and it is directly tied to the model’s ability to generalize. The VC-dimension theorem provides rigorous bounds on the generalization error and sample complexity, giving us essential insights into the trade-off between model complexity and generalization. The theory extends to more complex hypothesis classes such as linear classifiers, polynomial classifiers, and neural networks, where it serves as a critical tool for controlling overfitting and ensuring reliable performance on unseen data.
1.2.1.3 Python Code to Generate Figure 2 and Figure 3 Illustrating VC-Dimension Theory for Discrete Hypotheses
The Python code below produces the Figure 2 and Figure 3 illustrating VC-dimension theory for discrete hypotheses.
Figure 2.
VC growth function (Linear scale)
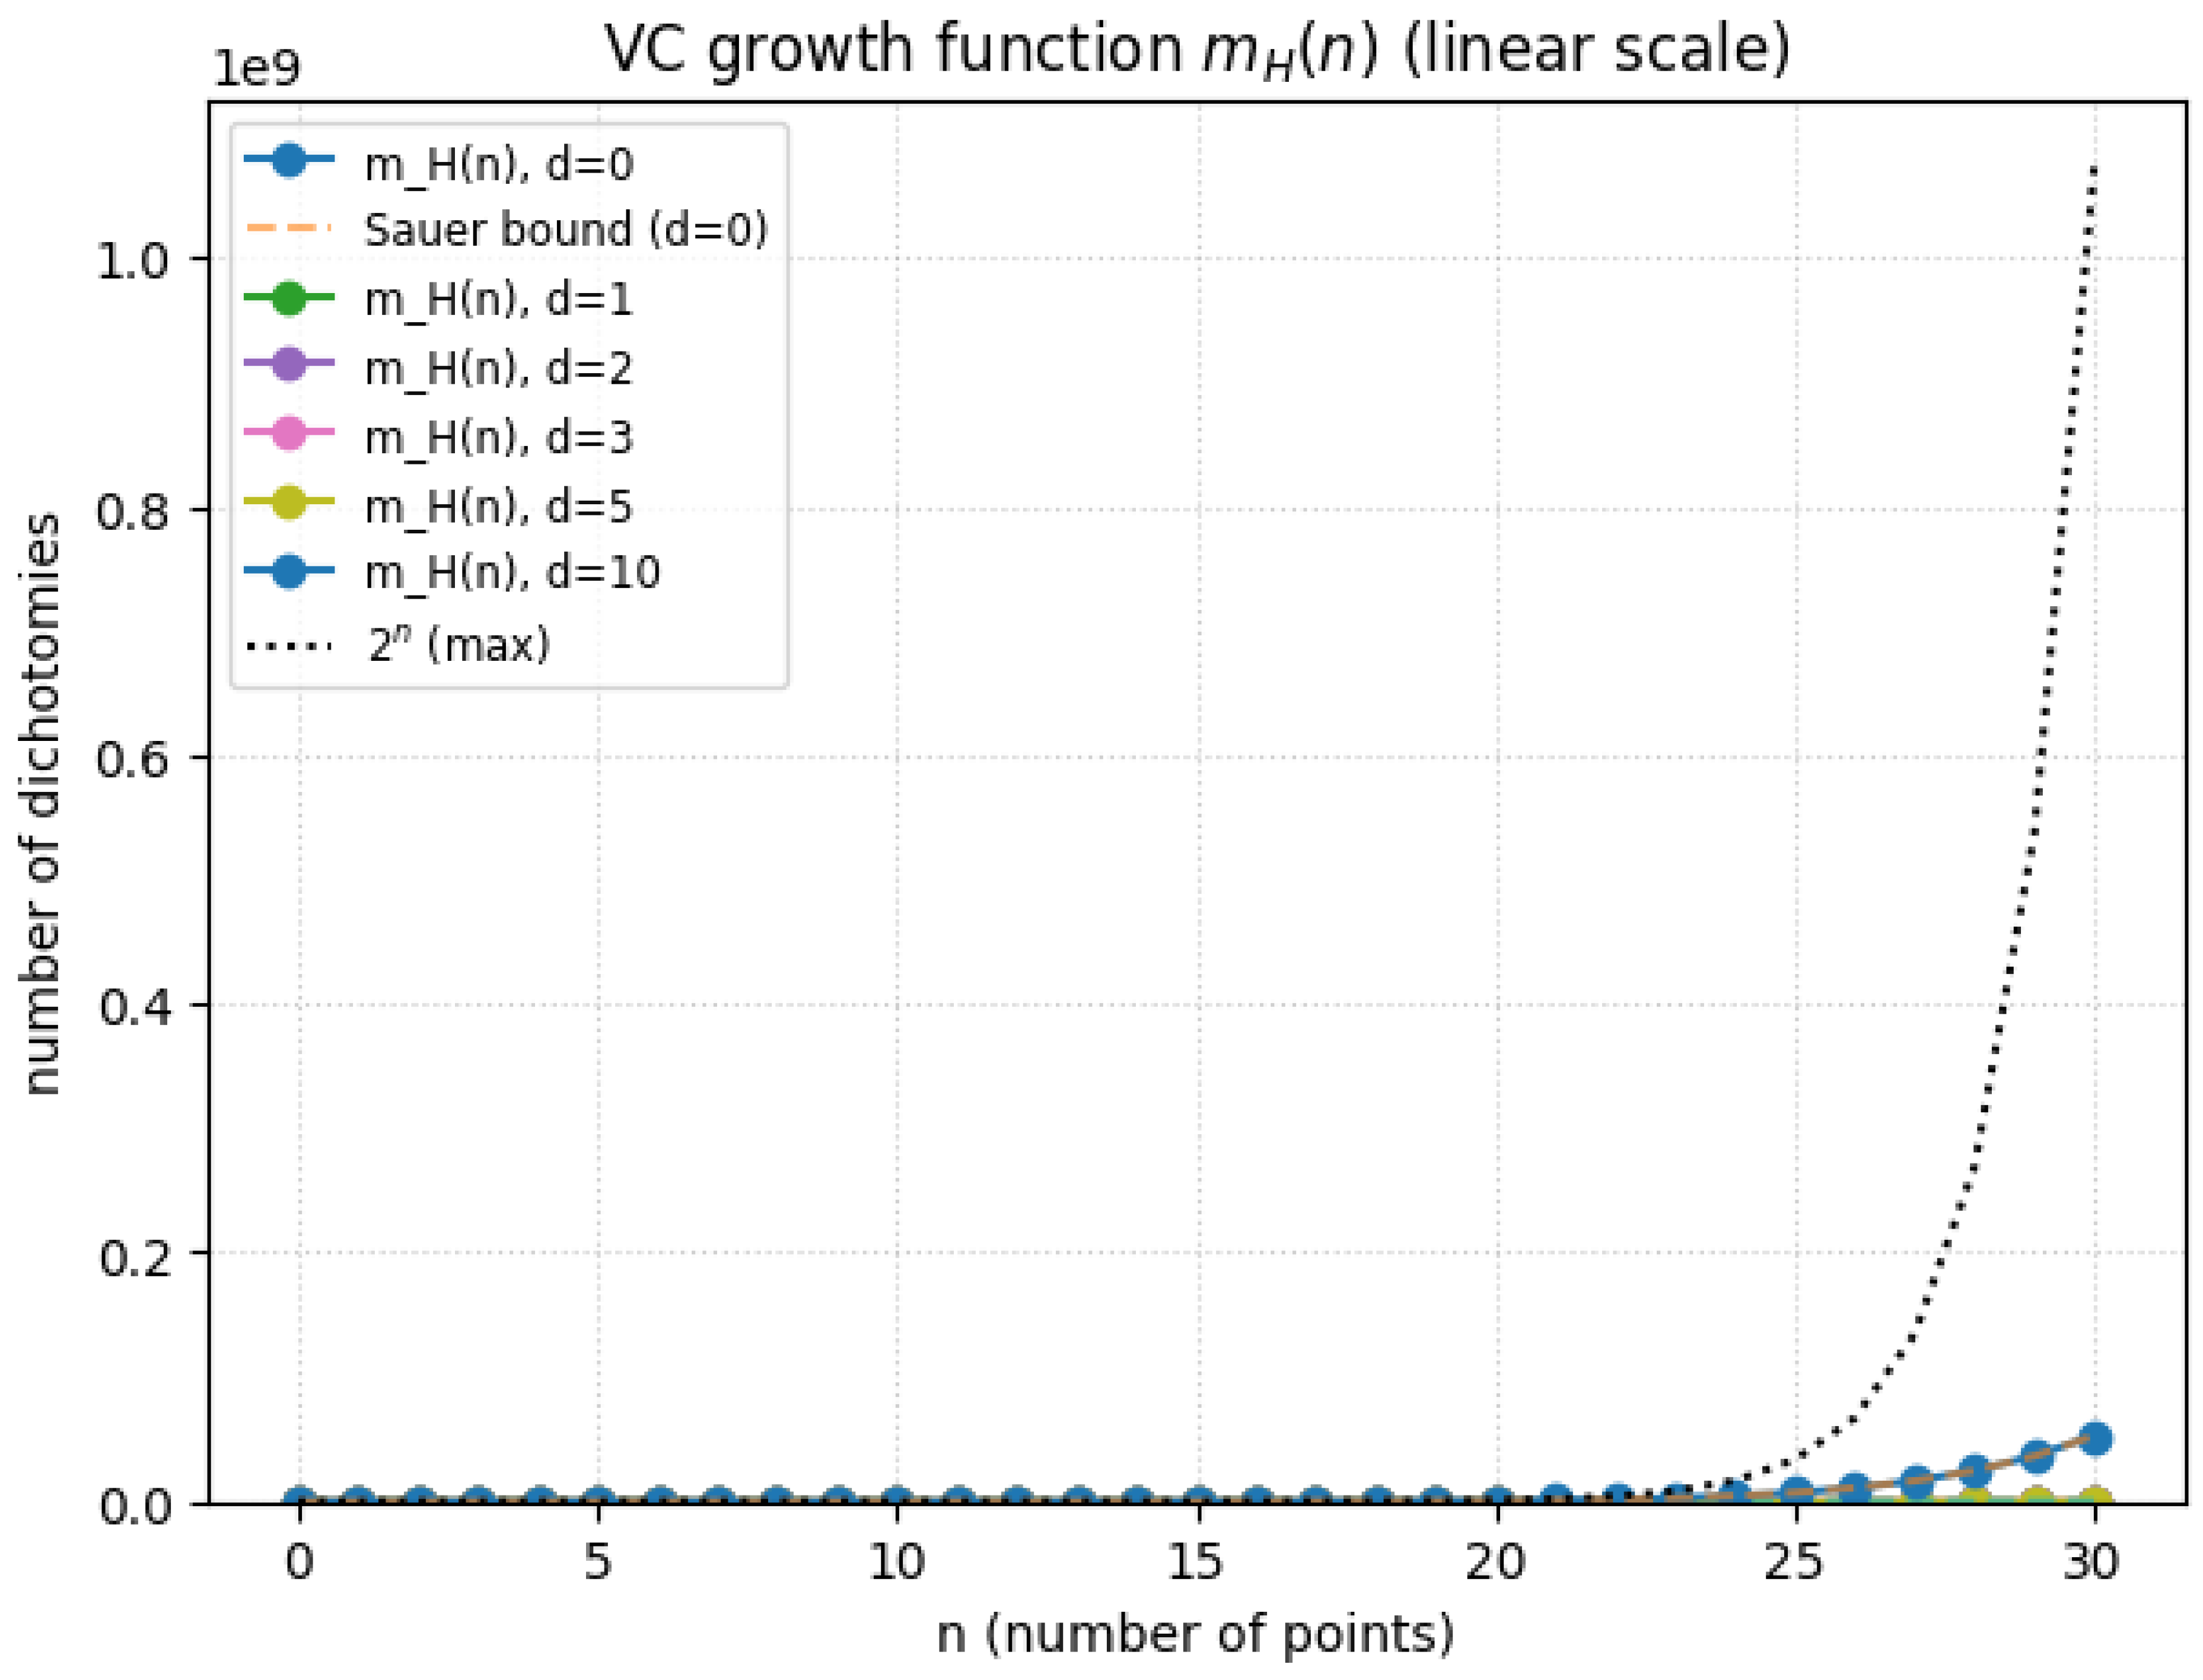
Figure 3.
VC growth function (Log scale)
1.2.2. Rademacher Complexity for Continuous Spaces
1.2.2.1 Literature Review of Rademacher Complexity for Continuous Spaces
Truong (2022) [31] in his article explored how Rademacher complexity impacts generalization error in deep learning, particularly with IID and Markov datasets. Gnecco and Sanguineti (2008) [32] developed approximation error bounds in Reproducing Kernel Hilbert Spaces (RKHS) and functional approximation settings. Astashkin (2010) [33] discusses applications of Rademacher functions in symmetric function spaces and their mathematical structure. Ying and Campbell (2010) [34] applies Rademacher complexity to kernel-based learning problems and support vector machines. Zhu et.al. (2009) [35] examined Rademacher complexity in cognitive models and neural representation learning. Astashkin et al. (2020) [36] investigated how the Rademacher system behaves in function spaces and its role in functional analysis. Sachs et.al. (2023) [37] introduced a refined approach to Rademacher complexity tailored to specific machine learning algorithms. Ma and Wang (2020) [38] investigated Rademacher complexity bounds in deep residual networks. Bartlett and Mendelson (2002) [39] wrote a foundational paper on complexity measures, providing fundamental theoretical insights into generalization bounds. Dzahini and Wild (2024) [40] in their paper extended Rademacher-based complexity to stochastic optimization methods. McDonald and Shalizi (2011) [41] showed using sequential Rademacher complexities for I.I.D process how to control the generalization error of time series models wherein past values of the outcome are used to predict future values.
1.2.2.2 Analysis of Rademacher Complexity for Continuous Spaces
Let represent a probability space where is a measurable space, is a sigma-algebra, and is a probability measure. The function class satisfies:
where denotes the essential supremum. For rigor, is assumed measurable in the sense that for every , there exists a countable subset such that:
Given , the empirical measure is:
The integral under for approximates the population integral under :
Let be independent Rademacher random variables:
These variables are defined on a probability space independent of the sample S.
The Duality and Symmetrization of Empirical Rademacher Complexity is also very important. The empirical Rademacher complexity of with respect to S is:
where denotes expectation over . The supremum can be interpreted as a functional dual norm in , where is the unit ball. Using the symmetrization technique, the Rademacher complexity relates to the deviation of from :
where:
This is derived by first symmetrizing the sample and then invoking Jensen’s inequality and the independence of . There are some Complexity Bounds that use Covering Numbers and Entropy that need to be discussed. In Metric Entropy, we let be the metric on . The covering number satisfies:
Regarding the Dudley’s Entropy Integral, For a bounded function class (compact under ):
There is also a Relation to Talagrand’s Concentration Inequality. Talagrand’s inequality provides tail bounds for the supremum of empirical processes:
reinforcing the link between and generalization.
There are some Applications in Continuous Function Classes. One example is the RKHS with Gaussian Kernel. For as the unit ball of an RKHS with kernel , the covering number satisfies:
yielding:
For , the covering number depends on the smoothness s and dimension d:
Rademacher complexity is deeply embedded in modern empirical process theory. Its intricate relationship with measure-theoretic tools, symmetrization, and concentration inequalities provides a robust theoretical foundation for understanding generalization in high-dimensional spaces.
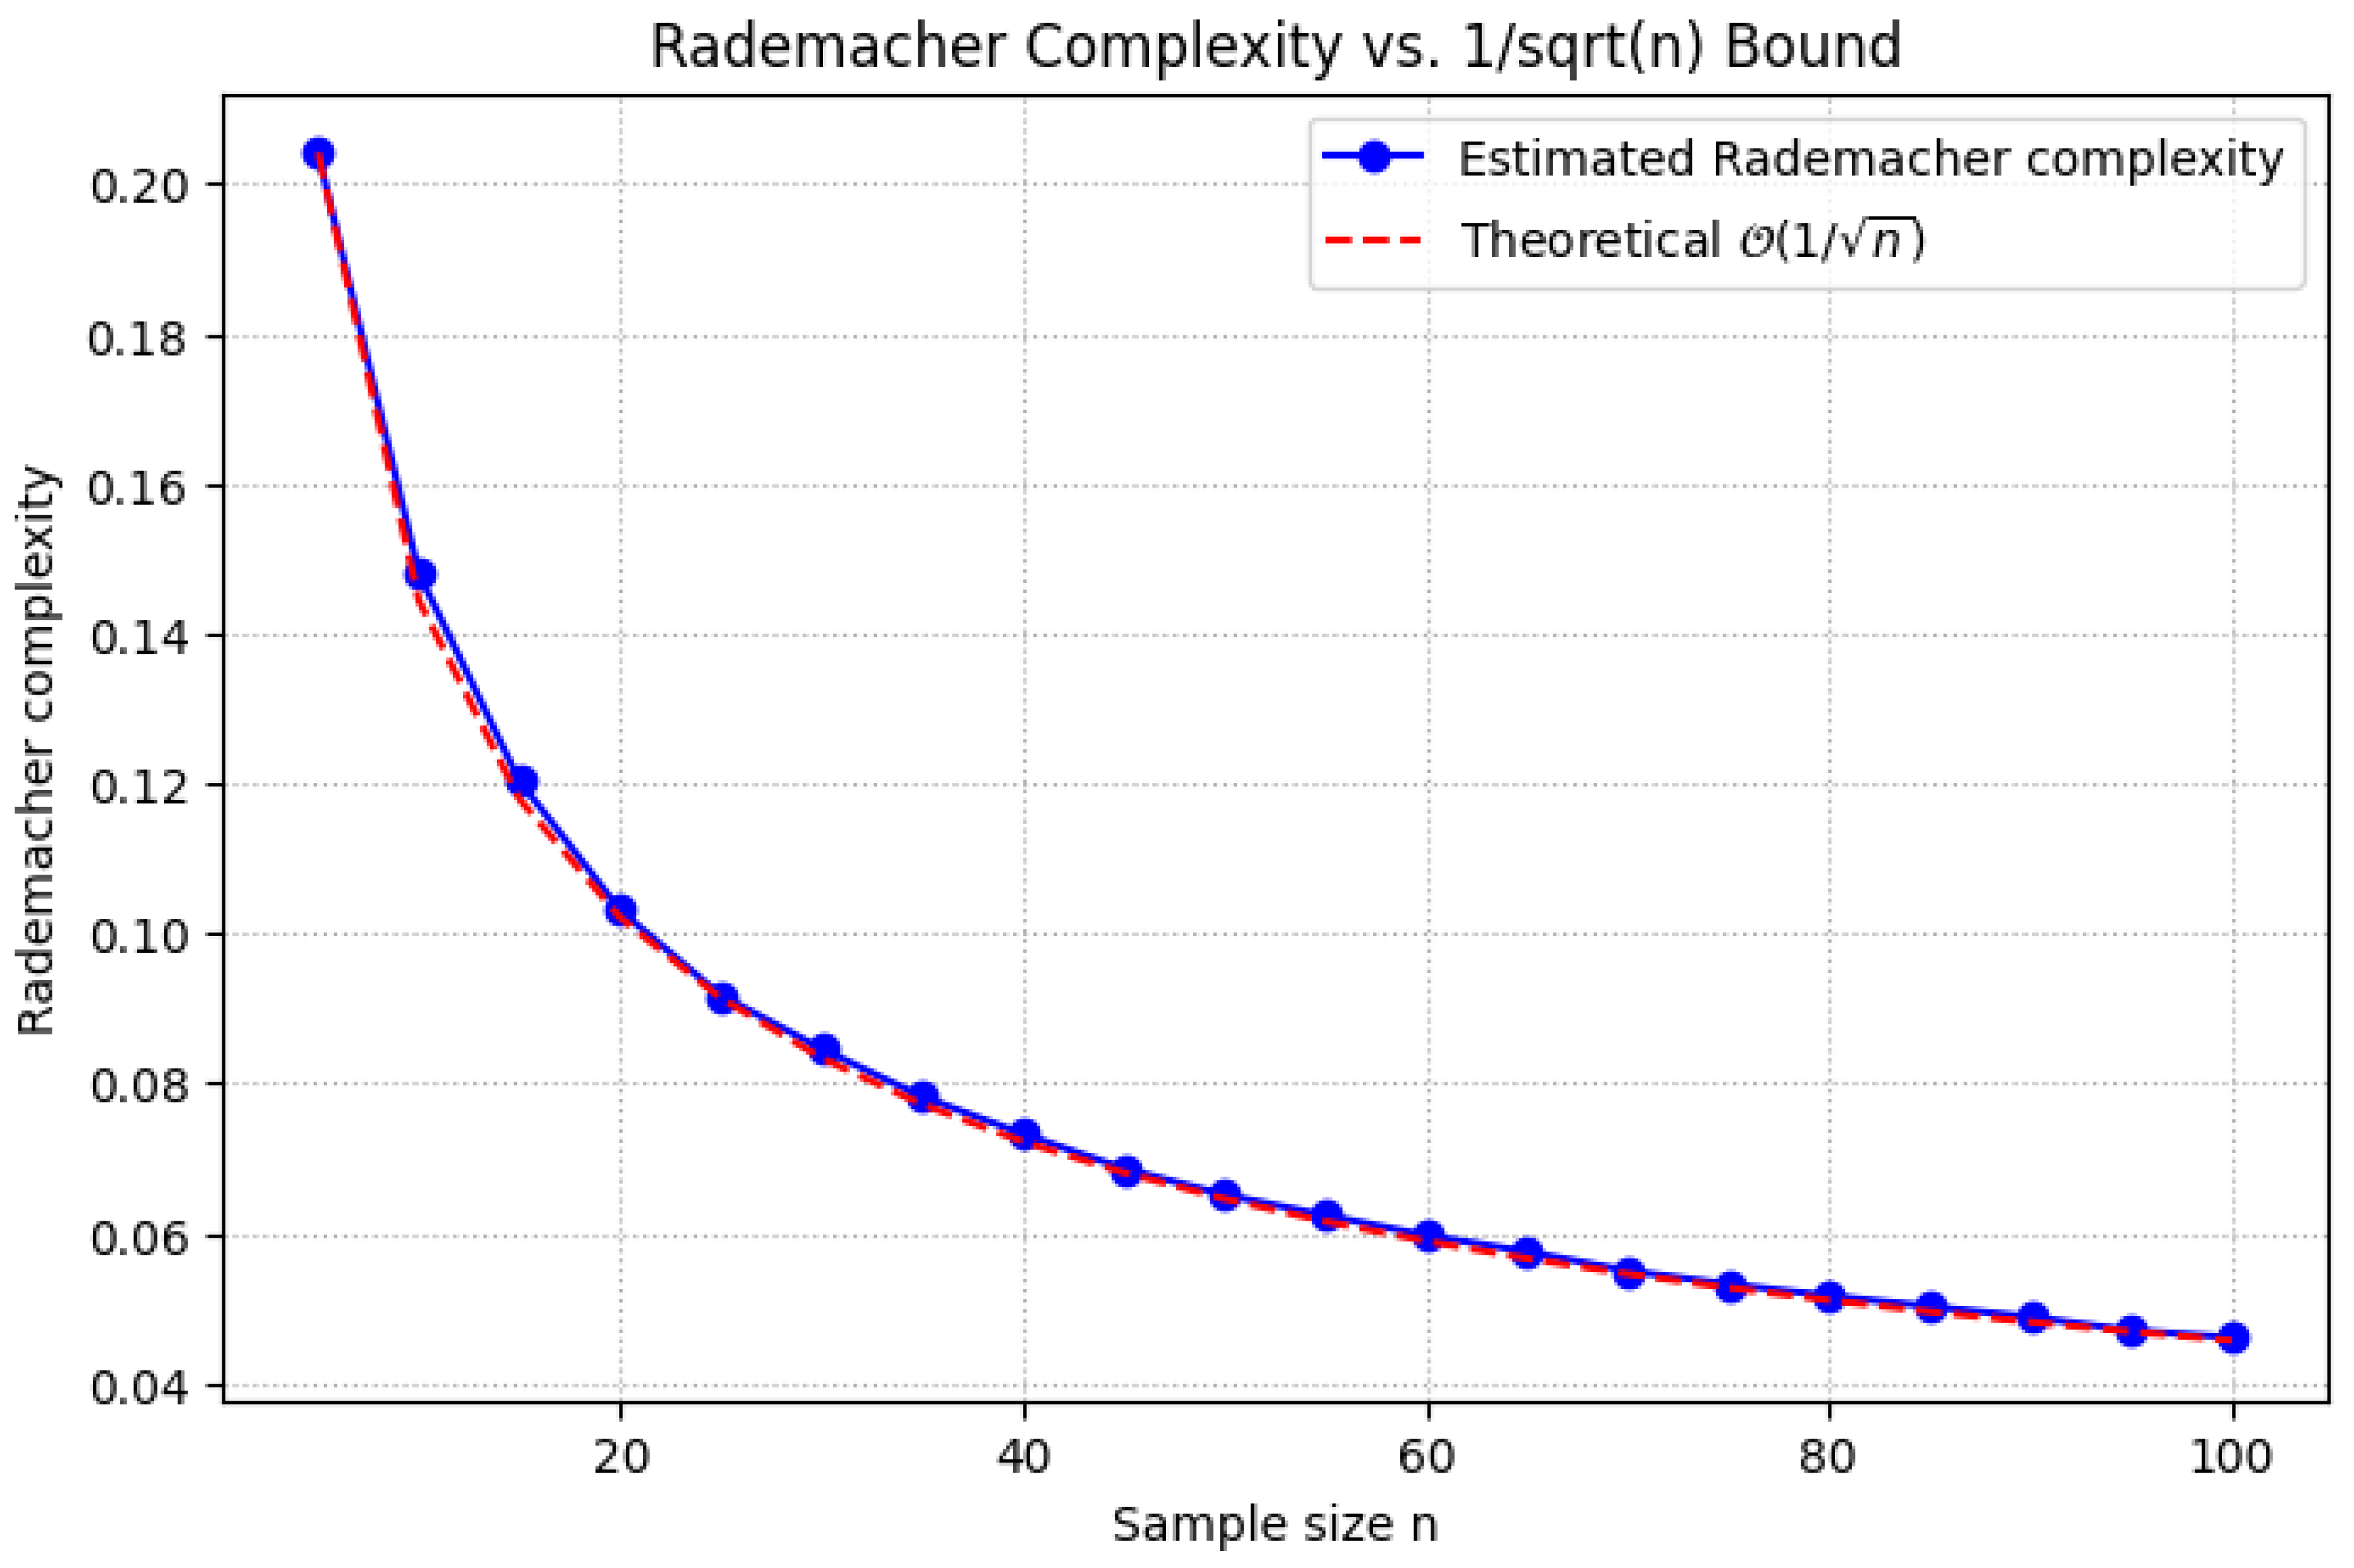
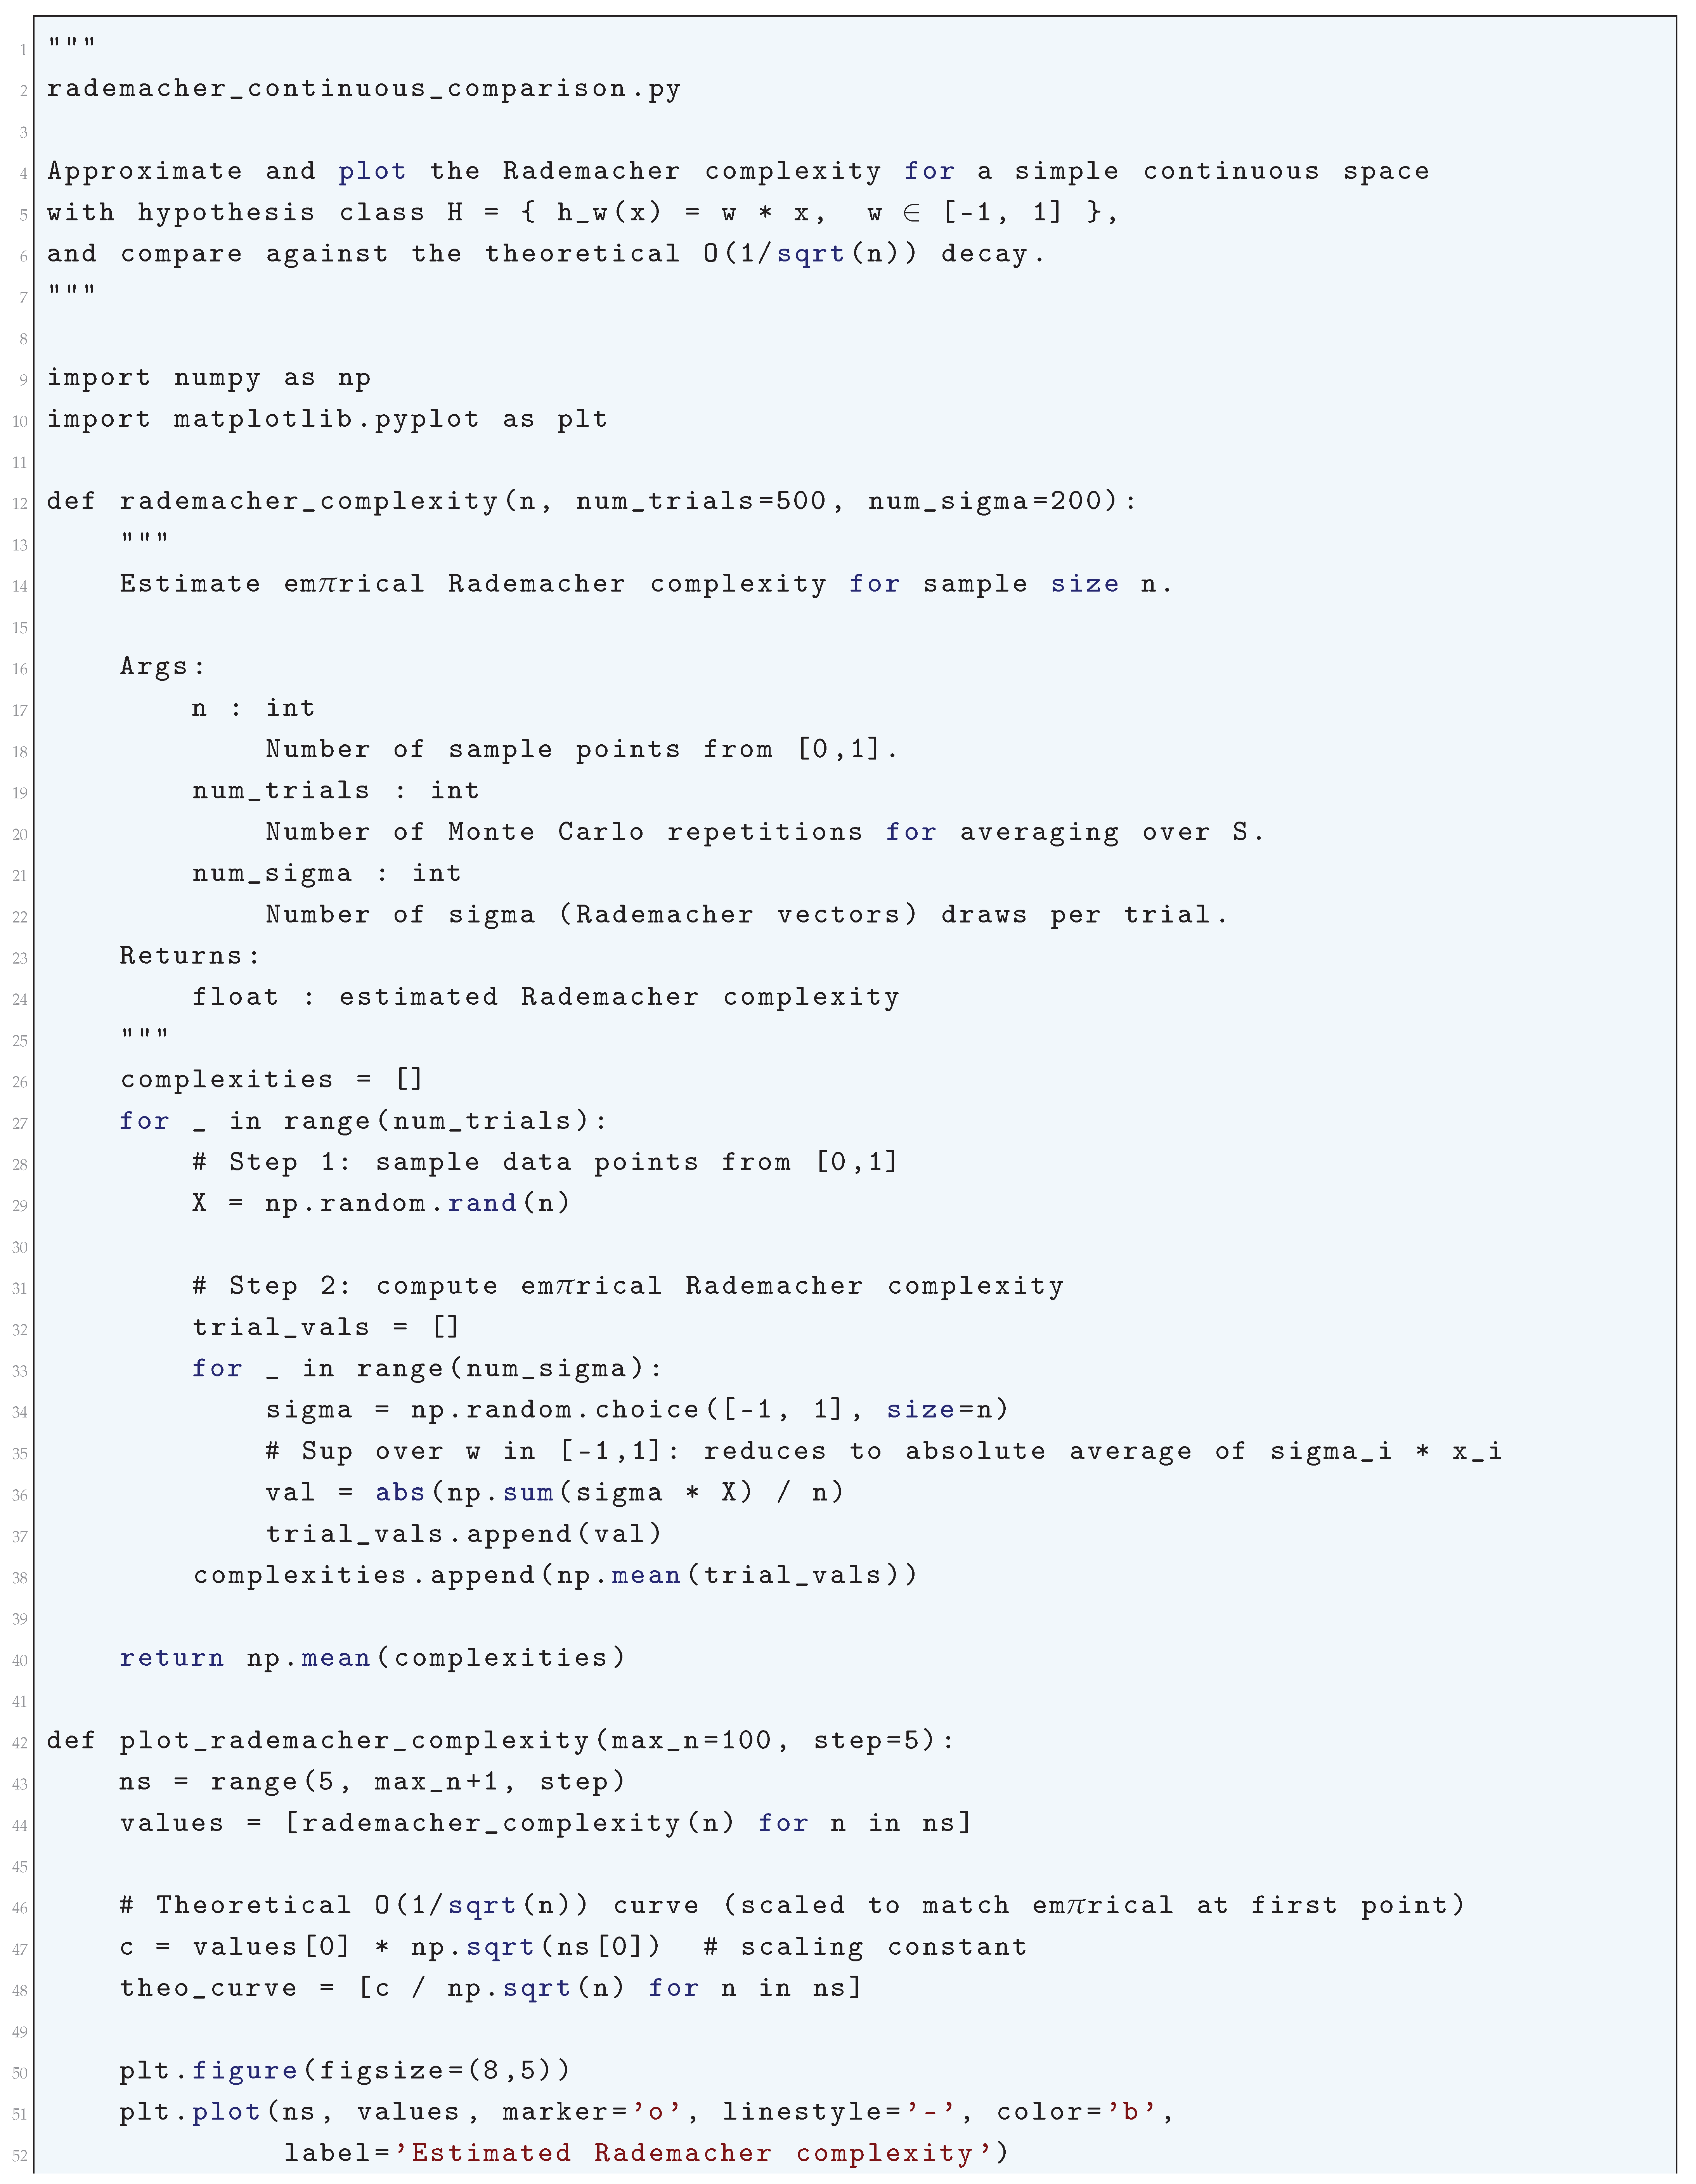
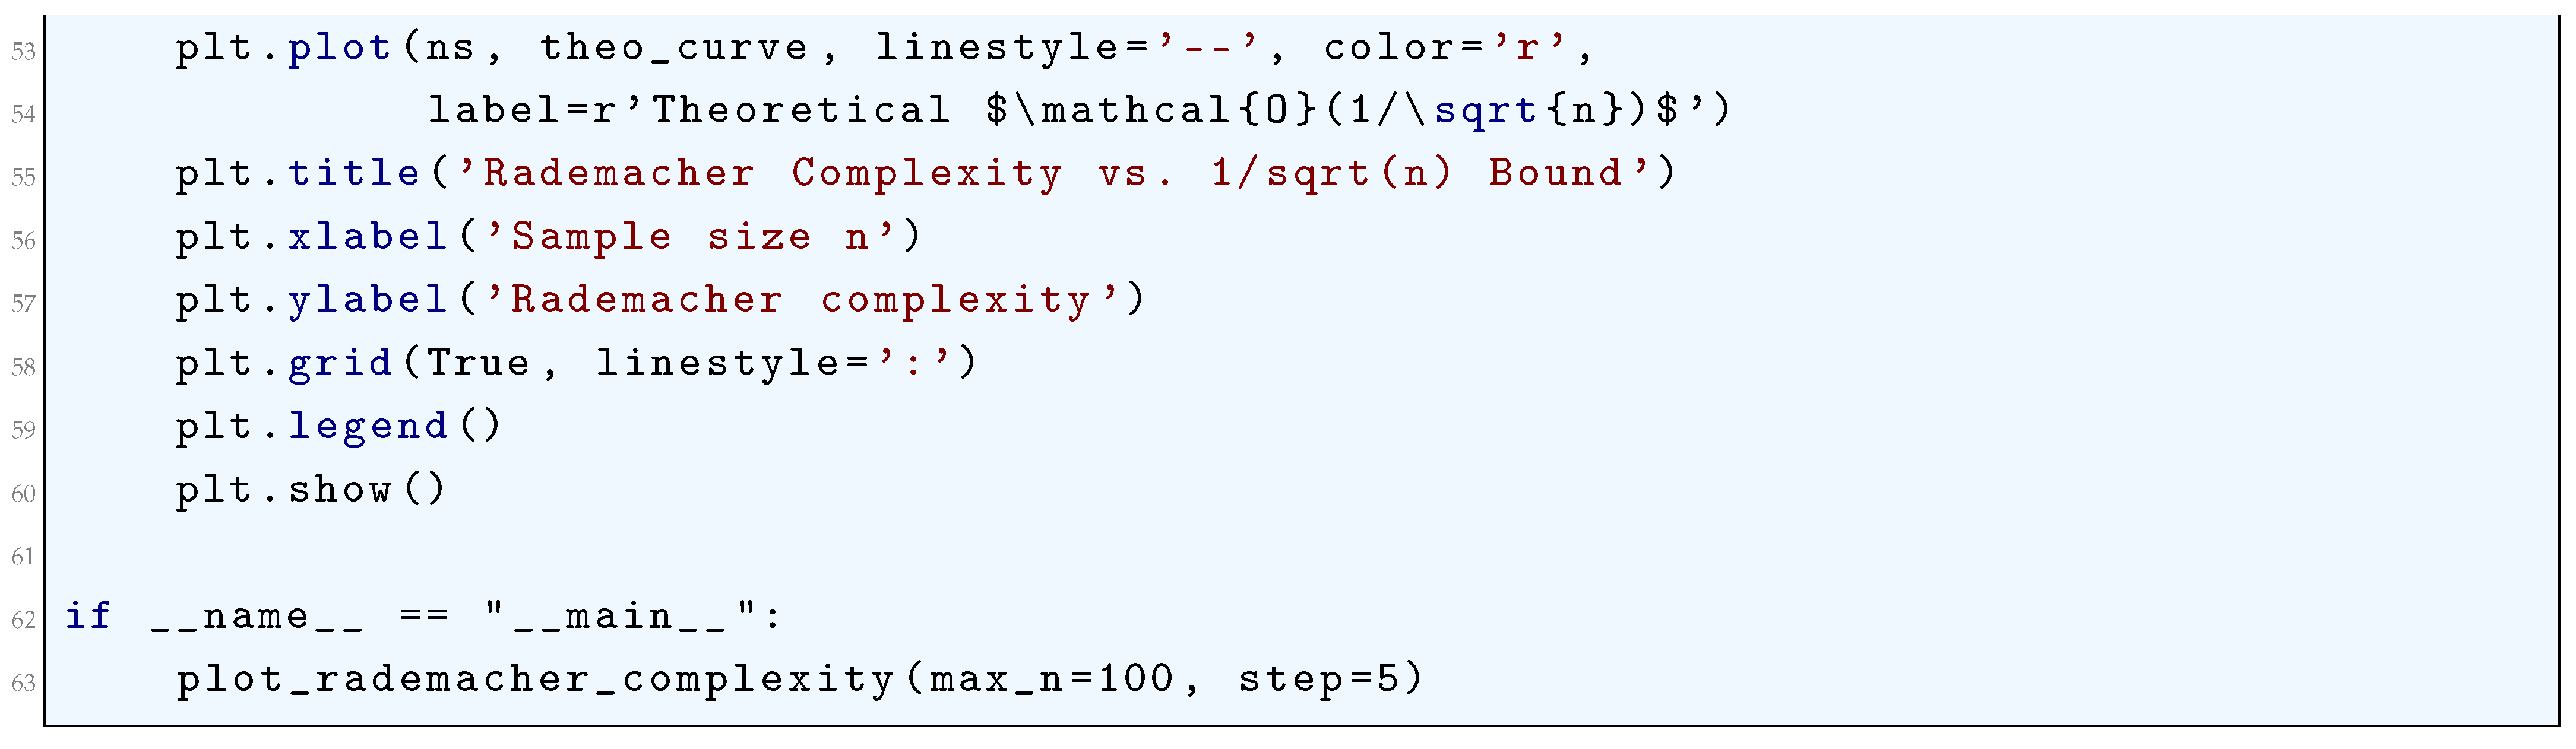
1.2.2.3 Python Code to Generate Figure 4 Illustrating Rademacher Complexity vs. Bound
The Python code below produces the Figure 4 illustrating Rademacher Complexity vs. Bound.
Figure 4.
Rademacher Complexity vs. Bound
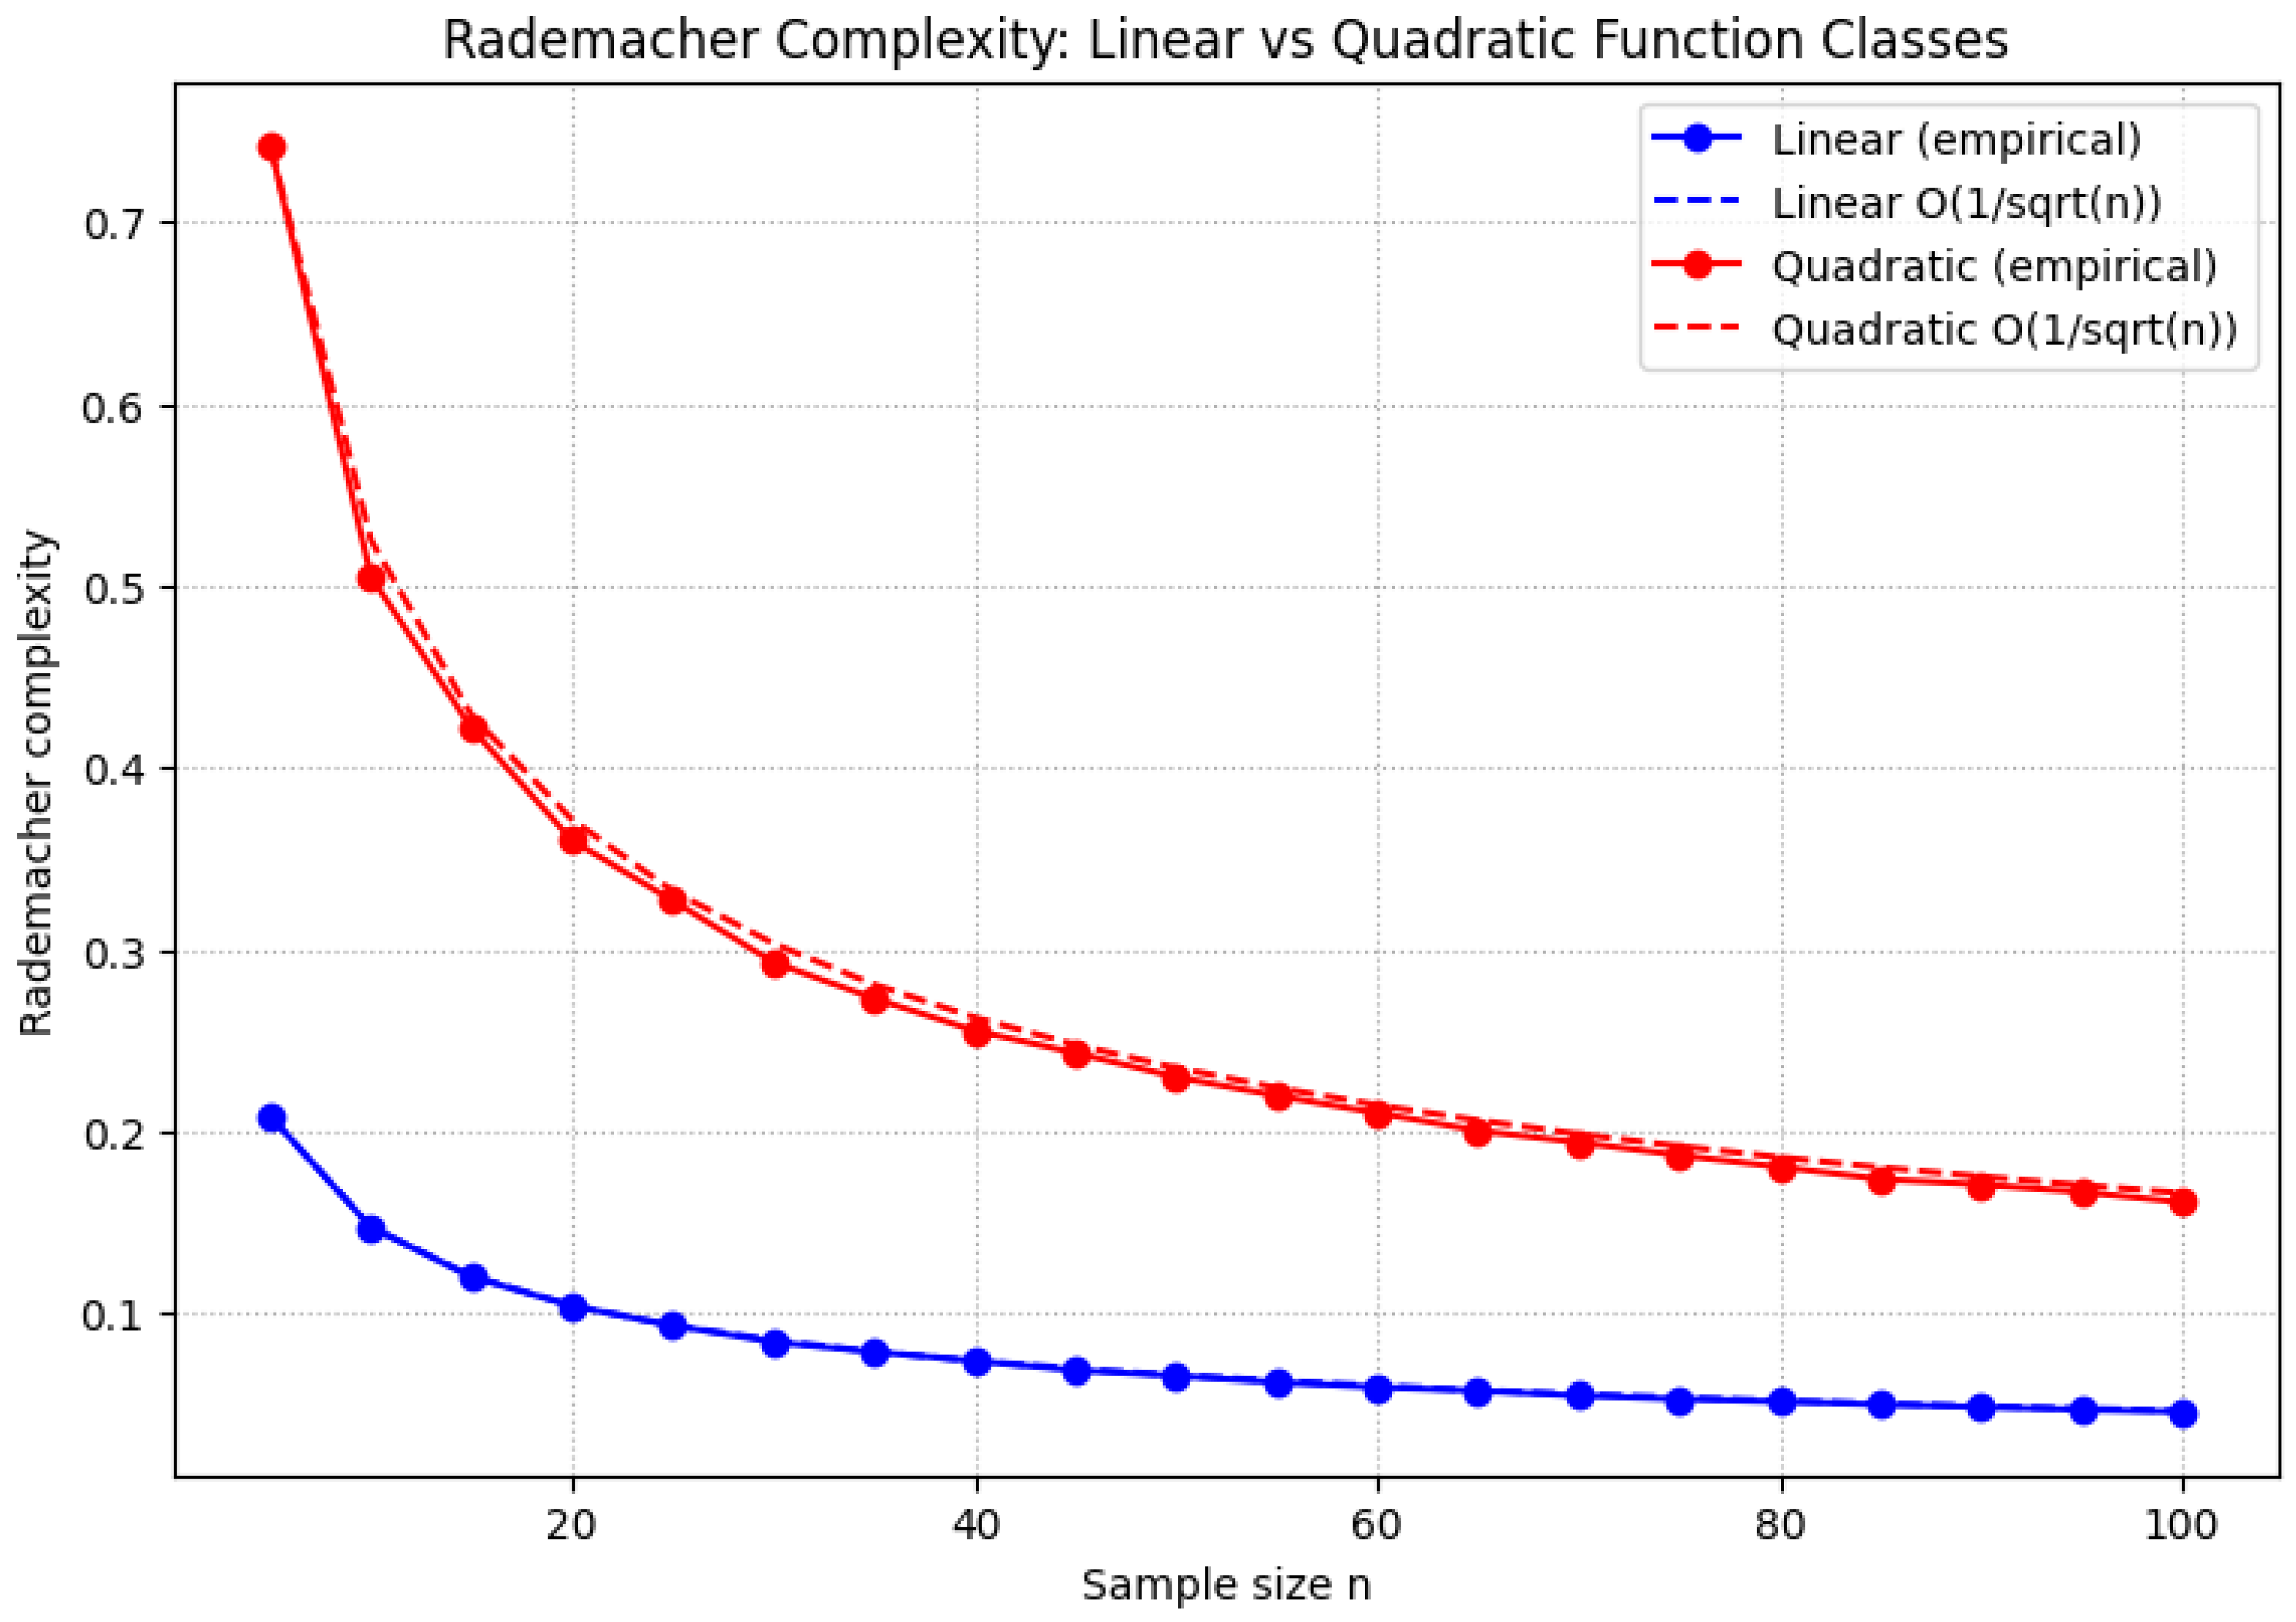
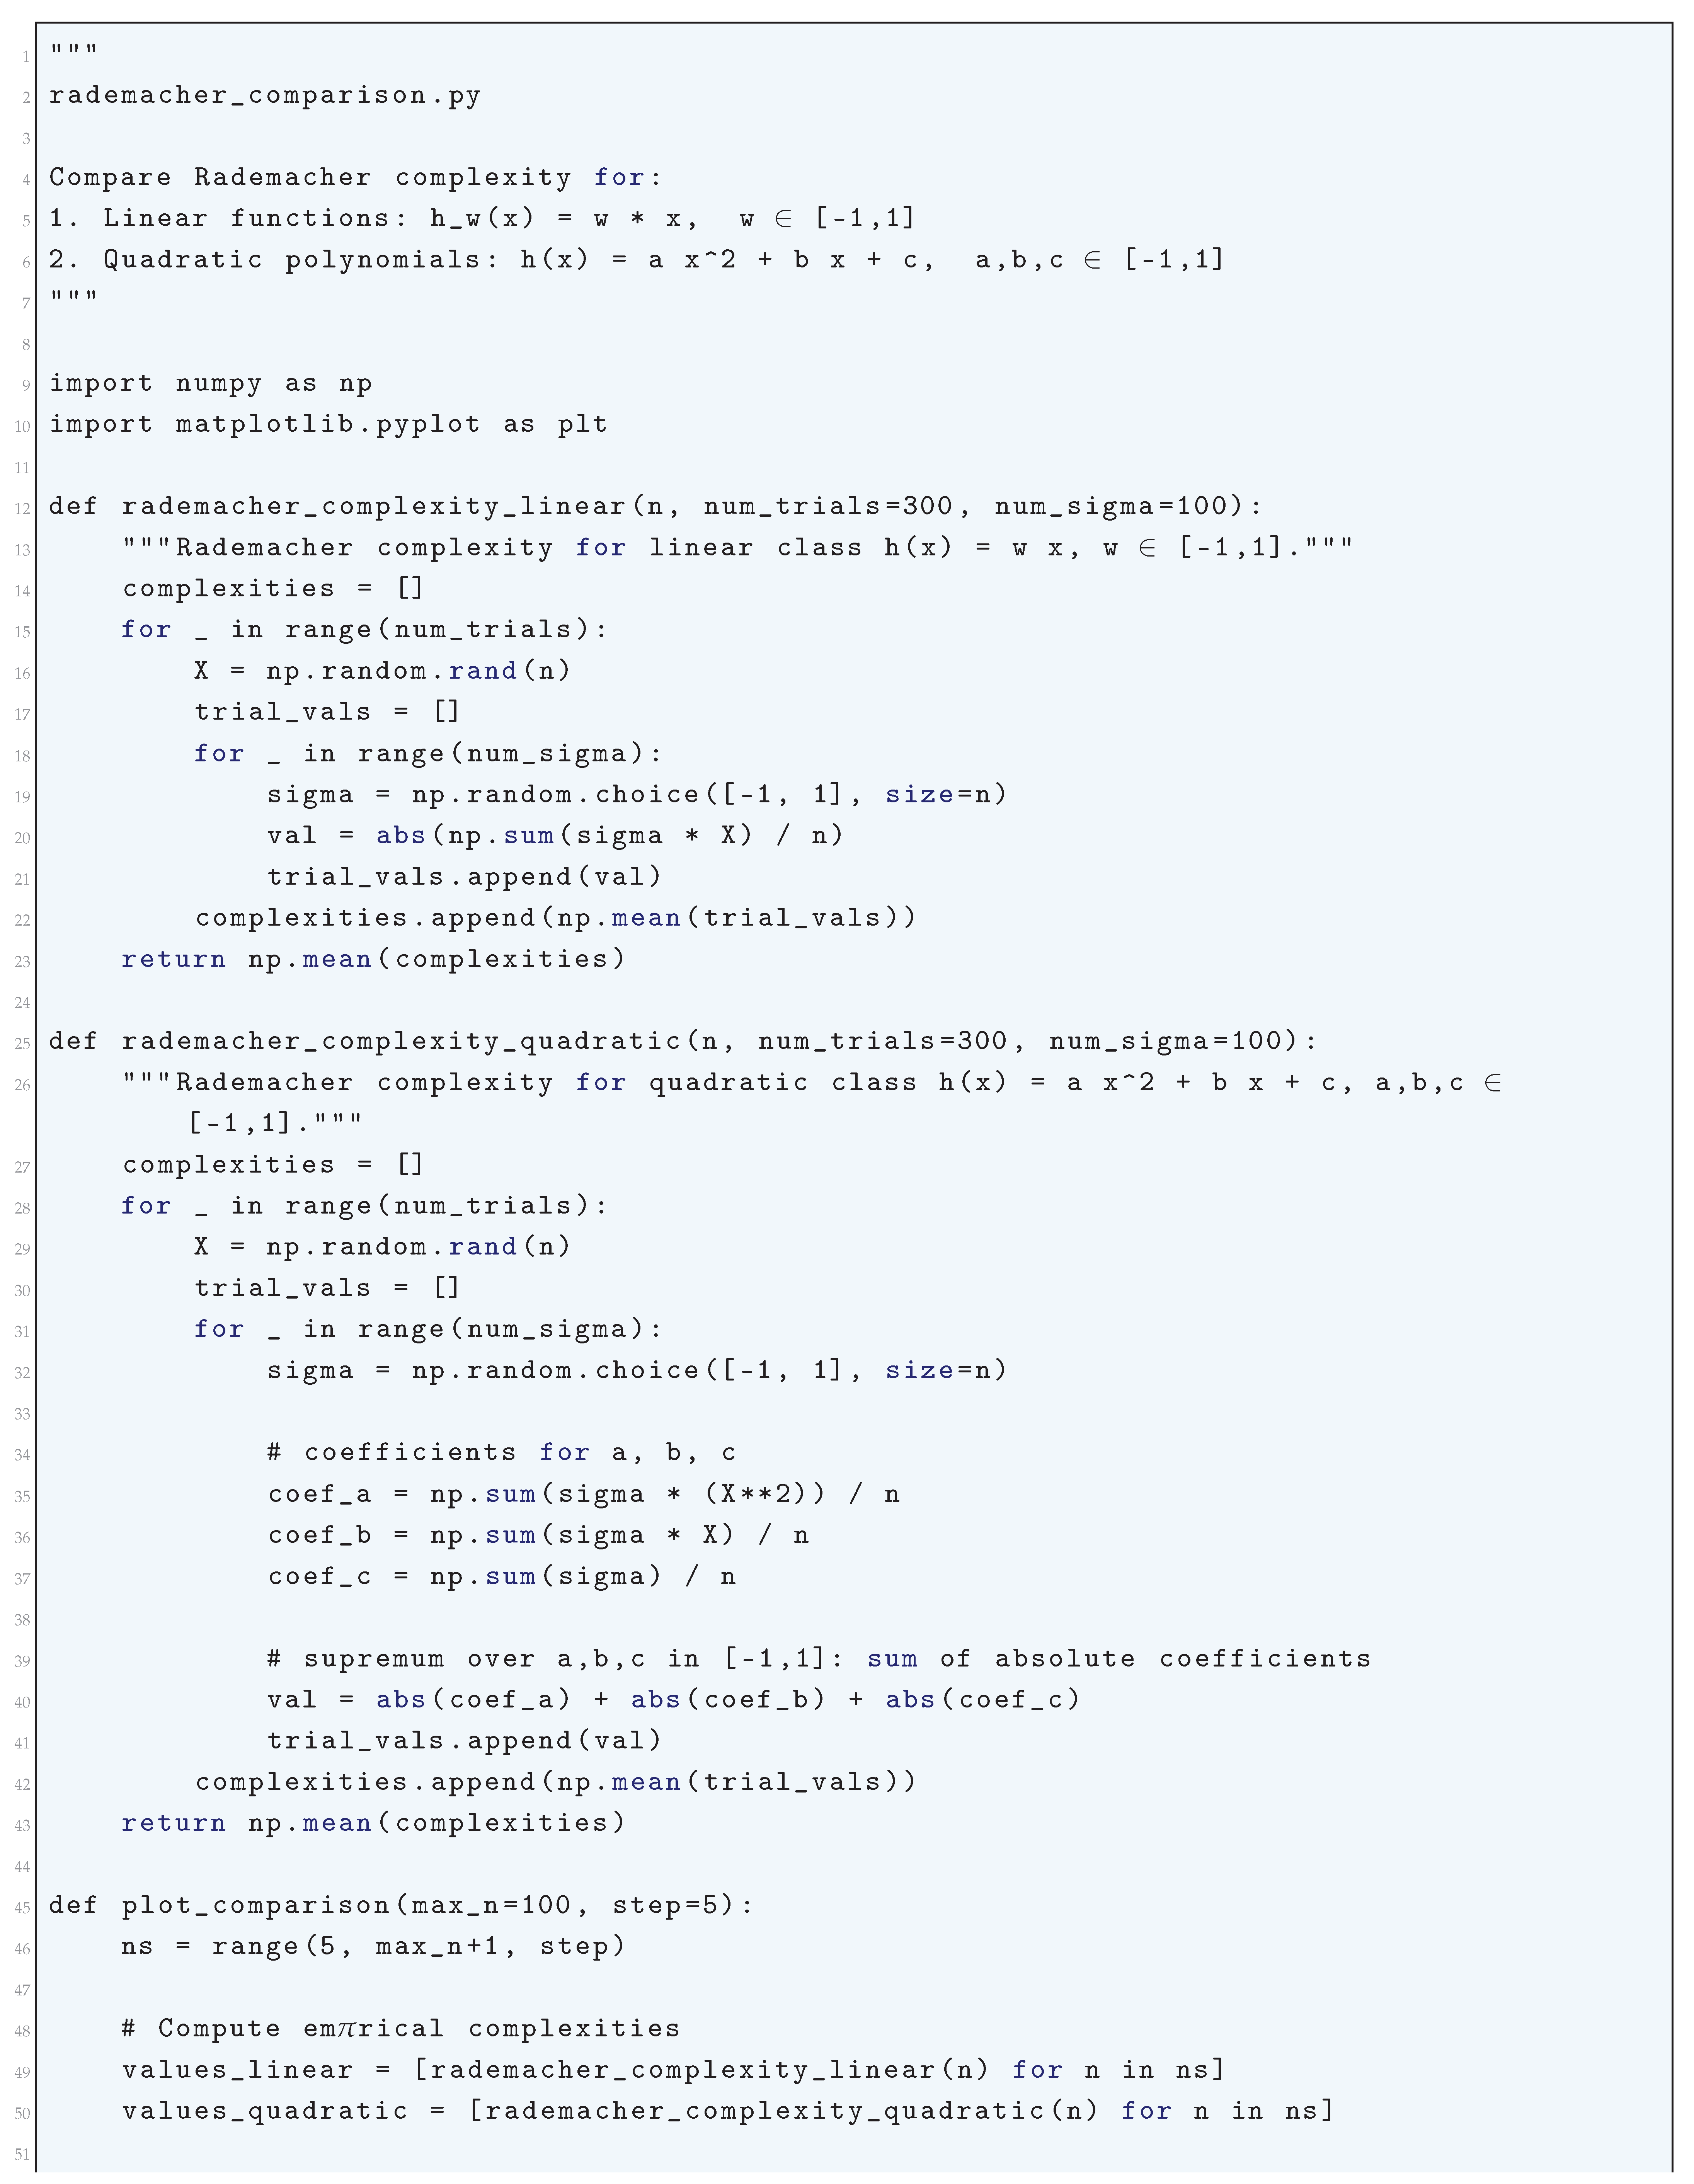
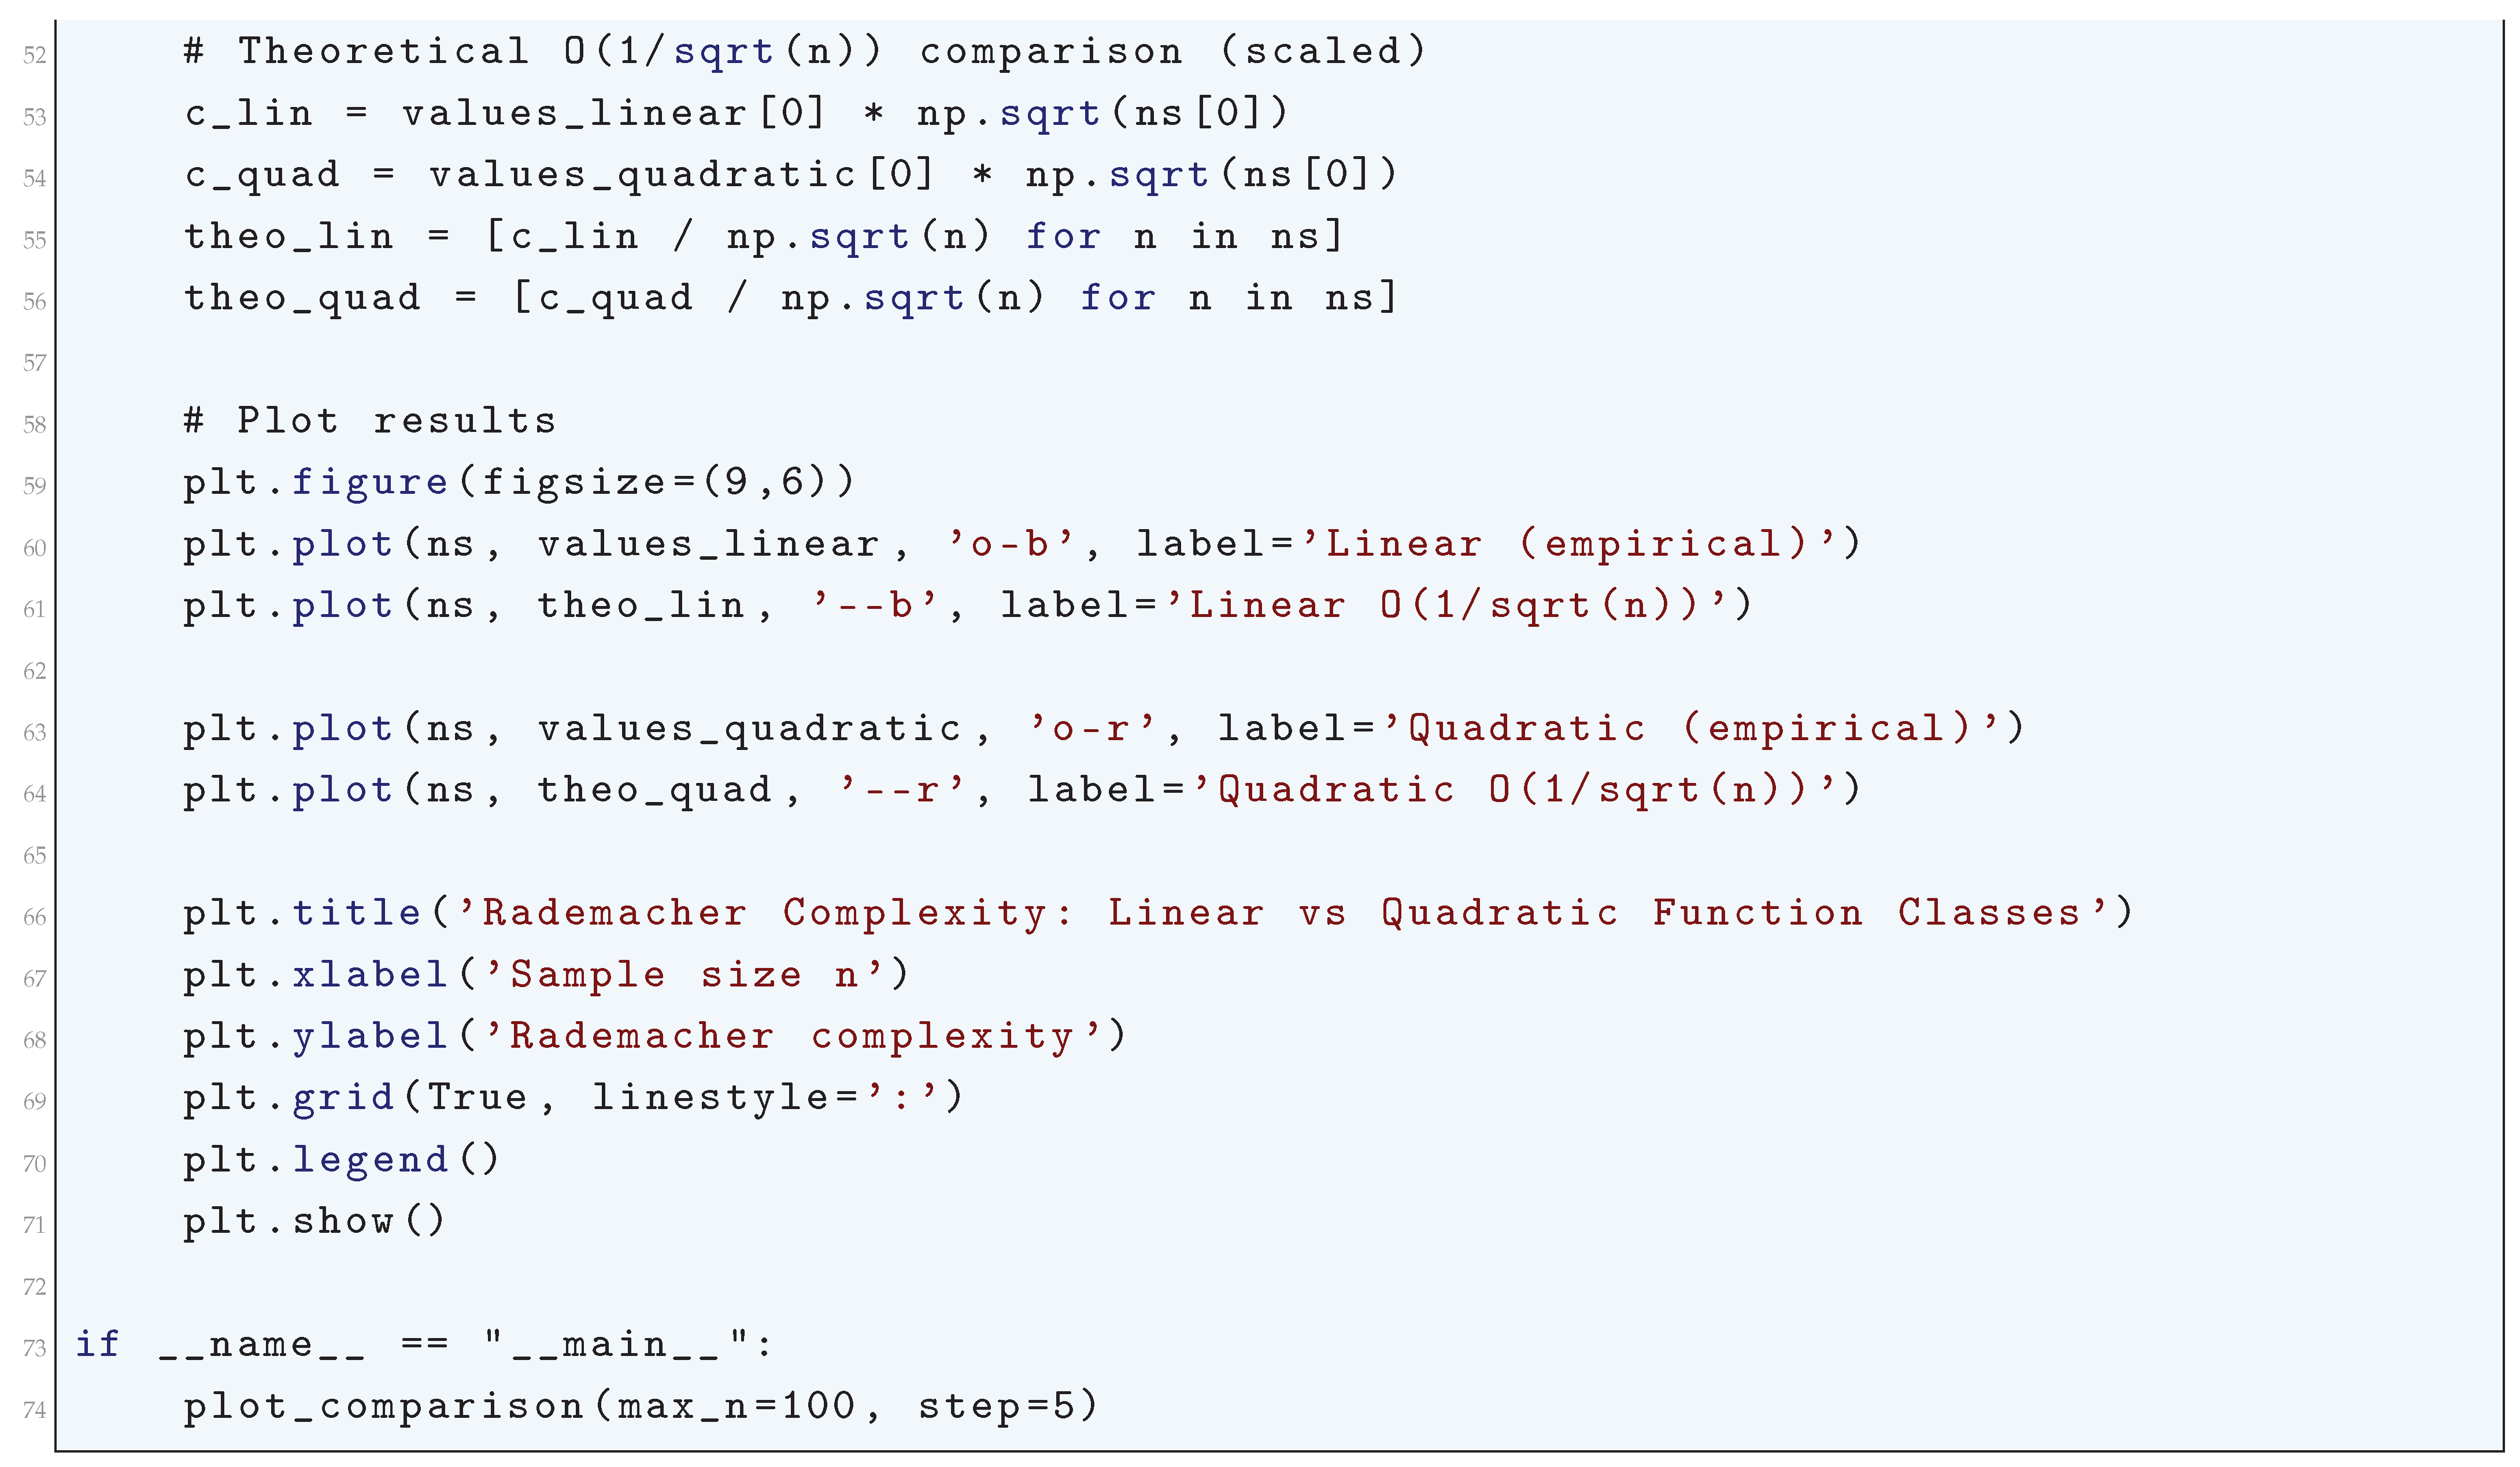
1.2.2.4 Python Code to Generate Figure 5 Illustrating Rademacher Complexity: Linear vs Quadratic Function Classes
The Python code below produces the Figure 5 illustrating Rademacher Complexity: Linear vs Quadratic Function Classes.
Figure 5.
Rademacher Complexity: Linear vs Quadratic Function Classes
1.2.3. Sobolev Embeddings
1.2.3.1 Literature Review of Sobolev Embeddings
Abderachid and Kenza (2024) [42] in their paper investigated fractional Sobolev spaces defined using Riemann-Liouville derivatives and studies their embedding properties. It establishes new continuous embeddings between these fractional spaces and classical Sobolev spaces, providing applications to PDEs. Giang et.al. (2024) [43] introduced weighted Sobolev spaces and derived new Pólya-Szegö type inequalities. These inequalities play a key role in establishing compact embedding results in function spaces equipped with weight functions. Ruiz and Fragkiadaki (2024) [44] provided a novel approach using Haar functions to revisit fractional Sobolev embedding theorems and demonstrated the algebra properties of fractional Sobolev spaces, which are essential in nonlinear analysis. Bilalov et.al. (2025) [45] analyzed compact Sobolev embeddings in Banach function spaces, extending the classical Poincaré and Friedrichs inequalities to this setting and provided applications to function spaces used in modern PDE theory. Cheng and Shao (2025) [46] developed the weighted Sobolev compact embedding theorem for function spaces with unbounded radial potentials and used this result to prove the existence of ground state solutions for fractional Schrödinger-Poisson equations. Wei and Zhang (2025) [47] established a new embedding theorem tailored to variational problems arising in Schrödinger-Poisson equations and used Hardy-Sobolev embeddings to study the zero-mass case, an important case in quantum mechanics. Zhang and Qi (2025) [48] examined the compactness of Sobolev embeddings in the presence of small perturbations in quasilinear elliptic equations and proved multiple solution existence results using variational methods. Xiao and Yue (2025) [49] established a Sobolev embedding theorem for fractional Laplacian function spaces and applied the embedding results to image processing, particularly edge detection. Pesce and Portaro (2025) [50] studied intrinsic Hölder spaces and their connection to fractional Sobolev embeddings and established new embedding results for function spaces relevant to ultraparabolic operators.
1.2.3.2 Analysis of Sobolev Embeddings
The Sobolev embedding theorem states that:
if , ensuring for smooth activations . For a function , its weak derivative satisfies:
where is the weak derivative.
This definition extends the classical notion of differentiation to functions that may not be pointwise differentiable. The Sobolev norm encapsulates both function values and their derivatives:
Key properties:
- Semi-norm Dominance: The Wk,p-norm is controlled by the seminorm , ensuring sensitivity to highorder derivatives.
- Poincaré Inequality: For Ω bounded, u − uΩ satisfies:
Sobolev spaces embed into or , depending on and n. These embeddings govern the smoothness and integrability of u and its derivatives. There are several Advanced Theorems on Sobolev Embeddings. They are as follows:
-
Sobolev Embedding Theorem: Let be a bounded domain with Lipschitz boundary. Then:
- If k > n/p, Wk,p(Ω) ↪ Cm,α() with m = ⌊k − n/p⌋ and α = k − n/p − m.
- If k = n/p, Wk,p(Ω) ↪ Lq(Ω) for q < ∞.
- If k < n/p, Wk,p(Ω) ↪ Lq(Ω) where .
-
Rellich-Kondrachov Compactness Theorem: The embedding is compact for . Compactness follows from:
- (a)
- Equicontinuity: -boundedness ensures uniform control over oscillations.
- (b)
- Rellich’s Selection Principle: Strong convergence follows from uniform estimates and tightness.
The Proof of Sobolev Embedding starts with the Scaling Analysis. Define . Then:
For derivatives:
The scaling relation aligns with the Sobolev embedding condition . Sobolev norms in are equivalent to decay rates of Fourier coefficients:
For , Fourier decay implies uniform bounds, ensuring .
Interpolation spaces bridge and , providing finer embeddings. Duality: Sobolev embeddings are equivalent to boundedness of adjoint operators in . For , ensures
if . Sobolev spaces govern variational problems in geometry, e.g., minimal surfaces and harmonic maps. On with fractal boundaries, trace theorems refine Sobolev embeddings.
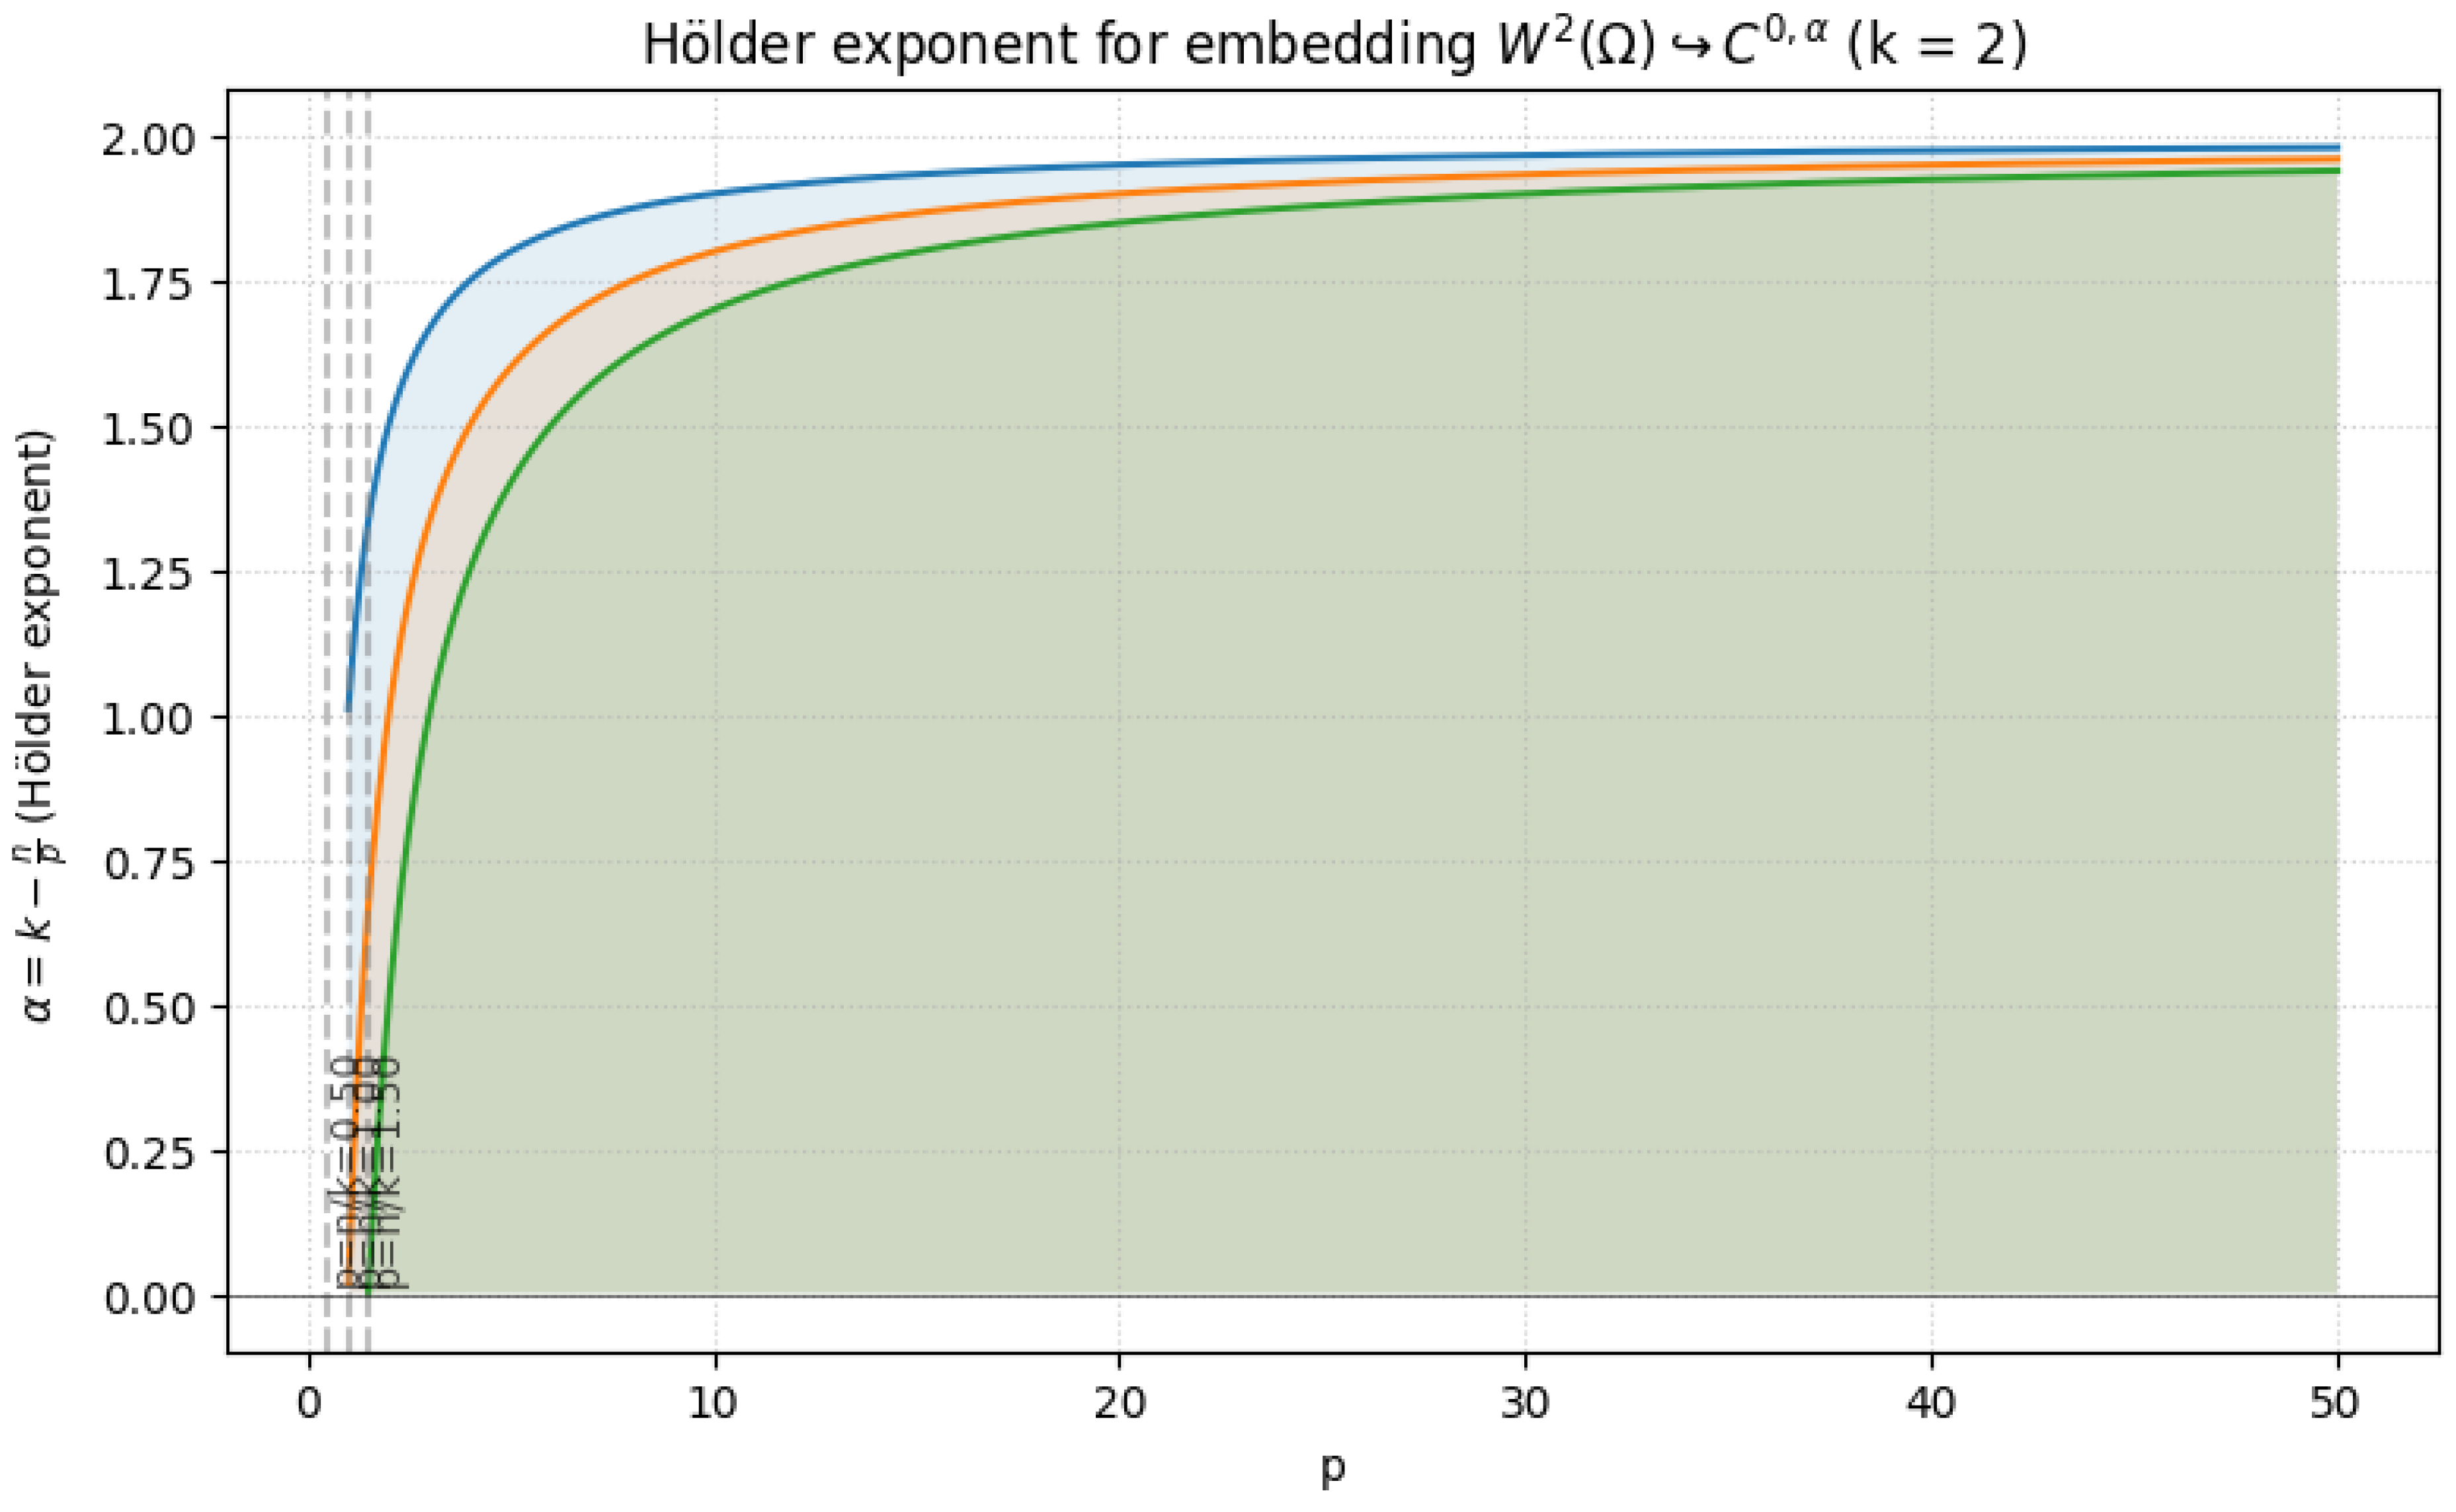
The Sobolev Embedding Theorem provides a continuous embedding of the space into a Hölder space when the regularity index exceeds the spatial dimension, specifically when . The Hölder exponent is not arbitrary but is given by the precise fractional part of this index. The fundamental equation is
but this holds strictly only if this value is less than 1. The general formulation is
provided . This relation is derived from scaling invariance properties of the underlying Sobolev norms. Consider the dilation . The Sobolev norm scales as
while the Hölder seminorm scales as
For an embedding to be scale-invariant, the scaling exponents must be consistent across the inequality
which forces the condition
leading directly to the identification
The optimality of this exponent is rigorously demonstrated by examining borderline functions that saturate the Sobolev inequalities. A canonical example is the function defined on a bounded domain containing the origin. Its membership in is determined by the integrability of its derivatives. The norm of the k-th derivative involves integrating
In n dimensions, using spherical coordinates, this integral is finite near zero if and only if
which requires , or equivalently, . Conversely, the Hölder continuity of is determined by the ratio . For , this seminorm is finite if and only if . The limiting case shows that a function can be in yet fail to be Hölder continuous for any exponent greater than . This is formalized by considering the function
where a detailed calculation shows that for , the function belongs to only if , but its Hölder seminorm is infinite, proving that the embedding
for the critical exponent , but holds for any .
The quantitative control offered by the Hölder exponent is expressed through the embedding inequality , where the norm on the left is defined as
The constant C depends on , and the domain . The mathematical rigor of the exponent is further highlighted in the Gagliardo-Nirenberg interpolation inequalities, which provide estimates of the form
where the parameters satisfy
and
Setting , , and seeking continuity implies , which recovers the condition . The Hölder exponent emerges when estimating the modulus of continuity directly from the -norm via the integral representation of a function through its derivatives, such as using the Fourier transform or convolution with a mollifier, leading to pointwise estimates like
for , where
For higher derivatives, the general formula
consistently appears, governing the precise degree of classical regularity attainable from weak solutions. This makes the Hölder exponent a fundamental bridge between the measurable, integral-based world of Sobolev spaces and the pointwise, geometric world of classical analysis.
1.2.3.3 Python Code to Generate Figure 6, Figure 7, Figure 8, and Figure 9 Illustrating Sobolev Embeddings
The Python code below produces the Figure 6, Figure 7, Figure 8, and Figure 9 illustrating Sobolev Embeddings.
Figure 6.
Sobolev conjugate (k = 1)
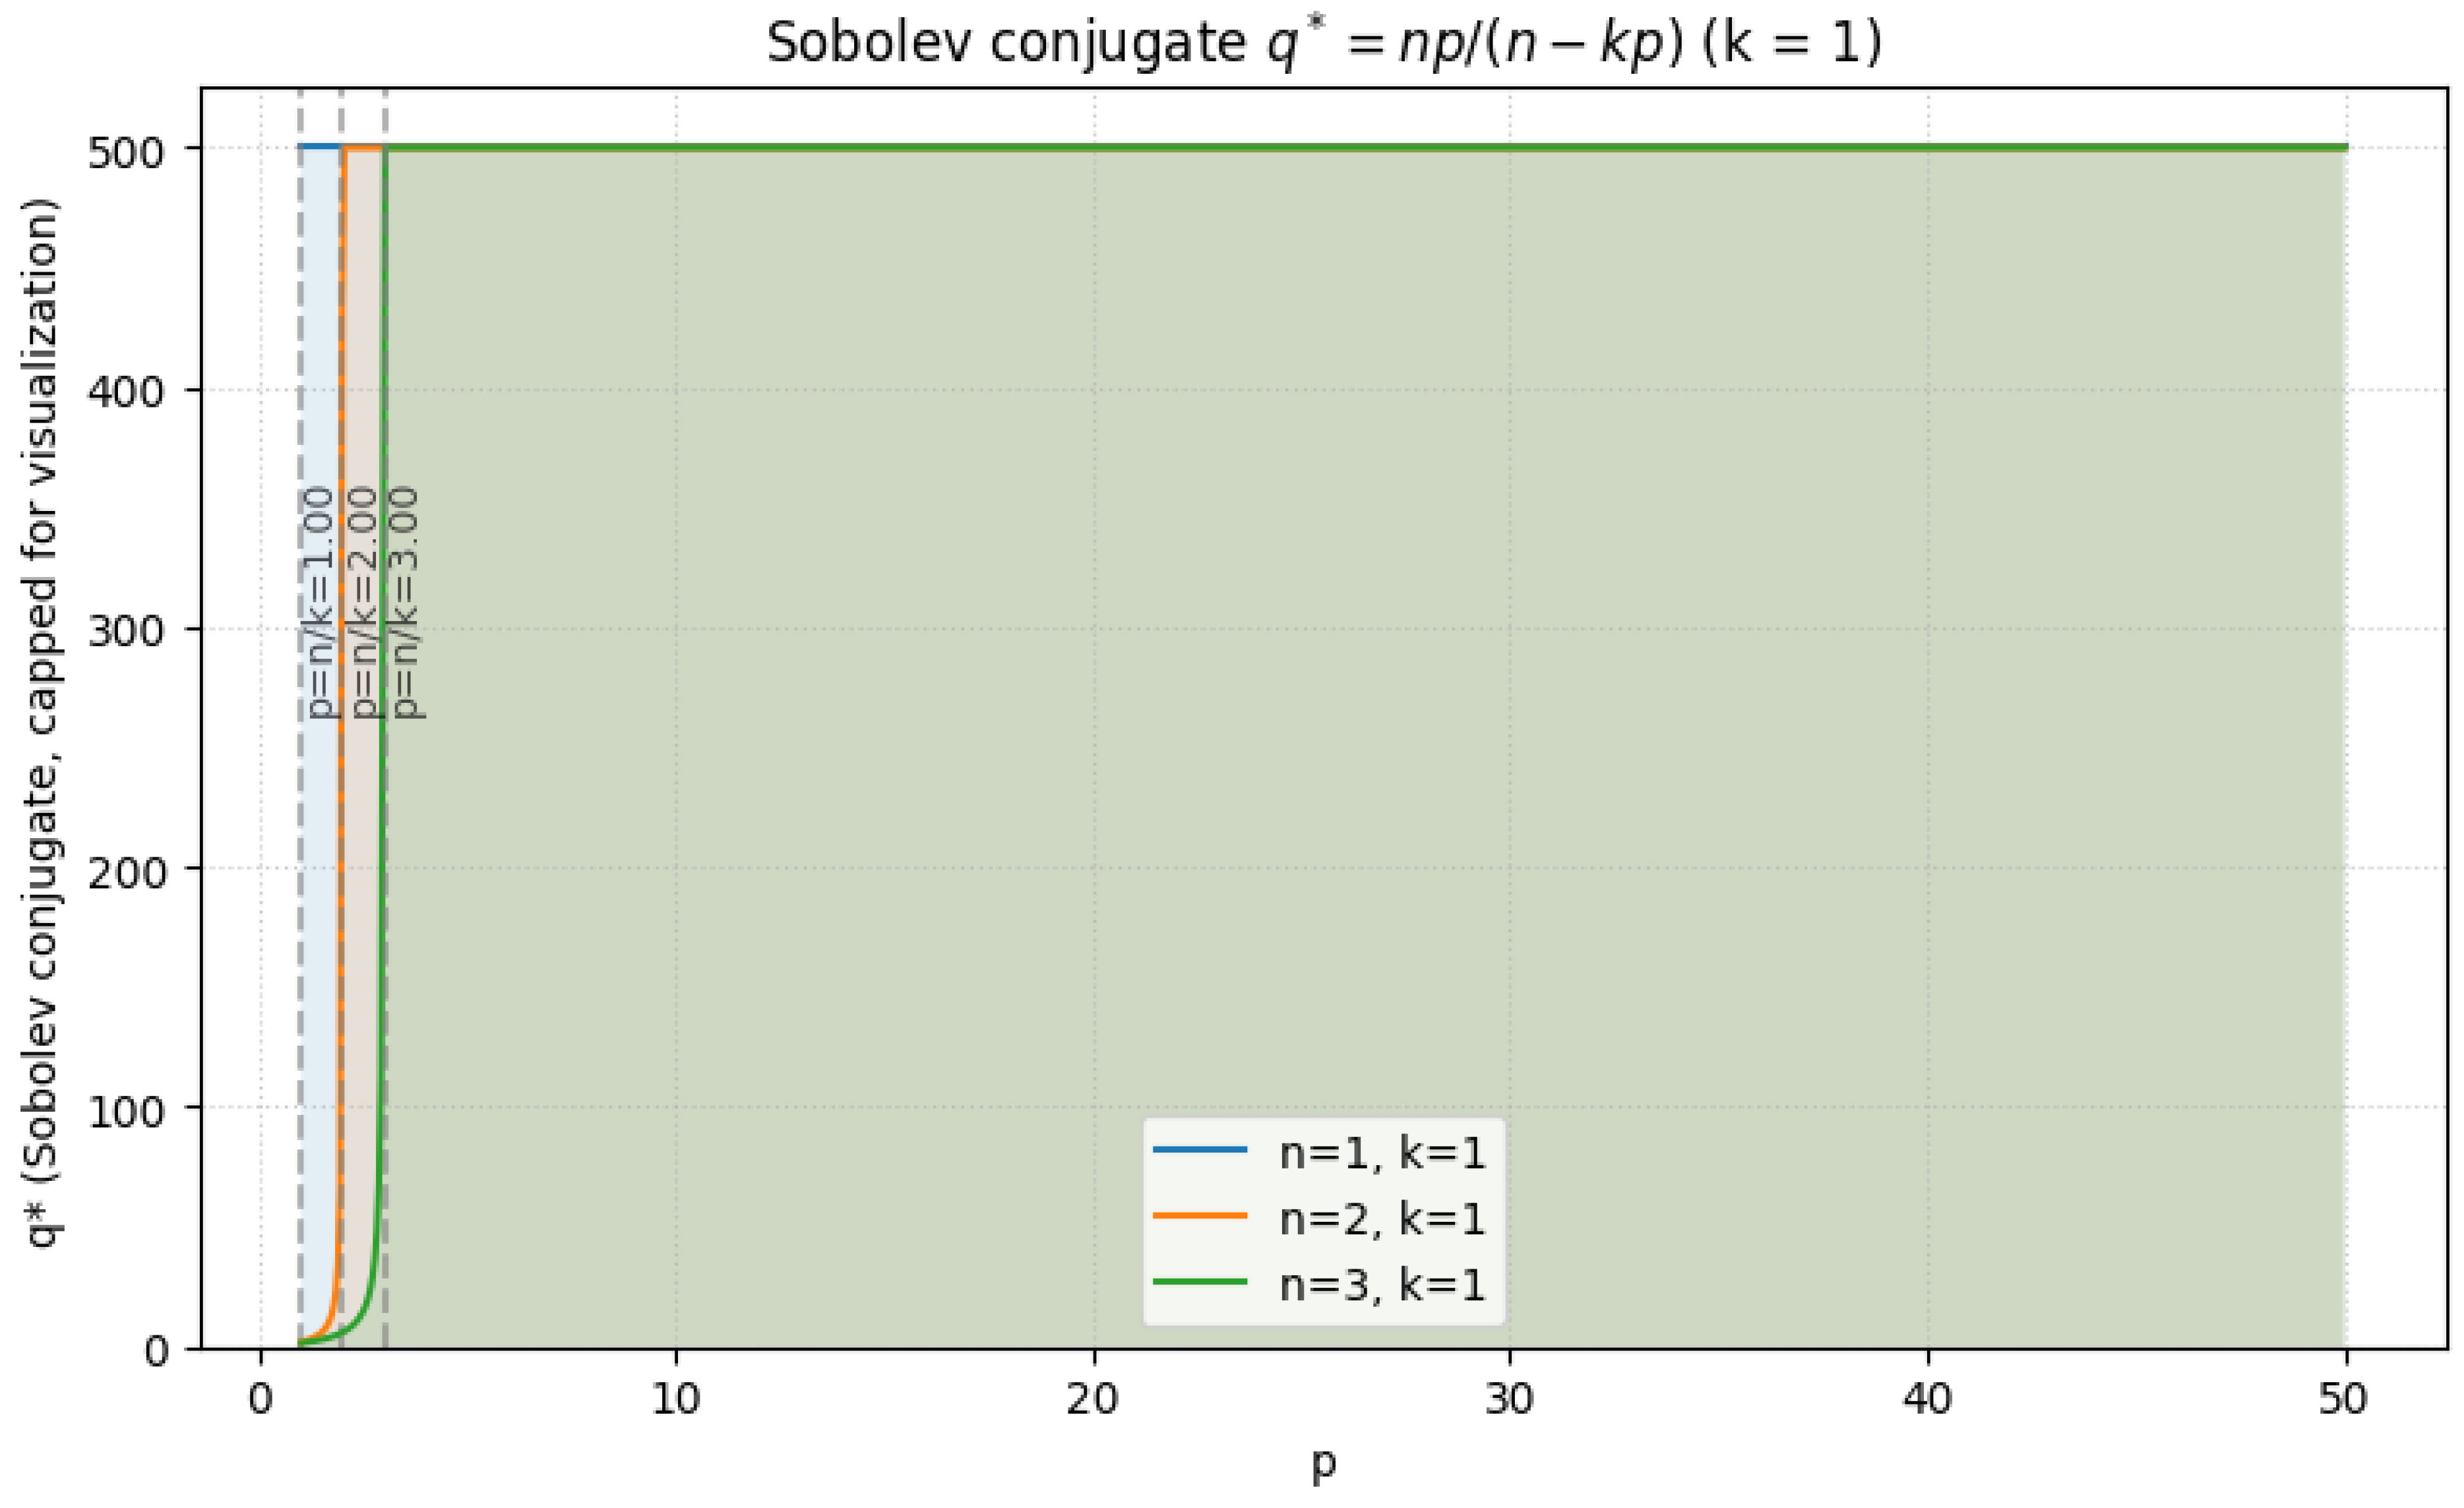
Figure 7.
Sobolev conjugate (k = 2)
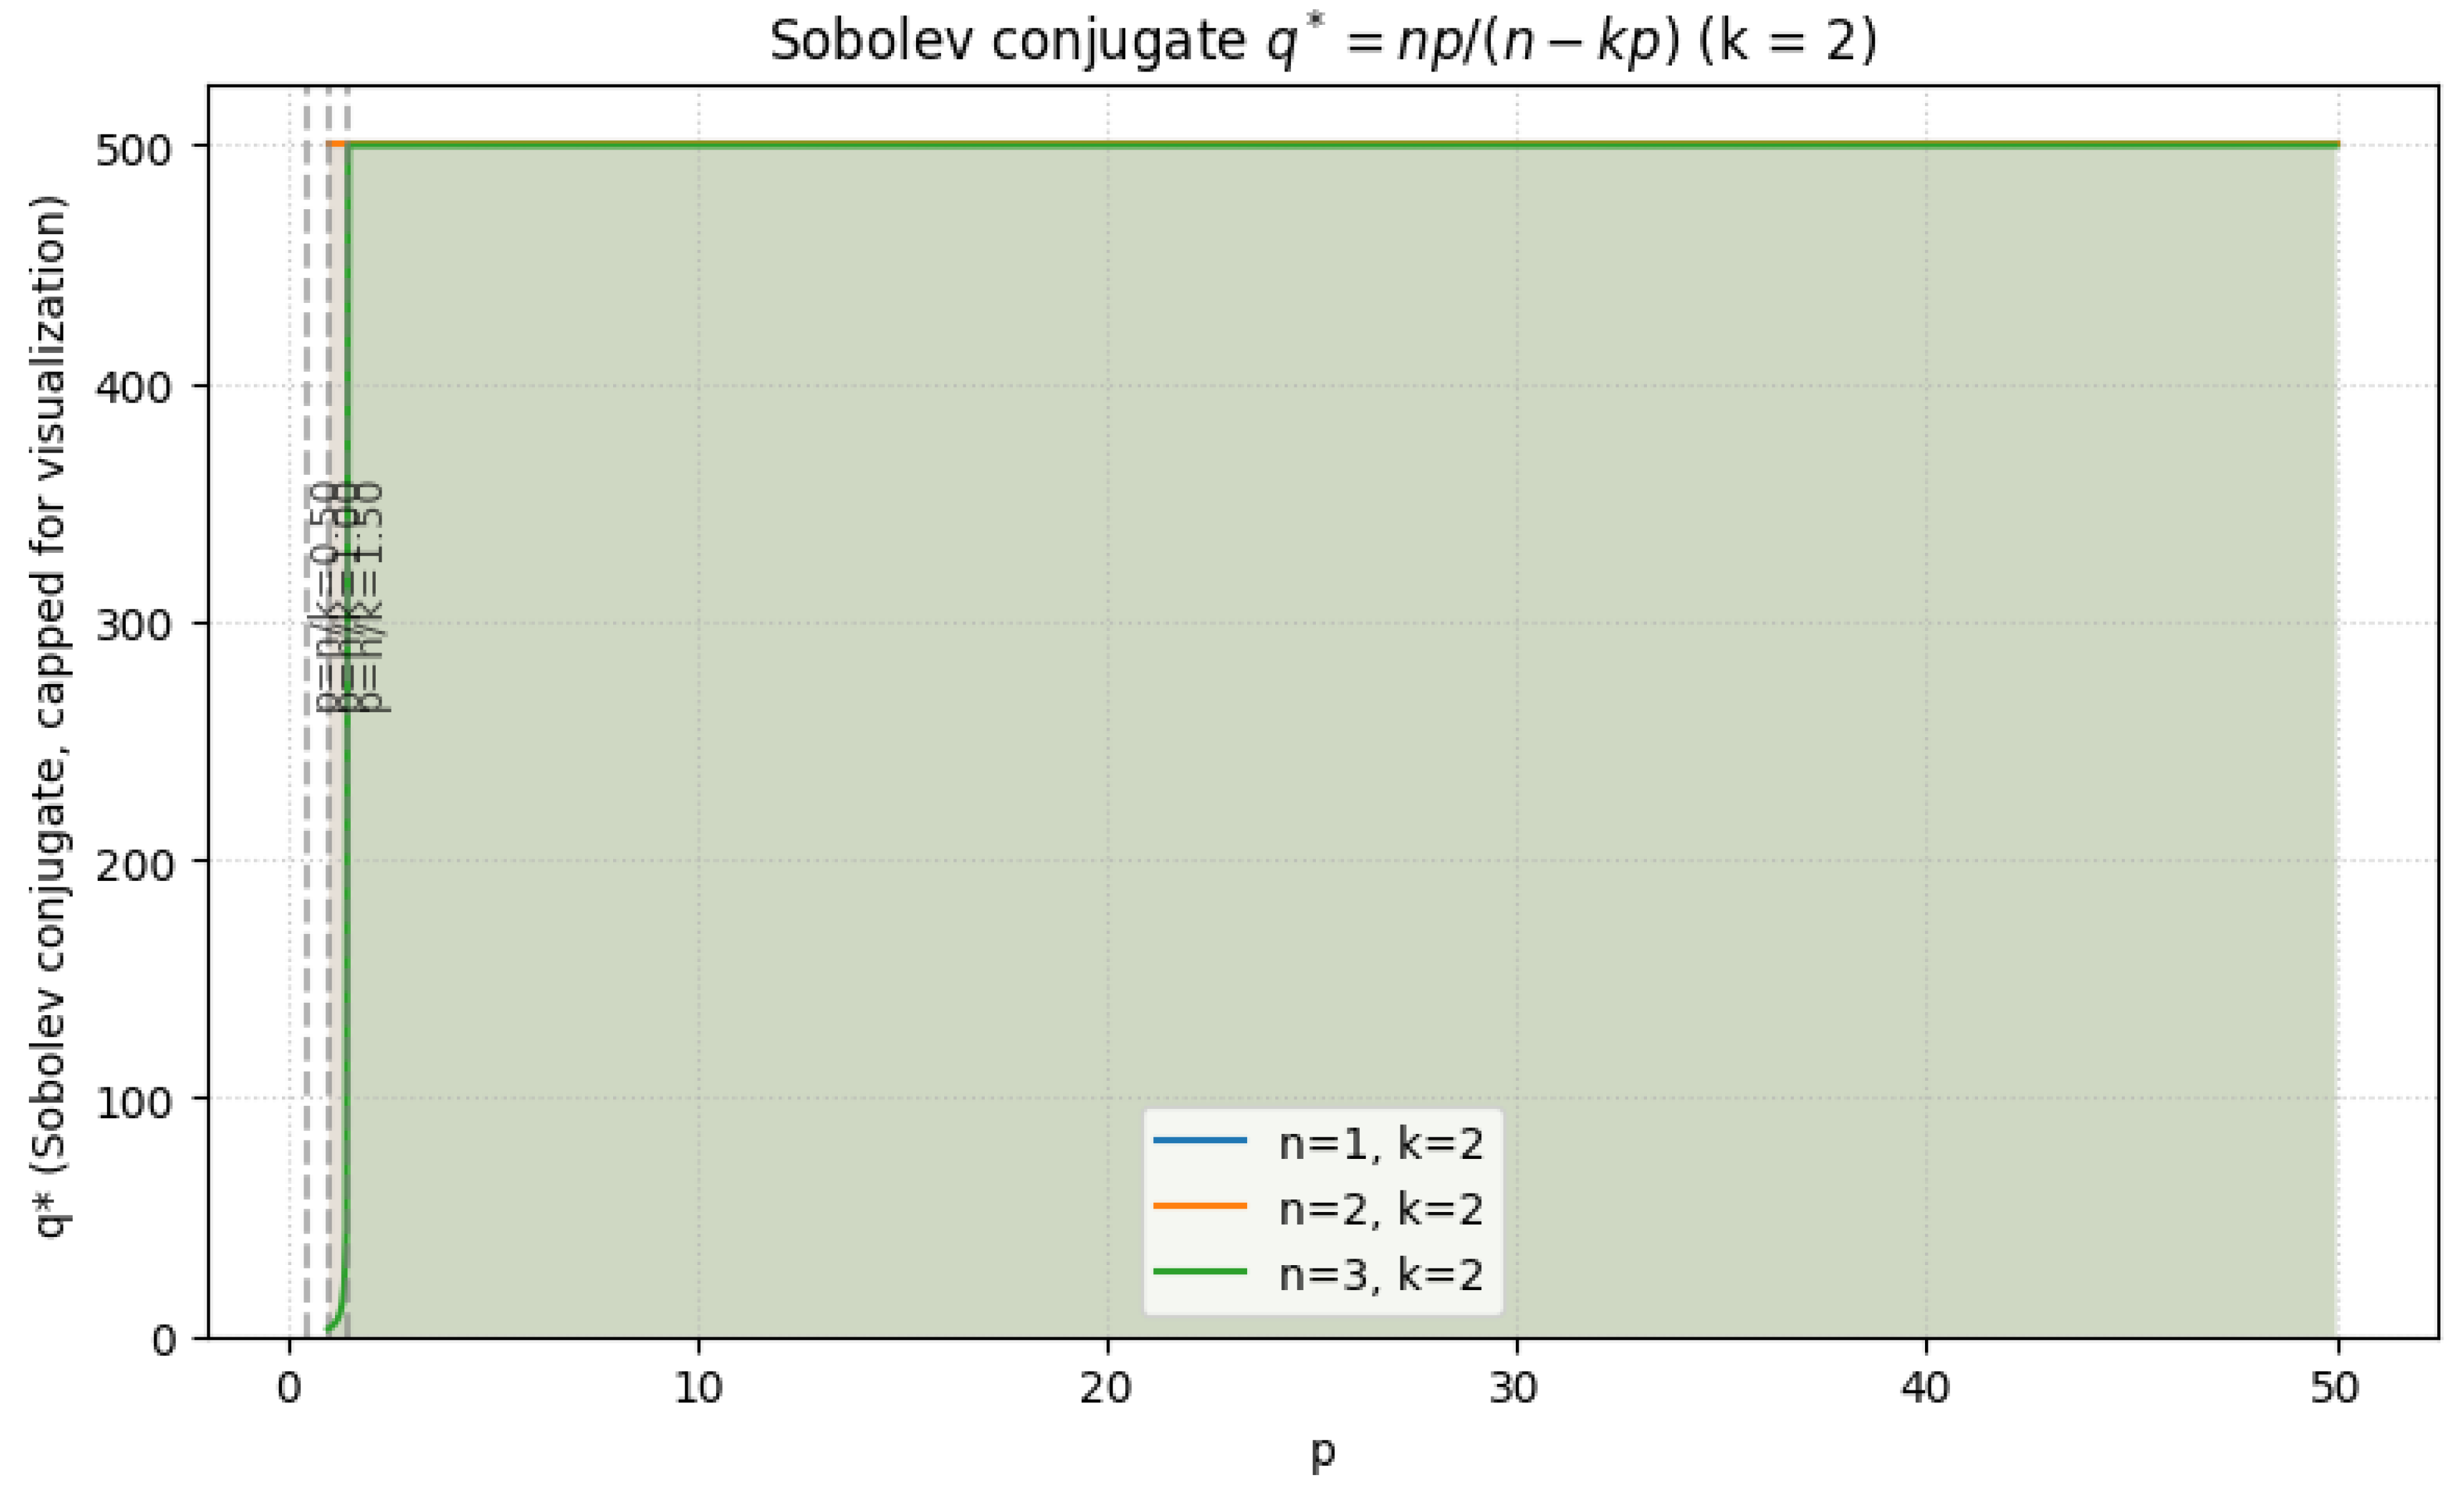
Figure 8.
Hölder exponent for embedding
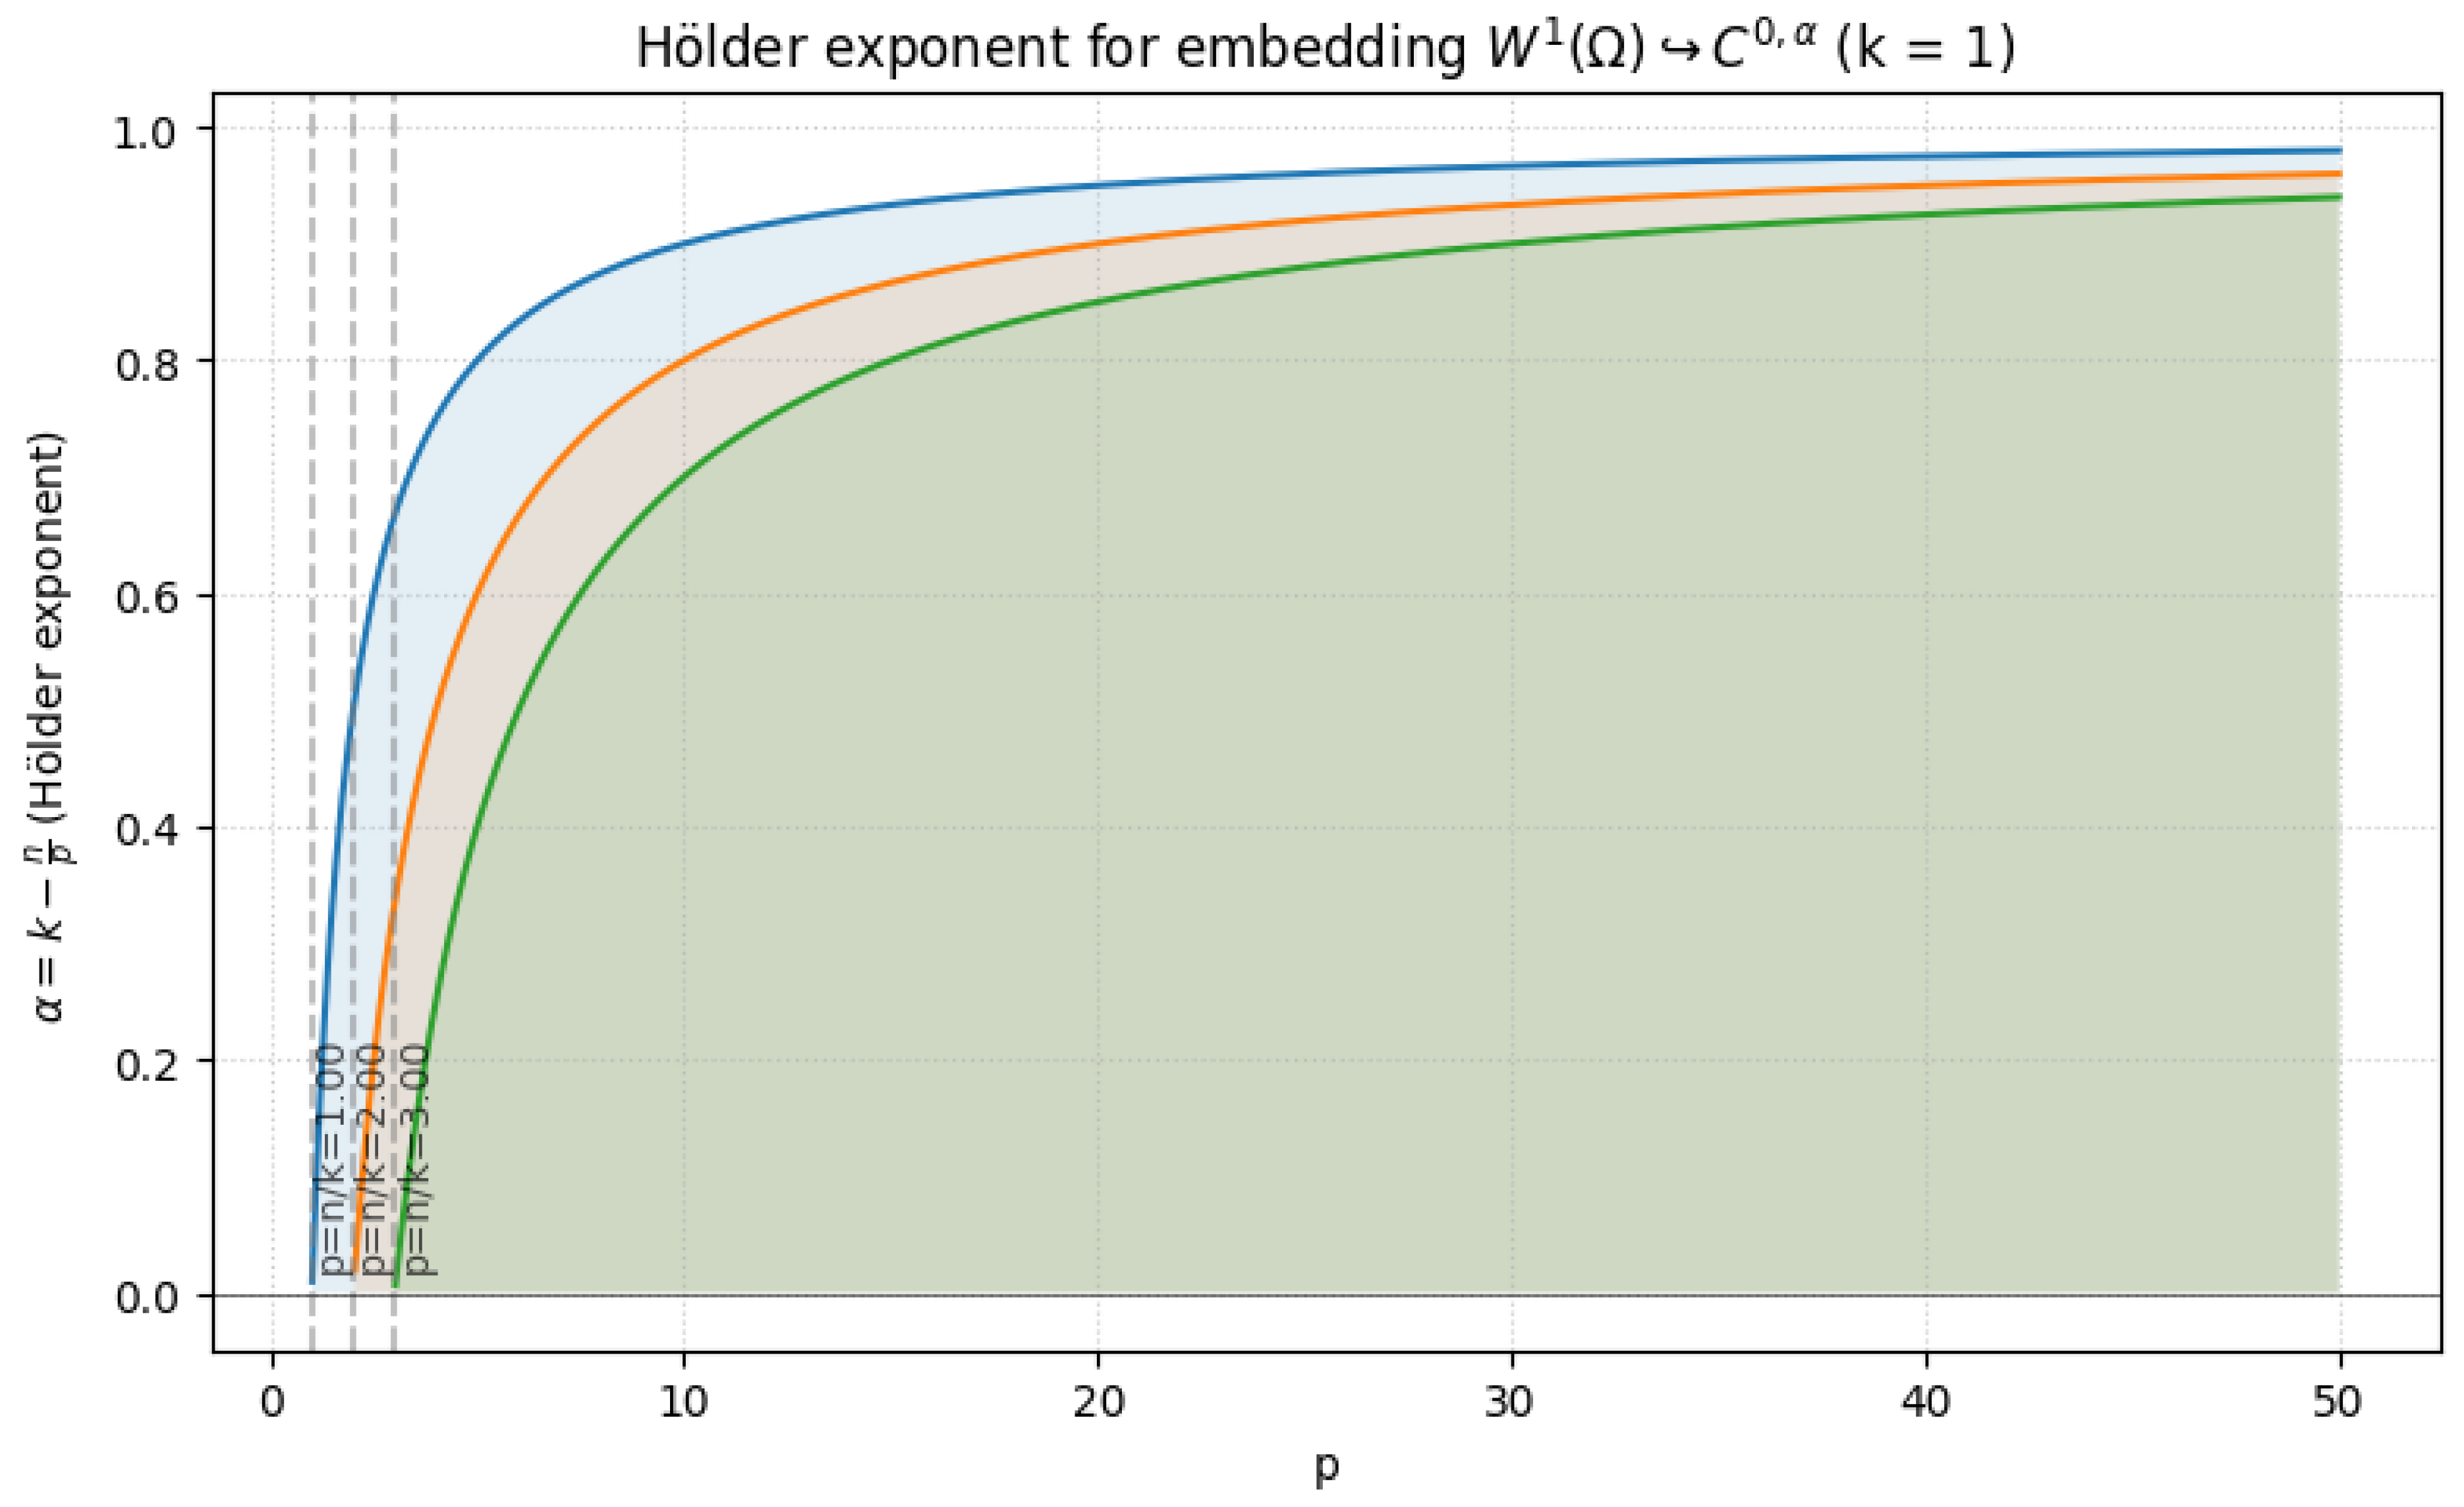
Figure 9.
Hölder exponent for embedding
1.2.4. Rellich-Kondrachov Compactness Theorem
The Rellich-Kondrachov Compactness Theorem is one of the most fundamental and deep results in the theory of Sobolev spaces, particularly in the study of functional analysis and the theory of partial differential equations. The theorem asserts the compactness of certain Sobolev embeddings under appropriate conditions on the domain and the function spaces involved. This result is of immense significance in mathematical analysis because it provides a rigorous justification for the fact that bounded sequences in Sobolev spaces, under certain conditions, have strongly convergent subsequences in lower-order normed spaces. In essence, the theorem states that while weak convergence in Sobolev spaces is relatively straightforward due to the Banach-Alaoglu theorem, strong convergence is not always guaranteed. However, under the assumptions of the Rellich-Kondrachov theorem, strong convergence in can indeed be obtained from boundedness in . The compactness property ensured by this theorem is much stronger than mere boundedness or weak convergence and plays a crucial role in proving the existence of solutions to variational problems by ensuring that minimizing sequences possess convergent subsequences in an appropriate function space. The theorem can also be viewed as a generalization of the classical Arzelà–Ascoli theorem, extending compactness results to function spaces that involve derivatives.
1.2.4.1 Literature Review of Rellich-Kondrachov Compactness Theorem
Lassoued (2026) [51] examined function spaces on the torus and their lack of compactness, highlighting cases where the classical Rellich-Kondrachov result fails. He extended compact embedding results to function spaces with periodic structures. He also discussed trace theorems and regular function spaces in this new context. Chen et.al. (2024) [52] extended the Rellich-Kondrachov theorem to Hörmander vector fields, a class of differential operators that appear in hypoelliptic PDEs. They established a degenerate compact embedding theorem, generalizing previous results in the field. They also provided applications to geometric inequalities, highlighting the role of compact embeddings in PDE theory. Adams and Fournier (2003) [53] in their book provided a complete proof of the Rellich-Kondrachov theorem, along with a discussion of compact embeddings. They also covered function space theory, embedding theorems, and applications in PDEs. Brezis (2010) [55] wrote a highly recommended resource for understanding Sobolev spaces and their compactness properties. The book included applications to variational methods and weak solutions of PDEs. Evans (2022) [56] in his classic PDE textbook includes a discussion of compact Sobolev embeddings, their implications for weak convergence, and applications in variational methods. Maz’ya (2011) [57] provided a detailed treatment of Sobolev space theory, including compact embedding theorems in various settings.
1.2.4.2 Analysis of Rellich-Kondrachov Compactness Theorem
To rigorously state the theorem, we consider a bounded open domain with a Lipschitz boundary. For , the theorem asserts that the embedding
is compact whenever . More precisely, this means that if is a bounded sequence in the Sobolev norm, i.e., there exists a constant such that
then there exists a subsequence and a function such that
which means that
To establish this rigorously, we first recall the fact that bounded sequences in are weakly precompact. Since is a reflexive Banach space for , the Banach-Alaoglu theorem ensures that any bounded sequence in has a subsequence (still denoted by ) and a function such that
This means that for all test functions , where is the Hölder conjugate of p satisfying , we have
However, weak convergence alone does not imply compactness. To obtain strong convergence in , we need additional arguments.
This is accomplished using the Fréchet-Kolmogorov compactness criterion, which states that a bounded subset of is compact if and only if it is tight and uniformly equicontinuous. More formally, compactness follows if
- The sequence does not oscillate excessively at small scales.
- The sequence does not escape to infinity in a way that prevents strong convergence.
To quantify this, we invoke the Sobolev-Poincaré inequality, which states that for , there exists a constant C such that
Applying this inequality to , we obtain
Since is weakly convergent in , we have
Thus,
which establishes the strong convergence in , completing the proof. The key insight is that compactness arises because the gradients of provide control over the oscillations of , ensuring that the sequence cannot oscillate indefinitely without converging in norm. The crucial role of Sobolev embeddings is to guarantee that even though does not embed compactly into itself, it does embed compactly into for . This embedding ensures that weak convergence in implies strong convergence in , proving the theorem.
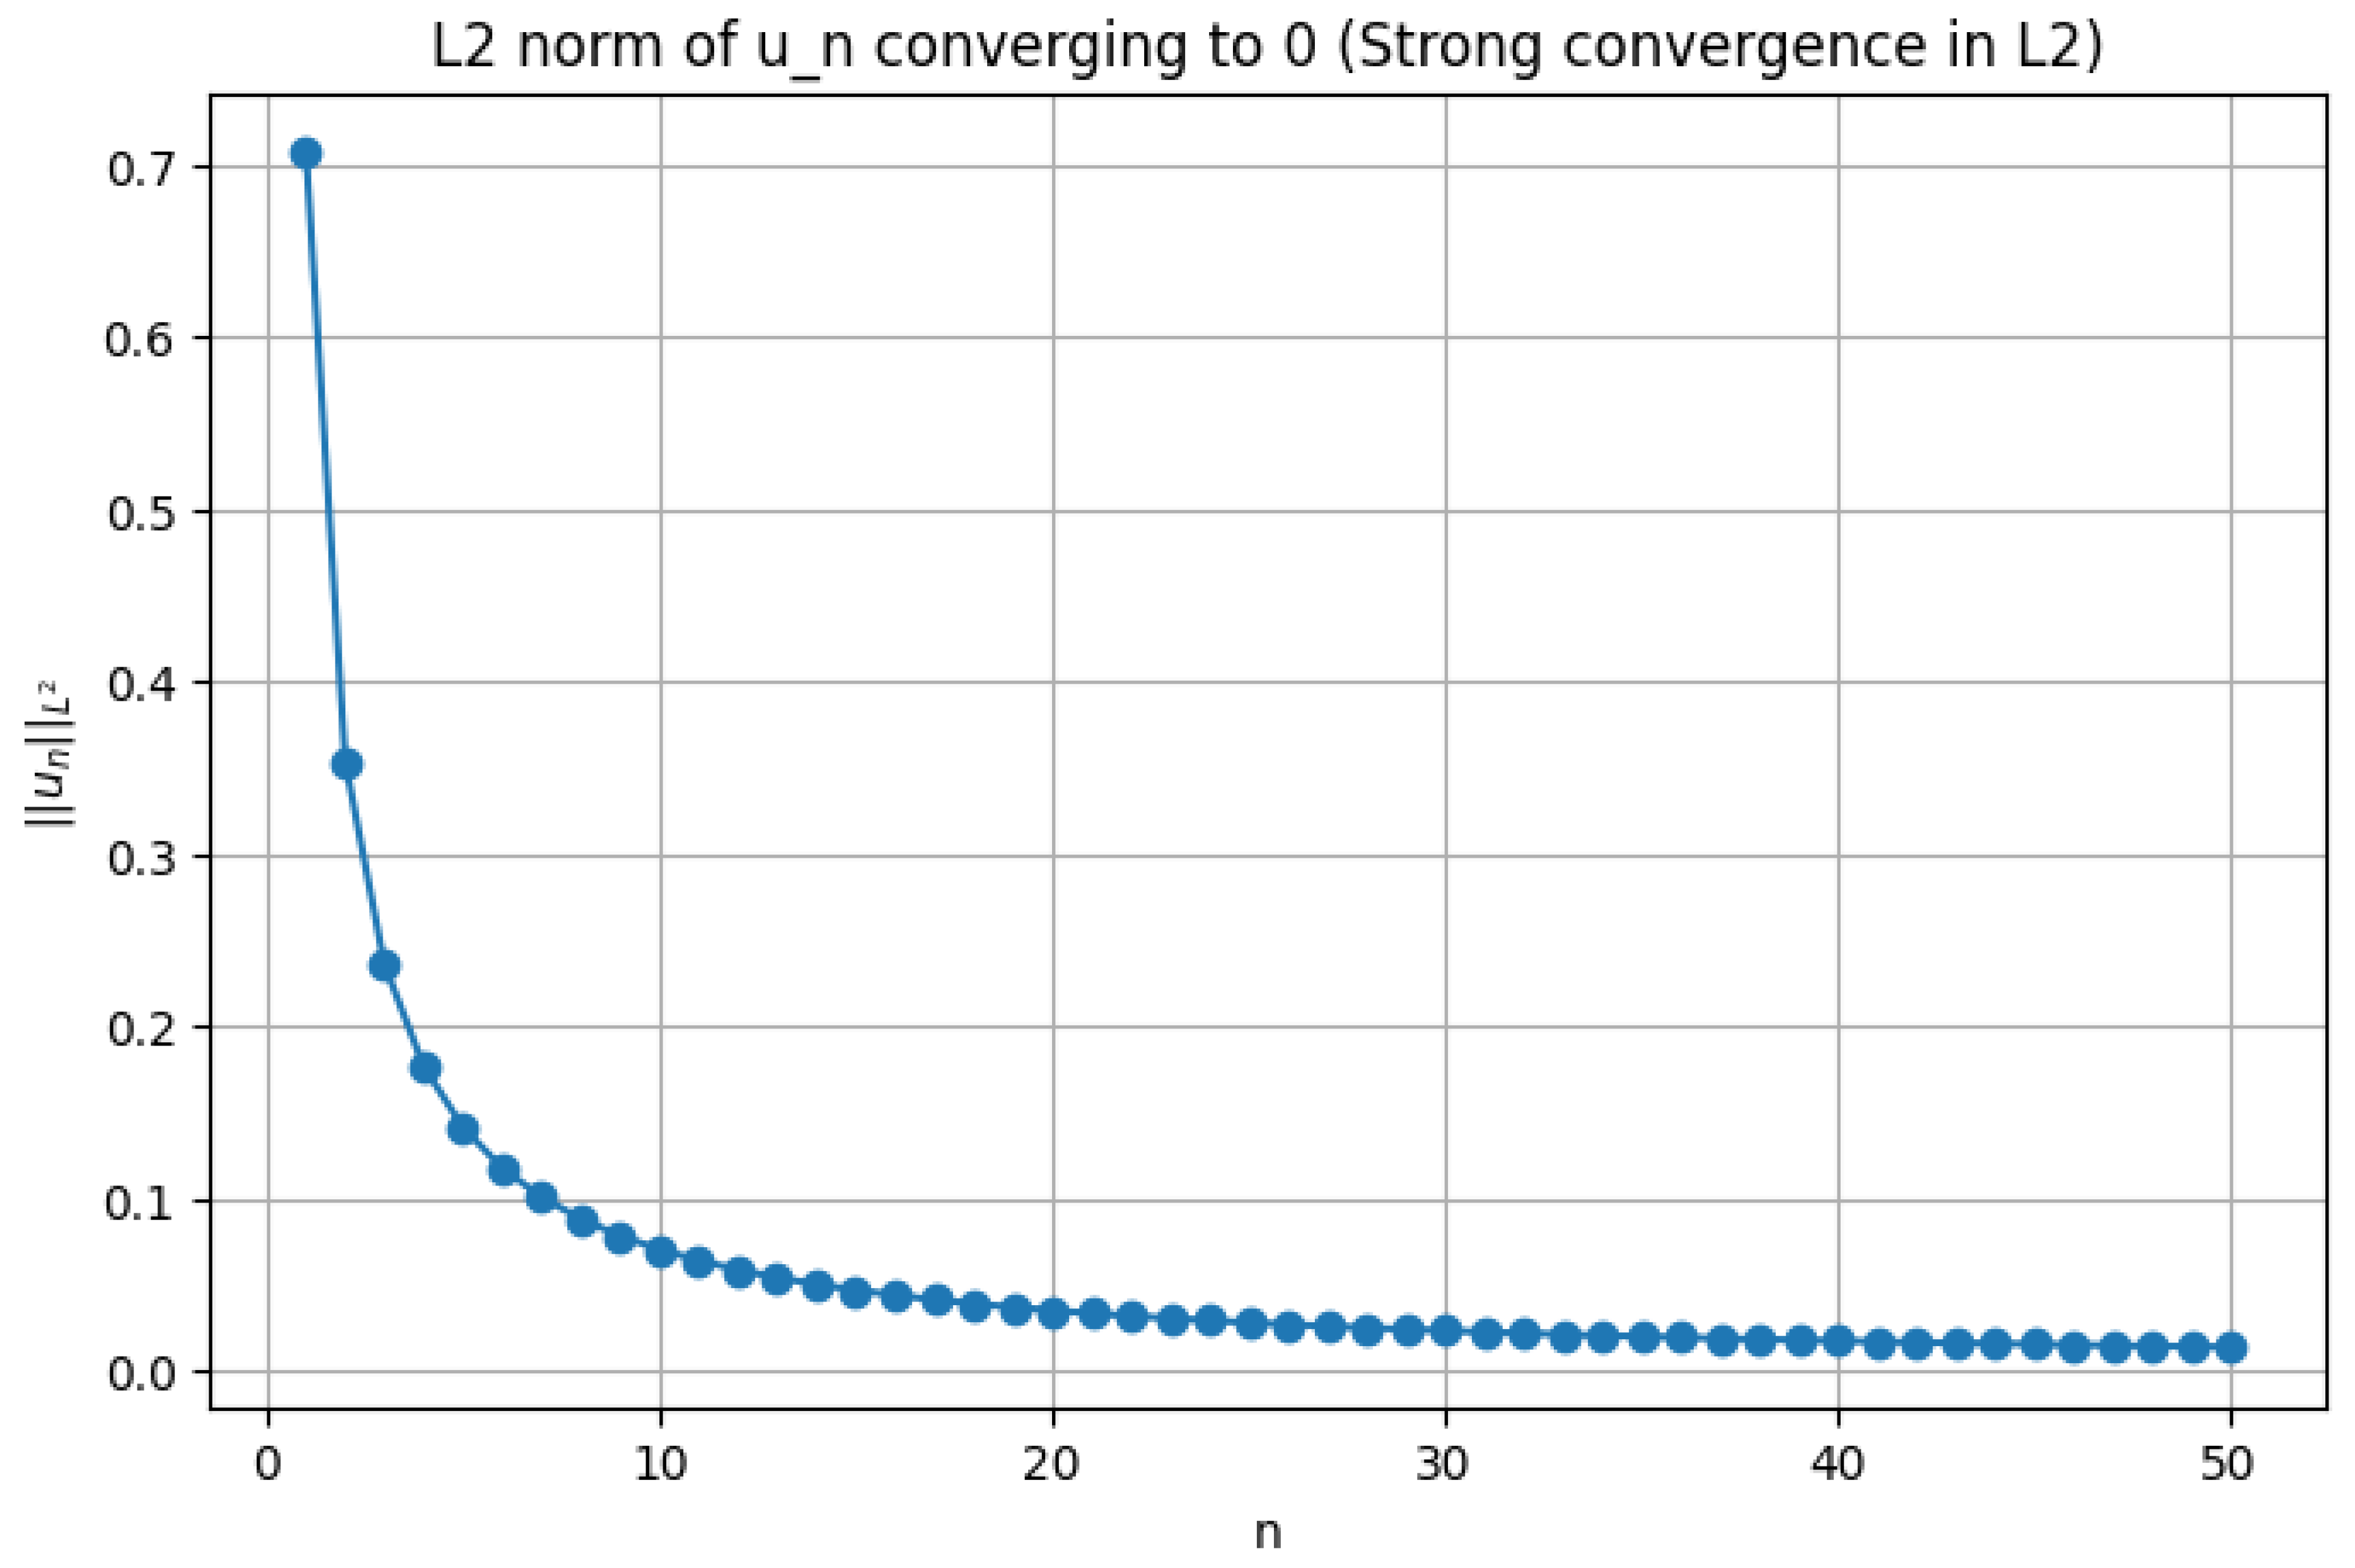
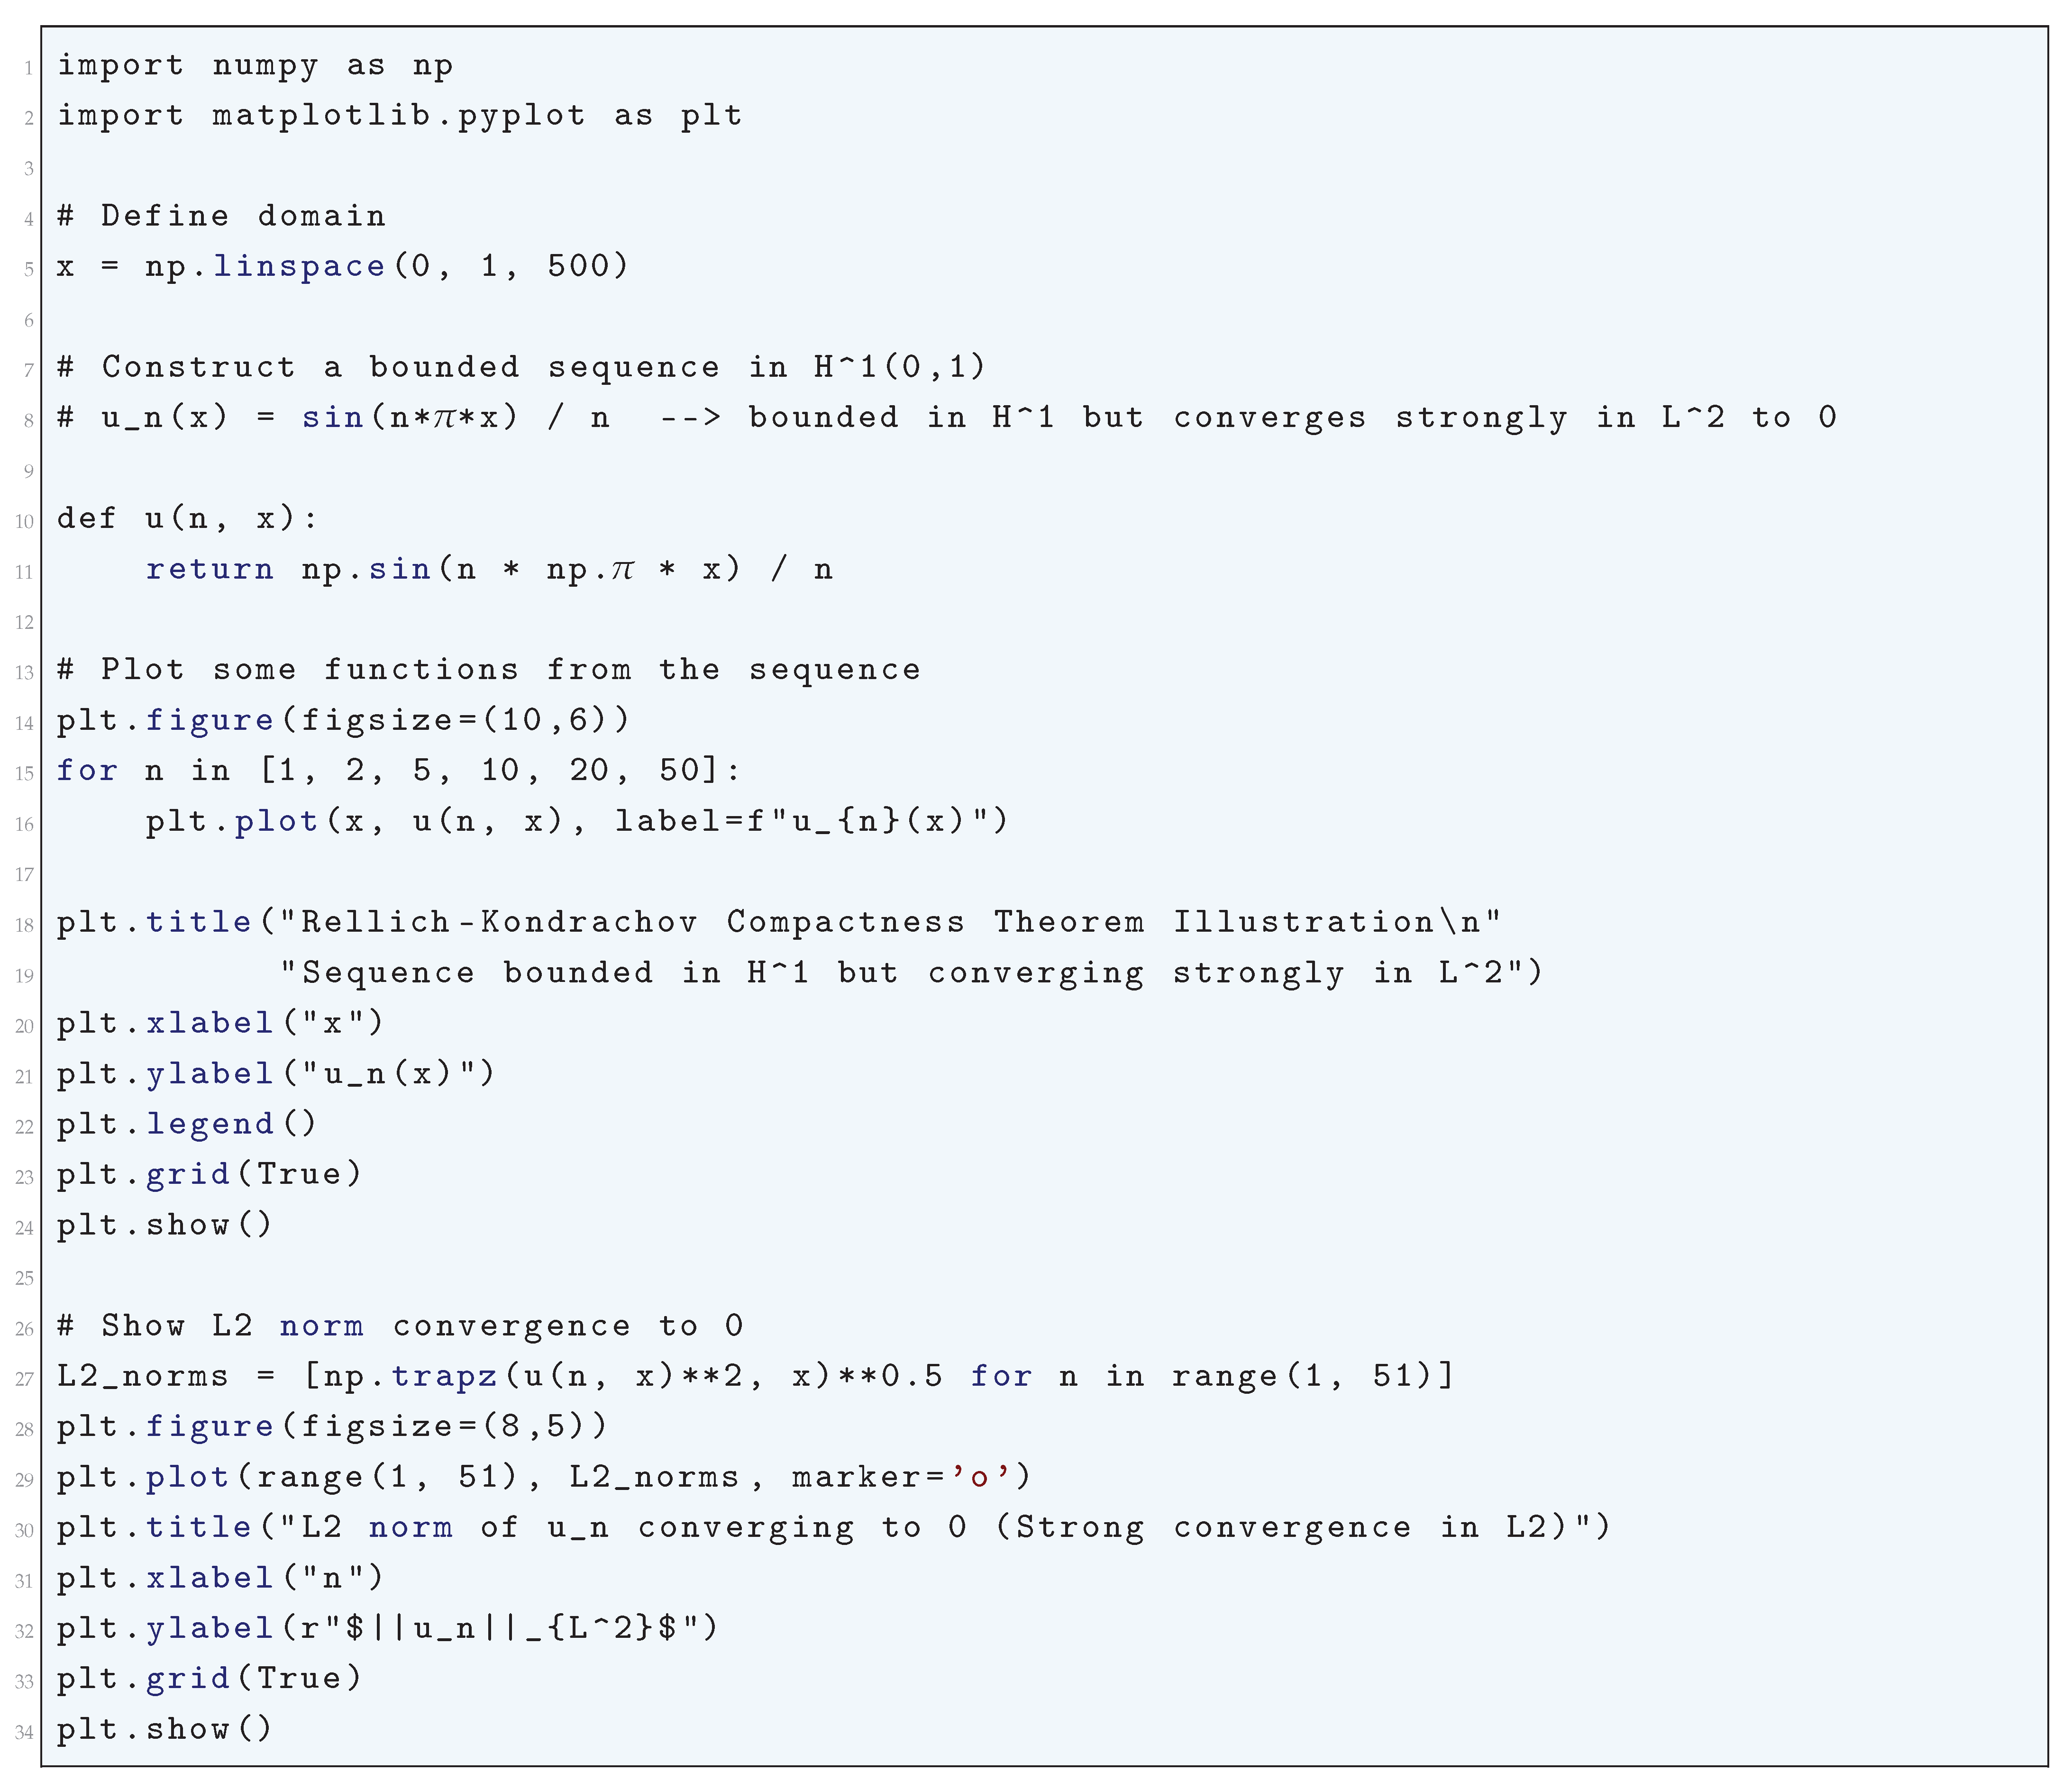
1.2.4.3 Python Code to Generate Figure 10 and Figure 11 Illustrating Rellich-Kondrachov Compactness Theorem
The Python code below produces the Figure 10 and Figure 11 illustrating Rellich-Kondrachov Compactness Theorem.
Figure 10.
Rellich-Kondrachov Compactness Theorem Illustration
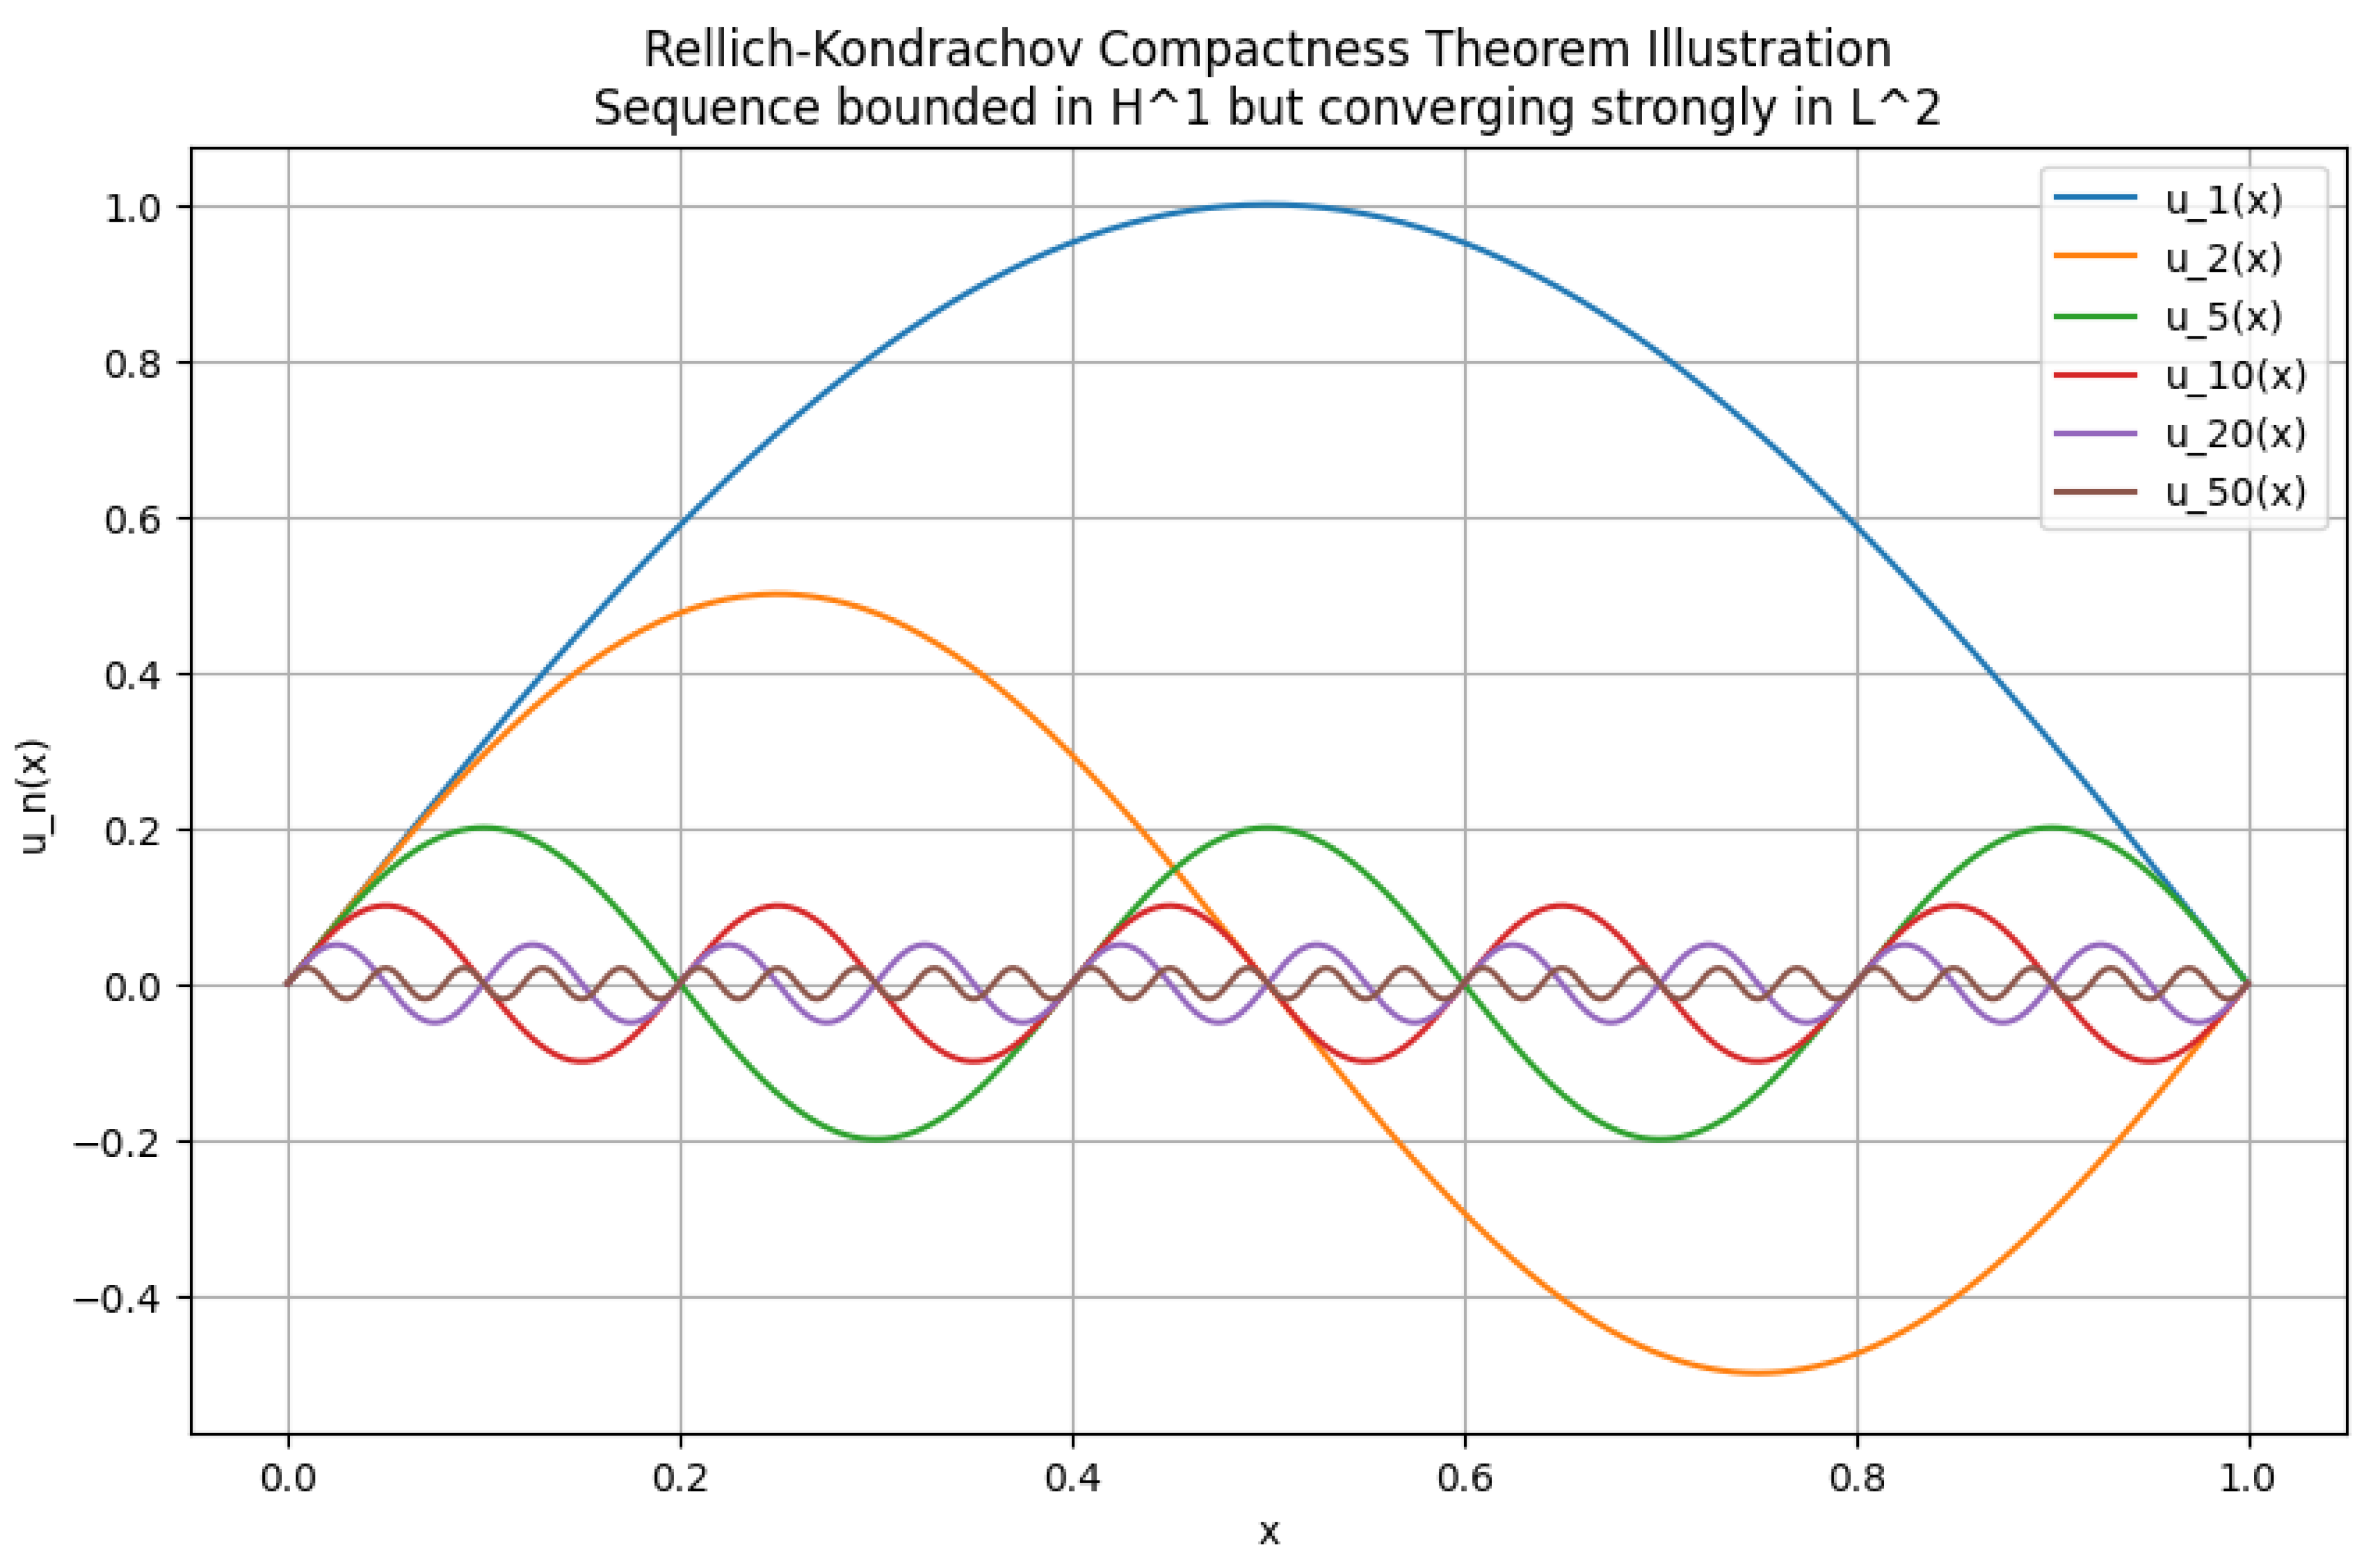
Figure 11.
L2 norm of converging to 0 (Strong convergence in L2)
1.2.5. Fréchet-Kolmogorov Compactness Criterion
1.2.5.1 Literature Review of Fréchet-Kolmogorov Compactness Criterion
The Fréchet-Kolmogorov compactness criterion is a fundamental result in functional analysis, particularly in the study of compact subsets of spaces, and has been extensively discussed and applied in numerous books and articles. One of the most authoritative references is the classic text by Walter Rudin (1973) [70], which provides a rigorous treatment of the criterion, embedding it within the broader context of weak compactness and equicontinuity in spaces. Rudin’s exposition is notable for its clarity and depth, linking the criterion to the Arzelà-Ascoli theorem and emphasizing its utility in proving compactness for families of functions. Another essential reference is by H.L. Royden (1968) [1537], which offers a detailed proof of the Fréchet-Kolmogorov theorem, highlighting its reliance on uniform integrability and tightness conditions. Royden’s treatment is particularly valuable for its pedagogical approach, making the criterion accessible to students while maintaining mathematical rigor. The monograph by Robert A. Adams and John J.F. Fournier (2003) [1522] delves into the Fréchet-Kolmogorov criterion in the context of Sobolev embeddings, demonstrating its critical role in establishing compactness for bounded subsets of Sobolev spaces. Adams and Fournier’s work is indispensable for researchers in partial differential equations, as it connects the criterion to applications in variational methods and elliptic regularity theory. Similarly, by Lawrence C. Evans (2010) [1528] discusses the criterion within the framework of weak convergence and compact embeddings, showcasing its importance in the analysis of solutions to PDEs. Evans’ presentation is particularly rigorous, with a focus on the interplay between the criterion and the Rellich-Kondrachov theorem. Another key text is by Lawrence C. Evans and Ronald F. Gariepy (1992) [1529], which explores the criterion’s implications for functions of bounded variation and its applications in geometric measure theory.
In the realm of probability theory, by Aad W. van der Vaart and Jon A. Wellner (1996) [1540] examines the Fréchet-Kolmogorov criterion as a tool for establishing tightness of probability measures on function spaces. This work is foundational for researchers in empirical process theory, providing a bridge between functional analysis and statistical applications. The authors rigorously develop the criterion’s connection to Prokhorov’s theorem and its use in proving Donsker-type results. Another probabilistic perspective is offered by Patrick Billingsley (1968) [1524], which discusses the criterion in the context of compactness for stochastic processes. Billingsley’s treatment is highly detailed, with a focus on the criterion’s role in proving relative compactness for sequences of measures on metric spaces. For a historical perspective, the original works by Maurice Fréchet (1906) [1541] and Andrey Kolmogorov (1931) [1542] are invaluable. Fréchet’s early 20th-century papers laid the groundwork for the abstract formulation of compactness in function spaces, while Kolmogorov’s contributions refined the criterion, particularly for spaces. These foundational texts are often cited in modern treatments for their pioneering insights. More recently, by Fernando Albiac and Nigel J. Kalton (2006) [1523] provides a modern exposition of the Fréchet-Kolmogorov criterion, embedding it within the broader theory of Banach spaces. Albiac and Kalton’s discussion is notable for its emphasis on the criterion’s relationship with other compactness principles, such as the Eberlein-Šmulian theorem.
The article by Jürgen Appell and Petr P. Zabrejko (1990) [1543] surveys various compactness criteria, including the Fréchet-Kolmogorov theorem, and discusses their applications in nonlinear analysis. This work is particularly useful for its comprehensive overview and its focus on practical implications for integral operators and fixed-point theorems. Another significant contribution is by Klaus Deimling (1985) [1527], which explores the criterion’s use in proving existence theorems for differential equations. Deimling’s treatment is rigorous and application-oriented, making it a valuable resource for researchers in nonlinear analysis. In the context of harmonic analysis, by Gerald B. Folland (1992) [1530] discusses the Fréchet-Kolmogorov criterion in relation to compactness for families of oscillatory integrals. Folland’s exposition is clear and concise, with a focus on the criterion’s role in proving convergence theorems for Fourier series and transforms. Similarly, by Loukas Grafakos (2008) [1531] includes a detailed discussion of the criterion, particularly its applications in the study of singular integrals and maximal functions. Grafakos’ work is highly technical but provides deep insights into the criterion’s utility in modern harmonic analysis.
The Fréchet-Kolmogorov criterion has also been extensively studied in the context of dynamical systems and ergodic theory. By Karl Petersen (1983) [1536] discusses the criterion’s role in proving compactness for families of invariant measures, highlighting its importance in the study of dynamical systems. Petersen’s treatment is mathematically rigorous and includes applications to symbolic dynamics and entropy theory. Another relevant reference is by Anatole Katok and Boris Hasselblatt (1995) [1533], which explores the criterion’s use in establishing compactness for sequences of diffeomorphisms and its implications for structural stability. In the field of numerical analysis, by K.W. Morton and D.F. Mayers (1994) [1535] discusses the Fréchet-Kolmogorov criterion in the context of finite difference methods. The authors demonstrate how the criterion can be used to prove convergence of numerical schemes by establishing compactness for sequences of approximate solutions. This practical perspective is complemented by by Philippe G. Ciarlet (1978) [1526], which applies the criterion to prove compactness for finite element approximations. Ciarlet’s work is highly regarded for its rigorous mathematical foundation and its emphasis on error estimation.
The Fréchet-Kolmogorov criterion has also found applications in control theory, as discussed by Jacques-Louis Lions (1971) [1534]. Lions’ work is seminal in this area, showing how the criterion can be used to establish compactness for families of controls and states in PDE-constrained optimization problems. Another important reference is by Roger Temam (1988) [1539], which applies the criterion to prove compactness for attractors in dissipative systems. Temam’s exposition is both deep and broad, covering applications to fluid mechanics and elasticity. Finally, the Fréchet-Kolmogorov criterion has been explored in the context of stochastic PDEs, as seen by Pao-Liu Chow (2007) [1525]. Chow’s work demonstrates the criterion’s utility in proving tightness for solutions to SPDEs, linking it to martingale theory and Skorokhod embeddings. This rigorous treatment is essential for researchers in stochastic analysis. Another notable reference is by Ioannis Karatzas and Steven E. Shreve (1991) [1532], which discusses the criterion’s role in proving compactness for diffusion processes. Karatzas and Shreve’s book is a cornerstone of stochastic analysis, with a thorough and mathematically precise exposition.
1.2.5.2 Analysis of Fréchet-Kolmogorov Compactness Criterion
The Fréchet-Kolmogorov compactness criterion provides necessary and sufficient conditions for a set , where , to be relatively compact, meaning that any sequence has a strongly convergent subsequence in . The criterion asserts that is relatively compact in if and only if the following three conditions hold: boundedness in , uniform integrability (tightness), and equicontinuity in an integral sense. The proof consists of establishing both the necessary and sufficient conditions.
To prove necessity, suppose that is relatively compact in . Then every sequence has a strongly convergent subsequence. This implies that the norms of the functions in are uniformly bounded, since otherwise there would exist a sequence such that , contradicting compactness. Hence, there exists a constant such that for all ,
Next, to establish uniform integrability, assume for contradiction that is not tight. Then there exists such that for every compact set , there exists some function satisfying
This contradicts relative compactness, as it implies the existence of a sequence with mass escaping to infinity, preventing any strong convergence in . Hence, for every , there exists a compact such that
To establish the necessity of equicontinuity, suppose for contradiction that it does not hold. Then there exists such that for every , there is some function and some shift h with such that
This contradicts compactness, as it implies the existence of arbitrarily oscillatory sequences preventing strong convergence in . Hence, for every , there exists such that for all ,
To prove sufficiency, assume that satisfies boundedness, uniform integrability, and equicontinuity. Consider a sequence . The first condition guarantees that the sequence is uniformly bounded in , ensuring weak compactness by Banach-Alaoglu. The second condition ensures that the functions do not escape to infinity, implying tightness. The third condition ensures that the sequence is equicontinuous, preventing high-frequency oscillations. By the diagonal argument, we can extract a subsequence that is a Cauchy sequence in , ensuring strong convergence. To rigorously show that a subsequence converges, define the modulus of continuity functional,
which satisfies as due to equicontinuity. Given , choose such that , and a compact set K such that
By weak compactness, there exists a subsequence converging weakly in to some f. Applying Vitali’s theorem, we obtain strong convergence, proving compactness. Thus, the Fréchet-Kolmogorov criterion is fully established.
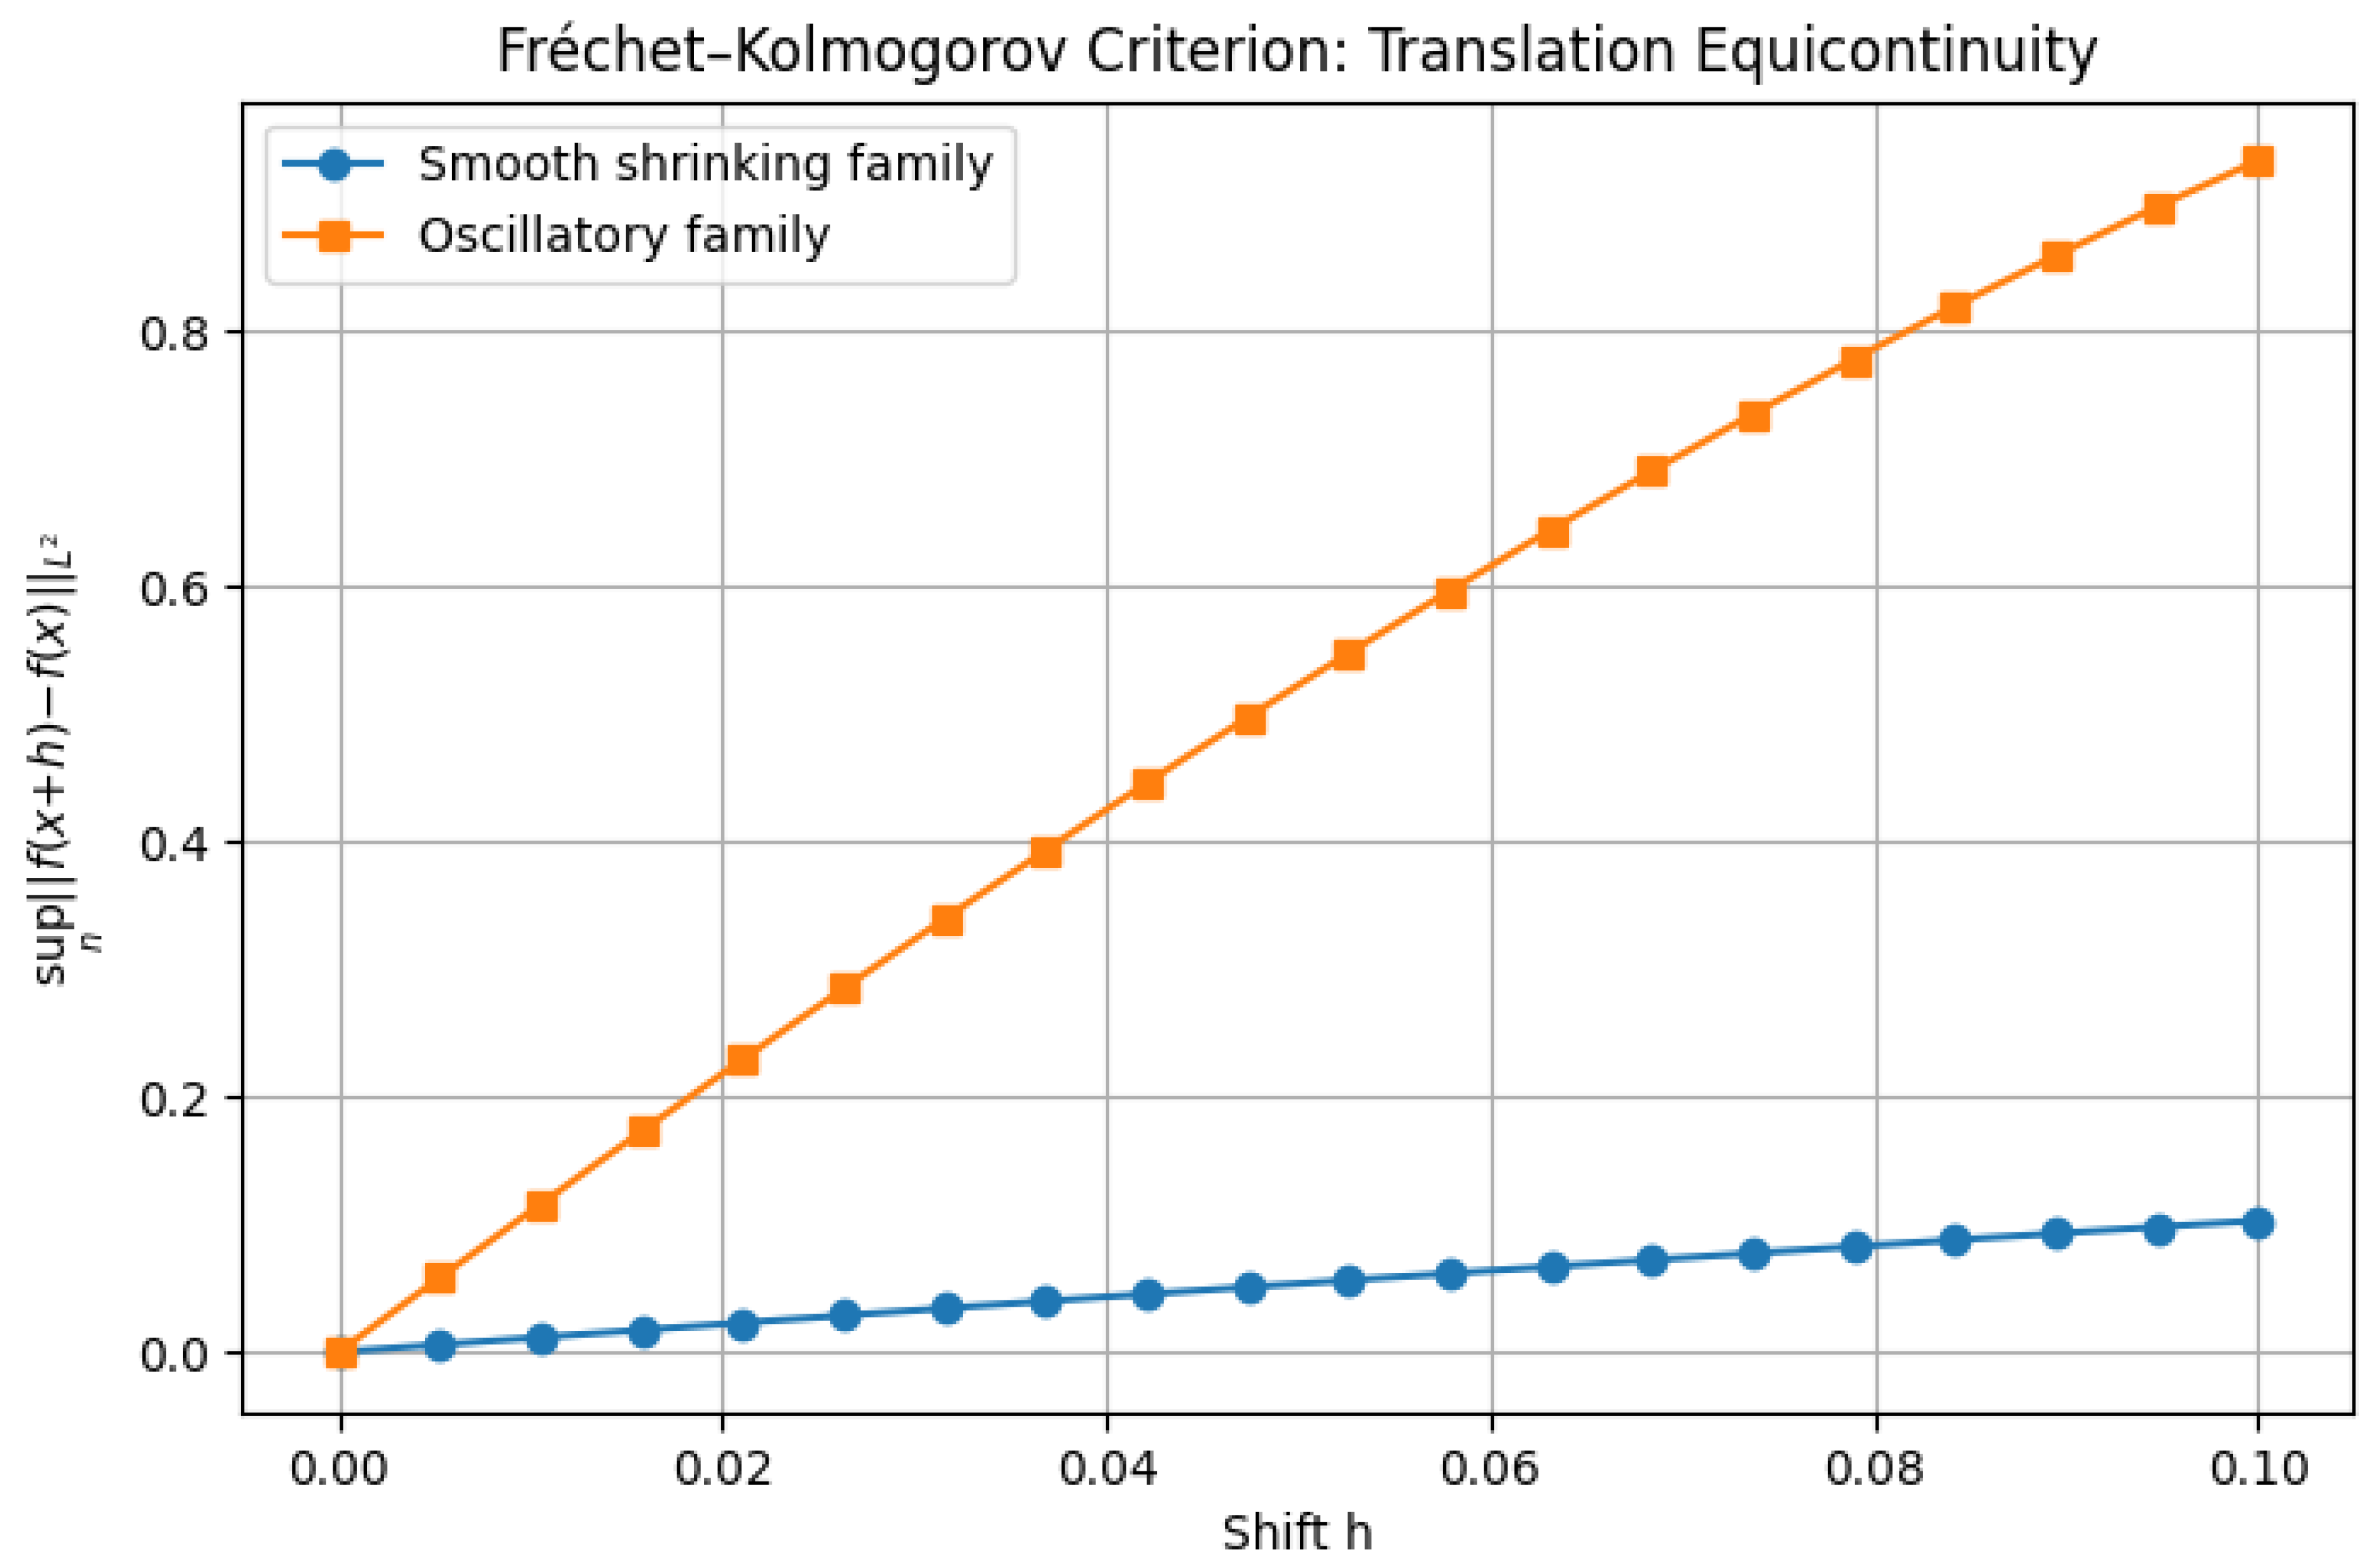
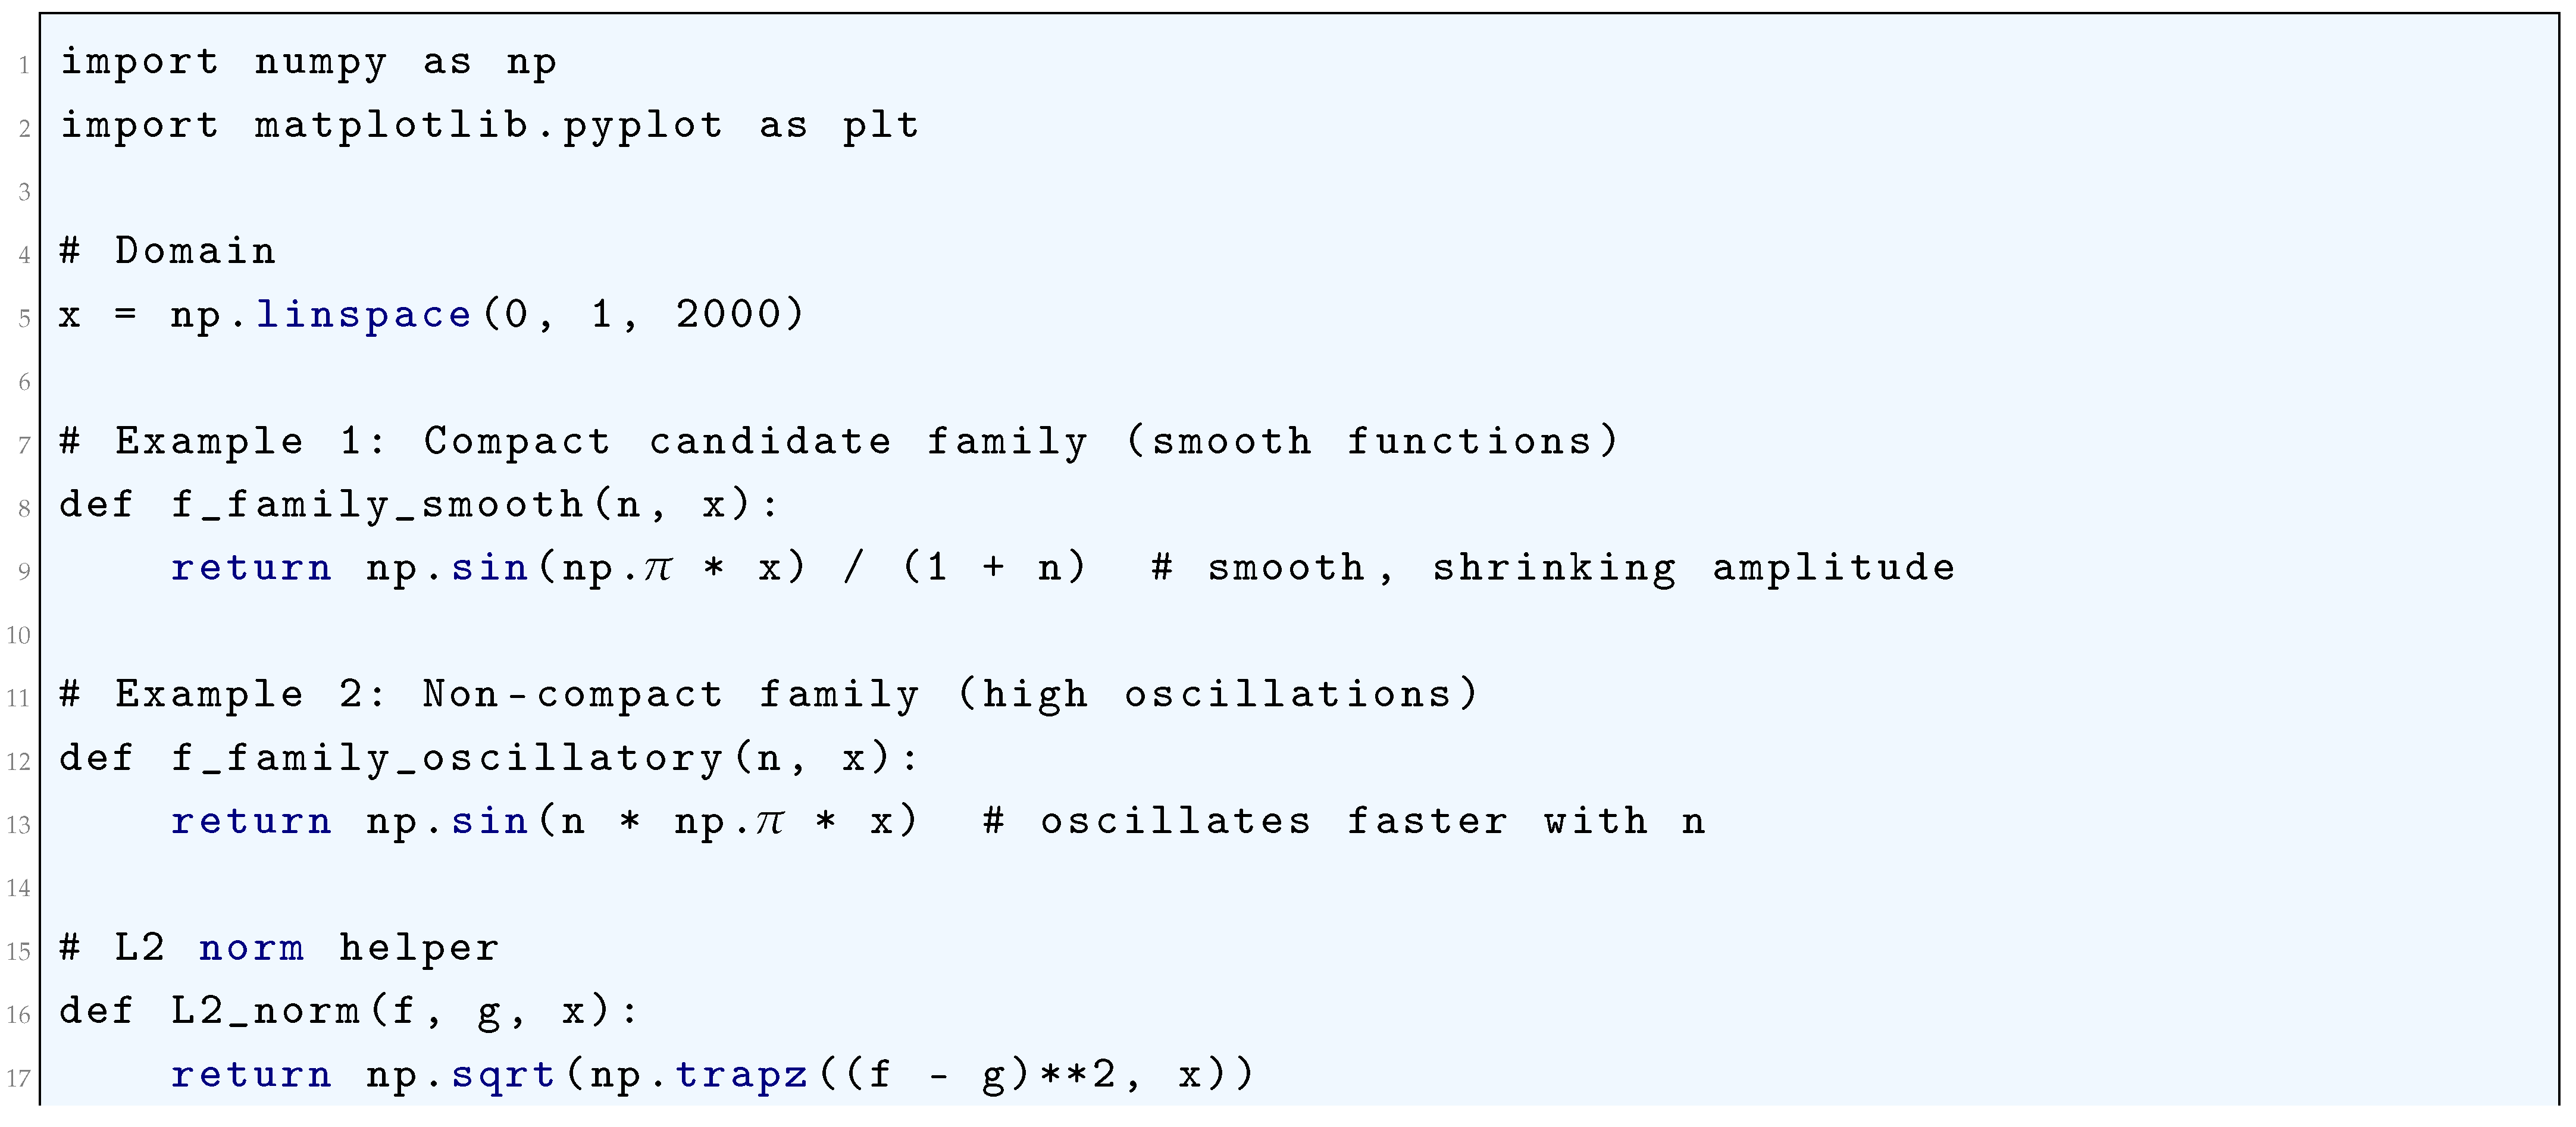
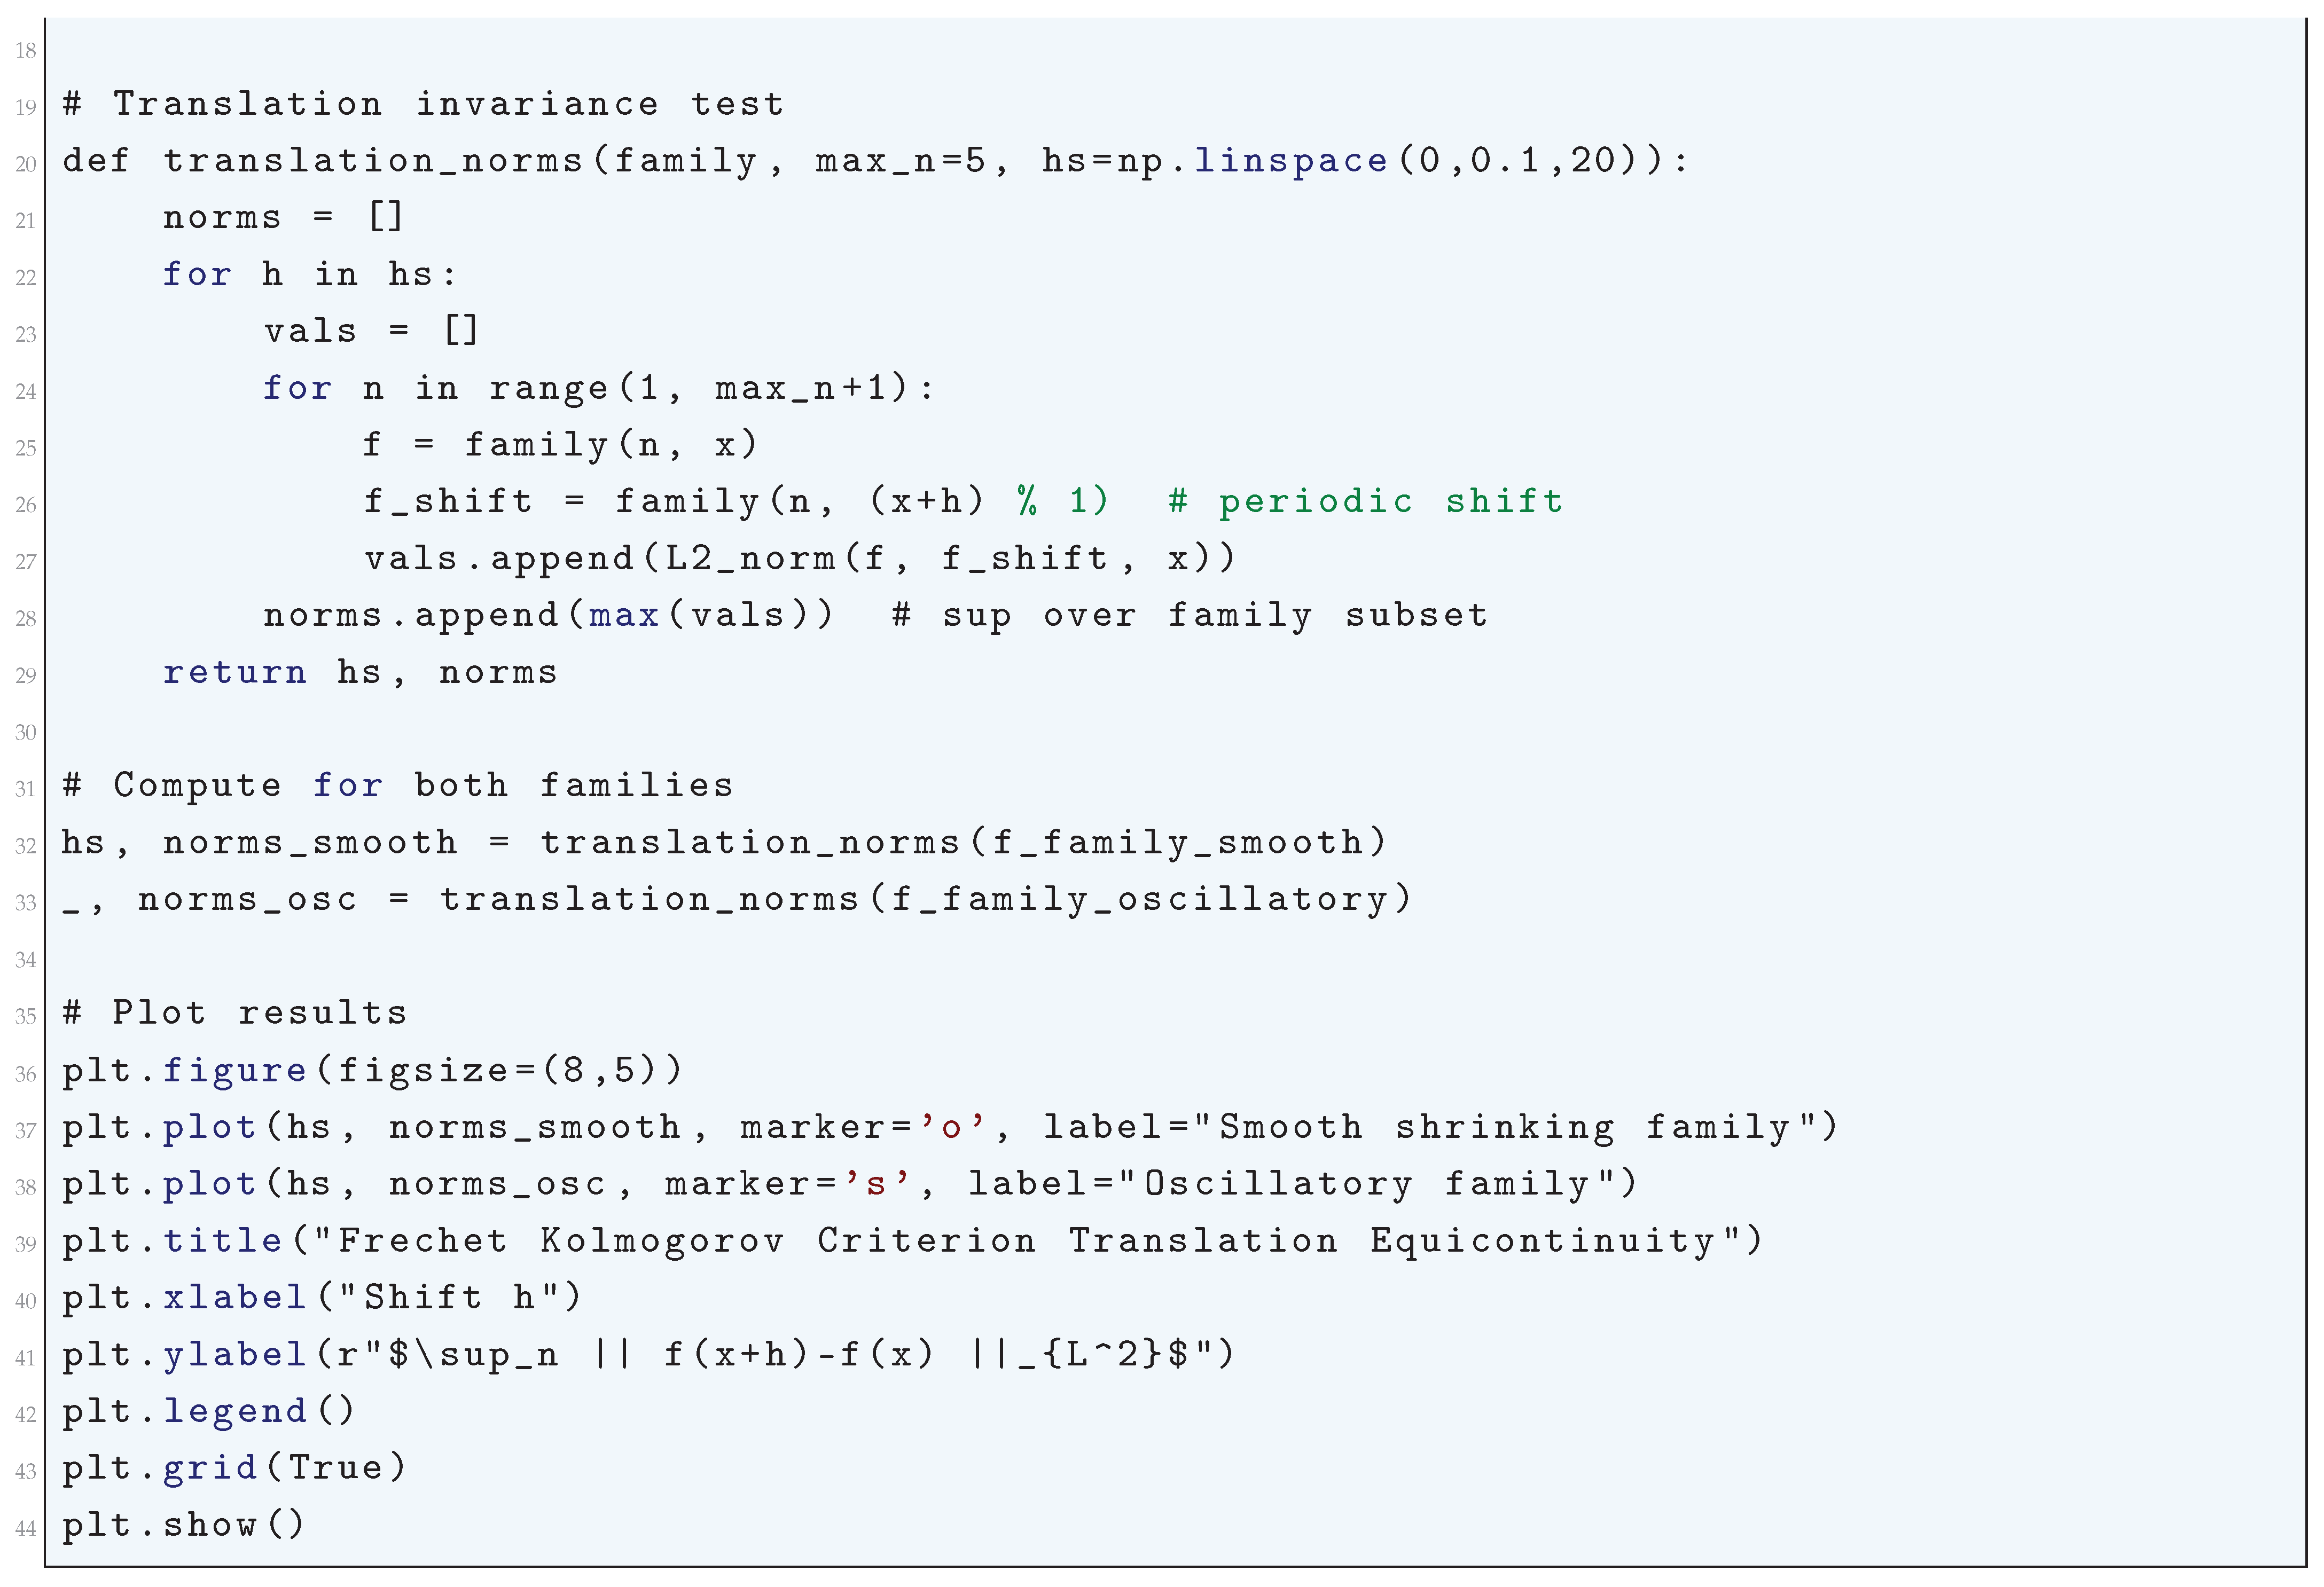
1.2.5.3 Python Code to Generate Figure 12
The Python code below produces the Figure 12 illustrating the Fréchet-Kolmogorov compactness criterion.
Figure 12.
Fréchet–Kolmogorov Criterion: Translation Equicontinuity
1.2.6. Sobolev-Poincaré Inequality
1.2.6.1 Literature Review of Sobolev-Poincaré Inequality
The Sobolev-Poincaré inequality is a cornerstone of modern analysis with far-reaching applications across partial differential equations, geometric analysis, and metric geometry. Among the most comprehensive treatments is Vladimir Maz’ya’s (1985) [1559] seminal work, which provides an exhaustive study of Sobolev-type inequalities including sharp constants, capacity theory, and their validity on both smooth and irregular domains. This foundational text is complemented by Haim Brezis’s (2011) [1549] contribution, which situates the inequality within functional analysis and PDE theory, particularly emphasizing its role in compact embeddings and elliptic regularity. The geometric aspects are profoundly explored in Mikhail Gromov’s (1999) [1555] work, extending classical results to general metric measure spaces, while Elliott Lieb and Michael Loss’s (2001) [1558] analysis offers crucial insights into optimal constants and connections with isoperimetric inequalities through real analytic methods. Heinonen’s (2001)[1563] lectures on analysis on metric spaces also discuss the Sobolev-Poincaré inequality and its application in various mathematical topics in great depth.
For applications to partial differential equations, David Gilbarg and Neil Trudinger’s (2001) [1562] treatment remains indispensable for its rigorous examination of local and global versions on bounded domains, particularly in regularity theory. The variational perspective appears prominently in Antonio Ambrosetti and Andrea Malchiodi’s (2007) [1546] study, which demonstrates how the inequality underpins existence results for nonlinear PDEs. In geometric contexts, Pierre Buser’s (1982) [1550] research on Riemannian manifolds establishes precise relationships between Poincaré constants and geometric data like curvature and diameter, whereas Nicola Garofalo and Dariusz Z. D’Agostino’s (1999) [1554] contributions derive sharp inequalities for sub-Riemannian structures. The probabilistic and geometric-analytic connections are masterfully presented in Dominique Bakry, Ivan Gentil, and Michel Ledoux’s (2014) [1547] work, linking the inequality to Markov semigroups and curvature-dimension conditions.
The extension to nonsmooth settings is systematically developed in Juha Heinonen and Pekka Koskela’s (2001, 2005) [1556][1557] research, which reformulates the inequality using upper gradients for applications in fractal and sub-Riemannian geometry. Luigi Ambrosio, Nicola Gigli, and Giuseppe Savaré’s (2005, 2008) [1544][1545] contributions provide groundbreaking syntheses with optimal transport and metric measure space theory. Hypoelliptic settings are addressed in Luca Capogna, Donatella Danielli, and Nicola Garofalo’s (2001) [1551] work on Hörmander vector fields, while Fabrice Baudoin and Michel Bonnefont’s (2012) [1548] research extends these to subelliptic operators. The heat kernel and spectral perspectives are thoroughly examined in E. Brian Davies’s (1989) [1552] investigation and Qi S. Zhang’s (2011) [1561] work on Ricci flow. Further abstract formulations appear in Karl-Theodor Sturm and Max-K. von Renesse’s (2005) [1560] optimal transport approach to curvature bounds, and Herbert Federer’s (1969) [1553] study provides essential links to currents and varifolds. Collectively, these works form a multifaceted theoretical edifice, demonstrating the Sobolev-Poincaré inequality’s central role in analysis, geometry, and probability through diverse yet interconnected perspectives.
1.2.6.2 Analysis of Sobolev-Poincaré Inequality
Let be a bounded domain with a Lipschitz boundary. Consider the Sobolev space for , which consists of functions whose weak derivatives also belong to . The Sobolev-Poincaré inequality asserts the existence of a constant such that
for all , where is the Sobolev conjugate exponent and is the mean value of u over , given by
To prove this inequality, we first use a representation formula for . Given any two points , we consider the fundamental theorem of calculus applied along the segment connecting x to y. Define the parametrization
Applying the fundamental theorem of calculus along this line segment,
By the chain rule,
Substituting this into the integral expression,
Taking the absolute value and applying Hölder’s inequality with conjugate exponents p and ,
Now, integrating both sides over , using Fubini’s theorem and Minkowski’s integral inequality,
Using the properties of integral norms and applying Hölder’s inequality again,
By averaging over and defining the mean-value term appropriately, we obtain
where C depends on and p, completing the proof.
Let be a bounded domain with a Lipschitz boundary. Consider the Sobolev space for , which consists of functions whose weak derivatives also belong to . The Sobolev-Poincaré inequality asserts the existence of a constant such that
for all , where is the Sobolev conjugate exponent and is the mean value of u over , given by
To prove this inequality, we first use a representation formula for . Given any two points , we consider the fundamental theorem of calculus applied along the segment connecting x to y. Define the parametrization
Applying the fundamental theorem of calculus along this line segment,
By the chain rule,
Substituting this into the integral expression,
Taking the absolute value and applying Hölder’s inequality with conjugate exponents p and ,
Now, integrating both sides over , using Fubini’s theorem and Minkowski’s integral inequality,
Using the properties of integral norms and applying Hölder’s inequality again,
By averaging over and defining the mean-value term appropriately, we obtain
where C depends on and p, completing the proof. The consequences and applications are:
- Regularity of PDE Solutions: The Sobolev-Poincaré inequality is crucial in proving the existence and regularity of weak solutions to elliptic PDEs.
- Compactness and Rellich-Kondrachov Theorem: It plays a role in proving the compact embedding of into , which is fundamental in functional analysis.
- Control of Function Oscillations: It quantifies how much a function can deviate from its mean, which is used in various areas of mathematical physics and geometry.
One important extension is the sharp form of the Sobolev-Poincaré inequality, which involves explicit best constants in terms of the domain geometry. Specifically, in some cases, the optimal constant is related to eigenvalues of the Laplace operator or geometric properties such as the diameter or inradius of . Another important extension is the fractional Sobolev-Poincaré inequality, which deals with function spaces like where s is fractional, incorporating nonlocal effects.
In conclusion, the Sobolev-Poincaré inequality is a powerful mathematical result that provides a precise relationship between function averages and their gradients. It is a cornerstone in modern analysis, with deep implications in PDE theory, functional analysis, and geometric measure theory.
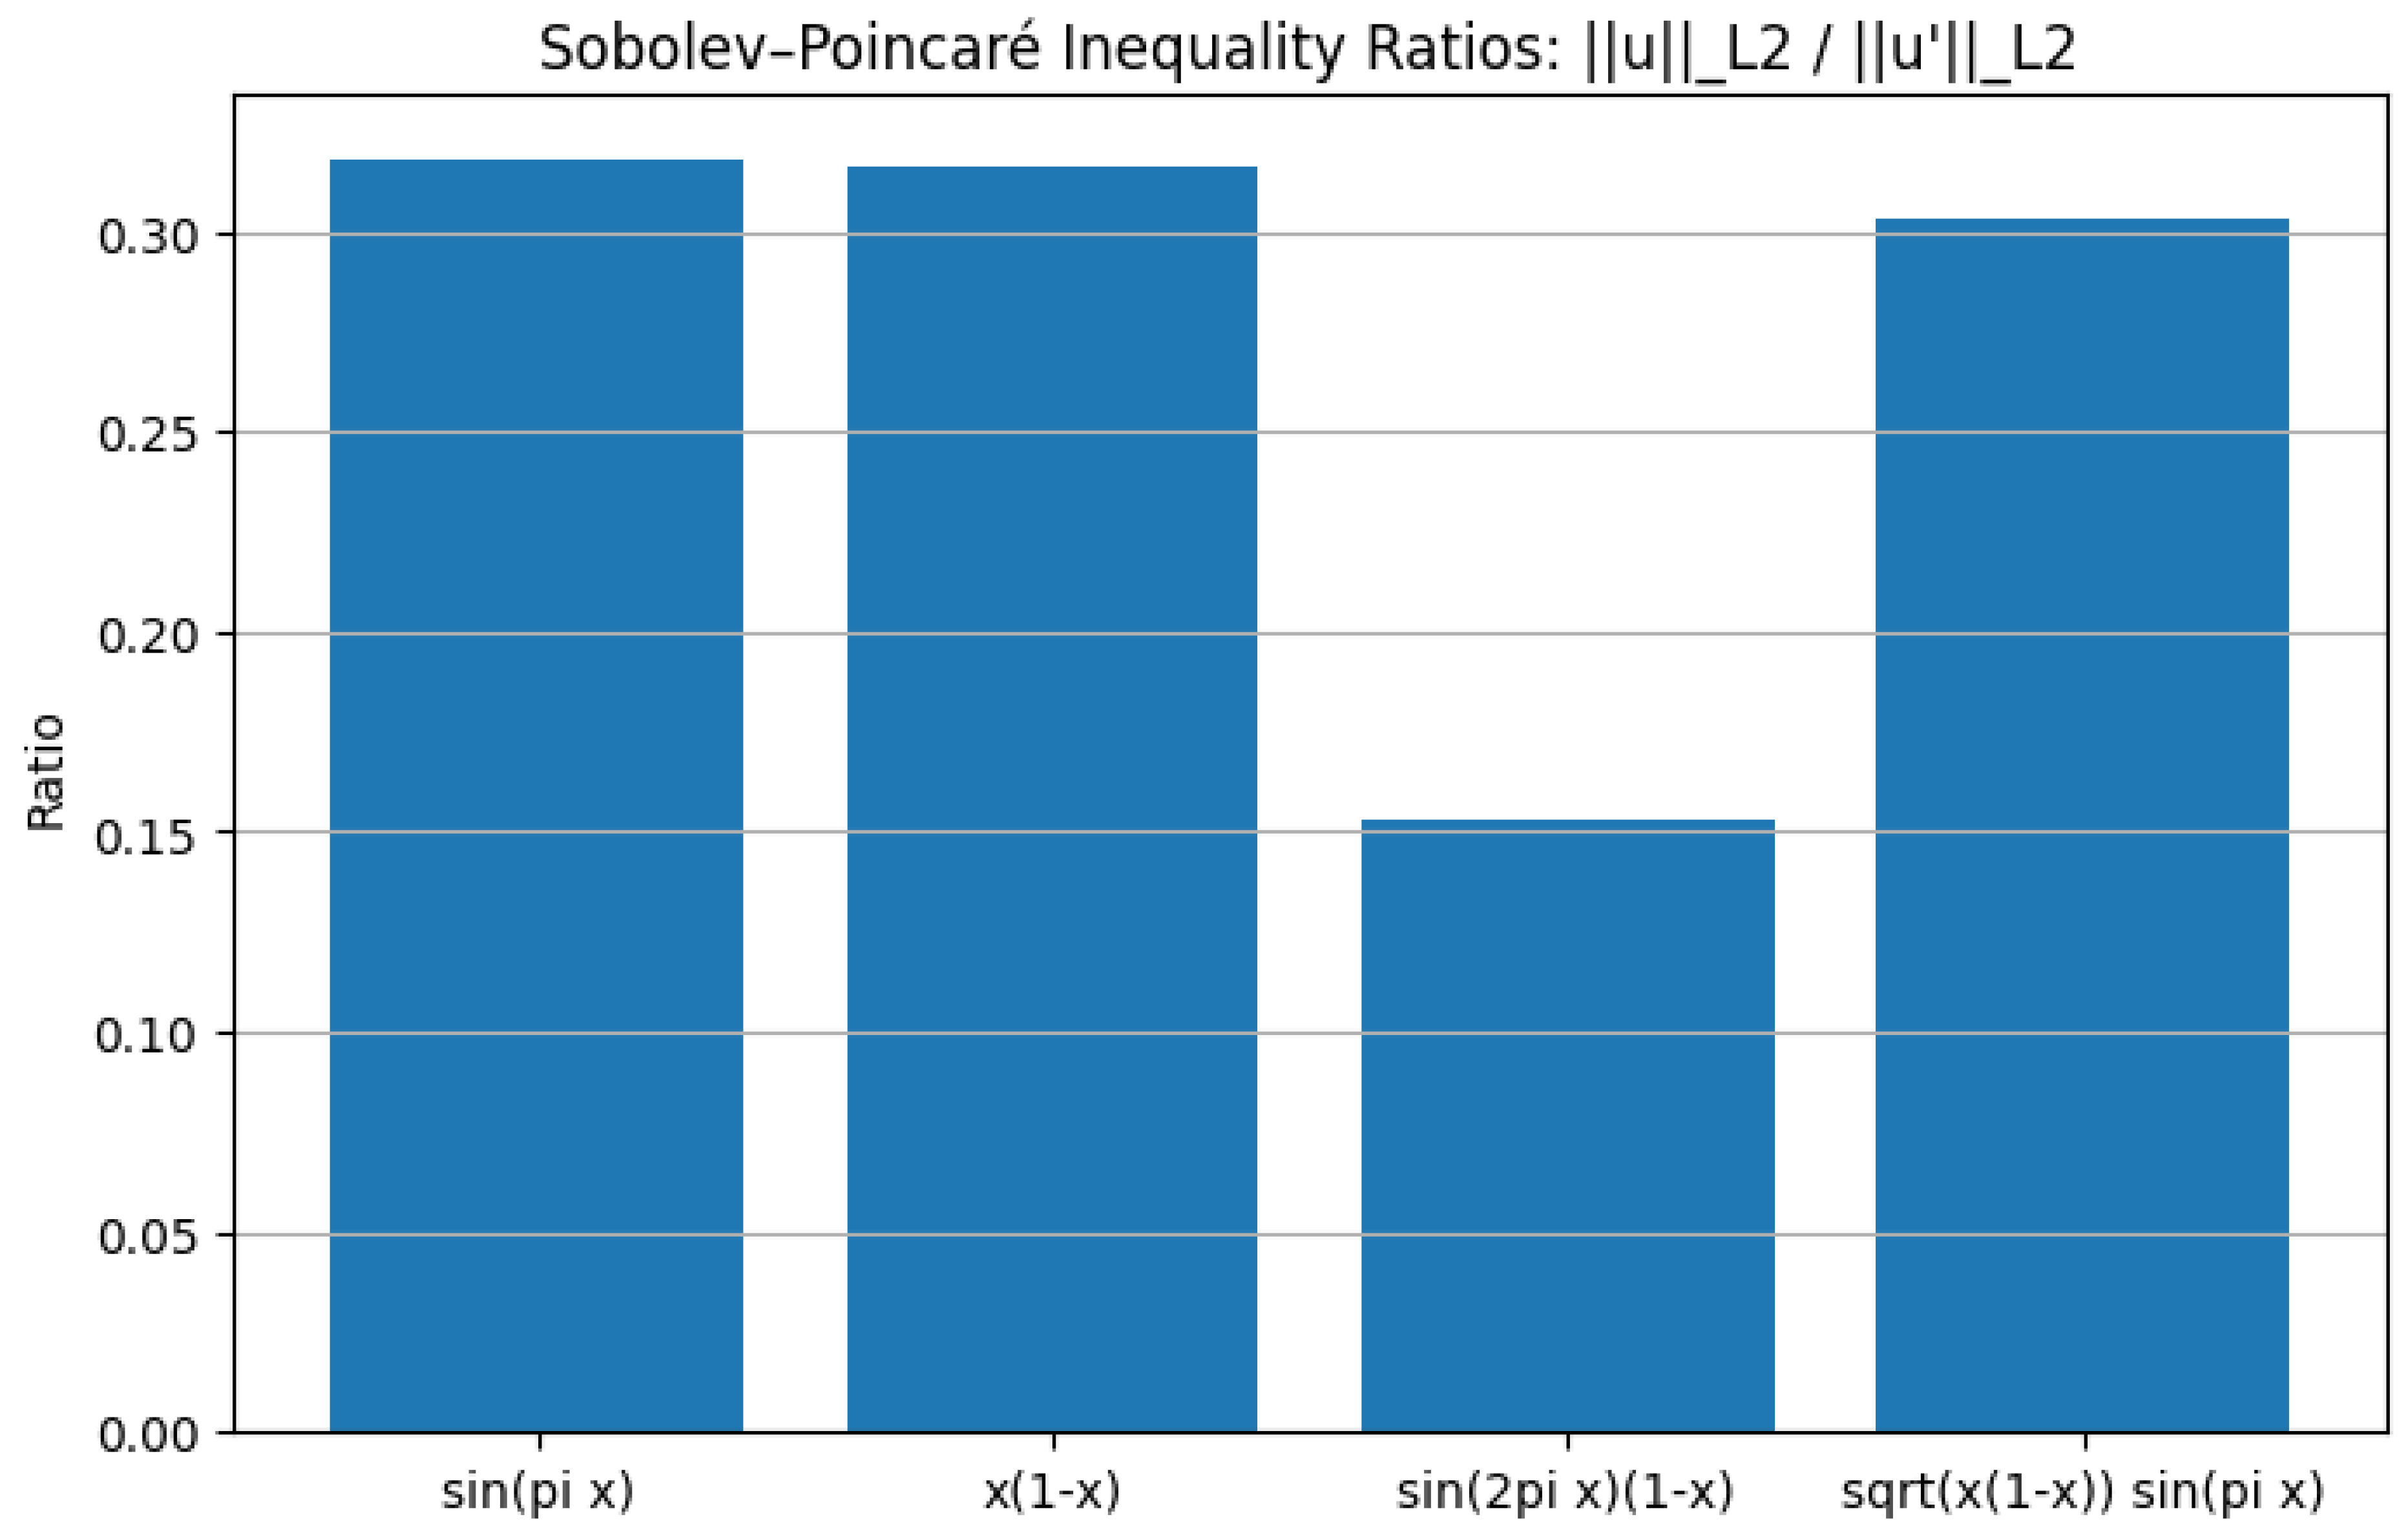
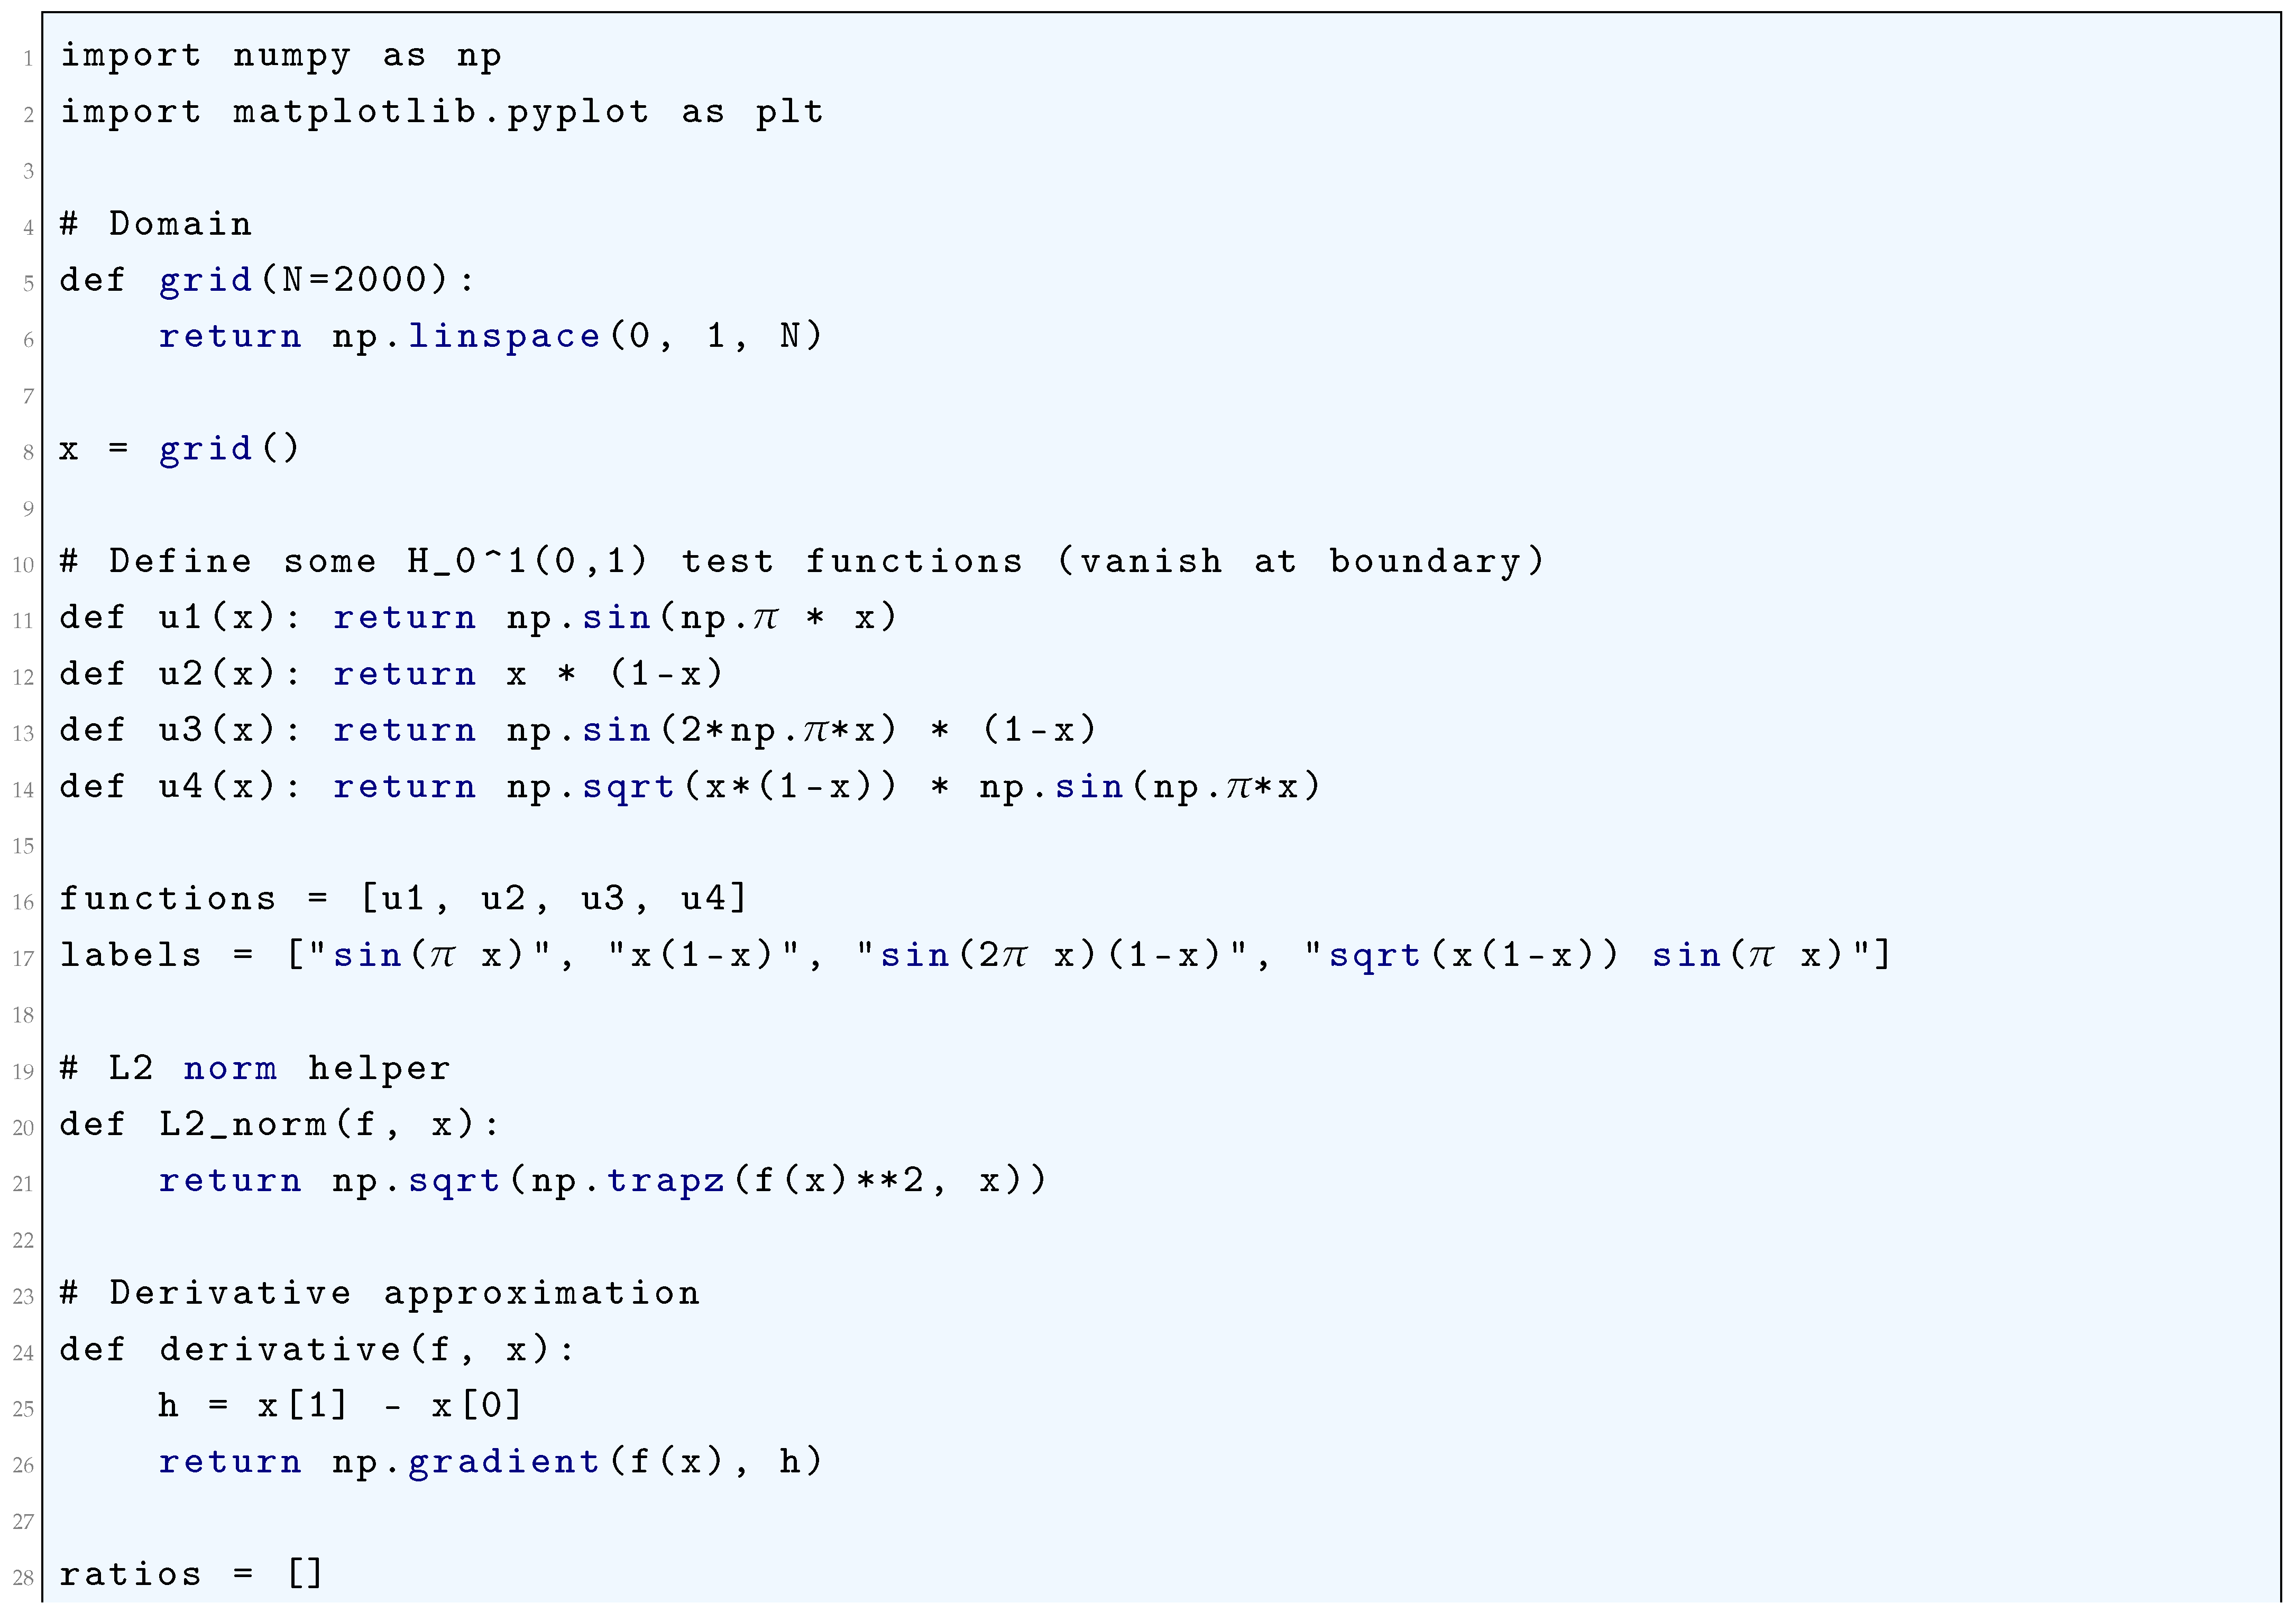
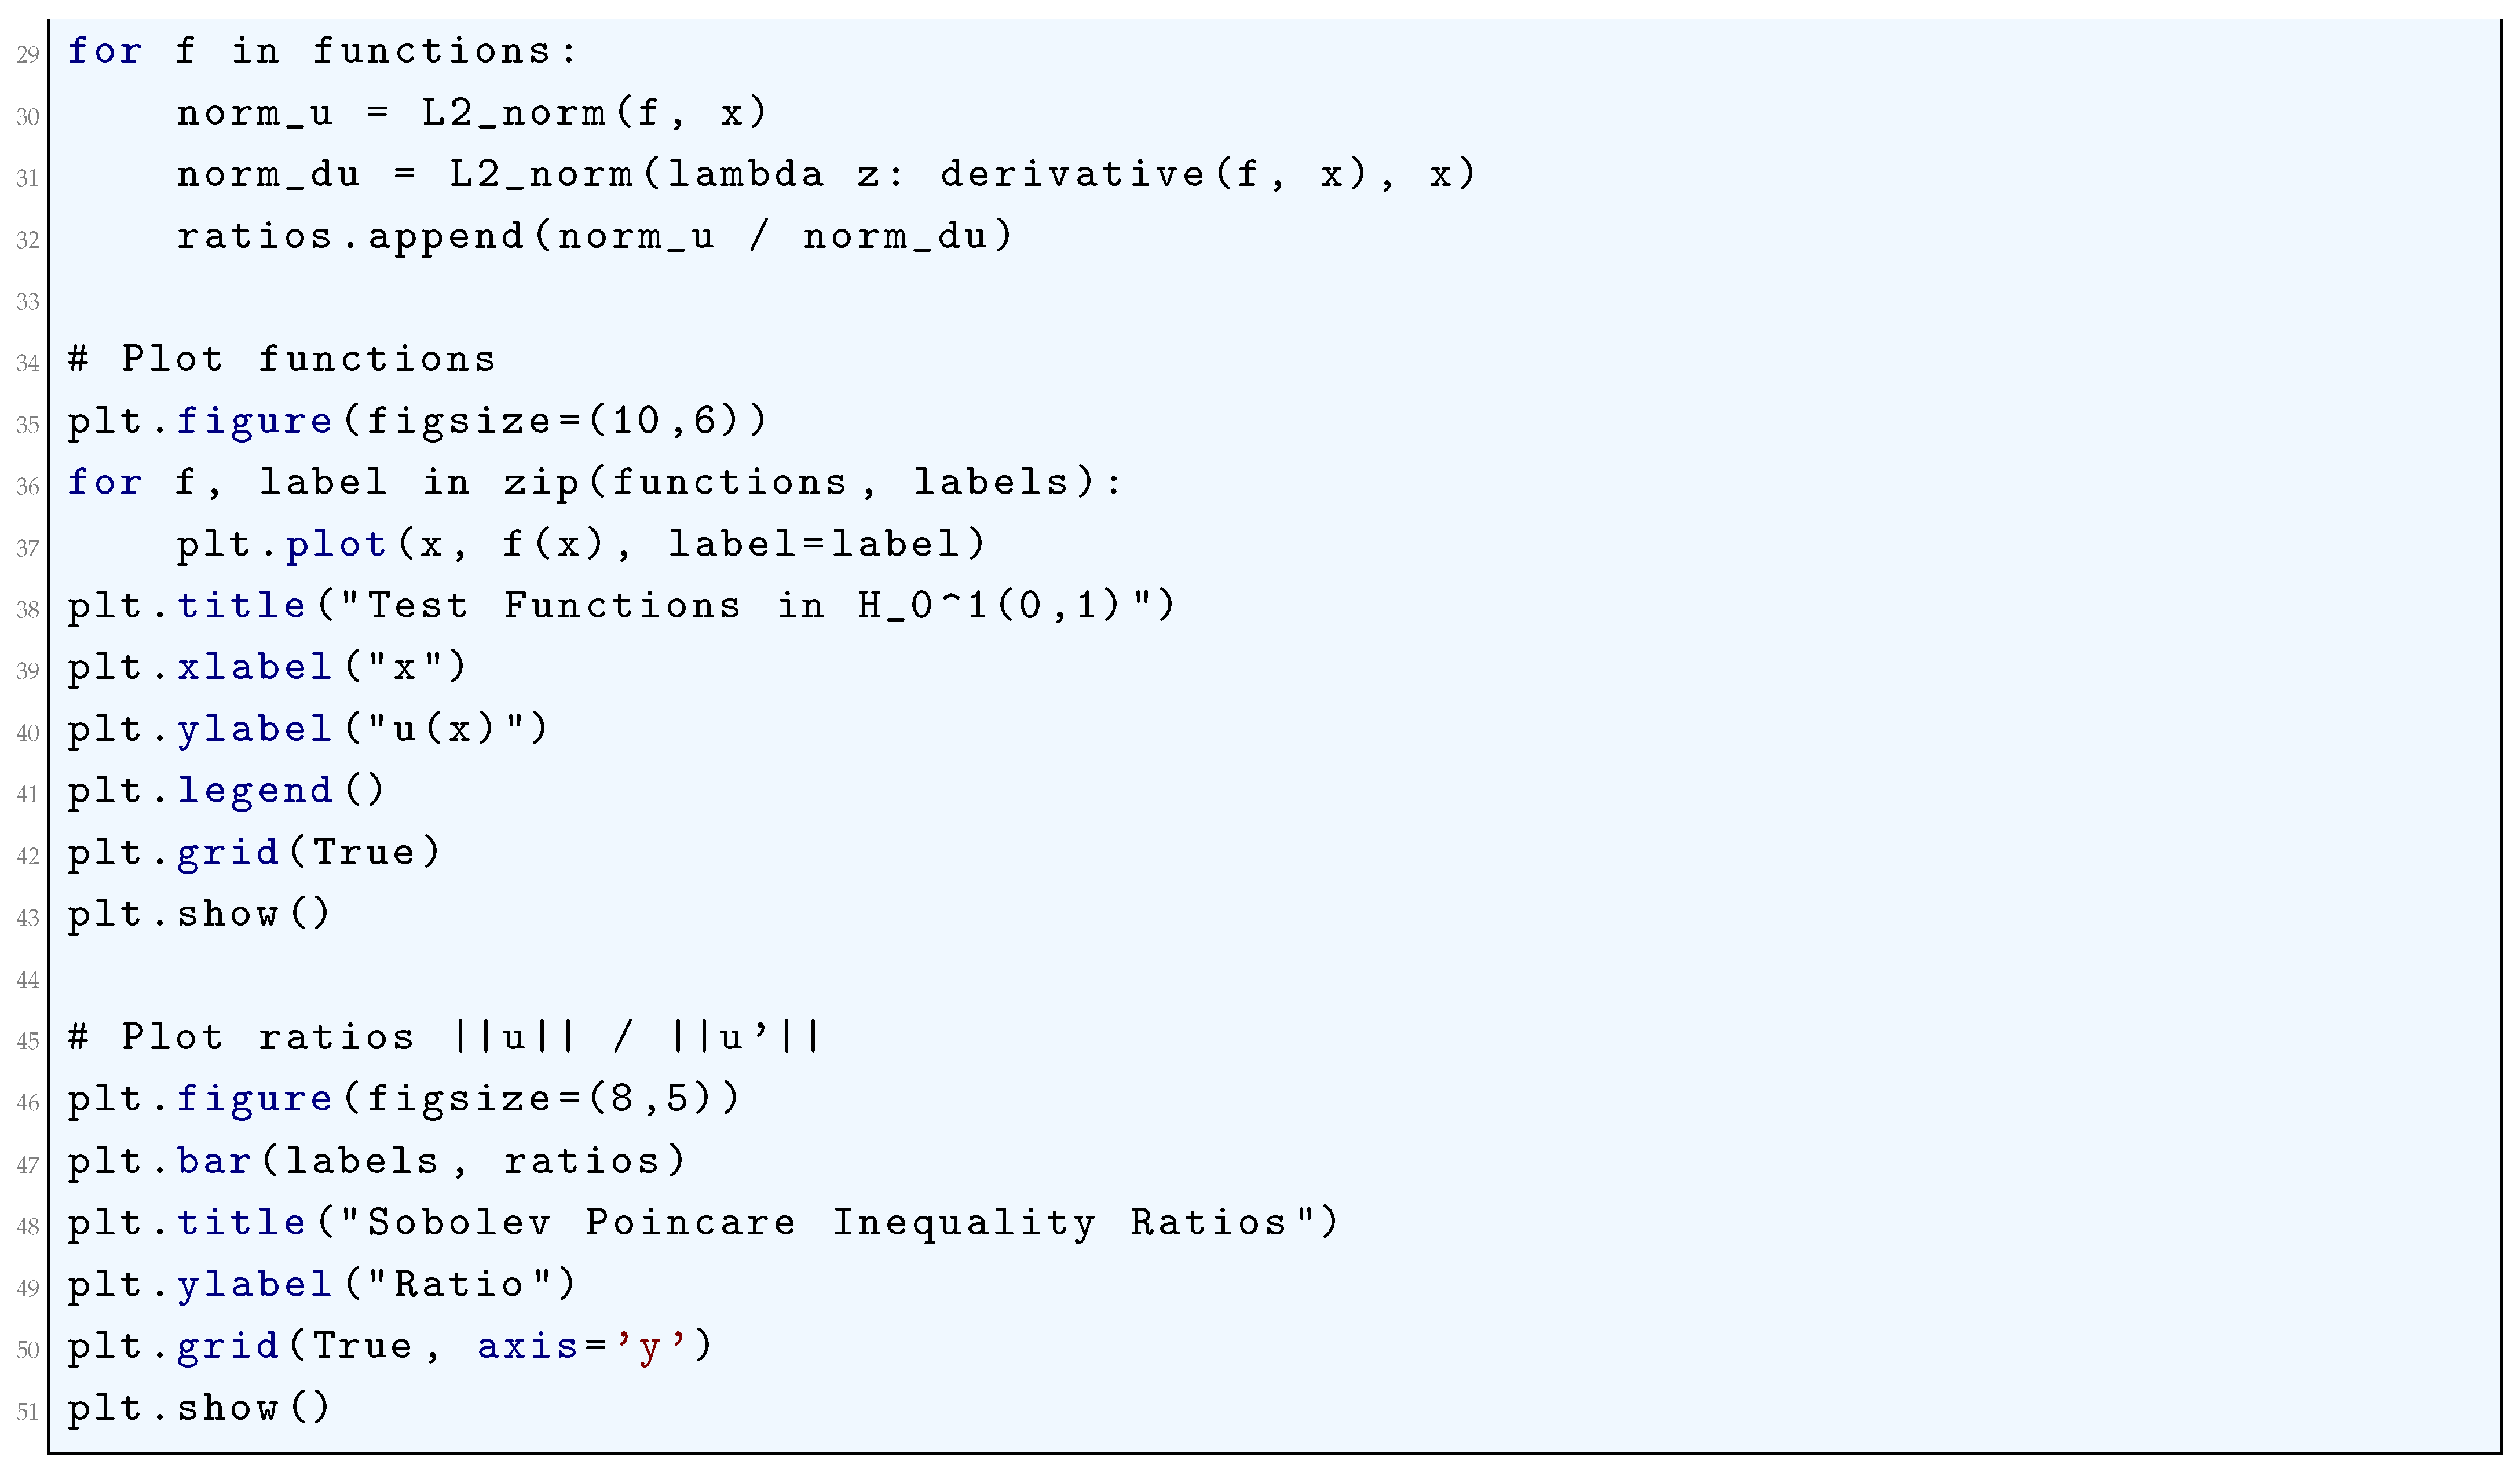
1.2.6.3 Python Code to Generate Figure 13 and Figure 14
The Python code below produces the Figure 13 and Figure 14 illustrating the Fréchet-Kolmogorov compactness criterion.
Figure 13.
Test Functions in
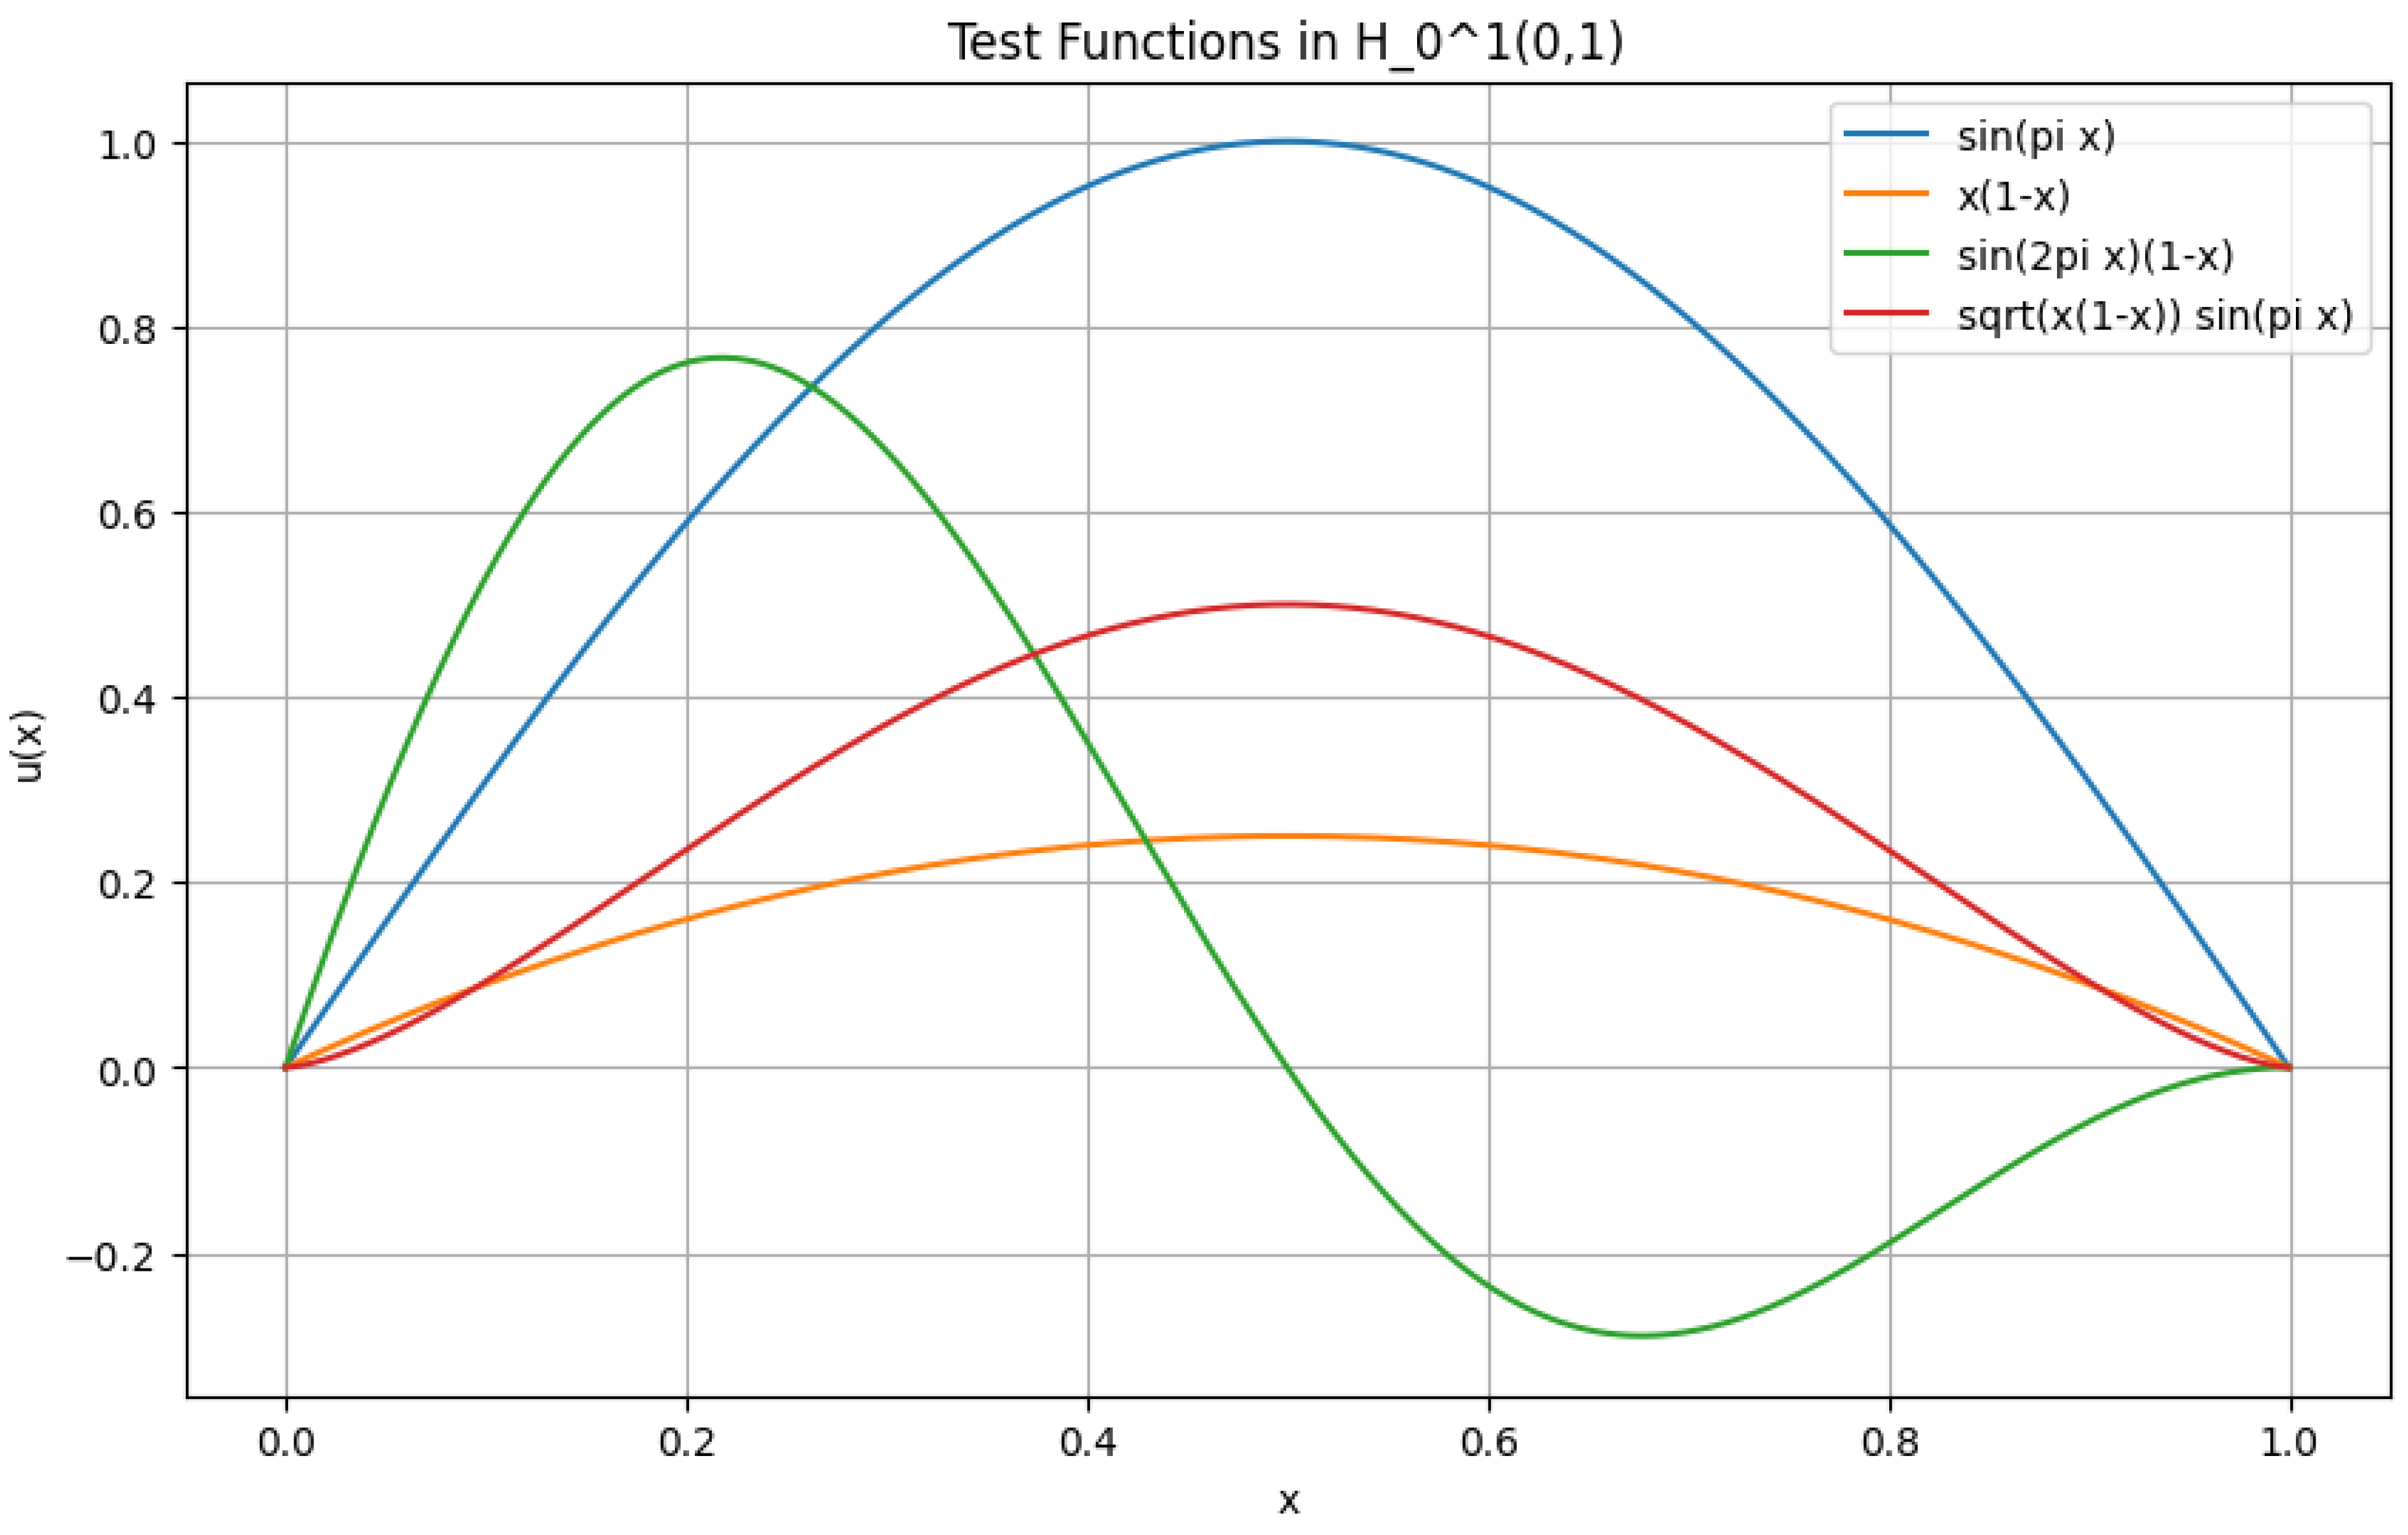
Figure 14.
Sobolev–Poincaré Inequality Ratios:
2. Universal Approximation Theorem: Refined Proof
The Universal Approximation Theorem (UAT) is a fundamental result in neural network theory, stating that a feedforward neural network with a single hidden layer containing a finite number of neurons can approximate any continuous function on a compact subset of to any desired degree of accuracy, provided that an appropriate activation function is used. This theorem has significant implications in machine learning, function approximation, and deep learning architectures.
The Universal Approximation Theorem (UAT) is a fundamental result in the theory of artificial neural networks, which states that a feedforward neural network with a single hidden layer and a non-polynomial activation function can approximate any continuous function on a compact subset of to arbitrary precision, provided the hidden layer has a sufficient number of neurons. Formally, let be a non-constant, bounded, and continuous activation function. For any continuous function defined on a compact set K, and for every , there exists a neural network of the form:
where N is the number of hidden units, are the input weights, are the biases, and are the output weights, such that:
The theorem underscores the expressive power of neural networks, demonstrating that even a single hidden layer is theoretically capable of approximating any continuous function, given enough neurons. The key assumptions are the non-polynomial nature of the activation function and the compactness of the domain. Common activation functions satisfying these conditions include the sigmoid , the hyperbolic tangent , and the rectified linear unit (ReLU) . The compactness requirement ensures that the function f is uniformly continuous, enabling the approximation to hold uniformly across the entire domain. The proof of the UAT typically relies on tools from functional analysis, such as the Stone-Weierstrass theorem or the Hahn-Banach theorem, which guarantee the density of certain function spaces. For instance, the Stone-Weierstrass theorem asserts that any subalgebra of continuous functions that separates points and contains the constant functions is dense in the space of continuous functions. By showing that the set of functions representable by a neural network forms such a subalgebra, the UAT can be derived. The non-polynomial condition on is critical to ensure the network can generate a rich enough class of functions to approximate arbitrary continuous mappings.
However, the theorem does not provide explicit bounds on the number of neurons N required to achieve a given accuracy , nor does it address the practical challenges of training such networks. In practice, deeper architectures with multiple hidden layers often outperform shallow networks, even though the UAT theoretically guarantees the sufficiency of a single hidden layer. This discrepancy highlights the difference between existence and learnability: while the UAT ensures the existence of an approximating network, finding such a network through optimization remains a non-trivial task. The theorem also does not account for the curse of dimensionality, which can make the required number of neurons infeasibly large for high-dimensional inputs. Despite these limitations, the UAT remains a cornerstone of neural network theory, providing a rigorous foundation for their universal applicability.
2.1. Literature Review of Universal Approximation Theorem
Hornik et. al. (1989) [58] in their seminal paper rigorously proved that multilayer feedforward neural networks with a single hidden layer and a sigmoid activation function can approximate any continuous function on a compact set. It extends prior results and lays the foundation for the modern understanding of UAT. Cybenko (1989) [60] provided one of the first rigorous proofs of the UAT using the sigmoid function as the activation function. They demonstrated that a single hidden layer network can approximate any continuous function arbitrarily well. Barron (1993) [61] extended UAT by quantifying the approximation error and analyzing the rate of convergence. This work is crucial for understanding the practical efficiency of neural networks. Pinkus (1999) [62] provided a comprehensive survey of UAT from the perspective of approximation theory and also discussed conditions for approximation with different activation functions and the theoretical limits of neural networks. Lu et.al. (2017) [63] investigated how the width of neural networks affects their approximation capability, challenging the notion that deeper networks are always better. They also provided insights into trade-offs between depth and width. Hanin and Sellke (2018) [64] extended UAT to ReLU activation functions, showing that deep ReLU networks achieve universal approximation while maintaining minimal width constraints. Garcıa-Cervera et. al. (2024) [66] extended the universal approximation theorem to set-valued functions and its applications to Deep Operator Networks (DeepONets), which are useful in control theory and PDE modeling. Majee et.al. (2024) [67] explored the universal approximation properties of deep neural networks for solving inverse problems using Markov Chain Monte Carlo (MCMC) techniques. Toscano et. al. (2024) [68] introduced Kurkova-Kolmogorov-Arnold Networks (KKANs), an extension of UAT incorporating Kolmogorov’s superposition theorem for improved approximation capabilities. Son (2025) [69] established a new framework for operator learning based on the UAT, providing a theoretical foundation for backpropagation-free deep networks.
2.2. Approximation Using Convolution Operators
Let us begin by considering the convolution operator and its role in approximating functions in the context of the Universal Approximation Theorem (UAT). Suppose is a continuous and bounded function. The convolution of f with a kernel function , denoted as , is defined as
The kernel is typically chosen to be smooth, compactly supported, and normalized such that
To approximate f locally, we introduce a scaling parameter and define the scaled kernel as
The factor ensures that remains a probability density function, satisfying
The convolution of f with the scaled kernel is given by
Performing the change of variables , we have and . Substituting into the integral, we obtain
This representation shows that is a smoothed version of , where the smoothing is controlled by the parameter . As , the kernel becomes increasingly concentrated around x, and we recover in the limit:
assuming f is continuous.
This result can be rigorously proven using properties of the kernel , such as its smoothness and compact support, and the dominated convergence theorem, which ensures that the integral converges uniformly to . Now, let us consider the role of convolution operators in the approximation of f by neural networks. A single-layer feedforward neural network is expressed as
where are coefficients, are weight vectors, are biases, and is the activation function. The activation function can be interpreted as a localized response function, analogous to the kernel in convolution. By drawing an analogy between the two, we can write the neural network approximation as
where is interpreted as a parameterized kernel defined by , , and , and represents a discretization step. The approximation error can be decomposed into two components:
The term represents the error introduced by smoothing f with the kernel , and it can be made arbitrarily small by choosing sufficiently small, provided f is regular enough (e.g., Lipschitz continuous).
The term quantifies the error due to discretization, which vanishes as the number of neurons . To rigorously analyze the convergence of to , we rely on the density of neural network approximators in function spaces. The Universal Approximation Theorem states that, for any continuous function f on a compact domain and any , there exists a neural network with finitely many neurons such that
This result hinges on the ability of the activation function to generate a rich set of basis functions. For example, if (ReLU), the network approximates by piecewise linear functions. If (sigmoid), the network generates smooth approximations that resemble logistic regression.
In this refined proof of the UAT, convolution operators provide a unifying framework for understanding the smoothing, localization, and discretization processes that underlie neural network approximations. The interplay between , , and reveals the profound mathematical structure that connects classical approximation theory with modern machine learning. This connection not only enhances our theoretical understanding of neural networks but also guides the design of architectures and algorithms for practical applications.
2.2.1. Python Code to Generate Figure 15 and Figure 16
The Python code below produces the Figure 15 and Figure 16 illustrating the Approximation Using Convolution Operators.
Figure 15.
Universal Approximation Theorem Illustration
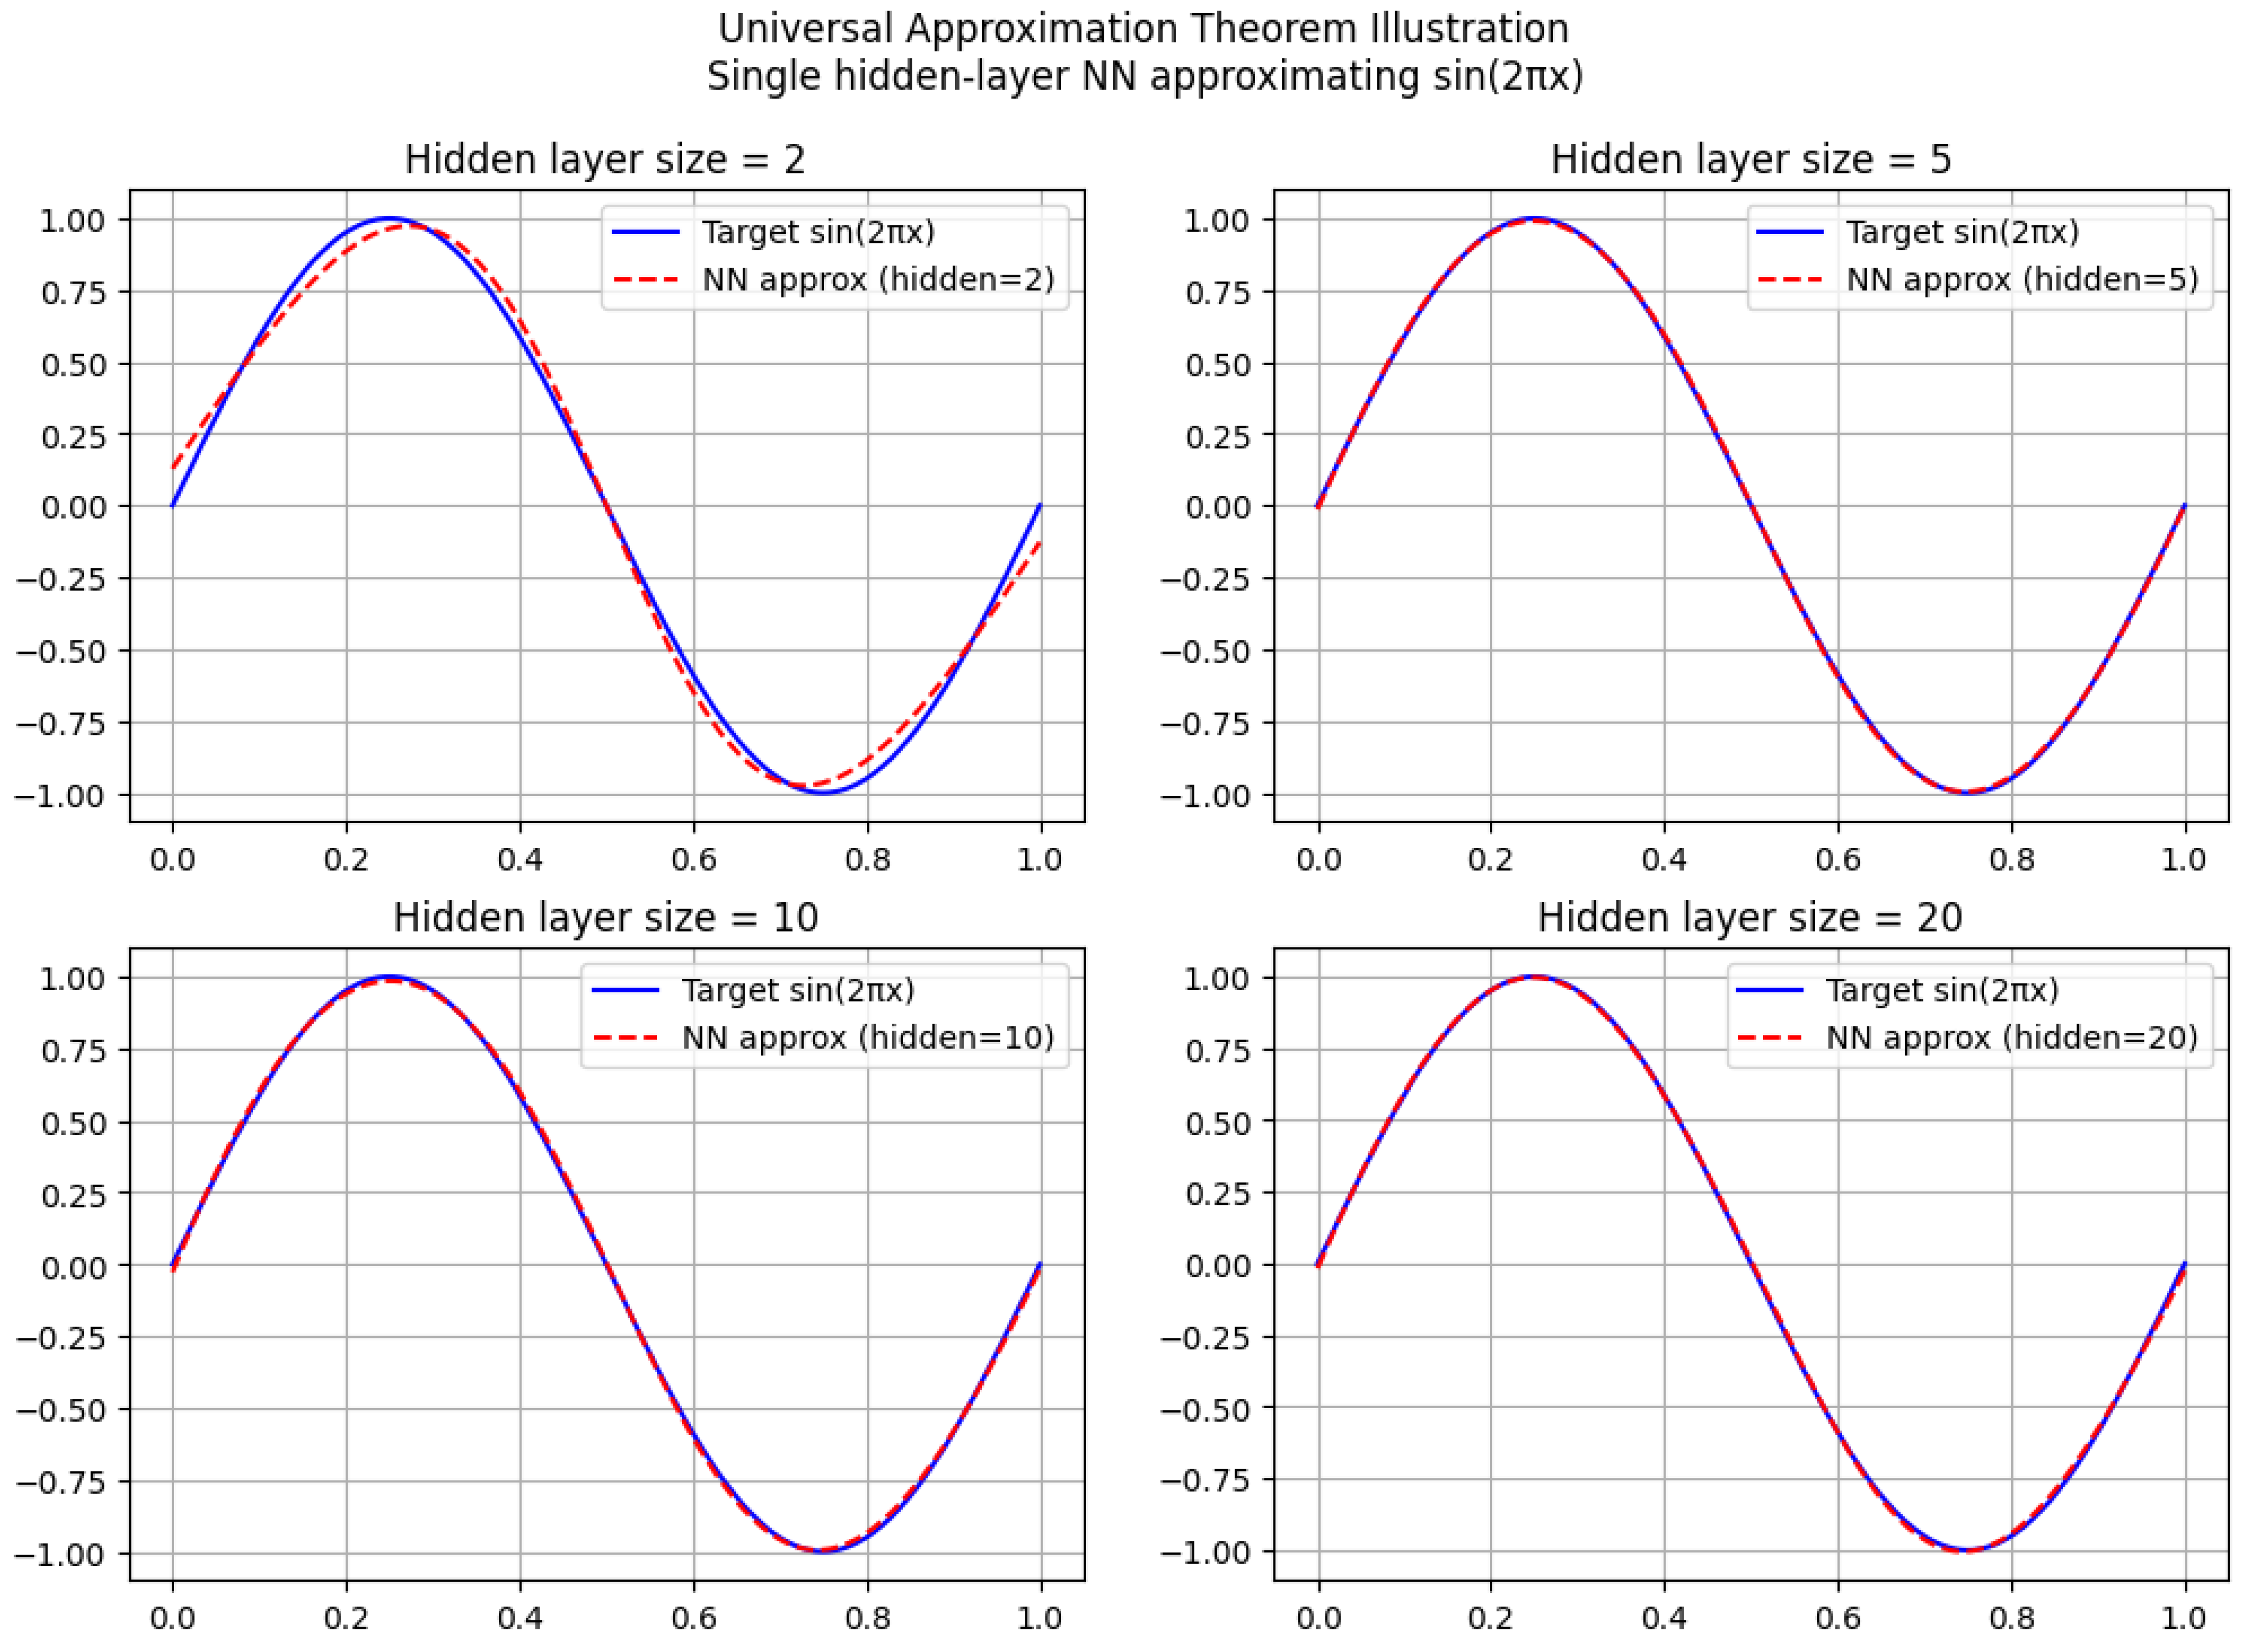
Figure 16.
Approximation Error vs Hidden Layer Size
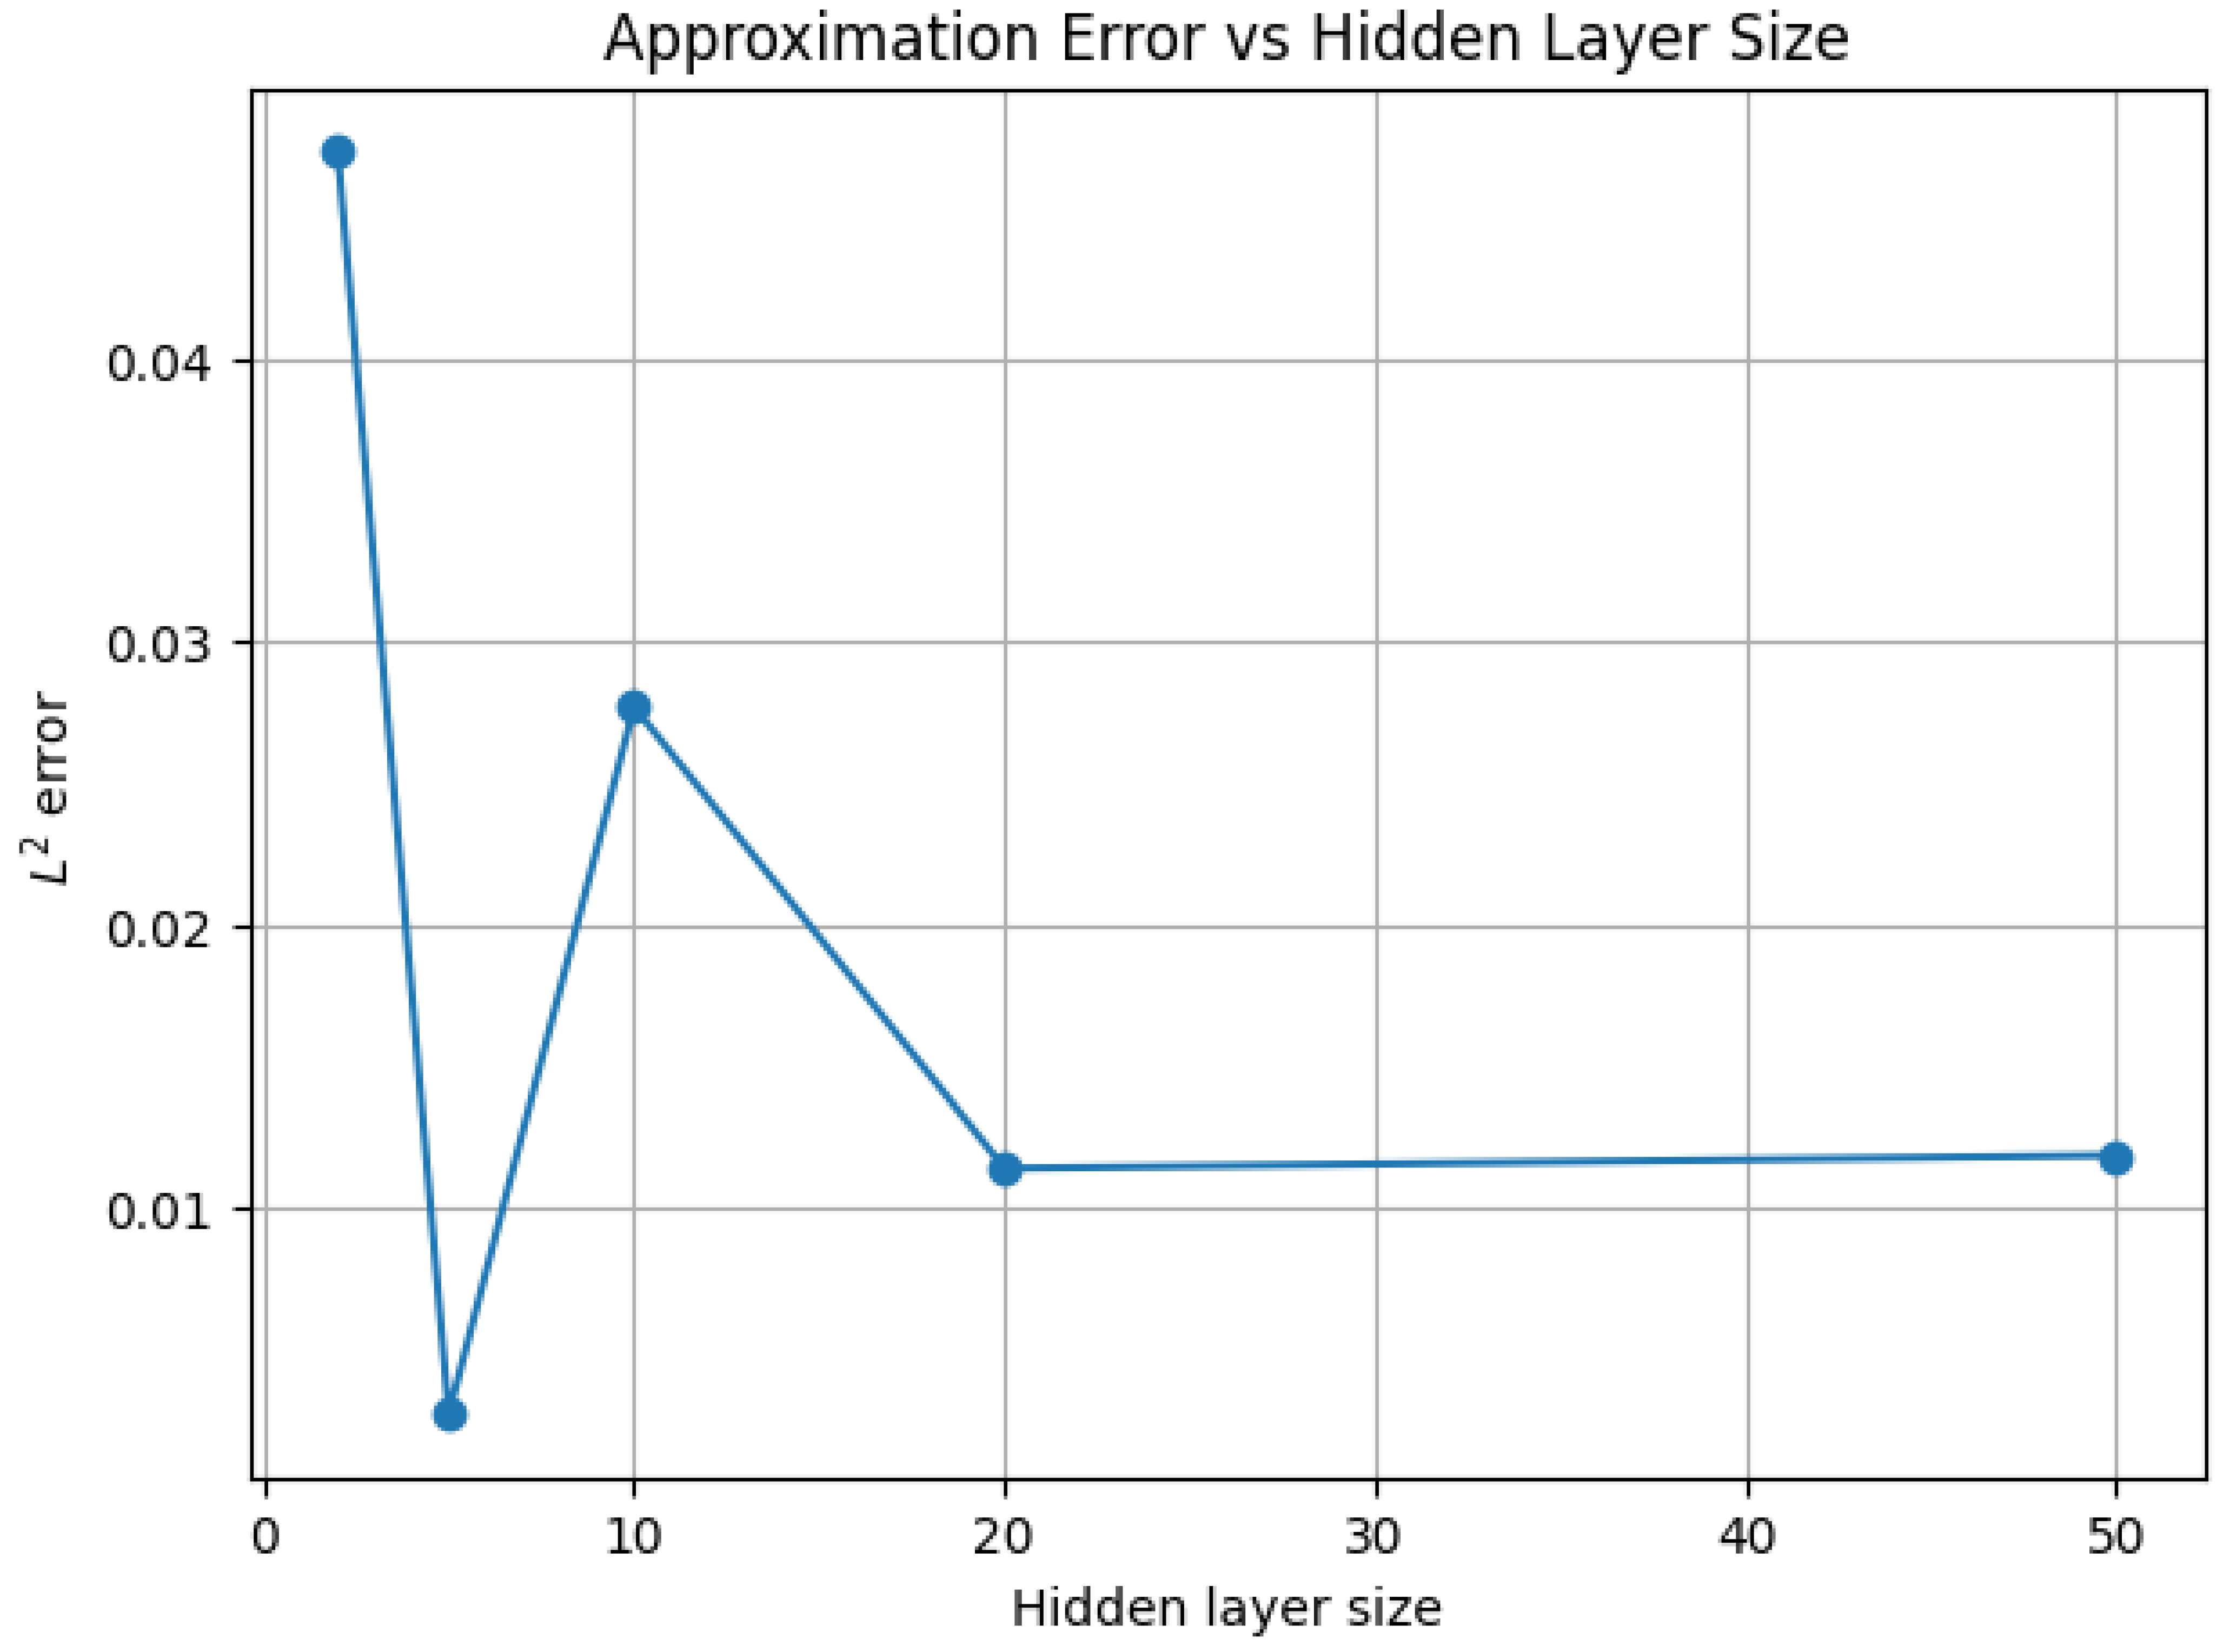
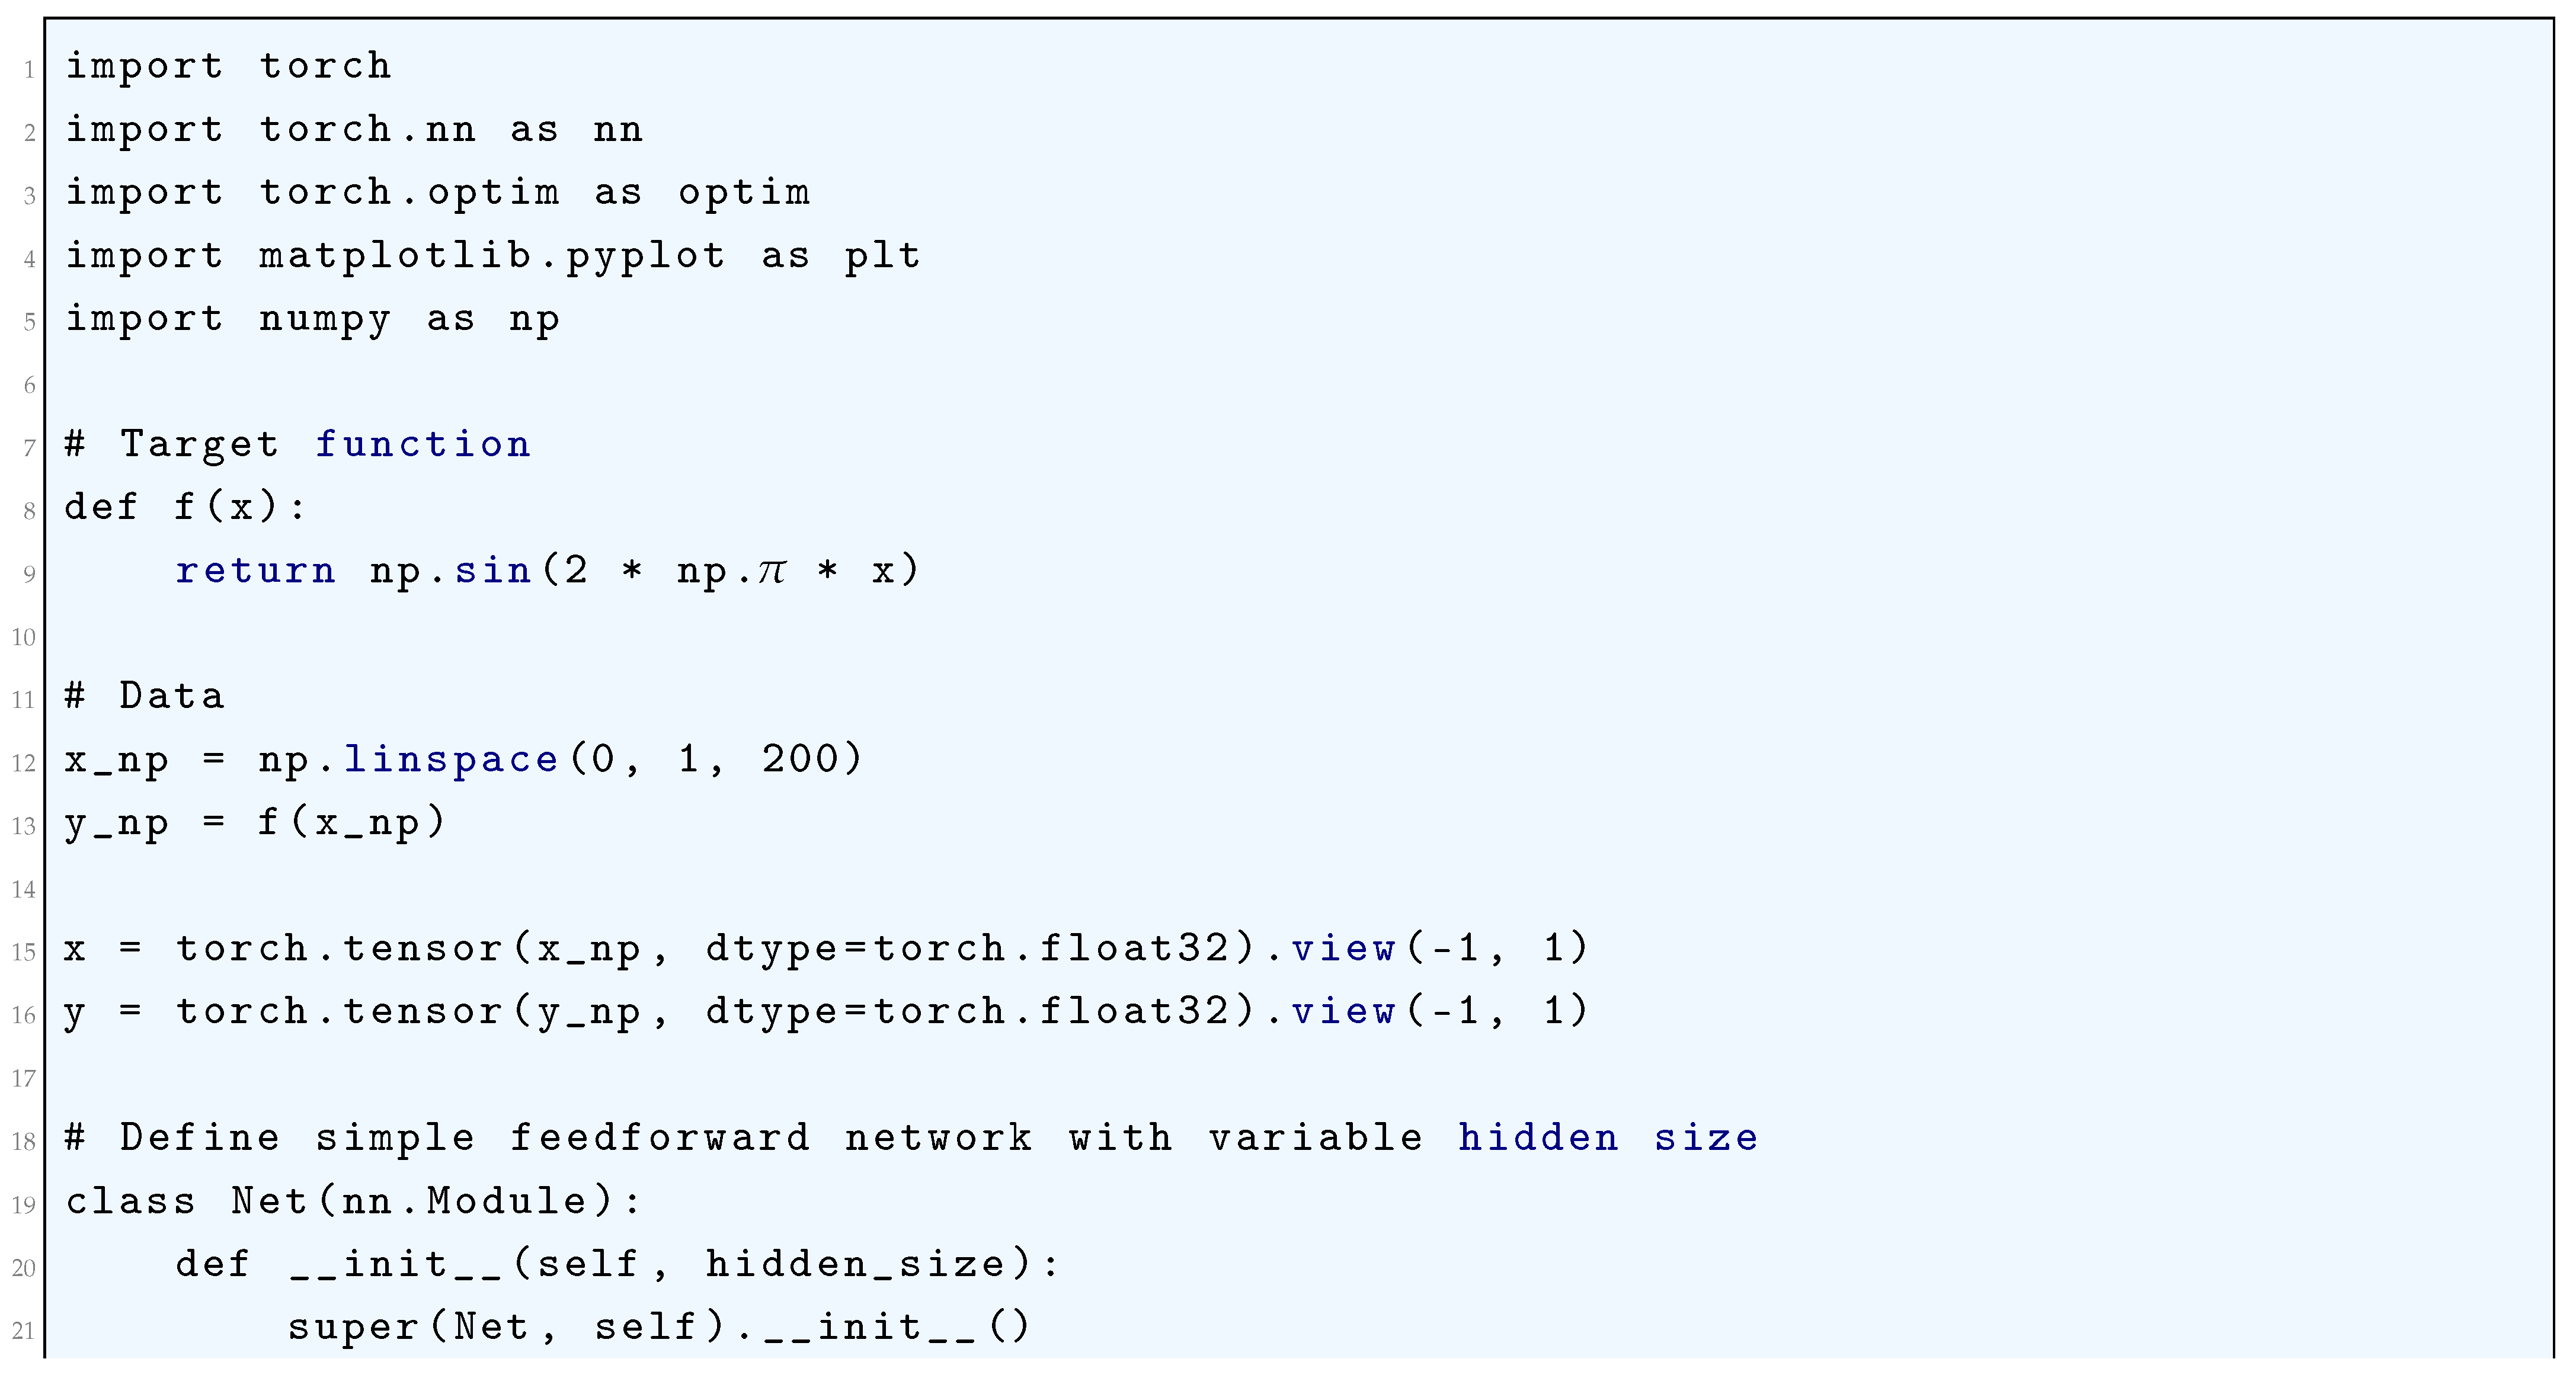
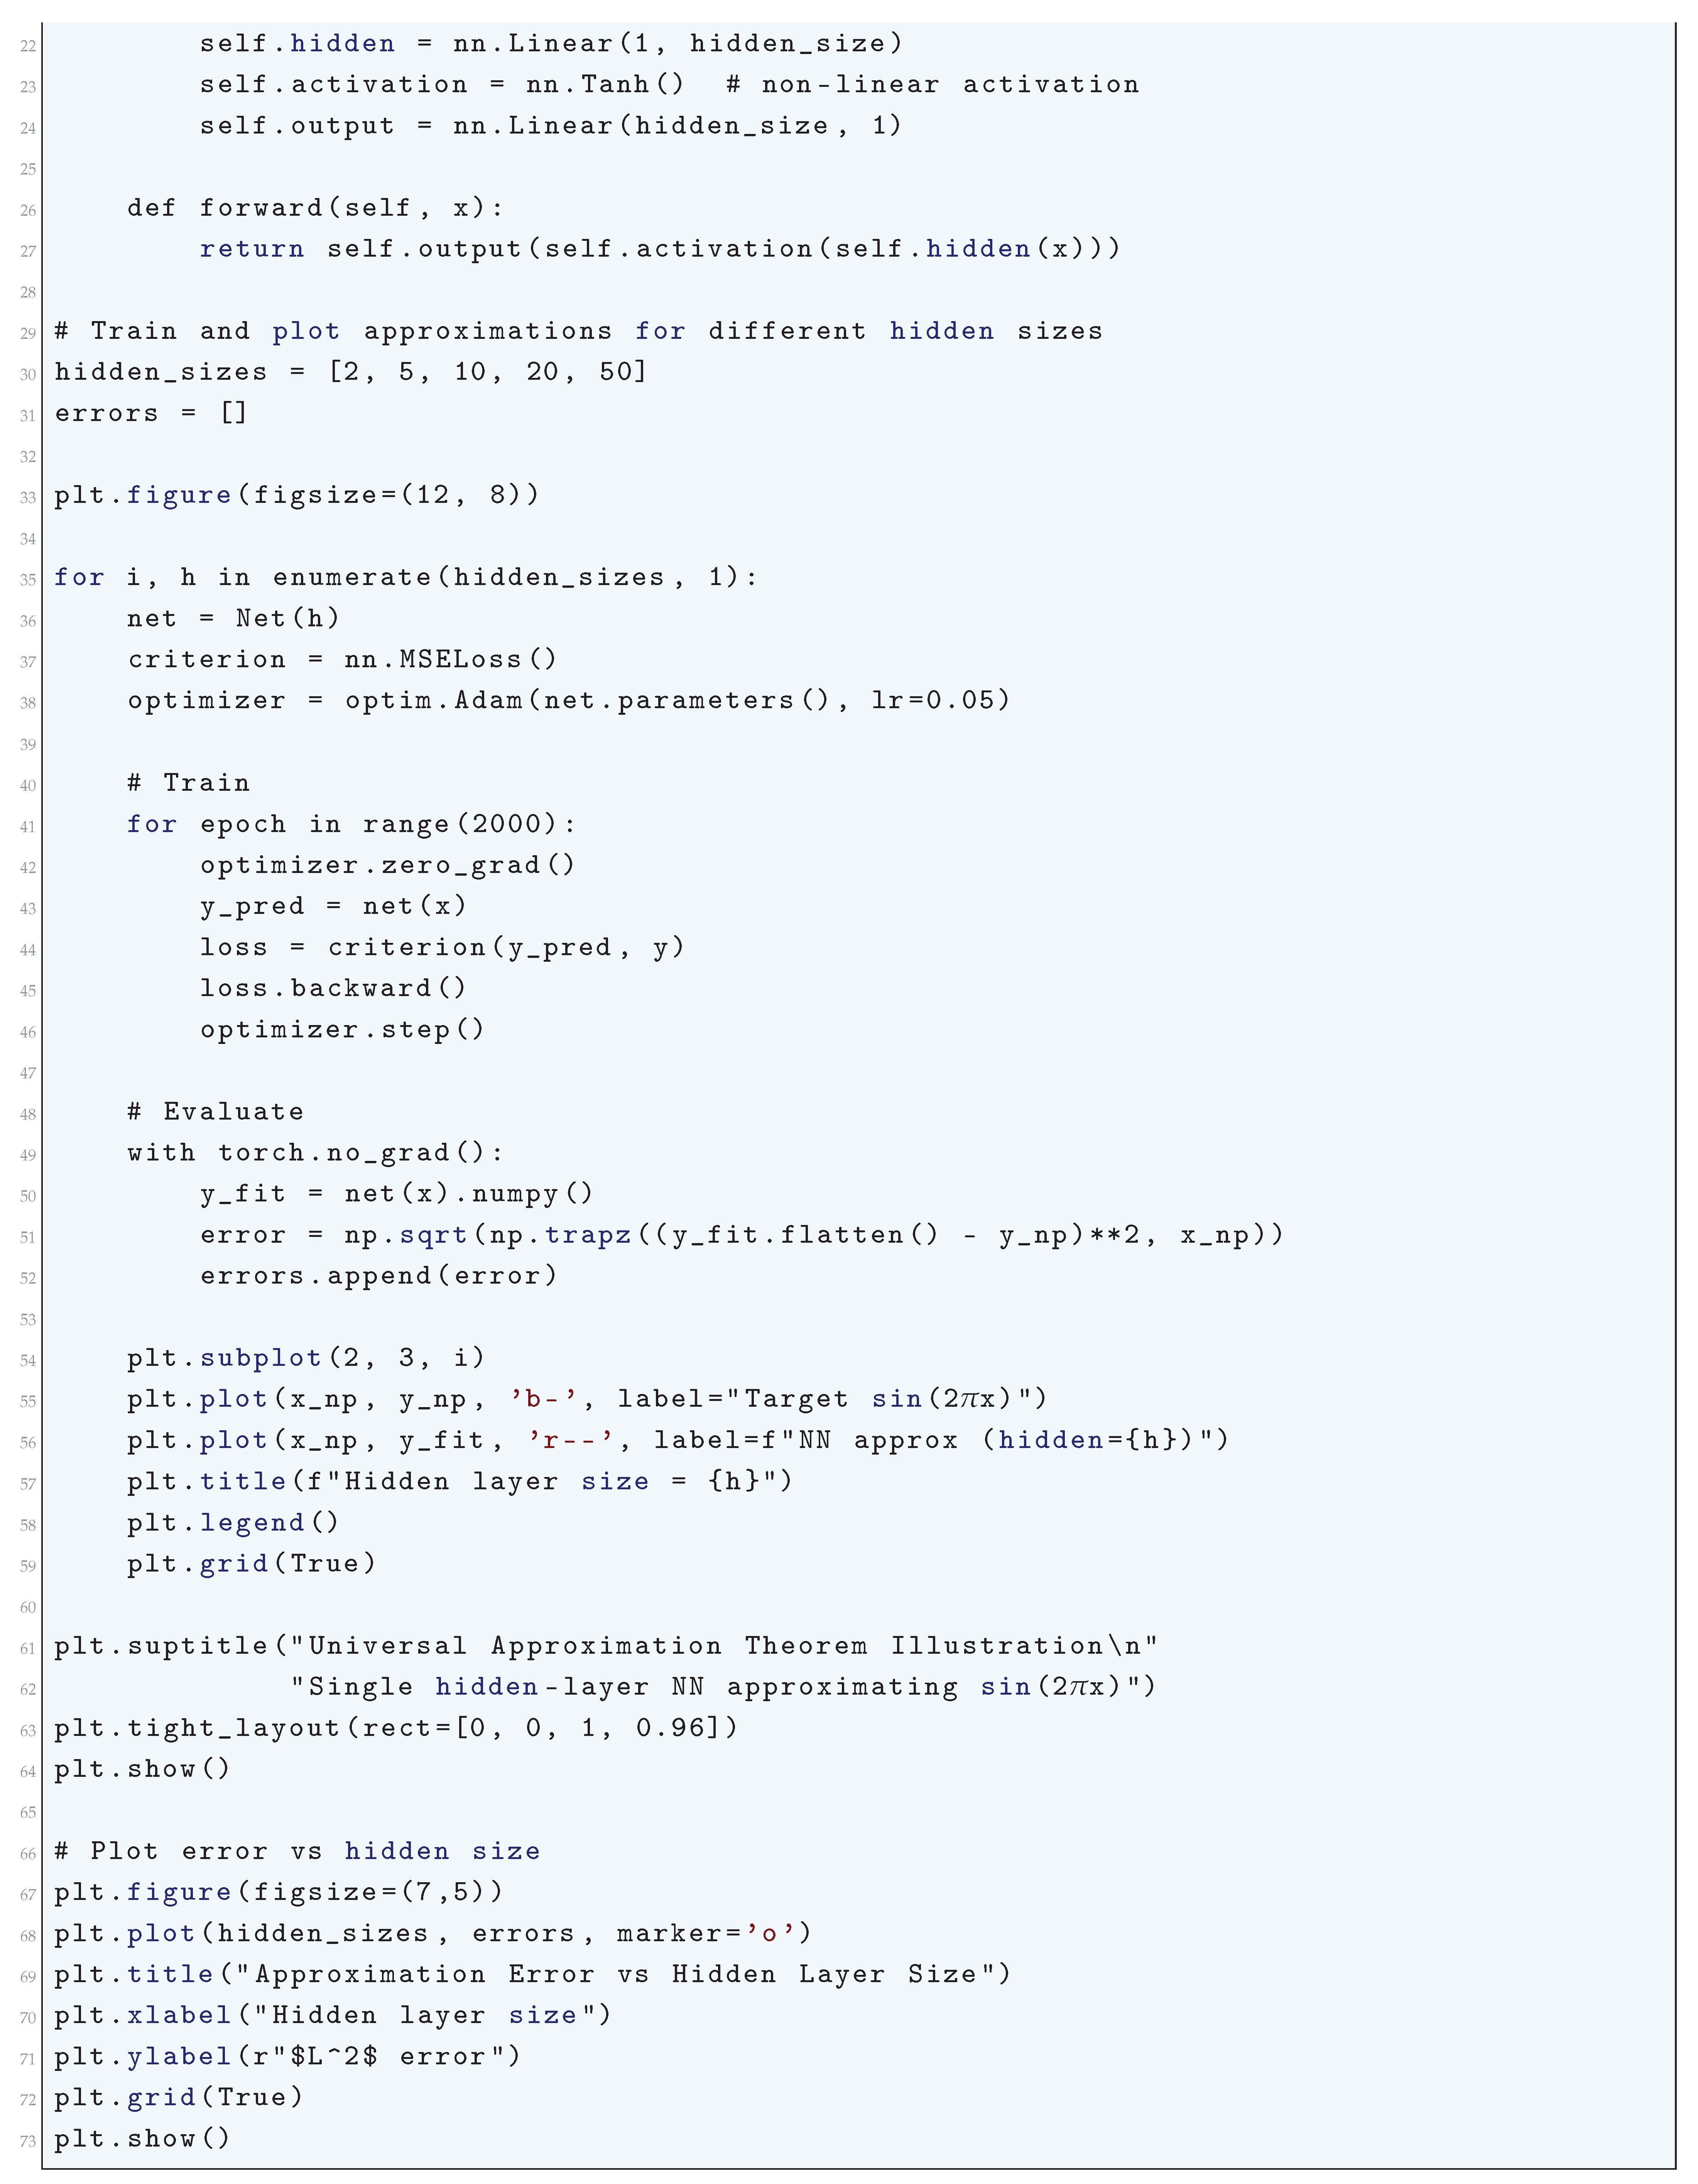
2.2.2. Stone-Weierstrass Application
2.2.2.1 Literature Review of Stone-Weierstrass Application
Rudin (1976) [70] introduced the Weierstrass approximation theorem and proves its generalization, the Stone-Weierstrass theorem. He also discussed the algebraic structure of function spaces and how the theorem ensures the uniform approximation of continuous functions by polynomials. He also presented examples and exercises related to compactness, uniform convergence, and Banach algebra structures. Stein and Shakarchi (2005) [71] extended the Stone-Weierstrass theorem into measure theory and functional analysis. He also proved the theorem in the context of Lebesgue integration. He also discussed how it applies to Hilbert spaces and orthogonal polynomials. He also connected the theorem to Fourier analysis and spectral decomposition. Conway (2019) [73] explored the Stone-Weierstrass theorem in the setting of Banach algebras and C-algebras*. He also extended the theorem to non-commutative function algebras and discussed the operator-theoretic implications of the theorem in Hilbert spaces. He also analyzed the theorem’s application to spectral theory. Dieudonné (1981) [74] traced the historical development of functional analysis, including the origins of the Stone-Weierstrass theorem and discussed contributions by Karl Weierstrass and Marshall Stone. He also explored how the theorem influenced topological vector spaces and operator theory and also included perspectives on the axiomatic development of function approximation. Folland (1999) [76] discussed the Stone-Weierstrass theorem in depth with applications to probability theory and ergodic theory and used the theorem to establish the density of algebraic functions in measure spaces He also connected the Stone-Weierstrass theorem to functional approximation in Lp spaces. He also explored the interplay between the Stone-Weierstrass theorem and the Hahn-Banach theorem. Sugiura (2024) [77] extended the Stone-Weierstrass theorem to the study of reservoir computing in machine learning and proved that certain neural networks can approximate functions uniformly under the assumptions of the theorem. He bridges classical functional approximation with modern AI and deep learning. Liu et al. (2024) [78] investigated the Stone-Weierstrass theorem in normed module settings and used category theory to generalize function approximation results. He also extended the theorem beyond real-valued functions to structured mathematical objects. Martinez-Barreto (2025) [79] provided a modern formulation of the theorem with rigorous proof and reviewed applications in operator algebras and topology. He also discussed open problems related to function approximation. Chang and Wei (2024) [80] used the Stone-Weierstrass theorem to derive new operator inequalities and applied the theorem to functional analysis in quantum mechanics. Caballer et al. (2024) [81] investigated cases where the Stone-Weierstrass theorem fails and provided counterexamples and refined conditions for uniform approximation. Chen (2024) [82] extended the Stone-Weierstrass theorem to generalized function spaces and introduced a new class of uniform topological algebras. Rafiei and Akbarzadeh-T (2024) [83] used the Stone-Weierstrass theorem to analyze function approximation in fuzzy logic systems and explored the applications in control systems and AI.
2.2.2.2 Analysis of Stone-Weierstrass Application
The Stone-Weierstrass Theorem serves as a cornerstone in functional analysis, bridging the algebraic structure of continuous functions with approximation theory. This theorem, when applied to the Universal Approximation Theorem (UAT), provides a rigorous foundation for asserting that neural networks can approximate any continuous function defined on a compact set. To understand this connection in its most scientifically and mathematically rigorous form, we must carefully analyze the algebra of continuous functions on a compact Hausdorff space and the role of neural networks in approximating these functions, ensuring that all mathematical nuances are explored with extreme precision. Let X be a compact Hausdorff space, and let represent the space of continuous real-valued functions on X. The supremum norm for a function is defined as:
This supremum norm is critical in defining the proximity between continuous functions, as we seek to approximate any function by a function g from a subalgebra .
The Stone-Weierstrass theorem guarantees that if the subalgebra A satisfies two essential properties—(1) it contains the constant functions, and (2) it separates points—then the closure of A in the supremum norm will be the entire space . To formalize this, we define the point separation property as follows: for every pair of distinct points , there exists a function such that . This condition ensures that functions from A are sufficiently “rich” to distinguish between different points in X. Mathematically, this is expressed as:
Given these two properties, the Stone-Weierstrass theorem asserts that for any continuous function and any , there exists an element such that:
This result ensures that any continuous function on a compact Hausdorff space can be approximated arbitrarily closely by functions from a sufficiently rich subalgebra. In the context of the Universal Approximation Theorem (UAT), we seek to apply the Stone-Weierstrass theorem to the approximation capabilities of neural networks. Let be a compact subset, and let be a continuous function defined on this set. A feedforward neural network with a non-linear activation function has the form:
where represents the inner product between the weight vector and the input x, and represents the bias term. The activation function is typically non-linear (such as the sigmoid or ReLU function), and the parameters are the weights and biases of the network. The function is a weighted sum of the non-linear activations applied to the affine transformations of x.
We now explore the connection between neural networks and the Stone-Weierstrass theorem. A critical observation is that the set of functions defined by a neural network with non-linear activation is a subalgebra of provided the activation function is sufficiently rich in its non-linearity.
This non-linearity ensures that the network can separate points in K, meaning that for any two distinct points , there exists a network function that takes distinct values at these points. This satisfies the point separation condition required by the Stone-Weierstrass theorem. To formalize this, consider two distinct points . Since is non-linear, the function with appropriately chosen weights and biases will satisfy:
Thus, the algebra of neural network functions satisfies the point separation property. By applying the Stone-Weierstrass theorem, we conclude that this algebra is dense in , meaning that for any continuous function and any , there exists a neural network function such that:
This rigorous result shows that neural networks with a non-linear activation function can approximate any continuous function on a compact set arbitrarily closely in the supremum norm, thereby proving the Universal Approximation Theorem. To further explore this, consider the error term:
For a given function f and a compact set K, this error term can be made arbitrarily small by increasing the number of neurons in the hidden layer of the neural network. This increases the capacity of the network, effectively enlarging the subalgebra of functions generated by the network, thereby improving the approximation. As the number of neurons increases, the network’s ability to approximate any function from becomes increasingly precise, which aligns with the conclusion of the Stone-Weierstrass theorem that the network functions form a dense subalgebra in . Thus, the Universal Approximation Theorem, derived through the Stone-Weierstrass theorem, rigorously proves that neural networks can approximate any continuous function on a compact set to any desired degree of accuracy. The combination of the non-linearity of the activation function and the architecture of the neural network guarantees that the network can generate a dense subalgebra of continuous functions, ultimately allowing it to approximate any function from . This result not only formalizes the approximation power of neural networks but also provides a deep theoretical foundation for understanding their capabilities as universal approximators.
2.2.2.3 Python Code to Generate Figure 17, Figure 18 and Figure 19
The Python code below produces the Figure 17, Figure 18 and Figure 19 illustrating the Stone-Weierstrass Application.
Figure 17.
Stone–Weierstrass (Weierstrass) demo: Bernstein polynomial approximations
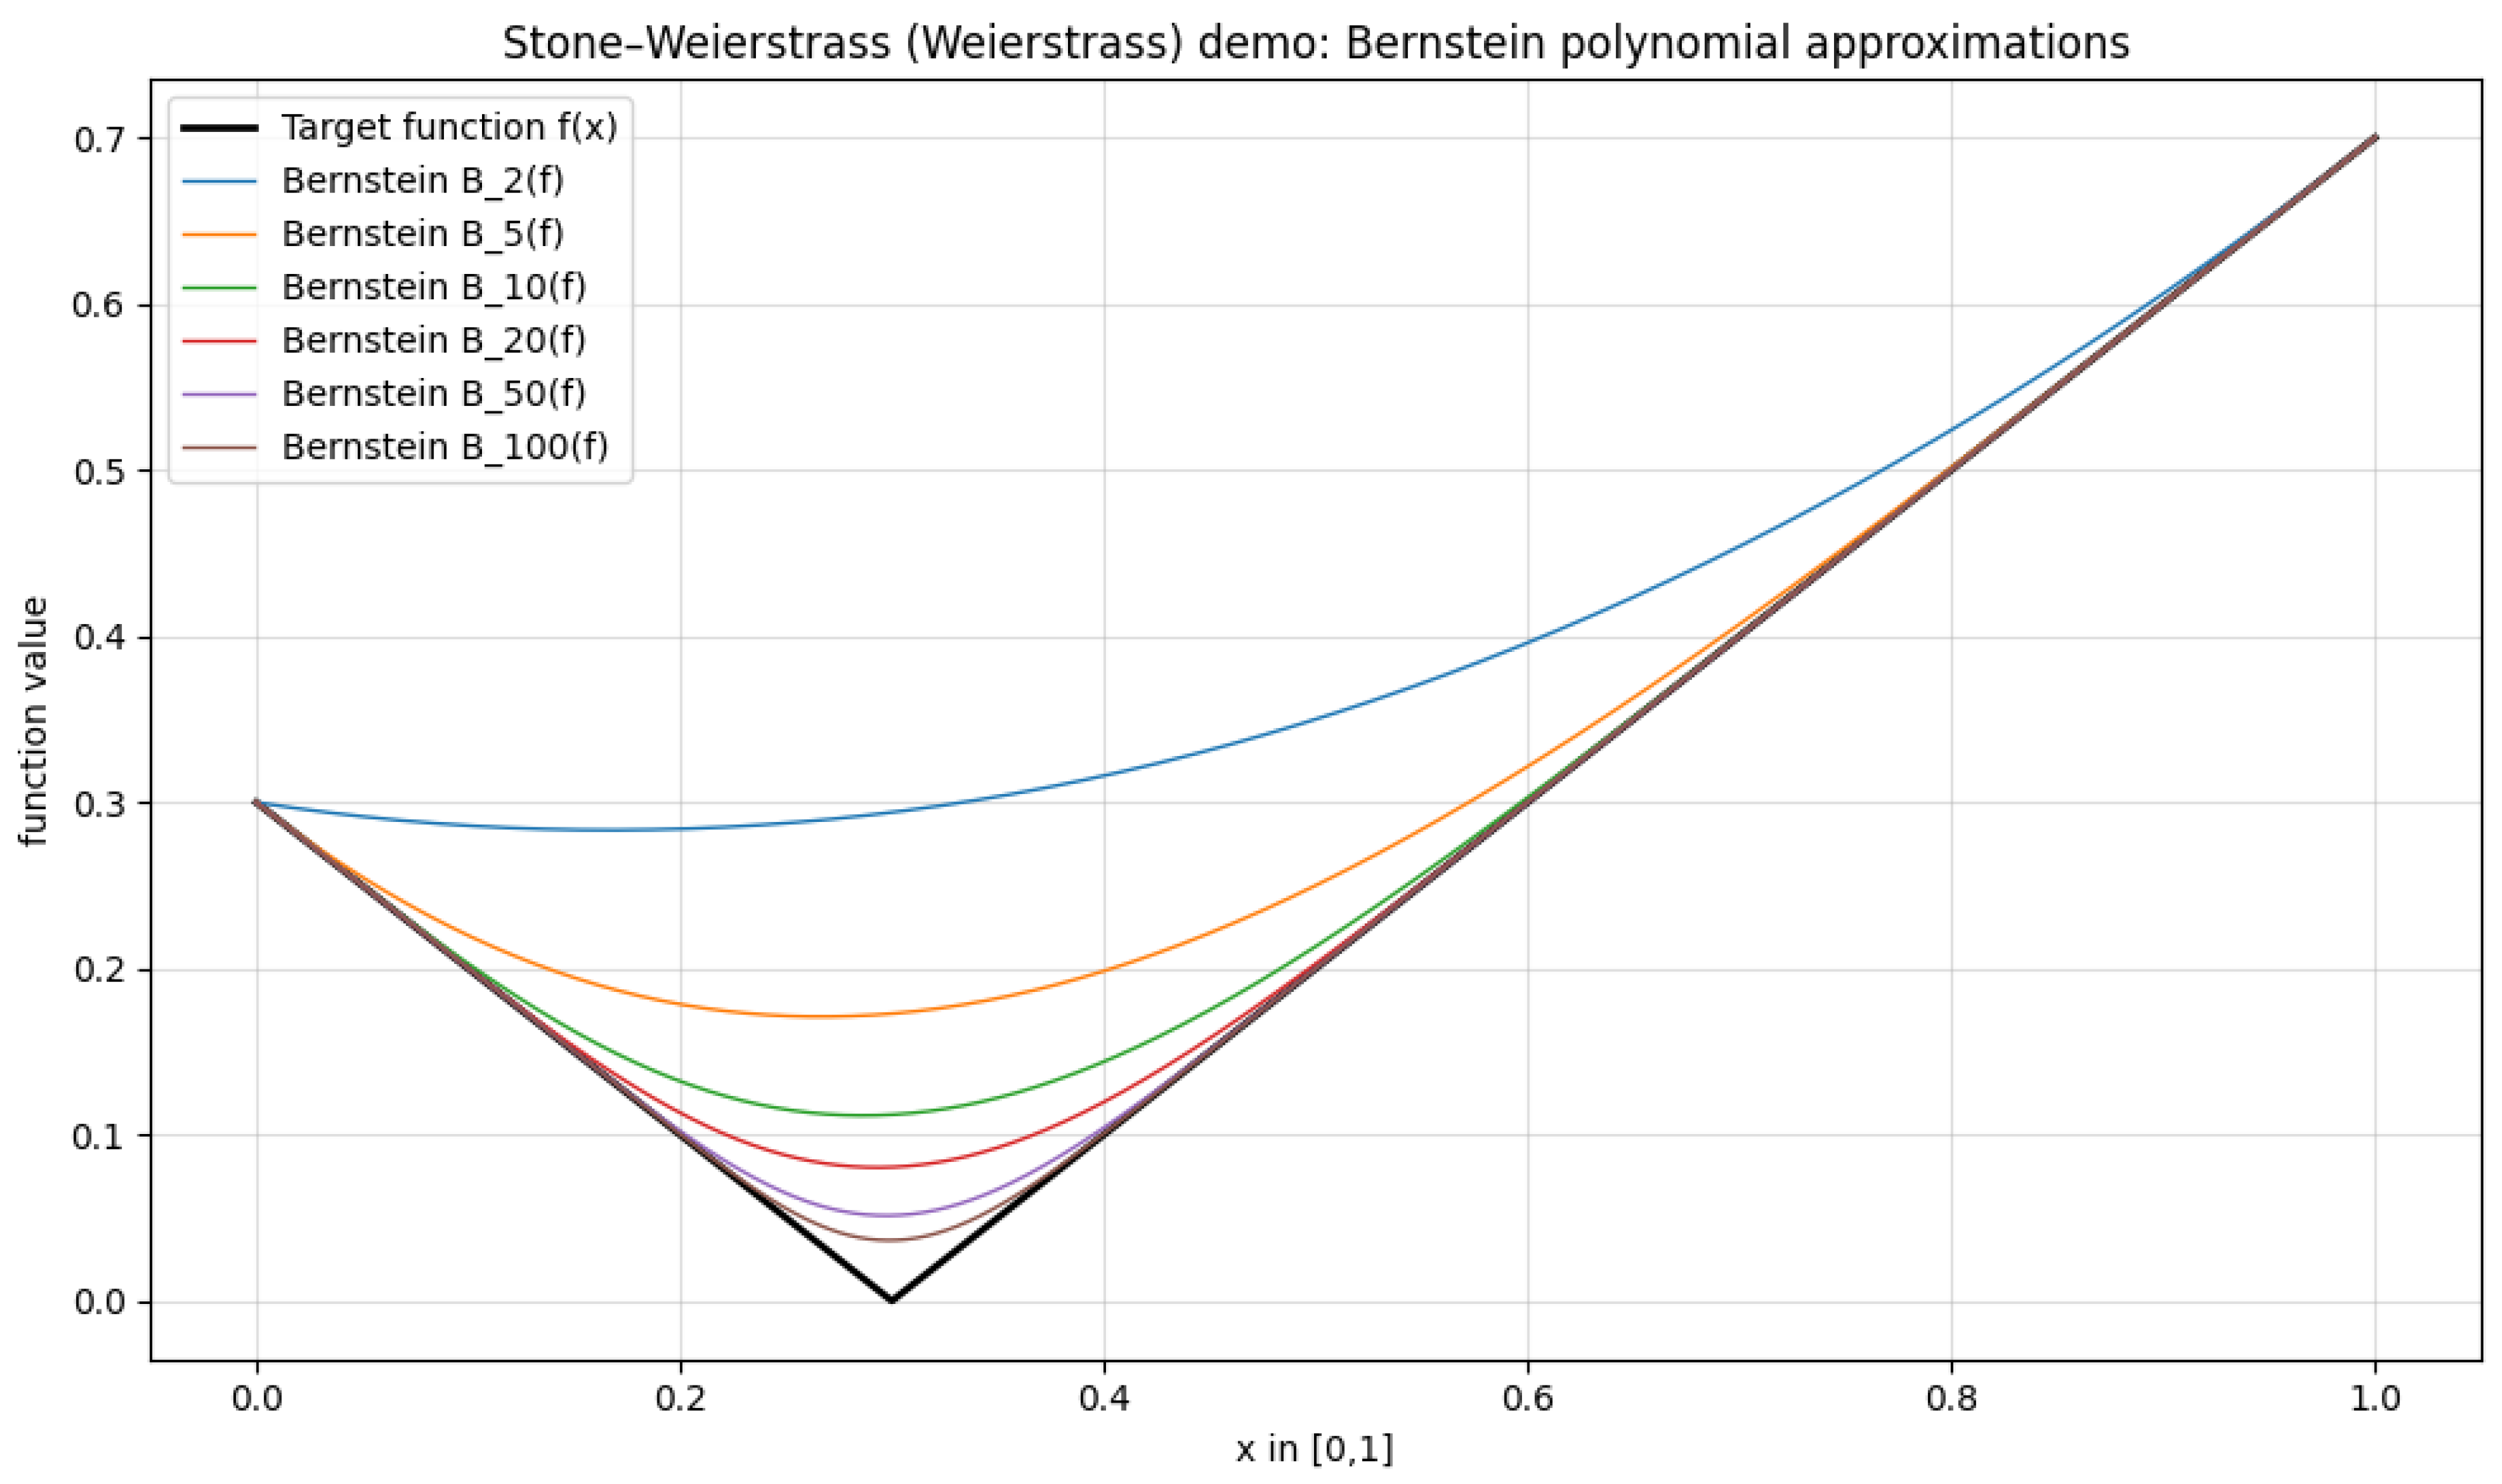
Figure 18.
Zoom near the kink — convergence is uniform
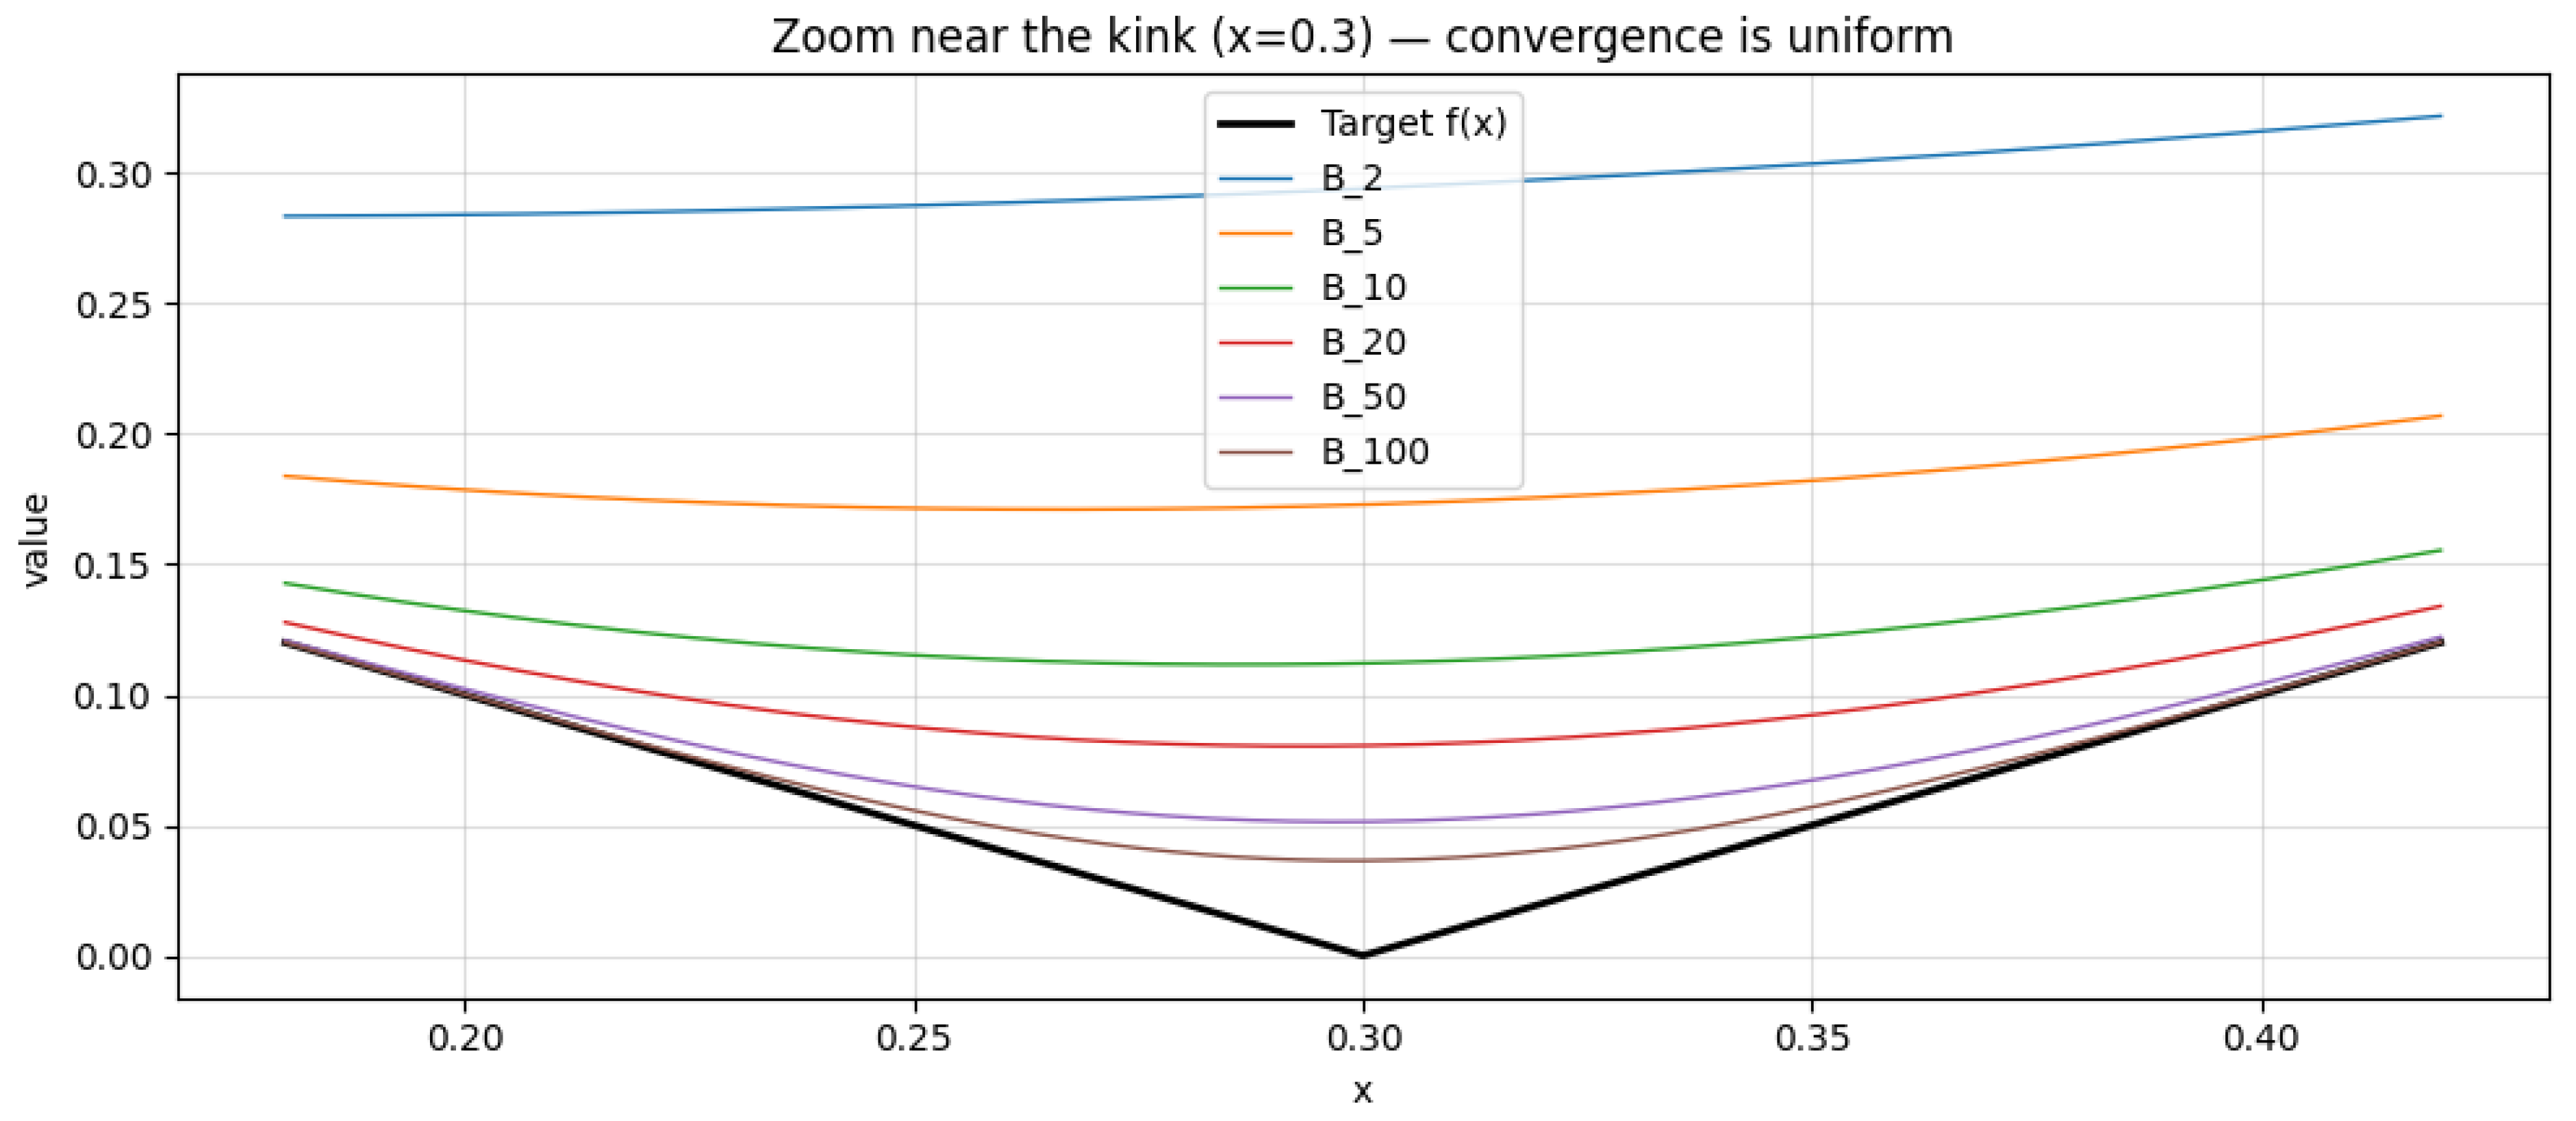
Figure 19.
Sup-norm error (log-log scale)
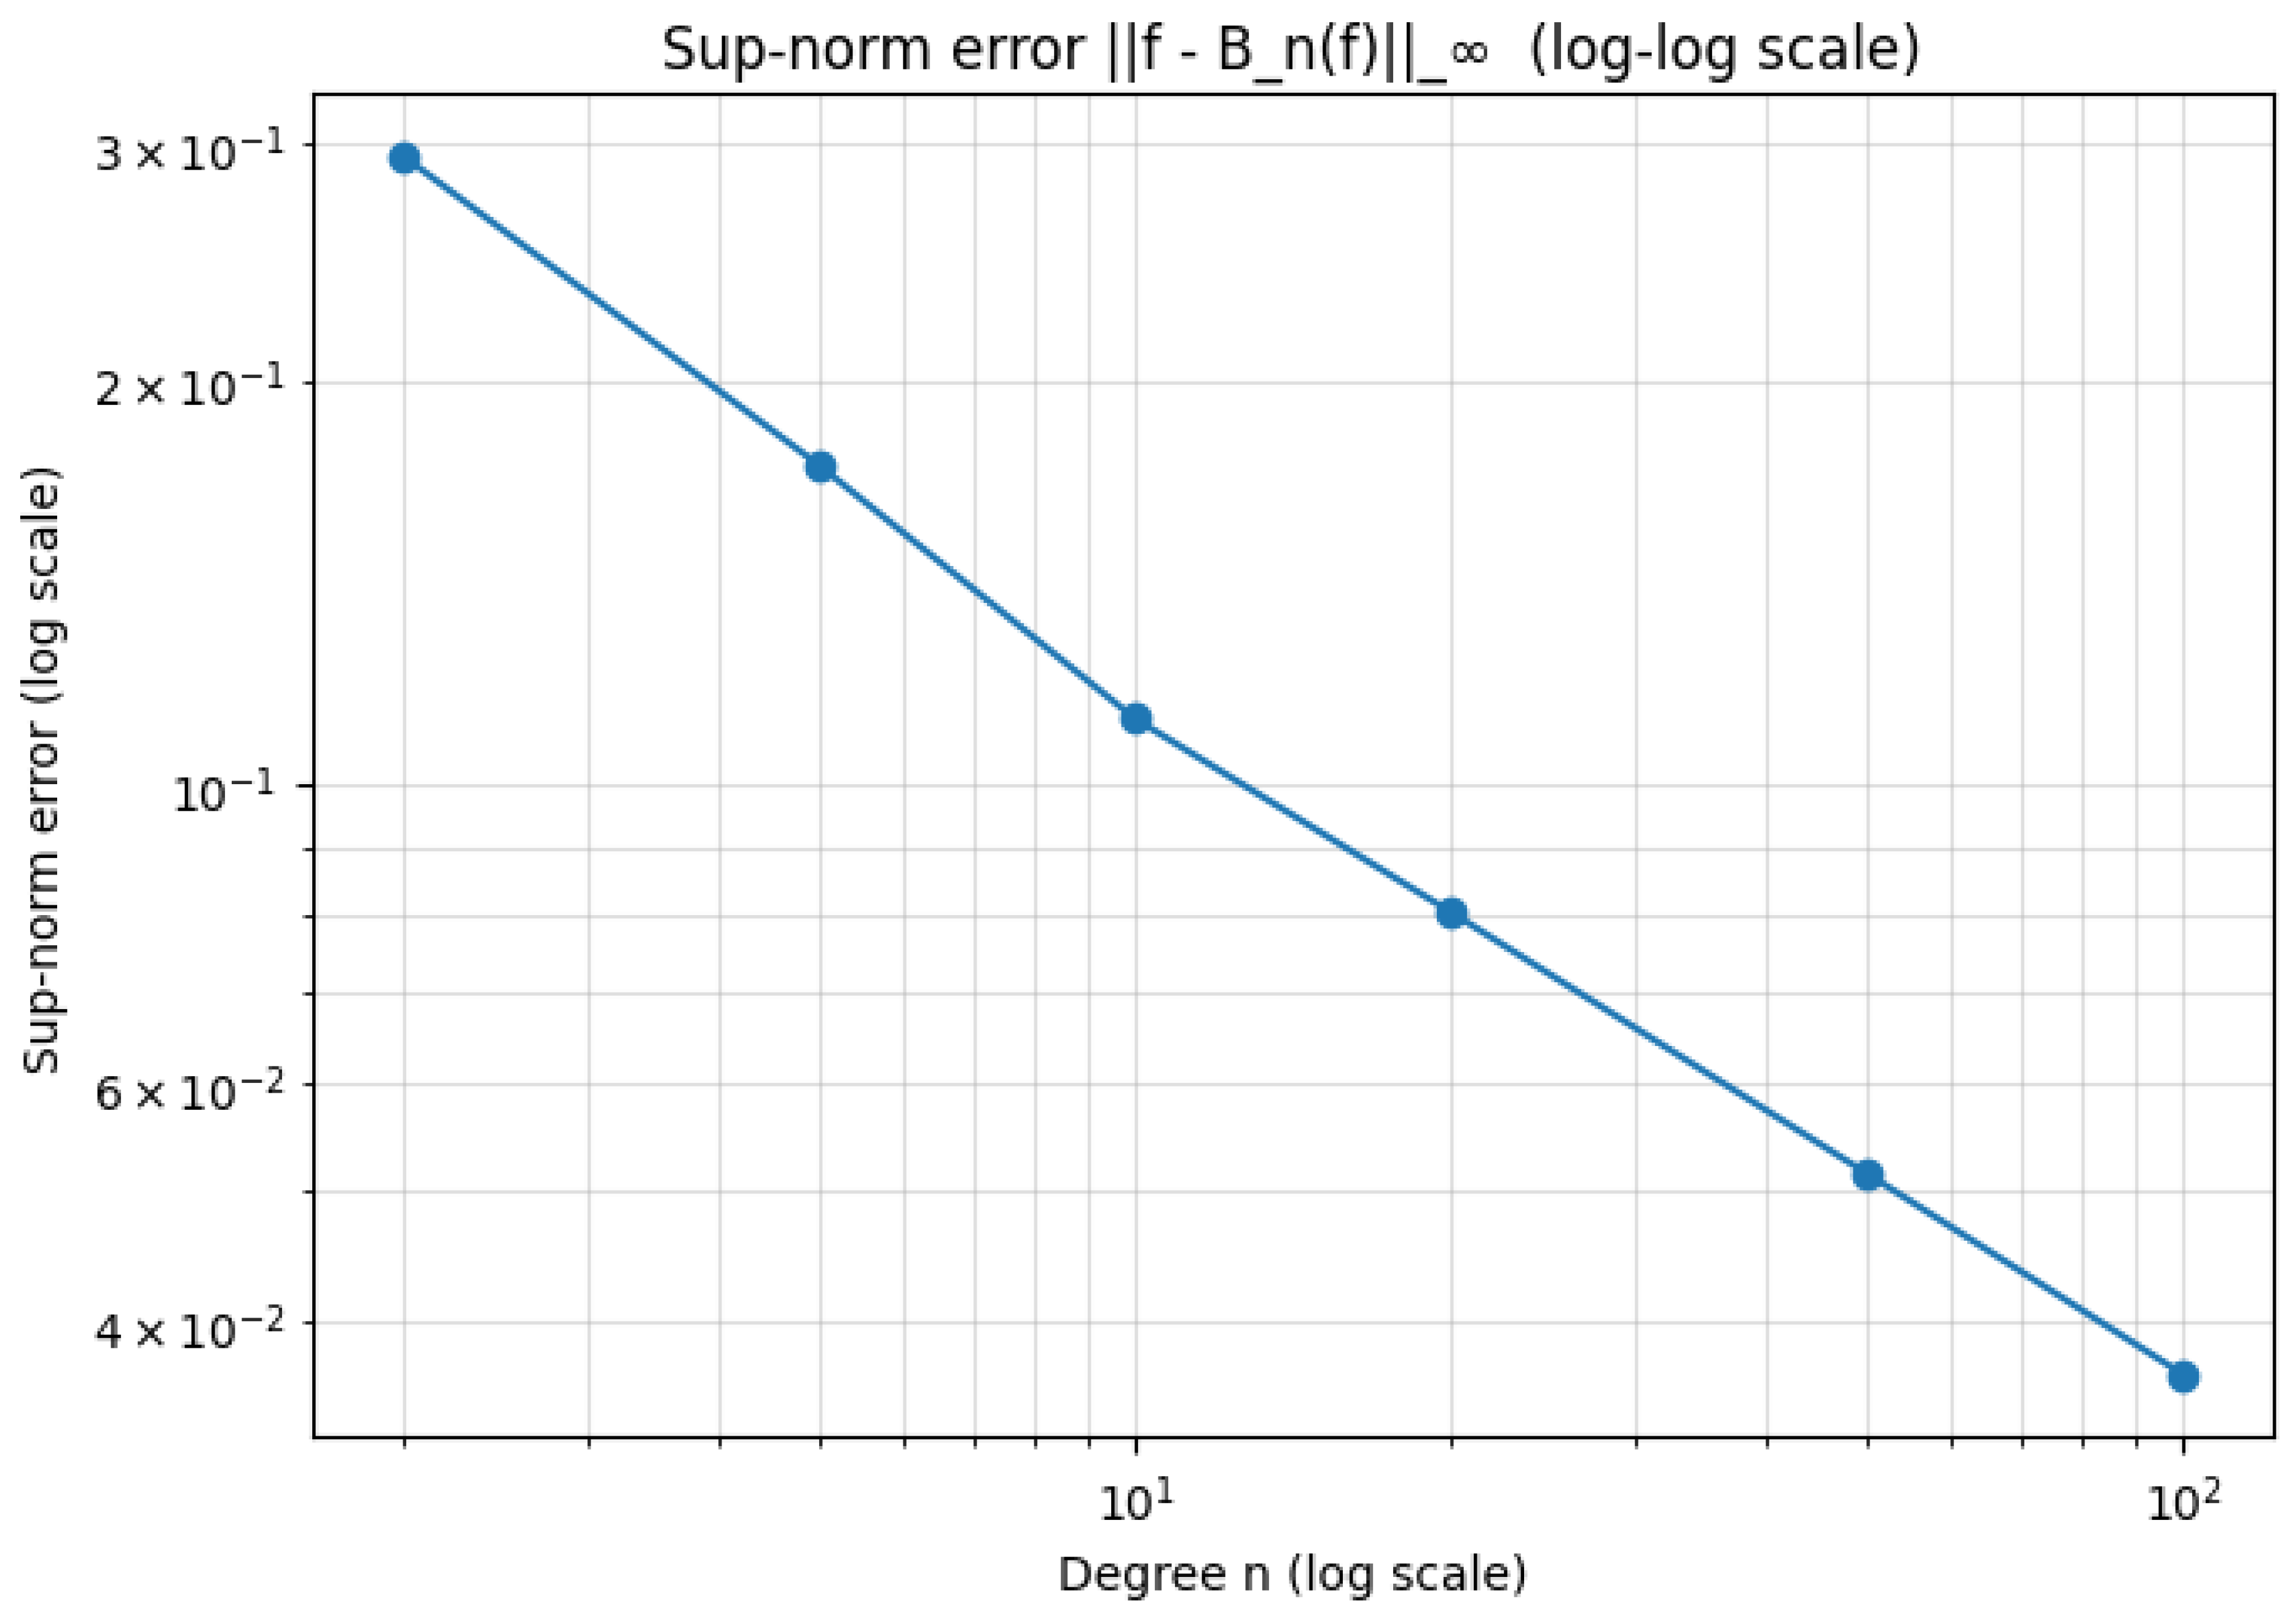
2.3. Depth vs. Width: Capacity Analysis
2.3.1. Bounding the Expressive Power
The Kolmogorov-Arnold Superposition Theorem is a foundational result in the mathematical analysis of multivariate continuous functions and their decompositions, providing a framework that underpins the expressive power of neural networks. It asserts that any continuous multivariate function can be expressed as a finite composition of continuous univariate functions and addition. It was first conjectured by Andrey Kolmogorov in 1956 and later rigorously proved by Vladimir Arnold in 1957. Formally, the theorem guarantees that any continuous multivariate function can be represented as a finite composition of continuous univariate functions and . Specifically, for , there exist functions and , such that
where the functions encode the univariate projections of the input variables , and the outer functions aggregate these projections into the final output. This decomposition highlights a fundamental property of multivariate continuous functions: their expressiveness can be captured through hierarchical compositions of simpler, univariate components.
2.3.1.1 Literature Review of Kolmogorov-Arnold Superposition Theorem
There are some Classical References on the Kolmogorov-Arnold Superposition Theorem (KST). Kolmogorov (1957) [84] in his Foundational Paper on KST established that any continuous function of several variables can be represented as a superposition of continuous functions of a single variable and addition. This was groundbreaking because it provided a universal function decomposition method, independent of inner-product spaces. He proved that there exist functions and such that any function can be expressed as:
where the are univariate functions. Kolmogorov provided a mathematical basis for approximation theory and neural networks, influencing modern machine learning architectures. Arnold (1963) [86] refined Kolmogorov’s theorem by proving that one can restrict the superposition to functions of at most two variables instead of one. Arnold’s formulation led to the Kolmogorov-Arnold representation:
making the theorem more suitable for practical computations. Arnold strengthened the expressivity of neural networks, inspiring alternative function representations in high-dimensional settings. Lorentz (2008) [87] in his book discusses the significance of KST in approximation theory and constructive mathematics. He provided error estimates for approximating multivariate functions using Kolmogorov-type decompositions. He showed how KST fits within Bernstein approximation theory. He helped frame KST in the context of function approximation, bridging it to computational applications. Building on this theoretical foundation, Hornik et. al. (1989) [58] demonstrated that multilayer feedforward networks are universal approximators, meaning that neural networks with a single hidden layer can approximate any continuous function. This work bridged the gap between the Kolmogorov-Arnold theorem and practical neural network design, providing a rigorous justification for the use of deep architectures. Pinkus (1999) [62] analyzed the role of KST in multilayer perceptrons (MLPs), showing how it influences function expressibility in neural networks. He demonstrated that feedforward neural networks can approximate arbitrary functions using Kolmogorov superposition. He also provided bounds on network depth and width required for universal approximation. He played a crucial role in understanding the theoretical power of deep learning. In more recent years, Montúfar, Pascanu, Cho, and Bengio (2014) [458] explored the expressive power of deep neural networks by analyzing the number of linear regions they can represent. Their work provided a modern perspective on the Kolmogorov-Arnold theorem, showing how depth enhances the ability of networks to model complex functions. Schmidt-Hieber (2020) [459] rigorously analyzed the approximation properties of deep ReLU networks, demonstrating their efficiency in approximating high-dimensional functions and further connecting the Kolmogorov-Arnold theorem to modern deep learning practices. Yarotsky (2017) [460] complemented this by providing explicit error bounds for approximating functions using deep ReLU networks, offering insights into how depth and activation functions influence approximation accuracy. Telgarsky (2016) [461] contributed to this body of work by rigorously proving that deeper networks can represent functions more efficiently than shallow ones, aligning with the hierarchical decomposition suggested by the Kolmogorov-Arnold theorem. This work provided theoretical insights into why depth is crucial in modern neural networks. Ghosh and Bhattacharya (2022) [328] propose a nested hierarchy of second-order upper bounds, , on the system failure probability of coherent binary systems, showing that the classical Kounias-Vanmarcke-Hunter-Ditlevsen (KVHD) bound is the weakest member of this hierarchy (); they rigorously prove the monotonic non-increasing nature of with respect to m and establish conditions for its strict improvement, providing a more accurate and conservative framework for reliability-based decision-making. Lu et. al. (2017) [462] explored the expressive power of neural networks from the perspective of width rather than depth, showing how width can also play a critical role in function approximation. This complemented the Kolmogorov-Arnold theorem by offering a more nuanced understanding of network design. Finally, Zhang et. al. (2021) [463] provided a rigorous analysis of how deep learning models generalize, which is closely related to their ability to approximate complex functions. While not directly about the Kolmogorov-Arnold theorem, their work contextualized these theoretical insights within the broader framework of generalization in deep learning, offering practical implications for the design and training of neural networks.
There are several very recent contributions in the Kolmogorov-Arnold Superposition Theorem (KST) (2024–2025). Guilhoto and Perdikaris (2024) [88] explored how KST can be reformulated using deep learning architectures. They proposed Kolmogorov-Arnold Networks (KANs), a new type of neural network inspired by KST. They showed that KANs outperform traditional feedforward networks in function approximation tasks. They also provided empirical evidence of KAN efficiency in real-world datasets. They also introduced a new paradigm in machine learning, making function decomposition more interpretable. Alhafiz, M. R. et al. (2025) [89] applied KST-based networks to turbulence modeling in fluid mechanics. They demonstrated how KANs improve predictive accuracy for Navier-Stokes turbulence models. They showed a reduction in computational complexity compared to classical turbulence models. They also developed a data-driven turbulence modeling framework leveraging KST. They advanced machine learning applications in computational fluid dynamics (CFD). Lorencin, I. et al. (2024) [90] used KST-inspired neural networks for predicting propulsion system parameters in ships. They implemented KANs to model hybrid ship propulsion (Combined Diesel-Electric and Gas - CODLAG) and demonstrated a highly accurate prediction model for propulsion efficiency. They also provided a new benchmark dataset for ship propulsion research. They extended KST applications to naval engineering & autonomous systems.
| Paper | Main Contribution | Impact |
| Kolmogorov (1957) | Original KST theorem | Laid foundation for function decomposition |
| Arnold (1963) | Refinement using 2-variable functions | Made KST more practical for computation |
| Lorentz (2008) | KST in approximation theory | Linked KST to function approximation errors |
| Pinkus (1999) | KST in neural networks | Theoretical basis for deep learning |
| Perdikaris (2024) | Deep learning reinterpretation | Proposed Kolmogorov-Arnold Networks |
| Alhafiz (2025) | KST-based turbulence modeling | Improved CFD simulations |
| Lorencin (2024) | KST in naval propulsion | Optimized ship energy efficiency |
2.3.1.2 Analysis of Kolmogorov-Arnold Superposition Theorem
In the context of neural networks, this result establishes the theoretical universality of function approximation. A neural network with a single hidden layer approximates a function by representing it as
where W is the width of the hidden layer, is a nonlinear activation function, are weights, are biases, and are output weights. The expressive power of such shallow networks depends critically on the width W, as the universal approximation theorem ensures that suffices to approximate any continuous function arbitrarily well. However, for a fixed approximation error , the required width grows exponentially with the input dimension n, satisfying a lower bound of
where C depends on the function’s Lipschitz constant. This exponential dependence, sometimes called the "curse of dimensionality," underscores the inefficiency of shallow architectures in capturing high-dimensional dependencies.
The advantage of depth becomes apparent when we consider deep neural networks, which utilize hierarchical representations. A deep network with D layers and width W per layer constructs a function as a composition of layer-wise transformations:
where denotes the output of the k-th layer, is the weight matrix, is the bias vector, and is the nonlinear activation. The final output of the network is then given by
The depth D of the network allows it to approximate hierarchical compositions of functions. For example, if a target function has a compositional structure
where each is a simple function, the depth D directly corresponds to the number of nested transformations. This compositional hierarchy enables deep networks to approximate functions efficiently, achieving a reduction in the required parameter count. The approximation error for a deep network decreases polynomially with D, satisfying
which is exponentially more efficient than the error scaling for shallow networks. In light of the Kolmogorov-Arnold theorem, the decomposition
demonstrates how deep networks align naturally with the structure of multivariate functions. The inner functions capture local dependencies, while the outer functions aggregate these into a global representation. This layered decomposition mirrors the depth-based structure of neural networks, where each layer learns a specific aspect of the function’s complexity. Finally, the parameter count in a deep network with D layers and width W per layer is given by
whereas a shallow network requires
parameters for the same approximation accuracy. This exponential difference in parameter count illustrates the superior efficiency of deep architectures, particularly for high-dimensional functions. By leveraging the hierarchical decomposition inherent in the Kolmogorov-Arnold theorem, deep networks achieve expressive power that scales favorably with both dimension and complexity.
2.3.1.3 Python Code to Generate Figure 20
The Python code below produces the Figure 20 illustrating the Kolmogorov-Arnold Superposition Theorem.
Figure 20.
Kolmogorov-Arnold Superposition Theorem (Toy Example)
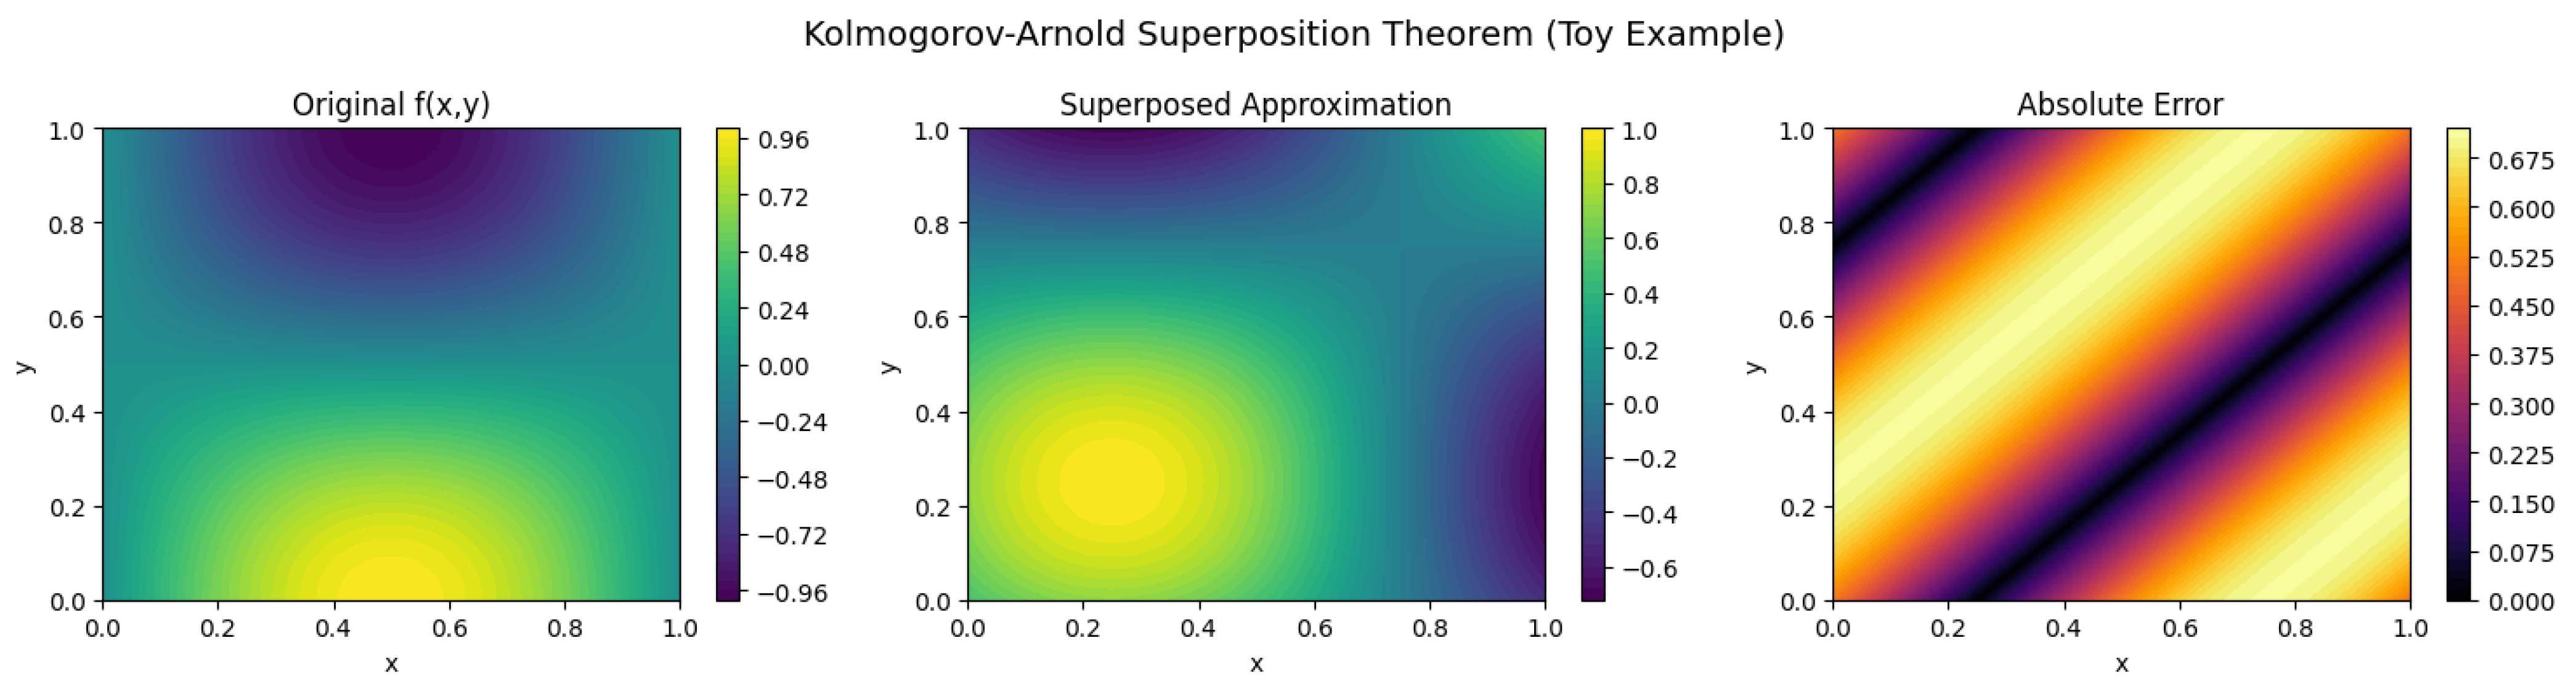
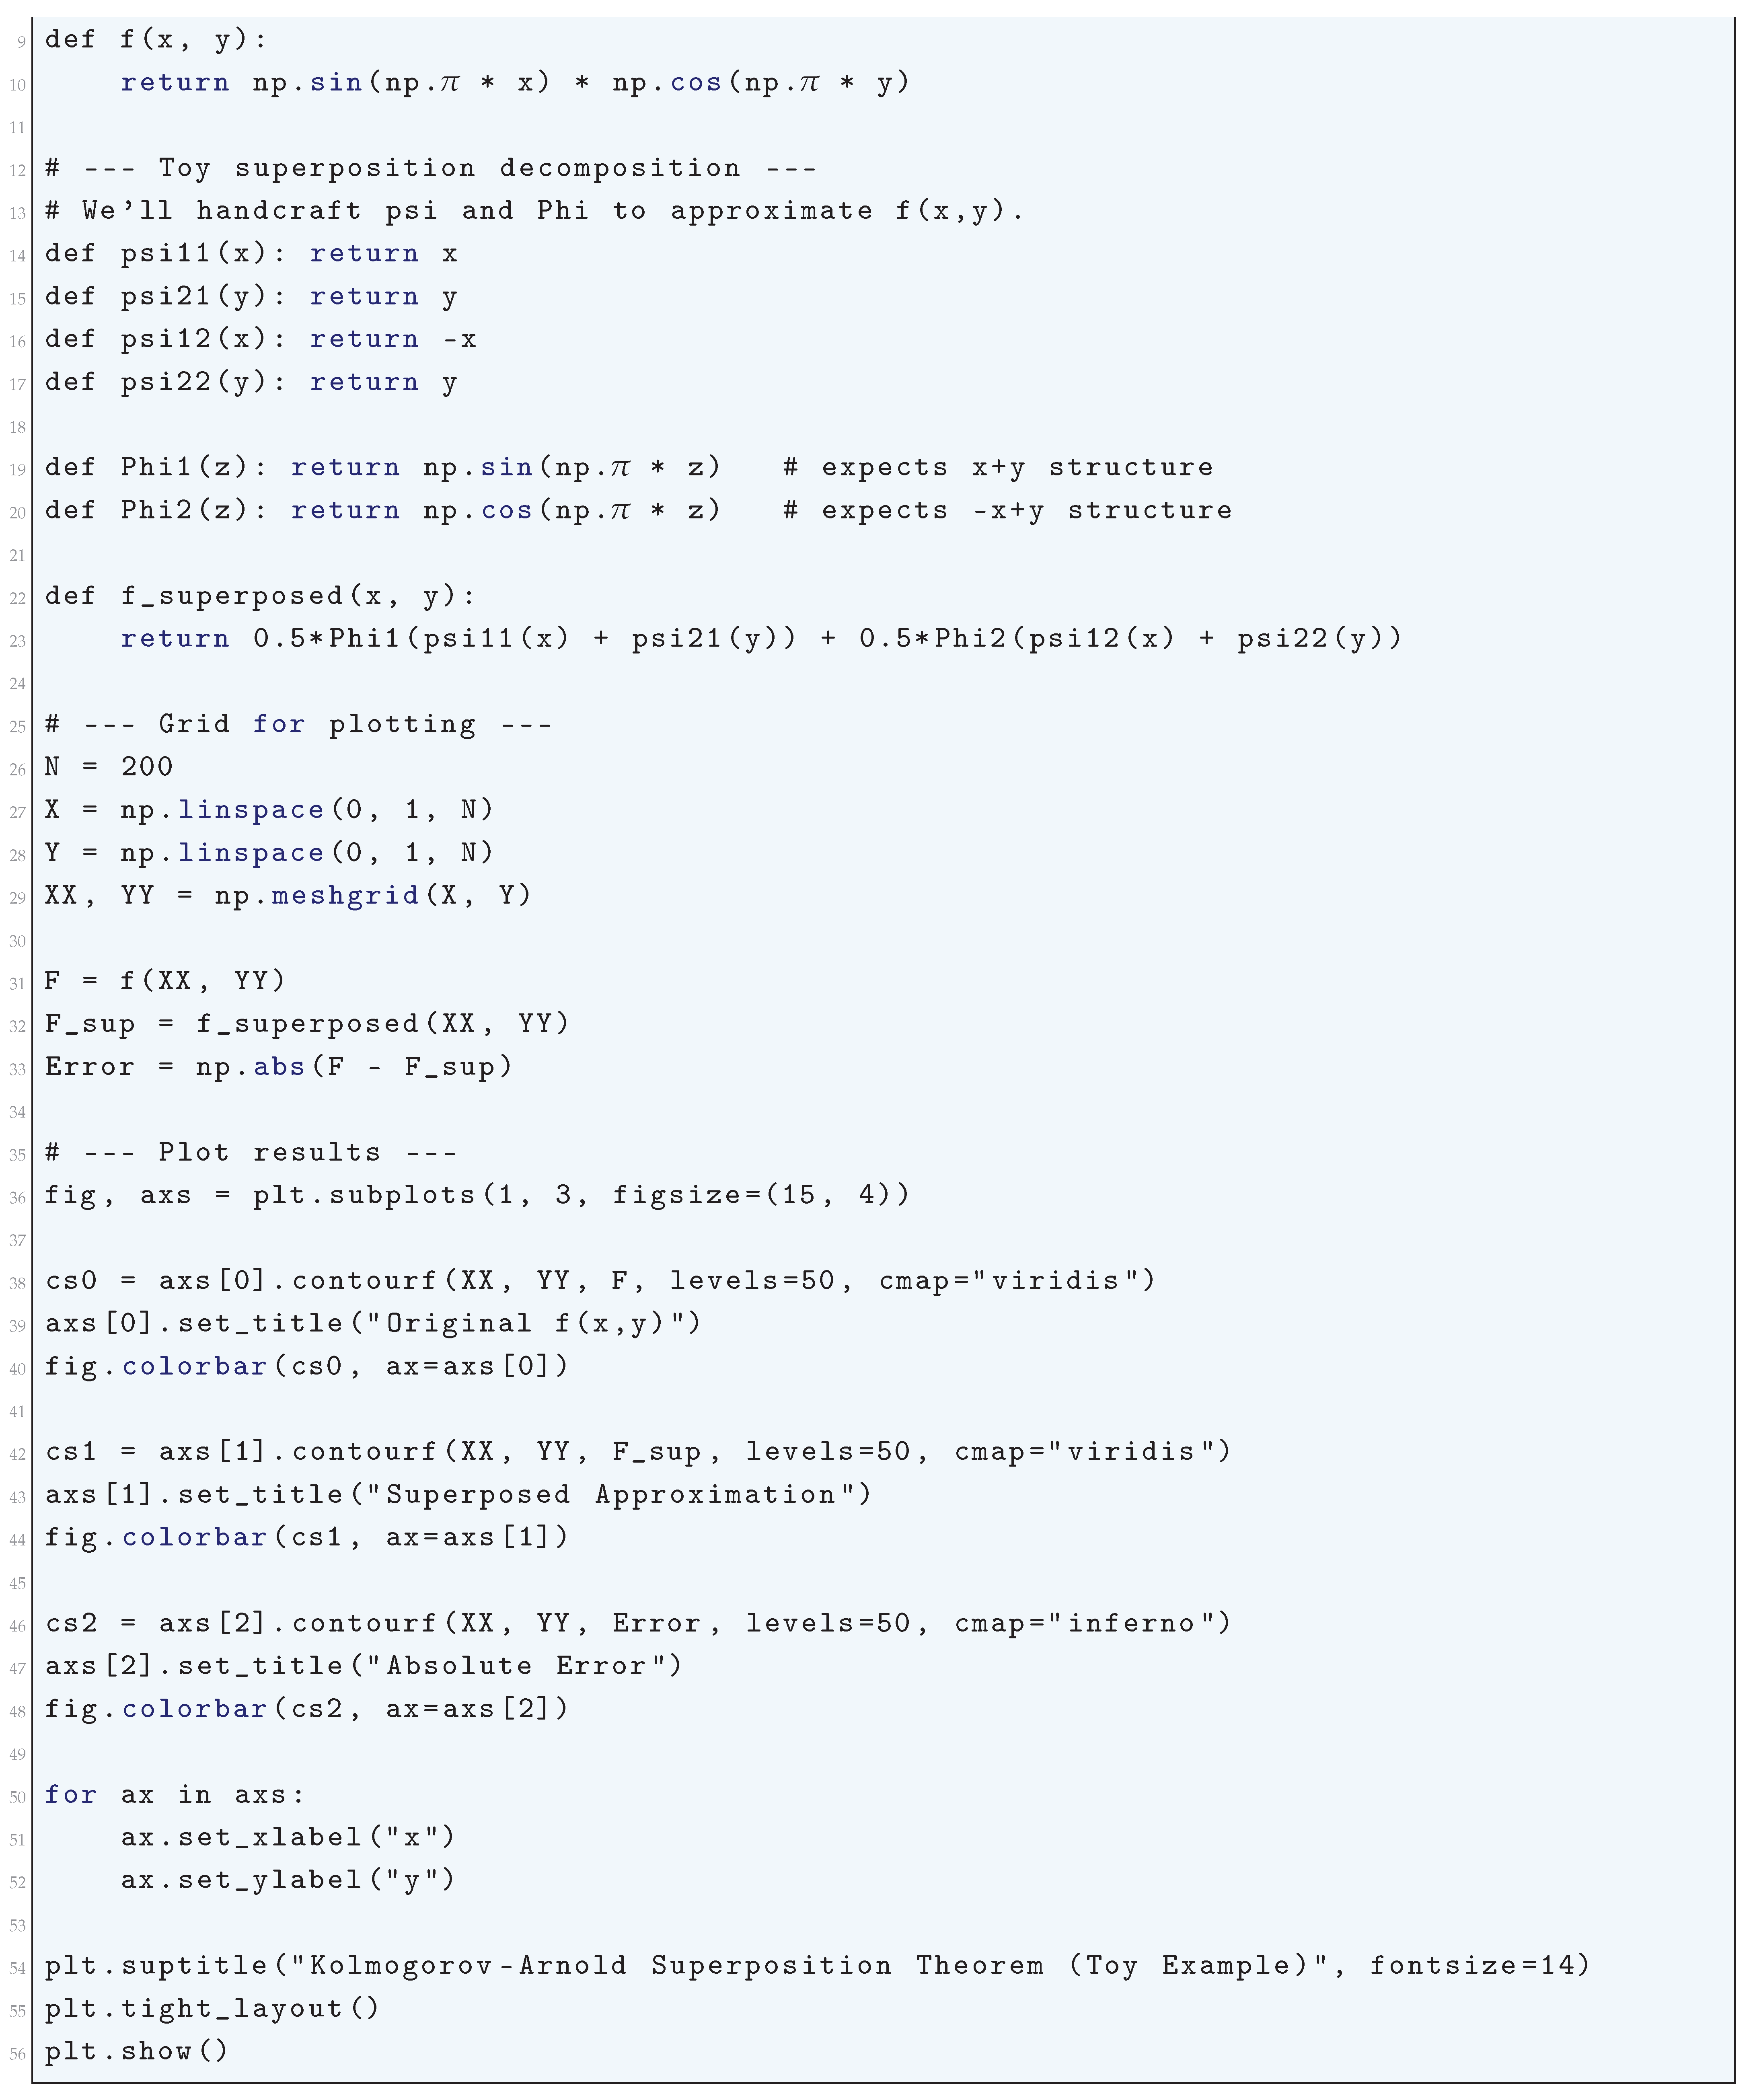
2.3.2. Fourier Analysis of Expressivity
2.3.2.1 Literature Review of Fourier Analysis of Expressivity
Juárez-Osorio et. al. (2024) [227] applied Fourier analysis to design quantum convolutional neural networks (QCNNs) for time series forecasting. The Fourier series decomposition helps analyze and optimize expressivity in quantum architectures, making QCNNs better at capturing periodic and non-periodic structures in data. Umeano and Kyriienko (2024) [228] introduced Fourier-based quantum feature maps that transform classical data into quantum states with enhanced expressivity. The Fourier transform plays a central role in mapping high-dimensional data efficiently while maintaining interpretability. Liu et. al. (2024) [229] extended Graph Convolutional Networks (GCNs) by integrating Fourier analysis and spectral wavelets to improve graph expressivity. It bridges the gap between frequency-domain analysis and graph embeddings, making GCNs more effective for complex data structures. Vlasic (2024) [230] presented a Fourier series-inspired feature mapping technique to encode classical data into quantum circuits. It demonstrates how Fourier coefficients can enhance the representational capacity of quantum models, leading to better compression and generalization. Kim et. al. (2024) [231] introduced Neural Fourier Modelling (NFM), a novel approach to representing time-series data compactly while preserving its expressivity. It outperforms traditional models like Short-Time Fourier Transform (STFT) in retaining long-term dependencies. Xie et. al. (2024) [232] explored how Fourier basis functions can be used to enhance the expressivity of tensor networks while maintaining computational efficiency. It establishes trade-offs between expressivity and model complexity in machine learning architectures. Liu et. al. (2024) [233] integrated spectral modulation and Fourier transforms into implicit neural representations for text-to-image synthesis. Fourier analysis improves global coherence while preserving local expressivity in generative models. Zhang (2024) [234] demonstrated how Fourier and Lock-in spectrum techniques can represent long-term variations in mechanical signals. The Fourier-based decomposition allows for more expressive representations of mechanical failures and degradation. Hamed and Lachiri (2024) [235] applied Fourier transformations to speech synthesis models, improving their ability to transfer expressive content from text to speech. Fourier series allows capturing prosody, rhythm, and tone variations effectively. Ghosh (2024) [989] presents a mathematically rigorous framework combining microstructural mechanics and continuum theory to analyze creep deformation, and derives constitutive models that integrate diffusion kinetics, dislocation dynamics, and grain-boundary behavior to predict time-dependent material deformation across diverse conditions. Ghosh (2023) [954] establishes the mathematical equivalence between the Galerkin Finite Element Method (FEM) formulation and the Central Difference formulation for the advection–diffusion equation, thereby providing a unified theoretical framework connecting finite element and finite difference time integration schemes. Ghosh (2023) [258] performs a detailed stability analysis of the second- and fourth-order Runge–Kutta methods, deriving and visualizing the corresponding stability regions in the complex plane, thereby providing deeper insight into the numerical stability characteristics of these widely used time integration schemes. Jahangiri (2022) [805] generalizes the classical open-top box optimization problem from rectangular bases to arbitrary polygons by identifying optimal corner cuts for regular and irregular prisms, and develops a new vertex-identification argument not found in prior literature. Lehmann et. al. (2024) [236] integrated Fourier-based deep learning models for seismic activity prediction. It explores the expressivity of Fourier Neural Operators (FNOs) in capturing wave propagations in different geological environments.
2.3.2.2 Analysis of Fourier Analysis of Expressivity
The Fourier analysis of expressivity in neural networks seeks to rigorously quantify how neural architectures, characterized by their depth and width, can approximate functions through the decomposition of those functions into their Fourier spectra. Consider a square-integrable function , for which the Fourier transform is defined as
where represents the frequency. The inverse Fourier transform reconstructs the function as
The magnitude reflects the energy contribution of the frequency to f.
Neural networks approximate f by capturing its Fourier spectrum, but the architecture fundamentally governs how efficiently this approximation can be achieved, especially in the presence of high-frequency components. For shallow networks with one hidden layer and a finite number of neurons, the universal approximation theorem establishes that
where is the activation function, are weights, are biases, and are coefficients. The Fourier transform of this representation can be expressed as
where denotes the Fourier transform of the activation function. For smooth activation functions like sigmoid or tanh, decays exponentially as , limiting the network’s ability to approximate functions with high-frequency content unless the width n is exceedingly large. Specifically, the Fourier coefficients decay as
where depends on the smoothness of . This restriction implies that shallow networks are biased toward low-frequency functions unless their width scales exponentially with the input dimension d. Deep networks, on the other hand, leverage their hierarchical structure to overcome these limitations. A deep network with L layers recursively composes functions, producing an output of the form
where is the activation function at layer l, are weight matrices, and are bias vectors. The Fourier transform of this composition can be analyzed iteratively. If represents the output of the l-th layer, then
where * denotes convolution and is the Fourier transform of the activation function. The recursive application of this convolution amplifies high-frequency components, enabling deep networks to approximate functions whose Fourier spectra exhibit polynomial decay. Specifically, the Fourier coefficients of a deep network decay as
where depends on the activation function. This is in stark contrast to the exponential decay observed in shallow networks.
The activation function plays a pivotal role in shaping the Fourier spectrum of neural networks. For example, the rectified linear unit (ReLU) introduces significant high-frequency components into the network. The Fourier transform of the ReLU activation is given by
which decays more slowly than the Fourier transforms of smooth activations. Consequently, ReLU-based networks are particularly effective at approximating functions with oscillatory behavior. To illustrate, consider the function
A shallow network requires an exponentially large number of neurons to approximate f when is large, but a deep network can achieve the same approximation with polynomially fewer parameters by leveraging its hierarchical structure.
The expressivity of deep networks can be further quantified by considering their ability to approximate bandlimited functions, i.e., functions f whose Fourier spectra are supported on . For a shallow network with width n, the required number of neurons scales as
where d is the input dimension. In contrast, for a deep network with depth L, the width scales as
reflecting the exponential efficiency of depth in distributing the approximation of frequency components across layers. For example, if with , a deep network requires significantly fewer parameters than a shallow network to approximate f to the same accuracy.
A neural network with an input and output can be expressed as a sum of nonlinearly transformed weighted combinations of the input. Mathematically, this can be written as
where is the activation function, are the weight vectors, are the biases, and are the output weights. To understand the spectral properties of , it is necessary to analyze the Fourier transform of the activation function , as the network output consists of a superposition of such transformed functions. The Fourier transform of is given by
Substituting the definition of , we obtain
The key term in this expression is the Fourier transform of the activation function , which we denote as
The decay rate of determines the extent to which different frequency components are retained in the Fourier spectrum of the neural network. If is a smooth function, then decays rapidly for large , implying that high-frequency components are suppressed. If is piecewise continuous or non-differentiable at some points, the decay rate of is slower, allowing the network to capture higher frequencies. To quantify the decay properties of the Fourier transform of an activation function, consider the case of the ReLU activation function, defined as
Its Fourier transform is given by
which exhibits a power-law decay. In contrast, the sigmoid activation function
has a Fourier transform that decays exponentially,
This strong decay implies that networks with sigmoid activation functions are biased toward learning only low-frequency components. Similarly, the hyperbolic tangent activation function also exhibits an exponential spectral decay. For a more general class of activation functions, the decay rate of can be estimated as
for some constants , implying that the function is a strong low-pass filter. If is piecewise smooth but non-differentiable at certain points (such as ReLU), then the Fourier transform satisfies a power-law decay
for some . A particularly interesting case arises when the activation function is sinusoidal, such as , for which the Fourier transform does not decay at all. The implications of these spectral properties become evident in the training dynamics of neural networks. When using gradient descent, the evolution of the Fourier coefficients of over time follows
where is an effective learning rate for each frequency. The decay behavior of influences , meaning that activation functions with strong spectral decay impose a bottleneck on the learning of high-frequency components. From a function approximation perspective, the spectral characteristics of the activation function determine the types of functions that can be efficiently represented by a neural network. Smooth activation functions lead to approximations that are predominantly low-frequency, whereas activation functions with slower Fourier decay allow the network to approximate functions with higher-frequency content. Thus, the activation function fundamentally shapes the Fourier spectrum of neural networks, controlling the network’s ability to represent and learn different frequency components.
| Activation Function | Fourier Decay Rate | Effect on Frequency Learning |
| Sigmoid | (Exponential) | Strong low-pass filter, retains only low frequencies |
| Tanh | (Exponential) | Strong low-pass filter, smooth approximations |
| ReLU | (Power-law) | Allows moderate frequency learning |
| Leaky ReLU | (Power-law) | Similar to ReLU with slightly improved high-frequency retention |
| Sinusoidal | No decay | Captures all frequencies, highly oscillatory functions |
This table summarizes the spectral characteristics of various activation functions and their impact on frequency learning in neural networks.
In summary, the Fourier analysis of expressivity rigorously demonstrates the superiority of deep networks over shallow ones in approximating complex functions. Depth introduces a hierarchical compositional structure that enables the efficient representation of high-frequency components, while width provides a rich basis for approximating the function’s Fourier spectrum. Together, these properties explain the remarkable capacity of deep neural networks to approximate functions with intricate spectral structures, offering a mathematically rigorous foundation for understanding their expressivity.
2.3.2.3 Python Code to Generate Figure 21 and Figure 22
The Python code below produces the Figure 21 and Figure 22 illustrating Target vs NN approximation (real space) and the Fourier Spectrum: Expressivity Analysis.
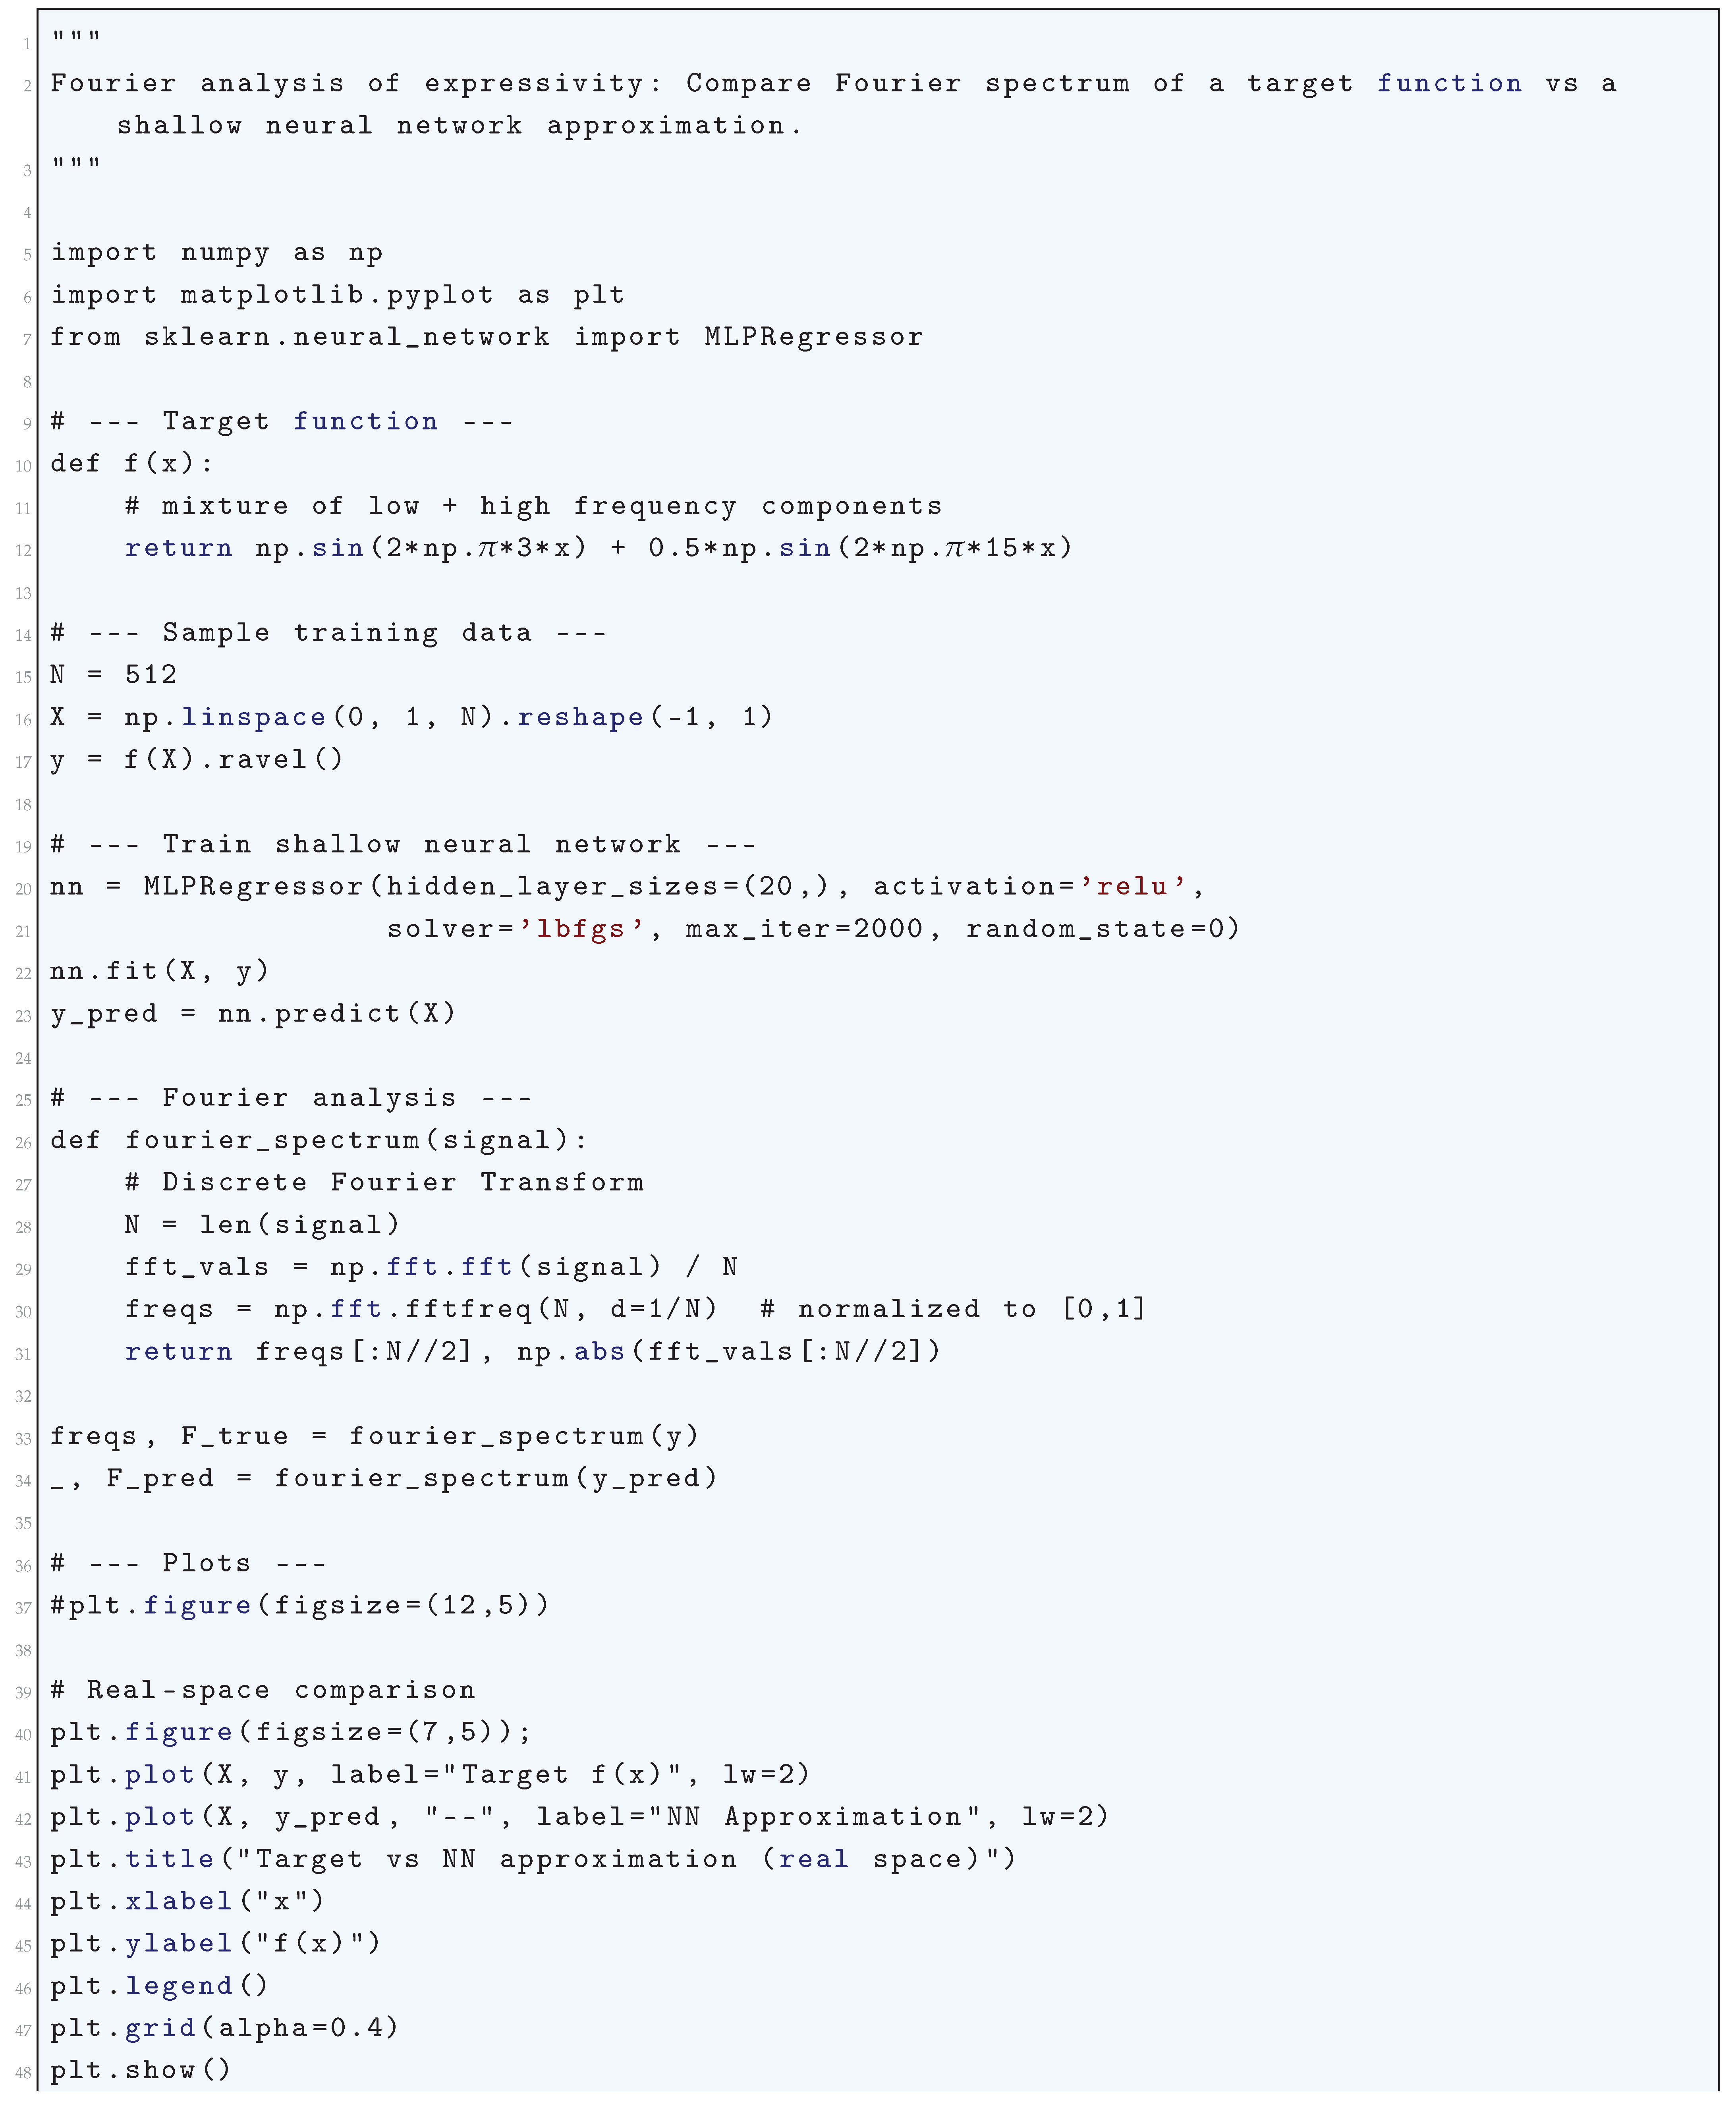
Figure 21.
Target vs NN approximation (real space)
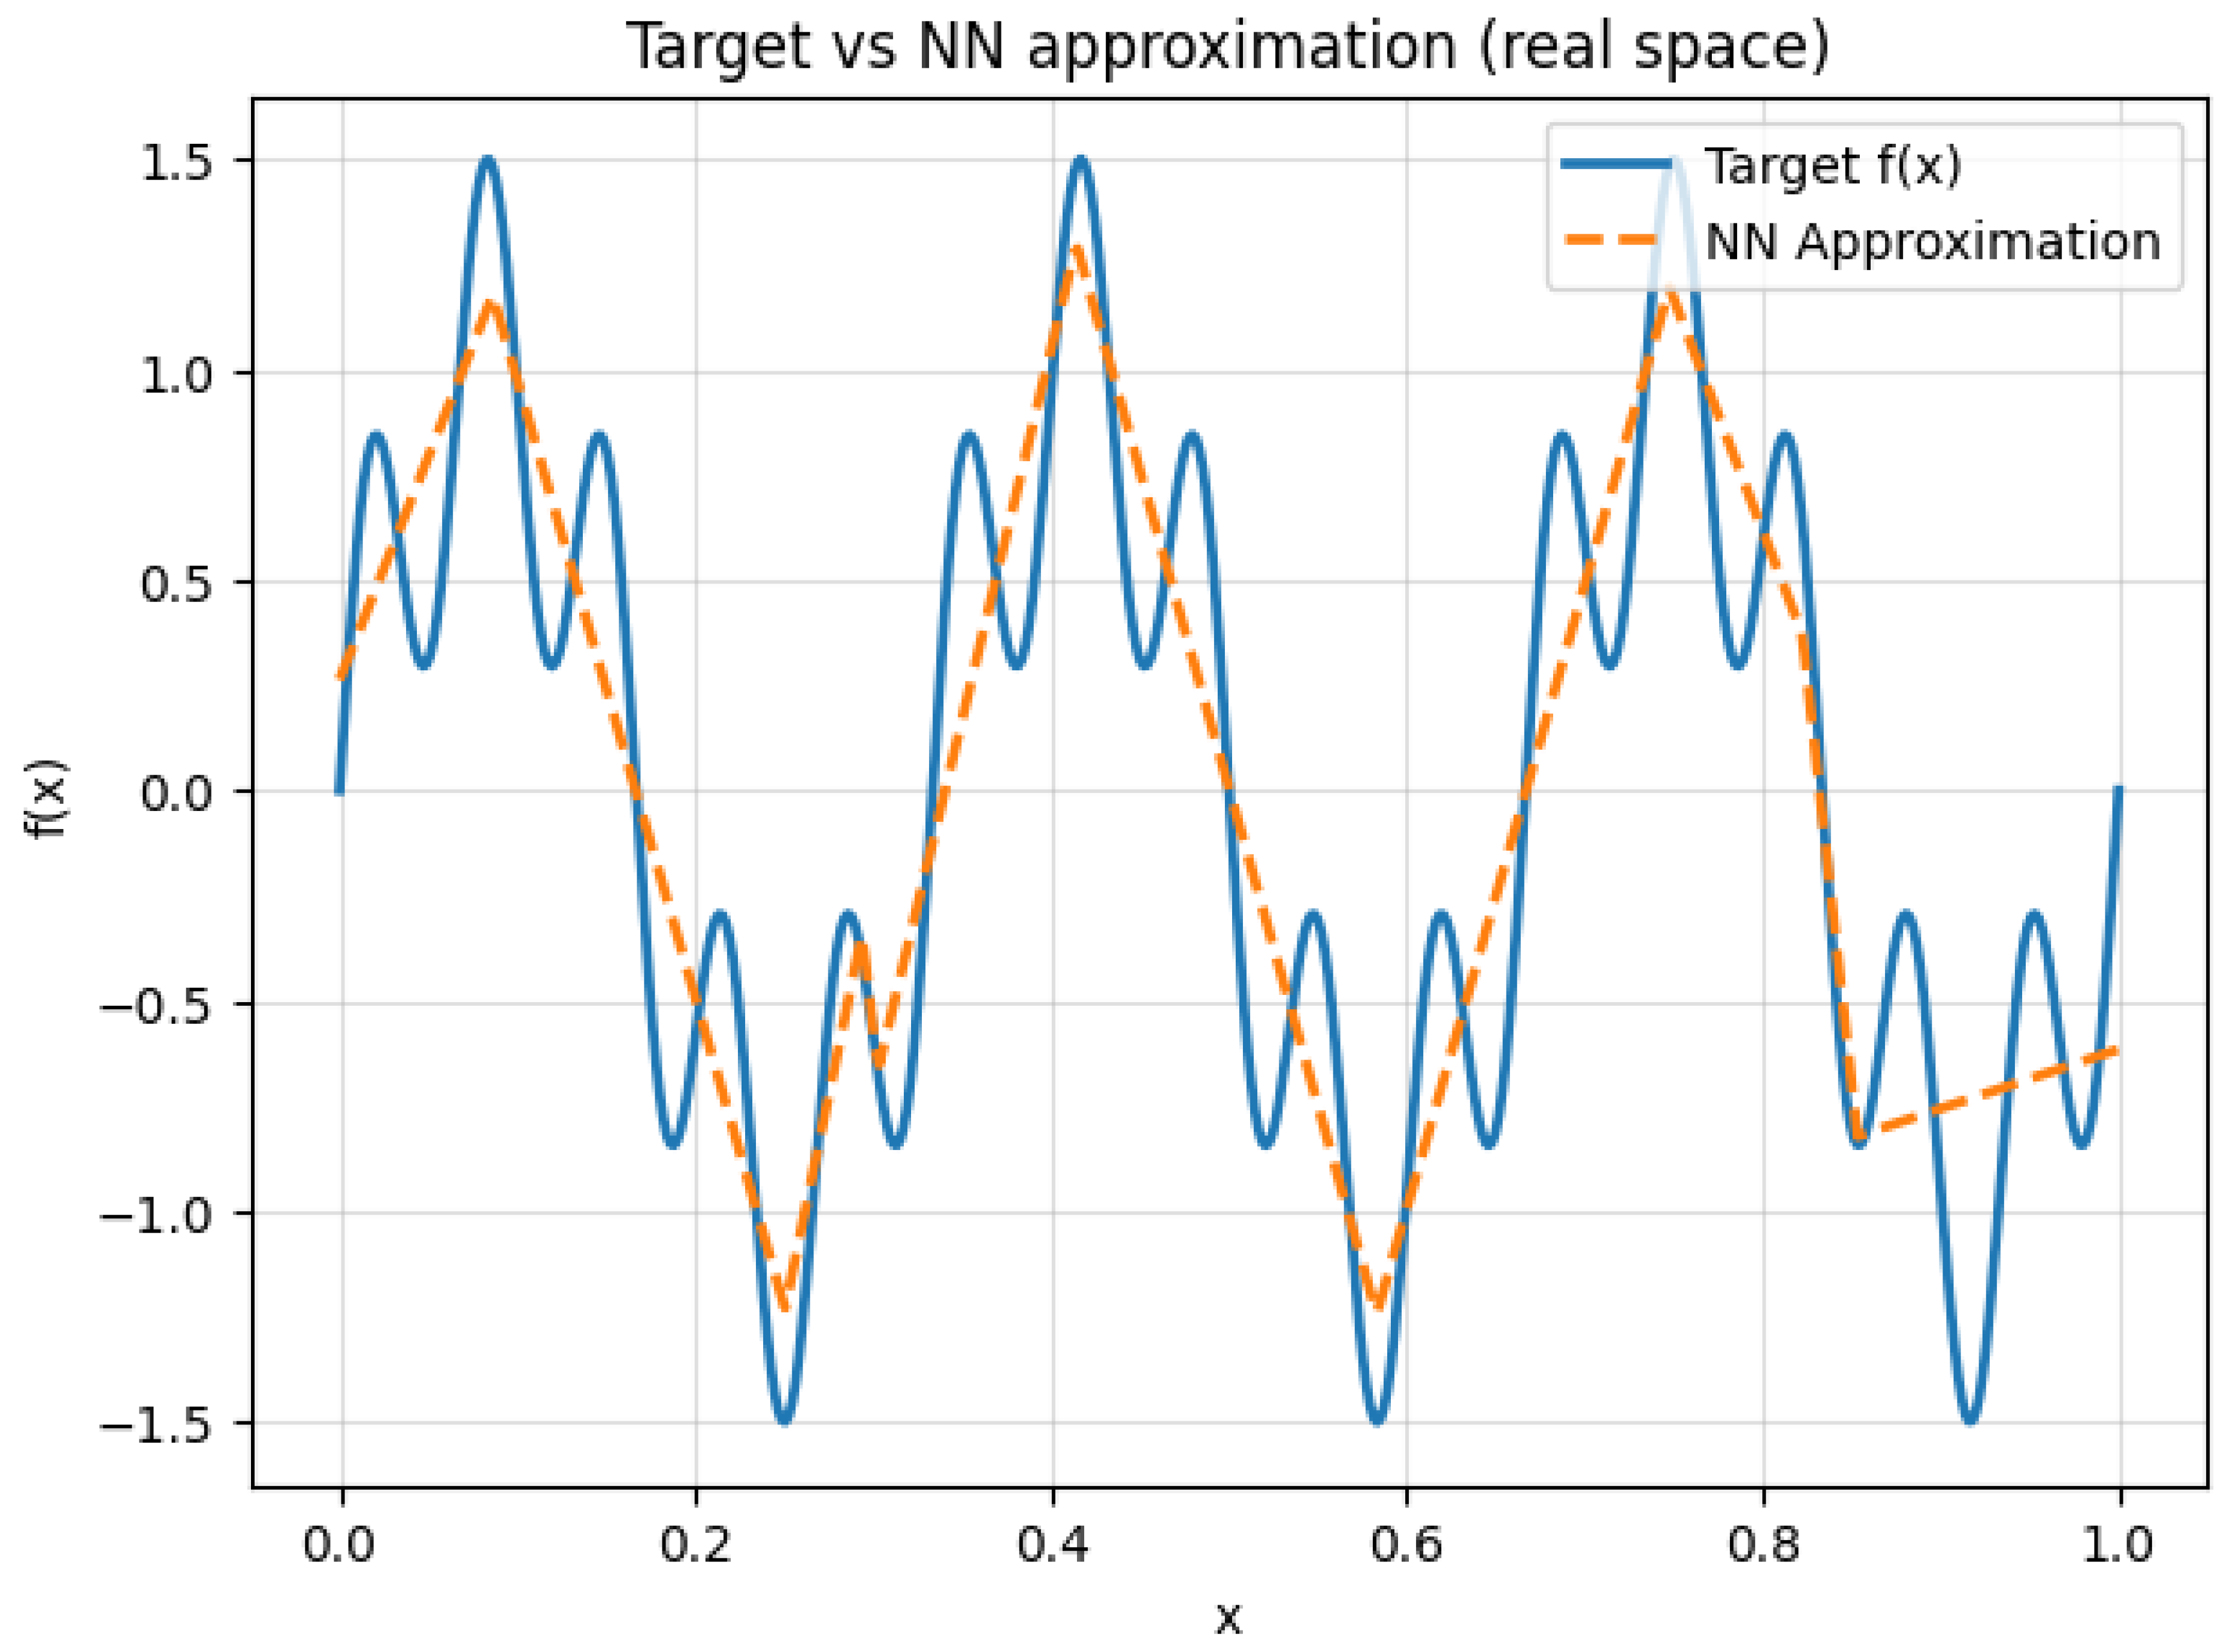
Figure 22.
Fourier Spectrum: Expressivity Analysis
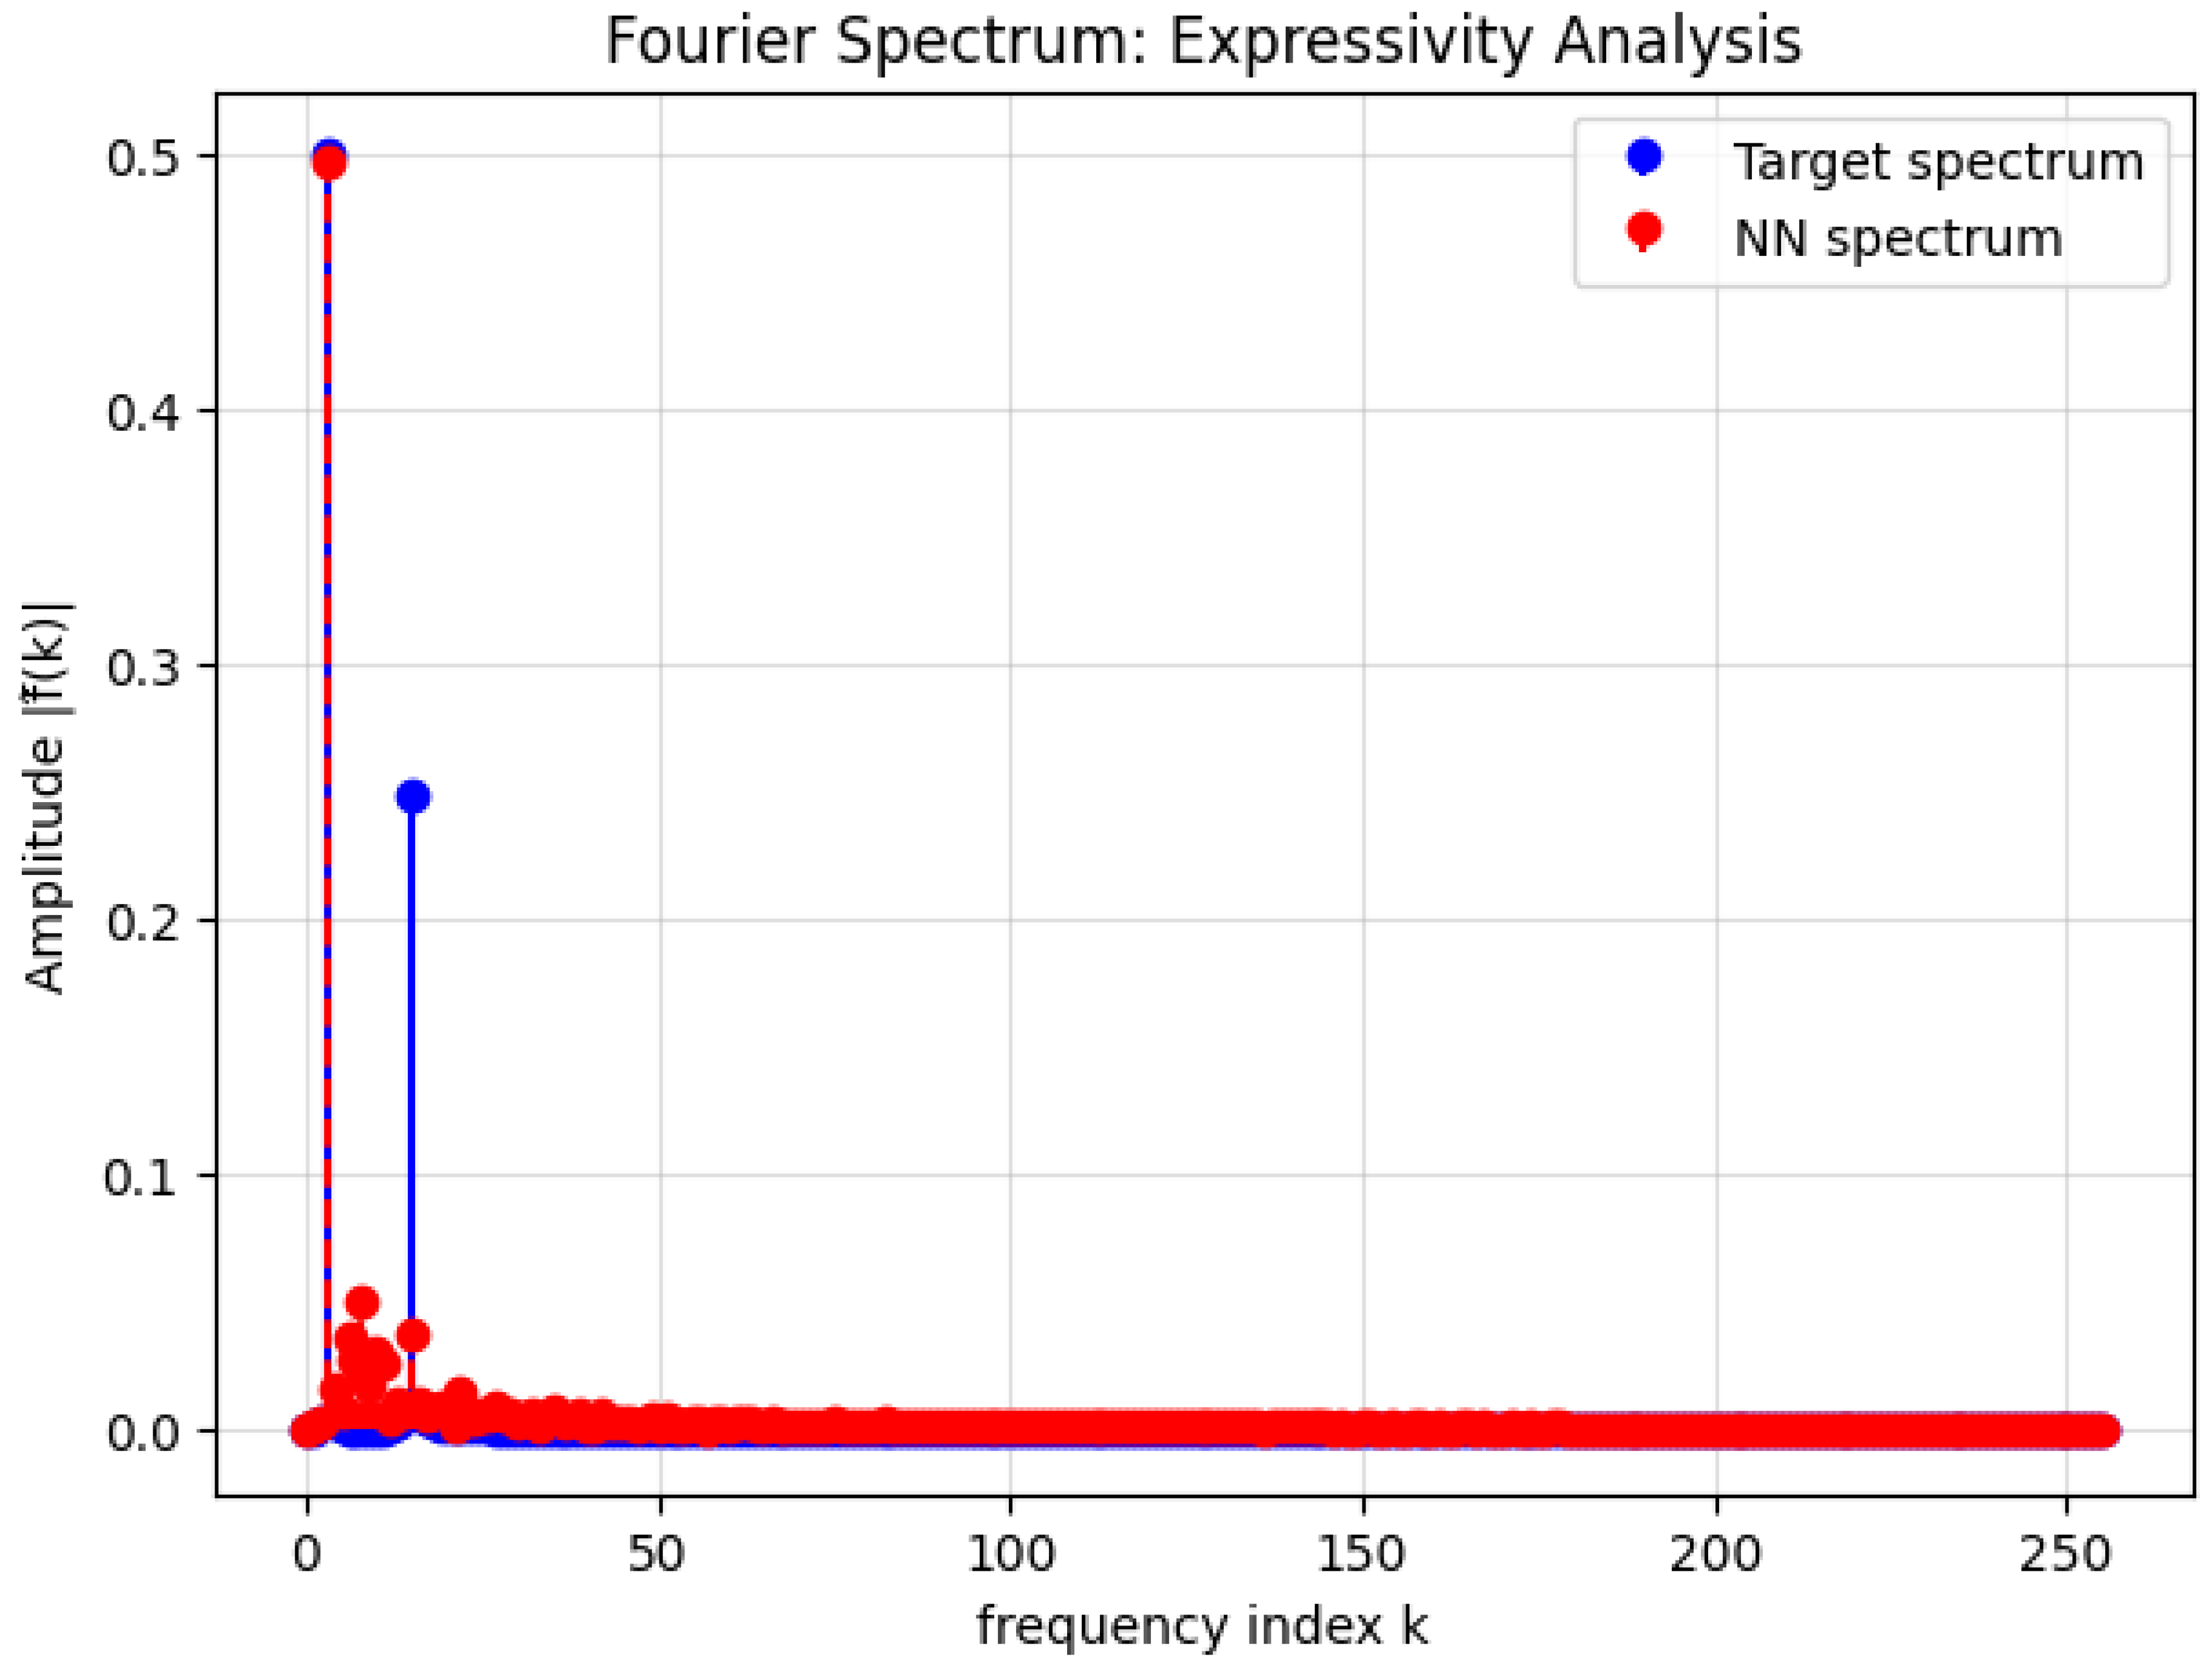
2.3.2.4 Python Code to Generate Figure 23 and Figure 24
The Python code below produces the Figure 23 and Figure 24 illustrating the Target vs Approximations (Real Space) and Fourier Spectrum: Expressivity of Architectures respectively.
Figure 23.
Target vs Approximations (Real Space)
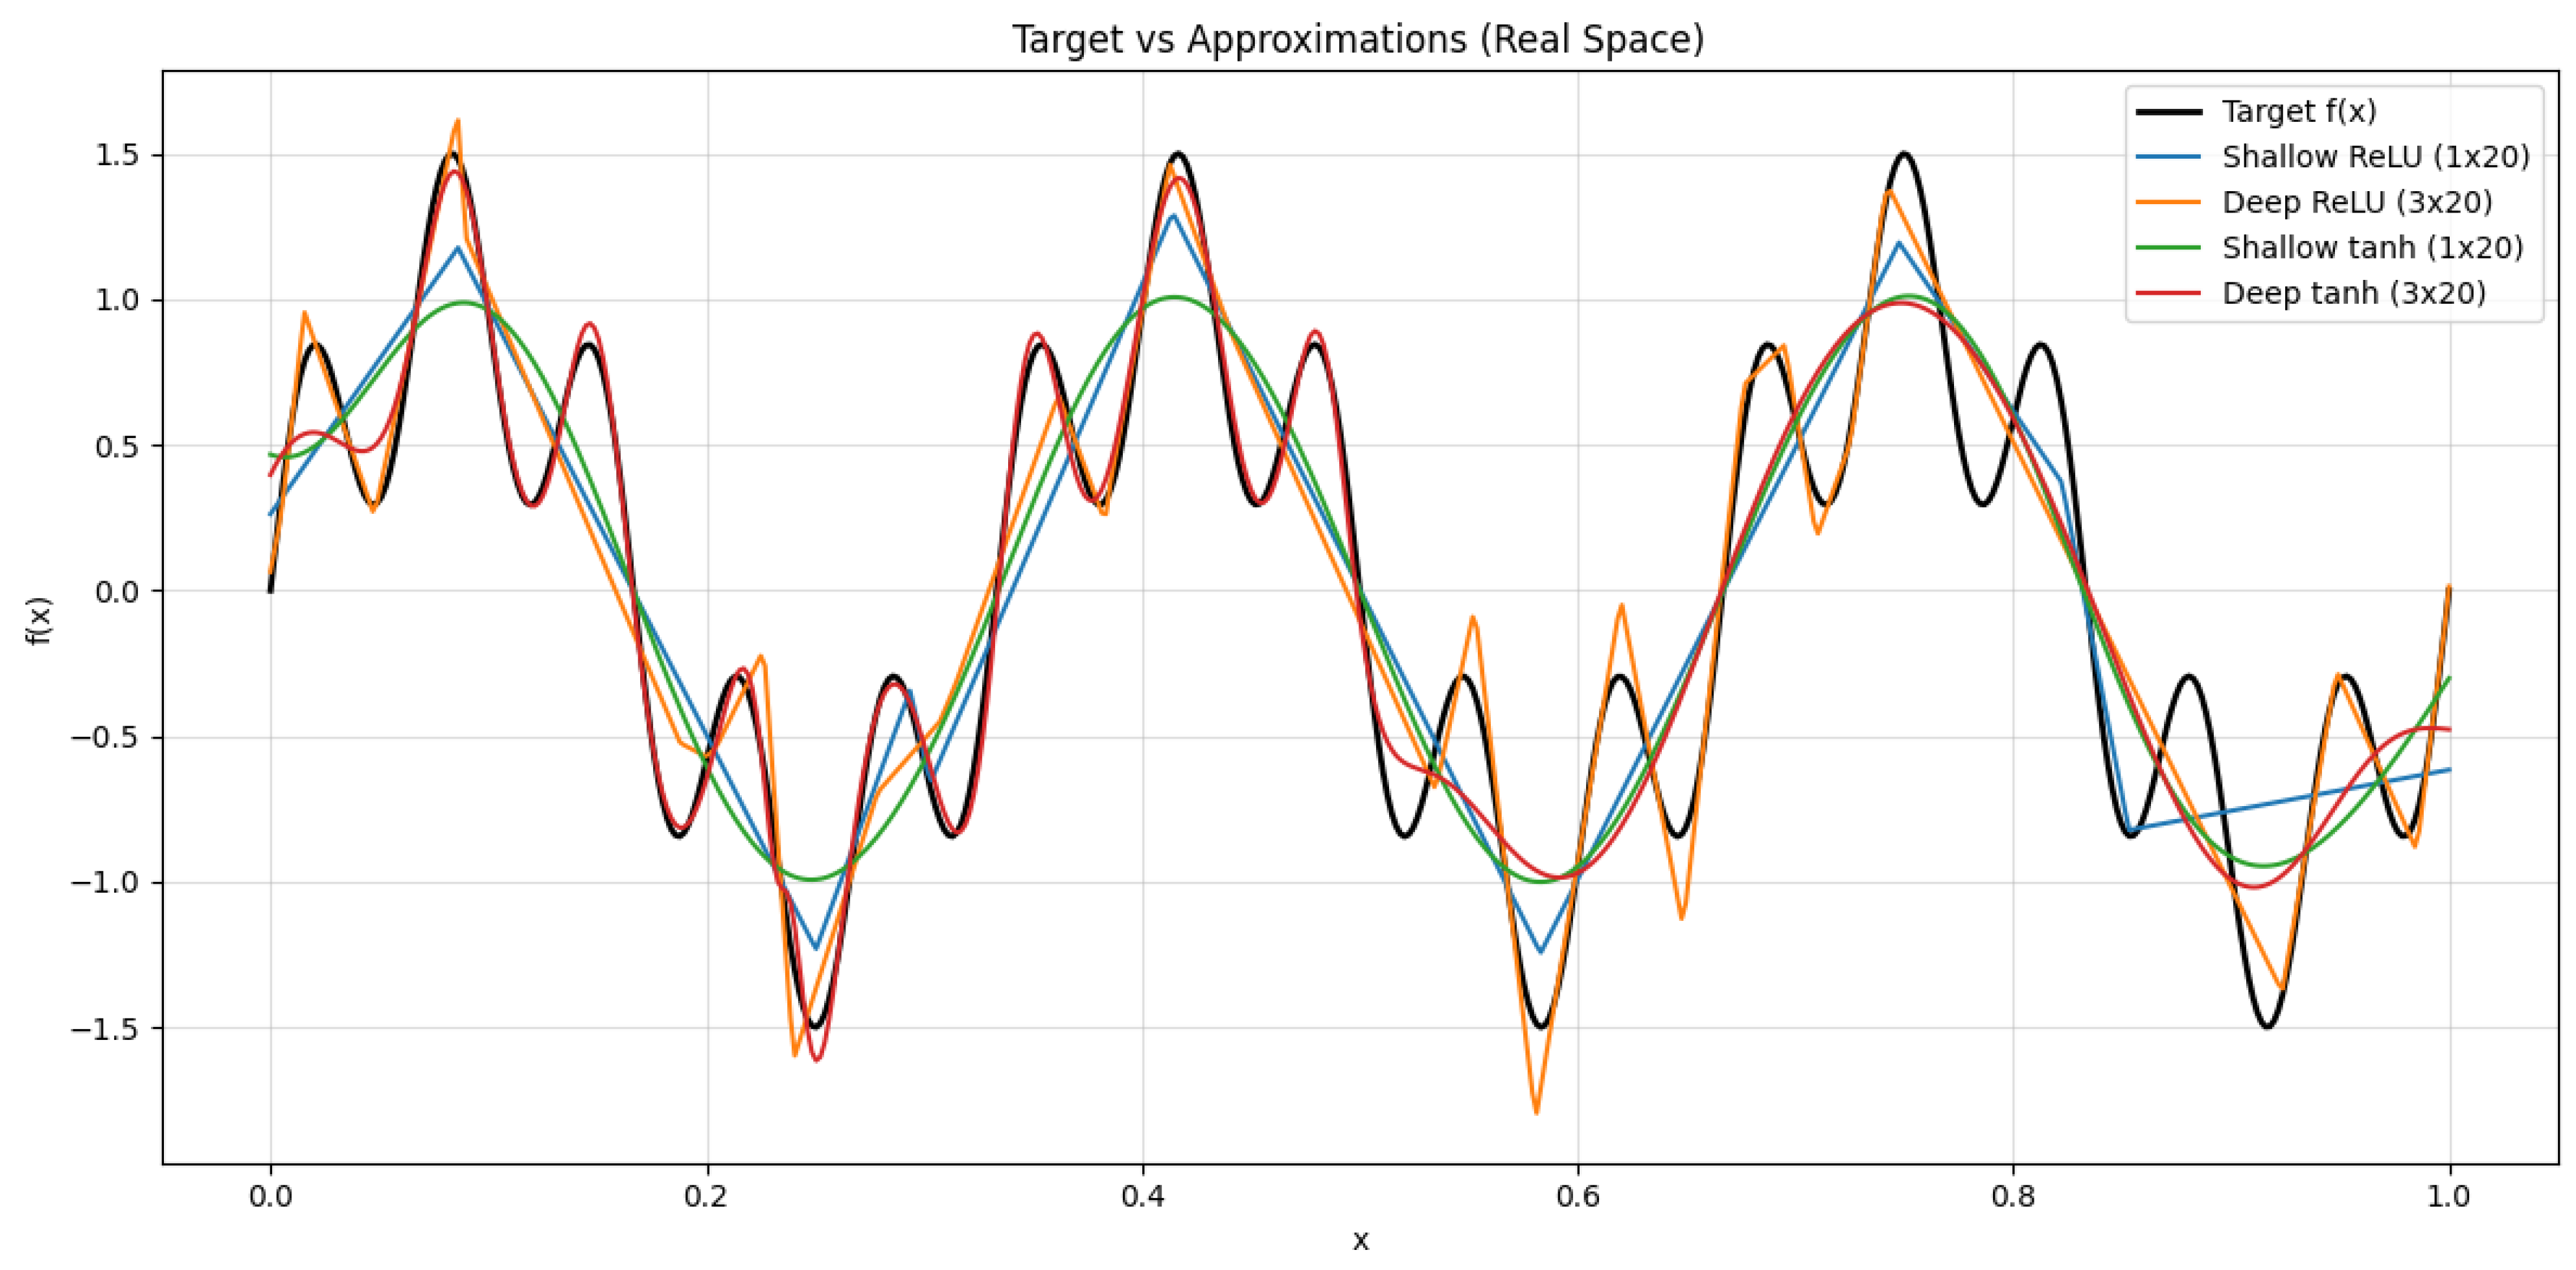
Figure 24.
Fourier Spectrum: Expressivity of Architectures
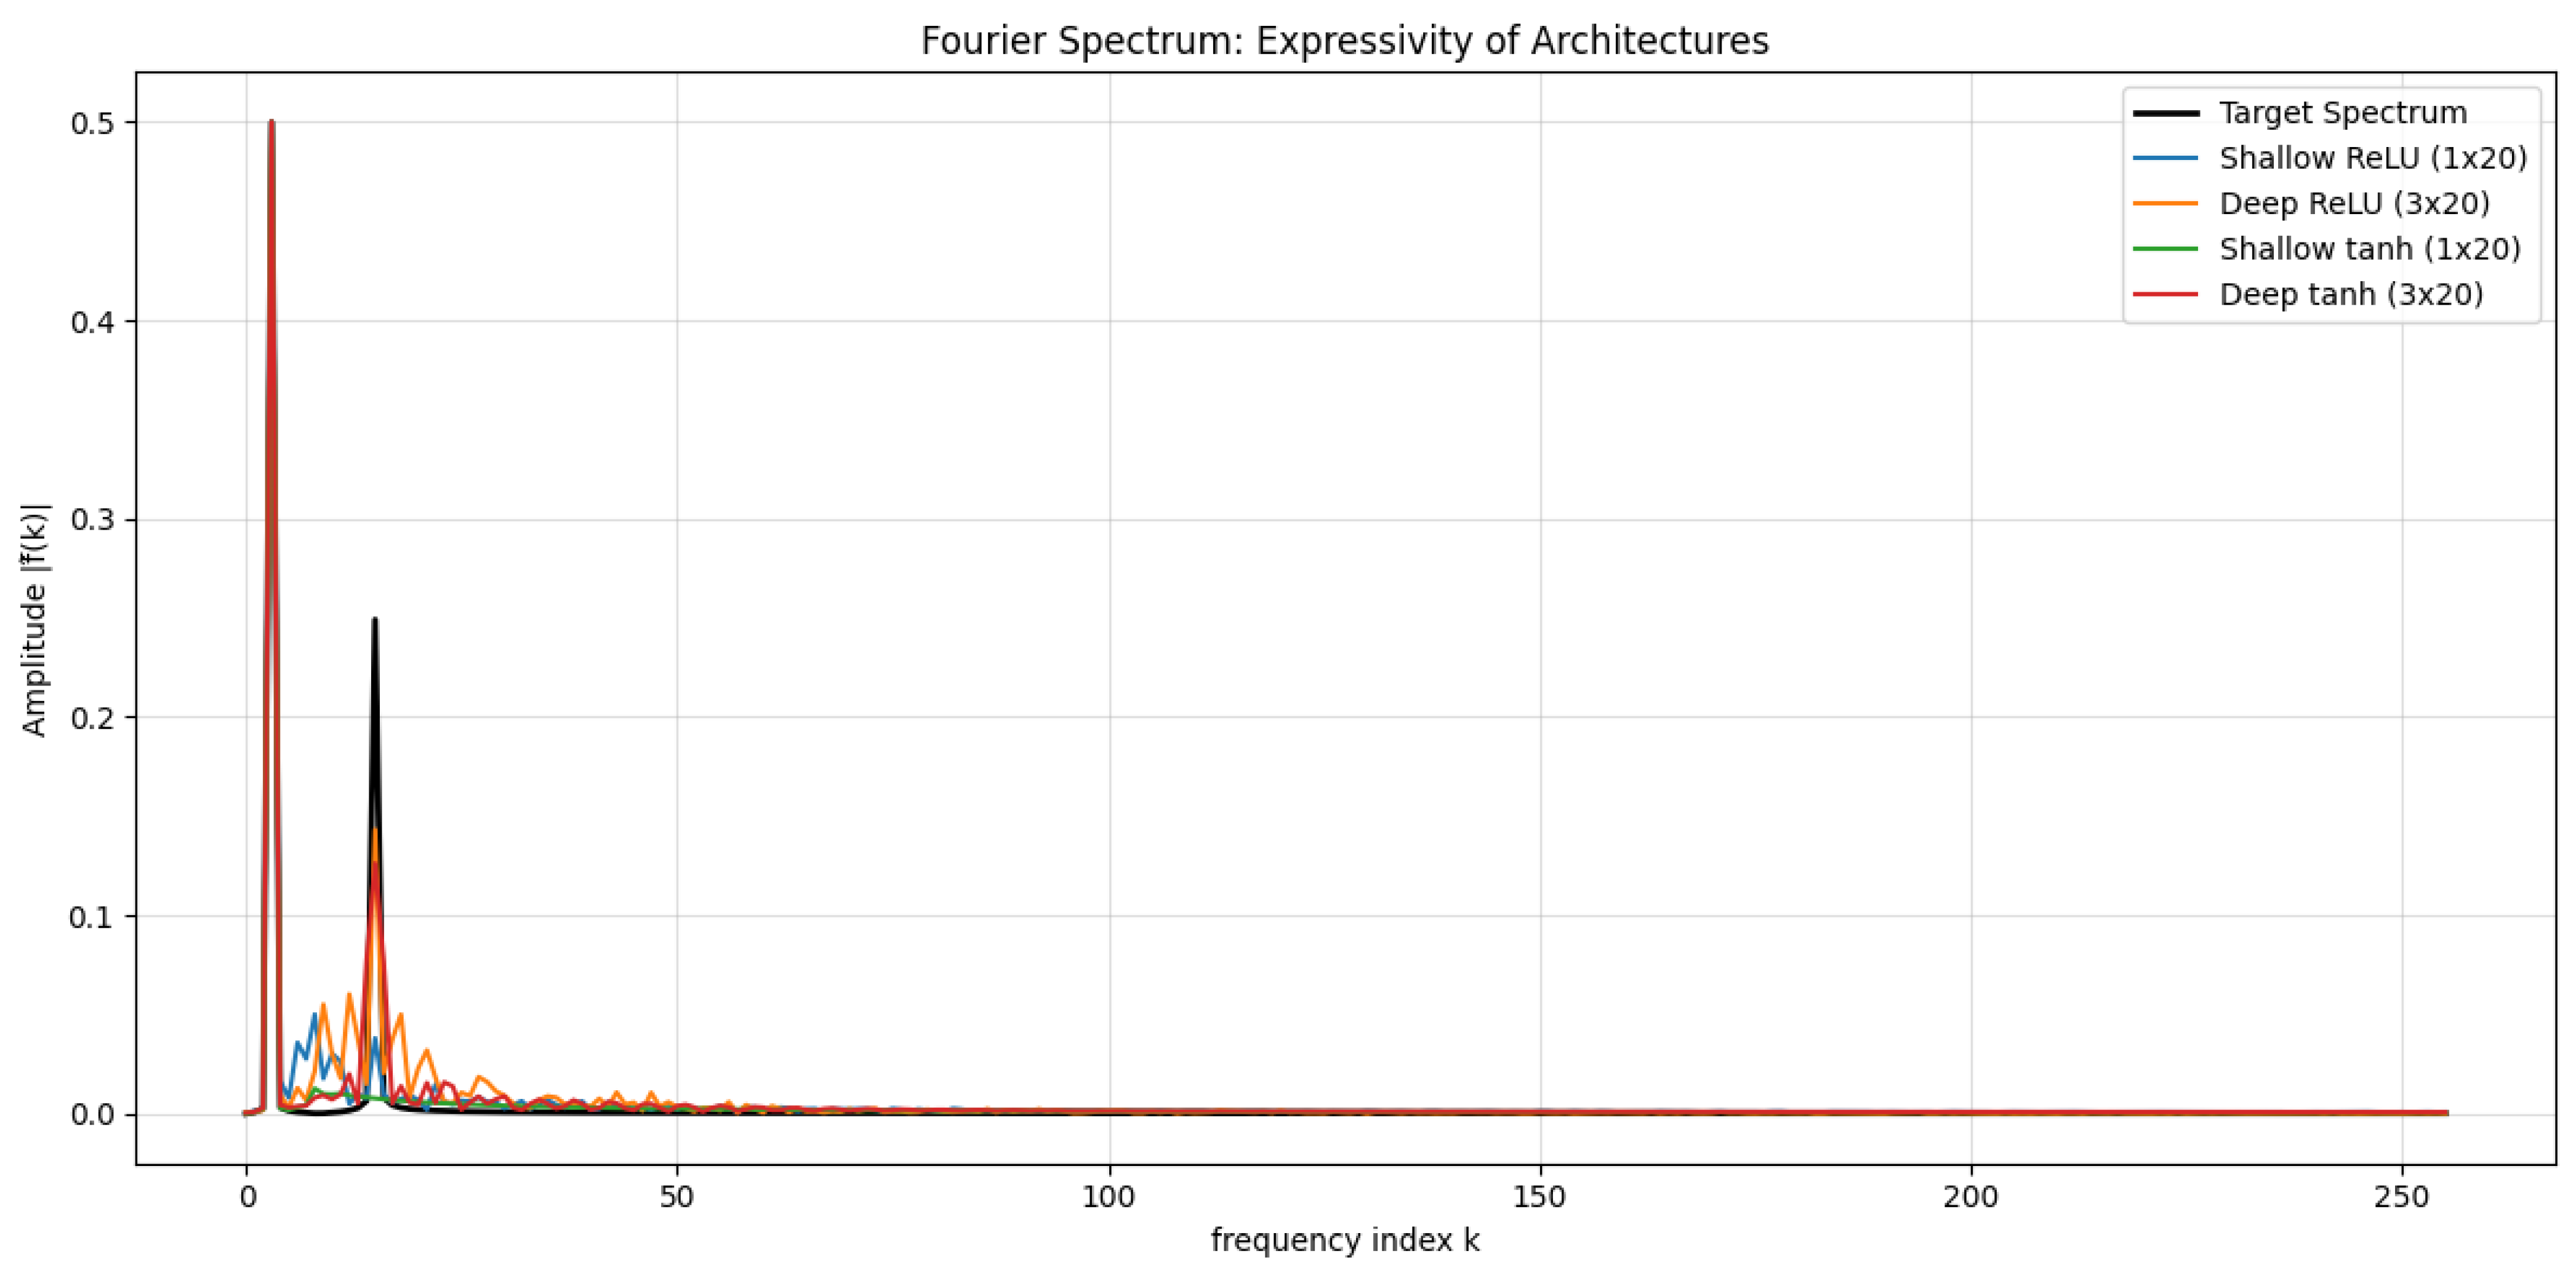
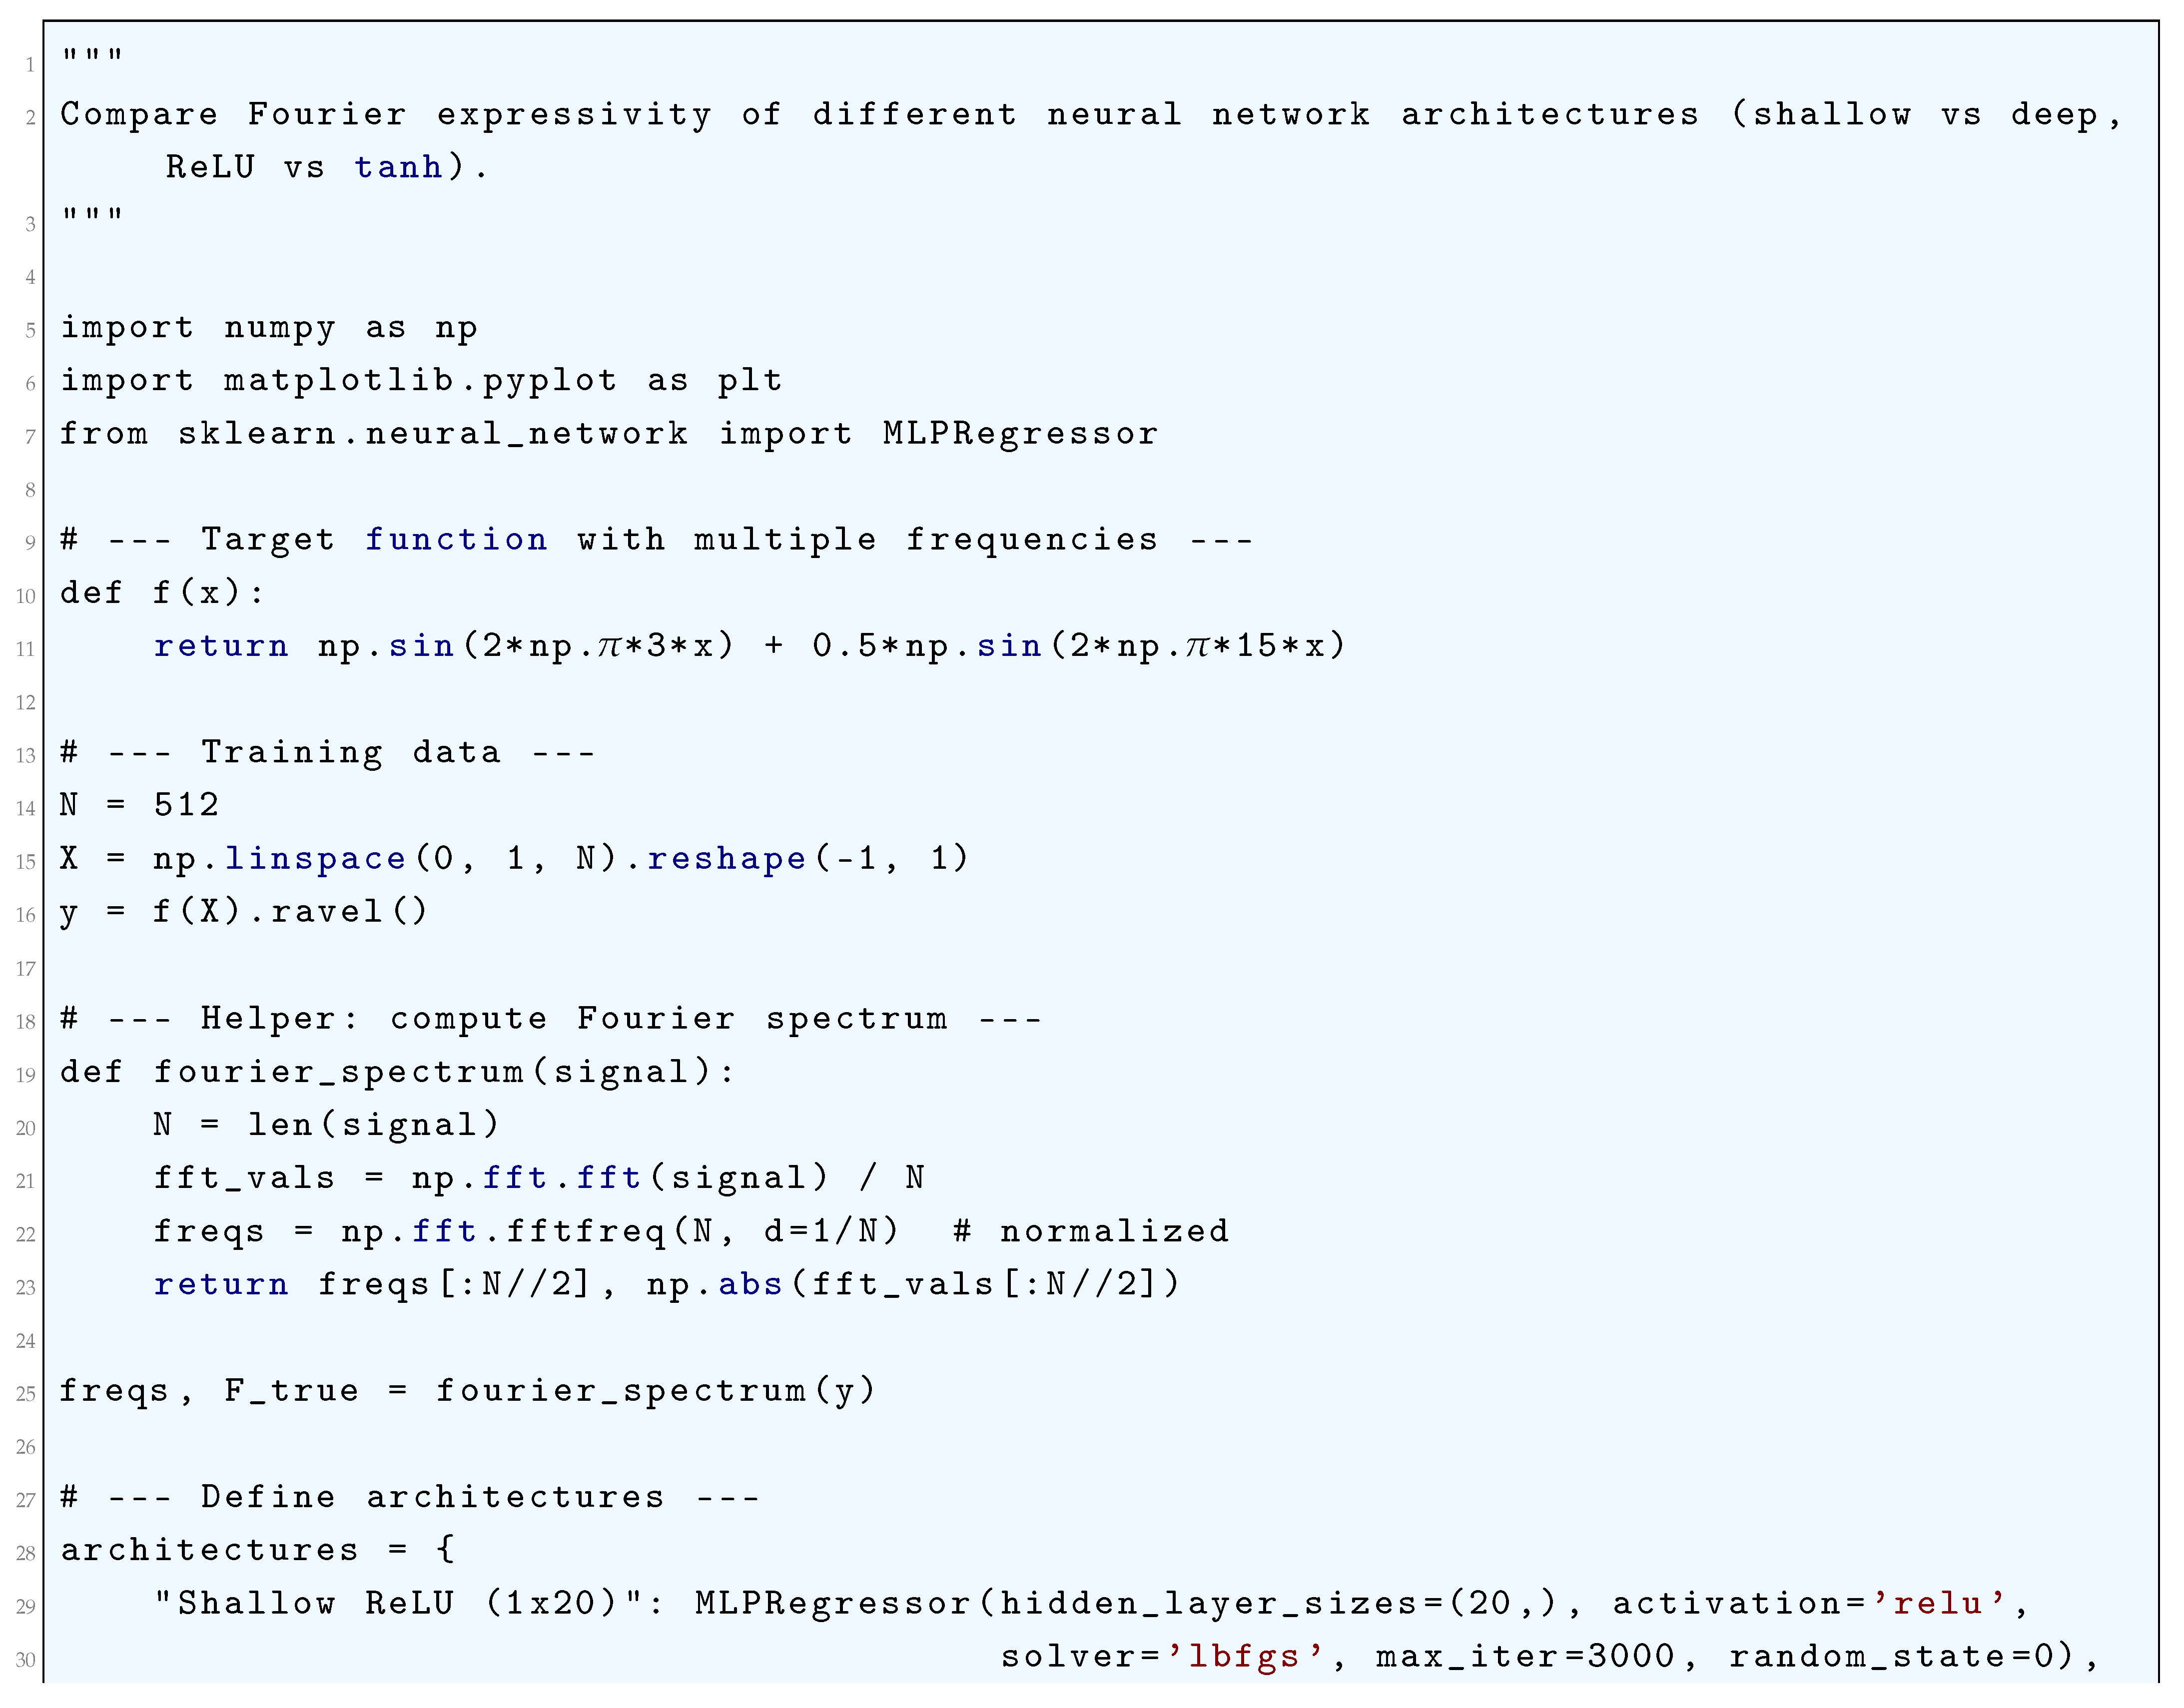
2.3.3. Fourier Transforms of Various Activation Functions
To rigorously derive the Fourier transforms of various activation functions, let us consider the Fourier transform definition:
We will explicitly derive for each activation function in a mathematically rigorous manner. This will include the Sigmoid, Tanh, ReLU, Leaky ReLU, and Sinusoidal activation functions.
2.3.3.1 Fourier Transform of the Sigmoid Function
The sigmoid activation function is given by:
The Fourier transform of is:
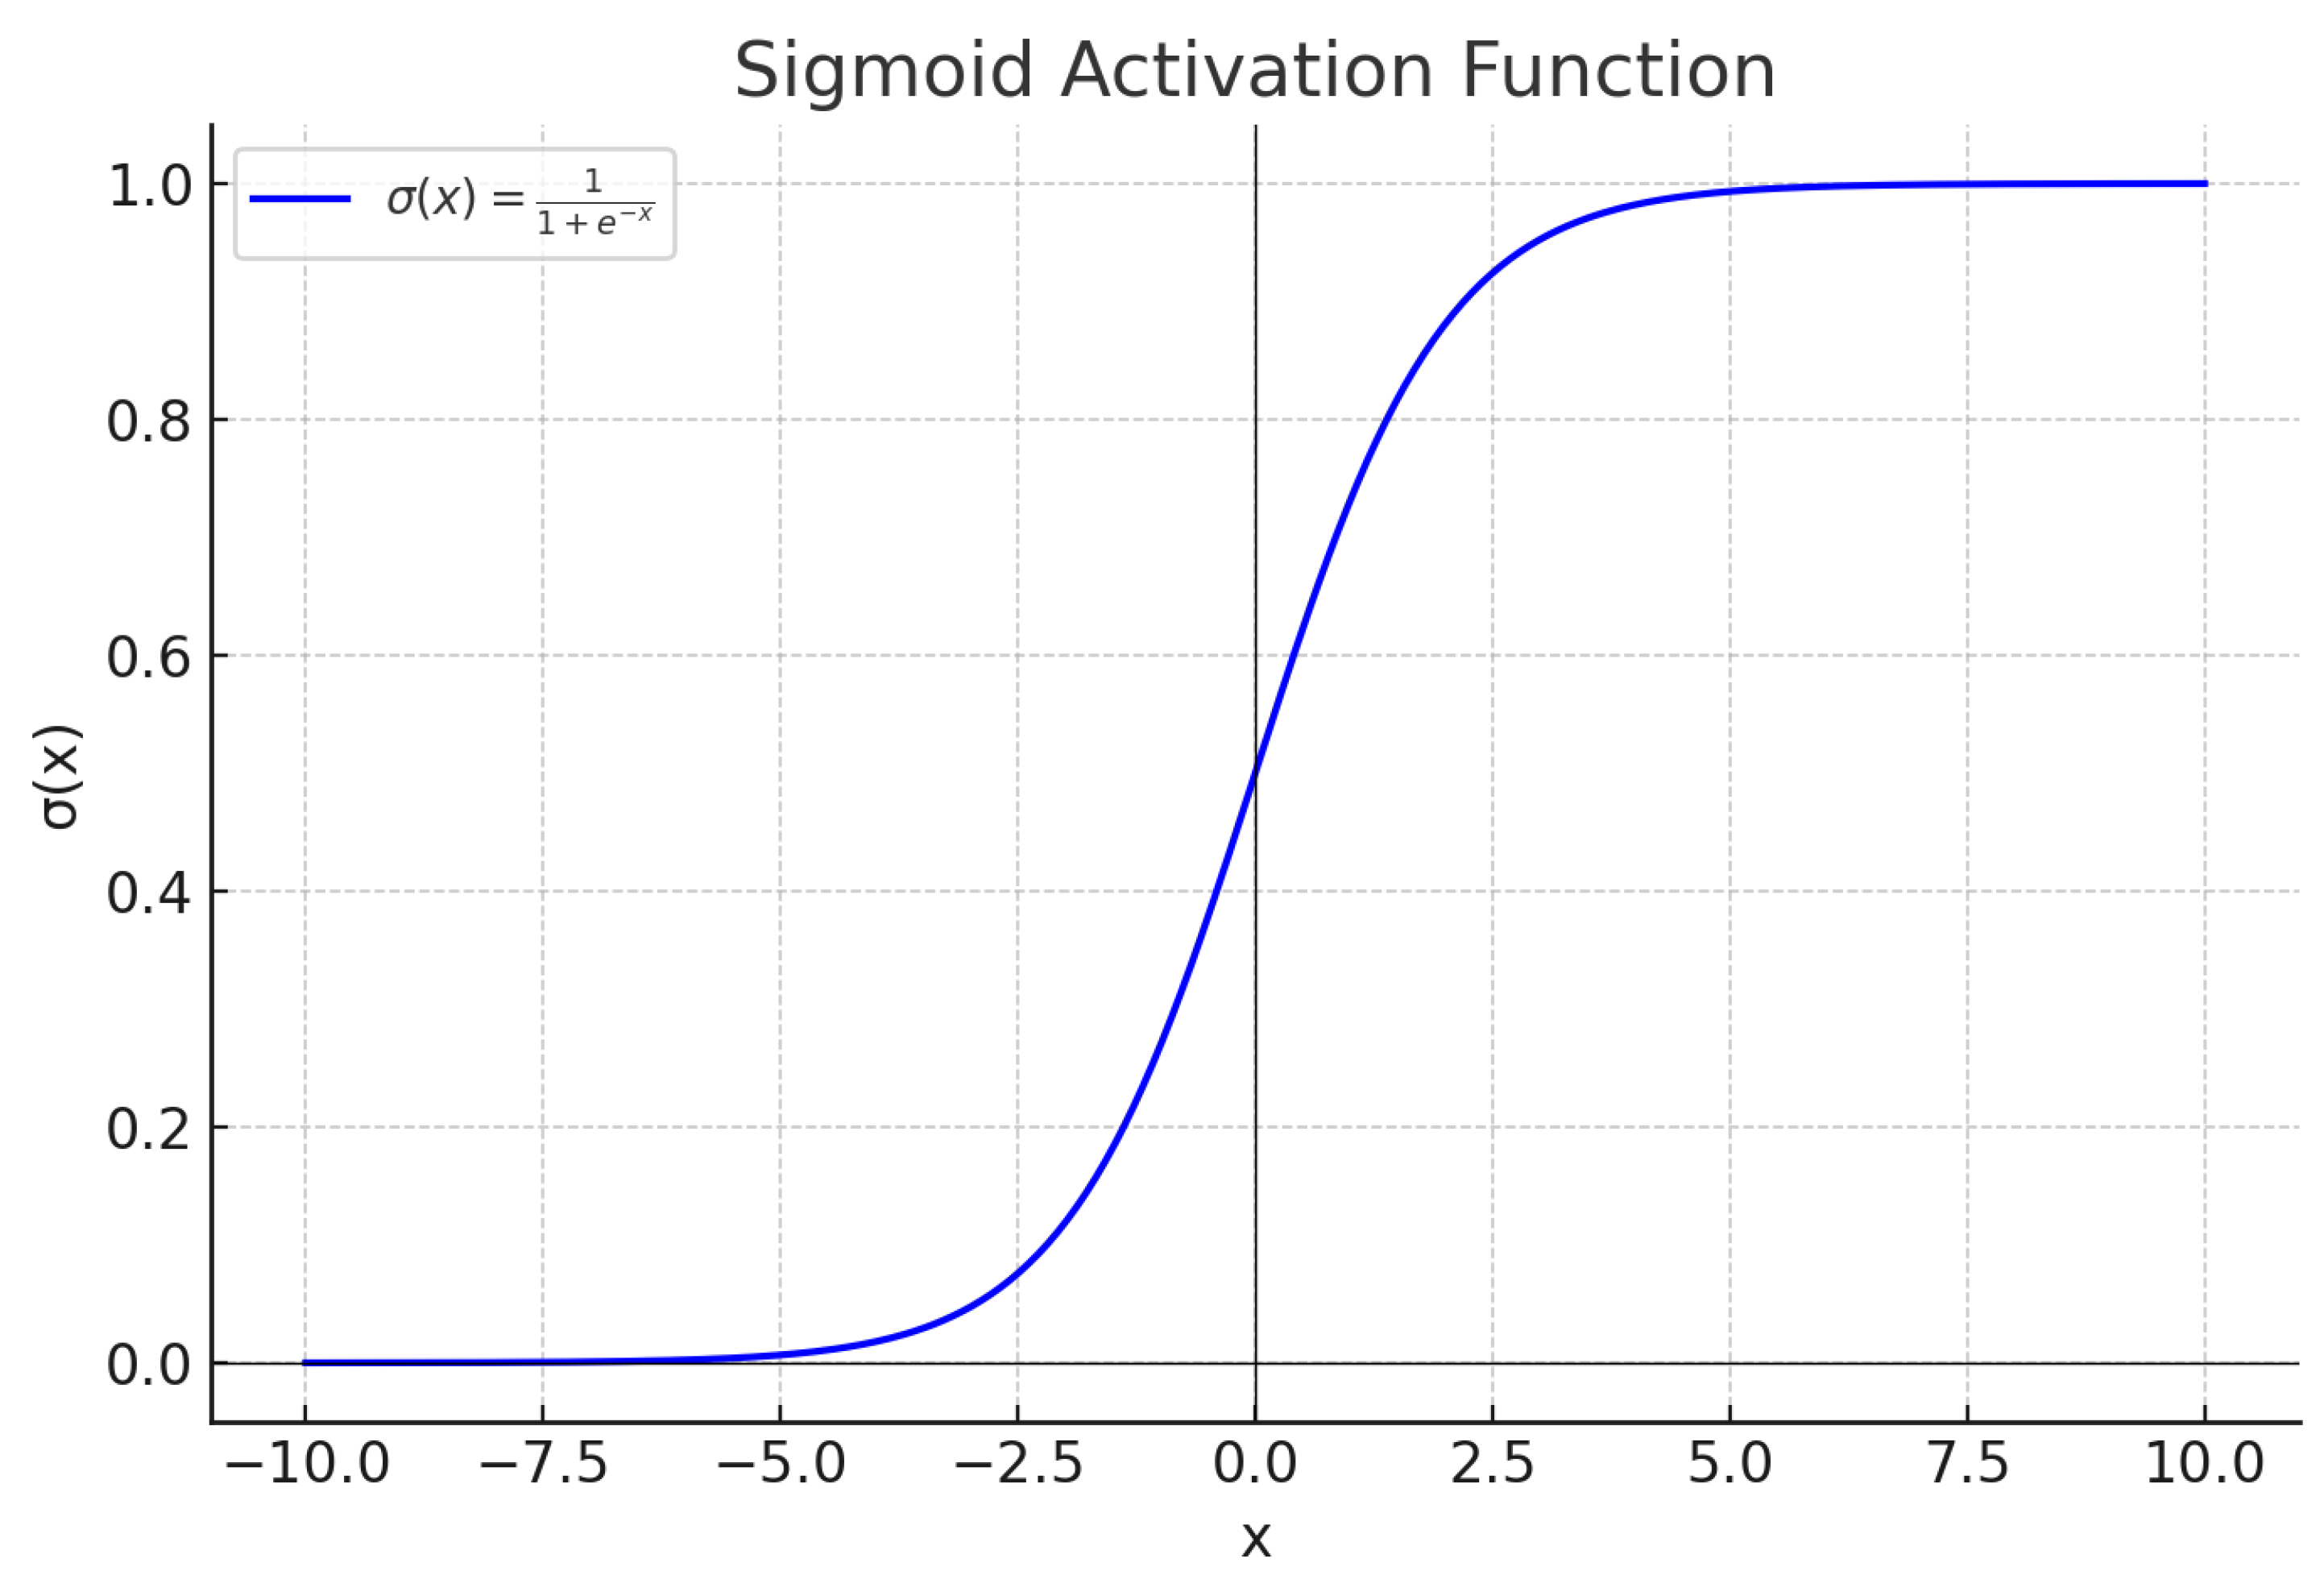 Rewriting using the identity:
the Fourier integral becomes:
Setting , so that , we transform the integral:
Simplifying:
This integral is well-known and can be computed using contour integration, yielding:
where is the hyperbolic cosecant function. For large , this decays as:
Figure 25.
Sigmoid Activation Function:
2.3.3.2 Fourier Transform of the Hyperbolic Tangent Function
The tanh activation function is:
Figure 26.
Hyperbolic Tangent Activation Function:
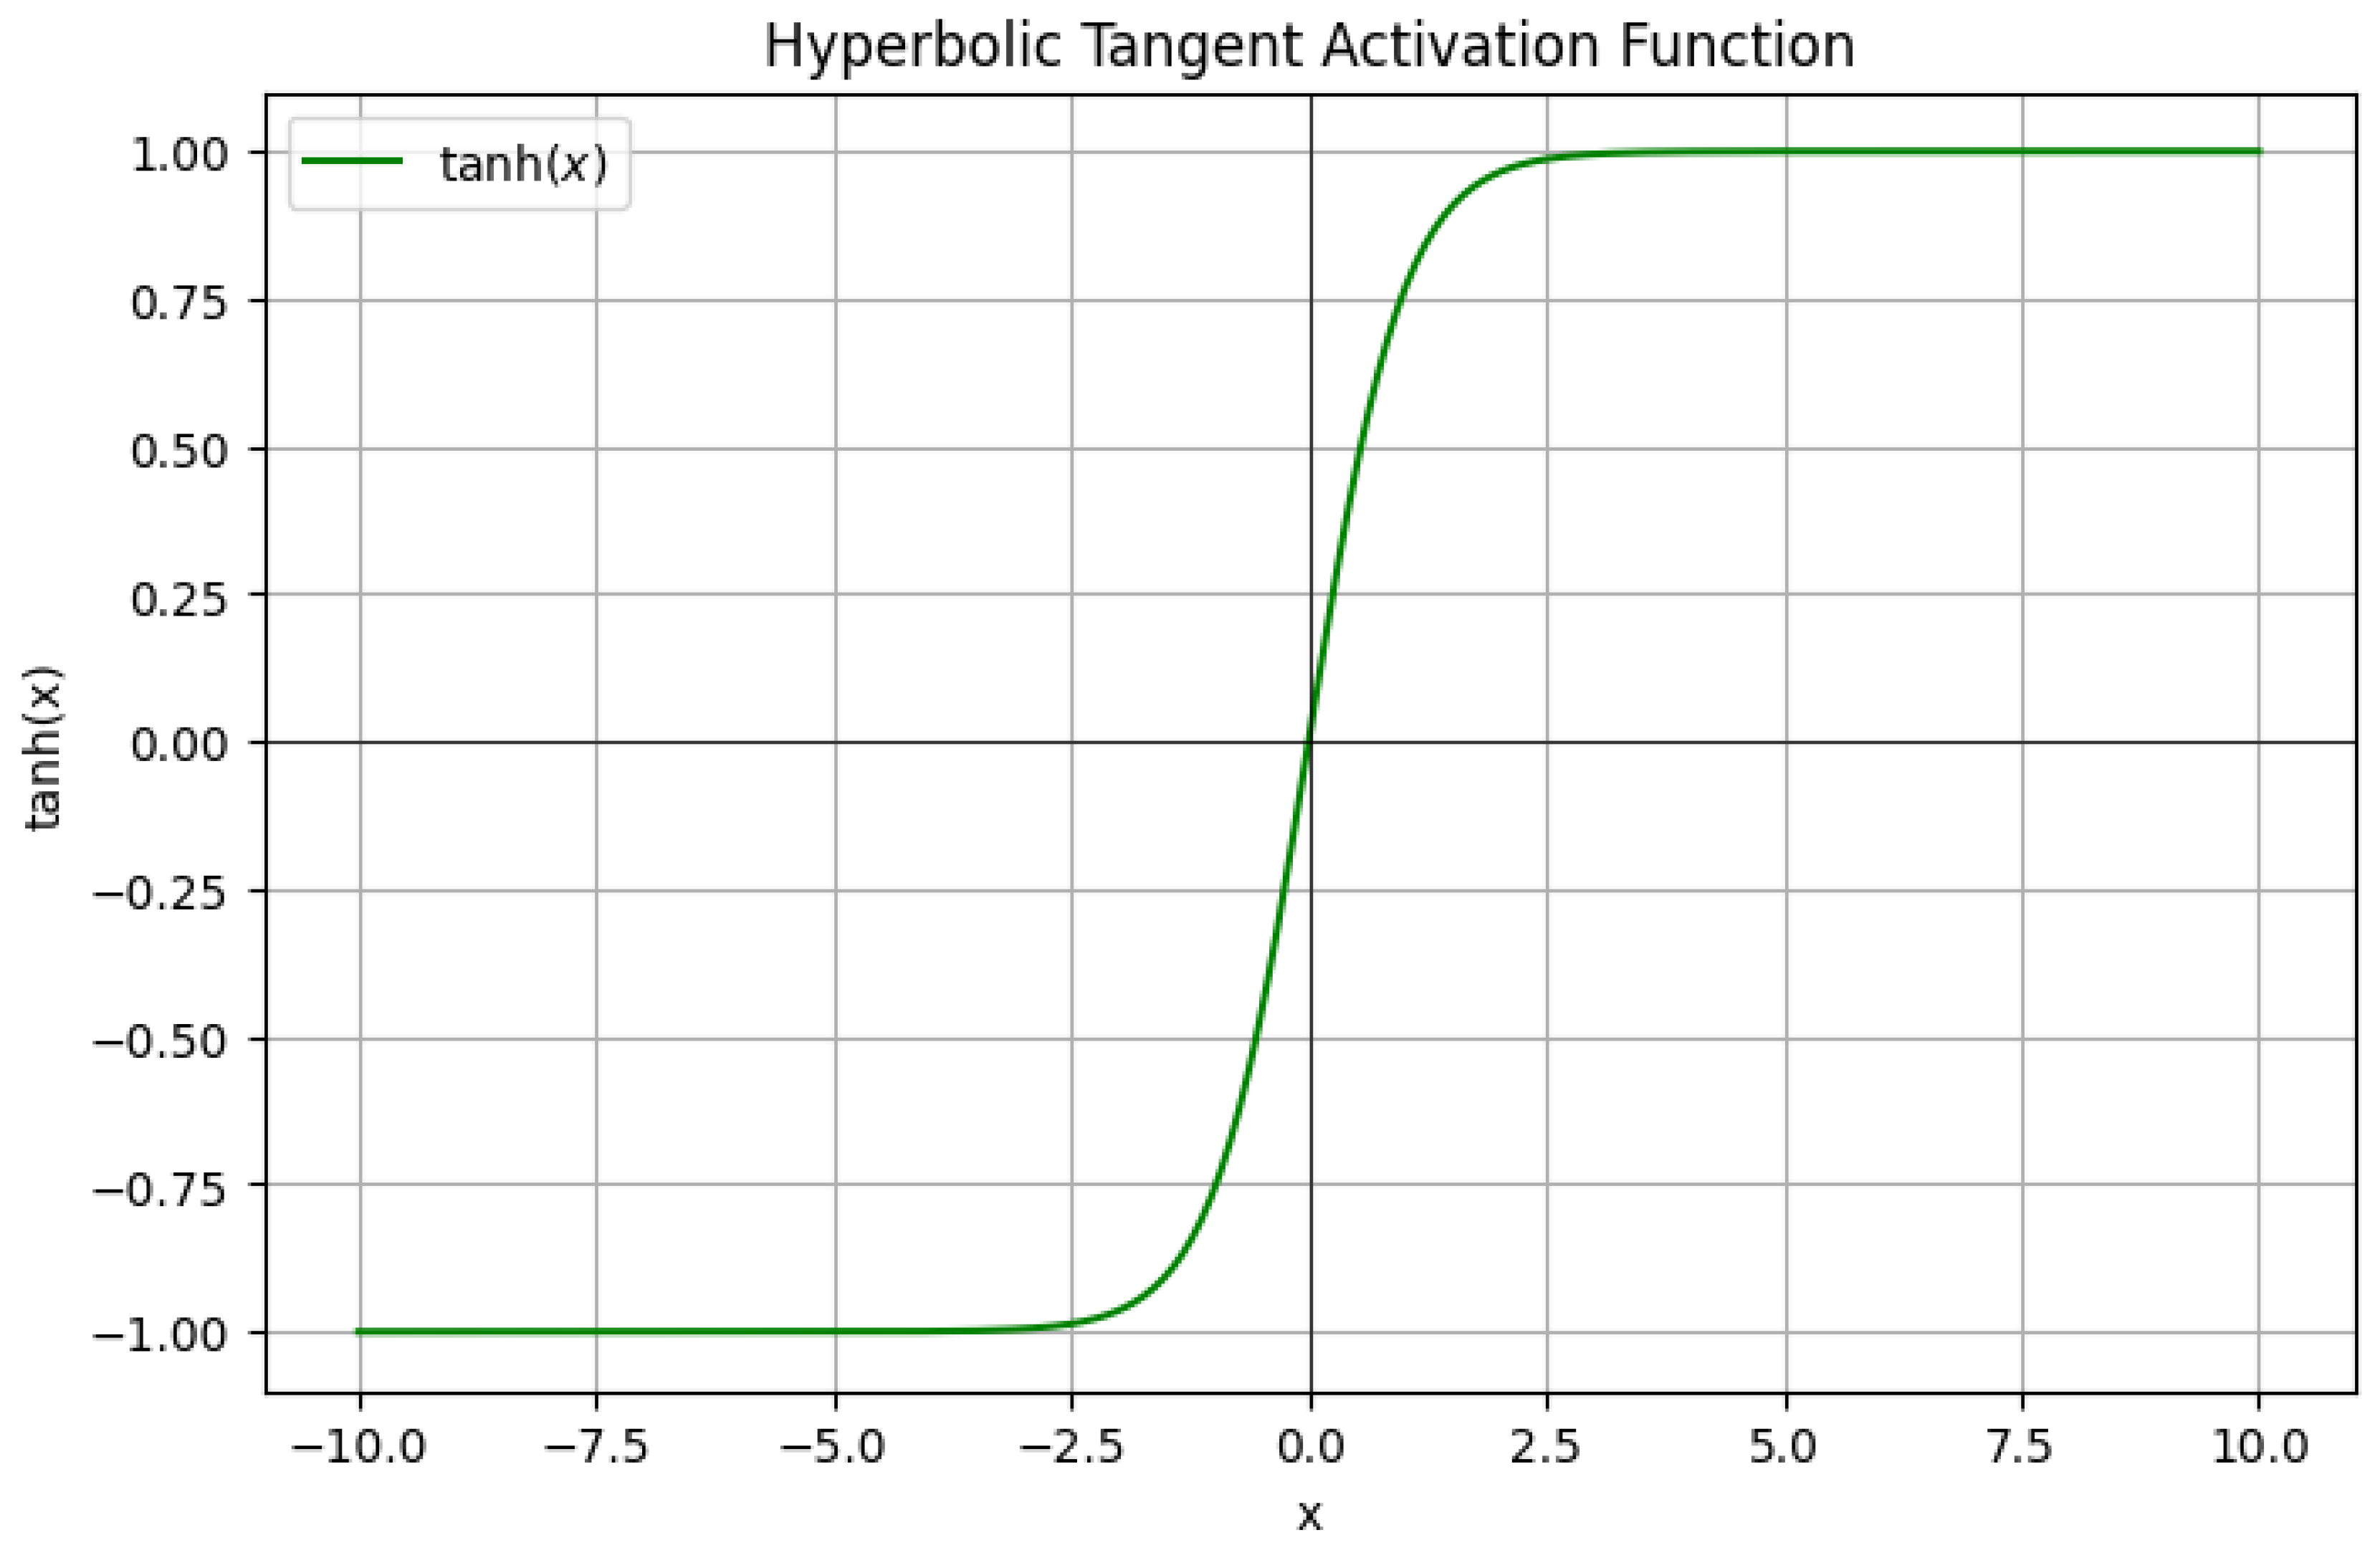
The Fourier transform is:
Using the identity:
and leveraging the result from the sigmoid case, we obtain:
Again, for large :
2.3.3.3 Fourier Transform of the ReLU Function
The ReLU activation function is:
Figure 27.
ReLU Activation Function:
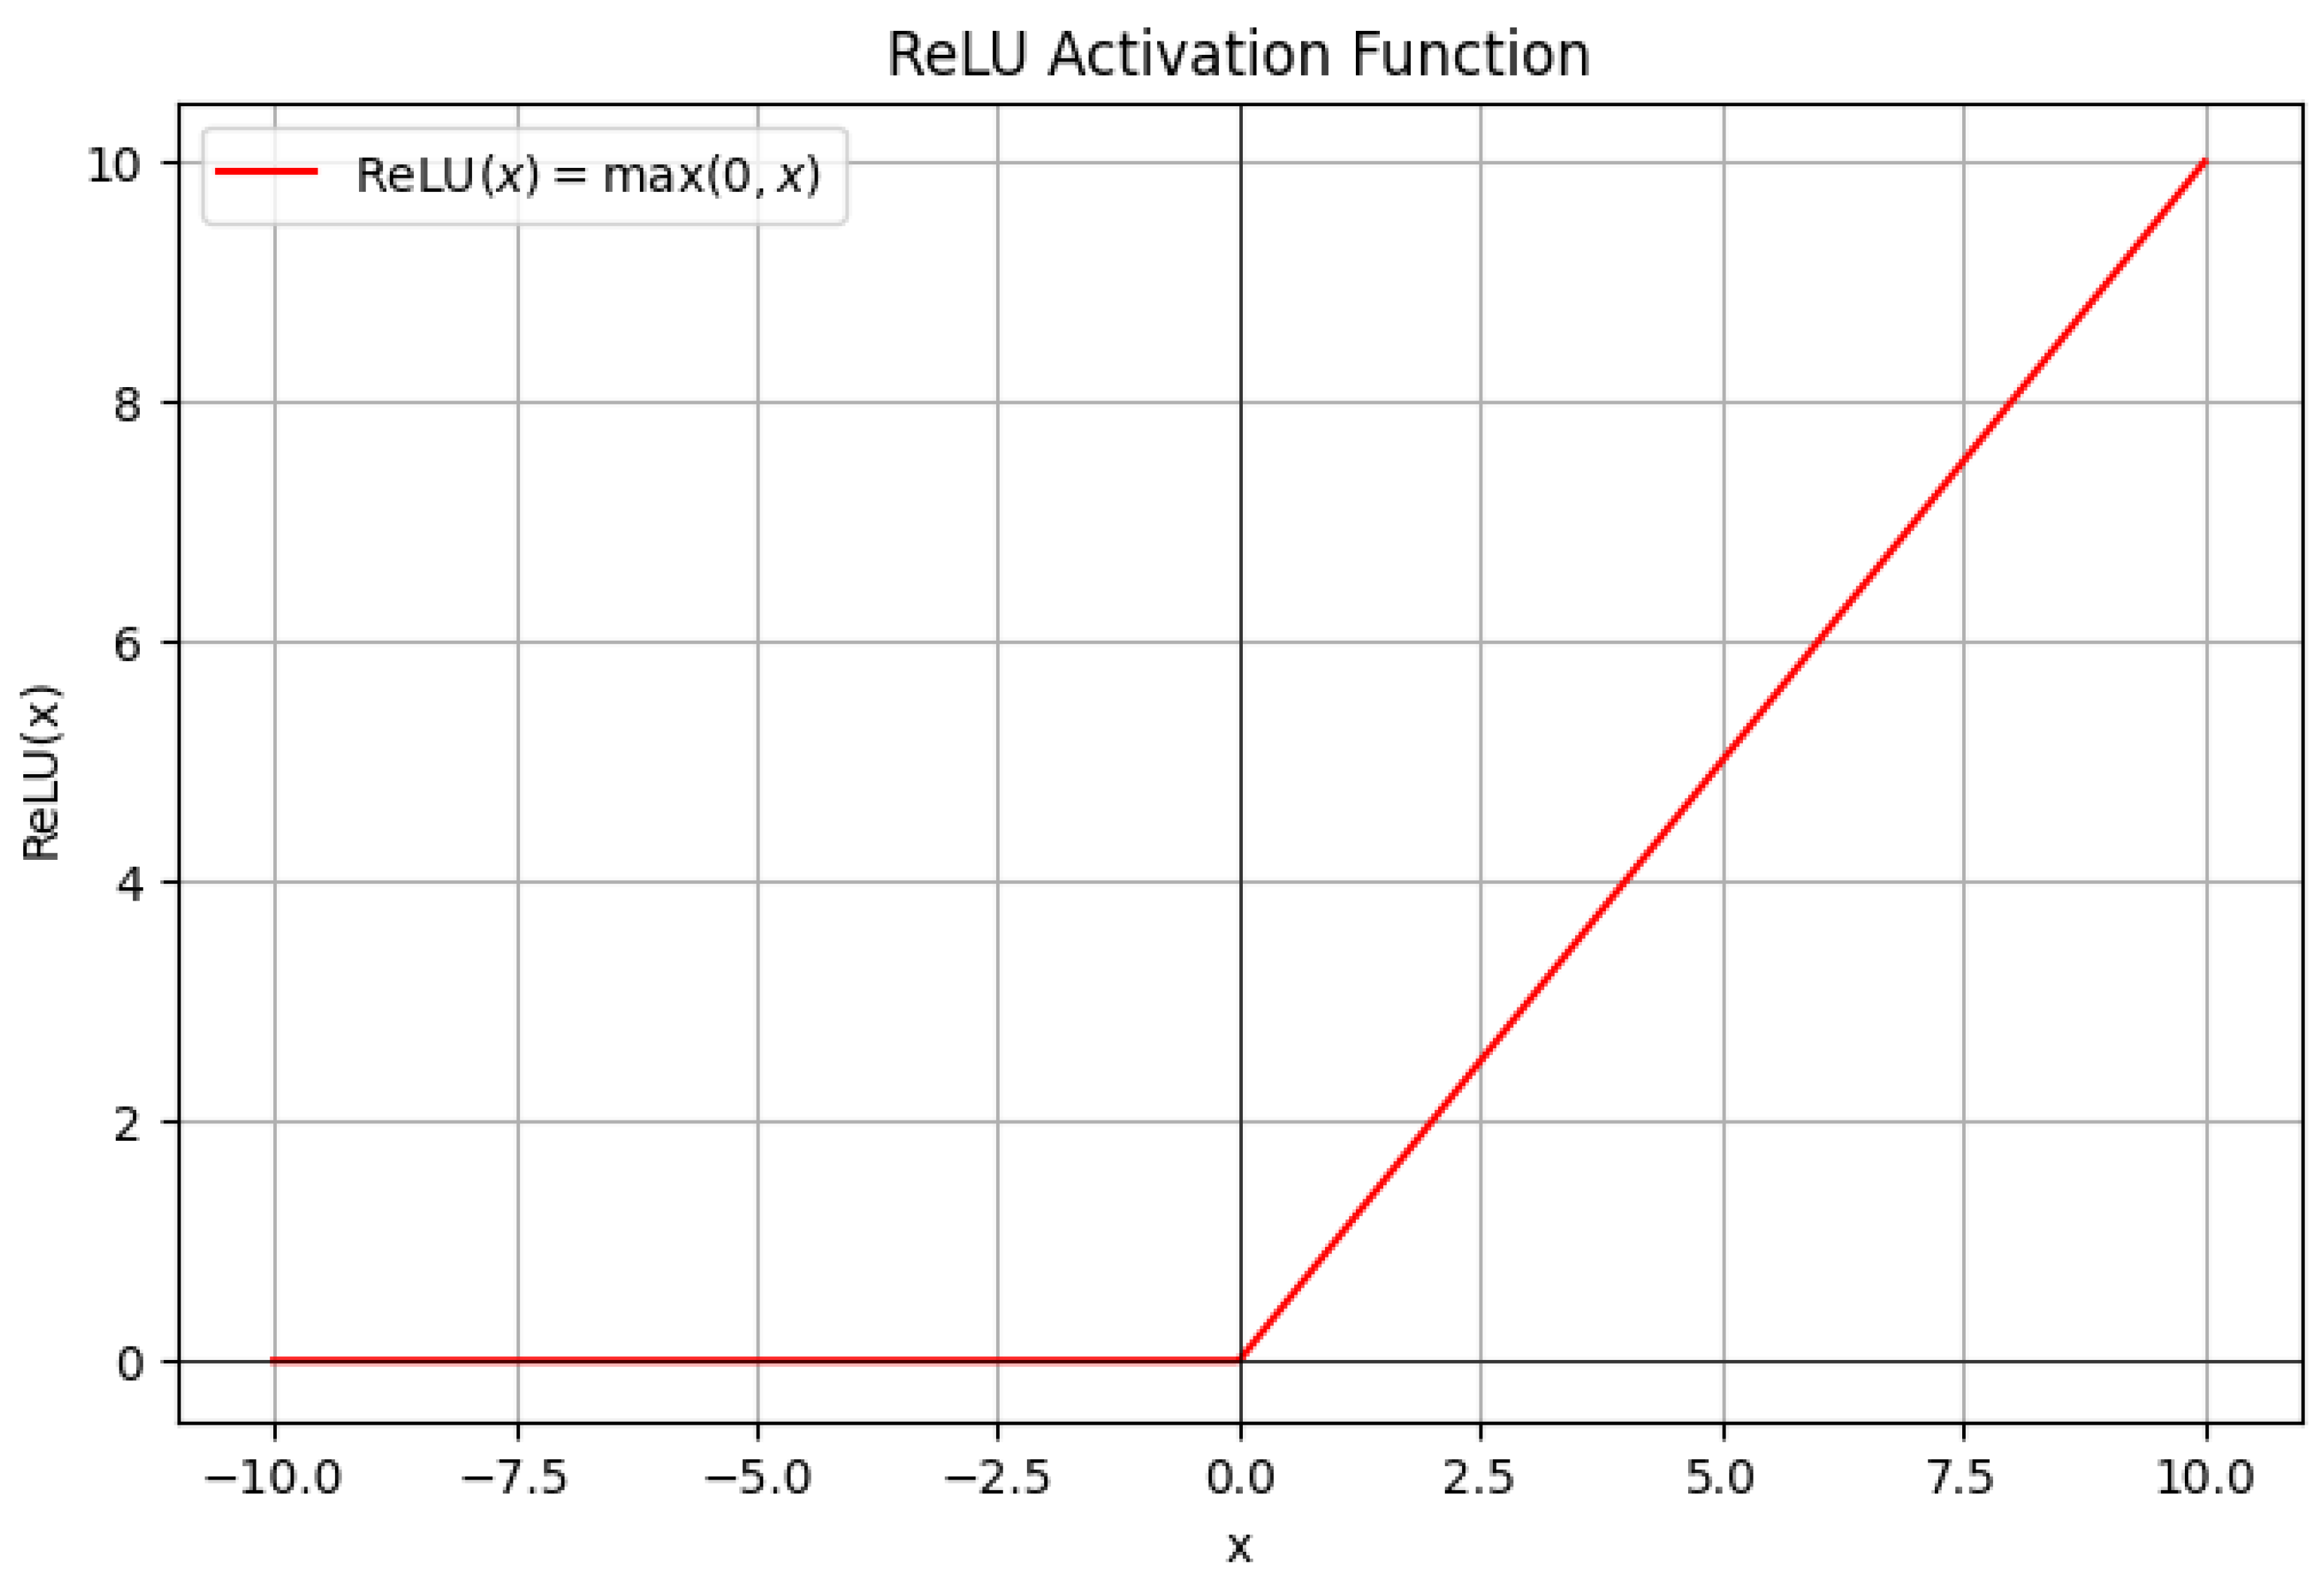
Thus, the Fourier transform is:
where is the Heaviside step function. Since is zero for , the integral simplifies to:
Using integration by parts with and , we find:
This exhibits a power-law decay:
2.3.3.4 Fourier Transform of the Leaky ReLU Function
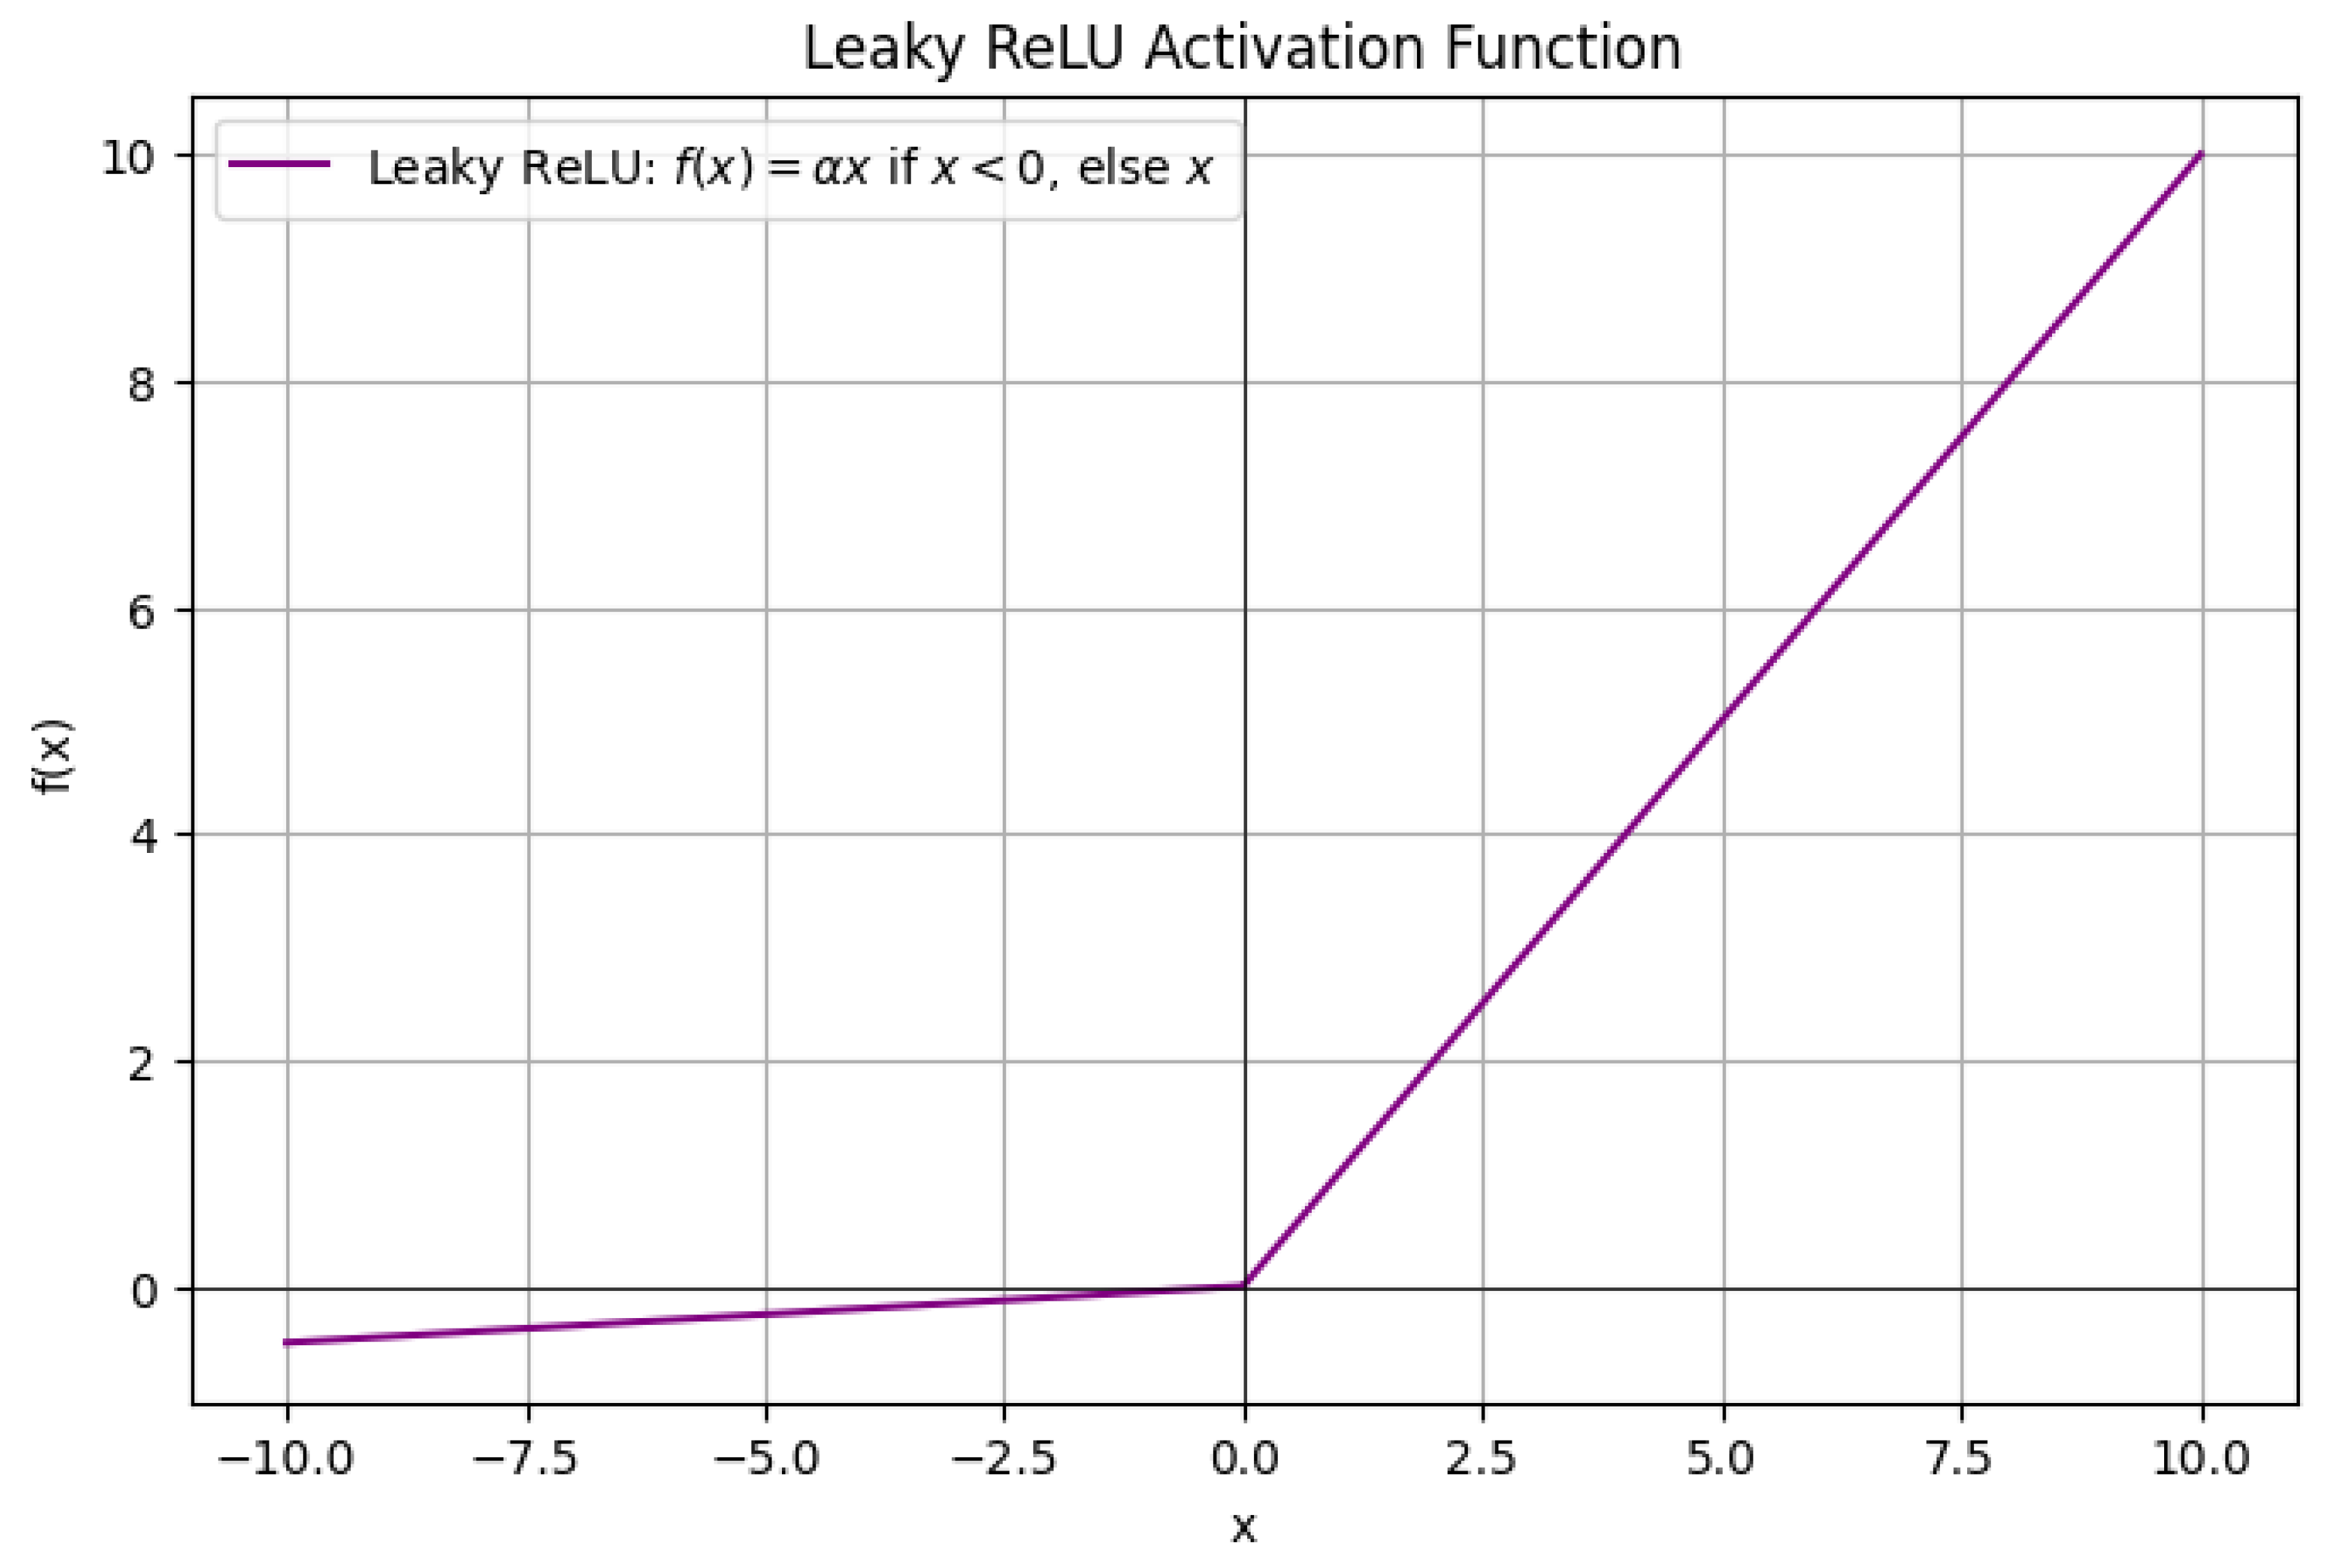
2.3.3.5 Fourier Transform of the Sinusoidal Activation Function
For , the Fourier transform is:
Figure 29.
Sinusoidal Activation Function
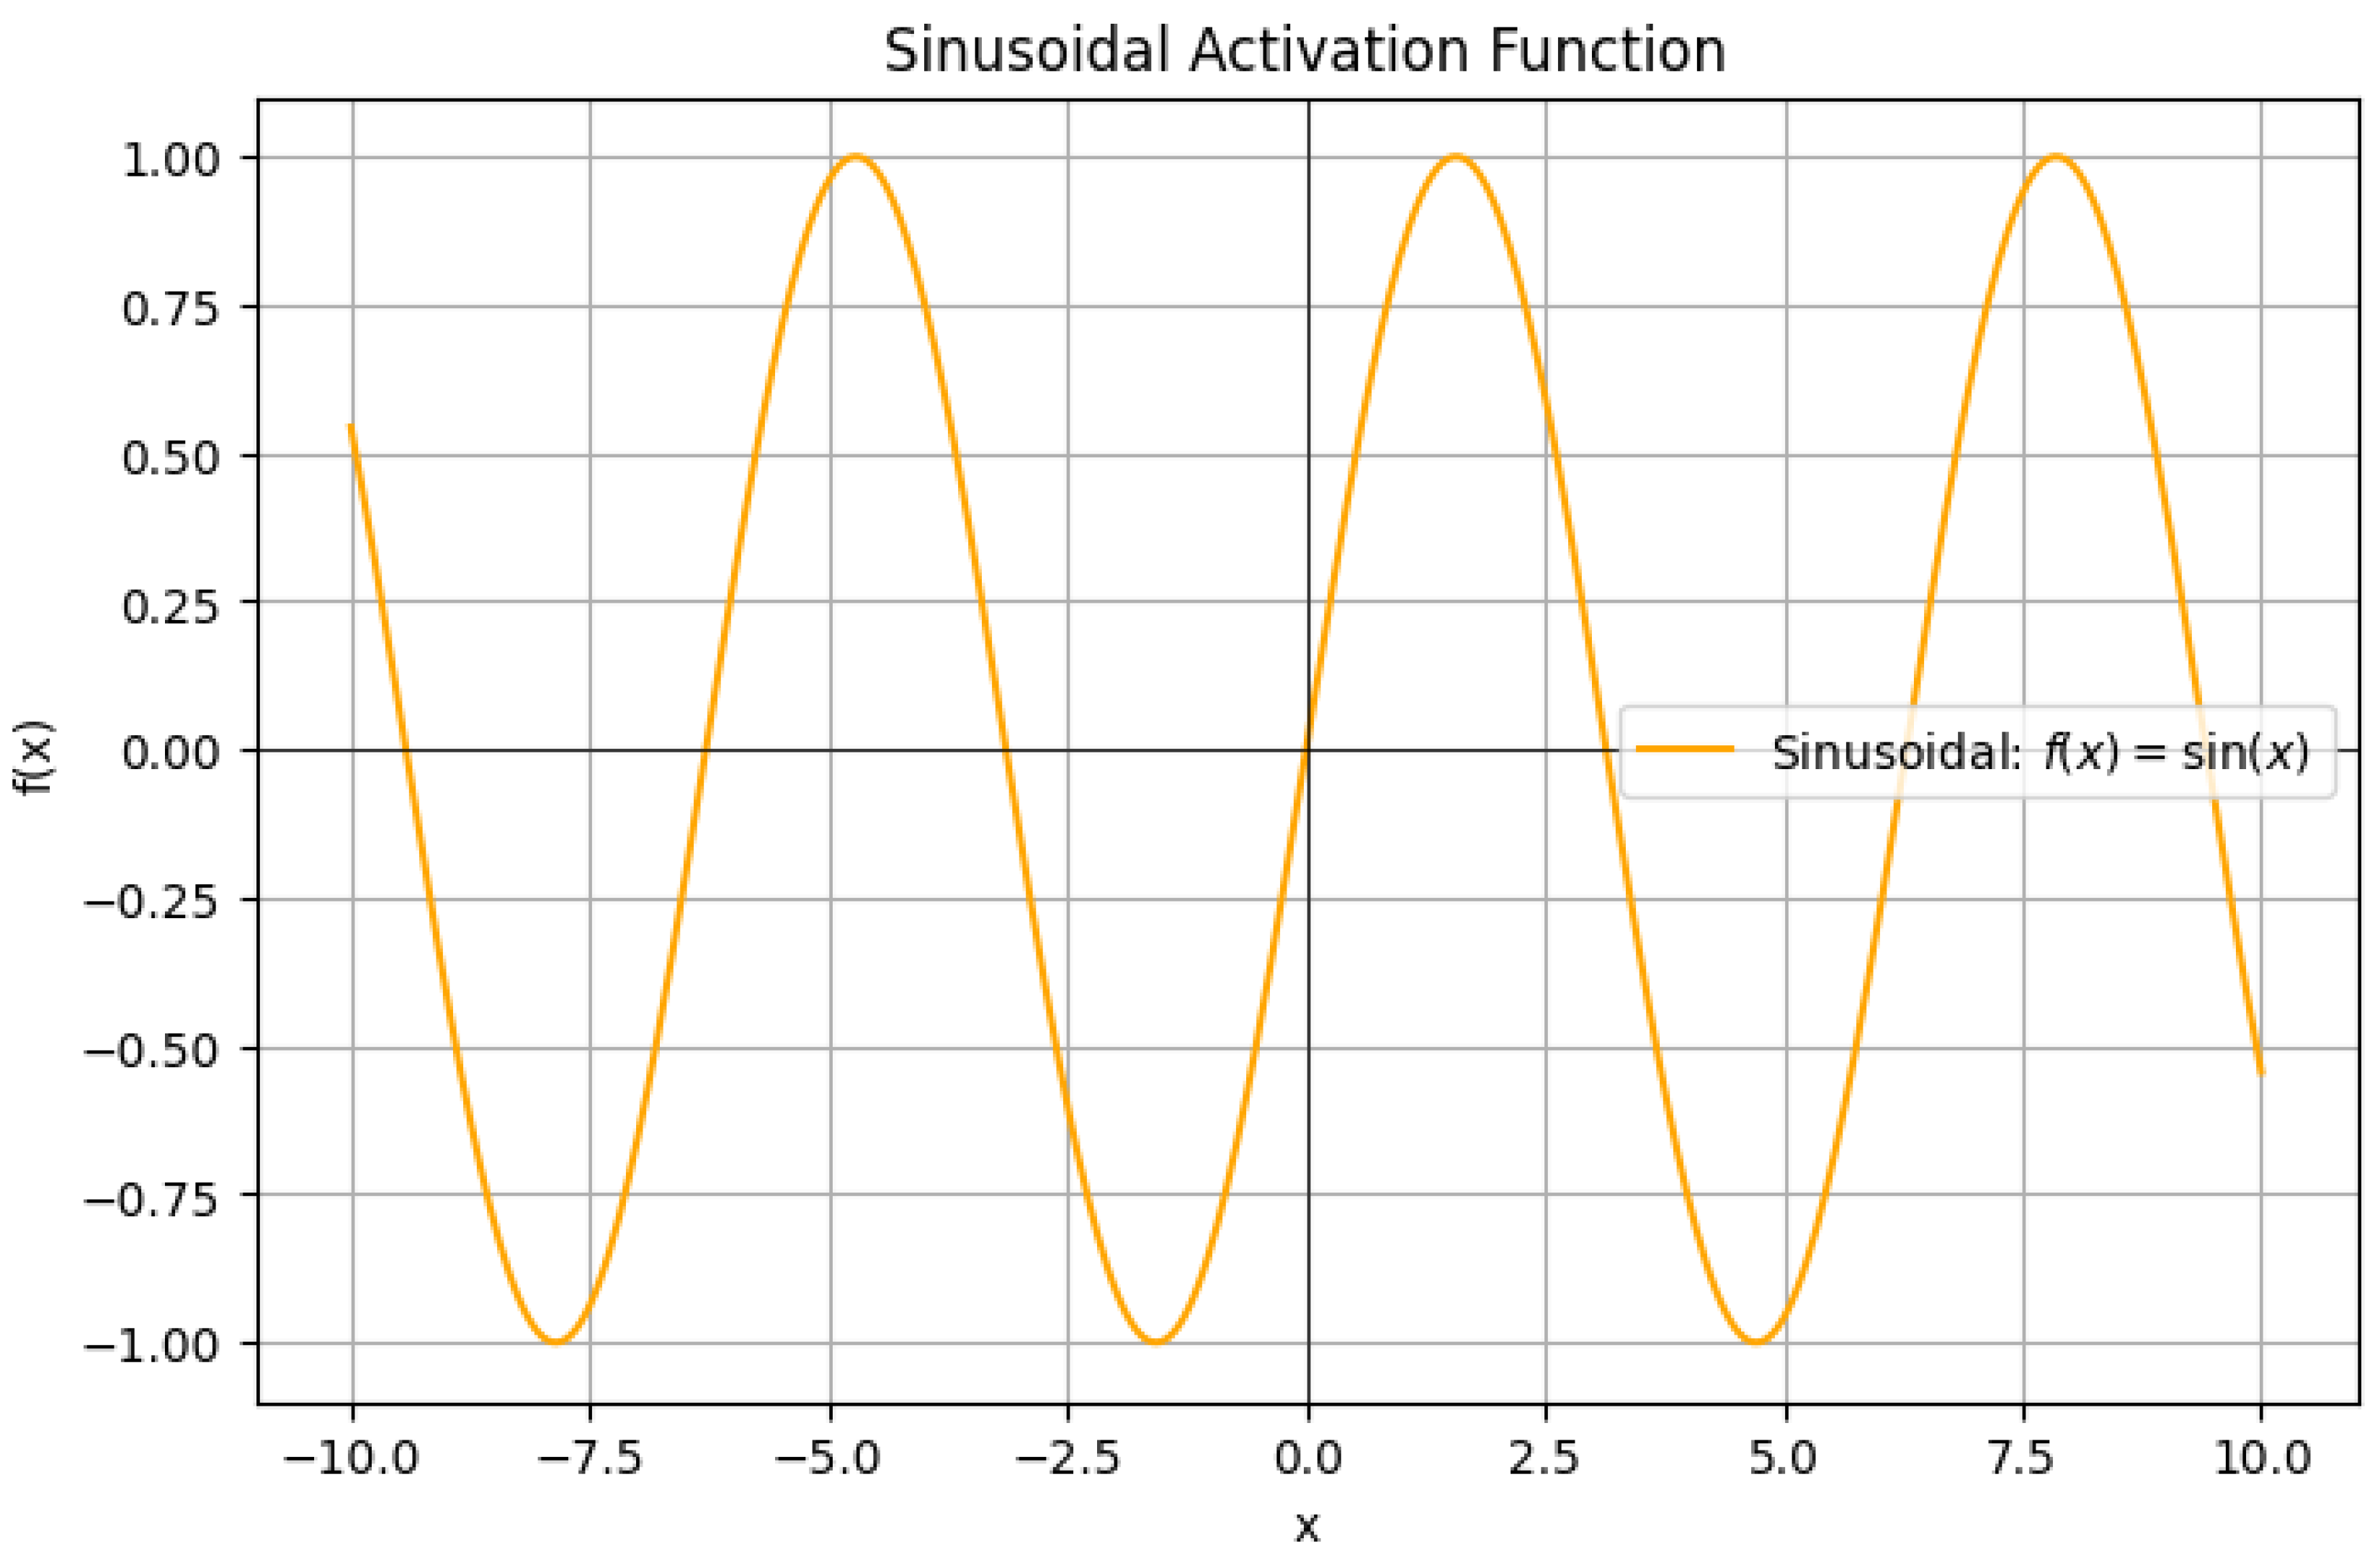
Using the Fourier transform properties of sine:
This shows that the sinusoidal activation function contains only two specific frequencies and does not decay, meaning it retains high-frequency components perfectly.
These rigorous derivations confirm how different activation functions influence the Fourier spectrum of neural networks. The decay properties play a crucial role in determining the network’s ability to learn high- or low-frequency functions.
2.4. The Connection Between Different Mathematics Problems and Deep Learning
2.4.1. Basel Problem and Deep Learning
The Basel Problem is a famous question in mathematical analysis that asks for the sum of the reciprocals of the squares of natural numbers:
Leonhard Euler solved this problem in the 18th century and astonishingly found that the sum converges to , meaning:
This result is remarkable because it links a seemingly simple infinite sum to the fundamental mathematical constant , which is deeply connected to trigonometry and Fourier analysis. A summary of notable proofs given by mathematicians to the Basel problem is given by Ghosh (2020) [698]. A solution to the Basel problem using the Calculus of Residues is given by Ghosh (2021) [800]. In modern mathematics, the Basel Problem’s solution is understood in the broader context of zeta functions, where the Riemann zeta function is defined as:
For , we recover the Basel Problem. The significance of such summations extends far beyond pure mathematics; they appear in areas such as signal processing, numerical analysis, and machine learning. In particular, deep learning models, which fundamentally rely on function approximation and optimization, exhibit connections to the types of series that arise in the Basel Problem, particularly in relation to Fourier series and the decay of spectral components in neural network approximations.
2.4.1.1 The Basel Problem, Fourier Series, and Function Approximation in Deep Learning
One of the most natural places where the Basel Problem appears in applied mathematics is in Fourier series. In Fourier analysis, a periodic function can be decomposed into a sum of sinusoidal functions with different frequencies. The coefficients of these sinusoidal components determine the function’s structure, and their squared magnitudes are directly tied to the Basel-type sums. Specifically, for a function with Fourier expansion:
Parseval’s theorem states that the total energy of the function is given by:
If the function is smooth, the coefficients decay rapidly, often behaving like or faster. The Basel Problem is thus closely related to the rate of decay of Fourier coefficients, which directly impacts how well a function can be approximated using a truncated Fourier series. Deep learning, particularly in neural network function approximation, shares a fundamental connection with Fourier series. Neural networks with sufficient width and depth can approximate arbitrary functions, and recent research has shown that deep networks tend to first learn lower-frequency components before higher frequencies—a phenomenon known as spectral bias. The Basel-type decay of Fourier coefficients is precisely what governs the smoothness of these approximations, meaning that understanding series like the Basel Problem helps us characterize how neural networks generalize and learn complex functions.
2.4.1.2 The Role of the Basel Problem in Regularization and Weight Decay
Another important connection between the Basel Problem and deep learning emerges in the context of regularization techniques, particularly L2 regularization, also known as weight decay. Regularization techniques in neural networks help prevent overfitting by penalizing large weight magnitudes, encouraging smoother function approximations. Mathematically, L2 regularization adds a penalty term to the loss function:
where are the weights of the network, and is a regularization parameter. This penalty ensures that the network does not learn excessively large weights, which could lead to high-frequency oscillations in the approximated function.The sum of squared weights in L2 regularization resembles the Basel-type summation of reciprocal squares. Just as the Basel Problem reflects the decay of Fourier coefficients for smooth functions, L2 regularization ensures that the learned function maintains smoothness by controlling the magnitude of weights. Thus, there is a deep analogy: both involve penalizing high-frequency components to favor smooth, well-behaved solutions.
2.4.1.3 Spectral Bias in Deep Learning and the Basel Problem
One fascinating empirical observation in deep learning is that neural networks naturally prioritize learning lower-frequency components of a function first. This phenomenon, known as spectral bias, is well-studied in the context of deep learning theory. It means that when a neural network is trained on a function, it first learns the dominant, low-frequency parts before capturing finer details at higher frequencies. This is strikingly similar to how the Basel Problem reflects the fundamental nature of low-frequency dominance in function representations. If we consider a function that can be expanded in a Fourier series, the Basel sum describes the contribution of lower-frequency components, which dominate the structure of the function. Similarly, in deep learning, neural networks exhibit behavior where early learning stages prioritize simple, smooth approximations, just as Fourier coefficients with lower indices contribute the most to a function’s overall shape.
Thus, the decay of Fourier coefficients (as described by the Basel Problem) provides an intuition for why neural networks prefer lower frequencies. This insight is valuable in designing deep learning architectures, especially in areas like implicit neural representations (INRs), where Fourier features are explicitly incorporated into the model design to control the spectral bias. While the Basel Problem originates in pure mathematics, its influence extends deeply into areas of applied mathematics, including function approximation, signal processing, and neural networks. The problem’s solution reveals a fundamental truth about how series behave, and this truth manifests in Fourier series, weight decay regularization, and spectral bias in deep learning. The key takeaway is that the Basel Problem describes the natural decay of Fourier coefficients in function approximations, and similar decay patterns emerge in deep learning when training networks to approximate complex functions. Euler’s result continues to play a role in shaping our understanding of function representations in neural networks today.
3. Training Dynamics and NTK Linearization
Training dynamics refers to the evolution of a neural network’s parameters during optimization, typically via gradient descent (GD) or stochastic gradient descent (SGD). Given a neural network with parameters , trained on a dataset , the loss function is minimized using the gradient flow (continuous-time approximation of GD):
The dynamics of the network’s predictions can be described by:
where is the Neural Tangent Kernel (NTK) matrix, defined as:
The NTK governs how small changes in parameters affect the network’s outputs, determining the trajectory of learning in function space.
For wide neural networks, the NTK remains approximately constant during training, leading to a simplified linearized dynamics approximation. Let denote the initial parameters (typically randomly sampled). The first-order Taylor expansion of around yields:
Under this linearization, the training dynamics simplify to kernel gradient descent with a fixed kernel , the NTK at initialization. The evolution of predictions becomes:
where is the initial network output. This shows that the network behaves like a linear model in the infinite-width limit, with convergence governed by the eigendecomposition of . The NTK theory provides a precise characterization of generalization and optimization in overparameterized neural networks, bridging kernel methods and deep learning. The key insight is that despite their nonlinearity, wide neural networks evolve in a regime where their training dynamics are effectively governed by a static, deterministic kernel.
3.1. Python Code to Generate Figure 30 Illustrating the Training Dynamics vs NTK Linearization
The Python code below produces the Figure 30 illustrating the Training Dynamics vs NTK Linearization.
Figure 30.
Training Dynamics vs NTK Linearization
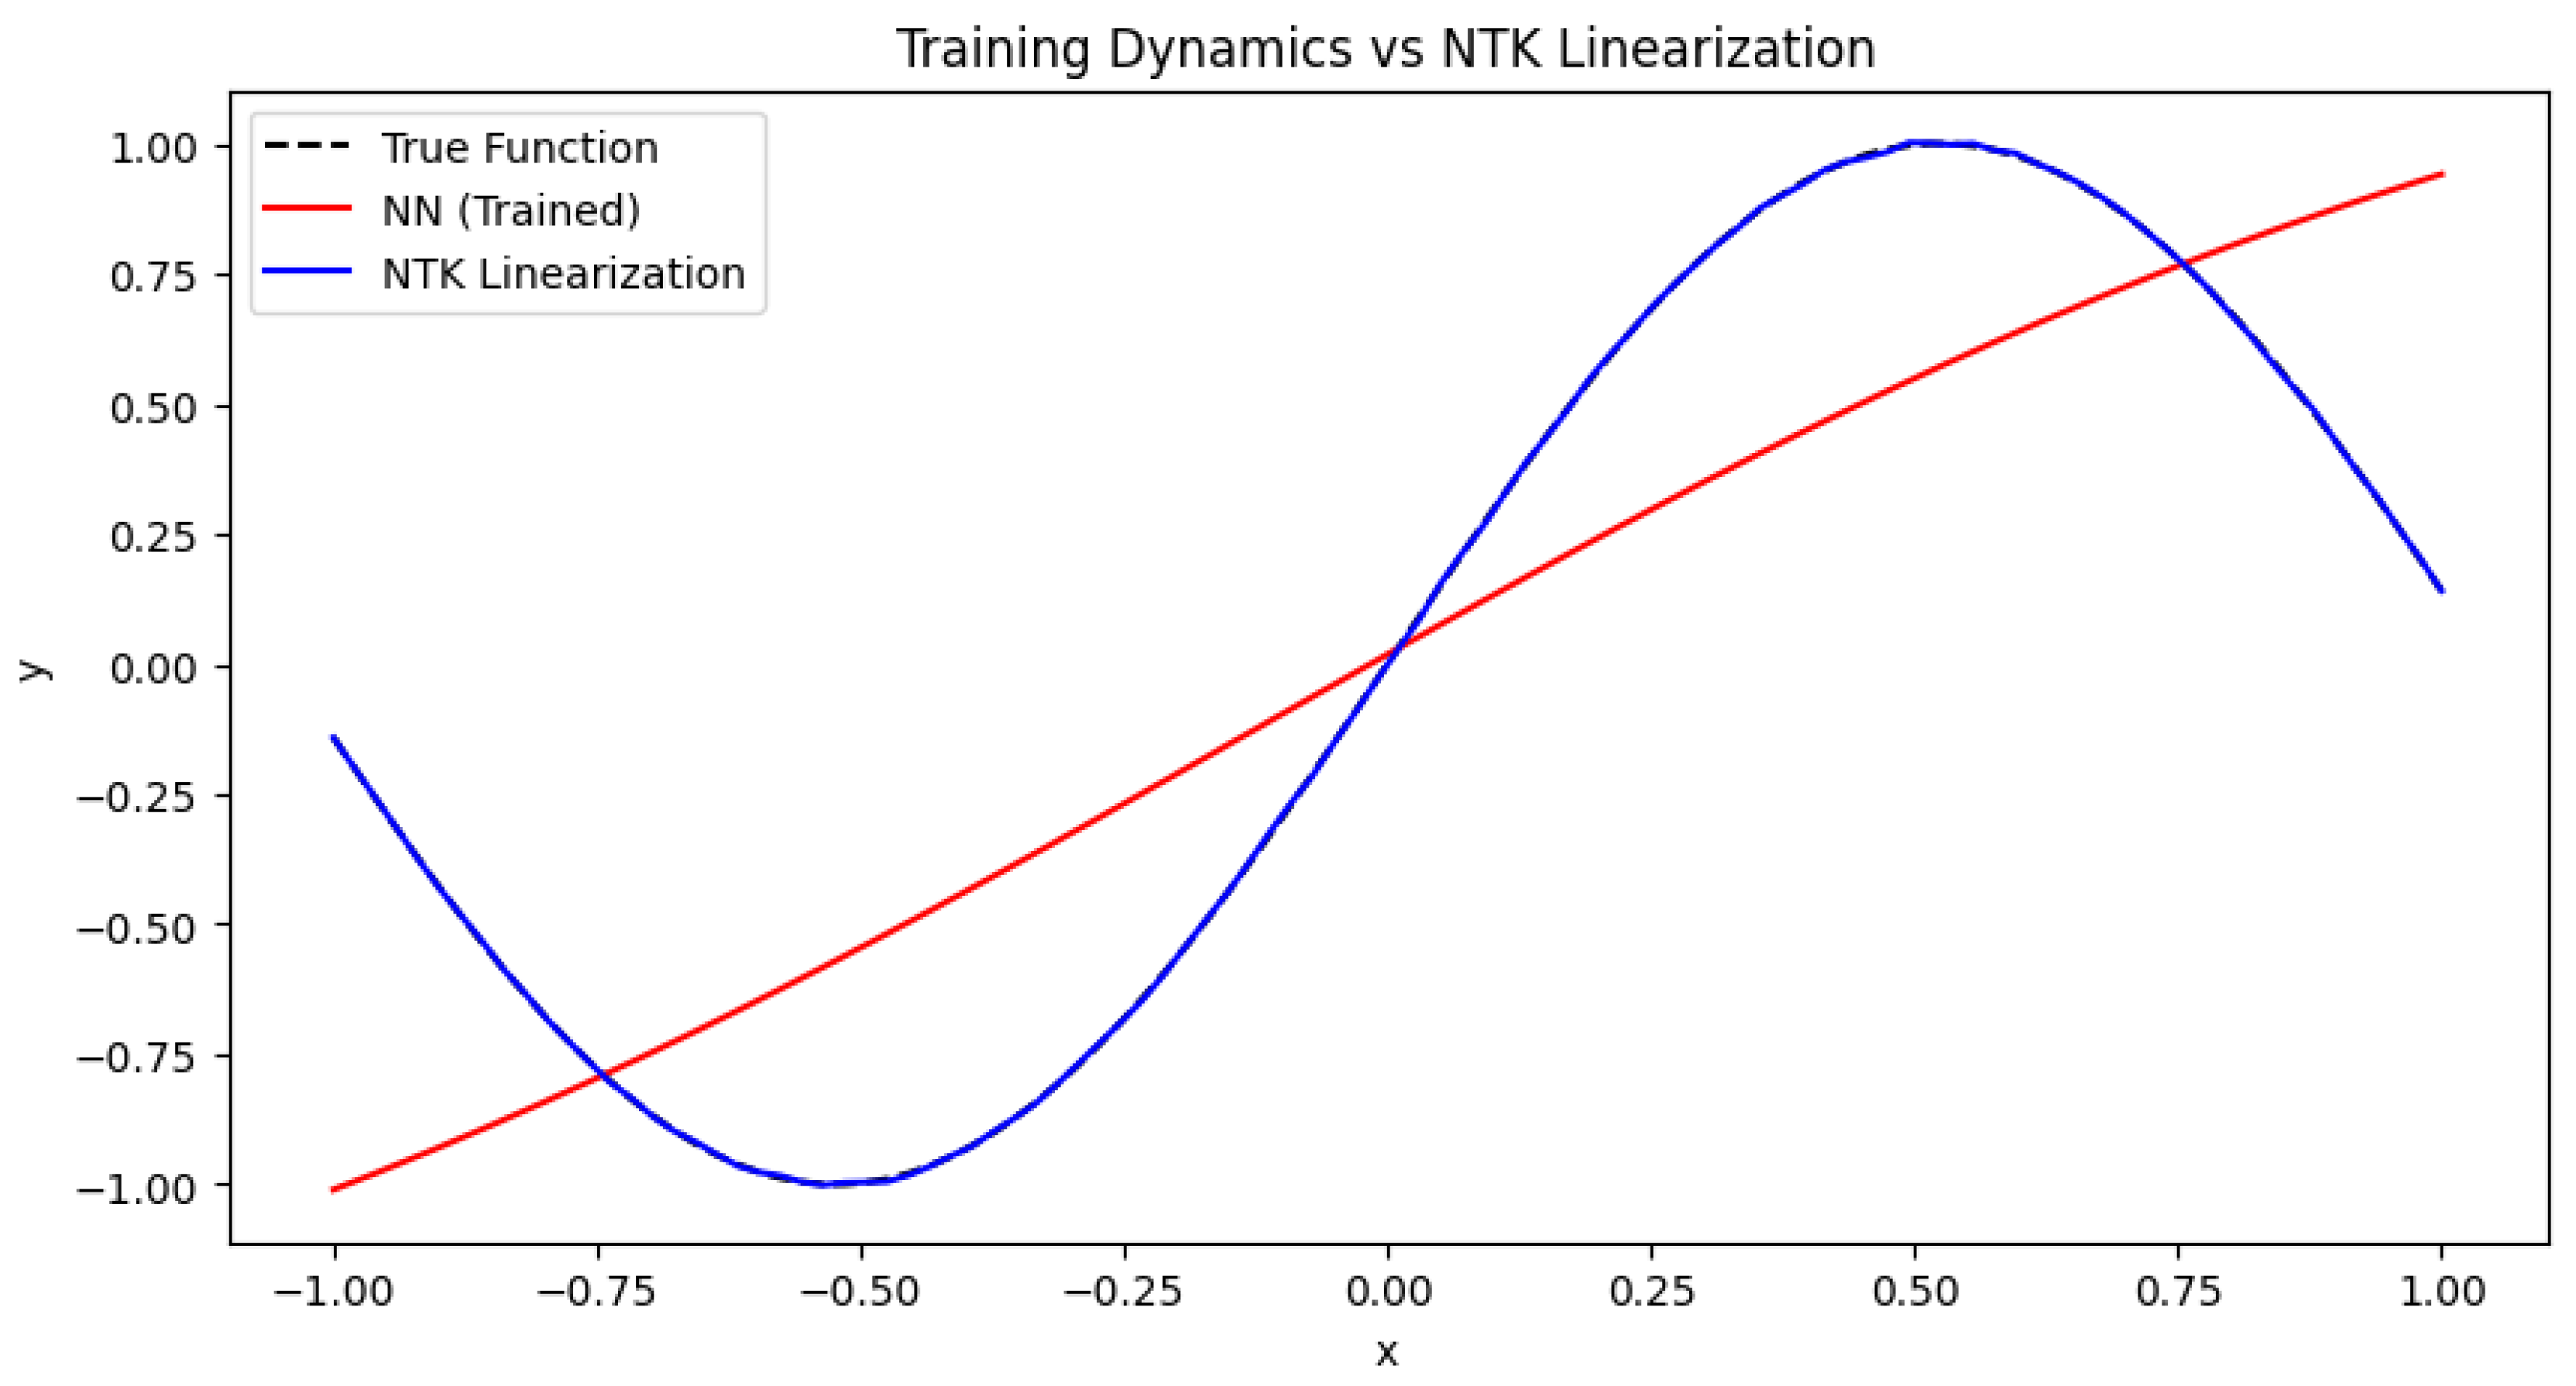
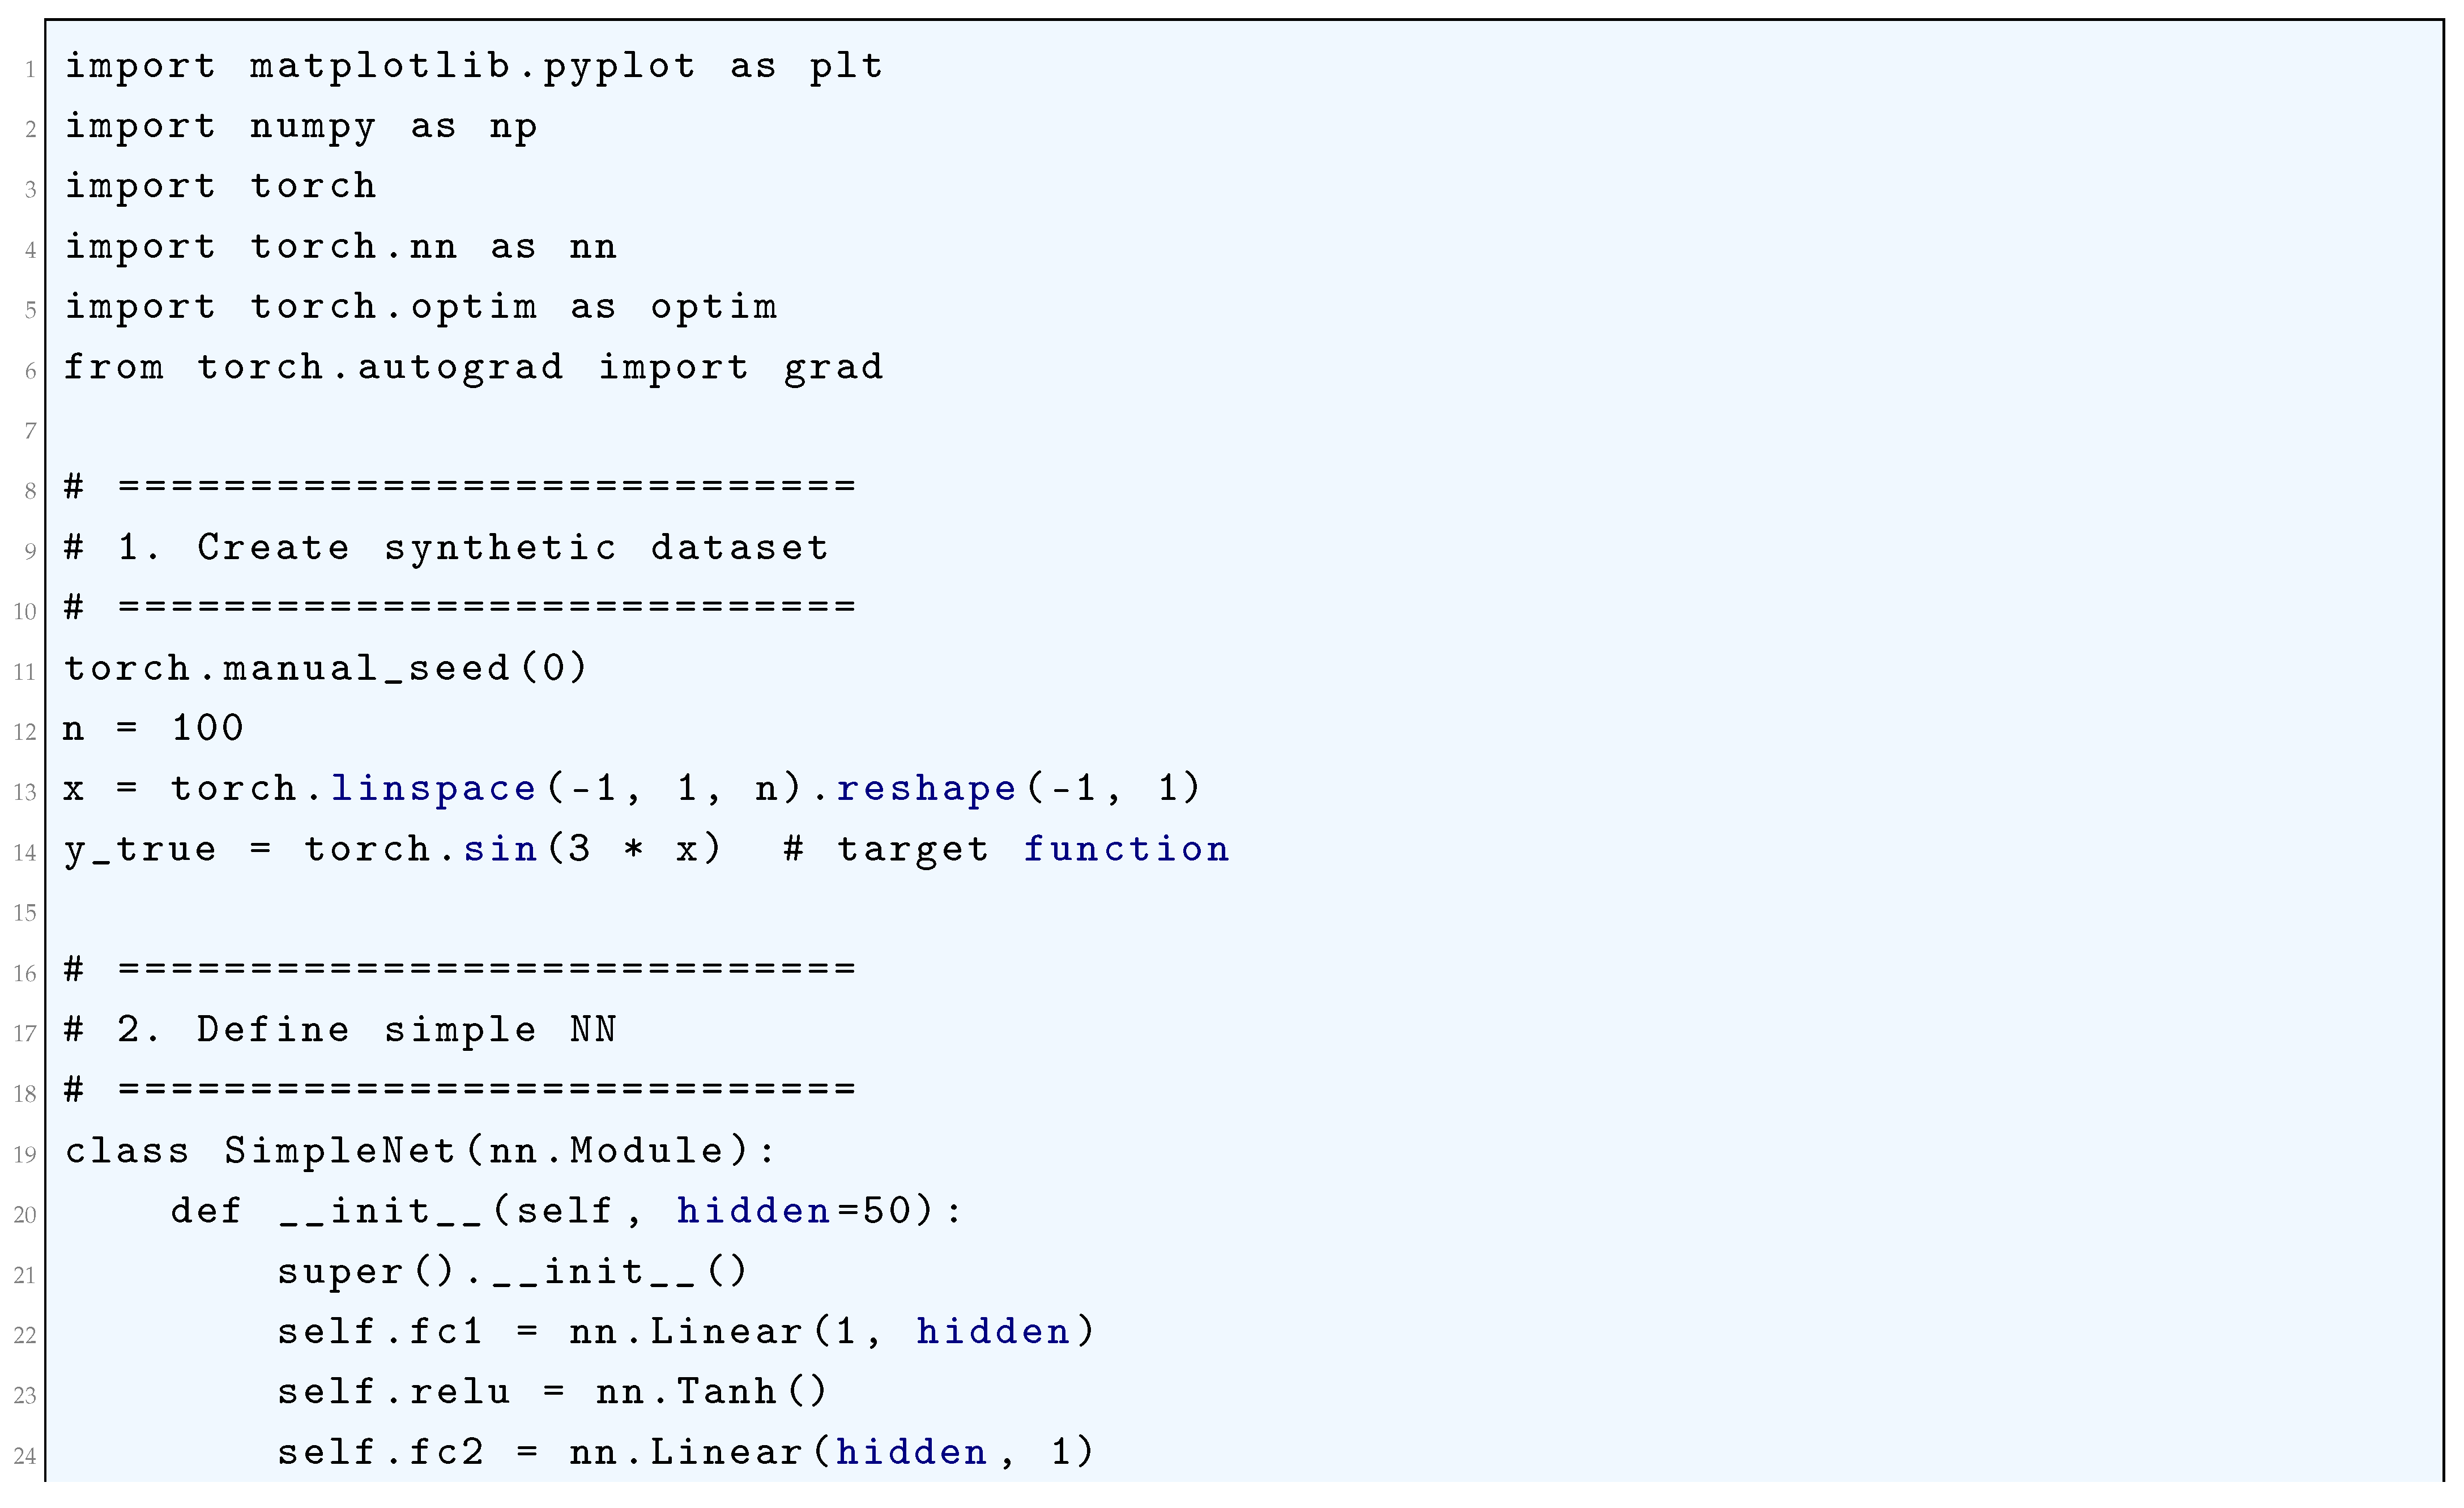
3.2. Literature Review of Training Dynamics and NTK Linearization
Trevisan et. al. [92] investigated how knowledge distillation can be analyzed using the Neural Tangent Kernel (NTK) framework and demonstrated that under certain conditions, the training dynamics of a student model in knowledge distillation closely follow NTK linearization. They explored how NTK affects generalization and feature transfer in the distillation process. They provided theoretical insight into why knowledge distillation improves performance in deep networks. Bonfanti et. al. (2024) [93] studied how NTK behaves in the nonlinear regime, particularly in Physics-Informed Neural Networks (PINNs). They showed that when PINNs operate outside the NTK regime, their performance degrades due to high sensitivity to initialization and weight updates. They established conditions under which NTK linearization is insufficient for PINNs, emphasizing the need for nonlinear adaptations. They provided practical guidelines for designing PINNs that maintain stable training dynamics. Jacot et. al. (2018) [94] introduced the Neural Tangent Kernel (NTK) as a fundamental framework for analyzing infinite-width neural networks. They proved that as width approaches infinity, neural networks evolve as linear models governed by the NTK. They derived generalization bounds for infinitely wide networks and connected training dynamics to kernel methods. They established NTK as a core tool in deep learning theory, leading to further developments in training dynamics research. Lee et. al. (2019) [95] extended NTK theory to arbitrarily deep networks, showing that even deep architectures behave as linear models under gradient descent and proved that training dynamics remain stable regardless of network depth when width is sufficiently large. They explored practical implications for initializing and optimizing deep networks. They strengthened NTK theory by confirming its validity beyond shallow networks. Yang and Hu (2022) [96] challenged the conventional NTK assumption that feature learning is negligible in infinite-width networks and showed that certain activation functions can induce nontrivial feature learning even in infinite-width regimes. They suggested that feature learning can be integrated into NTK theory, opening new directions in kernel-based deep learning research. Xiang et. al. (2023) [97] investigated how finite-width effects impact training dynamics under NTK assumptions and showed that finite-width networks deviate from NTK predictions due to higher-order corrections in weight updates. They derived corrections to NTK theory for practical networks, improving its predictive power for real-world architectures. They refined NTK approximations, making them more applicable to modern deep-learning models. Lee et. al. (2019) [98] extended NTK linearization to deep convolutional networks, analyzing their training dynamics under infinite width and showed how locality and weight sharing in CNNs impact NTK behavior. They also demonstrated practical consequences for CNN training in real-world applications. They bridged NTK theory and convolutional architectures, providing new theoretical tools for CNN analysis.
3.3. Gradient Flow and Stationary Points
3.3.1. Literature Review of Gradient Flow and Stationary Points
Goodfellow et. al. (2016) [120] provided a comprehensive overview of deep learning, including a detailed discussion of gradient-based optimization methods. It rigorously explains the dynamics of gradient descent in the context of neural networks, covering topics such as backpropagation, vanishing gradients, and saddle points. The book also discusses the role of learning rates, momentum, and adaptive optimization methods in shaping the trajectory of gradient flow. Sra et. al. (2012) [492] included several chapters dedicated to the theoretical and practical aspects of gradient-based optimization in machine learning. It provides rigorous mathematical treatments of gradient flow dynamics, including convergence analysis, the impact of stochasticity in stochastic gradient descent (SGD), and the geometry of loss landscapes in high-dimensional spaces. Choromanska et. al. (2015) [493] rigorously analyzed the loss surfaces of deep neural networks. It demonstrates that the loss landscape is highly non-convex but contains a large number of local minima that are close in function value to the global minimum. The paper provides insights into how gradient flow navigates these complex landscapes and why it often converges to satisfactory solutions despite the non-convexity. Arora et al. (2019) [494] provided a theoretical framework for understanding the dynamics of gradient descent in deep neural networks. It rigorously analyzes the role of overparameterization in enabling gradient flow to converge to global minima, even in the absence of explicit regularization. The paper also explores the implicit regularization effects of gradient descent and their impact on generalization. Du et. al. (2019) [485] establishes theoretical guarantees for the convergence of gradient descent to global minima in overparameterized neural networks. It rigorously proves that gradient flow can efficiently minimize the training loss to zero, even in the presence of non-convexity, by leveraging the high-dimensional geometry of the loss landscape. The authors provided a rigorous analysis of the exponential convergence of gradient descent in overparameterized neural networks. It shows that the gradient flow dynamics are characterized by a rapid decrease in the loss function, driven by the alignment of the network’s parameters with the data. The paper also discusses the role of initialization in shaping the trajectory of gradient flow. Zhang et al. (2017) [463] challenged traditional notions of generalization in deep learning. It rigorously demonstrates that deep neural networks can fit random labels, suggesting that the dynamics of gradient flow are not solely driven by the data distribution but also by the implicit biases of the optimization algorithm. The paper highlights the importance of understanding how gradient flow interacts with the architecture and initialization of neural networks. Baratin et. al. (2020) [495] explored the implicit regularization effects of gradient flow in deep learning from the perspective of function space. It rigorously demonstrates that gradient descent in overparameterized models tends to converge to solutions that minimize certain norms or complexity measures, providing insights into why these models generalize well despite their capacity to overfit. Balduzzi et al. (2018) [496] extended the analysis of gradient flow to multi-agent optimization problems, such as those encountered in generative adversarial networks (GANs). It rigorously characterizes the dynamics of gradient descent in games, highlighting the role of rotational forces and the challenges of convergence in non-cooperative settings. The paper provides tools for understanding how gradient flow behaves in complex, interactive learning scenarios. Allen-Zhu et al. (2019) [487] provided a rigorous convergence theory for deep learning models trained with gradient descent. It shows that overparameterization enables gradient flow to avoid bad local minima and converge to global minima efficiently. The paper also analyzes the role of initialization, step size, and network depth in shaping the dynamics of gradient descent.
3.3.2. Analysis of Gradient Flow and Stationary Points
The dynamics of gradient flow in neural network training are fundamentally governed by the continuous evolution of parameters under the influence of the negative gradient of the loss function, expressed as
The loss function, typically of the form
measures the discrepancy between the network’s predicted outputs and the true labels . At stationary points of the flow, the condition
holds, indicating that the gradient vanishes. To classify these stationary points, the Hessian matrix is examined. For eigenvalues of H, the nature of the stationary point is determined: for all i corresponds to a local minimum, for all i to a local maximum, and mixed signs indicate a saddle point.Under gradient flow , the trajectory converges to critical points:
The gradient flow also governs the temporal evolution of the network’s predictions . A Taylor series expansion of about an initial parameter gives:
where is the Jacobian and is the Hessian of with respect to .
In the NTK (neural tangent kernel) regime, higher-order terms are negligible due to the large parameterization of the network, and the linear approximation suffices:
Under gradient flow, the time derivative of the network’s predictions is given by:
Substituting the parameter dynamics , this becomes:
Defining the NTK as , and assuming constancy of the NTK during training (), the evolution equation simplifies to:
Rewriting in matrix form, let and . The NTK matrix evaluated at initialization defines the system:
The solution to this linear system is:
As , the predictions converge to the labels: , implying zero training error. The eigenvalues of determine the rates of convergence. Diagonalizing as , where Q is orthogonal and , the dynamics in the eigenbasis are:
with and . Solving, we obtain:
Each mode decays exponentially with a rate proportional to the eigenvalue . Modes with larger converge faster, while smaller eigenvalues slow convergence.
The NTK framework thus rigorously explains the linearization of training dynamics in overparameterized neural networks. This linear behavior ensures that the optimization trajectory remains within a convex region of the parameter space, leading to both convergence and generalization. By leveraging the constancy of the NTK, the complexity of nonlinear neural networks is reduced to an analytically tractable framework that aligns closely with empirical observations.
3.3.3. Hessian Structure
The Hessian matrix, , serves as a critical construct in the mathematical framework of optimization, capturing the second-order partial derivatives of the loss function with respect to the parameter vector . Each element reflects the curvature of the loss surface along the -direction. The symmetry of , guaranteed by the Schwarz theorem under the assumption of continuous second partial derivatives, implies . This property ensures that the eigenvalues of are real and the eigenvectors are orthogonal, satisfying the eigenvalue equation
The behavior of the loss function around a specific parameter value can be rigorously analyzed using a second-order Taylor expansion. This expansion is given by:
Here, the term represents the linear variation of the loss, while the quadratic term describes the curvature effects. The eigenvalues of dictate the nature of the critical point . Specifically, if all , is a local minimum; if all , it is a local maximum; and if the eigenvalues have mixed signs, is a saddle point. The leading-order approximation to the change in the loss function, , highlights the dependence on the eigenstructure of . In the context of gradient descent, parameter updates follow the iterative scheme:
where is the learning rate. Substituting the Taylor expansion of around gives:
To analyze this update rigorously, we project onto the eigenbasis of , expressing it as:
where . Substituting this expansion into the gradient descent update rule yields:
The convergence of this iterative scheme is governed by the condition , which constrains the learning rate relative to the spectrum of . For eigenvalues with large magnitudes, excessively large learning rates can cause oscillatory or divergent updates.
In the Neural Tangent Kernel (NTK) regime, the evolution of a neural network during training can be approximated by a linearization of the network output around the initialization. Let denote the output of the network for input x. Linearizing around gives:
The NTK, defined as:
remains approximately constant during training for sufficiently wide networks. The training dynamics of the parameters are described by:
which, under the NTK approximation, becomes:
where K is the NTK matrix evaluated at initialization. The evolution of the loss function is governed by the eigenvalues of K, which control the rate of convergence in different directions.
The spectral properties of the Hessian play a pivotal role in the generalization properties of neural networks. Empirical studies reveal that the eigenvalue spectrum of often exhibits a "bulk-and-spike" structure, with a dense bulk of eigenvalues near zero and a few large outliers. The bulk corresponds to flat directions in the loss landscape, which contribute to the robustness and generalization of the model, while the spikes represent sharp directions associated with overfitting. This spectral structure can be analyzed using random matrix theory, where the density of eigenvalues is modeled by distributions such as the Marchenko-Pastur law:
where are the spectral bounds and is the ratio of the number of parameters to the number of data points. This rigorous analysis links the Hessian structure to both the optimization dynamics and the generalization performance of neural networks, providing a comprehensive mathematical understanding of the training process. The Hessian satisfies:
For overparameterized networks, is nearly degenerate, implying the existence of flat minima.
3.3.4. NTK Linearization
The dynamics of neural networks under gradient flow can be comprehensively described by beginning with the parameterized representation of the network , where denotes the set of trainable parameters, is the input, and represents the output. The objective of training is to minimize a loss function , defined over a dataset , where and represent the input-target pairs. The evolution of the parameters during training is governed by the gradient flow equation , where is the gradient of the loss function with respect to the parameters. To analyze the dynamics of the network outputs, we first consider the time derivative of . Using the chain rule, this is expressed as:
Substituting , we have:
The gradient of the loss function, , can be expressed explicitly in terms of the training data. For a generic loss function over the dataset, this takes the form:
where represents the loss for the i-th data point. The gradient of the loss with respect to the parameters is therefore given by:
Substituting this back into the time derivative of , we obtain:
To introduce the Neural Tangent Kernel (NTK), we define it as the Gram matrix of the Jacobians of the network output with respect to the parameters:
Using this definition, the time evolution of the output becomes:
In the overparameterized regime, where the number of parameters p is significantly larger than the number of training data points n, it has been empirically and theoretically observed that the NTK remains nearly constant during training.
Specifically, , where represents the parameters at initialization. This constancy significantly simplifies the analysis of the network’s training dynamics. To see this, consider the solution to the differential equation governing the output dynamics. Let represent the matrix of network outputs for all training inputs, where the i-th row corresponds to . The dynamics can be expressed in matrix form as:
where is the NTK matrix evaluated at initialization, and is the gradient of the loss with respect to the output matrix F. For the special case of a mean squared error loss, , where is the matrix of target outputs, the gradient simplifies to:
Substituting this into the dynamics, we obtain:
The solution to this differential equation is:
where represents the initial outputs of the network. As , the exponential term vanishes, and the network outputs converge to the targets Y, provided that is positive definite. The rate of convergence is determined by the eigenvalues of , with smaller eigenvalues corresponding to slower convergence along the associated eigenvectors. To understand the stationary points of this system, we note that these occur when . From the dynamics, this implies:
If is invertible, this yields , indicating that the network exactly interpolates the training data at the stationary point. However, if is not full-rank, the stationary points form a subspace of solutions satisfying , where is the projection operator onto the column space of .
The NTK framework provides a mathematically rigorous lens to analyze training dynamics, elucidating the interplay between parameter evolution, kernel properties, and loss convergence in neural networks. By linearizing the training dynamics through the NTK, we achieve a deep understanding of how overparameterized networks evolve under gradient flow and how they reach stationary points, revealing their capacity to interpolate data with remarkable precision.
3.3.5. Python Code to Generate Figure 31 Illustrating the Gradient Flow and Stationary Points
The Python code below produces the Figure 31 illustrating the Gradient Flow and Stationary Points.
Figure 31.
Gradient Flow and Stationary Points
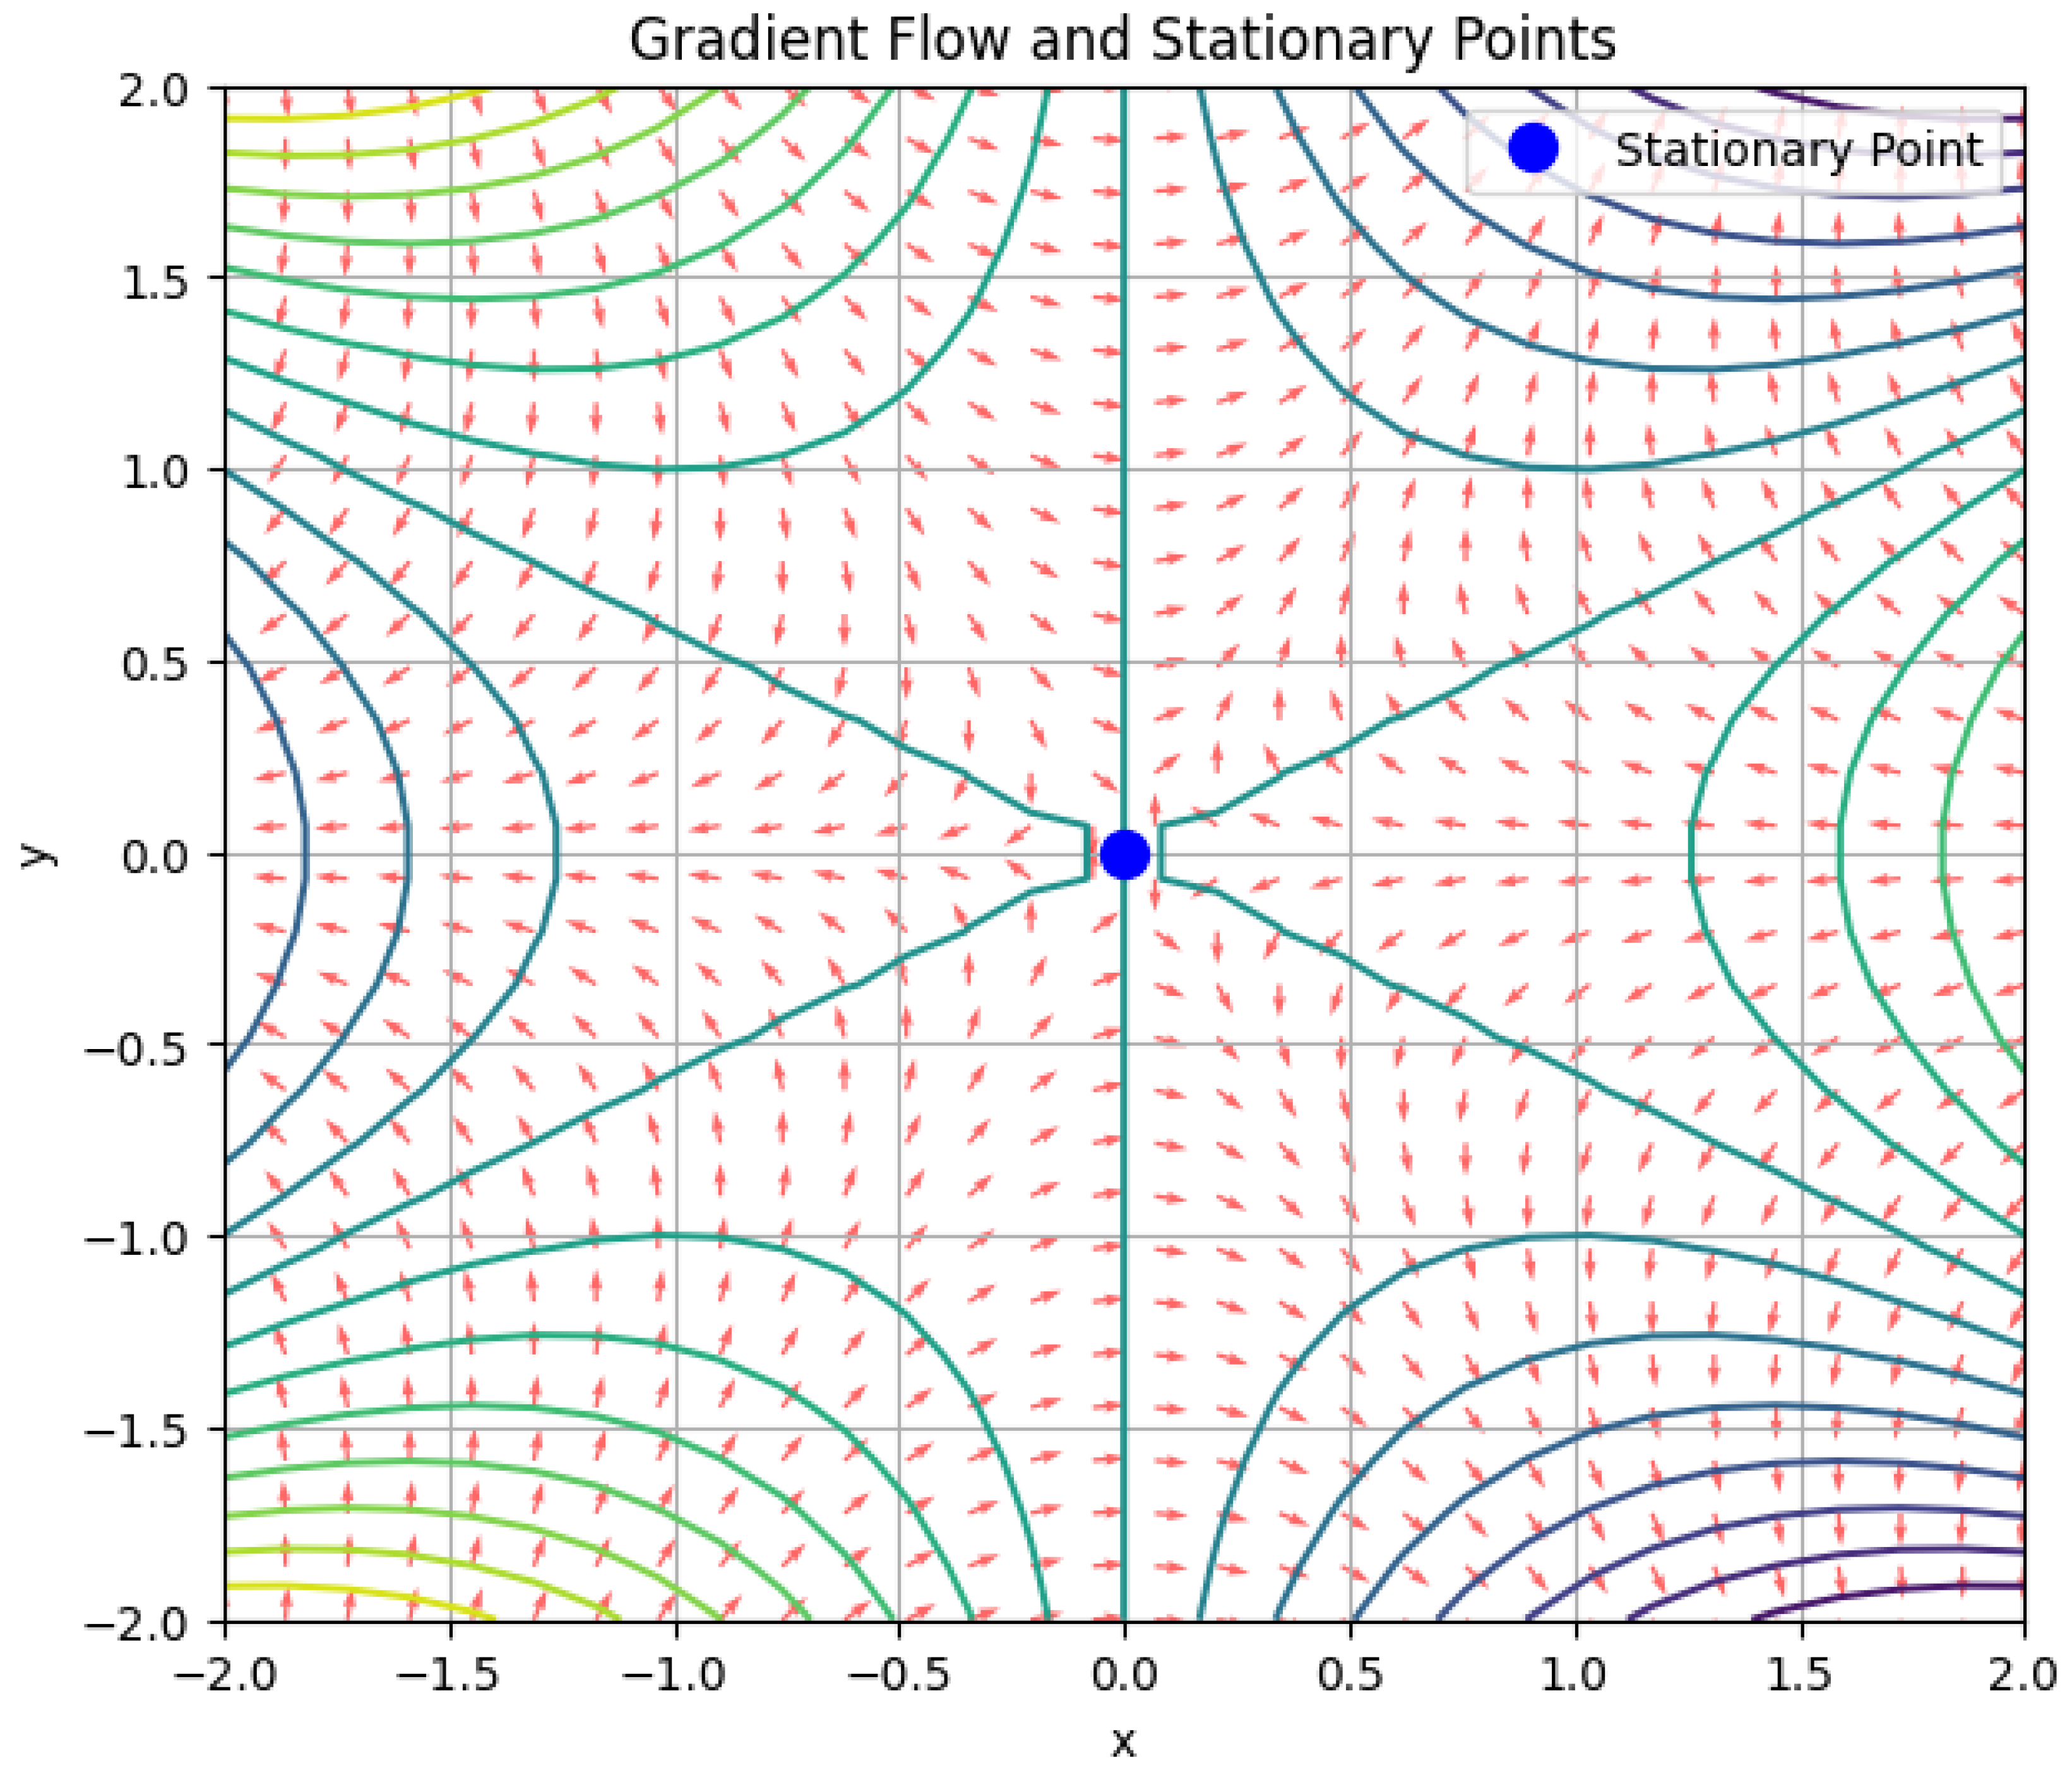
3.3.6. Python Code to Generate Figure 32 and Figure 33 Illustrating the Hessian Structure
Figure 32.
Hessian Structure (NTK Regime) & NTK Matrix
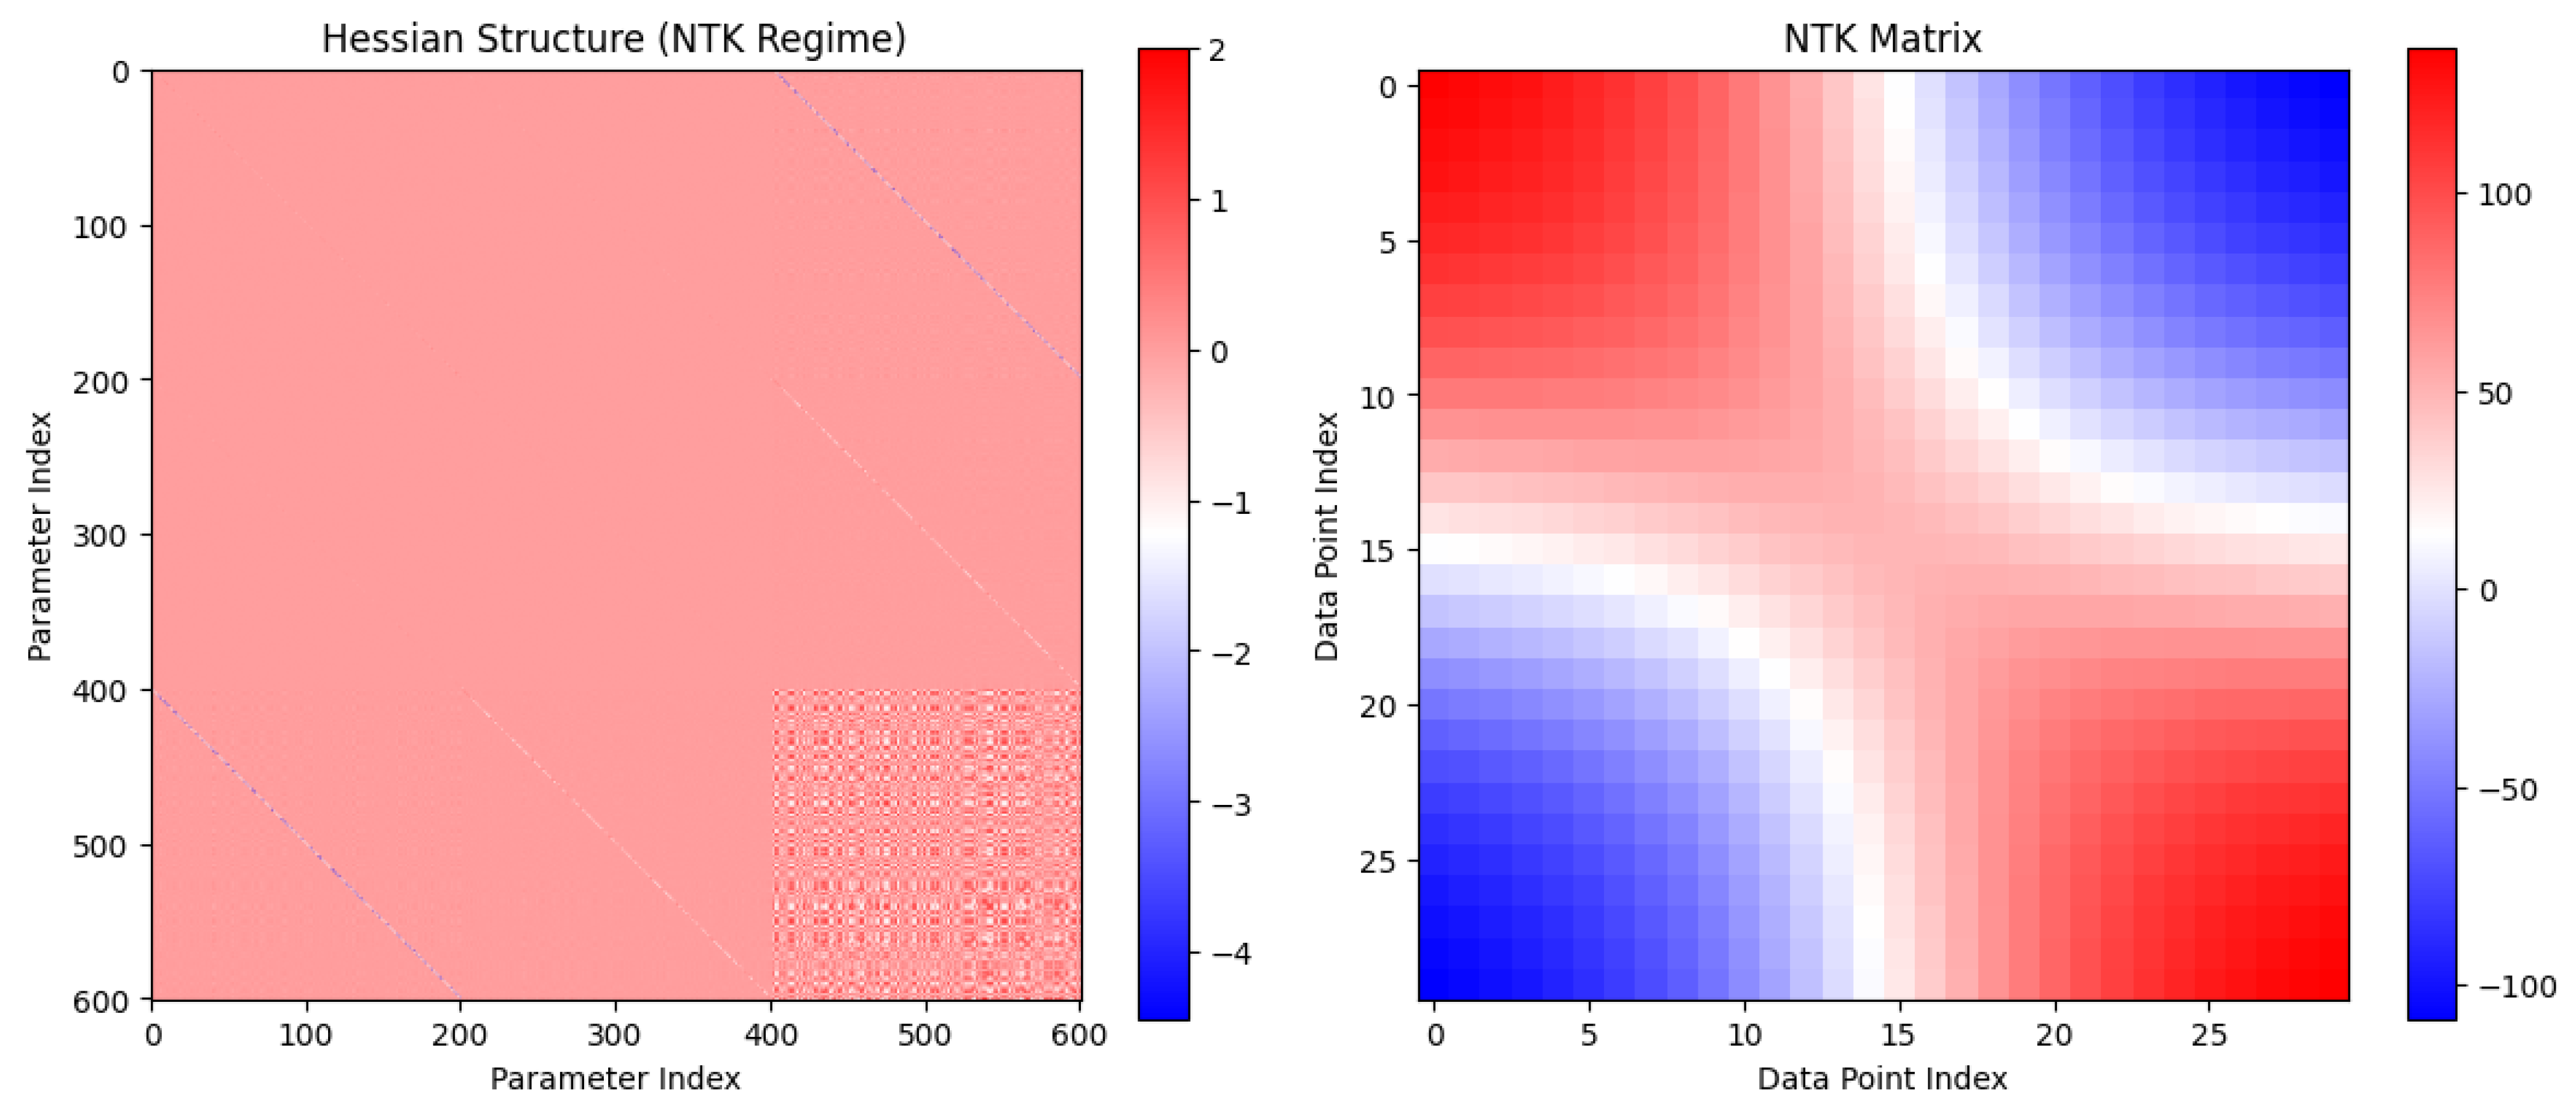
Figure 33.
Hessian Spectrum (NTK Regime)
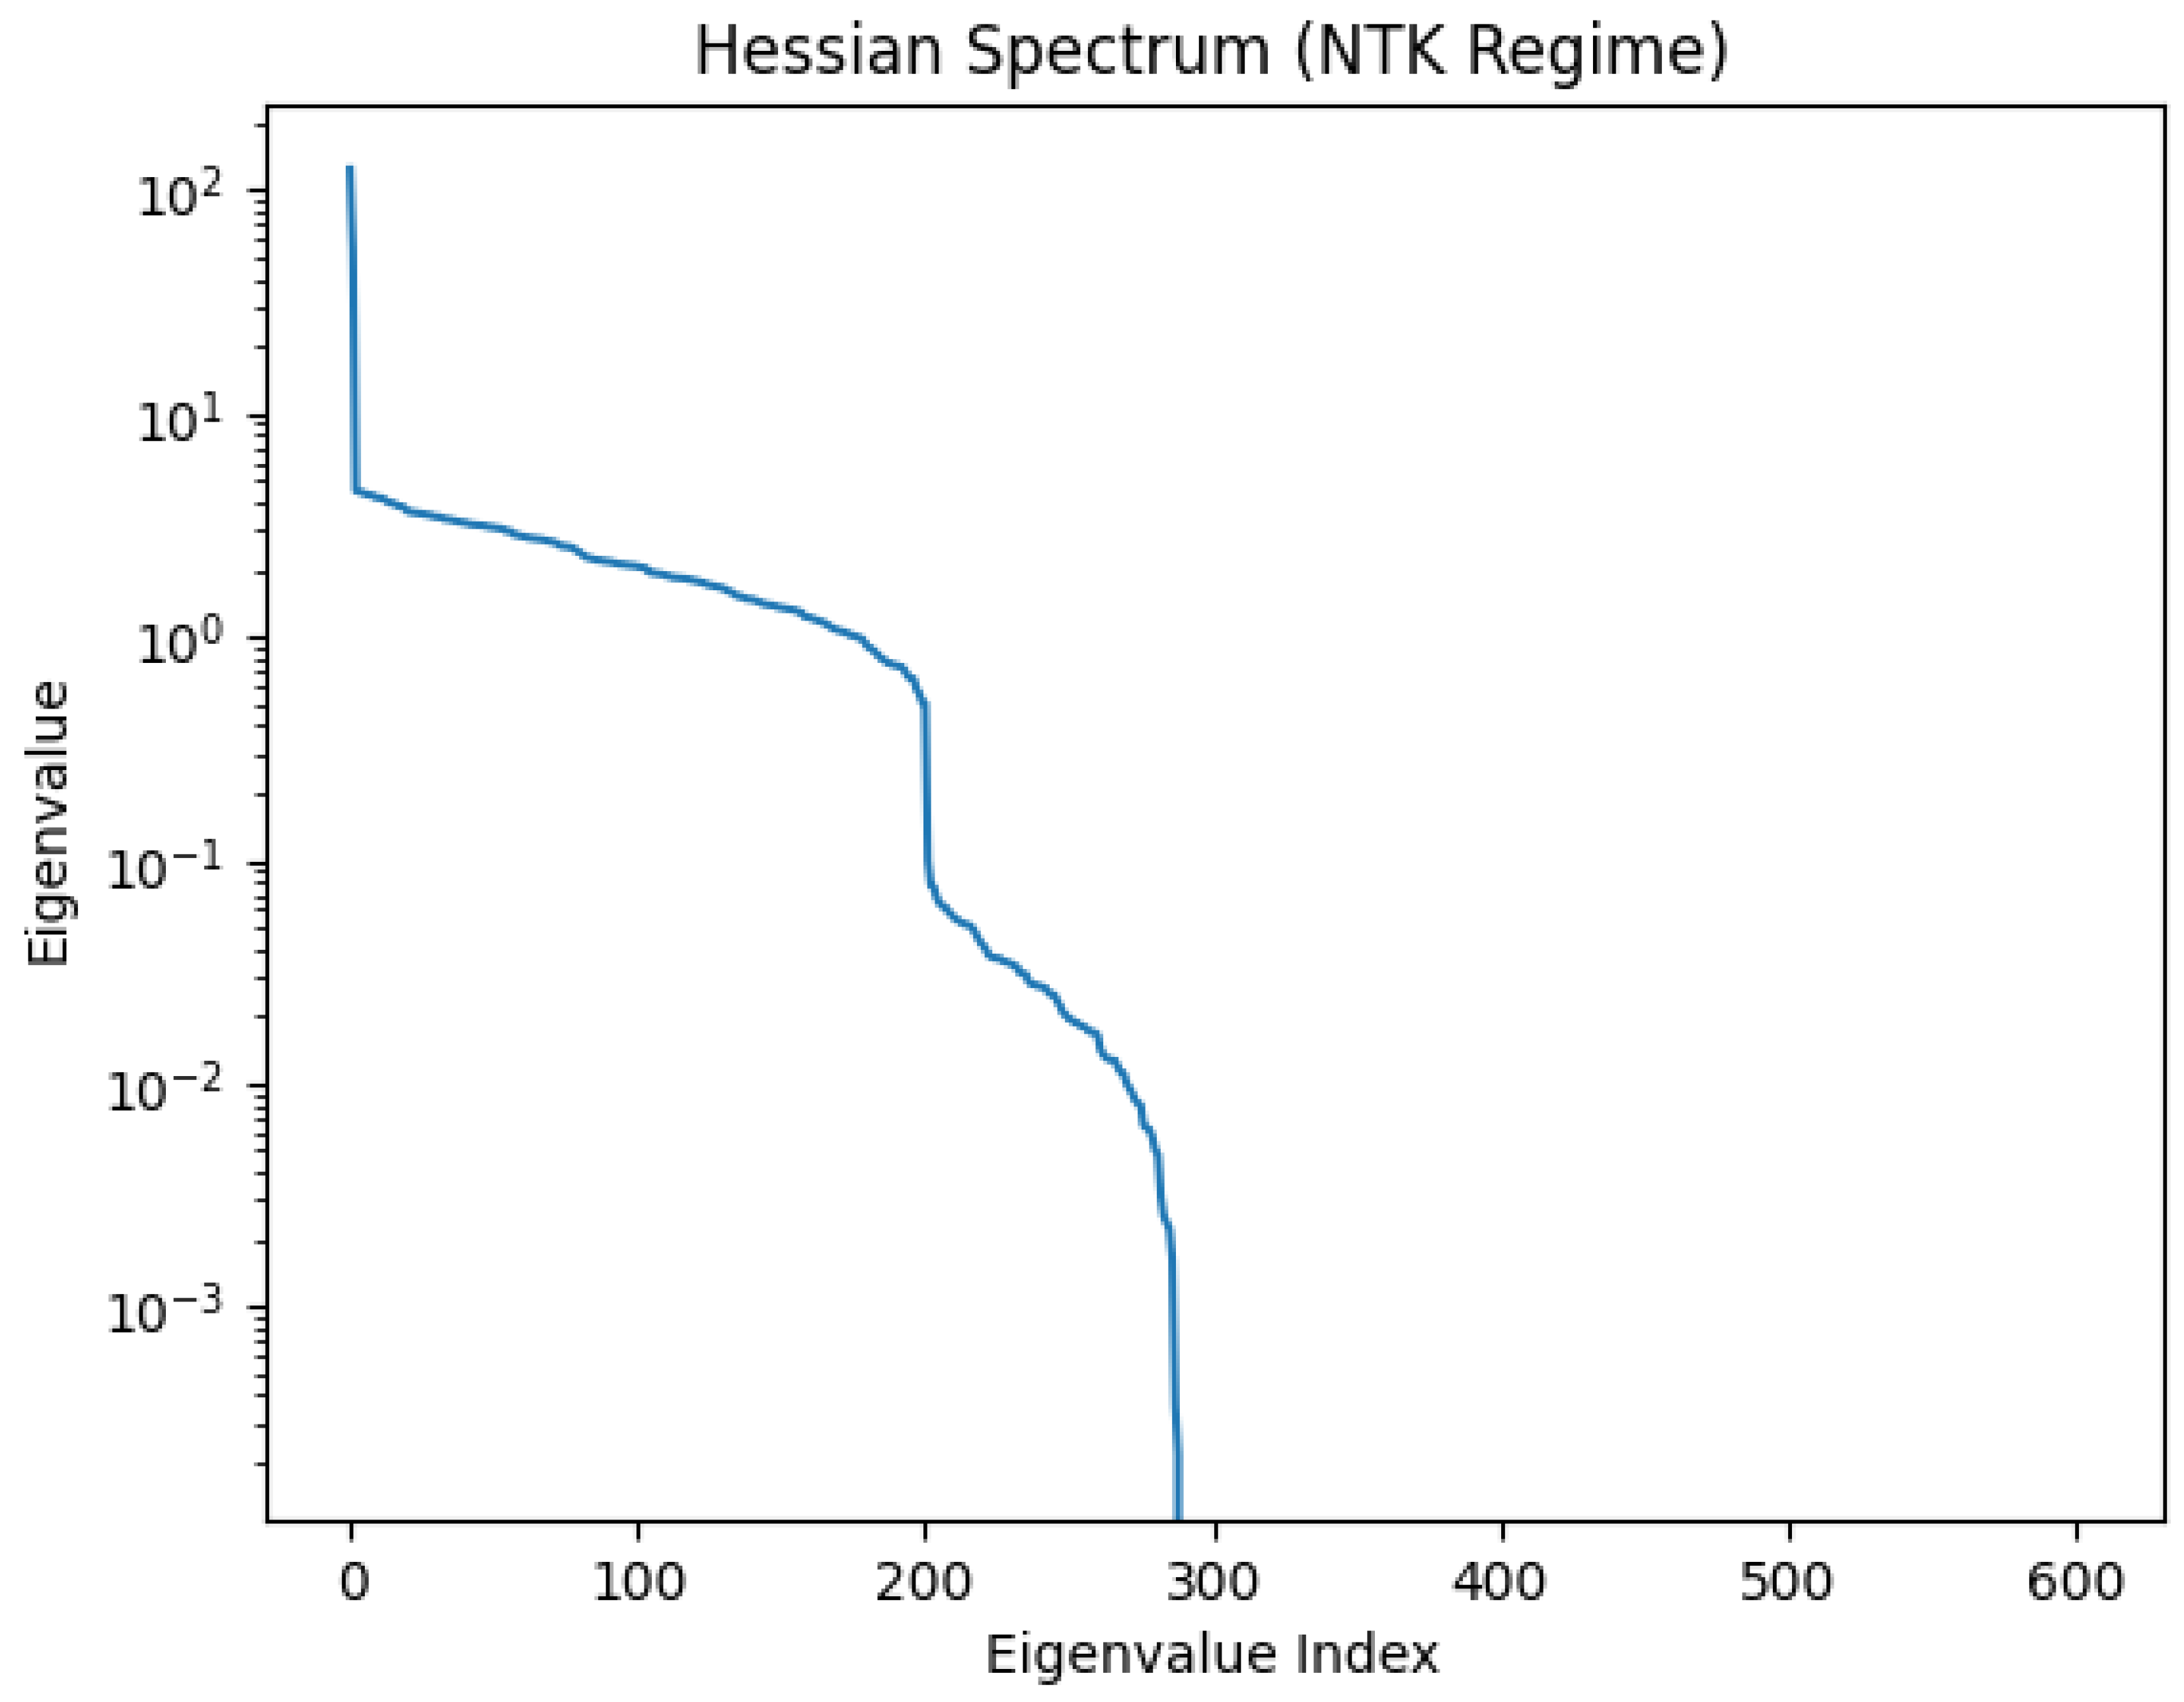
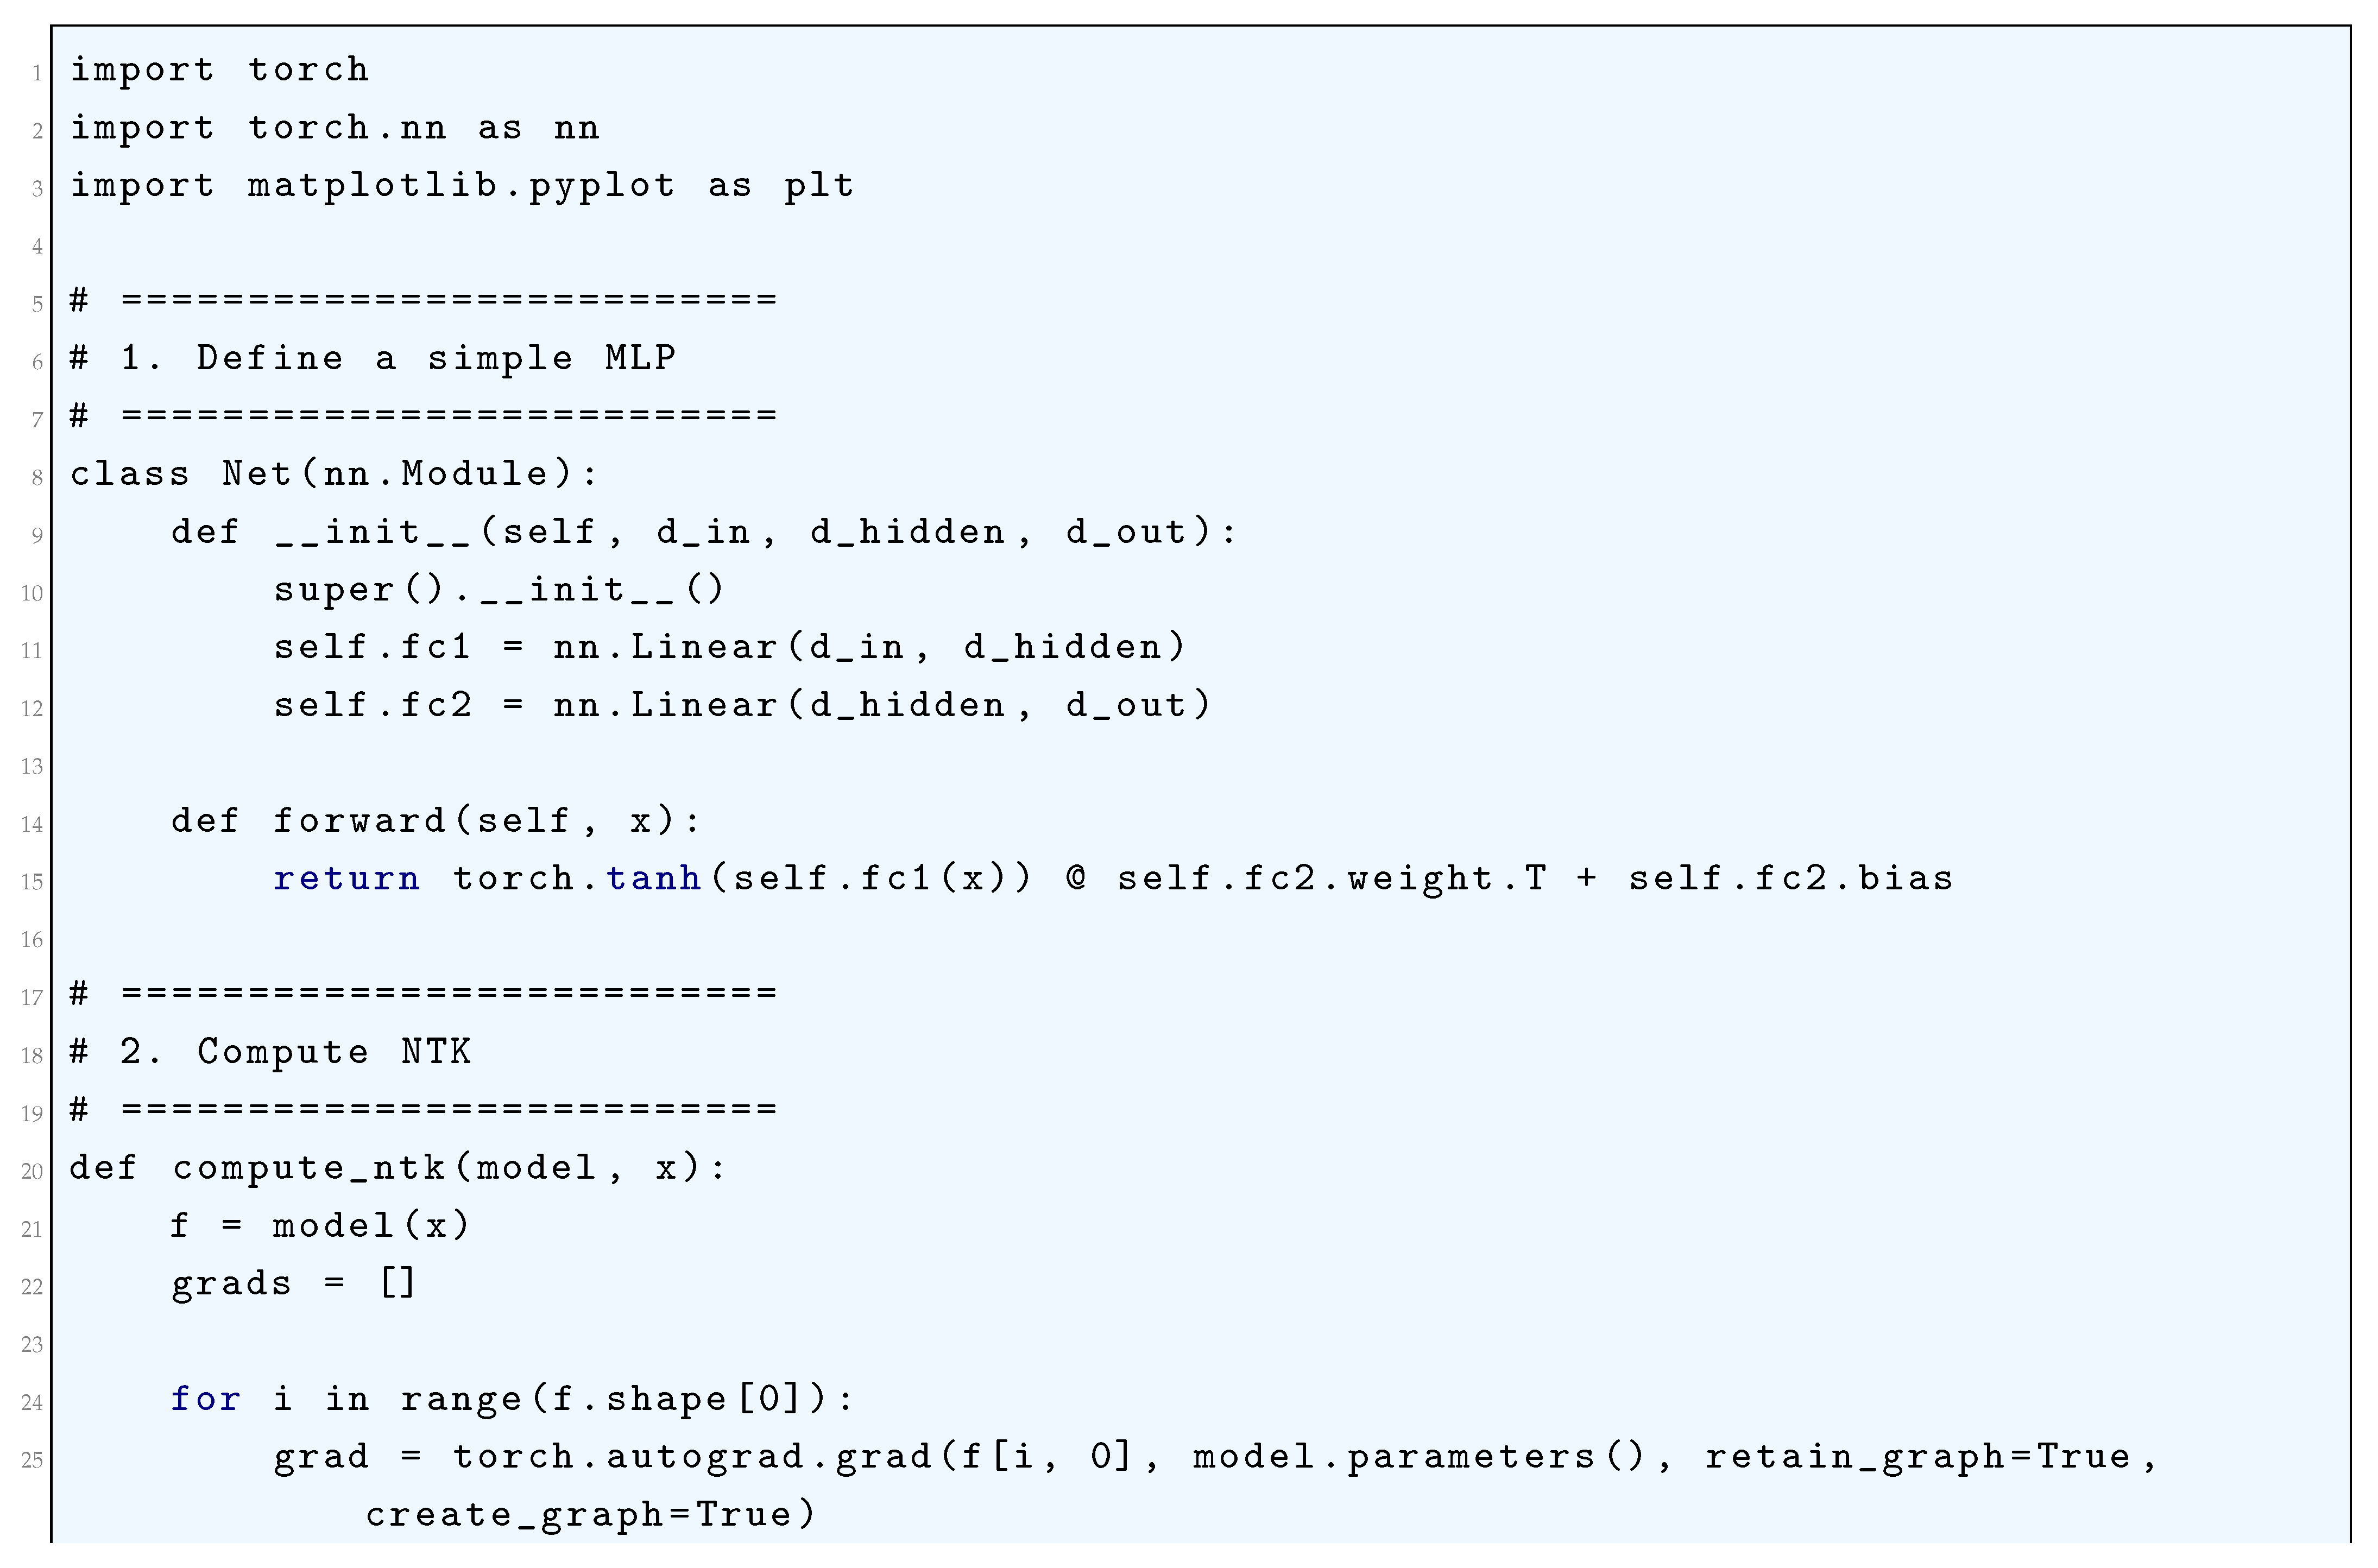
3.3.7. Python Code to Generate Figure 34 Illustrating the Final Fit & Training Dynamics (NN vs NTK)
The Python code below produces the Figure 34 illustrating the Final Fit & Training Dynamics (NN vs NTK).
Figure 34.
Final Fit & Training Dynamics (NN vs NTK)
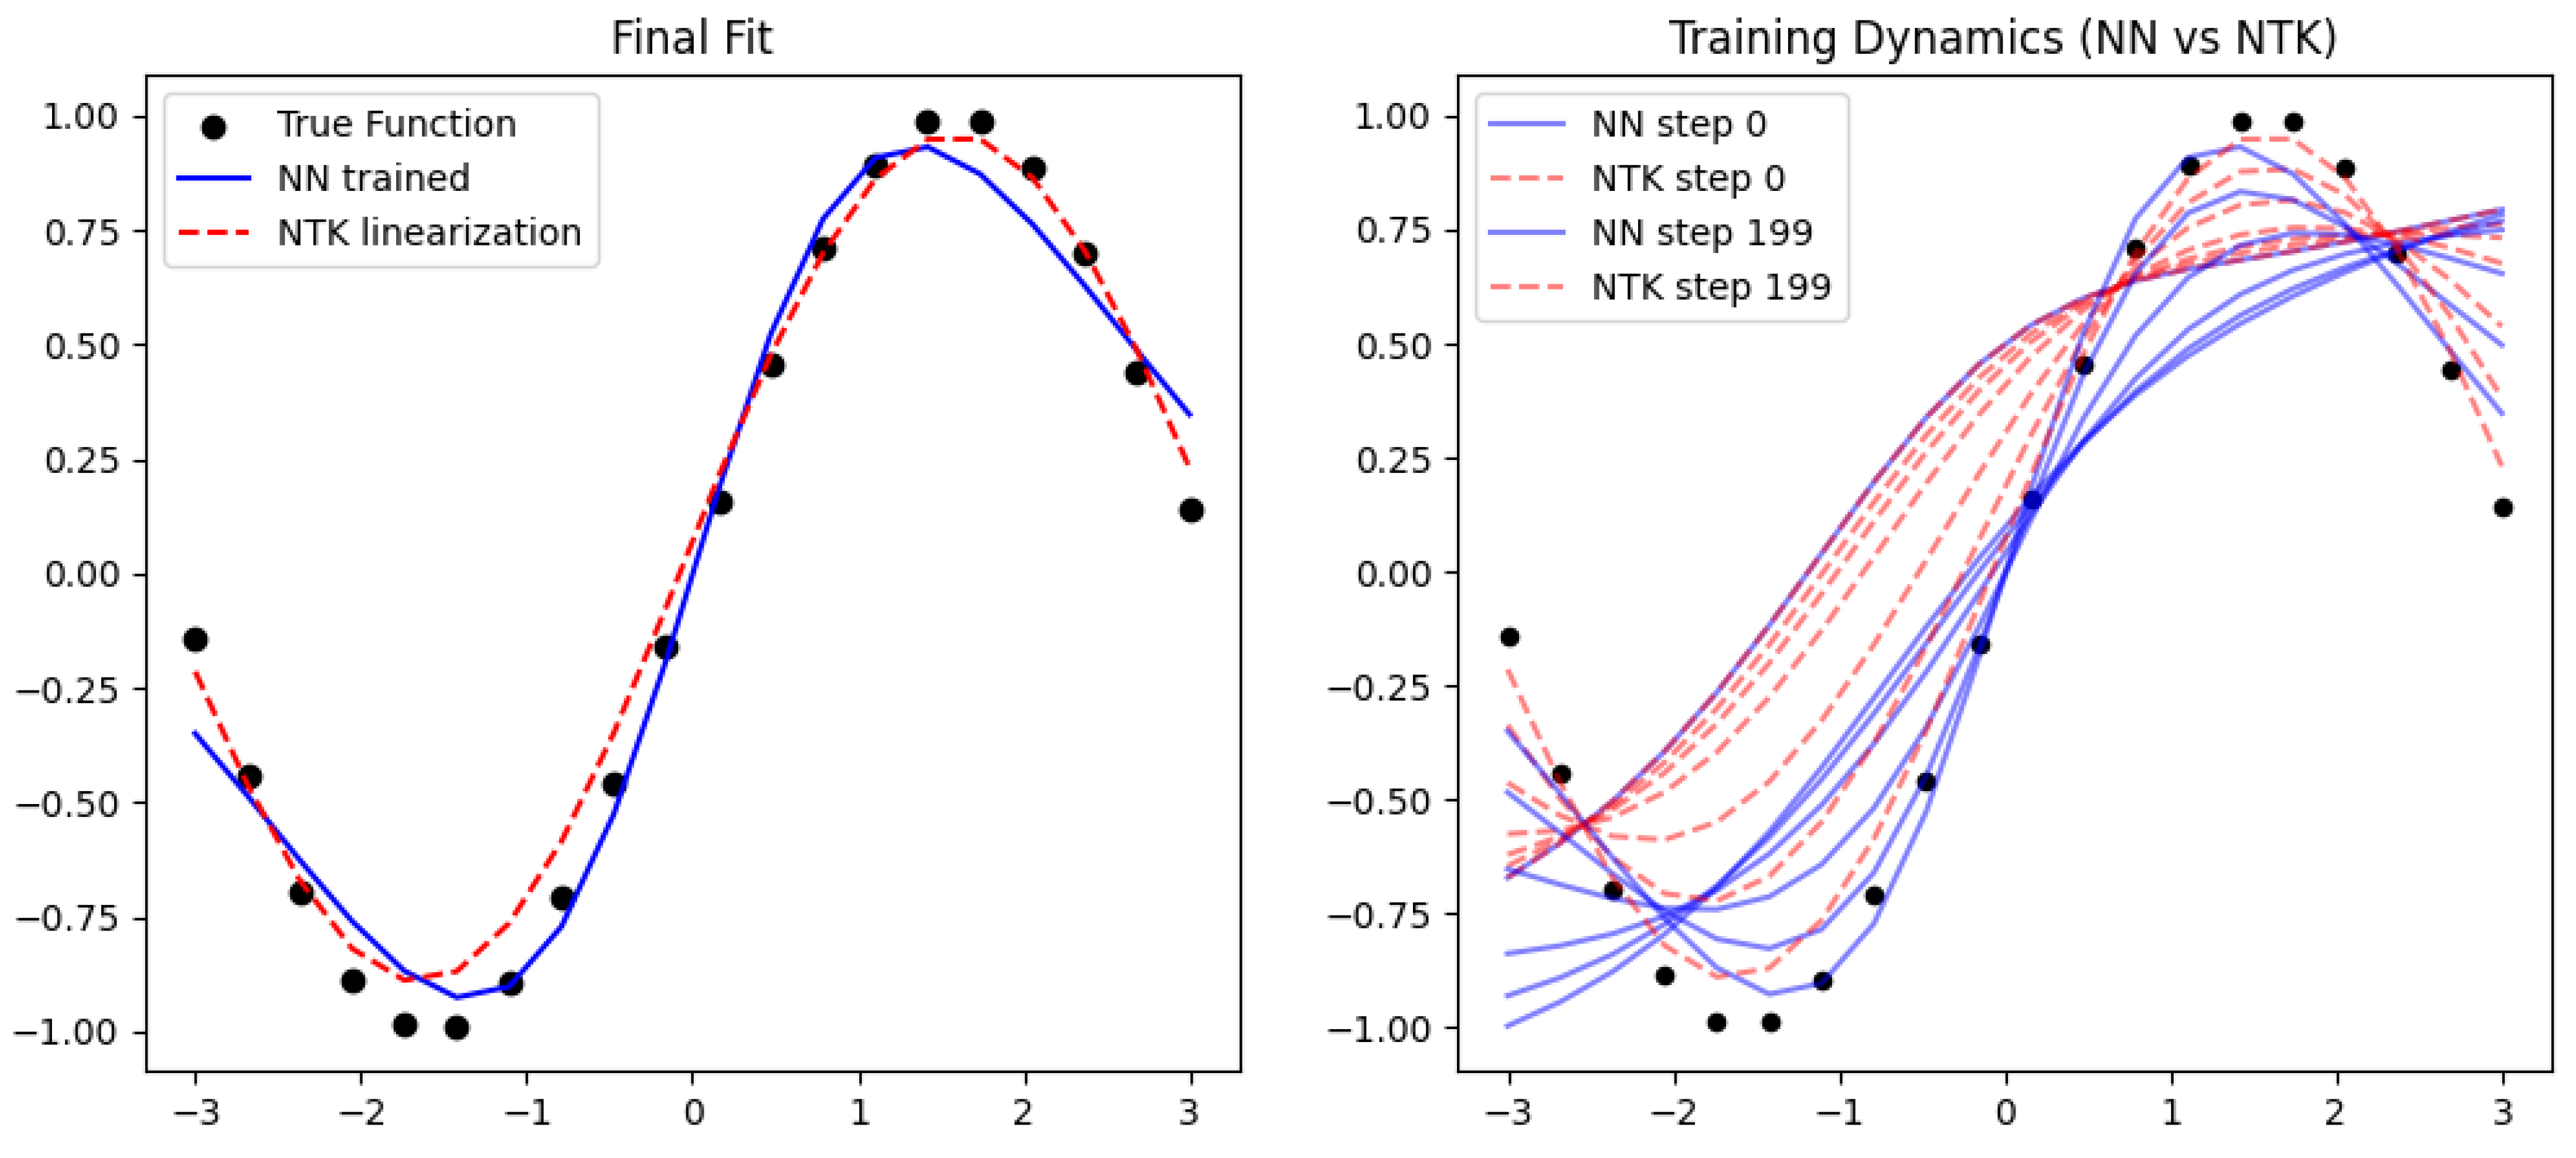
3.4. NTK Regime
3.4.1. Literature Review of NTK Regime
Jacot et. al. (2018) [94] in a seminal paper introduced the Neural Tangent Kernel (NTK) and establishes its theoretical foundation. The authors show that in the infinite-width limit, the dynamics of gradient descent in neural networks can be described by a kernel method, where the NTK remains constant during training. This work bridges the gap between deep learning and kernel methods, providing a framework to analyze the training and generalization of wide neural networks. Lee et. al. (2017) [95] did a work that predates the NTK but lays the groundwork by showing that infinitely wide neural networks behave as Gaussian processes. The authors derive the kernel corresponding to such networks, which is a precursor to the NTK. This paper is crucial for understanding the connection between neural networks and kernel methods. Chizat and Bach (2018) [484] provided a rigorous analysis of gradient descent in over-parameterized models, including neural networks. It complements the NTK framework by showing that gradient descent converges to global minima in such settings. The work highlights the role of over-parameterization in simplifying the optimization landscape. Du et. al. (2019) [485] proved that gradient descent can find global minima in deep neural networks under the NTK regime. The authors provide explicit convergence rates and show that the NTK framework guarantees efficient optimization for wide networks. This work strengthens the theoretical understanding of why deep learning works. Arora et. al. (2019) [486] provided a fine-grained analysis of optimization and generalization in two-layer neural networks under the NTK regime. It establishes precise bounds on the generalization error and shows how over-parameterization leads to benign optimization landscapes. Allen-Zhu et. al. (2019) [487] extended the NTK framework to deep networks and provided a comprehensive convergence theory for over-parameterized neural networks. The authors show that gradient descent converges to global minima and that the NTK remains approximately constant during training. Cao and Gu (2019) [488] derived generalization bounds for wide and deep neural networks trained with stochastic gradient descent (SGD) under the NTK regime. It highlights the role of the NTK in controlling the generalization error and provides insights into the implicit regularization of SGD. Yang (2019) [489] generalized the NTK framework to architectures with weight sharing, such as convolutional neural networks (CNNs). The author derives the NTK for such architectures and shows that they also exhibit Gaussian process behavior in the infinite-width limit. Huang and Yau (2020) [490] extended the NTK framework by introducing the Neural Tangent Hierarchy (NTH), which captures higher-order interactions in the training dynamics of deep networks. The authors provide a more refined analysis of the training process beyond the first-order approximation of the NTK. Belkin et. al. (2019) [491] explored the connection between deep learning and kernel learning, emphasizing the role of the NTK in understanding generalization and optimization. It provides a high-level perspective on why the NTK framework is essential for analyzing modern machine learning models.
3.4.2. Analysis of NTK Regime
The Neural Tangent Kernel (NTK) regime is a fundamental framework for understanding the dynamics of gradient descent in highly overparameterized neural networks. Consider a neural network parameterized by , where P represents the total number of parameters, and is the input vector. For a training dataset , the loss function at time t is given by
The parameters evolve according to gradient descent as , where is the learning rate.
In the NTK regime, we consider the first-order Taylor expansion of the network output around the initialization :
This linear approximation transforms the nonlinear dynamics of f into a simpler, linearized form. To analyze training, we introduce the Jacobian matrix , where . The vector of outputs , aggregating predictions over the dataset, evolves as
The NTK is defined as
As , the NTK converges to a deterministic matrix that remains nearly constant during training. Substituting the linearized form of into the gradient descent update equation gives
where is the vector of true labels. Defining the residual , the dynamics of training reduce to
The eigendecomposition , with orthogonal Q and diagonal , allows us to analyze the decay of residuals in the eigenbasis of :
where . Each component decays as
For small , the training dynamics are approximately continuous, governed by
leading to the solution
The NTK for specific architectures, such as fully connected ReLU networks, can be derived using layerwise covariance matrices. Let denote the covariance between pre-activations at layer l. The recurrence relation for is
where The NTK, a sum over contributions from all layers, quantifies how parameter updates propagate through the network.
In the infinite-width limit, the NTK framework predicts generalization properties, as the kernel matrix governs both training and test-time behavior. The NTK connects neural networks to classical kernel methods, offering a bridge between deep learning and well-established theoretical tools in approximation theory. This regime’s deterministic and analytical tractability enables precise characterizations of network performance, convergence rates, and robustness to initialization and learning rate variations.
3.4.3. Python Code to Generate Figure 35 Illustrating the Final Predictions in NTK Regime & Training Dynamics (NN vs NTK)
The Python code below produces the Figure 35 Illustrating the Final Predictions in NTK Regime & Training Dynamics (NN vs NTK).
Figure 35.
Final Predictions in NTK Regime & Training Dynamics (NN vs NTK)
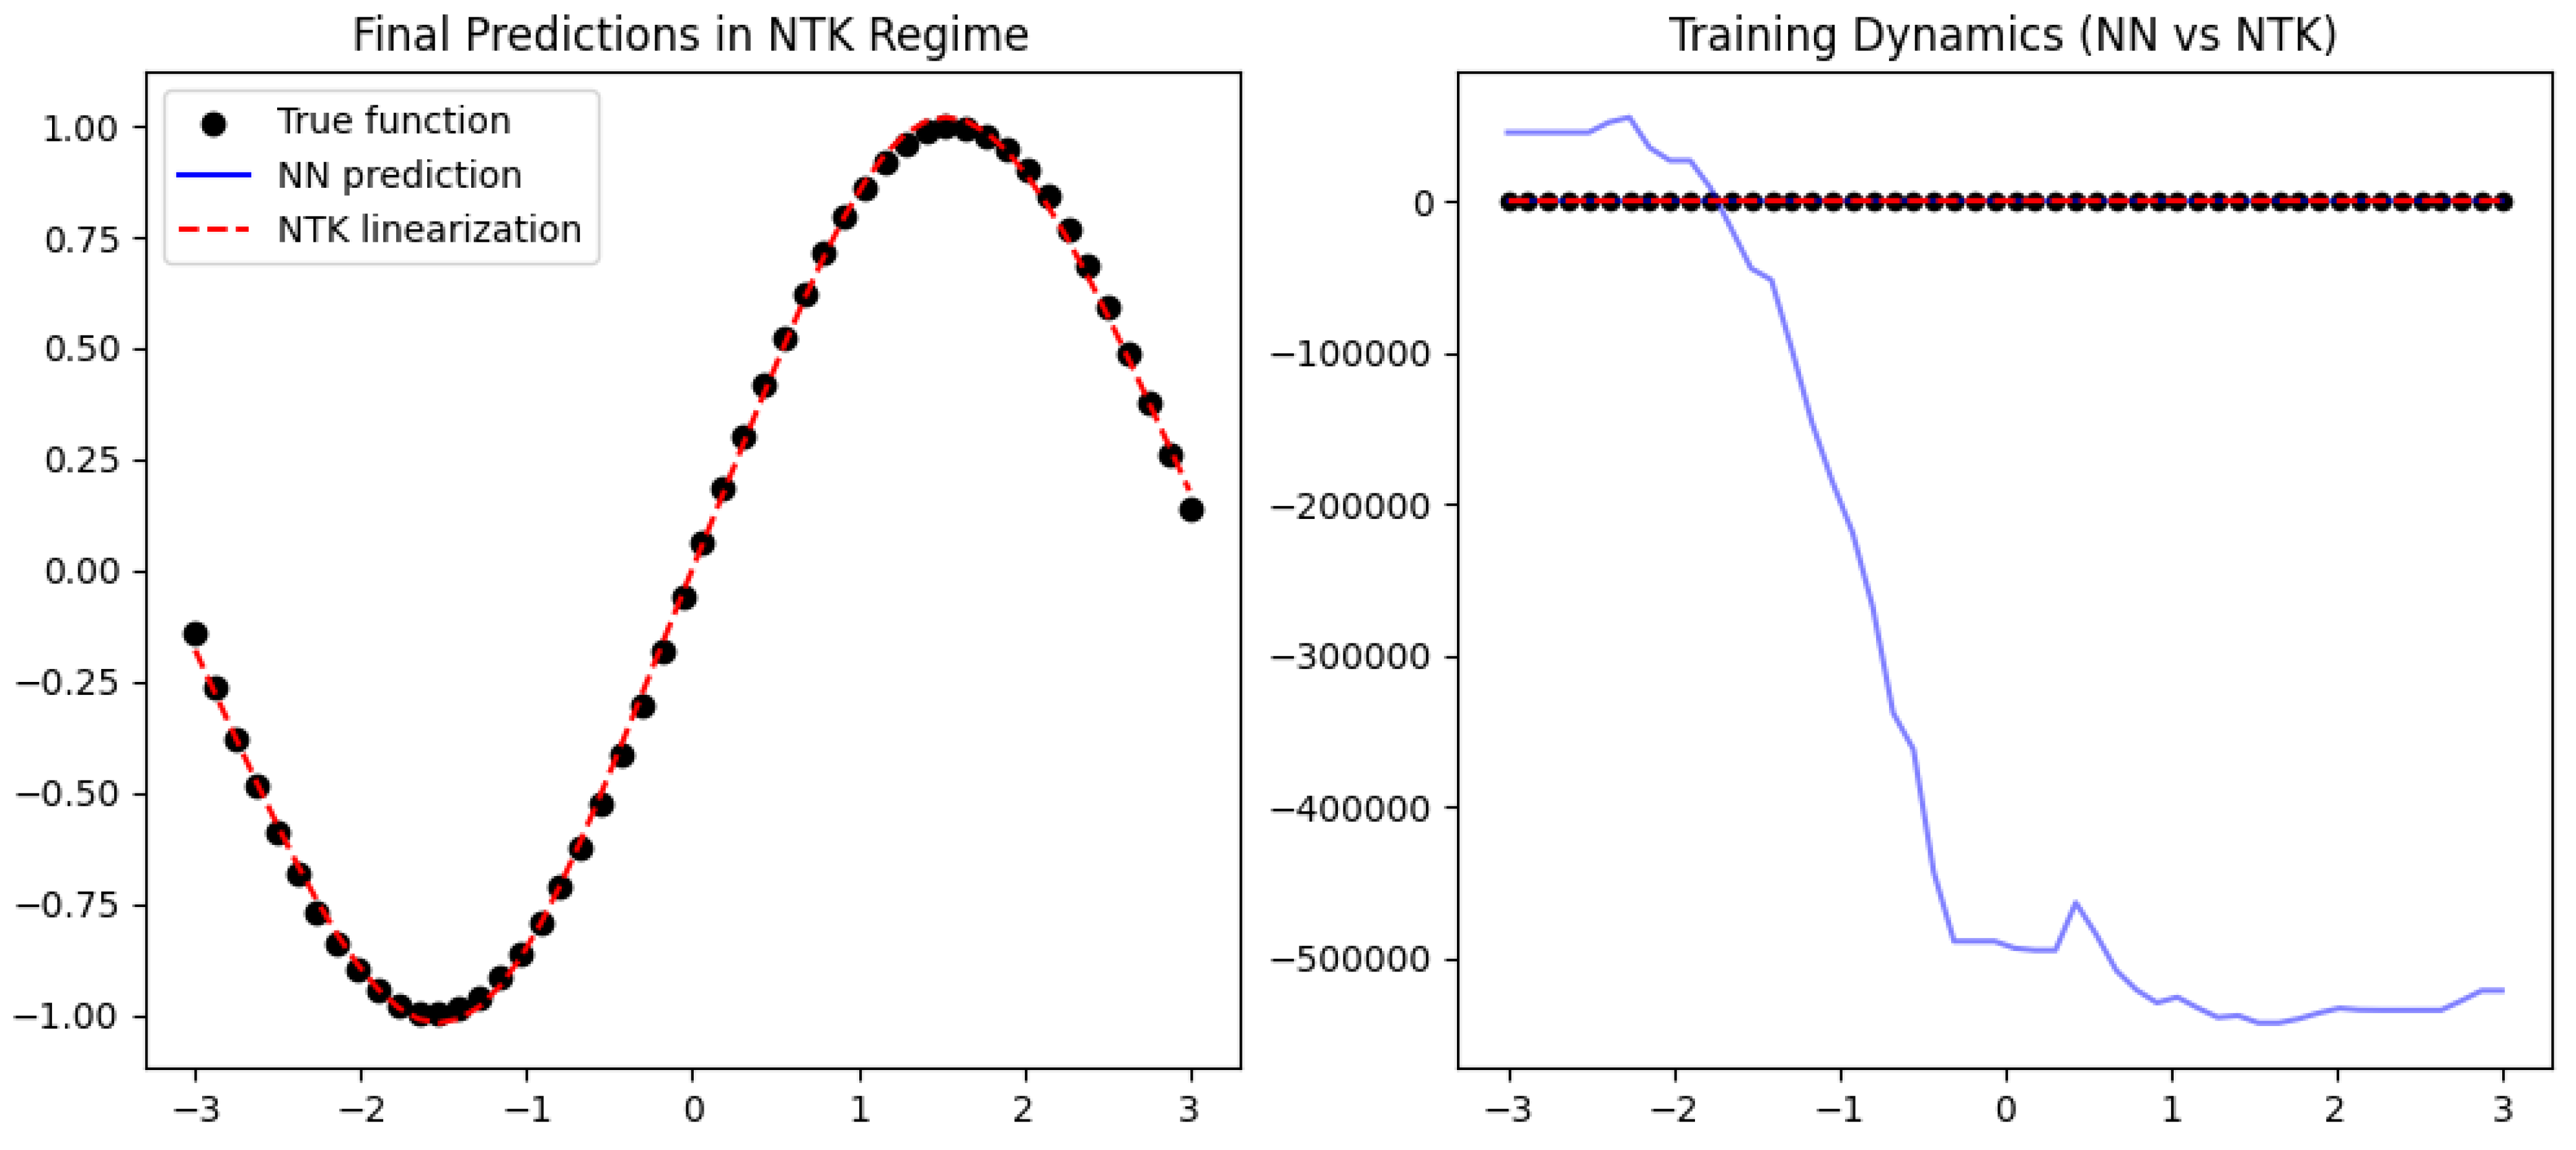
4. Generalization Bounds: PAC-Bayes and Spectral Analysis
The PAC-Bayes framework provides a rigorous mathematical approach to deriving generalization bounds for machine learning models, particularly in stochastic settings. Given a hypothesis space , a prior distribution P over (encoding initial beliefs before observing data), and a posterior distribution Q (learned from data), the PAC-Bayes theorem bounds the expected generalization error. Let denote the true risk of hypothesis and its empirical risk on a sample S of size m. The key PAC-Bayes bound states that, with probability at least over the draw of S, the following holds for all posteriors Q:
where is the Kullback-Leibler divergence between Q and P. This bound balances empirical performance and the complexity of the posterior relative to the prior, ensuring generalization when the learned distribution Q does not deviate excessively from P. The theorem is particularly useful in Bayesian deep learning and stochastic optimization, where Q is often taken as a Gaussian perturbation of a deterministic model.
Spectral analysis examines generalization through the lens of the loss landscape and the eigenspectrum of the Hessian or the Neural Tangent Kernel (NTK). Let be the Hessian of the loss at a local minimum, and let denote its eigenvalues. The effective dimensionality of the solution, which influences generalization, can be characterized by the ratio of the trace to the largest eigenvalue:
Sharp minima, associated with poor generalization, correspond to large relative to the trace, while flat minima (with smaller ) generalize better. Additionally, the NTK’s eigenspectrum determines the speed of gradient descent convergence and the stability of learning dynamics. Let be the NTK at initialization; its eigenvalue decay rate governs how quickly different modes of the target function are learned. If has a rapidly decaying spectrum, high-frequency components (corresponding to small eigenvalues) are learned slowly, leading to implicit regularization. The generalization error can be bounded in terms of the NTK’s eigendecomposition, linking spectral properties to model performance. This approach provides a mechanistic understanding of why overparameterized models generalize despite their capacity to overfit.
4.1. PAC-Bayes Formalism
4.1.1. Literature Review of PAC-Bayes Formalism
McAllester (1999) [99] introduced the PAC-Bayes bound, a fundamental theorem that provides generalization guarantees for Bayesian learning models. He established a trade-off between complexity and empirical risk, serving as the theoretical foundation for modern PAC-Bayesian analysis. Catoni (2007) [100] in his book rigorously extended the PAC-Bayes framework by linking it with information-theoretic and statistical mechanics concepts and introduced exponential and Gibbs priors for learning, improving PAC-Bayesian bounds for supervised classification. Germain et. al. (2009) [101] applied PAC-Bayes theory to linear classifiers, including SVMs and logistic regression. They demonstrated that PAC-Bayesian generalization bounds are tighter than classical Vapnik-Chervonenkis (VC) dimension bounds. Seeger (2002) [102] extended PAC-Bayes bounds to Gaussian Process models, proving tight generalization guarantees for Bayesian classifiers. He laid the groundwork for probabilistic kernel methods. Alquier et. al. (2006) [103] connected variational inference and PAC-Bayes bounds, proving that variational approximations can preserve generalization guarantees of PAC-Bayesian bounds. Dziugaite and Roy (2017) [104] gave one of the first applications of PAC-Bayes to deep learning. They derived nonvacuous generalization bounds for stochastic neural networks, bridging theory and practice. Cox and Ghosh (2022) [54] introduce an analogue of the Mertens function that exhibits similar oscillatory behavior, analyze its properties using Shapiro’s theorem, generalized Dirichlet products, and generalized Möbius inversion, thereby offering new insights into the analytic structure underlying Mertens-type functions. Rivasplata et. al. (2020) [106] provided novel PAC-Bayes bounds that improve over existing guarantees, making PAC-Bayesian bounds more practical for modern ML applications. Lever et. al. (2013) [107] explored data-dependent priors in PAC-Bayes theory, showing that adaptive priors lead to tighter generalization bounds. Rivasplata et. al. (2018) [108] introduced instance-dependent priors, improving personalized learning and making PAC-Bayesian methods more useful for real-world machine learning problems. Lindemann et. al. (2024) [109] integrated PAC-Bayes theory with conformal prediction to improve formal verification in control systems, demonstrating PAC-Bayes’ relevance to safety-critical applications.
4.1.2. Analysis of PAC-Bayes Formalism
The PAC-Bayes formalism is a foundational framework in statistical learning theory, designed to provide probabilistic guarantees on the generalization performance of learning algorithms. By combining principles from the PAC (Probably Approximately Correct) framework and Bayesian reasoning, PAC-Bayes delivers bounds that characterize the expected performance of hypotheses drawn from posterior distributions, given a finite sample of data. This document presents an extremely rigorous and mathematically precise description of the PAC-Bayes formalism, emphasizing its theoretical constructs and implications.
At the core of the PAC-Bayes formalism lies the ambition to rigorously quantify the generalization ability of hypotheses based on their performance on a finite dataset , where represents the underlying, and typically unknown, data distribution. The PAC framework, which was originally designed to provide high-confidence guarantees on the true risk
is enriched in PAC-Bayes by incorporating principles from Bayesian reasoning. This integration allows for bounds not just on individual hypotheses but on distributions Q over , yielding a sophisticated characterization of generalization that inherently accounts for the variability and uncertainty in the hypothesis space. There are some Mathematical Constructs: True and Empirical Risks. The true risk , as defined by the expected loss, is typically inaccessible due to the unknown nature of . Instead, the empirical risk
serves as a computable proxy. The key question addressed by PAC-Bayes is: How does relate to , and how can we bound the deviation probabilistically? For a distribution Q over , these risks are generalized as:
This generalization is pivotal because it allows the analysis to transcend individual hypotheses and consider probabilistic ensembles, where represents a posterior belief over the hypothesis space conditioned on the observed data.
We now need to discuss how Prior and Posterior Distributions encode knowledge and complexity. The prior P is a fixed distribution over that reflects pre-data assumptions about the plausibility of hypotheses. Crucially, P must be independent of S to avoid biasing the bounds. The posterior Q, however, is data-dependent and typically chosen to minimize a combination of empirical risk and complexity. This choice is guided by the PAC-Bayes inequality, which regularizes Q via its Kullback-Leibler (KL) divergence from P:
The KL divergence quantifies the informational cost of updating P to Q, serving as a penalty term that discourages overly complex posteriors. This regularization is critical in preventing overfitting, ensuring that Q achieves a balance between data fidelity and model simplicity.
Let’s derive the PAC-Bayes Inequality: Probabilistic and Information-Theoretic Foundations. The derivation of the PAC-Bayes inequality hinges on a combination of probabilistic tools and information-theoretic arguments. A central step involves applying a change of measure from P to Q, leveraging the identity:
This allows the incorporation of Q into bounds that originally apply to fixed h. By analyzing the moment-generating function of deviations between and , and applying Hoeffding’s inequality to the empirical loss, we arrive at the following bound for any Q and P, with probability at least :
The generalization bound is therefore given by:
where quantifies the divergence between the posterior Q and prior P.
This bound is remarkable because it explicitly ties the true risk to the empirical risk , the KL divergence, and the sample size m. The PAC-Bayes bound encapsulates three competing forces: the empirical risk , the complexity penalty , and the confidence term . This interplay reflects a fundamental trade-off in learning:
- Empirical Risk: captures how well the posterior Q fits the training data.
- Complexity: The KL divergence ensures that Q remains close to P, discouraging overfitting and promoting generalization.
- Confidence: The term shrinks with increasing sample size, tightening the bound and enhancing reliability.
The KL term also introduces an inherent regularization effect, penalizing hypotheses that deviate significantly from prior knowledge. This aligns with Occam’s Razor, favoring simpler explanations that are consistent with the data.
There are several extensions and Advanced Applications of Pac-Bayes Formalism. While the classical PAC-Bayes framework assumes i.i.d. data, recent advancements have generalized the theory to handle structured data, such as in time-series and graph-based learning. Furthermore, alternative divergence measures, like Rényi divergence or Wasserstein distance, have been explored to accommodate scenarios where KL divergence may be inappropriate. In practical settings, PAC-Bayes bounds have been instrumental in analyzing neural networks, Bayesian ensembles, and stochastic processes, offering theoretical guarantees even in high-dimensional, non-convex optimization landscapes.
4.1.2.1 Python Code to Generate Figure 36, Figure 37, and Figure 38 Illustrating PAC-Bayes Bound vs. Sample Size
The Python code below produces the Figure 36, Figure 37, and Figure 38 illustrating PAC-Bayes Bound vs. Sample Size.
Figure 36.
PAC-Bayes Bound vs. Sample Size (KL)
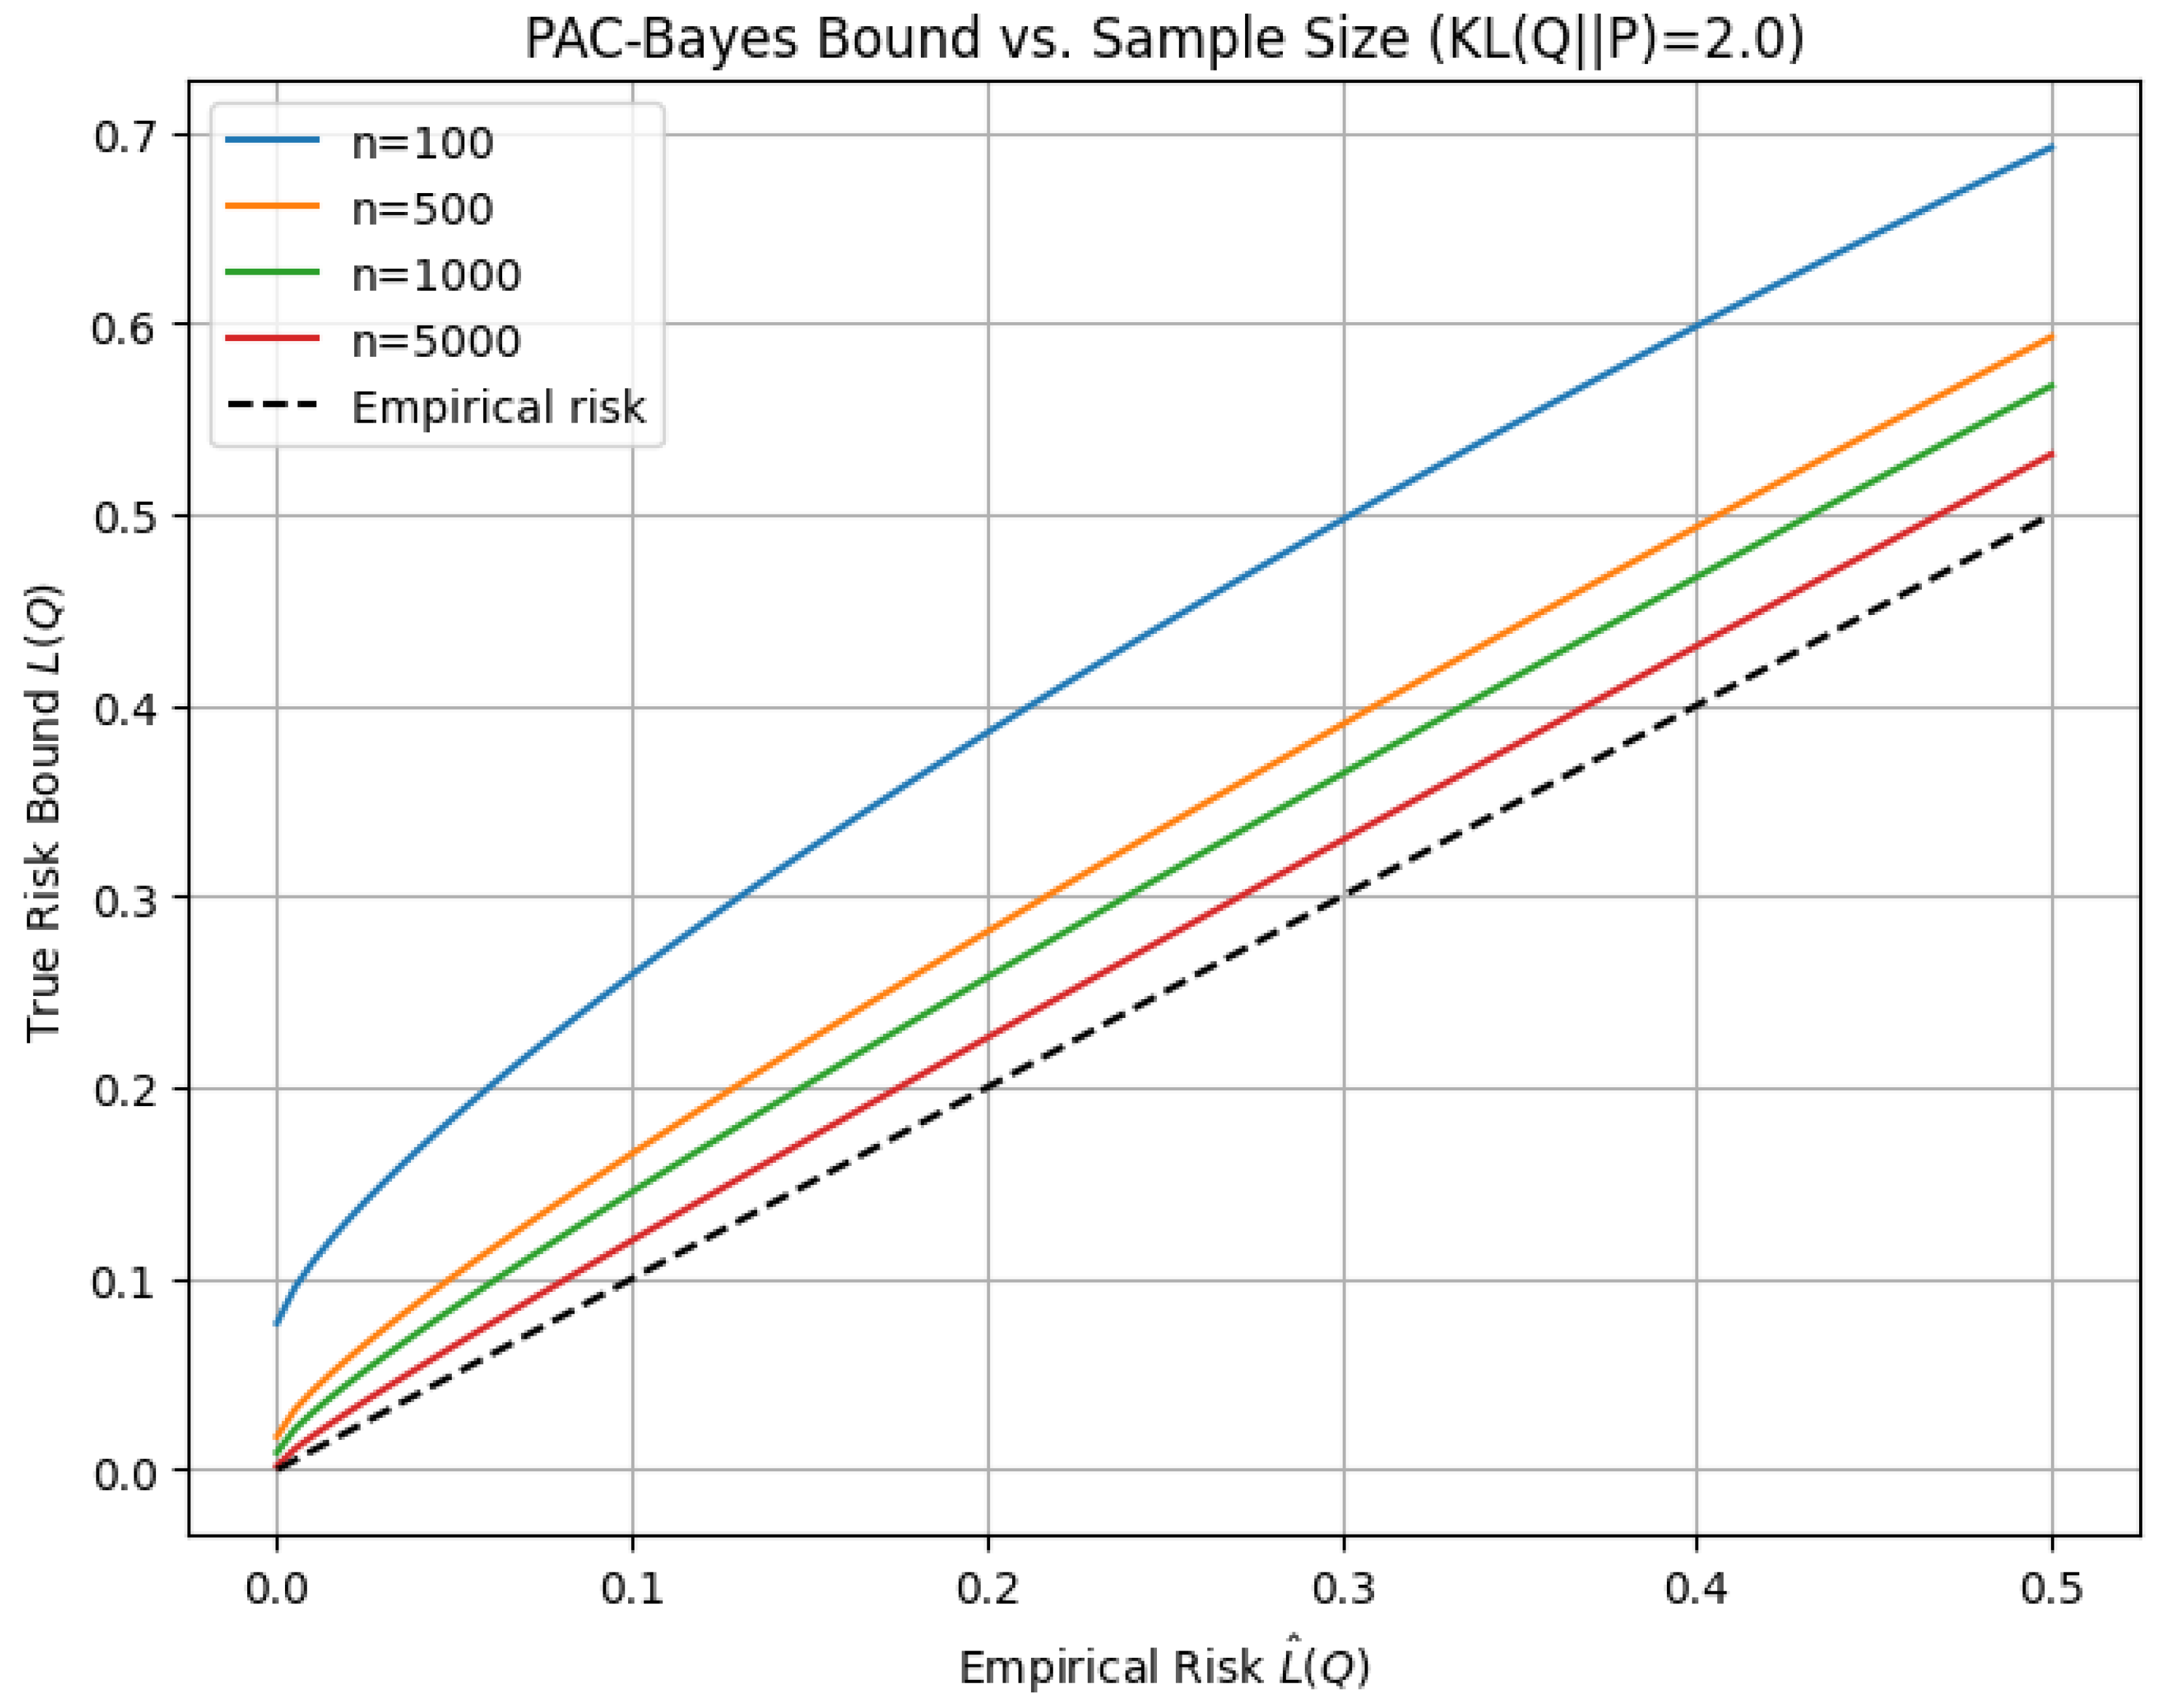
Figure 37.
PAC-Bayes Bound vs. Sample Size (KL)
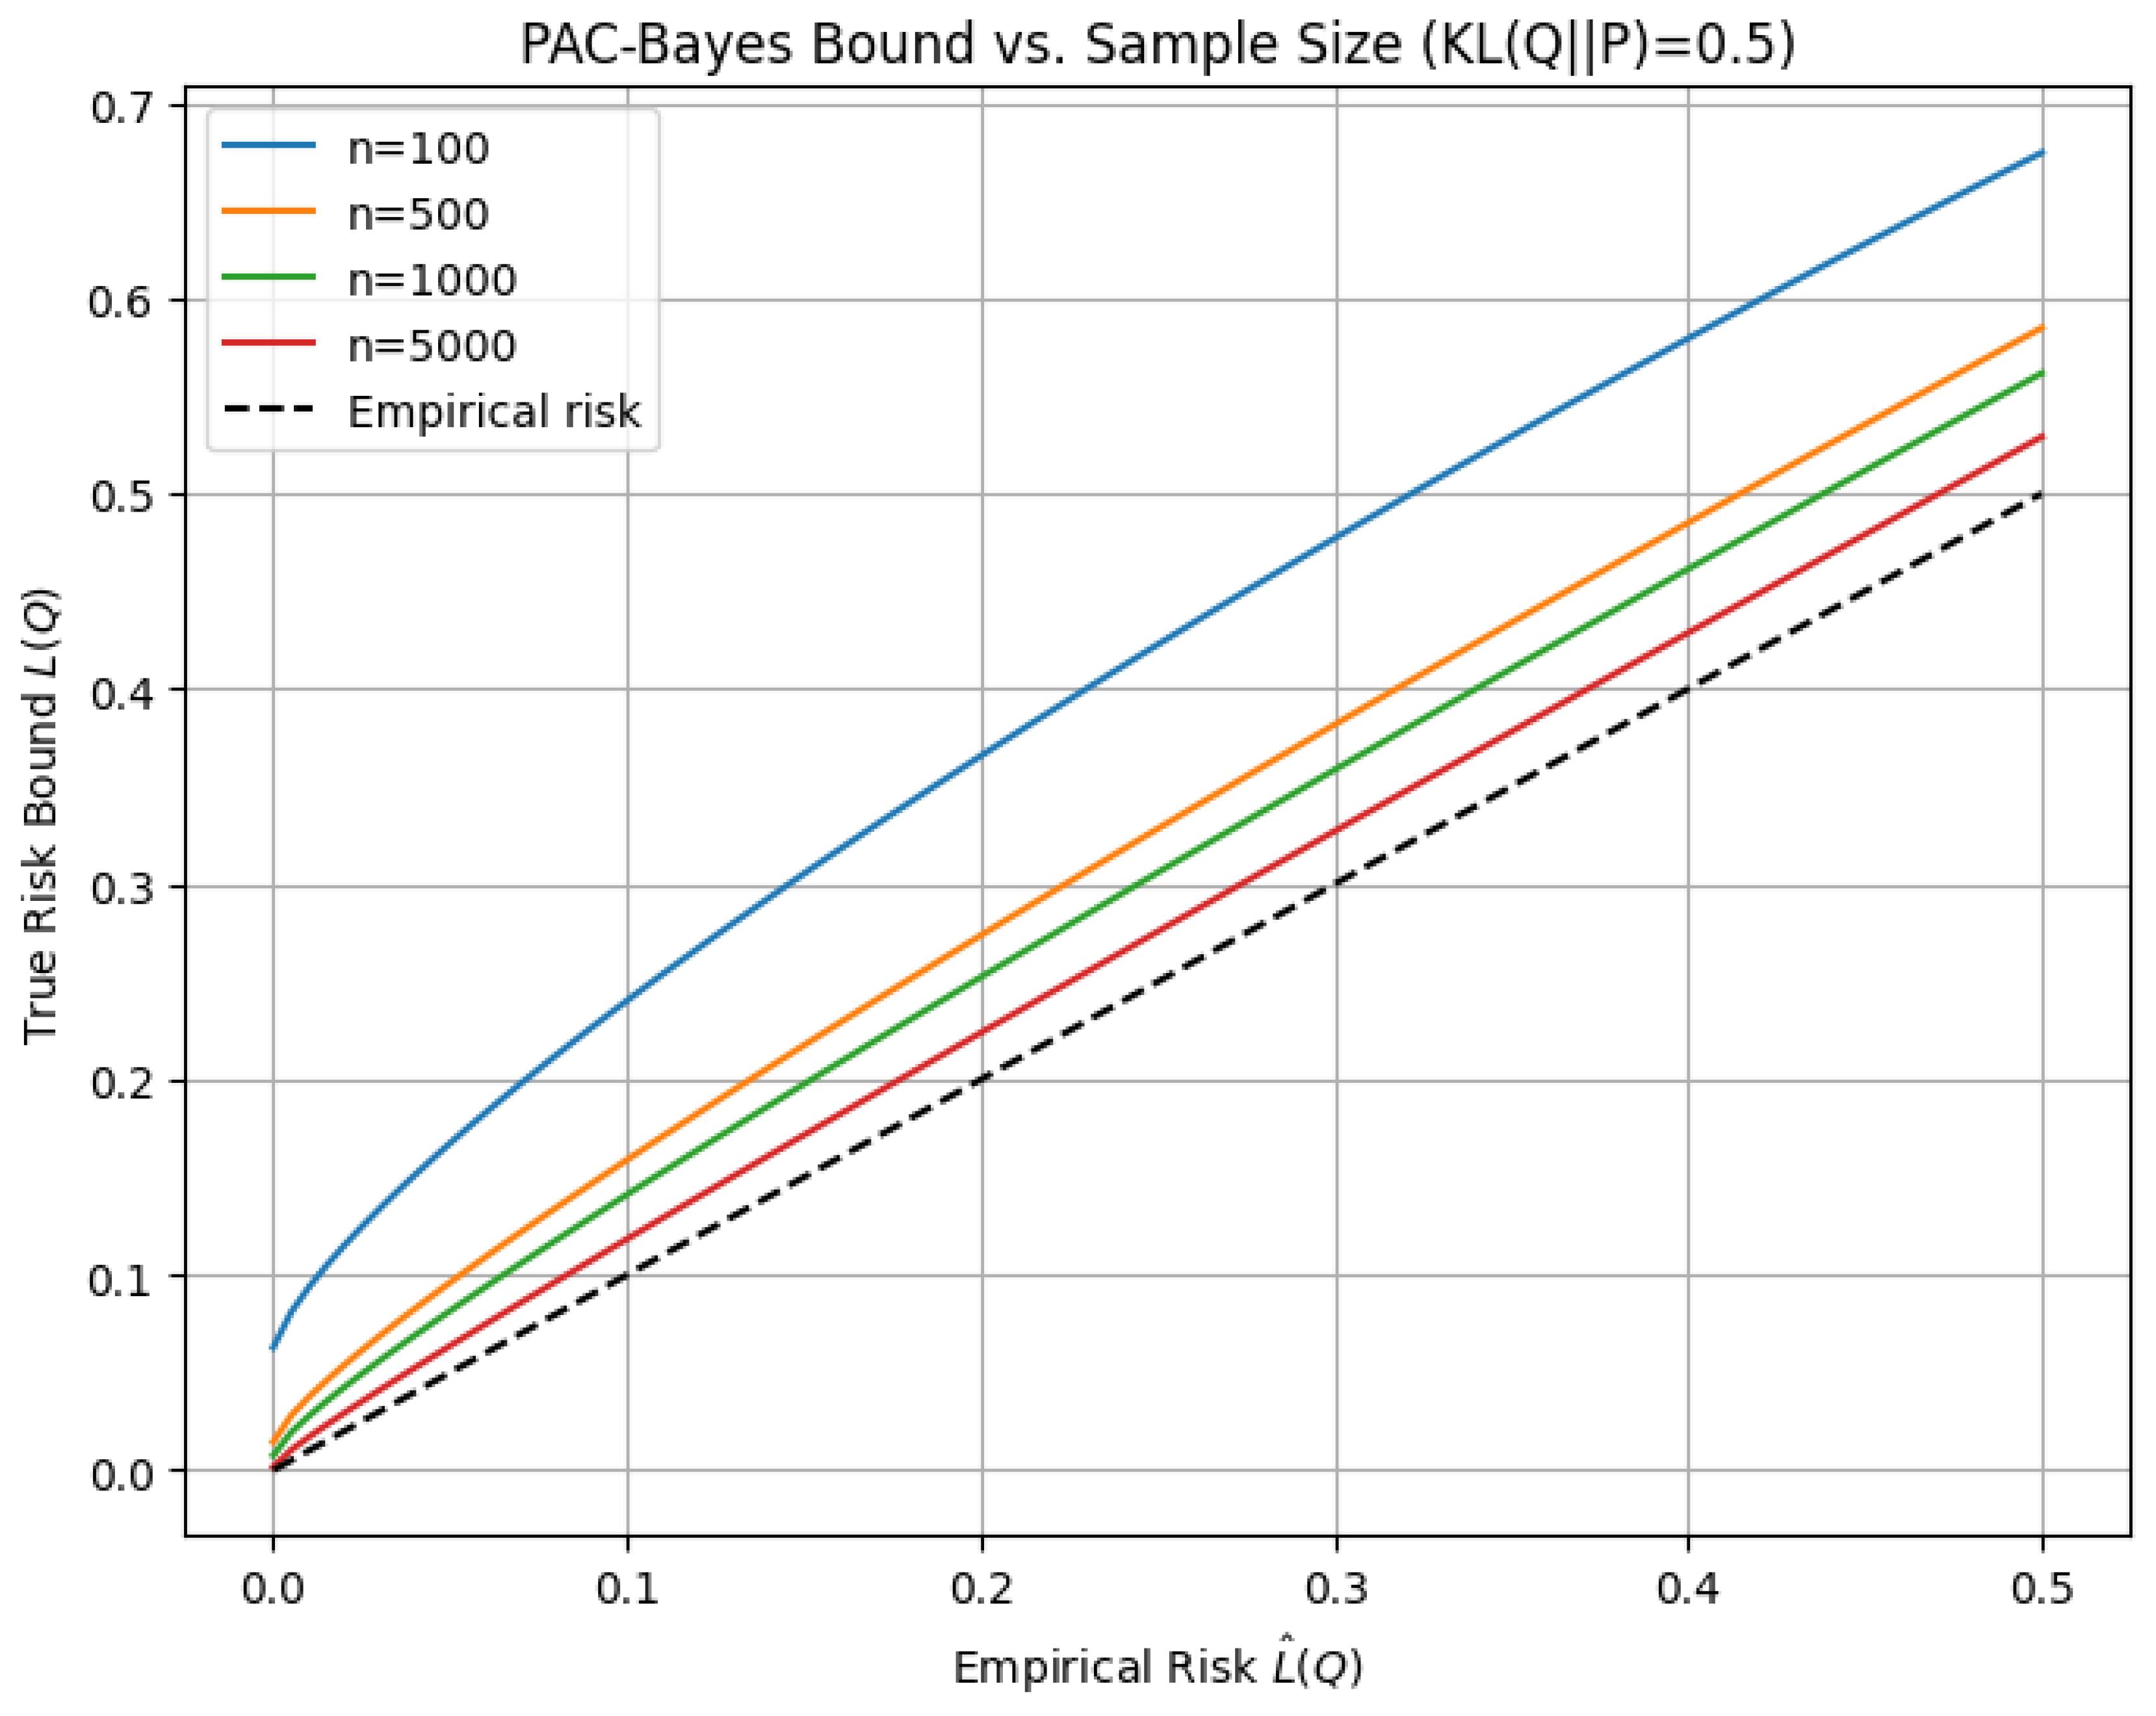
Figure 38.
PAC-Bayes Bound vs. Sample Size (KL)
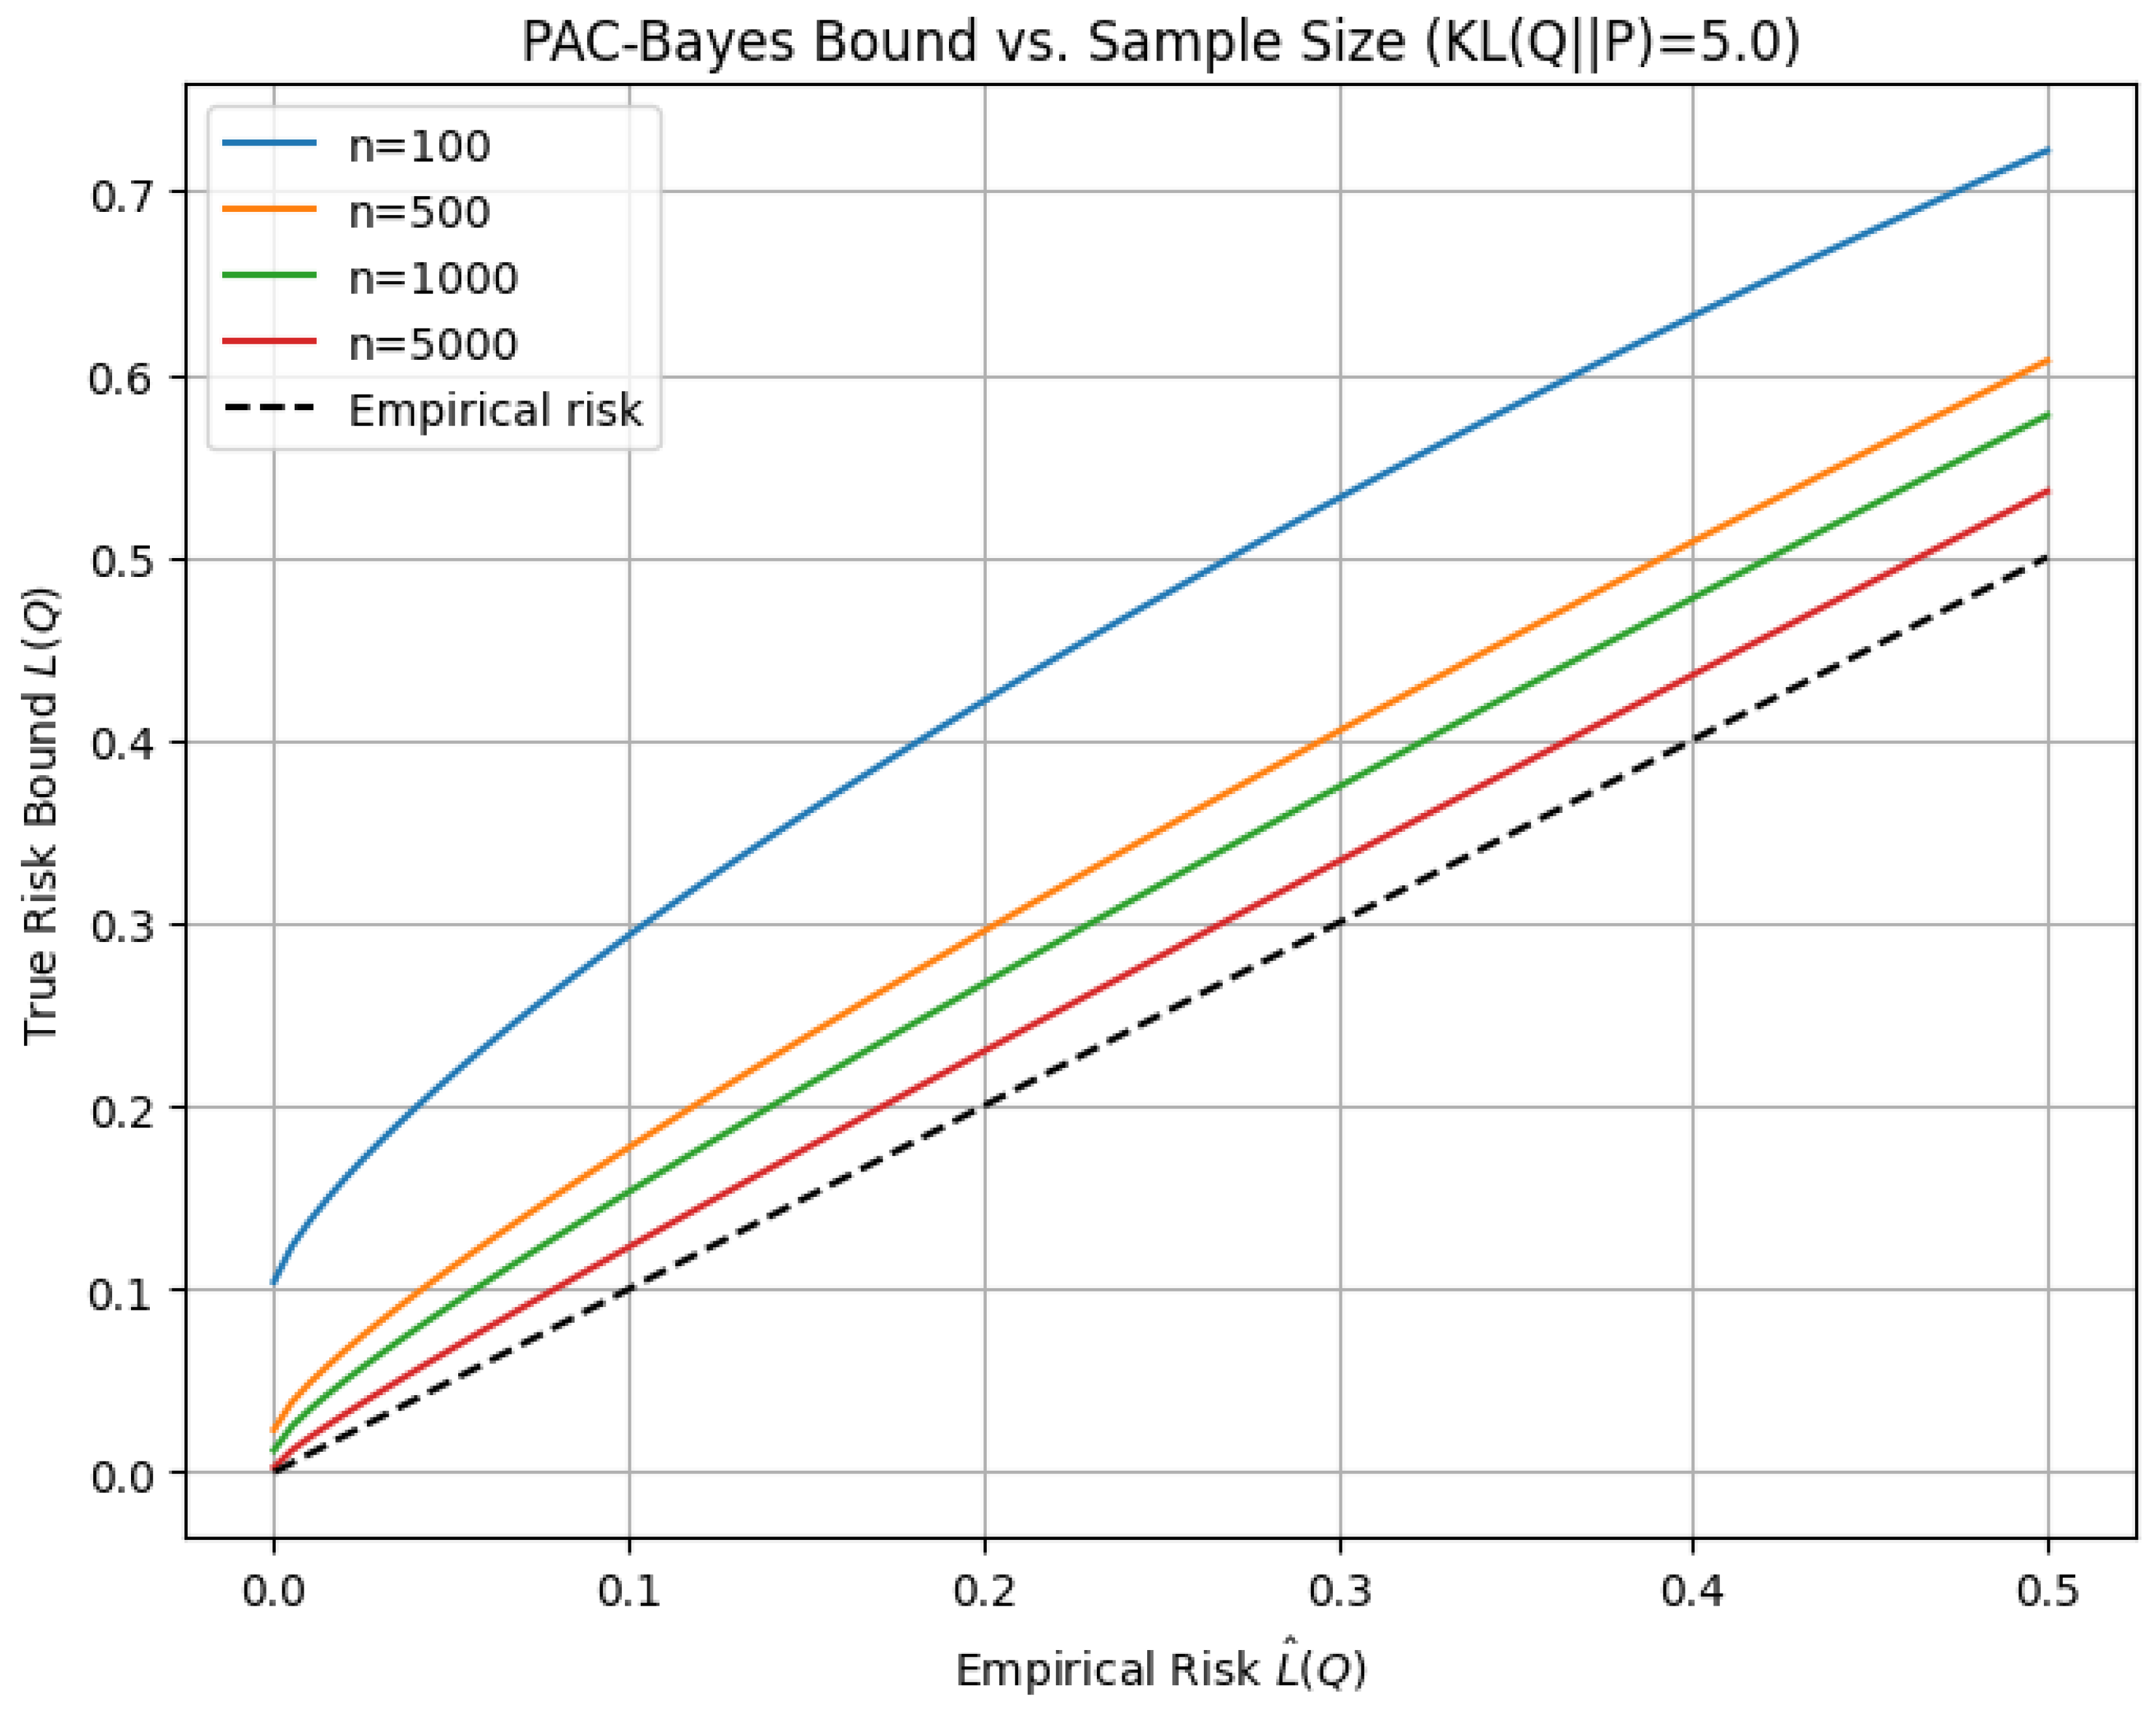
4.1.3. KL Divergence
The Kullback-Leibler (KL) divergence, also known as the relative entropy, is a fundamental concept in information theory, probability theory, and statistics. It quantifies the difference between two probability distributions, measuring the inefficiency of assuming that data is generated from one distribution when it is actually generated from another.
Mathematically, for two discrete probability distributions and defined over a common sample space , the KL divergence is given by
where the logarithm is conventionally taken to be the natural logarithm unless otherwise specified. For continuous probability distributions with probability density functions and , the KL divergence is defined as
The KL divergence can be understood as the expectation of the logarithmic difference between the two distributions, weighted by the true distribution :
Expanding this expectation in integral form,
The first integral represents the entropy of , denoted as
while the second integral represents the cross-entropy between and , given by
Thus, KL divergence can be rewritten as
which represents the additional number of bits required to encode data from when using a coding scheme optimized for instead of . Since the logarithm function is concave, an application of Jensen’s inequality to the function yields the fundamental property
with equality if and only if for all x, which follows from the strict convexity of the logarithm function. Unlike a metric, KL divergence is not symmetric, meaning that in general,
For two multivariate normal distributions and , the KL divergence is given by
where k is the dimension of the Gaussian distribution. This expression reveals that KL divergence accounts for both the difference in mean vectors and the difference in covariance structures.
The KL divergence has a fundamental connection to maximum likelihood estimation (MLE). Given a true data distribution and a parametric model , the parameter that minimizes the KL divergence
is equivalent to the maximum likelihood estimate, since minimizing KL divergence is equivalent to maximizing the log-likelihood function
This follows from the fact that the term does not depend on and is therefore irrelevant for optimization. In Bayesian inference, KL divergence plays a central role in variational inference. Given an intractable posterior , one approximates it with a tractable distribution , where the objective is to minimize
This minimization leads to the Evidence Lower Bound (ELBO),
which is central in modern probabilistic modeling. Moreover, KL divergence is related to mutual information. Given two random variables X and Y with a joint distribution and marginals and , the mutual information is given by
which quantifies the amount of information shared between X and Y. In information geometry, the Fisher information matrix is derived from the second-order expansion of KL divergence,
KL divergence is also connected to the Pinsker inequality,
This establishes KL divergence as a fundamental measure of probability distance in statistical inference and machine learning.
The Kraft–McMillan inequality establishes a necessary and sufficient condition for the existence of a uniquely decodable code with a given set of codeword lengths. For a code over a D-ary alphabet to be uniquely decodable, the codeword lengths must satisfy the inequality
This inequality is foundational because it directly links the lengths of codewords to a probability distribution. Specifically, if we define , then the Kraft sum condition
implies that can be normalized to form a probability distribution. This provides a formal bridge between the theory of codes and the theory of probability distributions, which is the central domain of information theory measures like the Kullback-Leibler (KL) Divergence.
The KL Divergence, or relative entropy, between two probability distributions P and Q over the same discrete set is defined as
Its importance in data compression is given by the source coding theorem, which states that the expected codeword length of an optimal code for a source with distribution P is bounded by
where is the Shannon entropy. When the code is designed for an incorrect distribution Q, the expected codeword length becomes
The Kraft–McMillan theorem guarantees that for any uniquely decodable code with lengths , there exists a probability distribution
where is the Kraft sum. This allows the lengths to be expressed as
and since , we have
The expected length when using a code optimal for Q on data from P is
Substituting the fundamental relation for a code that meets the Kraft inequality with equality for distribution Q yields
The difference between this suboptimal expected length and the entropy lower bound is
This simplifies directly to , as
Therefore, the KL Divergence quantifies the inefficiency, in bits or nats, incurred by using a code designed for a distribution Q when the true data-generating distribution is P. The mathematical rigor of this relationship is entirely contingent upon the Kraft–McMillan theorem, which provides the necessary condition
that legitimizes the interpretation of code lengths as representing a probability distribution, thereby enabling the derivation
for a code that is optimal for Q.
4.1.3.1 Python Code to Generate Figure 39, Figure 40 Illustrating KL Divergence in Bernoulli Random Variables and Figure 41, Figure 42 Illustrating KL Divergence in Gaussian Random Variables
The Python code below produces the Figure 39, Figure 40 illustrating KL Divergence in Bernoulli Random Variables and Figure 41, Figure 42 illustrating KL Divergence in Gaussian Random Variables.
Figure 39.
KL Divergence between Bernoulli(p) and Bernoulli(q)
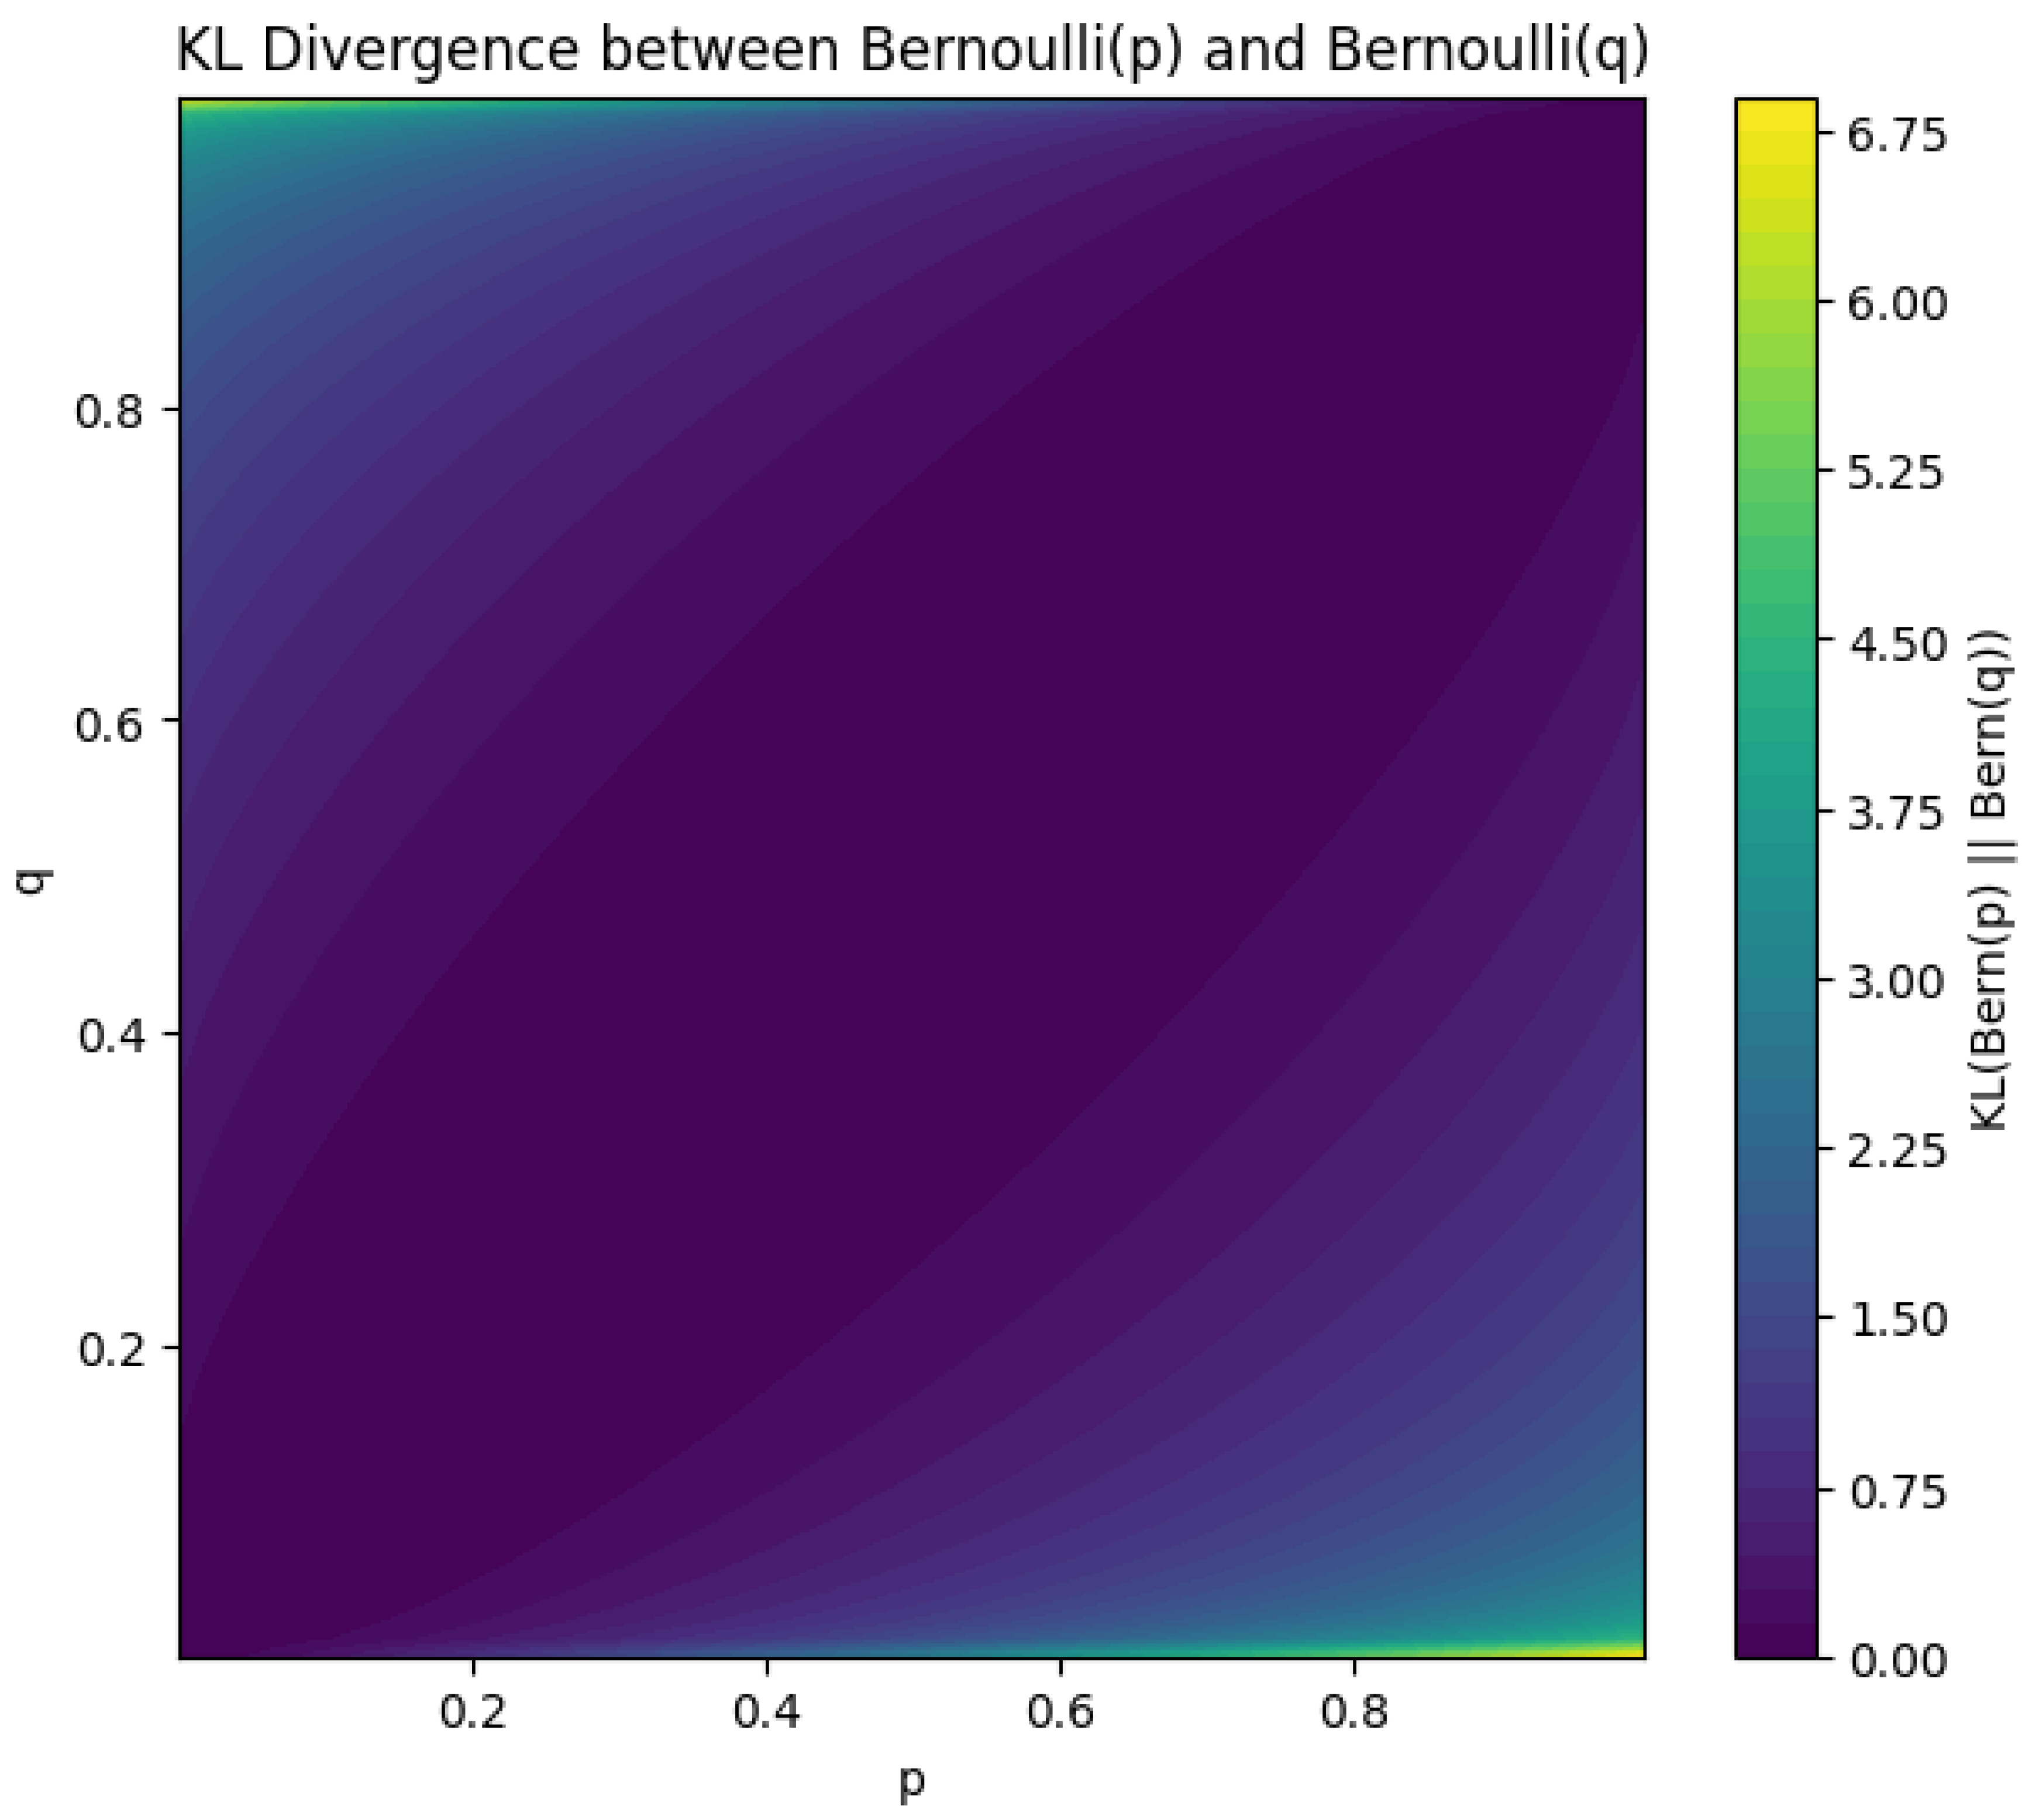
Figure 40.
KL Divergence as function of q for fixed p
Figure 41.
Gaussian KL Divergence (equal variances)
Figure 42.
Gaussian KL Divergence vs ()
4.1.4. Rényi Divergence
The Rényi divergence is a parametric family of divergences that generalizes the Kullback-Leibler (KL) divergence and provides a broader measure of dissimilarity between probability distributions.
Given two probability distributions P and Q defined on a measurable space , the Rényi divergence of order (for and ) is defined as
where and denote the Radon-Nikodym derivatives (i.e., probability density functions) of P and Q with respect to a common reference measure . That is,
For the case where P and Q are discrete distributions supported on a finite or countable set , the Rényi divergence takes the form
Equivalently, it can be expressed using expectation notation as
This expression shows that Rényi divergence is a moment-based measure of dissimilarity between P and Q, generalizing the standard KL divergence, which is recovered in the limit . To see this, we differentiate
with respect to and apply L’Hôpital’s rule. Explicitly, defining
we compute
Applying the logarithmic derivative, we obtain
demonstrating the convergence to the KL divergence. The Rényi divergence satisfies the following fundamental mathematical properties. It is non-negative,
Additionally, Rényi divergence is a monotonic function of , satisfying
For special values of , Rényi divergence simplifies to various known divergences. When , it becomes
which represents the negative logarithm of the probability mass that Q assigns to the support of P. When , we obtain
which is related to the chi-squared divergence. When , the divergence simplifies to
which measures the worst-case discrepancy between the two distributions. One crucial property of the Rényi divergence is its invariance under transformations. Given a Markov kernel T that maps P and Q to new distributions and , the data-processing inequality states
ensuring that no transformation can increase the divergence between distributions. Rényi divergence also satisfies the joint convexity property: for a mixture of probability distributions and with weights ,
This inequality demonstrates that Rényi divergence behaves well under probabilistic mixing. Another fundamental result is the Pinsker-type bound, which states that for , the Rényi divergence is bounded below by a function of the total variation distance ,
For small , this inequality shows that Rényi divergence behaves quadratically in the deviation between P and Q. Furthermore, the Rényi divergence is closely related to the Chernoff information, which determines the optimal exponent for Bayesian hypothesis testing. The Chernoff information is defined as
which plays a fundamental role in large deviations theory and hypothesis testing.
In summary, the Rényi divergence is a highly versatile and mathematically rich measure of dissimilarity between probability distributions. It generalizes the KL divergence, interpolates between various known divergence measures, satisfies essential properties such as monotonicity and data-processing inequalities, and has deep connections to large deviation theory, statistical estimation, and hypothesis testing.
4.1.4.1 Python Code to Generate Figure 43 and Figure 44 Illustrating Rényi Divergence
Figure 43.
Rényi Divergence between Gaussians vs.
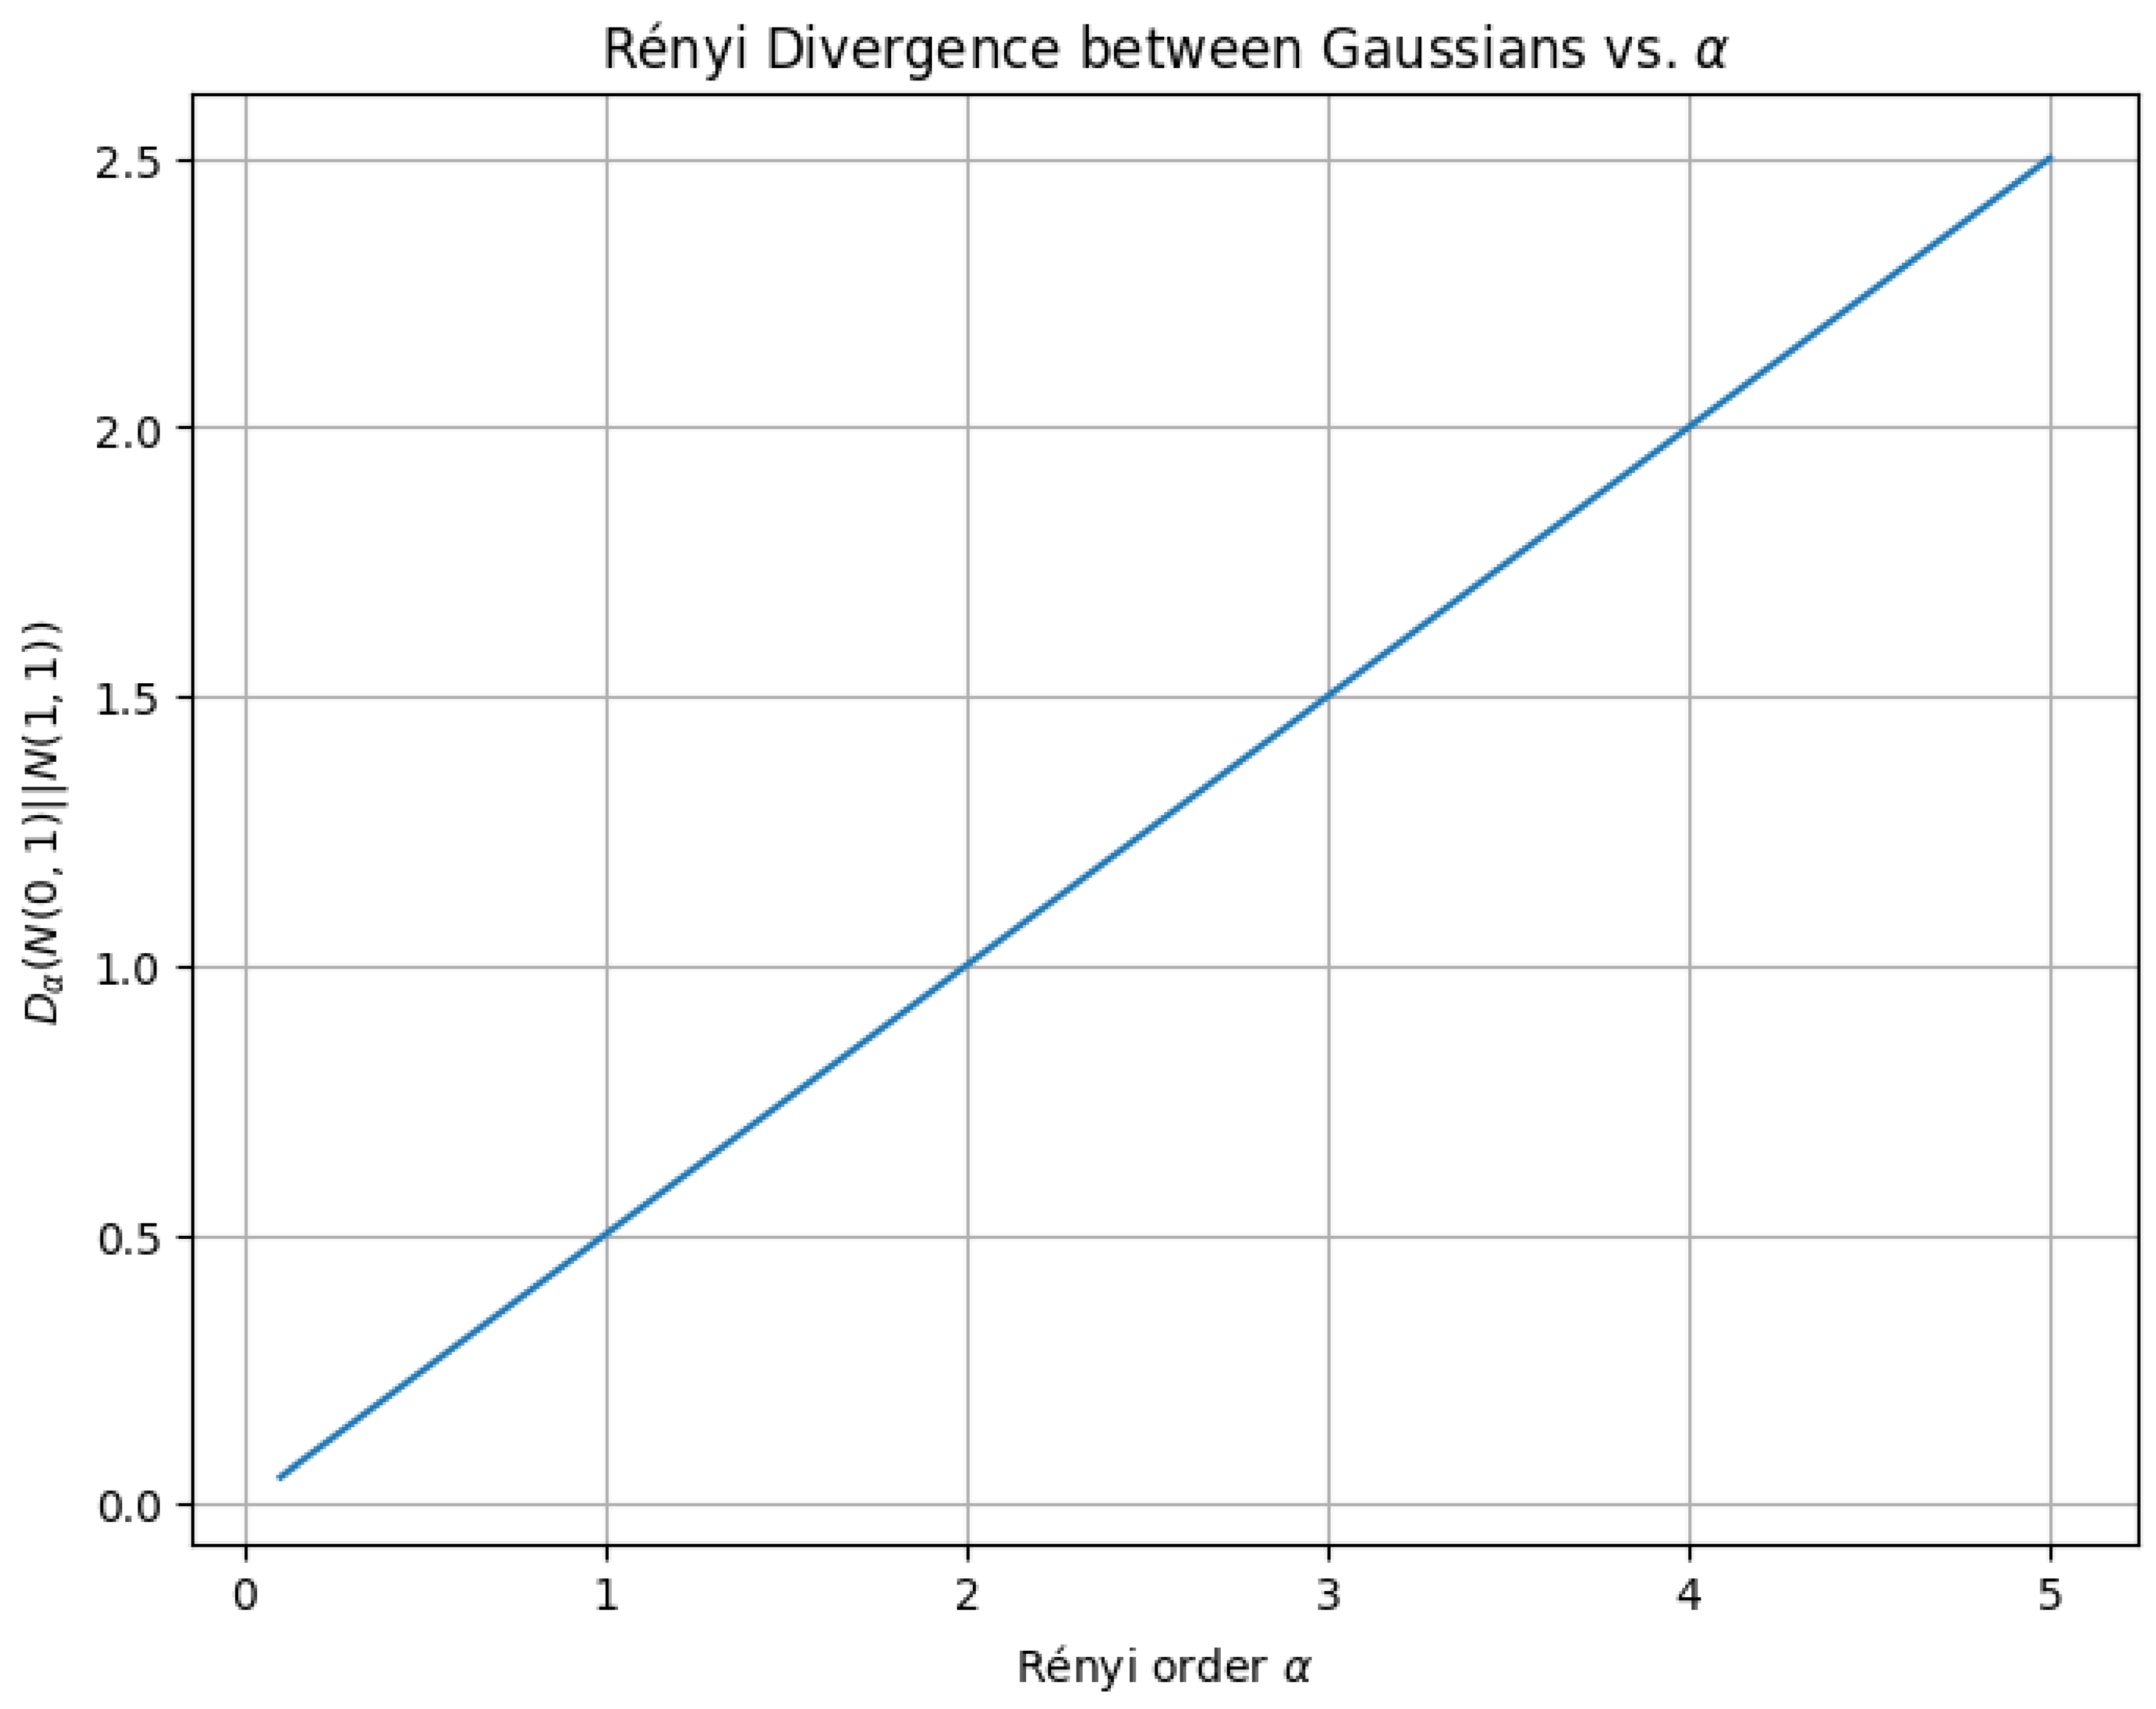
Figure 44.
Rényi Divergence Heatmap ()
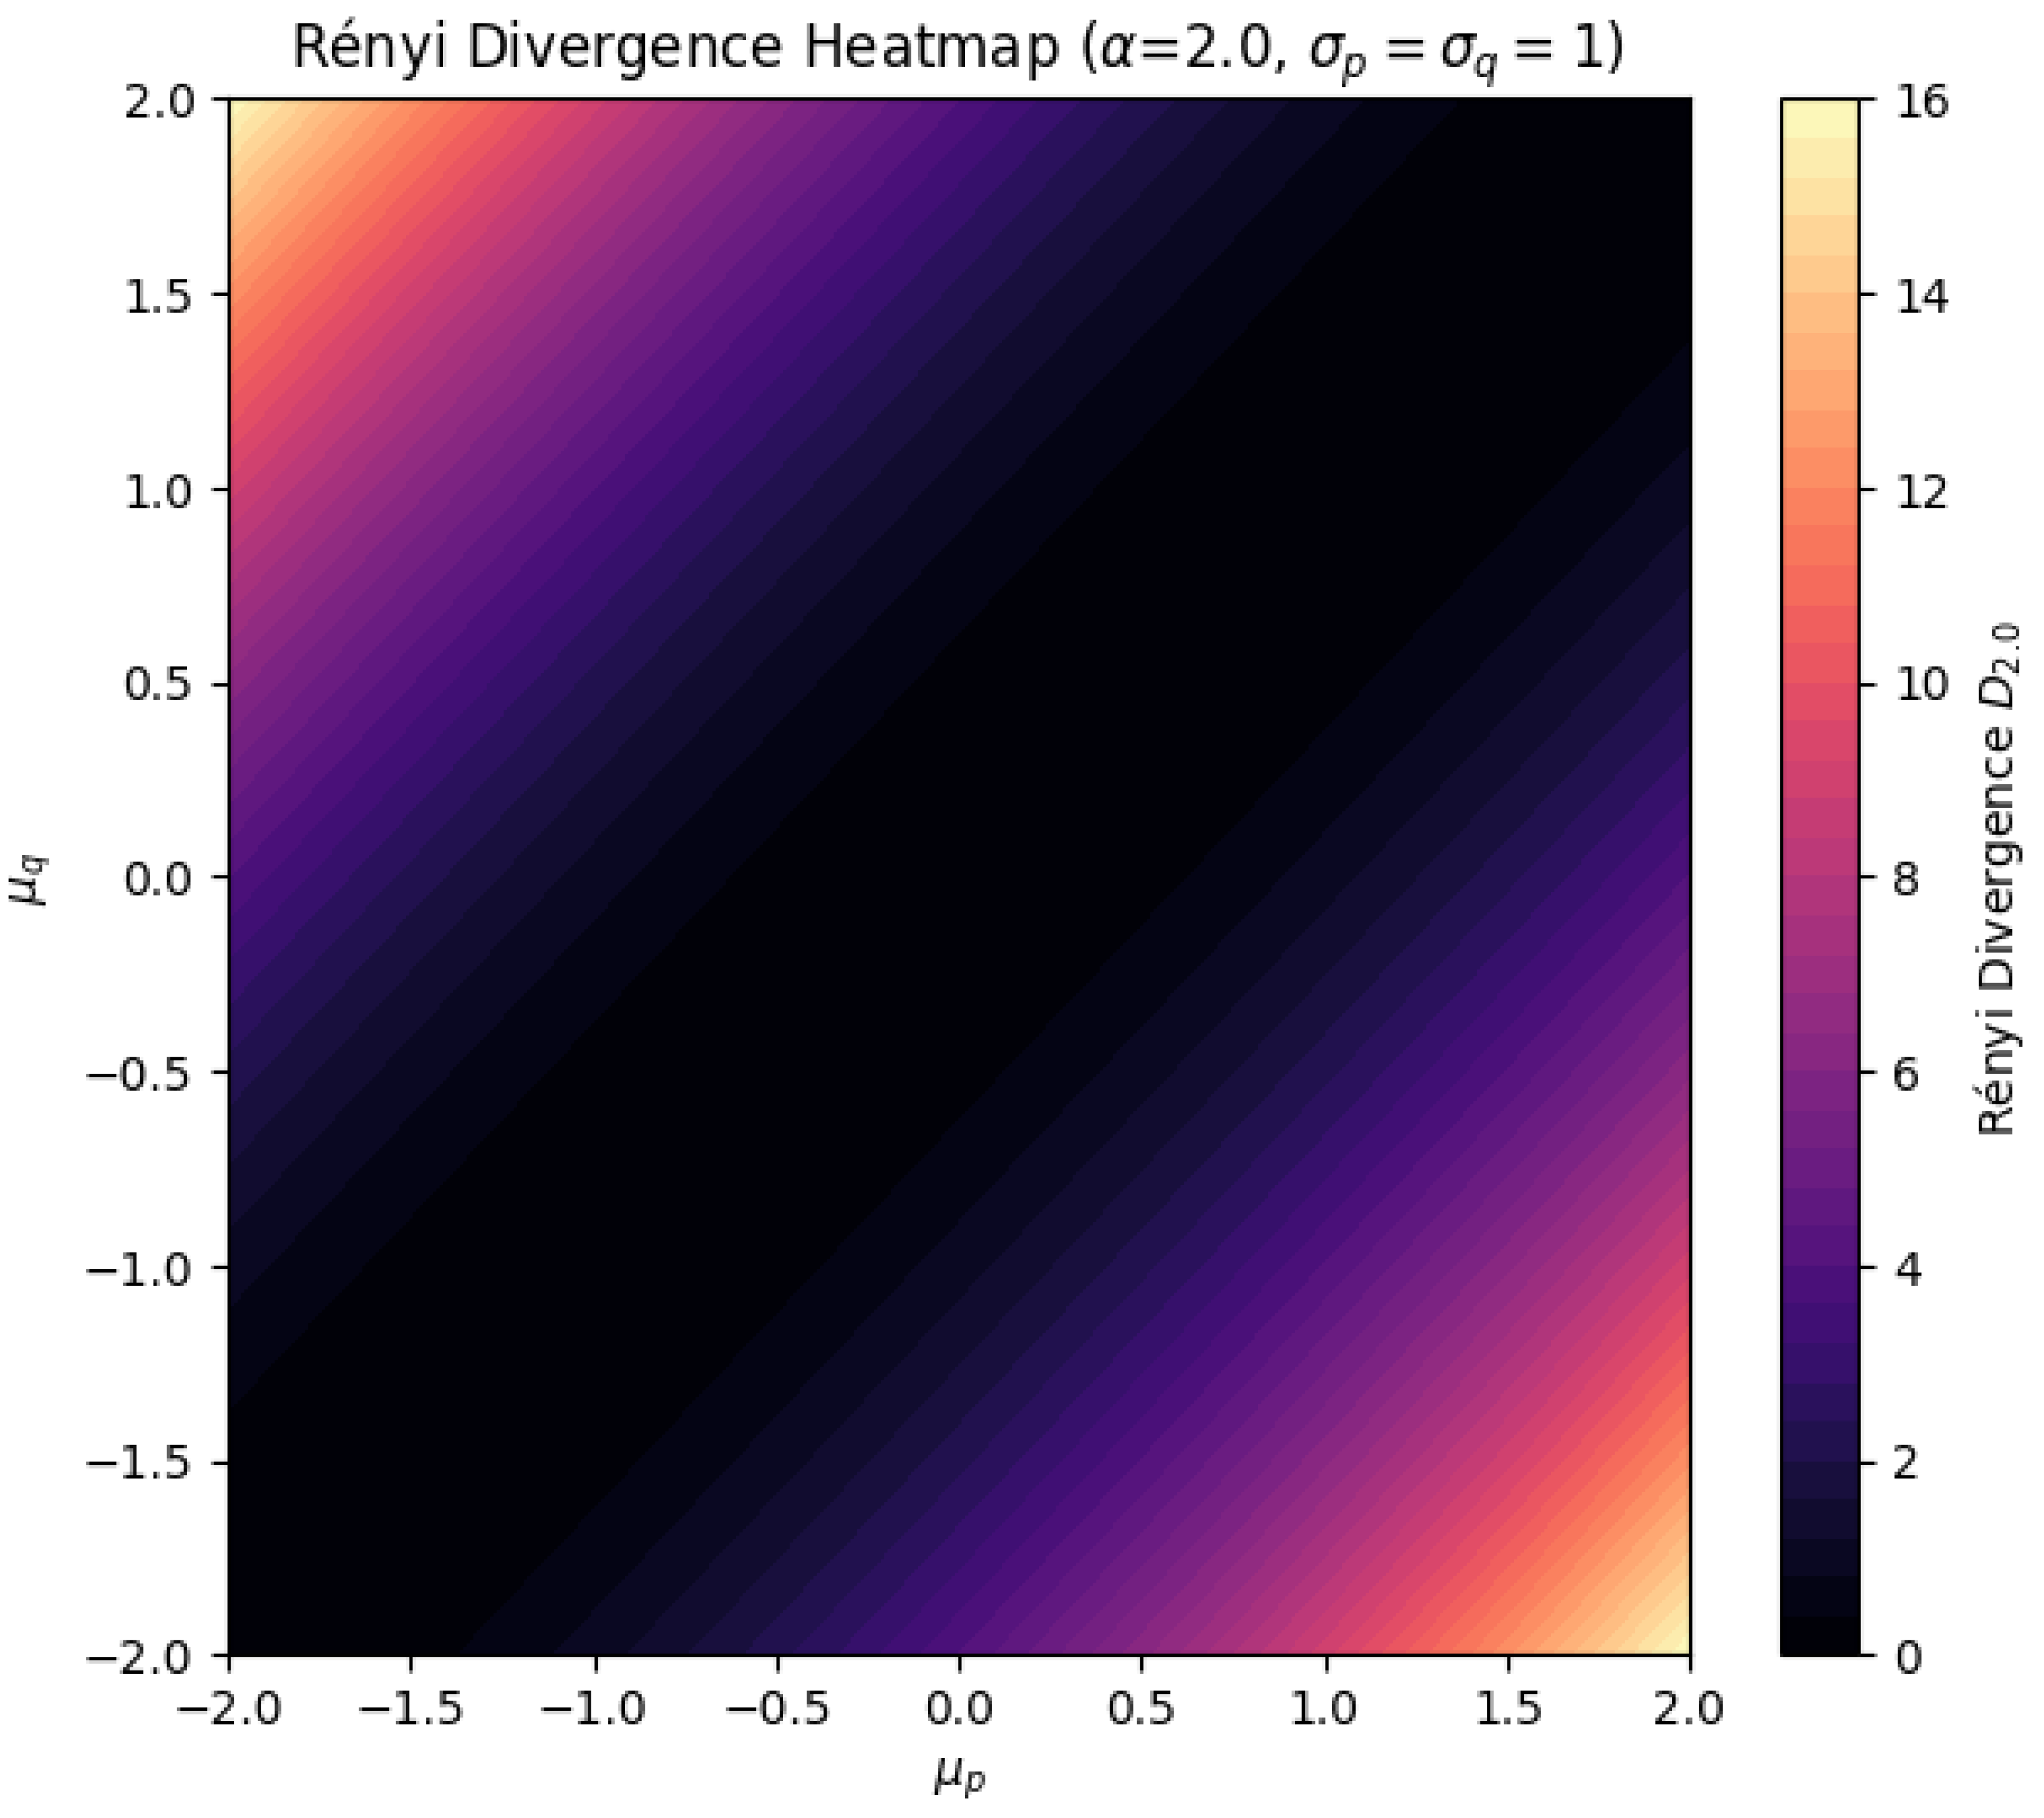
4.1.5. Wasserstein Distance
The Wasserstein distance, also referred to as the Earth Mover’s Distance (EMD), is a fundamental metric in the field of optimal transport theory that rigorously quantifies the distance between two probability measures by determining the minimal cost required to transport one measure into another.
Consider two probability distributions and , defined on a metric space . The Wasserstein distance of order is defined by
where denotes the set of all probability measures on the product space satisfying
This definition arises from the optimal transport problem, originally formulated by Monge in 1781 and later extended by Kantorovich. The Monge formulation seeks a transport map that pushes onto , i.e., satisfies
where denotes the pushforward measure defined by
The Monge formulation minimizes the total transport cost given by
However, the existence of an optimal transport map is highly constrained and may fail in many cases. To overcome this, Kantorovich introduced a relaxation in which transport maps are replaced by probability couplings , leading to the variational problem
This formulation allows for mass splitting, making the problem more tractable and ensuring the existence of minimizers under mild conditions. The dual formulation of the Wasserstein distance is given by
subject to the constraint
For , the Kantorovich-Rubinstein theorem provides an alternative characterization
When , the Wasserstein-1 distance has the closed-form expression
where and are the cumulative distribution functions of and , respectively. For , the squared Wasserstein-2 distance is given by
If and are Gaussian distributions and , then
The Wasserstein distance induces a metric on the space of probability measures, providing a notion of distance that is weaker than total variation but stronger than weak convergence.
Specifically, if in Wasserstein distance, then for any function f satisfying
it holds that
The Wasserstein metric endows the space of probability measures with a Riemannian-like structure, where geodesics are given by McCann interpolation, defined as
For discrete distributions
the Wasserstein distance reduces to a linear programming problem
Computationally, Wasserstein distances are expensive to evaluate, but regularized approximations such as Sinkhorn’s algorithm solve the entropically regularized problem
This approximation allows for efficient computation via iterative updates using the Sinkhorn-Knopp algorithm. The Wasserstein distance plays a crucial role in probability theory, statistics, machine learning, and functional analysis, providing a rigorous mathematical framework for comparing distributions with deep connections to convex geometry, measure theory, and differential geometry.
4.1.5.1 Python Code to Generate Figure 45, Figure 46, and Figure 47 Illustrating Wasserstein Distance
The Python code below produces the Figure 45, Figure 46, and Figure 47 illustrating Wasserstein distance.
Figure 45.
Wasserstein Distance vs Mean Difference ()
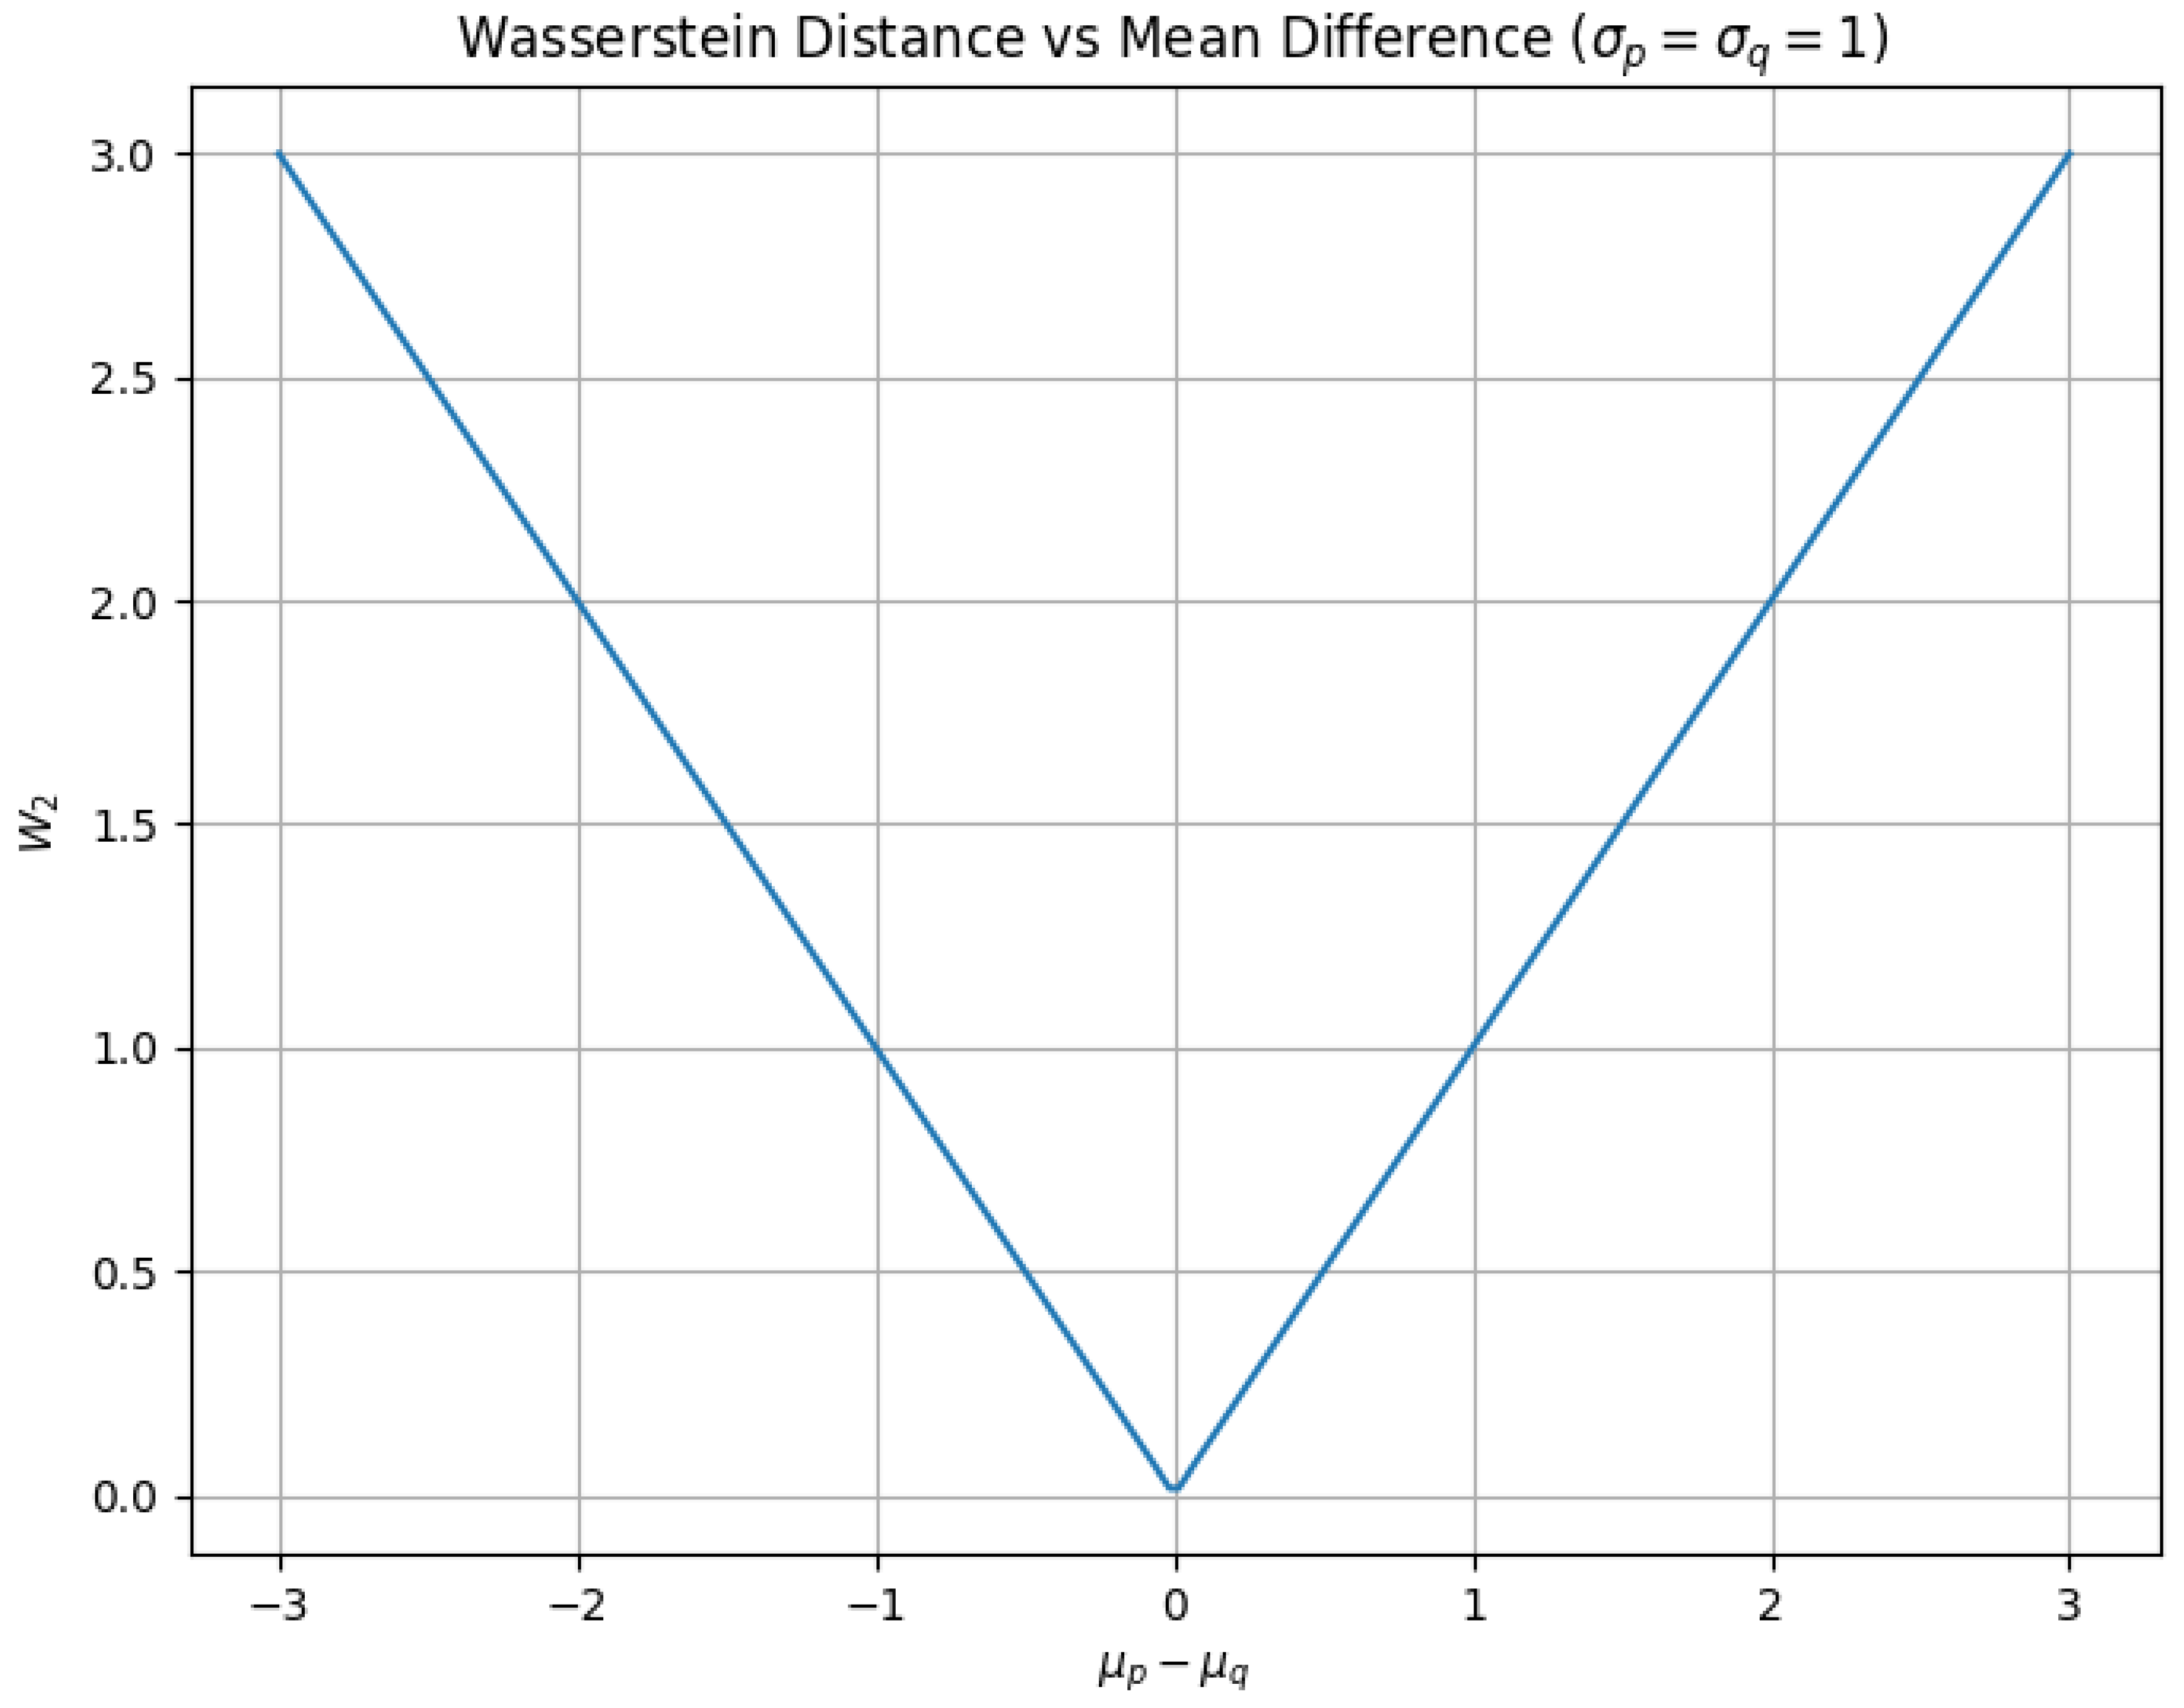
Figure 46.
Wasserstein Distance vs Variance ()
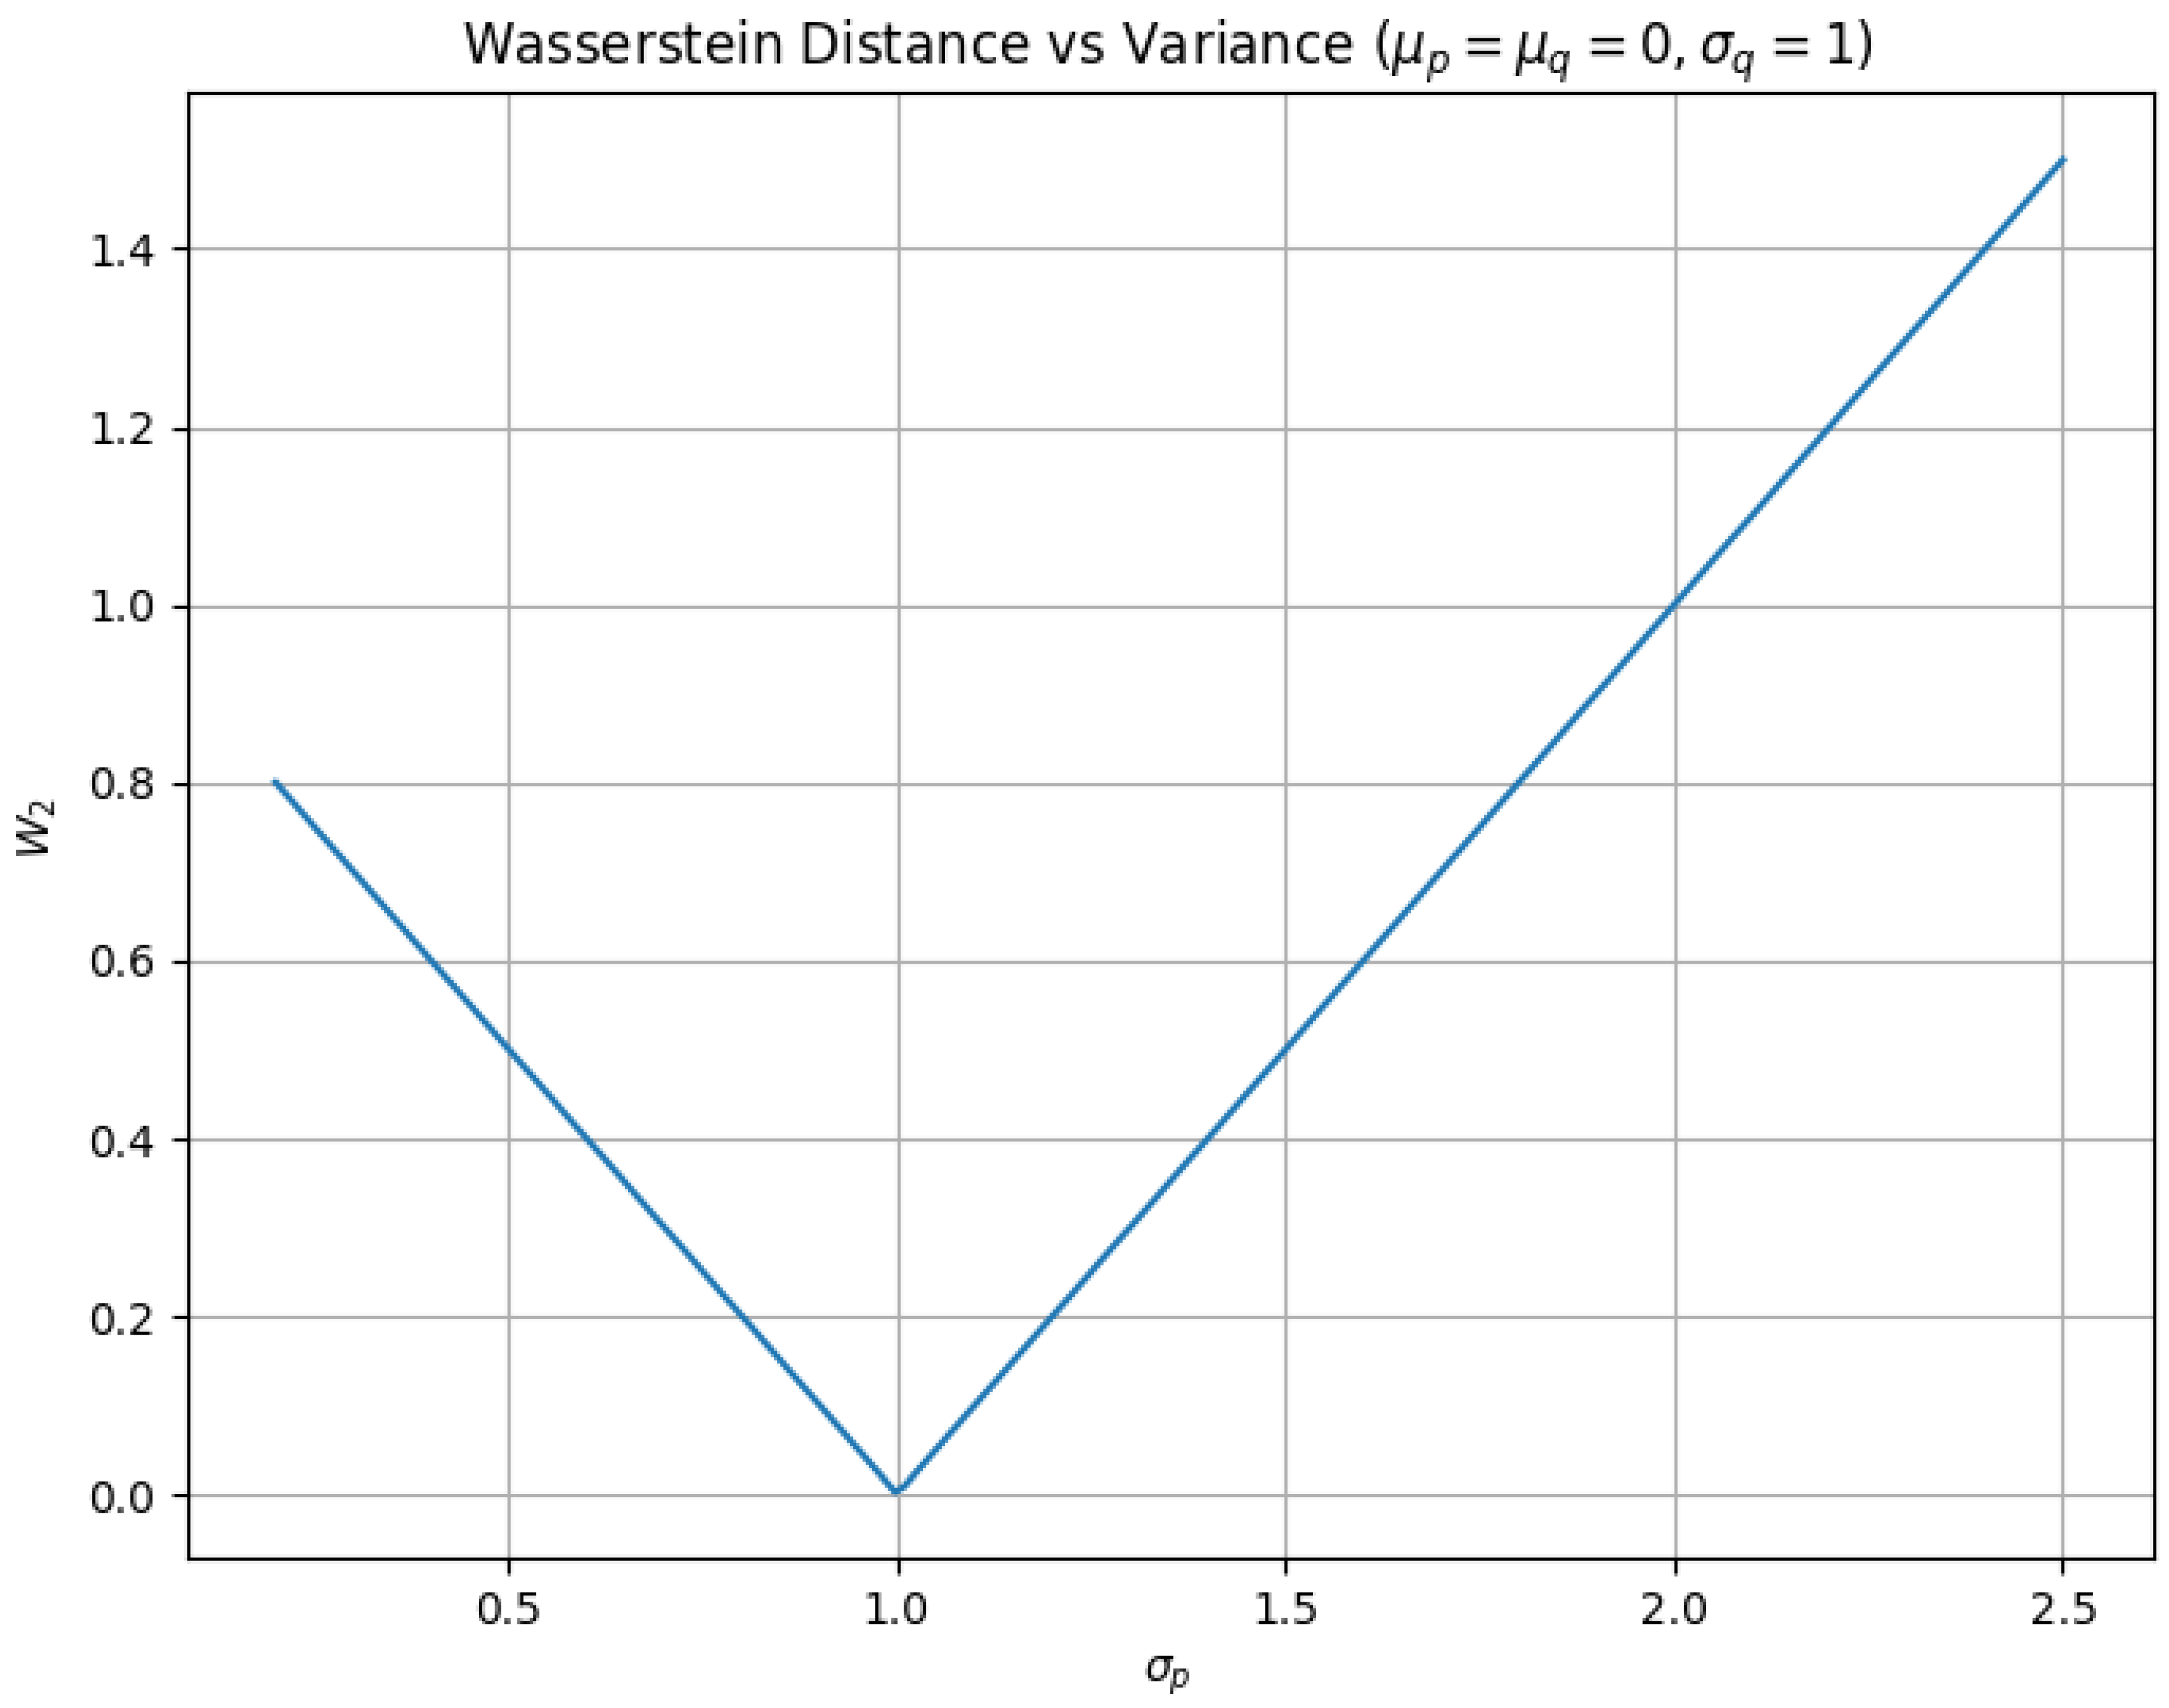
Figure 47.
Wasserstein Distance Heatmap ()
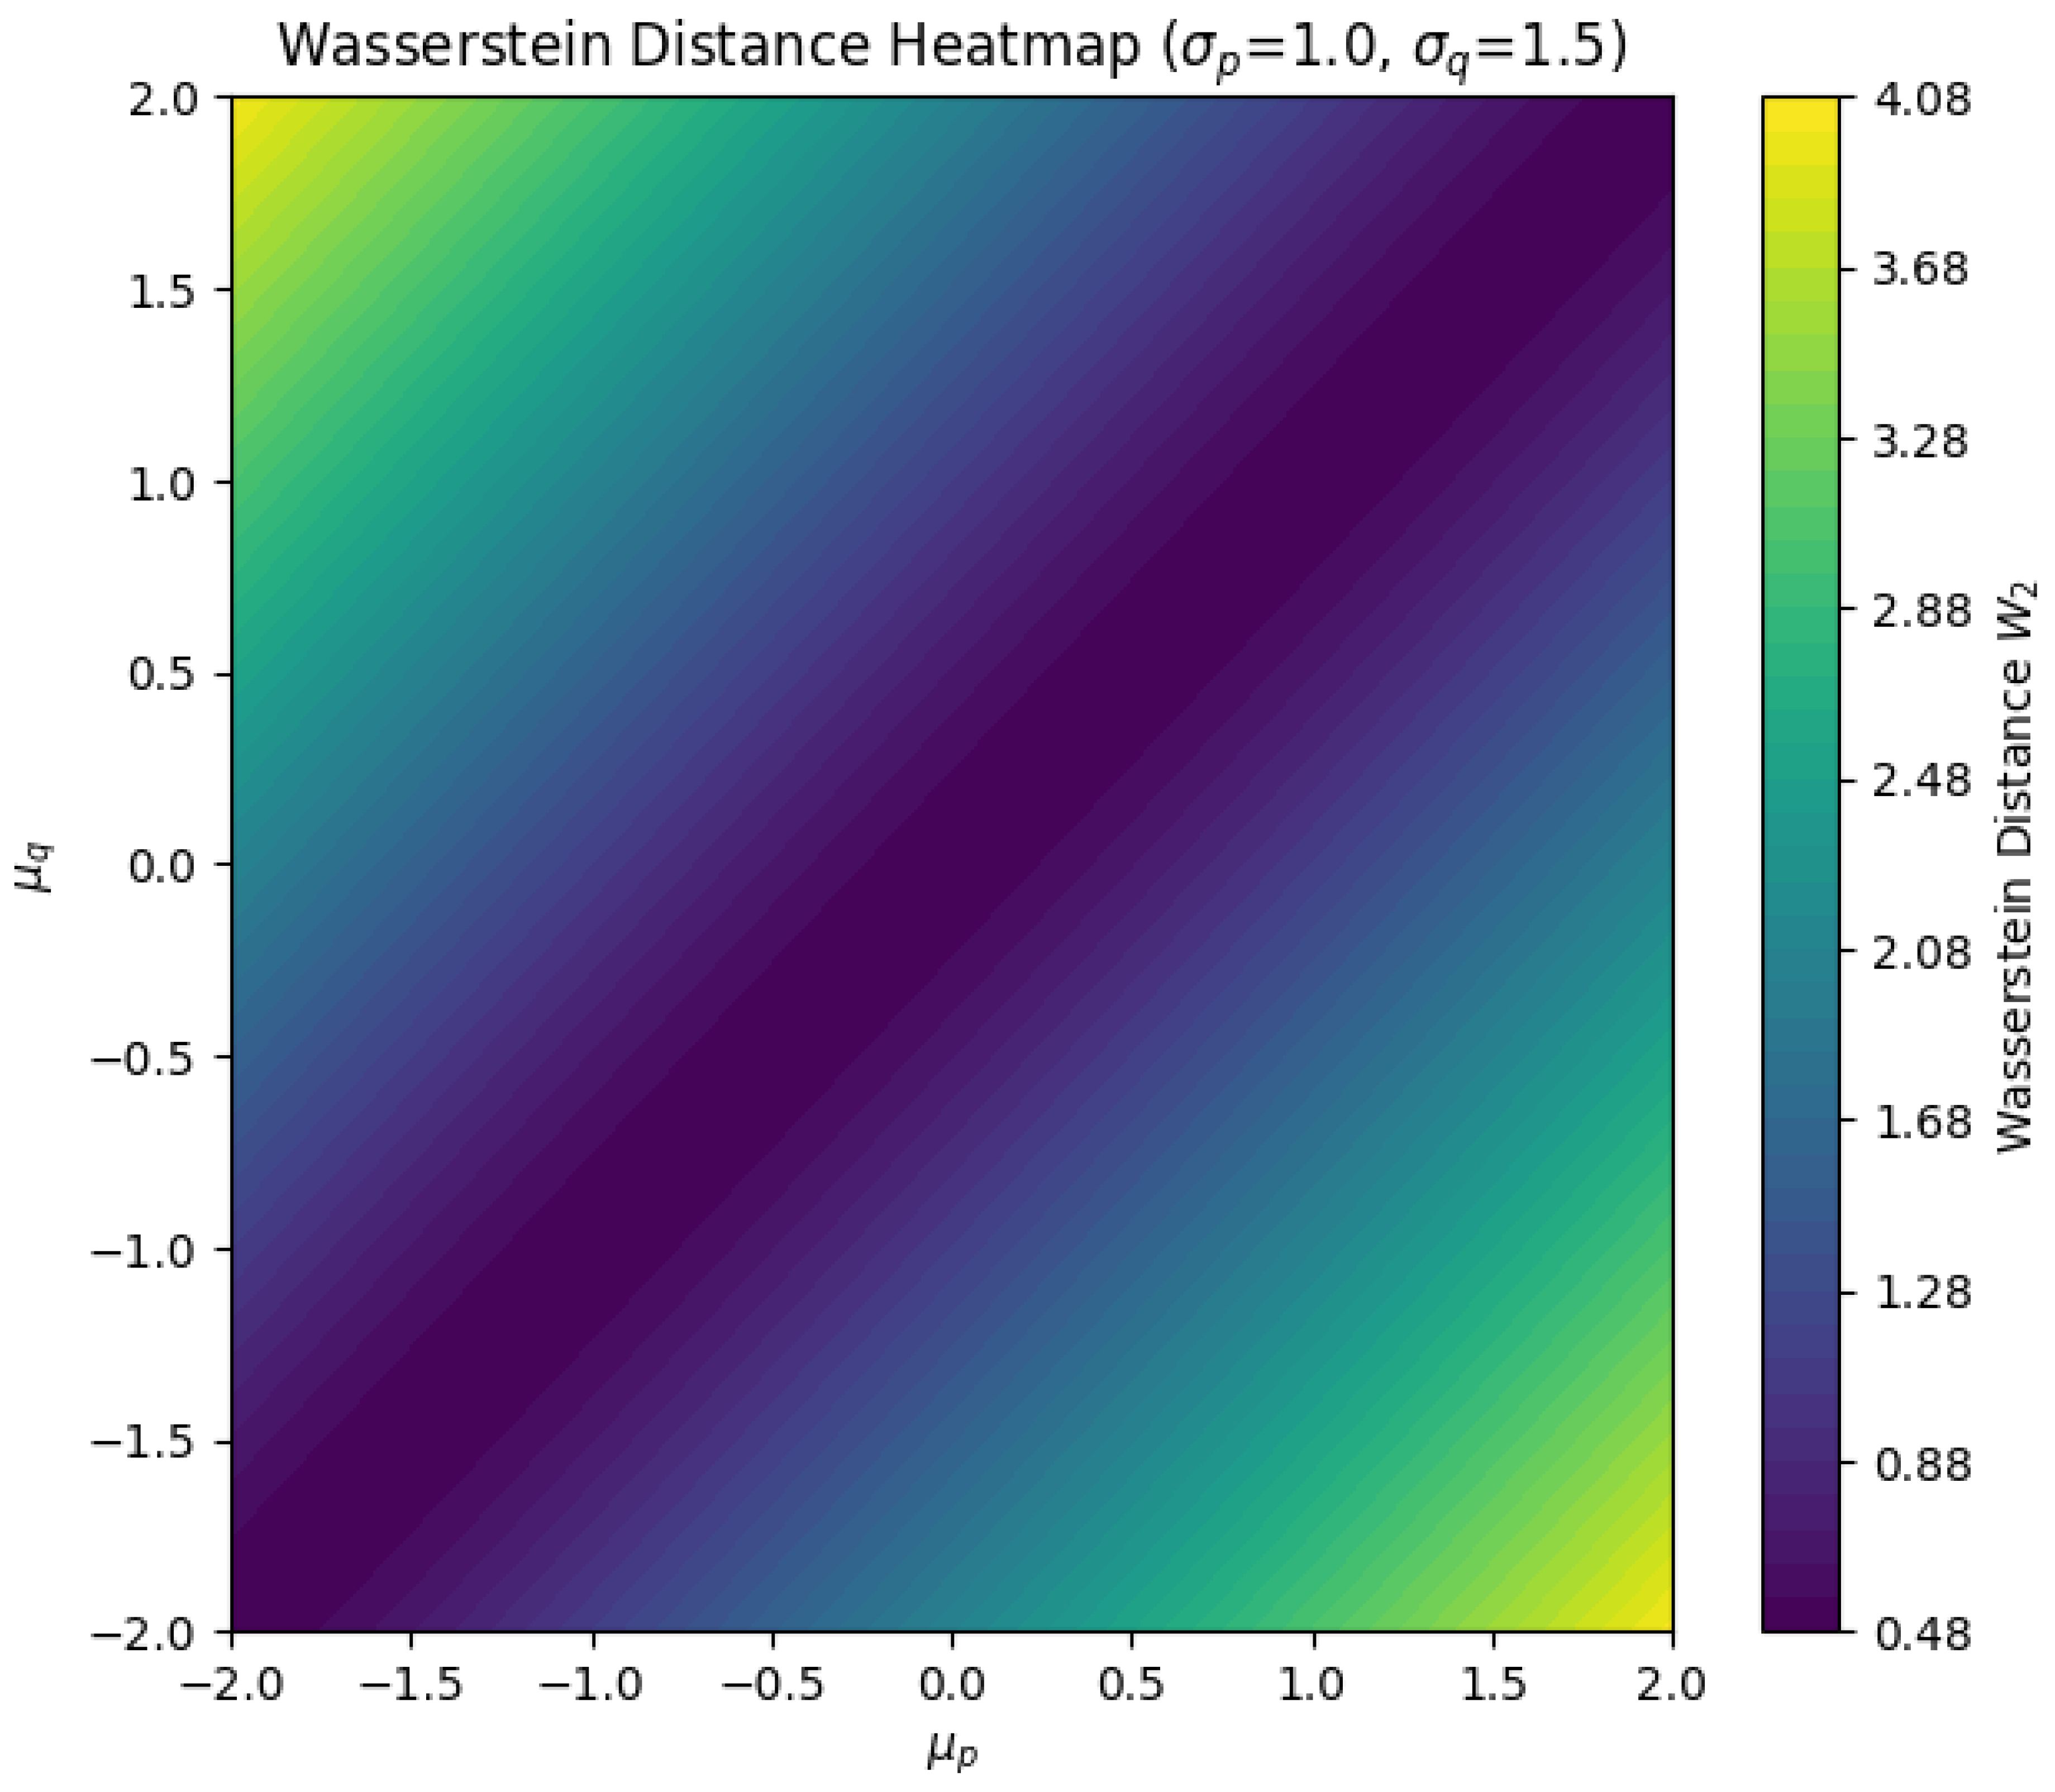
4.2. Spectral Regularization
The concept of spectral regularization, which refers to the preferential learning of low-frequency modes by neural networks before high-frequency modes, emerges from a combination of Fourier analysis, optimization theory, and the inherent properties of deep neural networks. This phenomenon is tightly connected to the functional approximation capabilities of neural networks and can be rigorously understood through the lens of Fourier decomposition and the gradient descent optimization process.
4.2.1. Literature Review of Spectral Regularization
Jin et. al. (2025) [110] introduced a novel confusional spectral regularization technique to improve fairness in machine learning models. The study focuses on the spectral norm of the robust confusion matrix and proposes a method to control spectral properties, ensuring more robust and unbiased learning. It provides insights into how regularization can mitigate biases in classification tasks. Ye et. al. (2025) [111] applied spectral clustering with regularization to detect small clusters in complex networks. The work enhances spectral clustering techniques by integrating regularization methods, allowing improved performance in anomaly detection and community detection tasks. The approach significantly improves robustness in highly noisy data environments. Bhattacharjee and Bharadwaj (2025) [112] explored how spectral domain representations can benefit from autoencoder-based feature extraction combined with stochastic regularization techniques. The authors propose a Symmetric Autoencoder (SymAE) that enables better generalization of spectral features, particularly useful in high-dimensional data and deep learning applications. Wu et. al. (2025) [113] applied spectral regularization to geophysical data processing, specifically for high-resolution velocity spectrum analysis. The approach enhances the resolution of velocity estimation in seismic imaging by using hyperbolic Radon transform regularization, demonstrating how spectral regularization can benefit applications beyond traditional ML. Ortega et. al. (2025) [114] applied Tikhonov regularization to atmospheric spectral analysis, optimizing gas retrieval strategies in high-resolution spectroscopic observations. The work significantly improves methane (CH4) and nitrous oxide (N2O) detection accuracy by reducing noise in spectral measurements, showcasing the impact of spectral regularization in remote sensing and environmental monitoring. Kazmi et. al. (2025) [115] proposed a spectral regularization-based federated learning model to improve robustness in cybersecurity threat detection. The model addresses the issue of non-IID data in SDN (Software Defined Networks) by utilizing spectral norm-based regularization within deep learning architectures. Zhao et. al. (2025) [116] introduced a regularized deep spectral clustering method, which enhances feature selection and clustering robustness. The authors utilize projected adaptive feature selection combined with spectral graph regularization, improving clustering accuracy and interpretability in high-dimensional datasets. Saranya and Menaka (2025) [117] integrated spectral regularization with quantum-based machine learning to analyze EEG signals for Autism Spectrum Disorder (ASD) detection. The proposed method improves spatial filtering and feature extraction using wavelet-based regularization, leading to more reliable EEG pattern recognition. Cox and Ghosh (2022) [72] develop a partial factorization algorithm that utilizes Mertens’ function to factor certain natural numbers, introduce a modified variant of Mertens’ function constrained to negative values (except at ), and explore its relationship with the sum-of-divisors function, thereby revealing new arithmetic connections between multiplicative and additive number-theoretic structures. Dhalbisoi et. al. (2024) [118] developed a Regularized Zero-Forcing (RZF) method for spectral efficiency optimization in beyond 5G networks. The authors demonstrate that spectral regularization techniques can significantly improve signal-to-noise ratios in wireless communication systems, optimizing data transmission in massive MIMO architectures. Wei et. al. (2025) [119] explored the use of spectral regularization in medical imaging, particularly in 3D near-infrared spectral tomography. The proposed model integrates regularized convolutional neural networks (CNNs) to improve tissue imaging resolution and accuracy, demonstrating an application of spectral regularization in biomedical engineering.
4.2.2. Analysis of Spectral Regularization
Let us define a target function , where , and its Fourier transform as
This transform breaks down into frequency components indexed by . In the context of deep learning, we seek to approximate with a neural network output , where represents the set of trainable parameters. The loss function to be minimized is typically the mean squared error:
We can equivalently express this loss in the Fourier domain, leveraging Parseval’s theorem:
To solve for , we employ gradient descent:
where is the learning rate. The gradient of the loss function with respect to is
At the core of this gradient descent process lies the behavior of the gradient with respect to the frequency components .
For neural networks, particularly those with ReLU activations, the gradients of the output with respect to the parameters are expected to decay for high-frequency components. This can be approximated as
which implies that the neural network is inherently more sensitive to low-frequency components of the target function during early iterations of training. This spectral decay is a direct consequence of the structure of the network’s activations, which are more sensitive to low-frequency features due to their smoother, lower-order terms. To understand the role of the neural tangent kernel (NTK), which governs the linearized dynamics of the neural network, we define the NTK as
The NTK essentially describes how the output of the network changes with respect to its parameters. The evolution of the network’s output during training can be approximated by the solution to a linear system governed by the NTK. The output of the network at time t is given by
where are the eigenvalues of , and are the corresponding eigenfunctions. The eigenvalues determine the speed of convergence for each frequency mode, with low-frequency modes (large ) converging more quickly than high-frequency ones (small ):
This differential learning rate for frequency components leads to the spectral regularization phenomenon, where the network learns the low-frequency components of the function first, and the high-frequency modes only begin to adapt once the low-frequency ones have been approximated with sufficient accuracy. In a more formal setting, the spectral bias can also be understood in terms of Sobolev spaces.
A neural network function can be seen as a function in a Sobolev space , where the norm of a function f in this space is defined as
When training a neural network, the optimization process implicitly regularizes the higher-order Sobolev norms, meaning that the network will initially approximate the target function in terms of lower-order derivatives (which correspond to low-frequency modes). This can be expressed by introducing a regularization term in the loss function:
where is a regularization parameter that controls the trade-off between data fidelity and smoothness in the approximation.
Thus, spectral regularization emerges as a consequence of the network’s architecture, the nature of gradient descent optimization, and the inherent smoothness of the functions that neural networks are capable of learning. The mathematical structure of the NTK and the regularization properties of the Sobolev spaces provide a rigorous framework for understanding why neural networks prioritize the learning of low-frequency modes, reinforcing the idea that neural networks are implicitly biased toward smooth, low-frequency approximations at the beginning of training. This insight has profound implications for the generalization behavior of neural networks and their capacity to approximate complex functions.
4.2.3. Python Code to Generate Figure 48 and Figure 49 Illustrating Spectral Regularization
Figure 48.
Effect of Spectral Regularization on Singular Values
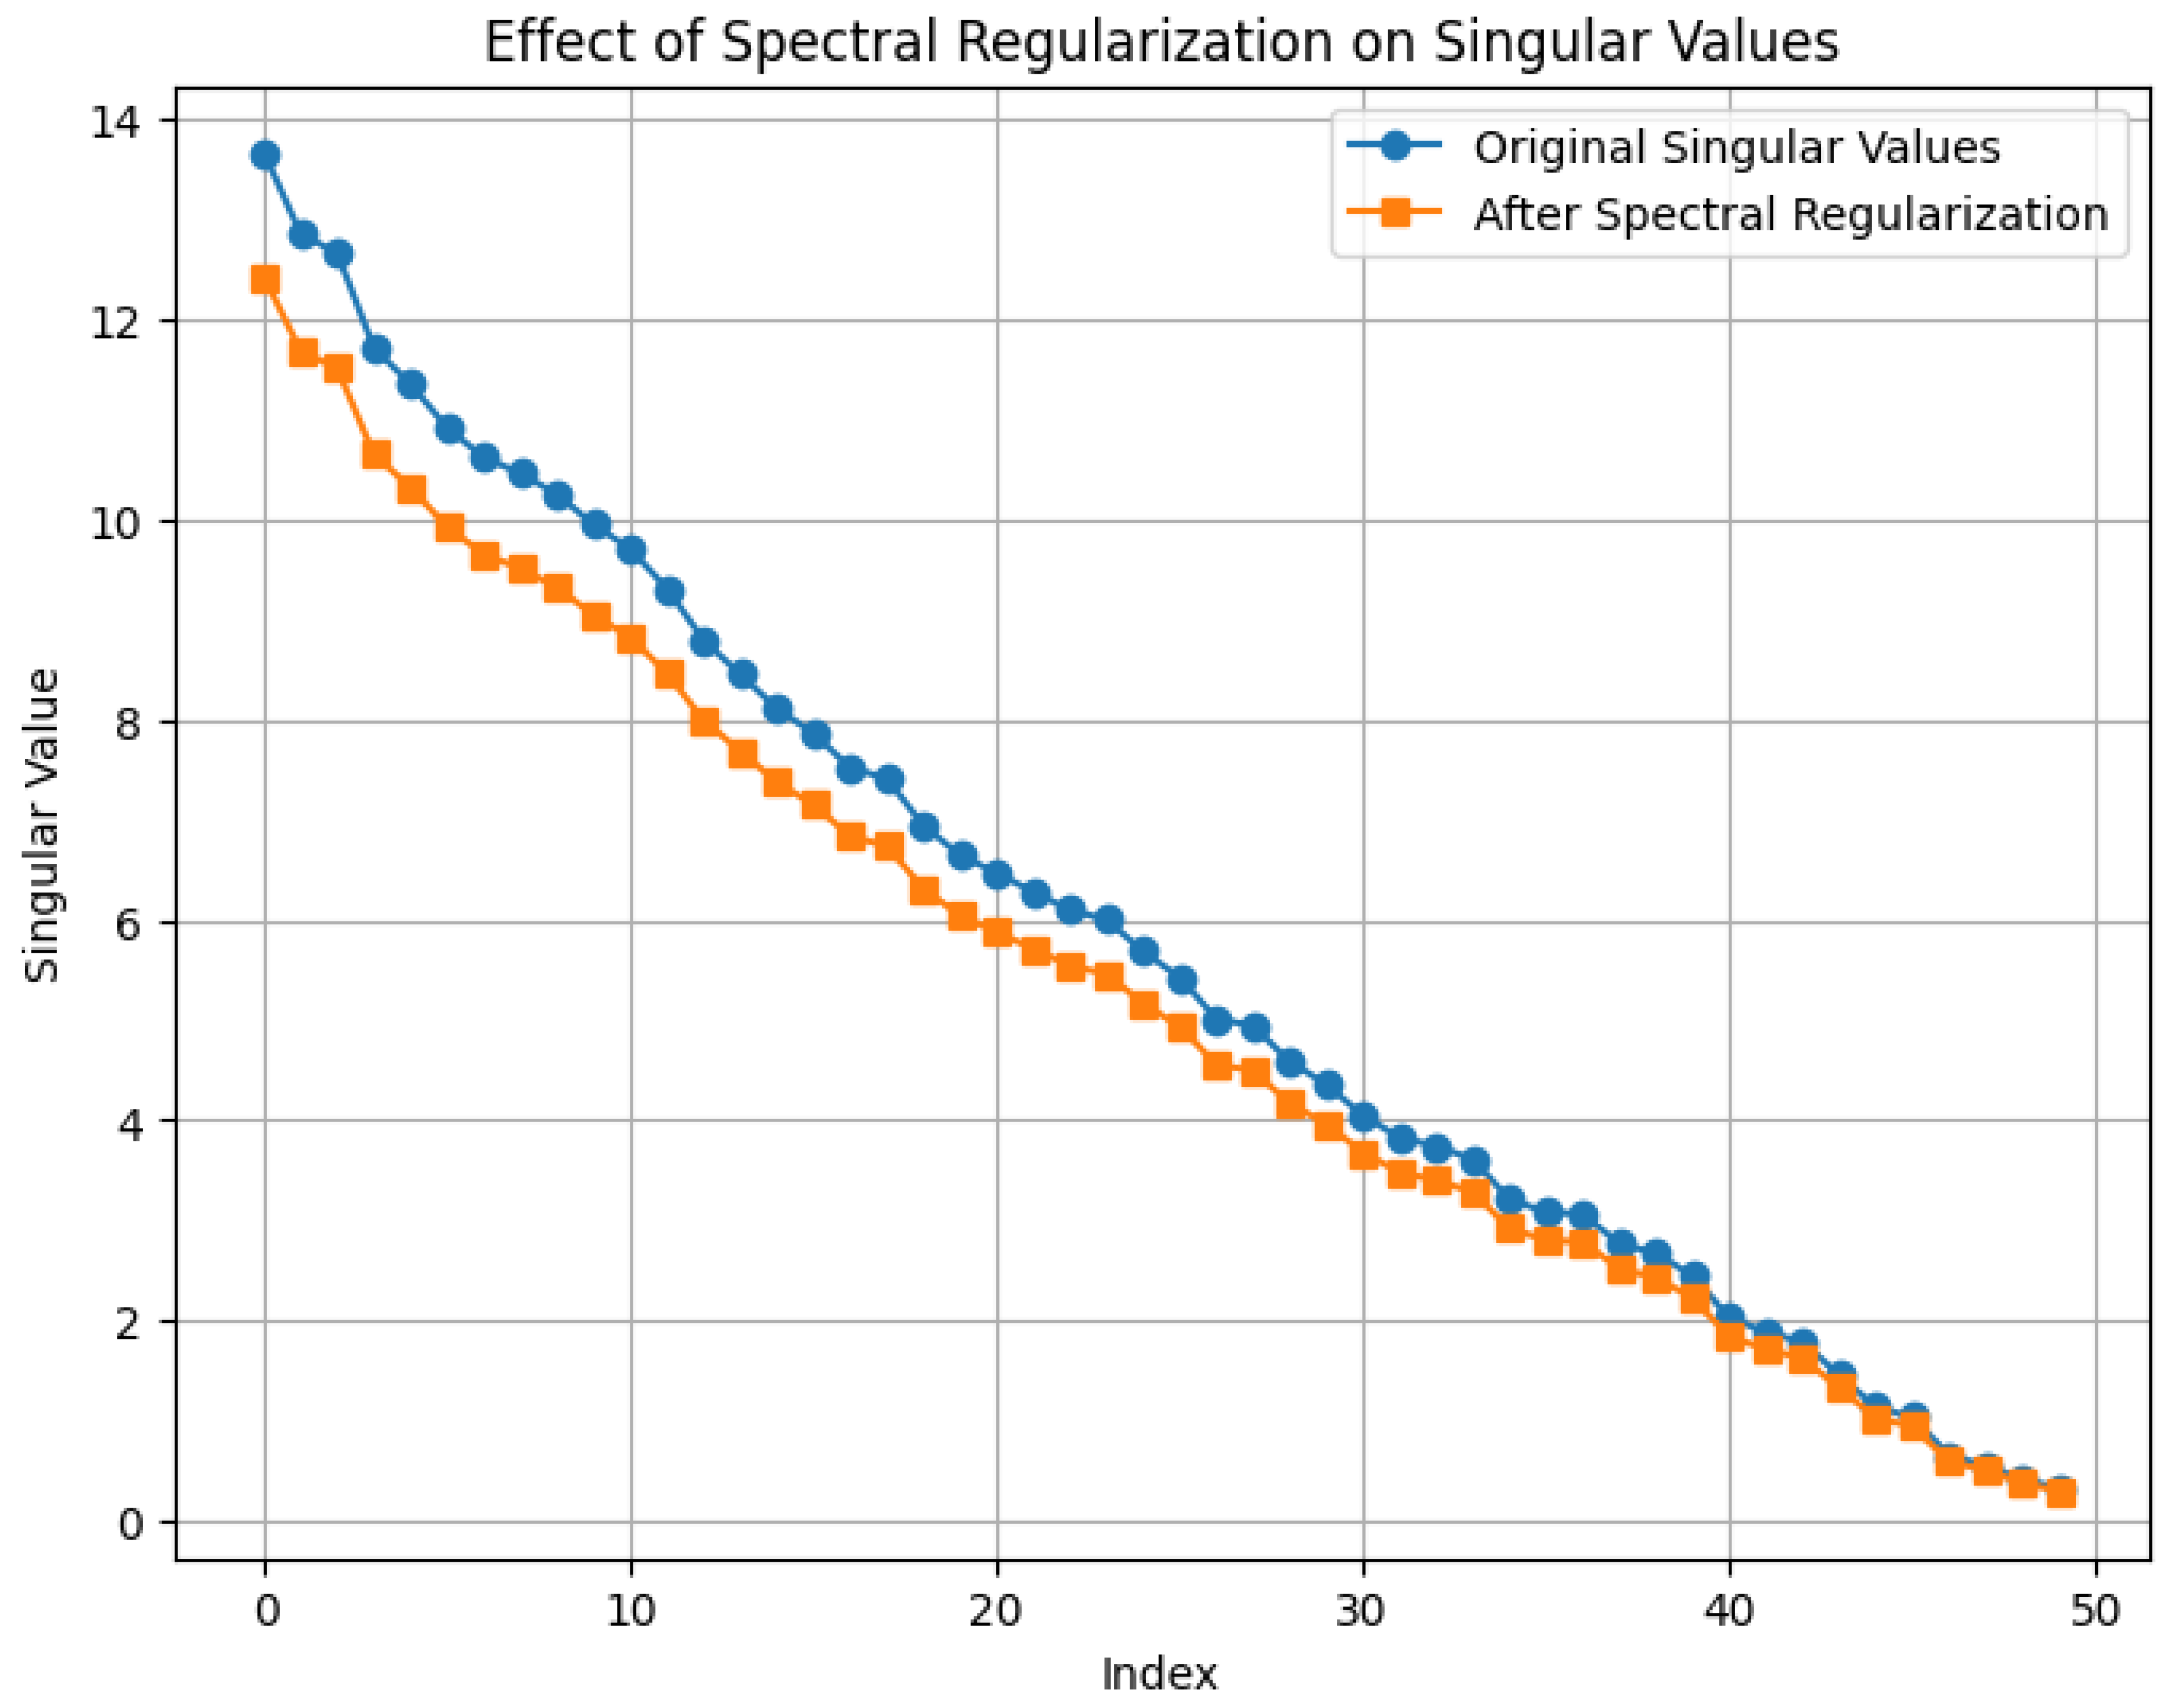
Figure 49.
Original Weight Matrix & After Spectral Regularization
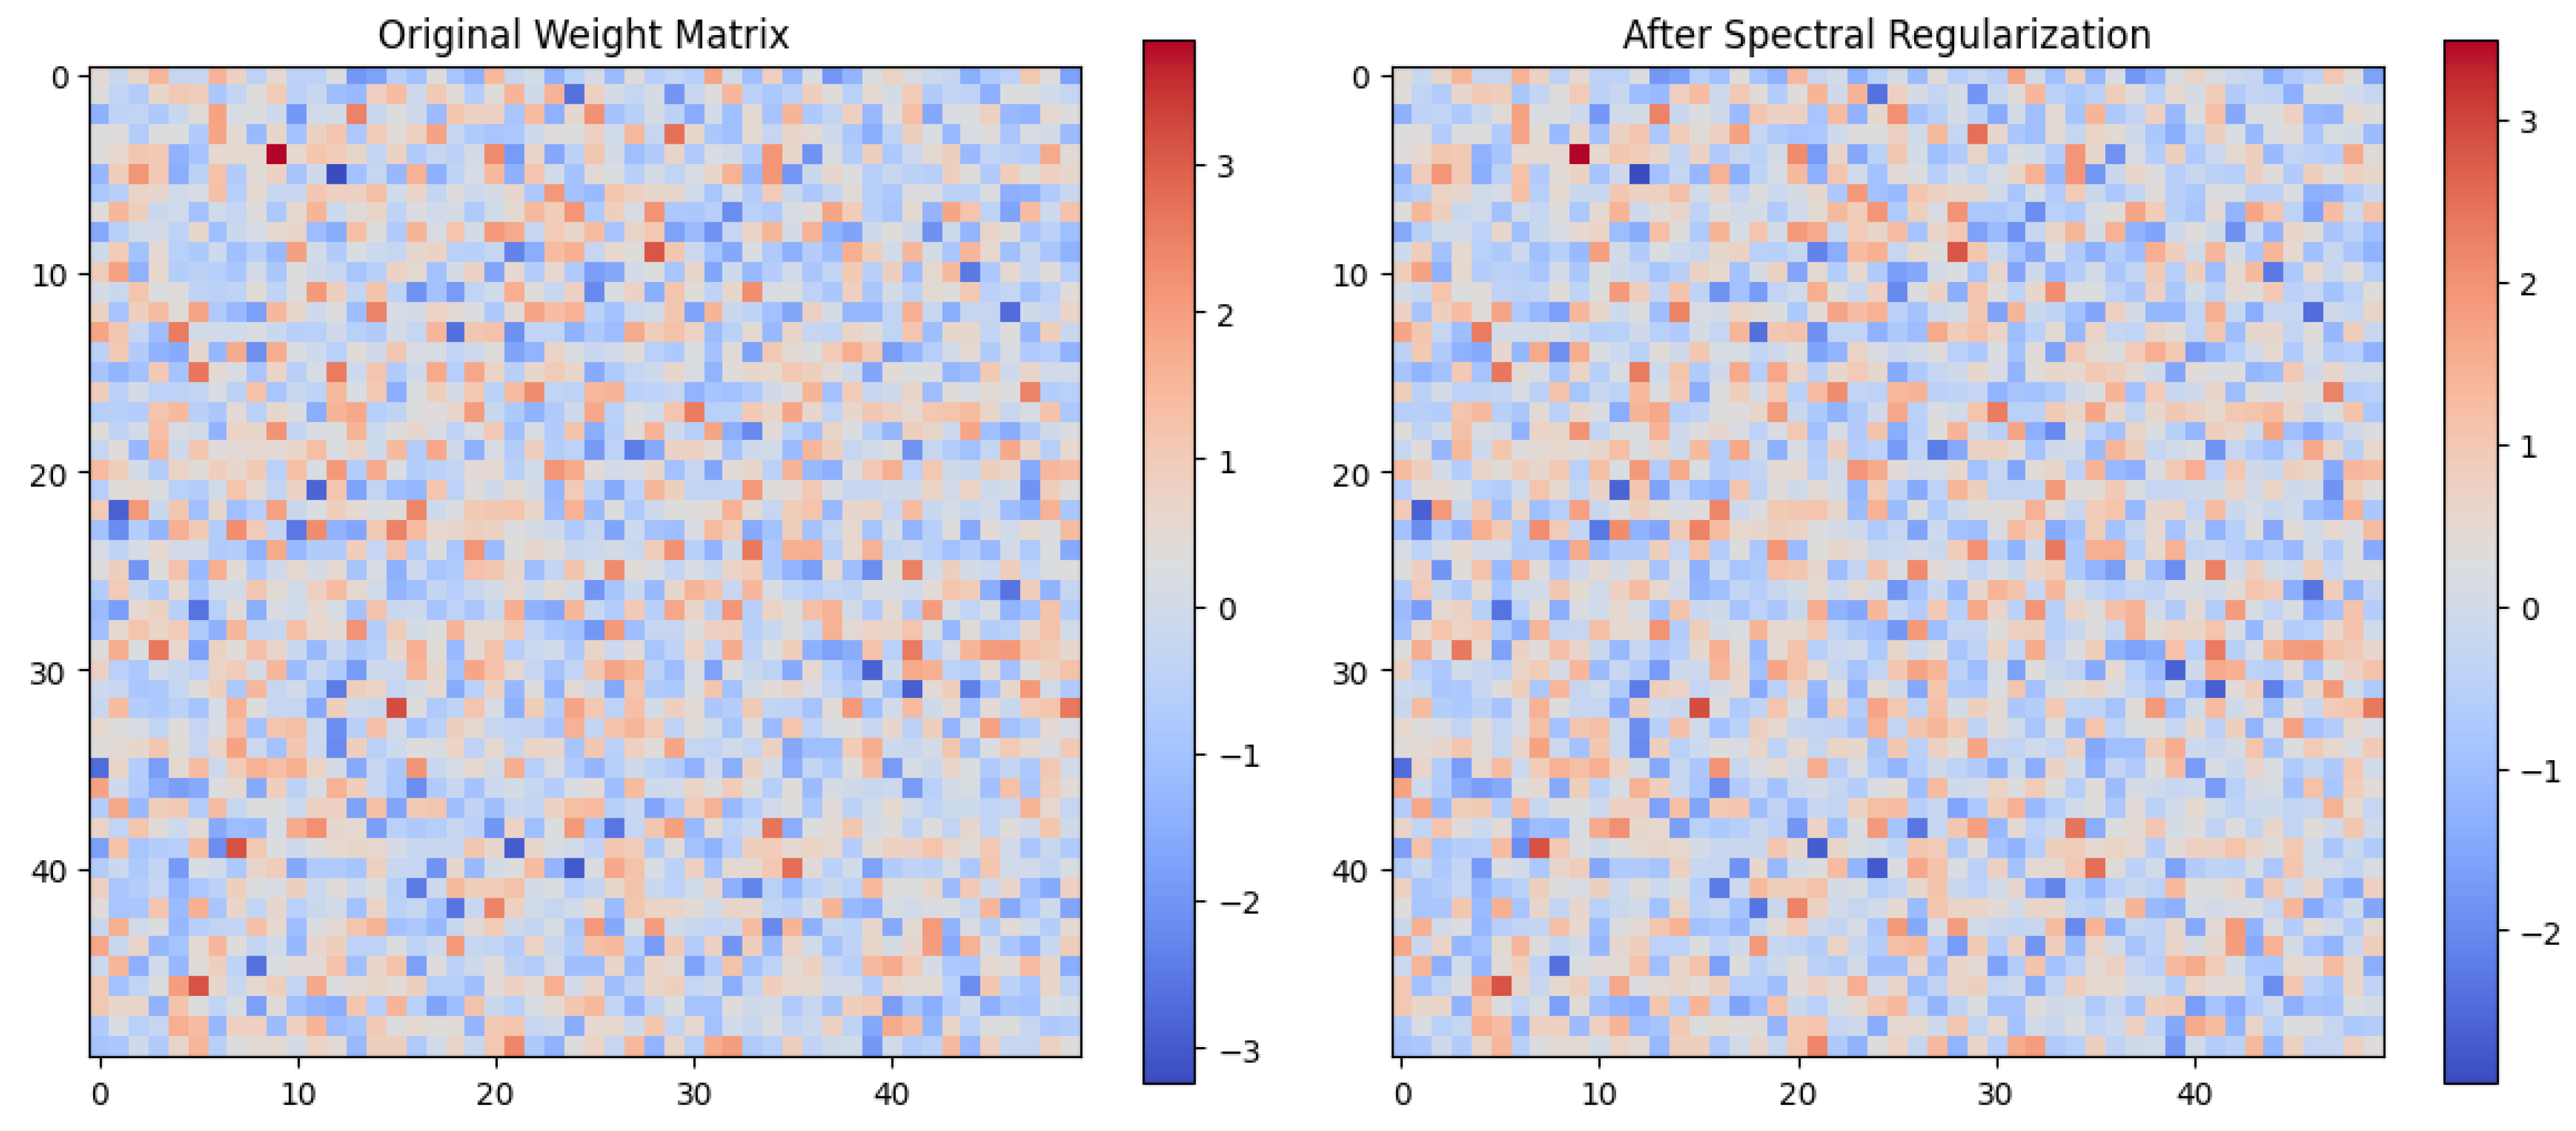
4.2.4. Python Code to Generate Figure 50 Illustrating Singular Value Spectrum of First Layer (MNIST)
The Python code below produces the Figure 50 illustrating Singular Value Spectrum of First Layer (MNIST).
Figure 50.
Singular Value Spectrum of First Layer (MNIST)
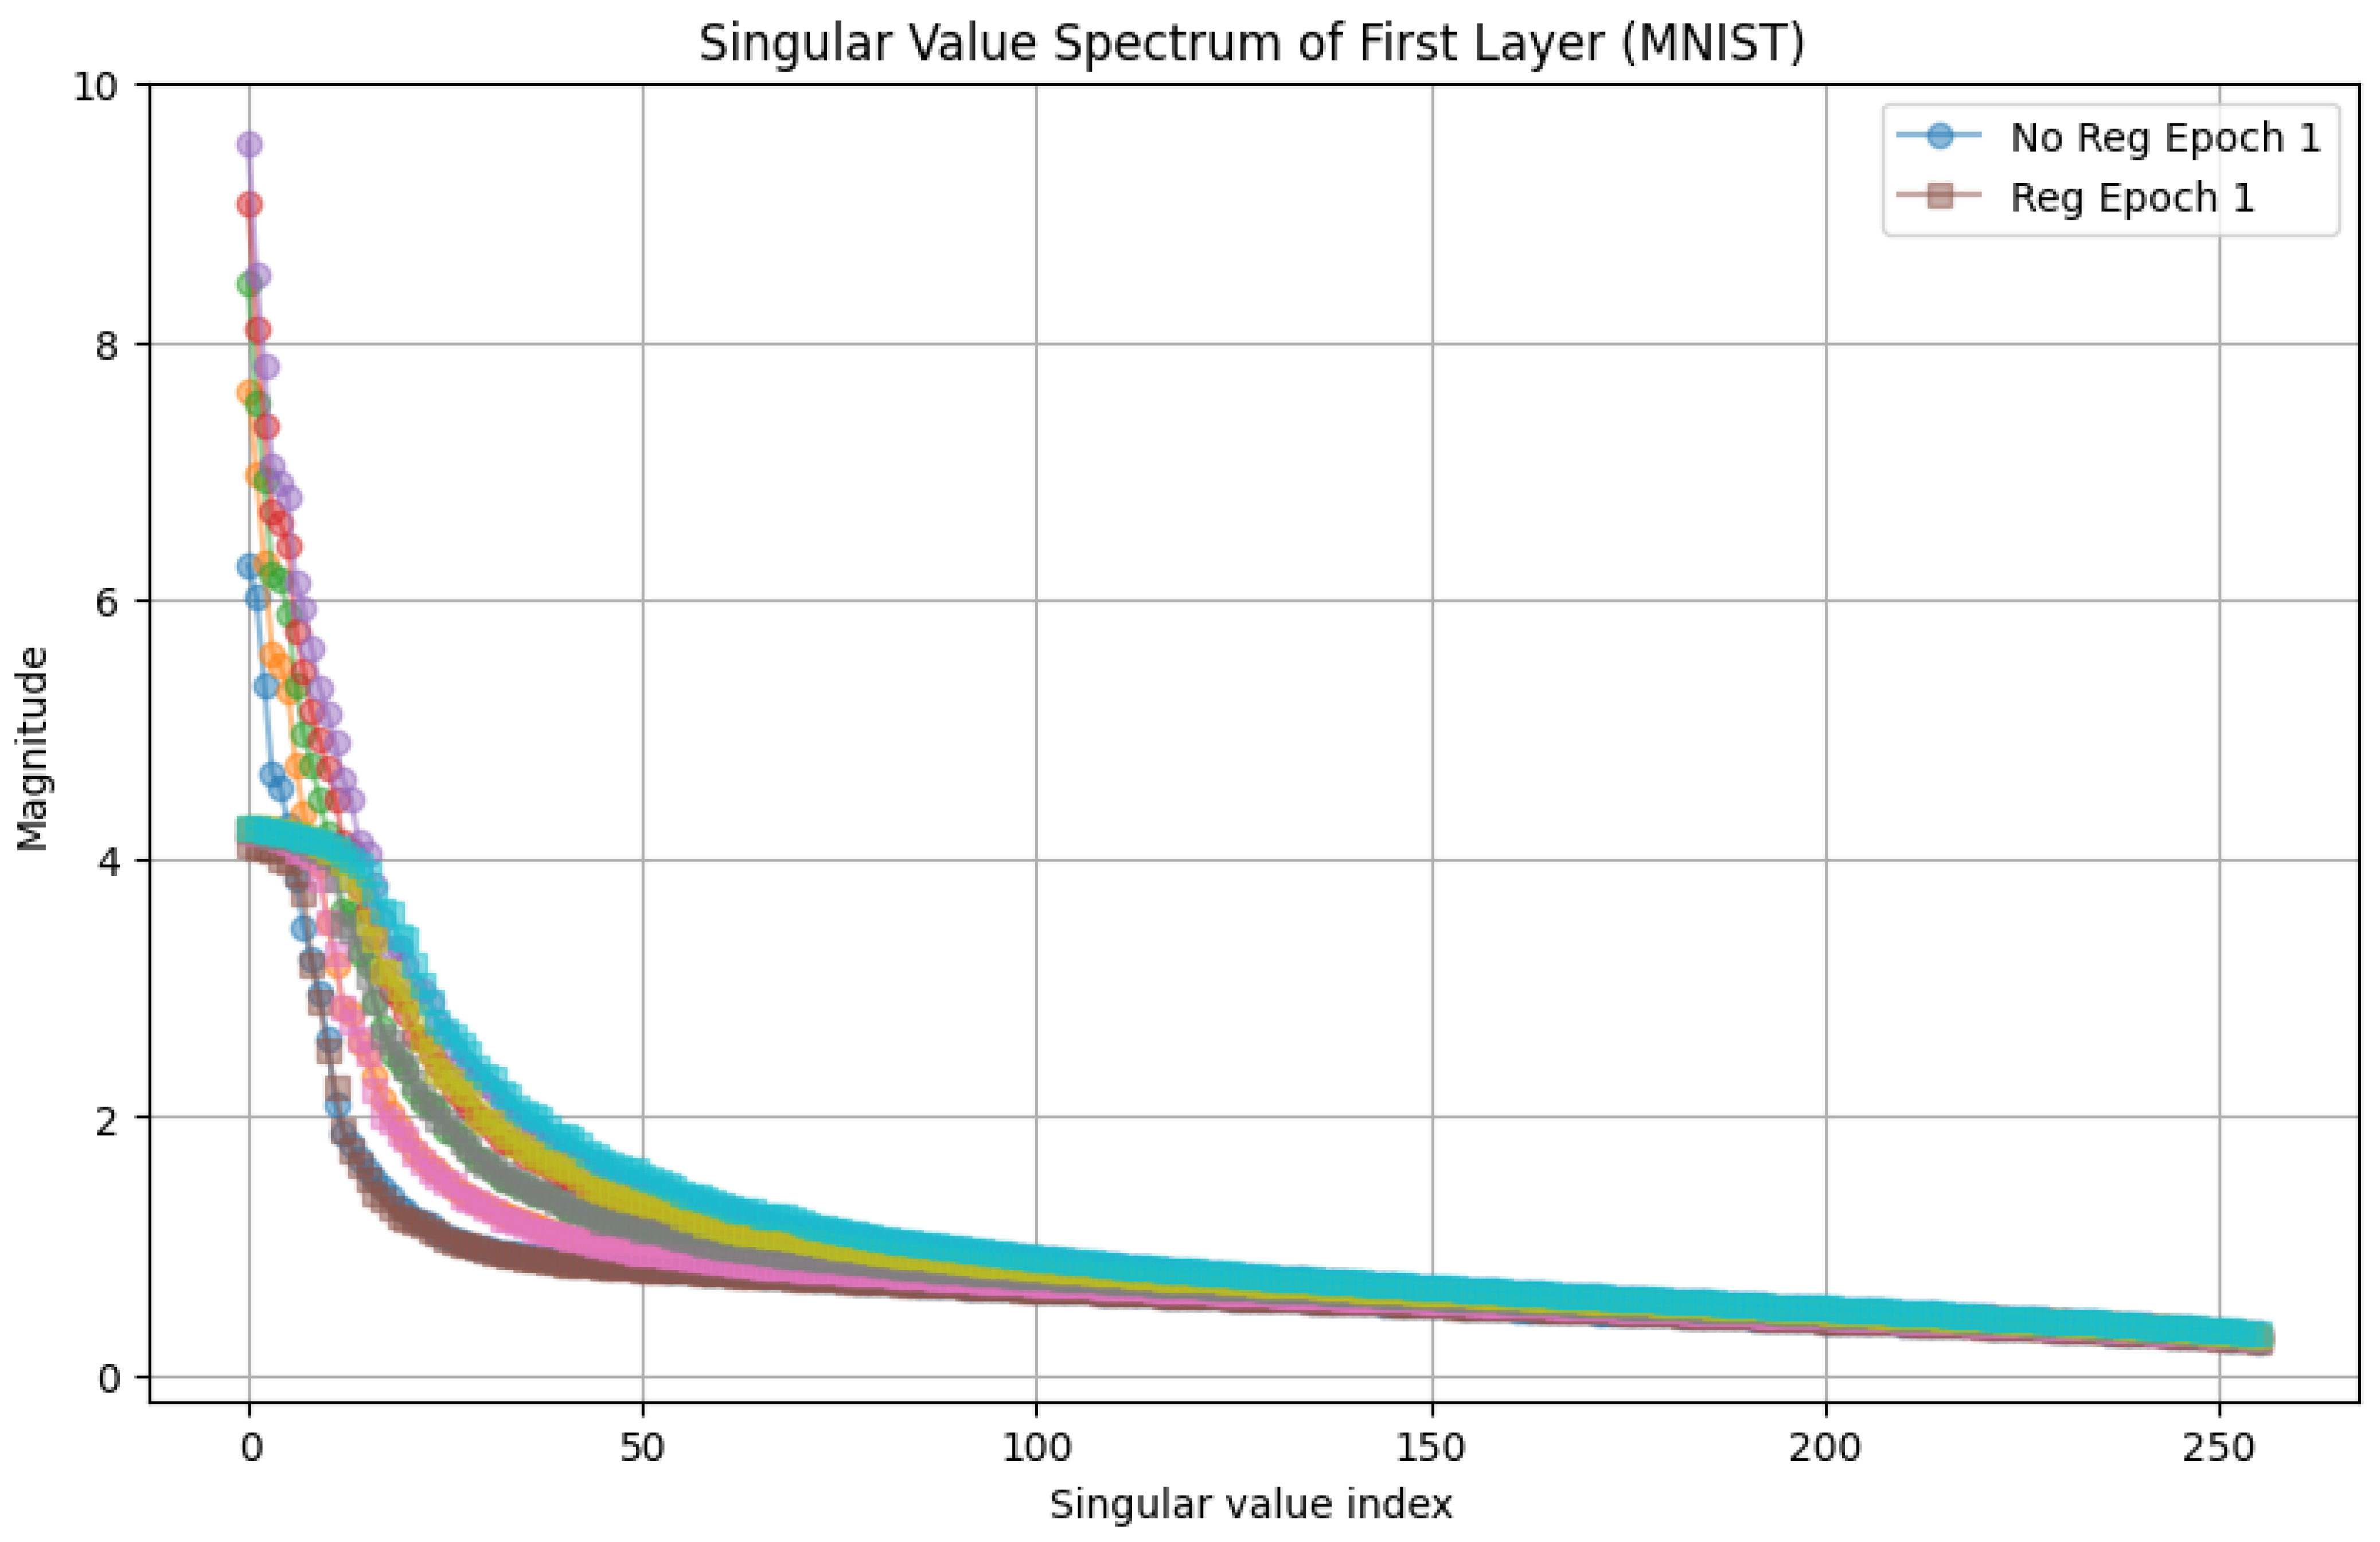
5. Game-Theoretic Formulations of Deep Neural Networks
The training of deep neural networks (DNNs) can be rigorously analyzed through game-theoretic frameworks, where optimization is interpreted as a competitive or cooperative interaction between different components of the model. In this setting, the learning process is modeled as a multi-player game, where each player corresponds to a subset of parameters (e.g., layers, neurons, or auxiliary networks), and their strategies are parameter updates that collectively influence the network’s performance. Let denote the parameters partitioned among K players. The objective is to minimize a global loss function , which induces a potential game where each player’s cost function aligns with the global loss. The Nash equilibrium of this game corresponds to a stationary point of , satisfying:
However, since exact equilibria are computationally intractable, training dynamics are often studied through online learning in games, where players iteratively adjust their strategies via gradient-based updates. For example, in generative adversarial networks (GANs), the generator and discriminator engage in a zero-sum game with value function:
where the generator seeks to minimize V while the discriminator maximizes it. The equilibrium corresponds to a saddle point satisfying:
The training dynamics of DNNs can also be formalized using differential game theory, where parameter updates follow continuous-time gradient flows. Consider a two-player game between feature extractors and classifiers in a deep network, where the state evolves according to the coupled ODEs:
The stability and convergence of such dynamics depend on the spectral properties of the game’s Jacobian matrix , defined as:
If has eigenvalues with negative real parts, the system converges to a stable equilibrium; otherwise, limit cycles or divergence may occur, as seen in GAN training. Furthermore, Stackelberg game formulations introduce hierarchical optimization, where one player (the leader, e.g., hyperparameters) commits to a strategy first, and the other (the follower, e.g., model parameters) responds optimally. This leads to bilevel optimization problems of the form:
These game-theoretic perspectives unify adversarial training, meta-learning, and multi-agent RL under a common framework, providing insights into convergence, robustness, and implicit regularization in deep learning.
5.1. Literature Review of Game-Theoretic Formulations of Deep Neural Networks
The game-theoretic formulations of deep neural networks have been explored extensively in recent literature, offering novel perspectives on optimization, adversarial robustness, and multi-agent interactions. One seminal contribution is the work by Goodfellow et al. (2014) [1472] on generative adversarial networks (GANs), which frames the training process as a two-player minimax game between a generator and a discriminator. This formulation has revolutionized unsupervised learning by enabling the generation of highly realistic data. The theoretical foundations of GANs have been further refined by Arjovsky et al. (2017) [1459], who introduced Wasserstein GANs to address convergence issues, providing a more stable training framework through the lens of optimal transport theory. Building on this, Gulrajani et al. (2017) [1473] proposed gradient penalty methods to enforce Lipschitz constraints, improving training stability. Another critical contribution comes from Shalev-Shwartz et al. (2012) [1495], who interpret supervised learning as a convex-concave game, establishing connections between empirical risk minimization and game-theoretic equilibria. This perspective has led to deeper insights into the generalization properties of neural networks, further explored by Hardt et al. (2016) [1475] through the lens of algorithmic stability.
The interplay between game theory and deep learning is also evident in adversarial robustness, where Madry et al. (2018) [1486] model adversarial attacks as a zero-sum game between a classifier and an adversary. Their work formalizes robust training as a min-max optimization problem, leading to the development of adversarially robust models. Similarly, Sinha et al. (2018) [1497] leverage distributionally robust optimization to frame adversarial training as a game against nature, providing probabilistic guarantees on model performance. These approaches highlight the utility of game-theoretic frameworks in addressing security challenges in deep learning, with additional insights from Raghunathan et al. (2018) [1492] on certified defenses and Zhang et al. (2019) [1502] on trade-offs between robustness and accuracy. Multi-agent reinforcement learning (MARL) is another domain where game theory plays a pivotal role. Littman’s (1994) [1483] formulation of Markov games extends single-agent reinforcement learning to competitive and cooperative settings, enabling the study of Nash equilibria in multi-agent systems. This has been expanded upon by Foerster et al. (2018) [1469], who introduce learning dynamics with opponent modeling, combining deep Q-learning with game-theoretic equilibria. Their work demonstrates how agents can adapt to others’ strategies in complex environments, a theme further developed by Lowe et al. (2017) [1484] with multi-agent actor-critic methods. Another notable contribution is by Lanctot et al. (2017) [1480], who propose the use of fictitious play and regret minimization in deep MARL, bridging the gap between classical game theory and modern deep learning techniques. Recent advances by Silver et al. (2017) [1496] in AlphaGo and OpenAI (2019) [1488] in multi-agent hide-and-seek showcase the practical success of these frameworks.
The optimization of neural networks has also been reinterpreted through game-theoretic lenses. For instance, Balduzzi et al. (2018) [1460] analyze gradient descent in deep learning as a dynamical system of interacting particles, drawing parallels to potential games. This perspective sheds light on the convergence behavior of neural networks, complemented by the work of Chizat & Bach (2018) [1462] on lazy training in wide networks. Meanwhile, Mertikopoulos et al. (2018) [1487] study the role of non-convexity in game-theoretic optimization, providing convergence guarantees for gradient-based methods in adversarial settings. Their work has implications for training GANs and other adversarial models, with additional theoretical grounding provided by Daskalakis et al. (2018) [1464] on the complexity of finding equilibria in non-convex games. Cooperative game theory has also found applications in explainability and feature attribution. Lundberg and Lee’s (2017) [1485] SHAP values, rooted in Shapley values from cooperative game theory, provide a principled framework for interpreting model predictions. This approach has been extended by Sundararajan et al. (2017) [1499] through integrated gradients, offering another game-theoretic perspective on feature importance. These methods have become standard tools for explainable AI, with further refinements by Janzing et al. (2020) [1477] on causal Shapley values and Frye et al. (2020) [1470] on contextual decomposition.
The intersection of game theory and deep learning continues to evolve, with recent work exploring mean-field games for large-scale multi-agent systems, as seen in the contributions of Carmona et al. (2019) [1461]. Their framework scales game-theoretic analysis to populations of agents, enabling applications in economics and robotics, with extensions by Perrin et al. (2020) [1491] on deep mean-field reinforcement learning. Another emerging direction is the use of auction theory in neural architecture search, where Liu et al. (2019) [1313] model the selection of network architectures as a combinatorial auction, optimizing resource allocation efficiently. These advancements underscore the breadth of game-theoretic applications in deep learning, from theoretical foundations to practical implementations, as seen in the work of Feng et al. (2020) [1467] on automated mechanism design. Further developments include the study of incentive alignment in federated learning, as explored by Li et al. (2020) [1482], who use mechanism design to ensure truthful participation among distributed agents. This line of work addresses challenges in collaborative learning environments, where strategic behavior must be accounted for, with additional insights from Kang et al. (2020) [1478] on reputation-based incentives. Additionally, the work of Letcher et al. (2019) [1481] on differentiable game theory provides tools for analyzing and optimizing the interactions of multiple loss functions in machine learning, offering a unified framework for multi-objective optimization, further refined by Schäfer & Anandkumar (2019) [1494] on competitive gradient descent.
The literature also delves into the role of information asymmetry in deep learning games, as exemplified by the work of Raghu et al. (2019) [1493] on signaling games in neural networks. Their analysis reveals how information bottlenecks emerge during training, influencing model behavior, with connections to the information bottleneck theory of Tishby et al. (2015) [1500]. Another significant contribution is by Perolat et al. (2022) [1489], who apply extensive-form games to hierarchical reinforcement learning, enabling sophisticated decision-making in structured environments, building on earlier work by Heinrich & Silver (2016) [1476] on fictitious self-play. Other notable contributions include the work of Czarnecki et al. (2020) [1463] on open-ended learning in games, which explores how agents can continuously adapt in dynamic environments, and the study of meta-learning in games by Al-Shedivat et al. (2018) [1458], which frames few-shot learning as a multi-agent interaction problem. The role of evolutionary dynamics in deep learning has been examined by Such et al. (2017) [1498], who apply population-based training to optimize hyperparameters, while Wang et al. (2019) [1501] explore the game-theoretic foundations of self-play in reinforcement learning.
Recent advances in differentiable economics by Dütting et al. (2019) [1466] and strategic classification by Hardt et al. (2016) [1475] further illustrate the growing synergy between game theory and deep learning. The work of Gemp et al. (2021) [1471] on resolving bargaining games with deep networks and the study of cooperative inverse reinforcement learning by Hadfield-Menell et al. (2016) [1474] highlight the potential for game-theoretic principles to guide AI alignment. Overall, the game-theoretic formulations of deep neural networks span a wide array of topics, from adversarial training and multi-agent systems to optimization and explainability. The contributions discussed here represent a fraction of the rich literature in this interdisciplinary field, which continues to grow as researchers uncover new connections between game theory and deep learning. Each of these works provides rigorous theoretical foundations, practical algorithms, or novel applications, collectively advancing our understanding of neural networks through the lens of game theory. The ongoing exploration of these ideas promises to yield further breakthroughs in the design, analysis, and deployment of intelligent systems.
5.2. Analysis of Game-Theoretic Formulations of Deep Neural Networks
Deep Neural Networks (DNNs) can be rigorously formulated within a game-theoretic framework by considering the interplay between competing objectives in optimization, adversarial robustness, and equilibrium strategies. The fundamental nature of DNNs involves a multi-agent optimization problem where various components interact within a high-dimensional function space.
Formally, a deep neural network is parameterized by a set of weights and seeks to optimize a loss function , where the training data is drawn from an unknown distribution. The optimization problem can be expressed as
A fundamental game-theoretic formulation of DNNs arises in adversarial training, where a deep network is trained to minimize an objective function while an adversary seeks to maximize it. This setting leads to a two-player zero-sum game where the adversary introduces perturbations such that the resulting optimization problem is
The equilibrium of this adversarial game corresponds to a minimax solution, satisfying the condition
If the loss function satisfies convexity in and concavity in , then the minimax theorem guarantees the existence of an equilibrium solution:
A notable game-theoretic application of DNNs is in Generative Adversarial Networks (GANs), where two neural networks, a generator and a discriminator , play a competitive game. The generator aims to produce realistic samples , while the discriminator seeks to distinguish between real and generated samples. The objective function for this adversarial game is
The Nash equilibrium condition for this game is given by
At equilibrium, the optimal generator satisfies
leading to a situation where the discriminator is unable to distinguish real from generated samples. If is parameterized by , then training the discriminator corresponds to solving
Given that neural networks can approximate arbitrary functions, their training can also be formulated in terms of multi-agent differential game theory.
Consider a dynamic system where the evolution of parameters follows
The Hamiltonian for this system is given by
where p is the costate variable and u represents control parameters. The Hamilton-Jacobi-Bellman equation characterizing optimal control in a reinforcement learning-based DNN training scenario is
Another approach to studying DNNs in a game-theoretic framework is through evolutionary game dynamics. Here, learning dynamics follow replicator equations given by
where represents the probability of selecting strategy i, is the fitness function for strategy i, and is the average fitness. In the context of neural networks, the replicator equation governs weight updates as follows:
This provides a mechanism for gradient-based optimization that incorporates selection and mutation principles.
Another critical formulation involves Nash equilibria in non-cooperative learning settings, such as federated learning, where multiple learners optimize separate but interdependent loss functions. The Nash equilibrium conditions require that
where denotes the set of parameters for all players except i. A Nash equilibrium is attained when
Under convexity assumptions, Nash learning dynamics can be characterized by a gradient projection algorithm:
Beyond Nash equilibria, deep neural networks can also be analyzed through variational inequalities, which generalize equilibrium concepts. Given a function , the variational inequality problem seeks such that
For adversarial training, the corresponding variational inequality formulation is
where denotes the optimal adversarial perturbation satisfying
This variational inequality provides a principled characterization of adversarial robustness in deep networks. The application of game-theoretic formulations to deep learning thus allows for a mathematically rigorous understanding of optimization, equilibrium conditions, and strategic interactions among network components.
5.2.1. Python Code to Generate Figure 51, Figure 52, and Figure 53 Illustrating Game-Theoretic Formulations of Deep Neural Networks
The Python code below produces the Figure 51, Figure 52, and Figure 53 illustrating Game-theoretic formulations of Deep Neural Networks.
Figure 51.
Min-Max Game Formulation (Adversarial Training)
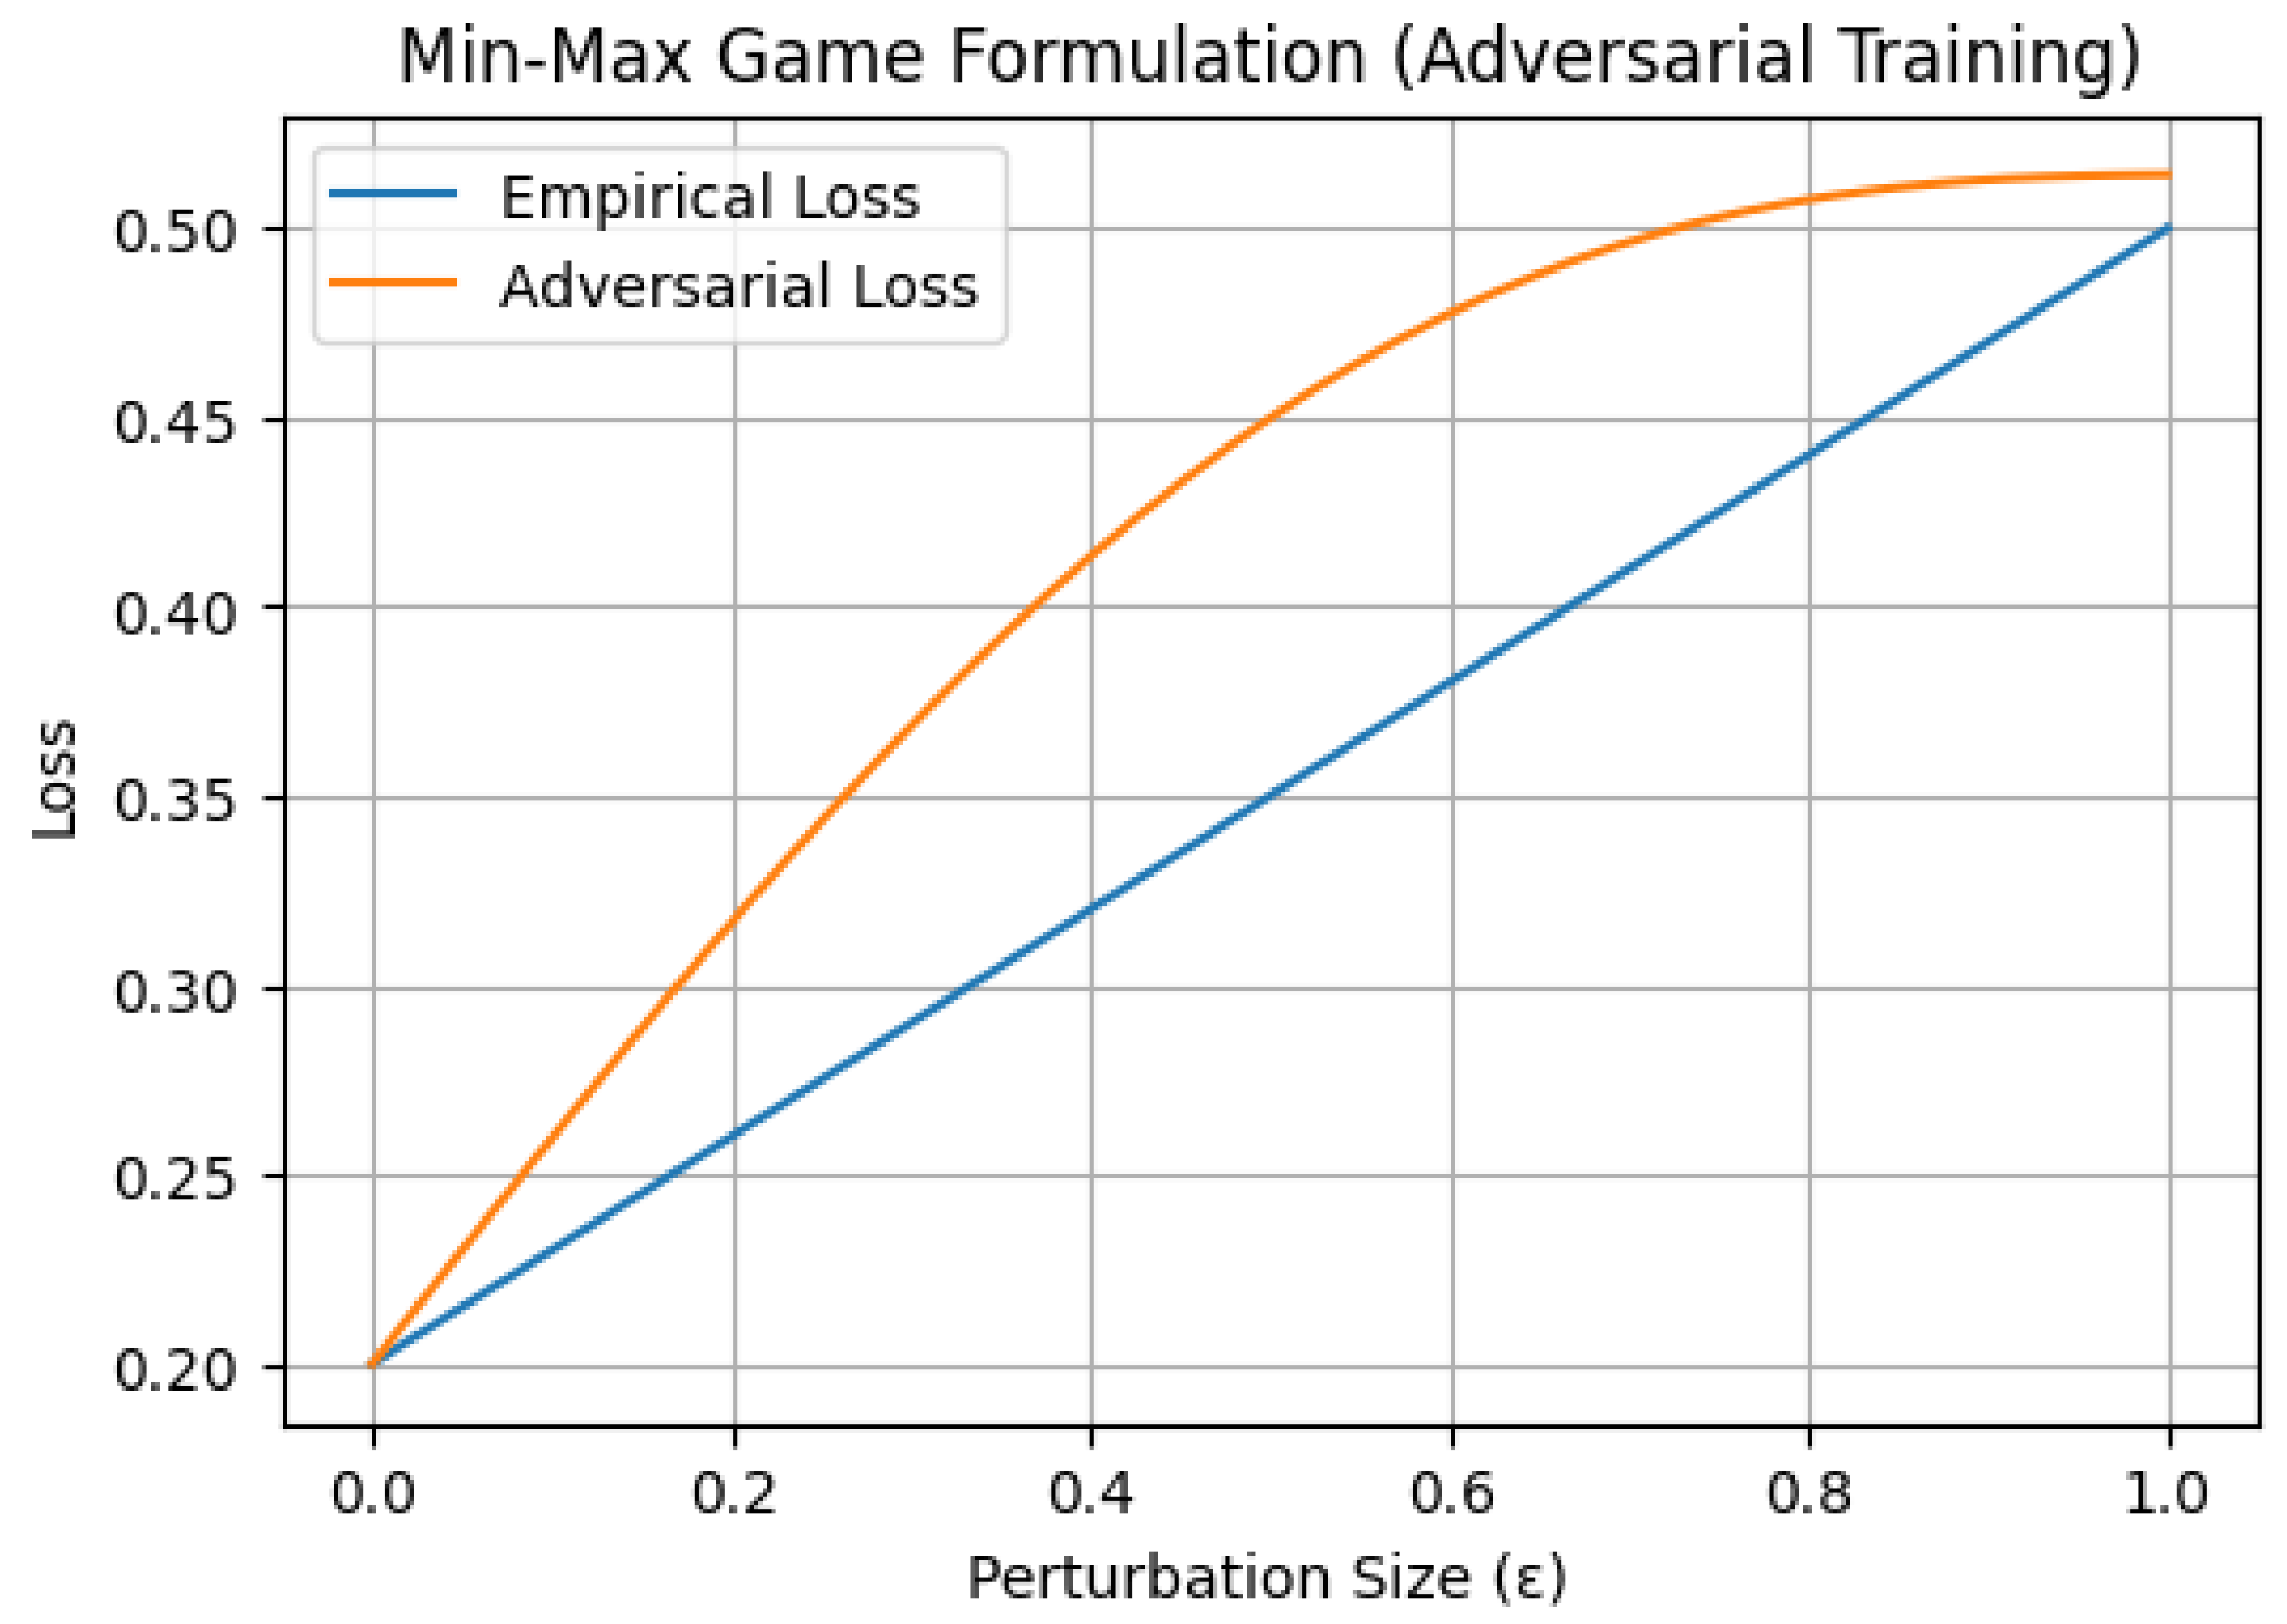
Figure 52.
Regularization as Game Formulation
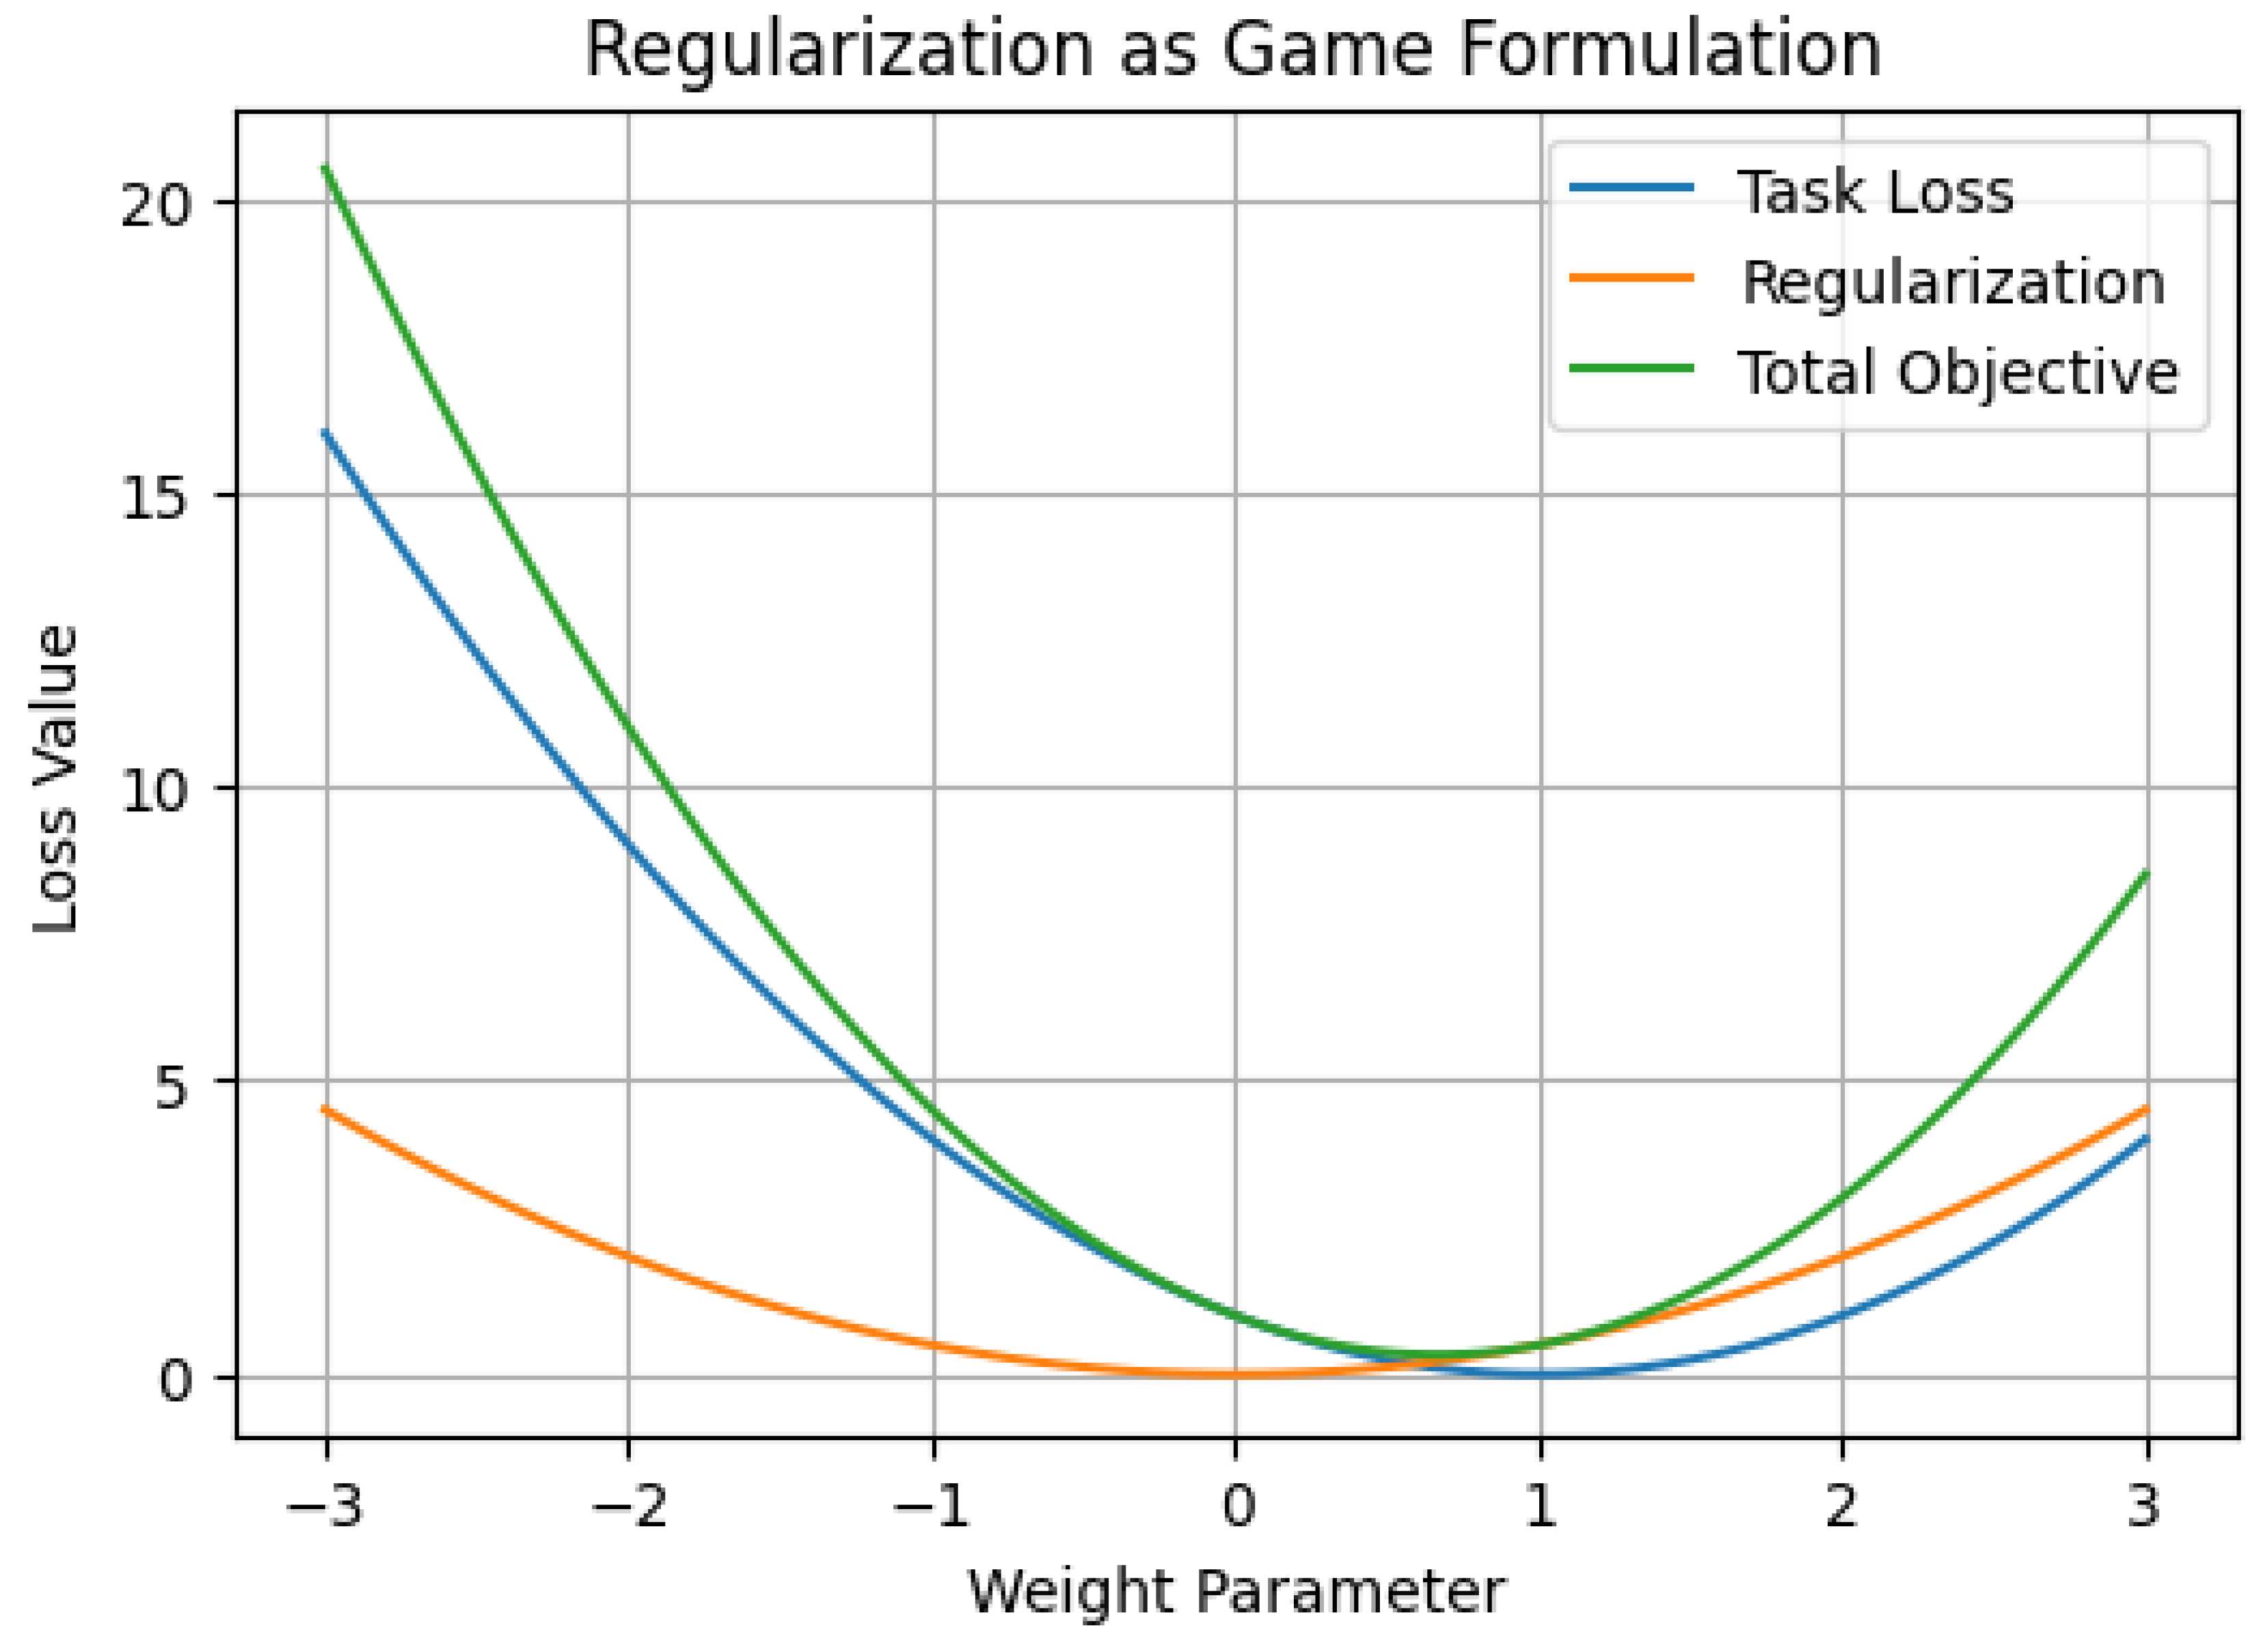
Figure 53.
Multi-Agent Game: Layers as Players
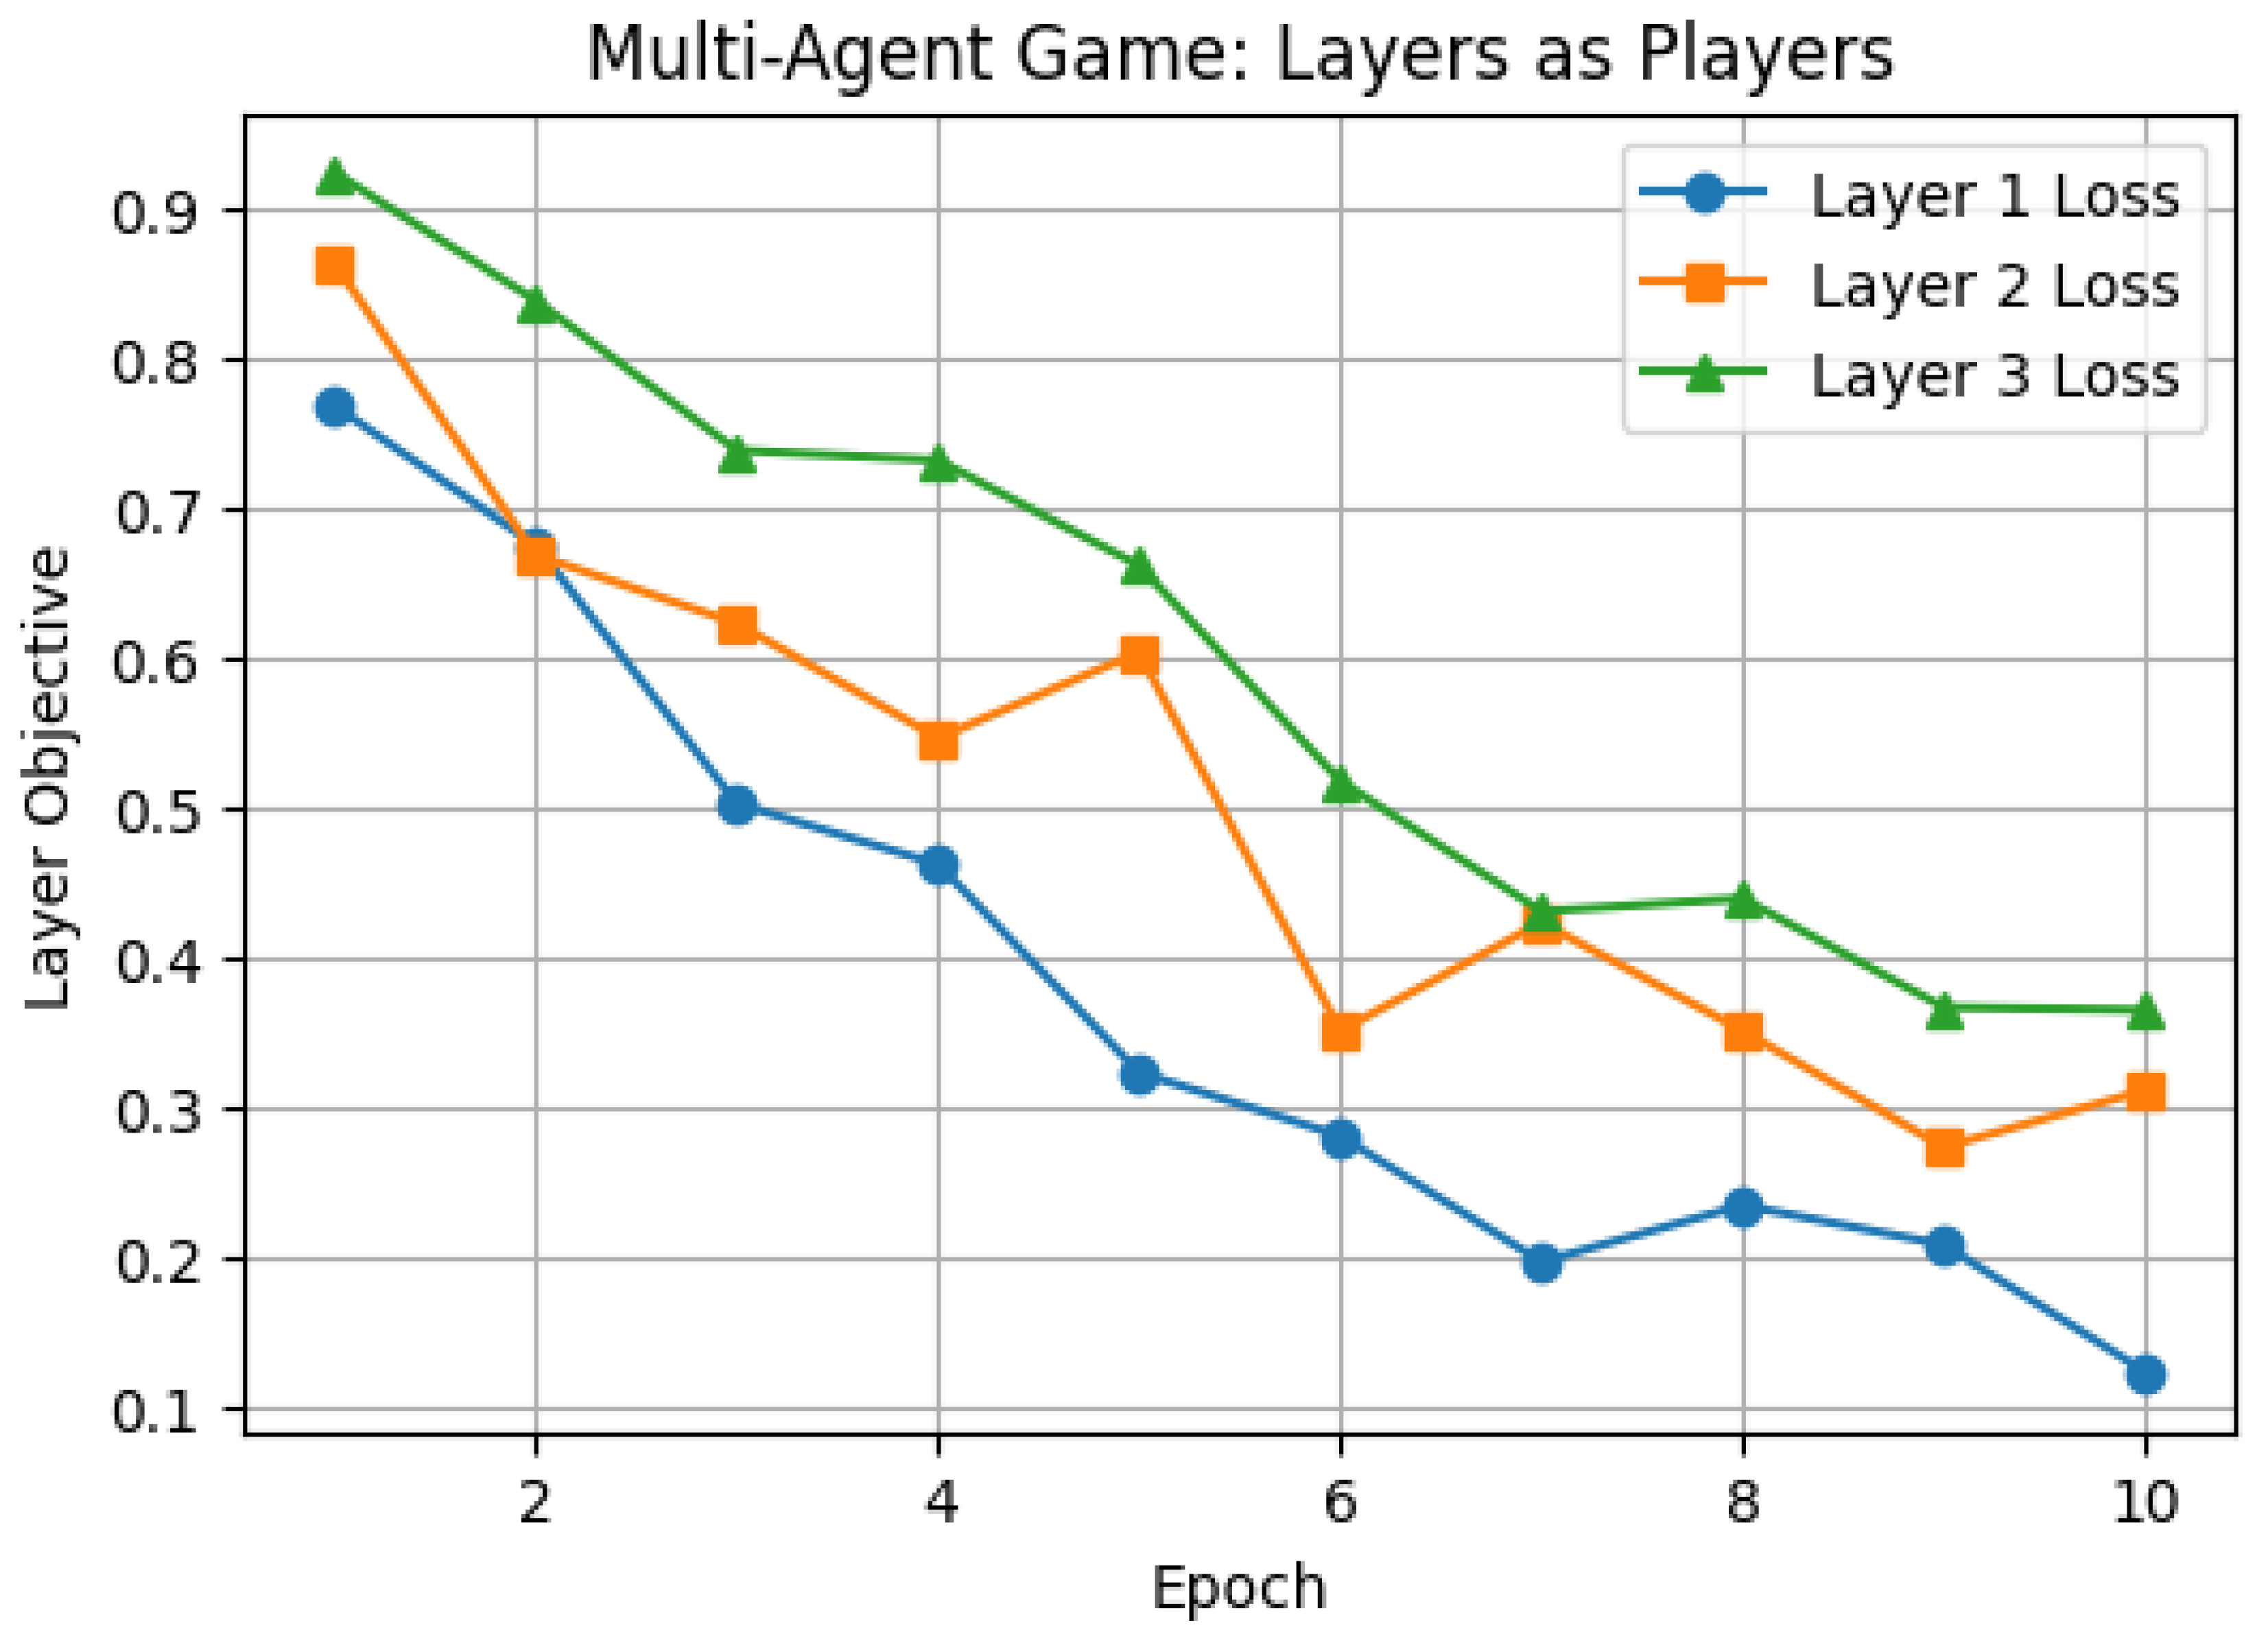
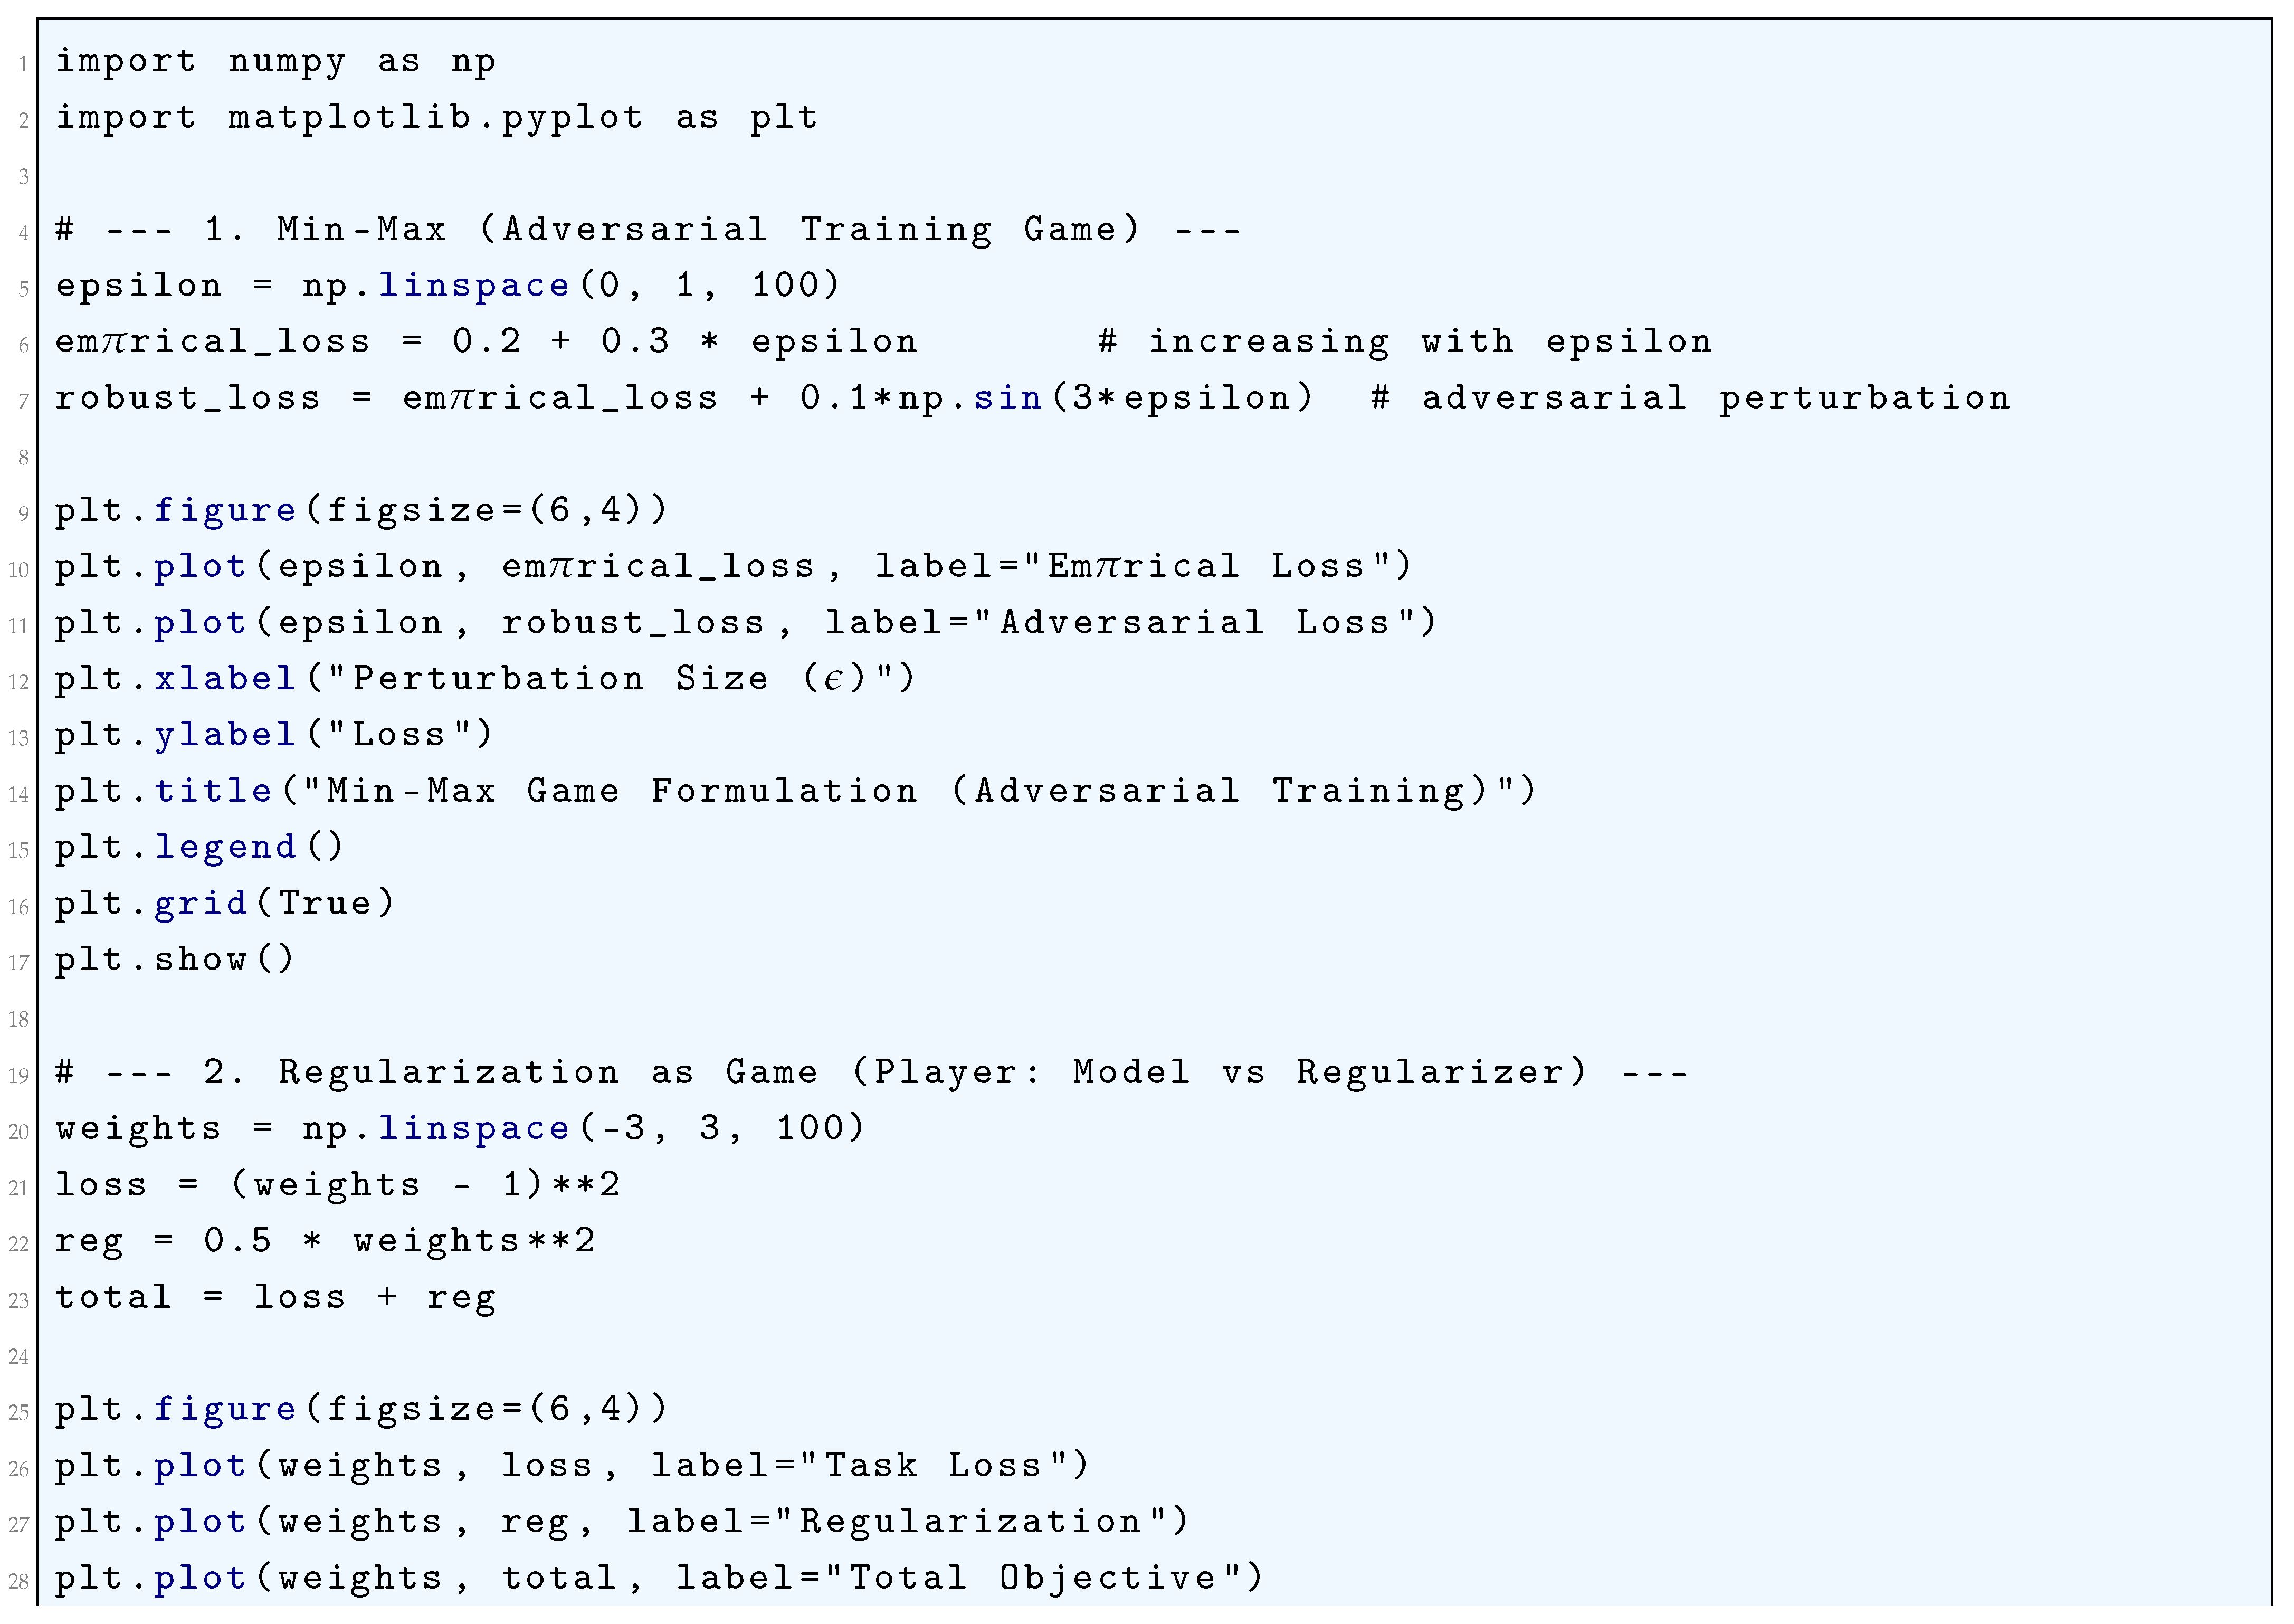
5.2.2. Min-Max (Saddle) Dynamics:
The function that serves as a canonical, analytically tractable model for studying the min-max saddle point dynamics that is central to the training of Generative Adversarial Networks (GANs) and other adversarial learning formulations within deep learning is
In this game-theoretic framework, the two players are the generator and the discriminator, whose parameters are abstracted here by the variables y and x, respectively.
The discriminator’s objective is to maximize the payoff function , while the generator’s objective is to minimize it. This defines a zero-sum game with the value function
and the overall goal is to find a Nash equilibrium, which is a point satisfying the saddle point condition
for all x and y in a local neighborhood.
The dynamics of the training process are typically modeled by simultaneous or alternating gradient descent-ascent. The vector field governing these dynamics is given by the gradients of the objective with respect to each player’s variable. For the bilinear objective , these gradients are
The simultaneous gradient descent-ascent update rule with learning rate is
and
This system of equations is linear and can be written in matrix form as
and
The eigenvalues of this update matrix are , which have magnitude . This implies that the dynamics are unstable and will diverge for any , causing the players’ parameters to orbit the equilibrium point on a trajectory of exponentially increasing radius. This simple model thus captures a fundamental pathology in adversarial training: the vector field
is non-conservative and has a non-zero rotational component, preventing convergence under naive gradient-based methods.
The divergence of this simple dynamic motivates the need for more sophisticated optimization algorithms in practical deep neural network training. The bilinear term is often a component of a larger loss landscape, and its presence induces rotational forces that can destabilize training. Algorithms such as Optimistic Mirror Descent (OMD) and the closely related Extra Gradient (EG) method are designed to counteract this instability. For example, the Optimistic Mirror Descent update for this problem is given by
and
The spectral analysis of this system reveals that it can converge for a sufficiently small learning rate , unlike the divergent simultaneous gradient method. The core mathematical insight is that the stability of the learning dynamics depends critically on the structure of the game’s Jacobian,
For the bilinear game, this Jacobian is a skew-symmetric matrix, and convergence guarantees for algorithms like OMD and EG are derived by showing that their update operators can mitigate the rotational effects encoded by this skew-symmetric component, thereby allowing the dynamics to spiral inward towards the saddle point rather than outward to infinity.
5.2.3. Potential/Cooperative Game (Gradient Descent on Shared Phi)
In the game-theoretic analysis of deep neural network training, a potential or cooperative game represents a foundational scenario where the interests of all parameter blocks are perfectly aligned. This framework is defined by the existence of a global, differentiable potential function , where represents the concatenated parameters of all N players or network components. The individual loss function for each player i is precisely this shared potential
for all i. Consequently, the game is one of pure cooperation, as all players share the identical objective of minimizing . The dynamics are governed by the simultaneous gradient, which is simply the full gradient of the potential function:
The learning process in this setting is equivalent to gradient descent on the shared objective . The continuous-time dynamics are described by the ordinary differential equation
where is the learning rate. The discrete-time update with a fixed learning rate is given by
A first-order Taylor expansion reveals the change in the potential function:
where
is the Hessian matrix of the potential. For sufficiently small such that
in the positive definite sense, the term linear in dominates, guaranteeing a decrease in the potential:
The game-theoretic properties are analyzed through the lens of the game Jacobian, , which is defined as the matrix of second-order derivatives of the individual losses.
For a potential game, this Jacobian is given by
This implies that is equivalent to the Hessian of the potential function, . A critical mathematical consequence is that the Jacobian of a potential game is symmetric
This symmetry is the defining characteristic of a potential game and ensures that the dynamics are a gradient flow. The eigenvalues of are all real, and their signs determine the stability of critical points. A point is a Nash equilibrium if
and it is a locally stable equilibrium under gradient descent if
meaning all eigenvalues of the Hessian are positive.
The convergence analysis leverages Lyapunov stability theory. The potential function itself serves as a Lyapunov function for the gradient dynamics. Its time derivative along the trajectories of the continuous-time system is
This quantity is strictly negative everywhere except at critical points where , confirming the global stability of the dynamics. In the discrete-time setting, under the assumption that is L-smooth, meaning
which implies
one can derive a quantitative convergence rate. Applying this at
yields
For a learning rate , this guarantees a monotonic decrease in the potential. After T iterations, the best iterate satisfies
where is the minimal value, proving convergence to a stationary point at a rate of . This mathematically rigorous framework provides the foundational guarantees for standard, non-adversarial deep learning, where the optimization landscape, despite its non-convexity, is traversed by a single, cohesive gradient flow.
5.2.4. Replicator Dynamics (Rock-Paper-Scissors) — Cyclic Behavior
The Replicator Dynamics equation, a cornerstone of evolutionary game theory, provides a continuous-time model for the evolution of strategy frequencies within a population. For a game with n pure strategies and a payoff matrix A, where denotes the payoff for strategy i against strategy j, the dynamics are defined for a population state , the -dimensional simplex where and . The rate of change of the frequency is given by
The term
is the expected payoff for strategy i, and
is the average payoff across the entire population. This equation dictates that strategies yielding above-average payoff proliferate, while those with below-average payoff diminish.
The Rock-Paper-Scissors (RPS) game is the canonical example of a zero-sum, non-transitive game that induces cyclic behavior under these dynamics. Its payoff matrix for the row player is given by
The average payoff in the population for this antisymmetric matrix () is always zero, , simplifying the replicator dynamics to . Writing these equations explicitly for the three strategies (Rock R, Paper P, Scissors S) yields the system:
The dynamics of this system conserve a specific quantity, which can be found by analyzing the time derivative of the logarithm of the product . Specifically,
This implies that the function
is a constant of motion, and consequently, the quantity
remains constant along any trajectory of the dynamics. The orbits of the system are closed curves defined by the level sets of K, resulting in perpetual, neutrally stable cycles around the interior Nash equilibrium .
This cyclic behavior is not merely a pathological example but a fundamental model for understanding non-convergent dynamics in multi-agent learning systems, including certain regimes in the training of deep neural networks, particularly Generative Adversarial Networks (GANs). The vector field defines a flow on the simplex. The Jacobian of this vector field at the interior equilibrium is
This matrix is skew-symmetric, , and its eigenvalues are . The purely imaginary conjugate pair confirm the presence of a center manifold, leading to oscillatory behavior. The connection to deep learning is established by noting that the simultaneous gradient descent-ascent dynamics on a bilinear loss function
which abstracts the interaction between two neural networks like a generator and a discriminator, yield a structurally similar vector field
For an antisymmetric A, this becomes
whose second-order form
describes a multi-dimensional harmonic oscillator. This mathematical equivalence demonstrates how the replicator dynamics’ inherent cycles manifest as rotational forces and training instability in adversarial neural network training, preventing convergence to a stationary Nash equilibrium.
5.2.5. Python Code to Generate Figure 54, Figure 55 and Figure 56 Illustrating Min-Max (Saddle) Dynamics, Potential/Cooperative Game (Gradient Descent on Shared Phi), and Replicator Dynamics (Rock-Paper-Scissors) — Cyclic Behavior
The Python code below produces the Figure 54, Figure 55 and Figure 56 illustrating Min-Max (Saddle) dynamics, Potential/Cooperative game (gradient descent on shared Phi), and Replicator dynamics (Rock-Paper-Scissors) — cyclic behavior.
Figure 54.
Min-Max (Saddle) dynamics:
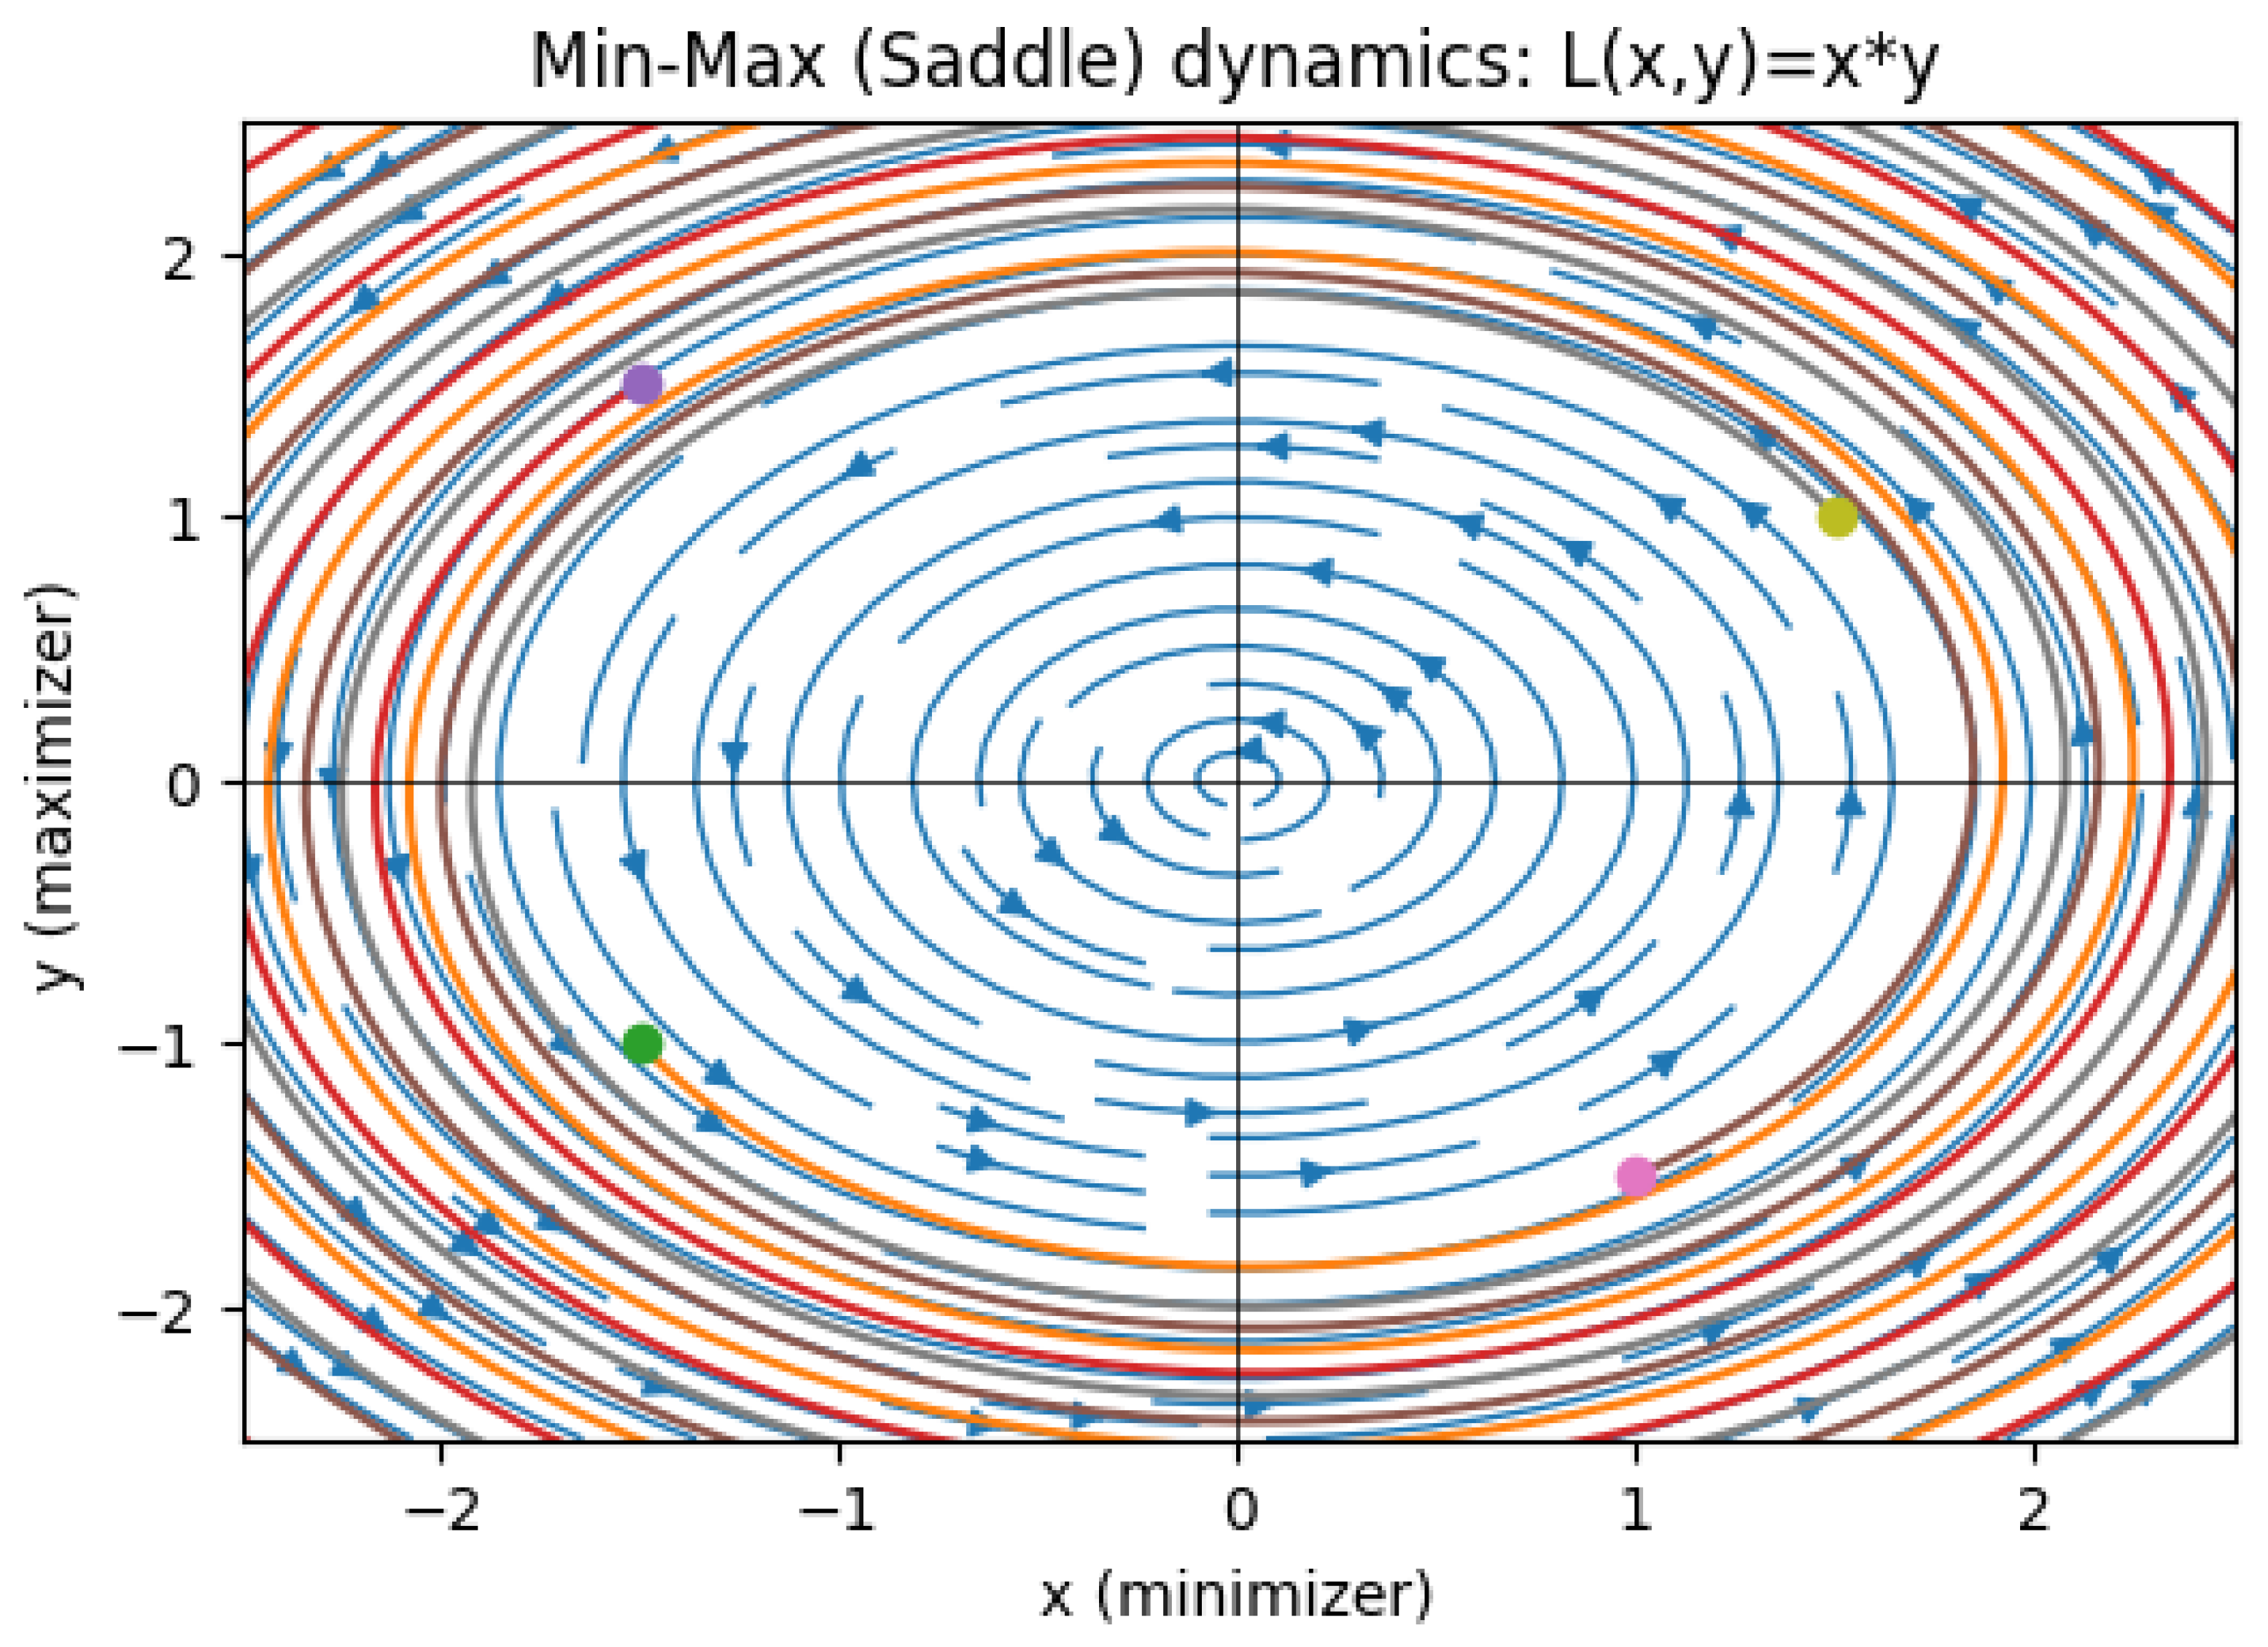
Figure 55.
Potential / Cooperative game (gradient descent on shared Phi)
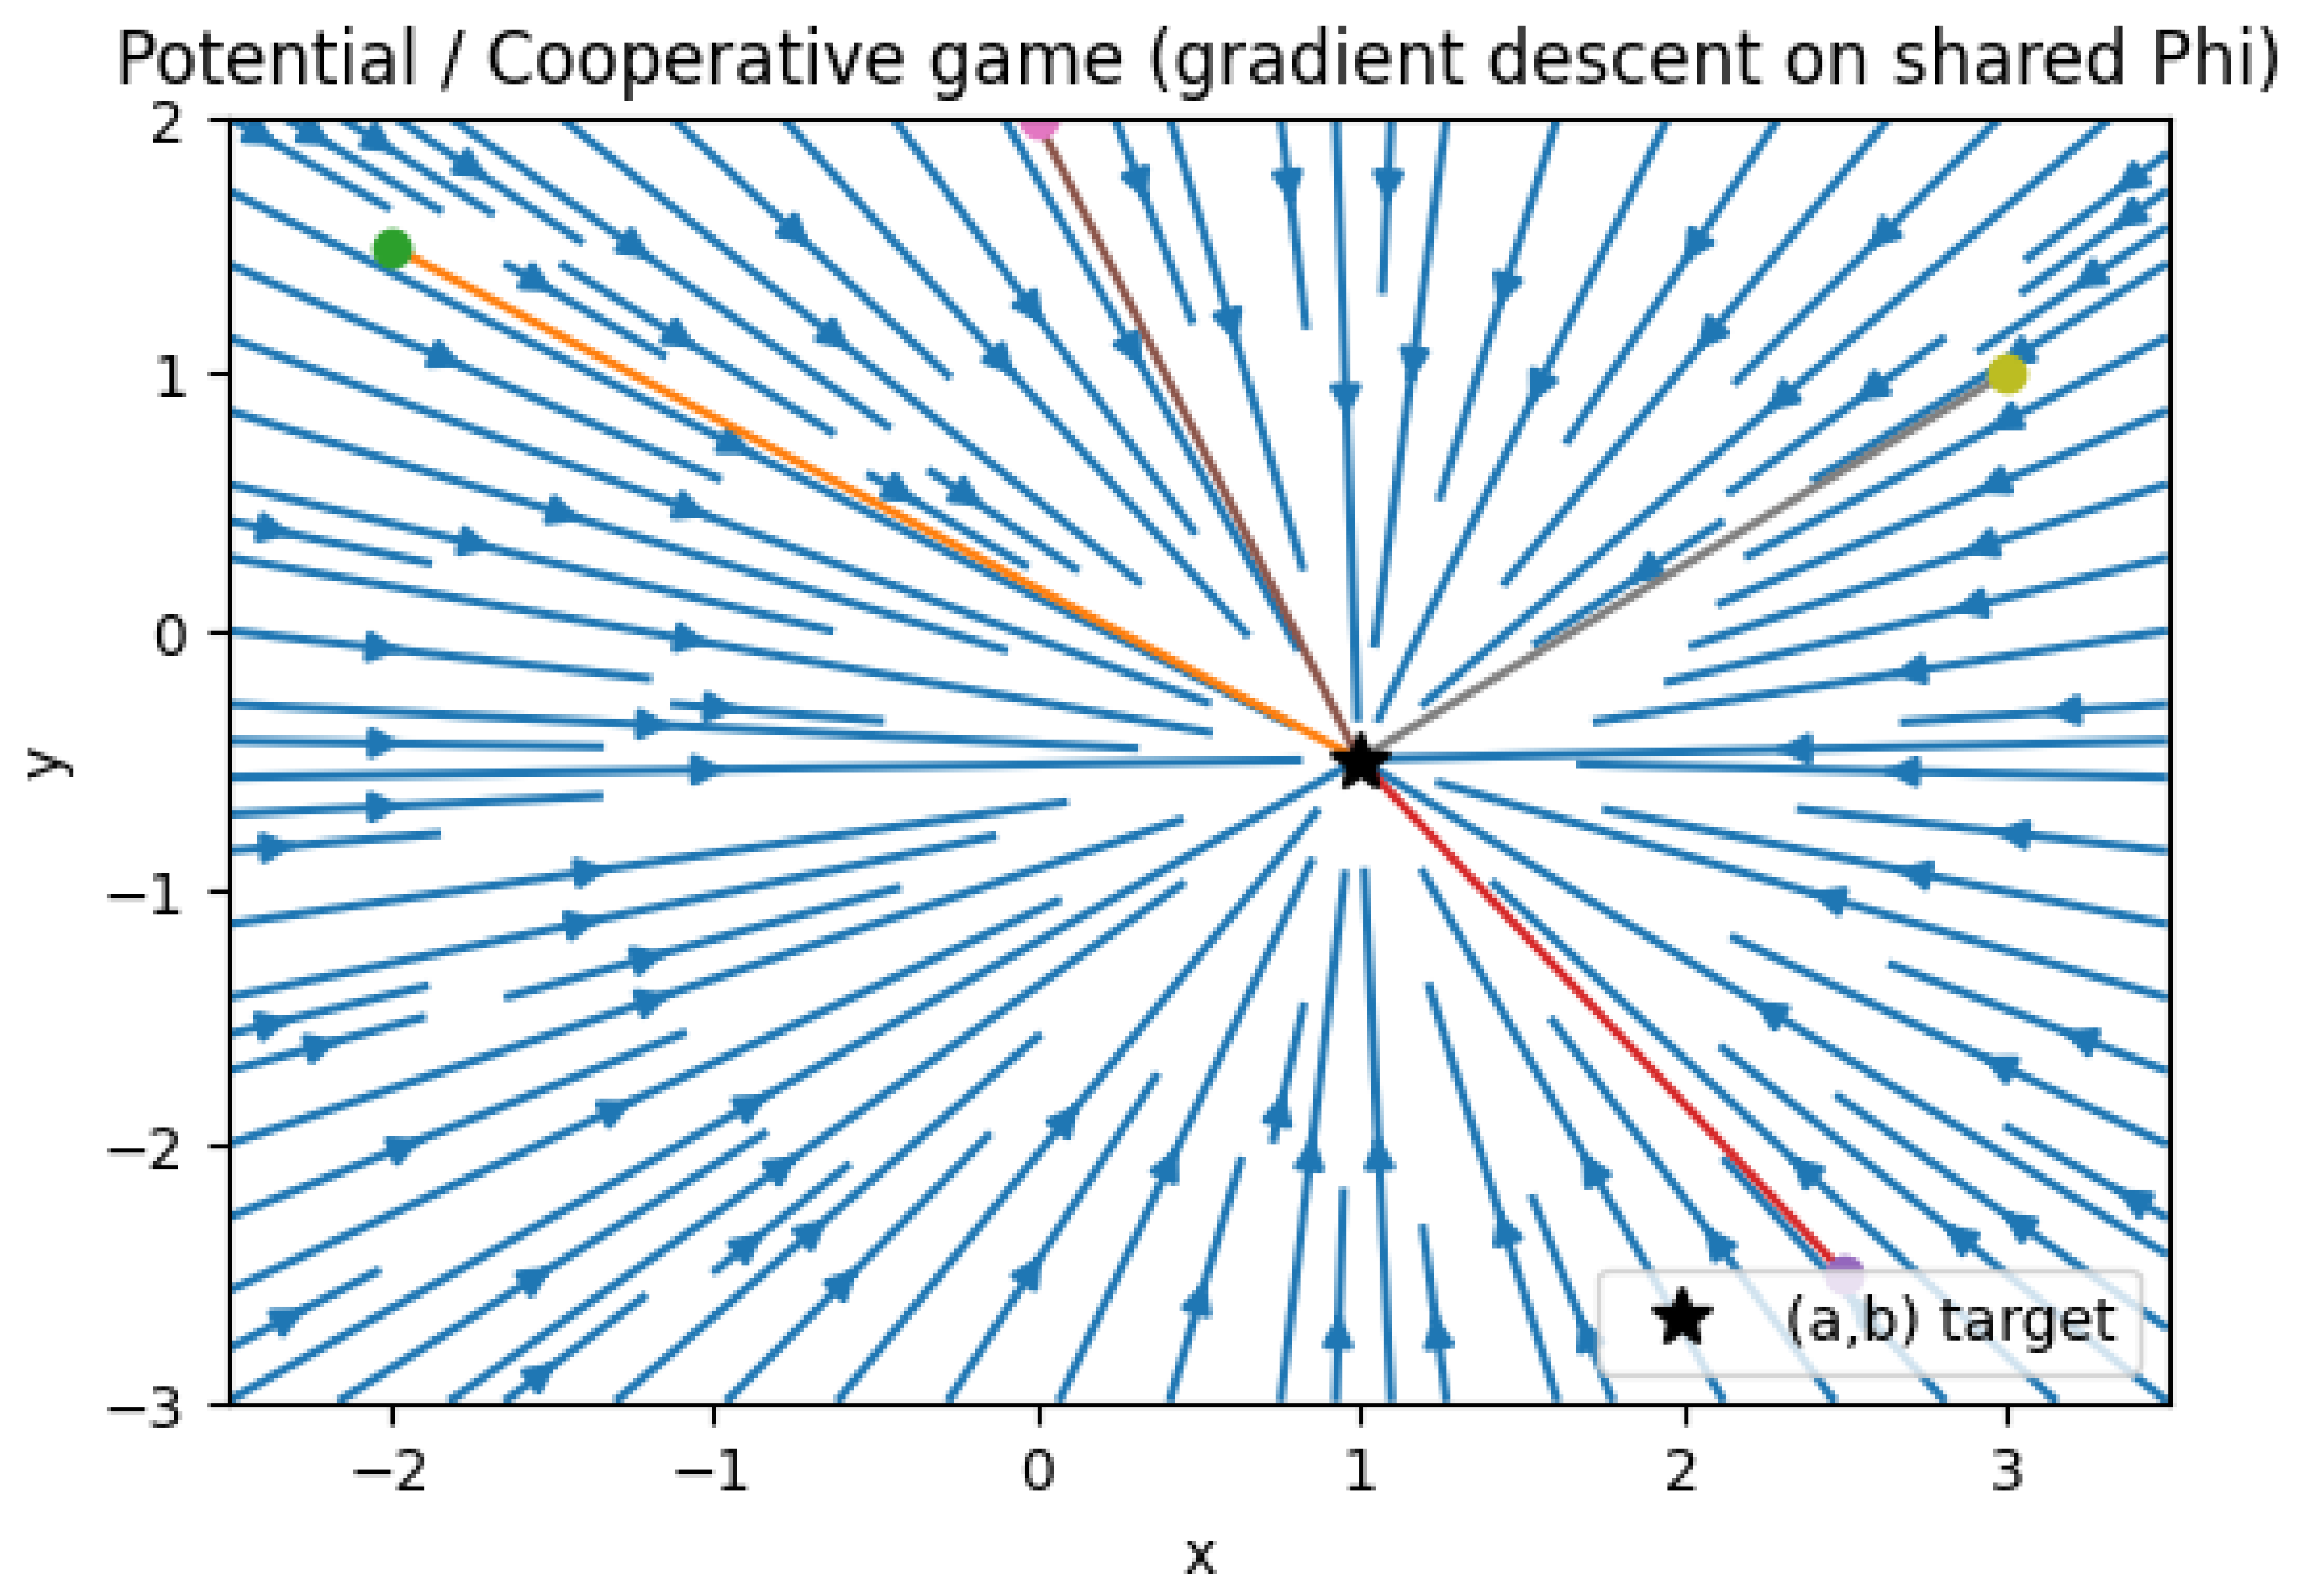
Figure 56.
Replicator dynamics (Rock-Paper-Scissors) — cyclic behavior
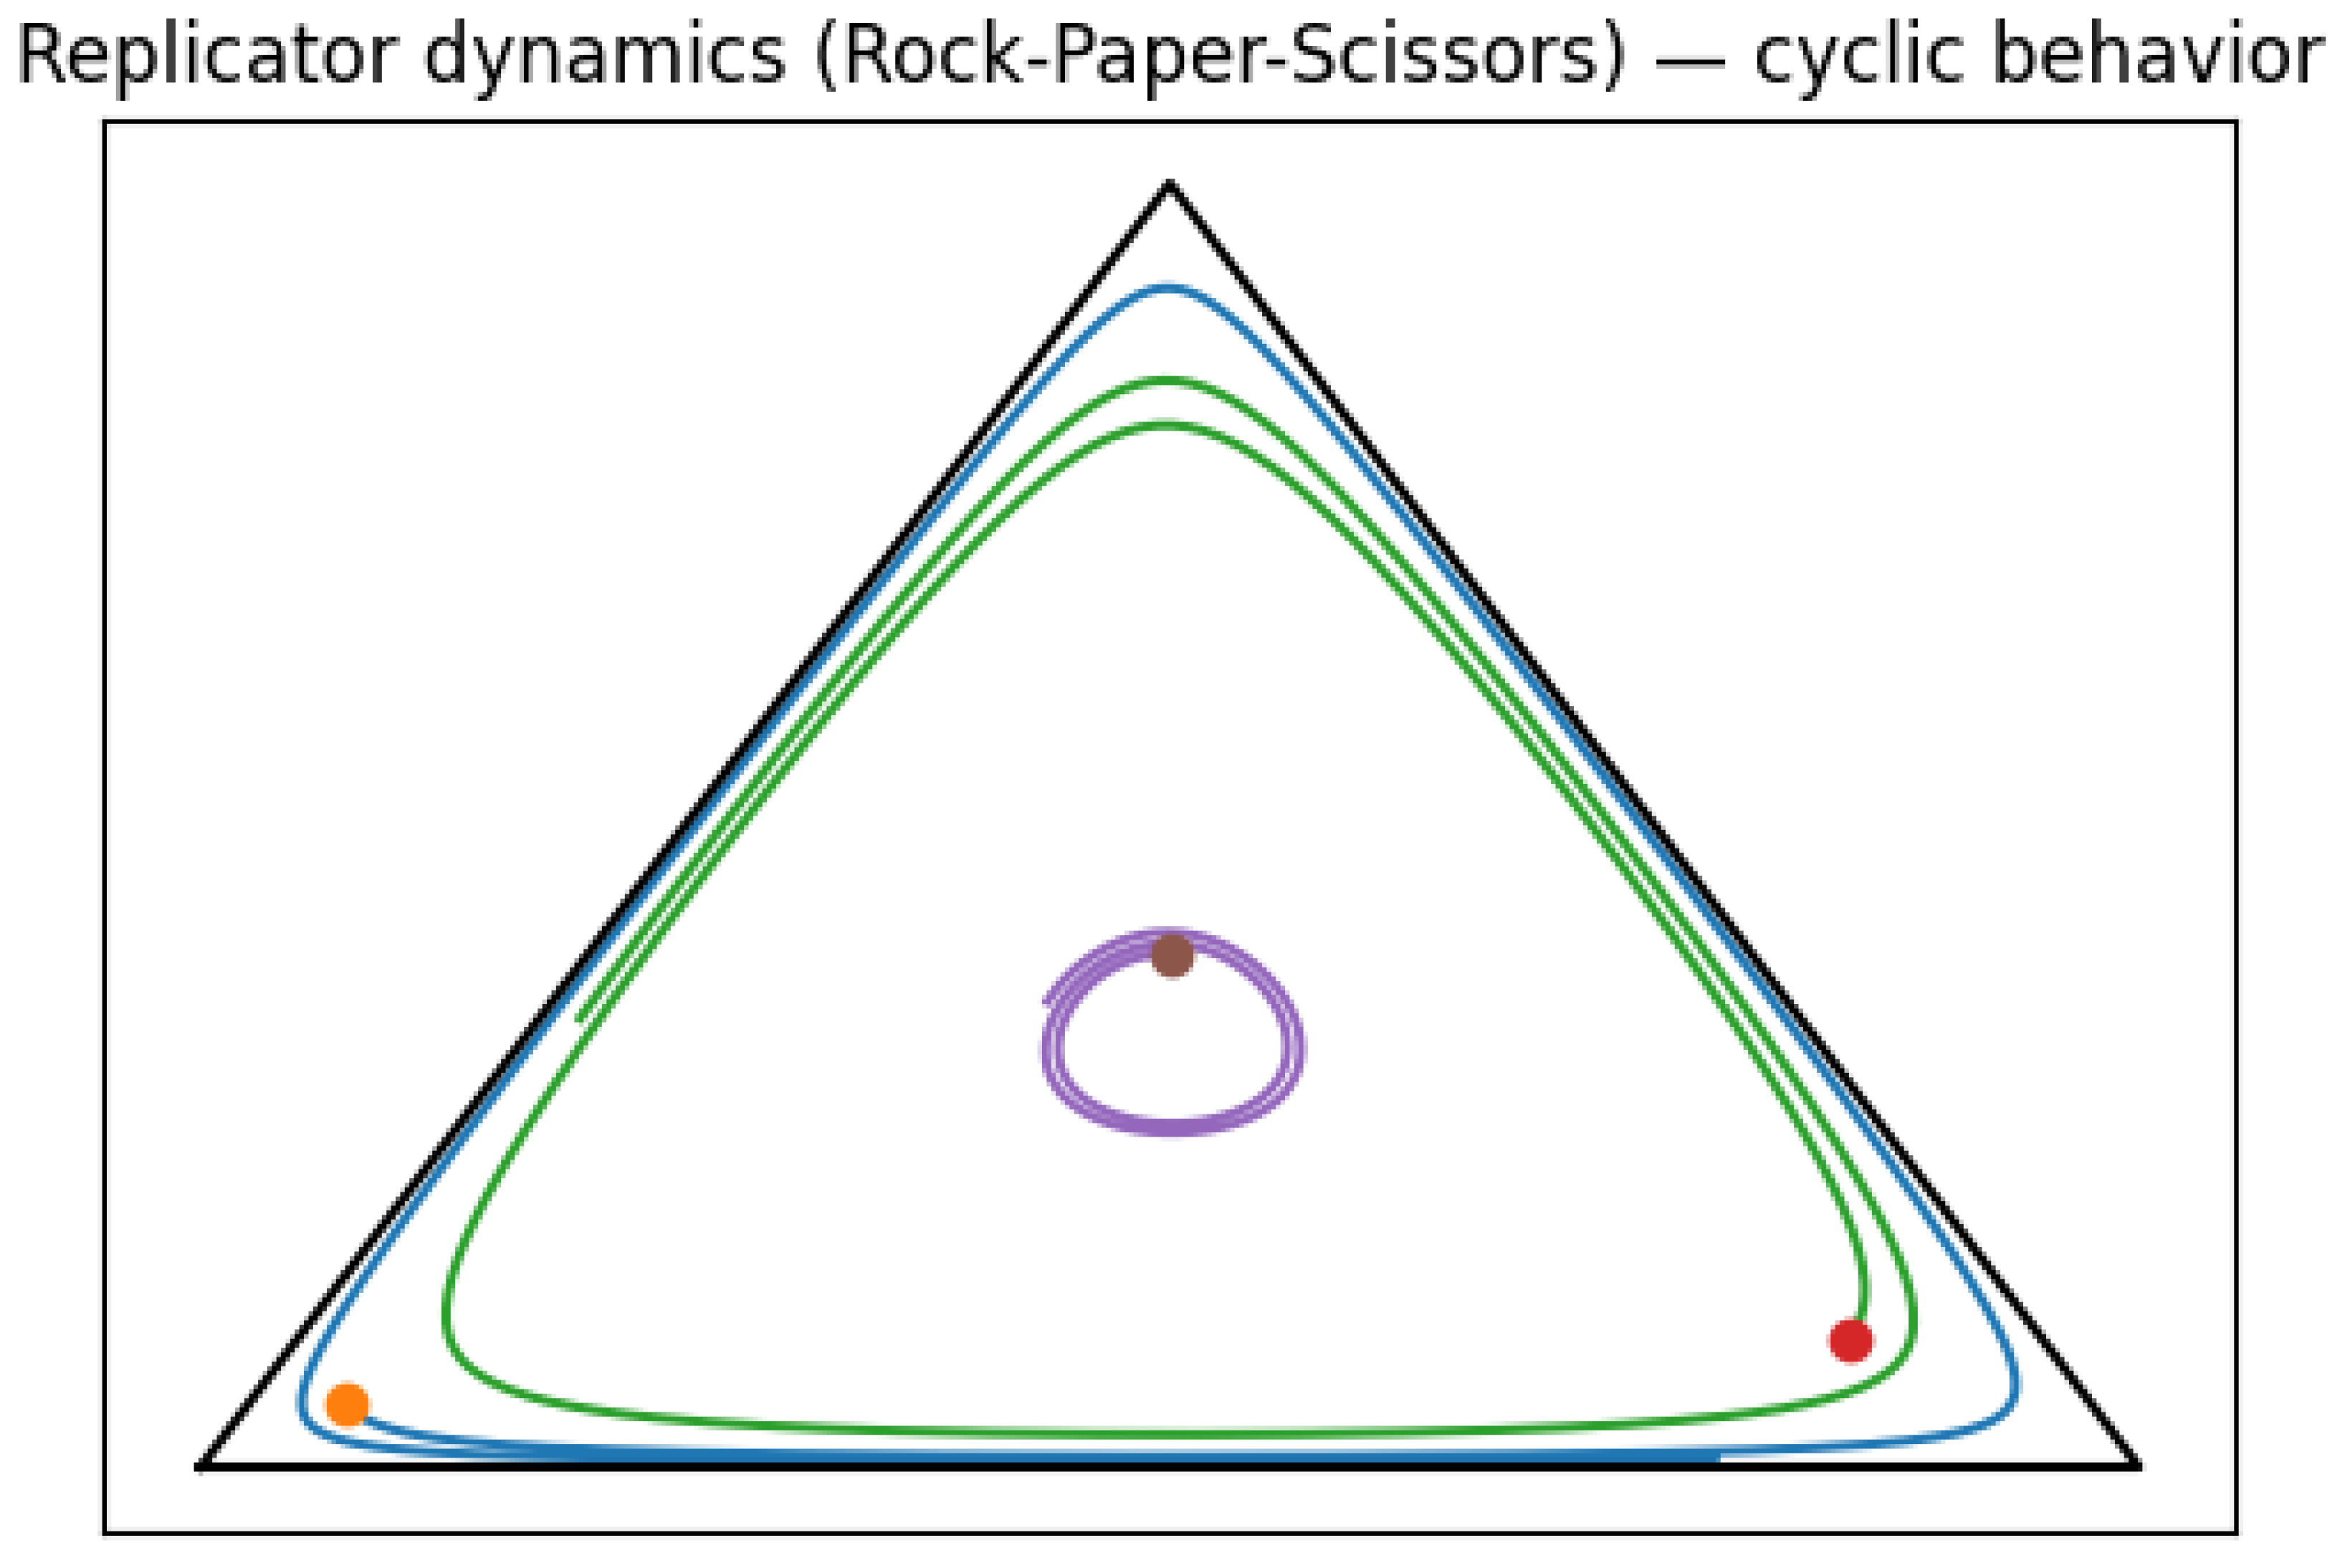
5.3. Game-Theoretic Formulations of Deep Neural Networks (DNNs) Through Evolutionary Game Dynamics
Deep neural networks (DNNs) can be formulated within the framework of evolutionary game dynamics, where the optimization of network parameters is recast as a competitive evolutionary process in which different parameter configurations act as strategies that undergo selection, mutation, and adaptation over time. This perspective allows a rigorous characterization of learning dynamics through replicator equations, Nash equilibria, and mutation-selection balance, thereby linking deep learning to fundamental principles in game theory and statistical physics. Given a neural network parameterized by , where is the space of all possible weight configurations, the performance of the network is quantified by a fitness function , which is typically defined as the negative of the empirical loss function . This loss function can be expressed as an expectation over a given dataset D,
where ℓ represents the pointwise loss function, such as the squared error loss or cross-entropy loss. The fitness of a given parameter configuration is then defined as
which ensures that lower loss corresponds to higher fitness. The evolutionary distribution of network parameters, denoted by , follows an evolutionary replicator-mutator equation,
where is the mean fitness across all parameter configurations,
The first term in the equation represents selection dynamics, where parameter configurations with higher fitness proliferate, while the second term models mutations, accounting for stochastic noise in learning updates. The steady-state solution to this equation corresponds to an evolutionarily stable distribution , which satisfies
for any small perturbation from . The learning process in deep networks can thus be viewed as an evolutionary competition in which weight distributions evolve toward stable equilibria or limit cycles.
The standard stochastic gradient descent (SGD) update rule, given by
can be reinterpreted as a mean-field approximation of the replicator equation with stochastic diffusion,
where represents a stochastic perturbation modeling noise in the gradient updates. In the limit of infinitesimally small learning rate , the SGD update can be seen as an Ornstein-Uhlenbeck process,
where denotes a Wiener process. The equilibrium distribution of network parameters is then governed by the Fokker-Planck equation,
This equation describes the evolution of the probability density of weight configurations under a combination of gradient descent and stochastic exploration, which can be interpreted as a mutation-selection process in an evolutionary game.
The steady-state solution corresponds to a Boltzmann-Gibbs distribution,
where acts as an inverse temperature parameter, and Z is the partition function ensuring normalization. This establishes a direct connection between deep learning optimization and principles of statistical mechanics, whereby learning dynamics resemble an energy minimization process subject to thermal noise. In the case of generative adversarial networks (GANs), the evolutionary perspective is particularly insightful. A GAN consists of a generator G and a discriminator D, which play a two-player zero-sum game governed by the minimax objective,
The training dynamics of GANs exhibit co-evolutionary behavior, which can be captured by the coupled replicator equations,
Unlike standard deep learning, GAN training often fails to converge to an equilibrium due to cycling behavior.
This phenomenon can be analyzed through Hamiltonian game dynamics,
These equations describe a conservative dynamical system, where learning trajectories follow closed orbits rather than converging to fixed points. This behavior is characteristic of zero-sum games and is mathematically analogous to the Red Queen effect in evolutionary biology, where competing species continually adapt without achieving a stable equilibrium.
5.3.1. Python Code to Generate Figure 57, Figure 58 and Figure 59 Illustrating Game-Theoretic Formulations of Deep Neural Networks (DNNs) Through Evolutionary Game Dynamics
The Python code below produces the Figure 57, Figure 58 and Figure 59 illustrating Game-theoretic formulations of deep neural networks (DNNs) through Evolutionary Game Dynamics.
Figure 57.
Replicator Dynamics as Gradient Descent
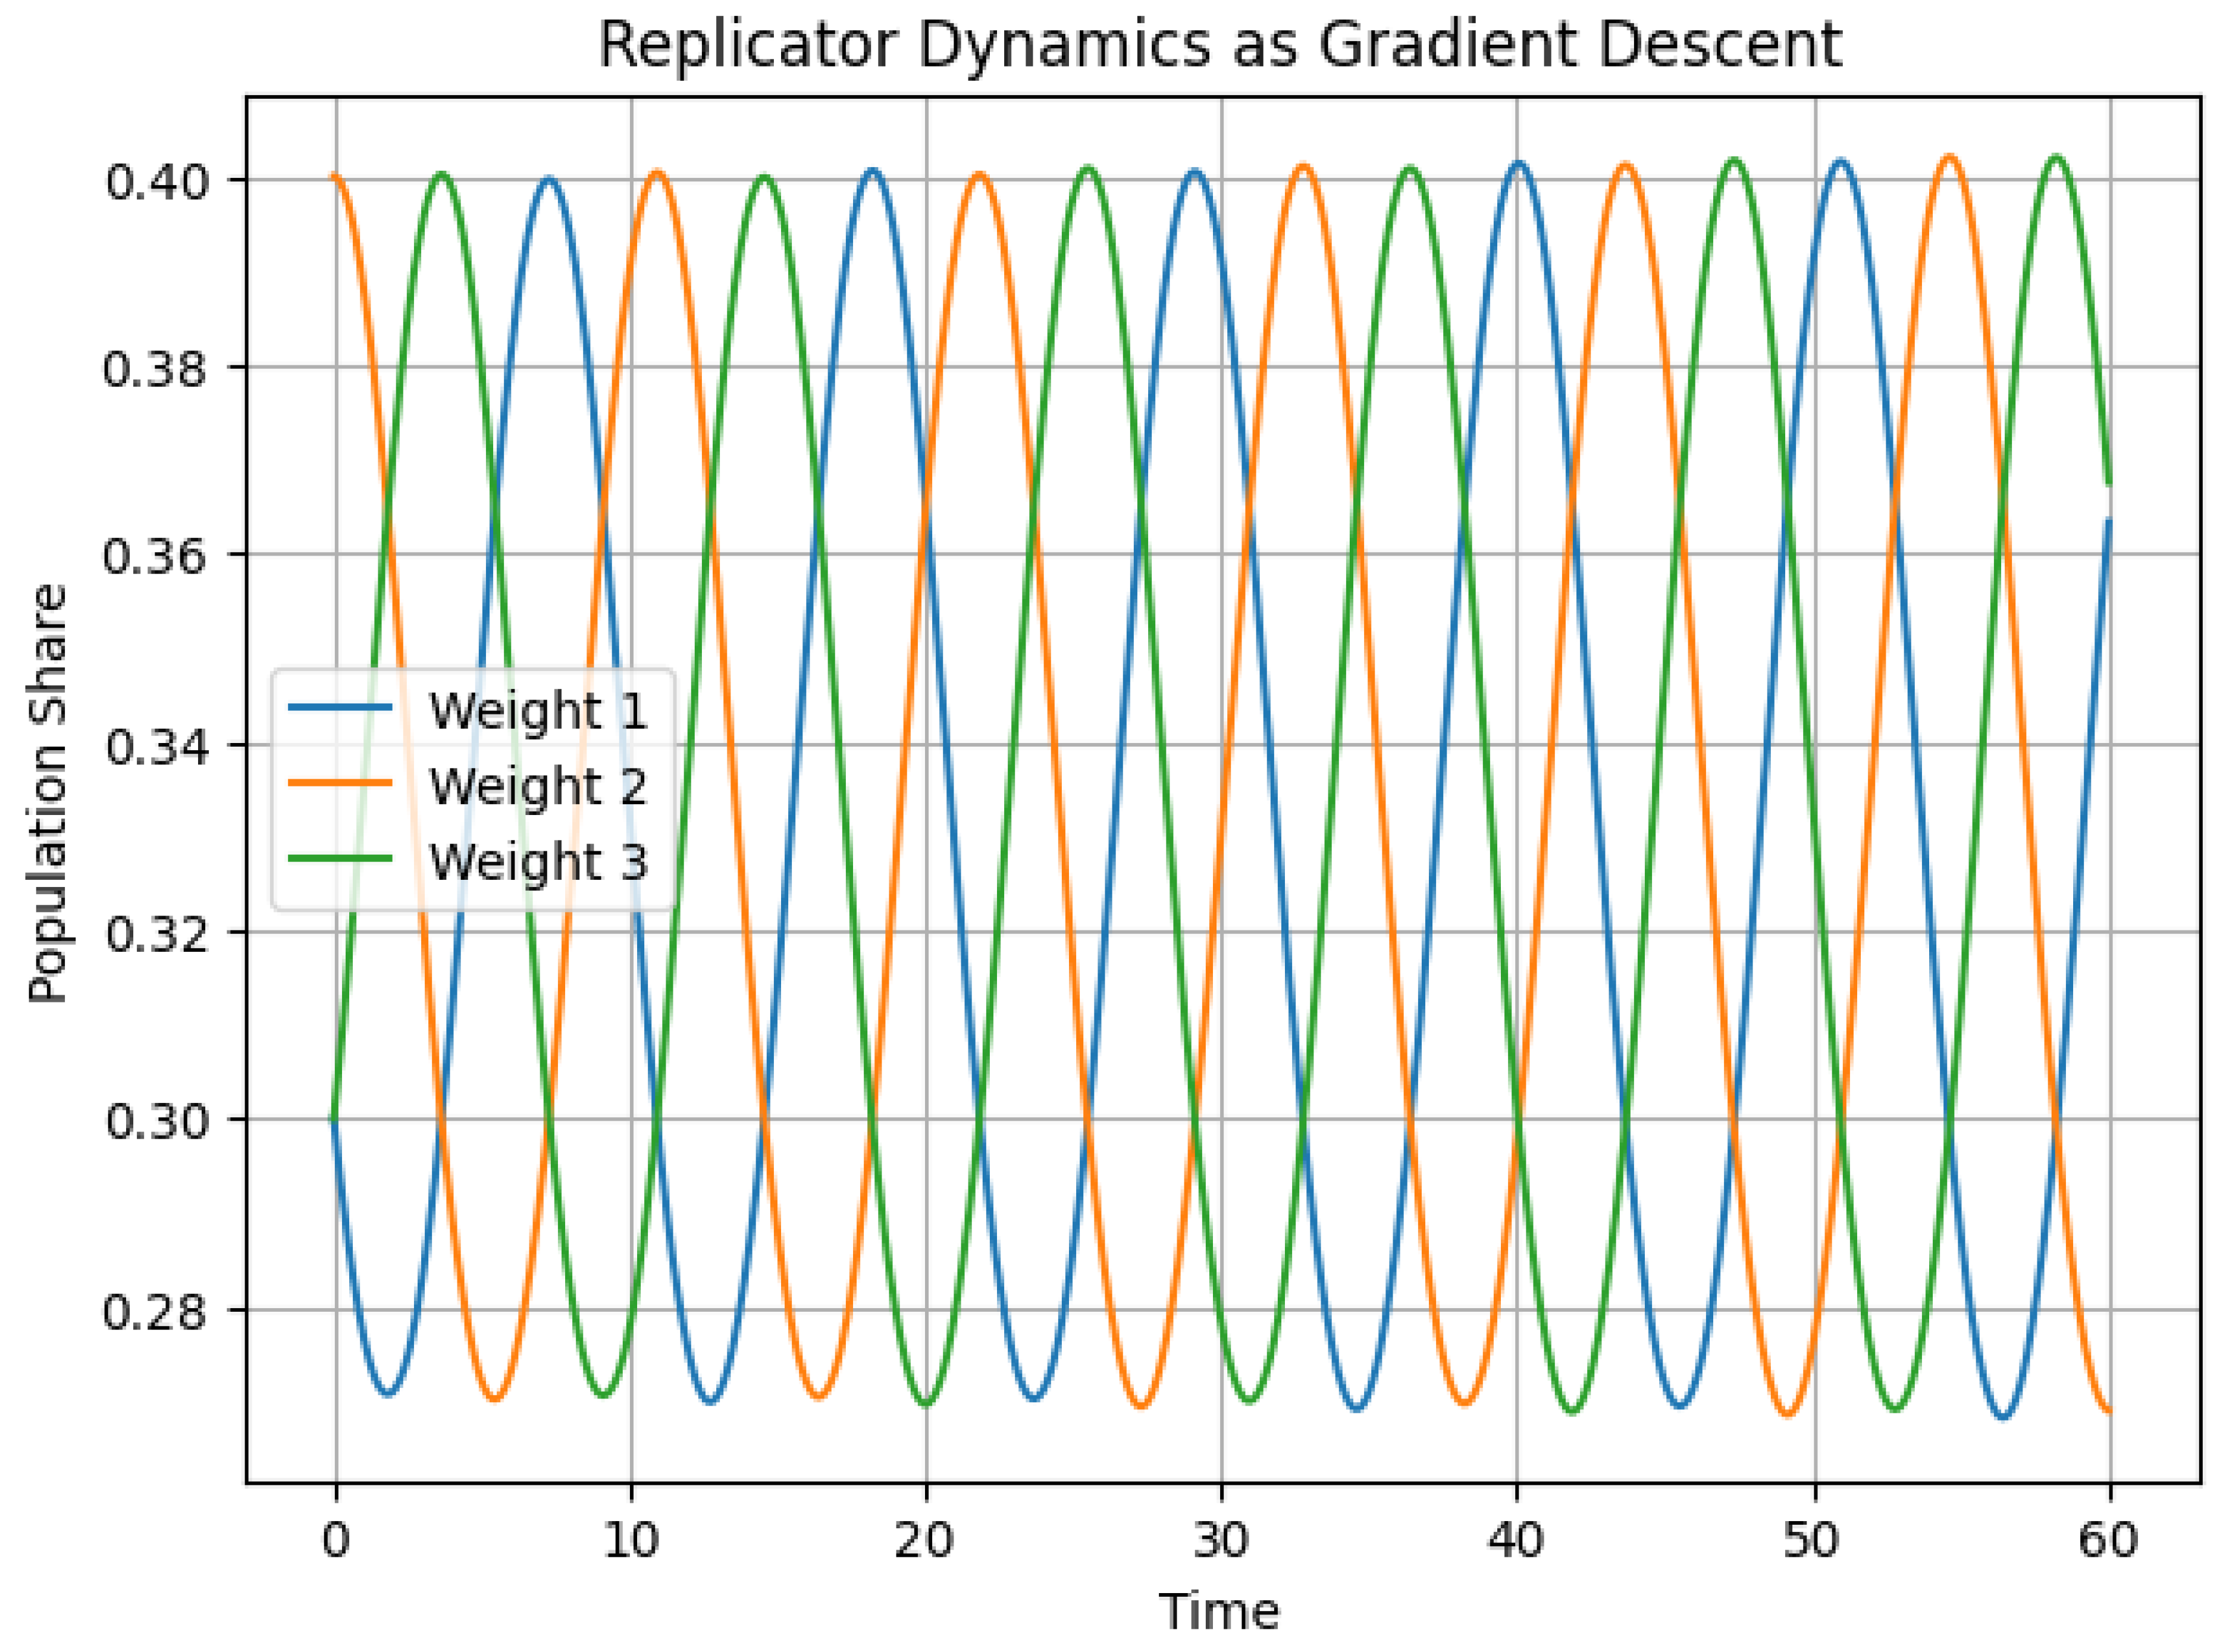
Figure 58.
Min-Max Dynamics (Adversarial Training)
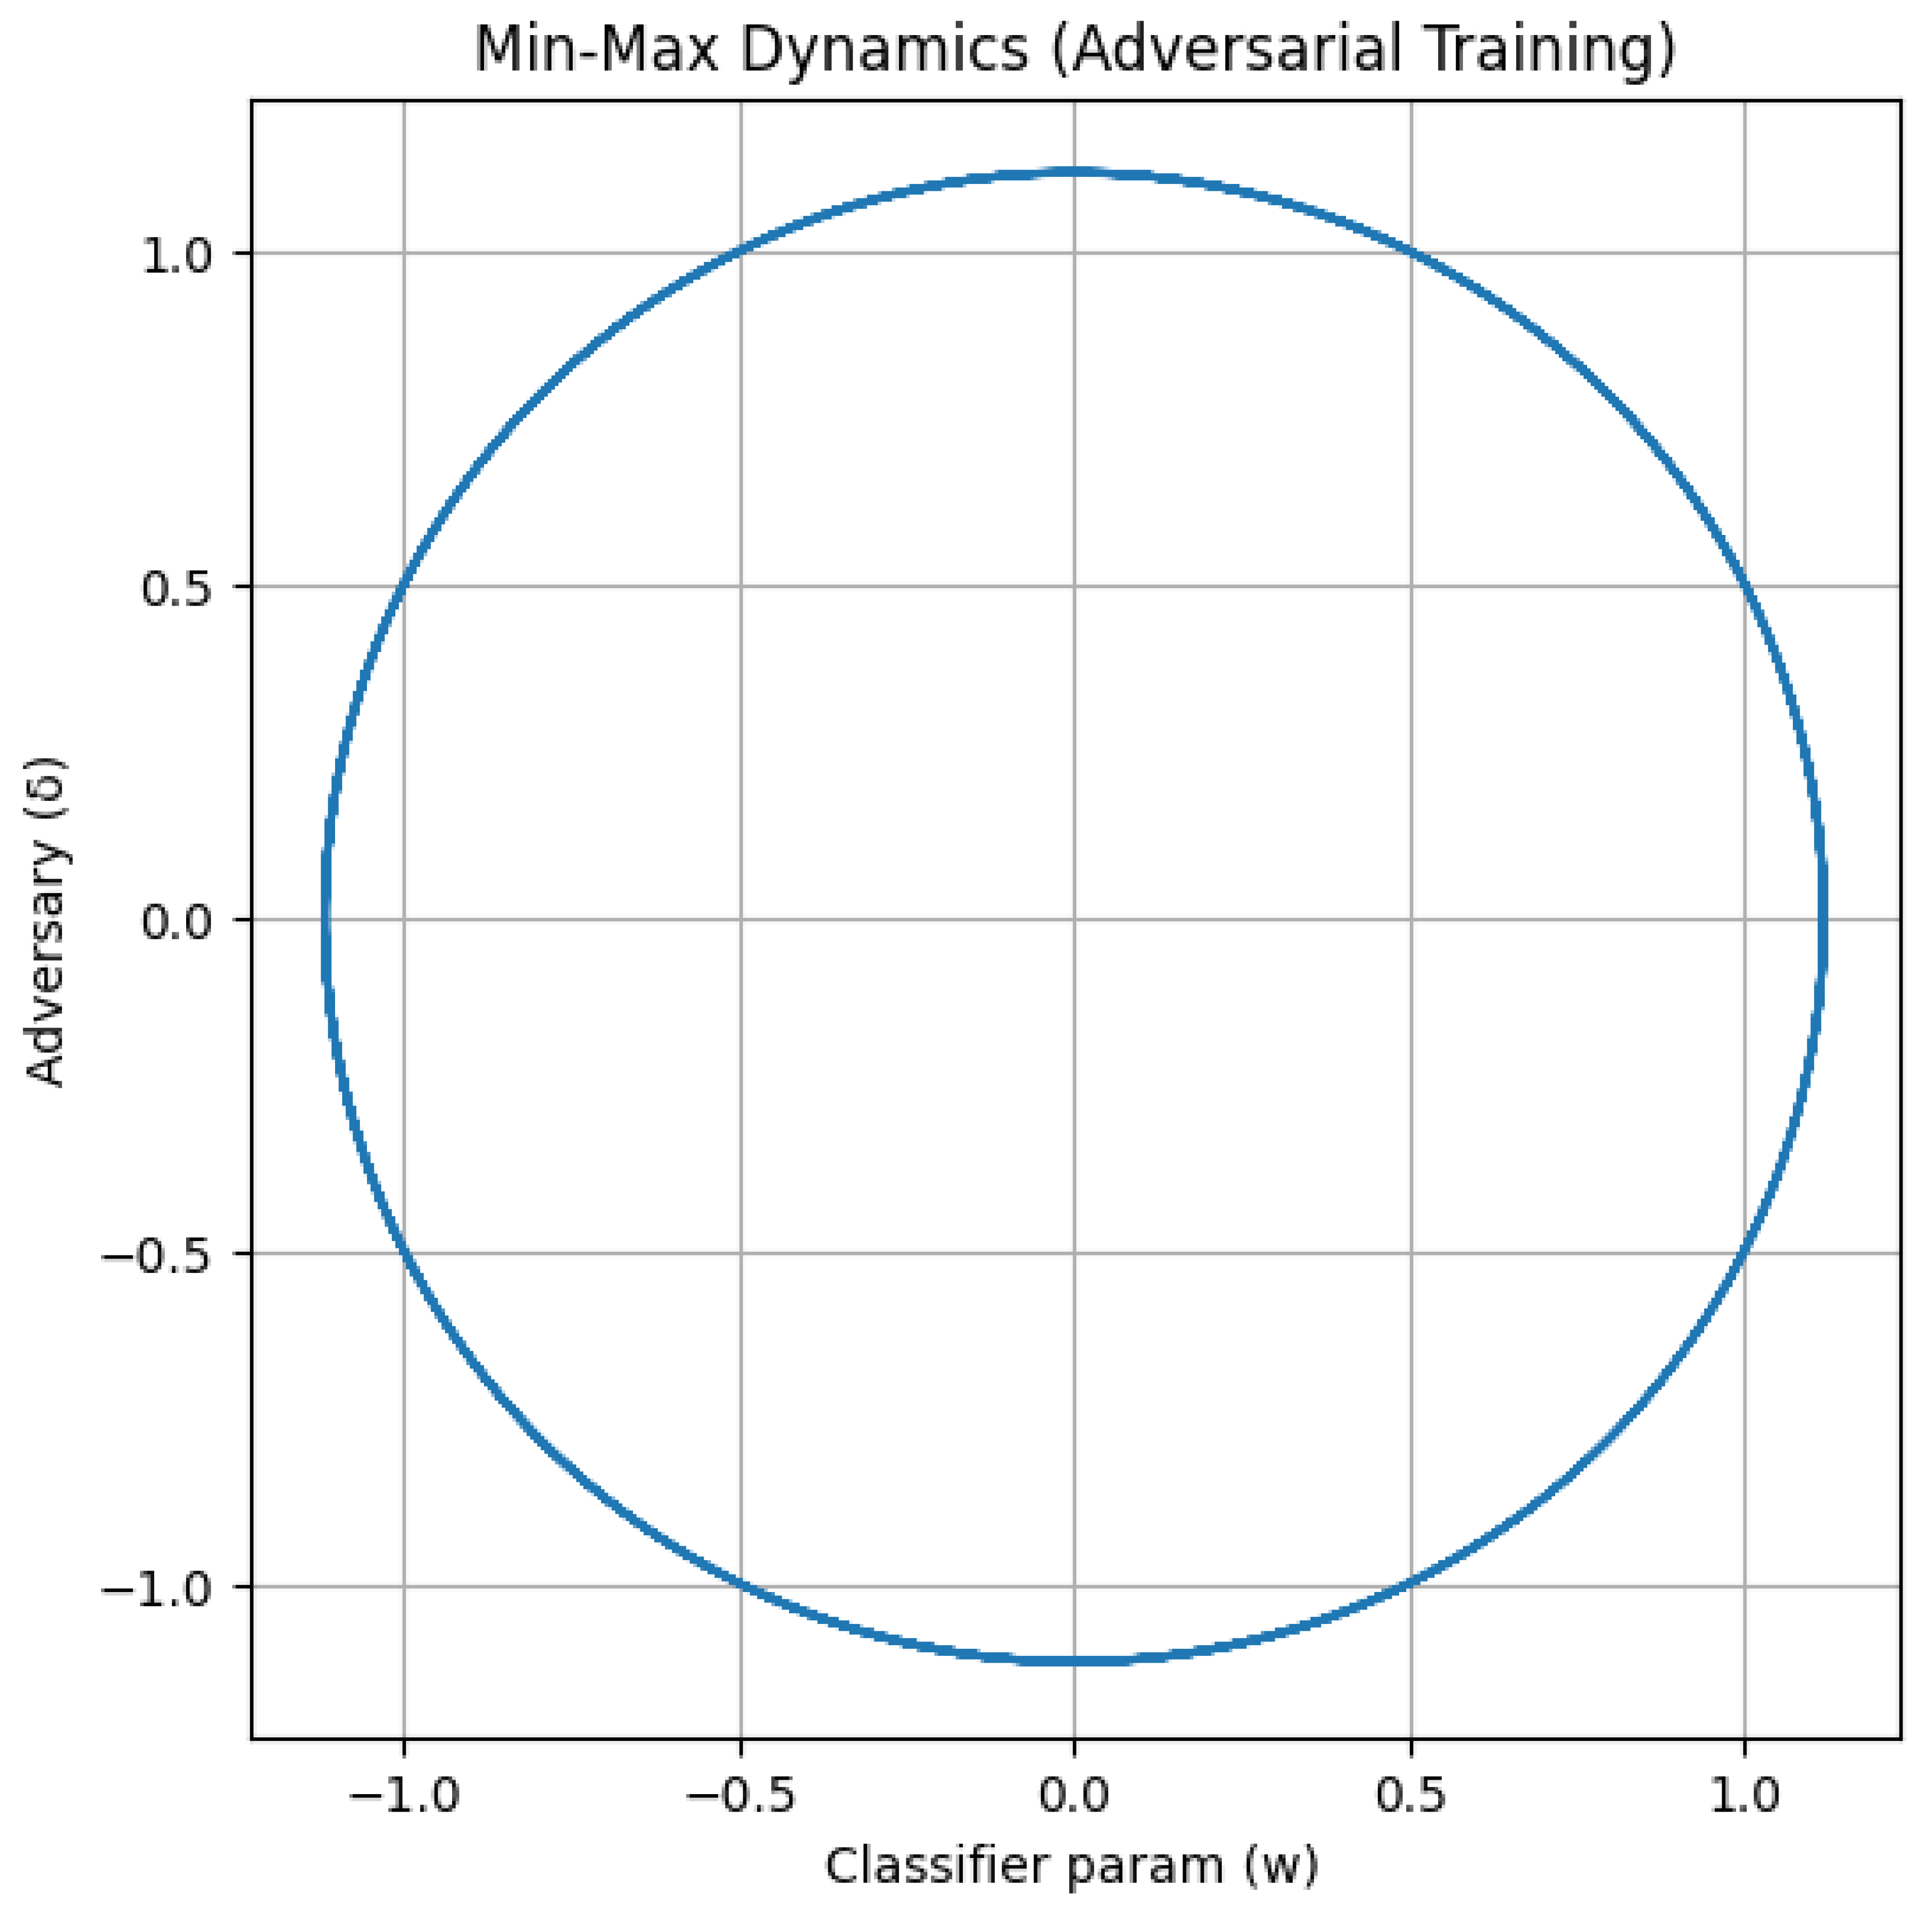
Figure 59.
Cooperative Game (Shared Potential)
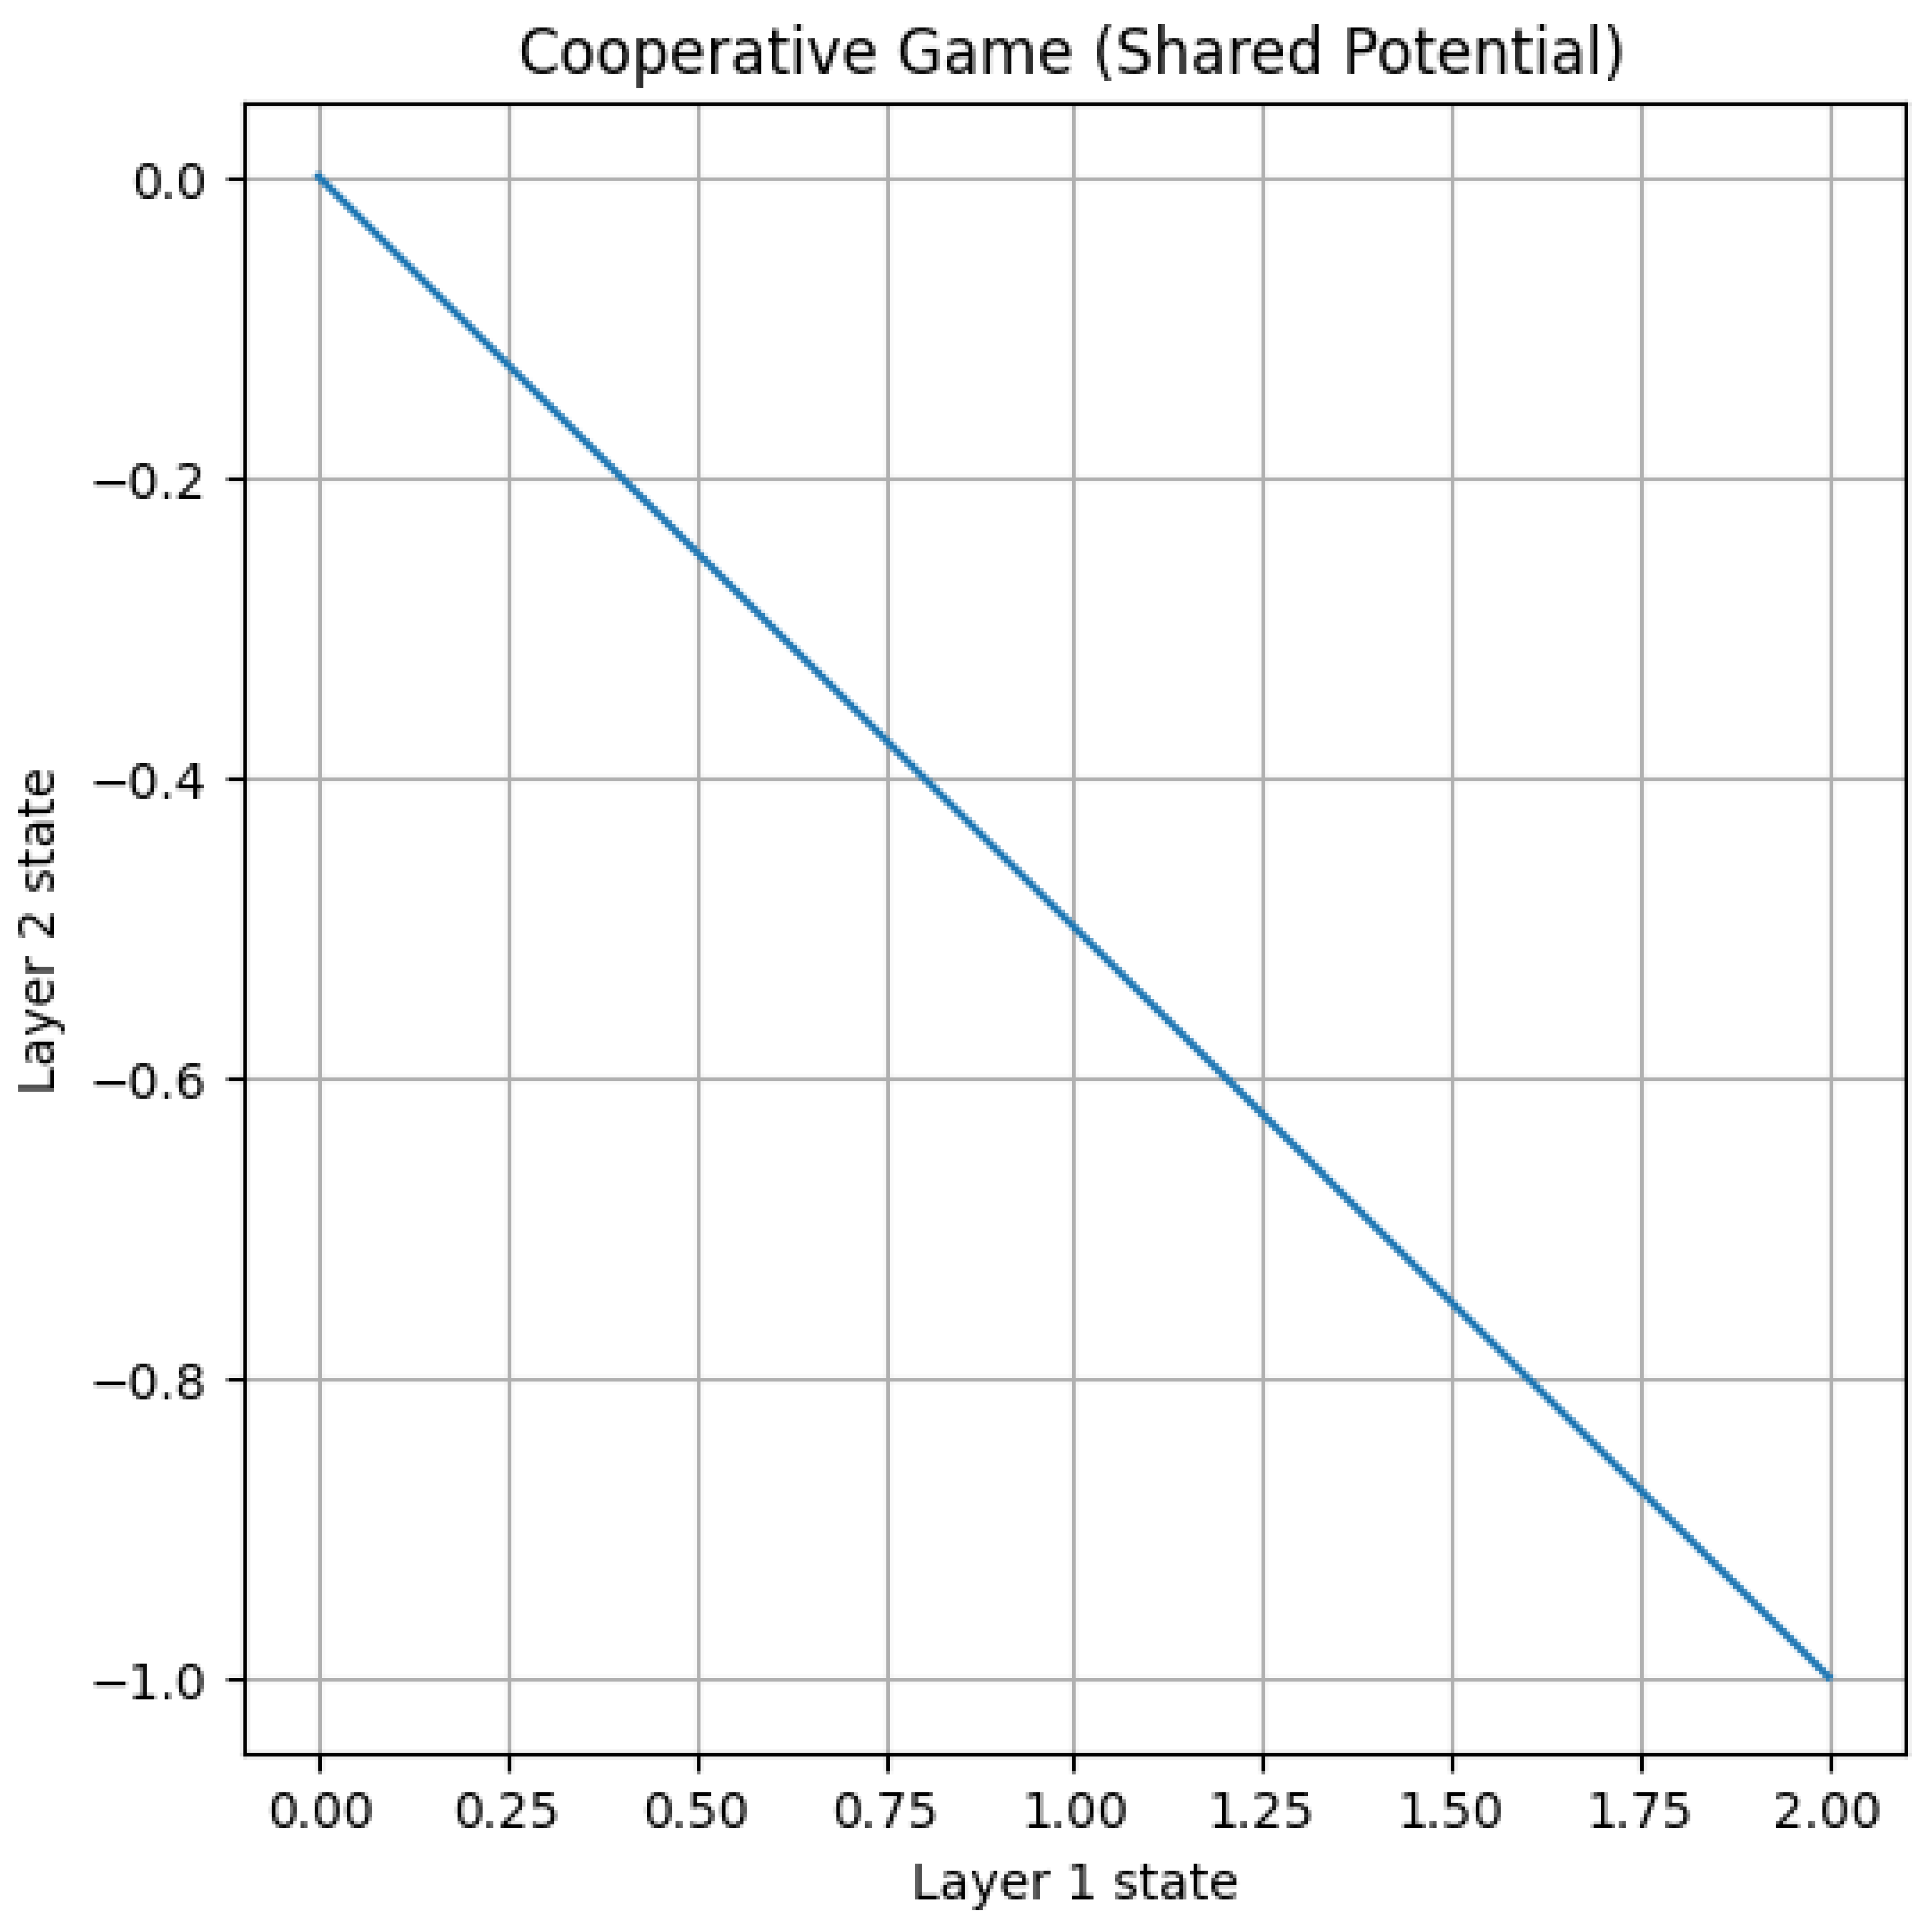
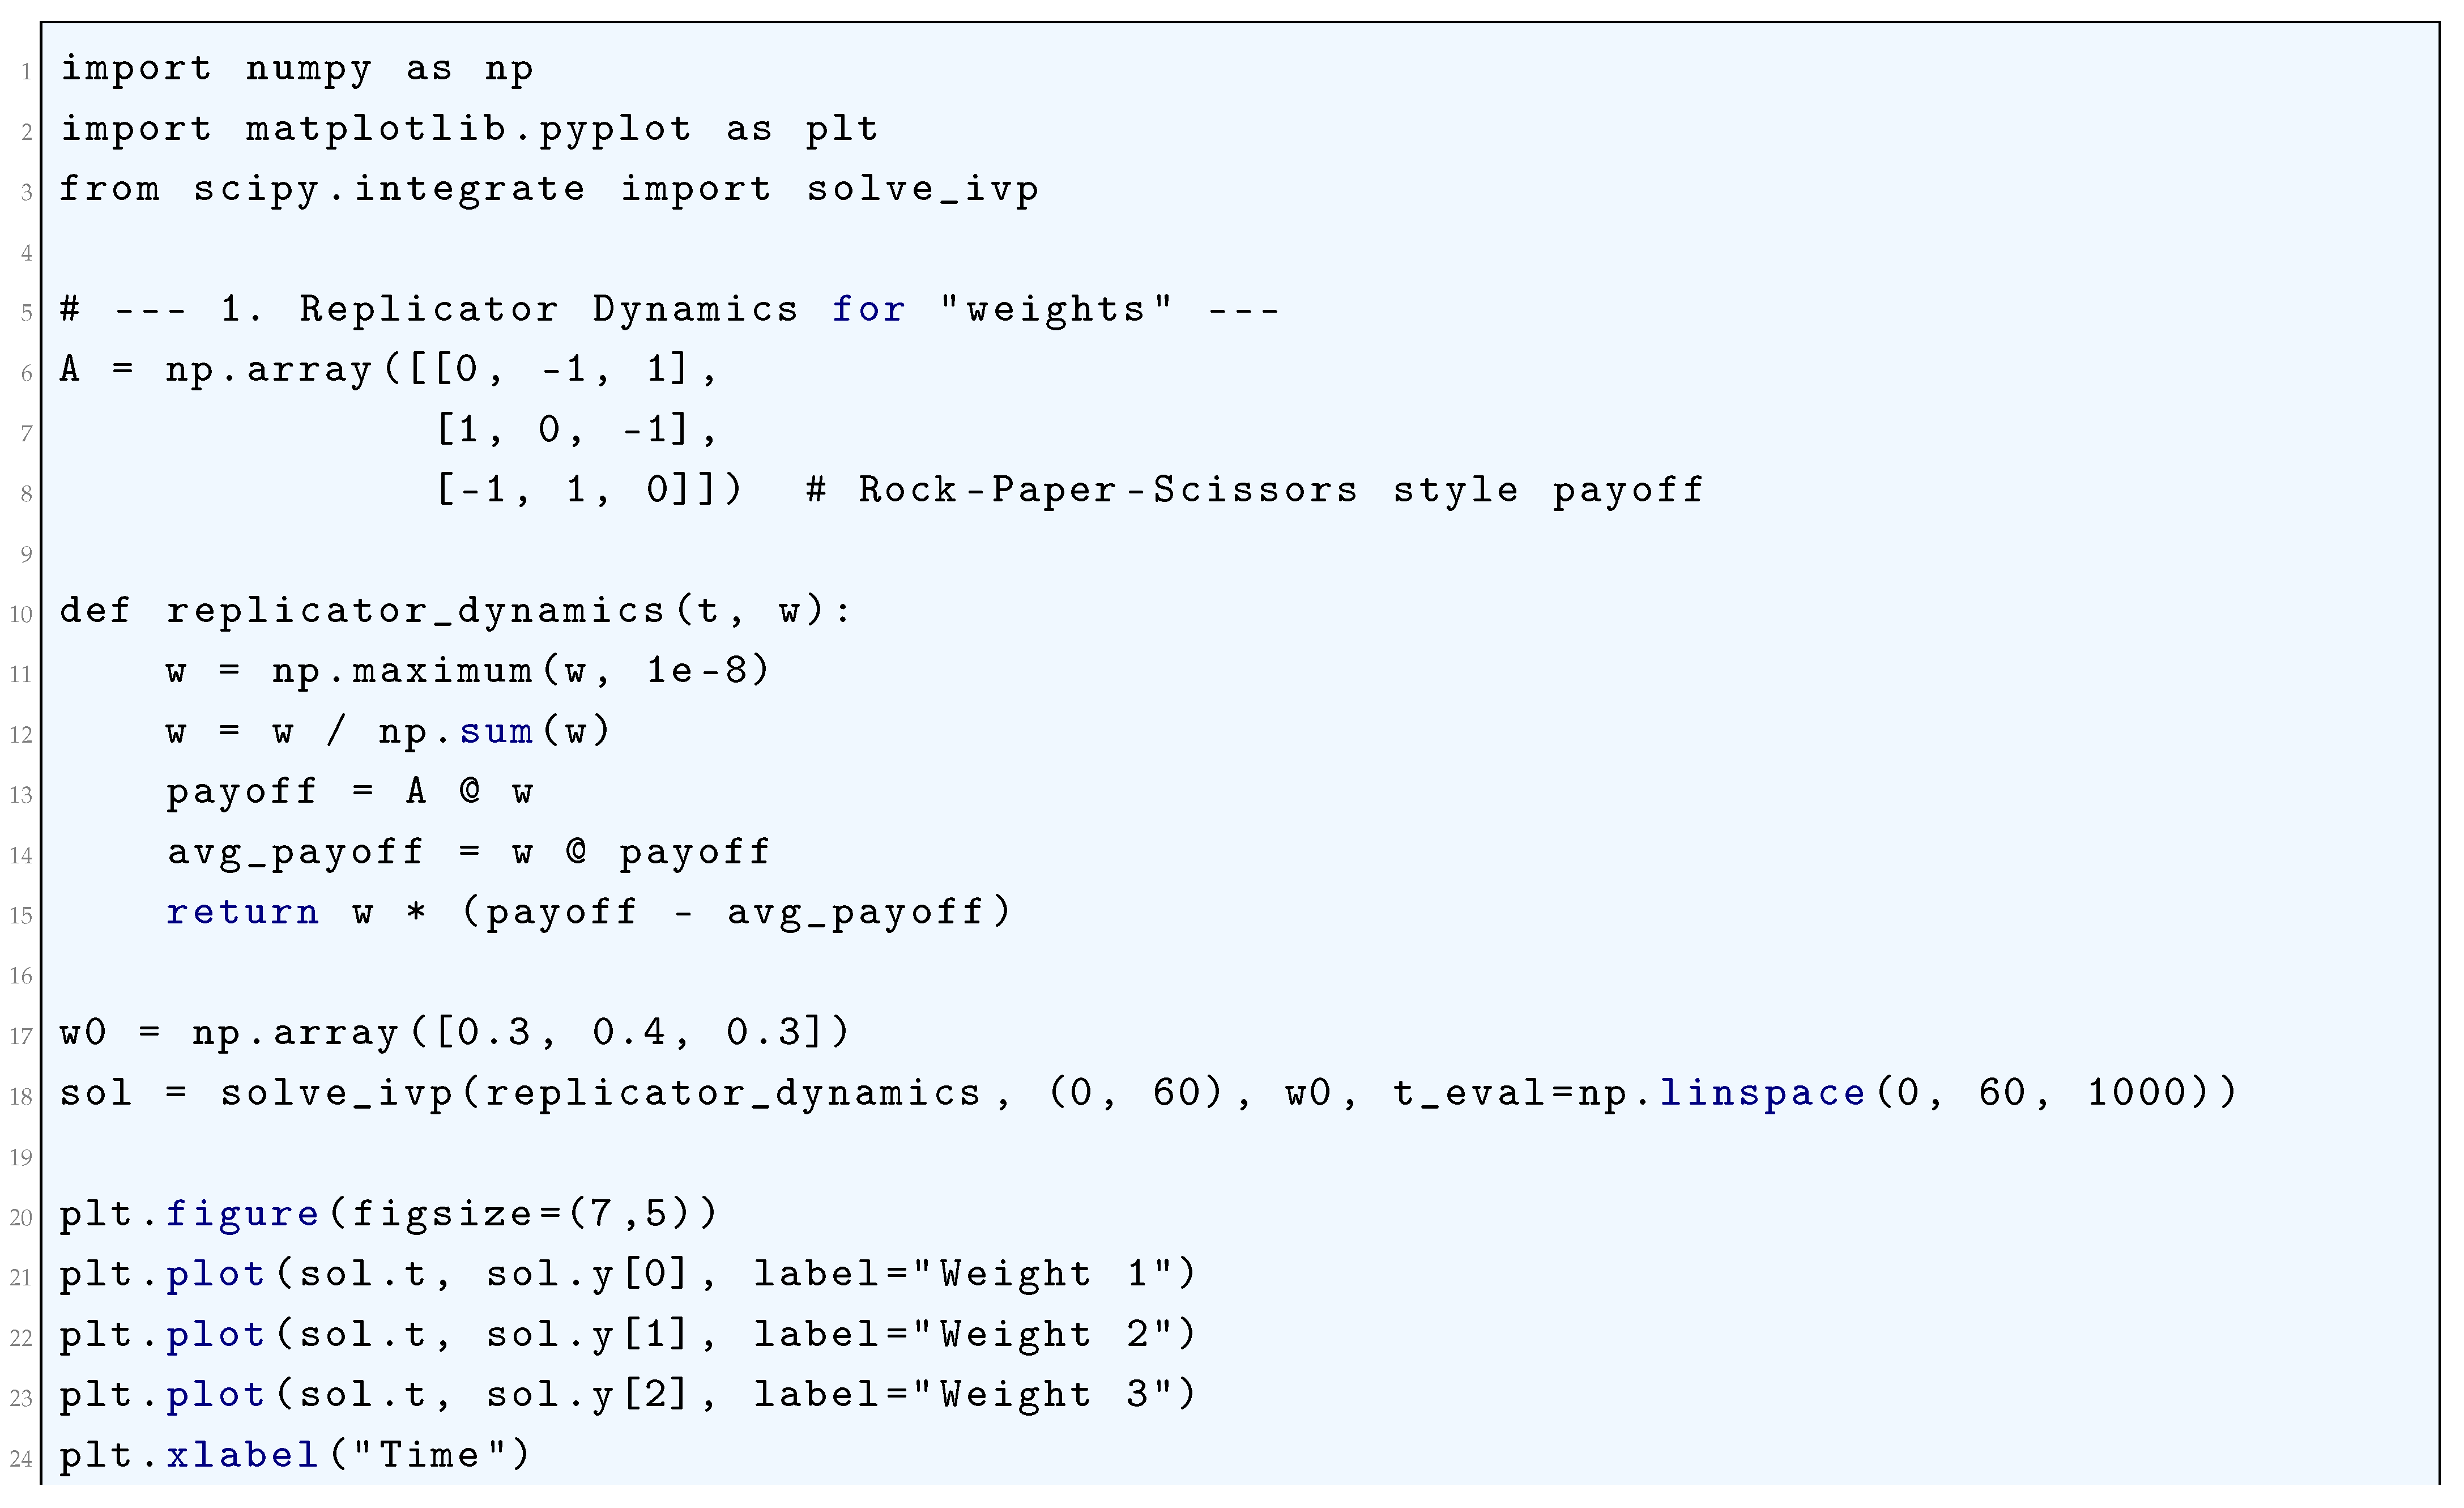
5.4. Analysis of Deep Neural Networks (DNNs) Through Variational Inequalities
Deep neural networks (DNNs) can be rigorously analyzed through the mathematical framework of variational inequalities, which provide a fundamental structure for understanding the equilibrium properties of optimization processes underlying deep learning. Variational inequalities (VIs) generalize optimization problems and offer a broader perspective on stability, convergence, and generalization in high-dimensional nonconvex settings. The problem of training a deep neural network can be formulated as a variational inequality by considering the minimization of a loss function , where the goal is to determine the optimal parameters satisfying the condition
This inequality characterizes the equilibrium conditions in the optimization landscape of deep learning. It expresses the fact that at the optimal point , any infinitesimal movement in the parameter space does not yield a lower value of the loss function. The gradient descent update rule, given by
where is the learning rate, can be rewritten as a projection-based variational inequality if constraints exist. Specifically, if the parameter space is constrained to a closed and convex set , then the variational inequality formulation of the training process is
This variational inequality expresses the fact that is a stationary point of the constrained optimization problem, meaning that the projected gradient update
ensures that the sequence converges to the solution of the variational inequality under suitable assumptions on the loss function. A key property in variational inequalities is monotonicity. The operator associated with the variational inequality is given by
and monotonicity is defined by the condition
For convex loss functions, is a monotone operator, ensuring the uniqueness of the equilibrium point. If is strongly monotone, satisfying
then the optimization process exhibits exponential convergence, meaning that the iterates satisfy
where C is a constant. This strong monotonicity property provides a rigorous foundation for understanding the rate of convergence of deep neural network training. In adversarial training, deep networks are often formulated as saddle-point problems of the form
where z represents an adversarial perturbation. The equilibrium conditions in this case are described by the system of variational inequalities
These inequalities characterize the stable equilibrium of the adversarial learning process, ensuring that neither the network nor the adversary can unilaterally improve their respective objectives. The analysis of stochastic gradient descent (SGD) in deep learning can also be conducted via variational inequalities. The expected gradient field in the presence of stochasticity is given by
where represents a random variable encoding the data distribution. The variational inequality for SGD is then
Stochastic approximation methods ensure convergence to the equilibrium point under conditions on the variance of the gradient estimator. Specifically, if is co-coercive, meaning there exists such that
then projected SGD satisfies
where is the variance of the stochastic gradient noise. This establishes a rigorous bound on the convergence rate of SGD in terms of variational inequalities. The generalization properties of deep networks can also be rigorously studied using variational inequalities. Given a distribution shift perturbation , the parameter shift satisfies the generalization bound
where the constant C is determined by the Lipschitz continuity of the gradient field. This bound ensures that the network’s performance remains stable under small perturbations in the data distribution. The variational inequality framework provides a unified perspective on optimization, equilibrium, and generalization in deep learning, offering rigorous theoretical insights into the dynamics of training and stability of neural networks.
5.4.1. Monotone/Potential Operator (Gradient of a Convex Potential)
A monotone operator is a fundamental object in the theory of variational inequalities, convex optimization, and equilibrium problems. Formally, let (H) be a real Hilbert space with inner product and induced norm . An operator is said to be monotone if for all , the inequality
holds. This condition encodes the idea that the operator does not decrease the angle between the difference of outputs and the difference of inputs, thereby generalizing the notion of a non-decreasing function in one dimension.
An important class of monotone operators arises as gradients of convex functions. Let be a convex and differentiable functional. Its gradient operator is defined by
Since is convex, it satisfies for all the first-order characterization of convexity:
Switching the roles of x and y yields
Adding these two inequalities gives
which proves that the gradient mapping is a monotone operator. Furthermore, if is strictly convex, then
which implies strict monotonicity of the operator. This property ensures uniqueness of solutions to variational inequality problems of the form: find such that
where is a convex feasible set. The monotonicity condition can also be interpreted geometrically. For the gradient of a convex function, the operator points in a direction that consistently aligns with the displacement vector between points in the domain. In other words, moving along the direction of the operator never contradicts the structure induced by convexity. This is the key mechanism underlying convergence of gradient-based algorithms in convex optimization.
In summary, the gradient of a convex potential is always a monotone operator, and the converse is also true in the sense that maximal cyclically monotone operators are precisely subdifferentials of convex functions. The equation
together with the inequality
completely captures the rigorous mathematical relationship between monotone operators and convex potentials.
5.4.2. Saddle/Non-Monotone Bilinear Operator (Models min–max Behavior)
Let , and denote . A saddle (min–max) objective is a function that is convex in x for every fixed y and concave in y for every fixed x. Associated to L one defines the operator
so that a saddle point satisfies the variational inequality
This VI formulation is equivalent to the saddle condition for all whenever (L) is convex–concave and sufficiently regular. A canonical and instructive special case is a bilinear objective
for which
The stationary (saddle) conditions and reduce to
so the solution set is ; in particular multiplicity of solutions occurs whenever (A) is rank-deficient.
For two arbitrary points and the bilinear operator satisfies the exact identity
hence (F) is (weakly) monotone in the sense that the left-hand side is identically zero for all . More generally for a smooth convex–concave L one has the monotonicity inequality
but the bilinear case is the extreme where the quantity is exactly zero rather than strictly positive.
The bilinear operator is therefore not a gradient field of any scalar potential on unless it is identically zero, because for any gradient field the Jacobian must be symmetric, whereas the Jacobian of the bilinear operator is the block matrix
which satisfies , J is skew-symmetric (block anti-symmetric) and thus cannot equal a symmetric matrix unless . Consider the continuous-time gradient-flow–ascent dynamics that arise from (F),
which for the bilinear case is the linear ODE
Because , all eigenvalues of (J) are purely imaginary (or zero); equivalently (J) generates a one-parameter family of orthogonal transformations and the quadratic energy is conserved along trajectories:
In the simplest scalar toy with one obtains , Jacobian , and the continuous dynamics
which is the harmonic oscillator; solutions are circular periodic orbits and the radius is constant in time.
The behaviour in discrete-time simultaneous gradient steps (explicit Euler) is markedly different and typically unstable. For a constant linear operator the explicit simultaneous update with step-size reads
For the scalar bilinear example the update matrix is
whose eigenvalues are and satisfy . Thus the explicit (simultaneous) method amplifies the norm and the iterates diverge for any fixed . This instability is the discrete-time manifestation of attempting to integrate a conservative rotational field with an explicit integrator: energy conservation in continuous time becomes energy growth under the explicit Euler map.
Stabilization of these rotational saddle dynamics can be achieved in several mathematically transparent ways. Adding a symmetric dissipative term (for ) to the operator, i.e. replacing by , yields a Jacobian whose symmetric part is (S) and hence the operator becomes strongly monotone with modulus at least :
Strong monotonicity implies uniqueness of the VI solution and gives (linear) contraction under appropriate implicit or proximal algorithms. Algorithmically, the extragradient method applied to a Lipschitz monotone operator F with stepsize produces the linear update for ,
and for a skew-symmetric J the term is symmetric negative semidefinite; in the scalar bilinear example giving
whose eigenvalues are and hence have modulus for consequently the extragradient step produces a contraction for sufficiently small and stabilizes the iteration where explicit simultaneous updates blow up. More generally, for monotone and L-Lipschitz operators the extragradient method converges with step-size (linear algebraic detail omitted here).
In summary, bilinear saddle operators arising in min–max problems furnish linear, skew-adjoint interaction terms that are not gradients of any scalar potential and which induce purely rotational continuous dynamics and discrete-time instabilities under naive simultaneous gradient updates. The mathematical diagnostics are
- The block-Jacobianwith
- The identityfor the bilinear case
- Conservation of quadratic energies in continuous time, and
- Discrete amplificationfor explicit Euler.
Algorithmic remedies—addition of symmetric dissipative terms, implicit/proximal discretizations, or extragradient/optimistic methods—convert the spectral properties so that the symmetric part of the Jacobian is positive (strong monotonicity) or the discrete map becomes contractive, thereby restoring convergence to equilibrium.
5.4.3. Skew (Rotation)
A skew operator is a linear operator whose defining property is antisymmetry with respect to the underlying inner product. In the setting of a finite-dimensional real Hilbert space with standard Euclidean inner product , a matrix is said to be skew-symmetric if
Equivalently, for all vectors , one has
This antisymmetry implies that the quadratic form associated with J vanishes identically, because for any
Thus, skew operators generate purely rotational effects in the vector space, preserving lengths and inner products. The eigenstructure of skew-symmetric matrices is determined by their antisymmetry. If J is real skew-symmetric, then for any eigenvalue–eigenvector pair with , one has
Taking inner products with u, it follows that
But the left-hand side vanishes since J is skew-symmetric, implying . Therefore, every eigenvalue is either zero or purely imaginary. In fact, the spectrum of J is symmetric with respect to the imaginary axis, and the nonzero eigenvalues occur in complex conjugate pairs . This fact reveals that J generates infinitesimal rotations, since purely imaginary eigenvalues correspond to circular motions.
The matrix exponential of a skew-symmetric operator describes finite rotations. For any ,
is an orthogonal matrix with determinant one, hence a rotation matrix. Orthogonality follows from the fact that
since . Thus, the flow generated by the differential equation
is given by
which traces a circular or rotational trajectory in the invariant subspaces associated with each conjugate pair of imaginary eigenvalues. The simplest case is the two-dimensional rotation operator. Let
Then the ODE expands to
which is the harmonic oscillator system. Its solution is
Thus, the trajectory is a circle centered at the origin with radius , and the motion is uniform rotation with unit angular velocity. The energy
is conserved exactly, because
In higher dimensions, skew-symmetric operators generate rotations within orthogonal two-dimensional subspaces corresponding to each pair of eigenvalues, while leaving the null space invariant. That is, decomposes into a direct sum of invariant planes where circular motions occur, and invariant lines where the dynamics are static. More explicitly, there exists an orthogonal transformation Q such that
with . Each block generates uniform rotation in its associated plane with angular speed .
The geometric effect of skew operators is thus entirely conservative: they preserve Euclidean distances and angles, merely redistributing directions through rotation. In optimization and game-theoretic dynamics, skew components in an operator correspond to cycling or rotational forces around equilibria rather than dissipative movement toward equilibria. This is reflected in the fact that monotonicity of skew operators is degenerate: for all
so skew operators are monotone but not strictly monotone. Their essential role is to encode conservative rotational dynamics rather than convergence-inducing gradients.
5.4.4. Skew + Dissipation
Let with the Euclidean inner product . Let denote a linearization of an operator F at a point (or consider the linear operator . Decompose J into its symmetric and skew-symmetric parts
with and . The phrase “Skew + Dissipation’’ refers precisely to this decomposition when S has positive semidefinite (or positive definite) character and (K) is skew-symmetric: (or with ) and . The algebraic and dynamical consequences follow from elementary identities and comparison inequalities.
For any one has the exact identity
so the skew part K does not enter the quadratic form that governs monotonicity. If then J is monotone in the sense that
and if for some then J is -strongly monotone:
Strong monotonicity immediately yields uniqueness of zeros: if and then and hence when .
Consider the continuous-time linear dynamics . The instantaneous rate of change of the quadratic energy satisfies, using the skew property ,
if . By Grönwall’s inequality this yields exponential decay
so the dissipation captured by S converts the conservative rotational action of (K) into an overall contracting flow. If with then is nonincreasing and one obtains Lyapunov stability but not exponential convergence in general.
Spectrally, if for a (complex) eigenpair then
and taking real parts gives the Rayleigh-type relation
Hence the real parts of eigenvalues of J lie in the numerical range of S; in particular implies for every eigenvalue of J. Consequently the linear semigroup generated by is exponentially stable with decay rate at least . The skew part K only shifts eigenvalues along the imaginary axis (sets the oscillation frequencies) but cannot move their real parts away from those determined by S.
In discrete time the explicit Euler map with step-size ,
is stable iff the spectral radius . The purely skew case yields eigenvalues in canonical rotational blocks and hence , so explicit steps amplify and diverge. By contrast, when (scalar dissipation and K is a rotation with frequency , the update matrix in the invariant plane is
whose eigenvalues satisfy
Thus a sufficient stability condition is
showing quantitatively how dissipation permits a finite explicit step-size that stabilizes the discrete map; when no positive suffices.
Algorithmic stabilization may also be effected by higher-fidelity integrators. The extragradient (EG) linearized update applied to a constant J produces the map
If is pure skew with on a rotation plane, then
whose eigenvalues are and hence
for sufficiently small . Thus EG introduces an effective symmetric contraction term (which is positive semidefinite when J is skew) and converts rotation into contraction; more generally for the term couples S and K and can improve stability relative to simultaneous explicit updates.
From the variational inequality viewpoint, adding dissipation upgrades monotonicity: if with and , then for the VI problem the operator is strongly monotone and the VI has a unique solution. The resolvent (proximal) operator is then a contraction: if and then
and inner-producting with and using strong monotonicity gives
hence
This resolvent contraction is the continuous-time analogue of how dissipation regularizes and guarantees stable implicit updates for nonconservative dynamics.
In summary, the mathematical role of “Skew + Dissipation’’ is: K encodes conservative rotational forces (purely imaginary spectral displacements, energy-preserving infinitesimal action) while S provides symmetric dissipation that determines real parts of the spectrum, monotonicity, energy decay, uniqueness, and contractivity. The interplay is quantitative: the magnitude of K sets frequencies and oscillation amplitudes, the minimal eigenvalue of S sets exponential decay rates in continuous time and allowable explicit step-sizes in discrete time, and algorithmic devices (EG, implicit resolvents, preconditioning) exploit the positive symmetric component or introduce effective symmetric terms to neutralize the destabilizing influence of the skew part.
5.4.5. Python Code to Generate Figure 60, Figure 61 Illustrating Monotone/Potential Operator and Figure 62 Illustrating Saddle Bilinear F (min-max) and Figure 63 Illustrating Skew (Rotation) F: R z and Figure 64 Illustrating Skew + Dissipation F: R + Alpha I
The Python code below produces the Figure 60, Figure 61 illustrating Monotone/potential operator and Figure 62 illustrating Saddle Bilinear F (min-max) and Figure 63 illustrating Skew (rotation) F: R z and Figure 64 illustrating Skew + Dissipation F: R + alpha I.
Figure 60.
Monotone/Potential F=grad Phi
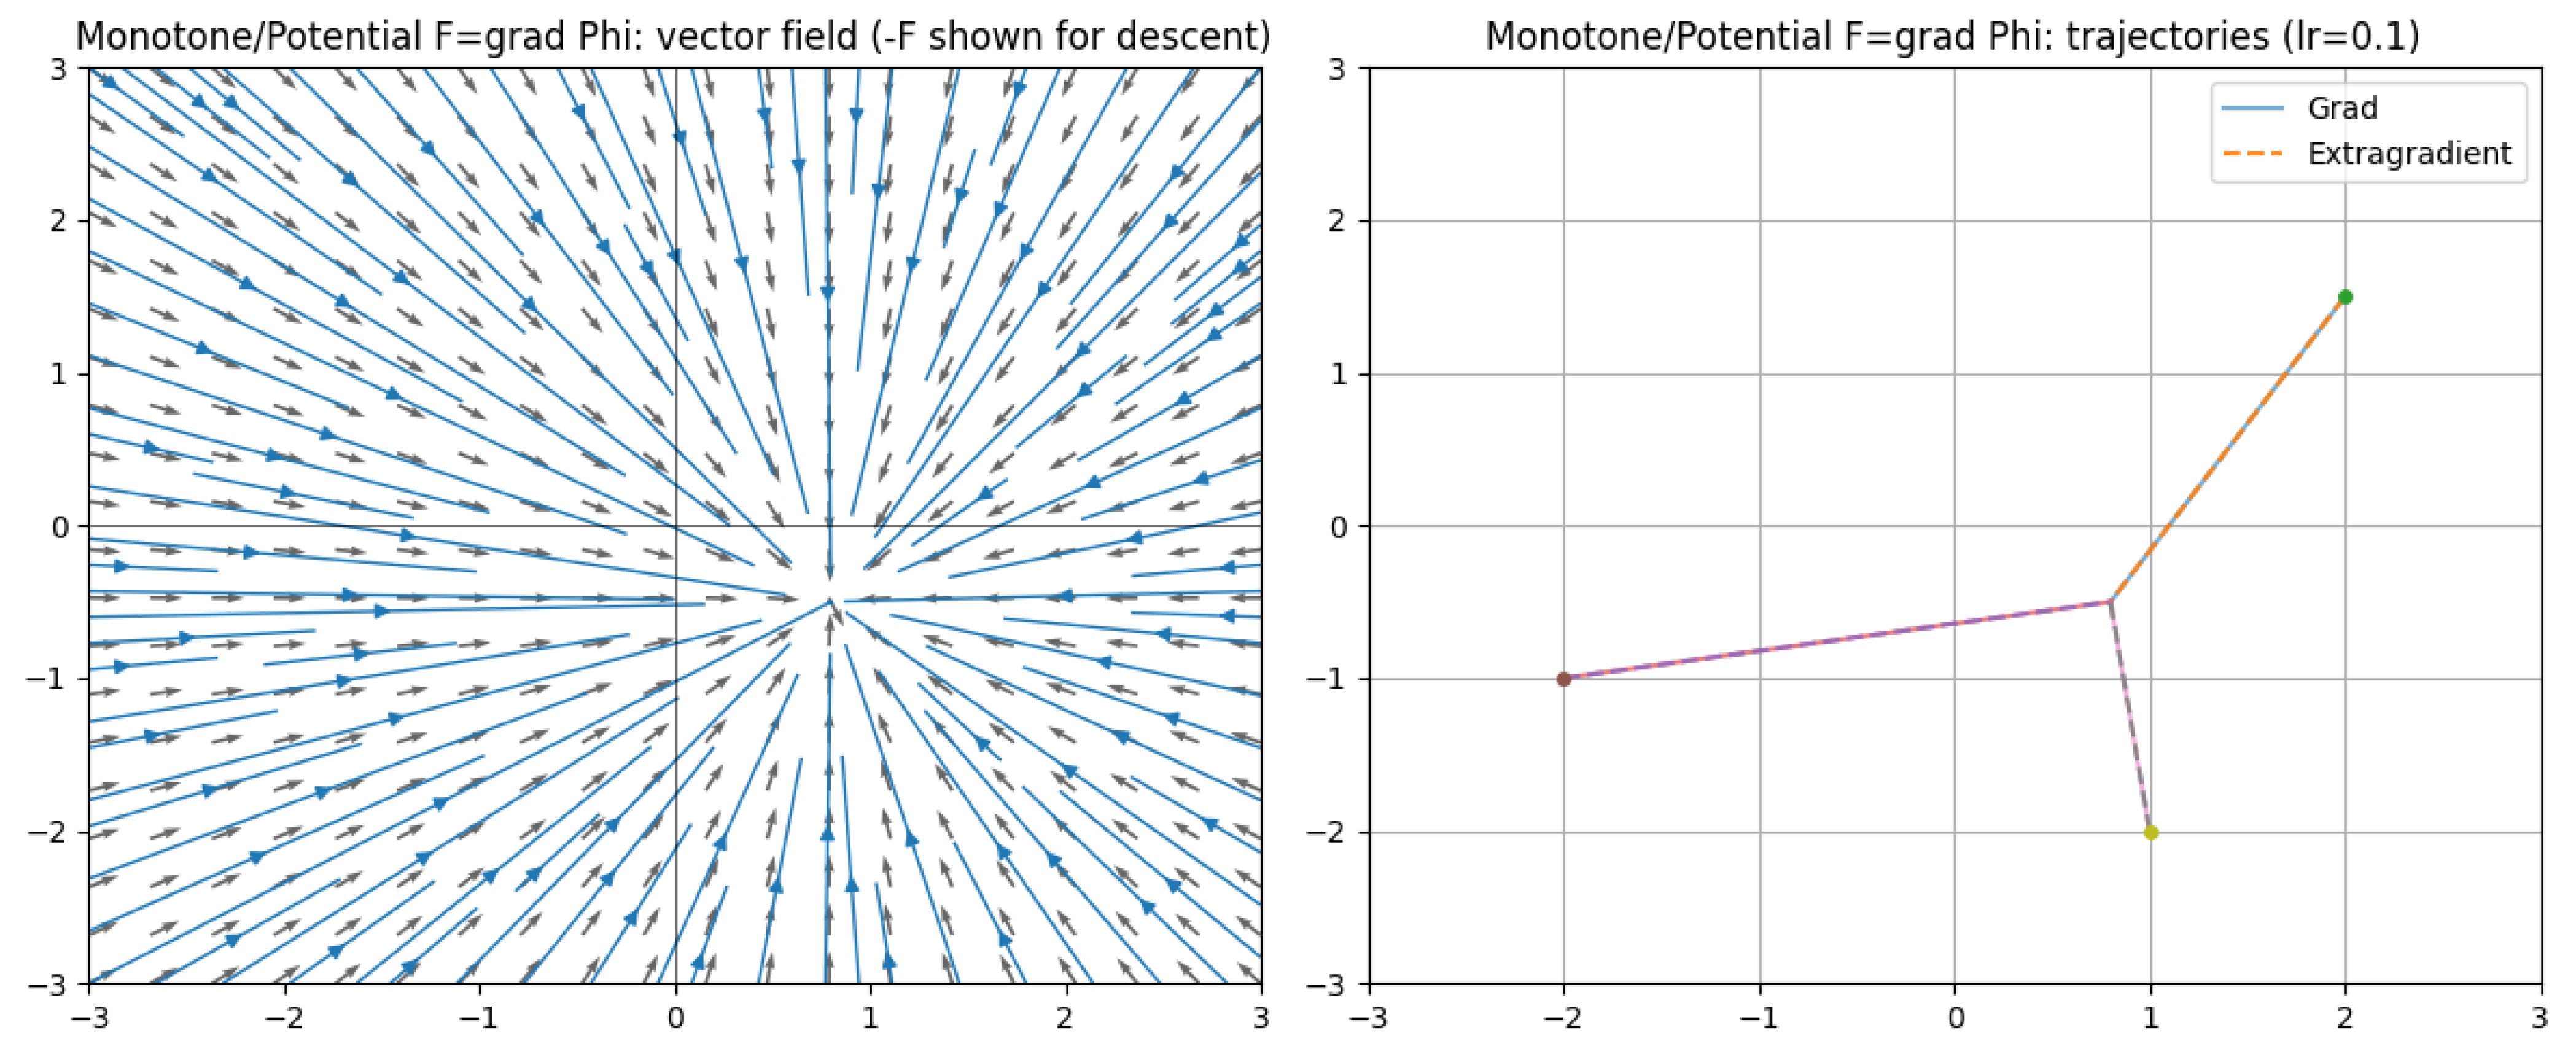
Figure 61.
Monotone case: Approx VI gap vs iteration
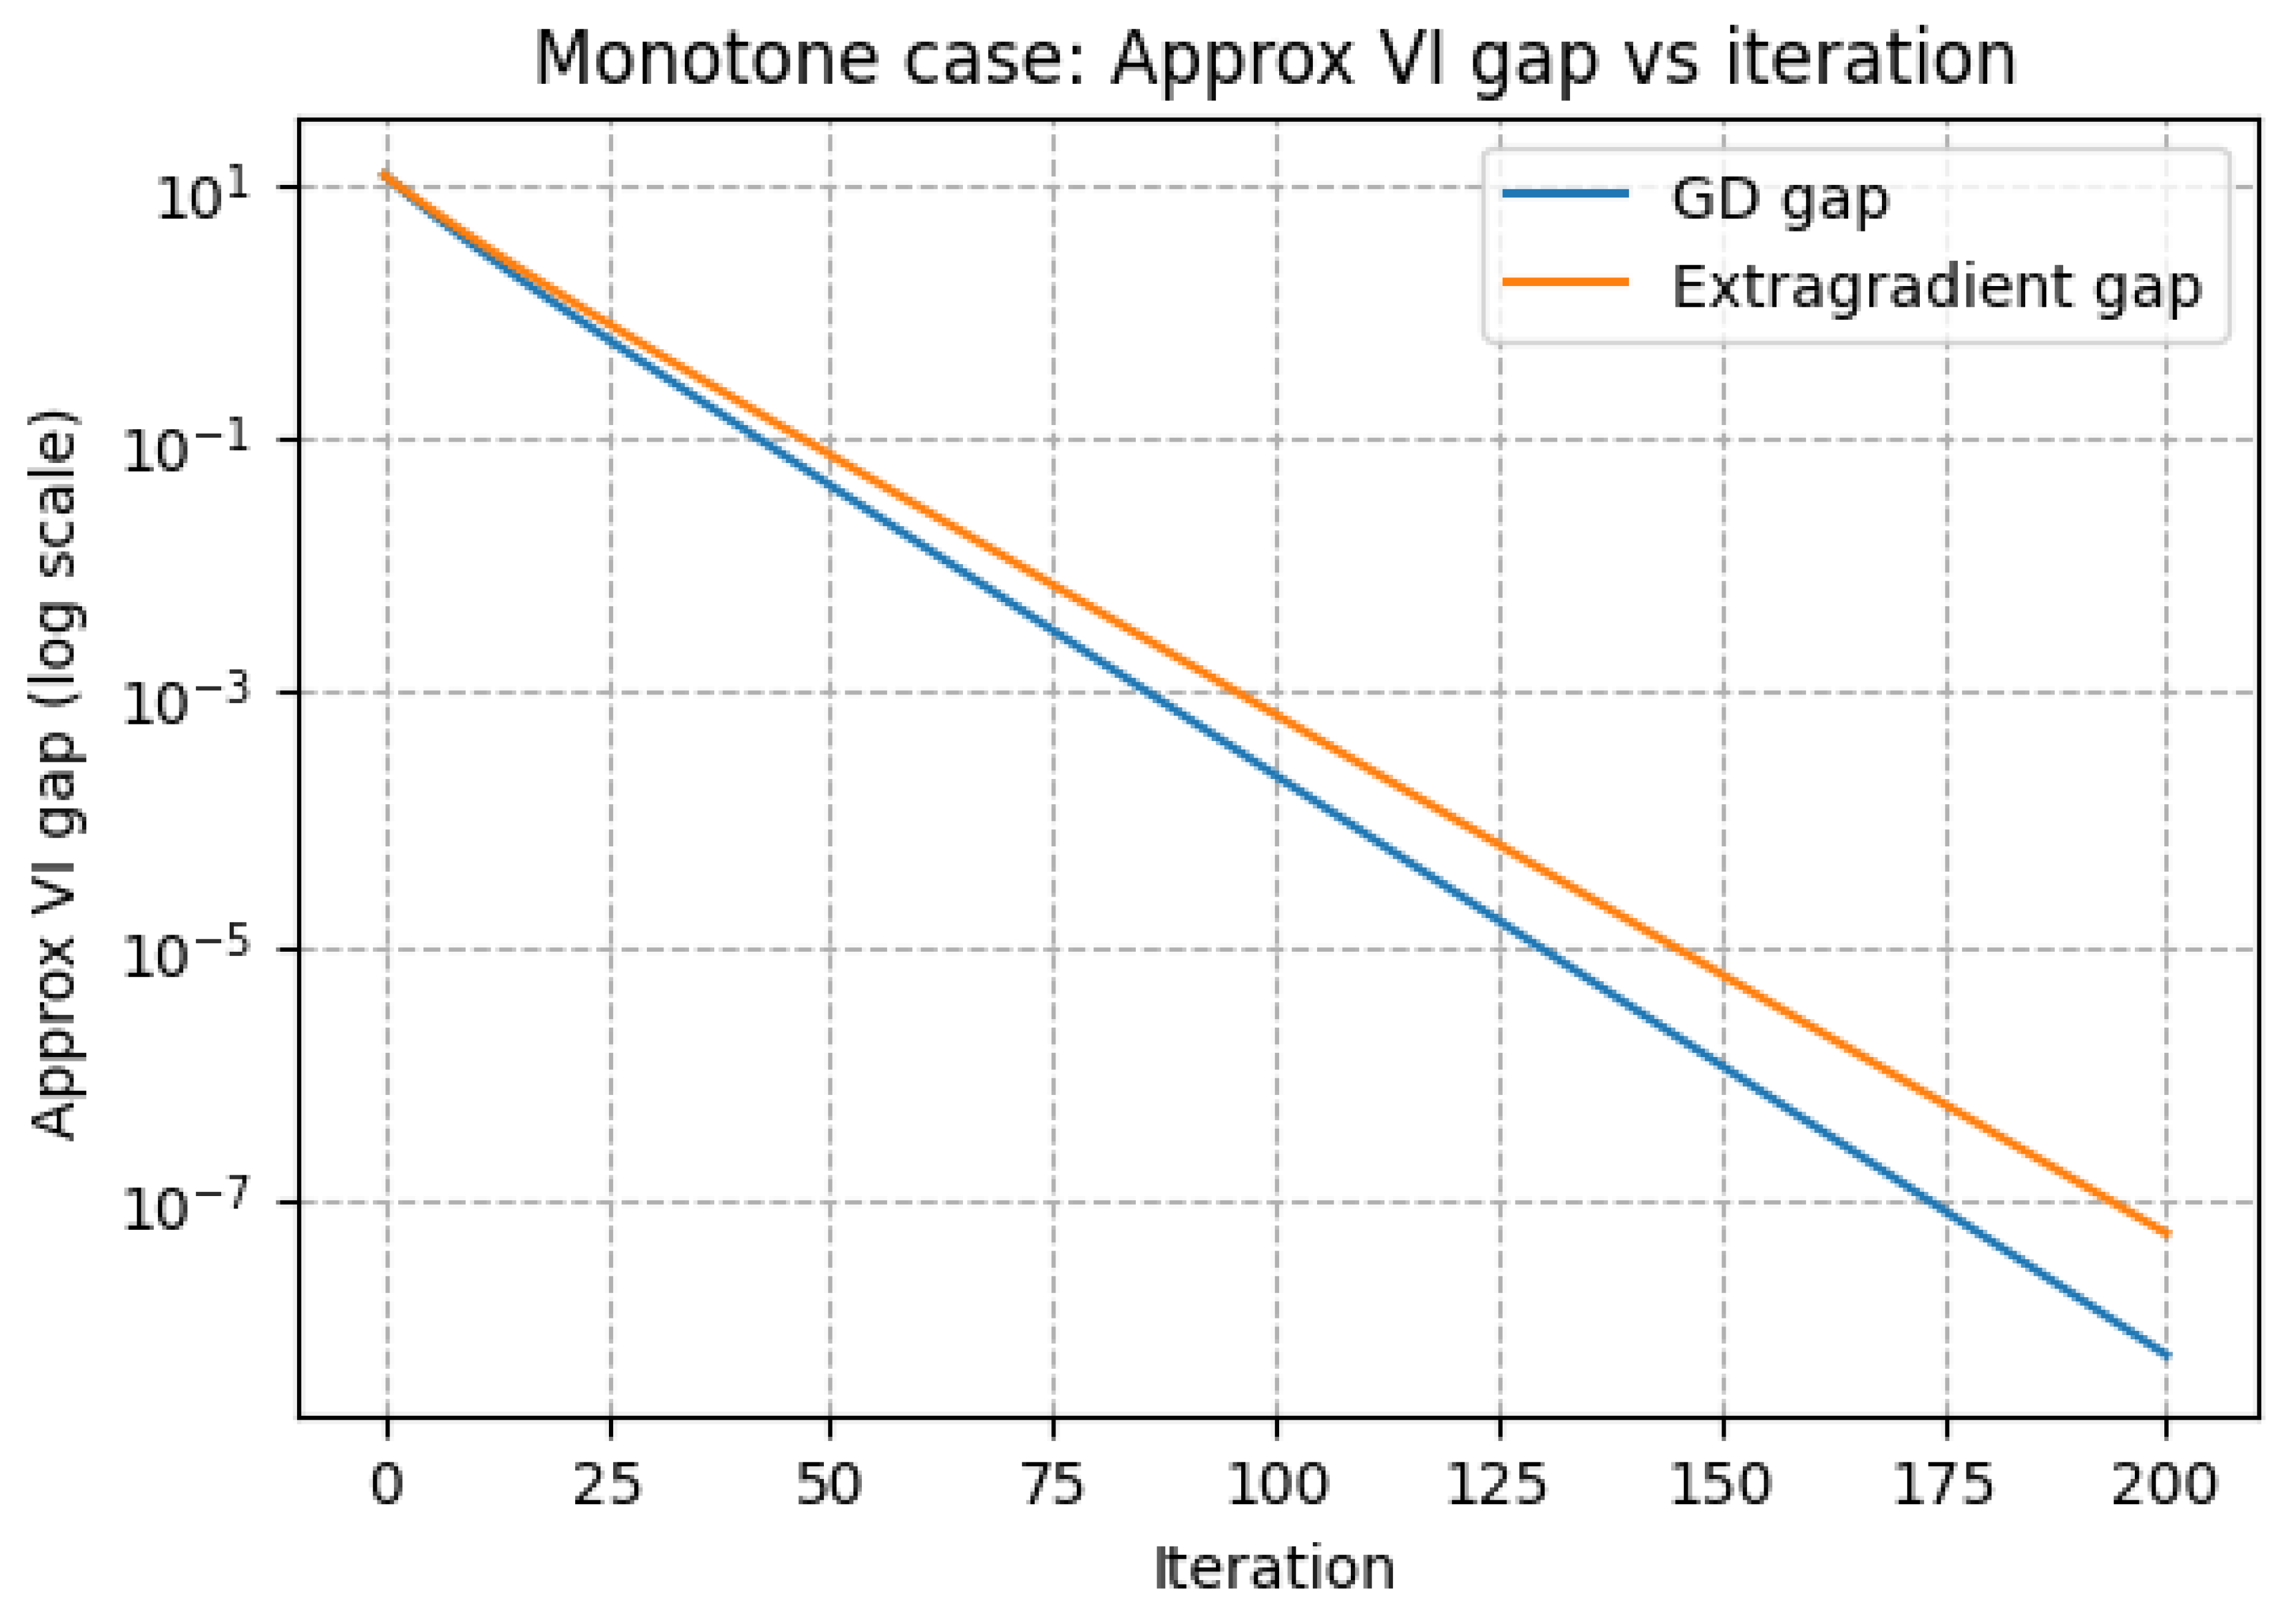
Figure 62.
Saddle Bilinear F (min-max)
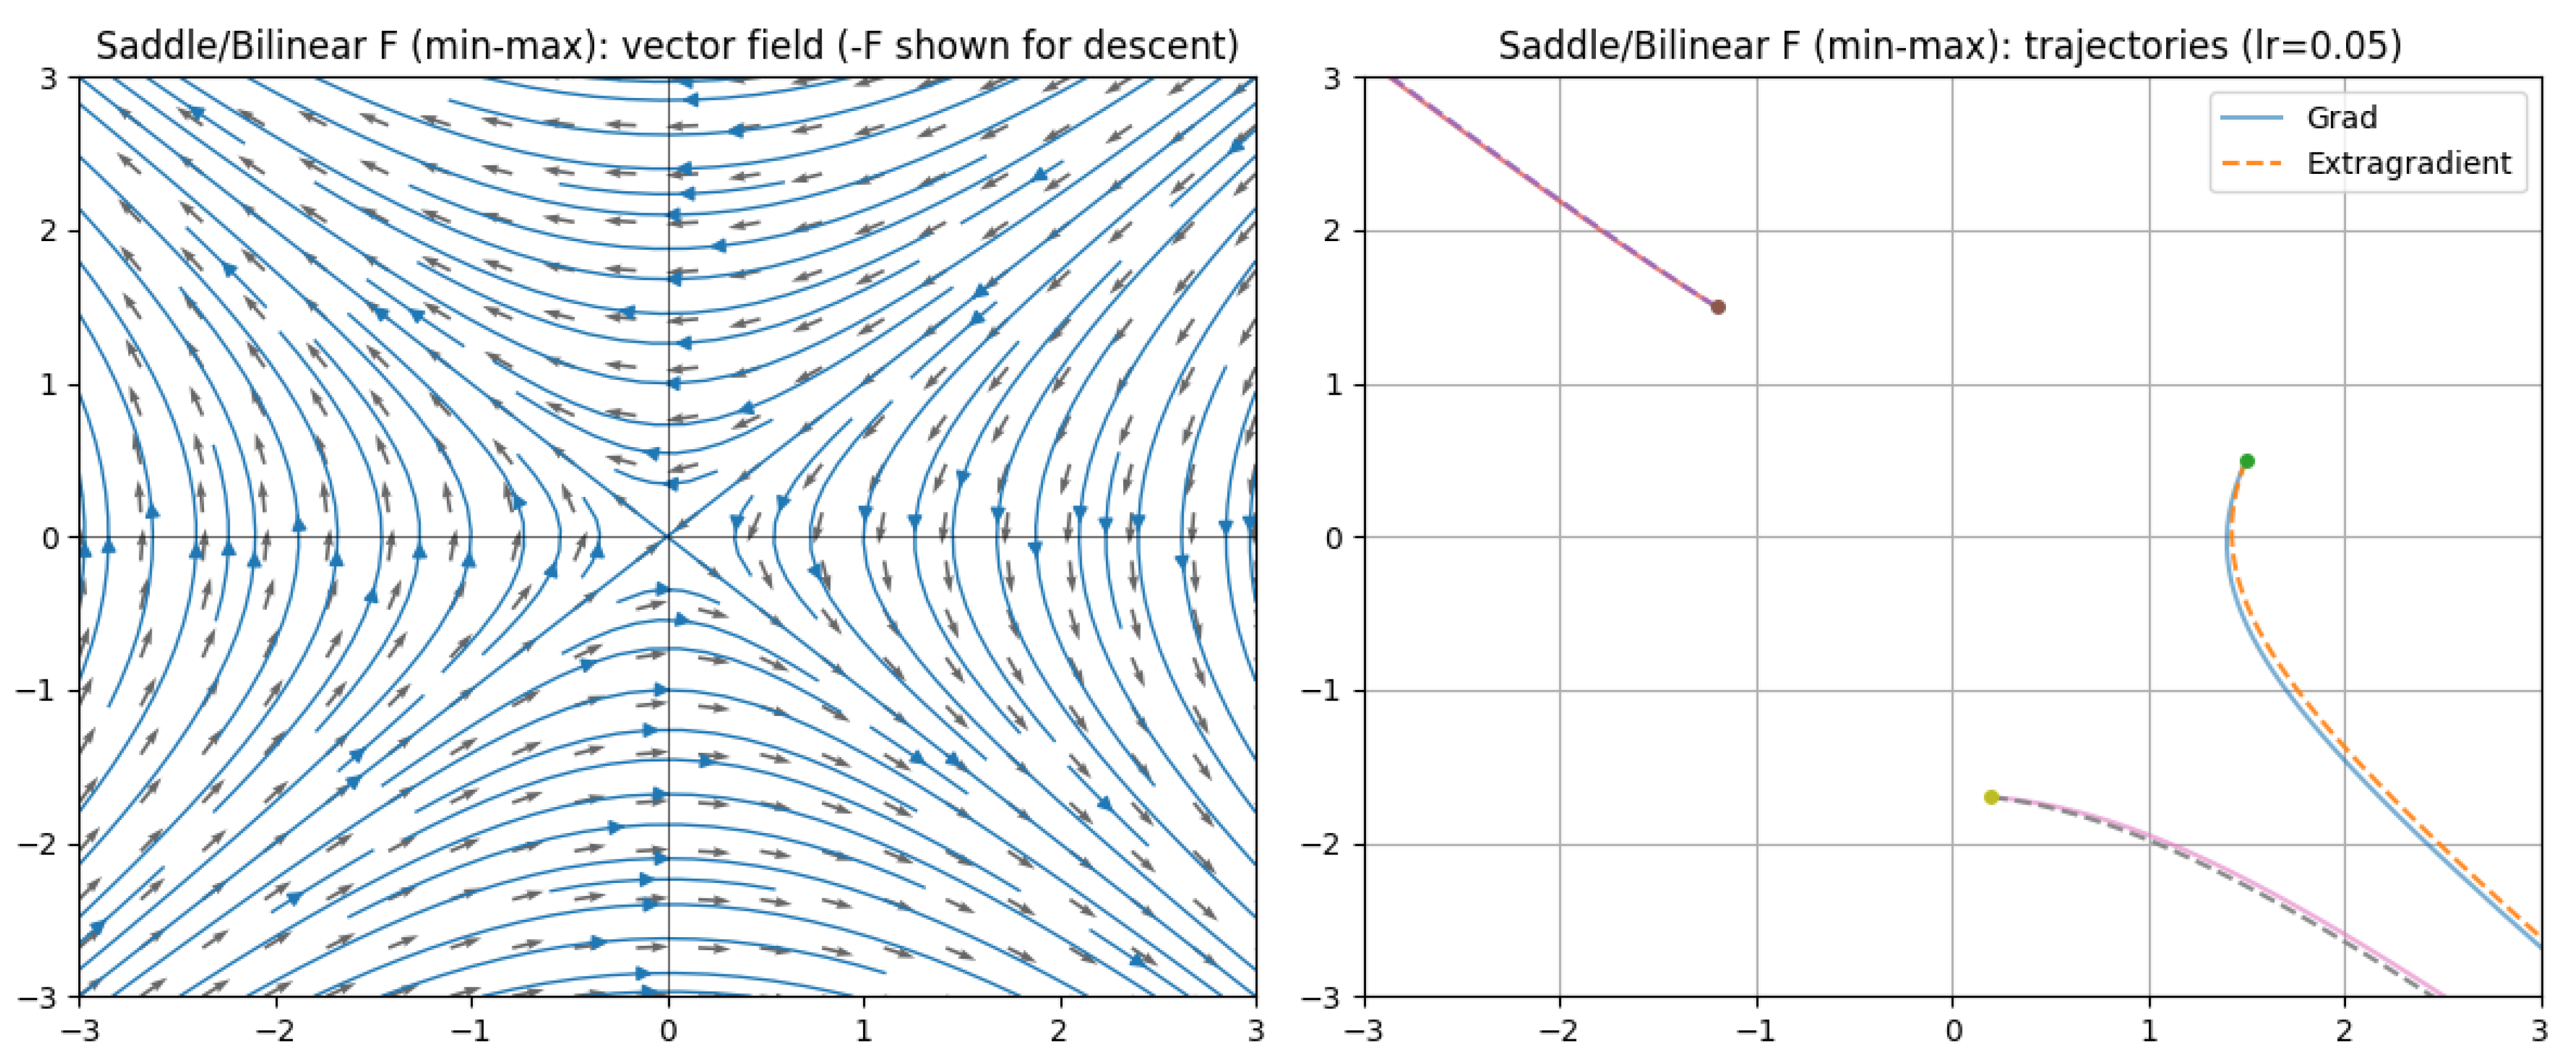
Figure 63.
Skew (rotation) F: R z
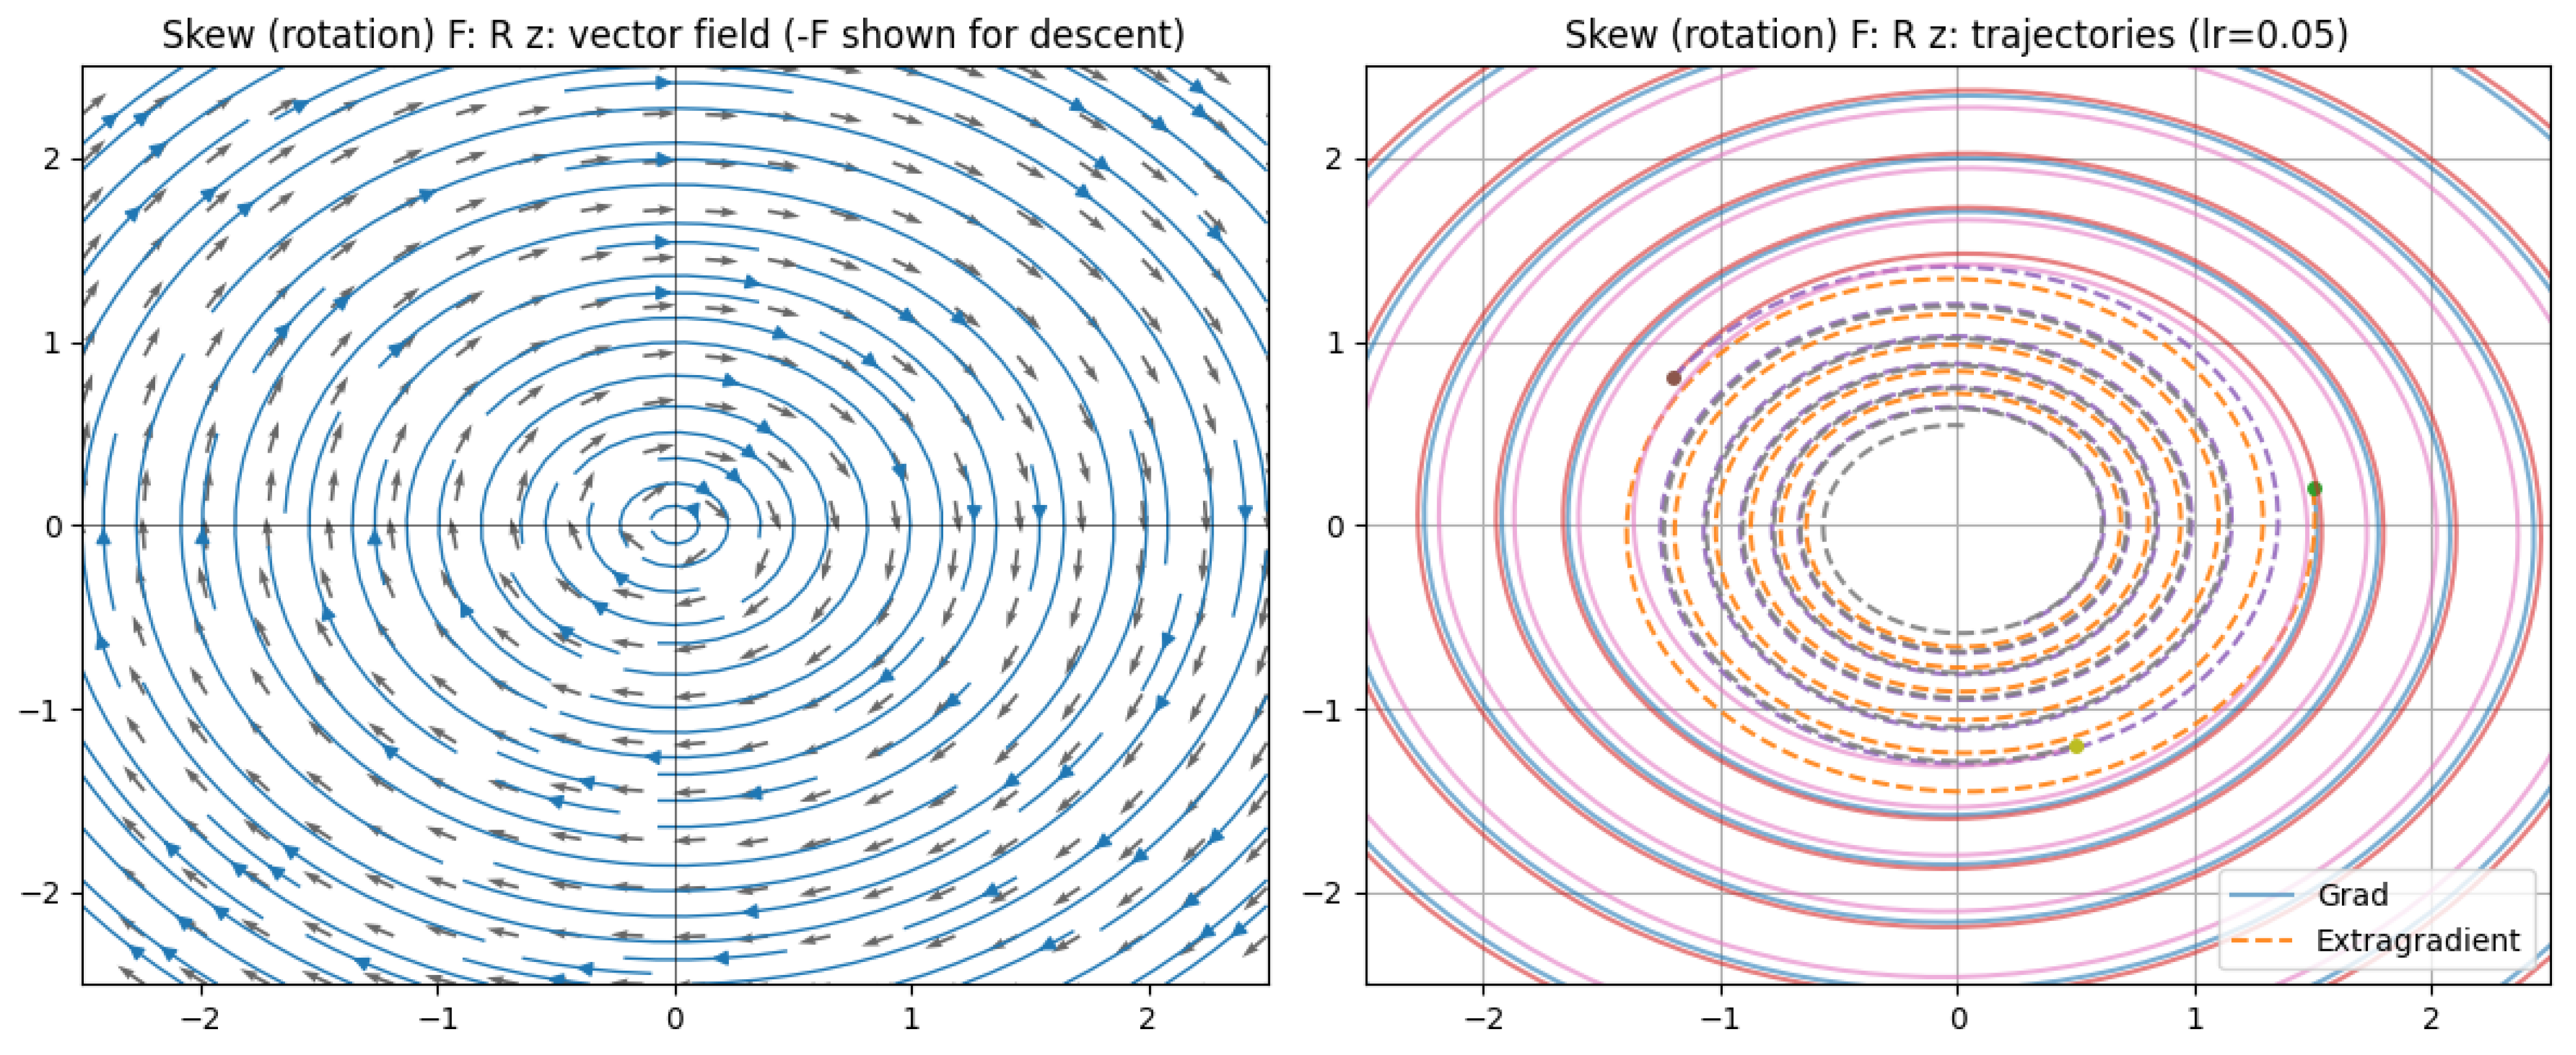
Figure 64.
Skew + Dissipation F: R + alpha I
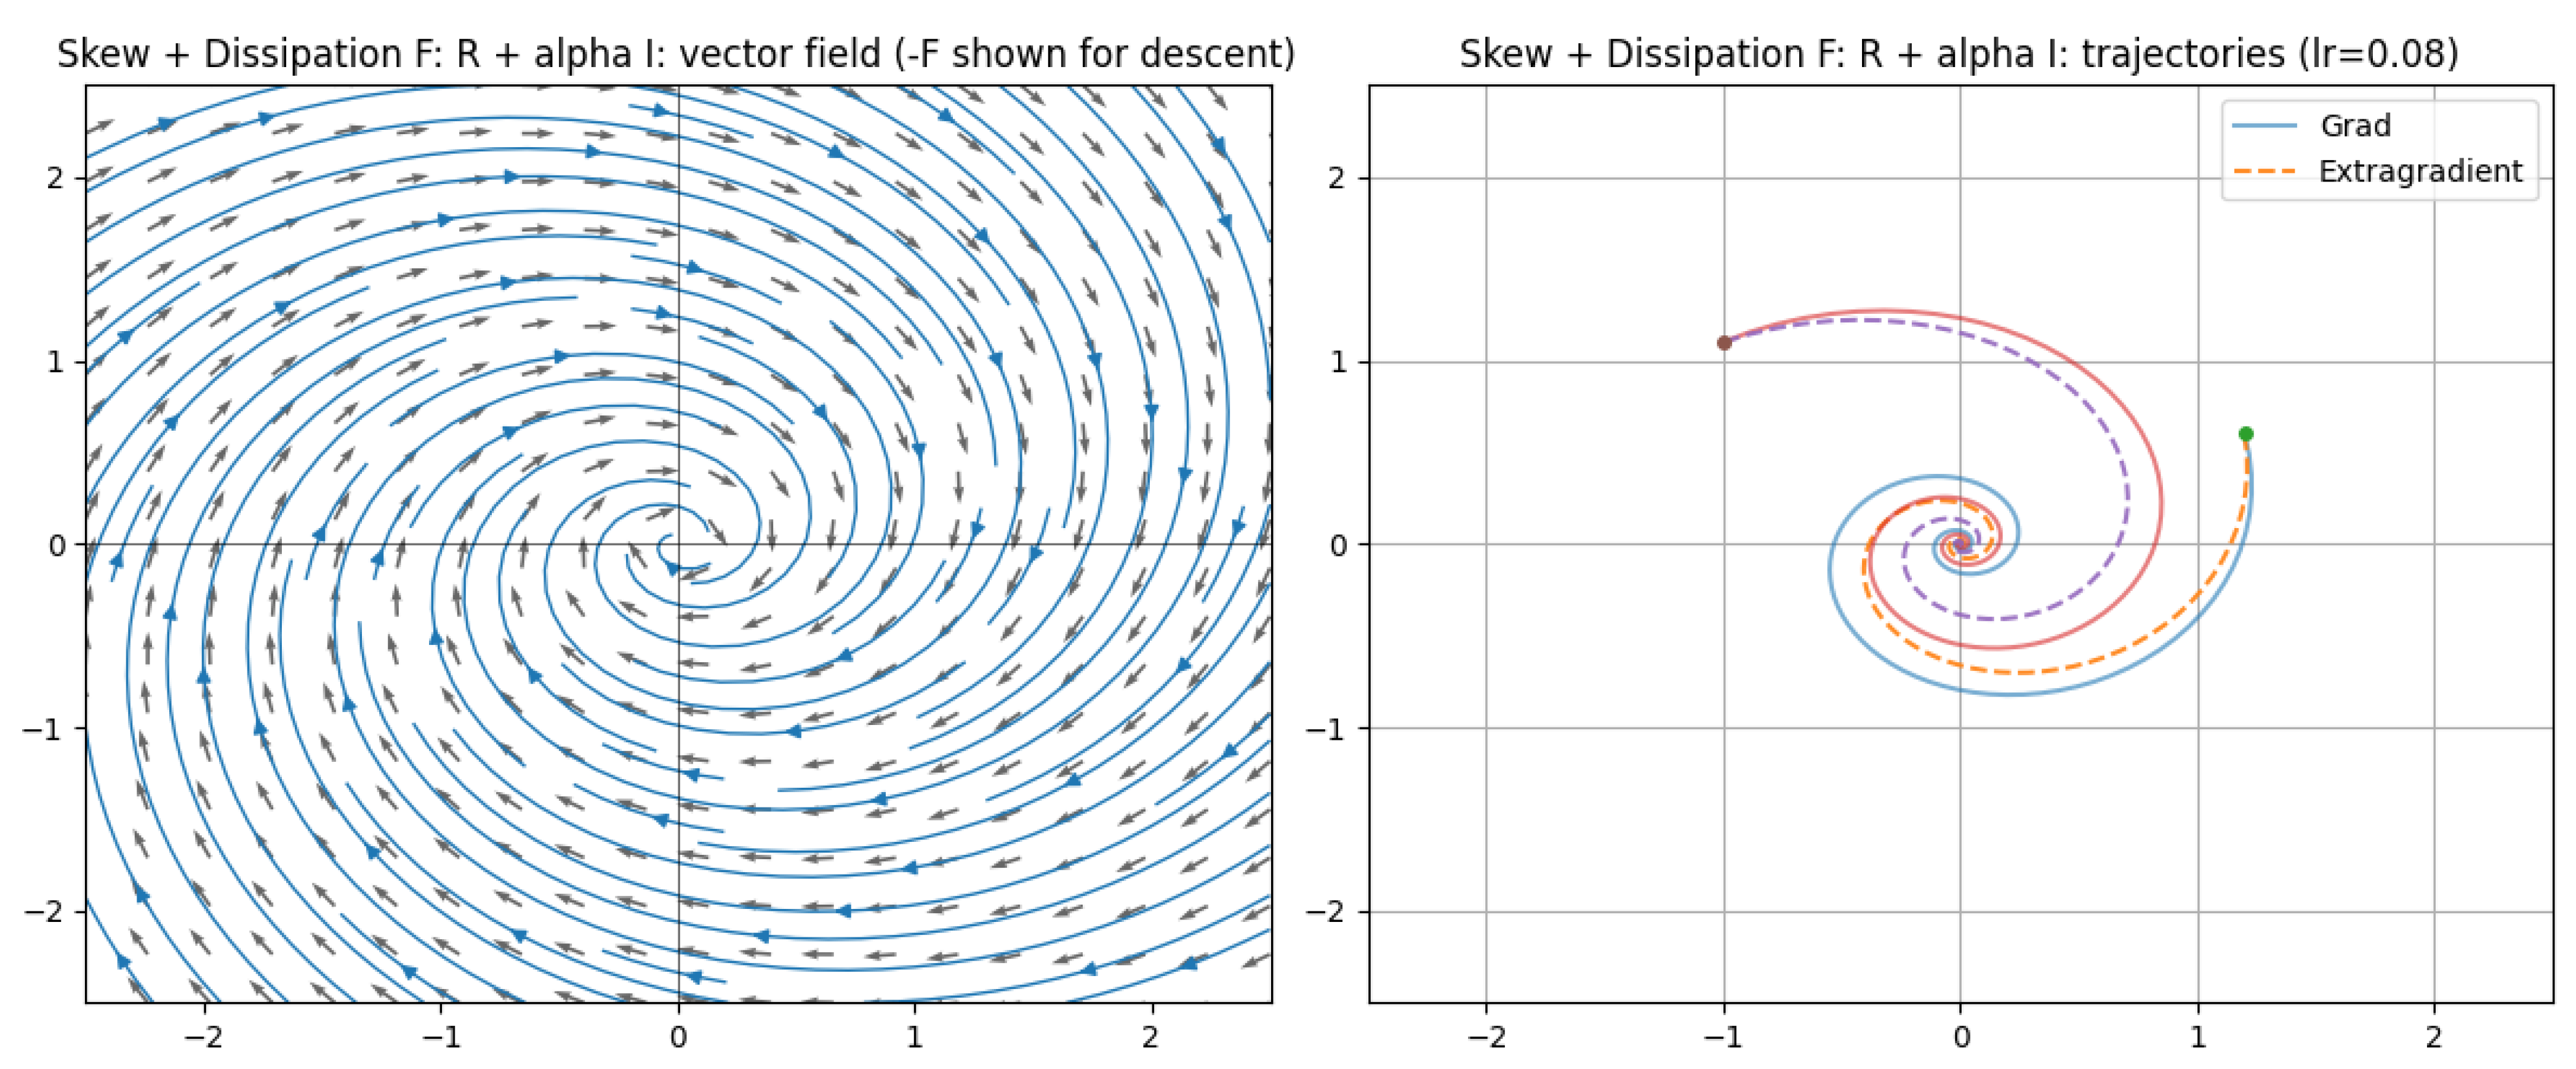
5.5. Optimal Control in Reinforcement Learning (RL)-Based Deep Neural Network (DNN) Training
Let represent the weight parameters of a deep neural network (DNN) at time step t. The evolution of these parameters over discrete time is governed by a controlled dynamical system, where the control input represents the weight update at each iteration. The fundamental objective of reinforcement learning (RL)-based DNN training is to determine an optimal control policy that minimizes a given performance criterion over a finite or infinite training horizon. The system dynamics are given by the equation
Let denote the cumulative loss function associated with a given control sequence , defined as
where is the instantaneous cost function. In the context of neural network training, the cost function is typically the empirical risk over a dataset , given by
where ℓ is a loss function such as cross-entropy or mean squared error, and represents the neural network’s output for an input x. The optimal control problem consists of finding a control sequence such that
Applying the principle of dynamic programming, the optimal cost-to-go function is defined recursively as
Expanding , the Bellman equation takes the form
Considering the continuous-time limit where the weight updates are infinitesimal, i.e., , we obtain the Hamilton-Jacobi-Bellman (HJB) equation
The optimal control satisfies
Alternatively, the problem can be analyzed using Pontryagin’s Maximum Principle. Define the Hamiltonian
where is the costate variable that evolves according to the adjoint equation
For optimality, the control must satisfy
Solving for , we obtain
In the reinforcement learning framework, the optimal control formulation is connected to policy optimization, where the policy determines the action given the state . The expected return under policy is given by
where is the reward function and is the discount factor. The policy gradient theorem states that
where is the state-action value function satisfying the Bellman equation
By applying the HJB equation, the optimal policy update rule is derived as
where is the learning rate, often adaptively adjusted based on second-order curvature information such as in natural gradient descent. More formally, using the Fisher information matrix , the optimal update rule can be written as
This establishes the link between optimal control and policy optimization in reinforcement learning, providing a rigorous theoretical foundation for RL-based DNN training.
5.5.1. Backpropagation as Pontryagin’s Maximum Principle (PMP)
We begin by formulating the supervised learning problem for a deep neural network as a discrete-time optimal control problem. Consider a network with L layers. Let the state represent the input to layer k, for . The initial state is the input data. The control variables are the parameters (weights and biases) of layer k. The state dynamics, which describe the forward propagation, are given by the equation
where is the activation function (e.g., a linear transformation followed by a non-linear element-wise function like ReLU or tanh). The objective of the training is to minimize a total cost function J that comprises a terminal cost and a running cost. The terminal cost is the loss function which measures the discrepancy between the final state (the network output) and the target label . The running cost can incorporate regularization terms on the controls, such as weight decay, leading to the full cost function
The optimal control problem is to find the sequence of controls that minimizes J subject to the dynamical constraints
Pontryagin’s Maximum Principle (PMP) provides necessary conditions for optimality for this class of problems. To apply PMP, we first define the Hamiltonian function for each stage k. The Hamiltonian is given by
where is the costate vector. The PMP states that for an optimal control sequence and the corresponding optimal state trajectory , there exists a corresponding costate trajectory satisfying the following canonical equations. The state evolution is given by the forward equation
which is identical to the network’s forward propagation. The costate evolution is governed by the backward equation
for . The boundary condition for the costate at the final time is determined by the terminal cost,
The maximization condition of PMP requires that the optimal control maximizes the Hamiltonian at every step along the optimal trajectory, that is,
for all admissible . For unconstrained controls, this often leads to the condition
which expands to
The connection to backpropagation emerges from the process of solving these necessary conditions. The standard method of successive approximation (MSA) involves a two-step iterative process. First, given a current control sequence , the state equation
is propagated forward from to to compute the state trajectory. Second, the costate equation
is propagated backward from to , initialized with
This backward pass is precisely the backpropagation algorithm. The vector is exactly the error signal, or the gradient of the loss with respect to the state , that is
The final step of MSA is to update the controls to satisfy the PMP maximization condition. For a simple case with no regularization, , the condition becomes
In practice, this condition is not enforced directly but is used to compute the gradient for a gradient-based optimizer. The gradient of the total cost J with respect to the control is given by
This is the same gradient computed by the backpropagation through time (BPTT) algorithm, where the term is the backward pass through the layer’s parameter Jacobian. Therefore, the backward pass of backpropagation is mathematically equivalent to the costate backward evolution of PMP, and the parameter gradient update is a single step (e.g., gradient ascent on the Hamiltonian) towards satisfying the PMP maximization condition. This rigorous mathematical correspondence reveals that the training of deep neural networks via gradient descent and backpropagation is an implementation of the Method of Successive Approximation for solving the necessary optimality conditions dictated by Pontryagin’s Maximum Principle.
5.5.2. The Method of Successive Approximation (MSA)
The Method of Successive Approximation (MSA) is a numerical algorithm for solving the necessary optimality conditions arising from Pontryagin’s Maximum Principle (PMP) for a discrete-time optimal control problem. In the context of training a deep neural network, the problem is formulated as minimizing a total cost
subject to the state dynamics
for , where is the input data, is the network output, is the target, are the parameters of layer k, and is a regularization function. The Hamiltonian for this system is defined as
where is the costate variable. The PMP provides the necessary conditions for optimality: the state equation
the costate equation
with the boundary condition
and the maximization condition
for all admissible , which for unconstrained, differentiable problems implies the stationarity condition
or explicitly
The MSA algorithm iteratively refines a sequence of control policies to satisfy these conditions. Given an initial guess for the control sequence for , the i-th iteration of MSA consists of two sequential passes. The first pass is the forward state propagation, which computes the state trajectory corresponding to the current control guess . This is executed by initializing with the input data and recursively applying the dynamics
for to . This forward pass is identical to a forward propagation through the neural network using the current parameters. The second pass is the backward costate propagation, which computes the costate trajectory using the computed states and controls . This pass is initialized with the gradient of the terminal loss
and proceeds backwards recursively using the costate equation
for . This backward pass is mathematically equivalent to the backpropagation algorithm, as the costate represents the negative gradient of the total cost with respect to the state,
The third and final step of the MSA iteration is the control update, which aims to satisfy the PMP maximization condition. A new control sequence is computed to maximize the Hamiltonian given the newly computed states and costates . The update is performed pointwise for each k by solving
For the common case where the dynamics are differentiable with respect to and the regularization is convex, the maximization condition leads to the implicit equation
which expands to
Solving this equation exactly for is often computationally intractable. Instead, a common approximation is to perform a single gradient ascent step on the Hamiltonian with respect to the control. This involves computing the gradient
and then updating the controls as
where is a learning rate. Crucially, the gradient is precisely the negative of the gradient required to minimize the total cost J, since
when the state and costate equations are satisfied. Therefore, the control update
is recovered, which is the standard gradient descent update used in backpropagation-based training. Thus, the MSA algorithm, with a single gradient step for the control update, is mathematically equivalent to the training of a deep neural network via forward propagation, backpropagation of errors, and a gradient descent step on the parameters, providing a rigorous optimal control interpretation of the entire learning process. The iteration continues until a convergence criterion on the control sequence or the total cost is met, yielding a solution that approximates the PMP necessary conditions.
5.5.3. Differentiable Optimization Layers
Differentiable Optimization Layers represent a profound integration of mathematical optimization into the fabric of deep neural networks, where the output of a layer is defined as the solution to a constrained optimization problem. The forward pass of such a layer, at a given depth k, computes the state by solving a parameterized problem:
where is a cost function internal to the layer, is a constraint set defined by parameters (the previous state) and (the layer’s control parameters or weights), and is the optimization variable. This formulation generalizes standard layers; for example, a linear layer followed by a ReLU activation can be interpreted as solving a quadratic program with non-negativity constraints. The primary challenge lies in differentiating through this argmin operation to compute the Jacobians and required for the backward pass during training. This is not a standard application of the chain rule because the mapping from parameters to solution is implicitly defined by the optimality conditions of the optimization problem.
The rigorous treatment of backpropagation through these layers relies on the implicit function theorem applied to the Karush-Kuhn-Tucker (KKT) conditions. For a convex optimization problem with inequality constraints, the Lagrangian is
where represents the inequality constraints, represents the equality constraints, and , are the dual variables. The KKT optimality conditions, which must hold at the solution , are stationarity:
primal feasibility:
dual feasibility:
and complementary slackness:
where ⊙ denotes the Hadamard product. The implicit function theorem states that if the Jacobian of the system of equations formed by the stationarity and active constraints with respect to the primal and dual variables is invertible at the solution, then the solution and the active dual variables are differentiable functions of the parameters .
To compute the necessary gradients for the backward pass, we consider the total derivative of the loss function ℓ with respect to the parameters. Let be the incoming gradient from the subsequent layer, which is the negative costate from the PMP viewpoint. The goal is to compute
and
Differentiating the system of KKT conditions that hold at the optimum with respect to the parameters provides a linear system to solve for these Jacobians. Let represent the concatenated vector of the primal variable and the dual variables for the active constraints (where is the set of indices for which and ). The active KKT conditions form a system
which includes the stationarity condition and the active equality constraints
The total derivative is
which yields
The Jacobian is the KKT matrix at the optimum. The desired Jacobian is a block of .
A more efficient and direct method, which avoids explicitly forming and inverting the full KKT matrix, involves solving a linear system that yields the gradient directly. The differential of the stationarity condition is
where and . Expanding this differential with respect to perturbations , , and the resulting changes , , gives:
where
is the Hessian of the Lagrangian with respect to . Simultaneously, the differentials of the active constraints must be zero:
and
This can be written as a linear system:
To compute the vector-Jacobian product , one sets to be the identity in the direction of interest and solves the adjoint of this system. The standard approach is to solve for the adjoint variables such that:
The solution to this adjoint system then gives the desired gradient with respect to the previous state:
An analogous procedure, solving a similar adjoint system but with the right-hand side terms derived from differentiation with respect to , yields the gradient . This formalism provides a complete and rigorous mechanism for embedding optimization problems as differentiable layers within a deep network, allowing for end-to-end training using gradient-based methods while maintaining a direct interpretation as an optimal control step within the network’s dynamics.
5.5.4. Neural Ordinary Differential Equations (Neural ODEs)
Neural Ordinary Differential Equations (Neural ODEs) formulate the forward propagation through a deep neural network as the solution to a continuous-time dynamical system defined by an ordinary differential equation. The state of the network, represented by a vector , evolves from an initial time to a final time according to the differential equation
where is a function parameterized by the network weights , and the initial condition is the input data . The output of the network is the state at the terminal time, . This formulation generalizes residual networks, where each layer performs an update
to the continuous limit as the number of layers approaches infinity and the step size approaches zero. The fundamental problem of training such a network is an optimal control problem, where the goal is to find the control parameters that minimize a loss function subject to the dynamical constraint of the ODE. The cost functional is
where is a running cost, often a regularization term on the weights or the state.
The necessary conditions for optimality are derived from the calculus of variations and Pontryagin’s Maximum Principle in continuous time. The Hamiltonian for this system is defined as
where is the costate variable. The PMP states that for an optimal control and the corresponding optimal state trajectory , there exists a costate trajectory satisfying the canonical equations. The state equation is the forward ODE:
The costate equation is the backward ODE:
with the terminal boundary condition
The optimality condition for the control requires that the Hamiltonian is maximized, leading to
for all .
The central innovation for training Neural ODEs is the adjoint sensitivity method, which provides a memory-efficient way to compute the gradient of the loss with respect to the parameters, , by solving a backward ODE. The adjoint state is defined as , which is exactly the negative of the costate, . Its dynamics are derived by differentiating the loss with respect to time. Consider the total derivative
However, ℓ is a constant function of t, so . A more rigorous derivation considers the gradient
from the PMP and constructs an augmented state
whose dynamics can be computed backwards. The definitive result is that the adjoint state satisfies the differential equation
with the initial condition
To compute the total gradient , an auxiliary variable is introduced, which evolves as
with . The total gradient is then
In practice, the forward pass is performed by numerically integrating the ODE
from to using an ODE solver to obtain the final state and the loss . The backward pass does not require storing the intermediate states of the forward pass. Instead, the combined adjoint system is solved backwards in time from to . The system to be solved is defined for the augmented state
and its dynamics are given by:
The initial conditions for this backward integration are
and
Crucially, to compute the right-hand side of this adjoint ODE, the state trajectory is required. It can be recomputed backwards from by solving the original ODE backwards, or more efficiently, it can be reconstructed during the backward pass if a reversible ODE solver is used, or by using a continuous-time checkpoints and interpolation based on the solver’s internal steps. The final value provides the necessary gradient for updating the parameters via gradient descent. This entire procedure, where the backward pass is computed by solving a differential equation, is a direct and rigorous implementation of the continuous-time PMP, establishing Neural ODE training as a canonical example of optimal control in deep learning. The absence of a discrete computational graph for backpropagation allows for adaptive computation and constant memory cost relative to depth, as the memory requirement is instead of for a network with L layers.
5.5.5. Stochastic Optimal Control for RL and Robust Training
Stochastic Optimal Control provides the foundational framework for Reinforcement Learning by considering dynamical systems governed by stochastic differential equations or Markov Decision Processes, where the state evolution incorporates inherent uncertainty. The continuous-time formulation models the state dynamics as
where is the state, is the control, is a standard Wiener process representing Brownian motion, and is the diffusion matrix. The objective is to find a control policy that minimizes the expected cost
where is the terminal cost and is the running cost. The fundamental equation of stochastic optimal control is the Hamilton-Jacobi-Bellman equation, a nonlinear partial differential equation for the optimal value function
The HJB equation is derived via the dynamic programming principle and Itô’s lemma, yielding
with the terminal condition . The term is the second-order differential operator arising from the variance of the Brownian motion, which is absent in deterministic control.
The connection to Reinforcement Learning emerges from the discrete-time, finite-horizon formulation known as a Markov Decision Process, defined by the tuple , where is the state space, is the action space, is the transition probability kernel, is the reward function, and is the discount factor. The objective is to maximize the expected discounted return
The optimal value function
satisfies the discrete-time HJB equation, known as the Bellman optimality equation:
Similarly, the optimal state-action value function
provides the basis for Q-learning algorithms. Policy iteration and value iteration are dynamic programming algorithms that solve these equations, and when the state and action spaces are large, deep neural networks are used as function approximators, leading to Deep RL. The parameters of a value network or a policy network are trained to minimize the Bellman error
or to maximize the expected return
using the policy gradient theorem
For robust training of deep neural networks in supervised learning, the problem is framed as a minimax game or a robust optimal control problem where the controller must perform well under worst-case perturbations. Given a training dataset , the dynamics of a deterministic network are
and the objective is to minimize the loss . In the presence of adversarial perturbations applied to the input or intermediate features, the robust training problem is
where is a bounded set of admissible perturbations, such as . This can be viewed as a zero-sum dynamic game where nature chooses the worst-case disturbance. The Hamiltonian for this robust control problem incorporates the disturbance
and the robust optimality conditions involve a maximization over the disturbance followed by a minimization over the control. Solving the inner maximization exactly is often intractable, leading to approximations like Projected Gradient Descent to find adversarial examples
which are then used in training, a method known as Adversarial Training.
A more formal approach uses stochastic control theory with uncertain dynamics. The dynamics are modeled as
where is a random noise vector. The goal is to find a control policy that minimizes the expected loss while being robust to the noise distribution. This leads to risk-sensitive optimal control, which optimizes a risk-measure of the cost, such as the exponential utility
where is a risk-aversion parameter. Using the Taylor expansion
it is clear this penalizes high variance in the loss. The Path Integral Control framework provides a solution for a specific class of stochastic problems where the dynamics are affine in the control and the cost is quadratic in the control. For a system with dynamics
and cost
the HJB equation can be linearized via a logarithmic transformation
leading to a linear PDE for . The optimal control is then given by
which can be estimated by sampling trajectories, forming the basis of the Model Predictive Path Integral (MPPI) control algorithm used in RL for policy improvement. This direct sampling-based approach bypasses the need for value function approximation and is highly suitable for complex, high-dimensional problems where DNNs represent the policy.
5.5.6. Stable and Efficient Network Design
The design of stable and efficient neural networks from an optimal control perspective necessitates the enforcement of structural constraints on the network’s dynamics to guarantee desirable properties such as Lyapunov stability, passivity, or contractivity, which in turn ensure robustness to input perturbations and prevent exploding gradients during training. Consider the discrete-time dynamical system representation of a neural network
where is the state and are the parameters. A fundamental stability concept is that of a contraction mapping, which requires the existence of a matrix measure such that the Lipschitz constant of each layer is strictly less than one, , ensuring that the distance between any two trajectories contracts over time. A more general and powerful framework is provided by Lyapunov theory. A Lyapunov function for the autonomous system
must satisfy for all and , and the condition
for some , guaranteeing global exponential stability of the equilibrium point. To design layers that inherently satisfy such properties, one can parameterize the layer as the solution to a constrained optimization problem or as the forward Euler discretization of a continuous-time system with known stability properties.
A prominent approach is to design layers that are nonexpansive, meaning they are 1-Lipschitz continuous
for all which prevents the amplification of input perturbations and gradient norms. This can be achieved by constraining the weights to be orthogonal or using spectral normalization, which enforces
where denotes the maximum singular value. A more rigorous method involves modeling the network as the discretization of a continuous-time Ordinary Differential Equation
and ensuring the continuous dynamics are contractive. A nonlinear system is contractive if there exists a uniformly positive definite metric
such that the generalized Jacobian
is uniformly negative definite, i.e.,
for some . A sufficient condition for contractivity in the identity metric is that the symmetric part of the Jacobian is uniformly negative definite
This insight leads to the design of stable continuous-time blocks, such as
where is a monotone activation function, which can be shown to be contracting under certain conditions on .
The training of such stable architectures can be framed as an optimal control problem with stability constraints. The objective is to minimize the loss
subject to the dynamics
and the algebraic stability constraints , where encodes constraints like spectral norm bounds. The Lagrangian for this constrained optimization is
where are the Lagrange multipliers for the stability constraints. The necessary conditions from the Karush-Kuhn-Tucker theorem include the state equation
the costate equation
with
and the stationarity condition with respect to the controls
complemented by the complementary slackness conditions
In practice, the stability constraints are often enforced via projected gradient descent or by reparameterizing the weights. For example, one can parameterize a weight matrix as
where has its spectral norm constrained to 1 via iterative power methods, and is a trainable scalar, ensuring
For recurrent networks and those with skip connections, more advanced concepts from robust control, such as the use of Linear Matrix Inequalities (LMIs), are required to guarantee stability. Consider a system with uncertain or time-varying parameters,
where , a bounded uncertainty set. The system is quadratically stable if there exists a matrix such that the LMI
holds for all . This can be extended to nonlinear systems via sector bounds on the activation functions. Let be a slope-restricted activation function in the sector , meaning
for all . A network layer
can be analyzed using the discrete-time version of the Kalman-Yakubovich-Popov lemma. Stability can be certified by finding a diagonal positive definite matrix and a matrix such that the following LMI is feasible:
Training a network to satisfy such LMIs during optimization is challenging but can be approximated by incorporating a regularization term that penalizes the violation of the stability condition, leading to a robust and stable network architecture whose training dynamics are themselves well-behaved, mitigating issues like vanishing and exploding gradients and enhancing generalization performance by enforcing a smooth input-output map. The integration of these control-theoretic stability constraints directly into the architecture and the training loop represents a principled approach to designing deep neural networks with predictable and reliable behavior, which is paramount for their deployment in safety-critical reinforcement learning applications.
5.5.7. Optimal Control of the Training Process Itself
The optimal control of the training process itself constitutes a meta-optimization problem where the parameters of the learning algorithm, such as the learning rate, momentum coefficients, or even the entire update rule, become the control variables in a higher-level dynamical system whose state is the entire set of model parameters and optimizer states. Let represent the parameters of the deep neural network at optimization step t, and let represent the state of the optimizer, which may include momentum vectors , variance estimates , and other auxiliary variables. The combined state is
The update rule of the optimizer defines the dynamics of this meta-system. For a generic optimizer, the dynamics can be expressed as
where is a vector of hyperparameters (e.g., learning rate, momentum decay factor) acting as the control signal, and
is the stochastic gradient computed on a minibatch at step t. The fundamental challenge is that the gradient is not an exogenous input but a function of the state and the data distribution, making the system a closed-loop feedback system with stochastic disturbances.
The objective of the meta-optimization is to find a hyperparameter policy
that minimizes the expected total loss over a horizon T, which is
where is a discount factor. This is a classic stochastic optimal control problem. The corresponding Bellman equation for the optimal meta-value function is
where the expectation is over the stochasticity in the gradient . The optimal hyperparameter control is then
Solving this exactly is intractable, but it provides a formal framework for gradient-based hyperparameter optimization. By considering the hyperparameters as fixed over a horizon, one can compute the hypergradient to perform meta-descent. This involves differentiating through the optimization process. The dynamics for a simple gradient descent optimizer are
The hypergradient for a horizon of one step is trivial:
For a longer horizon T, the hypergradient requires backpropagation through the entire training trajectory (through-time), given by
where
and
is the Hessian at step k, and
This product of Hessians is computationally prohibitive and numerically unstable, leading to approximations such as ignoring the higher-order terms and using the approximation
For more complex optimizers like Momentum or Adam, the state and its dynamics become crucial. The momentum optimizer has states and dynamics
where the controls are . The hypergradient for the learning rate involves differentiating through these dynamics:
where
This creates a recurrent system for the hypergradient that mirrors the parameter update itself. The Adam optimizer introduces further complexity with states , and dynamics
where the division and square root are element-wise. Differentiating through this requires careful application of the chain rule, and the hypergradients for , , and can be computed recursively, albeit with significant memory and computational cost if done exactly through a long horizon.
A more general and rigorous approach formulates this as a continuous-time optimal control problem for the training trajectory. The parameters evolve during training "time" according to the optimizer’s ODE, such as
for gradient flow. The meta-control problem is to find the time-varying learning rate that minimizes
The Hamiltonian for this meta-problem is
where is the meta-costate. The meta-costate equation is
with the terminal condition . The optimality condition for the control is
implying that the optimal learning rate is chosen such that the meta-costate is orthogonal to the gradient. This continuous-time formulation elegantly captures the trade-off: the term in the costate dynamics represents the interaction between the learning rate and the curvature of the loss landscape, guiding how should be adjusted to navigate sharp minima and flat regions effectively. This rigorous optimal control perspective provides a unifying theoretical foundation for understanding and designing adaptive learning rate schedules and other meta-optimization strategies, framing the entire training procedure of a deep neural network as a single, coherent control problem over the space of parameters.
5.5.8. Connections to Reinforcement Learning
The connections between optimal control and reinforcement learning are foundational and profound, with RL being essentially a framework for solving stochastic optimal control problems in the absence of a known dynamical model. The canonical formulation is the Markov Decision Process defined by the tuple , where is the state space, is the action space, is the transition probability kernel, is the reward function, and is the discount factor. The objective is to find a policy that maximizes the expected discounted return
The optimal value function
satisfies the Bellman optimality equation
which is the discrete-time, stochastic analogue of the Hamilton-Jacobi-Bellman equation from continuous optimal control. The Hamiltonian for the discrete MDP can be defined as
and the Bellman equation is then
directly mirroring the HJB condition
for the deterministic case.
Policy iteration and value iteration are the dynamic programming algorithms that solve the Bellman equations, and when the state and action spaces are large, function approximation is required, leading to Deep Reinforcement Learning where deep neural networks parameterize the value function or the policy . The training of these networks is itself an optimal control problem where the parameters or are the controls, and the dynamics are defined by the optimization algorithm. The value network parameters are trained to minimize the expected Temporal Difference error, which is derived from the Bellman equation. The TD error for a transition is
and the mean-squared projected Bellman error objective is
The gradient of this objective is
which can be seen as a stochastic gradient descent update aiming to satisfy the Bellman orthogonality condition, a form of policy evaluation in the linear function approximation setting.
For policy-based methods, the policy gradient theorem provides the foundational update rule. The objective is
where is a trajectory and
The policy gradient is
A more common and lower-variance form uses the state-action value function
yielding
where is the stationary state distribution under policy . This gradient can be interpreted from an optimal control perspective where the policy update is a step towards maximizing a performance metric, and the Q-function acts as a costate-like variable that evaluates the quality of the action. Advanced policy gradient methods like Trust Region Policy Optimization (TRPO) and Proximal Policy Optimization (PPO) explicitly incorporate a constraint on the policy change, framing the update as a constrained optimization problem
subject to
where
is the advantage function. This is a direct application of a trust-region method in the policy space, ensuring stable and monotonic policy improvement, which is a form of robust control against overly large policy updates.
The connection is further solidified in model-based reinforcement learning and planning. When a model of the environment dynamics is learned or known, optimal control methods can be directly applied for planning. The learned dynamics model , often parameterized by a deep neural network, allows the use of trajectory optimization techniques like Model Predictive Control (MPC) and the Linear Quadratic Regulator (LQR). For a finite horizon H, the goal is to find an action sequence that minimizes
The iLQR algorithm solves this by iteratively linearizing the dynamics around a nominal trajectory and quadratizing the cost, leading to a locally optimal linear feedback policy
The dynamics are linearized as
where
and the cost is quadratized as
The iLQR backward pass then computes the value function
recursively from to using the Riccati equations
and the optimal feedback gain is
with the value function parameters updated as
This direct application of optimal control provides a powerful planning algorithm that can be used to generate targets for policy and value network training, creating a hybrid model-based and model-free RL system where the strengths of both optimal control theory and deep learning are synergistically combined.
5.6. Differential Game Theory and Training Dynamics
Differential game theory provides a rigorous mathematical framework for analyzing the continuous-time dynamics of competing or cooperating agents in deep learning systems, such as generative adversarial networks (GANs), multi-agent reinforcement learning, and adversarial training. Consider a game with K players, where each player k controls a parameter vector that evolves in time according to a differential strategy. The collective state of the system is described by the joint trajectory , governed by coupled ordinary differential equations (ODEs) derived from gradient-based optimization:
Here, denotes the loss function for player k, which may be adversarial (e.g., in GANs) or cooperative (e.g., in distributed optimization). The dynamics are influenced by the interaction matrix , a block-structured Jacobian encoding pairwise competition or cooperation:
The eigenvalues of determine stability: if all eigenvalues have negative real parts, the system converges to a Nash equilibrium; if any are positive, instability or limit cycles may emerge, as observed in GAN training.
In the special case of zero-sum games (e.g., GANs), the dynamics can be reformulated as a Hamiltonian system, where the total "energy" is conserved along trajectories. Let denote the generator and discriminator parameters, respectively. The Hamiltonian dynamics are given by:
This formulation reveals oscillatory behavior when , explaining cyclic divergence in GANs. Alternatively, training dynamics can be analyzed via Wasserstein gradient flows, where parameter updates approximate the gradient flow of a functional in probability space. For a loss over a parameter distribution , the continuity equation describes its evolution:
where is the functional derivative. This perspective connects deep learning to mean-field theory, explaining phenomena like mode collapse and implicit regularization via the geometry of parameter distributions. The interplay between differential game theory and training dynamics thus provides a unified framework for understanding optimization, stability, and convergence in complex learning systems.
6. Optimal Transport Theory in Deep Neural Networks
Optimal transport (OT) theory provides a rigorous geometric framework for comparing probability distributions and has become a foundational tool in analyzing and training deep neural networks (DNNs). Given two probability measures and defined on metric spaces and , respectively, the Monge-Kantorovich problem seeks a transport plan that minimizes the expected cost of moving mass from to :
where is a cost function (e.g., Euclidean distance ), and denotes the set of joint distributions with marginals and . The optimal transport distance, or Wasserstein distance, quantifies the minimal effort required to reconfigure into :
In deep learning, OT is employed to align latent representations, regularize generative models, and define loss functions for distribution matching. For instance, Wasserstein GANs (WGANs) replace the Jensen-Shannon divergence with the 1-Wasserstein distance , leading to improved training stability:
where D is a 1-Lipschitz discriminator enforcing the Wasserstein constraint.
The computational complexity of OT motivates approximations such as entropy-regularized transport, where the Kantorovich problem is relaxed with a Kullback-Leibler (KL) divergence penalty:
The Sinkhorn algorithm solves this efficiently via iterative scaling, enabling scalable OT-based losses in DNNs. The Sinkhorn divergence, a debiased version of , is given by:
which is positive definite and avoids the bias of entropy smoothing. This divergence is used in tasks like domain adaptation, where source and target distributions and are aligned by minimizing for a feature map .
OT theory also informs the design of neural architectures through dynamic transport perspectives. The continuity equation describes the evolution of a parameter distribution under gradient flow:
where is the velocity field induced by the loss functional . This links to the Benamou-Brenier formula, which expresses as an infimum over kinetic energy:
subject to . In deep learning, this inspires Neural ODEs and normalizing flows, where layers are viewed as discretized OT maps. For example, a residual block approximates an infinitesimal transport along , with the network trained to minimize the OT cost between input and output distributions.
OT theory further provides mechanisms for geometric regularization via barycenters. Given distributions , their Wasserstein barycenter minimizes:
where are convex weights. In DNNs, this facilitates multi-task learning by interpolating between task-specific distributions in latent space. The barycentric projection of a transport plan also defines a mapping , used in style transfer and cross-domain alignment.
By embedding OT principles into deep learning, models gain robustness to distributional shifts, improved generative fidelity, and theoretically grounded training dynamics, bridging measure theory and neural optimization.
6.1. Literature Review of Optimal Transport Theory in Deep Neural Networks
Optimal transport theory has become a cornerstone in the analysis and design of deep neural networks, providing a rigorous framework for understanding geometric and probabilistic aspects of learning. Peyré and Cuturi (2019) [1515] offer a comprehensive introduction to the mathematical foundations of optimal transport, with a focus on computational aspects that are crucial for scaling these methods to high-dimensional spaces encountered in deep learning. Its contribution lies in bridging theoretical optimal transport with practical algorithms, enabling applications such as Wasserstein barycenters and gradient flows in neural network training. Santambrogio (2015) [1518] provides a rigorous treatment of the analytical aspects of optimal transport, including Kantorovich duality and Monge-Ampère equations, which are essential for understanding the geometric regularization effects of Wasserstein distances in neural networks. This text is particularly valuable for its deep mathematical insights into how transport-based losses can stabilize and improve generalization in deep models. Arjovsky et al. (2017) [1459] revolutionized generative modeling by introducing the Wasserstein distance as a loss function, addressing the vanishing gradients and mode collapse issues in traditional GANs. This work rigorously establishes the connection between optimal transport and adversarial training, showing how the Wasserstein metric provides a meaningful gradient signal even when the supports of the distributions are disjoint. Gulrajani et al. (2017) [1473] further refine this approach by proposing gradient penalty methods to enforce the Lipschitz constraint, a key technical contribution that ensures stable training. These works collectively demonstrate how optimal transport theory can lead to more robust and interpretable generative models. Frogner et al. (2015) [1508] explore the statistical properties of Wasserstein-based learning, providing generalization bounds and approximation guarantees for neural networks trained with optimal transport objectives. This work is foundational for understanding the trade-offs between expressivity and sample complexity in transport-based deep learning.
Villani (2009) [1521] offers a deep dive into the geometric and probabilistic aspects of optimal transport, with implications for understanding the latent space geometry of neural networks. Its contribution lies in connecting abstract measure-theoretic concepts to practical questions about how neural networks transform and interpolate between distributions. Cuturi (2013) [1505] introduces entropy-regularized optimal transport, a breakthrough that enables efficient computation of Wasserstein distances in high dimensions. This work is particularly impactful for deep learning, as it allows scalable training of models with optimal transport losses. Genevay et al. (2018) [1509] extend these ideas to generative modeling, showing how Sinkhorn divergences can be used to train variational autoencoders with improved sample quality. These contributions highlight the interplay between computational optimal transport and deep generative modeling. Taghvaei and Jalali (2019) [1519] propose a neural network-based approach to solving optimal transport problems, effectively learning the transport map as a parameterized function. This represents a significant shift from traditional linear programming methods, enabling scalable solutions to high-dimensional transport problems. Tolstikhin et al. (2018) [1520] introduce a framework for auto-encoder training based on optimal transport, providing a principled way to balance reconstruction accuracy and latent space regularization. This work is notable for its rigorous treatment of the connection between variational inference and Wasserstein distances. Ramdas et al. (2017) [1517] develop statistical tests based on optimal transport, with applications to evaluating generative models and detecting distributional shifts in deep learning. These contributions demonstrate the versatility of optimal transport in addressing fundamental challenges in neural network training and evaluation.
Ambrosio et al. (2008) [1503] provide a rigorous foundation for understanding gradient-based optimization in the space of probability measures, which is crucial for analyzing the dynamics of neural network training through the lens of optimal transport. Its contribution lies in formalizing the connection between Wasserstein gradient flows and optimization algorithms used in deep learning. Mei et al. (2018) [1513] apply optimal transport theory to analyze the convergence of stochastic gradient descent in overparameterized neural networks, showing how the particle dynamics can be described as a Wasserstein gradient flow. This work bridges the gap between theoretical optimal transport and practical deep learning optimization. Janati et al. (2020) [1511] extend optimal transport theory to handle mismatched masses, a common scenario in deep learning where distributions may not be normalized. This technical advancement enables more flexible applications of transport-based methods in neural networks. Evans (2021) [1507] surveys the broad landscape of optimal transport theory, with particular emphasis on its connections to partial differential equations and variational problems. This work is invaluable for understanding how transport-based regularization can influence the solutions learned by neural networks. Courty et al. (2017) [1504] introduce a framework for adapting neural networks across domains using Wasserstein distances, providing rigorous guarantees on target domain performance. This contribution is particularly impactful for transfer learning and unsupervised domain adaptation. Li et al. (2015) [1512] explore the relationship between optimal transport and kernel-based discrepancies, offering insights into alternative distributional metrics for generative modeling. These works collectively expand the toolbox of transport-based methods available for deep learning applications.
Rachev and Rüschendorf (1998) [1516] provide encyclopedic coverage of optimal transport theory, with extensive treatment of its probabilistic and statistical aspects. This reference is essential for understanding the measure-theoretic foundations of Wasserstein distances in neural network analysis. Deshpande et al. (2018) [1506] introduce computationally efficient approximations to optimal transport by projecting distributions onto random directions, enabling scalable training of generative models. This work represents an important practical advancement in making transport-based methods feasible for large-scale deep learning. Ozair et al. (2019) [1514] develop a transport-based dependency metric that can be used to regularize neural network representations, contributing to the field of disentangled representation learning. These contributions demonstrate the growing influence of optimal transport across various subfields of deep learning. Richards et. al. (2020) [222] provided an intuitive introduction to modeling Rayleigh–Bénard convection within a stochastic framework, emphasizing understanding over mathematical rigor. It outlines how stochastic processes such as Brownian motion and stochastic differential equations can be applied to model convective phenomena. The work serves as a conceptual and computational guide for developing numerical simulations of stochastic fluid dynamics systems. Huang et al. (2021) [1510] propose a method for constructing explicit transport maps in generative models, providing both theoretical guarantees and practical algorithms. This work bridges the gap between normalizing flows and optimal transport theory. The convergence analysis of transport-based optimization in deep learning is further advanced by rigorous studies connecting Wasserstein geometry with stochastic gradient descent dynamics. The interplay between optimal transport and deep learning continues to inspire new theoretical insights and algorithmic innovations, shaping the future of machine learning research and applications.
6.2. Analysis of Optimal Transport Theory in Deep Neural Networks
Optimal transport theory provides a mathematically rigorous framework for measuring distances between probability distributions by solving a constrained optimization problem that minimizes the cost of transporting mass from one distribution to another. Consider two probability measures and defined on a common measurable space , where has support and has support . Given a cost function , the optimal transport problem seeks to determine a transport plan that minimizes the total cost of transforming into . In the Monge formulation, this problem is expressed as
subject to the constraint that the transport map T satisfies the push-forward condition
which ensures that the measure is obtained by pushing forward through T, i.e., for any measurable set ,
The Monge problem is often ill-posed since a transport map may not exist. To alleviate this issue, the Kantorovich relaxation introduces a coupling between and , where is a probability measure on satisfying the marginal constraints
The Kantorovich formulation of the optimal transport problem is thus
where is the set of all couplings satisfying the marginal constraints. A commonly used cost function is the p-th power of the Euclidean distance, i.e., , which leads to the Wasserstein distance of order p, given by
The Wasserstein distance defines a proper metric on the space of probability measures, provided that and have finite p-th moments, i.e.,
In deep neural networks, optimal transport plays a crucial role in generative modeling, where it provides a more stable alternative to divergence-based training objectives. In Wasserstein generative adversarial networks (WGANs), the standard Jensen-Shannon divergence is replaced by the Wasserstein-1 distance, leading to the objective
where f is a Lipschitz-1 function, is the real data distribution, is the latent distribution, and is the generator function. The use of the Wasserstein distance improves gradient behavior and mitigates mode collapse, which is a common issue in standard GAN training. In domain adaptation, optimal transport is used to align source and target distributions by finding a transport plan that minimizes the Wasserstein distance between them. Given a source distribution and a target distribution , the goal is to find a transport map T such that
which is often achieved by solving
To ensure computational efficiency, entropy-regularized optimal transport introduces a regularization term based on the Kullback-Leibler divergence, leading to the Sinkhorn distance
The regularization parameter controls the trade-off between accuracy and computational efficiency. The Sinkhorn algorithm, which iteratively updates the dual potentials using Bregman projections, provides an efficient means of computing approximate solutions to the OT problem. Optimal transport has also been applied to learning energy-based models, where it is used to define a structured loss function for training probability models. In probabilistic autoencoders, OT distances provide a principled approach for matching latent and data distributions. In Bayesian deep learning, OT-based priors ensure that posterior distributions maintain smooth and stable representations, improving generalization in uncertainty estimation tasks. The OT-based barycenter problem arises in multi-modal learning, where the goal is to compute a central distribution that minimizes the sum of Wasserstein distances to a set of given measures . The barycenter is defined as
which generalizes the notion of averaging to probability distributions. Applications of OT barycenters include meta-learning, ensemble methods, and federated learning, where a global model must aggregate information from multiple local distributions while minimizing divergence. The theoretical properties of optimal transport, including dual formulations and regularity results, provide strong guarantees for its application in deep neural networks. The dual formulation of the Wasserstein distance is given by the Kantorovich-Rubinstein theorem, which states that for ,
This dual representation allows gradient-based optimization methods to efficiently approximate OT distances in neural network training. Furthermore, recent advances in computational optimal transport, including sliced Wasserstein distances and entropic maps, have enabled scalable implementations suitable for high-dimensional deep learning applications.
Optimal transport thus provides a fundamental mathematical framework for distributional matching in deep learning. By leveraging Wasserstein distances and entropy-regularized formulations, OT enables more stable training, improved generalization, and better interpretability in neural networks, making it an essential tool for modern deep learning methodologies.
6.3. Jensen-Shannon Divergence
The Jensen-Shannon divergence (JSD) is a rigorously defined, symmetric, and bounded measure of dissimilarity between two probability distributions P and Q. It is constructed from the Kullback-Leibler divergence (KLD) but incorporates a mixture distribution to ensure symmetry and finiteness. The JSD is defined as:
where M is the average distribution of P and Q, given by:
Here, and are the Kullback-Leibler divergences between P and M, and Q and M, respectively. The KLD for two discrete probability distributions P and M is defined as:
where and are the probabilities assigned to the i-th event by P and M, respectively. For continuous probability distributions, the KLD is expressed as:
where and are the probability density functions of P and M, respectively. Substituting the definition of M into the JSD, we obtain:
For continuous distributions, this becomes:
The JSD can also be expressed in terms of Shannon entropy. Let denote the Shannon entropy of P, defined for discrete distributions as:
For continuous distributions, the differential entropy is:
Using entropy, the JSD can be rewritten as:
This formulation demonstrates that the JSD measures the difference between the entropy of the average distribution M and the average of the entropies of P and Q. The JSD is bounded between 0 and 1 when the logarithm base is 2, as:
The lower bound is achieved when , and the upper bound is approached when P and Q are maximally different. The square root of the JSD is a metric, satisfying the triangle inequality:
for any probability distribution R. This property makes the JSD particularly useful in applications requiring a distance metric, such as clustering and classification. The JSD is also related to the total variation distance by the inequality:
This relationship connects the JSD to other statistical distances, providing a bridge between information-theoretic and measure-theoretic perspectives. The JSD is widely used in machine learning, bioinformatics, and statistics due to its symmetry, boundedness, and interpretability. It is particularly useful for comparing empirical distributions, as it avoids the infinite values that can arise with the KLD. The JSD can also be generalized to compare more than two distributions. For n distributions , the generalized JSD is:
This generalization retains the properties of the standard JSD, including symmetry and boundedness. The JSD is also closely related to the concept of mutual information, as it can be interpreted as the mutual information between a random variable and a mixture distribution. Specifically, for two distributions P and Q, the JSD can be expressed as:
where X is a random variable with distribution P or Q, and Y is a binary indicator variable selecting between P and Q. This interpretation provides a deeper understanding of the JSD as a measure of information overlap. In summary, the Jensen-Shannon divergence is a versatile and mathematically rigorous tool for quantifying the difference between probability distributions, with applications across numerous scientific and engineering disciplines. Its properties make it a preferred choice in many scenarios where symmetric and bounded divergence measures are required.
6.4. Matching Latent and Data Distributions in Probabilistic Autoencoders
Optimal Transport (OT) distances provide a mathematically rigorous framework for comparing probability distributions, making them particularly suitable for aligning latent and data distributions in Probabilistic Autoencoders (PAEs). The core idea of OT is to find the most efficient way to transform one distribution into another, where efficiency is quantified by a cost function. In the context of PAEs, this translates to minimizing the discrepancy between the encoded latent distribution and the prior distribution , as well as between the decoded data distribution and the true data distribution .
Let and be two probability measures defined on metric spaces and , respectively. The OT problem seeks a coupling that minimizes the total transportation cost:
where is a cost function, typically the Euclidean distance for . The p-Wasserstein distance is a special case of OT, defined as:
In PAEs, the latent distribution is often modeled as a Gaussian , and the prior is typically a standard Gaussian . The OT distance between these distributions can be computed using the 2-Wasserstein distance, which has a closed-form expression for Gaussian distributions:
For the decoded data distribution , the OT distance to the true data distribution can be approximated using discrete OT methods. Given samples from and from , the empirical OT problem becomes:
where and are empirical measures. The coupling is a doubly stochastic matrix satisfying and . The OT distance can be incorporated into the PAE objective function as a regularization term. The overall loss function combines the reconstruction loss and the OT-based regularization:
where and are hyperparameters controlling the strength of the regularization terms. The first term ensures accurate reconstruction, while the second and third terms enforce consistency between the latent and prior distributions, and between the decoded and true data distributions, respectively. The OT framework also allows for the use of entropy-regularized OT, which introduces a regularization term to the OT problem to make it computationally tractable. The entropy-regularized OT problem is given by:
where is the entropy of the coupling , and is the regularization parameter. This formulation leads to the Sinkhorn algorithm, which provides an efficient way to compute approximate OT distances.
In summary, OT distances offer a principled and mathematically rigorous approach for matching latent and data distributions in PAEs. By minimizing the Wasserstein distance between distributions, PAEs can achieve better alignment between the encoded latent space and the prior, as well as between the decoded data and the true data distribution. This results in more robust and interpretable models, with improved generative and reconstructive capabilities.
6.4.1. Probabilistic Autoencoders
Probabilistic autoencoders are generative models that combine the principles of autoencoders with probabilistic frameworks to learn a latent representation of data. Let be the observed data, and be the latent variable, where . The goal is to model the joint distribution , which can be factorized as:
Here, is the prior distribution over the latent space, often chosen as a standard Gaussian , and is the likelihood function, which models the data generation process. The encoder in a probabilistic autoencoder approximates the posterior distribution , which is typically intractable. Instead, a variational distribution is introduced, parameterized by , to approximate the true posterior. This distribution is often chosen as a Gaussian , where and are outputs of a neural network. The decoder, parameterized by , models the likelihood , which is also often Gaussian for continuous data:
The learning objective is to maximize the marginal likelihood , which can be expressed as:
However, this integral is intractable due to the high-dimensional latent space. Instead, the evidence lower bound (ELBO) is maximized, which is derived using variational inference:
The first term in the ELBO is the reconstruction loss, which encourages the model to accurately reconstruct the input data. The second term is the Kullback-Leibler (KL) divergence between the variational posterior and the prior , which regularizes the latent space to match the prior distribution. The ELBO can be rewritten as:
where and are the mean and variance of the i-th dimension of the latent variable . The parameters and are optimized using stochastic gradient descent. The expectation term in the ELBO is approximated using Monte Carlo sampling. For a single sample , the ELBO can be approximated as:
To enable backpropagation through the sampling process, the reparameterization trick is used. Specifically, is reparameterized as:
where and ⊙ denotes element-wise multiplication. This allows gradients to flow through the sampling process, enabling efficient optimization. The reconstruction loss depends on the type of data. For continuous data, it is often the negative log-likelihood of a Gaussian distribution:
For binary data, the Bernoulli distribution is used, and the reconstruction loss becomes:
where is the i-th element of the reconstructed data . The KL divergence term can be computed analytically for Gaussian distributions. For a standard Gaussian prior and a Gaussian variational posterior , the KL divergence is:
If the variational posterior is diagonal, i.e., , the KL divergence simplifies to:
The optimization of the ELBO is performed using gradient-based methods. The gradients of the ELBO with respect to and are computed using automatic differentiation. For a mini-batch of data , the stochastic gradient estimate of the ELBO is:
where . The probabilistic autoencoder can be extended to more complex architectures, such as hierarchical models with multiple layers of latent variables. In such cases, the latent variables are structured hierarchically, and the joint distribution is factorized as:
where are the latent variables at different levels of the hierarchy. The variational posterior is also factorized hierarchically:
The ELBO for hierarchical models includes additional KL divergence terms for each level of the hierarchy:
In summary, probabilistic autoencoders provide a principled framework for learning latent representations of data by combining the strengths of autoencoders and probabilistic models. The ELBO serves as the optimization objective, balancing reconstruction accuracy and regularization of the latent space. The reparameterization trick enables efficient gradient-based optimization, and the framework can be extended to hierarchical models for more complex data structures.
6.4.2. 2-Wasserstein Distance
The 2-Wasserstein distance, also known as the Earth Mover’s Distance (EMD) in the case of , is a metric used to quantify the difference between two probability distributions and defined on a metric space . It is a specific instance of the more general p-Wasserstein distance, which is defined for . The 2-Wasserstein distance is particularly significant due to its geometric interpretation and its applications in optimal transport theory, statistics, and machine learning.
Given two probability measures and on X, the 2-Wasserstein distance is defined as the infimum of the expected squared distance between random variables X and Y, where X is distributed according to and Y is distributed according to , over all possible joint distributions of with marginals and . Mathematically, this is expressed as:
where denotes the set of all joint probability measures on with marginals and , i.e., for any measurable sets , and . The distance is the metric on the space X, and the integral represents the expected squared distance under the coupling . The 2-Wasserstein distance can also be expressed in terms of the cumulative distribution functions (CDFs) of and when . Let and be the CDFs of and , respectively. Then, the 2-Wasserstein distance is given by:
where and are the quantile functions (inverse CDFs) of and , respectively. This formulation is particularly useful in one-dimensional settings, as it reduces the problem to computing the integral of the squared difference between the quantile functions. In the case where and are absolutely continuous with respect to the Lebesgue measure, with probability density functions and , the 2-Wasserstein distance can be related to the optimal transport map T that pushes forward to , i.e., . The map T minimizes the transport cost:
The optimal transport map T is often characterized by the Monge-Ampère equation, which relates the densities and through the Jacobian determinant of T:
In higher dimensions, the 2-Wasserstein distance is more challenging to compute, but it can be approximated using numerical methods such as linear programming, entropic regularization, or Sinkhorn iterations. The dual formulation of the 2-Wasserstein distance, derived from Kantorovich duality, provides another perspective:
where the supremum is taken over all pairs of continuous functions and on X satisfying the constraint:
This dual formulation is particularly useful in theoretical analyses and provides a connection to convex optimization. The 2-Wasserstein distance has several important properties, including symmetry, non-negativity, and the triangle inequality, making it a true metric on the space of probability measures with finite second moments. It is also sensitive to the geometry of the underlying space X, as it incorporates the metric directly into its definition. This geometric sensitivity makes it particularly useful in applications such as image processing, where the spatial arrangement of pixels is crucial.
In summary, the 2-Wasserstein distance is a powerful tool for comparing probability distributions, with deep connections to optimal transport theory, convex analysis, and geometry. Its rigorous mathematical formulation and rich theoretical properties make it a cornerstone of modern probability and statistics.
6.5. Optimal Transport (OT)-Based Priors in Bayesian Deep Learning
The incorporation of Optimal Transport (OT)-based priors into Bayesian Deep Learning frameworks ensures that posterior distributions maintain smooth and stable representations by leveraging the rigorous mathematical properties of the Wasserstein distance and its associated geometric structure. This approach is grounded in measure theory, functional analysis, and convex optimization, providing a robust foundation for uncertainty estimation tasks. Below, we provide a deeper and more mathematically rigorous exposition.
Let be a complete separable metric space, and let denote the space of probability measures on X with finite p-th moments. For , the p-Wasserstein distance is defined as:
where is the set of all couplings (joint distributions) with marginals P and Q. The Wasserstein distance induces a metric on , endowing it with a geometric structure that is sensitive to the underlying topology of X. This sensitivity ensures that the Wasserstein distance captures not only global but also local differences between distributions, making it particularly suitable for regularizing posterior distributions in Bayesian inference. In Bayesian Deep Learning, the prior and the posterior are probability measures over the parameter space . To ensure smoothness and stability of the posterior, we introduce an OT-based regularization term into the variational inference objective. Specifically, we augment the evidence lower bound (ELBO) with a Wasserstein penalty:
where is a regularization hyperparameter, and is the Kullback-Leibler divergence. The Wasserstein term enforces geometric consistency between the prior and the posterior, ensuring that the posterior does not deviate excessively from the prior in a manner that respects the underlying metric structure of . The smoothness of the posterior is guaranteed by the properties of the Wasserstein distance. Specifically, the Wasserstein distance is Lipschitz-continuous with respect to perturbations in the distributions. For any , the triangle inequality holds:
This inequality ensures that small changes in the data distribution D or the prior lead to proportionally small changes in the posterior , thereby promoting stability. Furthermore, the Wasserstein distance is convex in its arguments, which facilitates efficient optimization and guarantees the existence of a unique minimizer under appropriate conditions. To compute the Wasserstein distance in practice, we often employ entropic regularization, which transforms the OT problem into a strictly convex optimization problem. The entropic regularized Wasserstein distance is defined as:
where is the entropy of the coupling , and is the regularization parameter. The entropic regularization ensures that the optimal coupling is unique and has the form:
where f and g are dual potentials that satisfy the Schrödinger system of equations. This formulation allows for efficient computation using the Sinkhorn-Knopp algorithm, which iteratively updates the dual potentials f and g. The stability and smoothness of the posterior are further reinforced by the dual formulation of the Wasserstein distance. By the Kantorovich-Rubinstein duality, the 1-Wasserstein distance can be expressed as:
where is the set of 1-Lipschitz functions on X. This dual formulation highlights the role of Lipschitz continuity in controlling the smoothness of the posterior, as the Wasserstein distance penalizes functions that vary too rapidly.
In summary, OT-based priors ensure that posterior distributions maintain smooth and stable representations by leveraging the geometric and analytical properties of the Wasserstein distance. The Wasserstein distance provides a rigorous framework for regularizing Bayesian inference, ensuring that the posterior remains close to the prior in a geometrically meaningful way. This approach is computationally tractable due to entropic regularization and the Sinkhorn-Knopp algorithm, and it is theoretically grounded in measure theory, convex analysis, and functional analysis. The resulting Bayesian framework is robust to noise and distributional shifts, leading to improved generalization in uncertainty estimation tasks.
6.6. Application of Optimal Transport in Learning Energy-Based Models
The foundational principle of Optimal Transport lies in the minimization of the cost required to transport mass from one probability distribution to another. Let be a metric space, where X is the sample space and is a metric. Given two probability measures and defined on X, the OT problem seeks to find the optimal coupling that minimizes the total transportation cost:
where denotes the set of all joint probability measures on with marginals and , and is a cost function, typically chosen as for . For , this yields the squared Euclidean cost, and the corresponding OT distance is the 2-Wasserstein distance:
In the context of energy-based models, the model distribution is defined via an energy function and the Boltzmann-Gibbs distribution:
where is the partition function. The goal is to minimize the discrepancy between and , which can be achieved by minimizing the Wasserstein distance . The Kantorovich duality theorem provides a dual formulation of the OT problem:
subject to the constraint for all . Here, and are the Kantorovich potentials, which are related via the c-transform:
The Kantorovich potentials and can be parameterized using neural networks, leading to the Wasserstein Generative Adversarial Network (WGAN) framework. In this setting, the discriminator learns , while the generator minimizes the Wasserstein distance. The gradient of the Wasserstein distance with respect to the model parameters is given by:
where is the Kantorovich potential parameterized by . This gradient can be estimated using Monte Carlo sampling from and , enabling stochastic optimization. To enhance computational efficiency and stability, entropy regularization is often introduced, leading to the Sinkhorn divergence:
where
is the entropy of the coupling , and is the regularization parameter. The Sinkhorn divergence provides a smoothed approximation of the Wasserstein distance, which is particularly advantageous in high-dimensional settings. The optimization problem for learning EBMs using OT can be formulated as:
where is a regularization term, such as , and is a hyperparameter. The gradient of the Sinkhorn divergence with respect to is:
where is the optimal coupling under entropy regularization. This gradient can be computed efficiently using the Sinkhorn-Knopp algorithm, which iteratively updates the coupling and the potentials .
In summary, the application of Optimal Transport to learning energy-based models provides a mathematically rigorous framework for minimizing the discrepancy between data and model distributions. The interplay between Kantorovich duality, entropy regularization, and stochastic optimization enables efficient and scalable learning of complex, high-dimensional distributions. The resulting OT-based EBMs are both theoretically sound and practically effective, with connections to generative models such as WGANs and variational inference.
6.7. Sinkhorn-Knopp Algorithm
The Sinkhorn-Knopp algorithm is a numerical method for solving entropy-regularized optimal transport problems, which are central to many applications in deep neural networks, including generative modeling, domain adaptation, and representation learning. The optimal transport problem seeks to find a coupling matrix that minimizes the transportation cost between two probability distributions and , subject to marginal constraints. The cost is quantified by a cost matrix , where represents the cost of transporting mass from point i in the source distribution to point j in the target distribution. The entropy-regularized optimal transport problem introduces a regularization term to the objective function, resulting in the following convex optimization problem:
subject to the constraints:
where is the Frobenius inner product, is the regularization parameter, and is the entropy of the coupling matrix P. The regularization term ensures that the solution P is smooth and computationally tractable, as it penalizes deviations from uniformity. The Sinkhorn-Knopp algorithm solves this problem by leveraging the dual formulation of the entropy-regularized optimal transport problem. The dual problem can be derived using the method of Lagrange multipliers, introducing dual variables and corresponding to the marginal constraints. The Lagrangian of the problem is given by:
Taking the gradient of the Lagrangian with respect to P and setting it to zero yields the optimality condition:
This expression can be rewritten in terms of the Gibbs kernel , defined as , and the scaling vectors and . The coupling matrix P is then given by:
The Sinkhorn-Knopp algorithm iteratively updates the scaling vectors and to satisfy the marginal constraints and . The update rules are derived from the optimality conditions and are given by:
These updates ensure that the coupling matrix P converges to the unique solution of the entropy-regularized optimal transport problem. The convergence of the algorithm is guaranteed by the contractive nature of the updates, and the rate of convergence is linear in the number of iterations. In the context of deep neural networks, the Sinkhorn-Knopp algorithm is often used to compute approximate Wasserstein distances, which are essential for training generative models such as Wasserstein GANs. The Wasserstein distance between two probability distributions and is defined as:
where is the set of all coupling matrices satisfying the marginal constraints. The entropy-regularized version of the Wasserstein distance, known as the Sinkhorn distance, is given by:
where is the solution to the entropy-regularized optimal transport problem. The Sinkhorn-Knopp algorithm provides an efficient way to compute and, consequently, the Sinkhorn distance. The algorithm can also be extended to handle unbalanced optimal transport problems, where the source and target distributions do not necessarily have the same total mass. In this case, the optimization problem is modified to include additional penalty terms for deviations from the marginal constraints:
where is the Kullback-Leibler divergence, and are regularization parameters. The Sinkhorn-Knopp algorithm can be adapted to solve this problem by modifying the update rules for and :
This extension allows the algorithm to handle a broader range of applications in deep learning, such as semi-supervised learning and data augmentation, where the source and target distributions may not be perfectly aligned.
In summary, the Sinkhorn-Knopp algorithm is a highly efficient and mathematically rigorous method for solving entropy-regularized optimal transport problems. Its iterative nature, linear convergence rate, and ability to handle both balanced and unbalanced transport problems make it a versatile tool in deep learning. The algorithm’s reliance on matrix scaling operations ensures that it can be seamlessly integrated into existing deep learning frameworks, making it a cornerstone of modern optimal transport theory and its applications.
6.7.1. Sinkhorn Distance
The Sinkhorn distance is a mathematically rigorous and computationally efficient approximation of the optimal transport problem, which seeks to minimize the cost of transporting mass from one probability distribution to another. Let and be two discrete probability distributions defined over finite spaces, and let be a cost matrix where represents the cost of transporting a unit of mass from point i in the support of to point j in the support of . The optimal transport problem is formulated as:
where is the set of all valid transport plans, and are vectors of ones, and is the Frobenius inner product. The Sinkhorn distance introduces an entropic regularization term to this problem, resulting in the following optimization problem:
where is the regularization parameter, and is the entropy of the transport plan . The entropic regularization ensures that the optimal transport plan is unique and has the form:
where is the Gibbs kernel, and and are positive scaling vectors that satisfy the marginal constraints:
Here, ⊙ denotes element-wise multiplication. The Sinkhorn-Knopp algorithm is used to iteratively compute these scaling vectors:
where and are initialized as vectors of ones. The algorithm converges to the optimal scaling vectors and , which define the optimal transport plan . The Sinkhorn distance is then given by:
The regularization parameter controls the trade-off between the transportation cost and the entropy of the transport plan. As , the Sinkhorn distance approaches the original optimal transport distance, while as , the transport plan becomes more diffuse and the distance approaches the entropy-regularized Wasserstein distance. The Sinkhorn distance is computationally efficient due to the iterative nature of the Sinkhorn-Knopp algorithm, making it suitable for large-scale applications. The dual formulation of the regularized optimal transport problem provides additional insights into the structure of the Sinkhorn distance. The dual problem is given by:
where and are dual variables. The optimal dual variables and are related to the scaling vectors and by:
The Sinkhorn distance can thus be computed using either the primal or dual formulation, depending on the specific application. The dual formulation is particularly useful for deriving theoretical properties of the Sinkhorn distance, such as its convexity and smoothness with respect to the input distributions and . The Sinkhorn distance satisfies several key mathematical properties. First, it is symmetric, meaning that . Second, it satisfies the triangle inequality, making it a valid metric on the space of probability distributions. Third, it is differentiable with respect to the input distributions and , which is useful for gradient-based optimization in machine learning applications. Finally, the Sinkhorn distance is computationally efficient, with a time complexity of per iteration of the Sinkhorn-Knopp algorithm, making it scalable to high-dimensional problems. The Sinkhorn distance can also be generalized to continuous probability measures using the Kantorovich formulation of optimal transport. Let and be probability measures defined on metric spaces and , respectively, and let be a continuous cost function. The entropically regularized optimal transport problem in the continuous setting is given by:
where is the set of all joint probability measures with marginals and , and is the entropy of the coupling . The optimal coupling has the form:
where f and g are continuous functions satisfying the Schrödinger system:
The Sinkhorn distance in the continuous setting is then given by:
This formulation extends the Sinkhorn distance to continuous probability measures, enabling its application to a broader class of problems in probability theory, statistics, and machine learning. The Sinkhorn distance thus provides a rigorous and computationally efficient framework for measuring the dissimilarity between probability distributions, combining the theoretical foundations of optimal transport with the practical advantages of entropic regularization.
6.7.2. Wasserstein GANs
Wasserstein Generative Adversarial Networks (WGANs) are a class of generative models that utilize the Wasserstein-1 distance, also known as the Earth Mover’s Distance (EMD), to measure the discrepancy between the real data distribution and the generated data distribution . The Wasserstein-1 distance is defined as:
Here, represents the set of all joint distributions with marginals and , and the infimum is taken over all such joint distributions. The Wasserstein-1 distance quantifies the minimal cost required to transport mass from to , where the cost is proportional to the Euclidean distance . In WGANs, the generator G and the critic D are optimized to minimize and maximize the Wasserstein-1 distance, respectively. The critic D is trained to approximate the Wasserstein-1 distance between and . The objective function for the critic is given by:
Here, z is a random noise vector sampled from a prior distribution , and is the generated sample. To ensure that the critic D is a 1-Lipschitz function, a constraint is imposed on its gradients. This constraint is typically enforced using a gradient penalty term, leading to the modified critic loss function:
In this equation, is a hyperparameter controlling the strength of the gradient penalty, and is sampled uniformly along straight lines connecting pairs of points sampled from and . The term penalizes deviations from the 1-Lipschitz constraint, ensuring that the critic’s gradients have a norm of at most 1. The generator G is trained to minimize the Wasserstein-1 distance by maximizing the critic’s output on generated samples. The objective function for the generator is given by:
The optimization process alternates between updating the critic and the generator. The critic is updated multiple times for each update of the generator to ensure that it remains close to the optimal 1-Lipschitz function. The parameter updates for the critic and generator are given by:
Here, and are the parameters of the critic and generator, respectively, and and are the learning rates for the critic and generator. The training continues until the generator produces samples that are indistinguishable from real data according to the critic. The Wasserstein-1 distance provides several theoretical advantages over traditional GAN objectives, such as the Jensen-Shannon divergence used in the original GAN formulation. The Wasserstein-1 distance is continuous and differentiable almost everywhere, which leads to more stable training dynamics. Additionally, the Wasserstein-1 distance correlates better with sample quality, providing a meaningful metric for evaluating the performance of the generator. The mathematical properties of the Wasserstein-1 distance, including its sensitivity to the geometry of the underlying space and its ability to provide meaningful gradients even when the supports of and are disjoint, make WGANs a powerful tool for generative modeling.
In summary, WGANs optimize the following minimax objective:
where is the set of 1-Lipschitz functions. The Wasserstein-1 distance is approximated by the critic D, and the generator G is trained to minimize this distance. The use of the Wasserstein-1 distance in WGANs provides a theoretically grounded framework for generative modeling, leading to improved stability and performance compared to traditional GANs. The mathematical rigor of the Wasserstein-1 distance and its properties ensure that WGANs are well-suited for a wide range of generative tasks.
6.8. Kantorovich Duality
The Kantorovich duality theorem is a fundamental result in optimal transport theory that establishes the equivalence between the primal formulation of the optimal transport problem and a dual formulation based on potential functions. Given two probability spaces and , with a cost function , the primal Kantorovich formulation of optimal transport seeks to minimize the total transport cost over all possible couplings of and , where a coupling is a joint probability measure on whose marginals are and , respectively. Mathematically, this is expressed as
where is the set of all couplings satisfying
The Kantorovich duality states that the optimal transport cost can equivalently be expressed in terms of potential functions and satisfying the inequality
Under appropriate conditions, the optimal transport cost is given by the dual formulation
subject to the constraint
A key result in this formulation is that when the cost function is lower semi-continuous, the supremum is attained by functions and that satisfy
For the specific case of the Wasserstein-1 distance, where , the dual problem simplifies to
Here, the supremum is taken over all 1-Lipschitz functions , satisfying
This dual formulation is of fundamental importance in deep learning applications, particularly in the training of Wasserstein Generative Adversarial Networks (WGANs). In this setting, the generator transforms samples from a latent space into synthetic data points in , aiming to approximate a target data distribution . The discriminator network approximates the Kantorovich potential , leading to the objective
This adversarial framework provides a more stable training procedure than standard GANs, which rely on the Jensen-Shannon divergence. The Kantorovich duality ensures that the discriminator function learns a transport potential that characterizes the optimal transport map, guiding the generator toward minimizing the Wasserstein distance between the real and generated distributions. Beyond generative modeling, optimal transport theory is also applied in supervised learning, where the Wasserstein distance serves as a loss function for comparing distributions in high-dimensional spaces. When computational efficiency is required, entropic regularization techniques introduce an additional entropy penalty term , yielding the regularized transport problem
where
This modification allows for efficient computation via Sinkhorn iterations, leveraging the dual formulation
Such approaches are particularly useful in deep learning, where high-dimensional transport problems arise in applications such as domain adaptation, clustering, and metric learning. The theoretical underpinnings of Kantorovich duality thus play a critical role in designing robust algorithms for optimizing probability distributions in high-dimensional spaces, ensuring efficient convergence and improved generalization performance in deep neural networks.
6.9. Entropy Regularization
The entropy regularization of optimal transport arises from the classical Monge-Kantorovich formulation, where the goal is to find a transport plan that minimizes the expected transportation cost between two probability measures and . Mathematically, this can be expressed as the minimization problem
where is the space of joint probability distributions on with marginals and , respectively, satisfying the marginalization conditions
While this optimization problem is well-posed, it is computationally intractable in high-dimensional settings due to the combinatorial explosion of feasible transport plans. To mitigate this, an entropy regularization term is introduced, leading to the entropy-regularized optimal transport problem
where is the Shannon entropy of the transport plan , given by
The introduction of entropy regularization has fundamental mathematical consequences. First, it ensures the strict convexity of the optimization problem, which allows for efficient computation using iterative methods. Second, it guarantees the uniqueness of the optimal transport plan, preventing the degeneracy issues that arise in the classical unregularized setting. The optimal transport plan in the entropy-regularized setting takes the form
which is known as the Gibbs kernel representation. This form follows from the variational principle associated with entropy maximization under marginal constraints, leading to the closed-form solution
where and are dual potentials arising from the Lagrange multipliers enforcing the marginal constraints. The dual formulation of entropy-regularized optimal transport is derived from the Fenchel-Rockafellar duality theorem and takes the form
The dual potentials and satisfy the iterative update equations
These updates converge exponentially to the optimal dual potentials, enabling the efficient computation of entropy-regularized transport distances. In the discrete setting, where the probability measures and are represented as vectors and , the entropy-regularized optimal transport problem reduces to a matrix scaling problem. Given a cost matrix , the optimal transport matrix T satisfies
This leads to the Sinkhorn-Knopp iteration
where and division is element-wise. These updates ensure fast convergence and numerical stability, making entropy-regularized optimal transport suitable for large-scale applications in deep learning. In the context of deep neural networks, entropy-regularized optimal transport plays a crucial role in generative modeling, domain adaptation, and adversarial training. Given a parameterized generator with latent variable , the entropy-regularized Wasserstein loss for training a generative model is given by
This formulation enables stable gradient-based training by ensuring smoothness in the transport plan. Furthermore, in domain adaptation, the entropy-regularized Wasserstein distance is minimized between the source and target feature distributions and , leading to the optimization problem
This objective ensures that the learned representation preserves geometric consistency between domains while mitigating domain shift. Thus, entropy regularization in optimal transport provides a mathematically rigorous, computationally efficient, and theoretically well-grounded framework for deep learning applications, ensuring convexity, uniqueness, and numerical stability while enabling large-scale optimization in high-dimensional probability spaces.
6.9.1. Classical Monge-Kantorovich Formulation
The Monge-Kantorovich optimal transport problem seeks to determine the most efficient way to transport mass from one distribution to another while minimizing a given cost function. Let X and Y be two measurable spaces, each endowed with probability measures and , respectively, which are absolutely continuous with respect to the Lebesgue measure, having corresponding density functions and . The fundamental problem first considered by Monge is to find a measurable transport map satisfying the pushforward condition,
which ensures that mass is conserved. Given a cost function , the total transport cost associated with the map T is given by the functional
The Monge problem is then formulated as the minimization problem
where the infimum is taken over all measurable transport maps satisfying the pushforward condition. The primary difficulty in solving Monge’s problem lies in the fact that a transport map may not exist in general, particularly when the measure is more spread out than , or when mass-splitting is required, which motivates the relaxation of Monge’s problem to the Kantorovich formulation. Instead of restricting attention to deterministic transport maps, Kantorovich introduced the notion of transport plans, which are probability measures on the product space satisfying the marginal constraints
The set of all such couplings is denoted as , which consists of all probability measures whose projections onto X and Y coincide with and , respectively. The Kantorovich optimal transport problem is then formulated as the minimization problem
Under mild conditions, such as compactness of X and Y and continuity of , existence of an optimal transport plan is guaranteed. If is supported on the graph of a function , then the optimal plan corresponds to a Monge-type transport. The problem of characterizing such solutions leads naturally to Kantorovich duality, which provides a variational formulation of optimal transport in terms of potentials and . The dual problem is expressed as
subject to the inequality constraint
The optimality conditions for the Kantorovich dual problem imply the complementary slackness condition
which characterizes the support of the optimal transport plan. When the cost function is the squared Euclidean distance, , the transport problem reduces to finding a convex function whose gradient defines the optimal transport map. This leads to the Monge-Ampère equation
which provides a geometric interpretation of optimal transport: the transport map is given by the gradient of a convex function, ensuring volume preservation under mass transport. In this setting, the transport map satisfies
which is the Brenier map for the quadratic cost function. The induced transport cost is given by the Wasserstein-2 distance
A fundamental computational approach to solving optimal transport problems is entropic regularization, which introduces an entropy term
leading to the regularized optimal transport problem
These equations reveal deep connections between optimal transport, geometric analysis, and functional inequalities, providing a unifying framework for problems in probability, physics, and machine learning.
6.9.2. Fenchel-Rockafellar Duality Theorem
The Fenchel-Rockafellar duality theorem is a cornerstone result in convex analysis, establishing a deep connection between a primal convex optimization problem and its associated dual problem via the framework of convex conjugates and subdifferential calculus. It generalizes classical duality principles by employing functional analytic techniques and provides a powerful formulation for the optimality conditions in convex minimization problems. The theorem holds in the setting of a Banach space X paired with its continuous dual space , and its implications extend to a broad range of optimization and variational problems.
Consider two proper, convex, and lower semicontinuous functions and . The primal optimization problem is given by
which seeks to minimize the sum of these two convex functions over the domain X. The associated Fenchel conjugate function (also referred to as the Legendre-Fenchel transform) is defined as
which captures the maximum possible affine lower bound of . Similarly, the conjugate of g is given by
The Fenchel dual problem is then formulated as
The Fenchel-Rockafellar duality theorem states that under appropriate constraint qualifications, strong duality holds, meaning that the optimal values of the primal and dual problems coincide:
To ensure strong duality, a sufficient condition is the existence of a point such that
where the effective domain of a function is defined as
and the core (or algebraic interior) of a set S is given by
This constraint qualification ensures that the subdifferential intersection necessary for optimality is nonempty. In particular, the subdifferential of a convex function f at a point x is defined as
For optimality, we require that the subdifferentials of f and g satisfy
which guarantees the existence of a Lagrange multiplier such that
That is, the dual optimizer must belong to the intersection
This condition provides the necessary and sufficient optimality criterion in terms of subdifferential calculus. The theorem extends naturally to infinite-dimensional settings, where it serves as a foundation for convex variational problems in Hilbert and Banach spaces. By employing the Fenchel conjugates, it allows for a reformulation of many classical variational problems in dual terms, enabling powerful analytical techniques such as saddle-point theory, strong convexity conditions, and dual space representations. The theorem’s implications in optimization, functional analysis, and mathematical economics highlight its fundamental role in modern analysis.
6.10. Optimal transport theory Based Training Dynamics and Sinkhorn Divergences
Optimal transport theory provides a mathematical framework for comparing probability distributions by minimizing the cost of transporting mass from one distribution to another. The theory is rooted in the Monge-Kantorovich problem, which seeks a transport plan that minimizes the total cost of moving mass between two probability measures. Given two probability measures and on spaces X and Y, respectively, and a cost function , the optimal transport problem is formulated as:
where denotes the set of all joint probability measures on with marginals and . The solution to this problem defines the Wasserstein distance, which quantifies the minimal cost of transforming one distribution into another.
Training dynamics in machine learning can be analyzed through the lens of optimal transport, particularly when studying the evolution of model parameters or the distribution of data. Optimal transport-based training dynamics focus on minimizing the Wasserstein distance between the model’s output distribution and the target distribution. This approach is especially useful in generative modeling, where the goal is to align the generated samples with the true data distribution. The gradient flow of the Wasserstein distance induces a dynamics that pushes the model parameters toward configurations that minimize the transport cost. For a parameterized model , the optimization problem becomes:
where Q is the target distribution and is the Wasserstein distance with cost function c. The gradient descent update rule for involves computing the gradient of the Wasserstein distance, which can be approximated using the dual formulation of the optimal transport problem.
Sinkhorn divergences provide a computationally efficient alternative to the Wasserstein distance by introducing entropy regularization into the optimal transport problem. The entropy-regularized optimal transport problem is given by:
where is the entropy of the transport plan and is the regularization parameter. The Sinkhorn divergence is then defined as the difference between the regularized optimal transport cost and its self-transport terms:
where denotes the entropy-regularized Wasserstein distance. The Sinkhorn divergence retains many desirable properties of the Wasserstein distance, such as metricity for certain cost functions, while being amenable to efficient computation using iterative scaling algorithms like the Sinkhorn-Knopp algorithm. This makes it particularly suitable for large-scale machine learning applications where exact computation of the Wasserstein distance is infeasible.
In summary, optimal transport theory provides a rigorous foundation for analyzing training dynamics through the minimization of transport costs between distributions. The Wasserstein distance serves as a natural objective for aligning model outputs with target distributions, while Sinkhorn divergences offer a practical and scalable alternative through entropy regularization. These tools enable the development of efficient and theoretically grounded algorithms for generative modeling, domain adaptation, and other machine learning tasks involving distributional alignment.
6.11. Optimal Transport Theory in Neural Architecture and Gradient Flows
Optimal transport theory provides a mathematical framework for comparing probability distributions by minimizing the cost of transporting mass from one distribution to another. The theory is rooted in the Monge-Kantorovich problem, which seeks a transport plan that minimizes the total cost of moving mass between two probability measures. Given two probability measures and on spaces X and Y, respectively, and a cost function , the optimal transport problem is formulated as:
where denotes the set of all joint probability measures on with marginals and . The solution to this problem defines the Wasserstein distance, which quantifies the minimal cost of transforming one distribution into another.
Training dynamics in machine learning can be analyzed through the lens of optimal transport, particularly when studying the evolution of model parameters or the distribution of data. Optimal transport-based training dynamics focus on minimizing the Wasserstein distance between the model’s output distribution and the target distribution. This approach is especially useful in generative modeling, where the goal is to align the generated samples with the true data distribution. The gradient flow of the Wasserstein distance induces a dynamics that pushes the model parameters toward configurations that minimize the transport cost. For a parameterized model , the optimization problem becomes:
where Q is the target distribution and is the Wasserstein distance with cost function c. The gradient descent update rule for involves computing the gradient of the Wasserstein distance, which can be approximated using the dual formulation of the optimal transport problem.
Sinkhorn divergences provide a computationally efficient alternative to the Wasserstein distance by introducing entropy regularization into the optimal transport problem. The entropy-regularized optimal transport problem is given by:
where is the entropy of the transport plan and is the regularization parameter. The Sinkhorn divergence is then defined as the difference between the regularized optimal transport cost and its self-transport terms:
where denotes the entropy-regularized Wasserstein distance. The Sinkhorn divergence retains many desirable properties of the Wasserstein distance, such as metricity for certain cost functions, while being amenable to efficient computation using iterative scaling algorithms like the Sinkhorn-Knopp algorithm. This makes it particularly suitable for large-scale machine learning applications where exact computation of the Wasserstein distance is infeasible.
In summary, optimal transport theory provides a rigorous foundation for analyzing training dynamics through the minimization of transport costs between distributions. The Wasserstein distance serves as a natural objective for aligning model outputs with target distributions, while Sinkhorn divergences offer a practical and scalable alternative through entropy regularization. These tools enable the development of efficient and theoretically grounded algorithms for generative modeling, domain adaptation, and other machine learning tasks involving distributional alignment.
6.12. Geometric Regularization and Barycenters
Geometric regularization in optimal transport theory, particularly in the context of deep neural networks, refers to the imposition of structural constraints on the learned representations or model parameters to ensure they adhere to desirable geometric properties. This regularization leverages the Wasserstein distance, which inherently captures the underlying geometry of the data space, to penalize deviations from a prescribed geometric structure. Given a cost function and two probability measures and , the Wasserstein-p distance is defined as:
where is the set of all joint distributions with marginals and . In deep learning, geometric regularization can be incorporated by adding a Wasserstein-based penalty term to the loss function, ensuring that the learned distributions or feature maps respect the metric structure of the input space. For instance, if is the model’s output distribution and Q is the target distribution, the regularized objective may take the form:
where is the task-specific loss and controls the strength of the regularization. This approach is particularly useful in scenarios where preserving the geometric relationships between data points is critical, such as in manifold learning or domain adaptation.
Barycenters in optimal transport theory generalize the notion of averaging to probability measures on metric spaces, providing a way to compute a "mean" distribution that minimizes the total Wasserstein distance to a set of input distributions. Given a collection of probability measures and weights such that , the Wasserstein barycenter is defined as the solution to:
where is the space of probability measures on . In deep neural networks, barycenters can be employed to aggregate information from multiple sources or to interpolate between distributions in a geometrically meaningful way. For example, in multi-task learning, the barycenter can represent a consensus distribution that balances the objectives of different tasks, while in generative modeling, it can be used to blend styles or features from diverse datasets. The computation of barycenters often relies on iterative algorithms, such as the iterative Bregman projection method or entropy-regularized approximations, which scale efficiently to high-dimensional spaces.
The integration of geometric regularization and barycenters into deep neural networks underscores the power of optimal transport theory in providing principled tools for incorporating geometric constraints into learning algorithms. By leveraging the Wasserstein distance, these methods ensure that the learned representations respect the intrinsic geometry of the data, leading to more robust and interpretable models. The barycenter framework, in particular, offers a flexible mechanism for combining distributions in a way that preserves their structural relationships, making it invaluable for applications ranging from collaborative learning to generative modeling. Together, these concepts highlight the deep interplay between geometry and probability in modern machine learning.
7. Categorical Foundations of Deep Learning
The categorical foundations of deep learning provide a unifying mathematical framework for modeling neural networks as compositional structures within category theory. At its core, this approach formalizes neural architectures as morphisms in a monoidal category, where objects represent data types (e.g., vector spaces ) and morphisms correspond to parameterized functions (e.g., layers of a network). Given a symmetric monoidal category , a neural network is constructed via sequential and parallel compositions of simpler morphisms, governed by the categorical axioms of associativity and unitality. For instance, the composition of layers and is represented by the morphism , satisfying for all compatible h. The monoidal product ⊗ captures parallel processing, as in convolutional or attention layers, where the tensor product of morphisms represents independent transformations of parallel data streams. This framework generalizes backpropagation via functoriality: the derivative of a composite morphism is given by the chain rule, expressed categorically as the composition of the derivative functors , where maps objects to their tangent bundles and morphisms to their Jacobians.
The optimization of neural networks is naturally expressed through universal constructions in category theory. The backpropagation algorithm arises as a right Kan extension in the category of parameterized functions. Let be a category where objects are parameters and morphisms are updates induced by gradient descent. The loss functor sends each parameter configuration to its associated loss value, and the gradient is the universal arrow completing the diagram:
This universal property ensures that backpropagation optimally approximates the directional derivative of with respect to the parameter update strategy. Furthermore, the universal approximation theorem is reformulated categorically as a density result: the hom-set in the category of neural networks is dense in the hom-set of continuous functions under the topology of uniform convergence on compacta.
The categorical lens formalism captures stateful computations in recurrent networks and memory-augmented architectures. A lens consists of a forward map and a backward map , modeling both inference and gradient propagation. In a differentiable programming setting, lenses generalize automatic differentiation by encoding the full computation graph as a morphism in the category , where composition is given by the chain rule for stateful functions:
where . This perspective unifies architectures like LSTMs and neural ODEs, where the lens structure explicitly tracks hidden state dynamics. The hierarchical organization of deep networks is modeled using higher categories, where 2-morphisms represent transformations between layers (e.g., residual connections). For example, a ResNet block is a 2-morphism in the bicategory , where horizontal composition corresponds to sequential layers and vertical composition to skip connections. Symmetries, such as permutation equivariance in graph neural networks, are captured by actions of symmetric monoidal categories , ensuring that morphisms satisfy for permutations .
By grounding deep learning in category theory, these foundations reveal the intrinsic algebraic and geometric structures underlying neural architectures, enabling rigorous analysis of their expressivity, optimization, and generalization.
7.1. Introduction
7.1.1. Motivation: Why Category Theory for Deep Learning?
Deep Learning has achieved remarkable success across domains—from computer vision to natural language processing—yet its theoretical foundations remain fragmented. Traditional mathematical tools (linear algebra, calculus, probability) provide only a local understanding of neural networks, failing to capture their compositional, structural, and relational nature.
Category Theory offers a unifying framework for Deep Learning by:
- Abstraction over computation: Neural networks are fundamentally morphisms (maps) between data representations, and Category Theory provides tools to study compositions of such maps.
- Generalization across architectures: Whether working with CNNs, RNNs, or Transformers, Category Theory allows us to describe them as instances of categorical constructs (e.g., monoidal categories, functors).
- Handling complex data flows: Many Deep Learning constructs (e.g., attention mechanisms, residual connections) are naturally expressed via universal properties (limits, adjunctions).
- Bridging discrete and continuous reasoning: Gradient-based optimization (backpropagation) can be formulated categorically via lenses or reverse derivative categories.
Thus, Category Theory provides a meta-language for Deep Learning, enabling:
- Formal reasoning about model behavior.
- Systematic architecture design via compositionality.
- Novel generalizations (e.g., neural networks over graphs, higher-order interactions).
7.1.2. Limits of Traditional Mathematical Formalism in Modern Machine Learning
While traditional mathematics has been indispensable for Deep Learning, key limitations arise when scaling to modern systems:
- Lack of Compositionality: Deep Learning models are built via hierarchical composition of layers, but linear algebra treats them as sequences of matrix operations without inherent structure. The Category Theory Solution is to represent networks as morphisms in a category, where composition is associative by definition.
- Poor Handling of Complex Data Types: Tensors, graphs, and sequences require ad-hoc notation. Backpropagation, for instance, is often derived via index manipulation rather than structurally. The Category Theory Solution is to use monoidal categories to model tensors and string diagrams for graphical reasoning.
- Opaque Optimization Dynamics: Gradient descent is typically analyzed via local approximations (Taylor expansions), obscuring global behavior. The Category Theory Solution is to use reverse derivative categories (RDCs) to give an abstract formulation of backpropagation.
- Difficulty in Generalizing Architectures: Novel components (e.g., attention, memory) are introduced empirically without a unifying framework. The Category Theory Solution is to use universal properties (e.g., adjunctions) to guide principled extensions.
- Weak Theoretical Guarantees: Traditional theory (e.g., VC dimension) fails to explain the success of overparametrized Deep Learning models. The Category Theory Solution is to use functorial semantics to connect learning to algebraic invariants.
7.1.3. Overview of the Chapter and Learning Goals
Category Theory provides a powerful framework for understanding and designing Deep Learning models by abstracting their compositional structure and behavior. This chapter develops CT for DL systematically, with the following structure:
- Categories and Functors: At its core, a category formalizes the notion of objects (such as data spaces) and morphisms (such as neural network layers) that can be composed associatively. Functors extend this by mapping one category to another, preserving structure—allowing us to describe how neural architectures transform data systematically. We shall discuss the basic definitions, examples (e.g., FeedForwardNet, the category of neural networks).
- Universal Constructions: Universal constructions, including products and limits, characterize optimal ways to combine or relate objects. In Deep Learning, these appear in architectures like residual networks, where skip connections arise as coproducts, or attention mechanisms, which aggregate information universally. The ability to reason about such constructions enables principled architecture design rather than relying on intuition alone. We shall discuss the products, coproducts, and how they relate to branching architectures (e.g., ResNet skip connections).
- Monoidal Categories: Monoidal categories introduce tensor products, capturing parallel computation and multi-dimensional data flow. This framework elegantly models operations in convolutional networks or transformers, where tensor contractions and parallel processing are fundamental. String diagrams, a graphical notation from monoidal categories, offer an intuitive way to visualize and manipulate complex network structures. We shall discuss the modeling of tensors and parallel computation (e.g., CNNs as functors).
- Lenses and Backpropagation: Differentiation and optimization, central to Deep Learning, are naturally expressed using lenses and reverse derivative categories. A lens pairs a forward pass (evaluation) with a backward pass (gradient propagation), abstracting backpropagation as a compositional process. This shifts gradient-based learning from an algorithmic procedure to a categorical construct, clarifying its mathematical essence. We shall discuss the categorical differentiation via reverse derivative categories.
- Higher-Order Abstractions: Higher-order abstractions like adjunctions and monads further extend the expressive power of the framework. Adjunctions formalize relationships between paired functors, such as encoder-decoder networks in autoencoders, while monads model computational effects like stochasticity in dropout or reinforcement learning. These tools allow us to describe complex behaviors—such as memory, recursion, or attention—in a unified way. We shall discuss the adjunctions, monads, and their role in attention/ memory mechanisms.
Category theory does not replace traditional ML theory but extends it with a higher-level language for compositionality, abstraction, and generalization. By adopting CT, we gain tools to:
- Design models more systematically.
- Analyze them more rigorously.
- Discover new architectures more confidently.
The next sections will make these ideas precise, starting with the definition of a category and its applications to DL. Together, these categorical concepts provide a rigorous foundation for Deep Learning, transforming empirical practices into structured mathematical principles. By viewing neural networks as morphisms in appropriate categories, we gain a language for compositionality, optimization, and generalization—bridging the gap between abstract theory and practical implementation. This perspective not only clarifies existing architectures but also guides the invention of new ones, offering a pathway toward more systematic and interpretable machine learning.
7.2. Category Theory Primer for Machine Learners
We shall now discuss the foundational mathematical framework to describe the structure and compositionality inherent in machine learning models through the language of categories. At its core, a category consists of a collection of objects (e.g., data spaces, model architectures) and morphisms (e.g., parameterized functions, layers) between these objects, equipped with an associative composition operation and identity morphisms. For machine learning, the category is often informally considered, where objects are spaces of data representations (e.g., for n-dimensional feature vectors) and morphisms are learnable maps (e.g., neural network layers) parameterized by . Composition of morphisms and yields a new morphism , corresponding to the forward pass of a neural network:
The identity morphism represents the trivial transformation , though in practice, exact identities may be approximated due to architectural constraints. Universal constructions in category theory provide templates for common machine learning paradigms. The product of objects X and Y, denoted , models parallel data processing (e.g., multi-modal inputs), with projection morphisms and extracting components. Dually, the coproduct represents disjoint unions (e.g., batch concatenation). Limits and colimits generalize these notions to arbitrary diagrams, capturing architectures like attention mechanisms, where the output is a weighted limit of input features. For instance, the attention operation for queries Q, keys K, and values V can be viewed as a colimit construction:
where the softmax computes a convex combination of values, analogous to a categorical colimit over the alignment scores.
Functors map one category to another while preserving structure, offering a formalism for model transformations and embeddings. A loss functor might map learnable morphisms to their associated loss landscapes, where is a category of metric spaces. Natural transformations between functors describe parameter updates: for a model , gradient descent induces a natural transformation , where is the loss function and the learning rate. Adjunctions formalize optimization paradigms, such as the free-forgetful adjunction between unstructured data (e.g., raw images) and structured representations (e.g., latent embeddings), where the left adjoint F constructs a representation and the right adjoint U forgets it:
Monoidal categories capture parallel computation in neural networks. The tensor product represents parallelized data (e.g., channels in a convolutional layer), with morphisms acting independently on subsystems. The interchange law reflects the locality of operations like convolutions. String diagrams provide a graphical calculus for such settings, where wires represent data flow and boxes represent layers, simplifying proofs of network properties. Abstraction and generalization in machine learning are formalized via universal properties. For example, an universal approximator (e.g., an MLP) satisfies a universal property: for any continuous and , there exists a morphism (neural network) such that on compact . This mirrors the universal property of polynomial approximation in Stone-Weierstrass theorem. Sheaf theory further refines this by modeling local-to-global learning (e.g., graph neural networks), where data is structured as a presheaf and predictions are glued from local patches.
In summary, category theory provides a unifying language for machine learning, where models are morphisms, training is functorial optimization, and architectures are universal constructions. This framework bridges abstract mathematical principles with concrete implementations, revealing the compositional essence of learning systems while accommodating their statistical and approximate nature.
7.2.1. Basic Definitions: Categories, Functors, Natural Transformations, Adjunctions, Monoidal Categories
7.2.1.1 Categories A category consists of:
- A collection of objects (e.g., sets, vector spaces).
- For every pair , a set of morphisms (arrows) .
- A composition rule ∘ such that for and , there exists .
- An identity morphism for each object, satisfying:
- Associativity: For ,
A category is a fundamental mathematical structure that formalizes the notion of mathematical objects and the relationships between them through a precise algebraic framework. Formally, a category consists of two primary components: a collection of objects and a collection of morphisms satisfying specific axiomatic conditions. The objects, denoted by , represent the entities of interest within the category, which could be sets, vector spaces, topological spaces, or any other mathematically definable constructs. The morphisms, also called arrows, represent structure-preserving maps between these objects. For every pair of objects , there exists a set whose elements are the morphisms from X to Y. Each morphism is denoted as , where X is the domain and Y is the codomain.
The structure of a category is governed by two fundamental operations: composition and identity. Composition is a binary operation that takes two morphisms and and produces a composite morphism . This operation must satisfy the associativity axiom, which states that for any three morphisms , , and , the following equality holds:
This axiom ensures that the order in which compositions are evaluated does not affect the result, making the algebraic structure coherent. The second operation is the existence of an identity morphism for every object. Specifically, for each object , there exists a distinguished morphism such that for any morphism , the identities act as neutral elements for composition:
These axioms collectively ensure that the morphisms behave consistently under composition and that each object has a trivial self-map.
The power of category theory lies in its ability to abstract and generalize mathematical concepts across diverse fields. For instance, in the category , the objects are sets, and the morphisms are ordinary functions between sets. In , the objects are vector spaces over a field , and the morphisms are linear transformations. The categorical framework allows these seemingly distinct mathematical domains to be studied under a unified language, where universal properties, functors, and natural transformations become the tools for analysis. The abstract nature of categories enables mathematicians to distill the essence of mathematical structures, focusing on their relational properties rather than their internal constitution. This perspective has profound implications in areas ranging from algebraic topology to theoretical computer science and, more recently, in the formalization of machine learning architectures.
The notion of commutativity is central to category theory and is often visualized through commutative diagrams. A diagram in a category is said to commute if all paths between any two objects yield the same morphism under composition. For example, given morphisms and , the commutativity of the diagram:
expresses the equality , which trivially holds but illustrates the diagrammatic reasoning pervasive in category theory. More complex diagrams encode richer algebraic conditions, such as universal properties, which characterize objects like products, coproducts, and limits up to unique isomorphism. These properties are foundational in constructing and understanding categorical structures across mathematics.
In summary, a category is an algebraic structure that abstracts the relationships between mathematical objects through morphisms, composition, and identities, governed by axioms ensuring associativity and the existence of neutral elements. This abstraction provides a powerful language for unifying diverse mathematical disciplines and has become indispensable in modern theoretical frameworks, including those in machine learning. The rigorous formulation of categories enables precise reasoning about structure-preserving mappings, universal properties, and hierarchical constructions, making it a cornerstone of contemporary mathematics.
7.2.1.2 Functors A (covariant) functor between categories consists of:
- A mapping on objects.
-
For each morphism in , a morphism in , preserving:
- −
- Identities: .
- −
- Composition: .
A contravariant functor reverses arrows: .
A functor is a structure-preserving mapping between categories that serves as the fundamental notion of morphism in the realm of category theory. Formally, given two categories and , a (covariant) functor consists of two components that respect the categorical structure. First, it associates to each object an object . Second, to each morphism in , it assigns a morphism in . This assignment must satisfy the twin conditions of preserving identity morphisms and composition of morphisms. For every object , the functor preserves the identity morphism as follows:
ensuring that the identity structure is maintained under the mapping. For composable morphisms and in , the functor preserves composition through the equation:
which guarantees that the image of a composite morphism equals the composite of the images, thereby maintaining the compositional structure of the original category.
The contravariant functor represents a dual notion where the direction of morphisms is reversed. Specifically, a contravariant functor maps each morphism in to a morphism in , reversing the arrow direction while still preserving identities and composition. The composition preservation for contravariant functors takes the form:
where the order of composition is inverted compared to the covariant case. This reversal captures important mathematical phenomena such as duality in vector spaces, where the dual space functor sends each linear map to its transpose .
Functors serve as the primary vehicles for transporting mathematical structures between different categorical contexts. The power of functoriality lies in its ability to systematically relate disparate mathematical domains while preserving their essential structural relationships. For instance, the fundamental group functor maps pointed topological spaces to their fundamental groups and continuous maps to group homomorphisms, translating topological problems into algebraic ones. Similarly, in algebraic geometry, the spectrum functor establishes a bridge between commutative rings and topological spaces through the contravariant correspondence of prime ideals and Zariski topology.
The naturality condition for functors becomes particularly significant when considering their behavior with respect to transformations between categories. A natural transformation between two functors consists of a family of morphisms for each that commute with the images of morphisms under the functors. This means that for every morphism in , the following diagram commutes:
expressing the coherence condition . Natural transformations formalize the notion of consistent translation between different functorial perspectives on the same categorical data.
The ubiquity of functors in modern mathematics stems from their capacity to systematically capture structural parallels across diverse mathematical domains. In representation theory, group representations are understood through functors from the delooping of a group to vector spaces. In algebraic topology, homology and cohomology theories are realized as functors from topological categories to graded algebraic structures. The categorical language of functors provides a unifying framework that reveals deep connections between apparently unrelated mathematical constructions, while the rigorous preservation of composition and identities ensures the structural integrity of these connections. This makes functors indispensable tools not only in pure mathematics but also in theoretical computer science, where they model type constructors and computational effects, and in mathematical physics, where they describe symmetries and state space transformations.
7.2.1.3 Natural Transformations Given functors , a natural transformation assigns to each a morphism such that for every in , the following naturality condition holds:
A natural transformation represents a systematic way to transform one functor into another while respecting the underlying categorical structure. Formally, given two parallel functors between the same categories, a natural transformation consists of a family of morphisms indexed by the objects of , where for each object , there exists a component morphism in . These components must satisfy the naturality condition, which ensures that for every morphism in , the following diagram commutes:
This diagrammatic condition translates algebraically to the equation , expressing the coherence of the transformation across all morphisms in the category. The naturality condition guarantees that the transformation behaves uniformly with respect to the action of the functors on both objects and morphisms, making it a proper morphism between functors in the functor category .
The concept of naturality captures the mathematical intuition of "canonical" or "universally defined" transformations that depend solely on the categorical structure, without arbitrary choices. For instance, in the category of vector spaces over a field k, the double dual embedding defined by for and forms a natural transformation from the identity functor to the double dual functor. The naturality of this transformation means that for any linear map , the following equality holds:
where denotes the double dual map induced by T. This equation verifies that the embedding commutes with the application of linear maps, demonstrating that the transformation respects the linear structure across all vector spaces and their morphisms.
Natural transformations play a pivotal role in category theory by enabling the comparison of functors and the formulation of universal properties. They serve as the 2-morphisms in the 2-category of categories, where objects are categories, 1-morphisms are functors, and 2-morphisms are natural transformations. This hierarchical structure allows for the expression of sophisticated mathematical concepts, such as adjunctions and equivalences between categories, which can be characterized through natural isomorphisms—natural transformations where every component is an isomorphism. For example, an adjunction between functors and consists of a pair of natural transformations and satisfying the triangle identities:
These identities ensure the coherence of the adjunction, providing a rigorous framework for understanding dualities and universal constructions across mathematics. In algebraic topology, for instance, the Hurewicz transformation from homotopy groups to homology groups constitutes a natural transformation that preserves the topological structure, facilitating the translation between homotopy-theoretic and homological data. Similarly, in algebraic geometry, the sheafification functor comes equipped with a natural transformation from the identity functor to the sheafification functor, reflecting the universal property of sheafification.
The power of natural transformations lies in their ability to formalize the notion of structure-preserving mappings between different representations of the same categorical data. This capability is crucial in areas such as functional programming, where natural transformations between type constructors ensure the correctness of polymorphic functions, and in theoretical physics, where they model symmetries and dualities between physical theories. By providing a rigorous language for comparing and transforming functorial constructions, natural transformations unify diverse mathematical phenomena under a common conceptual framework, revealing deep connections between seemingly unrelated areas of mathematics and science.
7.2.1.4 Adjunctions
Adjunctions in Category Theory formalize profound relationships between pairs of functors, capturing a notion of "approximate equivalence" or "duality" between categories. Given two categories and , an adjunction consists of functors (the left adjoint) and (the right adjoint), together with a natural isomorphism between hom-sets:
for all objects and . This isomorphism must be natural in both X and Y, meaning that for any morphisms in and in , the following diagrams commute:
Here, denotes precomposition with , and denotes postcomposition with g. An equivalent formulation uses the unit and *counit* , which are natural transformations satisfying the triangle identities:
The unit universalizes the "embedding" of X into its image under the adjunction, while the counit evaluates or "realizes" the abstractly constructed object . For example, in the adjunction between the free group functor and the forgetful functor , the unit injects a set X into its free group, and the counit maps a group back to its underlying set.
Adjunctions generalize universal constructions: limits/colimits arise as adjoints to diagonal functors, and tensor-hom adjunctions in closed categories () encode currying. In machine learning, adjunctions model optimization (e.g., latent representation learning), where F constructs features and G decodes them, with the adjunction ensuring coherence between encoding and reconstruction. The naturality of the hom-set isomorphism reflects the stability of these processes under transformations of inputs or outputs. Adjunctions also underlie Kan extensions, where left/right adjoints to precomposition functors extend diagrams universally. For a functor and category , the left Kan extension is the left adjoint to precomposition , providing a way to "complete" partial diagrams. This abstract machinery clarifies phenomena like gradient descent (a Kan extension of loss functions along optimization paths) and attention mechanisms (extensions of local feature interactions).
In essence, adjunctions are the "optimal" relationships between categories, where one functor approximates the inverse of another, governed by universal properties and natural coherence conditions. They unify seemingly disparate constructions across mathematics and machine learning, from algebraic duality to neural network training dynamics, through a precise language of compositional equivalence.
7.2.1.5 Monoidal Categories
Monoidal categories provide a rigorous mathematical framework for capturing parallel computation in neural networks by formalizing the algebraic structure of simultaneous, independent operations across multiple data streams. At the core of this formalism lies the tensor product ⊗, which represents the parallel combination of objects (data spaces) and morphisms (network layers). In the category of neural networks, objects are vector spaces (or more generally, manifolds of activations), and the tensor product corresponds to the concatenation of parallel data streams—such as the channels in a convolutional layer or the heads in a multi-head attention mechanism. Morphisms between these combined spaces act independently on their respective subspaces, defined for and by:
where and are individual layer operations with weights and biases . This operation preserves the separability of parallel computations until explicitly combined by subsequent layers.
The monoidal unit (a trivial space) serves as the identity for ⊗, with isomorphisms reflecting that augmenting a network with empty data leaves it unchanged. The associativity of ⊗ is captured by the natural isomorphism , which permits the re-parenthesization of parallel streams—a property critical for modular network architectures like ResNets, where skip connections and branches must coherently merge. For neural networks, this translates to the equivalence of processing pipelines like and , ensuring that the order of combining parallel paths does not affect the final output. The interchange law governs the interaction between sequential and parallel composition, stating that for morphisms and , the following equality holds:
This law ensures that parallel and sequential operations commute in a well-defined manner, mirroring the locality of operations in convolutional networks or attention layers, where filters or attention heads process inputs independently before aggregation. Violations of this law due to non-linearities (e.g., activation functions) are mitigated by the approximate linearity of learned representations in practice.
Symmetric monoidal categories further introduce a braiding isomorphism , which models the permutation of parallel data channels. In neural networks, this captures operations like channel shuffling in ShuffleNet or the reordering of attention heads, where swaps subspaces without altering the underlying computation. The coherence conditions for —such as —guarantee that permuting and reverting returns the original configuration, a property leveraged in equivariant networks designed for symmetric inputs. The closure property of monoidal categories, when present, internalizes the space of parallelizable operations. In , the hom-object represents the space of all possible layers from A to B, and the isomorphism encodes the currying of parallel operations—a abstraction foundational to attention mechanisms, where keys, queries, and values are processed in parallel before interaction. The evaluation morphism then corresponds to the application of an attention head to its inputs.
In summary, monoidal categories rigorously axiomatize the parallel computation in neural networks through the tensor product ⊗, its associativity, unit, and interchange laws, while symmetry and closure properties model advanced architectural features. This framework abstracts the algebraic essence of parallelism, providing a unified language to reason about complex network architectures and their compositional invariants.
7.2.2. Use of String Diagrams and Abstraction and Generalization in Machine Learning
7.2.2.1 String Diagrams as Graphical Calculus for Neural Networks
String diagrams furnish a rigorous graphical calculus for reasoning about monoidal categories, offering an intuitive yet mathematically precise representation of neural network architectures where wires denote data flow (objects) and boxes (nodes) represent layers (morphisms). The formalism is grounded in the Penrose graphical notation, which translates categorical axioms into topological equivalences of diagrams, enabling syntactic manipulations that preserve semantic meaning. In the context of neural networks, a layer is depicted as a box with an input wire (of type ) entering from below and an output wire (of type ) exiting above:
 Composition of layers corresponds to vertical stacking of boxes, while the tensor product for parallel layers is represented by horizontal juxtaposition:
 The interchange law becomes a geometric triviality in string diagrams, as the equality manifests as isotopic deformation of the graph (sliding boxes past each other without cutting wires):
 Coherence conditions of monoidal categories (associativity, unit laws) are implicitly enforced by the diagrammatic syntax. For instance, associativity of ⊗ () corresponds to the absence of parentheses in diagrams-wires may freely cross or bend, as the underlying topological equivalence classes abstract over syntactic re-bracketing. The unit object I is represented by the absence of a wire, and the unit isomorphisms and are rendered as "yanking" wires straight:
 Symmetry in braided monoidal categories introduces crossings of wires, represented by the natural isomorphism . In neural networks, this captures operations like channel shuffling or attention head permutation, where swaps two parallel data streams:
 Evaluation and currying in closed monoidal categories are depicted as caps and cups. For a layer , its curried form is represented by bending the input wire B into an output:
 Neural network properties reduce to diagrammatic simplifications. For example, the universality of a multilayer perceptron (MLP) corresponds to the fact that any diagram of wires and boxes can be approximated (up to ) by a sufficiently large subdiagram of MLP layers. Residual connections are represented as a fork where the identity wire bypasses the box for f:
 The backpropagation algorithm arises as the dual (mirror image) of the forward pass diagram, with gradients flowing backward along reversed wires-a manifestation of the time-reversal symmetry in string diagrams for autonomous categories.
In essence, string diagrams distill the algebraic structure of neural networks into topological invariants, where equivalence of diagrams under deformation encodes equality of morphisms. This graphical calculus not only simplifies proofs of network properties (e.g., universality, equivariance) but also guides architectural design through visual intuition, bridging categorical abstraction and engineering practice.
7.2.2.2 Abstraction and Generalization in Machine Learning
Abstraction and generalization in machine learning are rigorously formalized through universal properties in category theory, which characterize mathematical objects by their relationships to all other objects in a category rather than by their internal structure. A universal property specifies that a particular construction is the "most efficient" solution to a given problem, unique up to isomorphism. In machine learning, this manifests when a model architecture or learning algorithm satisfies conditions that make it optimally representative or predictive across a class of problems.
For a learning task where data X is mapped to targets Y through some ground truth function , a universal approximator (e.g., a neural network) satisfies the following universal property: for any and compact , there exists a parameterization such that:
This universality is analogous to the universal property of free objects in algebra, where the free group on a set S satisfies: for any group G and map , there exists a unique homomorphism extending f. Here, is the "most general" group containing S, just as a universal approximator is the "most general" function approximator for f. The universal property of optimization formalizes gradient descent as a universal arrow in the category of loss landscapes. Given a loss functor , mapping parameters to metric spaces of their loss values, gradient descent constructs a universal morphism to the global minimum : for any initial , there exists a sequence of updates converging to under appropriate conditions. This universality is expressed via the commutativity of:
where the diagram commutes as the loss decreases monotonically.
Generalization is formalized through universal properties of Kan extensions, which extend partial models to complete ones. Given a training dataset (a functor from a small index category ), the left Kan extension of a model F along D computes the "best approximation" of F on unseen data. This universal property is expressed by the natural isomorphism:
where G is any candidate model. The right-hand side represents training-set performance, while the left-hand side captures generalization, making the Kan extension the optimal balance between the two. In representation learning, the universal property of quotients formalizes abstraction. For a data space X with equivalence relation ∼ (e.g., invariance to nuisance factors), the quotient map satisfies: any ∼-invariant map factors uniquely through q as . In deep learning, this corresponds to the encoder-decoder paradigm:
where Z is the latent space of abstract representations, and the encoder realizes the quotient by discarding ∼-irrelevant information. The universality ensures Z is the "most efficient" such space, justifying architectures like VAEs. Attention mechanisms are characterized by universal properties in monoidal categories. The attention operation is universal among all bilinear maps from that respect the query-key-value structure, expressed by the commuting diagram:
where is any other bilinear operation. This universality explains why attention can approximate arbitrary sequence-to-sequence operations given sufficient heads.
The universal property of neural networks thus lies at the intersection of approximation theory (Stone-Weierstrass), optimization (gradient descent as universal arrow), and representation (quotients and Kan extensions). These properties collectively ensure that well-designed ML systems are both maximally expressive (abstracting patterns) and minimally biased (generalizing beyond training data), with the category-theoretic framework providing the language to prove such claims rigorously.
7.2.3. Examples from Familiar Settings
7.2.3.1 Category of Sets ()
- Objects: Sets.
- Morphisms: Functions .
-
Functors:
- −
- The powerset functor maps A to its power set and to the direct image .
-
Natural Transformation:
- −
- The singleton map , where , is natural because for any ,
The category of sets, denoted Set, constitutes a foundational object in category theory where objects are all possible sets and morphisms are all possible functions between these sets. Formally, Set is defined as follows: for any two objects A and B in Set, the hom-set consists of all functions . Composition of morphisms is given by ordinary function composition: for and , the composite is defined by for all . This composition operation is strictly associative, meaning for all composable functions , and the identity morphism for each set A is the function defined by for all , satisfying and for any .
The category Set is Cartesian closed, meaning it possesses all finite products and exponentials. The product of two sets A and B is their Cartesian product , equipped with projection morphisms and defined by and . The universal property of the product states that for any set X and morphisms and , there exists a unique morphism such that and . The exponential object represents the set of all functions from A to B, with evaluation morphism defined by . This structure ensures that for any morphism , there exists a unique morphism such that .
Set also admits all limits and colimits, making it complete and cocomplete. The limit of a diagram is given by the set of cones over D, while the colimit is the quotient of the disjoint union of sets in D under an appropriate equivalence relation. For instance, the equalizer of two functions is the subset with inclusion , satisfying . Dually, the coequalizer is the quotient set , where ∼ is the smallest equivalence relation containing all pairs for , with projection satisfying .
The category Set serves as a canonical example of a topos, a category with Cartesian closure, finite limits, and a subobject classifier. The subobject classifier in Set is the two-element set , equipped with the characteristic function for any subset , defined by if and false otherwise. This structure allows Set to internalize logic via its subobject lattice, where logical operations correspond to set-theoretic operations on subsets.
Monomorphisms in Set are precisely the injective functions, characterized by the left-cancellation property: is monic if for all functions , implies . Epimorphisms are the surjective functions, satisfying the dual right-cancellation property. Isomorphisms are bijections, i.e., functions that are both injective and surjective. The Yoneda embedding maps each set A to its representable functor , demonstrating that Set is a locally small category where every object is determined by its relationships to other objects via morphisms.
The functor category for any small category inherits many properties from Set, including completeness and cocompleteness, making Set a foundational tool for studying presheaves and sheaves in algebraic geometry and logic. The interplay between Set and other categories is mediated by adjunctions, such as the free-forgetful adjunction between Set and categories of algebraic structures (e.g., groups, rings), where the free functor assigns to each set the free group generated by its elements, and the forgetful functor returns the underlying set of a group. This adjunction satisfies the natural isomorphism for any set A and group G.
In summary, Set provides a universal framework for mathematical constructions through its rich categorical structure, serving as the archetypal model for concepts like limits, adjunctions, and topos theory. Its role extends beyond foundations, offering concrete intuition for abstract categorical notions while maintaining rigorous formal power.
7.2.3.2 Category of Vector Spaces ()
- Objects: Vector spaces over .
- Morphisms: Linear maps .
-
Functors:
- −
- The dual space functor maps V to and to its transpose .
-
Natural Transformation:
- −
- The double dual embedding , where , is natural because for any linear ,
The category of vector spaces over a field , denoted , constitutes a fundamental example of an abelian category in which objects are vector spaces over and morphisms are -linear transformations between them. Formally, for any two objects V and W in , the hom-set consists of all linear maps satisfying for all and . Composition of morphisms is given by the standard composition of linear maps, which preserves linearity: for and , the composite is defined by . This composition is strictly associative, and the identity morphism is the linear operator , satisfying for any .
The category is enriched over itself, meaning that each hom-set naturally carries the structure of a -vector space. The vector space operations on are defined pointwise: for and , the sum and scalar multiple are given by and . This enrichment is compatible with composition, which is bilinear: and for all appropriately composable linear maps. The zero morphism is the linear map sending every to the zero vector in W.
is a monoidal category with respect to the tensor product . The tensor product of two vector spaces is characterized by the universal property that any bilinear map factors uniquely through a linear map . This gives the adjunction , where denotes the set of bilinear maps. The monoidal unit is the field itself, viewed as a one-dimensional vector space over itself, with natural isomorphisms for any .
Finite products and coproducts coincide in , both being given by the direct sum . The projections and are linear maps defined by and , while the inclusions and are given by and . The universal properties of product and coproduct are satisfied: for any linear maps and , there exists a unique linear map such that and ; dually, for any and , there exists a unique linear map such that and .
The category is abelian, meaning it has all kernels and cokernels, every monomorphism is a kernel, and every epimorphism is a cokernel. The kernel of a linear map is the subspace equipped with the inclusion , while the cokernel is the quotient space with the projection . A sequence is exact at W if and only if , and short exact sequences correspond to situations where T is injective, S is surjective, and .
The duality between vector spaces and their duals is captured by the contravariant functor . For finite-dimensional vector spaces, this duality is perfect: the canonical map given by is a natural isomorphism. This reflects the fact that is a compact closed category, where the dual space serves as the left and right dual of V with evaluation and coevaluation maps and defined by and for a basis of V with dual basis of .
The functor category for any small category inherits the abelian structure from , with all limits and colimits computed pointwise. This makes a central object in representation theory, where representations of groups, algebras, or other structures are studied as functors into . The tensor-hom adjunction further enriches the categorical structure, making a closed monoidal category.
In summary, provides a rich framework for linear algebra through its categorical properties, serving as a paradigmatic example of an abelian, monoidal, and compact closed category. Its structure facilitates the study of linear transformations, duality, and higher-dimensional algebraic constructs while maintaining deep connections to other branches of mathematics through representation theory and homological algebra.
7.2.3.3 Category of Neural Networks (Informal Example)
- Objects: Data spaces (e.g., ).
- Morphisms: Neural network layers (e.g., affine maps ).
-
Functors:
- −
- A training functor could map a network architecture to its trained parameter space.
The category of neural networks can be informally conceptualized as a categorical framework where objects represent data spaces (typically Euclidean spaces ) and morphisms correspond to parameterized neural network layers. For a fixed activation function , each morphism is defined by a parameter set where is a weight matrix and is a bias vector, with the layer operation given by . Here, is applied component-wise, and the parameter space for each morphism is the manifold of possible weights and biases. Composition of morphisms and yields a new morphism with parameters , where . This composition is associative up to the non-linearities introduced by , and the identity morphism is theoretically given by , though exact implementation requires to be the identity function and , which is often violated in practice due to architectural constraints.
The categorical structure becomes non-trivial when considering parallel compositions via monoidal products. Given two layers and , their tensor product is defined by block-diagonal weight matrices and concatenated biases: . This models architectural features like multi-head attention or residual connections, where parallel processing occurs. The interchange law holds only approximately due to activation function non-linearities, reflecting the empirical behavior of neural networks where parallel and sequential compositions interact non-ideally.
Universal properties in this category are relaxed to approximate versions. For instance, the "universal approximation" property of neural networks corresponds to the existence of a morphism that -approximates any continuous function on compact subsets, where is an error tolerance. This is expressed as for all , with K compact. The categorical product is replaced by a weakened notion where the diagram commutes only up to , reflecting the optimization-driven nature of neural networks. For a network N composed of layers , the actual computation approximates the idealized composition due to numerical errors and training imperfections.
This informal category differs from classical mathematical categories in its tolerance for approximation errors and its reliance on optimization to instantiate morphisms. The "functoriality" of neural architectures is observed empirically: a computational graph maps to a network in the category, but the functor laws and hold only approximately after training. The category thus captures the pragmatic essence of neural networks as composable, parameterized functions whose categorical structure emerges statistically through gradient-based optimization rather than through exact algebraic satisfaction of axioms.
7.2.4. Diagrams as Proofs and Reasoning Tools
In category theory, diagrams serve as rigorous proof tools through the formal machinery of commutative diagrams, where the equality of morphisms along different paths is guaranteed by the underlying categorical structure. A diagram commutes when for any two objects X and Y and all paths of morphisms between them, the composition of morphisms along each path yields identical results. For example, given morphisms , , and , the triangular diagram:
 commutes if and only if . This condition imposes an algebraic constraint on the morphisms, ensuring coherence in the categorical structure. Diagrams generalize equational reasoning to higher-dimensional compositions. The pasting lemma formalizes how smaller commutative diagrams can be glued along common morphisms to form larger commutative diagrams. Given two commuting squares sharing a morphism :
 the commutativity of the left square () and right square () implies the commutativity of the outer rectangle (). This compositional property mirrors the associativity of morphisms and extends to diagrams of arbitrary complexity. Universal constructions, such as limits and colimits, are defined via universal properties expressed through commutative diagrams. A product of objects A and B is characterized by a universal cone:
 such that for any object X with morphisms and , there exists a **unique** morphism making the diagram commute:
This universal property ensures that the product is uniquely determined up to isomorphism, and similar diagrams define coproducts, equalizers, and other categorical limits.
In categorical logic, string diagrams provide a graphical calculus for reasoning in monoidal categories, where morphisms are represented as boxes and composition as wiring. The interchange law:
is visually evident in string diagrams, where vertical stacking represents composition and horizontal juxtaposition represents the tensor product. This graphical language rigorously captures the algebraic structure while simplifying proofs of coherence conditions in symmetric monoidal categories. Diagrams also formalize adjunctions and Kan extensions through bijective correspondences between hom-sets. An adjunction between functors and is encoded by the natural isomorphism:
which can be represented as a family of commuting diagrams expressing the unit and counit . These diagrams enforce the triangle identities:
ensuring the coherence of the adjunction.
Thus, diagrams in category theory are not merely illustrative but constitute formal proofs through their commutativity conditions, universal properties, and graphical equivalences. They provide a synthetic language for expressing complex algebraic relationships, reducing intricate equational reasoning to diagrammatic manipulations that preserve categorical structure.
7.2.4.1 Commutative Diagrams A diagram commutes if all paths between two objects yield the same morphism. For example, the naturality square for :
Commutative diagrams constitute the visual language of category theory, providing a rigorous graphical calculus for expressing algebraic relationships between morphisms. Formally, a commutative diagram in a category is a directed graph whose vertices represent objects and whose edges represent morphisms, where the fundamental property asserts that all paths between any two vertices yield identical morphisms through composition. This means that for any pair of objects in the diagram, given two parallel paths and from X to Y, the equality must hold in . The canonical example appears in the definition of natural transformations, where for and , the square:
commutes by naturality, expressing the equation . This single diagram encapsulates the coherence condition that each component must satisfy relative to every morphism in the category. The power of this notation lies in its ability to compress complex algebraic identities into topological configurations of arrows, where the commutativity constraint ensures the consistency of the categorical structure.
The universality of commutative diagrams emerges through their capacity to characterize limits and colimits. A cone over a diagram consists of an object L with morphisms for each , making all induced triangles commute. The limit object satisfies the universal property that for any other cone , there exists a unique morphism rendering commutative all diagrams:
for every . Dually, colimits reverse all arrows while preserving commutativity. These diagrammatic conditions distill infinite verbal descriptions into finite graphical data, where the universal morphism u’s uniqueness follows from the commutativity constraints on all possible paths.
In abelian categories, commutative diagrams acquire enhanced potency through exact sequences and homology. The snake lemma’s proof revolves around the meticulous construction of a commutative diagram connecting kernels to cokernels:
where exactness and commutativity jointly induce the connecting homomorphism . Each commutative subdiagram encodes specific algebraic relations, while their collective commutativity ensures the lemma’s validity. The diagram serves not merely as illustration but as the actual mathematical object of study, where the geometric arrangement of arrows carries equational content.
Higher-dimensional category theory extends commutative diagrams to higher commutativity through pasting diagrams in 2-categories. For 2-morphisms and , their vertical and horizontal compositions must satisfy the interchange law, visualized through the commutativity of:
where the equality of pastings expresses the coherence between different compositions of 2-cells. This elevates commutative diagrams from planar graphs to higher-dimensional structures, where commutativity becomes homotopy coherence in -categories. The strict commutativity of 1-categorical diagrams generalizes to coherent homotopy commutativity in higher categories, mediated by systems of higher morphisms.
7.2.4.2 Universal Properties via Diagrams
A product is defined by a universal property: for any object Z with morphisms and , there exists a unique making the following commute:
where are projections.
Universal properties in category theory are most powerfully expressed through commutative diagrams that capture the essential uniqueness and existence conditions characterizing mathematical constructions. Formally, a universal property describes an object and morphisms that are either initial or terminal with respect to some diagrammatic condition, where this extremality is expressed through the existence of a unique factorization. The product of two objects , for instance, is defined by a universal cone consisting of the object equipped with projection morphisms and , such that for any other object Z with morphisms and , there exists a unique morphism making the following diagram commute:
This universal property simultaneously asserts existence through the morphism u and uniqueness through its distinctiveness in satisfying the commutative conditions. The product’s universal property thus reduces the infinite collection of possible cones to a single optimal solution, where the commutativity constraints enforce the precise alignment of structural relationships.
Colimits dualize this construction by reversing all arrows while preserving the universal factorization property. The coproduct is characterized by injection morphisms and such that for any object Z with morphisms and , there exists a unique rendering commutative:
The diagrammatic formulation encodes the coproduct’s universal mapping property as a terminal object in the category of cocones, where the existence of u mediates between the individual morphisms and their joint extension through the coproduct.
More sophisticated universal constructions like equalizers and pullbacks exhibit richer diagrammatic conditions. The equalizer of parallel morphisms is an object E with morphism satisfying , universal for this property in that any with factors uniquely through e:
The pullback of morphisms and extends this to a two-dimensional universal property, where the pullback square commutes and is universal among all such commuting squares:
Every pair of morphisms and with induces a unique making all resulting triangles commute. These diagrammatic universal properties collectively form the blueprint for categorical constructions, where the diagrams themselves become the definitions rather than mere illustrations. The universality is precisely the requirement that certain diagrams commute and that solutions to specified diagrammatic conditions exist and are unique up to isomorphism. This diagrammatic approach provides a unified language for universal properties across all branches of mathematics, from algebra to topology to logic, where the same categorical patterns recur in different concrete instantiations.
7.2.4.3 Applications in ML
- Backpropagation as a Functorial Diagram: The chain rule can be expressed as a commuting diagram in the category of differentiable functions.
- Attention Mechanisms: The query-key-value interaction in transformers can be modeled as a limit diagram.
7.2.4.3.1 Backpropagation as a Functorial Diagram
Backpropagation in neural networks admits a rigorous categorical formulation as a functor between appropriately defined categories of differentiable functions. Consider the category whose objects are Euclidean spaces and whose morphisms are differentiable functions , and the category whose objects are parameter spaces and whose morphisms are parameter updates. The backpropagation functor acts on morphisms by sending each differentiable function (where denotes the parameters) to its parameter gradient computation:
where the vertical morphisms represent changes in architecture and is the loss function. The functoriality of manifests in the chain rule, which ensures that for composable morphisms f and g, the gradient computation satisfies:
This equality expresses the fundamental property that backpropagation through a composition of layers corresponds to the composition of individual gradient computations. The diagram commutes precisely when the backward pass correctly accumulates gradients through the computational graph, with the functor preserving the compositional structure of the network.
The universal property of backpropagation emerges through its formulation as a lens in the category of reverse derivatives. Each parameterized function induces a lens pairing the forward pass with its parameter gradient. The backpropagation functor then becomes the realization of this universal construction, where the gradient computation is uniquely determined by the requirement to maintain coherence with the chain rule. This perspective reveals backpropagation as the canonical solution to the problem of gradient computation in compositional systems, with the functorial diagram:
capturing the essential relationship between forward computation and backward gradient flow. The commutativity of this diagram enforces the constraint that parameter updates must properly account for downstream gradient contributions, making explicit the information flow required for correct learning dynamics in neural networks.
7.2.4.3.2 Attention Mechanisms
The query-key-value interaction in transformer architectures admits a rigorous categorical formulation as a limit construction in an appropriate category of attention diagrams. Consider the category whose objects are triples representing query, key, and value vector spaces, and whose morphisms are linear transformations between these spaces that preserve the attention structure. The attention mechanism defines a diagram where is an indexing category capturing the pairwise interactions between queries and keys, with objects for all in the sequence positions and morphisms representing their compatibility relations. The limit of this diagram constitutes the universal object equipped with projection morphisms making all subdiagrams commute:
where is the space of attention scores and , are the natural transformations encoding the softmax normalization and scaling by . The universal property ensures that for any other object X with morphisms respecting these compatibility relations, there exists a unique morphism factoring all through the projections .
The value aggregation emerges through the cone condition over the limit, where the attention weights mediate between the limit projections and the value space V. This constructs a natural transformation from the constant functor to the diagram D, whose component at each position is the linear map weighted by . The multi-head attention mechanism appears as a product of such limits, where the universal property guarantees the independence of attention heads while maintaining their joint interaction through the value space:
Here merge represents the linear combination of head outputs, and the commutativity of the diagram enforces the consistency between individual head computations and their aggregated result. The residual connection and layer normalization further arise as universal constructions, where the skip connection forms a coproduct diagram and the normalization implements a coequalizer of scale transformations. This limit diagram perspective reveals the transformer’s attention mechanism as fundamentally a universal solution to the problem of context-aware sequence processing, where the architectural constraints emerge naturally from the categorical universal properties governing the interaction of queries, keys, and values.
7.2.5. Summary
Category Theory provides a rigorous language for ML by:
- Abstracting computation via categories and functors.
- Unifying structures (e.g., vector spaces, neural networks) under common principles.
- Enabling diagrammatic proofs for complex architectures.
This formalism is not just theoretical—it guides the design of scalable, interpretable models. For instance, monoidal categories formalize tensor operations in deep learning, while adjunctions describe optimality conditions in autoencoders.
7.3. Neural Networks as Composable Morphisms
7.3.1. Layers as Morphisms; Networks as Compositions
The formalization of neural network layers as morphisms in a categorical framework provides a rigorous mathematical foundation for understanding their compositional nature. Within the category , each neural network layer constitutes a morphism where and represent the input and output vector spaces respectively, and denotes the parameter space of weights and biases. These morphisms are required to be smooth maps, ensuring differentiability for gradient-based optimization. The parameterized nature of these morphisms is captured through the Cartesian product with the parameter space, making explicit the functional dependence on both input data and learned parameters.
The composition of layers in a feedforward neural network corresponds precisely to the categorical composition operation in . For a sequence of layers through , the entire network implements the morphism:
with the composite function defined recursively through the composition law:
This composition operation satisfies the associativity axiom strictly, meaning that for any three consecutive layers, the equality holds exactly at the level of parameterized functions. The identity morphism , defined by where ∅ represents the empty parameter set, serves as the neutral element for composition and corresponds to a trivial pass-through layer in neural network terms.
The monoidal structure of captures parallel composition of layers through the tensor product operation. Given two layers and , their parallel composition is the morphism:
defined by . This operation models architectural features like multi-head attention mechanisms where multiple layer computations occur in parallel. The interchange law governing the relationship between sequential and parallel composition ensures the coherence of these operations:
when the domains and codomains are properly aligned.
The categorical perspective reveals that common neural network operations correspond to standard categorical constructions. Batch normalization emerges as a natural transformation between parallel layers, while dropout can be modeled as a probabilistic morphism in a suitably enriched category. The universal property of certain colimits explains why skip connections in residual networks facilitate gradient flow - they provide categorical coproducts that preserve information through the composition chain. This abstract formulation demonstrates that successful neural network architectures often implicitly implement fundamental categorical concepts, providing a mathematical explanation for their empirical effectiveness.
7.3.1.1 Neural Networks as Composable Functions
A neural network can be viewed as a composition of parameterized functions (layers). Let:
-
Each layer be a function , where:
- −
- is the input space (e.g., ),
- −
- is the parameter space (e.g., weights and biases ),
- −
- is the output space.
- A network N with k layers is the composition:where .
Neural networks can be rigorously formalized as composable functions within a categorical framework, where each layer is treated as a morphism and the entire network is the composition of these morphisms. Let denote the category of parameterized functions, where objects are Euclidean spaces and morphisms are smooth functions equipped with parameters. Specifically, a morphism in is defined by a function , where is the parameter space associated with f. The parameters modulate the behavior of the function, analogous to the weights and biases in a neural network layer.
The composition of morphisms in captures the sequential application of layers in a neural network. Given two morphisms and , their composite is defined by the function:
This operation is associative, meaning that for three morphisms , , and , the equality:
holds, ensuring that the order of layer composition is unambiguous. The identity morphism is given by the function , which acts as a trivial layer preserving the input.
The categorical perspective generalizes to parallel compositions via monoidal structure. Given two morphisms and , their tensor product is defined by:
This allows for the modeling of parallel layer computations, such as those in multi-head attention or residual connections. The universality of neural networks arises from their ability to approximate arbitrary continuous functions through composition. The associativity and identity laws ensure that networks can be constructed modularly, while the monoidal structure accommodates branching architectures. This formalism extends naturally to recurrent networks by considering dynamical systems as morphisms in a suitable category, further demonstrating the flexibility of the compositional approach.
In summary, neural networks as composable functions are characterized by their representation as morphisms in , where composition corresponds to layer chaining, associativity guarantees structural coherence, and identity morphisms enable skip connections. The framework provides a rigorous foundation for analyzing and constructing neural architectures while preserving their functional and algebraic properties.
7.3.1.2 Category-Theoretic Interpretation
We define a category Para (for “parameterized functions”) where:
- Objects are spaces (e.g., ),
- Morphisms are pairs , where:is a smooth function, and .
- Composition of morphisms and is given by:where:
- Identity morphism is given by (no parameters).
Under this formalism, a neural network is a composition of morphisms in Para.
The category-theoretic interpretation of neural networks provides a rigorous mathematical framework for understanding their compositional structure through the lens of abstract algebraic concepts. At its core, this interpretation formalizes neural networks as morphisms in a specially constructed category where objects represent data spaces and arrows represent parameterized transformations. Let denote the category of parameterized functions, whose objects are smooth manifolds (typically Euclidean spaces ) representing possible input and output spaces of network layers. Each morphism in this category is realized as a smooth function where is a manifold of parameters, making explicit the dependence on learnable weights and biases.
The fundamental operation of neural network composition corresponds to the categorical composition of morphisms. Given two parameterized functions and , their composite is defined through the diagrammatic composition:
This composition operation satisfies the strict associativity axiom: for any triple of composable morphisms , , and , the equation
holds exactly, not just up to approximation. The identity morphism is given by the canonical projection where is the singleton parameter space, satisfying the identity laws for any morphism .
The categorical perspective reveals deeper structure through universal properties and adjunctions. The parameter space construction forms a monoidal structure where the tensor product of objects represents parallel composition of data spaces, and the tensor product of morphisms models parallel execution of network components. This gives rise to a symmetric monoidal category structure that captures both sequential and parallel composition of neural networks. Functoriality emerges when considering network architectures as functors from a computational graph category to . Each node in the computational graph maps to an object in , and each edge to a parameterized morphism. The functor preserves composition, guaranteeing that the semantic interpretation of the network respects the graph’s structure. This perspective enables rigorous treatment of network architectures as mathematical objects in their own right, rather than just particular instantiations with concrete parameters.
The categorical framework naturally accommodates advanced architectural features through standard constructions. Skip connections arise as coproducts, attention mechanisms as enriched categorical operations, and recurrent networks as fixpoints of endofunctors. The universal property of certain categorical limits explains why residual networks can overcome vanishing gradients - the identity morphism provides a canonical pathway for gradient flow that is preserved by the categorical structure. This abstract viewpoint reveals that many successful neural network design patterns correspond to fundamental categorical constructions.
7.3.2. The Category of Parameterized Functions
The category of parameterized functions, denoted Para, is a foundational construct in categorical machine learning that rigorously formalizes the structure of parameter-dependent transformations central to neural networks and other learned systems. Objects in Para are measurable spaces (typically Euclidean spaces or smooth manifolds), representing the domains and codomains of parameterized maps. A morphism is defined by a triple where is a measurable parameter space (often ) and is a measurable function in both arguments. For fixed parameters , this yields a deterministic map .
Composition in Para is governed by the parameterized product rule. Given morphisms and , their composite is defined by the function:
equipped with the product parameter space . This composition is strictly associative, with the identity morphism given by , where the parameter space is trivial (a singleton). The associativity and unit laws hold exactly:
Para is equipped with a symmetric monoidal structure for parallel computation. The tensor product is the Cartesian product , and the tensor product of morphisms and is:
The monoidal unit I is the singleton space , with unitor isomorphisms and ensuring that parallel composition with trivial data is coherent. The braiding isomorphism encodes the commutativity of parallel processes, critical for architectures like attention mechanisms. A gradient structure emerges when Para is restricted to differentiable functions. For with , the tangent map provides a functorial lift to the tangent category, enabling backpropagation as a categorical limit. Universal properties in Para characterize optimization: the learning adjunction relates parameterized functions to their empirical losses , with the universal arrow representing gradient descent.
In essence, Para provides a universal language for parameterized computation, where morphisms encapsulate both functional and parametric aspects, and their compositions model the hierarchical and parallel structures inherent in learned systems. The category’s monoidal and differential structures rigorously unify forward computation, backpropagation, and parallelization under a single mathematical framework.
7.3.2.1 Definition of the Category Para
The category Para is defined rigorously as follows:
- Objects: Euclidean spaces (or more generally, smooth manifolds).
- Morphisms: A morphism is a smooth function:where is the parameter space (also Euclidean).
- Composition: As defined above, composition is associative due to the associativity of function composition.
- Identity: The identity morphism is the projection .
The category of parameterized functions, denoted Para, is rigorously defined as a symmetric monoidal category that formalizes the structure of parameter-dependent transformations central to machine learning and optimization. Its objects are measurable spaces , typically Euclidean spaces or more general smooth manifolds representing data domains. A morphism in Para consists of:
- A parameter space (a measurable space, often )
- A measurable function
such that for fixed parameters , the map is a deterministic transformation. Composition of morphisms and is defined by the parameterized composite:
equipped with the product parameter space . This composition is strictly associative, with identity morphisms given by the trivial parameterization where the parameter space is the singleton . The monoidal structure of Para captures parallel computation. The tensor product of objects is their Cartesian product , while the tensor product of morphisms and is defined by:
with parameter space . The monoidal unit is the singleton space , and the associator/unitor isomorphisms are inherited from the Cartesian product in the base category (e.g., ).
Para is equipped with a gradient structure when modeling differentiable functions. Given a morphism where is smooth, the **parameter derivative** (for ) provides the tangent map for gradient-based optimization. This makes Para a category internal to the category of smooth manifolds, where morphisms are smooth in both inputs and parameters. The universal property of learning in Para arises via adjunctions. For a fixed architecture mapping parameterized functions to their behaviors on data , the left adjoint constructs the "freely learned" parameterization from data observations, satisfying:
where is a dataset functor. This adjunction formalizes empirical risk minimization as a universal construction. Para also models stochastic maps by allowing , where is the space of probability measures on Y. In this case, composition uses the Chapman-Kolmogorov equation for Markov kernels:
This extends Para to a Markov category, where Bayesian inference becomes a morphism factorization problem.
The categorical structure of Para thus unifies deterministic, stochastic, and differentiable parameterized processes under a single framework, with universal properties ensuring that learning algorithms (e.g., backpropagation, variational inference) arise as canonical constructions. Its morphisms encapsulate both the functional and parameter-space aspects of learned transformations, making it the natural setting for theoretical machine learning.
7.3.2.2 Functoriality of Neural Networks
A neural network architecture defines a functor from a computation graph category (a directed acyclic graph) to Para:
- Each node maps to a space ,
- Each edge maps to a parameterized morphism ,
- Functoriality ensures that compositions in the graph correspond to compositions in Para.
The functoriality of neural networks constitutes a rigorous categorical framework wherein neural architectures are formalized as functors between appropriately defined categories, preserving compositional structure while encapsulating both parameterized transformations and their learning dynamics. Let denote the category of neural architectures, whose objects are tuples representing layer input/output spaces X and parameter spaces , and whose morphisms are equivalence classes of parameterized functions for . A network functor maps each architectural component to its parameterized realization, such that:
- Object Preservation: (the underlying data space).
- Morphism Action: where .
- Compositionality: for composable , with parameter spaces concatenated:
- Identity Preservation: .
The functoriality condition ensures that the computational graph of a neural network strictly commutes with its categorical representation: for any diagram (where is a finite indexing category representing the network’s graph structure), the functor induces a limit-preserving map to Para, guaranteeing that parallel and sequential compositions in the architecture correspond to monoidal products and morphism compositions in Para.
Backpropagation emerges as a natural transformation between the network functor and a tangent functor , where augments each parameterized function with its gradient. The chain rule is encoded via the naturality condition:
where is the symmetry isomorphism in Para permuting gradient terms. This naturality ensures compatibility between the algebraic structure of the network and its differential optimization dynamics. Universal approximation is expressed as a functorial property: let be the category of topological spaces and continuous maps. The restriction functor forgets parameterizations, and a network family is universally approximating if for any in Top and compact , there exists such that:
Here, is a functorial neural architecture (e.g., MLPs with width ), and the condition asserts that the image of under R is dense in the space of continuous functions. Functoriality also governs parameter updates: stochastic gradient descent defines an endofunctor acting on morphisms by:
where is a loss functor . The functoriality of ensures that parameter updates commute with network composition, preserving the coherence of distributed training protocols.
In summary, the functorial perspective rigorously unifies the algebraic, differential, and approximation-theoretic aspects of neural networks, demonstrating that their empirical success stems from their inherent categorical structure as parameter-space functors preserving compositional and optimization-theoretic invariants.
7.3.2.3 Monoidal Structure (for Parallel Composition)
If we extend Para to a monoidal category, we can model parallel layer compositions (e.g., in multi-head attention or residual connections):
- Tensor product ⊗ combines spaces and parameters:
The monoidal structure in the context of parallel composition formalizes the algebraic and categorical foundations necessary to rigorously describe simultaneous, independent computations within neural networks and other parallelizable systems. At its core, a monoidal category consists of a category equipped with a tensor product and a unit object I, satisfying associativity and unit constraints up to natural isomorphism. For parallel computation in neural networks, the tensor product ⊗ represents the concurrent application of operations to distinct data streams, while the unit object I corresponds to the trivial case of no computational load.
Given two neural network layers and , their parallel composition is encoded as the tensor product , where and denote the concatenation or Cartesian product of the respective input and output spaces. Explicitly, for and , the action of is defined by:
This operation preserves the independence of f and g, ensuring no spurious interactions between the parallel streams. The associativity of ⊗ is captured by the natural isomorphism , which allows re-parenthesization of parallel computations without altering their semantic meaning. For neural networks, this justifies the arbitrary grouping of parallel branches, as in multi-head attention or residual connections, where the order of combining channels or features is irrelevant to the final output. The unit object I satisfies the isomorphisms and , which assert that parallel composition with an empty or trivial process leaves the original computation unchanged. In practice, this corresponds to identity skip connections or zero-padding in neural architectures, where the presence of an inert branch does not affect the active computation. The monoidal coherence conditions—pentagon and triangle identities—ensure these isomorphisms interact harmoniously, guaranteeing that diagrams of parallel computations commute. The interchange law governs the interaction between sequential and parallel composition, stating that for morphisms and , the following equality holds:
This law enforces that independent sequences of operations can be composed either sequentially within each branch or in parallel across branches, yielding identical results. In neural networks, this underlies the modularity of layers, where parallel sub-networks (e.g., convolutional filters) process inputs independently before aggregation. For symmetric monoidal categories, the additional natural isomorphism encodes the commutativity of parallel operations, permitting the reordering of data streams. This symmetry is critical for architectures like attention mechanisms, where the output is invariant to the permutation of input heads. The coherence of with the associator and unitors ensures that arbitrary rearrangements of parallel computations are semantically consistent.
In summary, the monoidal structure provides the algebraic scaffolding for parallel computation, where the tensor product ⊗ models concurrent execution, associativity and unit isomorphisms guarantee compositional flexibility, and the interchange law enforces the coherence of sequential and parallel operations. This framework rigorously captures the essence of parallelism in neural networks, from basic layer-wise processing to complex modular architectures, while ensuring mathematical consistency through categorical axioms.
7.3.3. Role of Associativity and Identity in Sequential Models
The role of associativity and identity in sequential models is foundational to their mathematical coherence and operational consistency, rigorously governed by the axioms of category theory. In the context of neural networks and other compositional systems, associativity ensures that the chaining of layers is unambiguous, while identity morphisms guarantee the existence of neutral transformations that preserve information flow.
For a sequential model composed of layers , , and , the associativity axiom demands that the order of function composition does not alter the model’s output:
This equality holds strictly when the layers are deterministic functions, as in feedforward networks, where is invariant to parenthesization. In parameterized settings (e.g., the category Para), associativity extends to parameter spaces: for , , and , the composite and share the same parameterization and map . This property is critical for modular architectures like ResNets or Transformers, where submodules can be freely recomposed without altering the model’s semantics. The identity morphism acts as a trivial layer satisfying:
for any . In **Para**, the identity is defined by , where the parameter space is empty. This axiom enforces that skip connections or residual branches behave as pure information passthroughs, ensuring that (as in ResNets) is well-defined. The identity’s naturality extends to gradient computations, where , preserving the chain rule in backpropagation. Associativity and identity jointly define the category of sequential models, where objects are data spaces and morphisms are (parameterized) transformations. The axioms ensure that any diagram of composable layers commutes, guaranteeing that the model’s output depends only on the functional pipeline, not on the order of intermediate operations. This categorical structure underpins the interpretability and correctness of neural architectures, as violations of associativity or identity would introduce ambiguities in forward inference and gradient propagation.
In practice, these axioms are approximately preserved even in stochastic or approximate settings (e.g., dropout, quantization), where associativity holds up to noise terms and identity is realized as a small-norm perturbation. The universality of these properties across architectures—from CNNs to diffusion models—demonstrates their necessity in unifying sequential computation under a rigorous algebraic framework.
7.3.3.1 Associativity of Composition
Associativity of composition is a fundamental axiom in category theory that ensures the unambiguous chaining of morphisms, providing the algebraic foundation for sequential processes in mathematics and machine learning. Formally, given three composable morphisms , , and in a category , associativity mandates that the order of composition does not affect the resulting morphism:
This equality asserts that the diagram formed by the compositions commutes, meaning the path taken through intermediate objects B and C is irrelevant to the final map from A to D. In the context of neural networks, where morphisms are parameterized functions , associativity guarantees that the forward pass of a deep network is invariant to the grouping of layers:
Here, the parameters concatenate via the product space , and the equality holds strictly for deterministic layers.
The associativity axiom extends to higher-order compositions in monoidal categories, where parallel and sequential operations interact. For morphisms , , and , the interchange law in a monoidal category ensures:
where ⊗ is the tensor product representing parallel composition. This generalizes associativity to networks with branching architectures, such as multi-head attention or residual connections, where the coherence of parallel and sequential paths is preserved. In stochastic settings, associativity holds up to measurable isomorphisms. For Markov kernels , , and , the Chapman-Kolmogorov equation enforces:
where is the pushforward measure. This probabilistic associativity underpins Bayesian networks and diffusion models, where the order of marginalization is invariant.
Associativity is not merely an algebraic convenience but a universal constraint ensuring the consistency of symbolic and computational representations. It allows complex systems to be decomposed into modular components, analyzed locally, and recomposed globally without ambiguity. Violations of associativity—such as in approximate or noisy computations—introduce non-trivial curvature in the category’s compositional structure, necessitating corrective mechanisms like regularization or synchronization protocols in distributed learning.
- The associativity law in Para ensures that composing layers in any order (while respecting dependencies) yields the same function:
- This justifies modular network design: we can group layers into submodules without changing behavior.
Ultimately, associativity of composition is the linchpin of categorical reasoning, enabling the rigorous study of neural networks, programming languages, and physical systems through the lens of morphism coherence and diagrammatic invariance.
7.3.3.2 Identity Morphisms and Skip Connections
Identity morphisms and skip connections are fundamental constructs in both category theory and neural network design, ensuring stability and coherence in information propagation. In a category , the identity morphism for an object X satisfies the axioms and for all morphisms and . For parameterized functions in the category Para, the identity is realized as , where the parameter space is trivial (a singleton), preserving input data under null transformation. In neural networks, skip connections operationalize identity morphisms by creating direct pathways that bypass nonlinear transformations. Given a layer , a residual connection implements , where the identity term ensures gradient stability during backpropagation. The derivative of this operation, (with the identity matrix), guarantees non-vanishing gradients by preserving the dominant eigenvalue of the Jacobian.
The categorical perspective reveals that skip connections enforce universal properties of identity. For any perturbation (e.g., noise or dropout), the composite approximates when , ensuring robustness. In monoidal categories, the coherence condition justifies the initialization of residual branches as identity maps, as in zero-initialized residual networks where early in training, reducing initial output variance. For stochastic networks, skip connections preserve the identity up to measure: if is a stochastic layer, the residual version (a convex combination with Dirac measure ) ensures the input distribution remains dominant. This aligns with the categorical definition of identity for Markov kernels, where for measurable .
- The identity morphism allows for skip connections (e.g., ResNet):
- Identity ensures that a “null” layer (doing nothing) is a valid network component.
The interplay between identity morphisms and skip connections thus provides a rigorous framework for stable deep learning, where categorical axioms ensure both mathematical consistency and empirical performance in architectures like ResNets and Transformers. The identity’s naturality—its preservation under composition and tensor products—underpins the design of modular, scalable networks resistant to degradation.
7.3.3.3 Universality of Sequential Models
The universality of sequential models is a rigorous mathematical property asserting their capacity to approximate arbitrary functional mappings to arbitrary precision under specified conditions, formalized through categorical and analytical frameworks. Let denote the class of sequential models (e.g., recurrent networks, Transformers) with composition operators ∘, and let be the space of continuous functions between compact domains and . A model family is universal if for every and , there exists a finite sequence of parameterized morphisms such that:
This approximation property emerges from the Stone-Weierstrass theorem when forms an algebra closed under composition, pointwise addition, and scalar multiplication, and separates points in .
In categorical terms, universality is characterized by the density of in the functor category , where encodes input data structures and represents outputs. For a sequential model to be universal, the Yoneda embedding must exhibit a natural isomorphism:
for all functors G representing target functions, ensuring that any G can be approximated by a sufficiently deep F. The approximation depth is governed by the model’s width and nonlinearity. For a ReLU network with L layers, the minimal width w required for -approximation of Lipschitz functions scales as , following the Yarotsky bound. Transformers achieve universality via their attention mechanism, where the self-attention operation densely approximates permutation-invariant operators through the universal approximation theorem for kernel integral transforms. Dynamical universality in recurrent models arises from the liquid state machine framework: a continuous-time RNN with sufficient hidden units h can approximate fading-memory filters as:
where is the reservoir state and are learnable parameters.
The universality property is preserved under categorical limits: if each component in a sequential model is universal, their colimit (e.g., infinite-depth limit) remains universal. This underpins the efficacy of deep architectures, where the functoriality of composition guarantees that approximation bounds compound multiplicatively rather than additively.
- The ability to compose morphisms arbitrarily allows for universal approximation (e.g., via deep feedforward networks).
- The categorical framework generalizes to recurrent networks by working in a category of dynamical systems, where morphisms are parameterized recurrent cells.
Thus, universality in sequential models is a confluence of analytic approximation theory, categorical density, and dynamical systems theory, ensuring that compositional hierarchies of simple functions can encapsulate the infinite-dimensional space of continuous operators.
7.3.4. Conclusion
By formalizing neural networks in the category Para, we obtain:
- Layers as morphisms, with networks as their compositions.
- A rigorous category of parameterized functions, supporting functorial and monoidal structures.
- Associativity and identity as fundamental properties enabling modular and correct-by-construction network design.
This framework extends naturally to more complex architectures (e.g., transformers, graph networks) by enriching Para with additional categorical structure (e.g., symmetric monoidal categories for parallel processing).
8. Open Set Learning
Open set learning is a foundational challenge in statistical learning theory and pattern recognition, characterized by the necessity of classifying data instances drawn from both known and unknown distributions. Consider a training dataset , where each instance is associated with a label from a finite set of known classes . The fundamental challenge in open set learning arises when test samples are drawn from a distribution that includes both the training distribution and an additional unknown component , such that
In classical closed-set classification, one seeks to find a function that minimizes an empirical risk functional of the form
where is a loss function such as categorical cross-entropy:
However, in the presence of unknown classes, minimizing only this risk function leads to overconfident misclassifications when a sample is assigned to one of the known classes. This necessitates the introduction of a rejection mechanism, leading to an extended open set risk functional
where is a loss function that penalizes misclassification of unknown samples. A common approach is to introduce a threshold-based rejection criterion where the classification function f satisfies
where is a rejection threshold such that if , the sample is assigned to an unknown category. The introduction of this threshold formally defines an open space , given by
which is crucial in minimizing the open space risk introduced by Scheirer et al. (2013):
Incorporating open space risk minimization into the learning framework, the overall objective function becomes
where is a hyperparameter that balances classification accuracy with rejection performance. The underlying theoretical framework necessitates consideration of both discriminative and generative approaches. In discriminative modeling, the classification function f can be regularized to enforce an explicit margin for open set rejection:
In generative modeling, the problem is framed as estimating the likelihood under a known class distribution model, such as a Gaussian Mixture Model (GMM):
where represents a multivariate Gaussian distribution with mean and covariance matrix , and is the prior weight of the k-th component. A likelihood-based rejection rule is then applied:
There are several class distribution models in which the open set learning problem can be framed as estimating the likelihood . To state all those class distribution models we first define few quantities. Let be the input feature space and be the known set of class labels. We assume that samples are drawn from a joint probability distribution , where the true distribution of unknown classes is not available during training. Open Set Learning requires estimating a function , where ⌀ represents an unknown class.
-
Gaussian Distribution Model (GDM) The fundamental assumption is that the feature distribution of each known class follows a multivariate normal distribution parameterized by the mean vector and covariance matrix . The likelihood of a given sample belonging to class c is:To quantify the confidence in assigning to class c, we compute the Mahalanobis distance:A sample is rejected as unknown if:where is a threshold chosen based on extreme value statistics.
- Gaussian Mixture Model (GMM) The Gaussian assumption can be generalized using a Gaussian Mixture Model (GMM), which represents each class as a weighted sum of multiple Gaussian components:where are the mixture weights satisfying , and each Gaussian component is given by:Unknown samples are rejected based on low maximum likelihood estimation (MLE) scores:where is a predefined threshold.
- Dirichlet Process Gaussian Mixture Model (DP-GMM) A Dirichlet Process (DP) prior can be introduced to allow the number of mixture components K to grow dynamically. The prior over the mixture weights follows:where is the concentration parameter controlling cluster sparsity. This enables automatic adaptation of the number of mixture components to better capture class distributions. The likelihood of follows:but with a nonparametric prior that ensures more flexible decision boundaries.
- Extreme Value Theory (EVT) Models The tail distribution of softmax probabilities is modeled using an Extreme Value Theorem (EVT) approach. Given softmax scores , we fit a Weibull distribution to the tail:A sample is rejected if:
- Bayesian Neural Networks (BNNs) BNNs introduce uncertainty estimation by placing priors over network weights:>Posterior inference is performed via Bayesian updating:A sample is rejected if the entropy of the predictive distribution is high:
- Support Vector Models (OC-SVM and SVDD) One-Class SVM (OC-SVM): Finds a separating hyperplane such that:subject to . A sample is rejected if:
- Support Vector Data Description (SVDD): Finds a minimum enclosing hypersphere with center and radius R:subject to:A sample is rejected if:
Each model presents a trade-off between expressivity, computational complexity, and interpretability. The choice of model for Open Set Learning depends on the underlying data distribution and the required rejection confidence.
A distance-based approach further refines the rejection mechanism by computing the Mahalanobis distance
and rejecting samples that satisfy
An alternative Bayesian formulation considers the posterior probability of a sample belonging to a known class:
Defining a prior probability , a Bayesian rejection model classifies a sample as unknown if
By leveraging a combination of margin constraints, likelihood estimation, and probabilistic modeling, open set learning provides a rigorous mathematical framework for handling unknown distributions while maintaining classification performance on known data. The continued development of theoretical models and practical algorithms in this domain is essential for deploying reliable machine learning systems in real-world scenarios where distributional shifts and novel categories are unavoidable.
8.1. Literature Review of Deep Neural Network-Based Open Set Learning
Open Set Learning (OSL) is a crucial area of machine learning that extends traditional classification by accounting for the presence of unknown classes in real-world applications. One of the seminal works in this domain is Scheirer et al.’s (2012) [1215] which introduced the concept of open space risk. The authors proposed the 1-vs-Set Machine, a classifier that minimizes empirical and open space risk, making it effective in identifying previously unseen categories. Following this, Bendale and Boult (2015) [1216] extended the framework to open world learning, wherein models must identify unknown categories and incrementally incorporate them into their learning process. Their Nearest Non-Outlier (NNO) algorithm provided a mechanism to dynamically learn from evolving data distributions. Another significant contribution came from Busto and Gall (2017) [1217] which focused on adapting models when the target domain contained classes not present in the source domain. Their Assign-and-Transform Iterative (ATI) method iteratively classified target samples as either belonging to a known class or as unknown, refining the learning process.
The challenge of domain adaptation in open set scenarios was further addressed by Saito et al. (2018) [1218] where adversarial training was used to align known class features while ensuring that unknown class features remained distinguishable. Their approach improved generalization across datasets with shifting distributions. Expanding on the theoretical foundations of OSL, Geng et al. (2020) [1219] provided a structured taxonomy of existing methods, evaluating their relative strengths and weaknesses. This survey has become a key reference for researchers entering the field. A novel approach to learning class boundaries in an open set scenario was proposed by Chen et al. (2020) [1221]. They introduced the concept of Reciprocal Points, which helped define the extra-class space for each known category, reducing misclassification of unknowns. This work significantly improved decision boundary learning for open set classification.

Table 1.
Summary of Contributions to Open Set Learning (OSL)
| Author(s) | Contribution |
|---|---|
| Scheirer et al. (2012) [1215] | Introduced the concept of open space risk and proposed the 1-vs-Set Machine classifier, which minimizes both empirical and open space risk to identify unseen categories. |
| Bendale and Boult (2015) [1216] | Extended the framework to open world learning with the Nearest Non-Outlier (NNO) algorithm, allowing incremental learning from evolving data. |
| Busto and Gall (2017) [1217] | Proposed the Assign-and-Transform Iterative (ATI) method for domain adaptation when the target domain includes unknown classes not present in the source. |
| Saito et al. (2018) [1218] | Used adversarial training to align features of known classes and distinguish unknowns, improving generalization in open set domain adaptation scenarios. |
| Geng et al. (2020) [1219] | Offered a comprehensive taxonomy and theoretical framework for Open Set Learning methods, becoming a foundational survey in the field. |
| Chen et al. (2020) [1221] | Introduced Reciprocal Points to define extra-class space and improve the separation between known and unknown classes. |
Few-shot learning in open set recognition presents additional complexities, as limited labeled data makes it difficult to differentiate between known and unknown categories. Addressing this, Liu et al. (2020) [1222] introduced the PEELER algorithm, which integrates meta-learning and entropy maximization to enhance recognition capabilities. Another innovative approach came from Kong and Ramanan (2021) [1223] where Generative Adversarial Networks (GANs) were leveraged to synthesize diverse open-set examples. This method helped in explicitly modeling the open space, improving classifier robustness. Advancing the theoretical aspects, Fang et al. (2021) [1224] provided generalization bounds for open set learning and introduced the Auxiliary Open-Set Risk (AOSR) algorithm, ensuring robust decision-making under open-world conditions.
Active learning, which involves selecting the most informative samples for labeling, was linked to open set recognition by Mandivarapu et al. (2022) [1225]. They proposed a framework where unknown instances were queried and incorporated into the learning process, making the classifier more adaptive to novel data. The impact of semi-supervised learning on OSL was explored by Engelbrecht and du Preez (2020) [1226]. They combined positive and unlabeled learning, improving model robustness when training data contained unknown categories. Similarly, Zhou et al. (2024) [1235] introduced a contrastive learning framework that used an unknown score to separate known and unknown instances more effectively.
Another fundamental challenge in open set recognition is handling distributional shifts, which was rigorously analyzed by Shao et al. (2022) [1227]. Their work addressed scenarios where class distributions evolved between training and testing, ensuring that OSL models could generalize despite such shifts. Theoretical underpinnings of OSL were further explored by Park et al. (2024) [1228] which provided insights into how neural networks distinguish between known and unknown classes using Jacobian-based metrics. Open set recognition also extends to object detection, as demonstrated by Liu et al. (2022) [1230] which developed a hybrid model that utilized both labeled and unlabeled data for detecting unknown objects in complex visual scenes.
Abouzaid et al. (2023) [1236] present a cost-effective alternative to conventional vector network analyzers by leveraging a D-band Frequency-Modulated Continuous-Wave (FMCW) radar system combined with deep learning models for material characterization, where the integration of an open-set recognition technique allows the system to reject measurements from unknown materials that were not encountered during training, ensuring enhanced reliability and robustness in practical applications; their work demonstrates how deep learning, when coupled with domain-specific hardware, can improve classification confidence in real-world settings where unknown materials may appear frequently. Similarly, Cevikalp et al. (2023) [1237] proposed a novel approach that effectively unifies anomaly detection and open set recognition by approximating class acceptance regions with compact hypersphere models, providing a clear separation between known and unknown instances, where their method improves the generalization capability of OSL models by explicitly defining decision boundaries that allow the model to reject unseen samples with greater confidence, bridging a crucial gap between two previously distinct problem domains and offering a new perspective on how class boundaries should be defined in high-dimensional spaces; their work emphasizes the importance of modeling uncertainty in classification tasks to improve the identification of unknown samples in real-world applications.
Palechor et al. (2023) [1238] highlight a critical limitation in current open-set classification research—namely, that existing evaluations are often performed on small-scale, low-resolution datasets that do not accurately reflect real-world challenges—so they introduce three large-scale open-set protocols built using subsets of ImageNet, where these protocols vary in terms of similarity between known and unknown classes to provide a more realistic assessment of open-set recognition models; furthermore, they propose a novel validation metric designed to evaluate a model’s ability to both classify known samples and correctly reject unknown ones, thus contributing significantly to the standardization of open-set evaluation methodologies and setting new benchmarks for future research in this domain, where their large-scale approach helps bridge the gap between academic research and practical deployment scenarios by providing a more realistic evaluation framework. Lastly, Cen et al. (2023) [1240] delve into the concept of Unified Open-Set Recognition (UOSR), which not only aims to reject unknown samples but also to handle known samples that are misclassified by the model, where they analyze the distribution of uncertainty scores and find that misclassified known samples exhibit uncertainty distributions similar to those of truly unknown samples, highlighting a fundamental limitation of existing open-set classifiers; they further explore how different training settings—such as pre-training and outlier exposure—affect UOSR performance, and they propose the FS-KNNS method for few-shot UOSR settings, which achieves state-of-the-art performance across multiple evaluation conditions, demonstrating that a unified framework capable of handling both unknown rejection and misclassification is necessary for real-world applications where classification errors can have significant consequences.
Table 2.
Summary of Additional Contributions to Open Set Learning (OSL)
| Authors (Year) | Citation Key | Contribution / Summary |
|---|---|---|
| Liu et al. (2020) | [1222] | Introduced the PEELER algorithm combining meta-learning and entropy maximization for few-shot open set recognition. |
| Kong and Ramanan (2021) | [1223] | Used GANs to generate diverse open-set examples, improving classifier robustness by explicitly modeling the open space. |
| Fang et al. (2021) | [1224] | Proposed generalization bounds and the Auxiliary Open-Set Risk (AOSR) algorithm for robust decision-making in open-world conditions. |
| Mandivarapu et al. (2022) | [1225] | Linked active learning with open set recognition by querying unknown instances for improved adaptivity. |
| Engelbrecht and du Preez (2020) | [1226] | Proposed a semi-supervised OSL model using positive and unlabeled learning to increase robustness to unknowns. |
| Zhou et al. (2024) | [1235] | Introduced a contrastive learning framework with an "unknown score" to enhance known-unknown separation. |
| Shao et al. (2022) | [1227] | Analyzed distributional shifts between training and testing phases, improving OSL generalization. |
| Park et al. (2024) | [1228] | Provided theoretical insights on distinguishing known and unknowns using Jacobian-based metrics in neural networks. |
| Liu et al. (2022) | [1230] | Developed a hybrid OSL object detection model combining labeled and unlabeled data for complex visual scenes. |
| Abouzaid et al. (2023) | [1236] | Used D-band FMCW radar with deep learning and open-set recognition for reliable material characterization. |
| Cevikalp et al. (2023) | [1237] | Unified anomaly detection and OSL using compact hypersphere models to define decision boundaries. |
| Palechor et al. (2023) | [1238] | Proposed large-scale ImageNet-based open-set protocols and a new validation metric for realistic OSL evaluation. |
| Cen et al. (2023) | [1240] | Introduced FS-KNNS for few-shot Unified Open-Set Recognition, analyzing uncertainty distributions and pretraining impacts. |
Huang et al. (2022) [1241] introduce a novel approach that leverages semantic reconstruction to bridge the gap between known and unknown classes by focusing on class-specific feature recovery, enabling more robust rejection of out-of-distribution samples. Complementarily, Wang et al. (2022) [1242] propose an Area Under the Curve (AUC)-optimized objective function that directly improves open-set recognition performance by training deep networks to balance the trade-off between closed-set classification and unknown sample detection, providing a novel perspective on learning decision boundaries in an end-to-end manner. Additionally, Alliegro et al. (2022) [1243] present a benchmark dataset tailored for 3D open-set learning, evaluating deep learning architectures on object point cloud classification where previously unseen object categories must be identified and rejected, highlighting the need for better feature representations in 3D data. Meanwhile, Grieggs et al. (2021) [1244] propose a unique application of OSL in the context of handwriting recognition, demonstrating how human perception can be leveraged to identify errors in automatic transcription systems when encountering unfamiliar handwriting styles, further expanding the applicability of OSL methodologies beyond traditional classification problems.
The intersection of open-set learning and object detection has also received attention, with Liu et al. (2022) [1230] introducing a semi-supervised framework that leverages labeled and unlabeled data to improve object detection models in open-world settings where new object categories emerge post-training, making their method highly relevant for real-world surveillance and autonomous driving applications. Similarly, Grcić et al. (2022) [1245] proposed a hybrid approach that combines traditional anomaly detection with deep feature learning to improve open-set performance in dense prediction tasks such as semantic segmentation. Moreover, Moon et al. (2022) [1246] introduced a simulator that generates synthetic samples mimicking the characteristics of unknown instances, allowing models to improve their robustness against unfamiliar data distributions. Meanwhile, Kuchibhotla et al. (2022) [1248] addressed the problem of incrementally learning new unknown categories, proposing a framework that adapts dynamically to new unseen data without requiring retraining, making it well-suited for applications like autonomous agents and continual learning scenarios.
Another critical research direction is open-set image generation, explored by Katsumata et al. (2022) [1249] where they propose a Generative Adversarial Network (GAN)-based framework for semi-supervised image synthesis, ensuring that generated images align with both known class distributions and the potential feature spaces of unknown samples, bridging the gap between generative modeling and open-set classification. Bao et al. (2022) [1250] extend OSL into the domain of temporal action recognition, developing a method that detects and localizes previously unseen human actions in video sequences, an essential capability for video surveillance and activity monitoring. Dietterich and Guyer (2022) [1251] conducted a theoretical analysis of why deep networks struggle with open-set generalization, proposing that model behavior is largely dictated by the level of feature familiarity during training, thereby highlighting the importance of designing architectures that explicitly account for feature generalization beyond closed-set learning.
Table 3.
Summary of Additional Contributions to Open Set Learning (OSL)
| Authors (Year) | Main Contribution |
|---|---|
| Huang et al. (2022) [1241] | Propose a semantic reconstruction approach that focuses on class-specific feature recovery, enhancing rejection of out-of-distribution samples by bridging the gap between known and unknown classes. |
| Wang et al. (2022) [1242] | Introduce an AUC-optimized objective function that trains deep networks to balance closed-set accuracy and unknown detection, improving open-set decision boundary learning. |
| Alliegro et al. (2022) [1243] | Present a benchmark dataset for 3D open-set learning in object point cloud classification, emphasizing the need for improved 3D feature representation. |
| Grieggs et al. (2021) [1244] | Apply OSL to handwriting recognition by leveraging human perception to identify transcription errors from unfamiliar handwriting styles, expanding OSL beyond classification. |
| Liu et al. (2022) [1230] | Propose a semi-supervised framework for open-world object detection using both labeled and unlabeled data, enabling dynamic adaptation to emerging object classes. |
| Grcić et al. (2022) [1245] | Combine anomaly detection and deep feature learning to enhance open-set semantic segmentation performance in dense prediction tasks. |
| Moon et al. (2022) [1246] | Introduce a simulator for generating synthetic unknown samples to improve model robustness against unfamiliar data distributions. |
| Kuchibhotla et al. (2022) [1248] | Develop an incremental learning framework for adapting to new unknown categories without retraining, suitable for continual learning and autonomous systems. |
| Katsumata et al. (2022) [1249] | Propose a GAN-based framework for semi-supervised open-set image generation that aligns synthesized images with both known and unknown class features. |
| Bao et al. (2022) [1250] | Extend OSL to temporal action recognition by detecting and localizing unseen human actions in video, applicable to surveillance and activity monitoring. |
| Dietterich and Guyer (2022) [1251] | Provide a theoretical analysis of why deep networks fail in open-set generalization, attributing it to feature familiarity levels and proposing architectural considerations. |
Long-tailed and class imbalance issues are further addressed by Cai et al. (2022) [1253] where they propose a method for localizing unfamiliar samples in long-tailed distributions by leveraging feature similarity measures to identify and reject outliers, providing an important step towards integrating OSL with long-tailed classification problems. Similarly, Wang et al. (2022) [1254] present a framework that generalizes open-world learning paradigms to specific user-defined tasks, improving model adaptability by considering the dynamics of real-world data distributions. Zhang et al. (2022) [1256] introduce an architecture search algorithm optimized for OSL, demonstrating that network design itself plays a crucial role in determining a model’s ability to reject unknown instances, thus contributing a new perspective to the development of OSL-optimized deep learning architectures. Lu et al. (2022) [1257] present a prototype-based approach that enhances open-set rejection by mining robust feature prototypes from known classes, refining decision boundaries by ensuring that unknown samples are adequately separated from learned class distributions. Their work aligns closely with recent efforts in prototype learning for anomaly detection and open-world learning, reinforcing the importance of well-structured feature representations in OSL.
The following five papers collectively advance the field of Open Set Learning (OSL) by addressing key challenges in recognizing known classes while rejecting unknown or out-of-distribution (OOD) samples. Xia et al. (2021) [1258] propose an Adversarial Motorial Prototype Framework (AMPF), leveraging adversarial learning to refine class prototypes and explicitly model uncertainty boundaries, offering strong theoretical grounding but facing instability in training. Kong and Ramanan (2021) [1259] introduce OpenGAN, which generates synthetic OOD data via GANs, improving generalization but requiring auxiliary OOD data for optimal performance. Huang et al. (2021) [1260] take a semi-supervised approach in Trash to Treasure, using cross-modal matching to mine useful OOD samples from unlabeled data, though this depends on multi-modal availability. Wang et al. (2021) [1262] present an energy-based model (EBM) for uncertainty calibration, providing a principled confidence measure without OOD data but at higher computational cost. Lastly, Zhang and Ding (2021) [1263] adapt prototypical matching for zero-shot segmentation with open-set rejection, offering efficiency but relying on pre-defined class embeddings. These works highlight diverse strategies—adversarial learning, generative modeling, multi-modal mining, energy-based uncertainty, and metric-based rejection—each with unique trade-offs in stability, data requirements, and scalability.
A comparative analysis reveals that generative approaches (OpenGAN, AMPF) excel in synthesizing or refining unknown-class representations but often suffer from training instability or data dependency. In contrast, discriminative methods (Huang et al. (2021) [1260], Xia et al. (2021) [1258]) leverage existing data more efficiently but may struggle with feature overlap or modality constraints. The energy-based framework stands out for its theoretical robustness in uncertainty quantification but lacks computational efficiency. Future directions could integrate these paradigms—e.g., combining generative synthetic data with energy-based calibration or extending contrastive learning to reduce multi-modal reliance. Additionally, bridging zero-shot learning (Zhang and Ding (2021) [1263]) with open-set recognition (Wang et al. (2021) [1262]) could yield more scalable solutions for real-world open-world scenarios.
Table 4.
Summary of Contributions to Open Set Learning (OSL)
| Authors (Year) | Main Contribution |
|---|---|
| Cai et al. (2022) [1253] | Propose a method to localize unfamiliar samples in long-tailed distributions using feature similarity measures, enabling outlier rejection and integrating OSL with long-tailed classification. |
| Wang et al. (2022) [1254] | Present a framework for adapting open-world learning to user-defined tasks, enhancing model adaptability to dynamic real-world data distributions. |
| Zhang et al. (2022) [1256] | Introduce an architecture search algorithm tailored to OSL, highlighting the importance of network design in effectively rejecting unknown instances. |
| Lu et al. (2022) [1257] | Develop a prototype-based method that refines decision boundaries and improves open-set rejection by mining robust feature prototypes from known classes. |
| Xia et al. (2021) [1258] | Propose the Adversarial Motorial Prototype Framework (AMPF), using adversarial learning to refine class prototypes and explicitly model uncertainty boundaries. |
| Kong and Ramanan (2021) [1259] | Introduce OpenGAN, which uses GANs to synthesize OOD data for improving generalization, although requiring auxiliary OOD data. |
| Huang et al. (2021) [1260] | Present a semi-supervised cross-modal method (Trash to Treasure) for mining OOD samples from unlabeled data, with dependency on multi-modal data availability. |
| Wang et al. (2021) [1262] | Develop an energy-based model (EBM) for uncertainty calibration that offers principled confidence measures without OOD data, albeit with high computational cost. |
| Zhang and Ding (2021) [1263] | Adapt prototypical matching for zero-shot segmentation with open-set rejection, achieving efficiency but relying on pre-defined class embeddings. |
Girish et al. (2021) [1264] propose a framework for discovering and attributing GAN-generated images in an open-world context, leveraging contrastive learning and unsupervised clustering to identify novel synthetic sources. This work is pivotal in extending open-set learning to generative models, where unknown sources must be incrementally detected. Similarly, Wang et al. (2021) [1265] tackle open-world video object segmentation by introducing a benchmark for dense, unidentified object segmentation, emphasizing the need for models to reject unknown objects while incrementally learning new categories. Their approach combines uncertainty estimation with spatio-temporal consistency, providing a robust baseline for dynamic open-world settings. Cen et al. (2021) [1266] further advance this direction by integrating deep metric learning into semantic segmentation, proposing a prototype-based mechanism to distinguish known and unknown classes through margin-based feature separation. Their work bridges open-set recognition and dense prediction, demonstrating significant improvements in unknown class rejection.
Wu et al. (2021) [1267] introduce NGC, a unified framework for learning with open-world noisy data, combining noise robustness with open-set rejection via graph-based label propagation and uncertainty-aware sample selection. This work is particularly rigorous in its theoretical analysis of noise tolerance in open-set scenarios. Bastan et al. (2021) [1268] explore large-scale open-set logo detection, employing hierarchical clustering and outlier-aware loss functions to handle real-world open-set noise. Their empirical results highlight the scalability challenges in open-set detection. Saito et al. (2021) [1269] propose OpenMatch, a semi-supervised learning method that enforces consistency regularization while explicitly handling outliers, offering a principled way to integrate open-set robustness into semi-supervised pipelines. Finally, Esmaeilpour et al. (2022) [1270] extend CLIP for zero-shot open-set detection, leveraging vision-language pretraining to recognize novel categories without labeled examples. Their work underscores the potential of multimodal models in open-world settings but also exposes limitations in fine-grained unknown class discrimination. Collectively, these papers advance open-set learning through novel architectures, benchmarks, and theoretical insights, though challenges remain in scalability, noise robustness, and generalizability to real-world open-ended environments.
Chen et al. (2021) [1272] introduce Adversarial Reciprocal Points Learning, which leverages adversarial optimization to create reciprocal points that define decision boundaries for known classes while rejecting unknowns through a novel geometric margin constraint. This approach is theoretically grounded in metric learning and adversarial robustness, demonstrating superior performance on benchmark datasets. Similarly, Guo et al. (2021) [1273] propose a Conditional Variational Capsule Network, combining capsule networks with conditional variational autoencoders to model complex data distributions, enabling better uncertainty quantification for open-set scenarios. Their work extends the theoretical framework of variational inference to hierarchical feature representations, improving discriminability between known and unknown classes. Bao et al. (2021) [1274] explore Evidential Deep Learning for action recognition, employing subjective logic to model epistemic uncertainty explicitly. Their method provides a probabilistic interpretation of open-set recognition, offering robustness against outliers in video data. Meanwhile, Sun et al. (2021) [1275] introduce M2IOSR, which maximizes mutual information between input data and latent representations to enhance feature discriminability. Their information-theoretic approach ensures compact class-specific manifolds while maintaining separability from unknown samples, supported by rigorous bounds on mutual information optimization. Hwang et al. (2021) [1276] tackle Open-Set Panoptic Segmentation, proposing an exemplar-based approach that leverages prototype learning to distinguish known and unknown objects in segmentation tasks. Their method combines metric learning with panoptic segmentation, providing a novel way to handle open-set scenarios in dense prediction tasks. Finally, Balasubramanian et al. (2021) [1278] focus on real-world applications, combining deep learning with ensemble methods for detecting unknown traffic scenarios. Their work emphasizes practical robustness, using ensemble diversity to improve uncertainty estimation in safety-critical environments.
Table 5.
Summary of Key Contributions to Open Set Recognition (OSR)
| Author(s) | Main Contribution |
|---|---|
| Girish et al. [1264] | Propose a framework for detecting GAN-generated images using contrastive learning and clustering to discover novel synthetic sources in open-world scenarios. |
| Wang et al. [1265] | Introduce a benchmark for open-world video object segmentation combining uncertainty estimation and spatio-temporal consistency to reject unknowns and learn new categories. |
| Cen et al. [1266] | Use deep metric learning with prototype-based margin separation to improve open-set semantic segmentation by distinguishing known and unknown classes. |
| Wu et al. [1267] | Present NGC, a framework combining graph-based label propagation and uncertainty-aware sample selection for robust learning under noisy and open-world conditions. |
| Bastan et al. [1268] | Address large-scale open-set logo detection using hierarchical clustering and outlier-aware loss to manage noisy real-world open-set data. |
| Saito et al. [1269] | Propose OpenMatch, a semi-supervised learning approach that integrates consistency regularization with open-set outlier rejection. |
| Esmaeilpour et al. [1270] | Extend CLIP to zero-shot open-set detection, leveraging vision-language models to detect novel categories without labeled data, but note limitations in fine-grained unknown discrimination. |
| Chen et al. [1272] | Introduce Adversarial Reciprocal Points Learning using adversarial optimization to define class boundaries while rejecting unknowns via a geometric margin constraint. |
| Guo et al. [1273] | Develop a Conditional Variational Capsule Network combining capsules and VAEs for hierarchical uncertainty modeling in open-set recognition. |
| Bao et al. [1274] | Apply Evidential Deep Learning and subjective logic to explicitly model epistemic uncertainty in video-based action recognition. |
| Sun et al. [1275] | Propose M2IOSR, an information-theoretic model that maximizes mutual information for compact, separable class manifolds and robust unknown rejection. |
| Hwang et al. [1276] | Address open-set panoptic segmentation using prototype learning to distinguish known and unknown objects, integrating metric learning in dense prediction. |
| Balasubramanian et al. [1278] | Focus on real-world detection of unknown traffic scenarios using ensemble diversity to improve uncertainty estimation and robustness. |
Salomon et al. (2020) [1285] propose Siamese networks for open-set face recognition in small galleries, leveraging metric learning to distinguish known from unknown classes effectively. Similarly, Jia and Chan (2021) [1284] introduce the MMF loss, extending traditional feature learning by incorporating margin-based constraints to enhance discriminability in open-set scenarios. Their follow-up work (Jia and Chan, 2022) [1283] presents a self-supervised de-transformation autoencoder that learns robust representations by reconstructing original images from augmented views, improving generalization to unknown classes. These approaches emphasize representation learning but differ in their mechanisms—metric learning vs. margin-based losses vs. self-supervised reconstruction—highlighting the trade-offs between discriminative power and generalization. Meanwhile, Yue et al. (2021) [1282] tackle open-set and zero-shot recognition through counterfactual reasoning, generating synthetic unknowns to refine decision boundaries. Their method bridges OSR and zero-shot learning by leveraging generative models, offering a unified perspective on handling unseen categories. Cevikalp et al. (2021) [1281] propose a deep polyhedral conic classifier, formulating OSR as a compact geometric problem where classes are modeled as convex cones, enabling both closed-set accuracy and open-set robustness. Zhou et al. (2021) [1280] take a different approach by learning "placeholder" prototypes for potential unknown classes during training, dynamically adjusting decision boundaries to accommodate novel test-time instances. Their method explicitly models uncertainty, contrasting with the geometric rigidity of polyhedral classifiers. Lastly, Jang and Kim (2023) [1279] present a teacher-explorer-student (TES) paradigm, where an "explorer" network identifies challenging open-set samples to guide the student’s learning process. This tripartite framework introduces a novel meta-learning aspect to OSR, emphasizing adaptive exploration over static modeling.
Sun et al. (2020) [1287] propose a Conditional Gaussian Distribution Learning (CGDL) method, which models class-conditional distributions to improve open-set recognition by leveraging uncertainty estimation. Similarly, Perera et al. (2020) [1288] introduce a hybrid generative-discriminative framework that combines variational autoencoders (VAEs) with discriminative classifiers to enhance feature separation between known and unknown classes. Meanwhile, Ditria et al. (2020) [1289] present OpenGAN, a generative adversarial network (GAN) variant designed to generate outliers that improve open-set detection by training the discriminator to reject synthetic unknowns. These works collectively emphasize the importance of probabilistic modeling and generative techniques in distinguishing between in-distribution and out-of-distribution samples, while also addressing scalability and generalization challenges in real-world applications. Further expanding the scope of OSL, Geng and Chen (2020) [1290] propose a collective decision framework that aggregates multiple classifiers to improve robustness in open-set scenarios, demonstrating the benefits of ensemble-based uncertainty quantification. Jang and Kim (2020) [1291] develop a One-vs-Rest deep probability model that explicitly estimates the probability of a sample belonging to an unknown class, offering a computationally efficient alternative to traditional threshold-based methods. Lastly, Zhang et al. (2020) [1292] explore hybrid models that combine discriminative and generative components, achieving state-of-the-art performance by jointly optimizing feature learning and open-set rejection. These studies highlight a trend toward hybrid architectures that integrate multiple learning paradigms to enhance open-set robustness.
Table 6.
Summary of Key Contributions to Open Set Recognition (OSR)
| Author(s) | Main Contribution |
|---|---|
| Salomon et al. [1285] | Apply metric learning to distinguish known from unknown classes in open-set face recognition with small galleries. |
| Jia and Chan [1284] | Incorporate margin-based constraints into feature learning to improve discriminability in OSR. |
| Jia and Chan [1283] | Learn robust representations through reconstruction of original images from augmented views to generalize to unknowns. |
| Yue et al. [1282] | Generate synthetic unknowns to refine decision boundaries using counterfactual reasoning, bridging OSR and zero-shot learning. |
| Cevikalp et al. [1281] | Model known classes as convex cones using a deep polyhedral conic classifier to enable open-set robustness. |
| Zhou et al. [1280] | Learn placeholder prototypes for potential unknown classes during training to dynamically adjust decision boundaries. |
| Jang and Kim [1279] | Introduce a teacher-explorer-student (TES) meta-learning framework where an explorer guides the student using challenging open-set samples. |
| Sun et al. [1287] | Propose a Conditional Gaussian Distribution Learning (CGDL) method to model class-conditional distributions for uncertainty-based OSR. |
| Perera et al. [1288] | Combine variational autoencoders (VAEs) with discriminative classifiers in a hybrid framework to separate known and unknown classes. |
| Ditria et al. [1289] | Present OpenGAN, which generates synthetic outliers to improve open-set detection by training the discriminator to reject unknowns. |
| Geng and Chen [1290] | Propose a collective decision framework that aggregates multiple classifiers to improve robustness in open-set scenarios. |
| Jang and Kim [1291] | Develop a One-vs-Rest deep probability model to estimate the probability of a sample belonging to an unknown class. |
| Zhang et al. [1292] | Explore hybrid models that combine discriminative and generative components for joint optimization of feature learning and OSR. |
Shao et al. (2020) [1293] tackle adversarial vulnerabilities in OSR with Open-set Adversarial Defense, proposing a defense mechanism that integrates open-set robustness into adversarial training, ensuring resilience against both adversarial attacks and unknown class intrusions. These works collectively advance OSR by refining feature learning and decision boundaries, though they differ in their emphasis on hybrid architectures, latent space optimization, and adversarial robustness. Yu et al. (2020) [1294] introduce a Multi-Task Curriculum Framework for Open-Set Semi-Supervised Learning, dynamically balancing supervised and unsupervised learning to progressively handle unknown classes, demonstrating strong performance in mixed-label settings. Miller et al. (2021) [1295] propose Class Anchor Clustering, a distance-based loss function that enforces compact class-specific clusters while maintaining separation, improving open-set classification by directly optimizing feature space geometry. Jia and Chan (2021) [1296] contribute MMF, a loss extension that enhances feature discriminability in OSR by jointly minimizing intra-class variance and maximizing inter-class separation. Finally, Oliveira et al. (2020) [1300] extend OSR to dense prediction tasks with Fully Convolutional Open Set Segmentation, introducing uncertainty-aware mechanisms to reject unknown pixels in segmentation, a novel application of open-set principles.
Yang et al. (2020) [1301] propose S2OSC, a holistic semi-supervised framework that integrates consistency regularization and entropy minimization to enhance open set classification, demonstrating robustness in handling both labeled and unlabeled data. Similarly, Sun et al. (2020) [1302] leverage conditional probabilistic generative models to estimate the likelihood of samples belonging to known classes, using uncertainty thresholds to reject unknowns, thus providing a probabilistic foundation for open set recognition. Yang et al. (2020) [1303] introduce the Convolutional Prototype Network (CPN), which learns discriminative prototypes for known classes and employs a distance-based rejection mechanism, achieving state-of-the-art performance on benchmark datasets. Dhamija et al. (2020) [1304] highlight the understudied challenge of open set detection in object recognition, proposing an evaluation framework that underscores the limitations of current object detectors in rejecting unknown classes. Their work calls for a paradigm shift in designing detection systems to account for open-world assumptions. Meyer and Drummond (2019) [1305] emphasize metric learning as a pivotal tool for open set recognition in robotic vision, demonstrating its efficacy in active learning scenarios where unknown classes are incrementally discovered. Oza and Patel (2019) [1306] present a multi-task learning approach that jointly optimizes classification and reconstruction tasks, leveraging autoencoders to model the latent space of known classes and detect outliers. Yoshihashi et al. (2019) [1307] propose Classification-Reconstruction Learning (CROSR), which combines discriminative and generative learning to improve open set performance by reconstructing input samples and using reconstruction error as a secondary cue for rejection.
Malalur and Jaakkola (2019) [1308] propose an alignment-based matching network that leverages metric learning for one-shot classification and OSR, emphasizing the importance of feature alignment in distinguishing known from unknown classes. Similarly, Schlachter et al. (2019) [1309] introduce intra-class splitting, a technique that refines decision boundaries by decomposing known classes into sub-clusters, thereby improving open-set discriminability. Meanwhile, Imoscopi et al. (2019) [1310] investigate speaker identification, demonstrating that discriminatively trained neural networks can effectively reject unknown speakers by optimizing confidence thresholds. These works collectively highlight the role of discriminative training and refined feature representations in OSR. On the other hand, Mundt et al. (2019) [1311] challenge the necessity of generative models for out-of-distribution detection, showing that deep neural network uncertainty measures—such as softmax entropy and Monte Carlo dropout—can achieve competitive performance without explicit generative modeling. This finding suggests that discriminative approaches, when properly calibrated, can suffice for open-set scenarios.
Liu et al. (2019) [1313] tackle large-scale, long-tailed recognition in an open world, proposing a decoupled learning framework that balances head and tail class performance while rejecting unknown samples—a critical advancement for practical deployment. Perera and Patel (2019) [1314] focus on deep transfer learning for novelty detection, leveraging pre-trained models to identify multiple unknown classes, thus bridging the gap between OSR and transfer learning. Finally, Xiong et al. (2019) [1315] shift the focus from classification to counting, presenting a spatial divide-and-conquer approach that transitions from open-set to closed-set object counting, demonstrating the versatility of OSR principles beyond traditional recognition tasks.
Table 7.
Summary of Key Contributions to Open Set Recognition (OSR)
| Author(s) | Main Contribution |
|---|---|
| Shao et al. [1293] | Developed Open-set Adversarial Defense by integrating OSR robustness into adversarial training, enabling resilience to both adversarial and unknown-class intrusions. |
| Yu et al. [1294] | Proposed a Multi-Task Curriculum Framework for semi-supervised OSR, balancing supervised and unsupervised learning to progressively handle unknown classes. |
| Miller et al. [1295] | Introduced Class Anchor Clustering, a distance-based loss to form compact class clusters while maximizing inter-class separation in the feature space. |
| Jia and Chan [1296] | Proposed MMF loss to enhance intra-class compactness and inter-class separation, improving discriminative feature learning in OSR. |
| Oliveira et al. [1300] | Extended OSR to semantic segmentation via Fully Convolutional Open Set Segmentation with uncertainty-aware pixel-wise rejection. |
| Yang et al. [1301] | Proposed S2OSC, a semi-supervised OSR framework combining consistency regularization and entropy minimization to exploit both labeled and unlabeled data. |
| Sun et al. [1302] | Used conditional probabilistic generative models to estimate likelihoods and reject unknowns based on uncertainty thresholds. |
| Yang et al. [1303] | Introduced Convolutional Prototype Network (CPN), learning prototypes for known classes and using distance-based rejection for OSR. |
| Dhamija et al. [1304] | Highlighted limitations in open set detection for object recognition and introduced an evaluation framework stressing real-world challenges. |
| Meyer and Drummond [1305] | Advocated for metric learning in robotic vision OSR, emphasizing active learning and incremental unknown class discovery. |
| Oza and Patel [1306] | Proposed a multi-task learning method using autoencoders for joint classification and reconstruction to detect outliers in OSR. |
| Yoshihashi et al. [1307] | Introduced CROSR, which combines classification and reconstruction to use reconstruction error as a cue for open set rejection. |
| Malalur and Jaakkola [1308] | Proposed an alignment-based matching network using metric learning for one-shot OSR with focus on feature alignment. |
| Schlachter et al. [1309] | Developed intra-class splitting to improve decision boundaries by subdividing known classes into more refined sub-clusters. |
| Imoscopi et al. [1310] | Focused on speaker identification in OSR using confidence thresholds in discriminatively trained neural networks. |
| Mundt et al. [1311] | Showed that uncertainty-based methods like softmax entropy and Monte Carlo dropout can rival generative models in OSR. |
Yang et al. (2019) [1316] explore open-set human activity recognition using micro-Doppler signatures, leveraging the distinct radar-based motion patterns to differentiate known from unknown activities, thus demonstrating the applicability of open-set methods in sensor-based domains. Similarly, Oza and Patel (2019) [1317] propose C2AE, a class-conditioned autoencoder that learns discriminative latent representations by reconstructing input samples conditioned on their class, effectively separating known and unknown samples through reconstruction error thresholds. This work is particularly notable for its integration of generative and discriminative learning, providing a robust framework for open-set recognition in computer vision. Liu et al. (2018) [1318] take a theoretical approach, introducing PAC guarantees for open category detection, ensuring probabilistic bounds on detection errors—a crucial contribution for safety-critical applications. Venkataram et al. (2018) [1319] adapt convolutional neural networks (CNNs) for open-set text classification, employing prototype-based rejection mechanisms, highlighting the adaptability of deep learning models to textual open-set scenarios. Meanwhile, Hassen and Chan (2018) [1320] propose a neural-network-based representation learning method that explicitly models uncertainty, improving open-set robustness by learning decision boundaries that account for unseen data distributions.
Further expanding the scope, Shu et al. (2018) [1321] investigate open-world classification, introducing a framework for discovering unseen classes incrementally, which bridges open-set recognition and continual learning. Dhamija et al. (2018) [1322] address "agnostophobia" (fear of the unknown) in deep networks by proposing loss functions that penalize overconfidence on unknown samples, enhancing model calibration in open-set environments. Finally, Zheng et al. (2018) [1324] explore open-set adversarial examples, revealing vulnerabilities in open-set systems and proposing defenses against adversarial attacks that exploit unknown-class detection mechanisms.
Table 8.
Summary of Key Contributions in Open Set Recognition and Related Tasks
| Author(s) | Main Contribution |
|---|---|
| Liu et al. [1313] | Proposed a decoupled learning framework for large-scale, long-tailed recognition that improves balance across head and tail classes while rejecting unknowns. |
| Perera and Patel [1314] | Explored deep transfer learning for novelty detection using pre-trained models to identify multiple unknown classes. |
| Xiong et al. [1315] | Presented a spatial divide-and-conquer framework for open-set to closed-set object counting, applying OSR concepts to counting tasks. |
| Yang et al. [1316] | Applied open-set recognition to human activity recognition using micro-Doppler radar signatures to distinguish known and unknown movements. |
| Oza and Patel [1317] | Introduced C2AE, a class-conditioned autoencoder that separates known and unknown samples using reconstruction error thresholds. |
| Liu et al. [1318] | Provided PAC-based theoretical guarantees for open category detection, offering bounds on detection error. |
| Venkataram et al. [1319] | Adapted CNNs for open-set text classification using prototype-based rejection mechanisms. |
| Hassen and Chan [1320] | Proposed a representation learning technique that models uncertainty to improve robustness to unknown data. |
| Shu et al. [1321] | Developed a framework for open-world classification, enabling discovery of new classes incrementally. |
| Dhamija et al. [1322] | Tackled overconfidence on unknowns by designing loss functions that reduce incorrect high-confidence predictions. |
| Zheng et al. [1324] | Investigated adversarial attacks in open-set systems and proposed defenses to enhance unknown-class detection reliability. |
Neal et al. (2018) [1325] introduce a novel approach using counterfactual image generation to simulate unknown classes, enhancing model robustness by exposing classifiers to synthetic outliers during training. Similarly, Rudd et al. (2017) [1326] propose the Extreme Value Machine (EVM), leveraging extreme value theory (EVT) to model the probability of sample inclusion, providing a theoretically grounded method for open set recognition. Vignotto and Engelke (2018) [1327] further refine EVT-based approaches by comparing Generalized Pareto Distribution (GPD) and Generalized Extreme Value (GEV) classifiers, demonstrating their effectiveness in modeling tail distributions for open set scenarios. Meanwhile, Cardoso et al. (2017) [1328] explore weightless neural networks, which rely on probabilistic memory structures rather than traditional weight updates, offering a unique solution for open set recognition that avoids retraining and adapts dynamically to new data. These works collectively advance the theoretical foundations of open set learning, with EVT-based methods and synthetic data generation emerging as dominant paradigms.
Adversarial and generative techniques also play a pivotal role in open set learning, as evidenced by several studies. Rozsa et al. (2017) [1329] compare Softmax and Openmax in adversarial settings, revealing Openmax’s superior robustness due to its ability to reject uncertain samples. Shu et al. (2017) [1330] extend open set principles to text classification with DOC, a deep learning framework that estimates the probability of a document belonging to an unknown class by modeling semantic boundaries. Generative approaches are further explored by Ge et al. (2017) [1331], who introduce Generative Openmax, synthesizing unknown class samples to improve multi-class open set classification. Complementing this, Yu et al. (2017) [1332] employ adversarial sample generation to create realistic outliers, training classifiers to distinguish known from unknown categories effectively.
A controversial perspective was presented by Vaze et al. (2021) [1231]. They argued that well-trained closed-set classifiers could perform open set recognition without specialized modifications, challenging existing methodologies. In addition to individual papers, several surveys and repositories have played crucial roles in advancing OSL research. Barcina-Blanco et al. (2023) [1232] provided an extensive literature review, identifying gaps and future directions in OSL, particularly its connections to out-of-distribution detection and uncertainty estimation. A curated collection of papers and resources by iCGY96 on GitHub [1233], which serves as a valuable knowledge repository for researchers.
Table 9.
Summary of Key Contributions in Open Set Learning Literature
| Author(s) | Main Contribution |
|---|---|
| Neal et al. [1325] | Introduced counterfactual image generation to simulate unknown classes and improve classifier robustness using synthetic outliers. |
| Rudd et al. [1326] | Proposed the Extreme Value Machine (EVM), leveraging EVT to model sample inclusion probabilities for open set recognition. |
| Vignotto and Engelke [1327] | Compared GPD and GEV classifiers for EVT-based modeling of tail distributions in open set recognition. |
| Cardoso et al. [1328] | Explored weightless neural networks using probabilistic memory structures, enabling dynamic adaptation to new data without retraining. |
| Rozsa et al. [1329] | Compared Softmax and Openmax under adversarial conditions, showing Openmax’s superior ability to reject uncertain samples. |
| Shu et al. [1330] | Developed DOC, a deep open classification framework for text, modeling semantic boundaries to detect unknown classes. |
| Ge et al. [1331] | Introduced Generative Openmax, synthesizing unknown class samples to improve multi-class open set classification. |
| Yu et al. [1332] | Used adversarial sample generation to train classifiers for distinguishing between known and unknown categories. |
| Vaze et al. [1231] | Claimed well-trained closed-set classifiers can inherently perform open set recognition without specific modifications. |
| Barcina-Blanco et al. [1232] | Provided a comprehensive literature review on OSL, highlighting its ties to out-of-distribution detection and uncertainty estimation. |
| iCGY96 (GitHub) [1233] | Curated a repository of papers and resources for open set learning research. |
Finally, while not explicitly about OSL, advances in topological deep learning have implications for open set scenarios. The Wikipedia article on "Topological Deep Learning" [1234] discusses how topological representations—such as graphs, simplicial complexes, and hypergraphs—can improve the ability of deep learning models to handle complex data structures. Understanding these mathematical foundations could lead to new techniques for open set classification by leveraging topological features to distinguish known from unknown data distributions.
These 20 contributions represent a broad spectrum of advancements in Open Set Learning, ranging from foundational theory to practical applications across diverse domains. The field continues to evolve, with researchers developing more robust methods to handle real-world uncertainties where unknown categories must be identified dynamically.
8.2. Literature Review of Traditional Machine Learning Open Set Learning
8.2.1. Foundational Theoretical Frameworks of Open Set Recognition
Open Set Recognition (OSR) challenges the classical closed-world assumption in classification tasks, where classifiers assume that test samples belong to a fixed set of known classes. A key theoretical contribution in this regard comes from Scheirer et al. (2012 [1215], 2014 [1340]), who formalized the concept of open space risk and introduced the Probability of Inclusion and Compact Abating Probability (CAP) models. These models rely on the notion that probability estimates should decay as one moves away from known training samples in the feature space. Their pioneering work provided a probabilistic bounding framework to mitigate open space risk, which is the risk of labeling samples in the space far from known training data. Their extended formulation in Scheirer et al. (2014) [1340] and Jain et al. (2014) [1341] offered a theoretical model for bounding decision regions using Weibull-calibrated decision functions, which underpinned later algorithmic strategies in OSR. These early efforts shifted the focus of machine learning from closed-world generalization to bounded-risk decision-making under unknown classes, laying the groundwork for the development of risk-aware open set classifiers.
8.2.2. Sparse and Hyperplane-Based Models for OSR
Building on these theoretical advances, Zhang and Patel (2017) [1342] proposed a sparse representation-based model for open set recognition, leveraging the observation that reconstruction residuals of samples from unknown classes tend to be higher when approximated by sparse combinations of known-class samples. This aligns conceptually with manifold-based learning, where unknown samples lie outside the manifold of known classes. Complementing this, Cevikalp (2016) [1343] introduced the Best Fitting Hyperplane (BFH) model that constructs hyperplanes to tightly encapsulate class manifolds, rejecting samples that lie beyond class-specific thresholds. The use of convex polyhedral conic classifiers by Cevikalp et al. (2017) [1344] is particularly noteworthy because it geometrically defines decision boundaries using polyhedral cones, enabling fine-grained modeling of class-specific subspaces with controlled inclusion properties. These methods marked a shift toward geometric modeling of decision boundaries and introduced a family of classifiers that reject unknown samples not by probability estimation, but through geometric conformity, paving the way for structural inductive biases in OSR.
8.2.3. Support Vector and Nearest Neighbor Approaches
A particularly impactful contribution to the OSR field is the Specialized Support Vector Machines (SSVM) model by Júnior et al. (2016) [1333], which extends the binary nature of conventional SVMs by incorporating open space risk directly into the objective function through a modified loss. SSVMs enforce margin constraints that not only separate known classes but also maximize rejection capability for samples outside the known class distributions. This framework refines the application of kernel methods to OSR, combining margin maximization with bounded decision regions. Complementarily, the Nearest Neighbors Distance Ratio (NNDR) model by Júnior et al. (Machine Learning, 2017) [1334] presents a non-parametric alternative by exploiting the ratio of distances between the first and second nearest neighbors in feature space to determine class membership confidence. NNDR’s simplicity allows it to be easily adapted across domains, though its effectiveness heavily depends on the embedding space quality. Together, SSVM and NNDR form a methodological dichotomy—parametric versus non-parametric—offering flexibility in addressing domain-specific constraints in OSR.
8.2.4. Domain Transfer and Zero-Shot Learning Integration
Dong et al. (2022) [1335] tackled the Open Set problem from a probabilistic domain separation perspective, integrating ideas from Generalized Zero-Shot Learning (GZSL). Their approach explicitly learns latent domain variables that disentangle the semantic space (representing class attributes or names) from the visual feature space. The core insight lies in representing open set uncertainty as a distributional mismatch between the source and target domains, introducing Bayesian inference mechanisms to model both intra-class and inter-class variabilities. This probabilistic modeling allows for adaptive thresholds based on estimated epistemic uncertainty, distinguishing between known and unknown domains. This direction is crucial for scenarios where semantic information is available (as in GZSL) but the supporting visual exemplars are missing, representing a convergence between domain generalization and OSR. The conceptual blend of OSR with domain separation and transfer learning pushes the field beyond traditional boundaries into multi-domain recognition problems.
8.2.5. Application-Centric Advances: Face Recognition and Text Classification
While many OSR studies focus on general object recognition, specific domains have benefited from customized adaptations. Vareto et al. (2017) [1336] addressed the open set face recognition problem using hashing-based functions, constructing compact binary embeddings that preserve inter-class distances while maximizing intra-class compactness. These binary representations allow efficient retrieval while facilitating open set rejection by thresholding Hamming distances. In text classification, Fei and Liu (2016) [1337] proposed a model that breaks the closed world assumption by introducing an open set text classifier based on clustering in semantic embedding space followed by probabilistic scoring of cluster affinity. Their work was among the earliest to show that textual open set recognition requires different inductive biases than visual data, such as attention to lexical sparsity and semantic drift. These domain-specific contributions highlight the adaptability of OSR principles to diverse tasks, demonstrating that open set rejection mechanisms must be finely tuned to the structure of the data modality in question.
8.2.6. Ensemble and Fusion-Based Enhancements
An important trend in recent OSR research is the integration of multiple recognition cues. Neira et al. (2018) [1339] proposed a data-fusion framework for OSR by combining multiple classifiers trained on distinct data representations or modalities. Their fusion strategy uses confidence-weighted voting, in which each classifier’s decision is weighted by its estimated confidence or risk, leading to a more robust rejection of unknowns. This ensemble-style method addresses the single-view limitations of earlier OSR models and promotes redundancy-aware classification, enhancing performance particularly in noisy or high-dimensional feature spaces. The core innovation here lies not merely in aggregation but in leveraging differential openness across models, exploiting the fact that some classifiers are more sensitive to open space regions than others. This line of research is critical for real-world deployment, where multiple sensor modalities or feature embeddings are often available, and the combined information must be integrated in a risk-aware, rejection-capable manner. It also paves the way for hybrid OSL systems combining symbolic reasoning, neural inference, and uncertainty quantification.
8.3. Mahalanobis Distance
The Mahalanobis distance is a fundamental metric in Open Set Learning (OSL), where the primary objective is to correctly classify known samples while rigorously rejecting unknown samples. Given a feature space , let the data distribution of known classes be characterized by a mean feature vector and a covariance structure. The Mahalanobis distance is an extension of the Euclidean distance that takes into account correlations between different feature dimensions and properly normalizes for variance in different directions of the feature space. If is a given feature vector extracted from a trained deep neural network and represents the mean feature vector of a particular class c, then the covariance matrix describes the spread of features around their respective class means. The Mahalanobis distance of the feature vector from the mean representation of class c is given by
This metric effectively measures how many standard deviations away the point is from the mean when considering the full covariance structure. The inverse covariance matrix accounts for correlations between different feature dimensions, ensuring that directions of high variance contribute less to the distance measurement, while directions of low variance contribute more. If the covariance matrix is diagonal, the Mahalanobis distance reduces to a normalized Euclidean distance, with each feature being scaled by the inverse of its standard deviation. Explicitly, if
then
However, in high-dimensional feature spaces where correlations exist between different feature components, the full covariance matrix must be considered. The primary utility of Mahalanobis distance in Open Set Learning stems from its ability to identify samples that deviate significantly from the known class distributions. The decision rule for classification in Open Set Learning using Mahalanobis distance is defined as follows: for a given test sample , the predicted label is assigned based on
where is the set of known classes. However, in Open Set Learning, the classification decision must also incorporate a rejection criterion for unknown samples. This is accomplished by introducing a rejection threshold , such that if
then is rejected as an unknown sample. The threshold is typically determined based on the distribution of Mahalanobis distances computed from the training set. Specifically, if the Mahalanobis distances of training samples follow a Gaussian distribution
then the threshold can be set as
where is a hyperparameter controlling the rejection sensitivity. A larger value of increases the likelihood of rejecting unknown samples but may also lead to the rejection of some in-distribution samples. Conversely, a smaller results in fewer rejections, potentially increasing the misclassification of unknown samples as known ones. In high-dimensional feature spaces, the covariance matrix may become singular or ill-conditioned, making the direct computation of unstable. To address this, a regularized covariance estimate is often employed:
where is a small regularization parameter, ensuring numerical stability. The corresponding regularized Mahalanobis distance is then given by
This formulation ensures robust covariance estimation and improves the generalization ability of the Mahalanobis distance metric. In deep Open Set Learning settings, feature representations obtained from neural networks may not be perfectly Gaussian, necessitating additional adaptation techniques. One approach is to learn feature embeddings such that Mahalanobis distance becomes more effective for Open Set Recognition. If is a neural network feature extractor parameterized by , then the loss function can be augmented to explicitly minimize intra-class Mahalanobis distances while maximizing inter-class separability:
Furthermore, in order to improve the rejection of out-of-distribution samples, an auxiliary dataset containing unknown samples can be used. The out-of-distribution loss is given by
This enforces a constraint that encourages the Mahalanobis distance of unknown samples to remain above the rejection threshold , improving the ability of the model to detect unknown samples. The combined objective function used in Open Set Learning can then be formulated as
where is a balancing hyperparameter. In addition to the rejection-based approach, Mahalanobis distance can be integrated with probabilistic modeling techniques such as Gaussian mixture models (GMMs) for better open set decision boundaries. Given a mixture model with C Gaussian components, the probability of a feature vector belonging to class c is computed as
where is the prior probability of class c and
is the Gaussian density function. This formulation enables a soft probabilistic decision rule for Open Set Learning. The Mahalanobis distance, due to its statistical foundation, provides a rigorous means of identifying unknown samples in Open Set Learning by leveraging class-specific feature distributions. Its ability to incorporate covariance structures makes it significantly more robust than Euclidean distance, leading to improved open set classification performance in high-dimensional spaces.
8.4. Literature Review of Bayesian Formulation in Open Set Learning
Open Set Learning (OSL) aims to handle scenarios where the model encounters unseen classes during inference. A Bayesian approach provides a principled probabilistic framework for quantifying uncertainty and distinguishing known from unknown instances. This involves incorporating prior knowledge, likelihood estimation, and posterior inference to make robust predictions under open-set conditions.
8.4.1. Literature Review of Bayesian Neural Networks (BNNs) for OSL
Gal and Ghahramani (2016, ICML) [1345] pioneered dropout as Bayesian approximation, showing that MC dropout during inference approximates variational inference in deep networks, enabling scalable uncertainty estimation. Lakshminarayanan et al. (2017, NeurIPS) [1346] demonstrated that deep ensembles outperform MC dropout in OOD detection by marginalizing over multiple model instantiations. Rudd et al. (2017, IEEE TPAMI) [1347] introduced the Extreme Value Machine (EVM), using extreme value theory to model tail distributions of class scores for open-set rejection. Malinin and Gales (2018, NeurIPS) [1348] proposed Prior Networks, which explicitly parameterize Dirichlet distributions over logits to separate distributional and data uncertainty. Liu et al. (2020, NeurIPS) [1349] designed an energy-based OOD detector that bypasses density estimation by leveraging the logit space of BNNs. Chen et al. (2021, ICLR) [1350] unified Bayesian online learning with OSL, enabling incremental adaptation to novel classes via variational inference. Nandy et al. (2020, NeurIPS) [1351] maximized the representation gap between known and unknown classes by joint optimization of discriminative and uncertainty objectives. Mukhoti et al. (2021, ICML) [1353] calibrated BNNs for OSL using gradient-based uncertainty regularization. Kristiadi et al. (2020, NeurIPS) [1354] showed that spectral normalization in BNNs improves OOD detection by enforcing distance-awareness. Ovadia et al. (2019, NeurIPS) [1355] benchmarked BNNs under dataset shift, revealing critical trade-offs between accuracy and uncertainty calibration in OSL.
Key Insight: BNNs excel in scalability and integration with deep learning but often rely on approximations that may underestimate uncertainty.
8.4.2. Literature Review of Dirichlet-Based Uncertainty for OSL
Sensoy et al. (2018, NeurIPS) [1356] formulated Evidential Deep Learning (EDL), treating predictions as subjective opinions under Dempster-Shafer theory, with Dirichlet concentrations encoding uncertainty. Bendale and Boult (2016, CVPR) [1357] introduced OpenMax, replacing softmax with Weibull-calibrated Dirichlet scores to reject unknowns. Oza and Patel (2019, CVPR) [1306] proposed C2AE, a class-conditioned autoencoder that uses reconstruction error and Dirichlet uncertainty for OSL. Yoshihashi et al. (2019, CVPR) [1307] combined VAEs with Dirichlet priors to jointly optimize classification and reconstruction for open-set robustness. Kong and Ramanan (2021, ICCV) [1223] developed OpenGAN, where Dirichlet uncertainty guides GANs to synthesize adversarial unknowns. Neal et al. (2018, ECCV) [1325] generated counterfactual unknowns using Dirichlet-based sampling to augment training data. Zhang et al. (2020, ECCV) [1292] hybridized Dirichlet models with discriminative classifiers, achieving SOTA on open-set benchmarks. Charoenphakdee et al. (2021, ICML) [1360] analyzed Dirichlet calibration under label noise, improving OSL reliability. Hendrycks et al. (2019, NeurIPS) [1361] used Dirichlet-based confidence thresholds to detect anomalies. Vaze et al. (2022, CVPR) [1362] generalized EVM to few-shot OSL by integrating meta-learning with Dirichlet uncertainty.
Key Insight: Dirichlet methods provide interpretable uncertainty but require careful calibration to avoid overconfidence.
8.4.3. Literature Review of Gaussian Processes (GPs) for OSL
Geng et al. (2020, IEEE TPAMI) [1219] surveyed GP-based OSL, highlighting their non-parametric flexibility for uncertainty quantification. Liu et al. (2020, NeurIPS) [1363] proposed distance-aware deep kernels, enabling GPs to scale to high-dimensional data while preserving uncertainty metrics. Van Amersfoort et al. (2020, ICML) [1364] combined GPs with deep feature extractors for deterministic uncertainty estimation. Smith and Gal (2018, UAI) derived GP-based adversarial detection bounds, proving robustness in OOD settings. Fort et al. (2019, NeurIPS) [1366] linked deep ensembles to GP posteriors, unifying ensemble and Bayesian nonparametric approaches. Sun et al. (2019, ICLR) [1368] bridged GPs and BNNs via functional variational inference, improving OOD generalization. Ober et al. (2021, ICML) [1367] identified pitfalls of deep kernel GPs in OSL, advocating for spectral normalization. Bradshaw et al. (2017, AISTATS) [1369] used sparse GPs to enable scalable open-world recognition. Daxberger et al. (2021, NeurIPS) [1370] enhanced GP uncertainty with Laplace approximations for deep learning. Kapoor et al. (2022, JMLR) [1371] developed GP-based active learning for OSL, optimizing query strategies for unknown class discovery.
Key Insight: GPs offer gold-standard uncertainty quantification but face computational bottlenecks in high dimensions.
8.4.4. Literature Review of Variational Autoencoders (VAEs) and Bayesian Generative Models
Pidhorskyi et al. (2018, NeurIPS) [1372] proposed adversarial autoencoders (AAEs) with probabilistic novelty detection via reconstruction likelihood. Schlegl et al. (2017, MICCAI) [1373] introduced AnoGAN, using latent space traversals for medical OOD detection. Xiao et al. (2020, NeurIPS) [1374] defined likelihood regret, a theoretically grounded OOD score comparing local latent densities. Nalisnick et al. (2019, ICLR) [1375] exposed VAEs’ failure modes, showing that OOD data can attain high likelihoods. Choi et al. (2018, NeurIPS) [1376] improved VAEs using WAIC-scored ensembles for anomaly detection. Denouden et al. (2018, NeurIPS Workshop) [1377] augmented VAEs with Mahalanobis distance in latent space for robust OOD detection. Kirichenko et al. (2020, NeurIPS) [1378] proved that normalizing flows fail in OOD detection without task-specific inductive biases. Serra et al. (2020, ICML) [1379] trained VAEs with input complexity measures to distinguish novelty. Morningstar et al. (2021, ICLR) [1380] proposed density-supervised VAEs, jointly optimizing likelihood and discriminative boundaries. Ruff et al. (2021, JMLR) [1381] unified deep one-class classification with VAE-based generative models.
Key Insight: VAEs excel in generative novelty detection but struggle with likelihood-based metrics; hybrid approaches are often necessary.
8.4.5. Critical Synthesis
BNNs dominate practical OSL due to scalability but approximate true posteriors. Dirichlet methods offer interpretability but need calibration. GPs provide theoretical rigor but are computationally expensive. VAEs enable generative OSL but require auxiliary metrics (e.g., likelihood regret).
Future Directions: Hybrid architectures (e.g., BNNs + GPs), tighter PAC-Bayesian bounds, and calibration-aware training are promising avenues. These Bayesian approaches collectively advance OSL by unifying uncertainty quantification with adaptive learning.
8.5. Analysis of Bayesian Formulation in Open Set Learning
We have to use Bayesian Decision Theory in Open Set Learning. In the Bayesian framework, given an input , the goal is to estimate the posterior probability of class membership:
where y belongs to the set of known classes , and represents the training data. The Bayesian formulation considers a prior distribution over classes and updates it using the likelihood via Bayes’ theorem:
where the evidence term is given by marginalization over all known classes:
For open-set scenarios, an additional unknown class is introduced, leading to:
where is the prior probability of encountering an unknown class. If is too low, the model may overcommit to known classes. We have to model the Likelihood via Generative Distributions. To estimate , a Bayesian model assumes a parametric likelihood such as a Gaussian mixture:
The parameters are inferred using Maximum A Posteriori (MAP) estimation:
By integrating out uncertainty in parameters, a Bayesian predictive distribution is obtained:
For open-set detection, if the posterior entropy
exceeds a threshold, the sample is classified as unknown. Bayesian Neural Networks can also be used for Open Set Learning. A Bayesian neural network (BNN) introduces a prior distribution over the network parameters , leading to a posterior distribution:
The predictive posterior for a test input is then given by:
Since this integral is intractable, approximation techniques such as Variational Inference (VI) or Monte Carlo Dropout are used. In VI, the posterior is approximated by a parametric distribution :
which results in an evidence lower bound (ELBO):
Predictions are made using multiple stochastic forward passes, yielding an uncertainty estimate through variance:
High variance corresponds to greater epistemic uncertainty, signaling an open-set sample. There are several Bayesian Nonparametric Methods for Open Set Learning. Bayesian nonparametric models, such as Gaussian Processes (GPs), provide an alternative approach. A GP places a prior over functions:
The posterior mean and variance for a new point given training data are:
If is large, the sample is flagged as unknown. Let’s now discuss the Bayesian Open Set Recognition with Dirichlet Distributions. A Bayesian framework can incorporate Dirichlet distributions for modeling class probabilities:
For open-set detection, an unknown class component is introduced, leading to an augmented Dirichlet prior:
If the posterior probability mass assigned to the unknown component is significant, the sample is rejected as open-set.
In conclusion, A Bayesian approach to Open Set Learning provides a principled uncertainty quantification mechanism, distinguishing unknown from known samples by leveraging posterior probabilities, entropy-based rejection criteria, and epistemic uncertainty estimates. The use of Bayesian Neural Networks, Gaussian Processes, and Dirichlet distributions enables robust open-set recognition, improving model reliability in real-world applications.
8.6. Gaussian Mixture Model (GMM)
In generative modeling, the open set learning problem is fundamentally rooted in the estimation of the likelihood function , where represents an observed data sample in a d-dimensional feature space, and y is a discrete class label. The Gaussian Mixture Model (GMM) is an ideal candidate for modeling this likelihood function due to its ability to approximate arbitrary density functions as a superposition of Gaussian components. Formally, the GMM models the conditional density function as a weighted sum of multivariate normal distributions:
where each Gaussian component k for class y is parameterized by a mean vector , a covariance matrix , and a mixture weight satisfying the normalization constraint:
The probability density function of each multivariate normal component is given explicitly by:
By expanding the quadratic form in the exponent, the probability density function can be rewritten in terms of Mahalanobis distance:
The total log-likelihood of the data under the GMM model is given by:
Direct computation of the log-sum can lead to numerical instability, which is mitigated using the log-sum-exp trick:
where
is chosen to stabilize exponentiation. For open set recognition, an input sample x is classified as an out-of-distribution (OOD) sample if its likelihood falls below a predefined threshold , i.e.,
An alternative formulation leverages Bayesian inference to determine the most probable class given an observed sample x. Using Bayes’ theorem,
where is the prior probability of class y, which is often assumed uniform over the set of known classes. The most probable class is then determined via the maximum a posteriori (MAP) estimation:
If is below a rejection threshold , the sample is assigned to an unknown category:
The training of the Gaussian Mixture Model parameters is performed using the Expectation-Maximization (EM) algorithm. Given a dataset , the E-step computes the posterior responsibility of each Gaussian component:
In the M-step, the parameters are updated as follows:
An alternative approach to OOD detection is based on the Mahalanobis distance, which measures the squared deviation of a sample from a Gaussian component:
If exceeds a predefined threshold , then the sample is classified as OOD:
The Gaussian Mixture Model provides a theoretically rigorous and computationally efficient approach for open set learning, leveraging probabilistic likelihood estimation, Bayesian inference, and robust distance measures to distinguish in-distribution and out-of-distribution samples. The parameter optimization via Expectation-Maximization ensures maximum likelihood estimation of the mixture components, and the decision criteria based on likelihood thresholds or Mahalanobis distances provide strong theoretical guarantees for identifying unknown samples.
8.7. Dirichlet Process Gaussian Mixture Model (DP-GMM)
In generative modeling, the open-set learning problem is fundamentally framed as estimating the conditional likelihood under a Dirichlet Process Gaussian Mixture Model (DP-GMM). The central challenge in open-set learning is to correctly handle data points that may arise from an unknown category, meaning that their underlying distribution differs from that of the training data. To achieve this, we employ a nonparametric Bayesian approach that allows for an unbounded number of mixture components, ensuring that the model can flexibly introduce new clusters for previously unseen samples. This is accomplished by imposing a Dirichlet Process (DP) prior on the mixture component weights, which results in a countably infinite Gaussian Mixture Model (GMM), effectively allowing the number of clusters to grow dynamically with the data. Given an observed dataset , where each represents a sample in a d-dimensional feature space and is its corresponding class label, the likelihood estimation problem can be expressed in the form
where z represents a latent variable denoting the cluster assignment. The likelihood follows a multivariate Gaussian distribution parameterized by cluster-specific mean and covariance , given by
Since the number of mixture components is unknown, a Dirichlet Process (DP) prior is imposed on the cluster assignment probabilities, leading to the hierarchical model
where G is a discrete random probability measure drawn from a Dirichlet Process with concentration parameter and base distribution , which defines the prior over component parameters. The construction of the DP-GMM is commonly represented using the stick-breaking process, where the mixture weights are recursively defined as
ensuring the normalization constraint
Given this formulation, the posterior distribution over cluster assignments follows
The open-set learning problem requires the ability to identify and appropriately model unseen categories. This is naturally handled by the Chinese Restaurant Process (CRP) representation of the DP, where a new data point is assigned to a new cluster with probability
where N is the total number of previously observed samples. Consequently, the likelihood of an unseen data point under the DP-GMM model expands as
A sample is classified as OOD (out-of-distribution) if its posterior likelihood falls below a learned threshold , which can be determined using a Bayesian uncertainty criterion, leading to the decision rule
To further quantify the uncertainty in cluster assignments, the Shannon entropy of the posterior is computed as
A high entropy indicates significant uncertainty, suggesting that the sample does not belong to any of the known categories and should be treated as an open-set example. If entropy exceeds a critical threshold, the sample is automatically assigned to a new cluster, thereby allowing the model to flexibly accommodate previously unseen classes. The hierarchical Bayesian formulation of the DP-GMM further provides a robust probabilistic framework for managing inherent ambiguity in classification by leveraging both the prior knowledge encoded in and the adaptive nature of the Dirichlet Process, which dynamically introduces new components as necessary. From an inference perspective, model parameters and mixture proportions are estimated using variational inference or Gibbs sampling, where the posterior updates involve integrating over all possible assignments z given the prior over cluster structure. The posterior distribution over mixture components follows
where the prior is typically chosen as a conjugate Normal-Inverse-Wishart (NIW) distribution, ensuring closed-form updates. The resulting Bayesian inference scheme ensures that uncertainty is explicitly quantified at every level of the learning process, making DP-GMM a principled generative model for open-set learning.
8.8. Conjugate Normal-Inverse-Wishart (NIW) Distribution
In the context of generative modeling, the open set learning problem is rigorously framed as the estimation of the likelihood for a data point x given a class label y, where y may belong to either a known class or an unknown class. This problem is addressed by modeling the likelihood under a conjugate Normal-Inverse-Wishart (NIW) distribution, which provides a mathematically tractable and statistically rigorous framework for parameter estimation. The NIW distribution serves as a conjugate prior for the multivariate normal distribution with unknown mean and covariance , enabling closed-form updates of the posterior distribution given observed data. The NIW distribution is parameterized by hyperparameters , , , and , where is the prior mean, is a scaling factor for the prior mean, is a symmetric positive definite scale matrix, and is the degrees of freedom. The joint probability density function of the NIW distribution is given by:
where is the multivariate normal distribution and is the inverse-Wishart distribution. The multivariate normal distribution is defined as:
and the inverse-Wishart distribution is defined as:
where is the multivariate gamma function, d is the dimensionality of the data, and tr denotes the trace of a matrix. Given a dataset , where and for known classes or for an unknown class, the likelihood is modeled as a multivariate normal distribution with class-specific parameters and . These parameters are drawn from the NIW prior distribution:
The posterior distribution of and given the observed data is also an NIW distribution, with updated hyperparameters . The updated hyperparameters are derived as:
where is the number of data points in class y, is the sample mean of the data points in class y, and is the scatter matrix for class y. The likelihood is obtained by marginalizing over the parameters and :
Due to the conjugacy of the NIW prior, this integral can be evaluated analytically, resulting in a multivariate Student’s t-distribution:
where is the multivariate Student’s t-distribution with mean , scale matrix , and degrees of freedom . The multivariate Student’s t-distribution is given by:
In the open set learning framework, the likelihood is used to compute the probability that a new data point x belongs to a known class y. If falls below a predefined threshold for all known classes y, the data point x is classified as belonging to an unknown class. This approach leverages the statistical properties of the NIW distribution and the multivariate Student’s t-distribution to provide a rigorous and principled solution to the open set learning problem. The mathematical formulation ensures that the model can effectively distinguish between known and unknown classes while maintaining robustness and interpretability.
8.9. Extreme Value Theory (EVT) Models
In generative modeling, the open set learning problem concerns the ability of a model to distinguish between seen and unseen data by estimating the likelihood . This problem is fundamentally linked to extreme value theory (EVT), which characterizes the statistical behavior of the tails of probability distributions. EVT provides a rigorous mathematical framework for modeling the behavior of rare events, which is crucial for identifying out-of-distribution (OOD) samples. Given an observed data point and a class label y, the likelihood function exhibits tail properties that can be asymptotically approximated using EVT. This follows from the Fisher-Tippett-Gnedenko theorem, which states that the maximum of independent and identically distributed (i.i.d.) random variables, properly normalized, converges to one of three types of extreme value distributions: Gumbel, Fréchet, or Weibull. The key observation in open set recognition is that samples from an unknown class exhibit extreme deviations in their likelihood estimates, which can be rigorously modeled through EVT-based tail fitting.
The first step in this formulation is to define a log-likelihood function, which quantifies the probability of observing a sample given a particular class. Let the log-likelihood function be given by
where captures the statistical relationship between the observed data and the conditional density function. In EVT-based approaches, one considers the distribution of extreme values of , specifically in the lower tail, since OOD samples tend to have significantly lower likelihoods. The fundamental result from EVT states that for a sufficiently large number of independent observations, the limiting distribution of the minimum values follows a Generalized Extreme Value (GEV) distribution, given by
where is the shape parameter, is the location parameter, and is the scale parameter. In the context of likelihood estimation, the limiting behavior of follows a Generalized Pareto Distribution (GPD), which describes the excess over a given threshold. The probability density function (PDF) of the GPD is given by
where represents the deviation from the maximum likelihood observed in training data. The fundamental insight from EVT is that for sufficiently high thresholds, the distribution of these deviations converges to the GPD. This allows us to estimate the probability that a given likelihood falls below a certain threshold using
which provides a principled way of defining OOD detection thresholds. A sample is considered to be OOD if
where is selected based on the EVT-derived confidence interval. Given a set of training samples from a known class, one can fit the EVT parameters by solving the maximum likelihood estimation (MLE) problem
This provides an optimal estimate of the tail parameters, ensuring that the EVT model accurately represents the behavior of extreme likelihood values. Once the parameters are estimated, one can compute a dynamic threshold for rejecting OOD samples by solving
where p is the desired false positive rate for in-distribution samples. The EVT-based formulation allows for a probabilistic characterization of whether a given sample belongs to a known or unknown class, rather than relying on heuristics. To incorporate this within a Bayesian framework, the posterior probability of a class given an observation is computed using Bayes’ theorem as
Since EVT provides a distributional form for under extreme value behavior, one can estimate the denominator using the cumulative probability function of the GPD:
Replacing with the EVT-derived approximation, the posterior can be rewritten as
This formulation ensures that as moves further into the tail, the posterior probability of all known classes decreases, leading to a natural rejection mechanism for OOD samples. An alternative approach to likelihood estimation involves using a logistic function to approximate the EVT threshold behavior, given by
where is a scale parameter controlling the steepness of the probability drop-off. The EVT-based model ensures that open set detection is grounded in rigorous statistical principles, as opposed to ad-hoc thresholding methods. The theoretical justification of EVT-based likelihood estimation follows from the asymptotic stability of the GPD under maximum domain of attraction conditions, ensuring that the fitted distribution remains valid for new samples. Consequently, the EVT-based formulation provides a robust and theoretically sound approach to estimating likelihoods under generative models, enabling principled open set recognition.
8.10. Bayesian Neural Networks (BNNs)
In generative modeling, the open set learning problem is fundamentally framed in terms of estimating the likelihood under Bayesian Neural Networks (BNNs) because the Bayesian framework allows for a principled quantification of uncertainty. Open set learning requires the model to be aware of its epistemic uncertainty—uncertainty arising from a lack of knowledge about the data distribution. This is crucial for distinguishing between in-distribution (ID) data and out-of-distribution (OOD) data, a problem that traditional deterministic neural networks struggle with. The Bayesian formulation mitigates this issue by considering an entire distribution over model parameters , rather than a single point estimate. The posterior distribution over the parameters given the dataset is given by Bayes’ theorem as
where is the likelihood function, is the prior over the network parameters, and is the marginal likelihood (also known as the model evidence), which ensures proper normalization. Since the marginal likelihood is intractable in deep neural networks due to the high-dimensional integral over all possible parameter configurations, approximate inference techniques such as variational inference, Monte Carlo methods (e.g., Hamiltonian Monte Carlo or Stochastic Gradient Langevin Dynamics), or Laplace approximations are employed to obtain an approximation to the posterior distribution. Given this posterior, the Bayesian predictive distribution for a new input conditioned on a class label is obtained by marginalizing over :
This integral encodes both aleatoric uncertainty (due to inherent noise in the data) and epistemic uncertainty (due to lack of knowledge). Since this integral is computationally intractable for high-dimensional parameter spaces, it is typically approximated via Monte Carlo integration using an ensemble of sampled parameters :
A fundamental property of Bayesian models in the context of open set learning is that the variance of the predictive distribution provides a direct measure of epistemic uncertainty. The predictive mean and variance are given by
For inputs that are outside the training distribution, the variance of the predictive distribution is expected to be significantly higher because the posterior over is conditioned only on the observed training data and lacks information about unseen samples. This property allows Bayesian models to naturally detect OOD data by thresholding on predictive uncertainty. To model the conditional likelihood , generative Bayesian models introduce latent variables z to capture underlying structure in the data:
Since direct inference over the latent variable posterior is intractable, variational inference approximates it with a variational distribution , leading to the Evidence Lower Bound (ELBO):
Here, denotes the Kullback-Leibler divergence, which enforces regularization by minimizing the difference between the approximate posterior and the true prior. In practice, deep generative models such as Variational Autoencoders (VAEs), Normalizing Flows, and Deep Energy-Based Models leverage Bayesian formulations to learn structured representations of in high-dimensional spaces. From a Bayesian decision-theoretic perspective, the total uncertainty in a prediction is measured using the predictive entropy:
Decomposing this entropy into aleatoric and epistemic components via mutual information, the epistemic uncertainty is captured by the expected Kullback-Leibler divergence between individual parameter-conditioned predictions and the full posterior predictive distribution:
Higher epistemic uncertainty indicates that the model is less confident in its prediction due to insufficient training data, which is a key indicator of an OOD sample. By setting an uncertainty threshold, a Bayesian classifier can reject predictions on OOD data, effectively implementing an open set classifier.
Bayesian neural networks thus provide a mathematically rigorous solution to the open set learning problem by naturally incorporating uncertainty through posterior inference over model parameters, leveraging predictive distributions to measure epistemic uncertainty, and applying principled probabilistic inference techniques such as variational approximations and Monte Carlo integration. The estimation of in this framework allows the model to dynamically adjust its confidence in predictions and provide robust detection of OOD samples by analyzing likelihood distributions.
8.11. Support Vector Models
In the context of generative modeling, the open set learning problem is rigorously formalized as the estimation of the conditional likelihood under Support Vector Machines (SVMs) by employing advanced probabilistic frameworks, optimization theory, and statistical learning principles. The objective is to model the distribution of data x conditioned on class labels y, where y may belong to a known set of classes or an unknown class . This necessitates a mathematically precise formulation that integrates discriminative learning with probabilistic reasoning to handle both known and unknown classes. The likelihood is derived from Bayes’ theorem, which decomposes the conditional probability as:
where is the posterior probability of class y given x, is the marginal distribution of x, and is the prior probability of class y. Under the SVM framework, the posterior is modeled using a discriminant function , which is optimized to separate classes while maximizing the margin. The optimization problem for learning is formulated as:
subject to the constraints:
where denotes the norm of in the reproducing kernel Hilbert space (RKHS) , C is a regularization parameter controlling the trade-off between margin maximization and classification error, and are slack variables accounting for misclassifications. The discriminant function is expressed as:
where is the weight vector in the feature space, is a feature mapping function, and is the bias term. To extend this framework to open set learning, the likelihood is augmented with a rejection mechanism to handle unknown classes. This is achieved by introducing a class-specific threshold , such that:
The threshold is determined by minimizing the empirical risk on a validation set , formalized as:
where is the indicator function, and is the loss incurred when an instance from an unknown class is misclassified as belonging to class y. This ensures that the model rejects instances from unknown classes with high confidence. The likelihood is further refined using kernel methods, which enable SVMs to operate in a high-dimensional feature space. The kernel function is defined as:
where denotes the inner product in the RKHS . The discriminant function in the kernelized form is given by:
where are the Lagrange multipliers obtained from solving the dual optimization problem:
subject to the constraints:
The kernelized discriminant function allows the model to capture complex decision boundaries in the input space. The likelihood is then estimated by combining the kernelized discriminant function with the rejection mechanism:
This formulation ensures that the model assigns high likelihood to instances from known classes while rejecting instances from unknown classes. The overall objective is to maximize the log-likelihood of the observed data under the model:
where represents the parameters of the model, including , , and . To further enhance the rigor, the optimization problem is regularized using a penalty term to prevent overfitting:
where is a regularization parameter, and is typically chosen as the -norm of the parameters:
This ensures that the model generalizes well to unseen data while maintaining discriminative power.
In conclusion, the open set learning problem under SVMs is rigorously framed as the estimation of through a combination of probabilistic modeling, kernel methods, and optimization. The discriminant function is optimized to separate known classes while incorporating a rejection mechanism for unknown classes, ensuring robust performance in open set scenarios. The likelihood is derived using Bayes’ theorem and refined through kernelized discriminant functions, resulting in a mathematically precise and computationally tractable framework for open set learning.
8.12. Support Vector Data Description
In the context of generative modeling, the open set learning problem is rigorously formalized under the Support Vector Data Description (SVDD) framework by constructing a probabilistic model for the likelihood through the optimization of a hypersphere that encapsulates the data distribution of class y. The hypersphere is defined by its center and radius , which are determined by solving a constrained optimization problem that minimizes the volume of the sphere while ensuring that the majority of the training data for class y lie within or close to the sphere. The primal optimization problem is formulated as:
subject to the constraints:
where are slack variables that permit deviations from the strict boundary, is a regularization parameter that balances the trade-off between the sphere’s volume and the penalty for outliers, and N is the cardinality of the training set. The likelihood is modeled as a function of the squared Euclidean distance , which quantifies the deviation of a test point from the center . Specifically, the likelihood is expressed as:
where Z is a normalization constant ensuring that , and is a scaling parameter that governs the rate of decay of the likelihood as the distance from the center increases. The distance is computed in a feature space induced by a kernel function , which allows for non-linear decision boundaries. The kernelized distance is given by:
where are the Lagrange multipliers obtained from the dual formulation of the SVDD optimization problem. The dual problem is derived by introducing Lagrange multipliers and for the inequality constraints, resulting in the following Lagrangian:
By setting the derivatives of the Lagrangian with respect to R, , and to zero, the dual optimization problem is obtained as:
subject to the constraints:
The solution to the dual problem yields the Lagrange multipliers , which are used to compute the center as:
The radius R is determined by selecting any support vector for which , and computing:
The likelihood is then used to classify a test point as belonging to the open set if the likelihood falls below a threshold , which is determined based on the desired trade-off between false positives and false negatives. The decision rule is formalized as:
The threshold can be estimated using cross-validation or other statistical techniques to optimize the model’s performance. This formulation provides a rigorous and mathematically sound framework for open set learning, combining principles from optimization, kernel methods, and probabilistic modeling to estimate the likelihood and distinguish between known and unknown classes in a principled manner. The SVDD-based approach ensures that the model generalizes well to unseen data while maintaining computational efficiency and robustness to outliers.
9. Zero-Shot Learning
Zero-shot learning (ZSL) is a machine learning paradigm in which a model is trained to recognize classes that were not present in the training data by leveraging auxiliary semantic information. Let denote the input space (e.g., images or texts) and the set of seen classes available during training. The goal is to generalize to a disjoint set of unseen classes , where . This is achieved through a semantic embedding space , which encodes class descriptions (e.g., attributes, word vectors, or textual prompts) and bridges the gap between seen and unseen classes.
The training objective involves learning a mapping from inputs to the semantic space, alongside a compatibility function that scores the alignment between input embeddings and class prototypes. For a sample with class , the model minimizes the following loss:
where maps classes to their fixed or learnable semantic embeddings (e.g., for attribute vectors ), is the one-hot encoded label, and ℓ is a cross-entropy or margin-based loss. At inference, the model predicts the class of an input x by maximizing compatibility over all possible classes:
In generalized zero-shot learning (GZSL), the model must classify inputs from both seen and unseen classes (), posing additional challenges due to bias toward seen classes. To mitigate this, a calibration function is often applied to logits:
where g adjusts scores to balance seen and unseen class predictions (e.g., via entropy regularization or temperature scaling). The semantic transfer is governed by the structure of : if is a linear space (e.g., word2vec), the model relies on geometric relationships (e.g., ). For nonlinear embeddings (e.g., CLIP), a joint vision-language space ensures that and are aligned through contrastive learning:
where is a temperature hyperparameter and is a batch of negative samples. Theoretical guarantees for ZSL depend on the coverage of by the convex hull of in , ensuring that unseen classes are semantically reachable via combinations of seen classes.
For complex class hierarchies, ZSL leverages knowledge graphs , where nodes represent classes and edges encode relations (e.g., "is-a" or "has-property"). The semantic embedding is then a function of graph convolutions:
where is the adjacency matrix, are initial node features, and are GNN parameters. This enables multi-hop reasoning, such as inferring that "zebra" is a subclass of "horse" with "stripes." Hybrid approaches combine symbolic (graph-based) and subsymbolic (vector-based) embeddings, with decomposed into orthogonal subspaces for attributes and relations :
where ⊕ denotes concatenation and MLP is a multilayer perceptron. The resulting framework unifies representation learning and logical inference, enabling zero-shot generalization even when is only indirectly related to .
The fundamental limit of ZSL is characterized by the mutual information between inputs and unseen classes, conditioned on seen classes. For a fixed , the generalization error is bounded by:
where n is the number of training samples. Open-set variants further distinguish known unknowns () from truly novel inputs by thresholding the entropy of :
for a threshold . This aligns with the statistical mechanics of few-shot learning, where acts as a low-dimensional manifold encoding the thermodynamic free energy of class discrimination. Thus, ZSL bridges geometric, statistical, and symbolic AI, offering a principled approach to learning beyond observed labels.
9.1. Literature Review of Zero-Shot Learning
Zero-shot learning (ZSL) has emerged as a pivotal paradigm in machine learning, enabling models to recognize classes not seen during training by leveraging auxiliary information such as attributes, semantic embeddings, or textual descriptions. The foundational work of Lampert et al. (2009) [1382] introduced attribute-based classification, where classes are described by high-level attributes, and a probabilistic framework is used to infer unseen classes. This approach formalizes ZSL as a transfer learning problem, where knowledge from seen classes is transferred to unseen classes via a shared semantic space . The key idea is to learn a mapping from the input space to the semantic space , followed by a compatibility function that scores the alignment between embeddings and class labels. Early methods relied on linear projections, as seen in the work of Akata et al. (2013) [1383], who proposed a bilinear compatibility function , where is the semantic embedding of class y and W is a learned weight matrix.
The literature has since evolved to address critical challenges such as the semantic gap and domain shift. Romera-Paredes and Torr (2015) [1384] proposed an elegant closed-form solution using ridge regression to learn the projection matrix W, minimizing , where X and S are matrices of seen class instances and their attributes, respectively. However, this approach assumes a linear relationship, which is often insufficient. Nonlinear extensions, such as deep neural networks, were introduced by Xian et al. (2017) [1386], who employed a multimodal embedding space to align visual and semantic representations. Their objective function incorporates a margin-based ranking loss to ensure correct class rankings. Concurrently, Zhang et al. (2017) [1387] proposed a generative adversarial network (GAN) framework to synthesize features for unseen classes, formalized as , where G generates fake features conditioned on class embeddings.
The domain shift problem, where the projected features of unseen classes deviate from their true distribution, was addressed by Fu et al. (2015) [1388] through transductive learning, leveraging unlabeled unseen class data during training. Their formulation minimizes , where is the supervised loss on seen classes and regularizes the projection using unseen class instances. Similarly, Kodirov et al. (2017) [1389] proposed a self-training framework with , enforcing sparsity to improve generalization. Another line of work focuses on hybrid models, as in the case of Changpinyo et al. (2016) [1390], who combined attribute-based and semantic embedding methods using a joint optimization framework , where A is a matrix mapping attributes to embeddings.
Recent advances have explored graph-based methods to model relationships between classes. Kampffmeyer et al. (2019) [1391] proposed a graph convolutional network (GCN) to propagate information across classes, with the loss , where is the adjacency matrix encoding class relationships. Similarly, Wang et al. (2018) [1392] introduced a knowledge graph framework to enrich semantic representations, while Li et al. (2019) [1393] leveraged hierarchical class structures to improve ZSL performance. The emergence of large-scale pretrained vision-language models like CLIP (Radford et al., 2021) [1394] has further revolutionized ZSL, enabling zero-shot transfer via natural language prompts. Their contrastive learning objective aligns images and text embeddings in a shared space, achieving state-of-the-art results.
Despite these advancements, challenges remain, such as bias towards seen classes and the need for robust evaluation protocols. Chao et al. (2016) [1395] highlighted the importance of generalized ZSL (GZSL), where the test set includes both seen and unseen classes, and proposed the harmonic mean to balance performance. Verma et al. (2018) [1396] addressed bias mitigation through calibrated stacking, while Huynh and Elhamifar (2020) [1397] proposed a compositional framework for fine-grained ZSL. Theoretical insights from Palatucci et al. (2009) [1398] and Socher et al. (2013) [1399] have also shaped the field, emphasizing the role of semantic spaces in knowledge transfer. The integration of meta-learning (Hariharan and Girshick, 2017) [1400] and few-shot learning (Xian et al., 2018) [1401] has further expanded ZSL’s applicability, while emerging paradigms like open-set recognition (Scheirer et al., 2013) [1402] and out-of-distribution detection (Yang et al., 2021) [1403] continue to push its boundaries.
9.2. Analysis of Zero-Shot Learning
Zero-Shot learning (ZSL) is a highly sophisticated paradigm in machine learning wherein a model is expected to classify instances from classes it has never encountered during training. Mathematically, we define a set of seen classes S and unseen classes U, such that the training set consists of labeled instances where , and the test set consists of instances where , with . The challenge of ZSL lies in leveraging semantic knowledge to generalize beyond the training distribution, necessitating a mapping function that extends to unseen categories.
The problem can be formulated using an attribute-based representation, where each class y is associated with a high-dimensional semantic embedding , which encodes meaningful relationships between classes. The objective is to learn a function that maps input samples to the same semantic space. Given a new sample , the predicted class is determined by minimizing a distance function d:
A common choice for d is the squared Euclidean distance:
or the cosine similarity:
The function g is often parameterized by a neural network with parameters , trained via minimizing a contrastive loss:
or a cross-entropy loss in a transformed space:
where is a similarity measure, often a bilinear transformation:
for some learned weight matrix W. Generalization to unseen classes depends on the structure of the semantic space, typically constructed using linguistic embeddings (e.g., Word2Vec, GloVe) or manually defined attribute vectors. The effectiveness of ZSL hinges on the assumption that semantic relationships transfer across classes, which can be formalized through a probabilistic model:
where is modeled via a generative process:
with z representing latent features shared across seen and unseen classes. Variational inference is commonly employed to approximate this integral, leading to an evidence lower bound (ELBO):
where is an inference network. Zero-shot learning can also be formulated through a linear mapping W such that:
where is a feature extractor (e.g., a deep CNN), and W aligns it with the semantic space. This leads to a ridge regression formulation:
solvable via the closed-form solution:
where A is the matrix of attribute vectors and F is the matrix of extracted features. The zero-shot classification task then reduces to:
which assigns the test instance to the nearest class in the semantic space. Generalized zero-shot learning (GZSL) extends this by allowing both seen and unseen classes at test time, requiring a calibrated compatibility function:
where controls the bias toward seen classes. The choice of semantic space and feature extractor significantly affects performance, as different embedding choices induce different generalization behaviors. Alternative formulations include energy-based models:
trained via hinge loss:
or meta-learning approaches that define a task-specific adaptation function:
to optimize generalization. These diverse formulations illustrate the intricate mathematical foundation of zero-shot learning, where the interplay between feature extraction, semantic embedding, and transfer mechanisms defines the success of the model in recognizing previously unseen categories.
9.3. Energy-based models for Zero-Shot Learning
Energy-based models (EBMs) for zero-shot learning (ZSL) provide a mathematically rigorous framework for learning representations that generalize beyond seen categories by modeling the compatibility between data samples and their semantic attributes. The core principle of EBMs in ZSL is the minimization of an energy function , which defines a measure of compatibility between an input sample x and a class label y. This function is designed such that correct pairings of have lower energy values compared to incorrect pairings. The probability of assigning x to class y is given by the Boltzmann distribution:
where the denominator represents the partition function, ensuring normalization across all possible class labels. This formulation enforces a probabilistic interpretation of the energy function, ensuring that samples are more likely assigned to classes with lower energy. In zero-shot learning, the fundamental challenge is to extend knowledge to unseen classes using auxiliary information, often in the form of semantic embeddings , which encode prior knowledge about each class y. The energy function is typically parameterized as a compatibility function between the input x and the semantic representation , formulated as
where is a feature extractor mapping x into a latent space, and W is a learnable weight matrix. The objective function is constructed to minimize the energy for correct class-attribute associations while maximizing it for incorrect ones. A contrastive loss is often used to enforce this property:
which penalizes incorrect associations by ensuring the energy of the correct class y is lower than all incorrect alternatives . To enhance generalization, additional regularization terms are often introduced. A common approach is the margin-based loss:
where is a margin enforcing separation between correct and incorrect classes. This formulation ensures robustness against overfitting to seen classes and enables transfer to unseen classes. To improve stability, energy-based models often employ gradient-based optimization strategies, leveraging backpropagation to refine W, , and other parameters. The gradients are computed as
where the expectation over incorrect classes ensures optimization is guided towards reducing energy for true class-attribute associations. A crucial aspect of EBMs in ZSL is the use of generative constraints, where the model is regularized using a reconstruction loss to ensure feature consistency across seen and unseen categories. A common approach involves a variational autoencoder (VAE)-based loss:
where is an approximate posterior, and is a prior distribution. This enforces meaningful latent representations for generalization to unseen classes. To further refine the learned embeddings, contrastive self-supervised techniques can be integrated. The contrastive learning loss is defined as
where is a temperature parameter and is a positive sample pair distribution. This regularization aligns semantically similar instances, ensuring the energy function learns robust and transferable representations. The inference stage in zero-shot learning using EBMs involves solving an optimization problem to assign a query sample x to the class y that minimizes the energy function:
where is evaluated for both seen and unseen classes. Since the energy function is trained using both contrastive and probabilistic constraints, it generalizes effectively to novel categories. In summary, EBMs for ZSL leverage compatibility functions, contrastive constraints, and probabilistic formulations to ensure robust zero-shot generalization. The interplay between energy minimization, semantic embeddings, and self-supervised learning techniques provides a mathematically rigorous approach for knowledge transfer across seen and unseen categories.
9.3.1. Various Loss function Used in Energy-Based Models for Zero-Shot Learning
Contrastive loss in Energy-based Models (EBMs) for Zero-Shot Learning (ZSL) is designed to ensure that embeddings of similar instances are brought closer together, while embeddings of dissimilar instances are pushed apart. Given a set of input-label pairs , the energy function is minimized for correct pairs and maximized for incorrect ones. The contrastive loss function can be formulated as
where represents the true label, represents a negative label, is an indicator function, and m is a margin parameter ensuring sufficient separation between positive and negative pairs. The energy function is typically parameterized using neural networks and optimized via stochastic gradient descent. The gradient updates follow
Margin-based loss extends the contrastive loss by enforcing a stricter separation criterion between positive and negative pairs. The loss function is
where ensures non-negative loss contributions. This formulation encourages to be strictly lower than by at least margin m. The gradient computation follows
Variational Autoencoder (VAE)-based loss introduces probabilistic modeling into EBMs for ZSL by defining a latent variable z that captures the underlying structure of the data. The energy function is parameterized as
The VAE-based loss is the negative Evidence Lower Bound (ELBO), given by
where is the approximate posterior, is the prior, and denotes the Kullback-Leibler divergence. The gradient updates for training involve
Contrastive learning loss in EBMs for ZSL builds upon the contrastive framework by explicitly constructing positive and negative pairs in an embedding space where similarity is measured. A common formulation is the InfoNCE loss
This formulation ensures that the energy of the correct label is minimized while normalizing across all possible labels. The corresponding gradient updates are
where is the probability of a label under the energy model. Each of these loss functions plays a crucial role in shaping the energy landscape for Zero-Shot Learning, ensuring effective generalization to unseen classes.
9.3.2. Generative Constraints in Energy-Based Models for Zero-Shot Learning
Generative constraints in energy-based models (EBMs) for zero-shot learning (ZSL) fundamentally stem from the principle of defining an energy landscape that enforces semantic compatibility between seen and unseen classes while maintaining representational fidelity to underlying data distributions. Given a dataset , where represents input features and belongs to the set of seen classes, the primary objective is to infer meaningful representations for an unseen class set , such that . The generative constraints in EBMs introduce an energy function , parameterized by , that assigns low energy to compatible pairs and high energy to incompatible ones, ensuring that the generative structure generalizes across class distributions.
where is the feature extractor mapping inputs to an embedding space, and is the semantic mapping function capturing class-level knowledge. Zero-shot generalization is imposed via a generative constraint that enforces energy-based regularization between seen and unseen class distributions, expressed as
where and are the joint distributions over seen and unseen data, respectively. This constraint ensures that the energy landscape maintains generalizability by aligning unseen class embeddings with seen class statistics. The generative constraints can be explicitly incorporated via an adversarial loss term that minimizes the Kullback-Leibler (KL) divergence between seen and unseen class distributions in the latent space:
where represents the latent feature encoding. Since direct estimation of is intractable, it is typically approximated using a generative model , leading to the variational formulation:
This enforces a shared latent space between seen and unseen distributions, facilitating knowledge transfer in a generative manner. A key generative constraint in EBMs is the entropy-based regularization, which ensures that the energy landscape does not collapse into degenerate solutions. The entropy of the conditional distribution is maximized via
which prevents the model from overfitting to seen classes by enforcing a smooth energy manifold. This is further complemented by a contrastive loss enforcing inter-class separability:
Together, these constraints regularize the energy function such that the generative structure captures semantic transferability between seen and unseen categories. Another fundamental generative constraint involves aligning class prototypes with their corresponding semantic representations through a structural loss
This ensures that the learned embeddings remain consistent with high-level class descriptions, enabling robust generalization to unseen categories. A further refinement of the generative constraint is the incorporation of a marginal energy regularization term, enforcing stability across variations in input perturbations:
where denotes a local perturbation neighborhood of x. This encourages energy invariance within class-consistent transformations, further reinforcing generalization properties. Finally, the overall training objective for EBMs in zero-shot learning integrates the aforementioned generative constraints into a single optimization problem:
where and are hyperparameters balancing the contributions of different generative constraints. This structured formulation ensures that the learned energy function captures meaningful relationships across both seen and unseen classes, enabling zero-shot generalization through robust energy-based generative modeling.
9.3.3. Use of Inference in Energy-Based Models for Zero-Shot Learning
Energy-based models (EBMs) provide a principled framework for zero-shot learning (ZSL) by defining a scalar energy function that assigns compatibility scores to input data samples x and output labels y. The core idea of inference in energy-based models for zero-shot learning is to leverage a structured energy landscape that captures semantic relationships between seen and unseen classes. This enables generalization to novel classes without requiring explicit training examples for them. The inference process is governed by the minimization of energy functions that encode both data likelihood and constraints imposed by semantic knowledge transfer mechanisms.
Mathematically, given a dataset consisting of training examples with inputs and their corresponding class labels , the goal of zero-shot inference is to predict labels for new inputs. The energy function is typically defined as
where is a learnable compatibility function parameterized by . Inference in EBMs for ZSL is performed by solving the minimization problem
The energy function is often decomposed into different terms capturing multiple constraints, such as semantic consistency, visual-semantic alignment, and regularization. A common formulation incorporates a bilinear compatibility function between input feature representations and class embeddings :
where W is a learnable weight matrix encoding the mapping between the visual and semantic spaces. The inference process then reduces to
Energy minimization for inference can also be formulated as a probabilistic model using the Boltzmann distribution:
Inference corresponds to maximum a posteriori (MAP) estimation:
One approach to improve inference performance in ZSL is to introduce additional constraints through a margin-based ranking loss:
where is a margin parameter ensuring that the correct label has a lower energy than incorrect ones. In scenarios where inference involves generative modeling, energy-based models can be coupled with contrastive divergence training. The gradient of the energy function with respect to the input features provides a principled way to update representations:
By leveraging learned semantic embeddings, energy minimization enables inference even in the absence of explicit training data for unseen categories. The effectiveness of energy-based models for zero-shot learning thus fundamentally relies on the quality of the learned energy landscape, ensuring smooth generalization from seen to unseen classes through structured energy minimization.
9.4. Meta-Learning Approaches for Zero-Shot Learning
Meta-learning approaches for zero-shot learning (ZSL) are fundamentally based on the principle of learning to learn, where a model is trained on a set of tasks such that it can generalize to novel tasks it has never encountered before. The primary challenge in zero-shot learning lies in the fact that during inference, the model must classify data samples from categories that were not seen during training. Meta-learning addresses this challenge by acquiring transferable knowledge that allows for rapid adaptation to new categories using minimal additional information. Let denote the input space and the label space. Given a training set , where and , the objective in zero-shot learning is to classify a test sample into one of the unseen categories , such that .
Meta-learning operates by optimizing a function parameterized by such that it minimizes an expected loss over a distribution of tasks. Each task is drawn from a distribution , where a task consists of a small support set and a query set . The meta-objective is to minimize the expected loss over all tasks:
A common meta-learning paradigm is the Model-Agnostic Meta-Learning (MAML) approach, which seeks to find an initial set of parameters such that fine-tuning on a new task requires minimal adaptation. Given a task with support set , MAML updates using one or more gradient descent steps:
where is the learning rate. The meta-update then optimizes by minimizing the loss over query samples after adaptation:
where is the meta-learning rate. Another approach is the meta-embedding strategy, where feature representations are learned to generalize across tasks. Let denote an embedding function mapping inputs to a latent space . The objective is to learn an embedding that maintains a consistent similarity structure across both seen and unseen categories. The compatibility function is often modeled as a bilinear compatibility function:
where is a semantic embedding of label y, and W is a learned transformation matrix. The model is trained to maximize the compatibility of correct pairs while minimizing that of incorrect pairs, often using a ranking loss:
where is a margin hyperparameter. Prototypical networks leverage metric-based meta-learning to learn a space where samples from the same class cluster together. Given a support set , the prototype for class c is computed as the mean embedding of its examples:
A query sample is classified by computing a distance metric, commonly the squared Euclidean distance:
Graph-based meta-learning frameworks construct a graph where nodes represent categories, and edges encode semantic or structural relationships. Given a graph convolutional network (GCN) with adjacency matrix A and feature matrix X, the node embeddings are computed iteratively as:
where are layer-specific learnable parameters and is a non-linearity. The final node embeddings serve as classifiers for unseen categories. Bayesian meta-learning introduces uncertainty quantification by modeling the parameters as distributions rather than point estimates. Let be a prior distribution over parameters. The posterior is computed using Bayes’ rule:
Inference is performed by marginalizing over the posterior:
Approximate inference methods such as variational Bayes or Monte Carlo sampling are used to estimate the integral. Each of these approaches forms the foundation of meta-learning in zero-shot learning, providing a mechanism to generalize across unseen categories using transferable knowledge.
9.4.1. Model-Agnostic Meta-Learning (MAML)
Model-Agnostic Meta-Learning (MAML) is a meta-learning algorithm designed to enable fast adaptation of a model to new tasks with minimal training data. The core idea behind MAML is to learn an initial set of parameters that serve as a good starting point for fine-tuning on new tasks using only a few gradient steps. This is particularly useful for zero-shot learning, where a model must generalize to unseen tasks without explicit training on them. Given a distribution over tasks , each task consists of a dataset . The goal is to find an initialization that minimizes the expected loss across all tasks after adaptation. Formally, the optimization problem can be written as
where represents the model parameters after adaptation on task . In the standard supervised learning setting, given a task-specific loss function , the adaptation process involves performing one or more gradient descent steps with respect to this loss function. The adapted parameters for task after one step of gradient descent are
where is the learning rate. The meta-objective is then formulated as
which involves optimizing the initial parameters to ensure that the adapted parameters yield low loss across tasks. This optimization is performed using gradient descent, leading to a second-order gradient update of the form
where is the meta-learning rate. The second-order term in this update makes MAML computationally expensive, but it allows for more expressive updates. In zero-shot learning, where the model must generalize to tasks without direct exposure to them during meta-training, the effectiveness of MAML is attributed to its ability to produce an initialization that is inherently generalizable. Specifically, if the task distribution is designed such that the training tasks span a diverse range of possible learning scenarios, then the learned initialization can generalize to unseen tasks by leveraging a smooth loss landscape across task variations. Mathematically, this can be expressed as minimizing the expected task-generalization error
where represents the distribution over unseen tasks. To approximate this expectation, a common strategy is to incorporate a regularization term that promotes smooth adaptation across task variations, yielding the regularized meta-objective
where is a regularization function that penalizes large gradients or promotes parameter smoothness, and controls the strength of this regularization. The zero-shot capability of MAML can be further improved by explicitly optimizing for robustness in the presence of distribution shifts. This can be achieved by modifying the meta-objective to incorporate an adversarial worst-case term
where represents an adversarially chosen distribution over test tasks. This leads to a minimax optimization problem, ensuring that the learned initialization is robust to extreme variations in task distributions. Additionally, when applied to function approximation problems such as few-shot regression or reinforcement learning, MAML can be interpreted as an implicit form of hierarchical Bayesian inference. In this interpretation, the meta-learned parameters serve as a prior, and task-specific fine-tuning corresponds to a Bayesian posterior update. This perspective connects MAML with variational inference methods, where the meta-learning process can be rewritten as optimizing the evidence lower bound (ELBO)
where represents the posterior distribution over task-specific parameters and is the learned meta-prior. The KL-divergence term enforces consistency between the meta-learned initialization and the task-specific updates.
9.4.2. Meta-Embedding Strategy
The meta-embedding strategy for zero-shot learning (ZSL) fundamentally relies on constructing an optimal embedding space where the semantic representations of seen and unseen classes align with feature representations derived from visual or textual modalities. Mathematically, given a set of seen class-label pairs , where represents the feature vector extracted from an image (e.g., using a deep convolutional neural network), and is the corresponding class label, the objective is to learn a function that maps feature representations to a semantic space where class relationships are preserved. The challenge is to generalize this function to a set of unseen class labels , such that for an unseen sample , its embedding aligns closely with the corresponding semantic representation of its true class label.
To achieve this, a semantic embedding space is constructed, where each class c (both seen and unseen) is represented by a prototype vector . The embeddings are often derived from textual descriptions (e.g., word vectors, attribute annotations) and must be aligned with the visual space. This alignment is achieved by learning a compatibility function that quantifies the compatibility between an input feature vector x and a class prototype . One common choice for is a bilinear compatibility function:
where is a learnable transformation matrix. The objective function for training is then given by a ranking loss that enforces the correct pair to have a higher compatibility score than incorrect class pairs:
where is a margin parameter ensuring separation between correct and incorrect matches. To enable generalization to unseen classes, meta-embedding strategies are introduced, where a meta-learned function constructs a class prototype dynamically:
where is a raw class descriptor (e.g., word embeddings, attribute vectors) and is a neural network that transforms into a semantically meaningful embedding. The training objective extends to minimizing the discrepancy between predicted and actual prototypes:
so that for unseen classes, provides a meaningful representation. This ensures that when an unseen instance is projected into the space, the classification decision:
is based on learned semantic relationships rather than direct supervision. Additionally, variational methods can be employed to refine embeddings by incorporating uncertainty estimation via a probabilistic latent space:
where and are the mean and covariance functions modeled via neural networks. The overall loss function then includes a Kullback-Leibler (KL) divergence term to regularize the learned distributions:
where is a regularization parameter. By integrating these techniques, meta-embedding strategies provide a robust and scalable approach for zero-shot learning, ensuring that unseen class representations align meaningfully with visual features.
9.4.3. Metric-Based Meta-Learning
Metric-based meta-learning for Zero-Shot Learning (ZSL) is fundamentally rooted in the concept of learning a function that embeds data points into a space where semantic similarities are preserved, facilitating knowledge transfer from seen to unseen classes. Let denote the input space, the label space, and be the training set, where , the set of seen class labels. The goal is to learn a function that maps input instances into an embedding space where classification is performed based on distances to class prototypes, enabling generalization to an unseen class set without direct training data.
The embedding function is parameterized as a deep neural network that learns a transformation from the raw input space to a metric space with a well-defined distance function . One commonly employed distance function is the squared Euclidean distance:
where and . Alternatively, cosine similarity is often used for improved generalization:
A central component of metric-based meta-learning is the construction of prototypes for each class, which serve as the representative embeddings for classification. The prototype of a class y is computed as the mean embedding of all support examples belonging to that class:
where is the set of all training instances labeled as y. Given a query instance , its class assignment is determined by computing the distance to all class prototypes and selecting the closest one:
In the meta-learning paradigm, training occurs episodically, where each episode simulates a ZSL scenario with a small support set and a query set . The meta-objective minimizes the classification loss over the query set using a nearest-prototype strategy:
where ℓ is typically the cross-entropy loss:
To enable zero-shot generalization, semantic descriptions of unseen classes, represented as attribute vectors , guide prototype construction. Instead of computing class prototypes directly from samples, they are inferred via a mapping function that aligns semantic and visual spaces:
where is a learnable transformation matrix. The classification decision for an unseen query sample then follows:
Training involves optimizing f and W jointly using episodic meta-learning, ensuring that f learns to generalize from seen to unseen classes by aligning feature embeddings with semantic representations. The meta-learning update follows:
where denotes the parameters of the embedding function f, is the learning rate, and gradients are computed over multiple episodes. The effectiveness of metric-based meta-learning in ZSL is enhanced by incorporating contrastive loss:
where is 1 if and belong to the same class, 0 otherwise, and is a margin parameter. This loss encourages similar instances to be closer while pushing dissimilar ones apart. Zero-shot generalization relies on the alignment between the semantic space and the learned metric space. Regularization techniques such as distribution calibration adjust the prototype computation by leveraging seen class distributions:
where is a set of semantically similar seen classes to y, and controls the balance between semantic projection and distribution calibration. By iteratively refining the metric space and semantic alignment, metric-based meta-learning enables effective zero-shot classification, where new classes are recognized based on learned semantic-visual correspondences without requiring additional samples. The integration of episodic training, prototype-based classification, contrastive learning, and semantic projection ensures that the learned model generalizes robustly to unseen categories.
9.4.4. Graph-Based Meta-Learning
Graph-based meta-learning for zero-shot learning (ZSL) fundamentally relies on constructing a graph representation of semantic relationships between classes and leveraging meta-learning techniques to transfer knowledge from seen classes to unseen ones. Given a set of training classes and a set of unseen classes with , the core idea is to embed both visual and semantic information into a structured graph , where nodes V represent class prototypes and edges E encode relationships among them. The objective is to learn a function that can generalize to despite lacking direct visual training examples.
Let each class be represented by a feature vector , typically derived from word embeddings such as Word2Vec or GloVe. The task is to learn a classifier , where is the probability of an input sample belonging to class c. The underlying principle of the graph-based approach is to propagate information across the graph structure using message passing frameworks such as Graph Neural Networks (GNNs). The node feature update at layer t is given by
where is the feature representation of class c at layer t, denotes the neighboring classes, is an edge weight encoding semantic similarity between class c and , and is a nonlinear activation function such as ReLU. The parameters and are learned via backpropagation. To transfer knowledge, meta-learning is employed by training the model on a sequence of meta-tasks , where is the support set and is the query set. The meta-learning objective is to minimize the expected loss across tasks:
where is the classifier parameterized by and is the classification loss. The classifier is optimized via an episodic training strategy, which mimics the zero-shot setting by holding out certain classes during training. Specifically, we define a parameterized distance metric for classification, such as cosine similarity
or a Mahalanobis distance
where is a learned covariance matrix capturing intra-class variations. The final classification decision is made via a softmax layer
To improve generalization to unseen classes, the model incorporates a regularization term based on the graph Laplacian , where is the degree matrix and is the adjacency matrix of the class graph. The regularization enforces smoothness in feature representations across the graph
Thus, the final objective function combines classification loss and regularization
where is a trade-off parameter. To refine embeddings, contrastive learning can be employed by defining a contrastive loss
where are semantically similar class pairs. The model is trained using stochastic gradient descent with updates
where is the learning rate. The learned class representations are then used to classify unseen class samples by assigning them to the nearest prototype
By leveraging the structured class graph, propagating knowledge through message passing, and optimizing via meta-learning, this approach enables robust zero-shot classification even when visual samples from unseen classes are unavailable.
9.4.5. Bayesian Meta-Learning
Bayesian meta-learning for zero-shot learning (ZSL) is fundamentally rooted in the probabilistic inference framework, where the goal is to infer the posterior distribution over tasks given a set of prior experiences. Let denote a set of tasks, where each task consists of a dataset , with being the input feature and the corresponding label. The fundamental Bayesian formulation models the posterior over a hypothesis h, which is parametrized by a latent variable , as
In Bayesian meta-learning, we assume that the task distribution follows a hierarchical generative model. Given a hyperprior distribution , the task-specific parameters are sampled conditionally on as
where are the task-specific parameters for . The likelihood of observing dataset given is then
For meta-learning, we define a posterior distribution over conditioned on all observed tasks:
where
For zero-shot learning, where a new task with dataset is encountered without labeled examples, the goal is to infer the posterior predictive distribution
A variational Bayesian approach approximates using a variational distribution , typically assumed to be Gaussian:
The variational objective is to minimize the KL divergence
which expands to the evidence lower bound (ELBO)
For amortized inference, we introduce an encoder , parameterized as a neural network, such that
During inference, for a new task , the posterior predictive distribution is given by marginalizing out :
Using Monte Carlo approximation, the integral can be estimated as
where . The function is modeled using a deep neural network , which outputs a probability distribution over classes. For zero-shot learning, the classifier must generalize to unseen classes by leveraging the inferred latent structure. This is achieved by incorporating semantic embeddings that define a probability distribution over labels:
This formulation enables the model to predict classes that were never observed in the training set by mapping the latent variable to a space shared across seen and unseen classes. The final optimization objective for meta-learning is
Through this Bayesian hierarchical approach, zero-shot learning emerges as a byproduct of inferring a shared structure across tasks, allowing for principled generalization to unseen distributions.
10. Neural Network Basics
Neural networks are parameterized function approximators that map input data to outputs through a composition of nonlinear transformations. At their core, they consist of layers of neurons, where each layer l applies an affine transformation followed by an elementwise activation function . For a network with L layers, the forward pass is recursively defined as:
with the final output . Here, and are the weight matrix and bias vector for layer l, and denotes the number of neurons in that layer. The activation functions (e.g., ReLU, sigmoid, or tanh) introduce nonlinearity, enabling the network to approximate complex functions. The universal approximation theorem states that for any continuous function and , there exists a single-hidden-layer network with sufficient width such that:
The parameters are learned by minimizing a loss function (e.g., cross-entropy for classification or mean squared error for regression) over a dataset . This is achieved via gradient descent, which updates the parameters iteratively as:
is the derivative of the activation function, and is propagated backward from layer . The learning process can be interpreted as a dynamical system in parameter space, where the trajectory follows the gradient flow:
Different neural architectures impose specific inductive biases through their structure. Convolutional neural networks (CNNs) leverage weight sharing and local connectivity for spatial invariance, where each layer applies a convolution operation:
with being the convolutional kernel of size . Recurrent neural networks (RNNs) process sequential data by maintaining a hidden state at each timestep:
capturing temporal dependencies. Self-attention mechanisms, as in transformers, compute dynamic feature interactions via scaled dot-products:
where are learned linear projections of the input. These architectures exemplify how neural networks encode domain-specific priors through their compositional structure and parameterization.
The expressivity of a neural network is governed by its depth L and width . For a ReLU network, the number of linear regions in its input-output mapping grows exponentially with depth, enabling piecewise linear approximations of high-dimensional functions. The loss landscape is non-convex, yet in overparameterized regimes (where the number of parameters exceeds the number of training samples), gradient descent often converges to global minima despite the presence of saddle points. This is partially explained by the neural tangent kernel (NTK) theory, which shows that in the infinite-width limit, the kernel matrix remains constant during training:
and the dynamics simplify to linearized gradient flow. The interplay between architecture, initialization, and optimization defines the practical success of neural networks in approximating intricate data distributions.
10.1. Literature Review of Neural Network Basics
Goodfellow et. al. (2016) [120] wrote one of the most comprehensive books on deep learning, covering the theoretical foundations of neural networks, optimization techniques, and probabilistic models. It is widely used in academic courses and research. Haykin (2009) [122] explained neural networks from a signal processing perspective, covering perceptrons, backpropagation, and recurrent networks with a strong mathematical approach. Schmidhuber (2015) [123] gave a historical and theoretical review of deep learning architectures, including recurrent neural networks (RNNs), convolutional neural networks (CNNs), and long short-term memory (LSTM). Bishop (2006) [124] gave a Bayesian perspective on neural networks and probabilistic graphical models, emphasizing the statistical underpinnings of learning. Poggio and Smale (2003) [125] established theoretical connections between neural networks, kernel methods, and function approximation. LeCun (2015) [126] discusses the principles behind modern deep learning, including backpropagation, unsupervised learning, and hierarchical feature extraction. Cybenko (1989) [60] proved the universal approximation theorem, demonstrating that a neural network with a single hidden layer can approximate any continuous function. Hornik et. al. (1989) [58] extended Cybenko’s theorem, proving that multilayer perceptrons (MLPs) are universal function approximators. Pinkus (1999) [62] gave a rigorous mathematical discussion on neural networks from the perspective of approximation theory. Tishby and Zaslavsky (2015) [127] introduced the information bottleneck framework for understanding deep neural networks, explaining how networks learn to compress and encode information efficiently.
10.2. Perceptrons and Artificial Neurons
The perceptron is the simplest form of an artificial neural network, operating as a binary classifier. It computes the linear combination z of the input features and a corresponding weight vector , augmented by a bias term . This can be expressed as
To determine the output, this value is passed through the step activation function, defined mathematically as
Thus, the perceptron’s decision-making process can be expressed as
where . The equation defines a hyperplane in , which acts as the decision boundary. For any input , the classification is determined by the sign of , specifically if and otherwise. Geometrically, this classification corresponds to partitioning the input space into two distinct half-spaces. To train the perceptron, a supervised learning algorithm adjusts the weights and the bias b iteratively using labeled training data , where represents the ground truth. When the predicted output differs from , the weight vector and bias are updated according to the rule
and
where is the learning rate. Each individual weight is updated as
For a linearly separable dataset, the Perceptron Convergence Theorem asserts that the algorithm will converge to a solution after a finite number of updates. Specifically, the number of updates is bounded by
where is the maximum norm of the input vectors, and is the minimum margin, defined as
The limitations of the perceptron, particularly its inability to solve linearly inseparable problems such as the XOR problem, necessitate the extension to artificial neurons with non-linear activation functions. A popular choice is the sigmoid activation function
which maps to the continuous interval . The derivative of the sigmoid function, essential for gradient-based optimization, is
Another widely used activation function is the hyperbolic tangent , defined as
with derivative
ReLU, or Rectified Linear Unit, is defined as
with derivative
These non-linear activations enable the network to approximate non-linear decision boundaries, a capability absent in the perceptron. Artificial neurons form the building blocks of multi-layer perceptrons (MLPs), where neurons are organized into layers. For an L-layer network, the input is transformed layer by layer. At layer l, the output is
where is the weight matrix, is the bias vector, and is the activation function. The network’s output is
The Universal Approximation Theorem guarantees that MLPs with sufficient neurons and non-linear activations can approximate any continuous function to arbitrary precision. Formally, for any , there exists an MLP such that
for all . Training an MLP minimizes a loss function L that quantifies the error between predicted outputs and ground truth labels . For regression, the mean squared error is
and for classification, the cross-entropy loss is
Optimization uses stochastic gradient descent (SGD), updating parameters as
Gradients are computed via backpropagation:
where is the error signal at layer l, recursively calculated as
This recursive structure, combined with chain rule applications, efficiently propagates error signals from the output layer back to the input layer.
Artificial neurons and their extensions have thus provided the foundation for modern deep learning. Their mathematical underpinnings and computational frameworks are instrumental in solving a wide array of problems, from classification and regression to complex decision-making. The interplay of linear algebra, calculus, and optimization theory in their formulation ensures that these networks are both theoretically robust and practically powerful.
10.3. Feedforward Neural Networks
Feedforward neural networks (FNNs) are mathematical constructs designed to approximate arbitrary mappings by composing affine transformations and nonlinear activation functions. At their core, these networks consist of L layers, where each layer k transforms its input into an output via the operation
Here, represents the weight matrix, is the bias vector, and is a component-wise activation function. Formally, if we denote the input layer as , the final output of the network, , is given by . Each transformation in this sequence can be described as , followed by the activation . The affine transformation encapsulates the linear combination of inputs with weights and the addition of biases . For any two layers k and , the overall transformation can be represented by
Expanding this, we have
Without the nonlinearity introduced by , the network reduces to a single affine transformation
where and
Thus, the incorporation of nonlinear activation functions is critical, as it enables the network to approximate non-linear mappings. Activation functions are applied element-wise to the pre-activation vector . The choice of activation significantly affects the network’s behavior and training. For example, the sigmoid activation compresses inputs into the range and has a derivative given by
The hyperbolic tangent activation maps inputs to with a derivative
The ReLU activation , commonly used in modern networks, has a derivative
These derivatives are essential for gradient-based optimization. The objective of training a feedforward neural network is to minimize a loss function , which measures the discrepancy between the predicted outputs and the true targets over a dataset . For regression problems, the mean squared error (MSE) is often used, given by
In classification tasks, the cross-entropy loss is widely employed, defined as
where represents the one-hot encoded labels. The gradient of with respect to the network parameters is computed using backpropagation, which applies the chain rule iteratively to propagate errors from the output layer to the input layer. During backpropagation, the error signal at the output layer is computed as
where ⊙ denotes the Hadamard product. For hidden layers, the error signal propagates backward as
The gradients of the loss with respect to the weights and biases are then given by
These gradients are used to update the parameters through optimization algorithms like stochastic gradient descent (SGD), where
with as the learning rate. The universal approximation theorem rigorously establishes that a feedforward neural network with at least one hidden layer and sufficiently many neurons can approximate any continuous function on a compact domain . Specifically, for any , there exists a network such that for all . This expressive capability arises because the composition of affine transformations and nonlinear activations allows the network to approximate highly complex functions by partitioning the input space into regions and assigning different functional behaviors to each.
In summary, feedforward neural networks are a powerful mathematical framework grounded in linear algebra, calculus, and optimization. Their capacity to model intricate mappings between input and output spaces has made them a cornerstone of machine learning, with rigorous mathematical principles underpinning their structure and training. The combination of affine transformations, nonlinear activations, and gradient-based optimization enables these networks to achieve unparalleled flexibility and performance in a wide range of applications.
10.4. Activation Functions
In the context of neural networks, activation functions serve as an essential component that enables the network to approximate complex, non-linear mappings. When a neural network processes input data, each neuron computes a weighted sum of the inputs and then applies an activation function to produce the output. Mathematically, let the input vector to the neuron be , and let the weight vector associated with these inputs be . The corresponding bias term is denoted as b. The net input z to the activation function is then given by:
where represents the dot product of the weight vector and the input vector. The activation function is then applied to this net input to obtain the output of the neuron a:
The activation function introduces a non-linearity into the neuron’s response, which is a crucial aspect of neural networks because, without it, the network would only be able to perform linear transformations of the input data, limiting its ability to approximate complex, real-world functions. The non-linearity introduced by is fundamental because it enables the network to capture intricate relationships between the input and output, making neural networks capable of solving problems that require hierarchical feature extraction, such as image classification, time-series forecasting, and language modeling. The importance of non-linearity is most clearly evident when considering the mathematical formulation of a multi-layer neural network. For a feed-forward neural network with L layers, the output of the network is given by the composition of successive affine transformations and activation functions. Let denote the input vector, and be the weight matrix and bias vector for the k-th layer, and be the activation function for the k-th layer. The output of the network is:
If were a linear function, say for some constant c, the composition of such functions would still result in a linear function. Specifically, if each were linear, the overall network function would simplify to a single linear transformation:
where and are constants dependent on the parameters of the network. In this case, the network would have no greater expressive power than a simple linear regression model, regardless of the number of layers. Thus, the non-linearity introduced by activation functions allows neural networks to approximate any continuous function, as guaranteed by the universal approximation theorem. This theorem states that a feed-forward neural network with at least one hidden layer and a sufficiently large number of neurons can approximate any continuous function , provided the activation function is non-linear and the network has enough capacity.
Next, consider the mathematical properties that the activation function must possess. First, it must be differentiable to allow the use of gradient-based optimization methods like backpropagation for training. Backpropagation relies on the chain rule of calculus to compute the gradients of the loss function with respect to the parameters (weights and biases) of the network. Suppose is the loss function, where is the predicted output of the network and is the true label. During training, we compute the gradient of with respect to the weights using the chain rule. Let represent the output of the activation function at layer k, where is the input to the activation function. The gradient of the loss with respect to the weights at layer k is given by:
The term is the derivative of the activation function, which must exist and be well-defined for gradient-based optimization to work effectively. If the activation function is not differentiable, the backpropagation algorithm cannot compute the gradients, preventing the training process from proceeding.
Now consider the specific forms of activation functions commonly used in practice. The sigmoid activation function is one of the most well-known, defined as:
Its derivative is:
which can be derived by applying the chain rule to the expression for . Although sigmoid is differentiable and smooth, it suffers from the vanishing gradient problem, especially for large positive or negative values of z. Specifically, as , , and similarly as , . This results in very small gradients during backpropagation, making it difficult for the network to learn when the input values become extreme. To mitigate the vanishing gradient problem, the hyperbolic tangent (tanh) function is often used as an alternative. It is defined as:
with derivative:
The tanh function outputs values in the range , which helps to center the data around zero. While the tanh function overcomes some of the vanishing gradient issues associated with the sigmoid function, it still suffers from the problem for large , where the gradients approach zero. The Rectified Linear Unit (ReLU) is another commonly used activation function. It is defined as:
with derivative:
ReLU is particularly advantageous because it is computationally efficient, as it only requires a comparison to zero. Moreover, for positive values of z, the derivative is constant and equal to 1, which helps avoid the vanishing gradient problem. However, ReLU can suffer from the dying ReLU problem, where neurons output zero for all inputs if the weights are initialized poorly or if the learning rate is too high, leading to inactive neurons that do not contribute to the learning process. To address the dying ReLU problem, the Leaky ReLU activation function is introduced, defined as:
where is a small constant, typically chosen to be . The derivative of the Leaky ReLU is:
Leaky ReLU ensures that neurons do not become entirely inactive by allowing a small, non-zero gradient for negative values of z. Finally, for classification tasks, particularly when there are multiple classes, the Softmax activation function is often used in the output layer of the neural network. The Softmax function is defined as:
where is the input to the i-th neuron in the output layer, and the denominator ensures that the outputs sum to 1, making them interpretable as probabilities. The Softmax function is typically used in multi-class classification problems, where the network must predict one class out of several possible categories.
In summary, activation functions are a vital component of neural networks, enabling them to learn intricate patterns in data, allowing for the successful application of neural networks to diverse tasks. Different activation functions—such as sigmoid, tanh, ReLU, Leaky ReLU, and Softmax—each offer distinct advantages and limitations, and their choice significantly impacts the performance and training dynamics of the neural network.
10.5. Loss Functions
In neural networks, the loss function is a crucial mathematical tool that quantifies the difference between the predicted output of the model and the true output or target. Let be the input vector and the corresponding target vector for the i-th training example. The network, parameterized by weights , generates a prediction denoted as , where represents the model’s output. The objective of training the neural network is to minimize the discrepancy between the predicted output and the true label across all training examples, effectively learning the mapping function from inputs to outputs. A typical objective function is the average loss over a dataset of N samples:
where represents the loss function that computes the error between the true output and the predicted output for each data point. To minimize this objective function, optimization algorithms such as gradient descent are used. The general update rule for the weights is given by:
where is the learning rate, and is the gradient of the loss function with respect to the weights. The gradient is computed using backpropagation, which applies the chain rule of calculus to propagate the error backward through the network, updating the parameters to minimize the loss. For this, we use the partial derivatives of the loss with respect to each layer’s weights and biases, ensuring the error is distributed appropriately across all layers.
In summary, the loss function plays a central role in guiding the optimization process in neural network training by quantifying the error between the predicted and true outputs. Different loss functions are employed depending on the nature of the problem, with MSE being common for regression and cross-entropy used for classification. Regularization techniques such as L2 and L1 regularization are incorporated to prevent overfitting and ensure better generalization. Through optimization algorithms like gradient descent, the neural network parameters are iteratively updated based on the gradients of the loss function, with the ultimate goal of minimizing the loss across all training examples.
10.5.1. Loss Functions for Regression Tasks
10.5.1.1 Mean Squared Error (MSE/L2 Loss)
For regression tasks, the Mean Squared Error (MSE) loss is frequently used. This loss function quantifies the error as the average squared difference between the predicted and true values. The MSE for a dataset of N examples is given by:
where is the network’s predicted output for the i-th input . The gradient of the MSE with respect to the network’s output is:
This gradient guides the weight update in the direction that minimizes the squared error, leading to a better fit of the model to the training data.
In neural network training, the optimization process often involves regularization techniques to prevent overfitting, especially in cases with high-dimensional data or deep networks. L2 regularization (also known as Ridge regression) is one common approach, which penalizes large weights by adding a term proportional to the squared L2 norm of the weights to the loss function. The regularized loss function becomes:
where is the regularization strength, and represents the parameters of the network. The gradient of the regularized loss with respect to the weights is:
This additional term discourages large values of the weights, reducing the complexity of the model and helping it generalize better to unseen data. Another form of regularization is L1 regularization (or Lasso regression), which promotes sparsity in the model by adding the L1 norm of the weights to the loss function. The L1 regularized loss function is:
The gradient of this regularized loss function with respect to the weights is:
where is the sign function, which returns 1 for positive values of , for negative values, and 0 for . L1 regularization encourages the model to select only a small subset of features by forcing many of the weights to exactly zero, thus simplifying the model and promoting interpretability. The optimization process for neural networks can be viewed as solving a non-convex optimization problem, given the highly non-linear activation functions and the deep architectures typically used. In this context, stochastic gradient descent (SGD) is commonly employed to perform the optimization by updating the weights based on the gradient computed from a random mini-batch of the data. The update rule for SGD can be expressed as:
where is the gradient of the loss function computed over the mini-batch, and is the learning rate. Due to the non-convexity of the objective function, SGD tends to converge to a local minimum or a saddle point, rather than the global minimum, especially in deep neural networks with many layers.
10.5.1.2 Mean Absolute Error (MAE/L1 Loss)
The Mean Absolute Error (MAE), equivalently termed L1 loss, is a fundamental statistical loss function defined as the expected value of the absolute deviation between a vector of true target values, , and a corresponding vector of predictions, , over a dataset of N independent and identically distributed (i.i.d.) observations. Its formal definition is given by the functional :
This formulation directly measures the average magnitude of errors without considering their direction, imposing a linear penalty on the residuals . This linearity stands in stark contrast to the quadratic penalty of the Mean Squared Error (MSE, or L2 loss),
a distinction that fundamentally alters the estimator produced by its minimization and its robustness properties.
From a statistical learning perspective, the process of empirical risk minimization involves finding the model parameters that minimize the expected loss. For MAE, this is:
where is the true data distribution. The solution to this optimization problem converges to an estimator of the conditional median of the target distribution,
This is proven by considering the derivative of the expected loss. For a fixed input , the point estimate a that minimizes is indeed the median. This contrasts with MSE, which targets the conditional mean, , a property that makes MAE far more robust to outliers as the median is less sensitive to extreme values in the tail of the distribution than the mean.
The analytical properties of the MAE function present specific challenges for gradient-based optimization. The absolute value function, , is Lipschitz continuous but non-differentiable at . Consequently, the gradient of the MAE loss with respect to a prediction must be expressed using the concept of a subgradient. The subdifferential at a point z is the set of all values that serve as a valid substitute for the derivative. For , the subdifferential is:
Therefore, the subgradient of the MAE loss for a single data point with respect to the prediction is:
The overall gradient of the total loss with respect to the model’s parameters is then computed via the chain rule during backpropagation. If the model output is , then:
This gradient has a constant magnitude of 1 for all misclassified samples, which ensures that no single outlier can dominate the parameter update step. However, it provides no second-order information (the Hessian is zero almost everywhere), and its discontinuous nature at the optimum can lead to oscillations and slower convergence rates compared to the smooth, quadratic basins of attraction found in MSE optimization, often necessitating the use of more sophisticated optimization techniques or a transition to a smooth analogue like the Huber loss near the minimum.
10.5.1.3 Huber Loss (Smooth Mean Absolute Error)
The Huber loss function, often termed Smooth Mean Absolute Error, is a piecewise-defined loss function employed in regression tasks to combine the beneficial properties of both the Mean Squared Error (MSE) and the Mean Absolute Error (MAE). Its primary motivation is to be robust to outliers in the data, like the MAE, while simultaneously maintaining differentiability at zero, a property of MSE that is crucial for stable optimization using gradient-based methods. The function achieves this by behaving quadratically for small errors, ensuring smoothness, and linearly for large errors, mitigating the excessive influence of outliers that is characteristic of the quadratic MSE. The transition point between these two regimes is governed by a hyperparameter, (delta), which defines the threshold at which the loss transitions from a quadratic to a linear behavior. The value of must be a positive real number, , and its specific value is often determined through hyperparameter tuning, though a common default is .
Mathematically, the Huber loss for a single prediction-error pair, where the residual is defined as , is formally expressed as:
This piecewise definition can be understood by analyzing its two distinct behavioral domains. For residuals whose absolute value is less than or equal to the threshold , the loss is exactly equal to one-half of the squared error
The factor of is included for mathematical convenience, as it cancels out the factor of 2 arising from the derivative, simplifying the gradient computation. In this region, the function is convex and exhibits a quadratic growth, which provides a strong, continuous gradient signal for small errors, promoting efficient convergence during training.
For residuals that exceed the threshold , meaning , the loss function transitions to a linear growth rate. The expression in this regime is
The linear term, , ensures that the loss increases at a constant rate for large errors, making it significantly more robust to outliers than the MSE, which would grow quadratically. The constant subtractive term, , is not an arbitrary adjustment but is a necessary component to ensure the function is continuous and smooth at the point of transition, . This term guarantees that the two pieces of the function meet at the boundary point.
The continuity and differentiability of the Huber loss function are its defining scientific features. The function is continuous at , which is verified by evaluating both expressions at that point: from the quadratic piece equals from the linear piece. Furthermore, the function is differentiable everywhere, including at the critical point . The derivative of the loss with respect to the residual is given by:
At , the derivative from the left is , and the derivative from the right is , confirming the differentiability of the function. This continuous first derivative is essential for the stable application of gradient descent optimization algorithms, as it prevents the erratic behavior that can occur with the MAE loss, whose gradient is discontinuous at zero. The Hessian of the Huber loss also exists for , where it is equal to 1, and for , where it is equal to 0. This structure makes it a useful penalty function in advanced optimization contexts like proximal methods. In practice, the total cost for a dataset is computed as the mean of the individual Huber losses over all N data points:
The selection of thus represents a trade-off; a larger value means more data points are treated quadratically (MSE-like behavior), while a smaller value means more points are treated linearly (MAE-like behavior).
10.5.1.4 Python Code to Generate Figure 65 Illustrating Mean Squared Error (MSE/L2) Loss Function
Figure 65.
Mean Squared Error (MSE/L2) Loss Function
The Python code below produces the Figure 65 illustrating Mean Squared Error (MSE/L2) Loss Function.
10.5.1.5 Python Code to Generate Figure 66 Illustrating Mean Absolute Error (MAE/L1) Loss Function
The Python code below produces the Figure 66 illustrating Mean Absolute Error (MAE/L1) Loss Function.
Figure 66.
Mean Absolute Error (MAE/L1) Loss Function
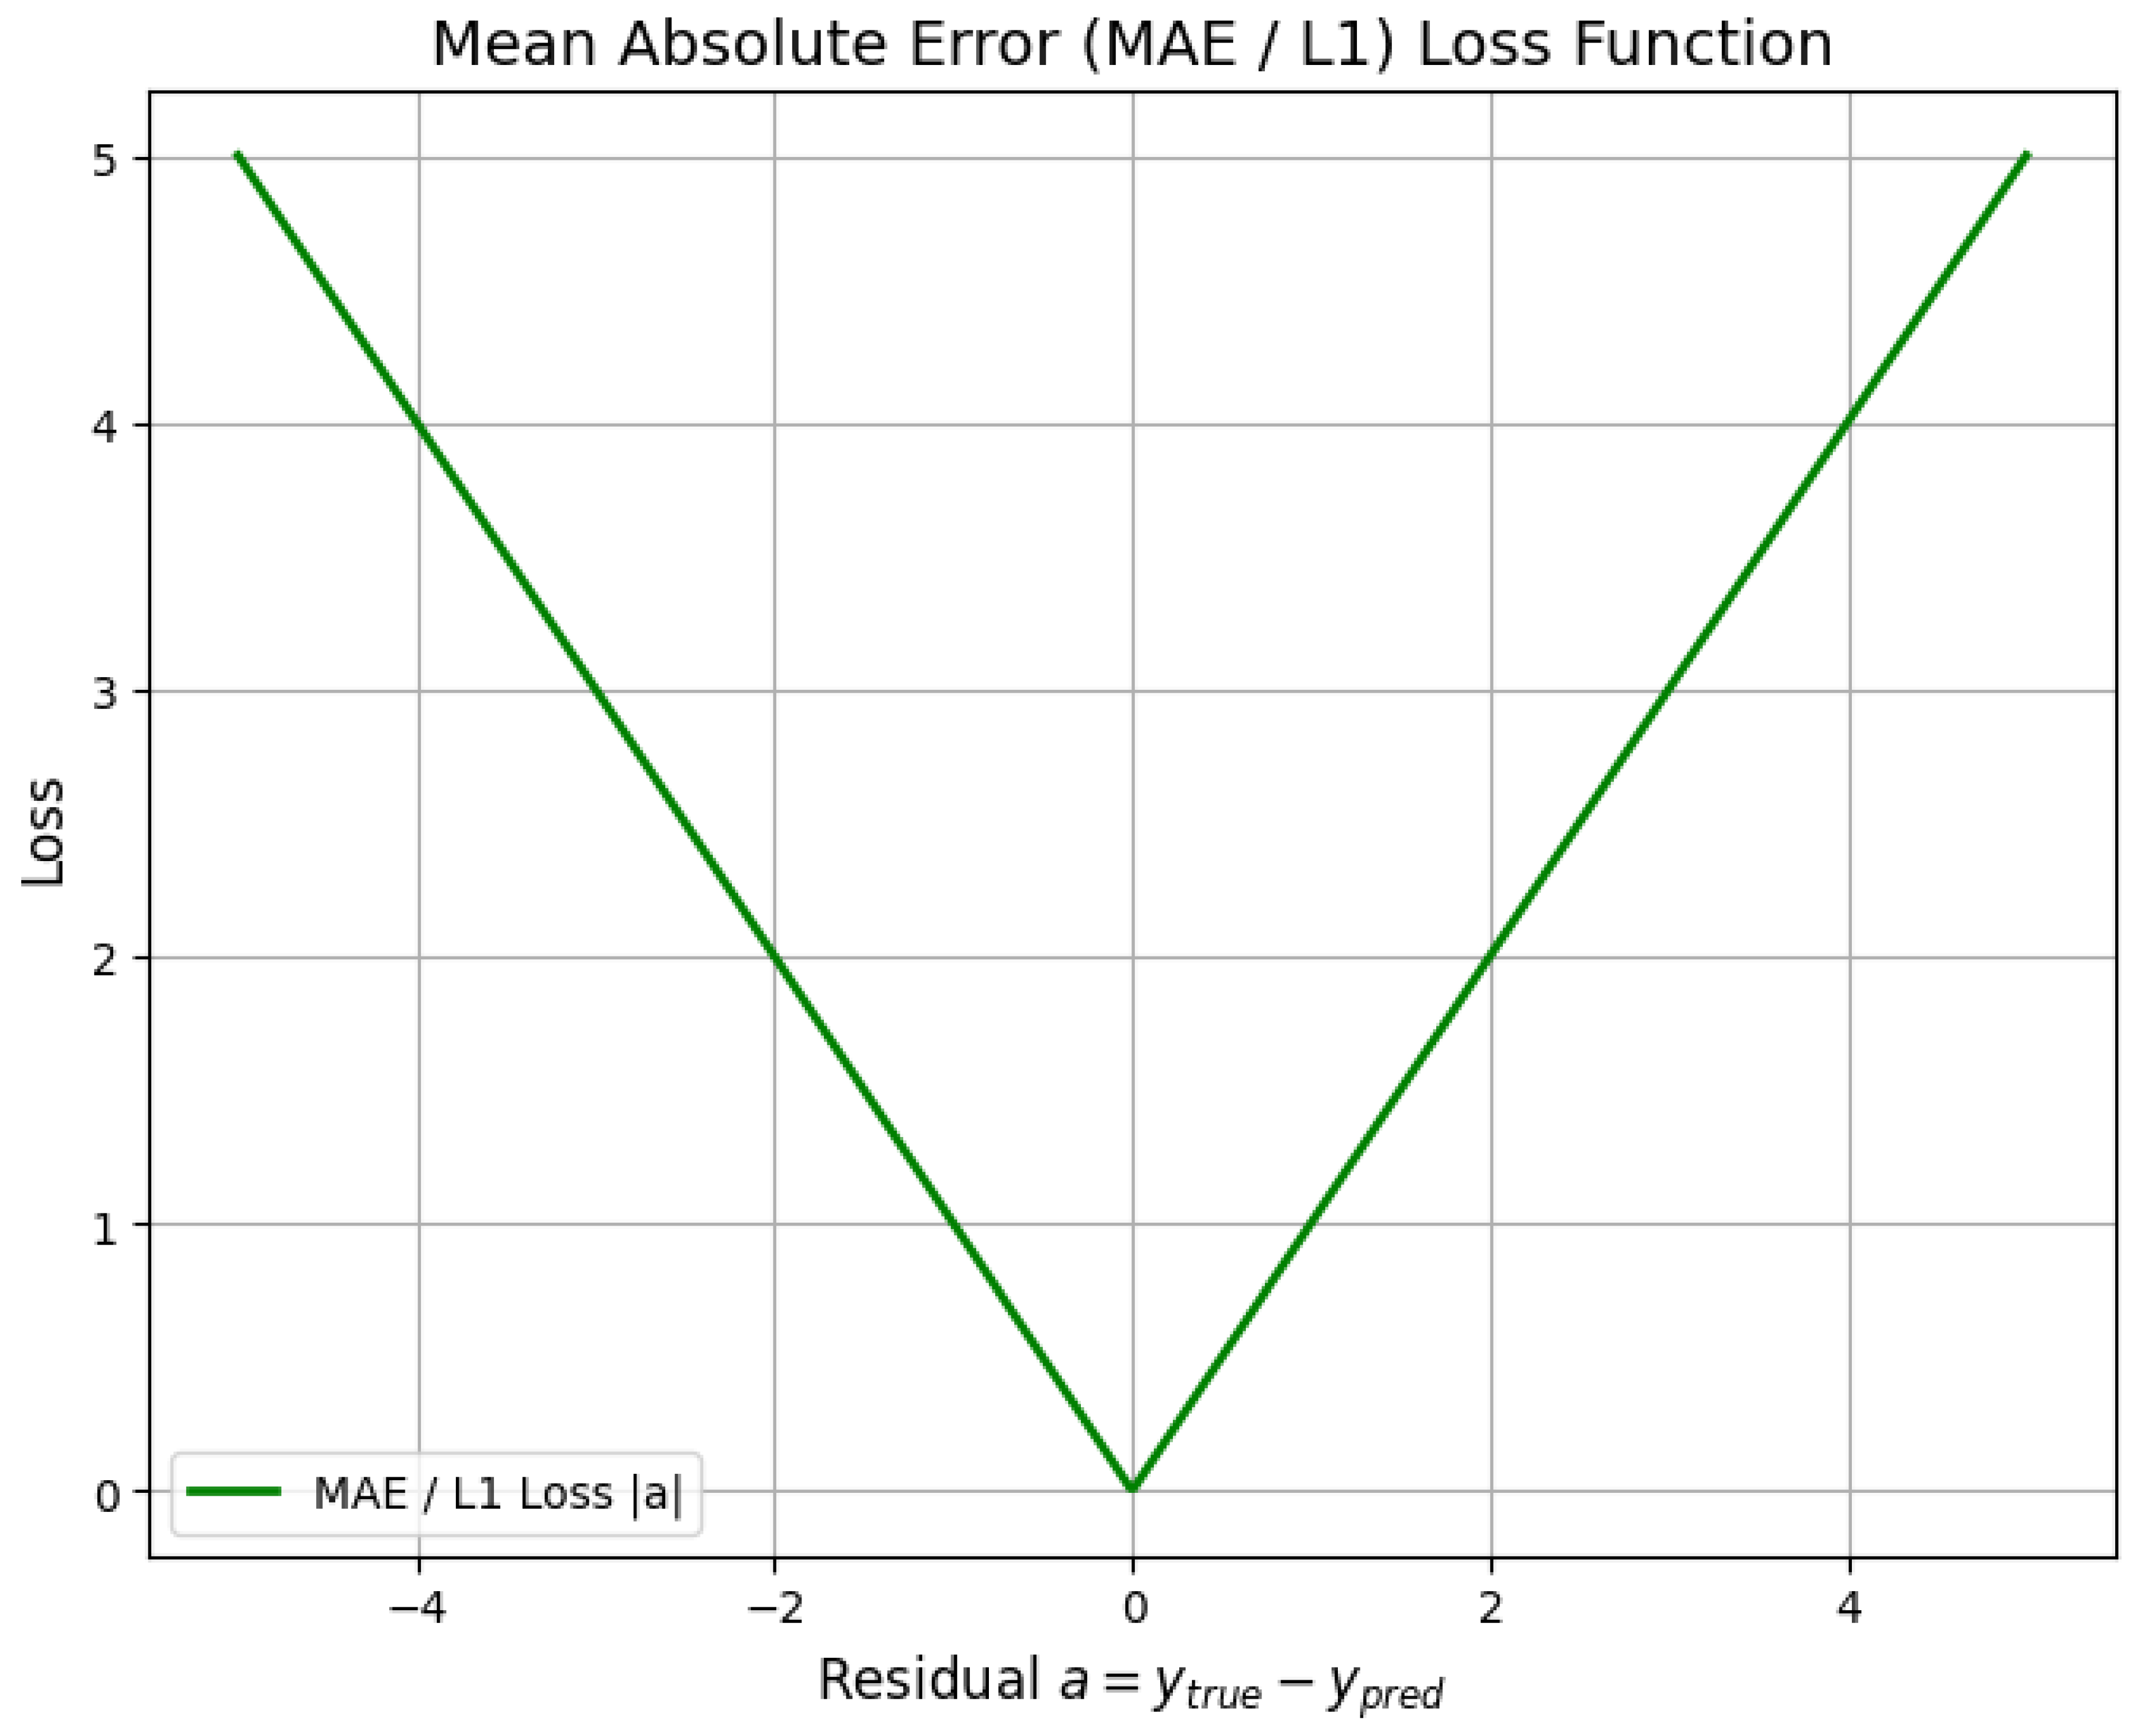
10.5.1.6 Python Code to Generate Figure 67 Illustrating Huber Loss Function
The Python code below produces the Figure 67 illustrating Huber Loss Function.
Figure 67.
Huber Loss Function
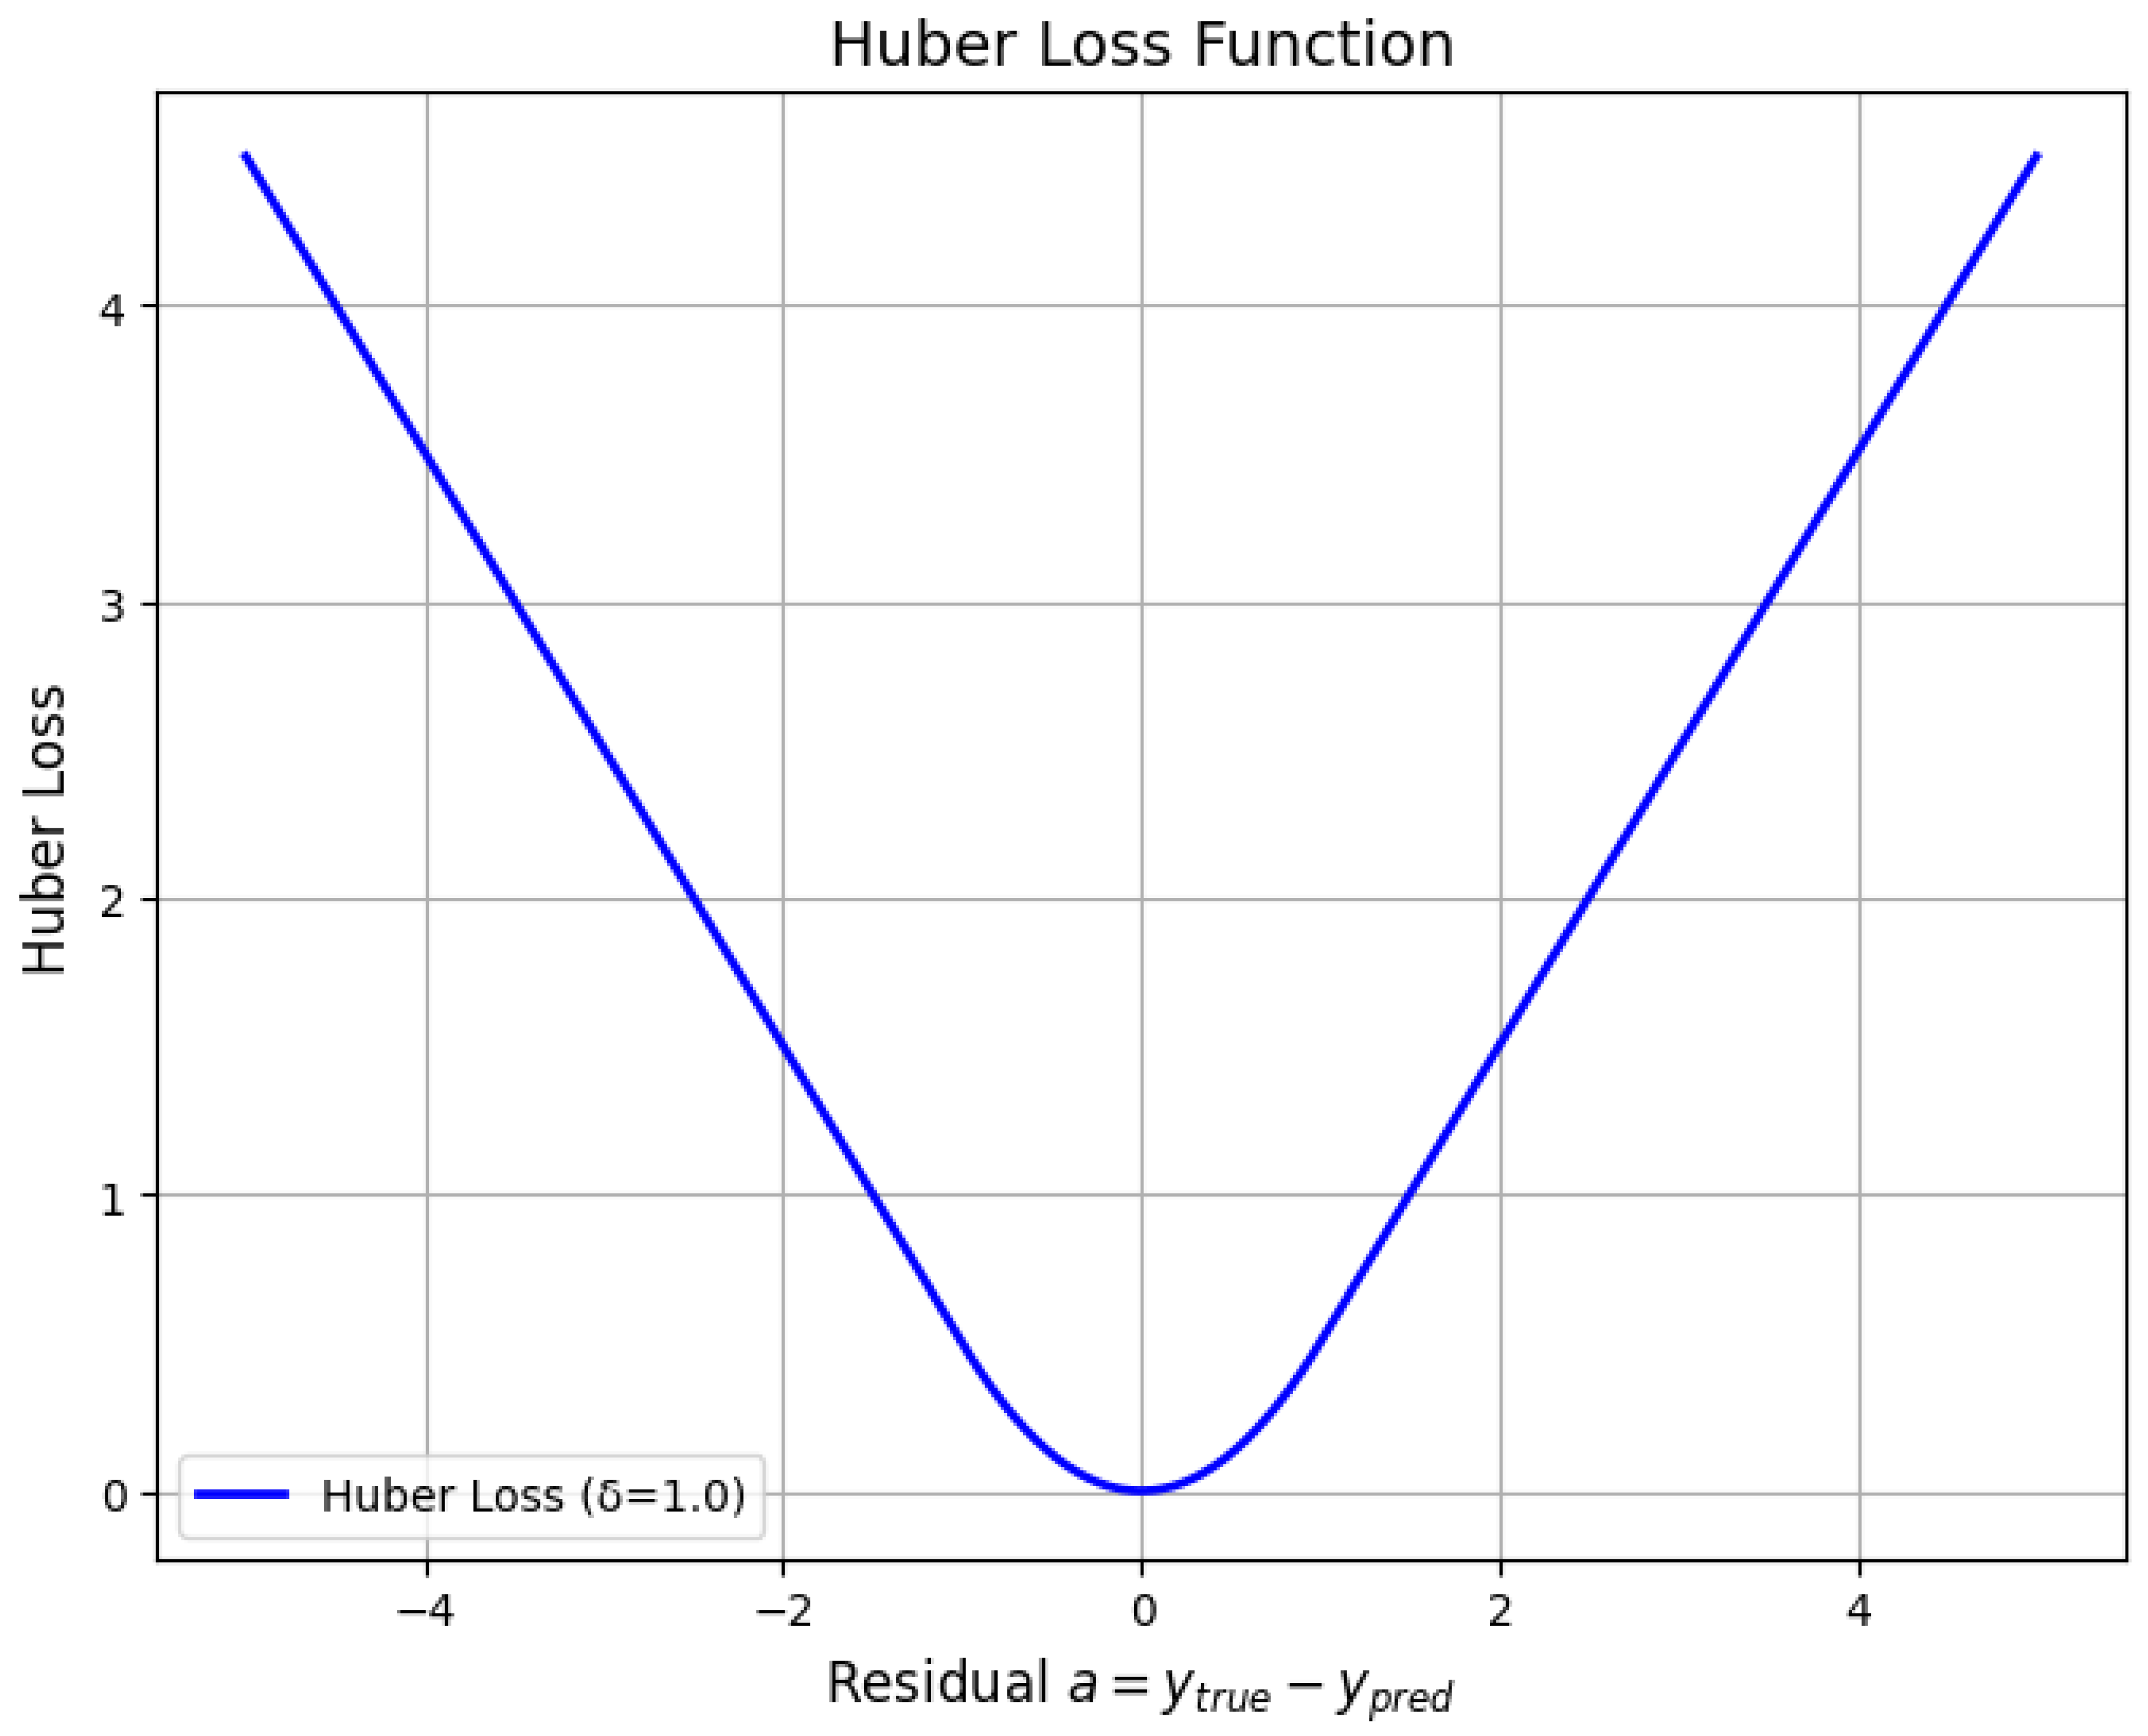
10.5.1.7 Python Code to Generate Figure 68 Comparing the Loss Functions: Huber, MSE, MAE
The Python code below produces the Figure 68 comparing the Loss Functions: Huber, MSE, MAE.
Figure 68.
Comparison of Loss Functions: Huber, MSE, MAE
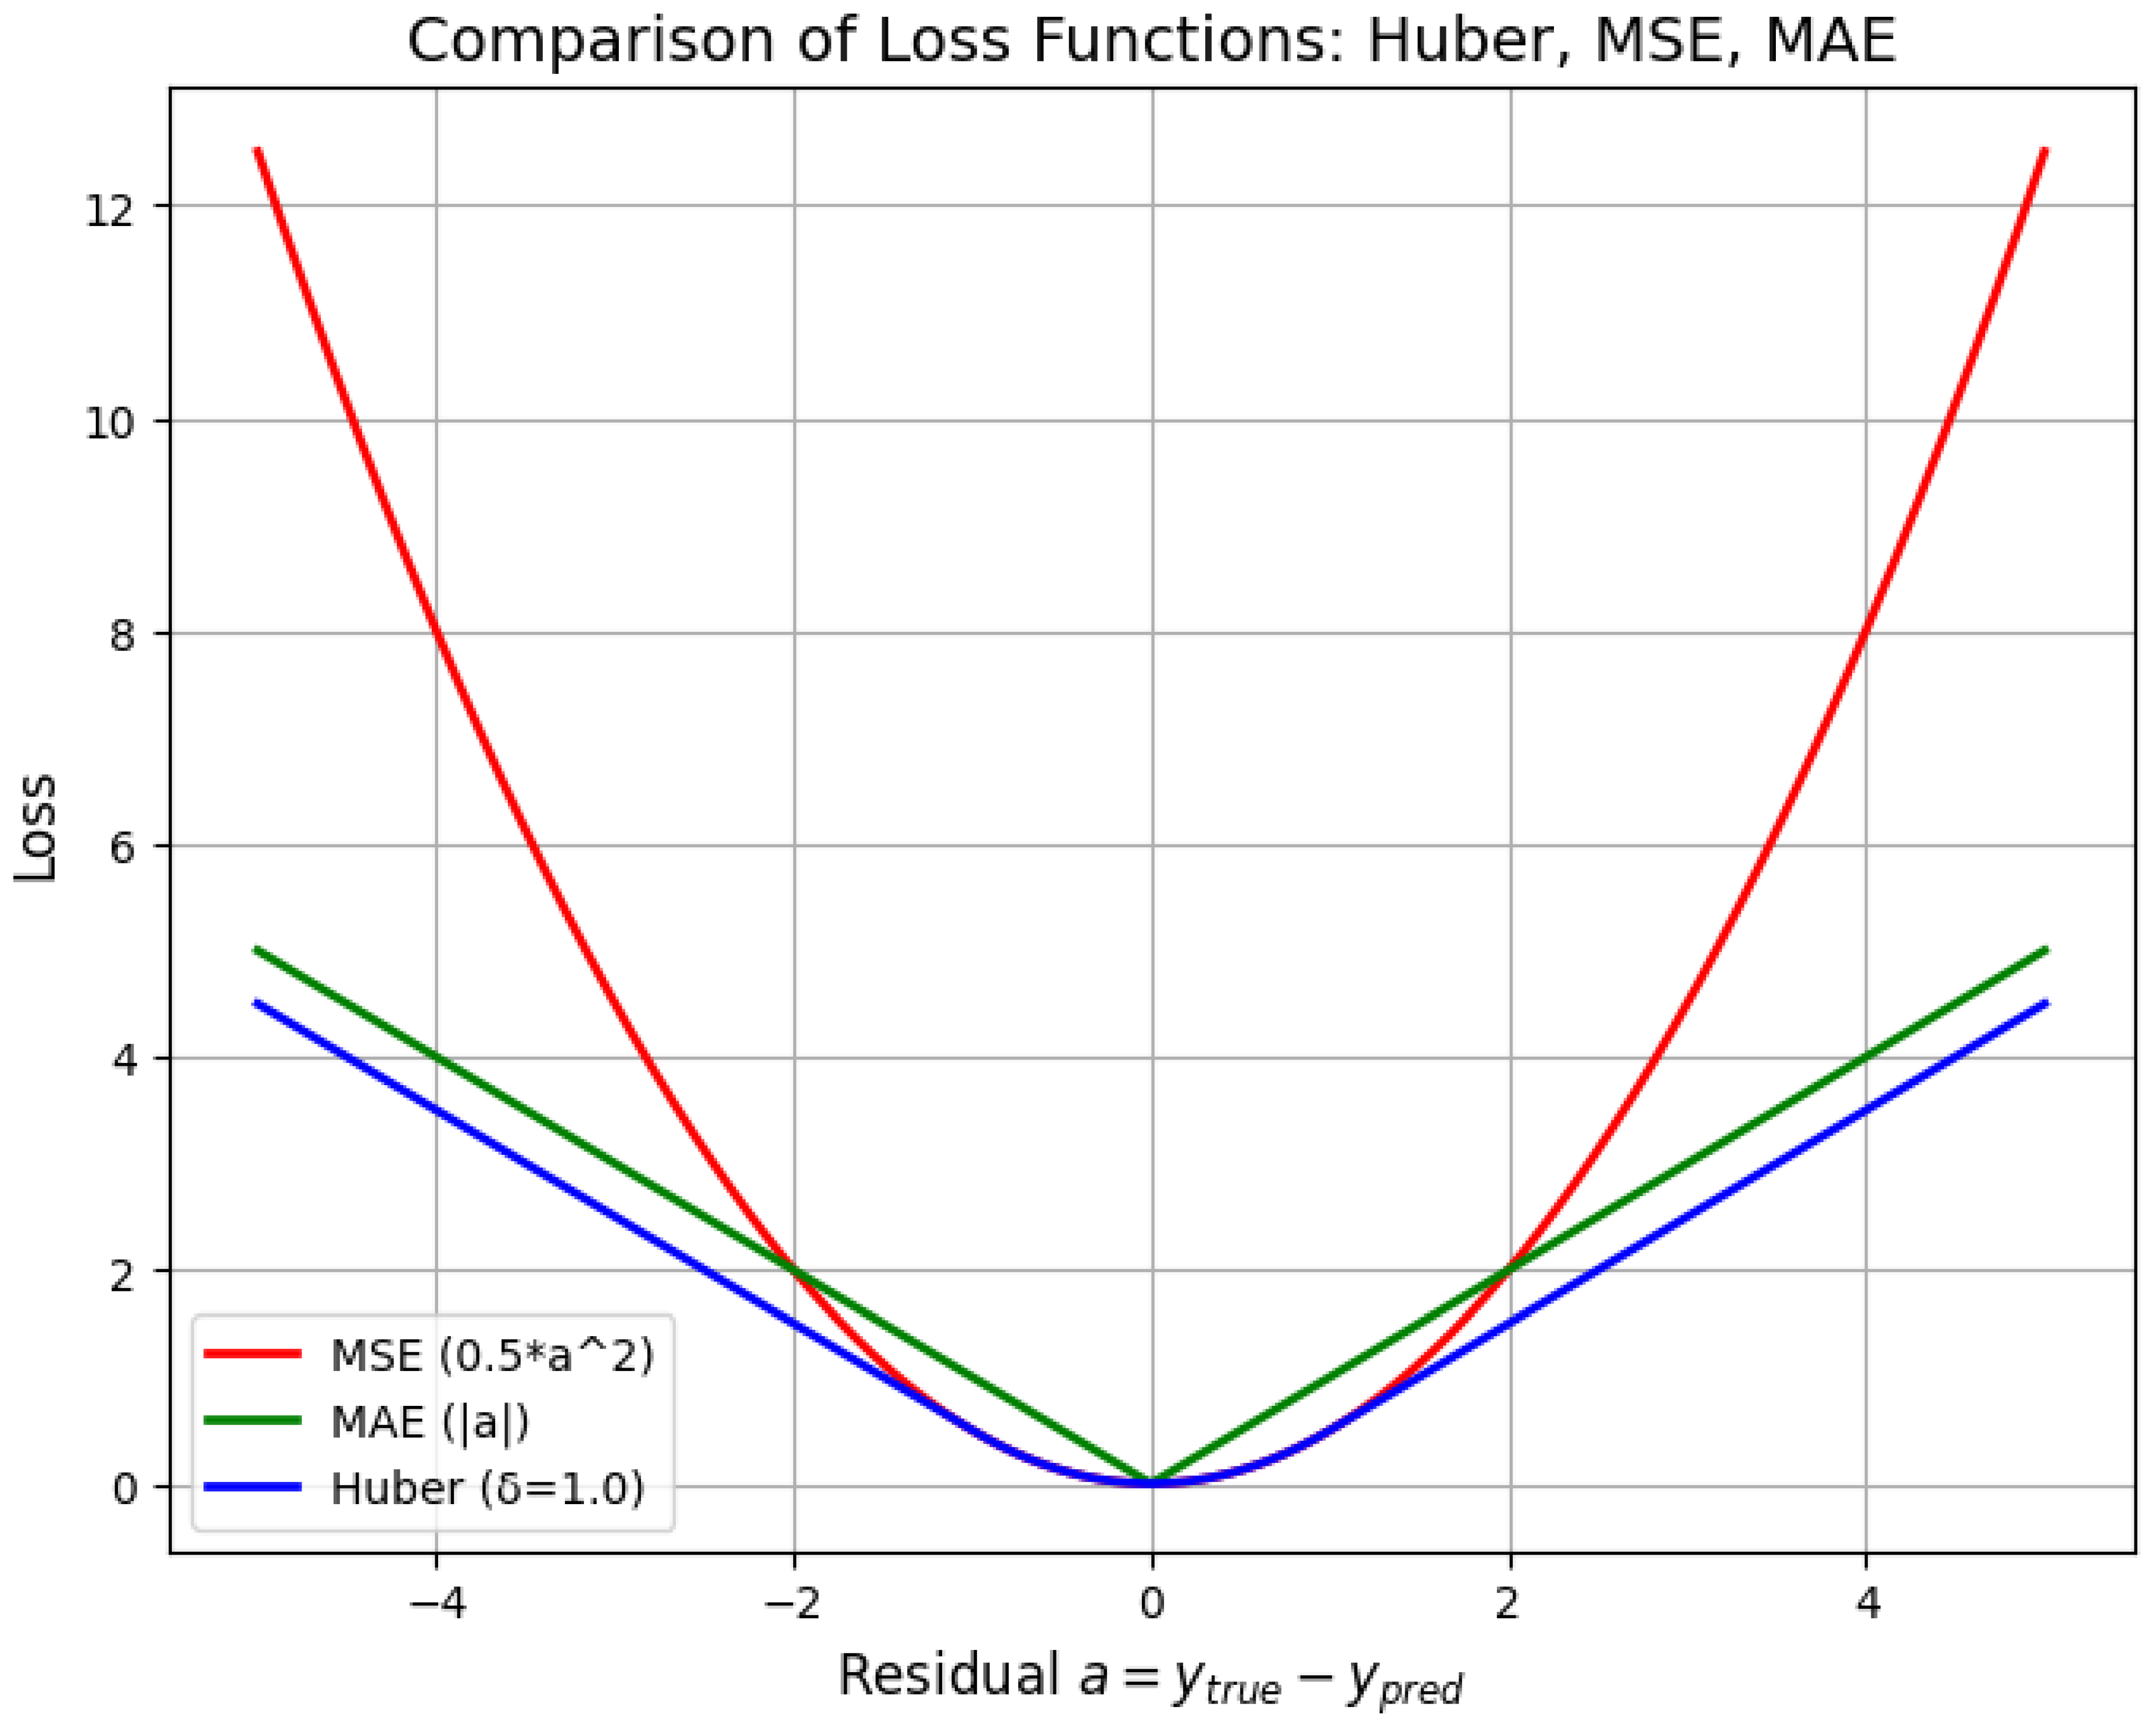
10.5.2. Loss Functions for Classification Tasks
For classification tasks, the cross-entropy loss is often employed, as it is particularly well-suited to tasks where the output is a probability distribution over multiple classes. In the binary classification case, where the target label is either 0 or 1, the binary cross-entropy loss function is defined as:
where is the predicted probability that the i-th sample belongs to the positive class (i.e., class 1). For multiclass classification, where the target label is a one-hot encoded vector representing the true class, the general form of the cross-entropy loss is:
where C is the number of classes, and is the predicted probability that the i-th sample belongs to class c. The gradient of the cross-entropy loss with respect to the predicted probabilities is:
This gradient facilitates the weight update by adjusting the model’s parameters to reduce the difference between the predicted probabilities and the actual class labels.
10.5.2.1 Binary Cross-Entropy (Log Loss)
The Binary Cross-Entropy loss function is the cornerstone of optimization for binary classification models, deriving its form directly from the principles of maximum likelihood estimation for a Bernoulli distribution. Consider a dataset of N independent and identically distributed observations, where the true labels are and the model’s prediction is the parameter , representing the estimated probability that . The probability of observing a single label given the input is given by the Bernoulli probability mass function:
The likelihood function for the entire dataset, assuming conditional independence, is the product of these probabilities:
The maximum likelihood estimate (MLE) for the parameters is found by maximizing this likelihood. To simplify this optimization, we take the natural logarithm, obtaining the log-likelihood:
Since optimization algorithms are typically designed for minimization, we define the loss function as the negative log-likelihood, scaled by to represent an empirical expectation over the data distribution:
Minimizing is thus equivalent to maximizing the likelihood of the observed data under the assumed Bernoulli model, ensuring the learned parameters yield a predicted probability distribution that is most consistent with the true labels.
From an information-theoretic perspective, Binary Cross-Entropy is the specific instance of the Kullback-Leibler (KL) Divergence between the empirical data distribution P and the model’s predictive distribution Q. For a single data point, the true distribution P is a degenerate Bernoulli distribution with parameter , having a probability mass of 1 at the true class. The model’s distribution Q is a Bernoulli distribution with parameter . The KL Divergence, which measures the information loss when Q is used to approximate P, is:
This expression can be decomposed as
The first term is the negative entropy of the true distribution . Since P is deterministic, , as is defined to be 0 by continuity and . Thus, the divergence simplifies to
The Binary Cross-Entropy loss is then the expectation of this divergence over the dataset:
The analytical properties of Binary Cross-Entropy are paramount for its use with gradient-based optimization.
The output of the neural network is typically produced by a sigmoid activation function applied to the final logit z, ensuring the prediction lies in the valid probability range :
The gradient of the loss with respect to the logit z exhibits a crucial simplification. We compute this gradient using the chain rule. First, the partial derivative of the loss for a single term with respect to the prediction is:
The derivative of the sigmoid activation with respect to its input is well-known:
Applying the chain rule, the gradient of the loss with respect to the logit is:
Distributing the terms yields:
This results in the elegant and stable gradient formula:
This simplicity is a key advantage. The gradient is merely the error between the prediction and the true label. Its magnitude is proportional to the error, providing a strong, clear signal for weight updates through backpropagation. The Hessian matrix, which contains the second derivatives, can be derived from this gradient. For a single data point, the second derivative with respect to the logit is
for , confirming the loss is convex with respect to the input logit . This local convexity contributes to the stable convergence properties of the optimization process when using this loss function.
10.5.2.2 Categorical Cross-Entropy
Categorical Cross-Entropy is the generalization of binary cross-entropy to multi-class classification problems where each instance belongs to exactly one of mutually exclusive classes. Its derivation is rooted in maximum likelihood estimation for the multinomial distribution. For a single data point, the true label is represented by a one-hot encoded vector , where if the instance belongs to class k and 0 otherwise. The model’s output is a probability distribution over the K classes, typically obtained using a softmax activation function on the final layer’s logits . The softmax function is defined as
which ensures and . The probability of observing the true label under this categorical model is given by the multinomial PMF for a single trial:
The likelihood for the entire dataset of N independent observations is
The log-likelihood is
The Categorical Cross-Entropy loss is consequently defined as the negative log-likelihood, scaled by the sample size:
Minimizing this loss is equivalent to maximizing the likelihood of the data, forcing the model’s predicted distribution to converge towards the true data distribution, which is a point mass at the correct class.
The information-theoretic interpretation of Categorical Cross-Entropy is that it computes the expected Kullback-Leibler Divergence between the true distribution P and the model’s distribution Q for each data point. For a single instance, the true distribution P is a categorical distribution with all probability mass on the true class , so where is the Kronecker delta. The model’s distribution Q is defined by . The KL Divergence is:
The terms are defined as 0 by continuity. This is identical to the inner sum for a one-hot vector , as only the term for is non-zero. Therefore, the loss
is the average KL Divergence across the dataset, measuring the total information loss when using the model’s distribution Q to approximate the true data distribution P.
The gradient of the Categorical Cross-Entropy loss with respect to the logits is particularly elegant and central to its use in backpropagation. The loss for a single sample is
To compute , we must account for the softmax function, as each logit influences every output due to the normalization in the denominator. The partial derivative of the softmax output for class k with respect to the logit for class j is:
where is the Kronecker delta. Using the chain rule, the gradient of the loss with respect to a specific logit is:
This sum can be separated:
Since is a one-hot vector, . This leads to the profoundly simple and stable result:
This gradient
is a vector whose j-th component is simply the difference between the predicted probability and the true label for class j. This elegant form ensures that the error signal propagated backwards during training is directly proportional to the discrepancy between the entire predicted distribution and the true distribution, providing a strong and clear direction for parameter updates. The Hessian of the loss with respect to the logits can be derived from this gradient and is related to the covariance of the predicted distribution, but the simplicity of the first-order gradient is its most critical property for efficient optimization in deep learning.
10.5.2.3 Sparse Categorical Cross-Entropy
Sparse Categorical Cross-Entropy is a computationally optimized variant of the standard Categorical Cross-Entropy loss function, designed for multi-class classification tasks where the true labels are provided as integer indices rather than one-hot encoded vectors. This formulation is mathematically equivalent to Categorical Cross-Entropy in its underlying probabilistic foundation but differs in its implementation, leading to significant gains in memory efficiency and computational speed, particularly when the number of classes K is very large. The fundamental principle remains maximum likelihood estimation for a categorical distribution. For a dataset of N samples, the true label for the i-th sample is given as an integer , which implicitly defines a degenerate probability distribution where and is the Kronecker delta. The model, as in the non-sparse case, produces a probability distribution over the K classes via the softmax function applied to a vector of logits :
The likelihood of observing the true label is , and the corresponding negative log-likelihood for a single sample is
The full Sparse Categorical Cross-Entropy loss is then the empirical expectation of this negative log-likelihood:
This is computationally and notationally more efficient than the standard form
because it avoids the explicit construction and storage of the entire matrix of one-hot encodings, requiring only the storage of an integer vector of length N for the labels. The minimization of this loss function is identical to minimizing the KL Divergence
for each sample, where is the model’s distribution.
The gradient computation for Sparse Categorical Cross-Entropy, crucial for backpropagation, reveals its intimate connection to the standard formulation while highlighting its efficiency. The gradient of the loss for a single sample with respect to the logits must be computed. This requires the partial derivative for any class j. The derivative of the loss with respect to the predicted probability of the true class is
The connection to all logits is made through the Jacobian of the softmax function
Applying the chain rule, the gradient for an arbitrary logit is:
This results in the same elegantly simple gradient vector as the standard formulation:
where is now the implicit one-hot vector corresponding to the integer label , meaning its j-th component is .
From an implementation perspective, this means the gradient for the logit corresponding to the true class is , and for all other logits , it is simply . This result is identical to the gradient derived for the one-hot encoded case; however, the computational pathway to achieve it is more efficient. There is no need to materialize a full one-hot matrix, perform a large matrix multiplication, or sum over all K classes for each sample during the gradient calculation. The backward pass can be implemented by first computing the softmax probabilities , then copying this entire vector as the gradient , and finally subtracting 1 from the single element at the index of the true label . This operation is per sample, but the constant factors and memory overhead are drastically lower than in the one-hot case, making Sparse Categorical Cross-Entropy the preferred choice in practice for problems with a large number of classes, such as in language modeling or large-scale image classification.
10.5.2.4 Kullback-Leibler Divergence (KL Divergence)
The Kullback-Leibler (KL) Divergence, denoted , is a fundamental measure of information theory that quantifies the difference between two probability distributions P and Q over the same random variable X. It is not a true metric, as it is not symmetric and does not satisfy the triangle inequality; rather, it is a divergence that measures the information loss when a distribution Q is used to approximate the true distribution P. For discrete distributions, the KL Divergence is defined as
where is the sample space, and the sum is taken over all possible values of X. For continuous distributions, the definition involves an integral:
where p and q are the probability density functions of P and Q, respectively. The logarithm is typically taken with base 2 (yielding units of bits) or base e (yielding units of nats), and by convention, and for , reflecting the infinite penalty for assigning zero probability to an event that is possible under P. The divergence is always non-negative, , with equality if and only if almost everywhere, a result known as Gibbs’ inequality, which follows from the strict concavity of the logarithm function and Jensen’s inequality.
For a fixed discrete probability distribution P:
The plot of KL Divergence as a function of shall be
The KL Divergence can be decomposed into two interpretable components: the cross-entropy between P and Q minus the entropy of P. Cross-entropy measures the average number of bits needed to encode events from P using a code optimized for Q, defined as
for discrete variables. The entropy of P
measures the inherent uncertainty or the average number of bits needed to encode events from P using an optimal code. Thus
This decomposition shows that the divergence represents the extra number of bits required to encode data from P when using a code based on Q, rather than the true distribution P. In the context of machine learning, where P is often the true data distribution and Q is the model’s distribution, minimizing the KL Divergence is equivalent to minimizing the cross-entropy, since is fixed with respect to the model parameters. This is why cross-entropy loss is ubiquitously used in classification tasks.
For a fixed discrete probability distribution P:
The 2D plot of KL Divergence as a function of and shall be
The mathematical properties of the KL Divergence are critical for its applications. It is convex in both P and Q, meaning that for any two pairs of distributions and , and for , we have
This convexity ensures that optimization problems involving KL Divergence have unique minima under certain constraints. The divergence also factors elegantly for independent distributions. If and , then
Additivity extends to more complex factorizations, such as in variational inference, where it is used to approximate posterior distributions. The gradient of the KL Divergence with respect to the parameters of Q is essential for gradient-based optimization. For a parameterized distribution , we have
as the entropy of P is independent of . This gradient is the same as that of the cross-entropy loss, facilitating its use in training probabilistic models like variational autoencoders, where it acts as a regularizer to push the approximate posterior toward a prior distribution , ensuring tractable inference and meaningful latent representations.
10.5.2.5 Python Code to Generate Figure 69 Illustrating Binary Cross-Entropy (BCE) Loss Function
The Python code below produces the Figure 69 illustrating Binary Cross-Entropy (BCE) Loss Function.
Figure 69.
Binary Cross-Entropy (BCE) Loss Function
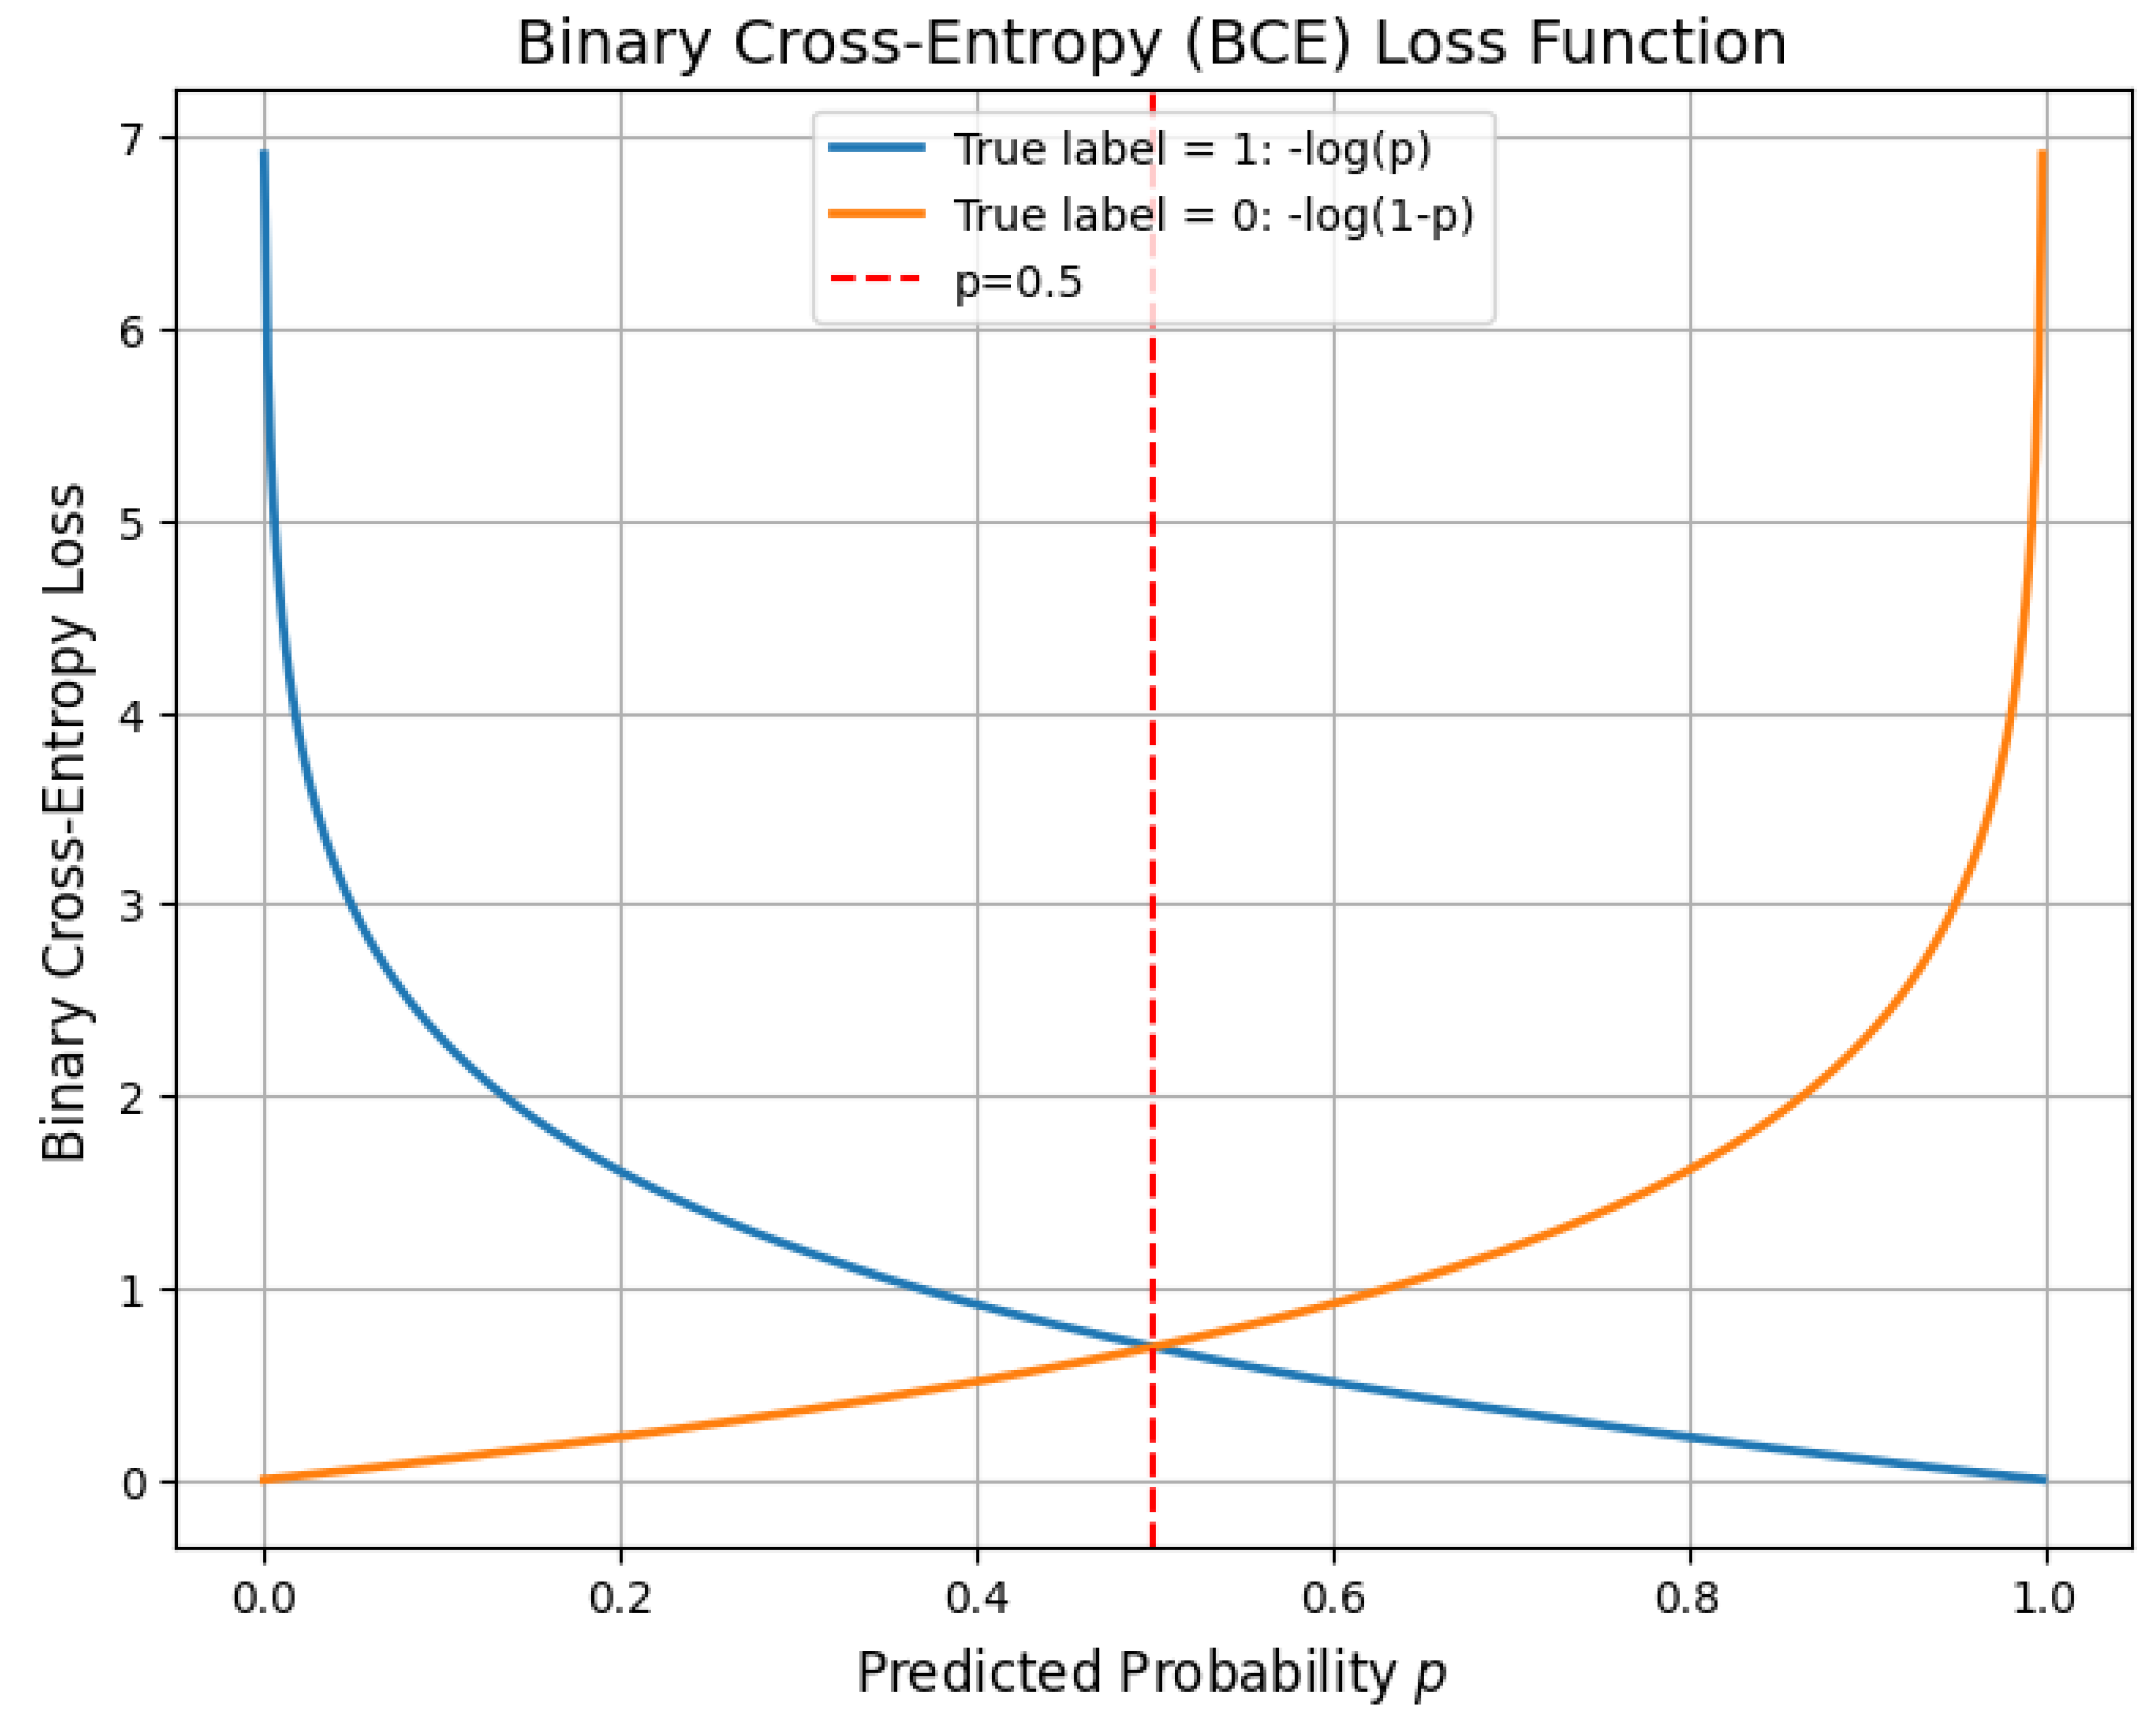
10.5.2.6 Python Code to Generate Figure 70 Illustrating Binary Cross-Entropy Loss Surface
The Python code below produces the Figure 70 illustrating Binary Cross-Entropy Loss Surface.
Figure 70.
Binary Cross-Entropy Loss Surface
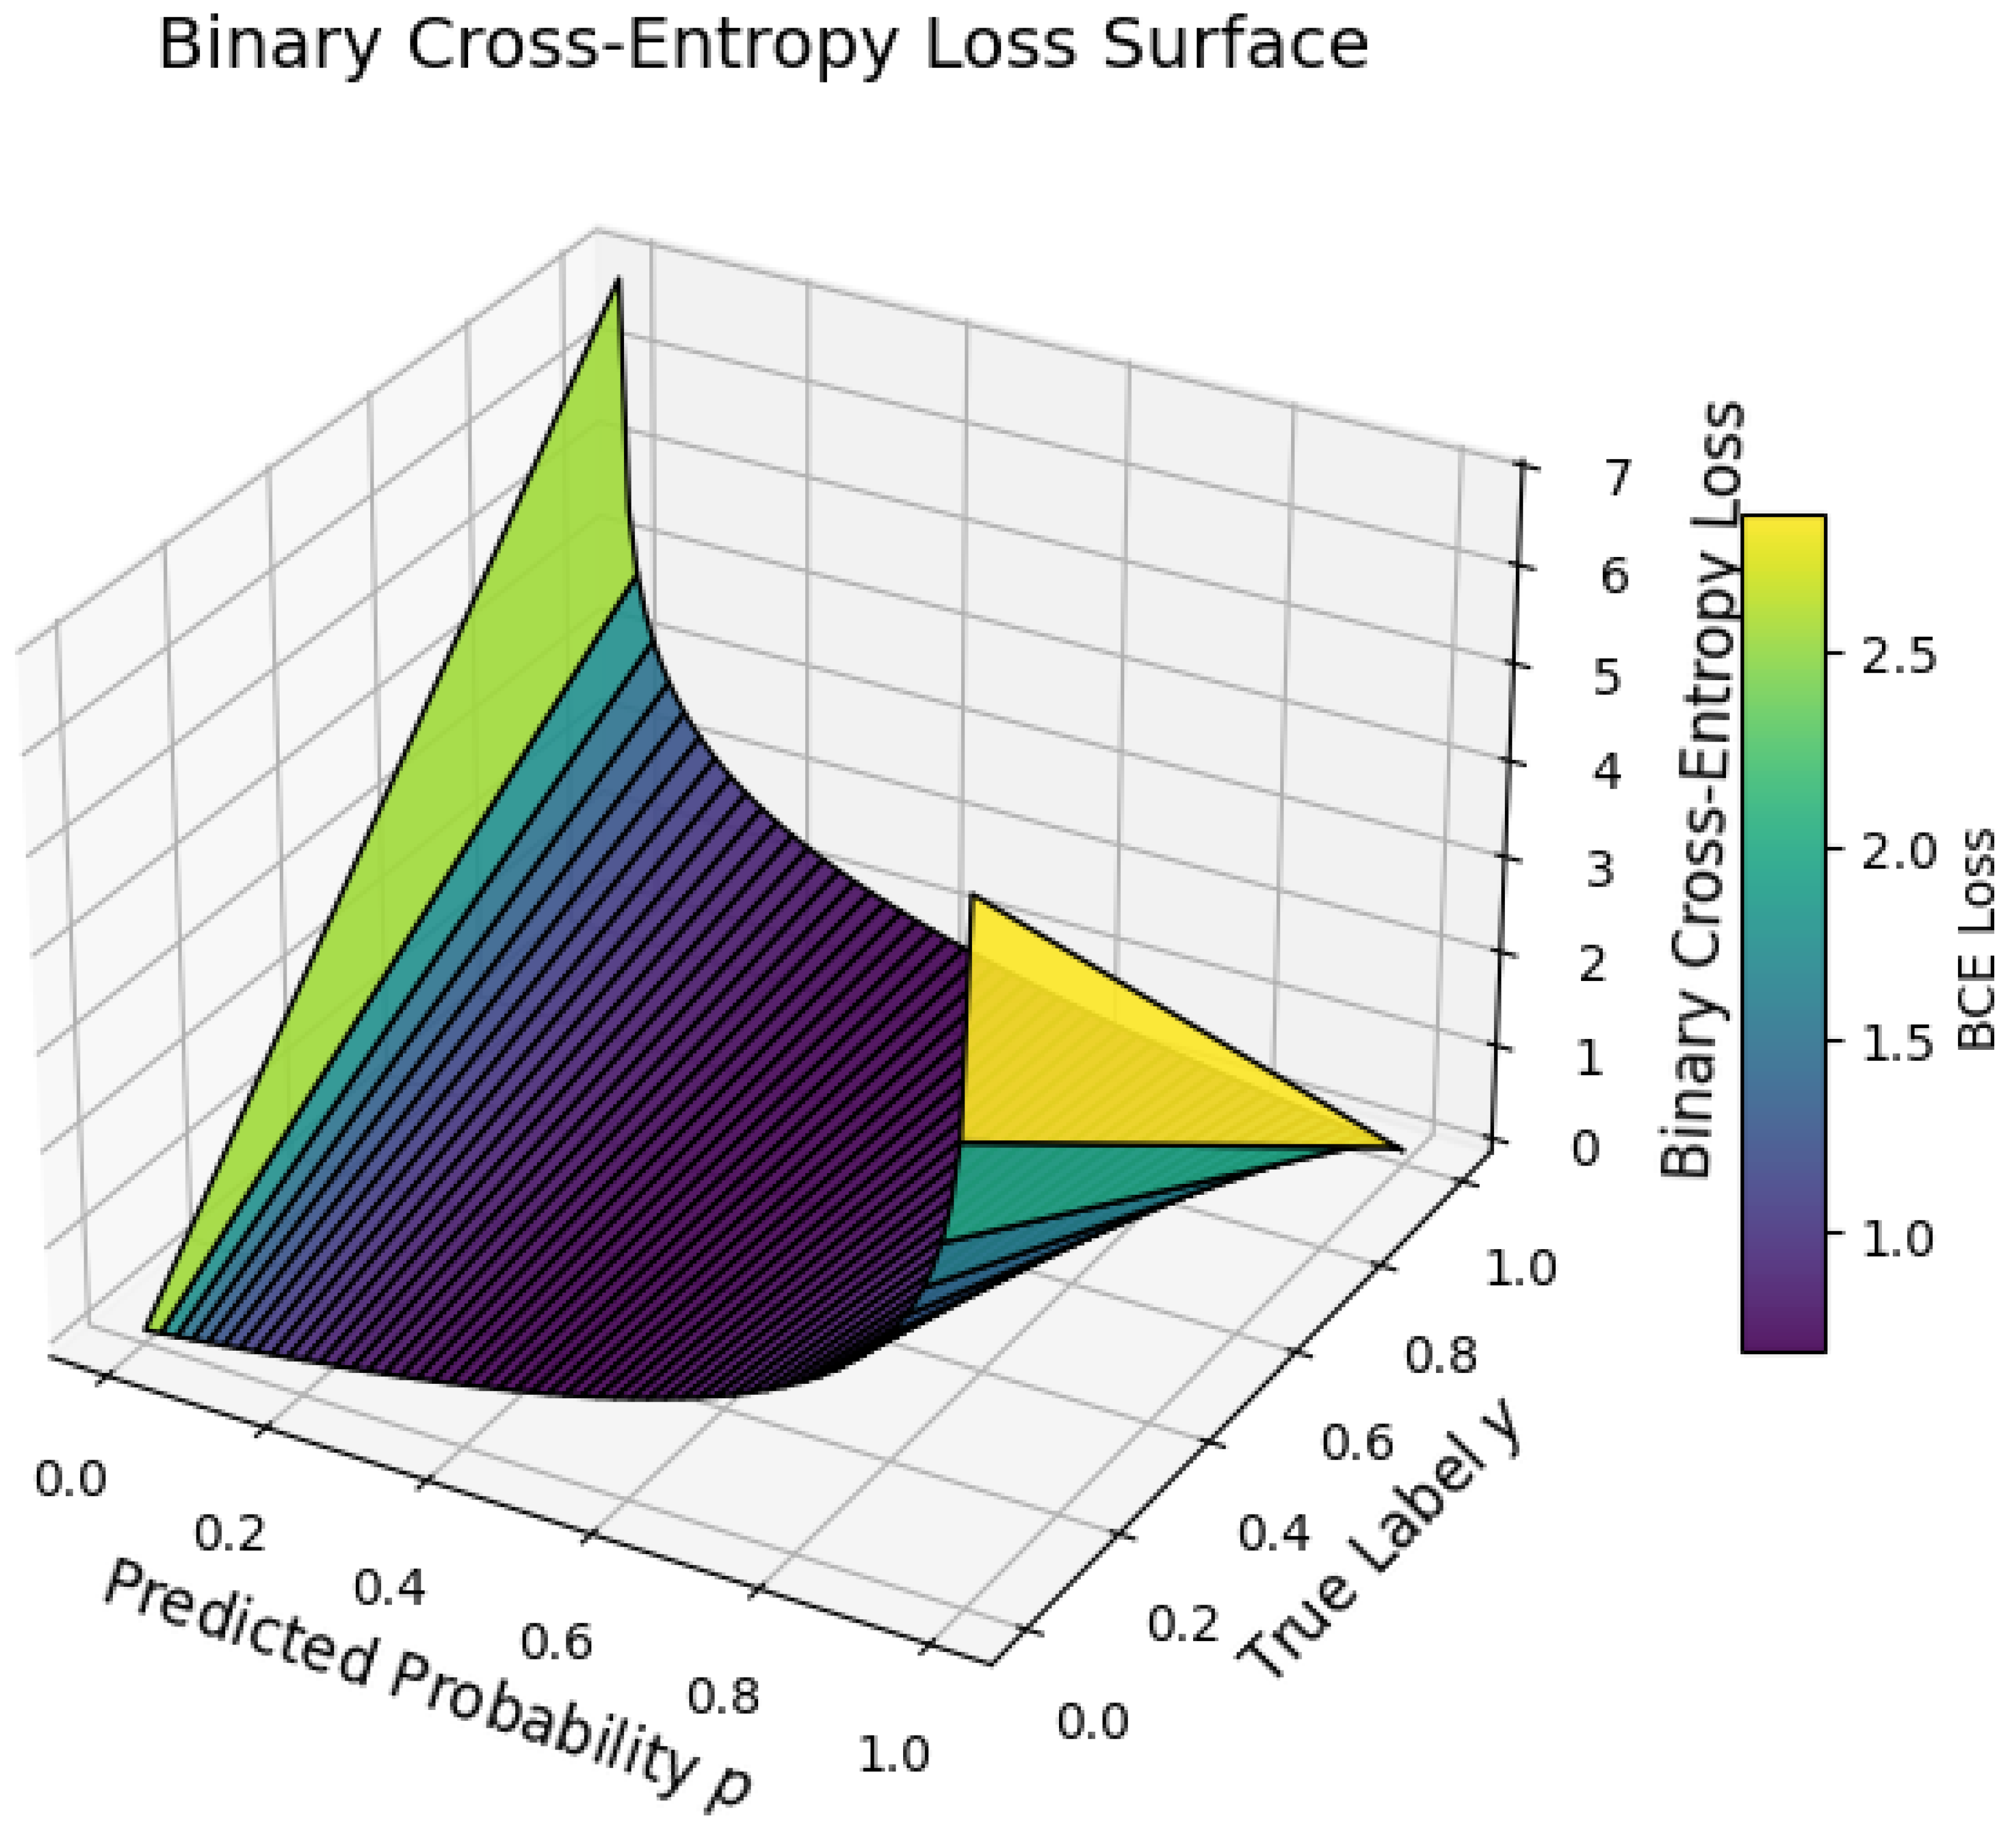
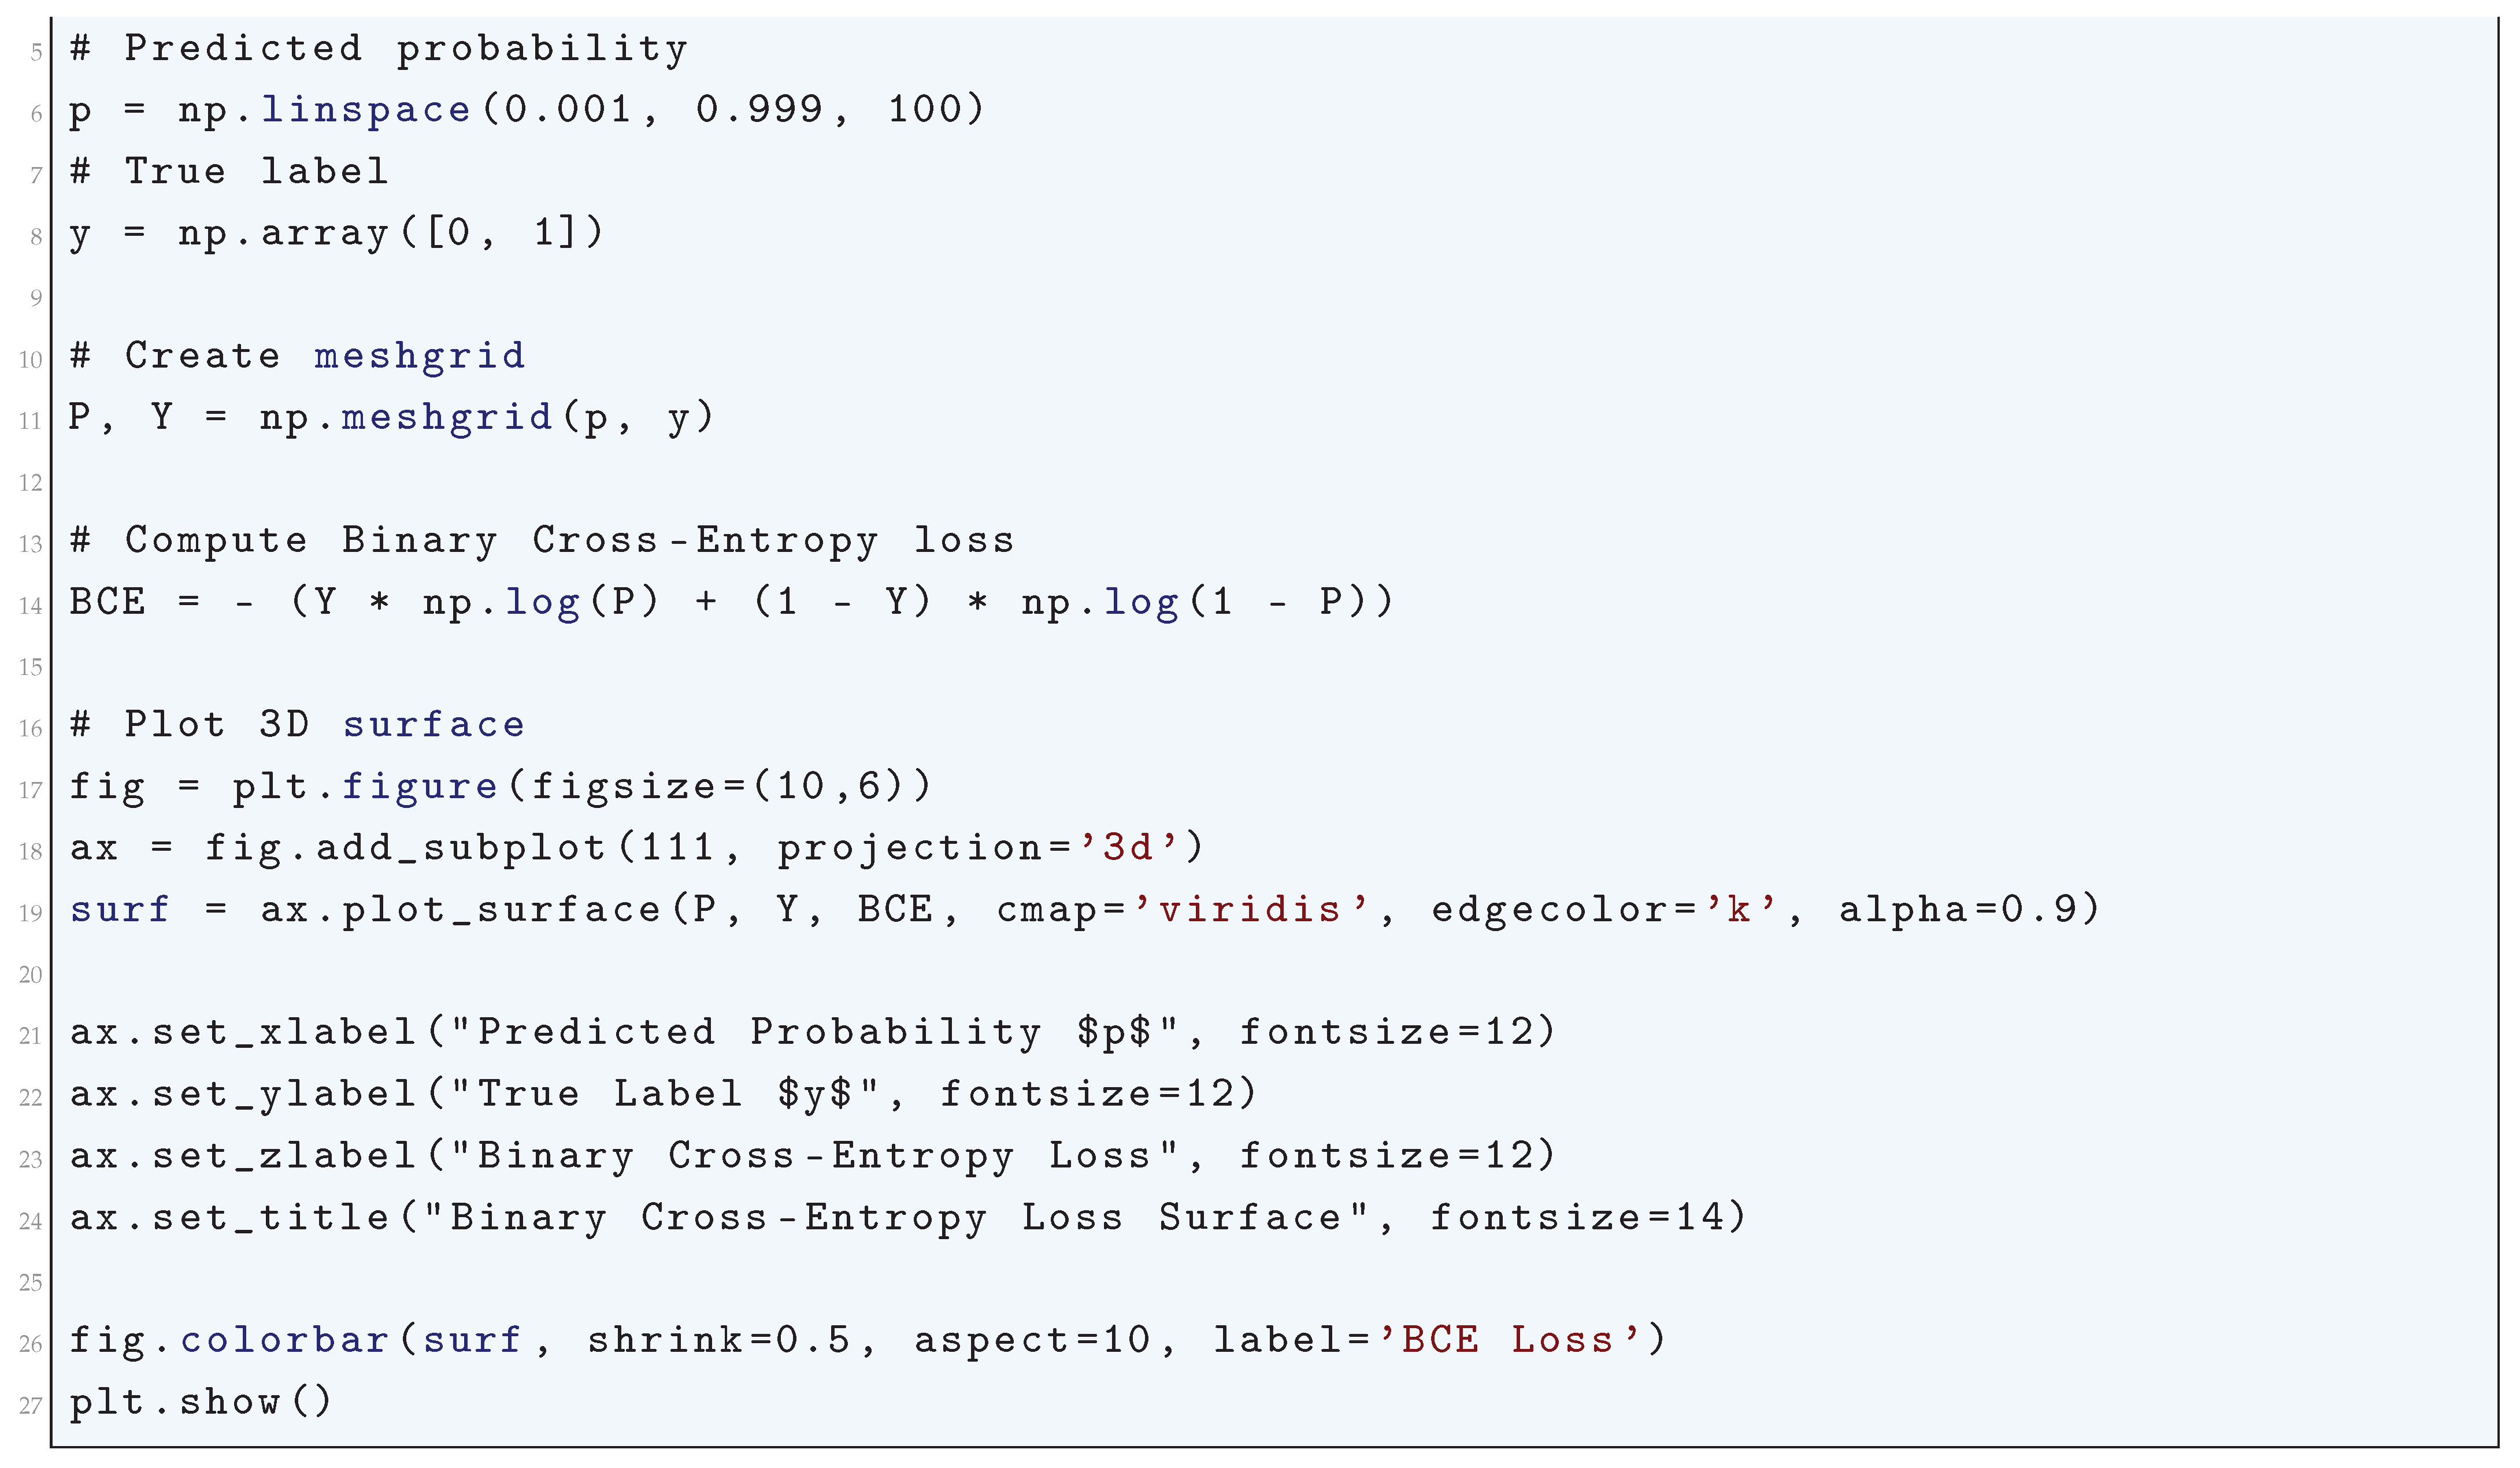
10.5.2.7 Python Code to Generate Figure 71 Illustrating Categorical Cross-Entropy Loss
The Python code below produces the Figure 71 illustrating Categorical Cross-Entropy Loss.
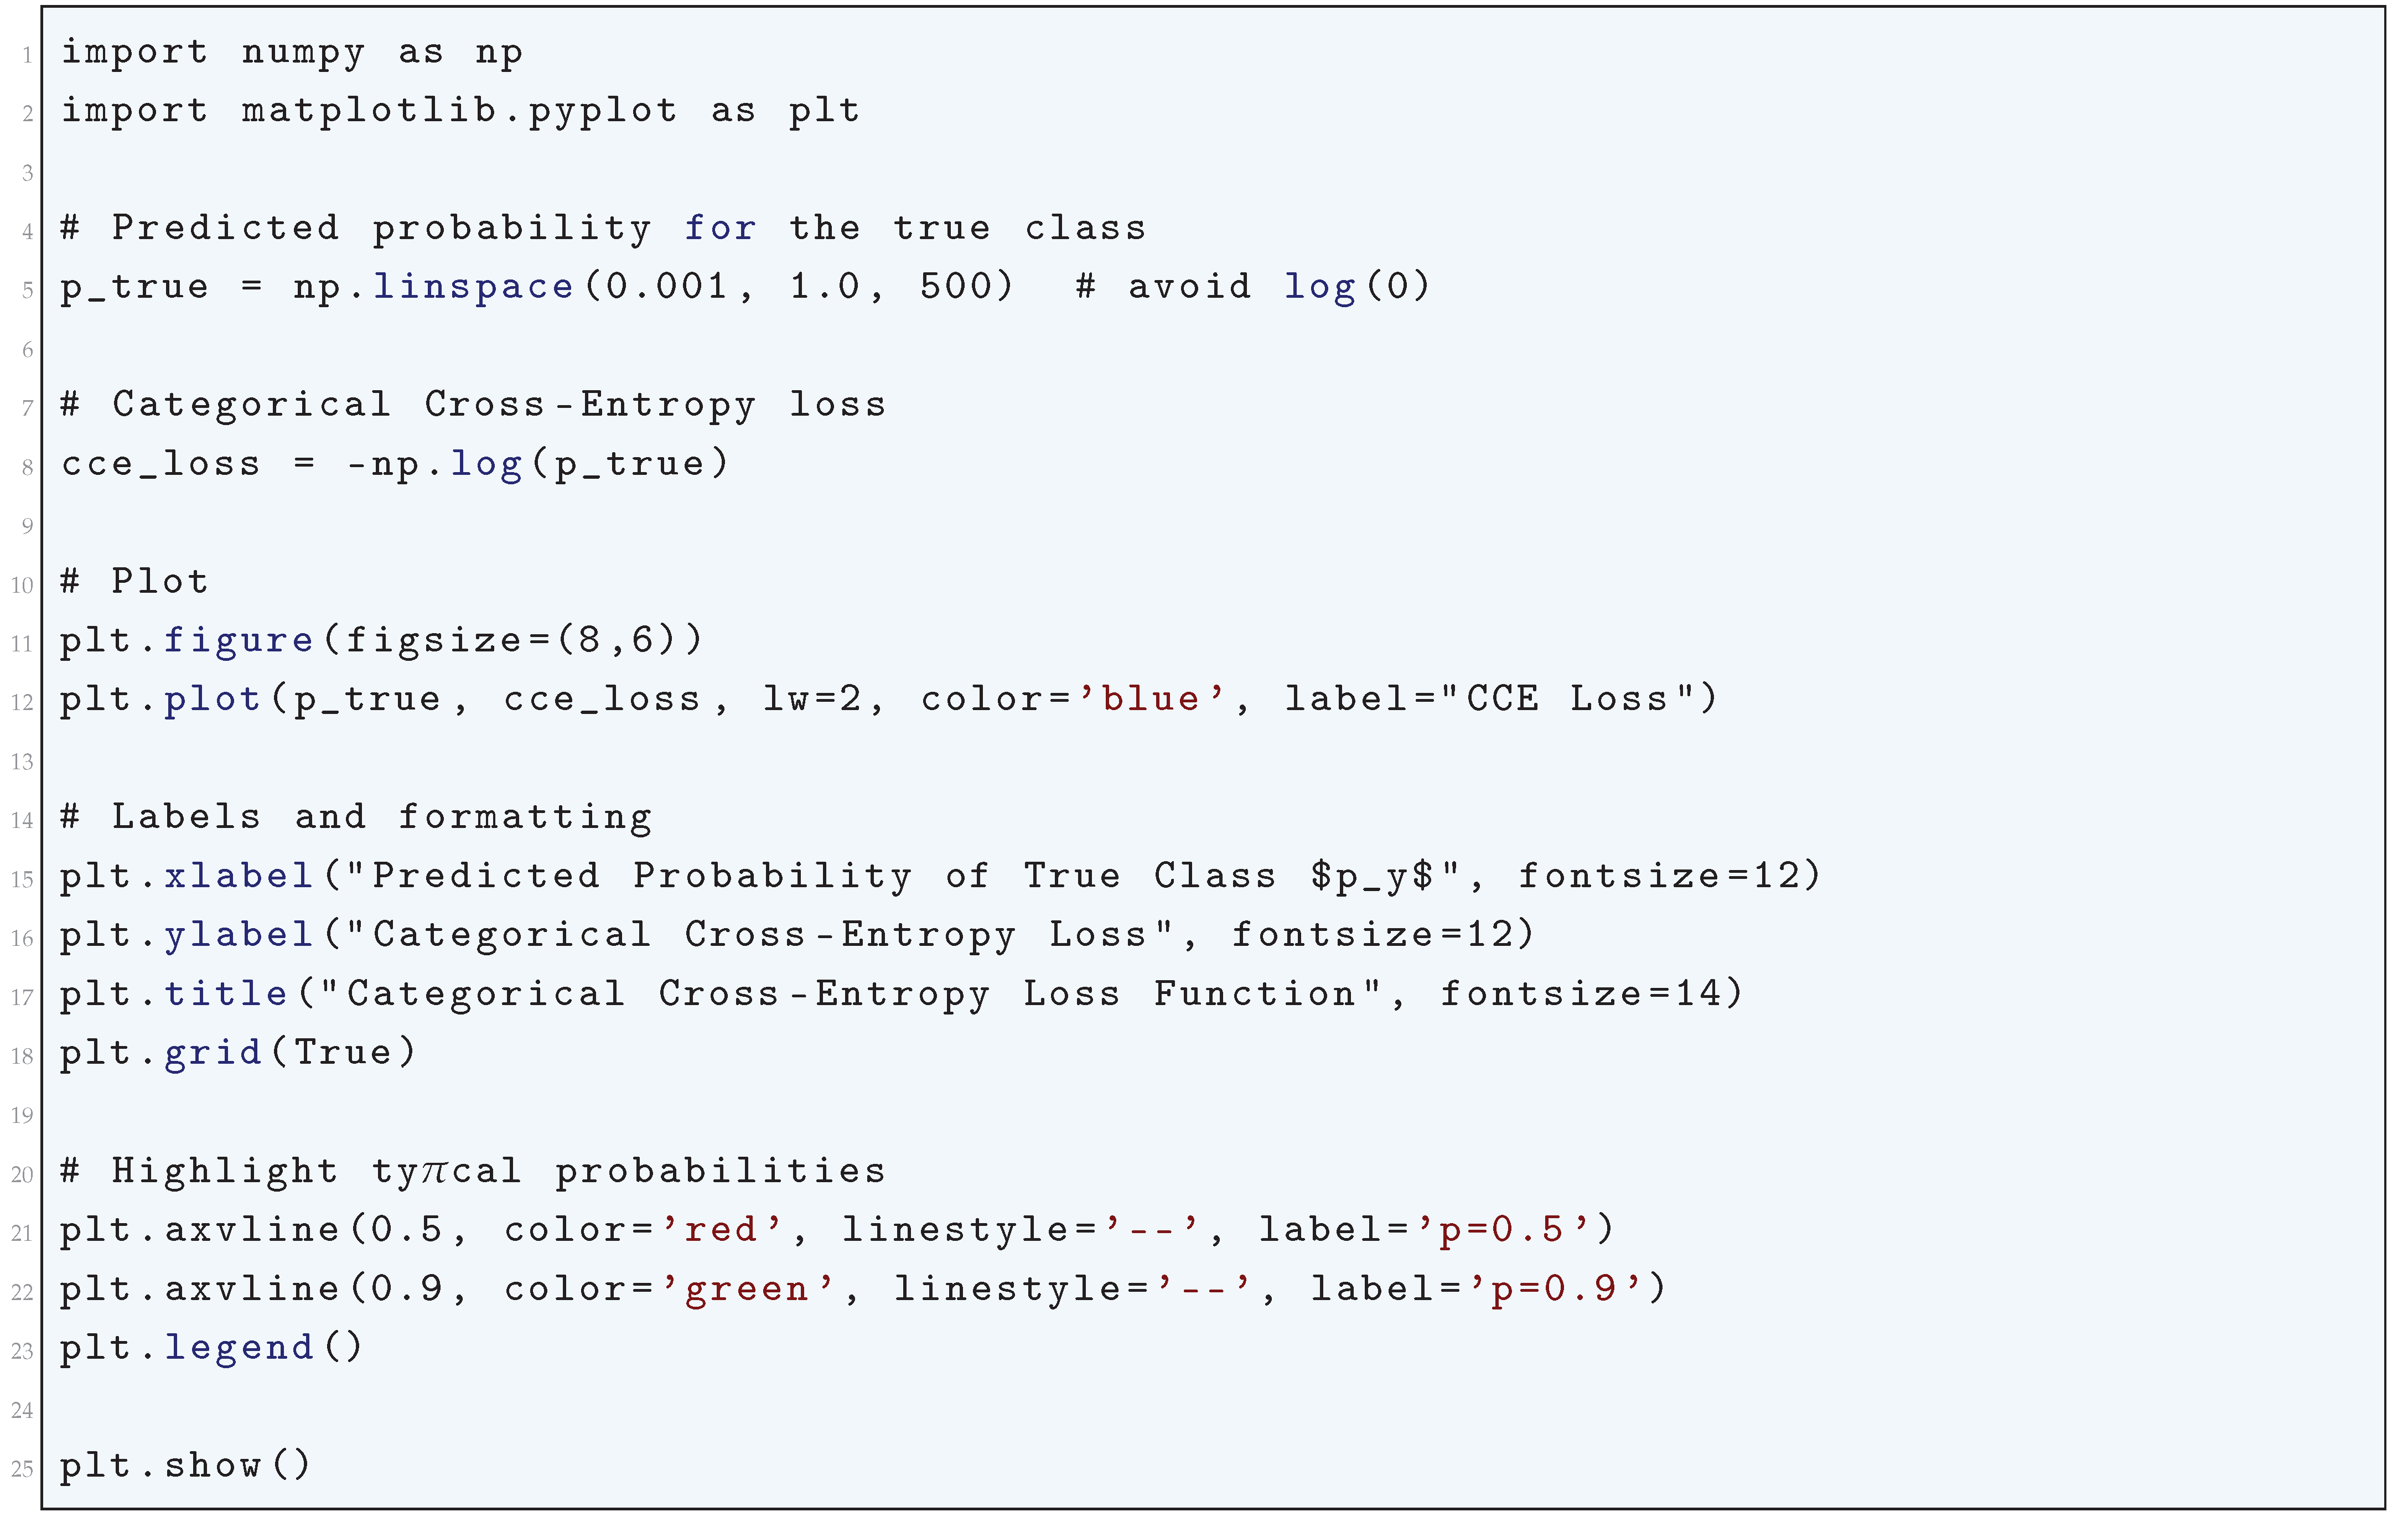
Figure 71.
Categorical Cross-Entropy Loss
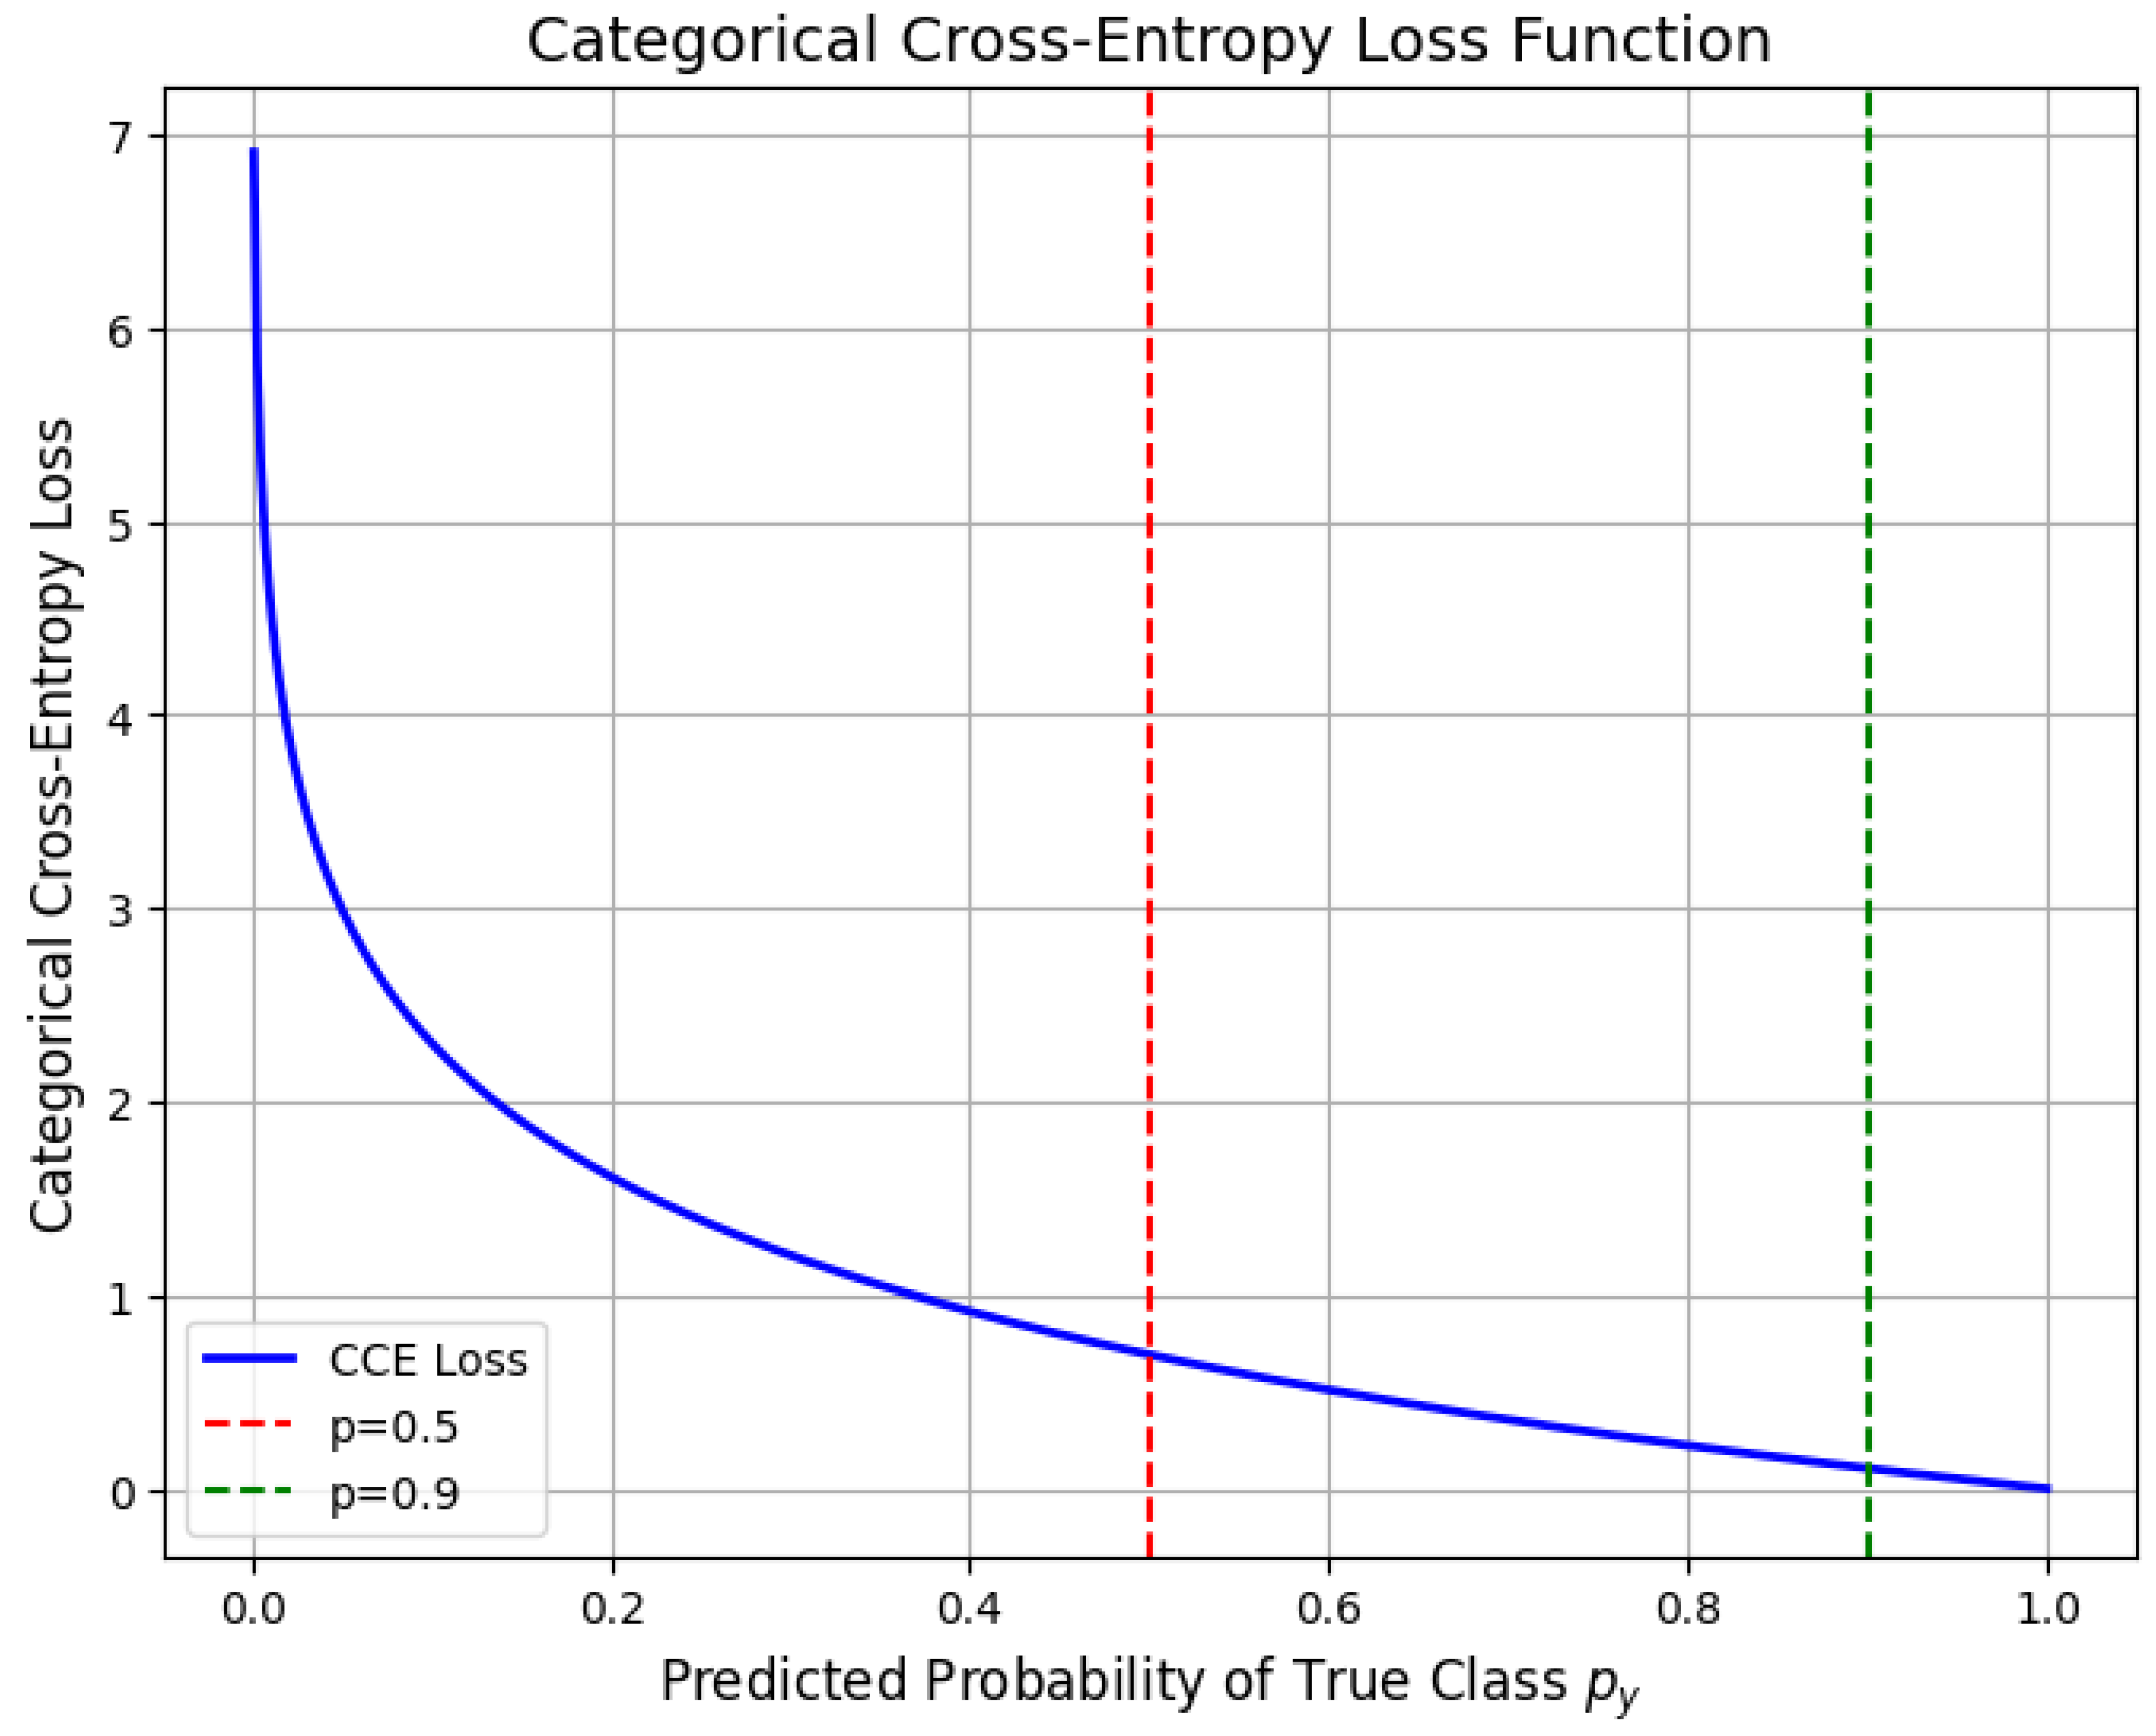
10.5.2.8 Python Code to Generate Figure 72 Illustrating Categorical Cross-Entropy Loss
The Python code below produces the Figure 72 illustrating Categorical Cross-Entropy Loss.
Figure 72.
Categorical Cross-Entropy Loss
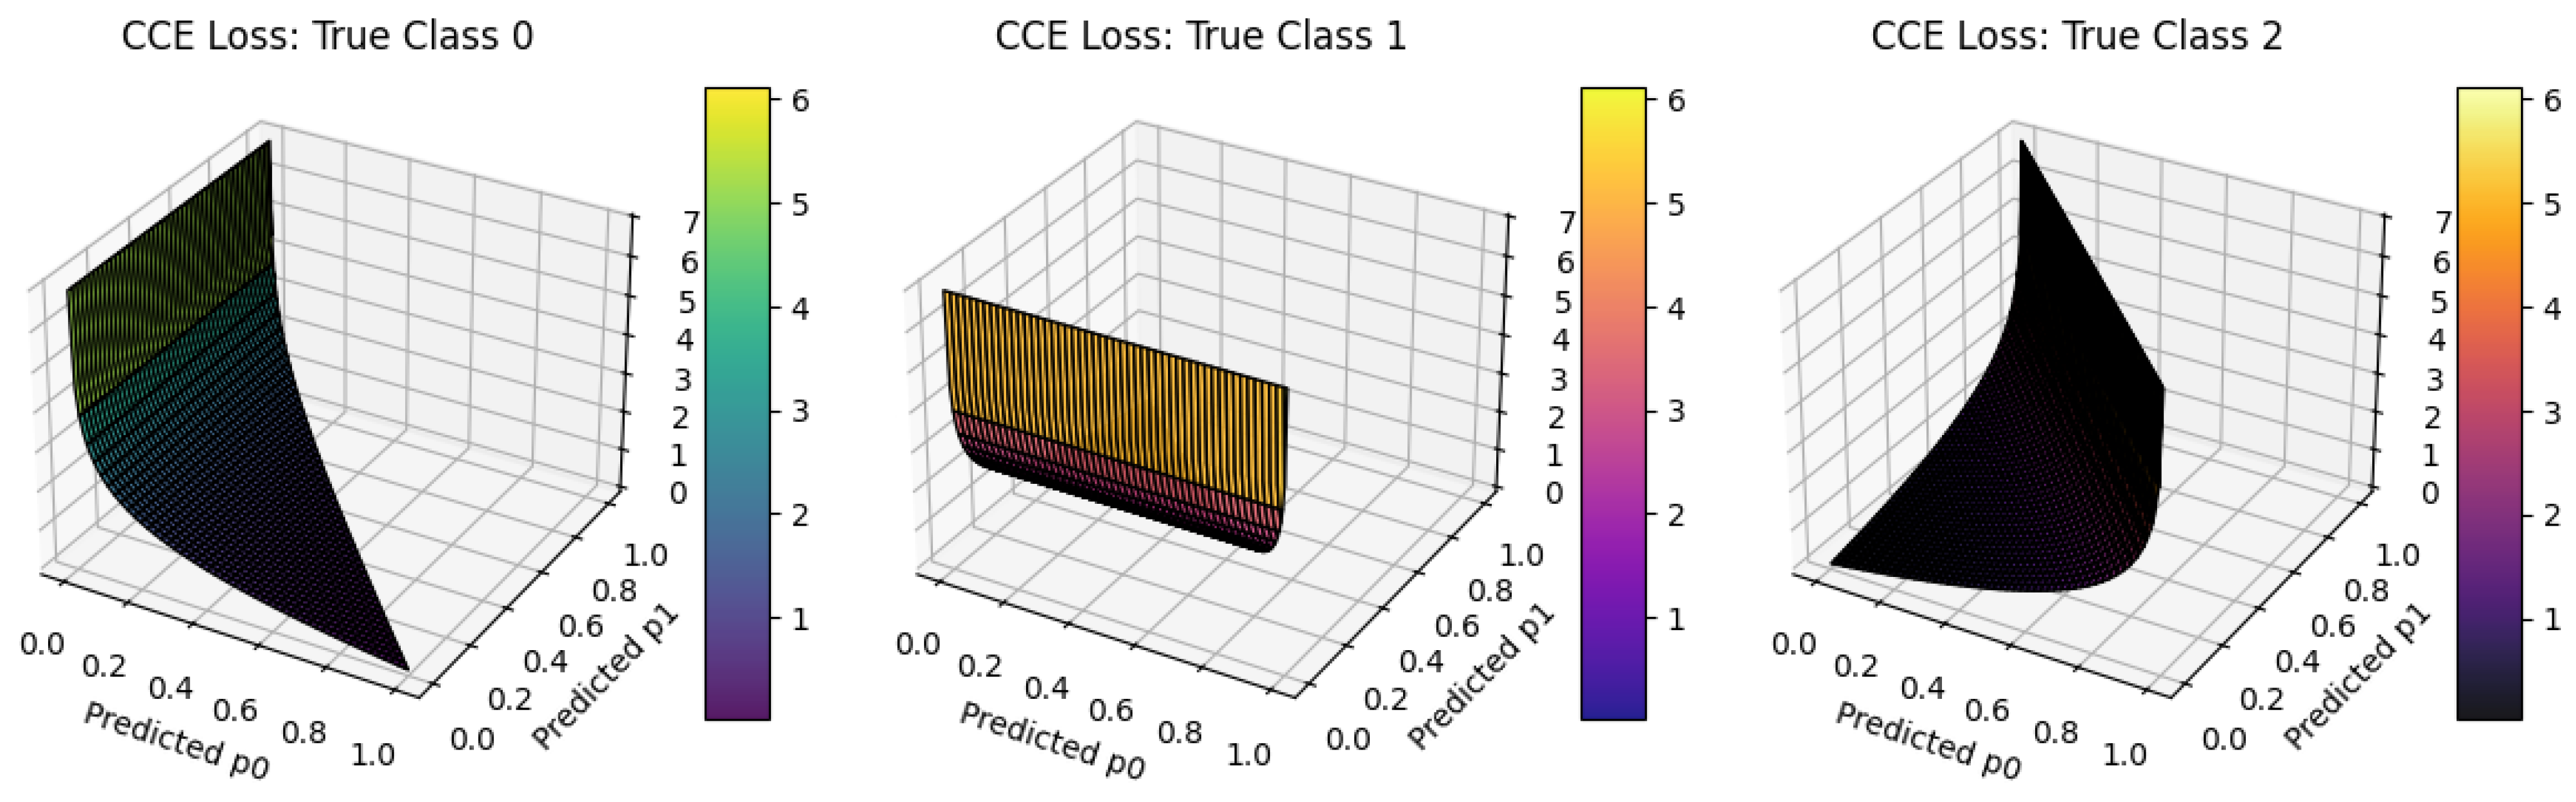
10.5.2.9 Python Code to Generate Figure 73 Illustrating Sparse Categorical Cross-Entropy Loss
The Python code below produces the Figure 73 illustrating Sparse Categorical Cross-Entropy Loss.
Figure 73.
Sparse Categorical Cross-Entropy Loss
10.5.2.10 Python Code to Generate Figure 74 Illustrating Surface Plot of Sparse Categorical Cross-Entropy Loss
The Python code below produces the Figure 74 illustrating Surface Plot of Sparse Categorical Cross-Entropy Loss.
Figure 74.
Surface Plot of Sparse Categorical Cross-Entropy Loss
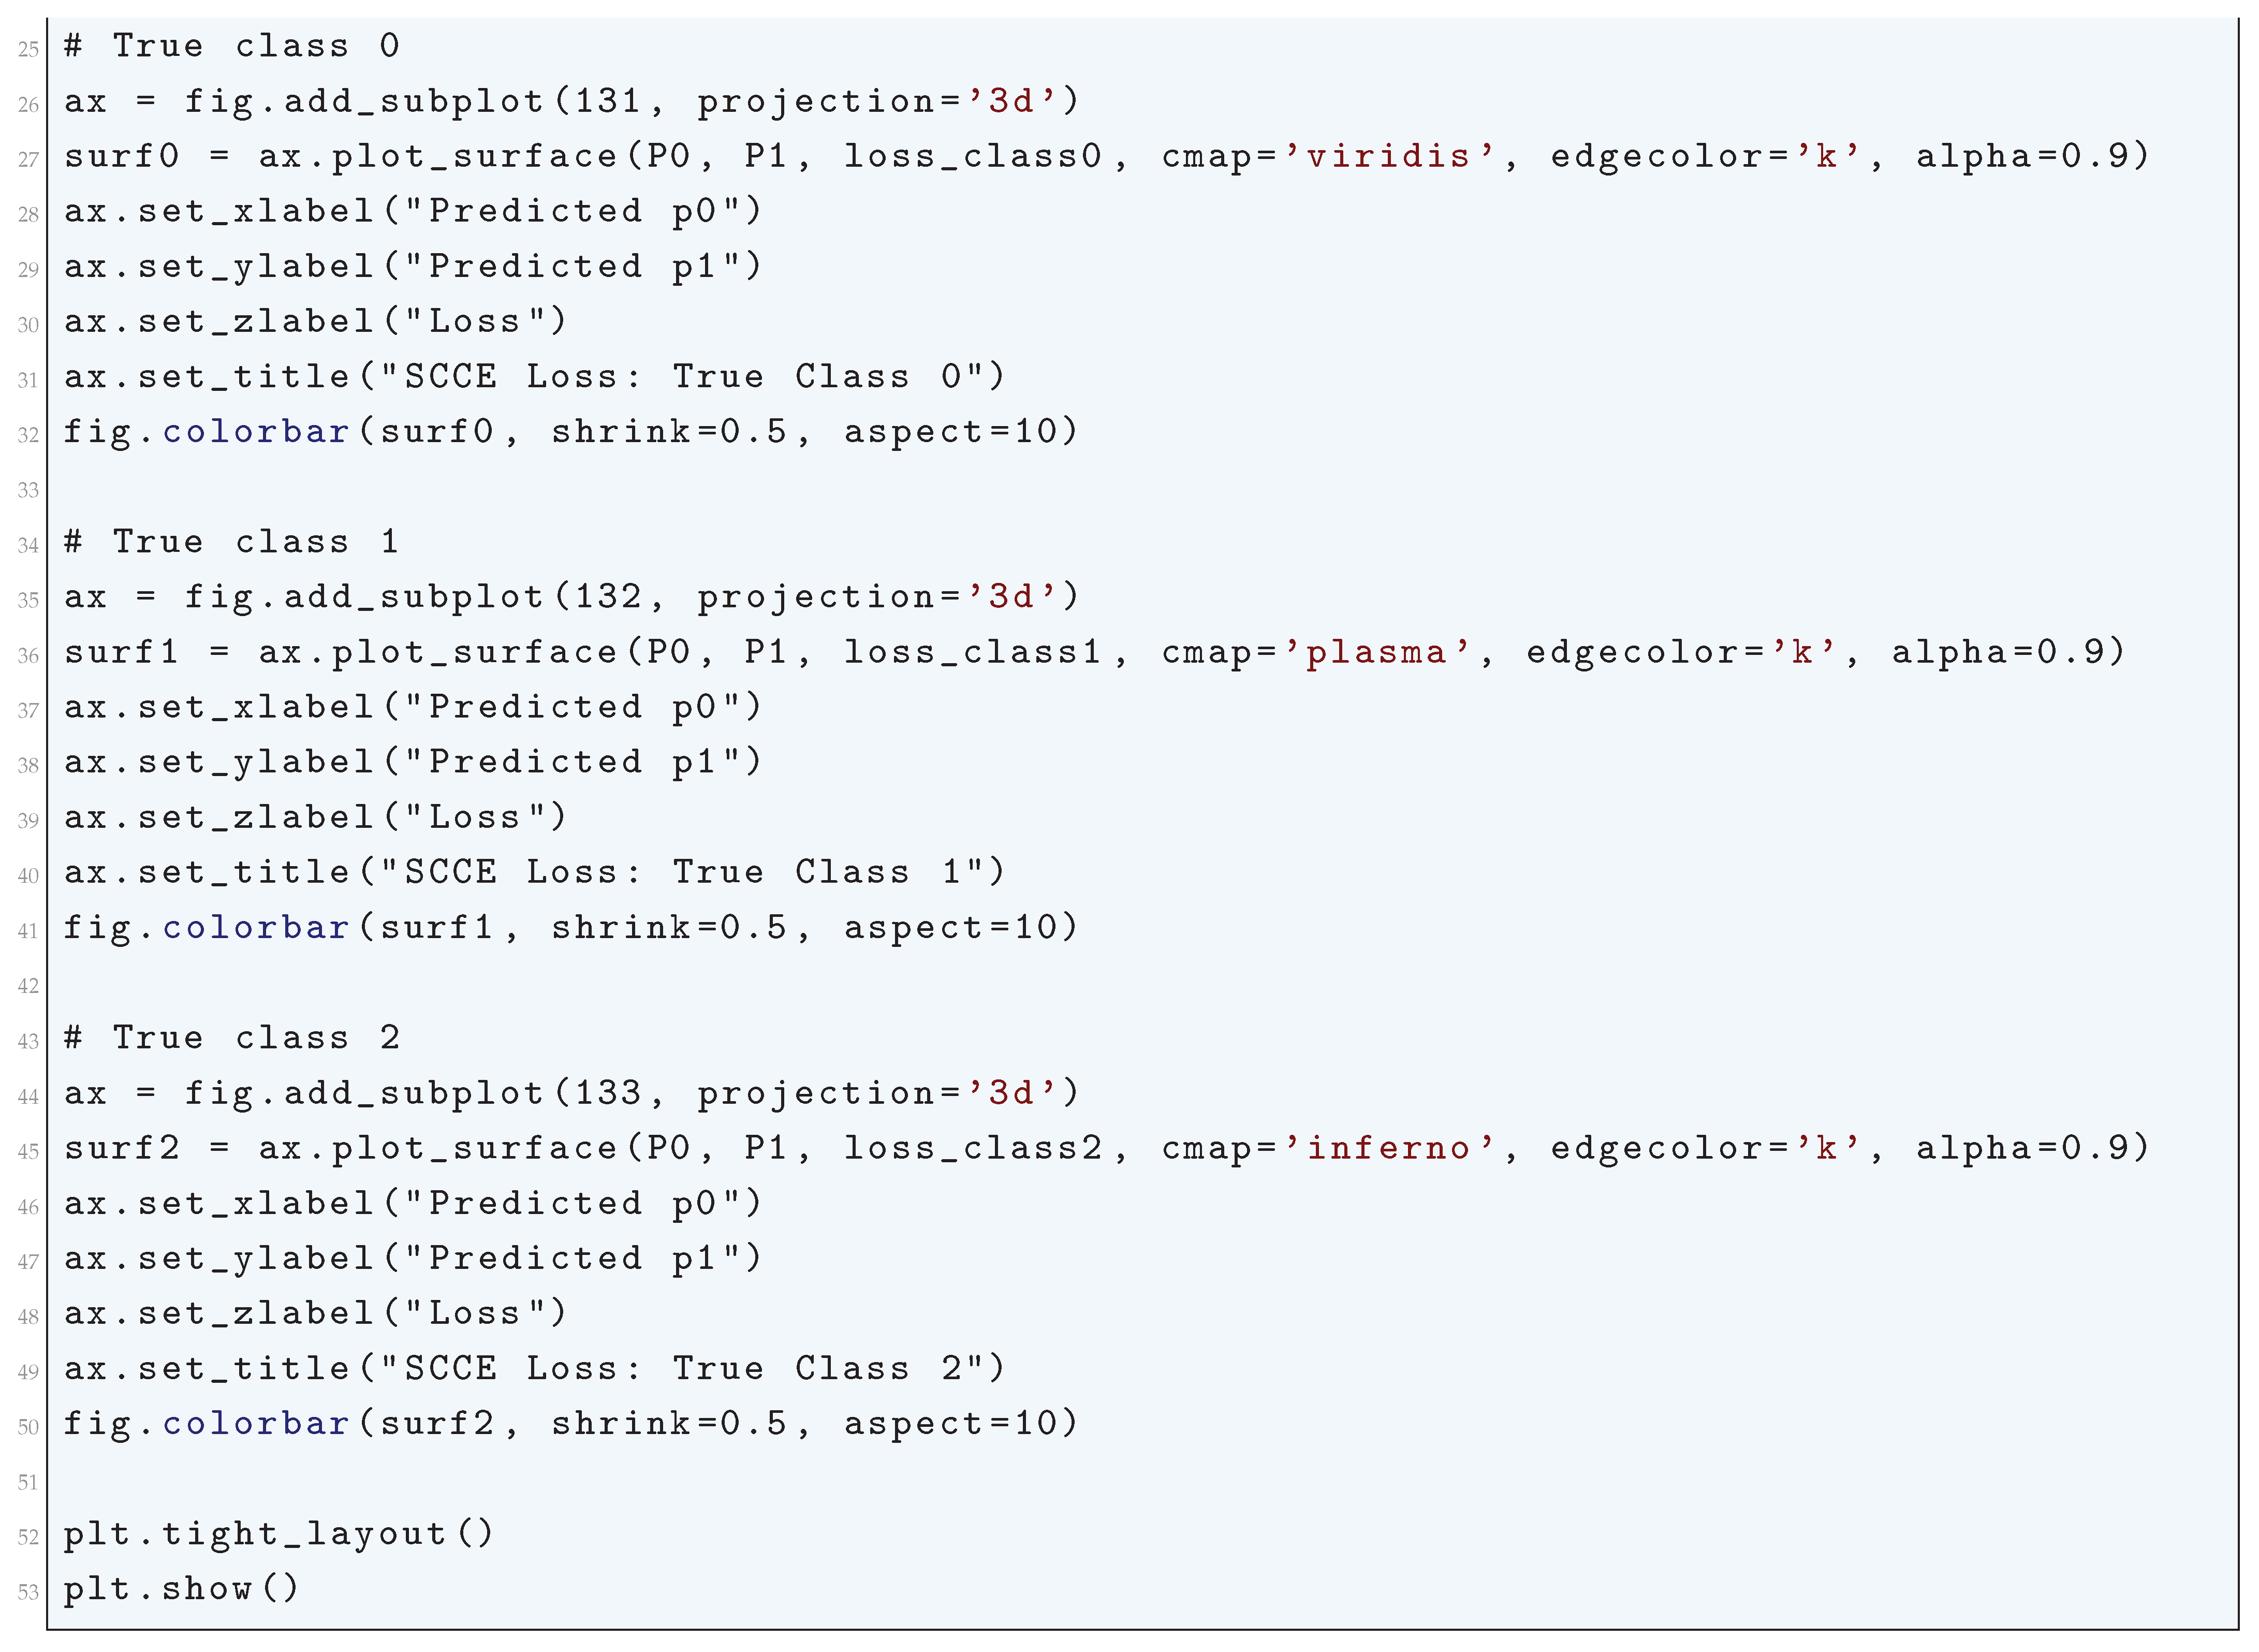
10.5.2.11 Python Code to Generate Figure 75 Illustrating KL Divergence
The Python code below produces the Figure 75 illustrating KL Divergence.
Figure 75.
Plot of KL Divergence
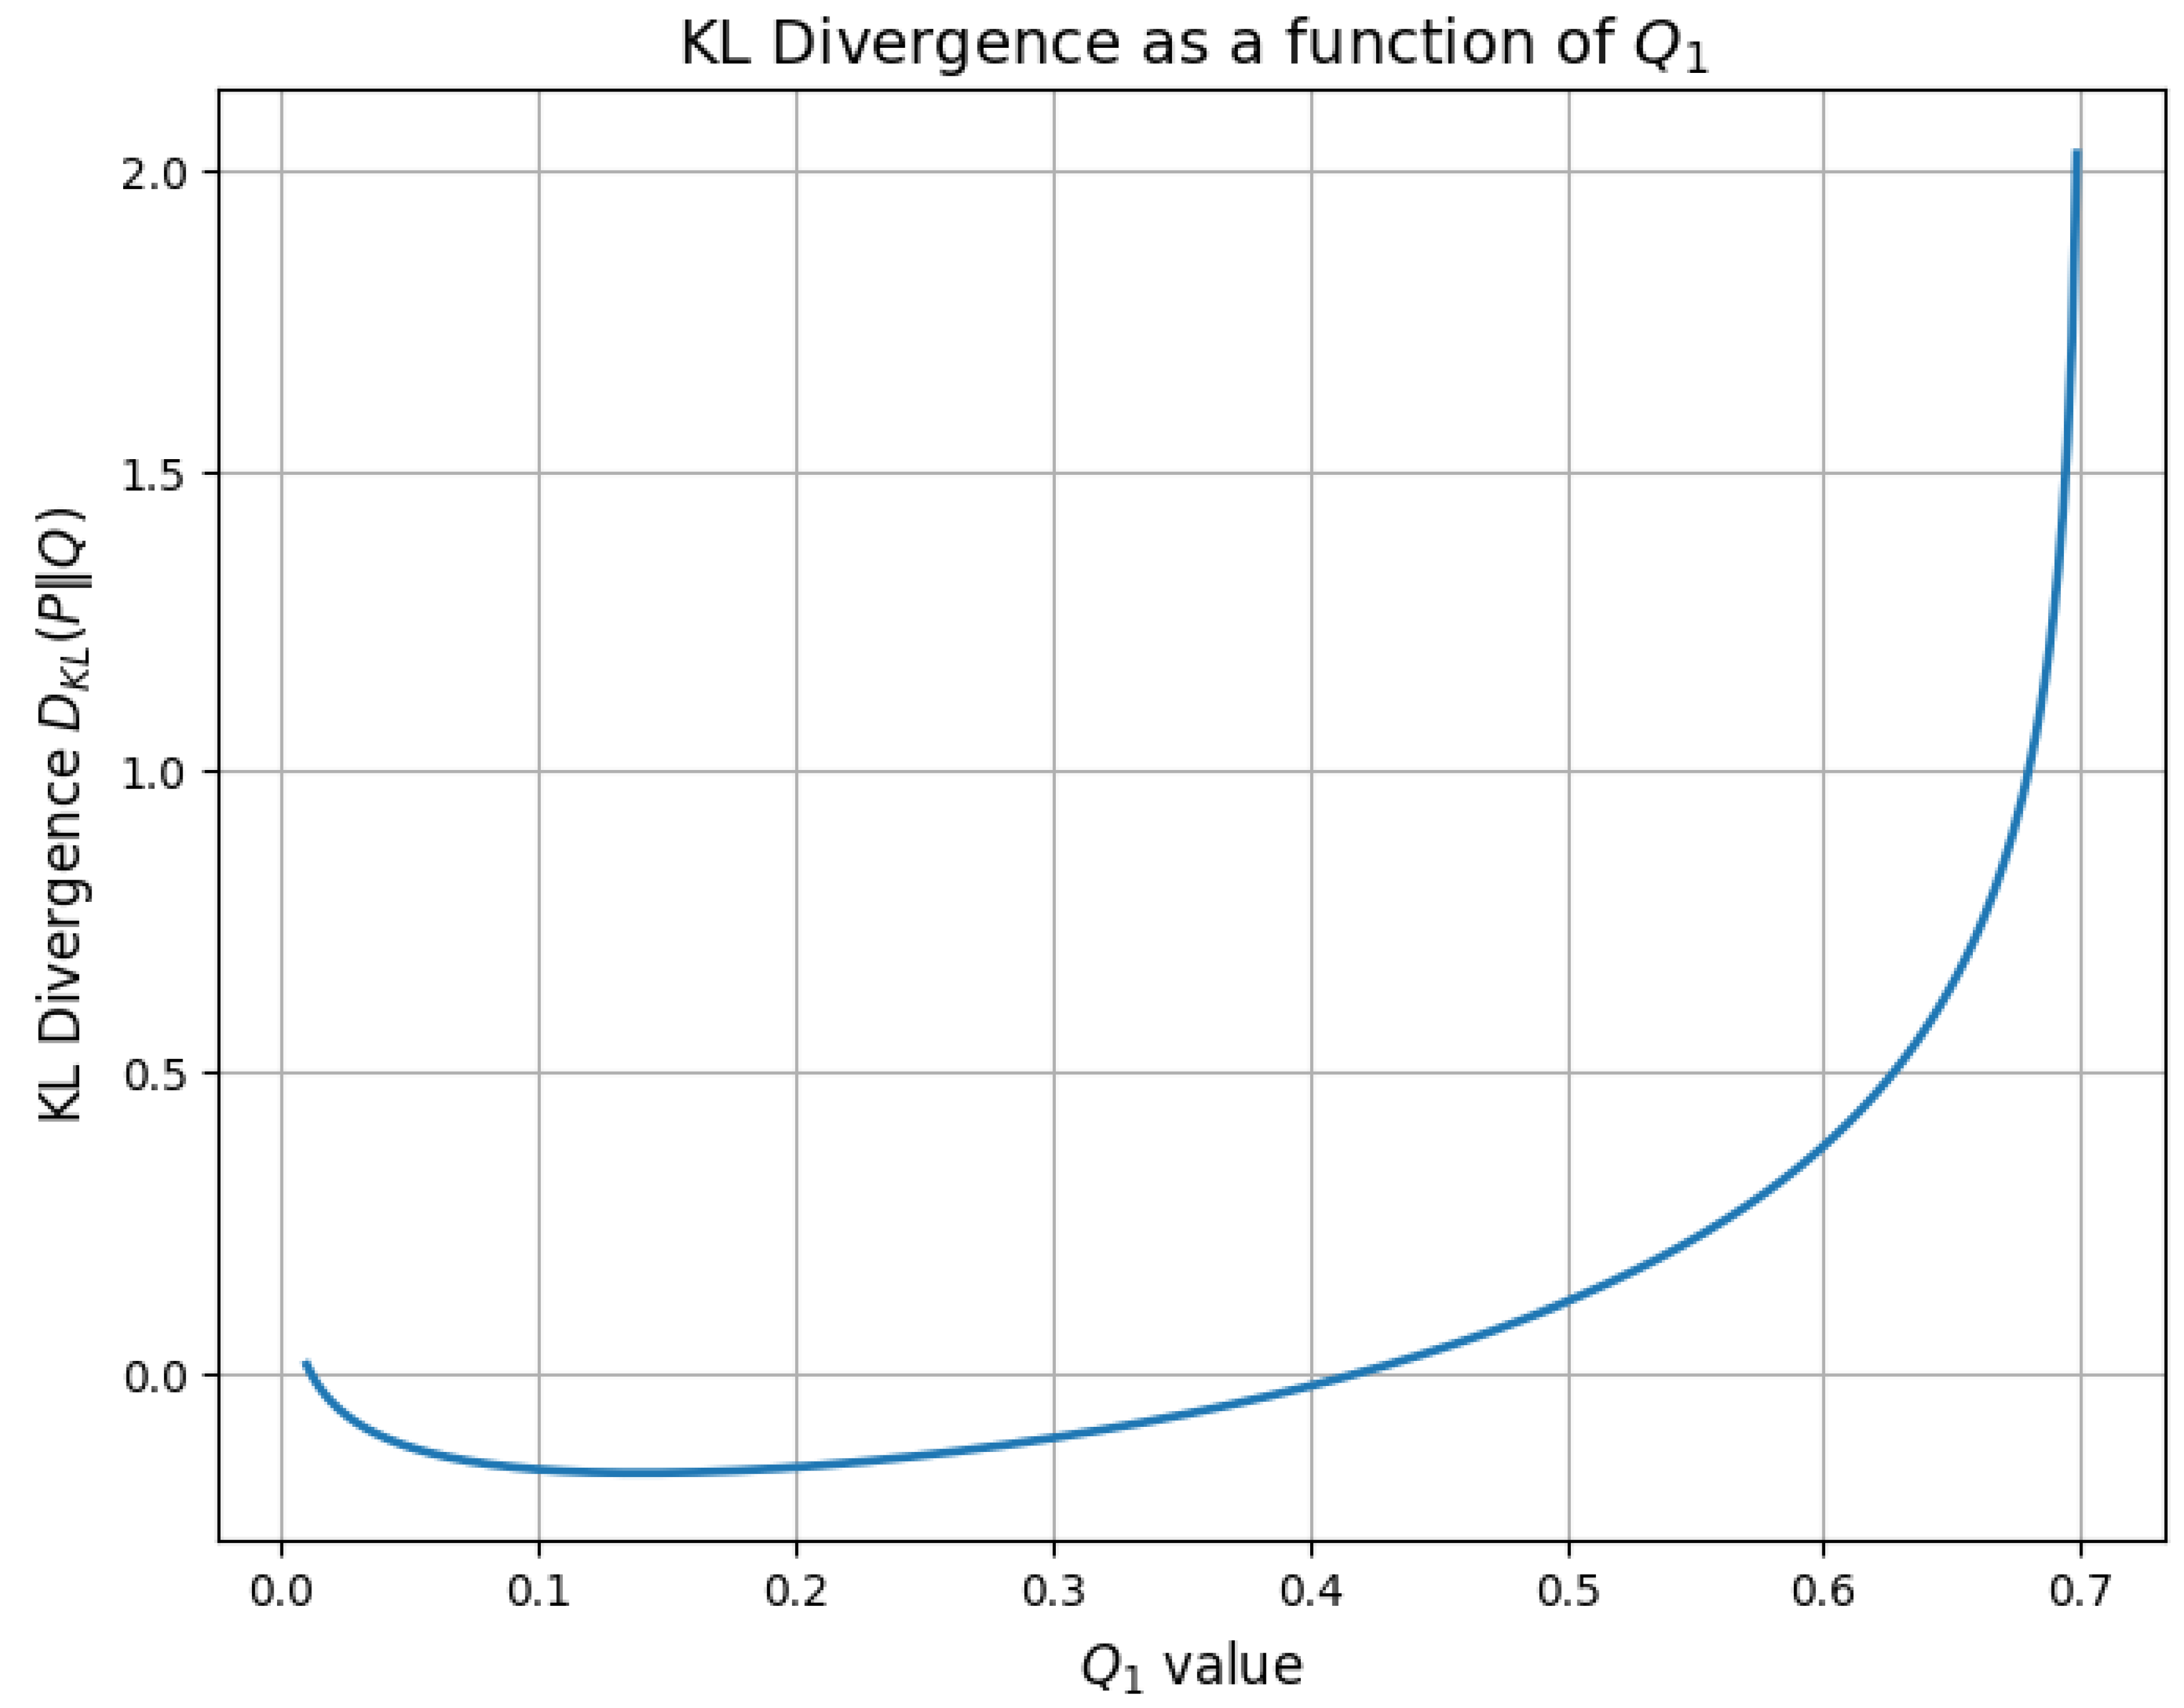
10.5.2.12 Python Code to Generate Figure 76 Illustrating 2D Surface Plot of KL Divergence
The Python code below produces the Figure 76 illustrating 2D Surface Plot of KL Divergence.
Figure 76.
2D Surface Plot of KL Divergence
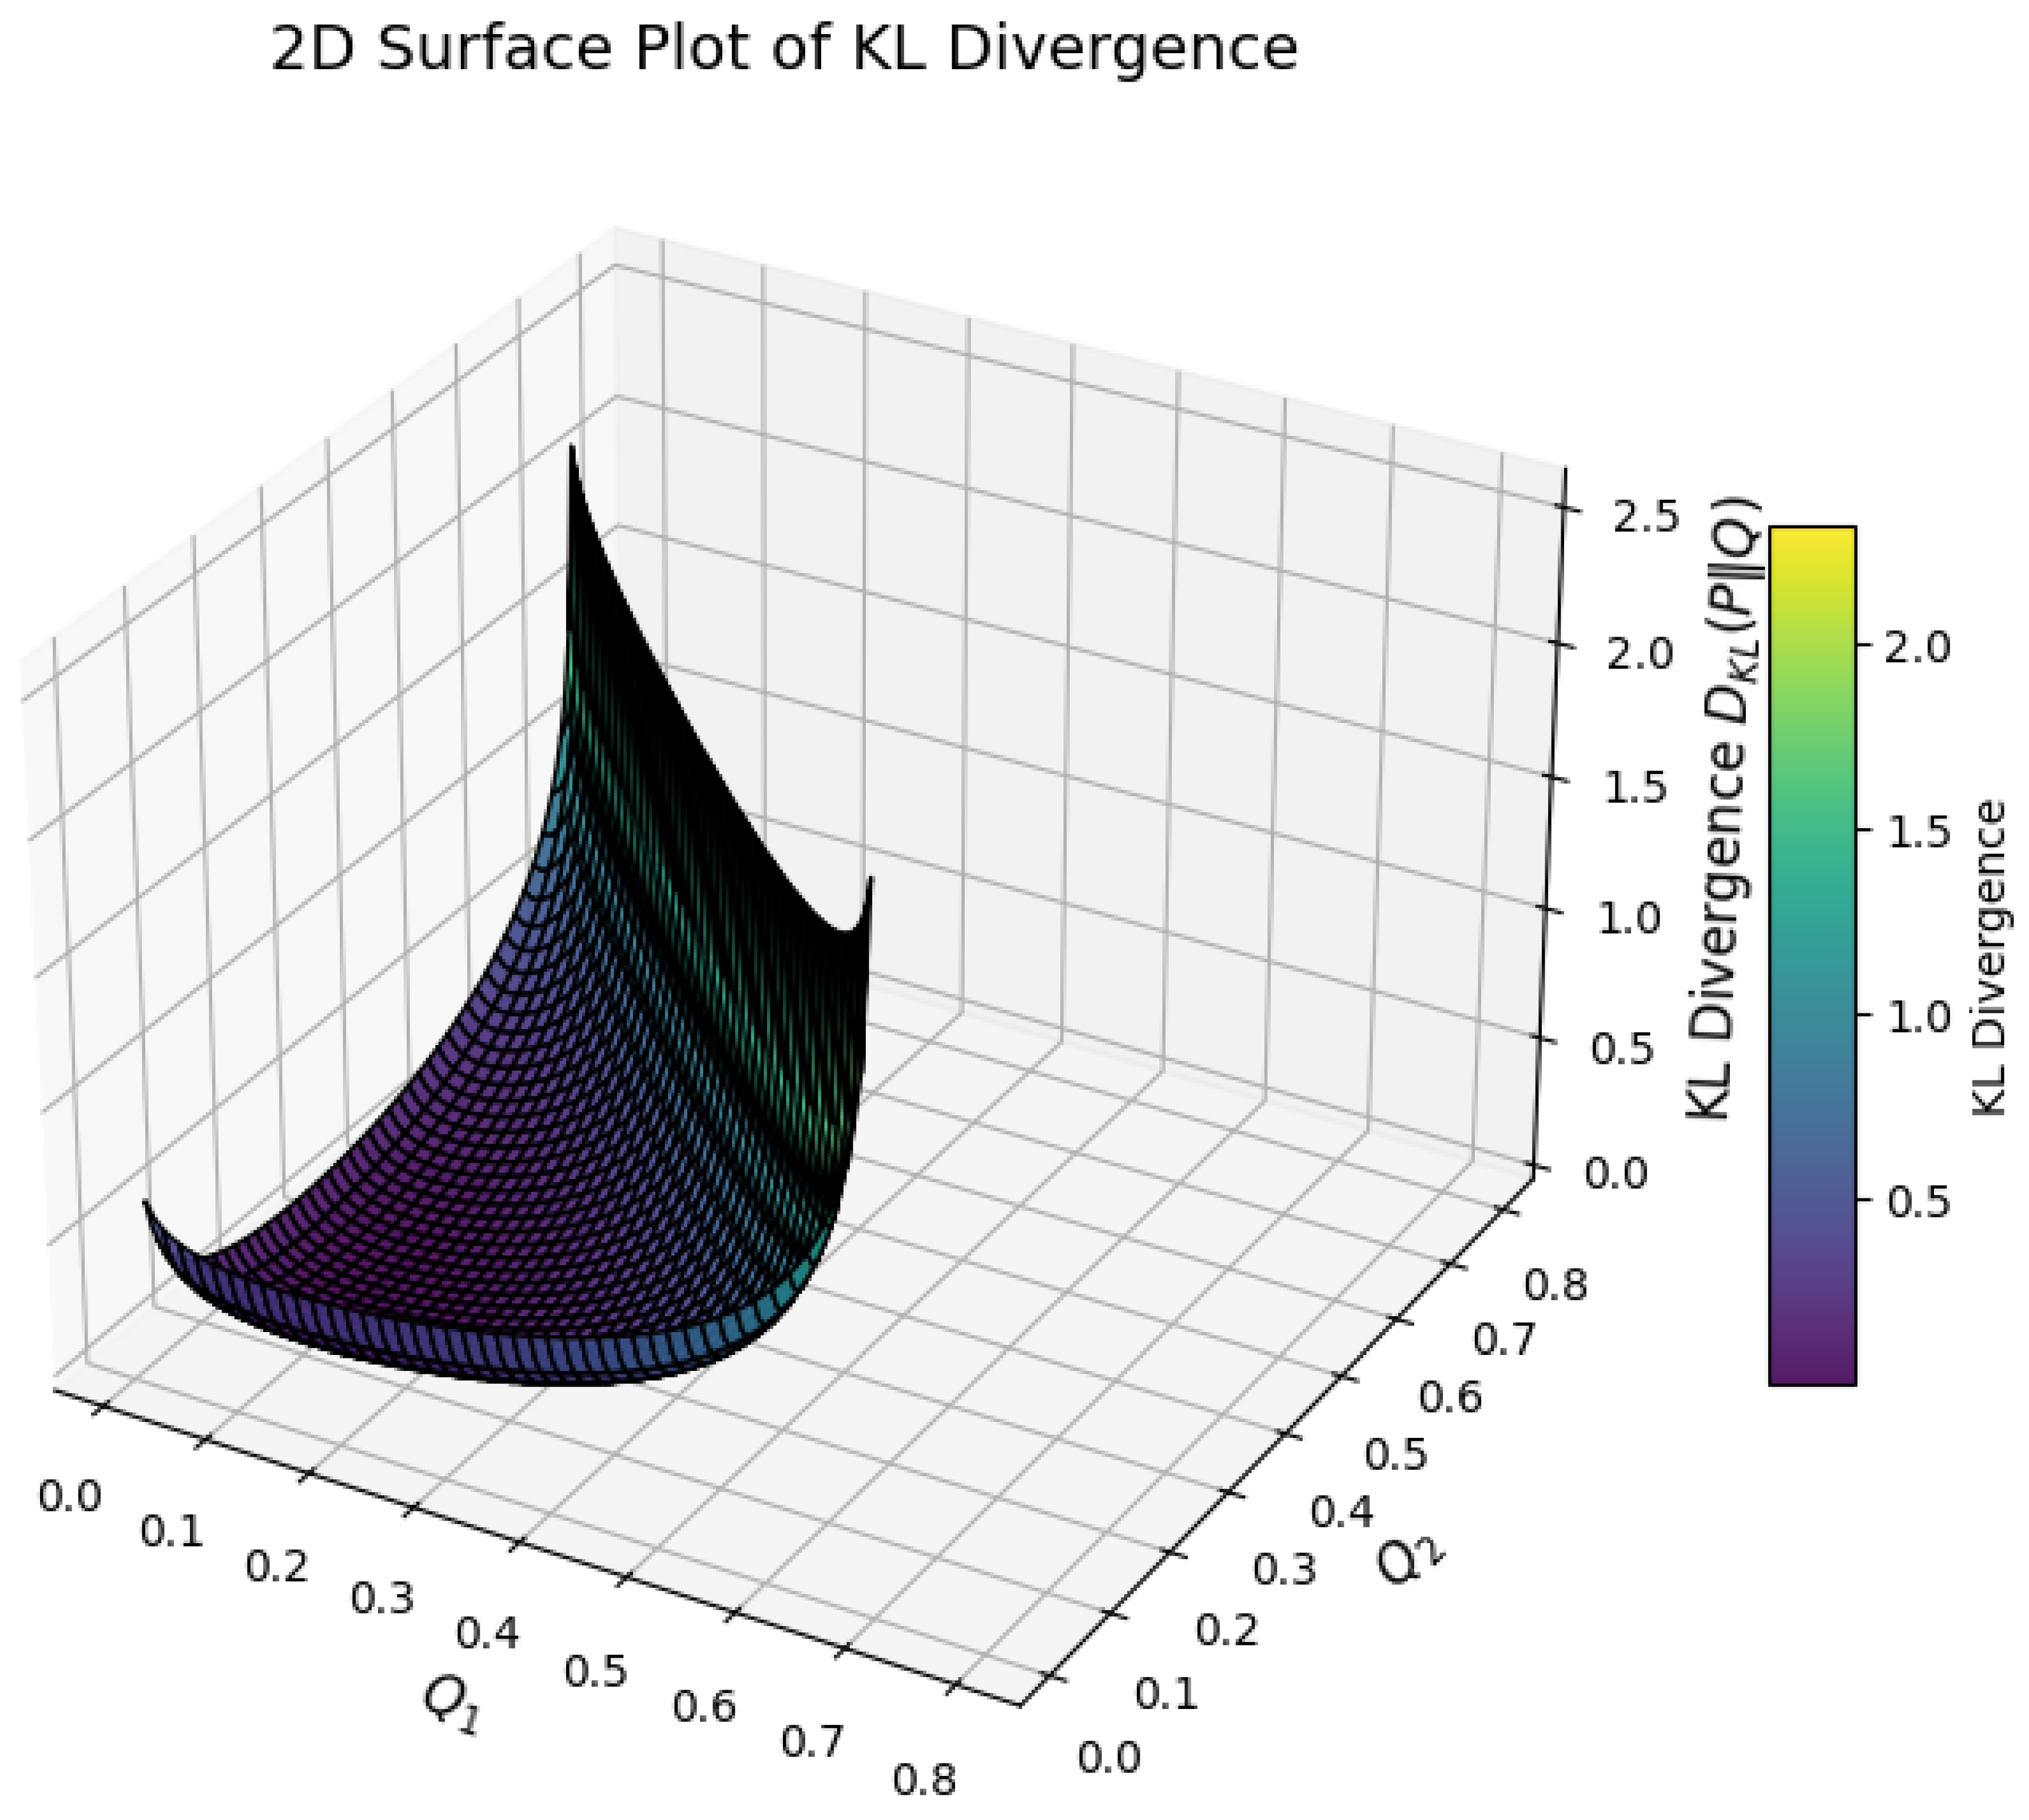
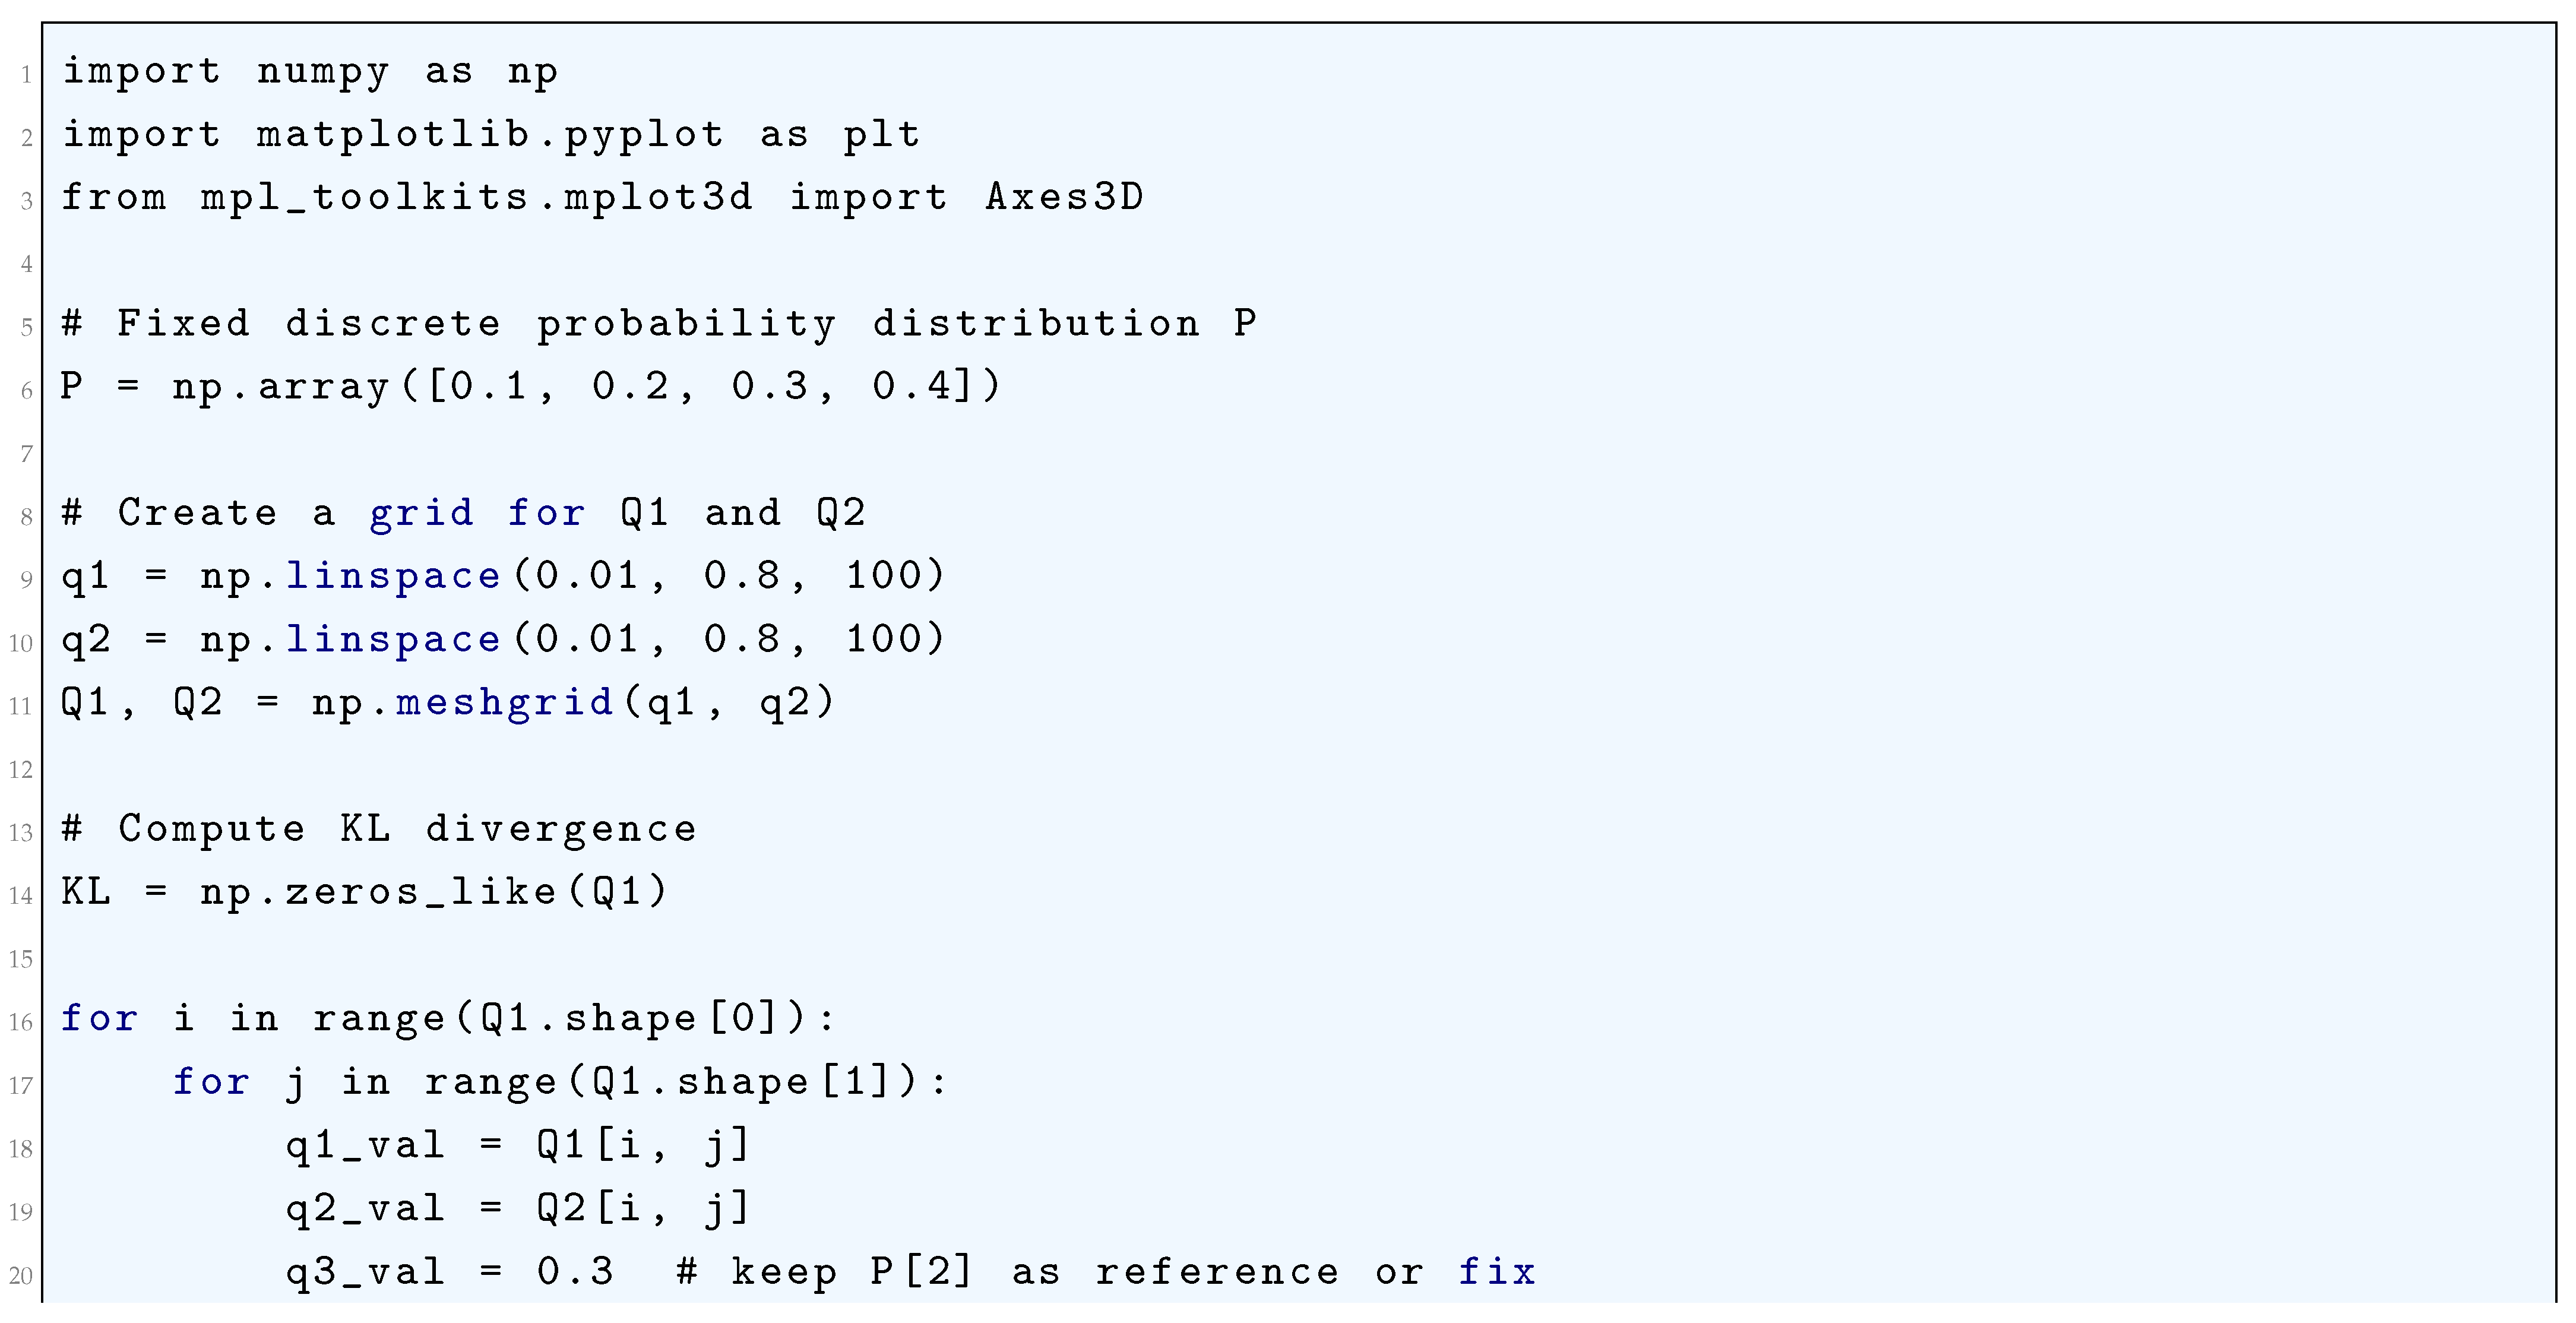
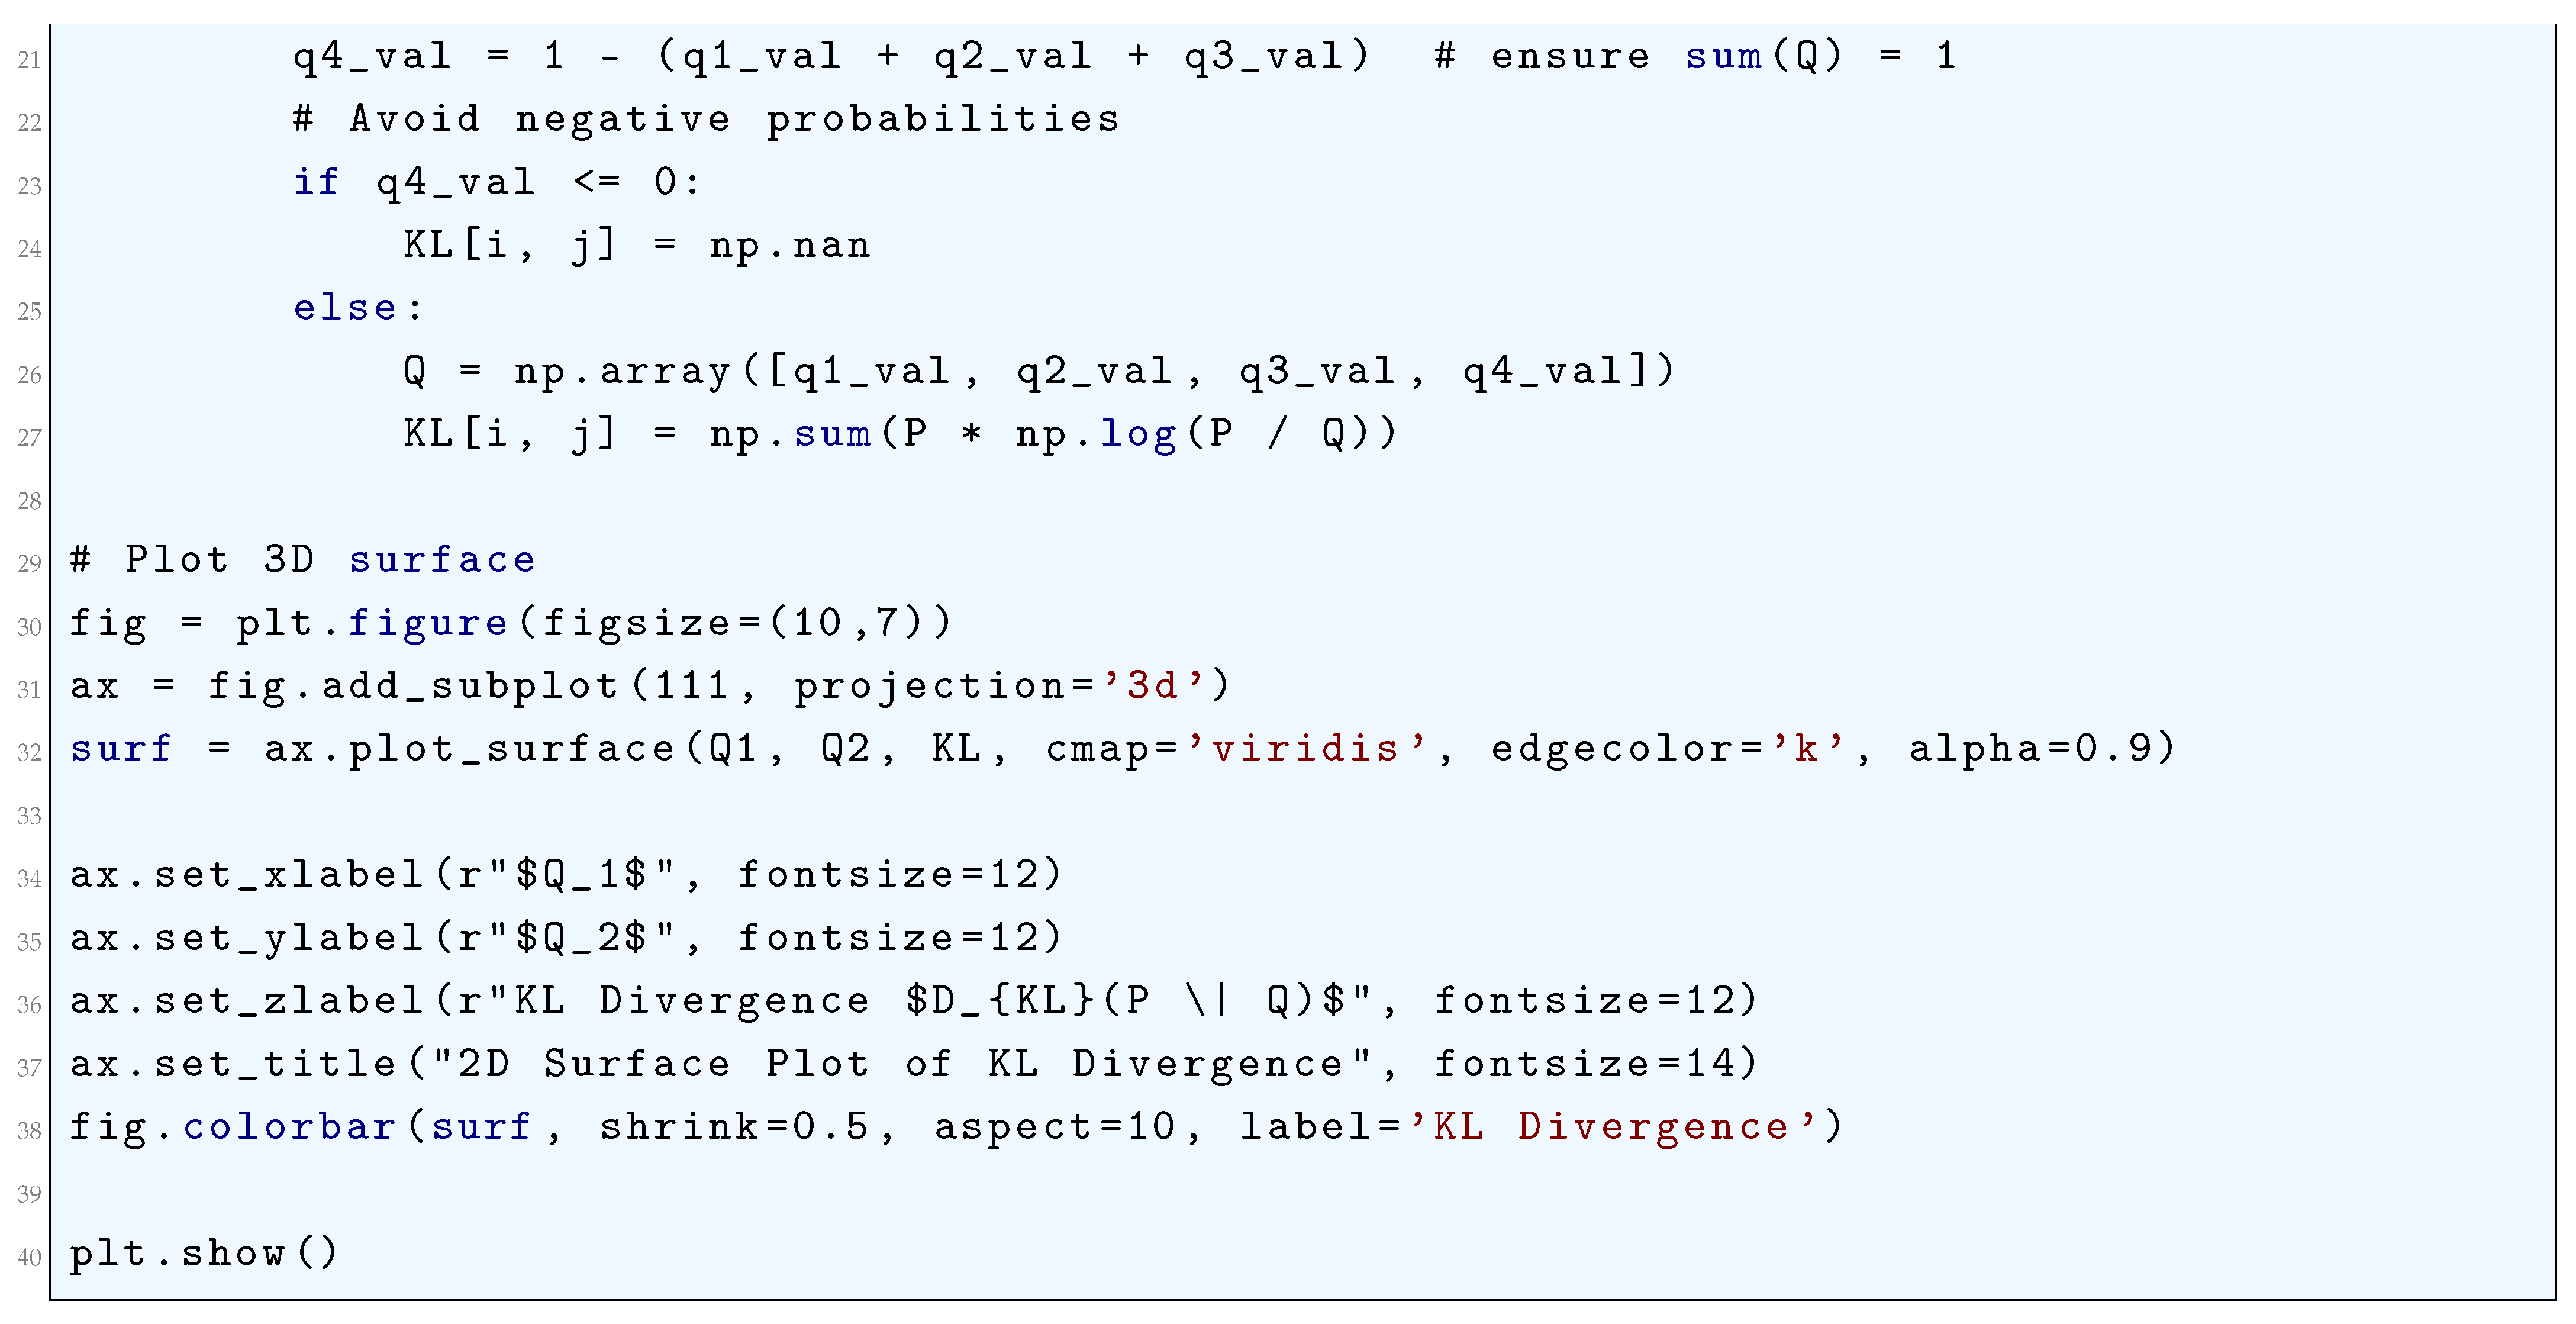
10.5.3. Advanced and Specialized Loss Functions
10.5.3.1 Loss Functions for Generative Adversarial Networks (GANs)
10.5.3.1.1 Wasserstein Loss (Earth Mover’s Distance)
The Wasserstein Loss, also known as the Earth Mover’s Distance (EMD) or Kantorovich-Rubinstein metric, is a fundamental function from optimal transport theory that provides a mathematically rigorous and continuous measure of the distance between two probability distributions. Unlike the Kullback-Leibler (KL) or Jensen-Shannon (JS) divergences, which can be undefined or exhibit vanishing gradients when the distributions have disjoint supports—a common scenario in the low-dimensional manifolds of high-dimensional data like images—the Wasserstein Distance is defined even for non-overlapping distributions and yields a smooth, meaningful gradient that is essential for stable optimization in deep learning, particularly in Generative Adversarial Networks (GANs). For two probability distributions (real data) and (generated data) defined on a metric space , the p-th Wasserstein distance is defined as the minimum cost of transporting mass from to , where the cost is taken to be the p-th power of the distance. For , which is most common in machine learning, it is given by:
Here, denotes the set of all joint distributions whose marginal distributions are and , i.e.,
and
This primal formulation directly captures the intuition of finding the most efficient transport plan that moves the probability mass from to , with the cost proportional to the distance .
Computing the infimum over all possible couplings is intractable for high-dimensional problems. However, a transformative result from duality theory, the Kantorovich-Rubinstein duality, provides a computationally feasible equivalent formulation. The duality states that:
where the supremum is taken over all 1-Lipschitz functions , meaning functions that satisfy
for all . This dual form is the foundation of the Wasserstein Loss in Wasserstein GANs (WGANs). Instead of minimizing the distance directly, one maximizes the difference in expectations between the real and generated data over a family of Lipschitz-constrained functions, represented by a critic network with parameters w. The training objective becomes a minimax game:
where is the generator mapping noise z to data space. The critic is trained to maximize this expression, effectively estimating the Wasserstein distance, while the generator is trained to minimize it by making the generated distribution indistinguishable from under the critic’s assessment.
The critical mathematical detail is the enforcement of the 1-Lipschitz constraint on the critic function . Without this constraint, the maximization could diverge to infinity, rendering the loss meaningless. Several techniques exist to enforce this constraint approximately. The original WGAN paper proposed weight clipping, constraining the weights w of the critic to a compact space , which ensures the network is K-Lipschitz for some K but can lead to pathological behavior like capacity underuse or gradient vanishing. A more effective and widely adopted method is the Gradient Penalty (WGAN-GP), which adds a regularization term to the loss that directly enforces the Lipschitz constraint on the interpolated data points. The WGAN-GP loss for the critic is:
where is a random point sampled along straight lines between points from and , i.e.,
with , , . This term penalizes the gradient norm of the critic at these points, deviating from 1, thus encouraging it to be 1-Lipschitz. The generator’s loss remains
The differentiability and continuity of the Wasserstein Loss under this formulation provide stable, linear gradients that do not saturate, even when the critic is optimal, solving the key training instability problems of traditional GANs that use JS divergence. The value of the Wasserstein Loss itself also correlates well with the perceived quality of the generated samples, making it a useful diagnostic metric during training.
10.5.3.1.2 Least Squares GAN (LSGAN) Loss
The Least Squares Generative Adversarial Network (LSGAN) loss function is a modification of the standard Generative Adversarial Network (GAN) objective that replaces the binary cross-entropy loss with a least squares term, fundamentally altering the properties of the optimization landscape to improve training stability and mitigate the vanishing gradients problem inherent in the original formulation. The core theoretical motivation stems from the observation that minimizing the Pearson divergence between the model distribution and the data distribution can be achieved through a least squares cost function, which provides smoother and more non-vanishing gradients, especially when updating the generator on samples that are on the correct side of the decision boundary but are still far from the real data manifold. In the standard GAN framework, the discriminator D (often called the critic in this context) is trained to output a probability that a sample is real, using the sigmoid activation and binary cross-entropy loss. LSGAN re-frames this: the discriminator D is now a function that assigns a real-valued score to inputs, and its objectives for real and fake data are defined by the least squares error. Specifically, for a real sample , the desired discriminator output is a, and for a generated sample where , the desired output is b, with a and b being hyperparameters typically set to . The loss functions for the discriminator D and generator G are thus formulated as:
Here, c is another hyperparameter denoting the value that the generator wants the discriminator to believe for its generated samples; a common choice is , meaning the generator aims to make its samples indistinguishable from real data by pushing their discriminator scores towards 1. The choice of these targets a, b, and c is not arbitrary; it has a theoretical basis in minimizing a specific f-divergence. The objective for the discriminator is to minimize the squared error of its predictions relative to the target labels a (real) and b (fake), effectively performing regression rather than classification. This formulation ensures that even if a generated sample is correctly classified as fake (i.e., is close to b), it still incurs a significant loss if it is far from the decision boundary, providing a strong gradient signal to the generator to improve. Conversely, in the standard GAN, a generated sample that is confidently wrong (far on the wrong side of the decision boundary) results in a saturated sigmoid and a vanishingly small gradient.
The mathematical optimality of the LSGAN can be analyzed by solving for the optimal discriminator for a fixed generator G. For any given generator, the discriminator objective is to minimize the expected squared error. Assuming the densities for real data and for generated data exist, the objective can be written as an integral over the input space:
To find the function D that minimizes this, we take the functional derivative with respect to and set it to zero:
Solving for yields the optimal discriminator:
Substituting this optimal discriminator back into the generator’s objective function reveals the quantity that the generator is ultimately minimizing. With c as the generator’s target, the generator loss becomes:
By plugging in the expression for , this loss can be shown to be proportional to the Pearson divergence between and , plus a constant, for specific choices of a, b, and c. The most common setting leads to the generator minimizing
This divergence is smoother and better behaved than the Jensen-Shannon divergence targeted by the original GAN, leading to more stable training dynamics. The gradients for the generator are given by
Since is a linear term, it does not saturate, ensuring that the generator receives a usable gradient as long as the discriminator provides a meaningful score , which it does due to the regression task. This property is the primary advantage of LSGAN: it avoids the vanishing gradient problem that plagues standard GANs when the discriminator becomes too confident, thereby facilitating more reliable convergence and often producing higher quality generated samples.
10.5.3.1.3 Adversarial Loss (Standard GAN Loss)
The Adversarial Loss, as formulated in the original Generative Adversarial Network (GAN) framework, establishes a two-player minimax game between a generator network G and a discriminator network D, where the solution is a Nash equilibrium. The generator G maps samples from a prior noise distribution (typically a multivariate Gaussian or uniform distribution) to the data space, synthesizing samples intended to resemble real data. The discriminator D is a binary classifier that outputs a probability that a given input x originates from the real data distribution rather than the generator’s distribution . The objective function for this game is given by the value function :
This formulation derives from the principle of binary cross-entropy minimization. For a fixed generator G, the optimal discriminator is the function that maximizes this expression for every x. The argument inside the expectation for the discriminator is
To find the maximizing for a fixed x, we take the functional derivative with respect to and set it to zero, yielding the condition:
Solving this equation provides the optimal discriminator for a fixed generator:
Substituting this optimal discriminator back into the value function reveals the global loss function that the generator is ultimately minimizing:
This expression can be rewritten in terms of the Kullback-Leibler (KL) divergence and the Jensen-Shannon (JS) divergence. Specifically, it equals:
where the Jensen-Shannon divergence is defined as
with
Thus, the global minimum of the generator’s loss is achieved if and only if , at which point for all x, and .
The training process involves alternating gradient-based updates for D and G. The discriminator update maximizes by ascending its stochastic gradient:
where is a minibatch from the real data and is a minibatch from the noise prior. The generator update minimizes by descending its stochastic gradient. However, in early training, when is close to zero, the gradient of vanishes, providing no learning signal. To circumvent this, practitioners often maximize
instead of minimizing
which provides stronger gradients early on, though it changes the theoretical interpretation. The gradient for this modified generator objective is:
Despite the theoretical guarantee of convergence to the true data distribution, the training of standard GANs is notoriously unstable due to several factors: the simultaneous gradient descent on a non-convex game often leads to oscillatory behavior rather than convergence to the Nash equilibrium; the supports of and may be disjoint in high-dimensional spaces, causing the JS divergence to be constant and gradients to be zero; and mode collapse can occur, where the generator maps multiple noise inputs to the same output, failing to capture the full diversity of the data distribution. The adversarial loss thus represents a foundational but practically challenging objective that has spurred numerous variants designed to stabilize training and improve performance.
10.5.3.2 Loss Functions for Siamese and Metric Learning
10.5.3.2.1 Contrastive Loss
Contrastive Loss is a distance-based loss function fundamental to metric learning and siamese network architectures, designed to learn an embedding space where similar data pairs are projected closer together while dissimilar pairs are pushed apart by a margin.
The core objective is to train a parameterized embedding function that maps input samples into a low-dimensional manifold where the Euclidean distance
directly reflects semantic similarity. For a training pair of samples , a label Y is defined where if the pair is similar (positive pair) and if dissimilar (negative pair). The loss function for a single pair is formulated as:
Here, is a hyperparameter defining the margin—the minimum distance that dissimilar pairs should maintain. The first term, , applies to positive pairs and minimizes the squared Euclidean distance between their embeddings, directly pulling them together. The second term applies to negative pairs and is active only when their distance is less than the margin m; it penalizes the pair by the squared difference between the margin and their current distance, effectively pushing them apart until their separation is at least m. This loss function encourages the embedding function to create a structured space where intra-class variance is minimized and inter-class variance is maximized, with the margin providing a buffer zone to prevent excessive contraction of the entire dataset into a single point.
The mathematical properties of Contrastive Loss reveal its optimization dynamics. The gradient with respect to the embedding vectors drives the learning process. For a positive pair , the gradient of the loss with respect to the distance d is , which is linear and pulls the embeddings together with a force proportional to their current separation. For a negative pair where , the gradient is
which pushes the embeddings apart with a force that diminishes as the distance approaches the margin. If for a negative pair, the loss is zero and no gradient is produced.
The gradients with respect to the embeddings themselves are derived through the chain rule. For a positive pair, the gradient for an embedding vector is:
For a negative pair with , the gradient is:
These gradients show that the update magnitude for positive pairs is linear in the distance, while for negative pairs it is sublinear, scaling with . This structure helps prevent catastrophic collapse where all embeddings converge to zero, as the repulsive force for negative pairs counteracts the attractive force for positive pairs. The margin m is critical; it defines the scale of the embedding space and prevents the loss from becoming trivial (e.g., all distances shrinking to zero).
The overall loss for a minibatch is typically the average over all pairs. In practice, forming pairs can lead to quadratic complexity, but mining hard negatives—focusing on negative pairs that are currently too close—can improve efficiency and performance. Contrastive Loss is a foundational objective that has been extended in numerous ways, such as in triplet loss and modern self-supervised methods like SimCLR, but its core principle of contrasting similar and dissimilar pairs remains a pillar of representation learning.
10.5.3.2.2 Triplet Loss
Triplet Loss is a metric learning objective designed to learn an embedding function that projects input data into a Euclidean space where semantically similar points are clustered and dissimilar points are separated by a distance proportional to their semantic difference.
It operates on triplets of samples: an anchor sample , a positive sample (semantically similar to the anchor, e.g., same class), and a negative sample (semantically dissimilar to the anchor, e.g., different class). The fundamental aim is to ensure that the distance between the anchor and positive is less than the distance between the anchor and negative by at least a predefined margin . Mathematically, this constraint is expressed as
and the loss for a single triplet is defined as the amount by which this inequality is violated:
This is a hinge-like loss that is zero if the embedding function successfully pushes the negative pair beyond the margin relative to the positive pair, and positive otherwise, providing a gradient to correct the embedding. The margin m acts as a hyperparameter controlling the minimum desired separation between positive and negative pairs, preventing the trivial solution where all embeddings collapse to a single point and enforcing a meaningful topology in the latent space.
The optimization dynamics of Triplet Loss are governed by the gradients with respect to the embedding vectors. Let
and
denote the Euclidean distances for the positive and negative pairs, respectively. The loss is active only when
In this case, the gradients are computed as follows. The gradient with respect to the anchor embedding is:
The gradient with respect to the positive embedding is:
The gradient with respect to the negative embedding is:
These gradients reveal that, when active, the loss pulls the anchor and positive together while pushing the anchor and negative apart. The update magnitudes are proportional to the current distances, providing a self-stabilizing effect: large violations yield large gradients, while small violations yield fine adjustments. The overall loss for a dataset is the average over all valid triplets, but sampling all possible triplets is computationally prohibitive.
Thus, hard negative mining is critical: selecting triplets where the negative is currently closer to the anchor than the positive i.e.
or semi-hard negatives where
but the loss is still positive. This focuses learning on the most informative triplets that violate the margin constraint, improving efficiency and convergence. The success of Triplet Loss hinges on the careful balance between attractive and repulsive forces, and it has been foundational for tasks like face recognition and image retrieval, where learning a discriminative embedding is paramount.
10.5.3.2.3 Center Loss
Center Loss is a supervised learning objective function designed to enhance the discriminative power of learned features by simultaneously promoting inter-class dispersion and intra-class compactness in the feature space of a deep neural network. It operates alongside a traditional softmax cross-entropy loss, which primarily encourages features to be separable by maximizing the decision boundary between different classes but does not explicitly enforce features of the same class to form tight, distinct clusters. The Center Loss addresses this by introducing a penalty term that pulls the deep features of each sample toward the center of its corresponding class, thereby reducing the intra-class variations that can impede robust classification, especially under challenging conditions like pose changes or illumination variations in face recognition.
Mathematically, for a training dataset with N samples and C classes, let be the deep feature of the i-th sample belonging to class . The Center Loss maintains a learnable center vector for each class, which is updated iteratively during training to represent the mean feature of that class. The Center Loss term for a single sample is defined as the squared Euclidean distance between the feature vector and its corresponding class center :
The complete loss function is then a weighted combination of the softmax cross-entropy loss and the Center Loss :
where is a hyperparameter that balances the two loss components, and are the weight vector and bias for class j in the final fully connected layer, and the softmax loss ensures inter-class separability.
The optimization of Center Loss involves updating both the network parameters and the class centers through backpropagation. The gradients of the total loss L with respect to the feature vector and the center are critical for training. The gradient of L with respect to is:
where is the gradient from the softmax loss, which pushes features toward the decision boundary of their class, while the Center Loss gradient pulls features toward their class center. The centers are updated based on the features of all samples in the batch belonging to class j, but to avoid large perturbations caused by misclassified samples, the update uses a scaling factor and is computed as:
where is the indicator function, and the centers are updated via
This update gradually moves each center toward the mean of its class features without being overly sensitive to mini-batch noise.
The interplay between the softmax loss and Center Loss ensures that features not only are separable but also exhibit small intra-class variance, leading to a more robust and generalized feature representation. The hyperparameter controls the trade-off: too small a weakens the intra-class compactness effect, while too large a may overwhelm the softmax loss, causing features to collapse into their centers and degrading classification performance. Center Loss has proven effective in tasks requiring high discriminative feature learning, such as face verification and fine-grained recognition, by producing features that are both highly discriminative and invariant to intra-class variations.
10.5.3.3 Loss Functions for Style Transfer and Super-Resolution
10.5.3.3.1 Perceptual Loss
Perceptual Loss is a feature-based loss function that quantifies the discrepancy between two images not in raw pixel space but in a high-dimensional feature space extracted by a pre-trained deep convolutional neural network (typically a VGG network trained on ImageNet), thereby measuring perceptual similarity rather than strict pixel-to-pixel correspondence.
This approach is grounded in the hypothesis that features learned by a network trained for a high-level task (e.g., image classification) encode semantic and perceptual information that is more aligned with human visual perception than low-level pixel errors. Given a target image y and a generated image , let denote the feature map activations from the j-th layer of a pre-trained network when processing an image x. The Perceptual Loss between y and is defined as the Euclidean distance between their feature representations at one or more layers:
where , , and are the number of channels, height, and width of the feature map at layer j, and the normalization by the spatial dimensions ensures the loss is scale-invariant across layers. By leveraging hierarchical features from multiple layers (e.g., ReLU layers from VGG-16), the loss captures both high-level semantic content (from deeper layers) and finer texture details (from shallower layers), enabling the generation of images that are perceptually realistic even if they exhibit slight geometric or photometric deviations from the target.
The mathematical rigor of Perceptual Loss arises from its interpretation as a metric in the feature manifold of a pre-trained network. The feature extractor serves as a non-linear mapping from the image space to a feature space , where distances correlate with perceptual differences. The loss assumes that has learned a sufficiently rich and disentangled representation where semantically similar images are mapped to nearby points. The gradient of the loss with respect to the generated image is computed through the pre-trained network:
where is the Jacobian of the feature map at . Since is pre-trained and fixed, these gradients guide the optimization process to adjust in directions that minimize feature-space distance, effectively transferring perceptual attributes from y to . This is particularly useful for tasks like style transfer, super-resolution, and image synthesis, where maintaining perceptual fidelity is more critical than pixel-level accuracy. However, the loss depends heavily on the choice of network and the layers j; deeper layers emphasize semantic content, while shallower layers capture spatial details. Variants of Perceptual Loss, such as using the LPIPS (Learned Perceptual Image Patch Similarity) metric, further improve by learning the feature space distance from human judgments, but the core principle remains: leveraging deep features as a perceptual metric for image comparison.
10.5.3.3.2 Style Loss
Style Loss is a specialized function used primarily in neural style transfer to quantify the difference in stylistic appearance between two images by comparing the statistical properties of their feature representations, specifically the correlations between filter responses encoded by the Gram matrix of feature activations from a pre-trained deep convolutional network. Unlike perceptual loss, which focuses on content similarity by matching feature maps directly, style loss operates on the premise that the style of an image is captured by the inter-channel correlations within feature maps, which correspond to textures, patterns, and visual motifs independent of the spatial structure.
Given a feature map activation tensor extracted from layer j of a pre-trained network (e.g., VGG-19) for an image x, the Gram matrix is computed as the inner product between the vectorized feature maps across spatial dimensions, effectively measuring the covariance between channels:
where index feature channels. This matrix is symmetric and positive semi-definite, and its elements represent the degree to which features k and l co-occur spatially in the image. The style loss between a target style image and a generated image is then defined as the mean squared error between their Gram matrices across a set of layers :
where denotes the Frobenius norm, and the normalization by accounts for the number of elements in the Gram matrix. This loss encourages the generated image to exhibit similar texture statistics to the style image by matching the second-order moments of feature distributions, effectively transferring stylistic attributes such as brushstrokes, color palettes, and patterns without preserving the spatial content.
The mathematical foundation of style loss relies on the interpretation of the Gram matrix as an estimator of the feature distribution’s covariance structure. Minimizing the Frobenius norm between Gram matrices is equivalent to minimizing the Euclidean distance between the vectorized representations of the feature correlations, which aligns the stylistic properties of the generated image with those of the target style. The gradient of the style loss with respect to the generated image is computed through the chain rule:
where involves the Jacobian of the Gram matrix computation. This gradient updates to increase or decrease specific feature correlations, effectively synthesizing textures that mimic the style image. The choice of layers is critical: shallow layers capture low-level textures (e.g., edges, colors), while deeper layers encode higher-order style patterns (e.g., complex structures). In practice, style loss is combined with content loss (e.g., perceptual loss) and often a total variation regularization term to produce visually coherent stylized images. The efficacy of style loss stems from its ability to disentangle style from content by leveraging the statistical independence of feature correlations from spatial arrangements, making it a cornerstone of artistic style transfer and texture synthesis in computer vision.
10.5.3.3.3 Total Variation (TV) Loss
Total Variation (TV) Loss is a regularization term employed in image processing and inverse problems to impose spatial smoothness on an image by penalizing excessive and spurious variations in pixel intensities, thereby reducing noise and undesired high-frequency artifacts while preserving essential edges and structures.
It is grounded in the mathematical theory of functions of bounded variation, where the total variation of a function is defined as the integral of the absolute value of its gradient, capturing the total magnitude of oscillations and discontinuities. For a discrete 2D image with height H and width W, the anisotropic Total Variation Loss is commonly defined as the sum of the absolute differences between adjacent pixels along the horizontal and vertical directions:
This formulation measures the -norm of the discrete gradients, promoting sparsity in the image gradient domain and encouraging piecewise constant regions with sharp boundaries. An alternative isotropic Total Variation Loss combines the horizontal and vertical differences using the Euclidean norm at each pixel:
which more accurately approximates the continuous total variation but is computationally more intensive due to the square root operation. The primary effect of TV Loss is to suppress small fluctuations caused by noise or artifacts while preserving significant edges, as the -norm imposes a stronger penalty on small gradients than the -norm used in quadratic smoothness terms.
The mathematical properties of TV Loss arise from its convexity and non-differentiability at zero. The gradient of the anisotropic TV Loss with respect to the image x is straightforward but requires care at points of non-differentiability. For a single pixel , the partial derivative of is:
where the `sign` function is defined in the subgradient sense at zero (typically returning 0 for a zero difference). This gradient effectively acts as a diffusion term that reduces variations between neighbors, flattening regions with small gradients while leaving large jumps unchanged. In optimization problems, such as image reconstruction or generation, TV Loss is often added as a regularization term with a weight to the primary loss function:
where ensures fidelity to observed data (e.g., mean squared error for reconstruction). The parameter controls the trade-off between smoothness and data fidelity; too large a oversmooths the image, erasing fine details, while too small a fails to suppress noise. TV Loss is particularly effective in tasks like image denoising, inpainting, and style transfer, where it helps produce visually plausible results by eliminating unstructured noise and creating piecewise smooth outputs. Its use in deep learning, such as in generative models, stabilizes training by preventing high-frequency artifacts that can arise from unconstrained optimization, ensuring that generated images adhere to natural image statistics characterized by sparse gradients.
10.5.3.4 Loss Functions for Uncertainty Estimation and Bayesian Deep Learning
10.5.3.4.1 Evidence Lower Bound (ELBO) Loss
The Evidence Lower Bound (ELBO) loss is the foundational objective function in variational inference, a method used to approximate intractable posterior distributions in probabilistic models, most prominently in Variational Autoencoders (VAEs). It derives from the principle of maximizing the log-likelihood of the observed data , which is computationally infeasible due to the integration over latent variables z. Instead, variational inference introduces an approximate posterior distribution , parameterized by , and seeks to minimize the Kullback-Leibler (KL) divergence between and the true posterior . This divergence is non-negative and satisfies:
where is the ELBO, defined as:
The ELBO provides a lower bound on the log-evidence , as the KL term is always non-negative. Maximizing the ELBO is equivalent to minimizing , thus making a better approximation of the true posterior. The first term in the ELBO, , is the reconstruction loss, which encourages the decoder to generate data that matches the observed input x. The second term, , acts as a regularizer, penalizing deviations of the approximate posterior from the prior , typically chosen as a standard Gaussian . This KL divergence term can often be computed analytically, especially when both and are Gaussian, ensuring computational efficiency.
The optimization of the ELBO involves gradient-based methods, but the expectation term poses a challenge due to the non-differentiability of sampling from . This is addressed by the reparameterization trick, which expresses the latent variable as a deterministic function of parameters and an auxiliary noise variable: with . For a Gaussian , this becomes
where . This transformation allows gradients to flow through the stochastic layer, enabling unbiased Monte Carlo estimates of the gradient:
The KL divergence term for Gaussian distributions has a closed-form expression:
where J is the dimensionality of z, and and are the parameters of . This term encourages the latent codes to remain close to the prior, preventing overfitting and promoting a structured latent space. The ELBO loss is thus:
which is minimized during training. The balance between reconstruction accuracy and latent regularization is automatic but can be tuned with a weight parameter in variants like -VAE, which uses to emphasize disentangled representations. The ELBO framework ensures tractable optimization while providing a rigorous bound on the data likelihood, making it a cornerstone of modern deep generative models.
10.5.3.4.2 Negative Log-Likelihood (NLL) Loss
Negative Log-Likelihood (NLL) Loss is a fundamental objective function in statistical estimation and machine learning that arises from the principle of maximum likelihood estimation (MLE), aiming to find the parameters of a model that make the observed data most probable.
Given a parametric model that defines the probability of data point x under parameters , and assuming independent and identically distributed (i.i.d.) data samples , the likelihood function is
Maximizing this likelihood is equivalent to minimizing the negative log-likelihood, due to the monotonicity of the logarithm function, leading to the NLL loss:
The normalization by N expresses the loss as an empirical expectation over the data distribution: , which is the cross-entropy between the true data distribution and the model distribution . Minimizing the NLL loss thus minimizes the Kullback-Leibler divergence , as
where is the entropy of the data and is constant with respect to . This establishes NLL as a direct measure of how well approximates .
In practice, for discrete outcomes such as classification, is often a categorical distribution where the model outputs a probability vector over classes. For a true label (represented as a one-hot vector) and predicted probabilities , the NLL loss for that sample is , which is the cross-entropy loss. For continuous data, such as regression, is typically a parametric distribution like a Gaussian , and the NLL loss becomes:
which couples the mean and variance terms. In heteroscedastic regression, where the variance is also predicted, minimizing NLL allows the model to learn uncertainty estimates automatically. The gradient of the NLL loss with respect to the parameters is:
which is the negative of the gradient of the log-likelihood. For exponential family distributions, this gradient has favorable properties, often leading to efficient optimization. The Hessian of the NLL loss is related to the Fisher information matrix
which characterizes the curvature of the likelihood surface and plays a key role in natural gradient methods. NLL loss is widely used in deep learning for generative modeling (e.g., VAEs, autoregressive models), classification, and probabilistic regression, providing a statistically principled way to train models that output full probability distributions rather than point estimates. Its minimization ensures consistency and efficiency under correct model specification, per the asymptotic properties of MLE.
10.5.3.5 Loss Functions for Domain Adaptation
10.5.3.5.1 Domain Adversarial Loss
Domain Adversarial Loss is a strategic objective function employed in domain adaptation to learn feature representations that are invariant across a source domain and a target domain , thereby facilitating knowledge transfer from a label-rich source to an unlabeled target.
The core idea is to train a feature extractor that produces embeddings which are indistinguishable between domains, as judged by a domain classifier that acts as an adversary. This induces a minimax game: the feature extractor aims to confuse the domain classifier, while the domain classifier strives to correctly identify the domain origin of features. Formally, let and be samples from the source and target distributions and , respectively. The feature extractor maps input x to a feature vector . The domain classifier takes f as input and outputs a probability that the feature originates from the source domain. The domain adversarial loss is then defined as the binary cross-entropy loss for the domain classifier:
where and are the number of source and target samples in the batch. The parameters of the domain classifier are optimized to minimize this loss, thus improving domain discrimination. Conversely, the parameters of the feature extractor are optimized to maximize this loss, effectively making the features domain-invariant. This adversarial dynamic is encapsulated in the overall objective:
In practice, this is achieved by gradient reversal during backpropagation: when updating , the gradient from is multiplied by (a hyperparameter) before being propagated through the feature extractor, thus implementing the maximization step.
The mathematical rigor of domain adversarial training stems from its connection to minimizing the -divergence between the source and target feature distributions. Let and be the distributions of features for and , respectively. The domain classifier aims to approximate the optimal discriminator between and , which achieves an error rate related to the Jensen-Shannon divergence. By training the feature extractor to maximize the domain classifier’s loss, it effectively minimizes the divergence between and , leading to aligned feature distributions. The overall loss for the system often combines the domain adversarial loss with a task-specific loss (e.g., classification loss on the source domain):
where denotes the parameters of a task-specific classifier (e.g., label predictor) that uses the features f, and controls the trade-off between task performance and domain invariance. The gradient updates are:
where the negative sign for on implements the gradient reversal. This framework ensures that the learned features are both discriminative for the task and invariant to domain shifts, enabling effective unsupervised domain adaptation. The success of domain adversarial loss hinges on balancing the adversary’s strength; too weak a classifier fails to align distributions, while too strong a one can overwhelm the task loss and degrade feature quality.
10.5.3.5.2 Maximum Mean Discrepancy (MMD) Loss
Maximum Mean Discrepancy (MMD) Loss is a non-parametric, kernel-based measure for comparing two probability distributions by evaluating the distance between their means in a reproducing kernel Hilbert space (RKHS), providing a rigorous framework for testing whether two samples are drawn from the same distribution without requiring density estimation.
Given two distributions P and Q over a space , and a feature map that projects samples into an RKHS with kernel
the MMD is defined as the distance between the mean embeddings and :
Using the kernel trick, this can be expressed entirely in terms of kernel evaluations:
which avoids explicit computation of the feature maps. For empirical samples and , an unbiased estimator of is:
where the sums exclude diagonal terms to avoid bias. The choice of kernel k is critical; common choices include the Gaussian kernel
where the bandwidth controls the sensitivity to multi-scale structures in the data. The MMD loss is zero if and only if when the kernel is characteristic (e.g., Gaussian), meaning the kernel map is injective, ensuring that the mean embedding captures all information about the distribution.
The mathematical properties of MMD make it particularly suitable for training generative models and domain adaptation. Minimizing MMD between the model distribution and the data distribution P provides a loss function that encourages the generator to produce samples that match the statistical properties of the real data. The gradient of the MMD loss with respect to the model parameters is:
which requires sampling from and differentiating through the kernel function. This gradient can be computed efficiently using automatic differentiation. In practice, for large datasets, minibatch estimates are used, though care must be taken with the biased estimator that includes diagonal terms when gradients are involved. The loss function is differentiable almost everywhere (for smooth kernels) and provides stable gradients, unlike adversarial losses that can suffer from vanishing gradients or mode collapse. MMD has deep connections to integral probability metrics and is equivalent to the distance between distributions under the function class induced by the kernel. Its computational complexity is , which can be prohibitive for large batches, but linear-time approximations exist, such as:
which uses non-overlapping pairs for an unbiased estimate with complexity. MMD is widely used in domain adaptation to align feature distributions between source and target domains, in generative models like MMD-GANs, and in two-sample hypothesis testing, providing a robust and statistically powerful measure of distributional similarity.
10.5.3.6 Loss Functions for Object Detection and Segmentation
10.5.3.6.1 IoU Loss (Intersection over Union) and Its Variants (GIoU, DIoU, CIoU)
The fundamental Intersection over Union (IoU) metric for two axis-aligned bounding boxes, a ground truth box A defined by its top-left and bottom-right coordinates and a predicted box B with coordinates , is calculated by first determining the coordinates of their intersection I:
The area of intersection is
The area of the union is computed from the areas of the individual boxes: , where
and
The IoU is then:
The IoU Loss is simply
The gradient of this loss with respect to a predicted coordinate, say , is found through careful application of the chain rule. The derivative is non-zero only if the boxes intersect :
Since
and is itself a piecewise function:
This complexity and the zero gradient for non-overlapping boxes motivated the development of improved variants. Generalized IoU (GIoU) Loss introduces a convex enclosure C, the smallest box containing both A and B, with coordinates:
The area of C is . GIoU is defined as:
The GIoU Loss is . Its gradient provides a signal even for non-overlapping boxes. The derivative with respect to a coordinate incorporates the new term:
The derivative is non-zero only if is the left-most point:
This guides the predicted box to expand towards the enclosure. Distance IoU (DIoU) Loss incorporates a penalty on the normalized distance between the box centers. Let the center points be
and
The Euclidean distance between centers is
Let c be the diagonal length of the enclosure C:
DIoU is defined as:
The DIoU Loss is
Its gradient includes a term that directly minimizes the center distance:
The derivative of the center distance with respect to the coordinate is:
assuming the prediction affects the center point . The derivative of the diagonal length c is:
Complete IoU (CIoU) Loss builds upon DIoU by adding an aspect ratio penalty term. It introduces a measure v to quantify the aspect ratio consistency:
where and are the width and height of the ground truth and predicted boxes, respectively. A trade-off parameter is defined as
CIoU is then:
The CIoU Loss is
Its gradient is the most complex, requiring the derivative of the aspect ratio term v with respect to the box dimensions. The gradient with respect to the predicted width is:
Similarly, the gradient with respect to the height is:
These gradients are then propagated back to the coordinate parameters through the relationships
and
for example
This comprehensive penalty ensures convergence not only in overlap and center alignment but also in the shape of the predicted bounding box, leading to superior regression accuracy.
The careful derivation of these gradients is essential for their implementation in deep learning frameworks using automatic differentiation.
10.5.3.6.2 Dice Loss
Dice Loss is a region-based loss function originating from the Sørensen–Dice coefficient, a statistical metric used to gauge the similarity between two sets. In the context of image segmentation, it measures the overlap between the predicted segmentation mask P and the ground truth mask G, making it particularly effective for tasks characterized by severe class imbalance, such as medical image segmentation where the object of interest often occupies a small fraction of the image. The Dice coefficient for binary segmentation is defined as:
where N is the total number of pixels, is the predicted probability that pixel i belongs to the foreground class, and is the corresponding ground truth label.
The Dice Loss is then formulated as
which directly minimizes the dissimilarity between the predicted and true regions. To ensure numerical stability and avoid division by zero, especially when both masks are empty, a smooth term (typically 1) is added to both the numerator and denominator:
This loss function is differentiable and can be optimized using gradient-based methods. The gradient of the Dice Loss with respect to the predicted probability at a specific pixel j is crucial for backpropagation and is given by:
This gradient indicates that the update for each pixel is influenced by the global statistics of the entire mask—specifically, the sums over all pixels—rather than just the local error. This property makes Dice Loss inherently global and particularly sensitive to the overall structure of the segmentations, providing a strong gradient signal even when the foreground region is small.
The mathematical formulation of Dice Loss can be extended to multi-class segmentation problems using a one-hot encoded representation for C classes. For each class c, the loss is computed separately and then averaged, leading to:
where is the predicted probability that pixel i belongs to class c, and is the corresponding ground truth indicator. In practice, Dice Loss is often combined with other loss functions, such as cross-entropy, to form a composite objective that leverages both region-based and distribution-based optimization. The combined loss
helps to balance the emphasis on pixel-wise accuracy and overall region overlap, often leading to improved performance and more stable convergence. The hyperparameter controls the contribution of the Dice term. From a computational perspective, the sums over all pixels make the loss efficient to compute using tensor operations, and its differentiability allows for seamless integration into deep learning frameworks. The Dice coefficient’s equivalence to the F1 score, a harmonic mean of precision and recall, underscores its suitability for scenarios where both false positives and false negatives are critical, as it naturally balances these two metrics without requiring explicit weighting.
10.5.3.6.3 Focal Loss
Focal Loss is a dynamically scaled cross-entropy loss function designed to address the extreme foreground-background class imbalance prevalent in one-stage object detection models, such as RetinaNet, by systematically reducing the relative loss contribution from well-classified examples and focusing training on hard, misclassified examples. The loss is a modification of the standard binary cross-entropy (BCE) loss for binary classification, defined for a true label and a model-estimated probability for the class with label . To notational convenience, we define as the model’s estimated probability for the true class:
The standard binary cross-entropy loss is then
The fundamental innovation of Focal Loss is the introduction of a modulating factor , where is a tunable focusing parameter, and a weighting factor for the class , with the weight for being . The complete formulation of Focal Loss is
The modulating factor is the core component that dictates the dynamic scaling; for a well-classified example where , this factor approaches 0, thus down-weighting the loss contribution for that example. Conversely, for a misclassified example where , the modulating factor approaches 1, and the loss is largely unaffected. The rate of this down-weighting is controlled by ; higher values of (e.g., ) further suppress the loss from easy examples, intensifying the focus on hard negatives. The factor is a static weight used to address class imbalance by increasing the importance of the rare class (e.g., foreground) in the loss; it can be set inversely proportional to the class frequency.
The mathematical properties of Focal Loss are critical to its efficacy. The loss function is continuous and differentiable almost everywhere, which is essential for gradient-based optimization. The gradient of Focal Loss with respect to the model’s output logit z (where ) reveals its behavior during training. The gradient is given by:
This can be simplified, considering the definition of , to:
A more intuitive understanding emerges when considering the case of a positive example (), where the gradient magnitude is proportional to .
This shows that the gradient signal diminishes for easy examples (high ) and remains significant for hard examples (low ), directly addressing the class imbalance issue where the vast number of easy negative examples would otherwise dominate the gradient. The loss is convex for a given value of , but the dynamic scaling makes the overall optimization landscape more complex, requiring careful tuning of the learning rate. The hyperparameter smoothly interpolates the loss behavior; when , Focal Loss is equivalent to -balanced cross-entropy, and as increases, the effect of the modulating factor becomes more pronounced. The parameter helps to counter the implicit weighting introduced by , which can suppress the loss for the rare class if its examples are initially easy; setting higher for the rare class ensures it continues to receive sufficient learning signal. In practice, the combined effect of and drastically improves the precision-recall trade-off on imbalanced datasets, allowing one-stage detectors to surpass the performance of more complex two-stage architectures by efficiently harnessing a much larger and more diverse set of candidate proposals during training, whose gradients are no longer drowned out by a sea of trivial background examples.
10.5.3.7 Loss Functions for Knowledge Distillation
10.5.3.8 Loss Functions for Reinforcement Learning
10.5.3.8.1 Hinge Loss
The Hinge Loss function is a convex relaxation of the 0-1 loss primarily employed for maximum-margin classification, most notably in Support Vector Machines (SVMs) but also applicable to neural networks.
Its objective is not to produce probability estimates but to find a decision boundary that maximizes the geometric margin between classes, thereby enhancing the model’s generalization capability. For a binary classification task with true labels and a model that produces real-valued scores (where is the weight vector and b is the bias), the Hinge Loss for a single data point is defined as
This piecewise function is zero if , meaning the prediction is correct and lies beyond the margin boundary, and increases linearly for .
The term is known as the functional margin; a positive value indicates a correct classification, and its magnitude represents the confidence of the prediction. The loss explicitly penalizes predictions that are either incorrect or correct but within the margin boundary (where ), with the penalty proportional to the degree of margin violation. The aggregate loss over a dataset of N samples is typically given by
where the regularization term is not merely a technical addition but is fundamental to the maximum-margin principle, directly controlling the trade-off between maximizing the margin and minimizing classification error.
From an optimization perspective, the Hinge Loss is convex and piecewise linear, which allows for efficient training using subgradient methods. Its subgradient with respect to the model’s parameters is central to learning. For a single data point, the subdifferential is:
In practice, at the point of non-differentiability , a common convention is to choose a subgradient of 0, treating the point as part of the flat region. The overall subgradient of the regularized objective L with respect to is therefore
This leads to a simple and intuitive update rule: for samples that violate the margin , the update is
(if using a subgradient of ), where is the learning rate, which pushes the decision boundary to correctly classify the sample, while the regularization term shrinks the weights. Samples outside the margin do not contribute to the weight update. This sparsity in the gradient contribution is a key property, as it means the final classifier is only defined by a subset of critical training examples—the support vectors—which are the samples that lie on or within the margin .
The Hinge Loss can be generalized to multi-class classification, known as the Crammer-Singer loss or multi-class Hinge Loss. For a problem with K classes, where the true label for a sample is an integer and the model produces a score vector , the loss is defined as
This formulation penalizes the model if the score for the correct class is not greater by at least a margin of 1 than the maximum score among all incorrect classes. The subgradient for this loss involves the incorrect class that achieves the maximum score
leading to updates that increase the score for the correct class and decrease the score for this most offending incorrect class. The Hinge Loss’s primary strength is its focus on the geometric structure of the problem, promoting robust classifiers with good generalization bounds derived from statistical learning theory, such as the Vapnik-Chervonenkis (VC) dimension and Rademacher complexity, which directly relate to the concept of the margin. Its main limitation is its lack of inherent probabilistic calibration, as it outputs a decision function rather than a probability, though methods like Platt scaling can be applied post-hoc to address this.
10.5.3.8.2 Value Loss
Value Loss, in the context of reinforcement learning (RL) and particularly actor-critic methods, is a objective function designed to train the value function estimator , parameterized by , to accurately predict the expected cumulative return from a given state s.
The value function represents the expected return when starting from state s and following policy :
where is the discount factor and is the reward at time t. The Value Loss is typically defined as the mean squared error (MSE) between the predicted value and a target value estimate , which is derived from empirical returns or bootstrapped estimates. In the Monte Carlo approach, the target is the actual return
leading to the loss
However, due to the high variance of , temporal difference (TD) methods are preferred, where the target is the bootstrapped estimate
using parameters from a previous iteration to enhance stability. The loss becomes:
where is the state distribution under policy . In advanced algorithms like Proximal Policy Optimization (PPO) and Generalized Advantage Estimation (GAE), the value loss is minimized concurrently with the policy loss to reduce variance and accelerate learning. The gradient of the value loss with respect to the parameters is:
which adjusts to minimize the TD error
To prevent overfitting and ensure training stability, the value loss is often clipped or regularized. For instance, in PPO, the value function is trained via multiple epochs on the same data, and the loss may include a clipping term or a entropy bonus. The objective becomes:
though this is less common than the policy clipping.
Alternatively, a squared error loss with a penalty on the divergence from the previous value function can be used:
where is a hyperparameter. The target can be computed using GAE, which provides a low-variance estimate of the advantage function by exponentially averaging TD errors of different steps:
where
is the GAE estimate, with controlling the bias-variance trade-off. The value loss is then:
This formulation ensures that the value function learns to approximate the true value function , which is critical for accurate advantage estimation and effective policy updates. The optimization of the value loss is typically performed using stochastic gradient descent, with gradients computed over minibatches of trajectories to ensure computational efficiency and convergence. The value function’s accuracy directly influences the policy gradient estimates, as the advantage is used to scale the policy updates, making the value loss a cornerstone of stable and efficient reinforcement learning.
10.5.3.8.3 Policy Loss
Policy Loss is the objective function used to optimize the policy in reinforcement learning, where represents the parameters of a neural network that maps states s to a probability distribution over actions a. The fundamental goal is to maximize the expected cumulative reward
where is a trajectory and is the discount factor. The policy gradient theorem provides the foundation for the policy loss by giving the gradient of this objective:
where
is the advantage function, measuring how much better action is compared to the average action in state . The basic policy loss is then formulated as the negative of the objective to be minimized:
where is an estimate of the advantage. However, this vanilla policy gradient can lead to unstable updates with high variance.
To address stability issues, Proximal Policy Optimization (PPO) introduces a clipped surrogate objective that prevents excessively large policy updates. Let
be the probability ratio between the new and old policies. The unclipped objective is
where CPI denotes conservative policy iteration. PPO modifies this by clipping the probability ratio to remain near 1, forming the primary policy loss:
where is a hyperparameter, typically 0.1 or 0.2. The clip function restricts to the interval , ensuring the policy update does not change too radically.
The min operator ensures the objective is a lower bound (pessimistic clip) on the unclipped objective, preventing the policy from being improved excessively when the advantage is positive and from being degraded too much when the advantage is negative. The gradient of this loss with respect to requires careful computation of the derivatives of the probability ratio. For a positive advantage , the gradient is
which becomes if , and 0 otherwise. For a negative advantage , the gradient is
which becomes if , and 0 otherwise. This clipping mechanism effectively removes the incentive for moving outside of the interval .
An alternative PPO objective combines the clipped surrogate with a penalty on the KL divergence between the new and old policies:
where is an adaptive coefficient. The KL divergence for categorical policies is
and its gradient encourages the new policy to not deviate too far from the old policy in terms of action distribution. The complete PPO objective often includes a value function error term and an entropy bonus for exploration, leading to the total loss:
where are coefficients, is the value loss, and is the entropy. The policy gradient can be computed using the likelihood ratio trick:
allowing for efficient estimation from trajectories. For continuous action spaces, where the policy is often a Gaussian distribution
the log probability is
and its gradient with respect to involves the derivatives of the mean and standard deviation networks. The policy loss thus provides a mathematically grounded mechanism for incrementally improving the policy while maintaining training stability through constraints on the policy change.
10.5.3.8.4 Entropy Regularization
Entropy Regularization is a technique employed in reinforcement learning, particularly in policy optimization methods like Proximal Policy Optimization (PPO) and Soft Actor-Critic (SAC), to encourage exploration by penalizing low entropy in the policy distribution, thereby preventing premature convergence to suboptimal deterministic policies.
The entropy of a discrete probability distribution is defined as
which measures the uncertainty or randomness in the action selection; maximum entropy is achieved by the uniform distribution where all actions are equally likely, while minimum entropy (zero) corresponds to a deterministic policy. In the context of the maximum entropy reinforcement learning framework, the standard objective of maximizing the expected cumulative reward is augmented with an entropy term to form a modified objective
where is a temperature parameter that controls the relative importance of entropy versus reward. The policy loss function then incorporates entropy regularization as a negative term to be maximized (or a positive term to be minimized when framed as a loss), leading to
where is the advantage estimate. The gradient of the entropy term with respect to the policy parameters is
which can be computed efficiently using automatic differentiation.
For continuous action spaces where the policy is parameterized as a Gaussian distribution
the entropy has a closed-form expression. For a multivariate Gaussian with diagonal covariance
the entropy is
The gradient of this entropy with respect to the standard deviation parameters is straightforward:
which provides a clear signal to increase the standard deviations, thereby increasing exploration.
In practice, the temperature parameter can be treated as a hyperparameter or adapted dynamically during training to maintain a target entropy level , often set as the negative dimension of the action space
The loss for the temperature parameter is
and its gradient
adjusts to balance the entropy penalty. The inclusion of entropy regularization alters the optimal policy to a softmax form:
where is the soft Q-function that includes entropy bonuses. This results in a policy that not only seeks high rewards but also maintains stochasticity, which improves exploration and robustness by preventing the policy from becoming too confident too early. The mathematical effect of entropy regularization is to smooth the optimization landscape, making gradient estimates more reliable and reducing the likelihood of getting trapped in local optima, which is crucial for solving complex environments with sparse rewards.
10.5.3.9 Loss Functions for Sparse and Structured Outputs
10.5.3.9.1 Kullback-Leibler (KL) Divergence Loss (as a Sparsity Constraint)
The utilization of Kullback-Leibler (KL) Divergence as a sparsity constraint is a Bayesian regularization technique that forces the empirical distribution of activations within a neural network layer, typically a hidden layer of an autoencoder, to approximate a pre-specified sparse prior distribution.
This method induces a form of representational sparsity, where only a small fraction of units are significantly active for any given input, thereby learning efficient, distributed codes. The core mathematical object is the KL divergence between two Bernoulli distributions: a target sparse prior with a very low mean activation probability (e.g., ), and the empirical average activation of a particular hidden unit j over a batch of m training examples. For a single unit, the average activation is
where
is the activation of unit j for input , and f is a sigmoidal activation function. The KL divergence for a Bernoulli distribution, which measures the inefficiency of assuming the distribution when the true distribution is , is given by:
This function has the desired properties of a sparsity penalty: it is zero if and only if , and it increases asymmetrically as deviates from . The asymmetry is crucial; it penalizes units that are too active more heavily than units that are not active enough , although the term for still provides a pulling force towards the target. The total sparsity penalty for a hidden layer with s units is the sum of the KL divergences over all units: .
This penalty term is then added to the primary objective function, such as the reconstruction error of an autoencoder, scaled by a sparsity regularization parameter . The complete loss function for a sparse autoencoder becomes:
The gradient of this composite loss with respect to the network’s parameters must be computed for backpropagation. The gradient of the KL penalty term with respect to the average activation is:
This gradient indicates the direction to push to minimize the penalty. Since is not a direct parameter but a function of the activations , the chain rule is applied.
The gradient of the total loss J with respect to the activation of unit j for a single example i receives an additional contribution from the sparsity penalty:
Given that
the derivative
Therefore, the sparsity-induced gradient for a single training example is effectively
This term is then propagated backwards through the activation function to update the weights and biases . For a sigmoid activation , the gradient with respect to the pre-activation is
This mechanism ensures that the learning process not only minimizes reconstruction error but also adjusts the parameters to drive the average activations of the hidden units towards the desired sparse target , resulting in a model that discovers statistically significant features in the data without over-representing them.
10.5.3.9.2 Structured Support Vector Machine (SSVM) Loss
The Structured Support Vector Machine (SSVM) loss, also known as the max-margin Markov network loss or structured hinge loss, is a convex objective function for training models that predict complex, interdependent output structures from an input , where is a discrete but exponentially large space (e.g., all possible sequences, sparse trees, or segmentations).
The fundamental principle is a generalization of the binary SVM margin principle to structured outputs: the score
of the correct output structure should be greater than the score of any other structure by a margin that scales with the loss incurred by predicting instead of . Here, is a joint feature map that encodes the compatibility between input and output , and are the model parameters. The structured hinge loss for a single training example is formulated as:
where is a task-specific cost function that quantifies the discrepancy between the true structure and a candidate structure ; it is zero if and positive otherwise. The maximization over , often called the "loss-augmented inference" problem, finds the most violating incorrect structure—the one that has a high score according to the current model and also incurs a high cost . The complete objective function for the SSVM, including regularization, is:
This objective is convex in because it is a sum of a convex quadratic function and maxima of affine functions of .
The optimization of this loss is typically performed using subgradient methods. The subgradient of the loss with respect to is given by the difference between the feature vector of the maximally violating structure and the feature vector of the true structure:
where
This subgradient indicates the direction to adjust to increase the score gap between the true structure and the most offending incorrect structure.
The critical computational challenge is solving this loss-augmented inference problem efficiently. For many structured problems where the cost function decomposes additively over the output structure (e.g., Hamming loss over sequences), and the feature map factorizes according to a graphical model (e.g., a chain or tree), dynamic programming algorithms like the Viterbi algorithm or belief propagation can compute exactly and efficiently. The overall training algorithm involves iterating over examples, solving for for each, and updating the weights via
where is a learning rate. A common alternative is the margin-rescaled formulation presented above; another is the slack-rescaled formulation, which scales the margin by the cost:
The SSVM framework provides a principled, margin-based approach to structured prediction with strong theoretical guarantees, but its efficacy hinges on the tractability of the loss-augmented inference problem and the design of a meaningful feature map that captures the input-output relationships.
10.5.3.9.3 Conditional Random Field (CRF) Loss
The Conditional Random Field (CRF) loss function is derived from the principle of maximum likelihood estimation for conditional probabilistic graphical models, specifically designed for structured prediction tasks where the output variables exhibit mutual dependencies given an input sequence .
A CRF directly models the conditional probability without making independence assumptions among the output variables , unlike generative models like Hidden Markov Models. For a linear-chain CRF, which is common in sequence labeling, the probability distribution is defined by a Gibbs distribution:
where is a feature vector capturing the association between input and label at position t (unary potential), is a feature vector capturing the transition between adjacent labels and (pairwise potential), are the model parameters to be learned, and is the partition function ensuring normalization:
The summation over all possible label sequences makes direct computation intractable for long sequences, but the chain structure allows efficient calculation using the forward-backward algorithm. The CRF loss for a training dataset is the negative conditional log-likelihood:
Minimizing this loss maximizes the likelihood of the true label sequences under the model. The gradient of the loss with respect to the parameters reveals a crucial contrast between the empirical counts and the model’s expected counts. The gradient for the unary parameters is:
and for the pairwise parameters :
The first term in each gradient is the empirical feature count from the training data, and the second term is the expected feature count under the current model distribution .
These marginal probabilities and are computed efficiently using the forward-backward algorithm, which leverages the Markov property to perform dynamic programming. The forward algorithm calculates
the probability of being in state y at time t given the observations up to t, recursively:
The backward algorithm similarly calculates
Therefore we have
The partition function is obtained as
The marginal probability for a single label is
and for two consecutive labels is
Optimization of the CRF loss is typically performed using iterative gradient-based methods like L-BFGS or stochastic gradient descent.
The convexity of the negative log-likelihood ensures convergence to a global optimum, and regularization is often added to the loss to prevent overfitting:
The CRF loss effectively captures dependencies between output labels, making it superior to independent classifiers for structured tasks like named entity recognition and part-of-speech tagging.
10.5.3.9.4 Connectionist Temporal Classification (CTC) Loss
Connectionist Temporal Classification (CTC) loss is a objective function designed for sequence-to-sequence learning tasks where the alignment between the input sequence
and the target sequence
is unknown and , commonly encountered in speech recognition and handwriting recognition.
The fundamental challenge is that the same target label sequence can be generated by multiple, variable-length alignments between the input and output. CTC addresses this by introducing a latent alignment path
where each belongs to an extended alphabet
which includes the original labels L plus a special blank symbol (denoted here as "−"). The blank symbol represents no label emission and is crucial for handling repetitions and variable timing. The conditional probability of a path given the input sequence is factorized as a product of independent probabilities at each time step, which are output by a recurrent neural network with a softmax layer over :
where is the probability of emitting symbol at time t.
A many-to-one mapping function , known as the CTC collapse function, is defined to remove all blank symbols and then merge consecutive duplicate symbols. For example,
The total probability of a given label sequence is the sum of the probabilities of all paths that map to it under :
The CTC loss function for a training example is the negative log-likelihood of this probability:
The central computational problem is efficiently calculating the sum over the exponentially large number of paths in . This is solved using a dynamic programming algorithm analogous to the forward-backward algorithm in Hidden Markov Models, known as the CTC forward-backward algorithm.
The algorithm operates on a modified label sequence of length , which is created by inserting blank symbols at the beginning, end, and between every pair of labels in . For example, if , then . This ensures that valid paths can transition between labels only via a blank. Let the forward variable be the total probability of all valid paths of length t that map to the first symbols of (where s is an index in ). The recurrence relation for is complex due to the rules imposed by : a path can only extend by staying on the same label, moving to the next label, or inserting a blank between non-repeating labels. The recurrence is:
where the indicator function allows the transition if it conforms to the collapse rules (e.g., skipping a blank or a non-repeating label). The initial conditions are and , with all others zero. The total probability is then the sum of the forward variables at the final time step for the last two nodes of :
Similarly, a backward variable is defined as the probability of all paths starting from time t and position s in to the end, and it is computed backwards from T to 1.
The gradient of the CTC loss with respect to the network outputs is essential for backpropagation. It can be expressed using the forward and backward variables:
The derivative is the sum of the probabilities of all paths that go through the symbol k at time t, which is computed as , where is the set of indices s in for which . This yields the final gradient:
This gradient is then propagated back through the softmax layer to update the network weights. The CTC loss elegantly handles the alignment problem without pre-segmented data, making it a cornerstone of modern sequence-to-sequence models.
Its main limitation is the conditional independence assumption between output frames, which more advanced models like RNN-Transducers aim to address.
10.5.3.9.5 Maximum Margin Markov Networks Loss
Maximum Margin Markov Networks (M³N) loss is a structured prediction objective that integrates the max-margin principle of Support Vector Machines (SVMs) with the probabilistic graphical model framework of Markov networks, providing a convex optimization formulation for learning discriminative models over interdependent output variables.
The core idea is to ensure that the score assigned to the correct output structure is greater than the score of any other structure by a margin that scales with the dissimilarity between them, as measured by a task-specific loss function . The score of a structure is defined linearly as
where is a joint feature mapping that decomposes over the cliques of the Markov network. For a pairwise Markov network, this decomposition is
where and are feature functions for nodes and edges respectively, and is the set of edges in the graph. The M³N loss for a single example is formulated as the structured hinge loss:
This loss is zero if the margin constraint
holds for all , and positive otherwise. The complete regularized objective function is:
where are slack variables allowing soft margins and C is a regularization parameter.
This formulation has an exponentially large number of constraints, but it can be optimized using the cutting-plane algorithm, which iteratively adds the most violated constraint for each training example. The most violated constraint for example i is found by solving the loss-augmented inference problem:
The key computational requirement is that this maximization must be tractable. When the loss function decomposes additively over the graph structure (e.g., Hamming loss), and the feature mapping decomposes over the same cliques, dynamic programming or graph cuts can be used for efficient exact inference.
The dual formulation of the M³N objective provides insight into the representation of the solution. The dual problem involves maximizing a concave objective over dual variables for each example i and each structure :
subject to . The optimal weight vector is given by
The Karush-Kuhn-Tucker (KKT) conditions for optimality require that only for structures that achieve the maximum in the loss-augmented inference problem for example i, meaning the solution is sparse and only supported by a small set of "active" structures. The gradient of the primal loss with respect to is a subgradient:
which can be used in subgradient descent optimization. The M³N framework generalizes multiclass SVMs and provides a principled way to incorporate structural dependencies into max-margin learning, with strong theoretical guarantees on generalization error.
However, its practical applicability depends critically on the ability to solve the loss-augmented inference problem efficiently, which restricts its use to structures where exact inference is feasible, such as sequences, trees, or graphs with low treewidth. The margin rescaling approach in M³N can be contrasted with slack rescaling, which uses constraints of the form
but margin rescaling is more commonly used due to its more straightforward integration with efficient inference algorithms.
10.5.3.9.6 Listwise Ranking Losses
Listwise ranking losses are a class of objective functions designed for learning to rank by directly modeling the probability distribution over the entire permutation of items in a list, thereby optimizing the global ordering rather than focusing on independent pairwise comparisons. The fundamental principle is to define a mapping from the predicted scores of items, assigned by a model , to a probability distribution over all possible permutations of those items, and then to minimize the discrepancy between this predicted distribution and the idealized distribution derived from the ground truth ranking. The ground truth is typically represented as a set of relevance scores for a list of n items associated with a query. The ListNet framework, a prominent listwise approach, utilizes the Plackett-Luce model to define the probability of a particular permutation of the indices . According to this model, the probability of a permutation is given by the product of sequential conditional probabilities:
where are the predicted scores from the model, , and denotes the item placed at the j-th position in the permutation. This model captures the notion that the probability of an item being ranked first is proportional to the exponential of its score, and subsequent positions are determined by repeatedly applying the same logic to the remaining items.
The ground truth distribution is often not a full permutation but a set of relevance labels. To handle this, the top-one probability is used as a surrogate. The top-one probability for item i is the probability that it is ranked first under the Plackett-Luce model:
Similarly, the ground truth top-one probability is defined using the actual relevance scores:
where is a transformation function, typically chosen as an exponential function to maintain a softmax form, or a linear function for simplicity. The loss function for a single query is then defined as the cross-entropy between the two top-one probability distributions over the n items:
If is the exponential function, this simplifies to:
The gradient of this loss with respect to the predicted score of a single item is:
This gradient has an elegant interpretation: it is the difference between the predicted probability that item j is the most relevant and the ground truth probability. This gradient is then backpropagated through the scoring function to update the model parameters . The loss function is convex in the scores , and the optimization process effectively pushes the predicted score distribution to match the ground truth relevance distribution.
A more direct but computationally intensive listwise loss is the likelihood loss, which aims to maximize the probability of the optimal permutation. If the ground truth is a full ordering , the loss is the negative log-likelihood under the Plackett-Luce model:
The gradient of this loss for a score involves a sum over all positions in the permutation where the item appears and all items that were ranked below it, making it more complex than the top-one approximation. Listwise losses are considered superior to pairwise and pointwise losses in information retrieval because they directly optimize the entire list structure, which is the ultimate goal of ranking.
However, their computational cost is higher due to the need to compute the normalization term over all items for each query, and they require meaningful ground truth relevance scores rather than just binary preferences. The mathematical rigor of listwise approaches lies in their direct formulation as probabilistic models of permutation, providing a principled foundation for learning ranking functions that perform well on metrics like Normalized Discounted Cumulative Gain (NDCG).
10.5.3.9.7 Pairwise Ranking Losses
Pairwise ranking losses constitute a fundamental family of objective functions in metric learning and information retrieval, operating on the principle of comparing pairs of items to learn a representation or scoring function that imposes a desired ordinal structure on the data. The core objective is to ensure that for a given anchor instance , the distance to a positive (similar) instance is smaller than the distance to a negative (dissimilar) instance by at least a specified margin. Let be an embedding function parameterized by that maps an input x to a vector in , and let be a distance metric, typically the Euclidean distance . The generalized pairwise hinge loss, or margin ranking loss, for a triplet is defined as:
where is the margin hyperparameter.
This loss is zero if the negative instance is already more distant from the anchor than the positive instance by at least the margin m, and increases linearly with the violation otherwise. The gradient of this loss with respect to the embedding vectors drives the learning process. When the loss is active
The gradients are:
where
and
These gradients pull the anchor and positive together while pushing the anchor and negative apart, with forces inversely proportional to their current distances, providing a stable optimization landscape.
A more probabilistic formulation is provided by the Bayesian Personalized Ranking (BPR) loss, which is derived from a maximum posterior estimator for implicit feedback data. The BPR objective maximizes the probability that a user prefers a positive item over a negative item . The probability is modeled by a sigmoid function over the difference of their scores:
where is a scoring function. The BPR loss for a triplet is the negative log-likelihood:
This is a smooth approximation of the hinge loss. Its gradient with respect to the score difference is:
which provides a well-defined, non-zero gradient for all inputs. The gradients with respect to the model parameters are then computed via the chain rule based on the specific form of .
For a scoring function based on Euclidean distance in an embedding space, where
the BPR loss encourages the distance between the user and the positive item to be less than the distance to the negative item. The gradient computations become analogous to the margin ranking loss but with a weighting factor from the sigmoid derivative. The overall objective for a dataset is the sum over all valid triplets , which can be sampled from the observed interactions. The optimization of pairwise ranking losses is efficient because it scales with the number of pairs rather than the full list, but it requires careful sampling of informative triplets. Hard negative mining, which selects negative instances that are currently close to the anchor, is critical for efficient learning and high model performance. The mathematical rigor of pairwise losses lies in their direct optimization of the relative order between items, which aligns with ranking metrics more closely than pointwise approaches, while remaining computationally more tractable than full listwise methods.
10.5.3.9.8 Contrastive Divergence (CD) Loss
Contrastive Divergence (CD) loss is an approximate maximum likelihood learning algorithm for energy-based probabilistic models, most notably Restricted Boltzmann Machines (RBMs), which provides an efficient method to estimate the gradient of the log-likelihood function without requiring intractable computations over the entire model distribution.
The core challenge in training an RBM with parameters —where is the weight matrix between visible units and hidden units , and , are bias vectors—is that the log-likelihood gradient for a single training datum involves an expectation over the model distribution :
The first term, the positive phase, is tractable as it requires averaging over the conditional distribution , which factorizes due to the bipartite structure of the RBM. The second term, the negative phase, is an expectation over the joint model distribution and is computationally prohibitive as it sums over all possible configurations of and . Contrastive Divergence approximates this negative phase expectation by starting from the data point and running a short Markov Chain Monte Carlo (MCMC) simulation for k steps (typically ), rather than running the chain to convergence.
The CD-k algorithm proceeds as follows. First, given a training sample , sample a hidden state from the conditional distribution:
For binary units, this is
where is the sigmoid function. Then, for k steps, alternately sample visible and hidden states: sample from where
and then sample from .
After k steps, the gradient approximation for the weight matrix is:
For the biases, the approximations are
and
The CD loss is not an explicit function to be minimized but rather defines this stochastic gradient update rule. The parameter update becomes
where is the positive phase expectation and is the expectation estimated after k steps of sampling. The mathematical justification for CD is that it follows the gradient of a difference of two divergences:
where is the data distribution, is the equilibrium distribution of the Markov chain defined by the model, and is the distribution of the visible units after k steps of the chain starting from the data. While is not the gradient of the log-likelihood, it has been proven to be a valid learning rule that minimizes the KL divergence under certain conditions.
The bias introduced by using a finite k is significant; CD-1 does not converge to the maximum likelihood estimate but to a fixed point that minimizes a different objective. However, in practice, CD-1 works remarkably well for pre-training deep belief networks. The gradient estimates are noisy but unbiased estimators of the true gradient only if the chain is at equilibrium, which it is not for finite k. Persistent Contrastive Divergence (PCD) is a variant that maintains a single persistent chain across parameter updates to better approximate the model distribution, but CD-k remains the foundational algorithm. The loss, interpreted as the contrast between the data-driven configuration and the model-driven reconstruction after a brief "dream" cycle, provides a computationally feasible mechanism for training generative models with latent variables, bridging the gap between theoretical maximum likelihood and practical iterative parameter estimation.
10.5.3.9.9 Persistent Contrastive Divergence (PCD) Loss
Persistent Contrastive Divergence (PCD) is an advanced algorithm for training energy-based models like Restricted Boltzmann Machines (RBMs) that addresses a fundamental limitation of the standard Contrastive Divergence (CD) algorithm by maintaining a persistent Markov chain across parameter updates to provide a better approximation of the model distribution used in the negative phase of learning.
The core objective remains the maximization of the log-likelihood of the training data, whose gradient for a single datum is
The intractability of the negative phase expectation is circumvented by MCMC sampling. While CD-k initializes a chain from each training example and runs it for a small number of steps k (often just one), this approach biases the estimate because the chain is far from equilibrium when the samples are taken. PCD eliminates this bias by maintaining a single, persistent fantasy particle or a set of particles that are not reset to training data between parameter updates. Instead, after each parameter update, the current state of the chain is retained and used as the initial state for the next MCMC step.
The PCD algorithm initializes a set of fantasy particles from some initial distribution (e.g., random or from a previous model). For each iteration of learning, given a minibatch of training data , the parameter update for the weight matrix is computed as:
where is the learning rate. The key difference from CD is that the negative sample is not obtained by running a short chain from a data point but is the current state of the persistent chain. After the parameter update, the fantasy particles are updated by performing one or more Gibbs sampling steps according to the new parameters . A Gibbs step consists of sampling the hidden units given the visible units:
and then sampling the new visible units:
This update is formalized as:
where is the transition operator of the Markov chain defined by the model (e.g., block Gibbs sampling). Because the chain is persistent, the fantasy particles eventually converge to samples from the stationary distribution if the parameters change slowly enough. This makes the negative phase estimate an asymptotically unbiased estimator of the true negative phase expectation , unlike the biased estimate from CD-k.
The mathematical foundation of PCD relies on the theory of Markov chains and stochastic approximation. The learning process can be viewed as a stochastic approximation algorithm that aims to find the root of the function
The PCD update rule is
where the sequence is a homogeneous Markov chain whose transition kernel depends on the evolving parameter . The convergence of this algorithm is non-trivial because the samples are drawn from a non-stationary distribution. However, under the condition that the learning rate decreases appropriately for
and the parameter changes are sufficiently small, the chain can track the slowly evolving model distribution, and the algorithm converges to a maximum likelihood estimate. A common improvement is PCD with fast weights, which uses a separate, faster-evolving set of parameters to define the Markov chain while the primary parameters are updated more slowly, enhancing stability. The PCD loss, therefore, is not a closed-form function but an algorithmic procedure for estimating the gradient of the log-likelihood, providing a more accurate and stable training method for RBMs than CD by reducing the bias in the negative phase approximation through persistent state tracking.
10.5.3.9.10 Hausdorff Distance Loss
The Hausdorff Distance Loss is a metric for comparing two point sets, and , that is particularly useful in image segmentation and shape matching due to its sensitivity to the worst-case discrepancy between the sets, making it robust to outliers and focused on the global structure of the boundaries rather than pixel-wise overlap. The classical Hausdorff distance is defined as the maximum of the directed distances from each set to the other:
where the directed Hausdorff distance is given by
and is a underlying norm, typically the Euclidean distance. This formulation is highly non-convex and non-differentiable, and extremely sensitive to a single outlier point; a single point in A far from any point in B will cause to be large regardless of the proximity of all other points. To mitigate this for practical optimization, a more general, differentiable approximation is used, often based on computing statistics over the distances rather than the strict maximum. The generalized loss function for a predicted set B against a ground truth set A is formulated using a smooth rank-based approximation. One common approach is to replace the max and min operators with their smooth counterparts, such as the log-sum-exp for the maximum and a simple average or a soft-minimum for the minimum. The directed distance can be approximated as
for a finite p, but a more robust and differentiable version uses the concept of the Hausdorff distance based on the k-th ranked distance rather than the maximum. The k-th ranked distance is defined as the k-th smallest value of for . The loss is then
where
This is known as the Partial Hausdorff Distance and is less sensitive to outliers.
For integration with gradient-based deep learning, a fully differentiable loss is essential. This is achieved by expressing the minimum and ranked maximum operations in terms of continuous functions. The minimum distance from a point a to the set B can be approximated with a softmin function:
where is a temperature parameter controlling the sharpness of the approximation; as , this approaches the true minimum. Similarly, the directed distance can be approximated by a softmax over the distances for all :
The complete symmetric Hausdorff loss is then
The gradient of this loss with respect to a point in the predicted set is complex due to the nested nature of the operations.
It involves the chain rule through the softmax and softmin functions. The derivative of the softmin function with respect to a point b is:
This gradient assigns a weight to each point b based on its proximity to a. The derivative of the softmax-directed distance with respect to is given by the Jacobian of the softmax, which is
The full gradient is then obtained by summing the contributions from all points through the chain rule:
The second term requires a symmetric calculation for points in A. In practice, for image segmentation, the point sets A and B are the coordinates of the boundary pixels of the ground truth and predicted masks. The Hausdorff Distance Loss directly penalizes the largest segmentation error, encouraging the model to accurately capture the entire contour of an object. This makes it highly effective for medical image segmentation, where the precise delineation of organ boundaries is critical, and it complements pixel-wise losses like Dice or Cross-Entropy by focusing on the worst-case error rather than the average.
10.5.3.10 Python Code to Generate Figure 77 Illustrating 1D Wasserstein Distance of Two Distributions Having Parameters: Normal() and Normal()
The Python code below produces the Figure 77 illustrating 1D Wasserstein Distance of two distributions having parameters: Normal() and Normal().
Figure 77.
1D Wasserstein Distance of two distributions having parameters: Normal() and Normal()
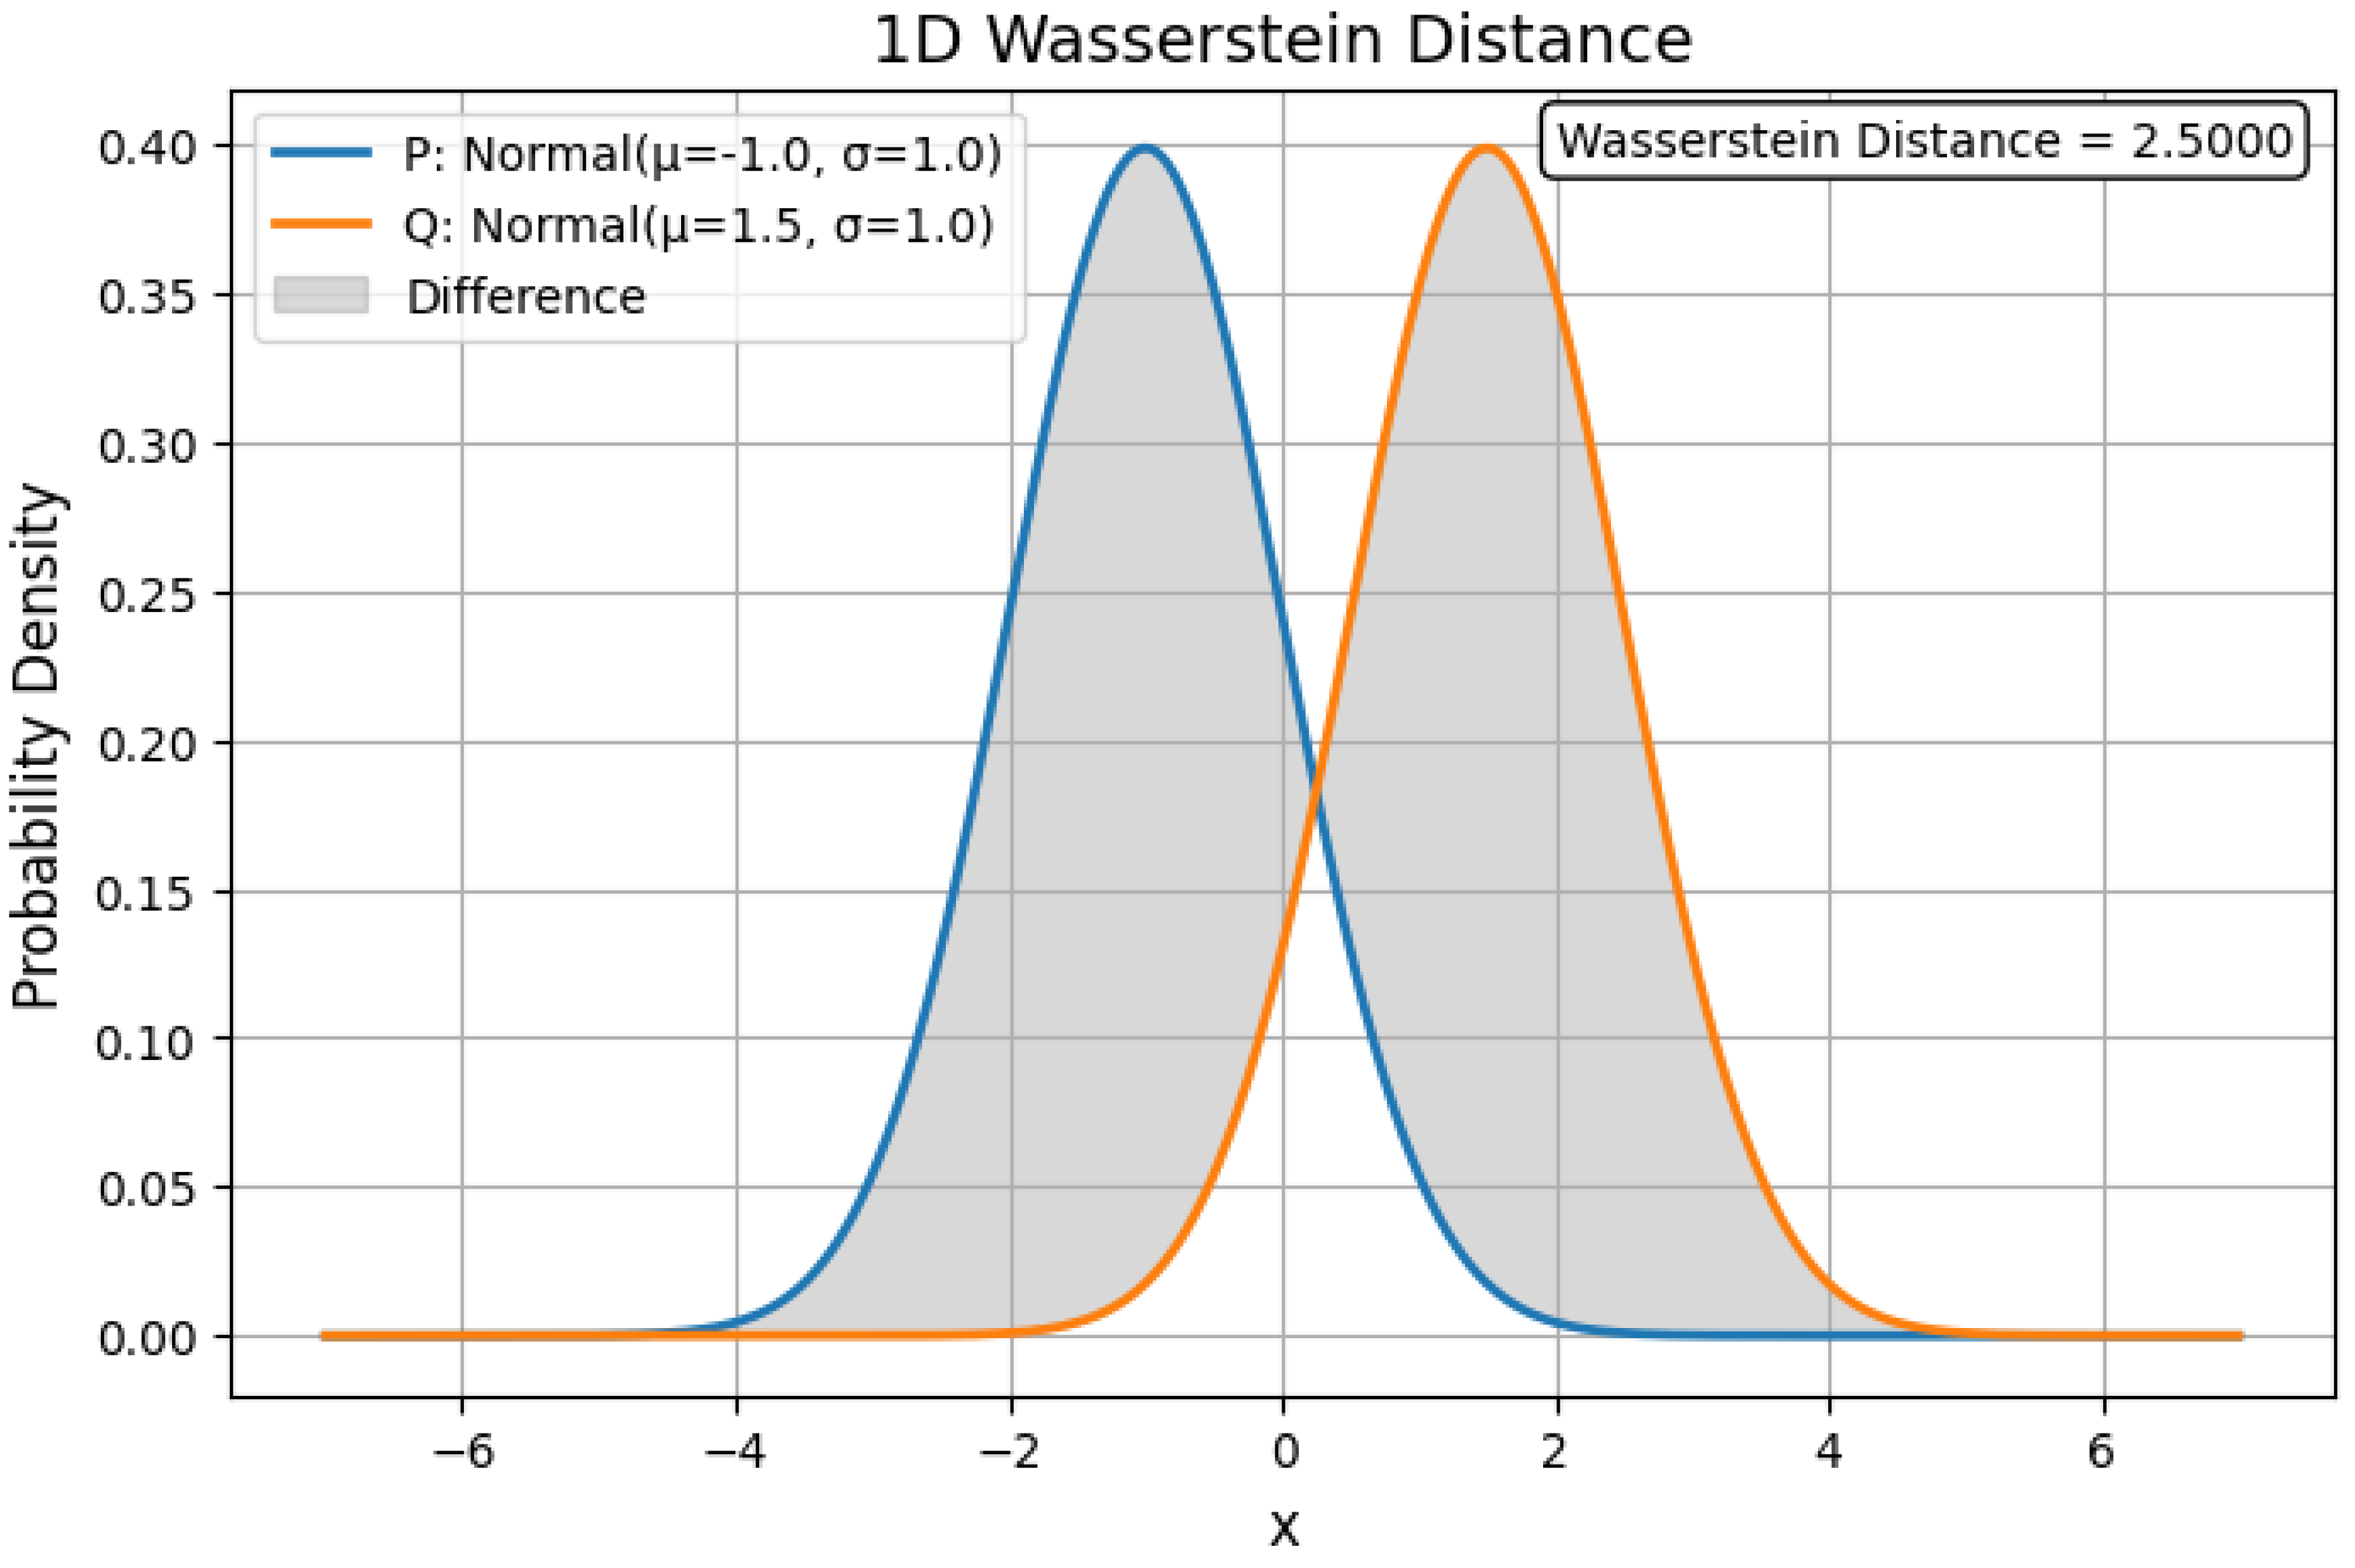
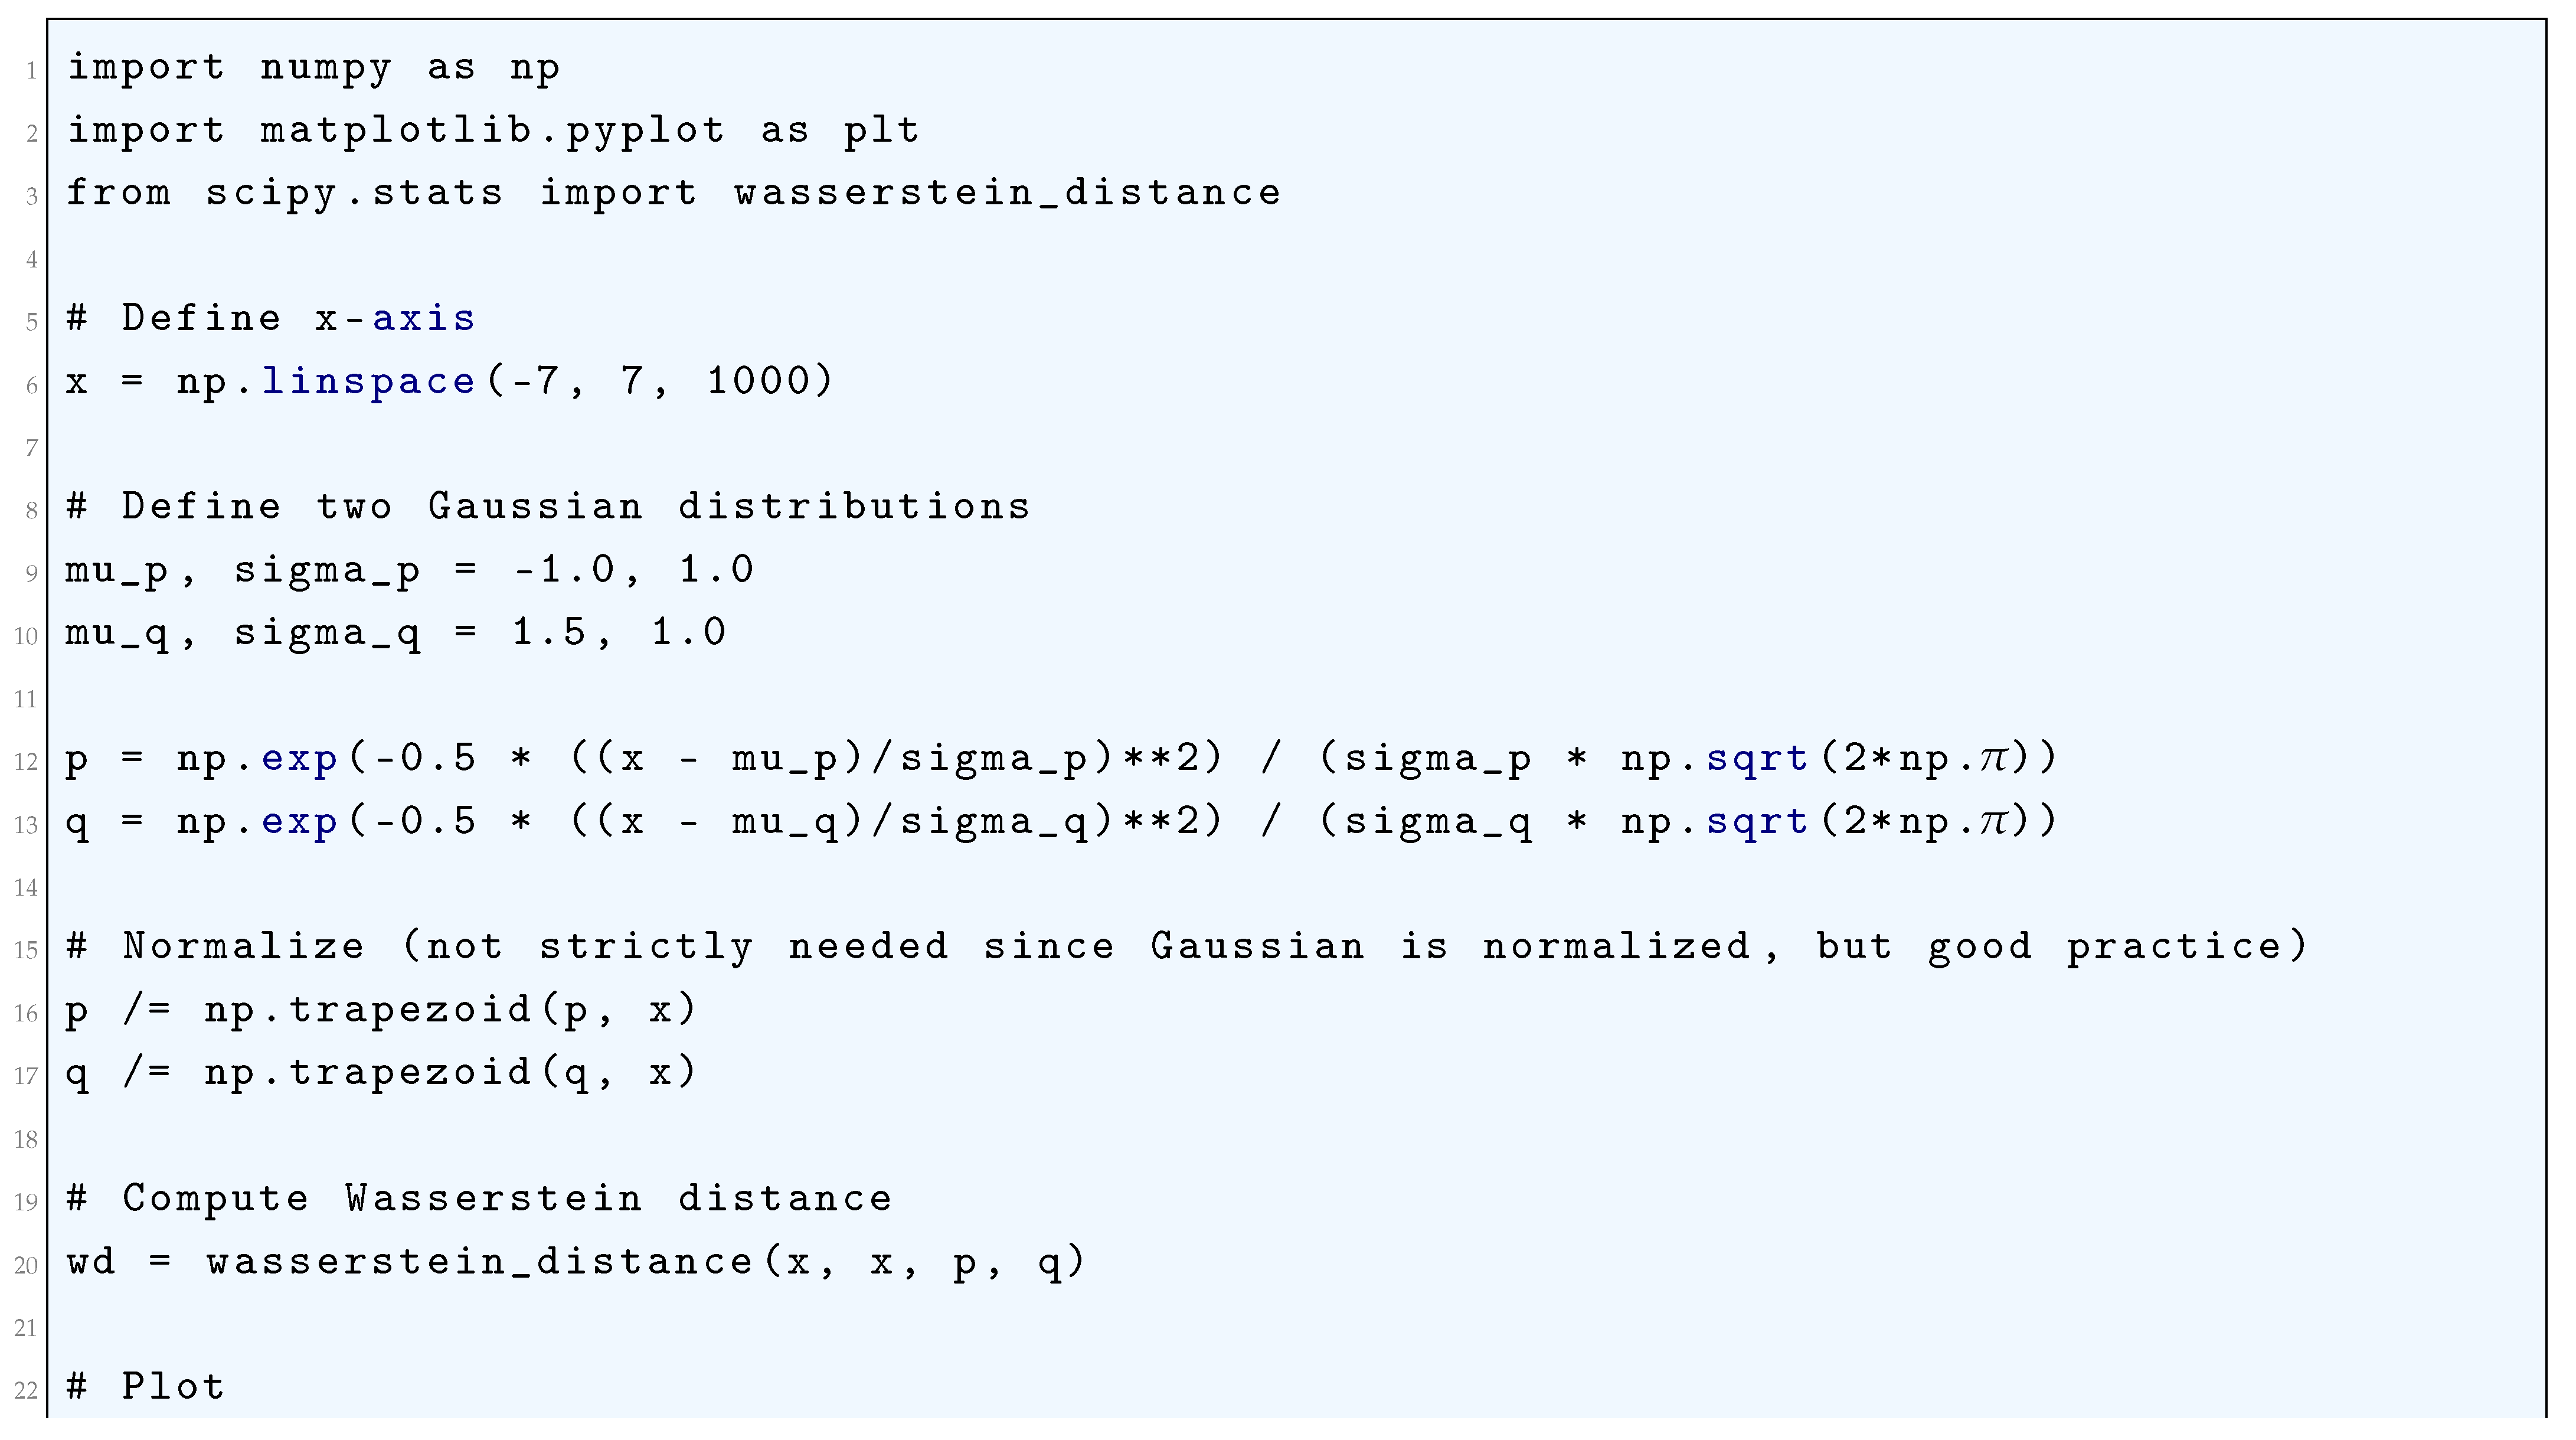
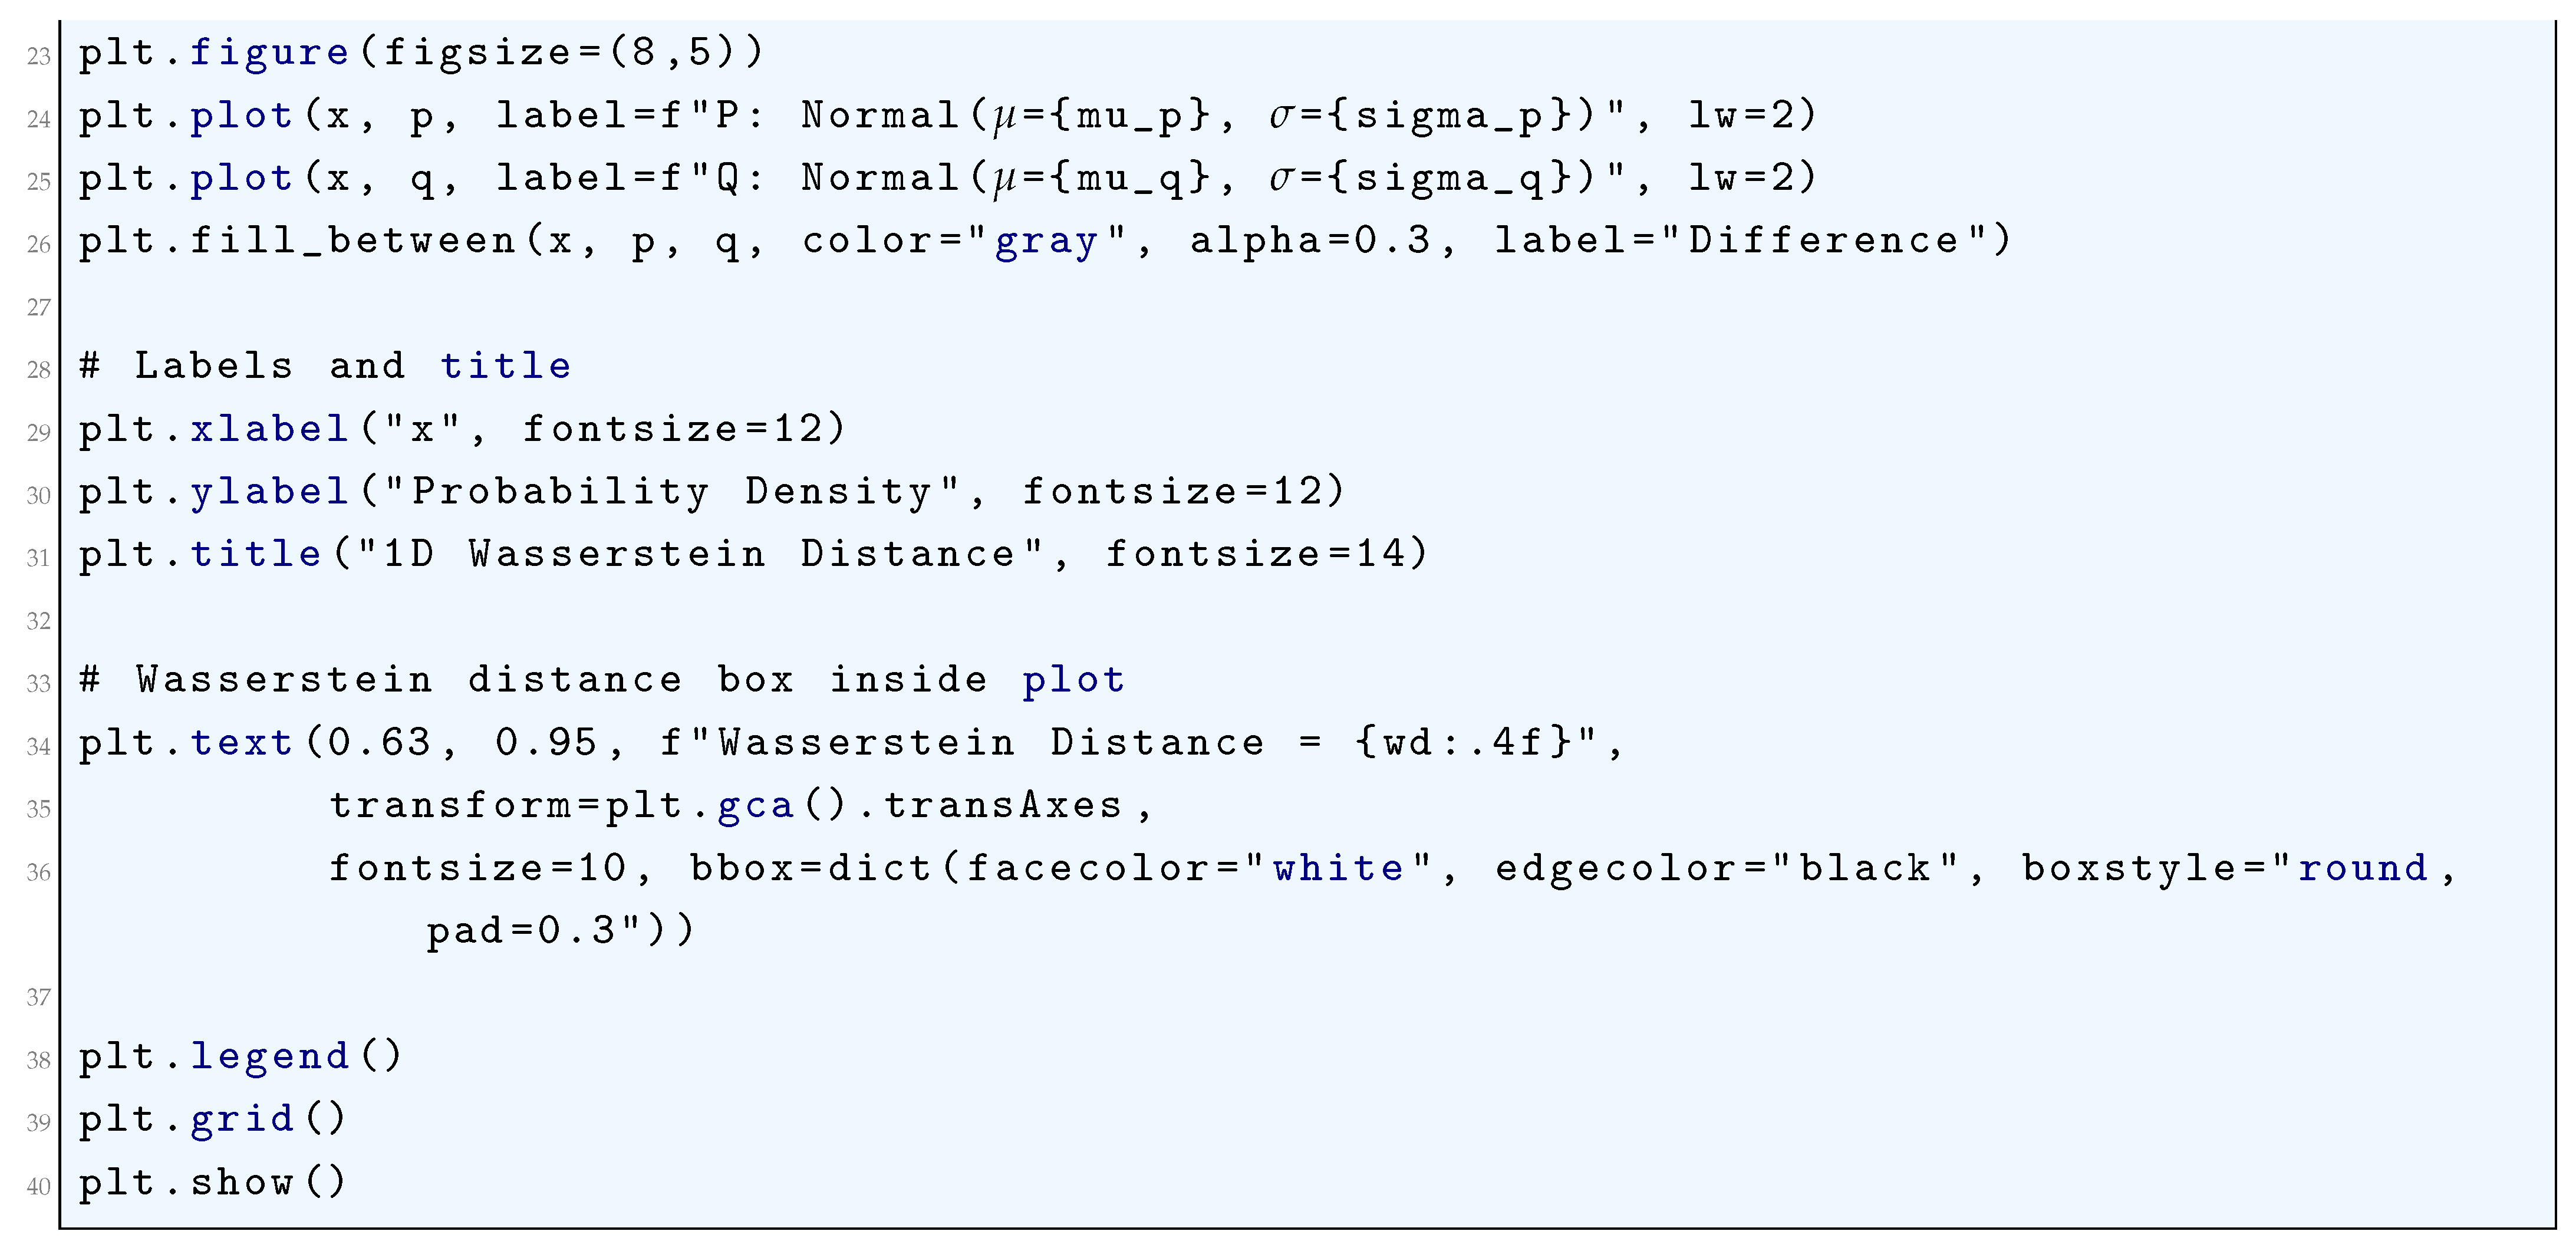
10.5.3.11 Python Code to Generate Figure 78 Illustrating Multidimensional Wasserstein Distance of Two Distributions Having Parameters, Distribution A: , Distribution B:
The Python code below produces the Figure 78 illustrating Multidimensional Wasserstein Distance of two distributions having parameters, Distribution A: , Distribution B: .
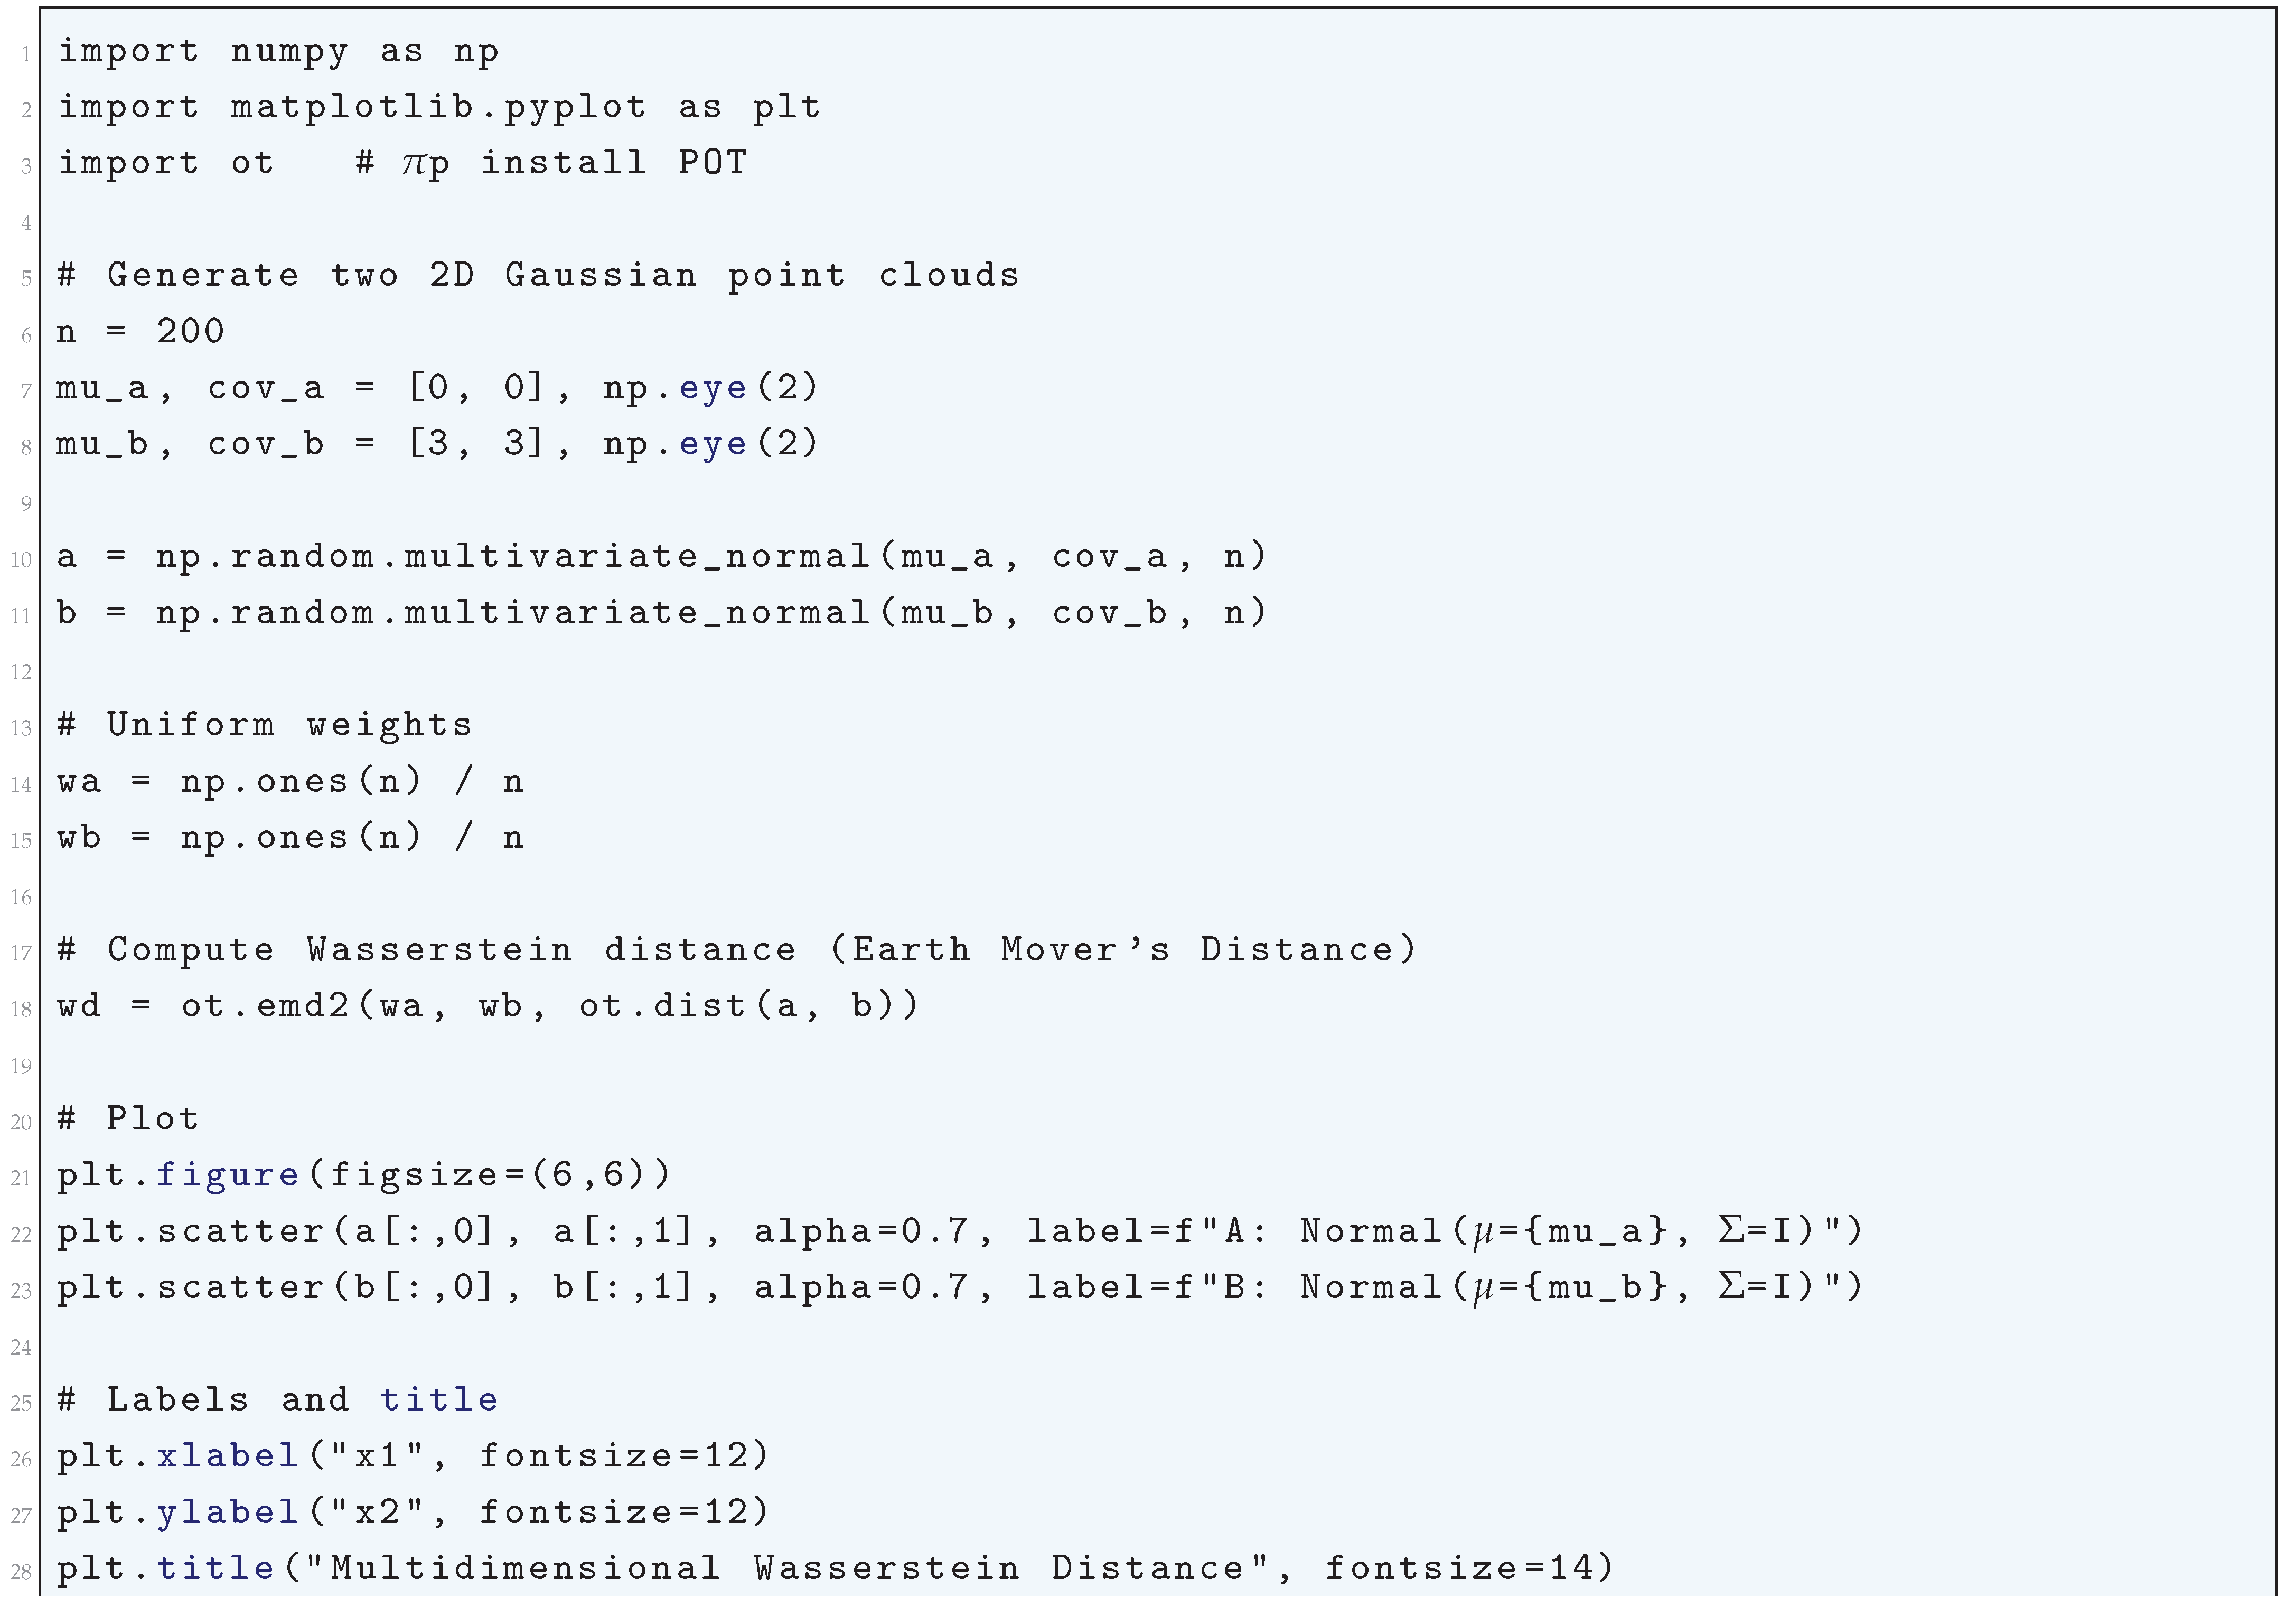
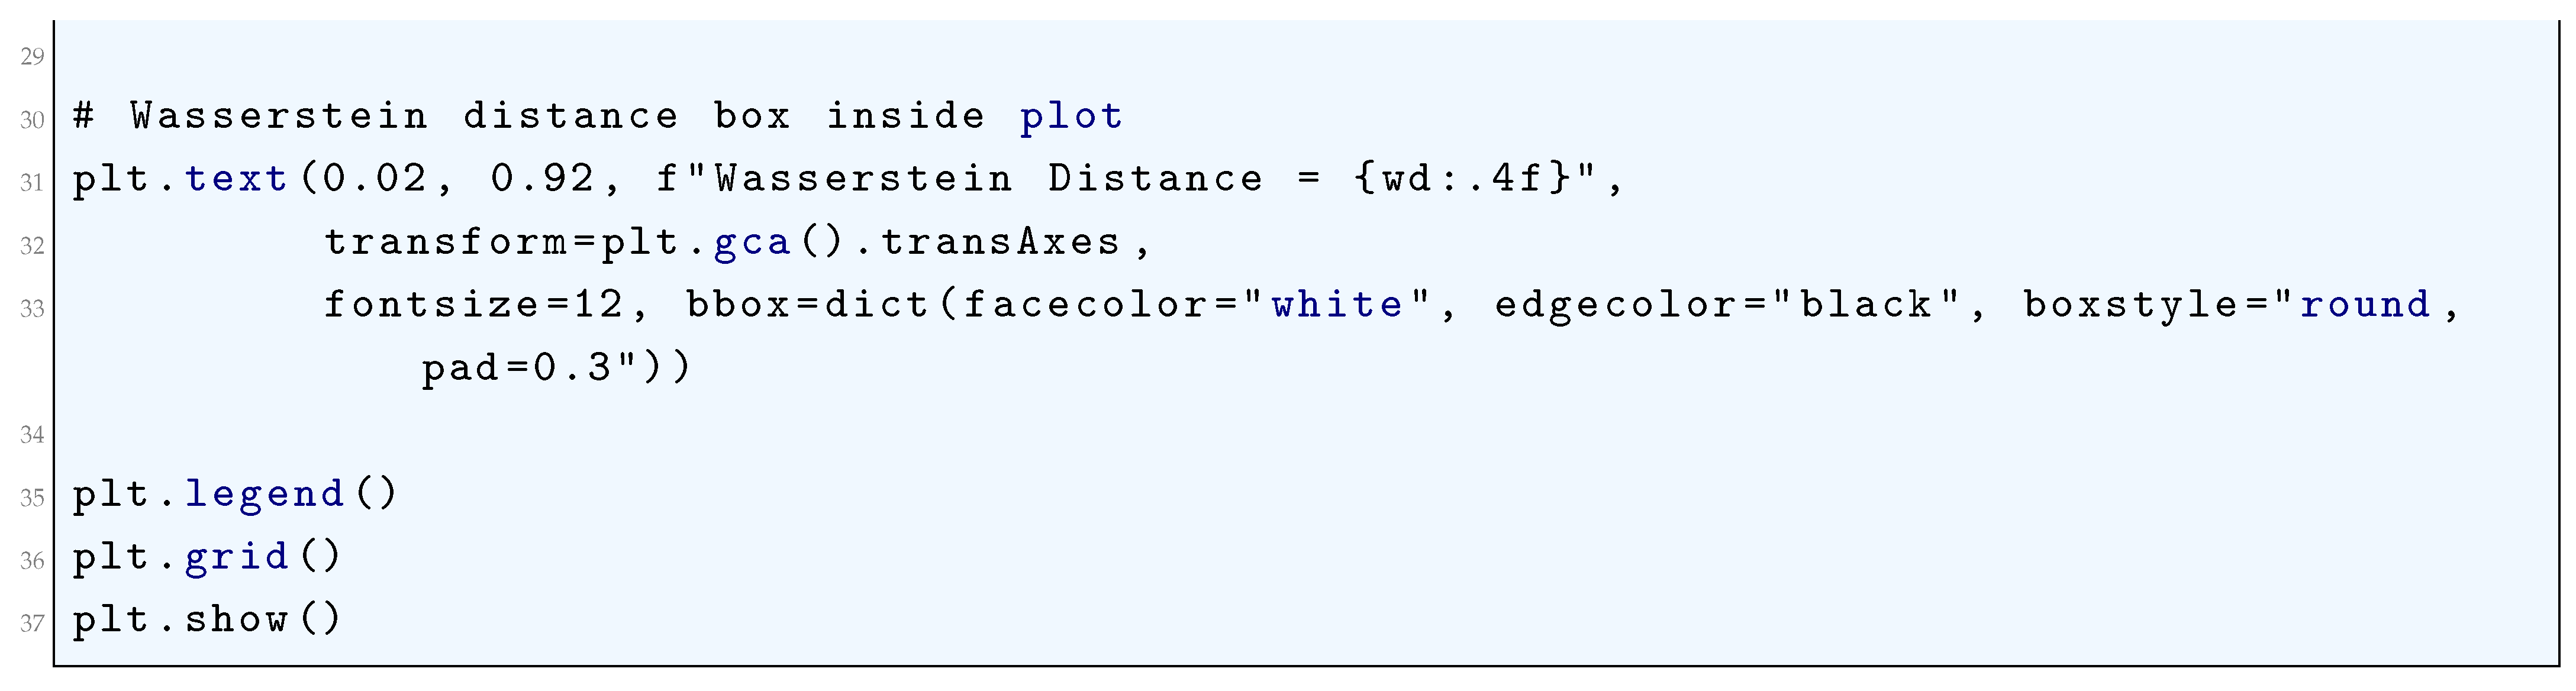
Figure 78.
Multidimensional Wasserstein Distance of two distributions having parameters, Distribution A: , Distribution B:
Figure 78.
Multidimensional Wasserstein Distance of two distributions having parameters, Distribution A: , Distribution B:
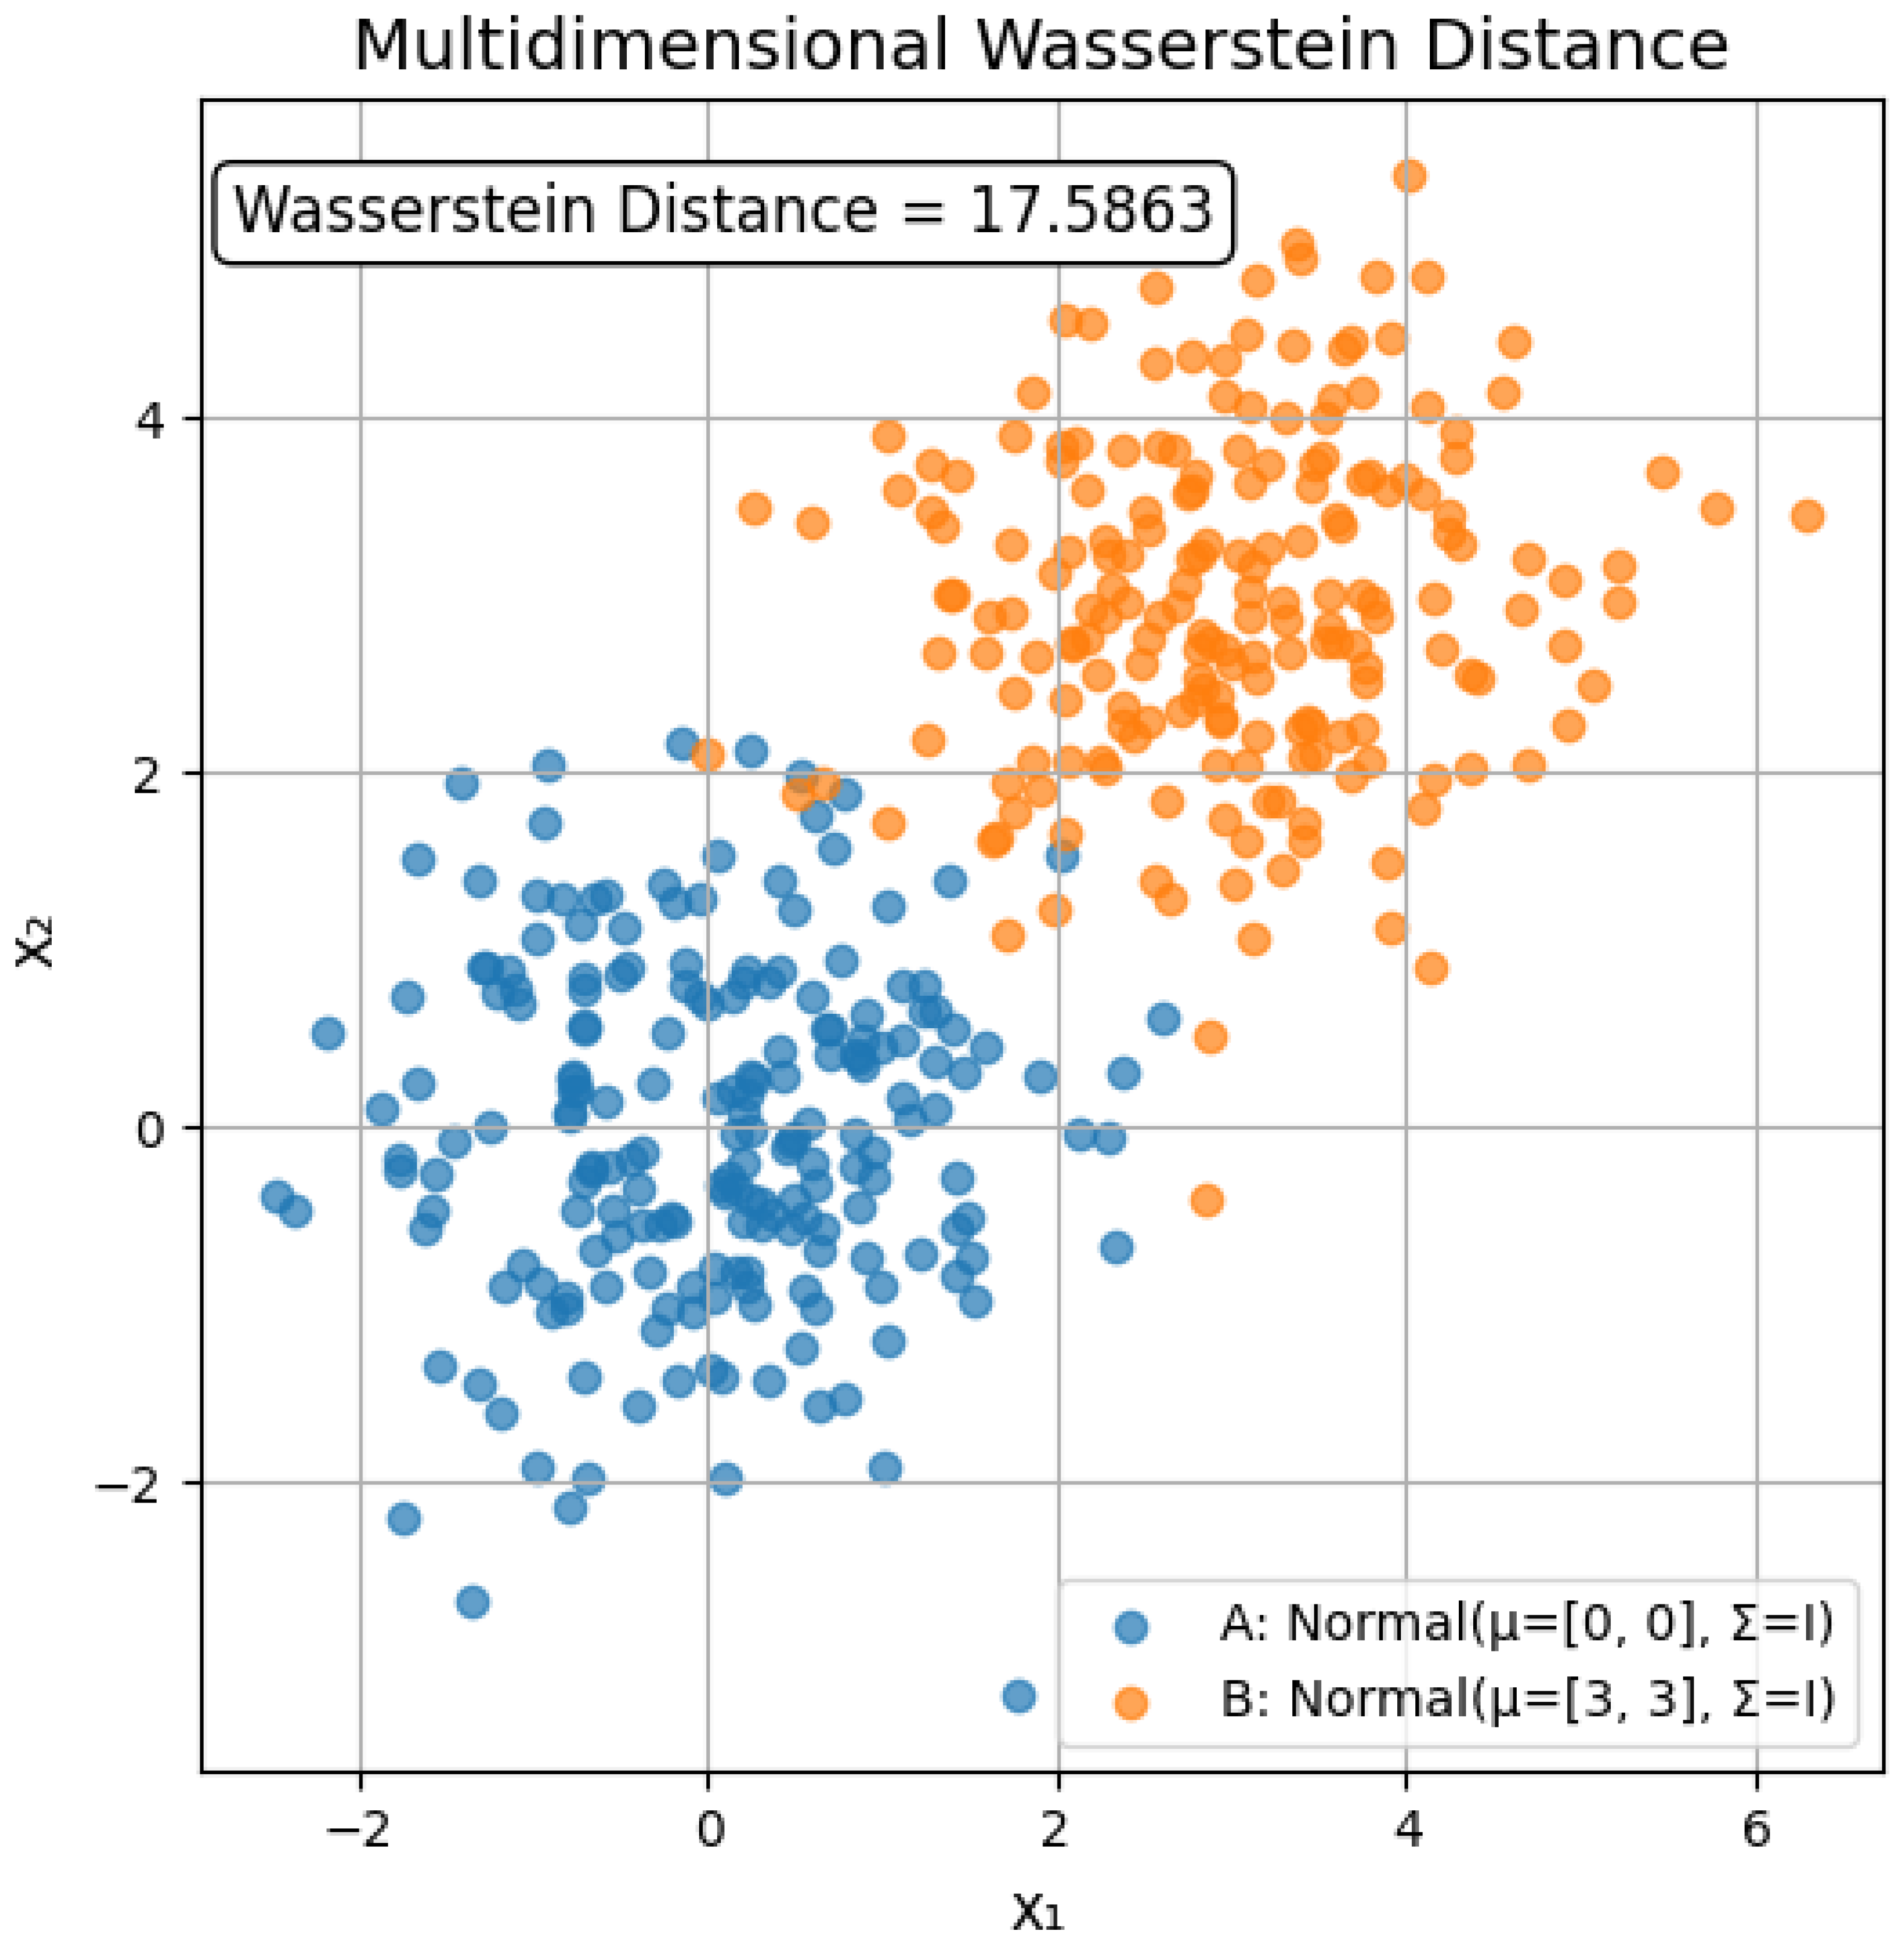
10.5.3.12 Python Code to Generate Figure 79 Comparing Equal CDF, WGAN Critic, GAN Discriminator
The Python code below produces the Figure 79 comparing Equal CDF, WGAN Critic, GAN Discriminator.
Figure 79.
Comparison: Equal CDF, WGAN Critic, GAN Discriminator
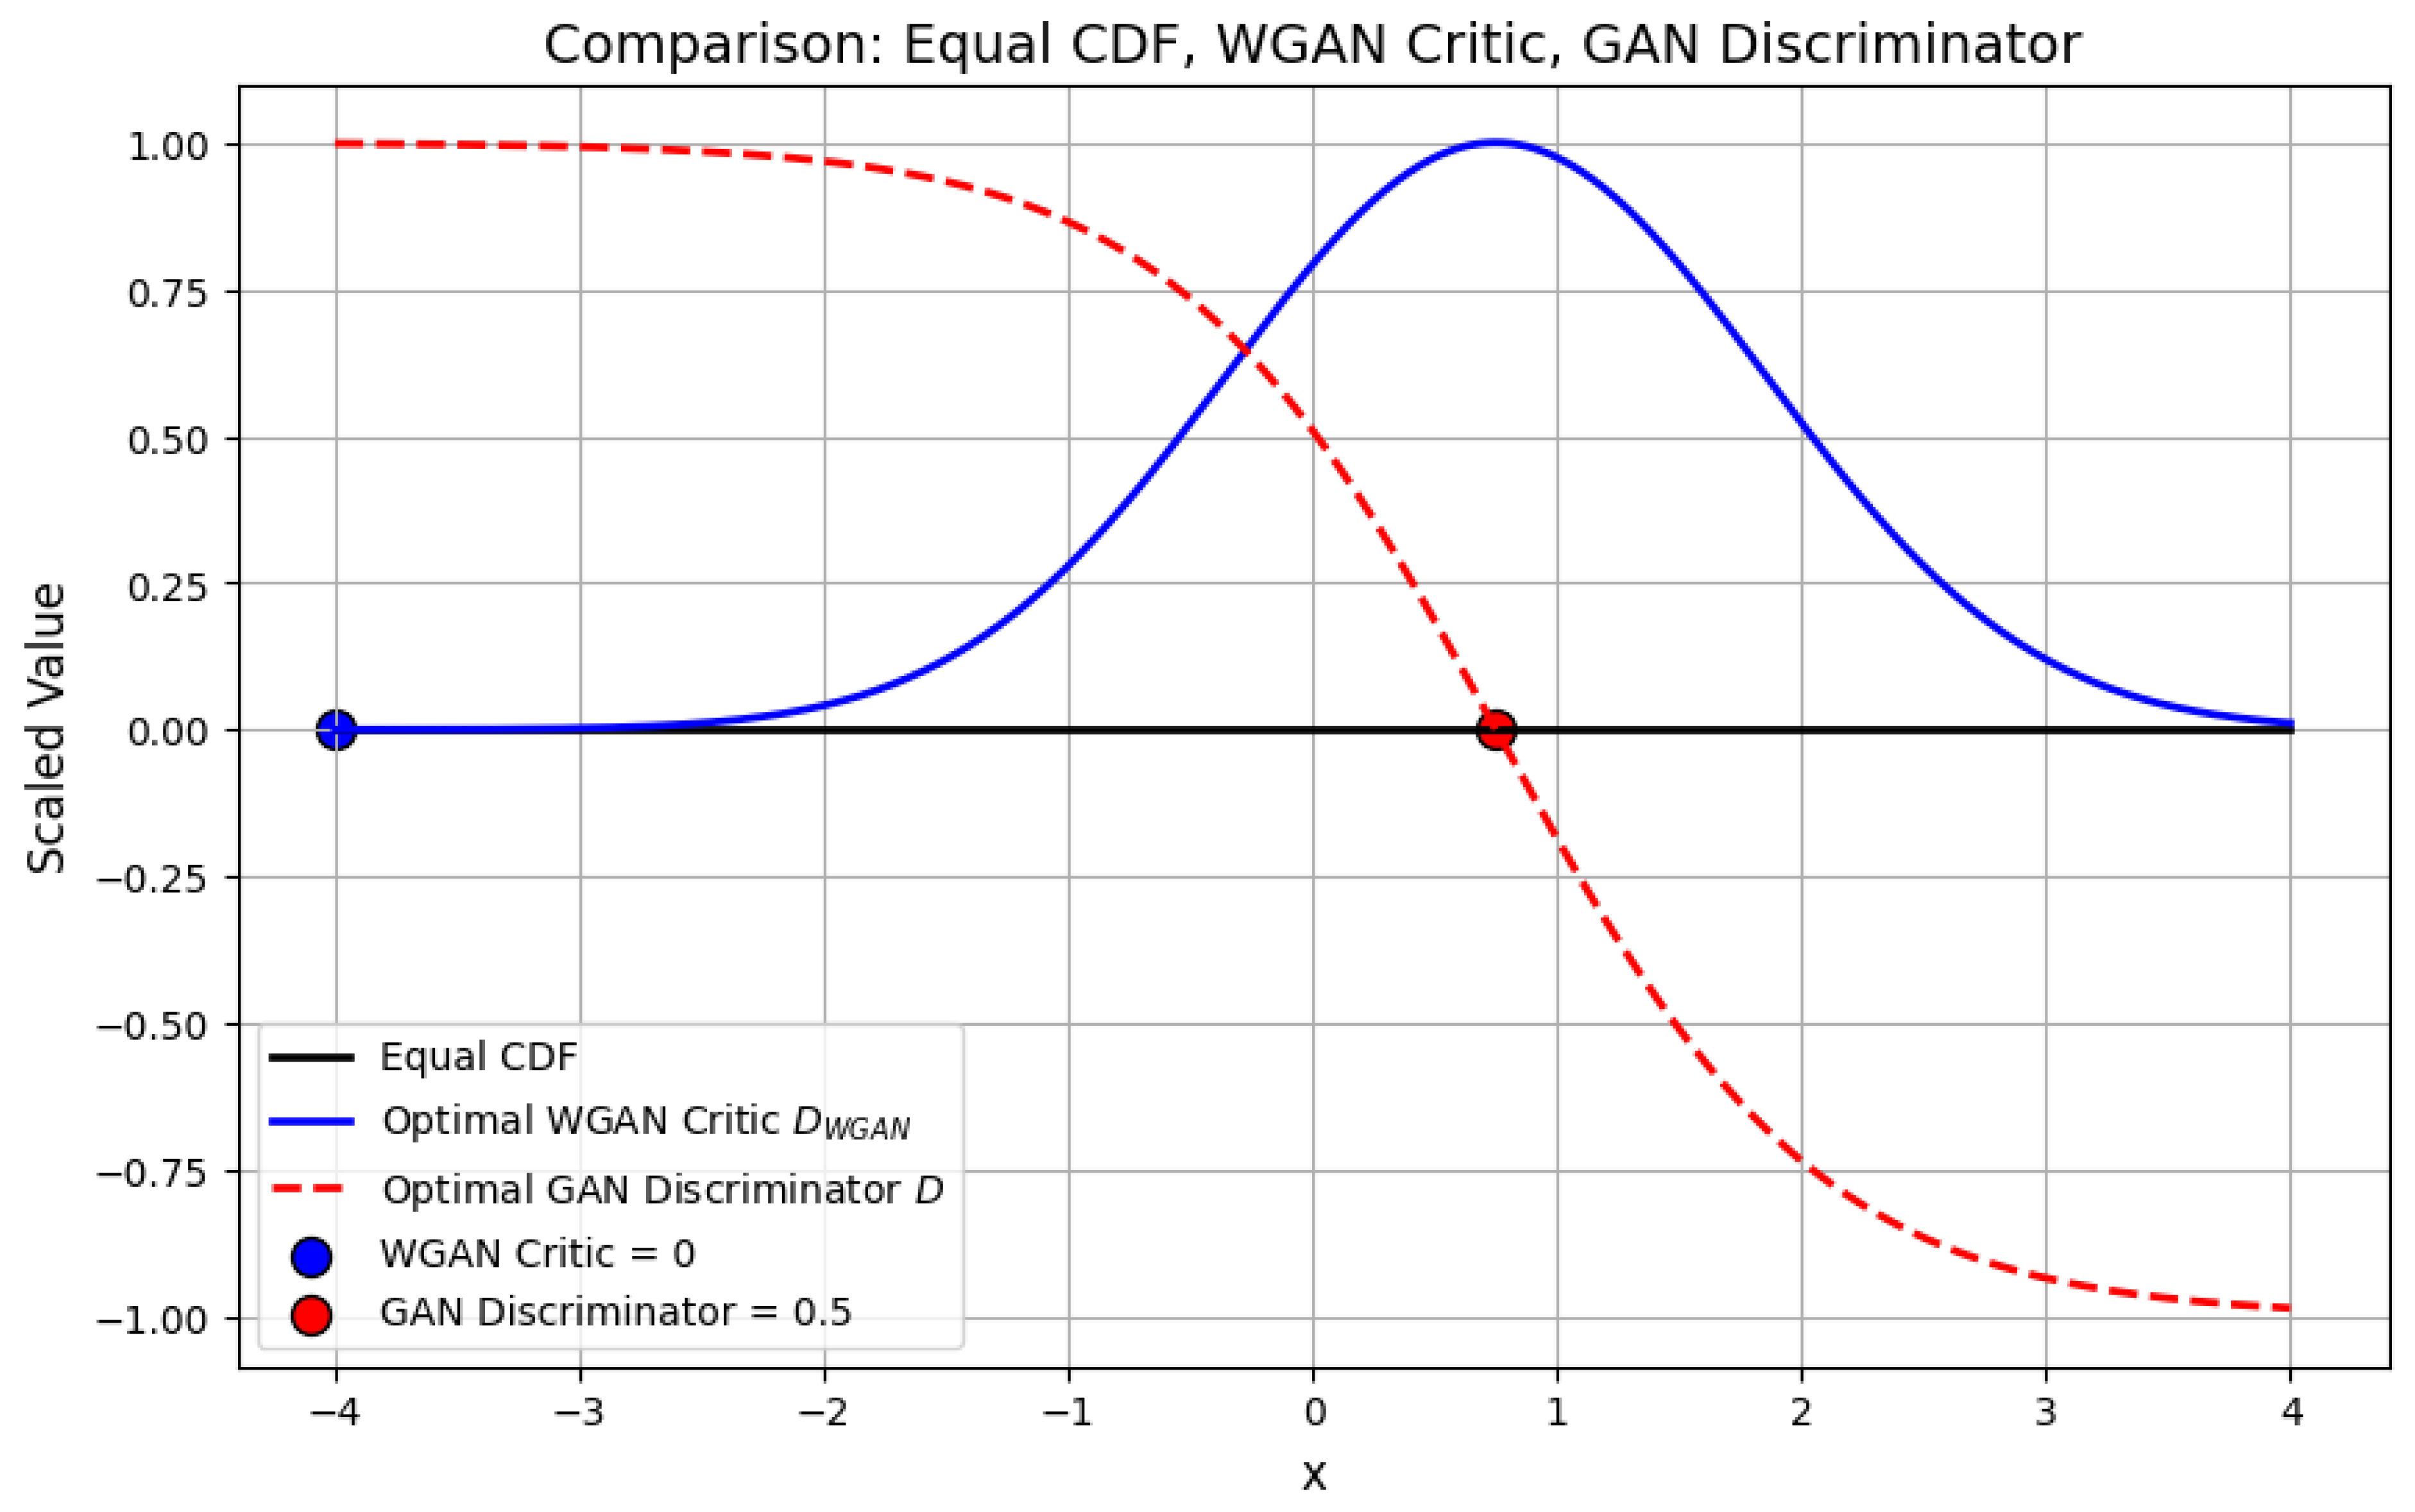
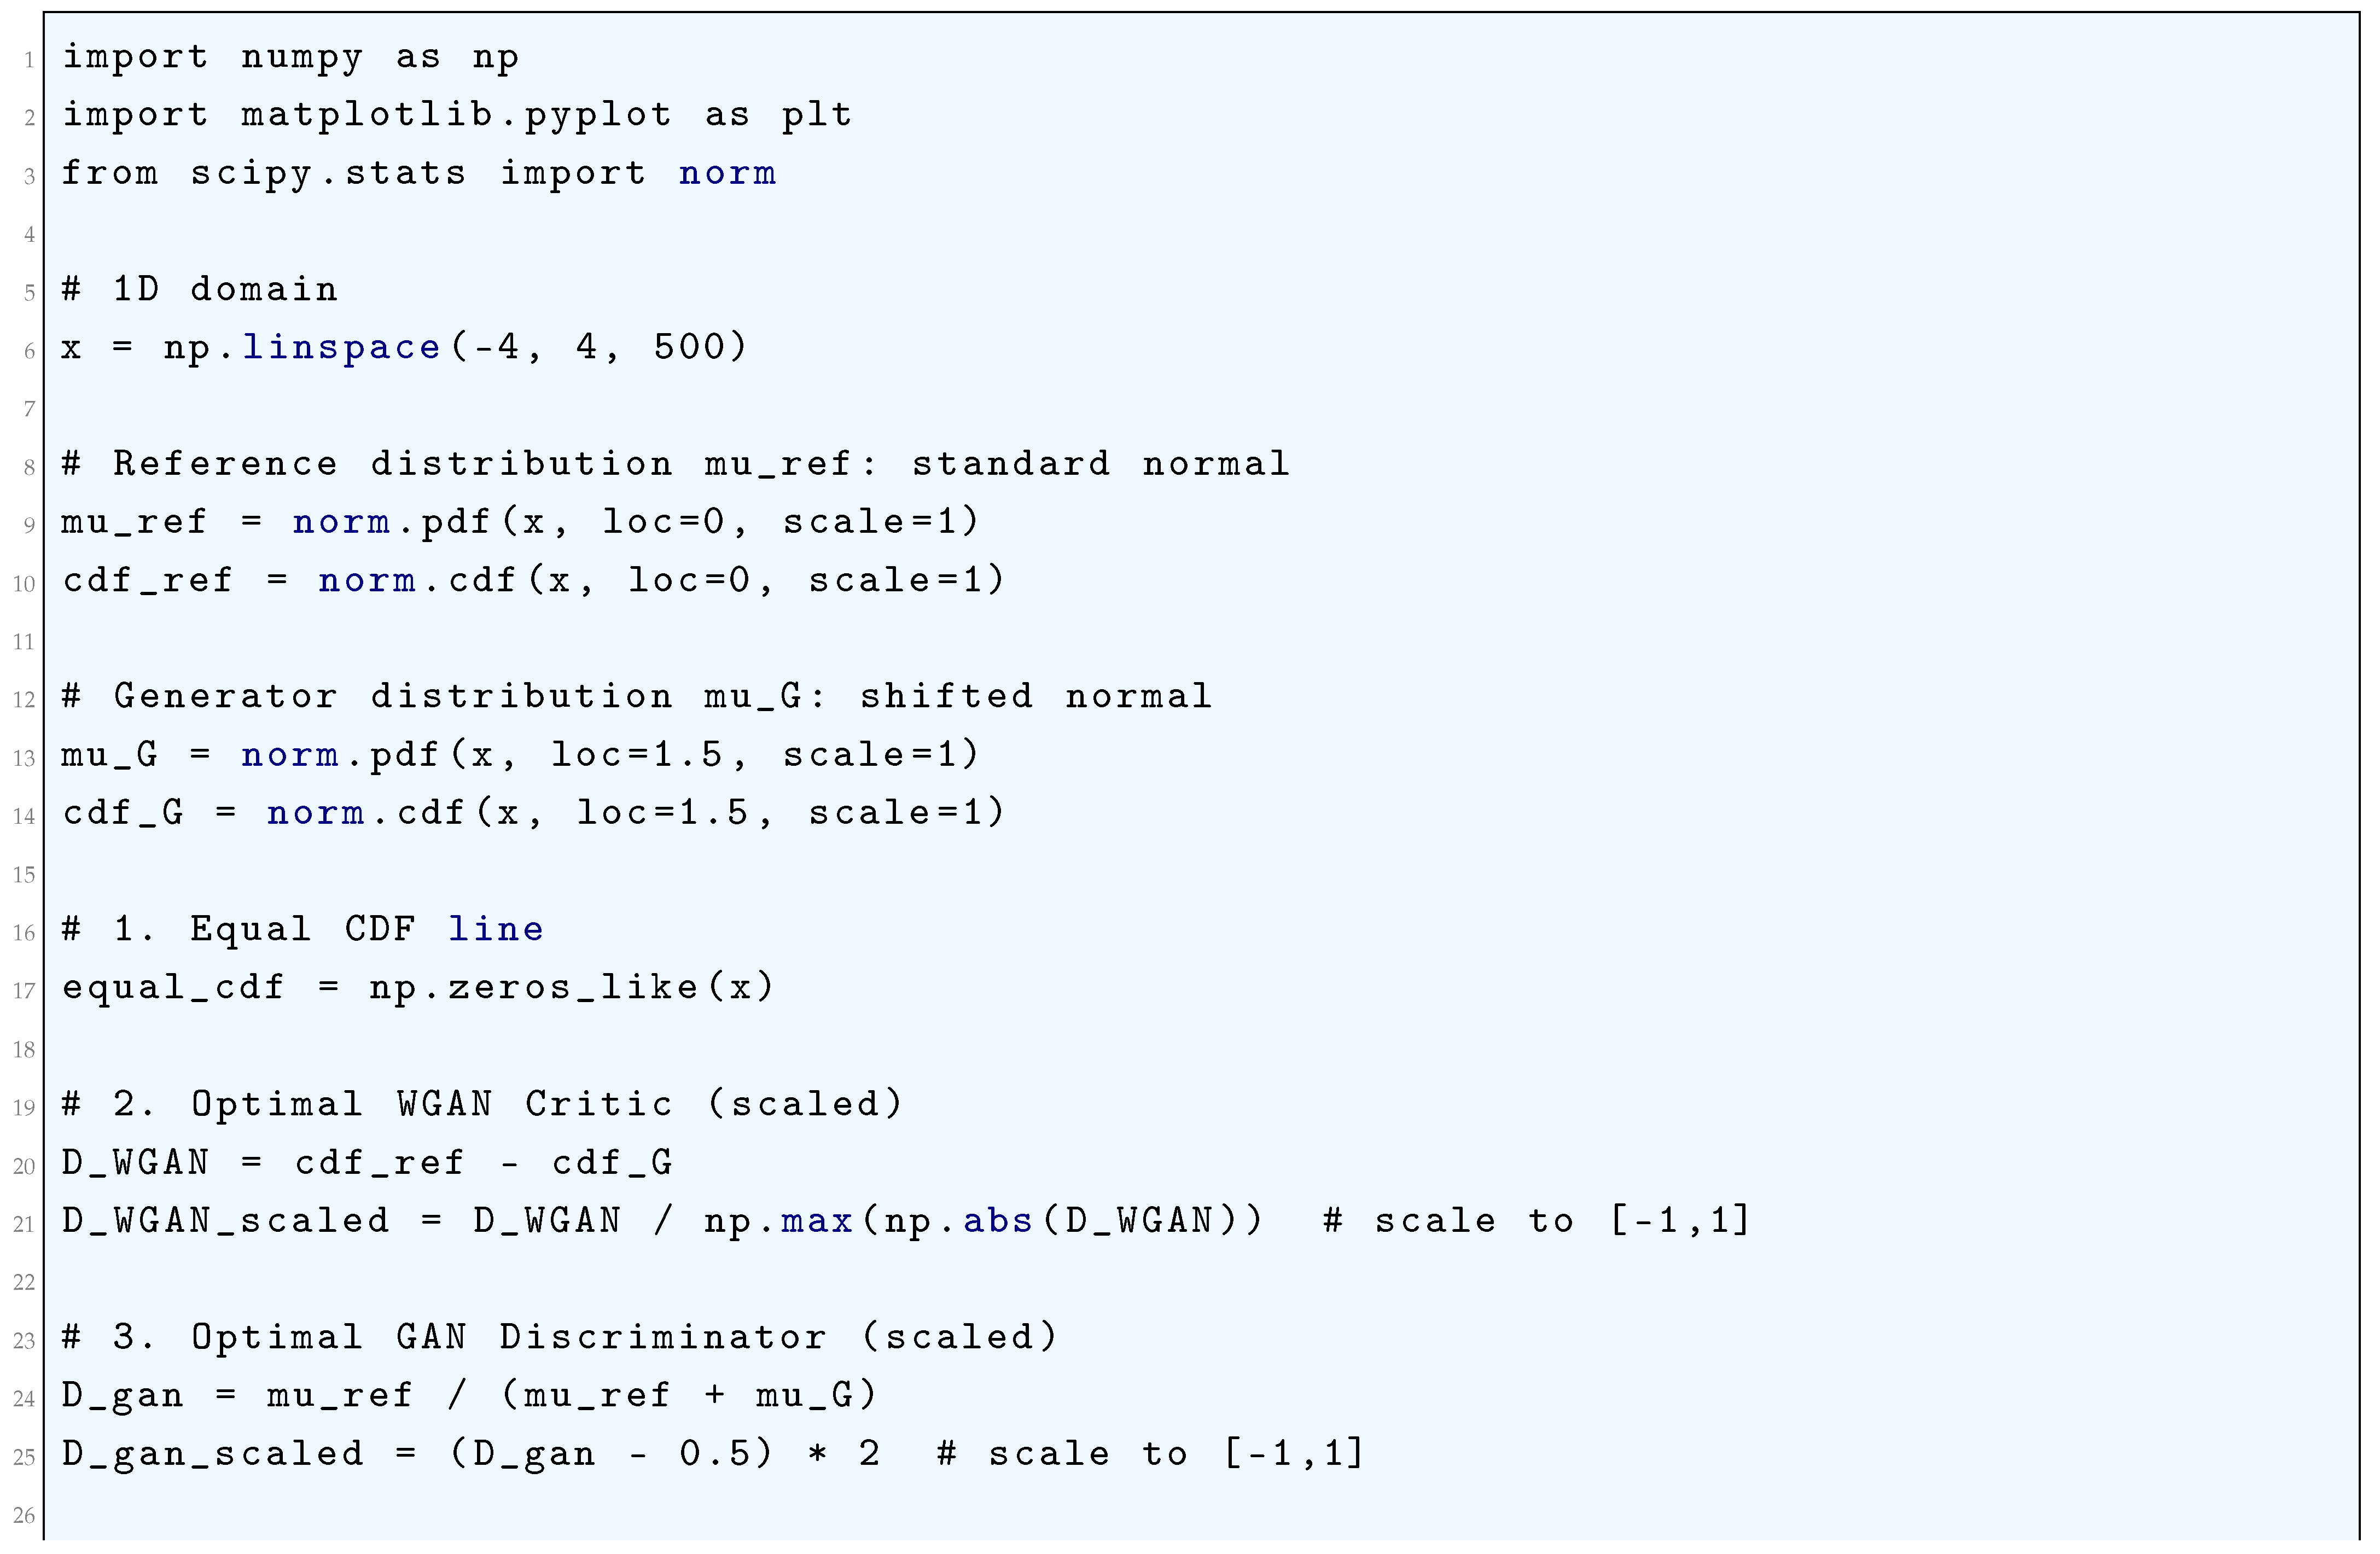
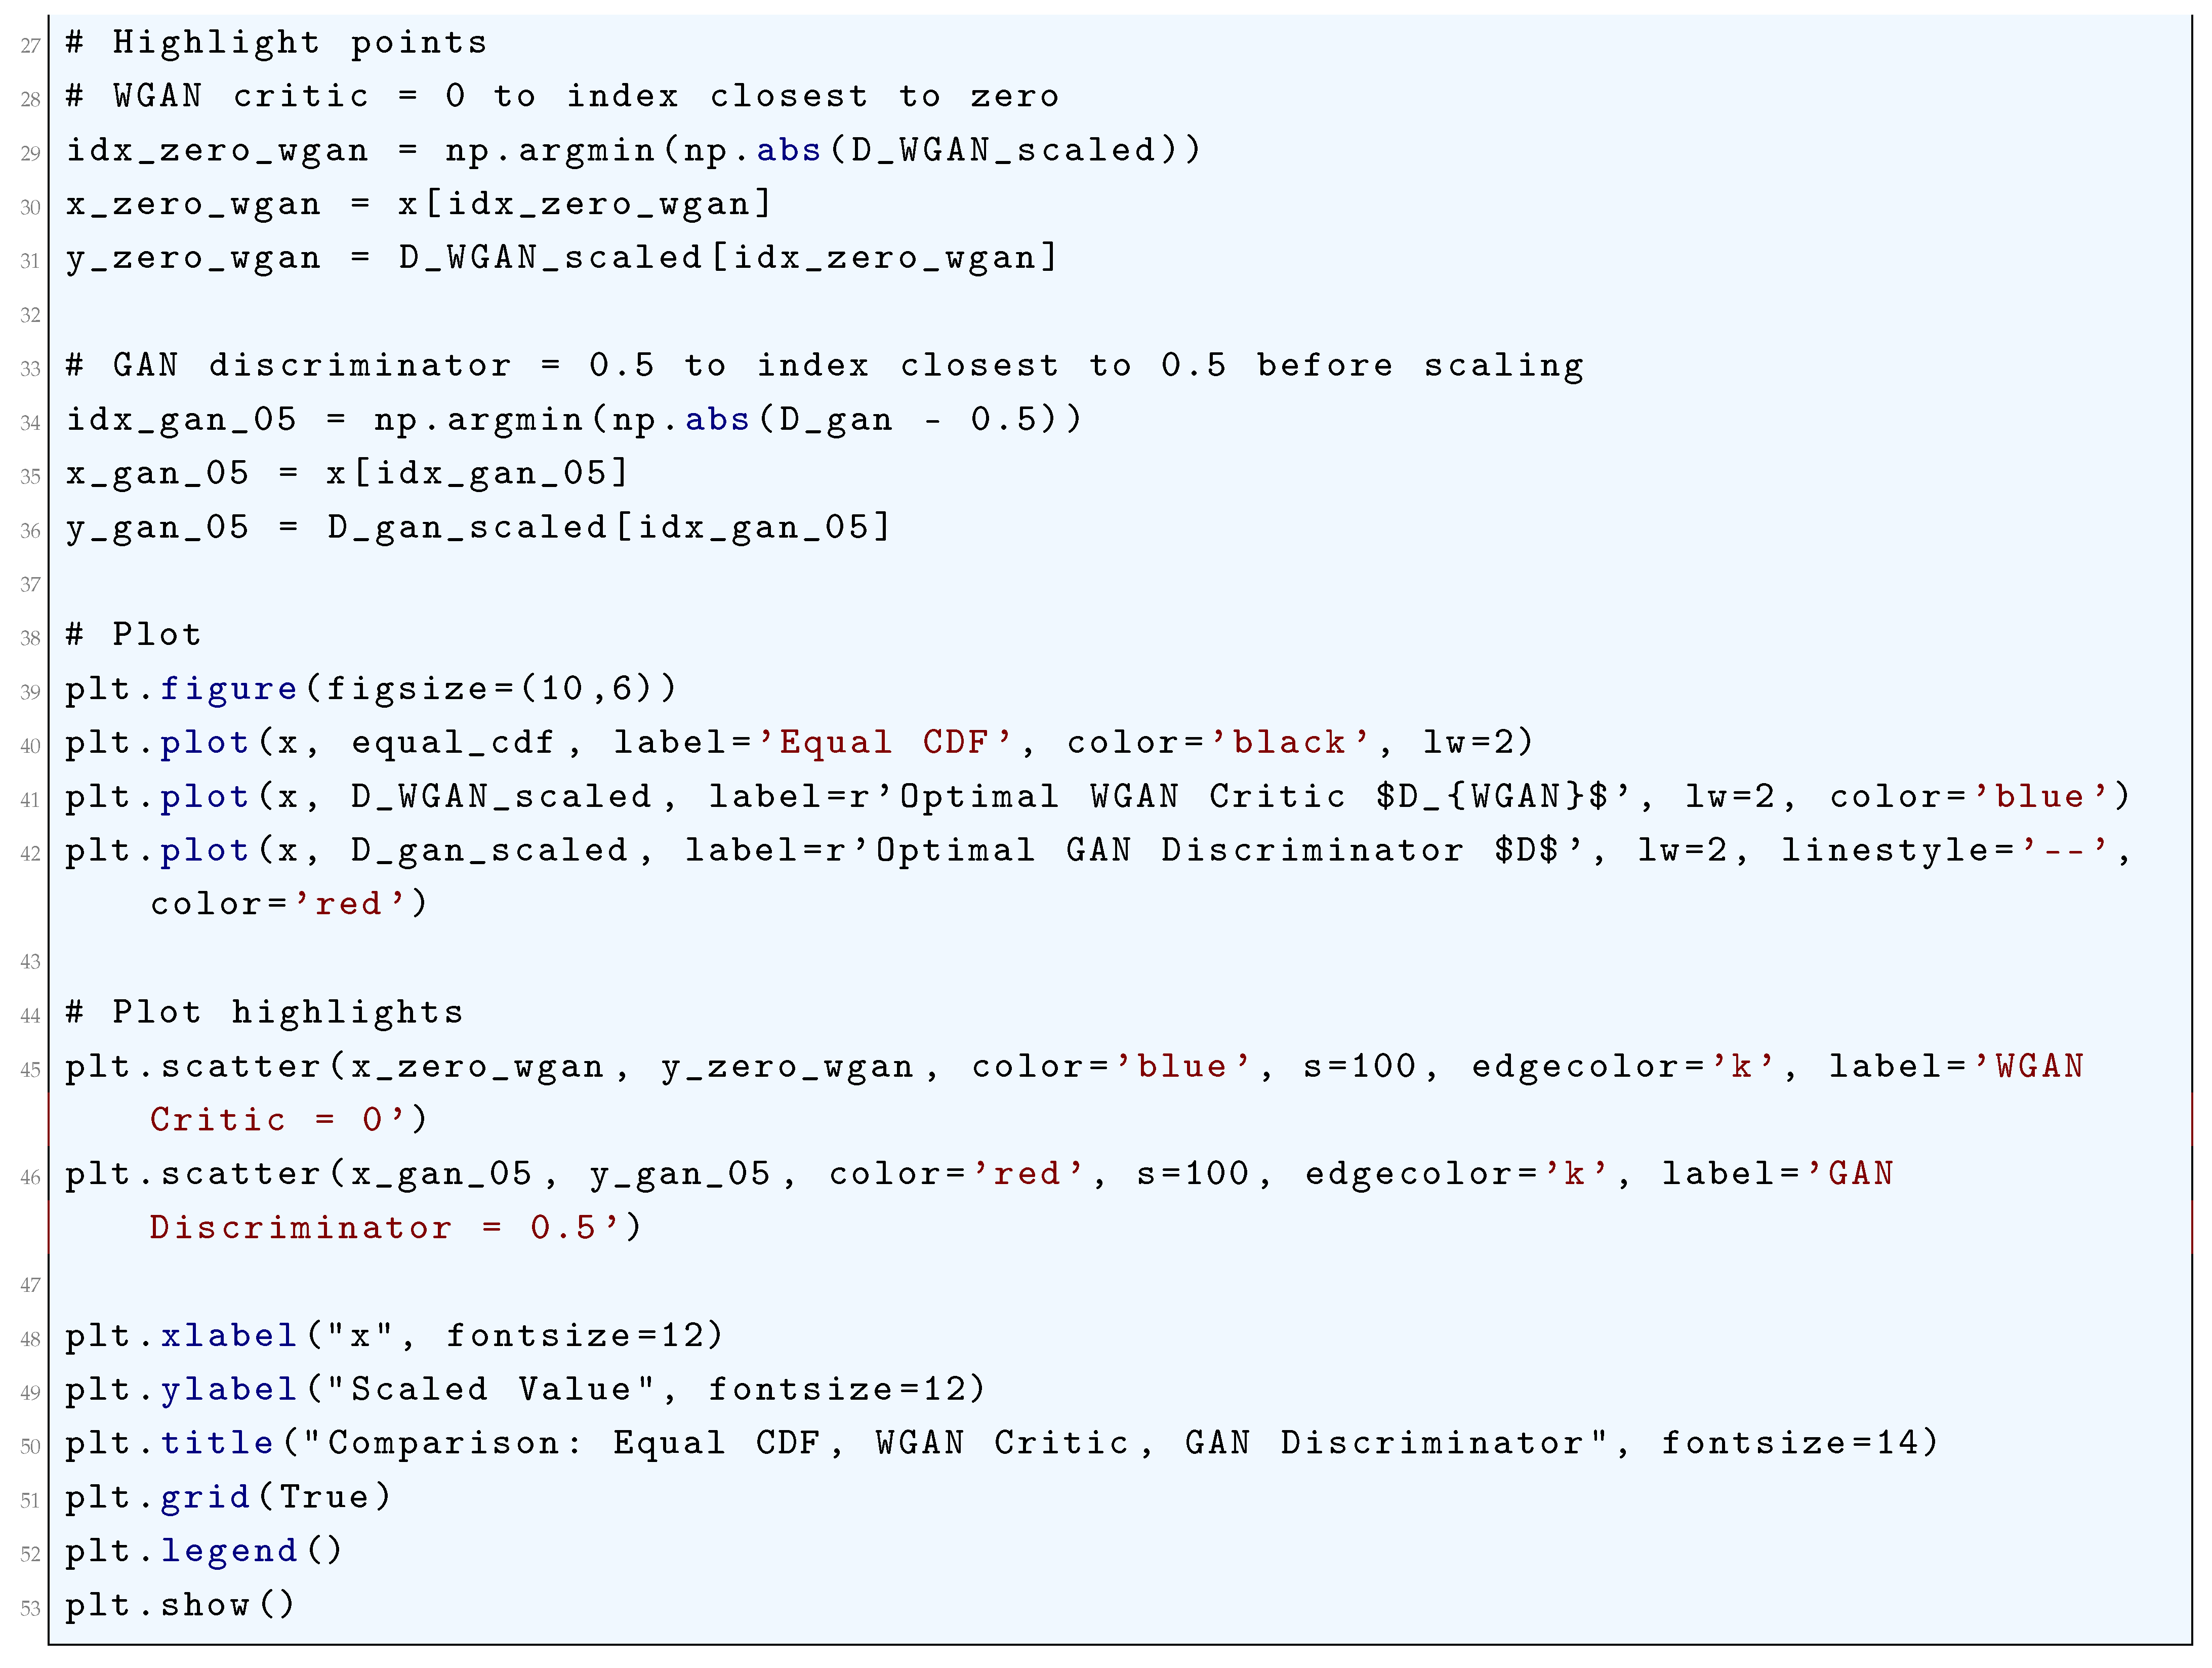
10.5.3.13 Python Code to Generate Figure 80 Illustrating Least Squares GAN (LSGAN) Loss Functions
The Python code below produces the Figure 80 illustrating Least Squares GAN (LSGAN) Loss Functions.
Figure 80.
Least Squares GAN (LSGAN) Loss Functions
10.5.3.14 Python Code to Generate Figure 81 Illustrating Standard GAN (Adversarial) Loss Functions
The Python code below produces the Figure 81 illustrating Standard GAN (Adversarial) Loss Functions.
Figure 81.
Standard GAN (Adversarial) Loss Functions

10.5.3.15 Python Code to Generate Figure 82 Illustrating Contrastive Loss Functions
The Python code below produces the Figure 82 illustrating Contrastive Loss Functions.
Figure 82.
Contrastive Loss Functions
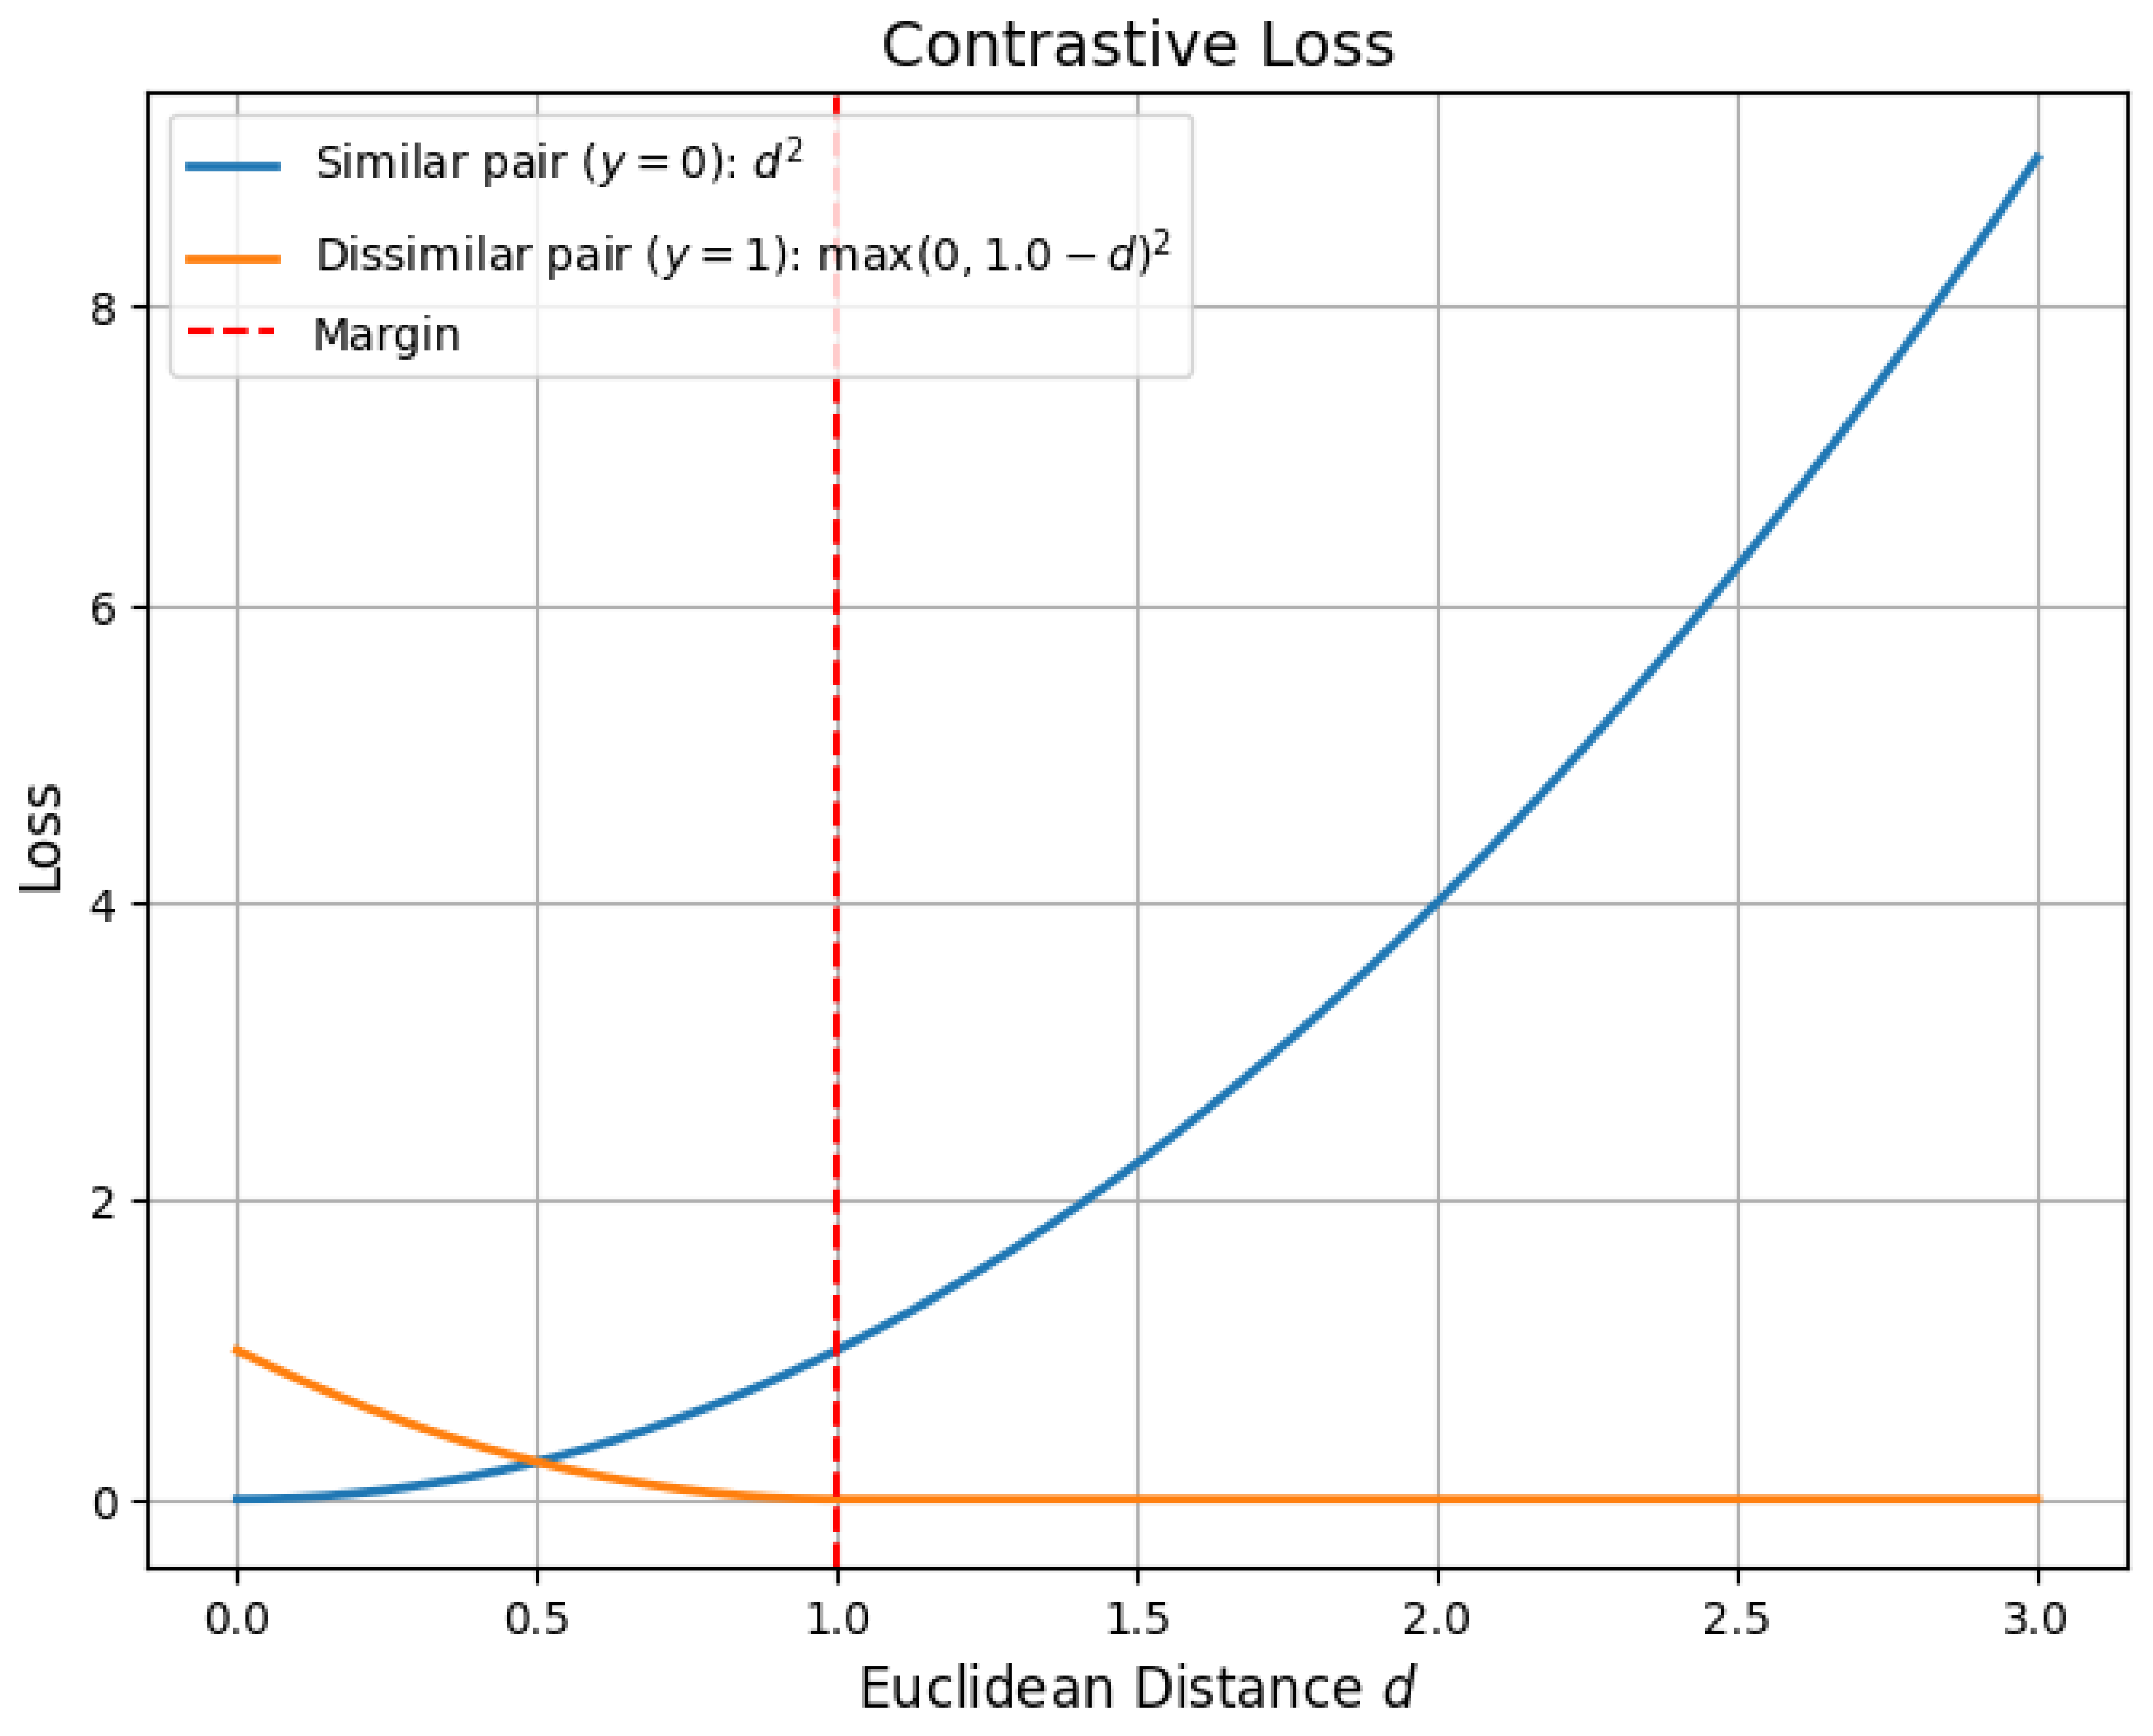
10.5.3.16 Python Code to Generate Figure 83 Illustrating Contrastive Loss Landscapes
The Python code below produces the Figure 83 illustrating Contrastive Loss Landscapes.
Figure 83.
Contrastive Loss Landscapes
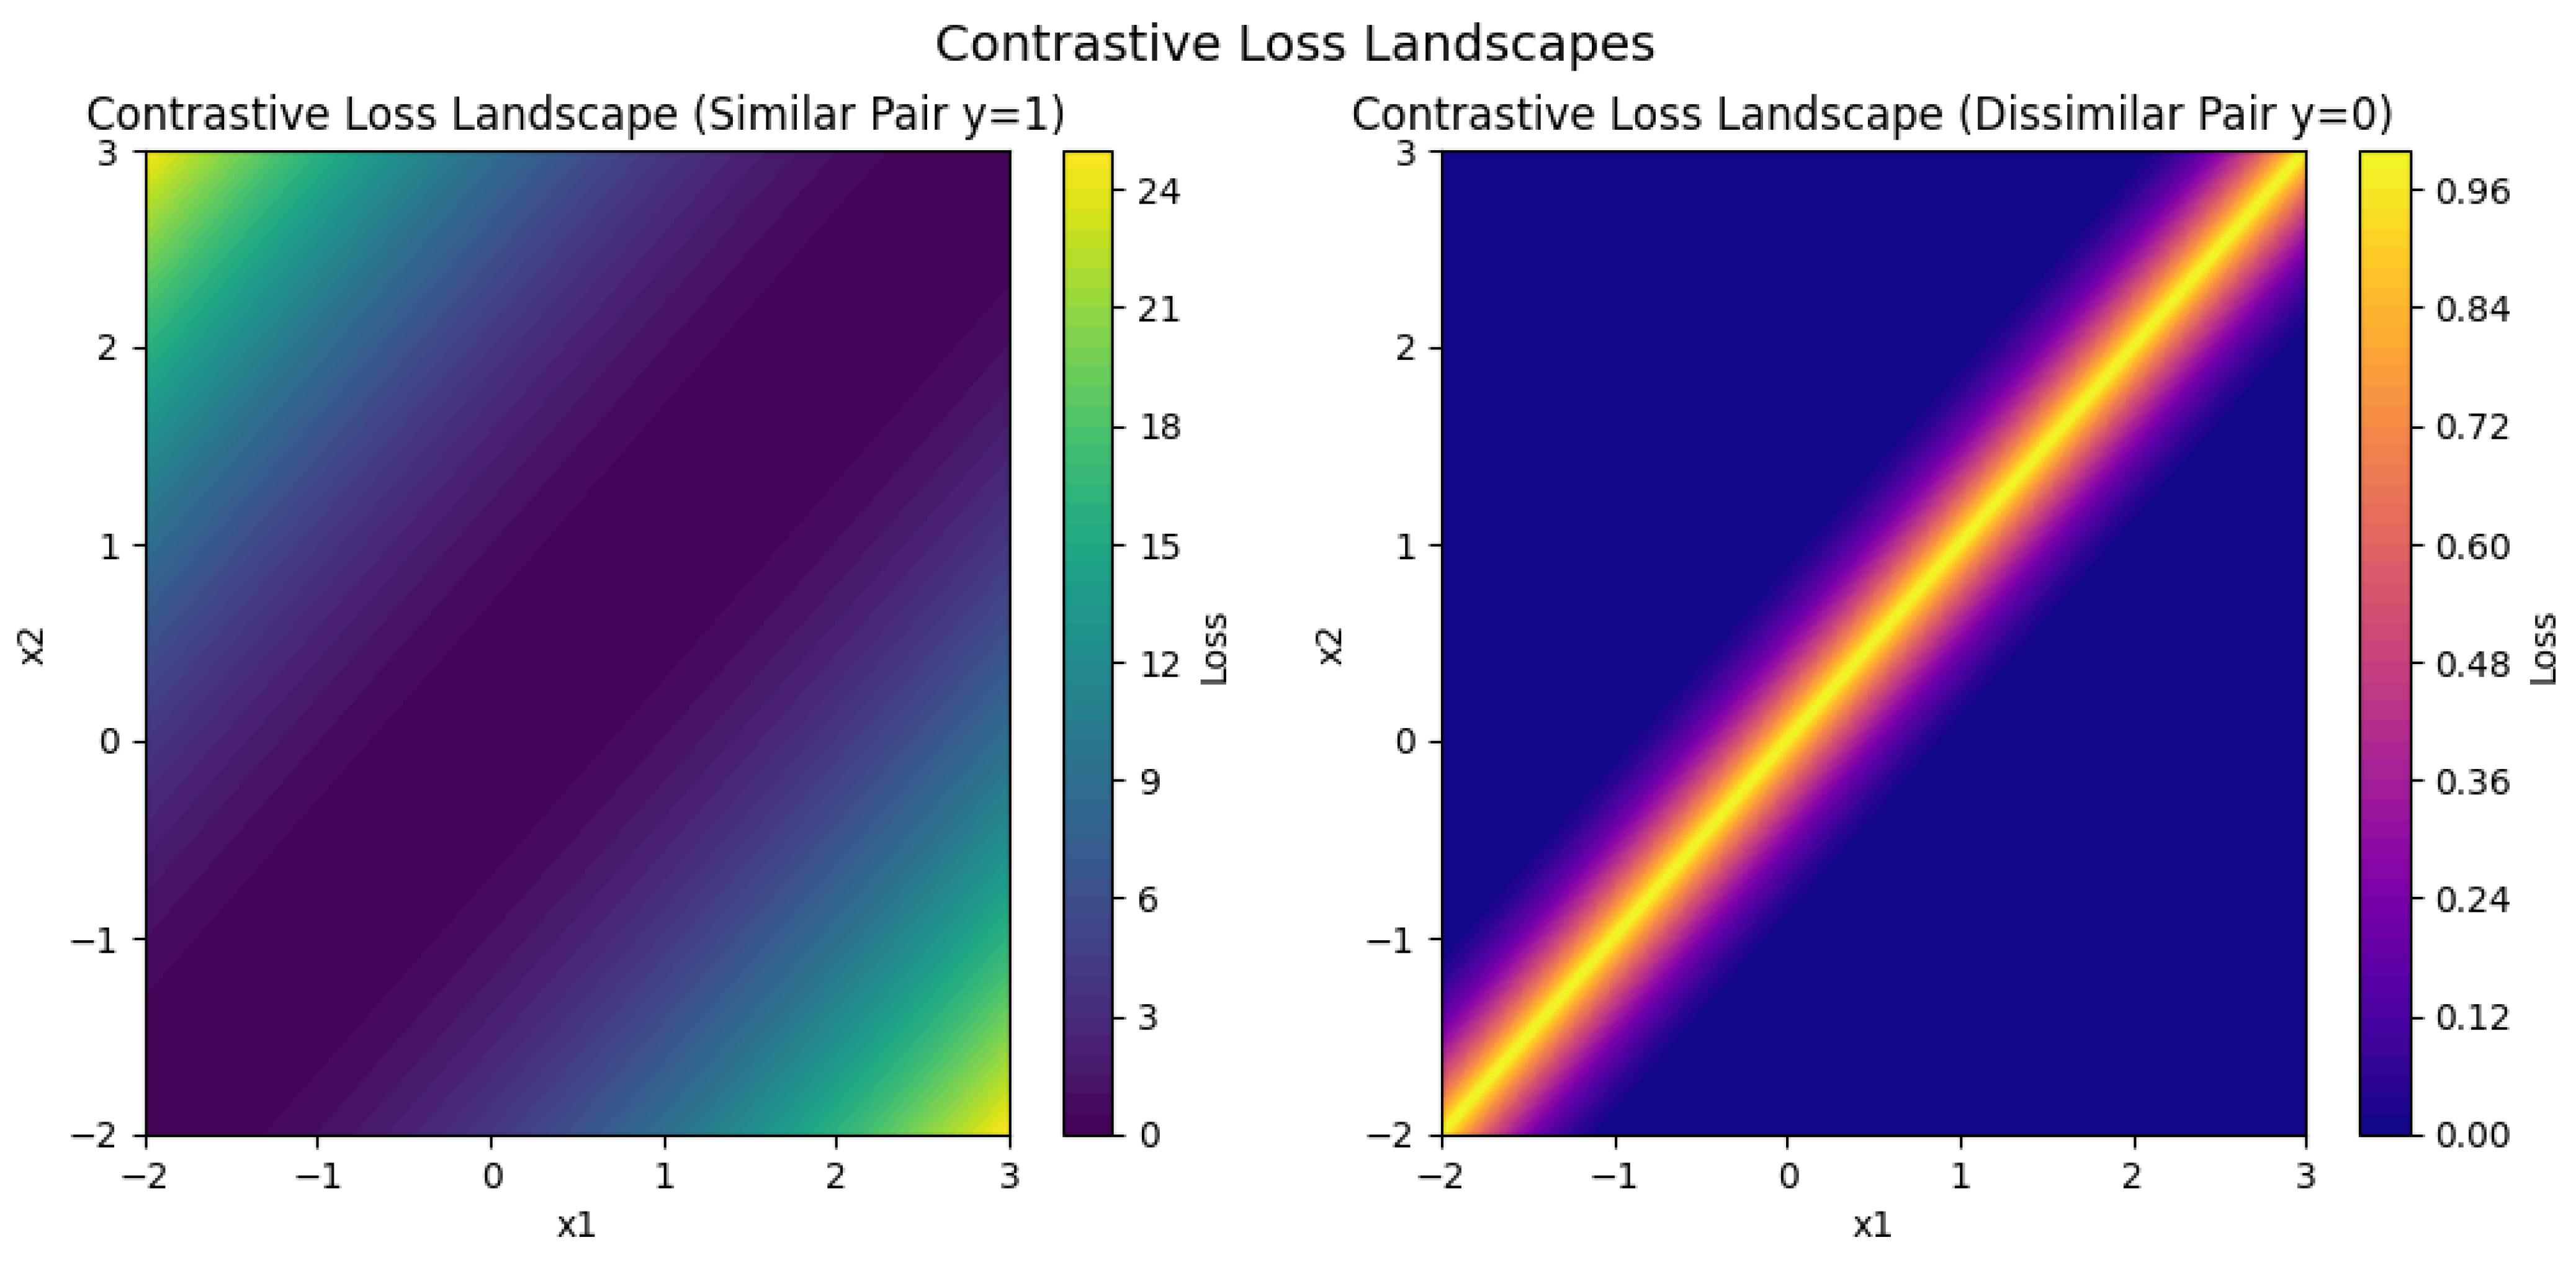
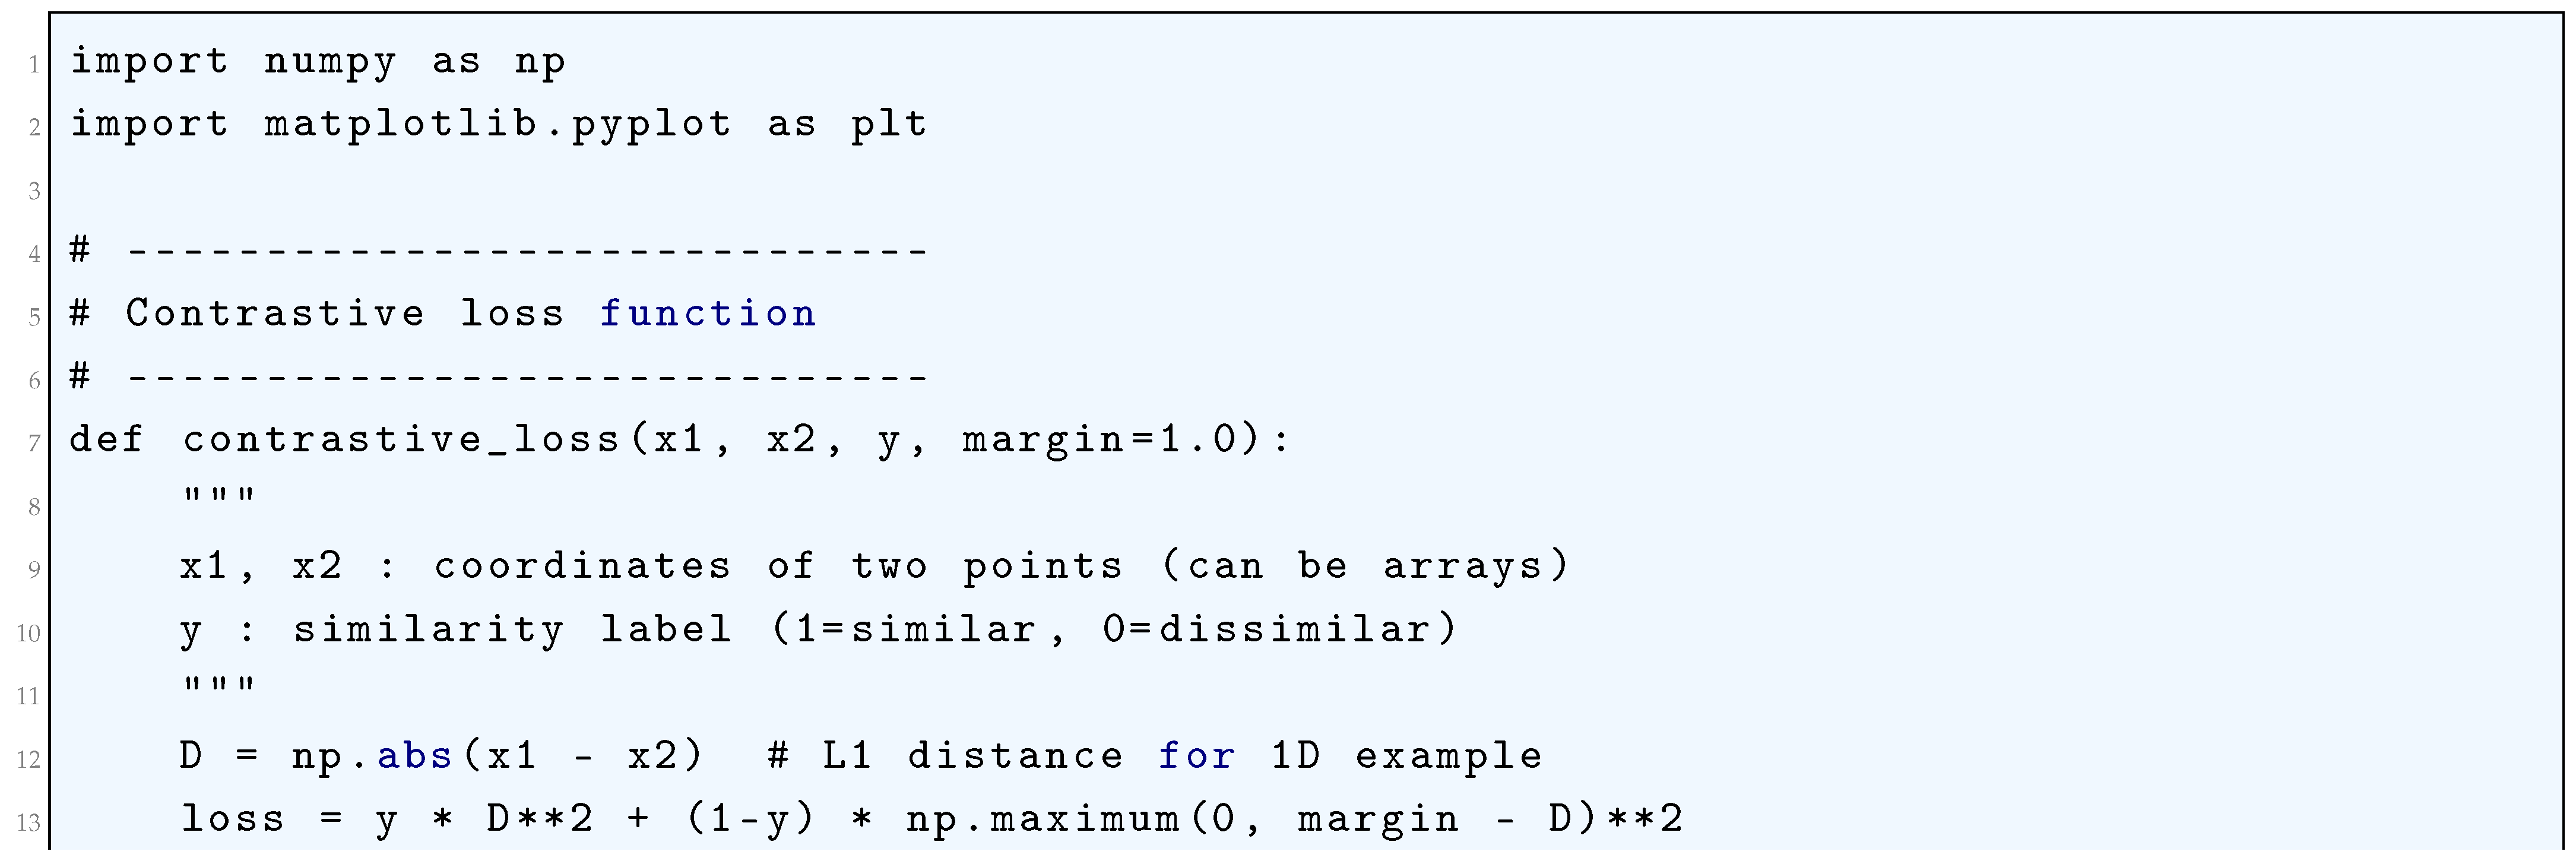
10.5.3.17 Python Code to Generate Figure 84 Illustrating 3D Contrastive Loss Landscapes
The Python code below produces the Figure 84 illustrating 3D Contrastive Loss Landscapes.
Figure 84.
3D Contrastive Loss Landscapes
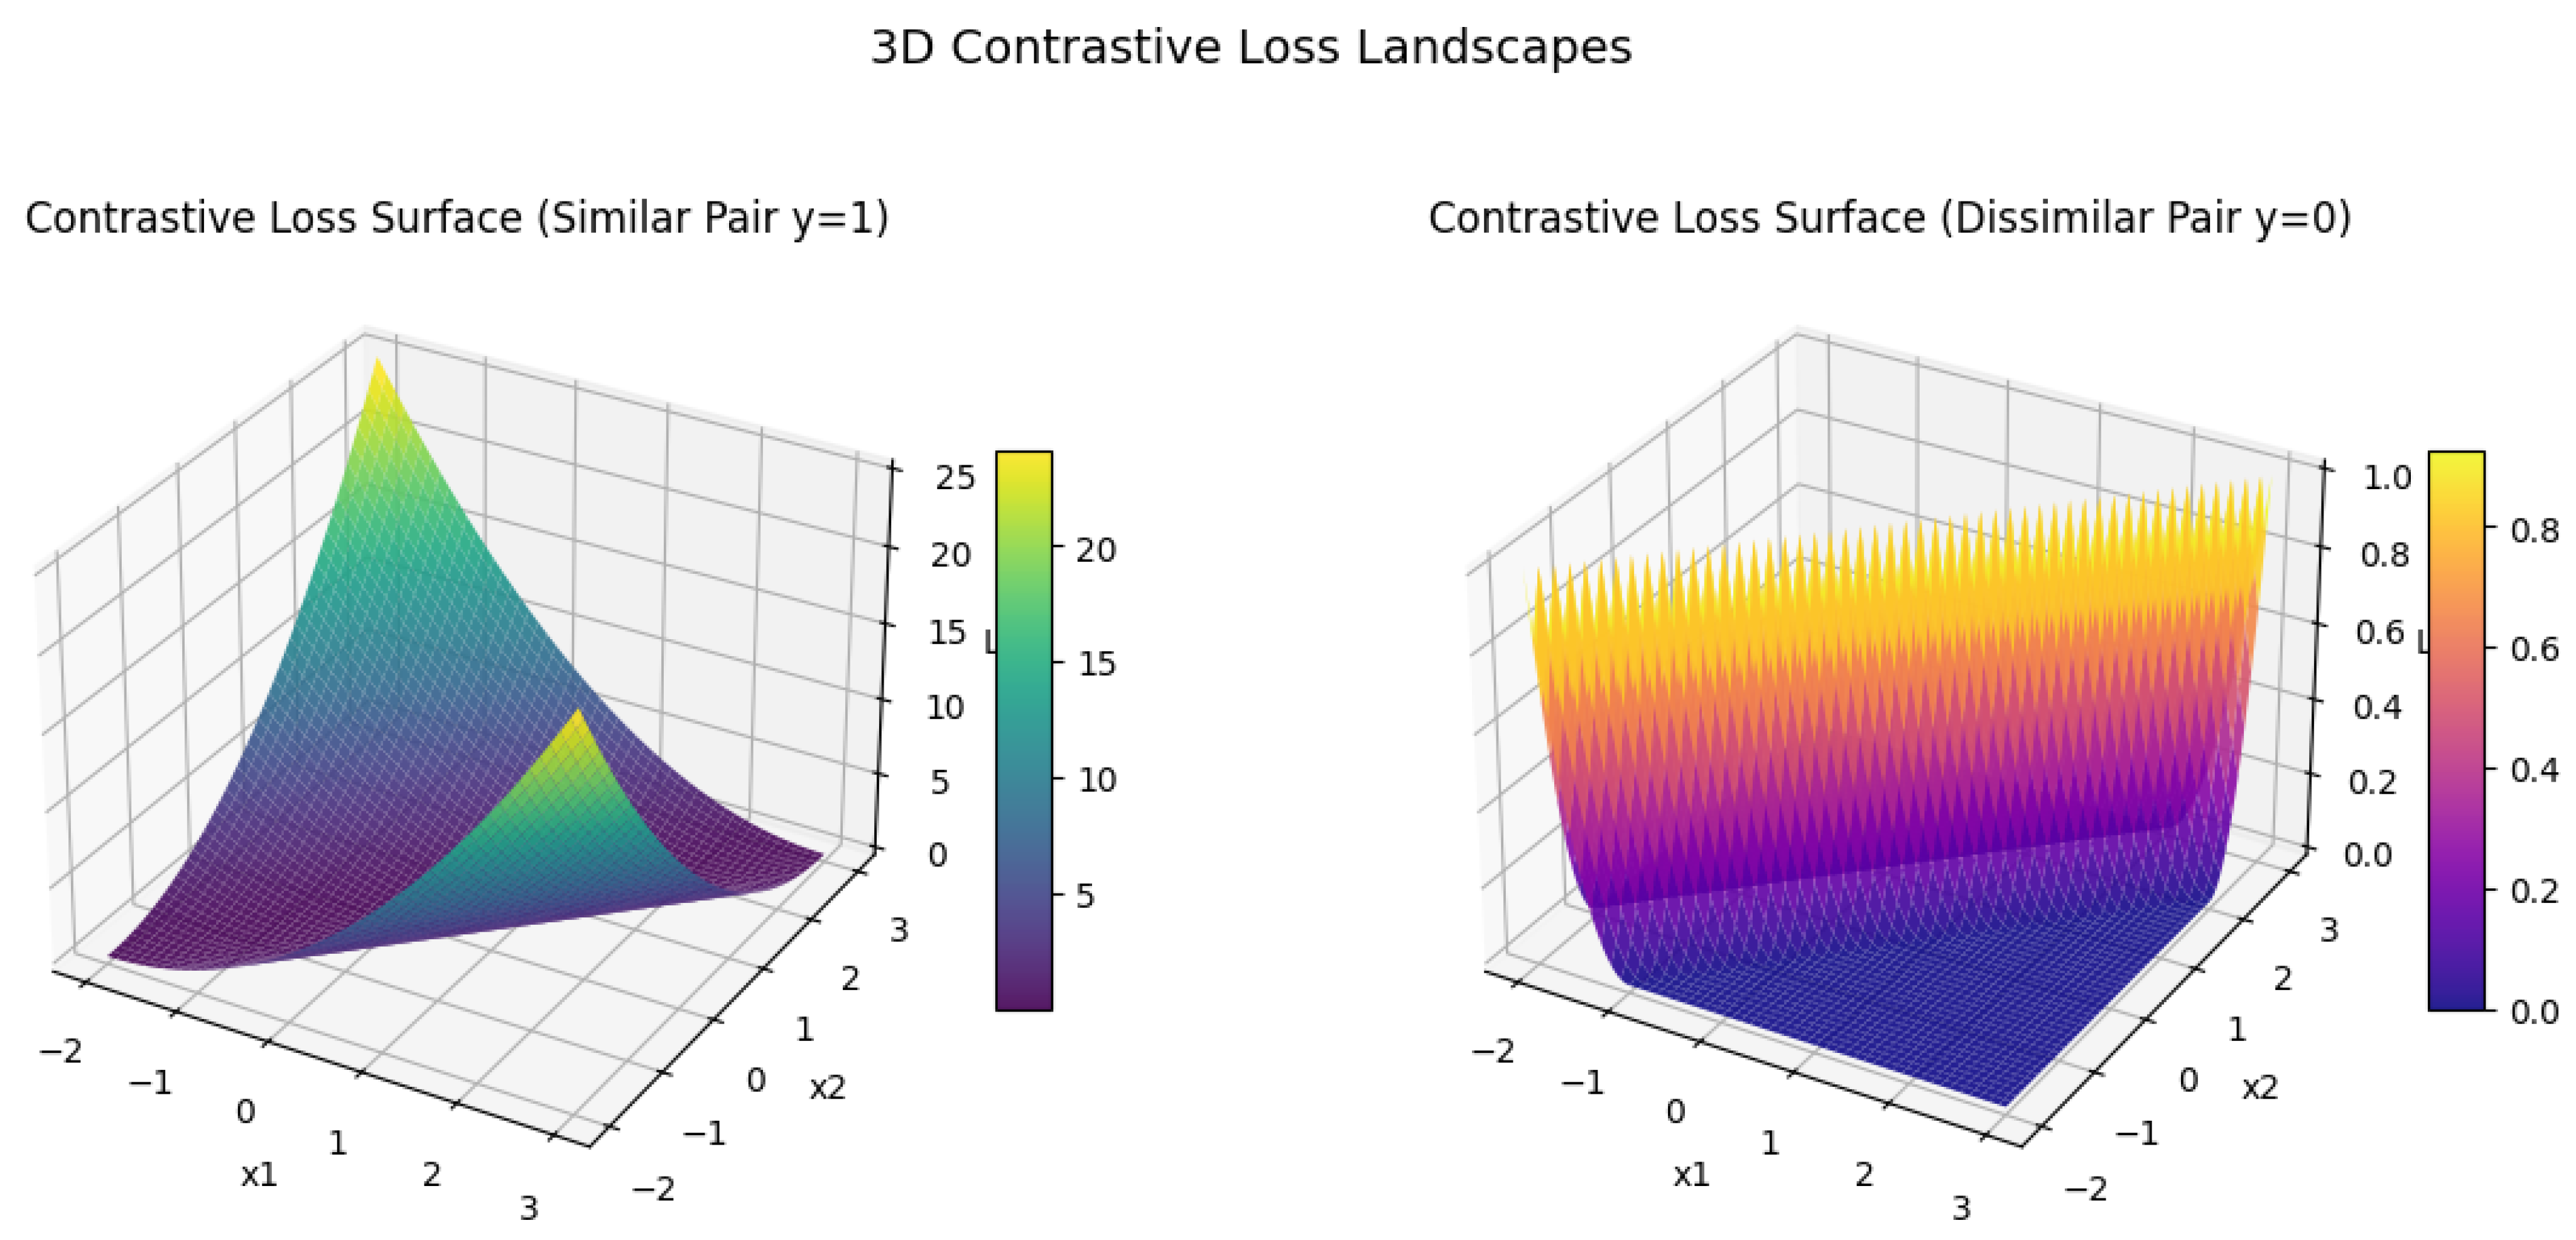
10.5.3.18 Python Code to Generate Figure 85 Illustrating Triplet Loss Function
The Python code below produces the Figure 85 illustrating Triplet Loss Function.
Figure 85.
Triplet Loss Function
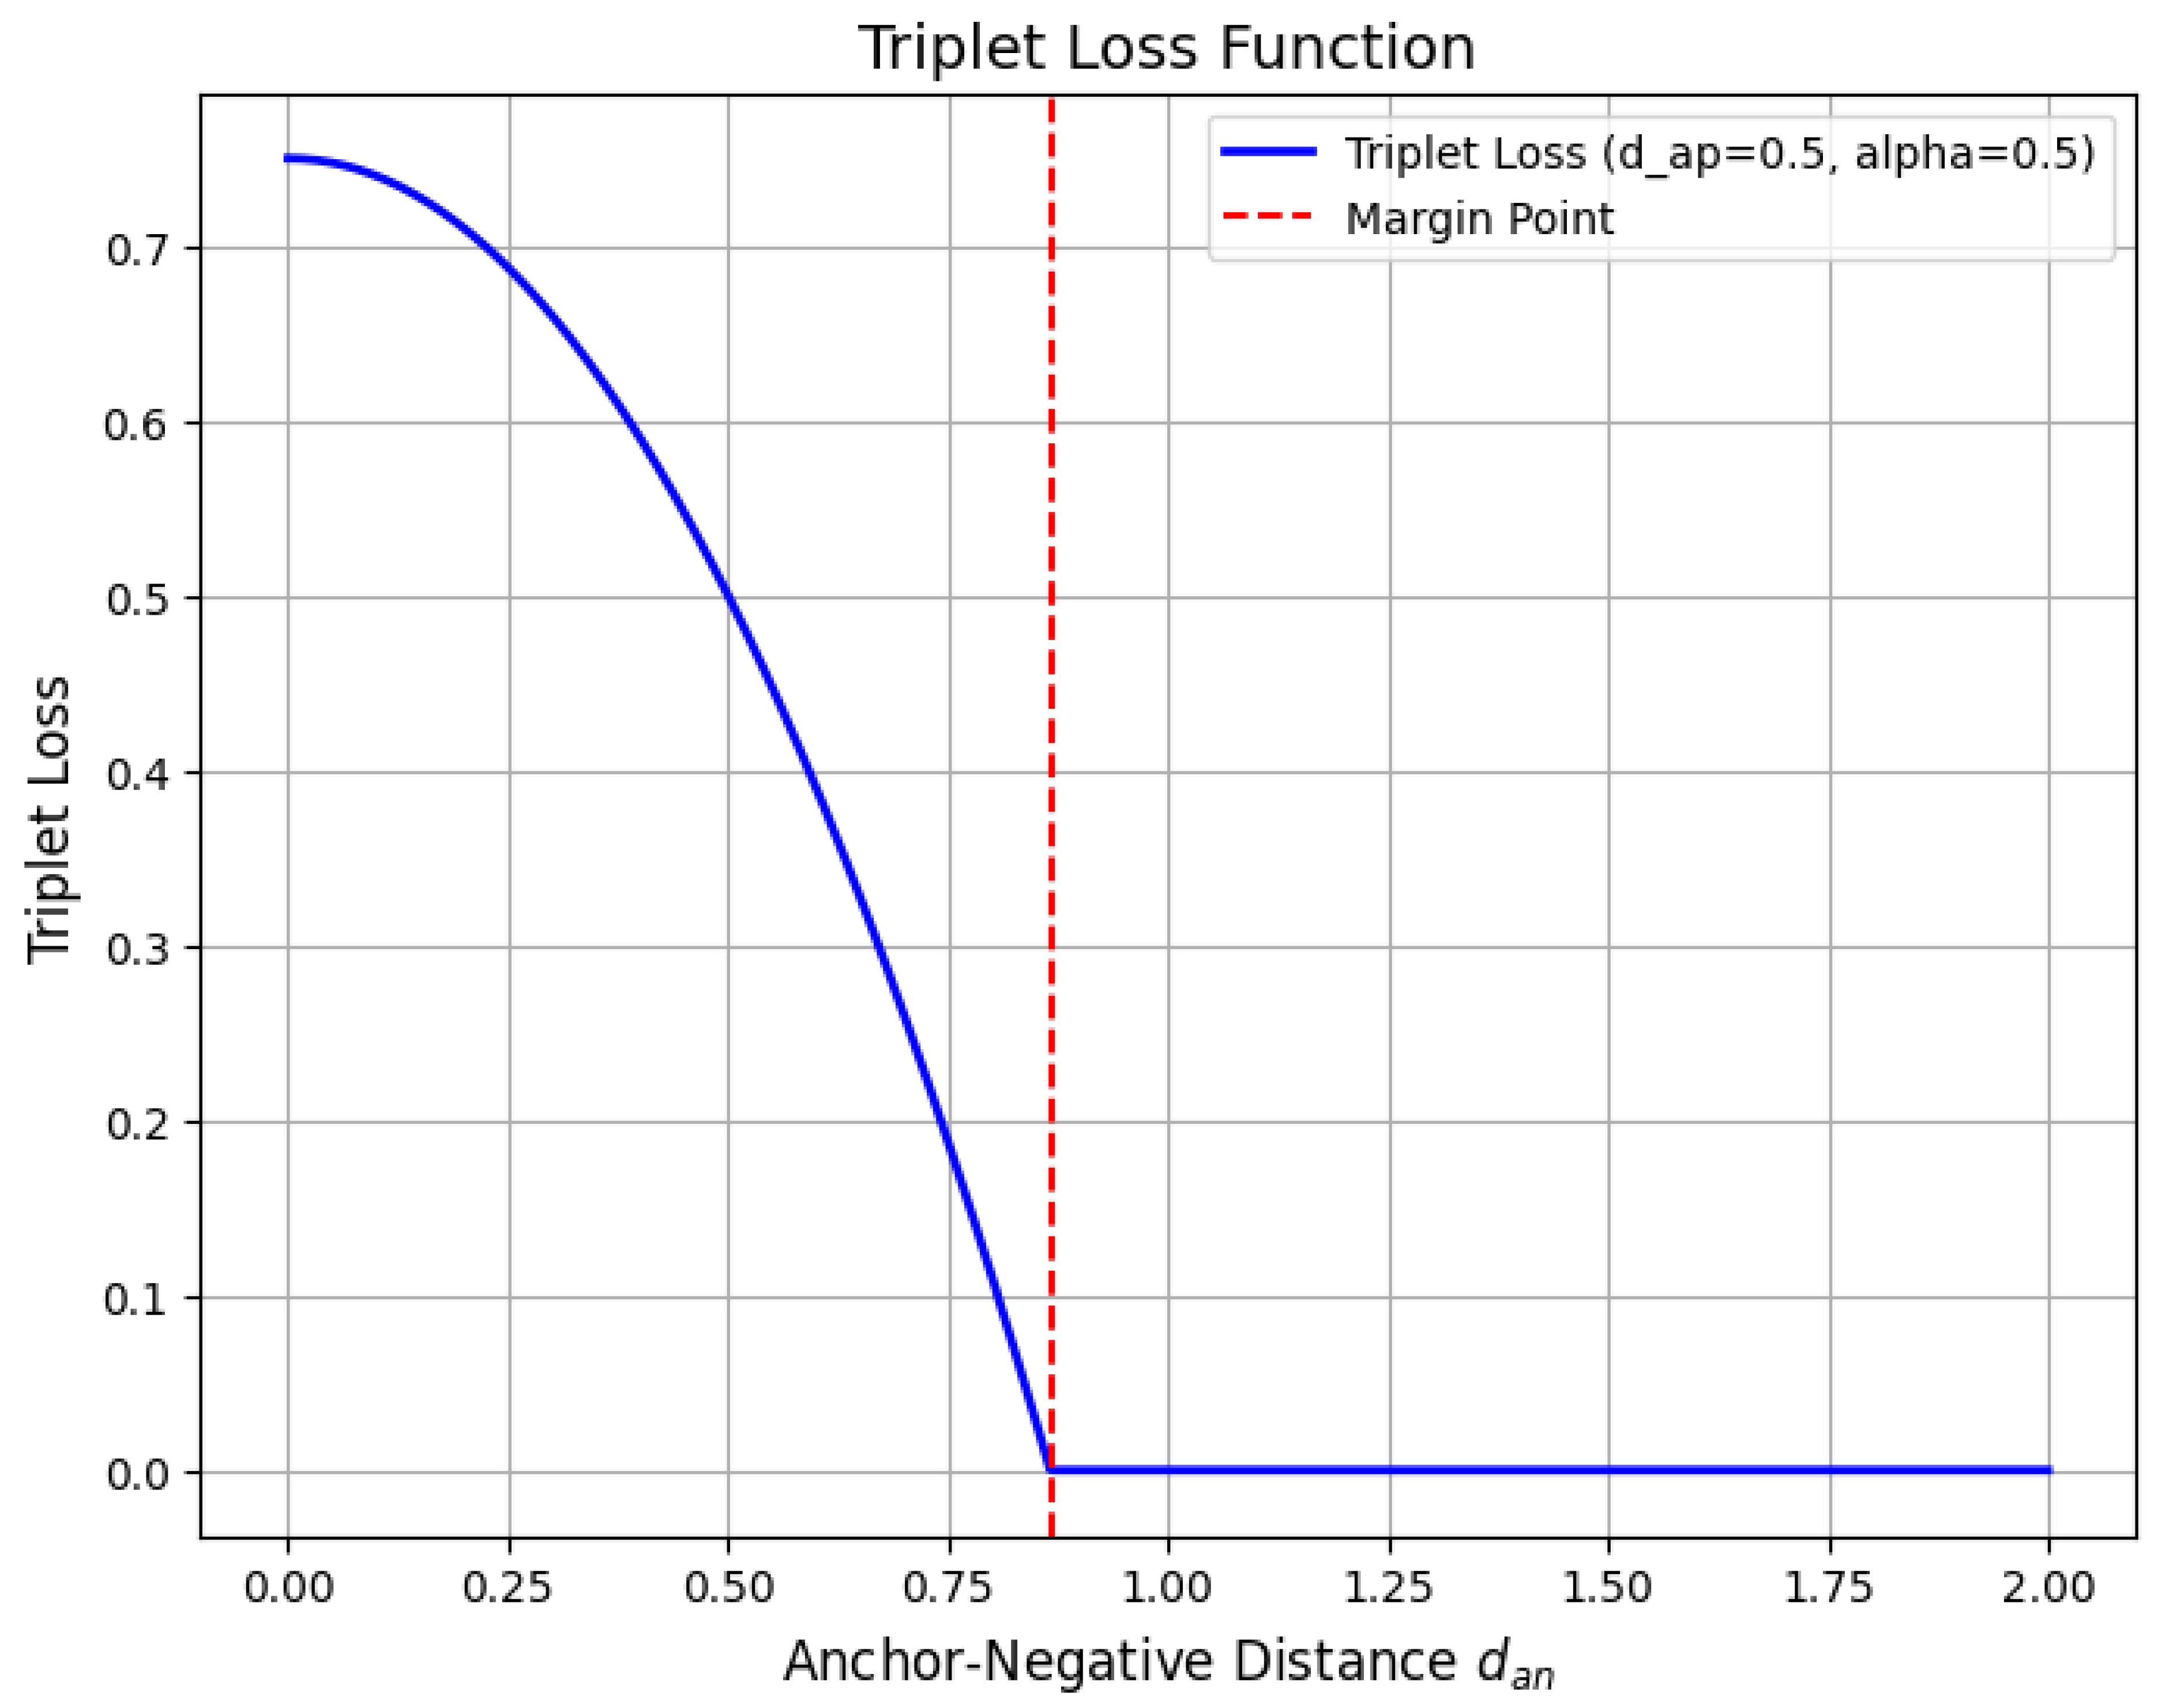
10.5.3.19 Python Code to Generate Figure 86 Illustrating Triplet Loss Landscape
The Python code below produces the Figure 86 illustrating Triplet Loss Landscape.
Figure 86.
Triplet Loss Landscape
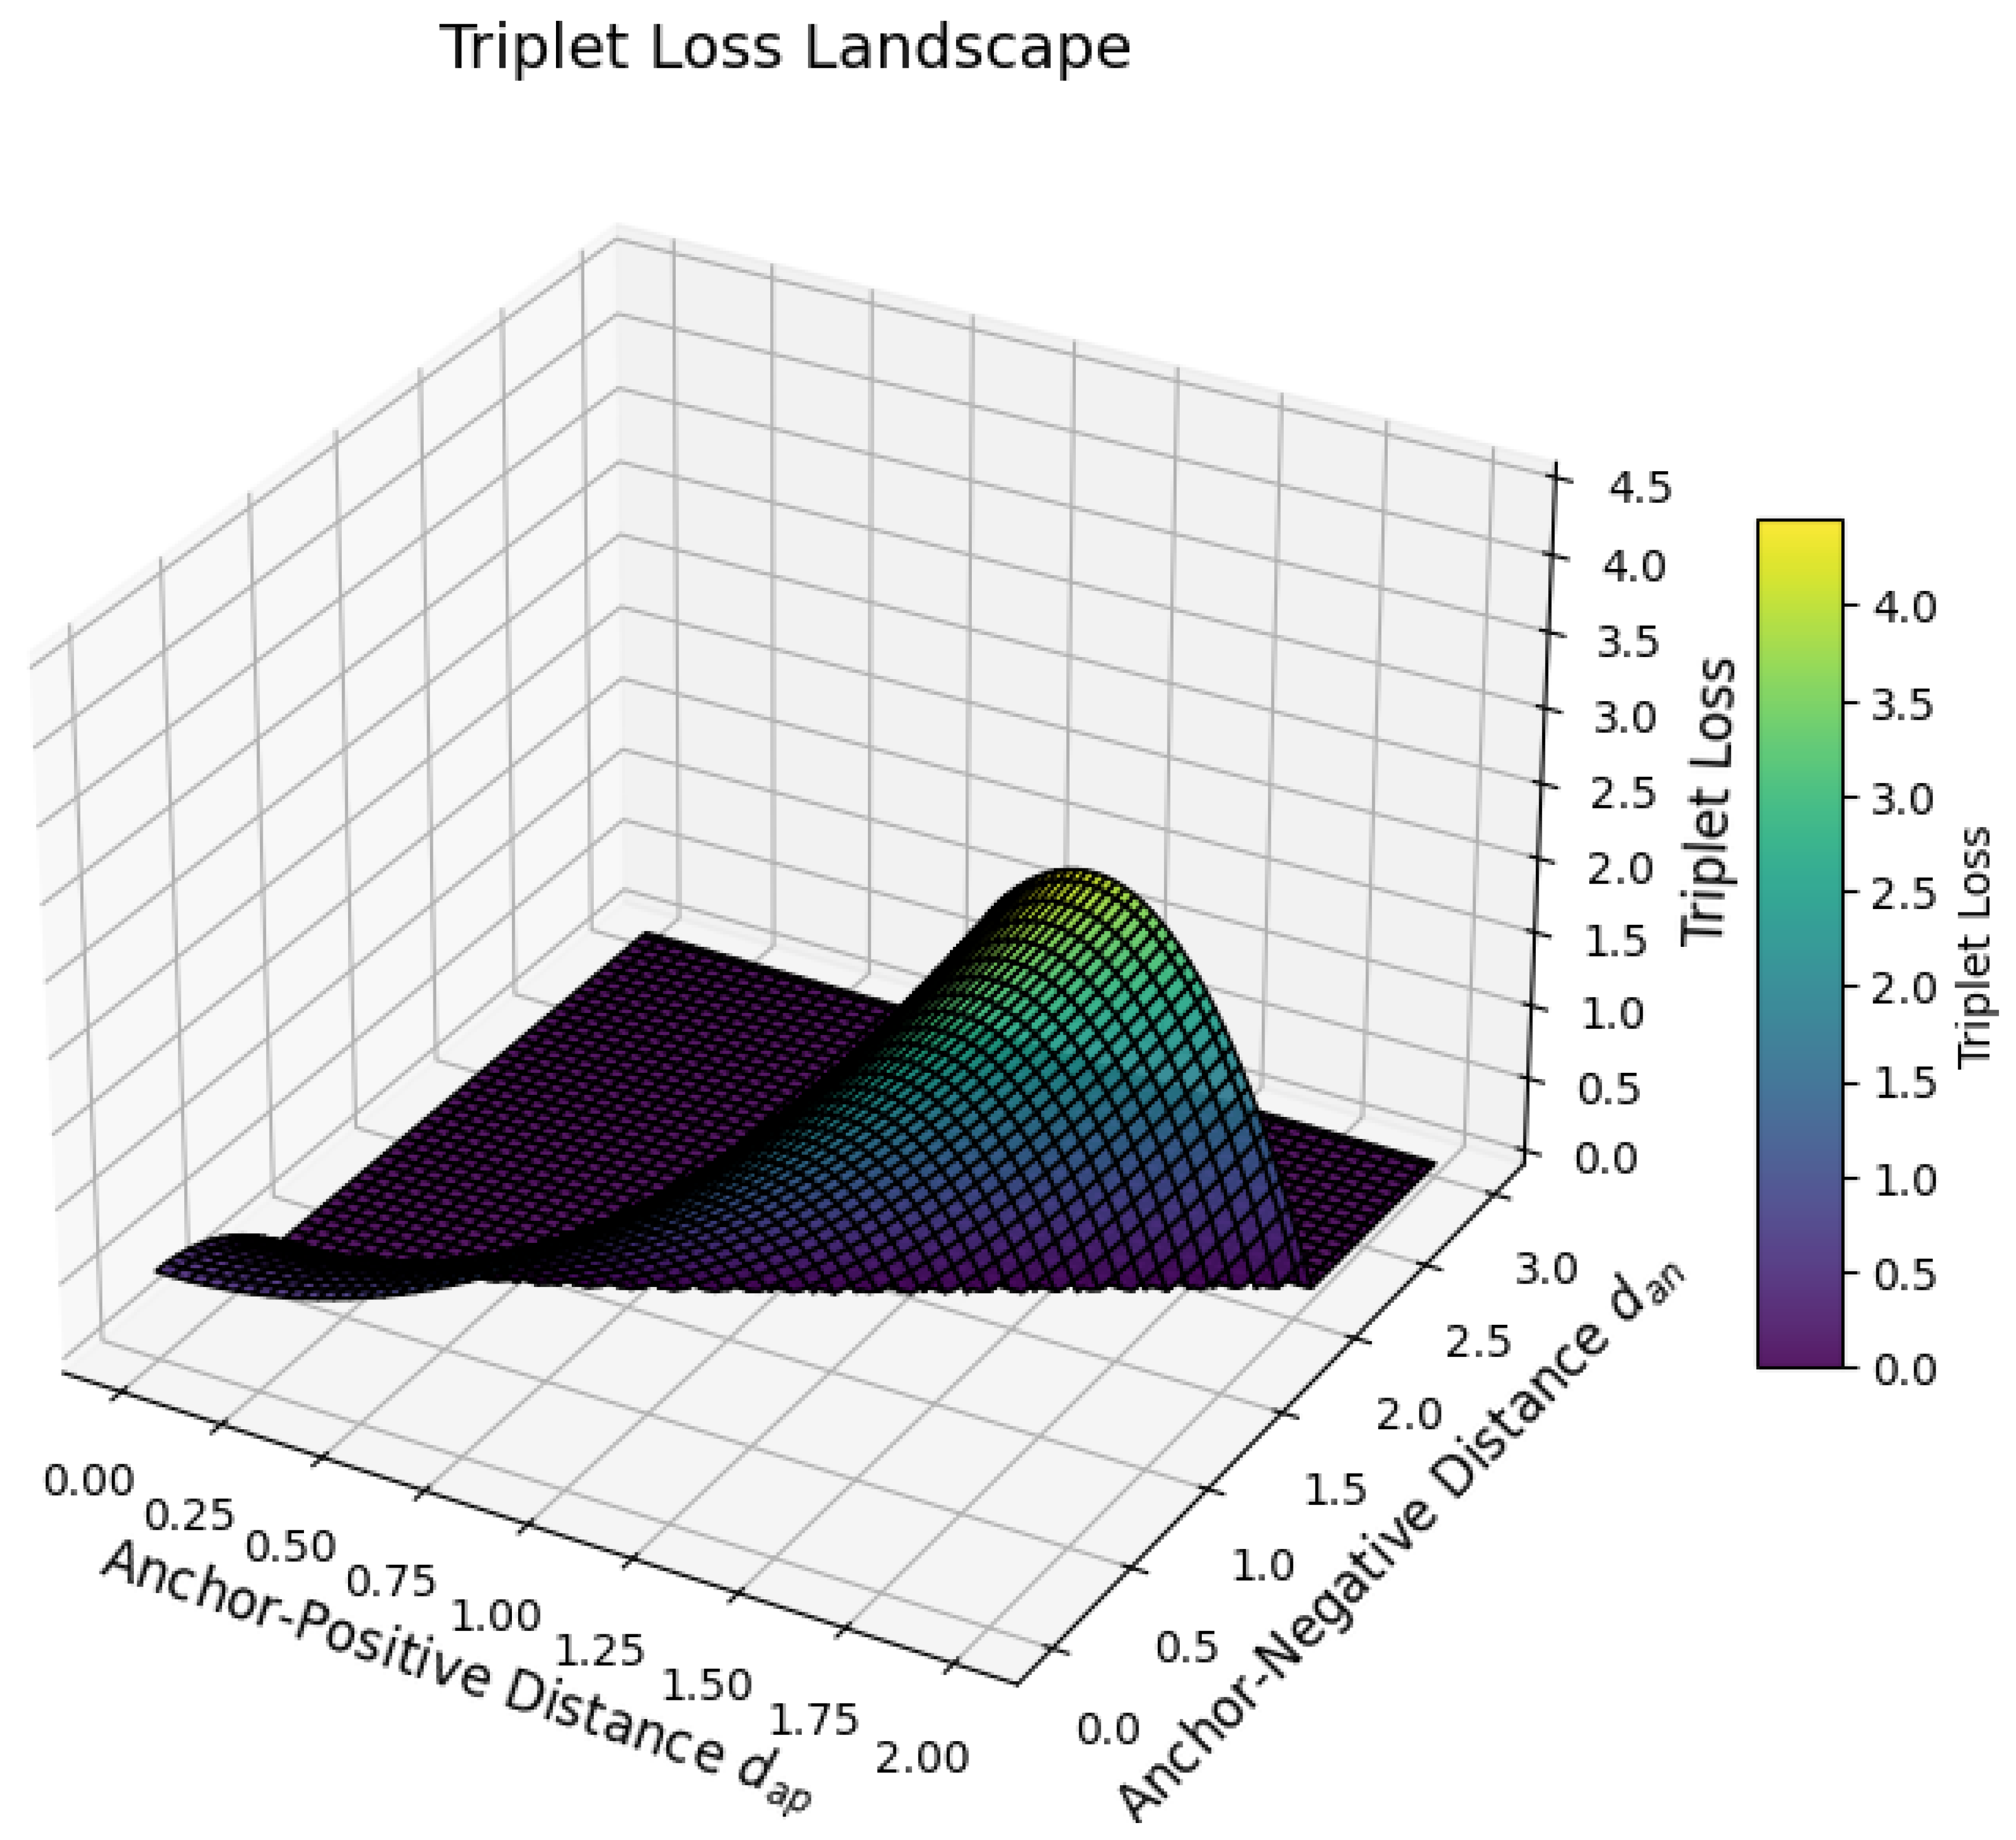
10.5.3.20 Python Code to Generate Figure 87 Illustrating Triplet Loss Contour Plot
The Python code below produces the Figure 87 illustrating Triplet Loss Contour Plot.
Figure 87.
Triplet Loss Contour Plot
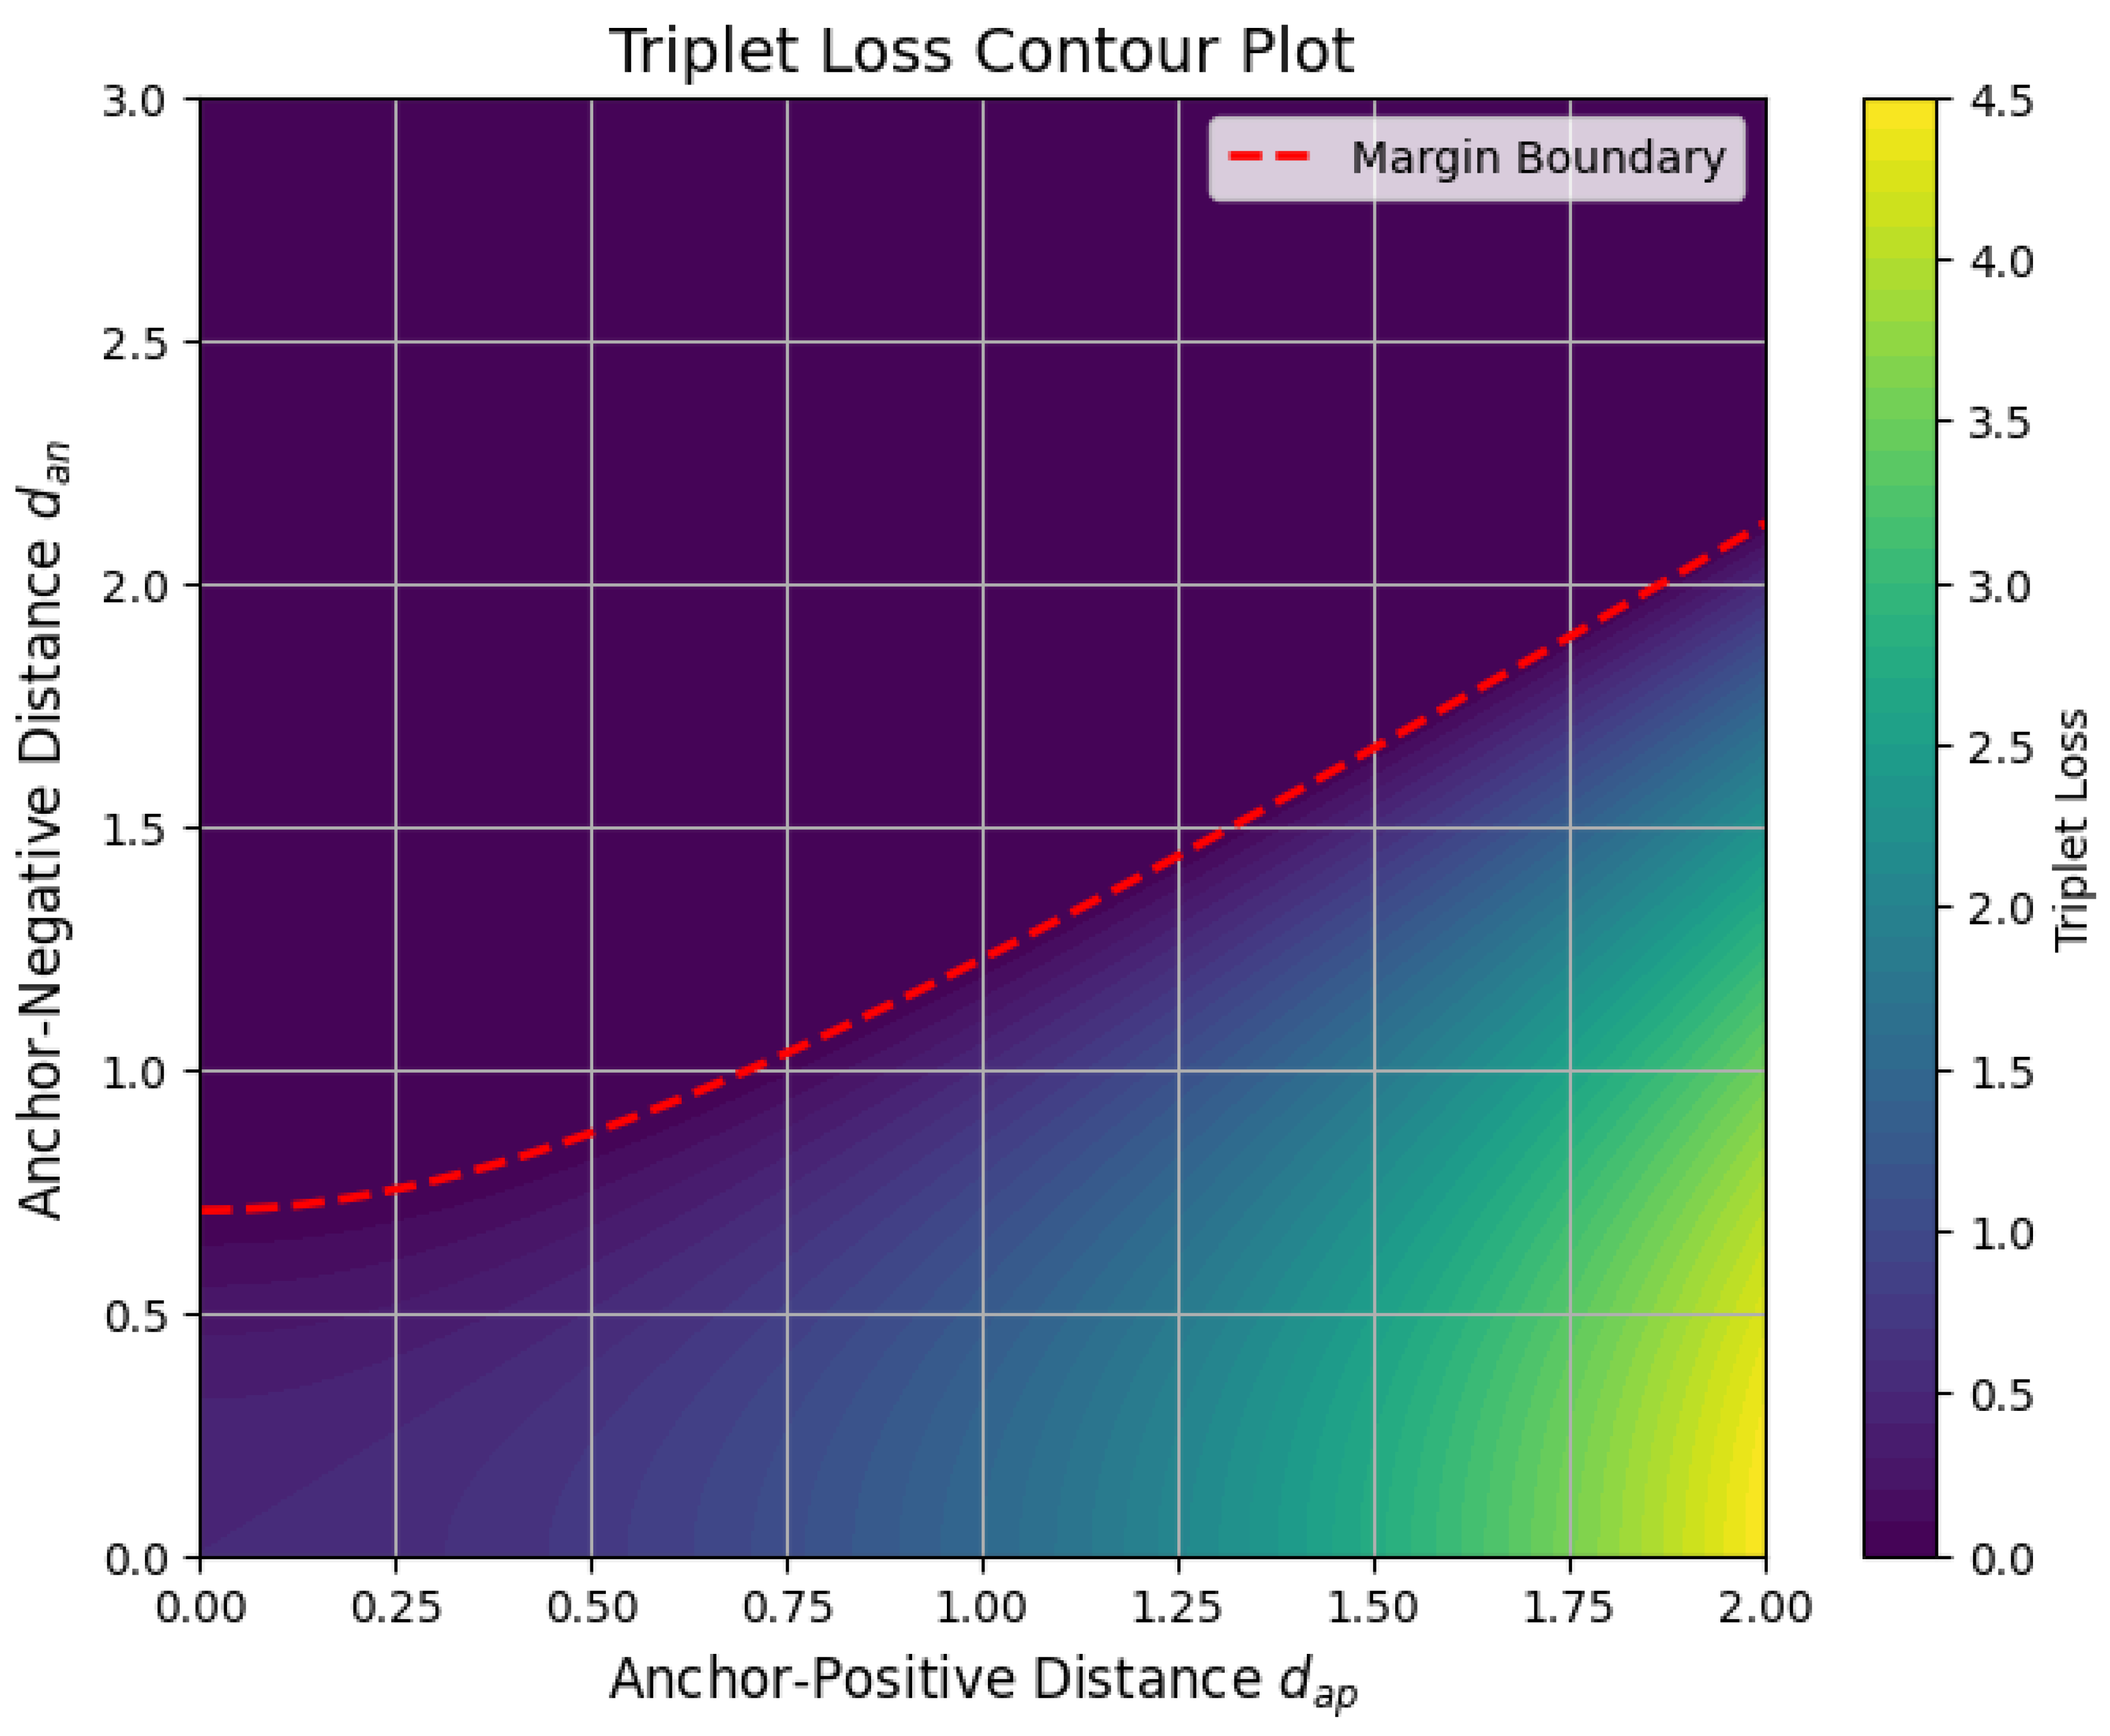
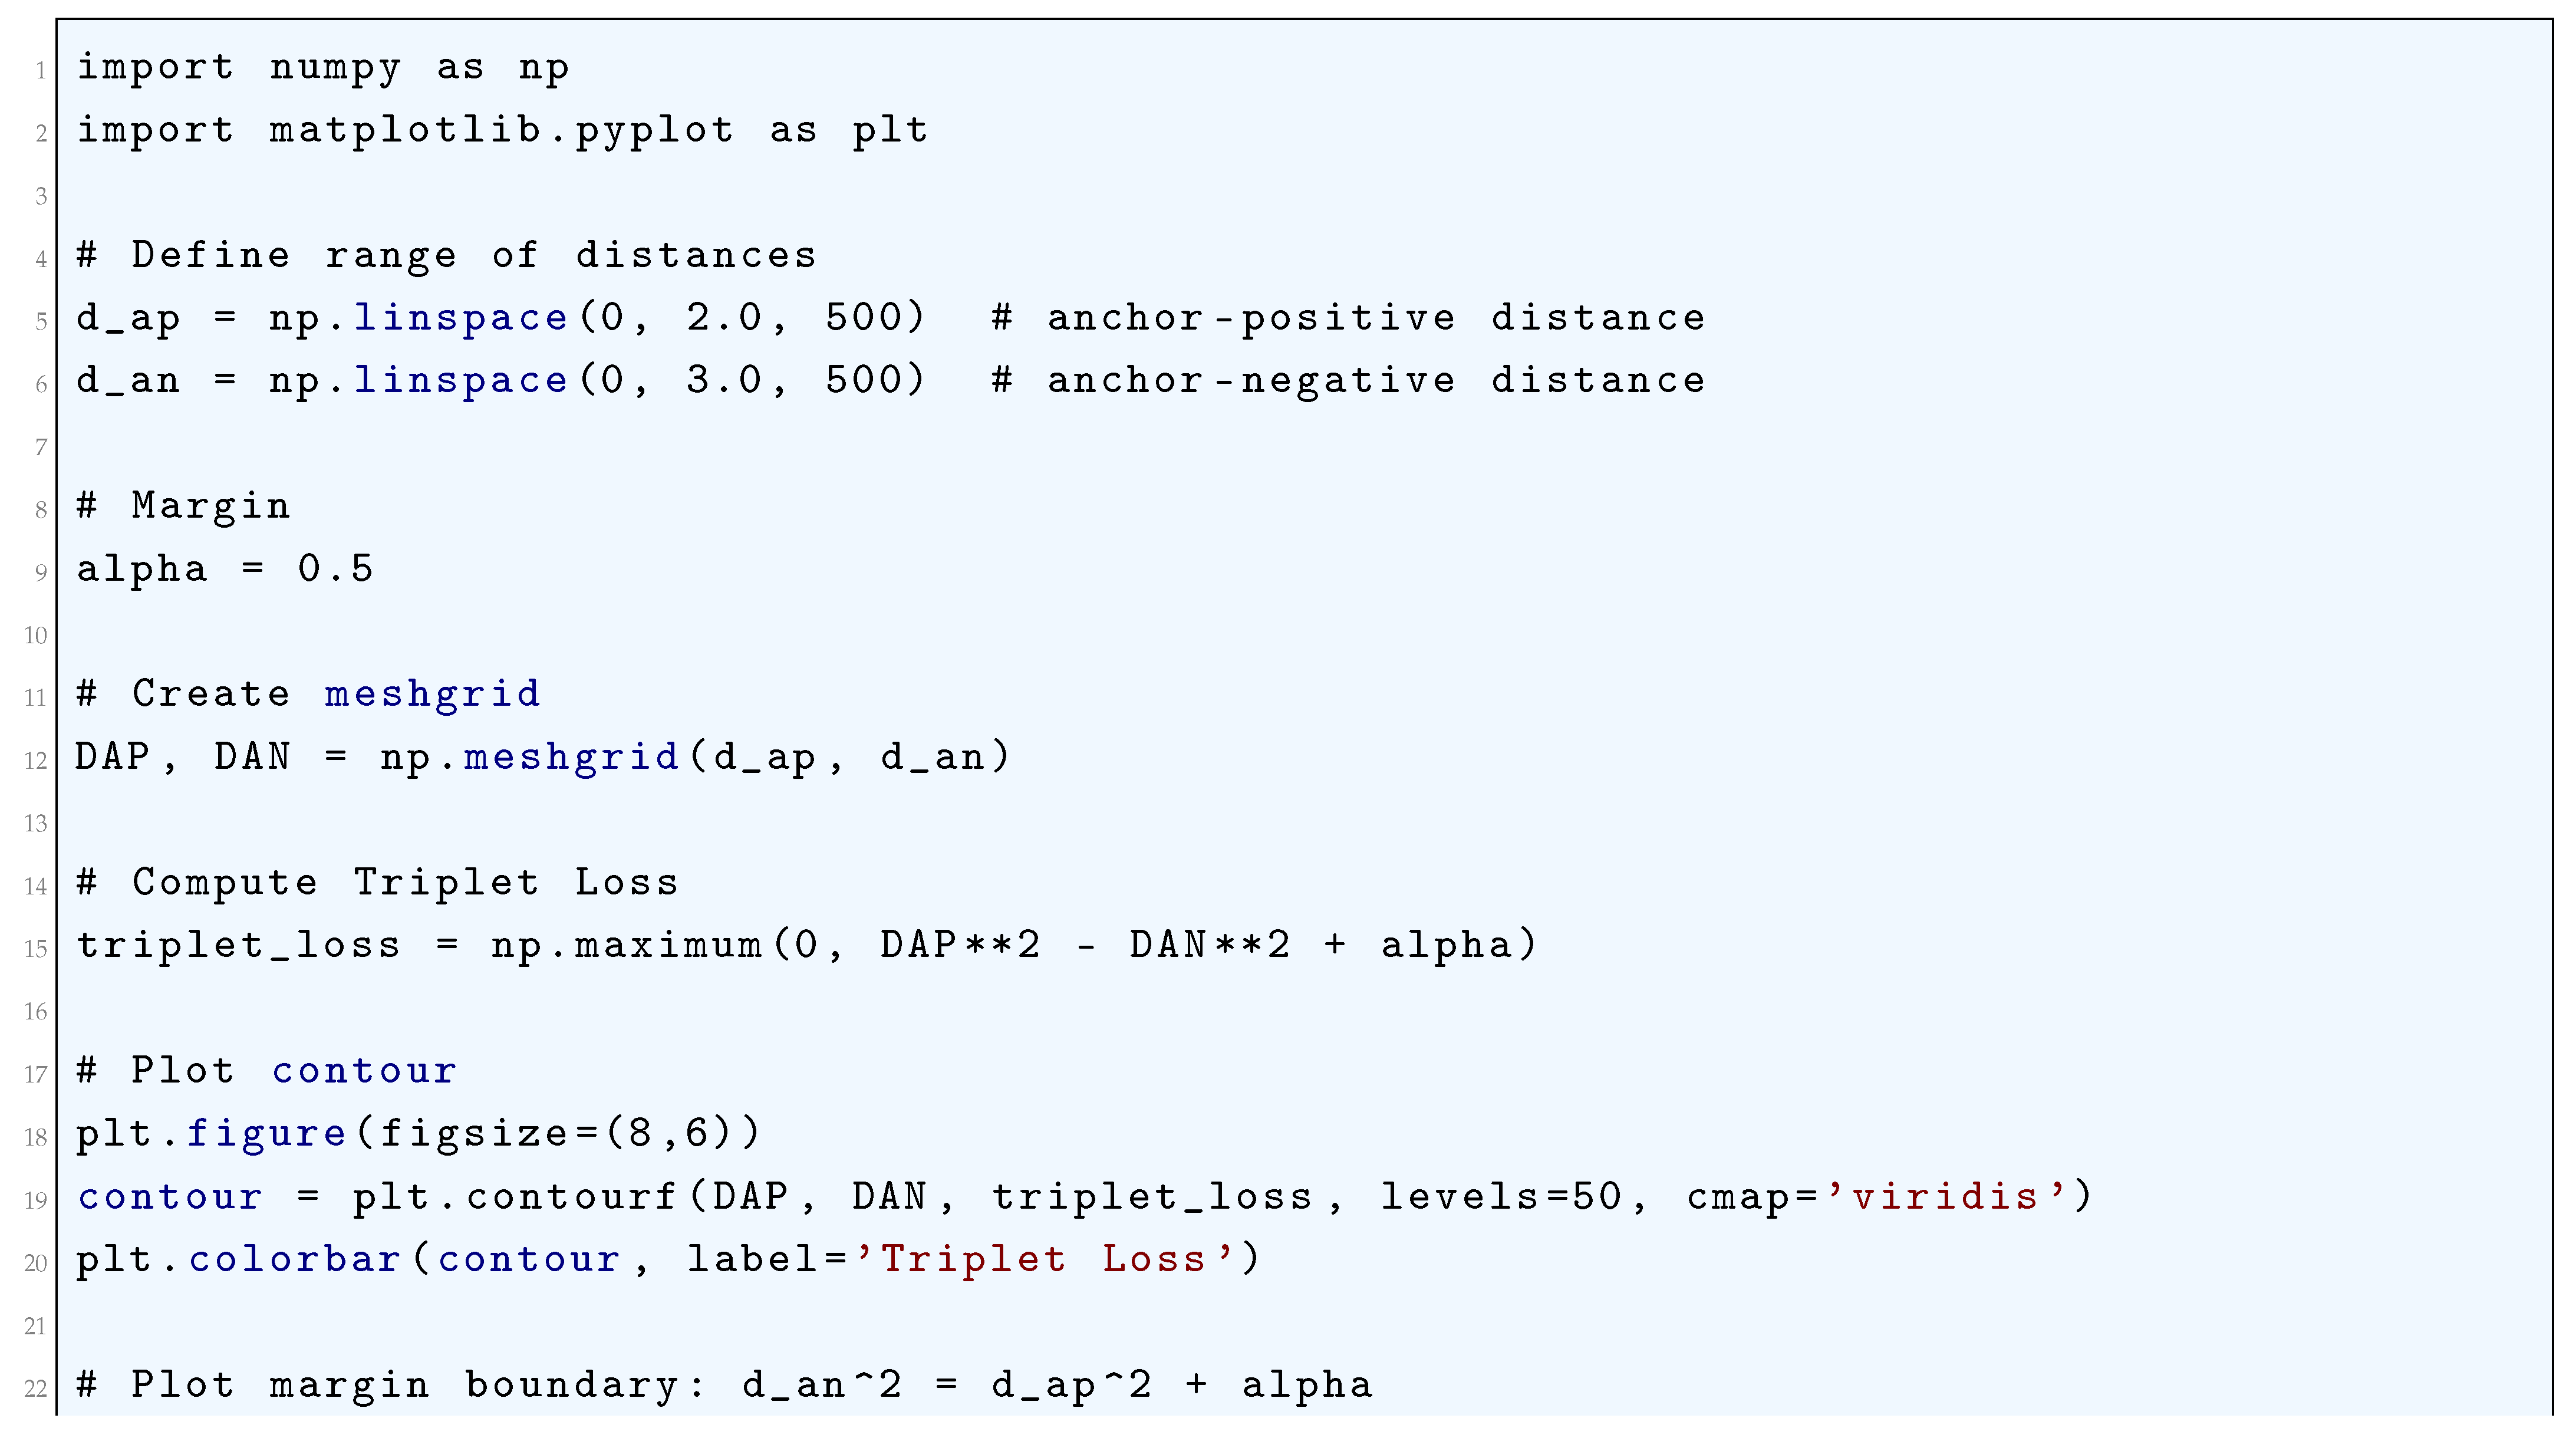
10.5.3.21 Python Code to Generate Figure 88 Illustrating Center Loss Function
The Python code below produces the Figure 88 illustrating Center Loss Function.
Figure 88.
Center Loss Function
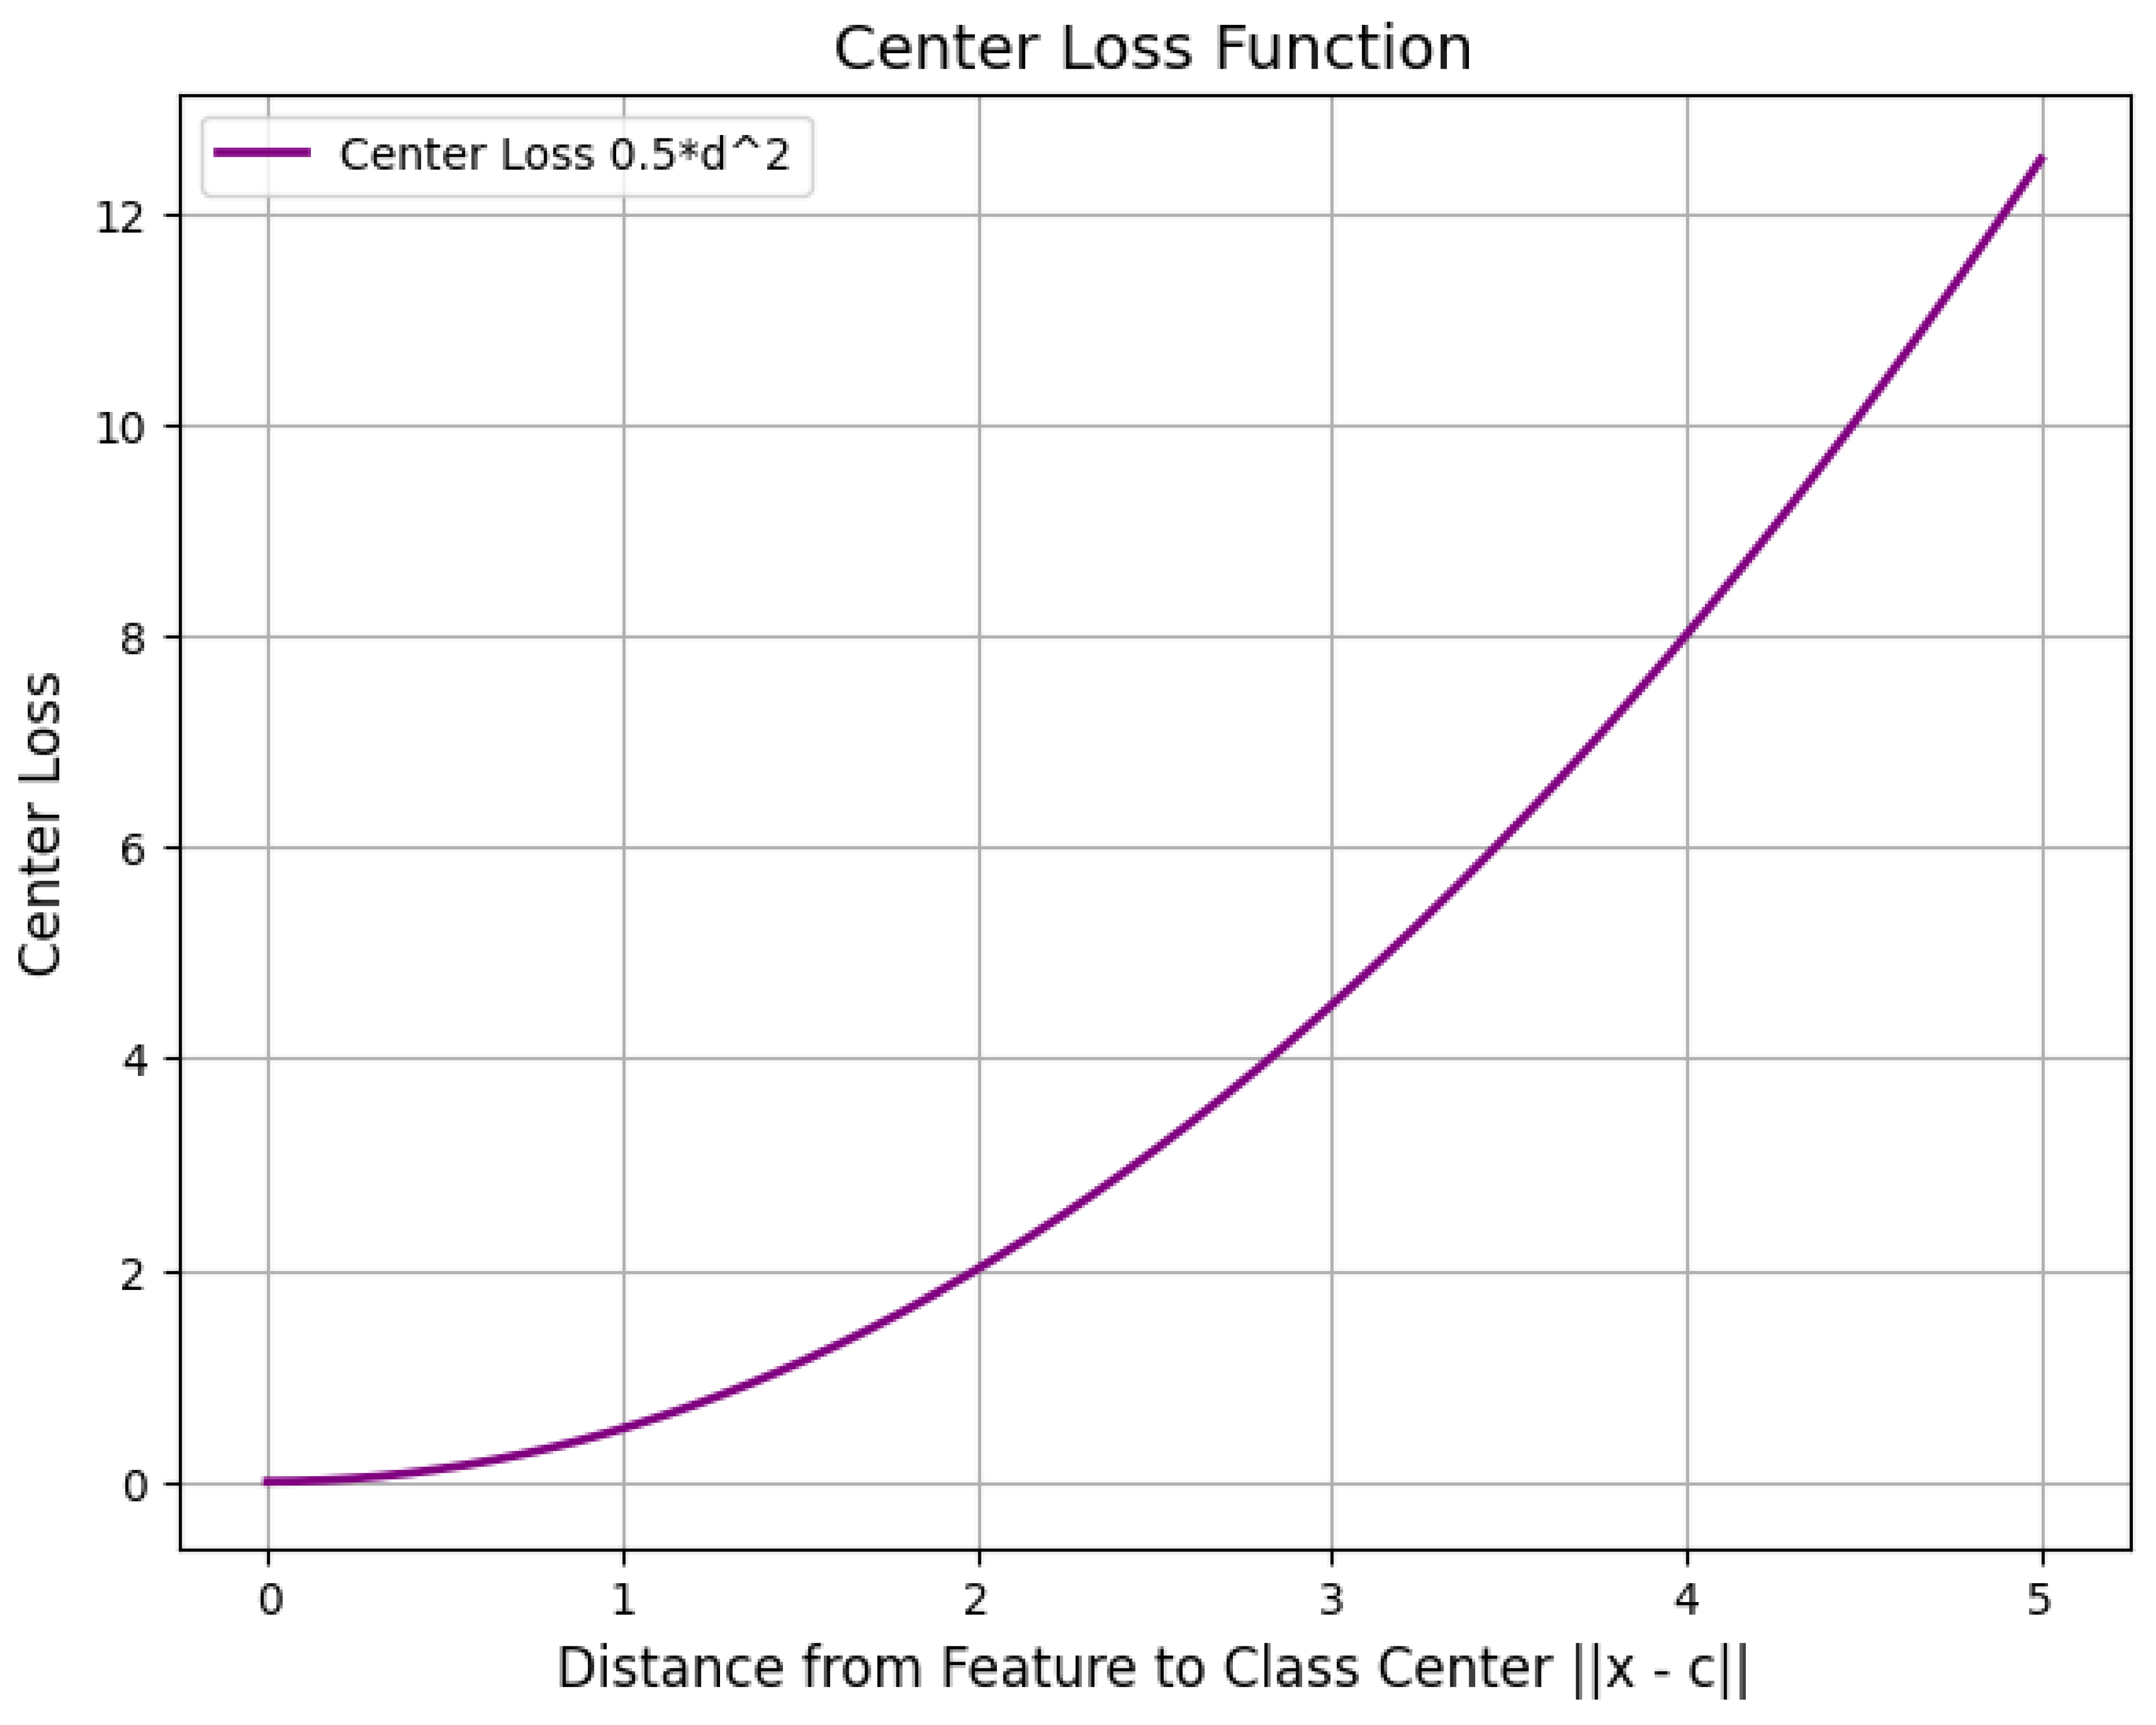
10.5.3.22 Python Code to Generate Figure 89 Illustrating Center Loss Visualization: Features vs Class Centers
The Python code below produces the Figure 89 illustrating Center Loss Visualization: Features vs Class Centers.
Figure 89.
Center Loss Visualization: Features vs Class Centers
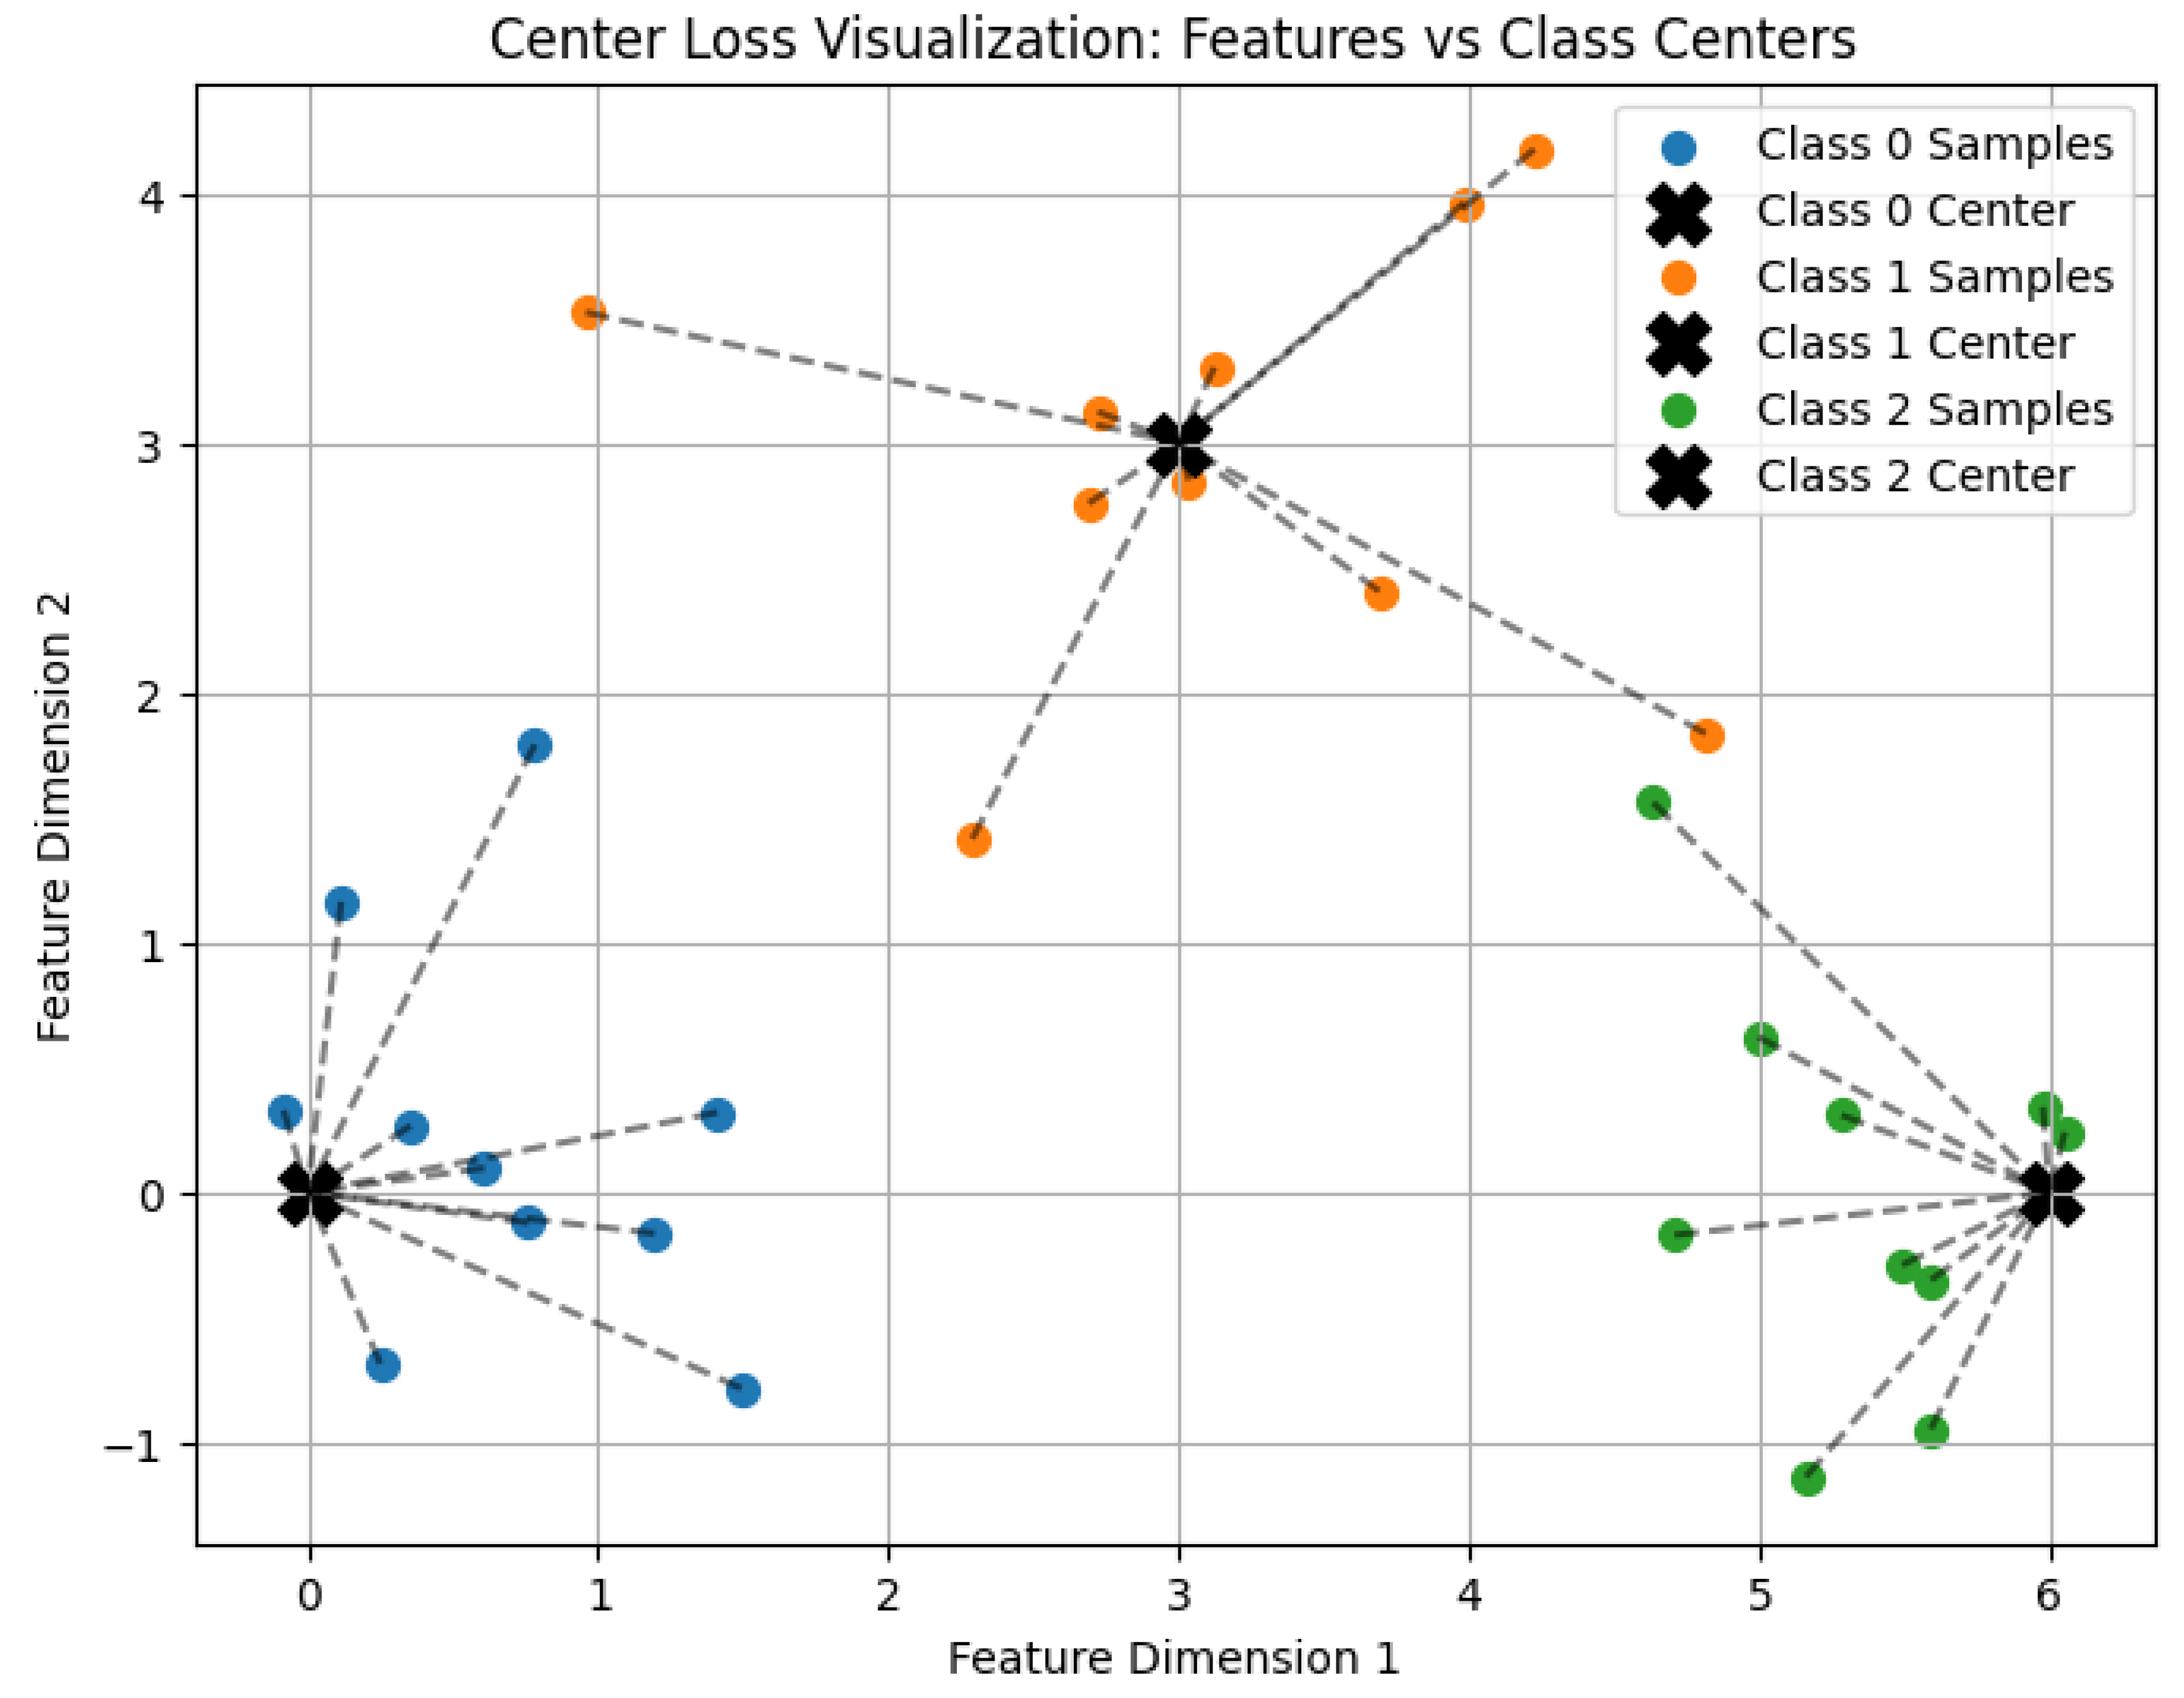
10.5.3.23 Python Code to Generate Figure 90 Illustrating 3D Center Loss Surface
The Python code below produces the Figure 90 illustrating 3D Center Loss Surface.
Figure 90.
3D Center Loss Surface
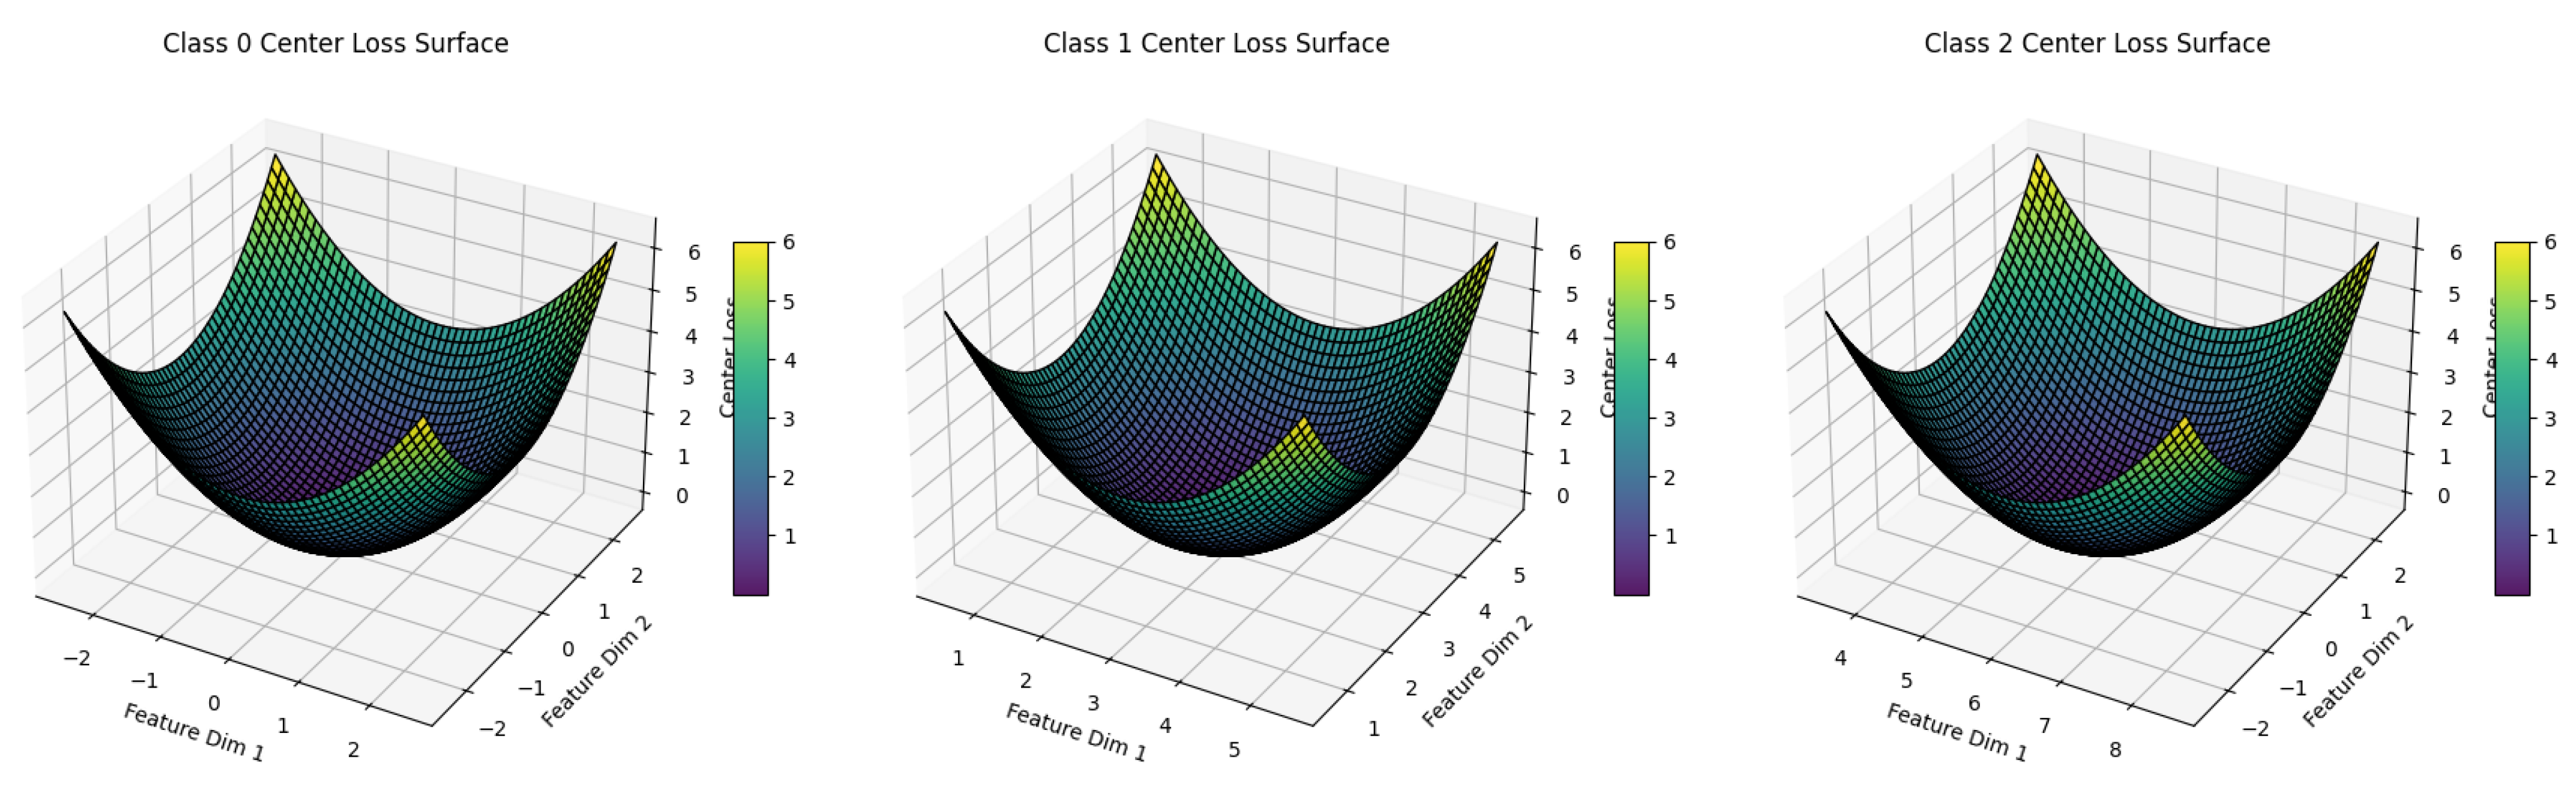
10.5.3.24 Python Code to Generate Figure 91 Illustrating Perceptual Loss Function
The Python code below produces the Figure 91 illustrating Perceptual Loss Function.
Figure 91.
Perceptual Loss Function
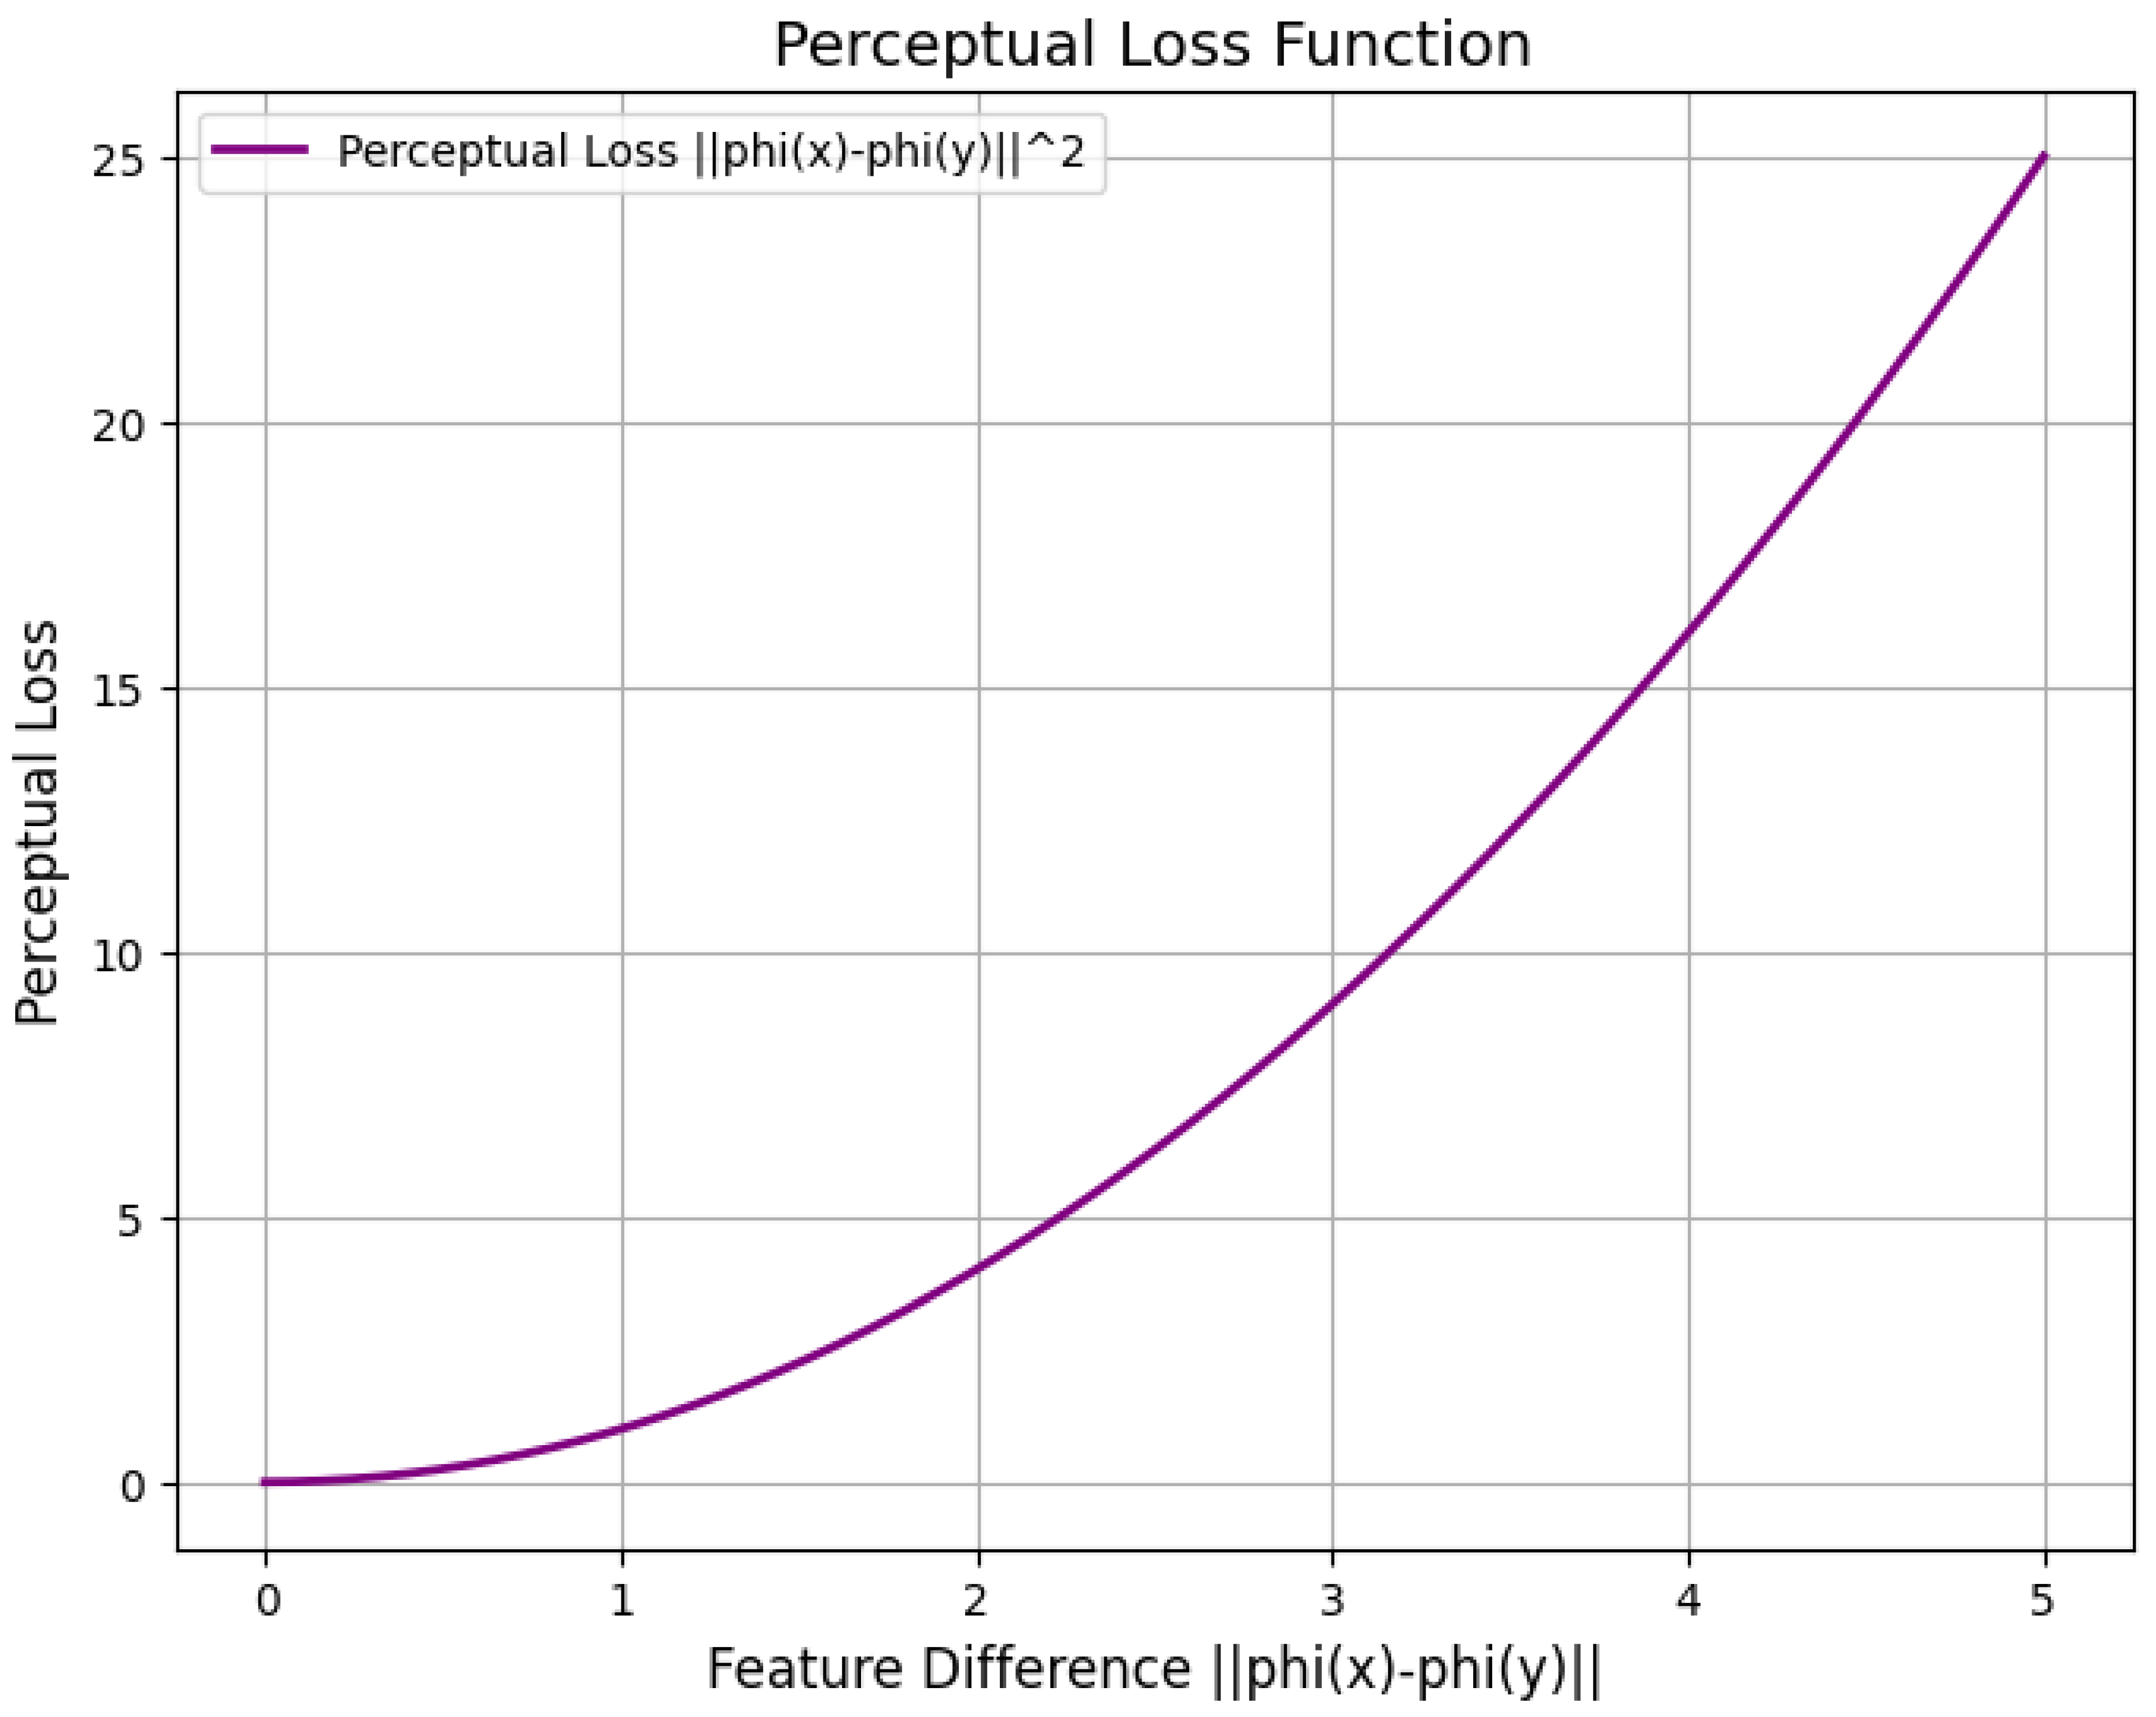
10.5.3.25 Python Code to Generate Figure 92 Illustrating Pixel-Wise MSE vs Perceptual Loss (Nonlinear Features)
The Python code below produces the Figure 92 illustrating Pixel-wise MSE vs Perceptual Loss (Nonlinear Features).
Figure 92.
Pixel-wise MSE vs Perceptual Loss (Nonlinear Features)
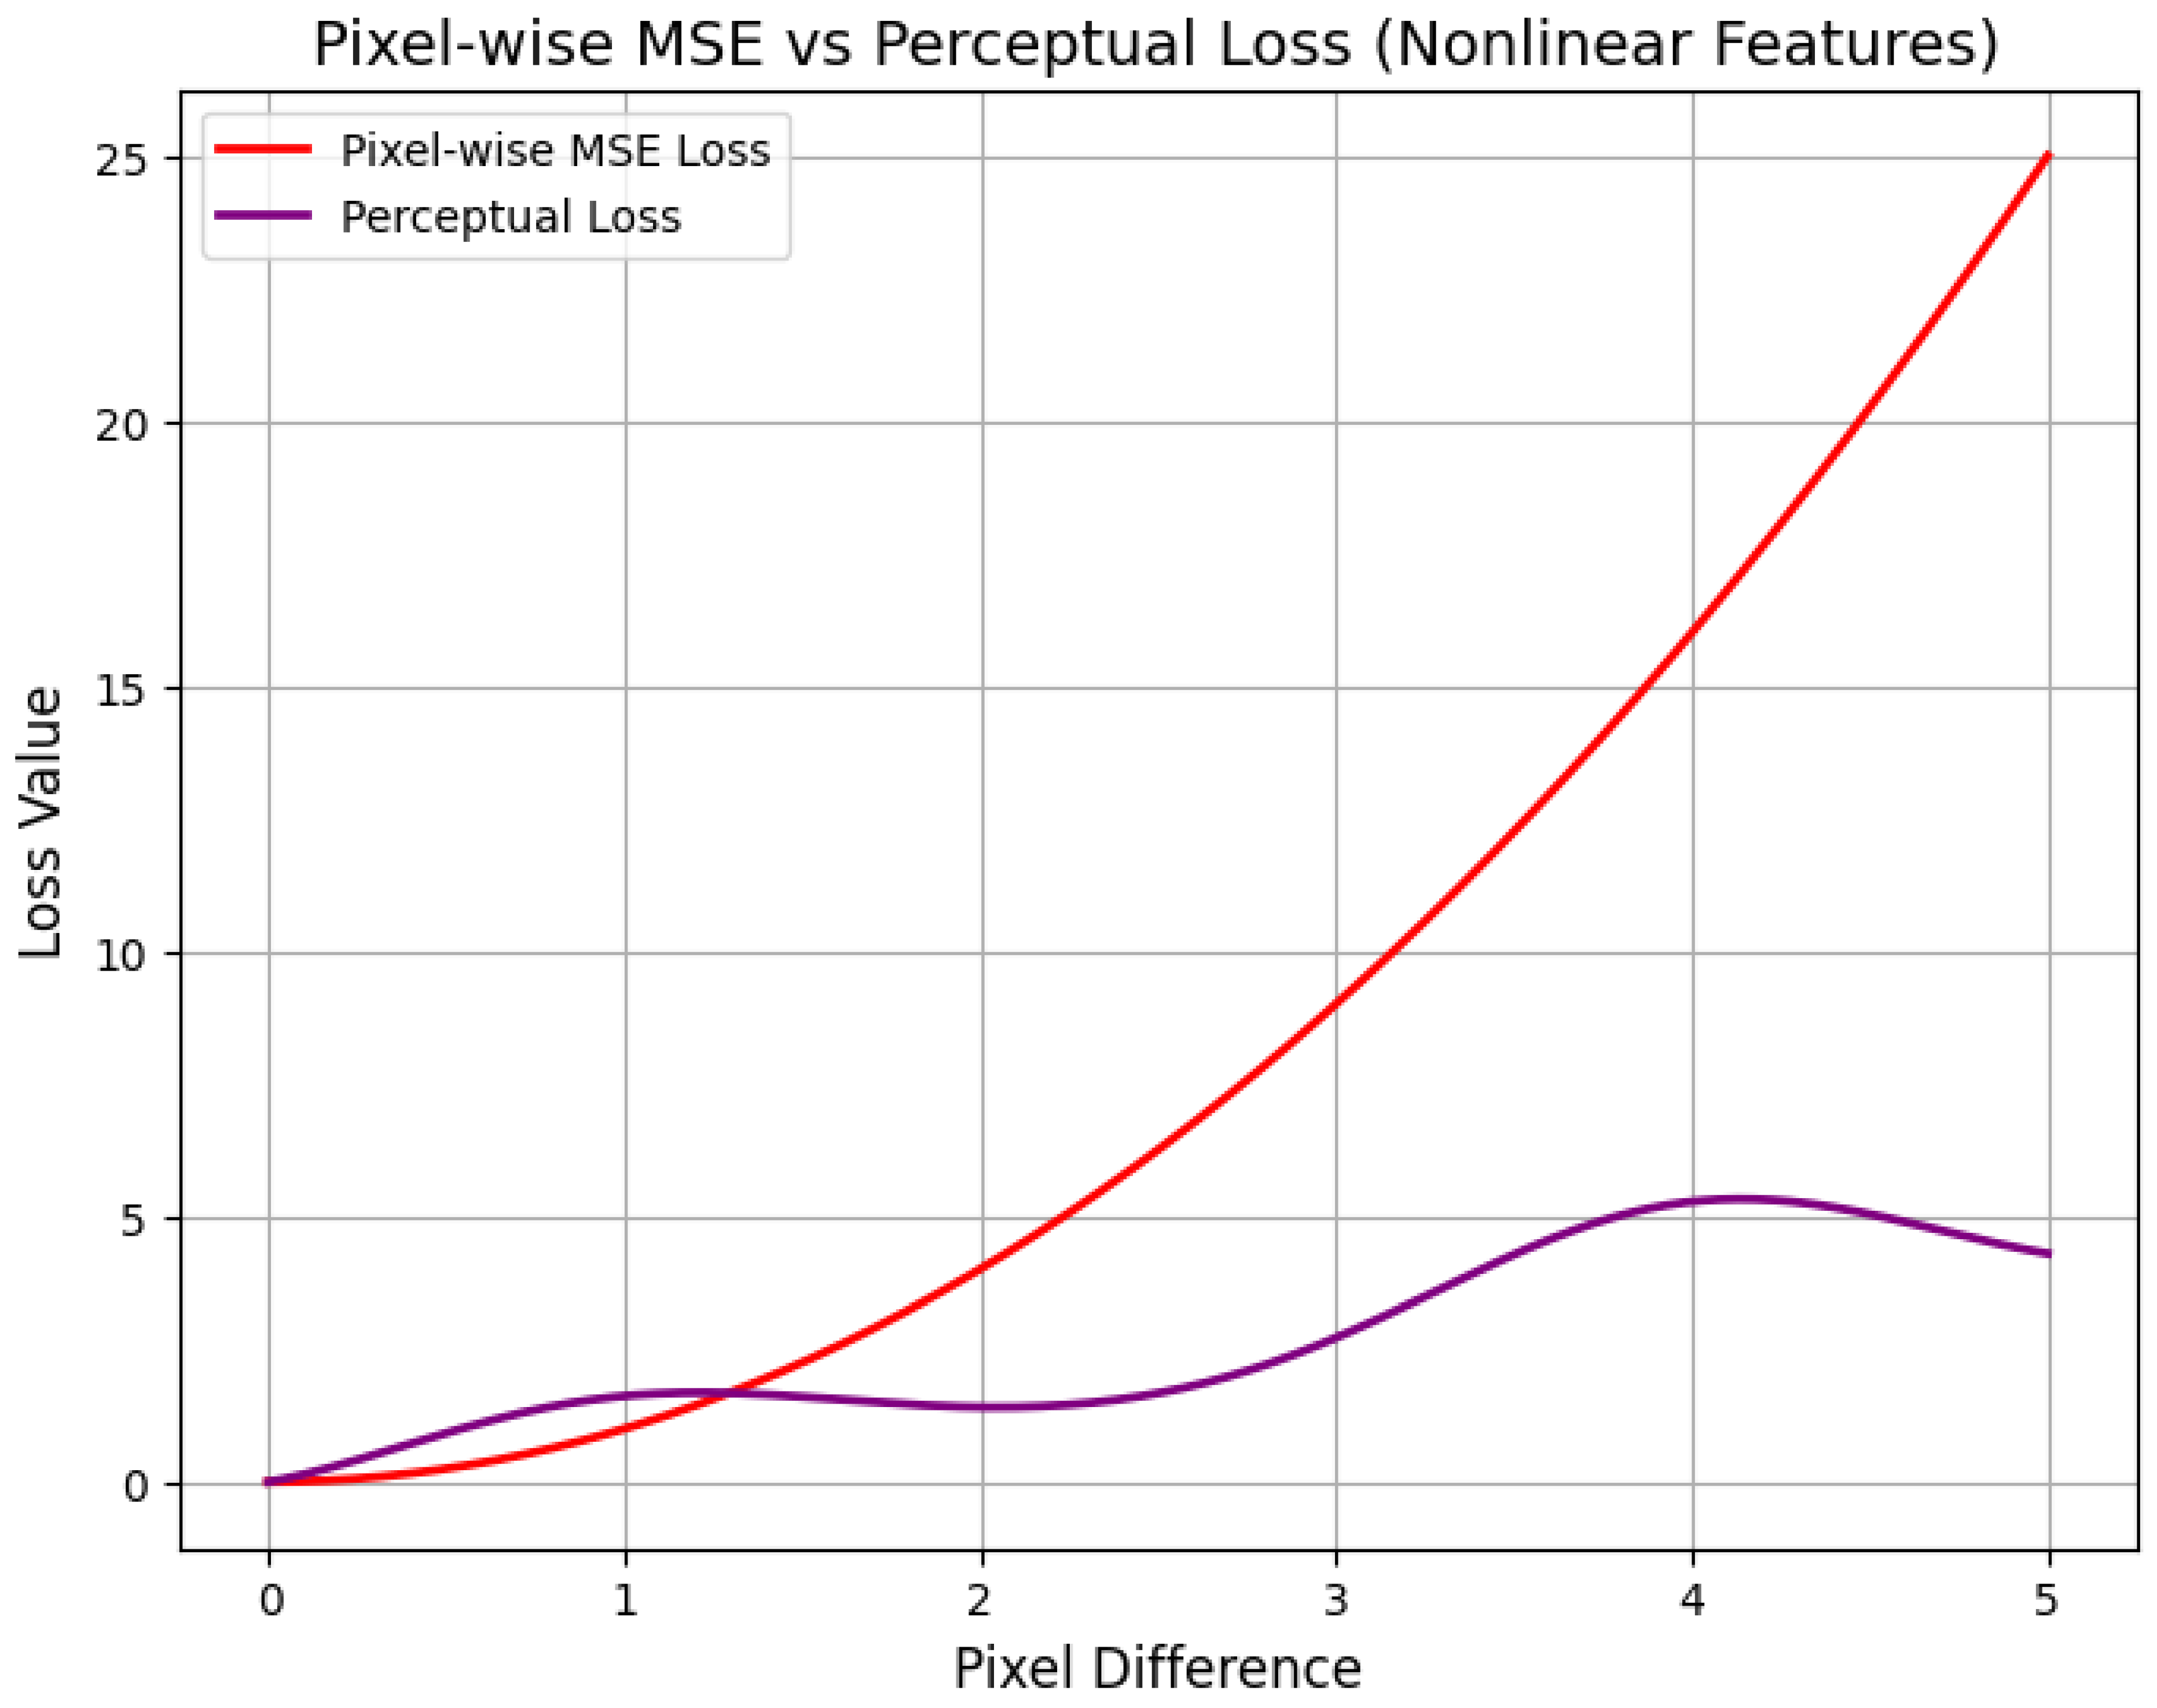
10.5.3.26 Python Code to Generate Figure 93 Illustrating Style Loss Function in Neural Style Transfer
The Python code below produces the Figure 93 illustrating Style Loss Function in Neural Style Transfer.
Figure 93.
Style Loss Function in Neural Style Transfer
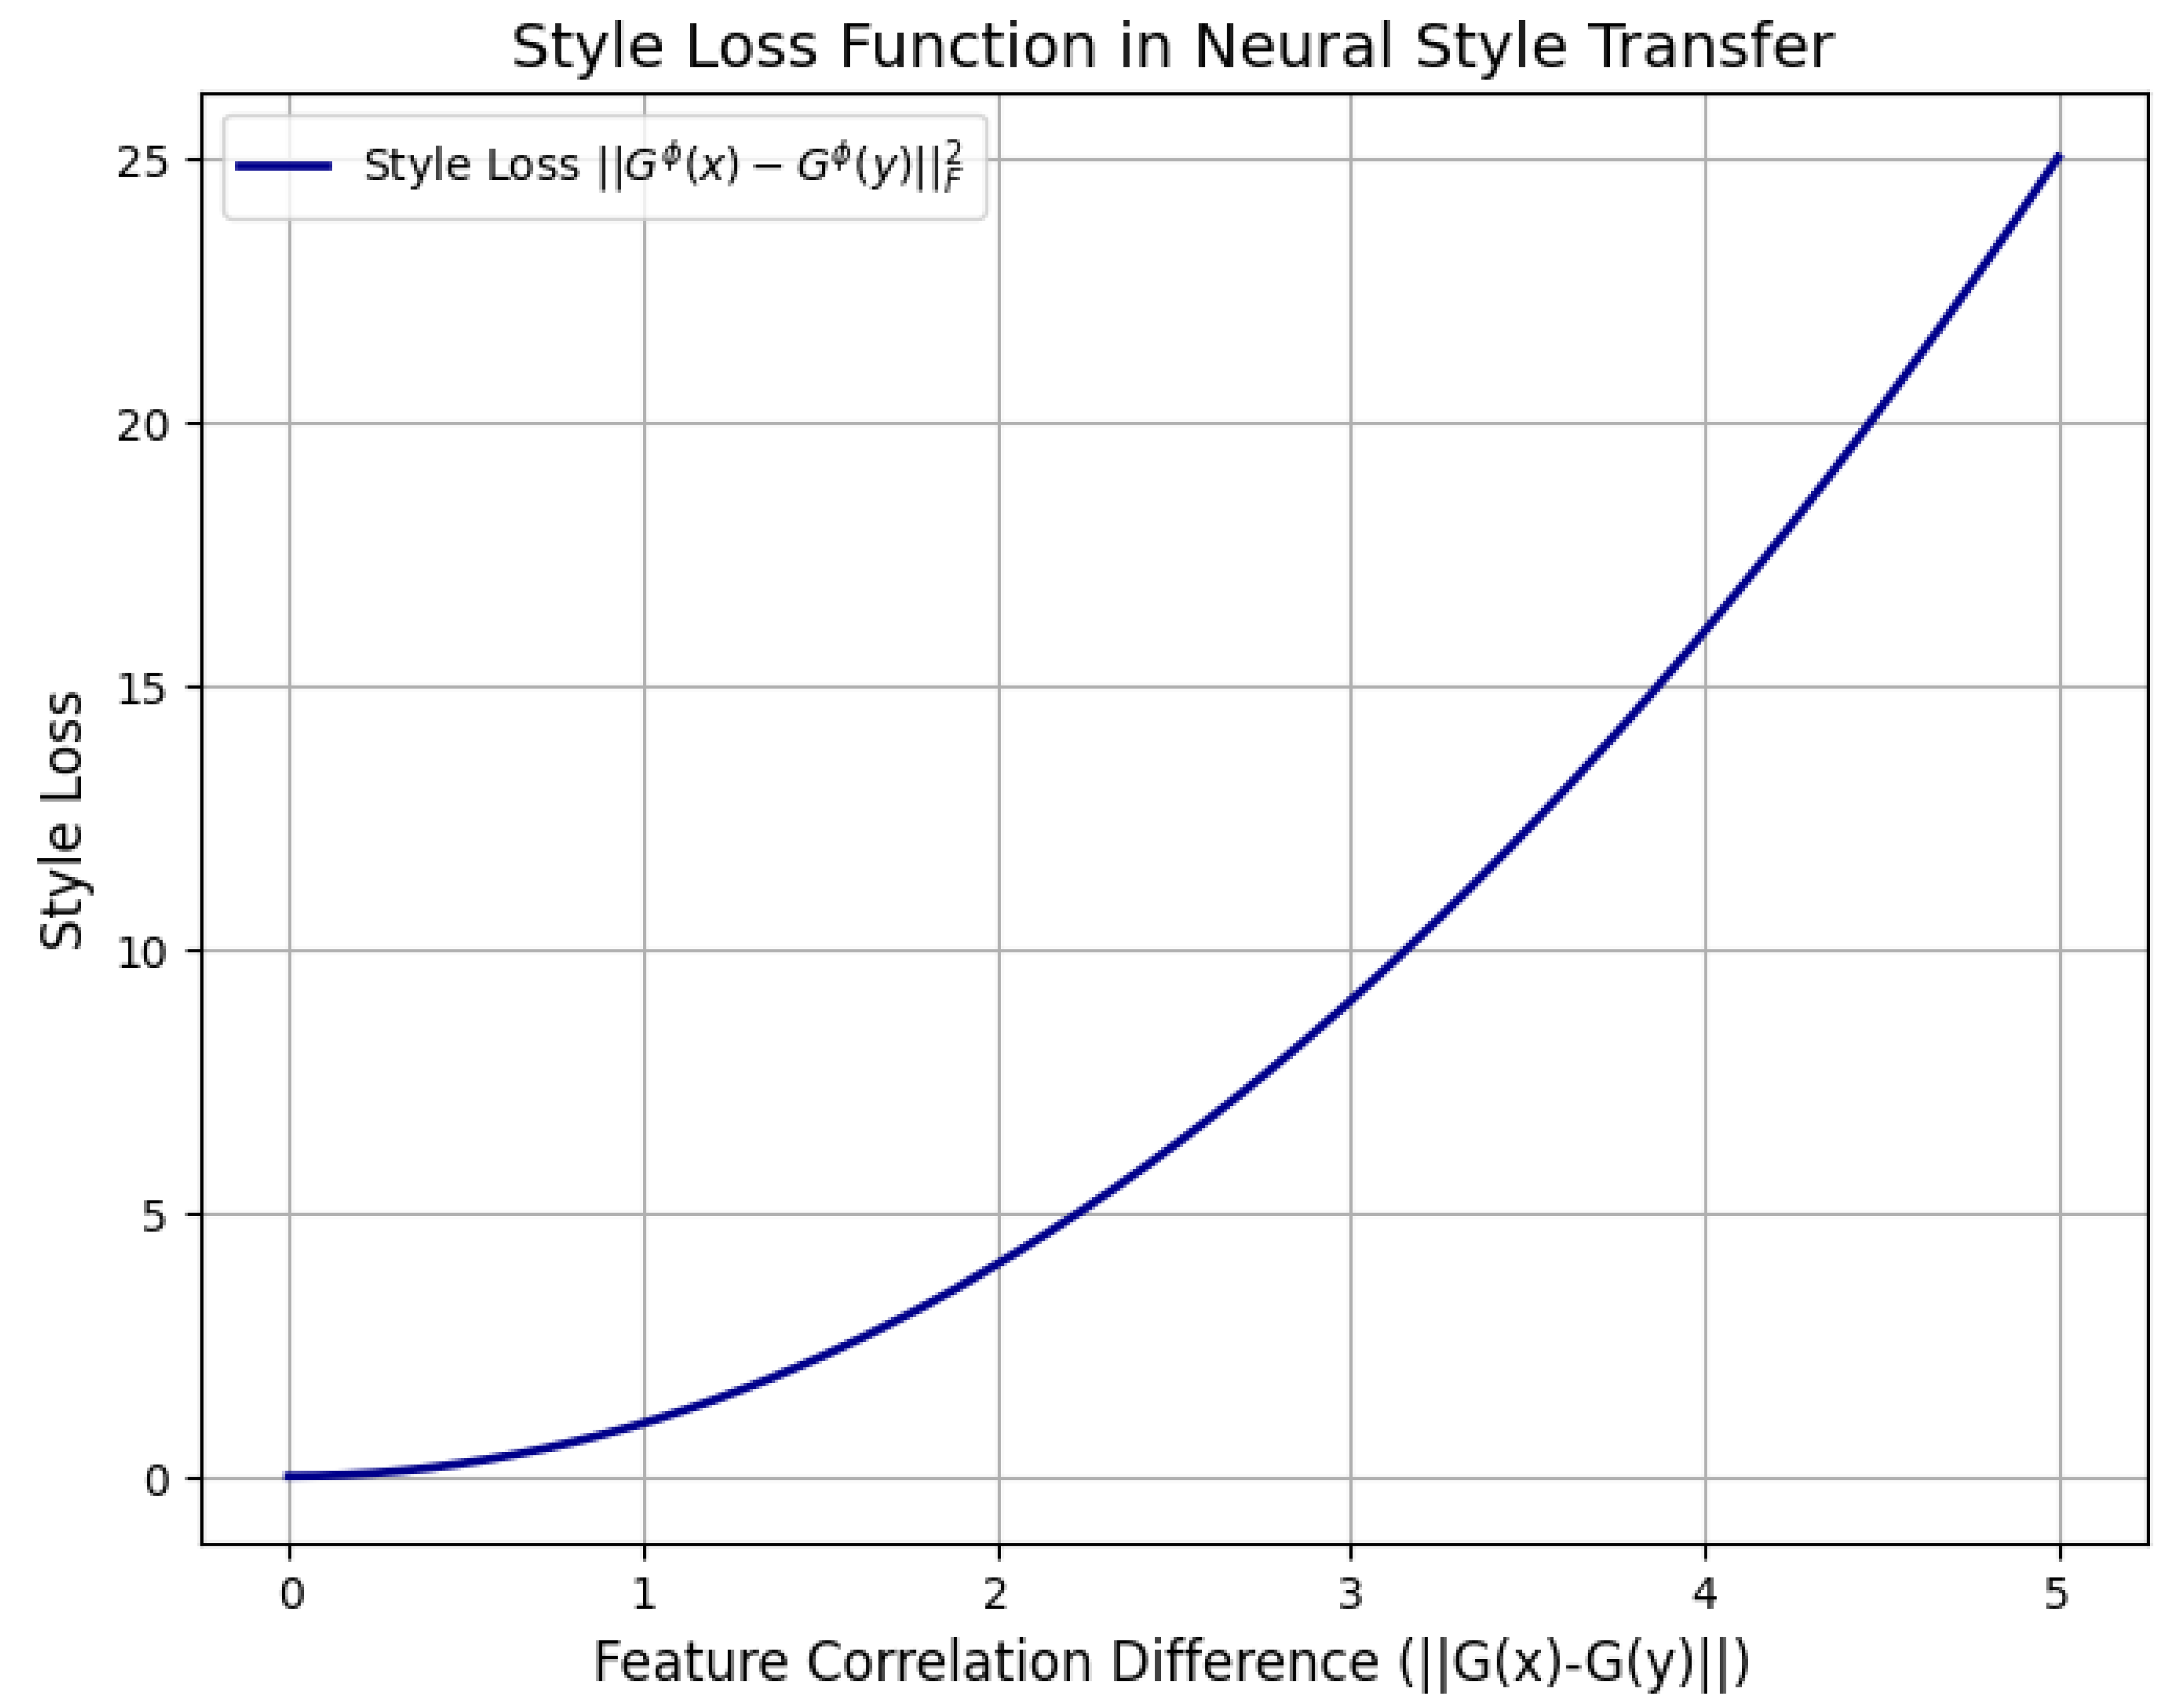
10.5.3.27 Python Code to Generate Figure 94 Illustrating Style Loss vs Scaling of Generated Features
The Python code below produces the Figure 94 illustrating Style Loss vs Scaling of Generated Features.
Figure 94.
Style Loss vs Scaling of Generated Features
10.5.3.28 Python Code to Generate Figure 95 Illustrating Total Variation (TV) Loss
The Python code below produces the Figure 95 illustrating Total Variation (TV) Loss.
Figure 95.
Total Variation (TV) Loss
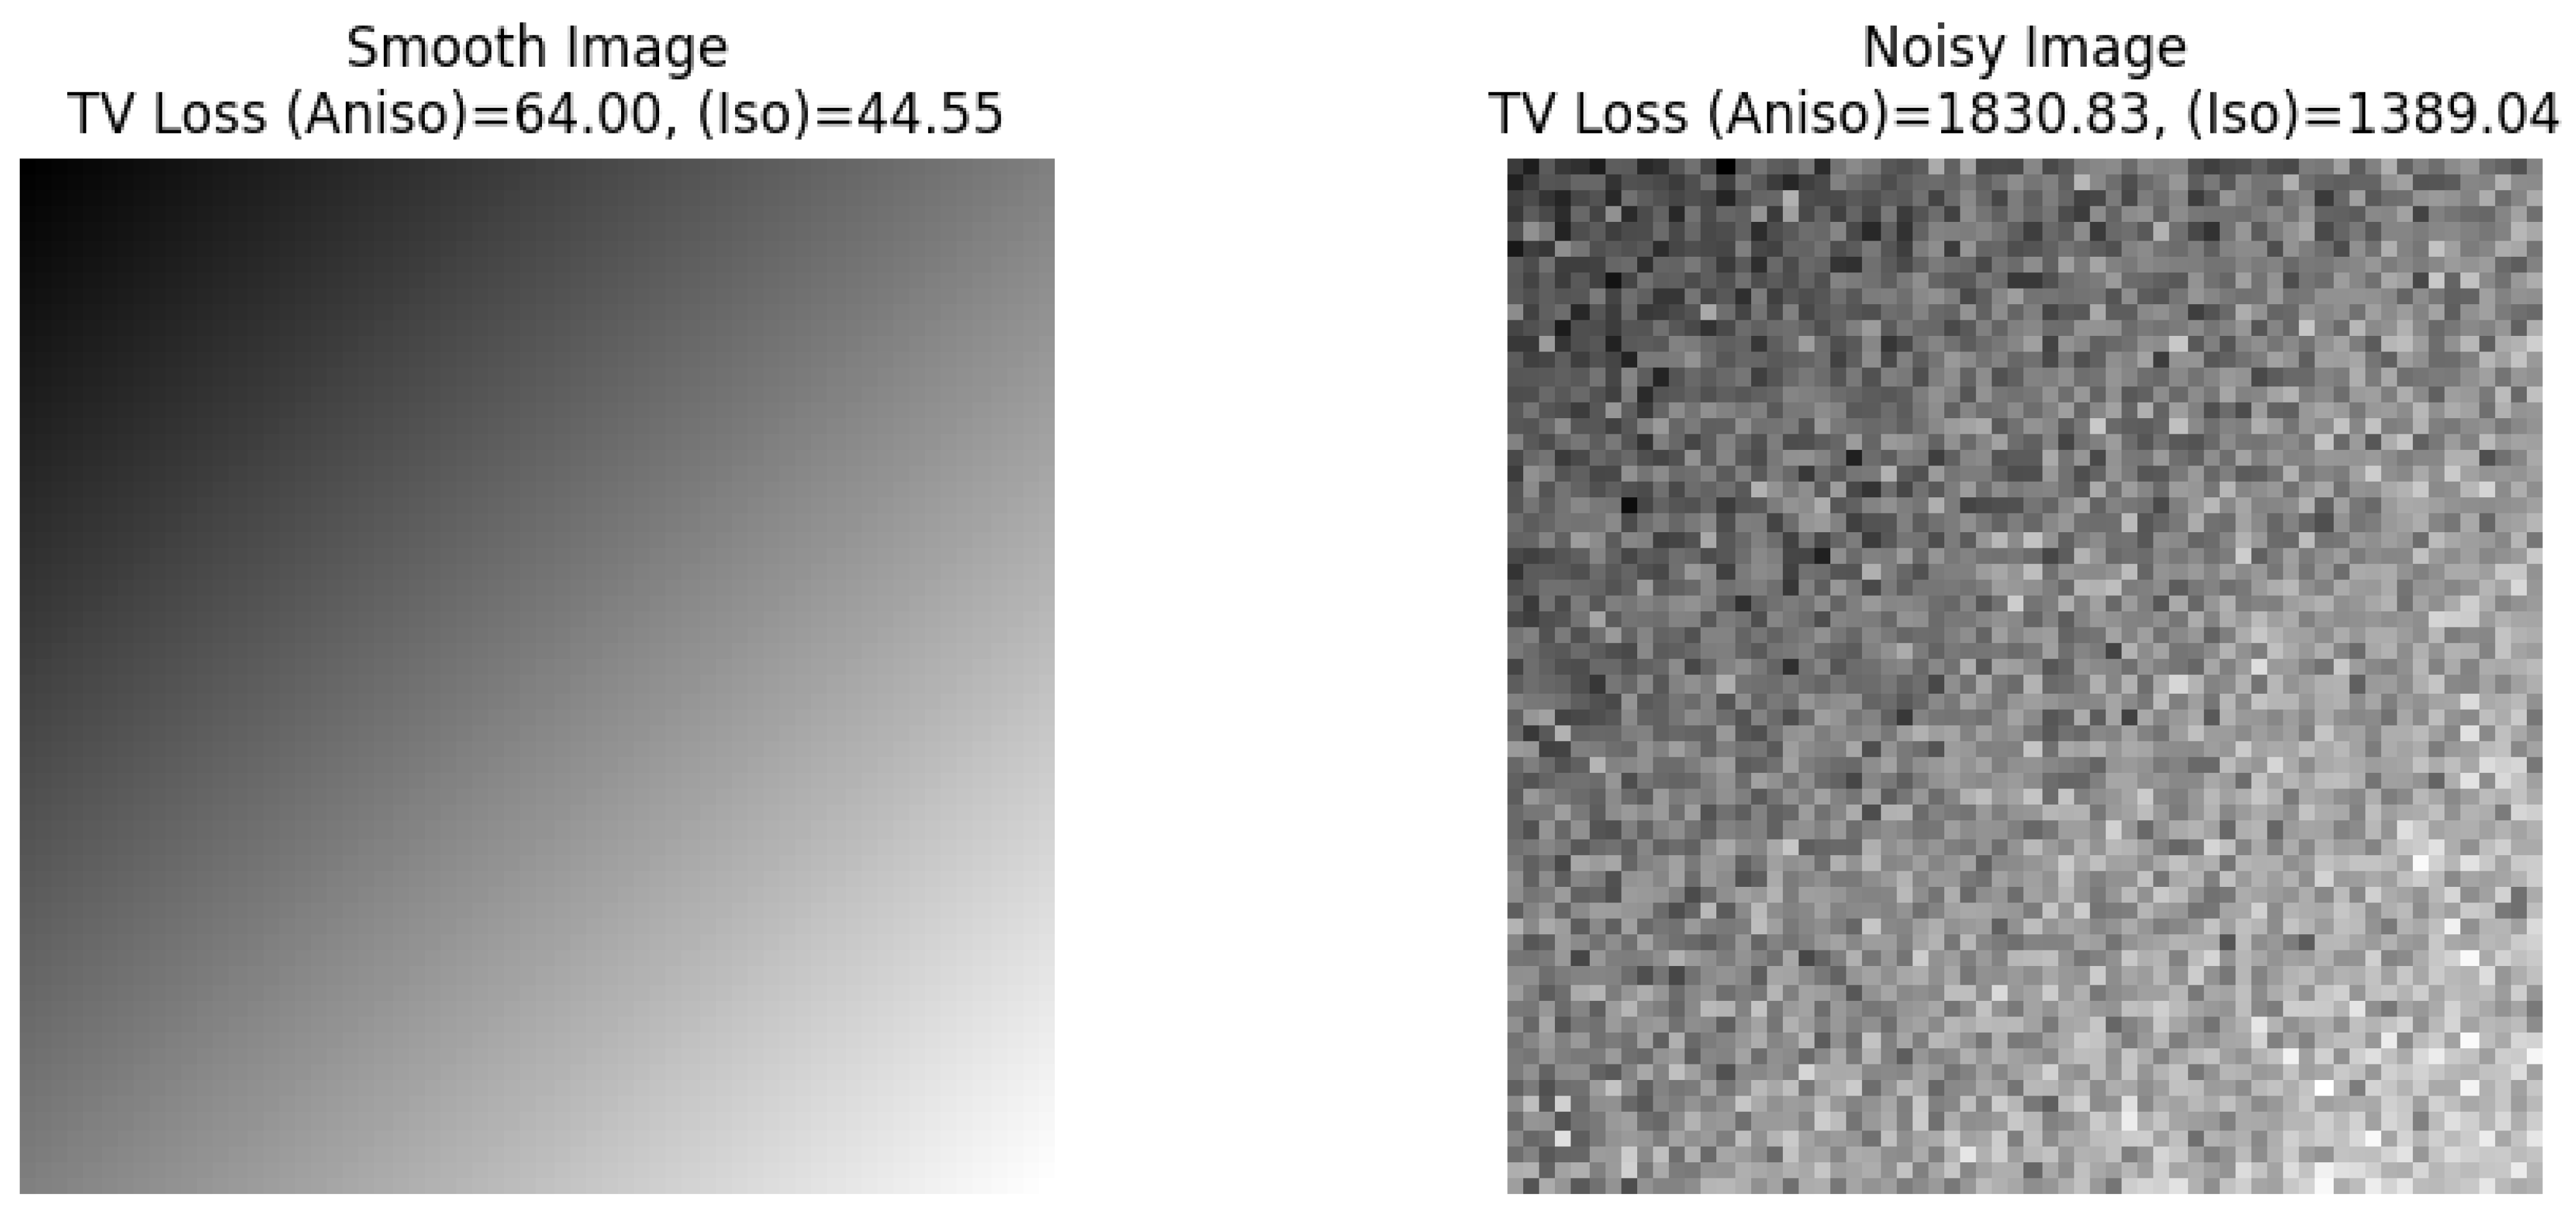
10.5.3.29 Python Code to Generate Figure 96 Illustrating Total Variation Loss vs Noise Level
The Python code below produces the Figure 96 illustrating Total Variation Loss vs Noise Level.
Figure 96.
Total Variation Loss vs Noise Level
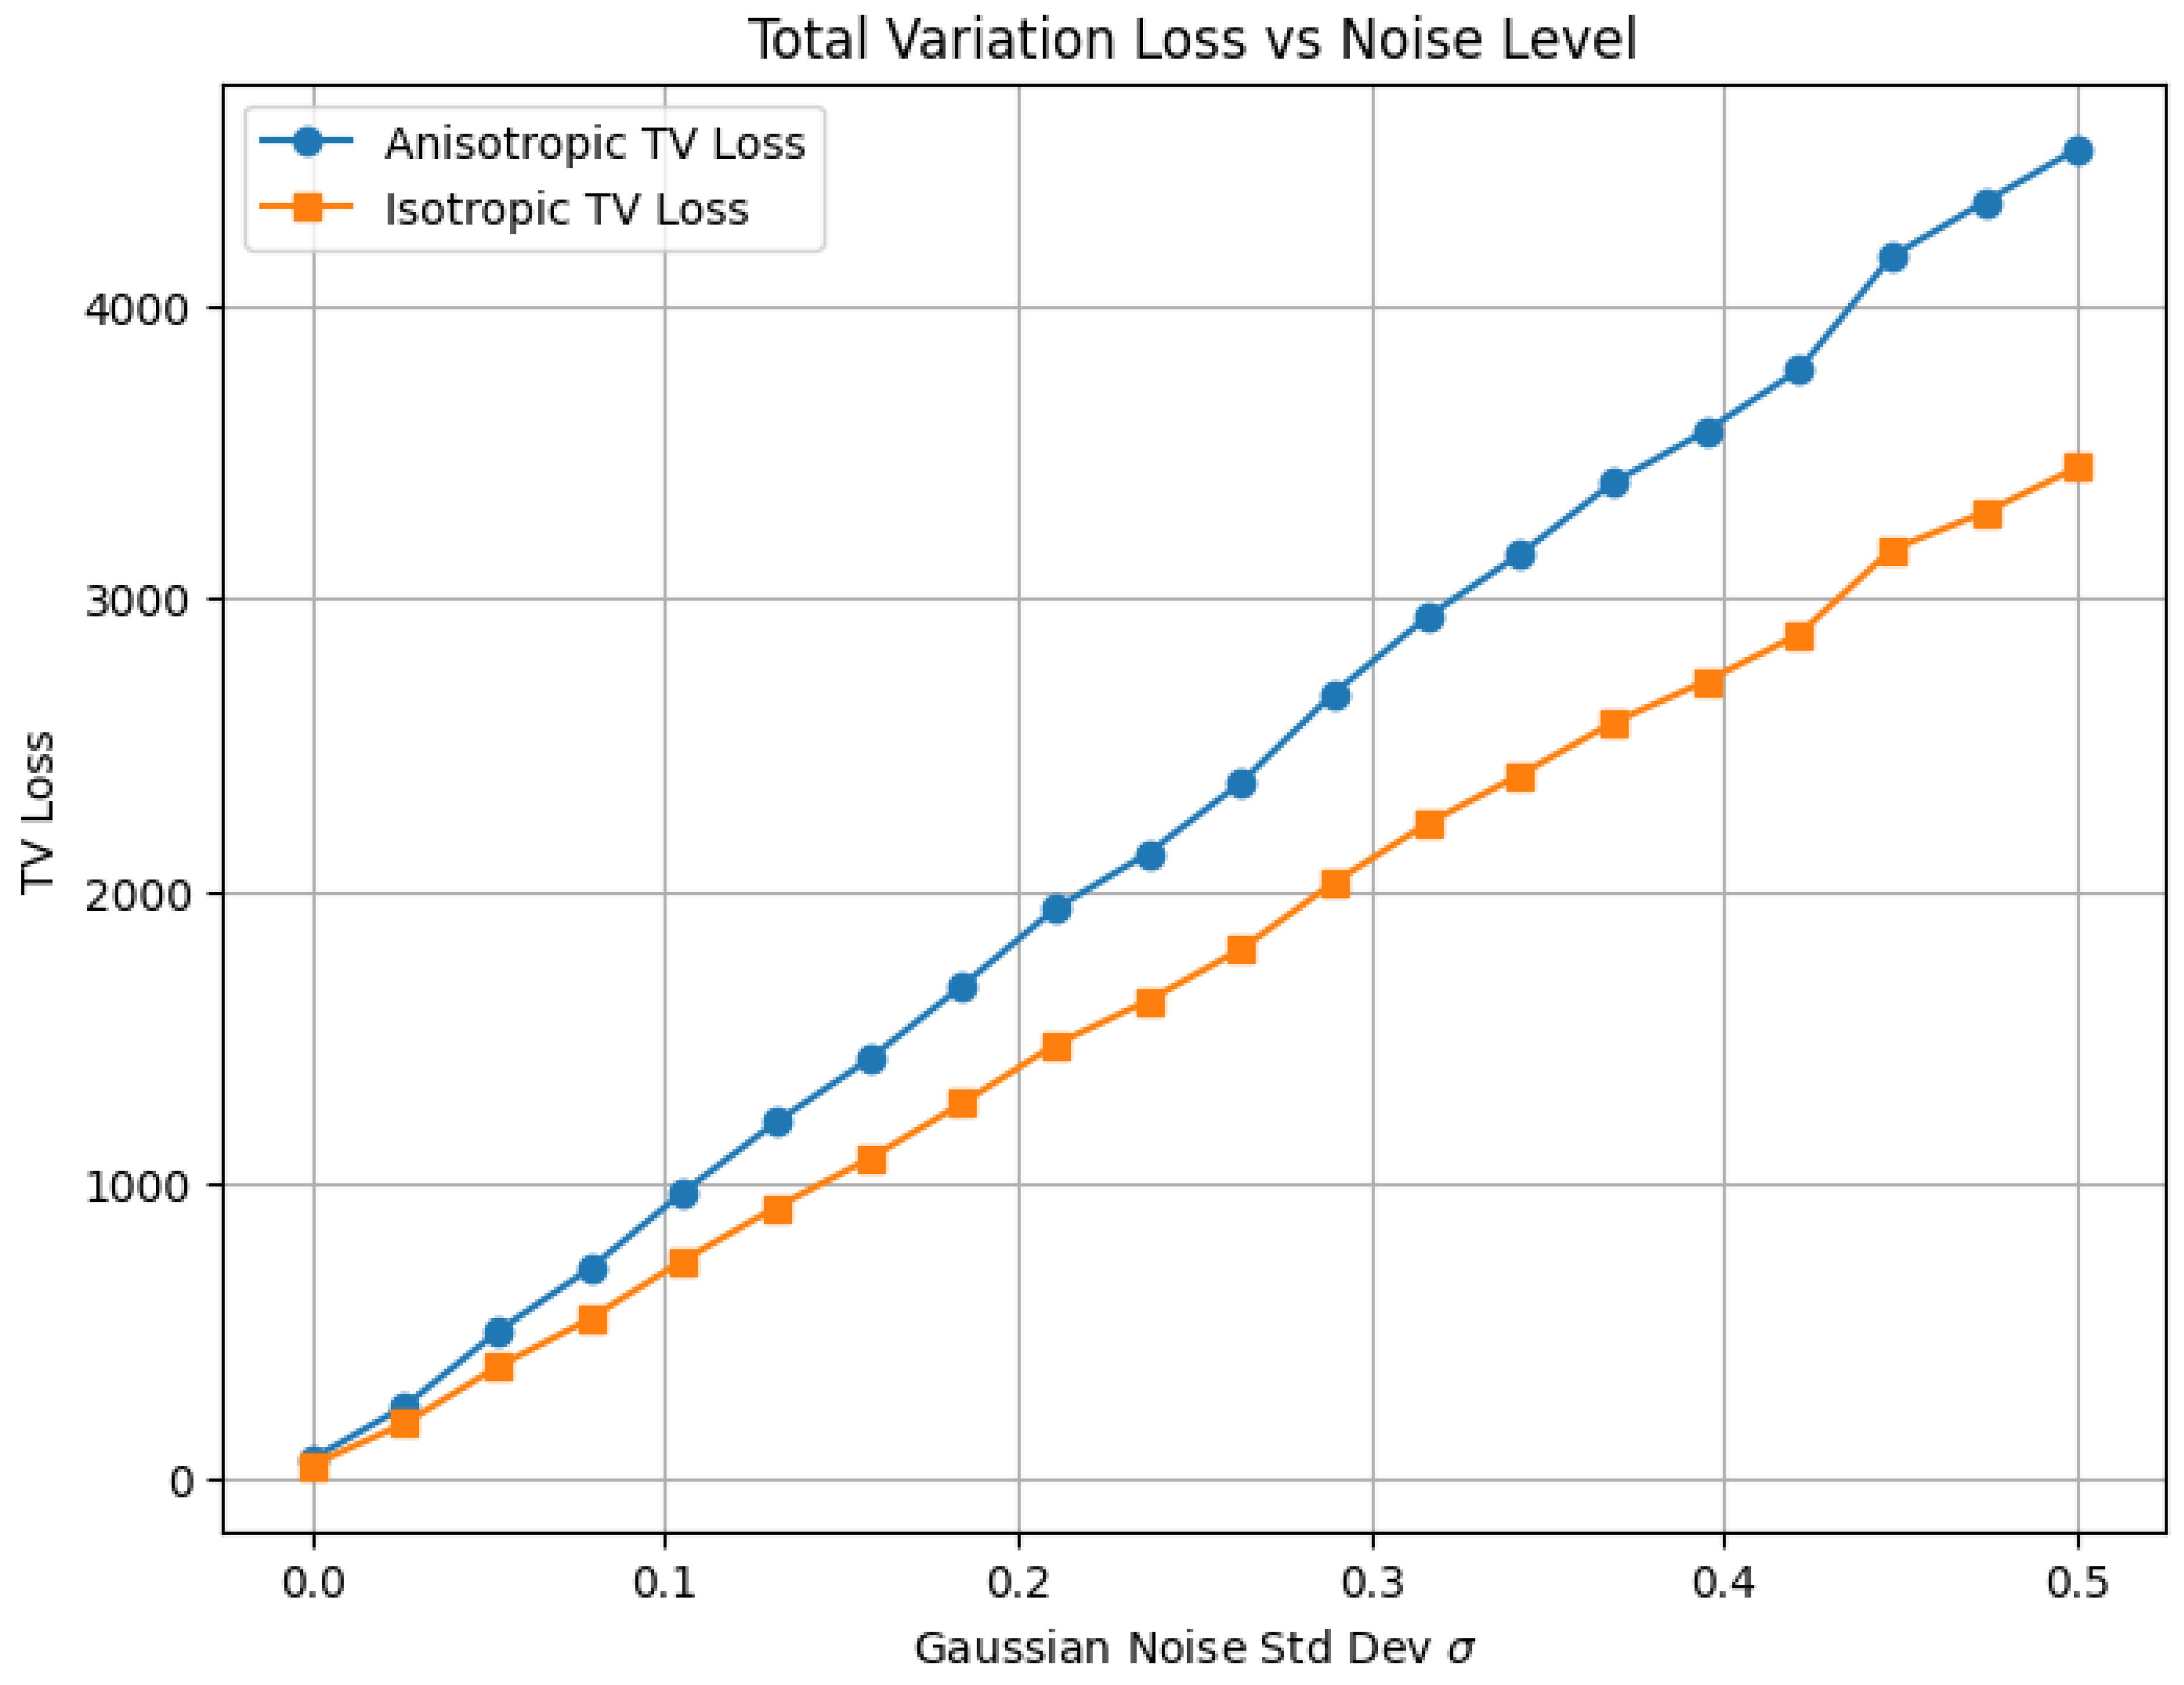
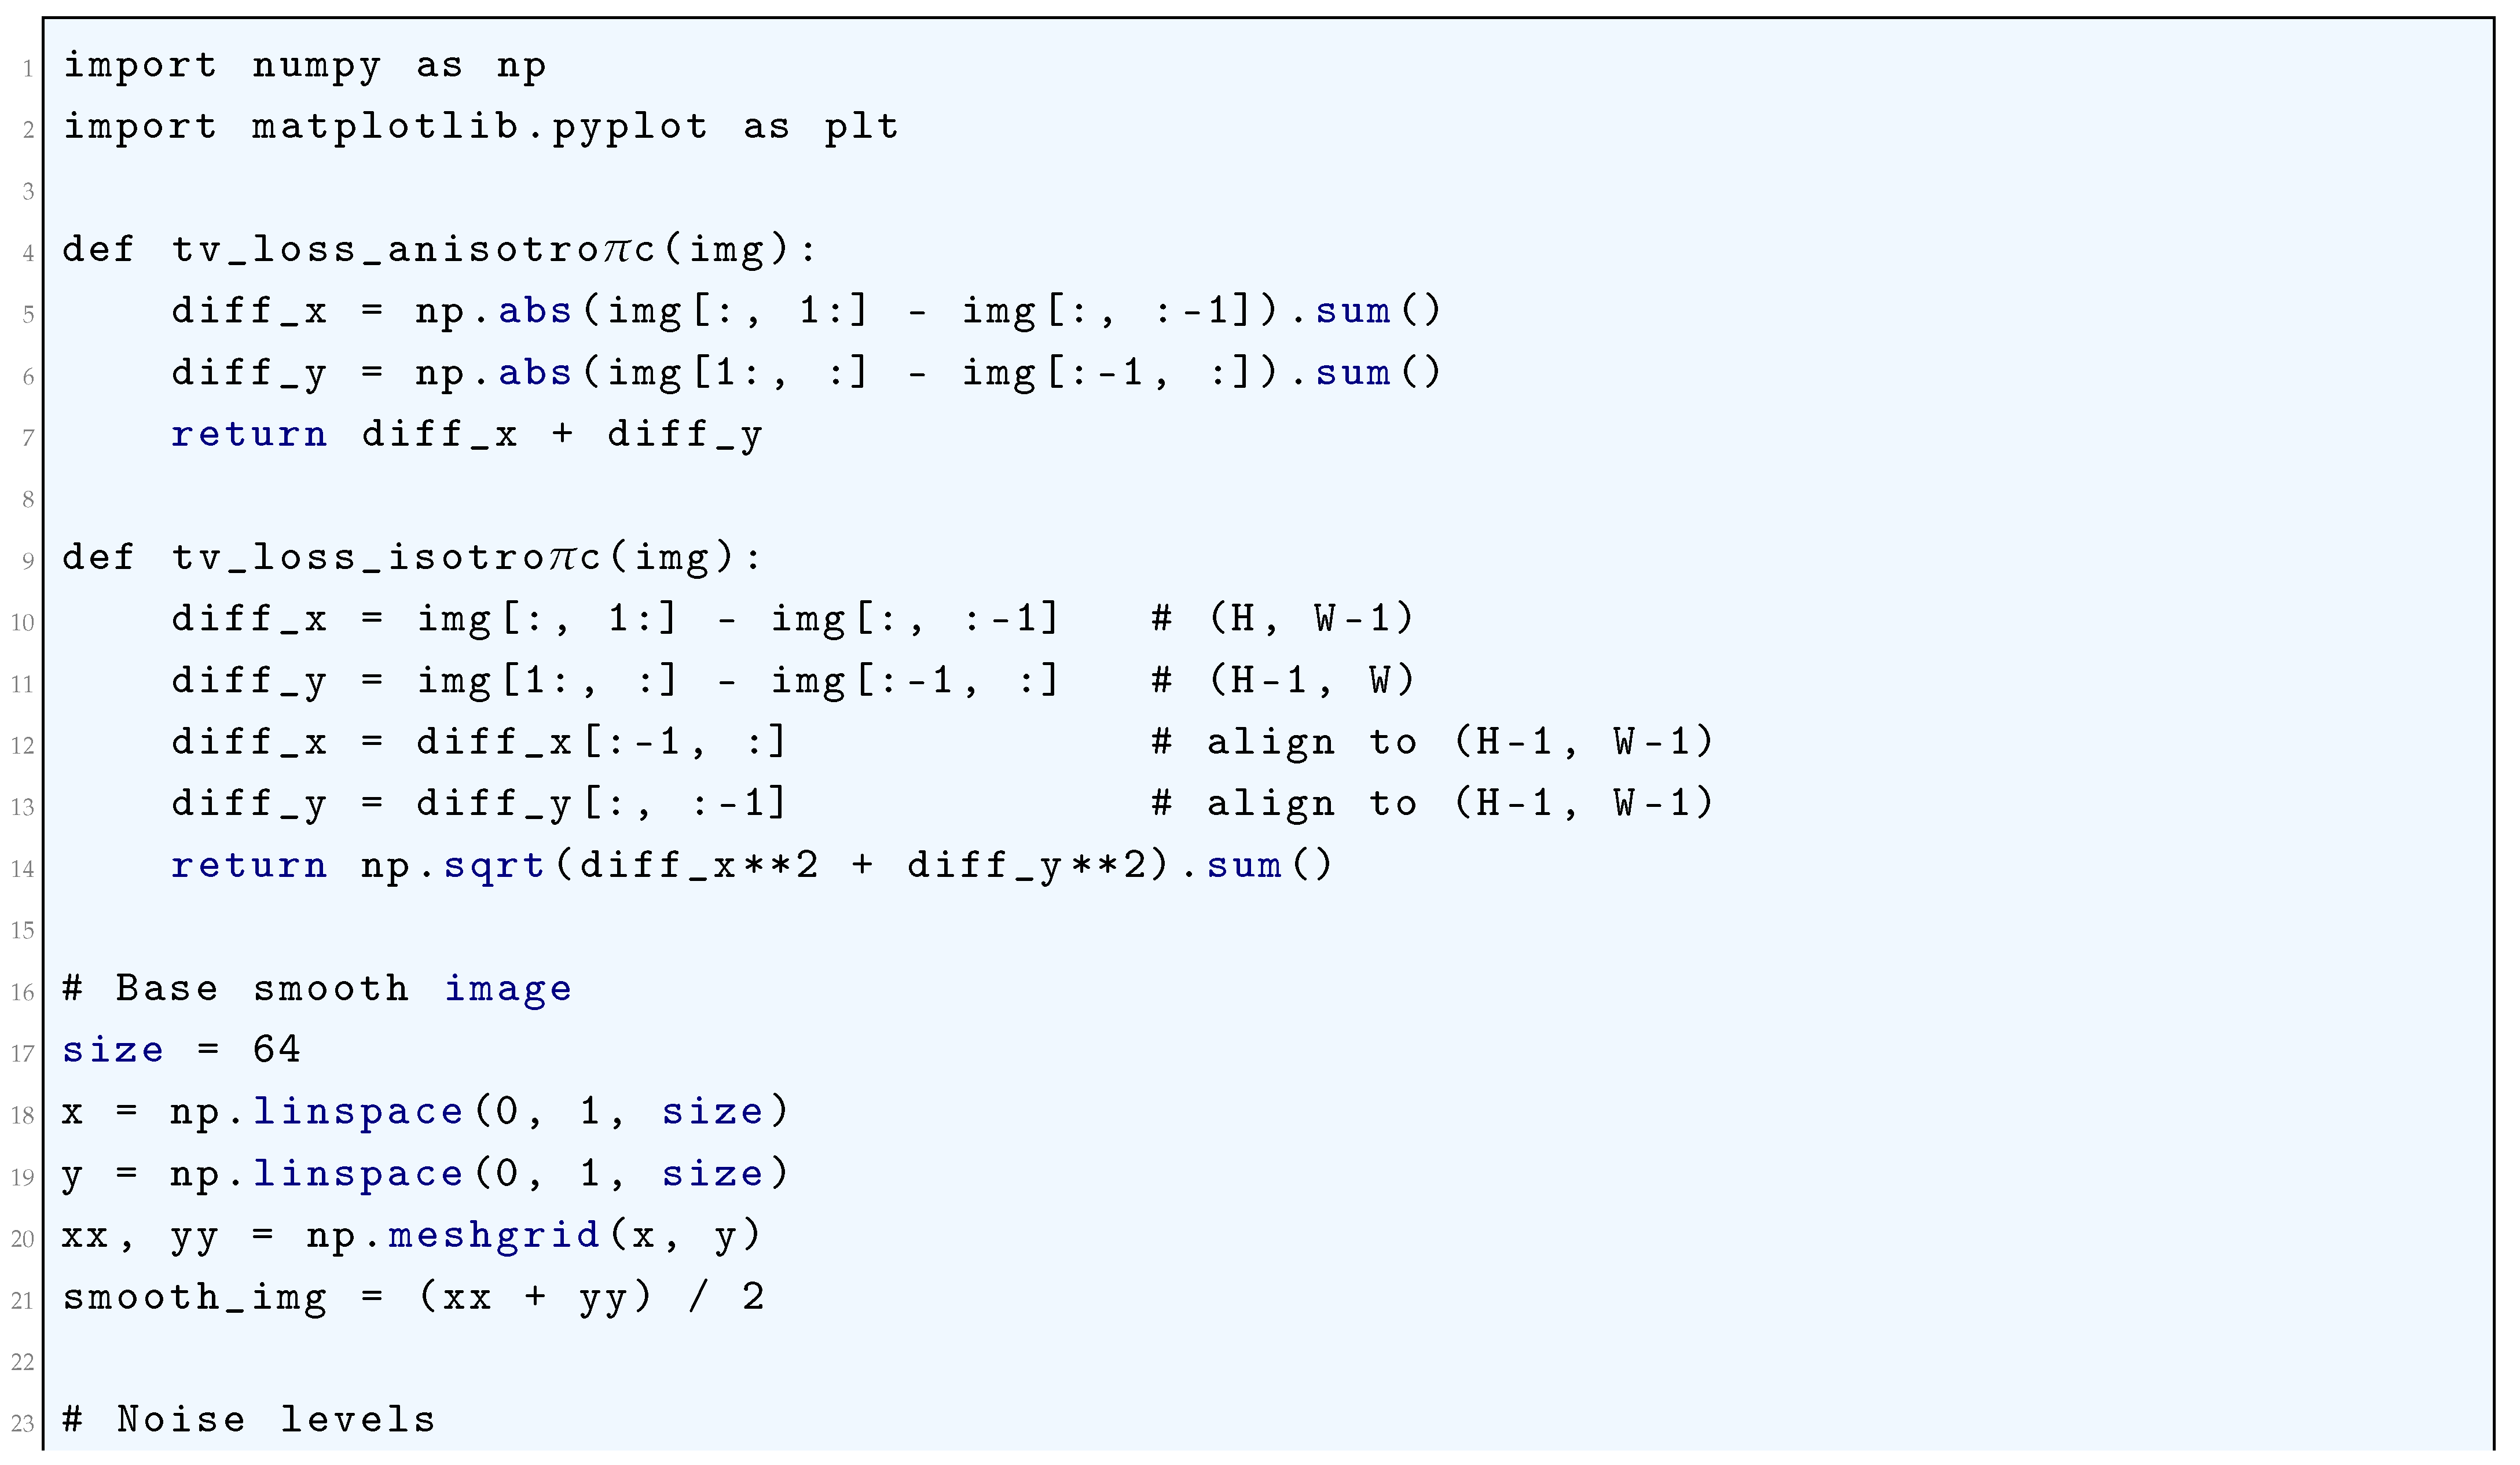
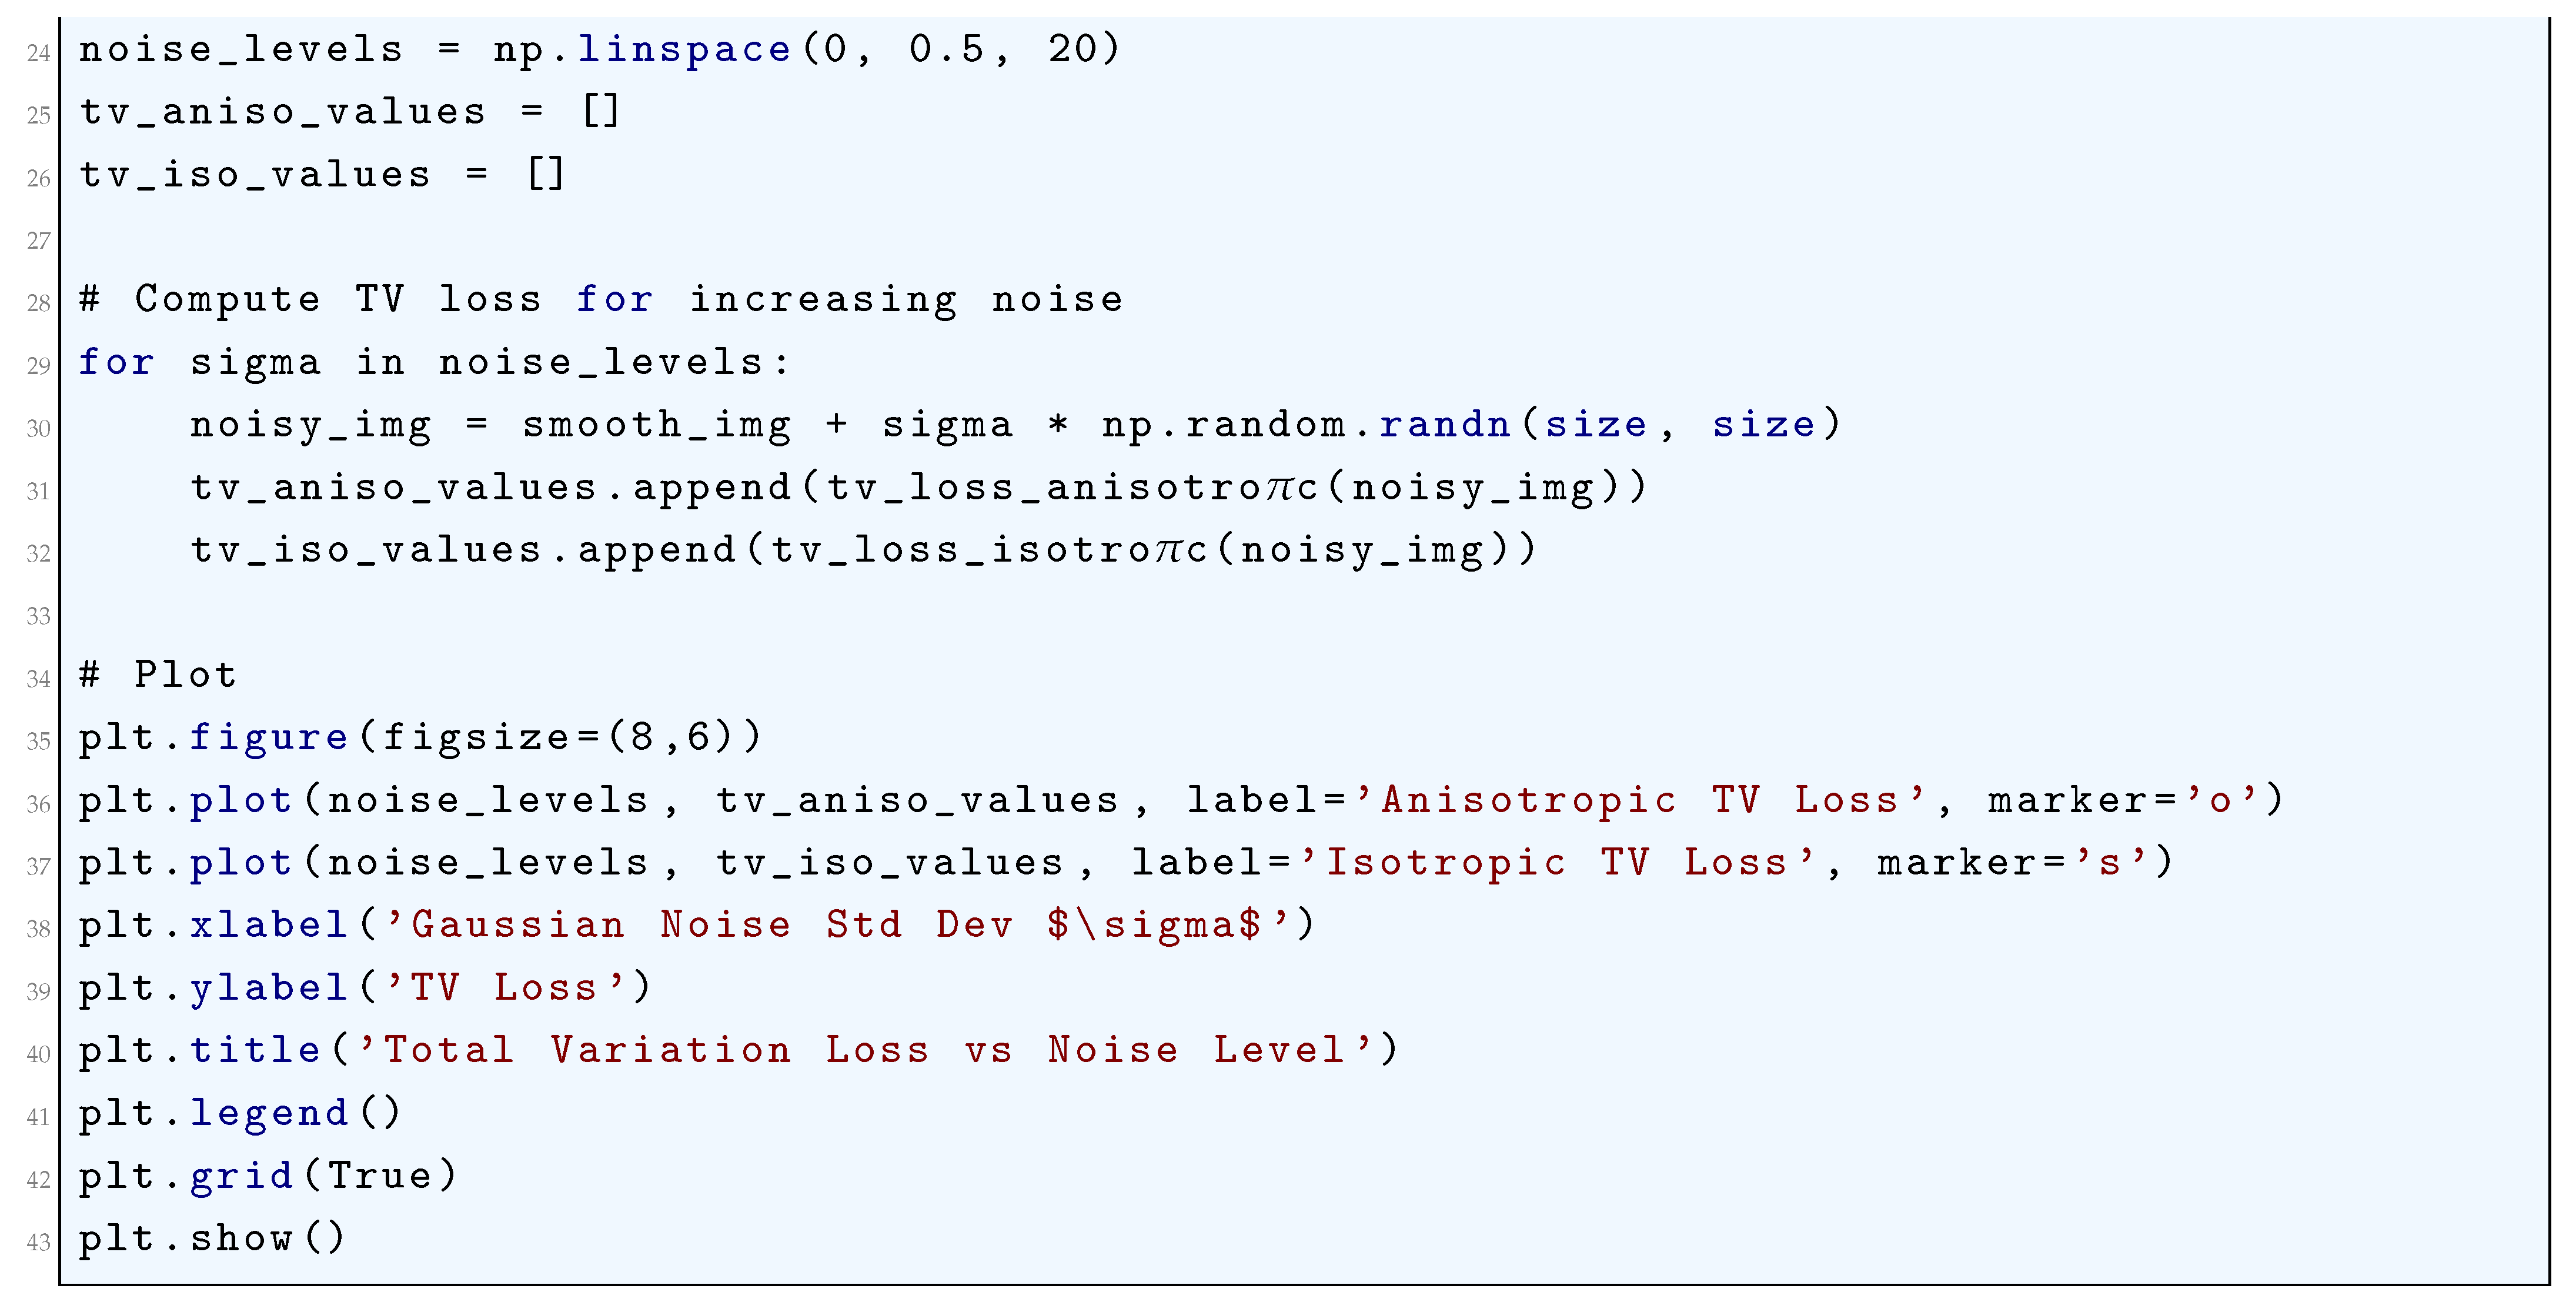
10.5.3.30 Python Code to Generate Figure 97 Illustrating Evidence Lower Bound (ELBO) Loss During Training
The Python code below produces the Figure 97 illustrating Evidence Lower Bound (ELBO) Loss during Training.
Figure 97.
Evidence Lower Bound (ELBO) Loss during Training
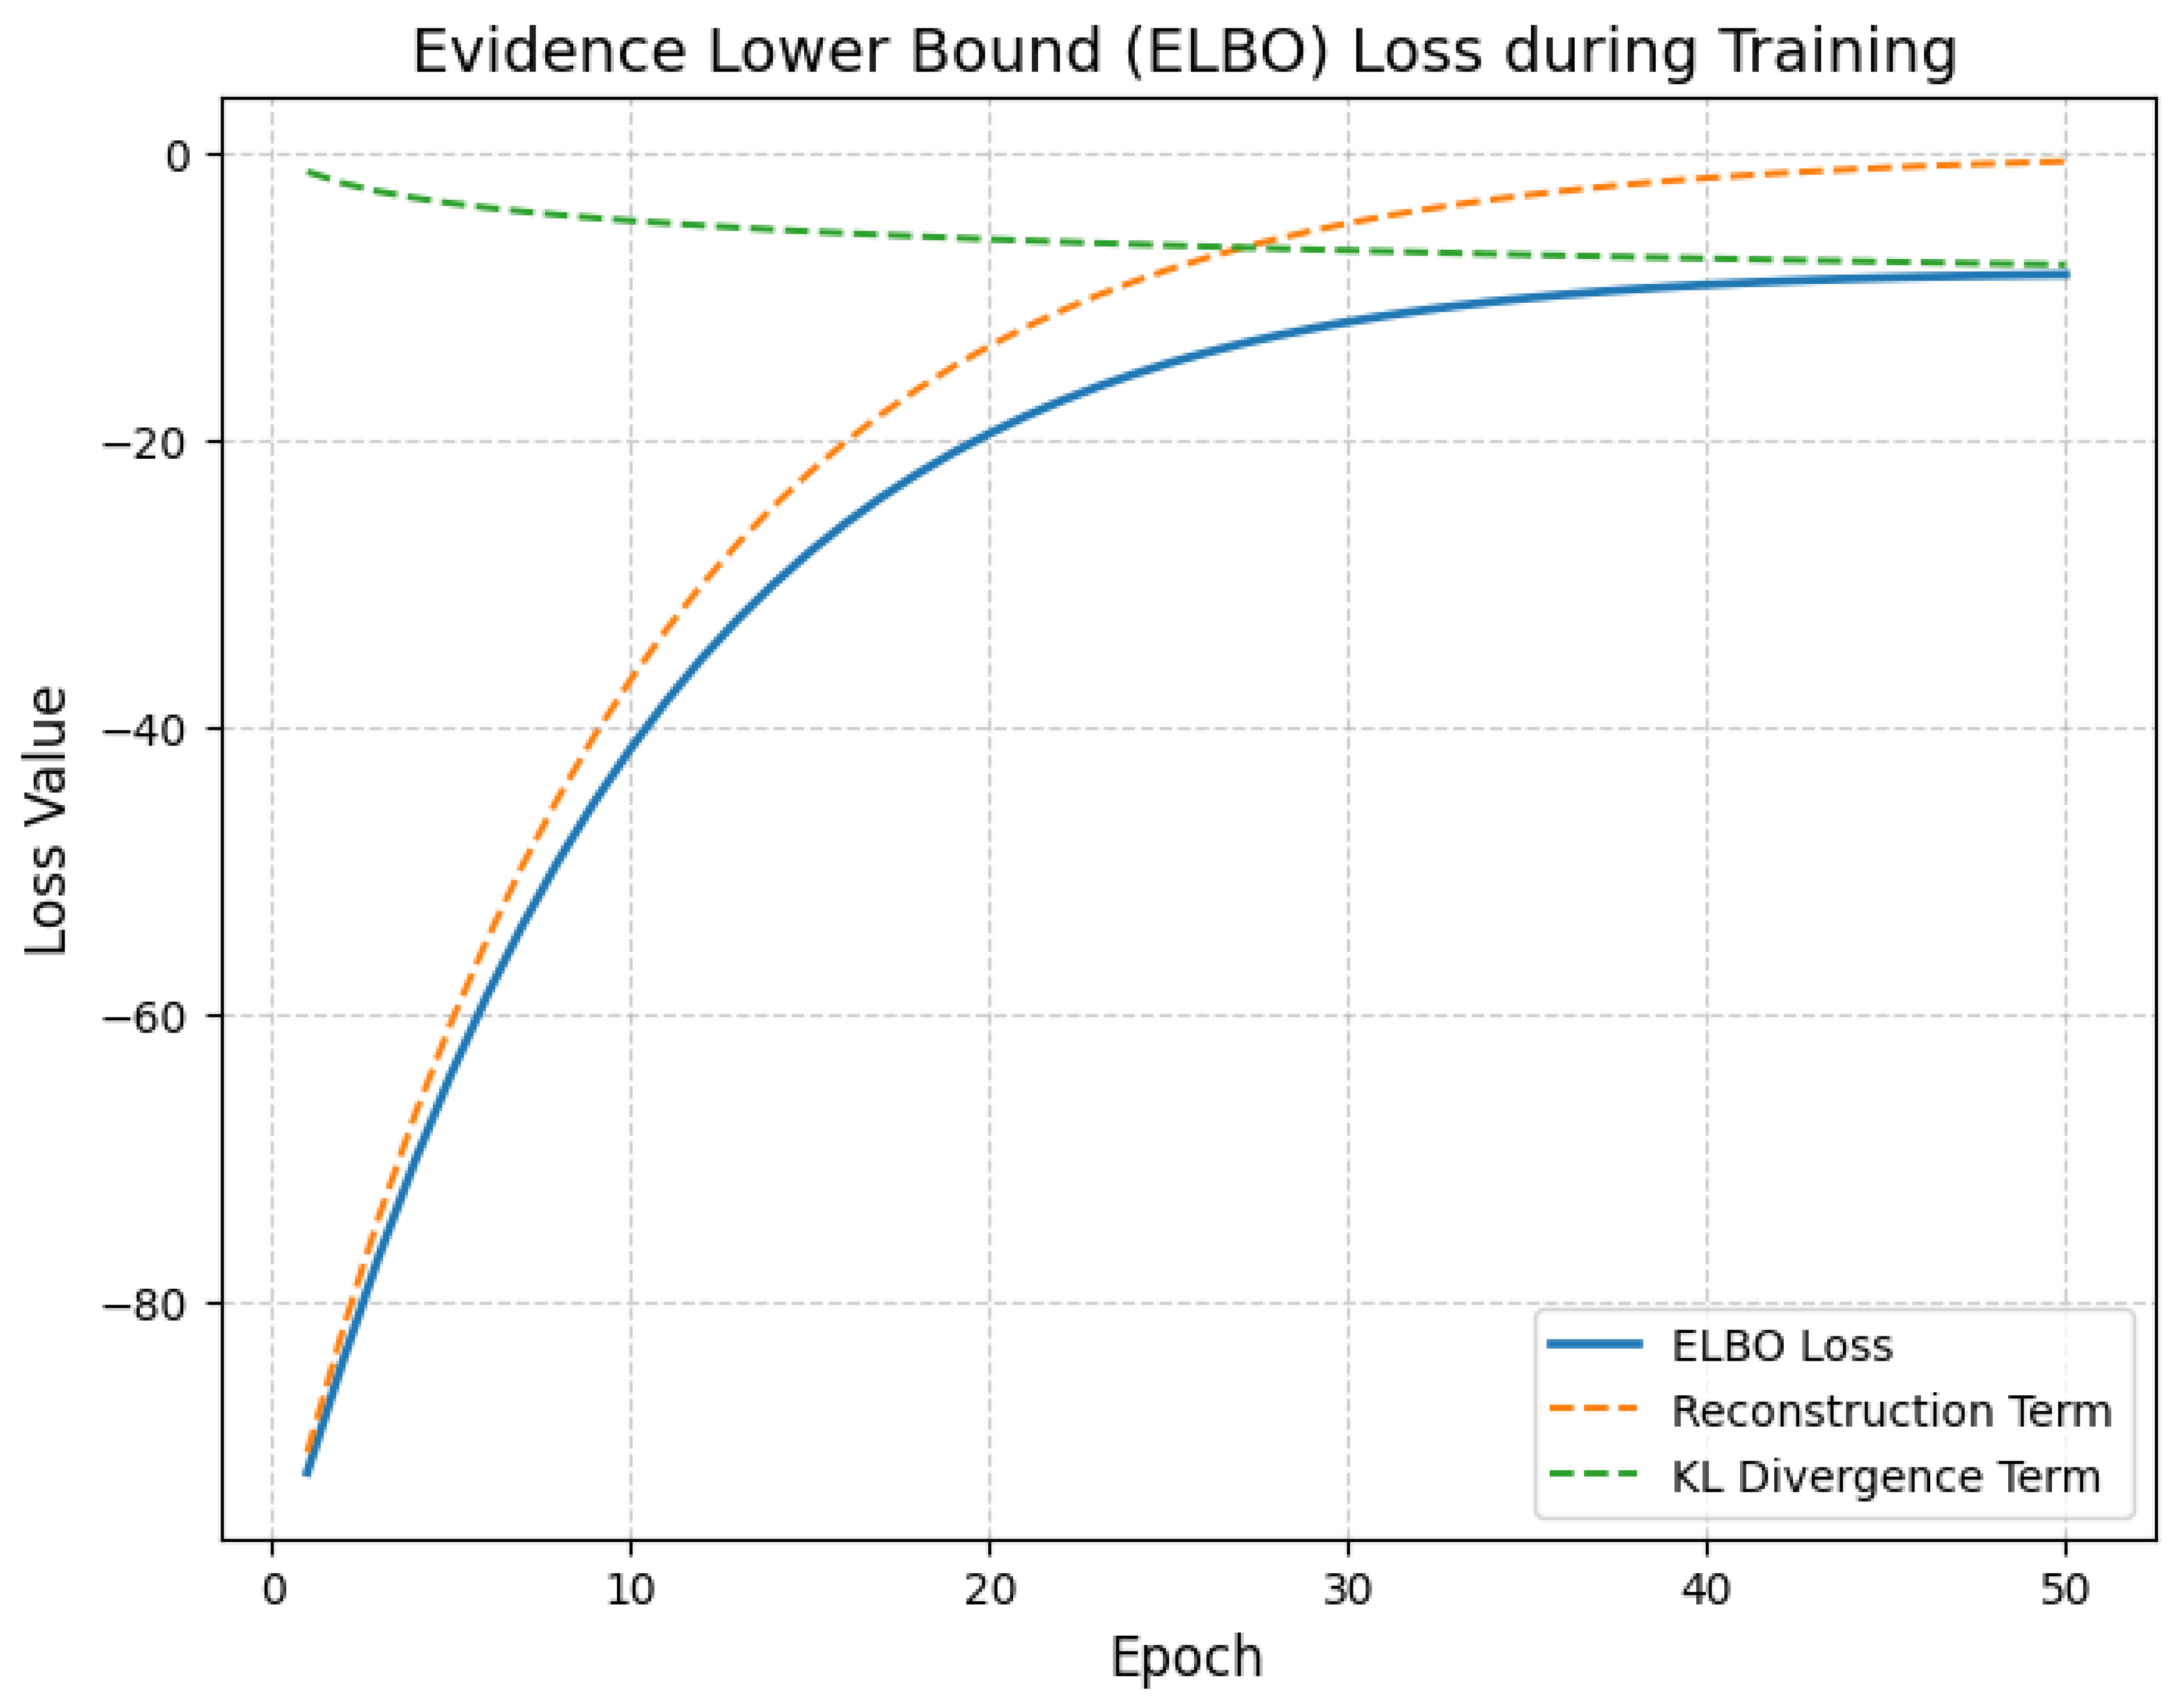
10.5.3.31 Python Code to Generate Figure 98 Illustrating Negative Log-Likelihood (NLL) Loss
The Python code below produces the Figure 98 illustrating Negative Log-Likelihood (NLL) Loss.
Figure 98.
Negative Log-Likelihood (NLL) Loss during Training
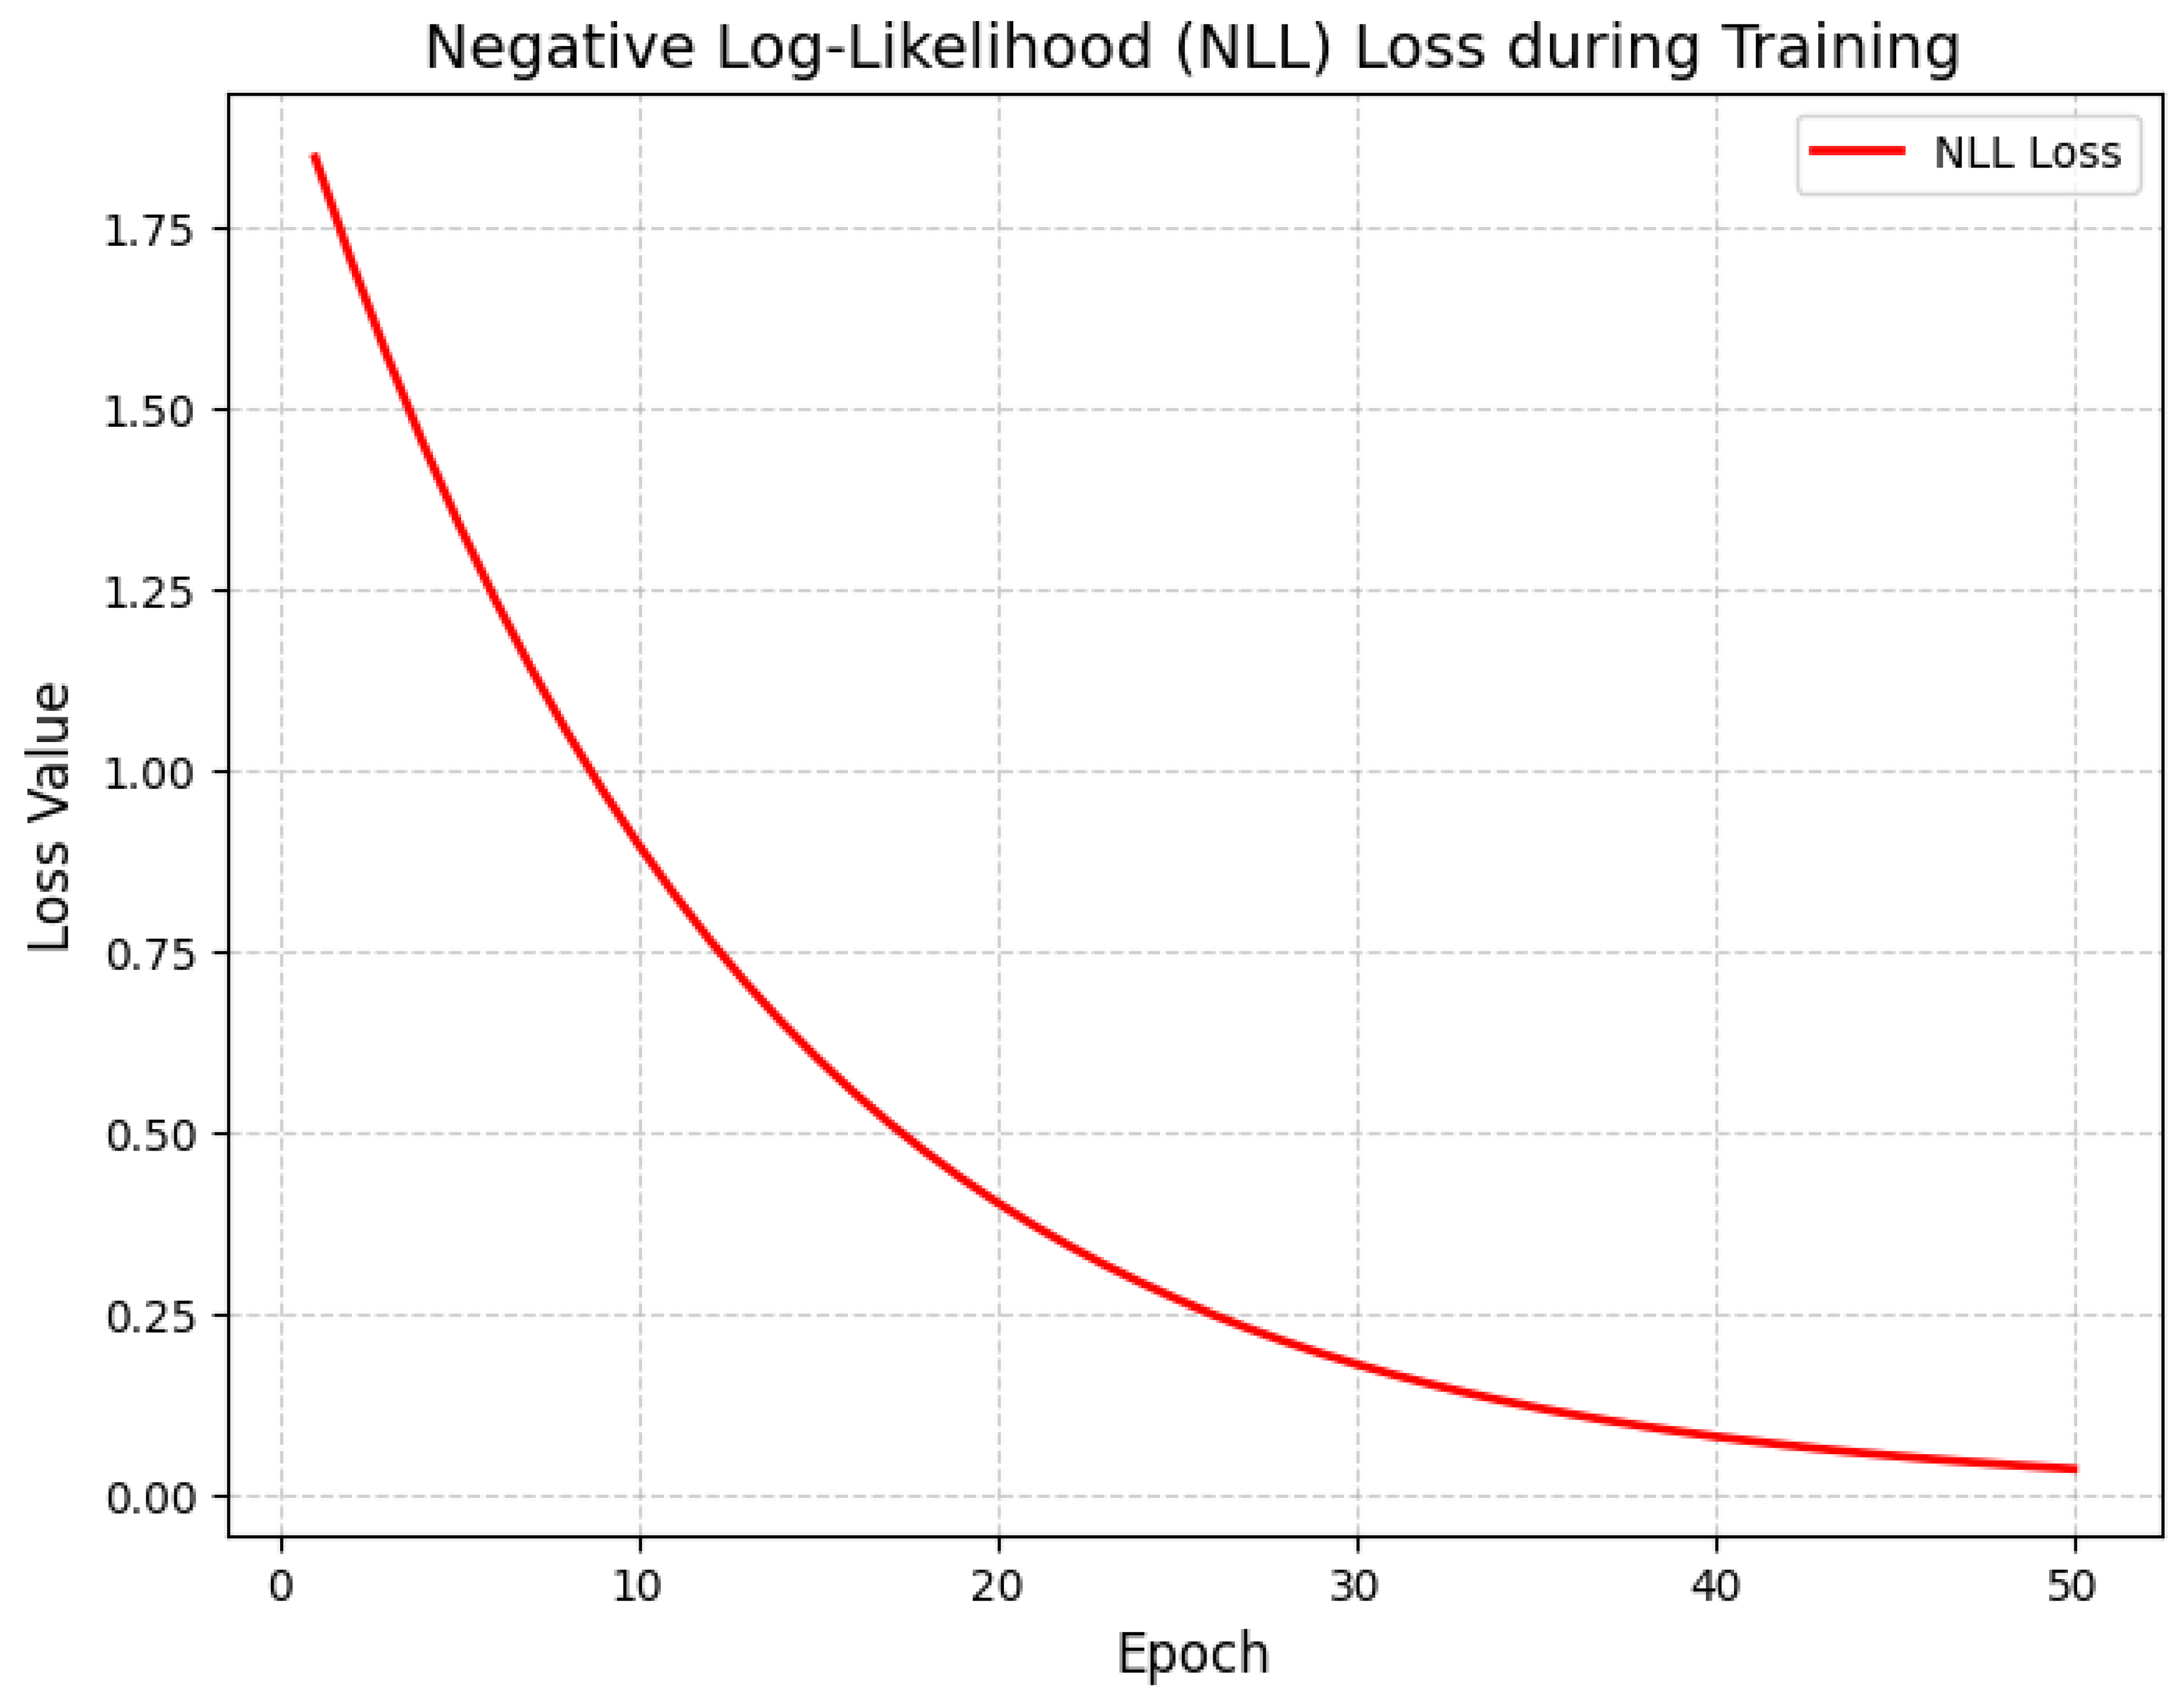
10.5.3.32 Python Code to Generate Figure 99 Illustrating Domain Adversarial Loss During Training
The Python code below produces the Figure 99 illustrating Domain Adversarial Loss during Training.

Figure 99.
Domain Adversarial Loss during Training
10.5.3.33 Python Code to Generate Figure 100 Illustrating Maximum Mean Discrepancy (MMD) Loss During Training
The Python code below produces the Figure 100 illustrating Maximum Mean Discrepancy (MMD) Loss during Training.
Figure 100.
Maximum Mean Discrepancy (MMD) Loss during Training
10.5.3.34 Python Code to Generate Figure 101 Illustrating IoU Loss and Variants (GIoU Loss, DIoU Loss, CIoU Loss)
The Python code below produces the Figure 101 illustrating IoU Loss and Variants (GIoU Loss, DIoU Loss, CIoU Loss).
Figure 101.
IoU Loss and Variants (GIoU Loss, DIoU Loss, CIoU Loss)
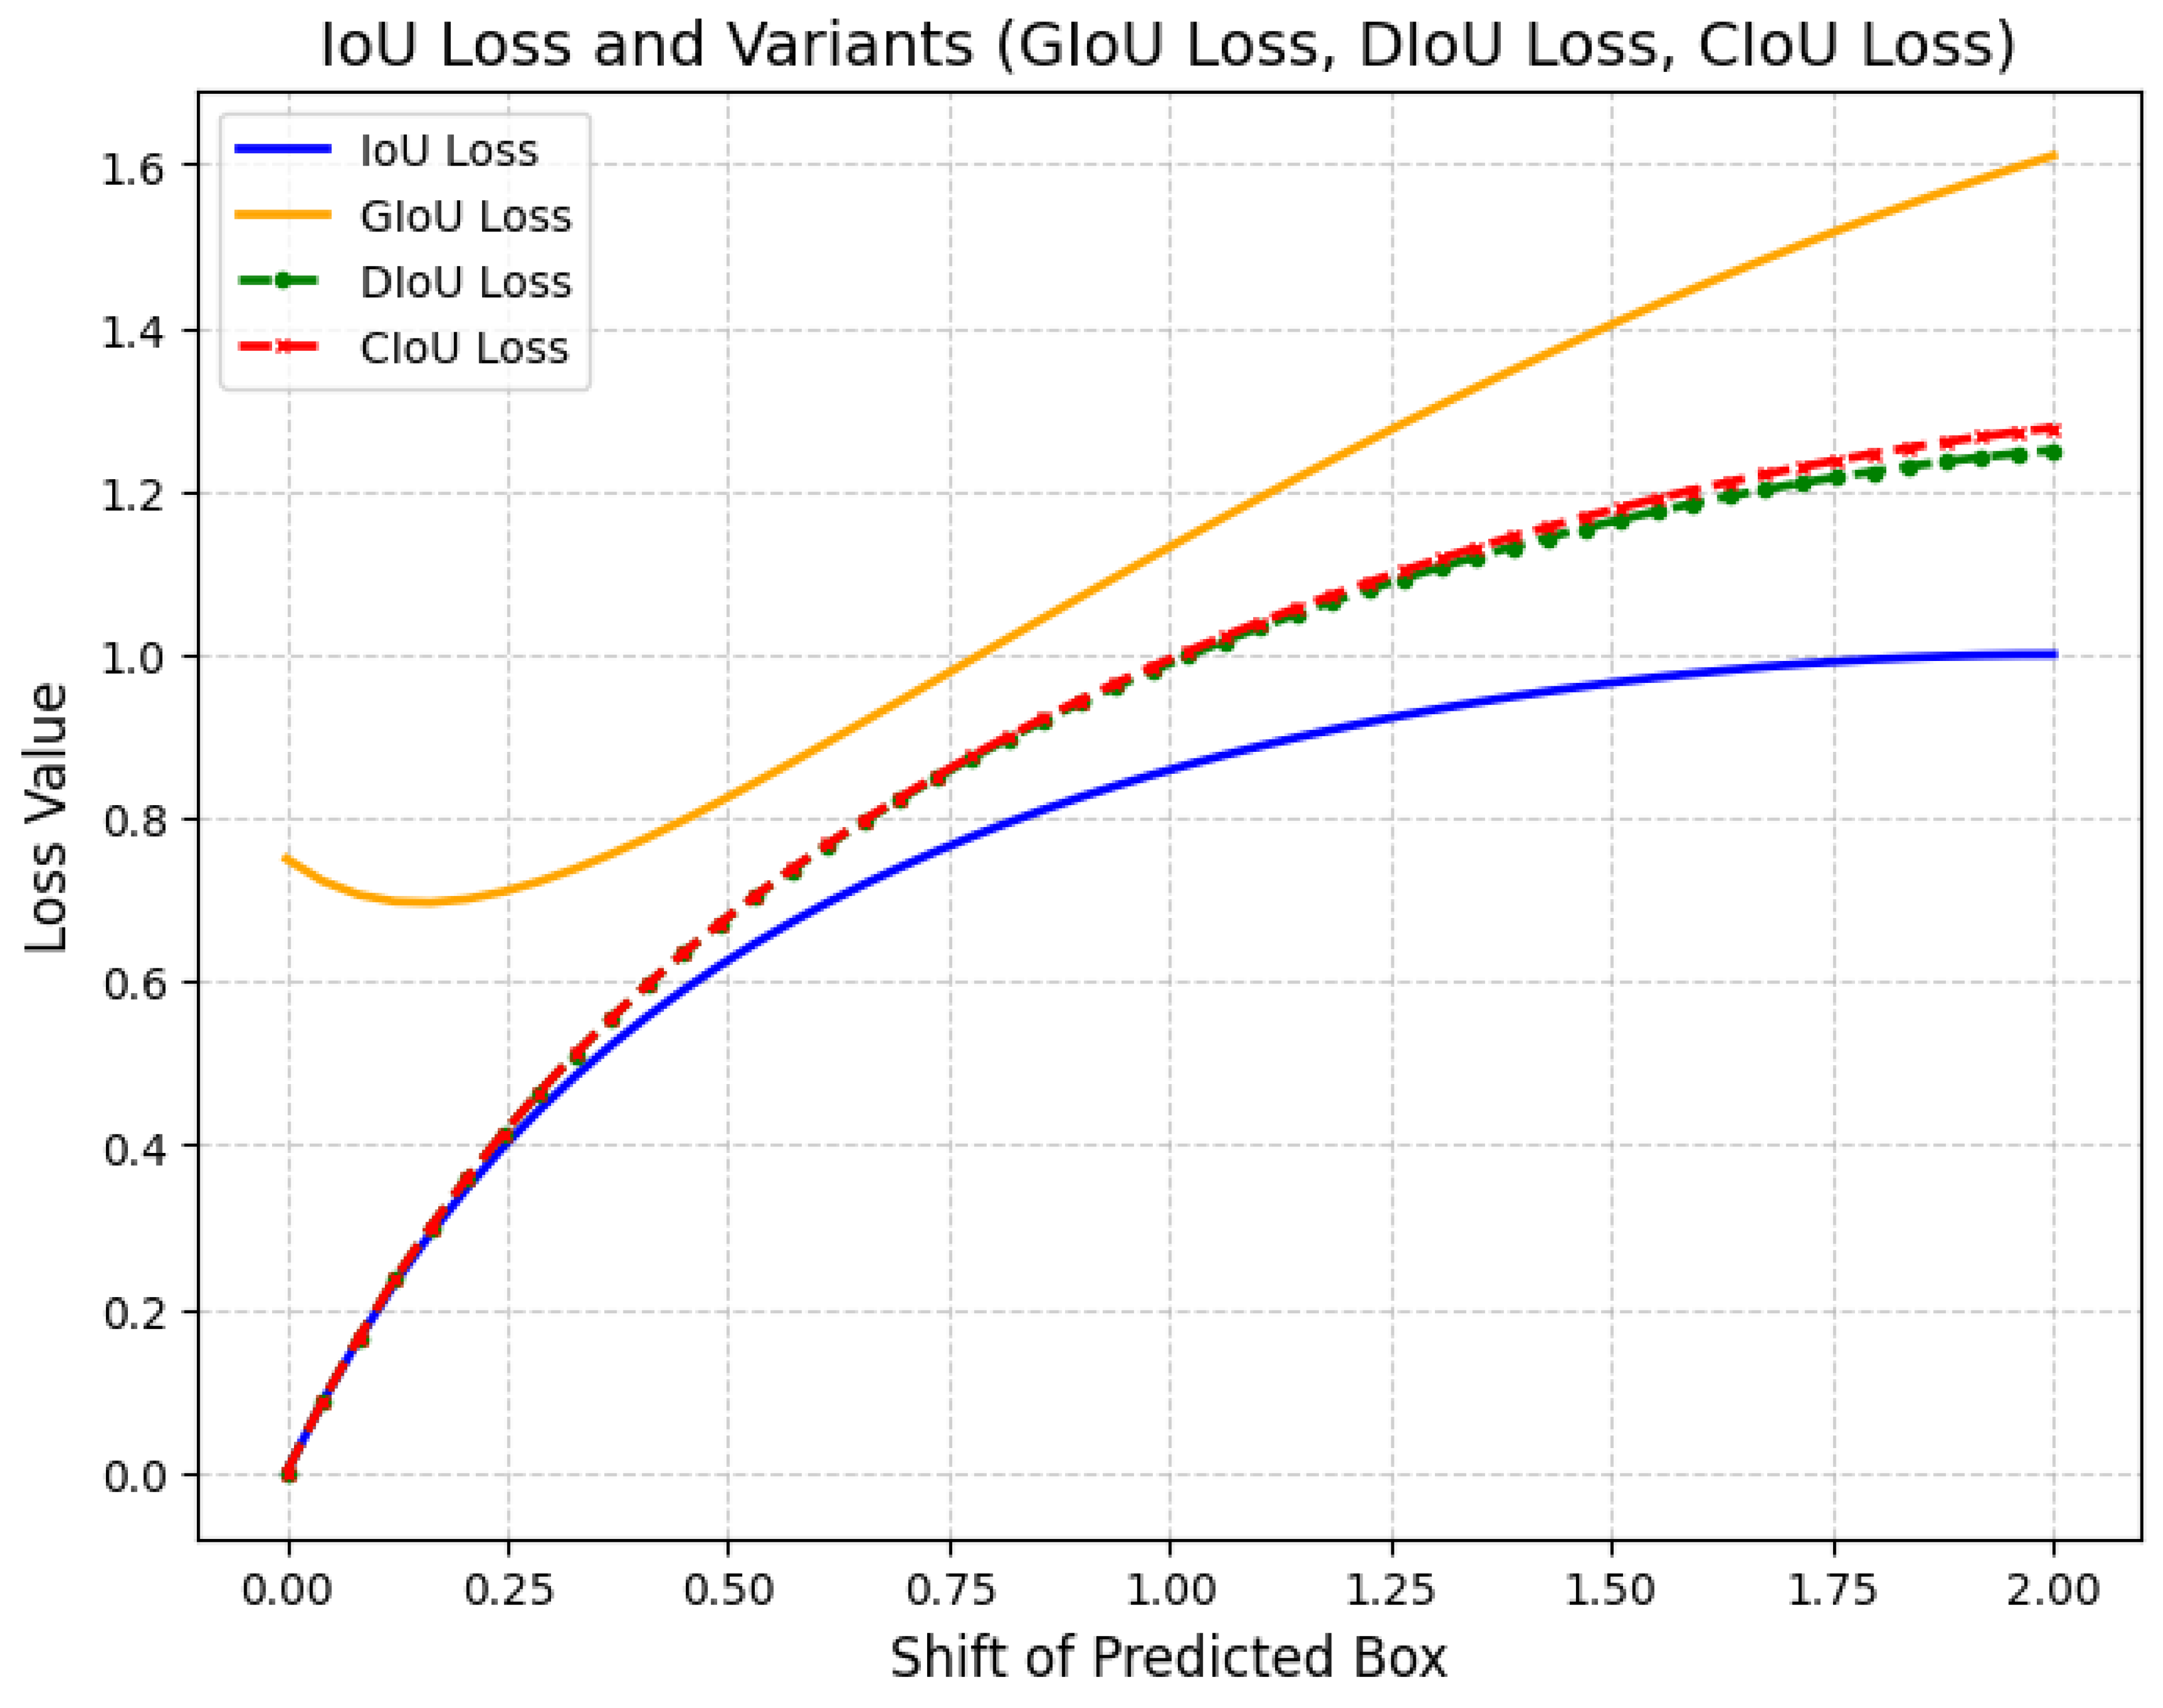
10.5.3.35 Python Code to Generate Figure 102 Illustrating Dice Loss During Training
The Python code below produces the Figure 102 illustrating Dice Loss during Training.
Figure 102.
Dice Loss during Training
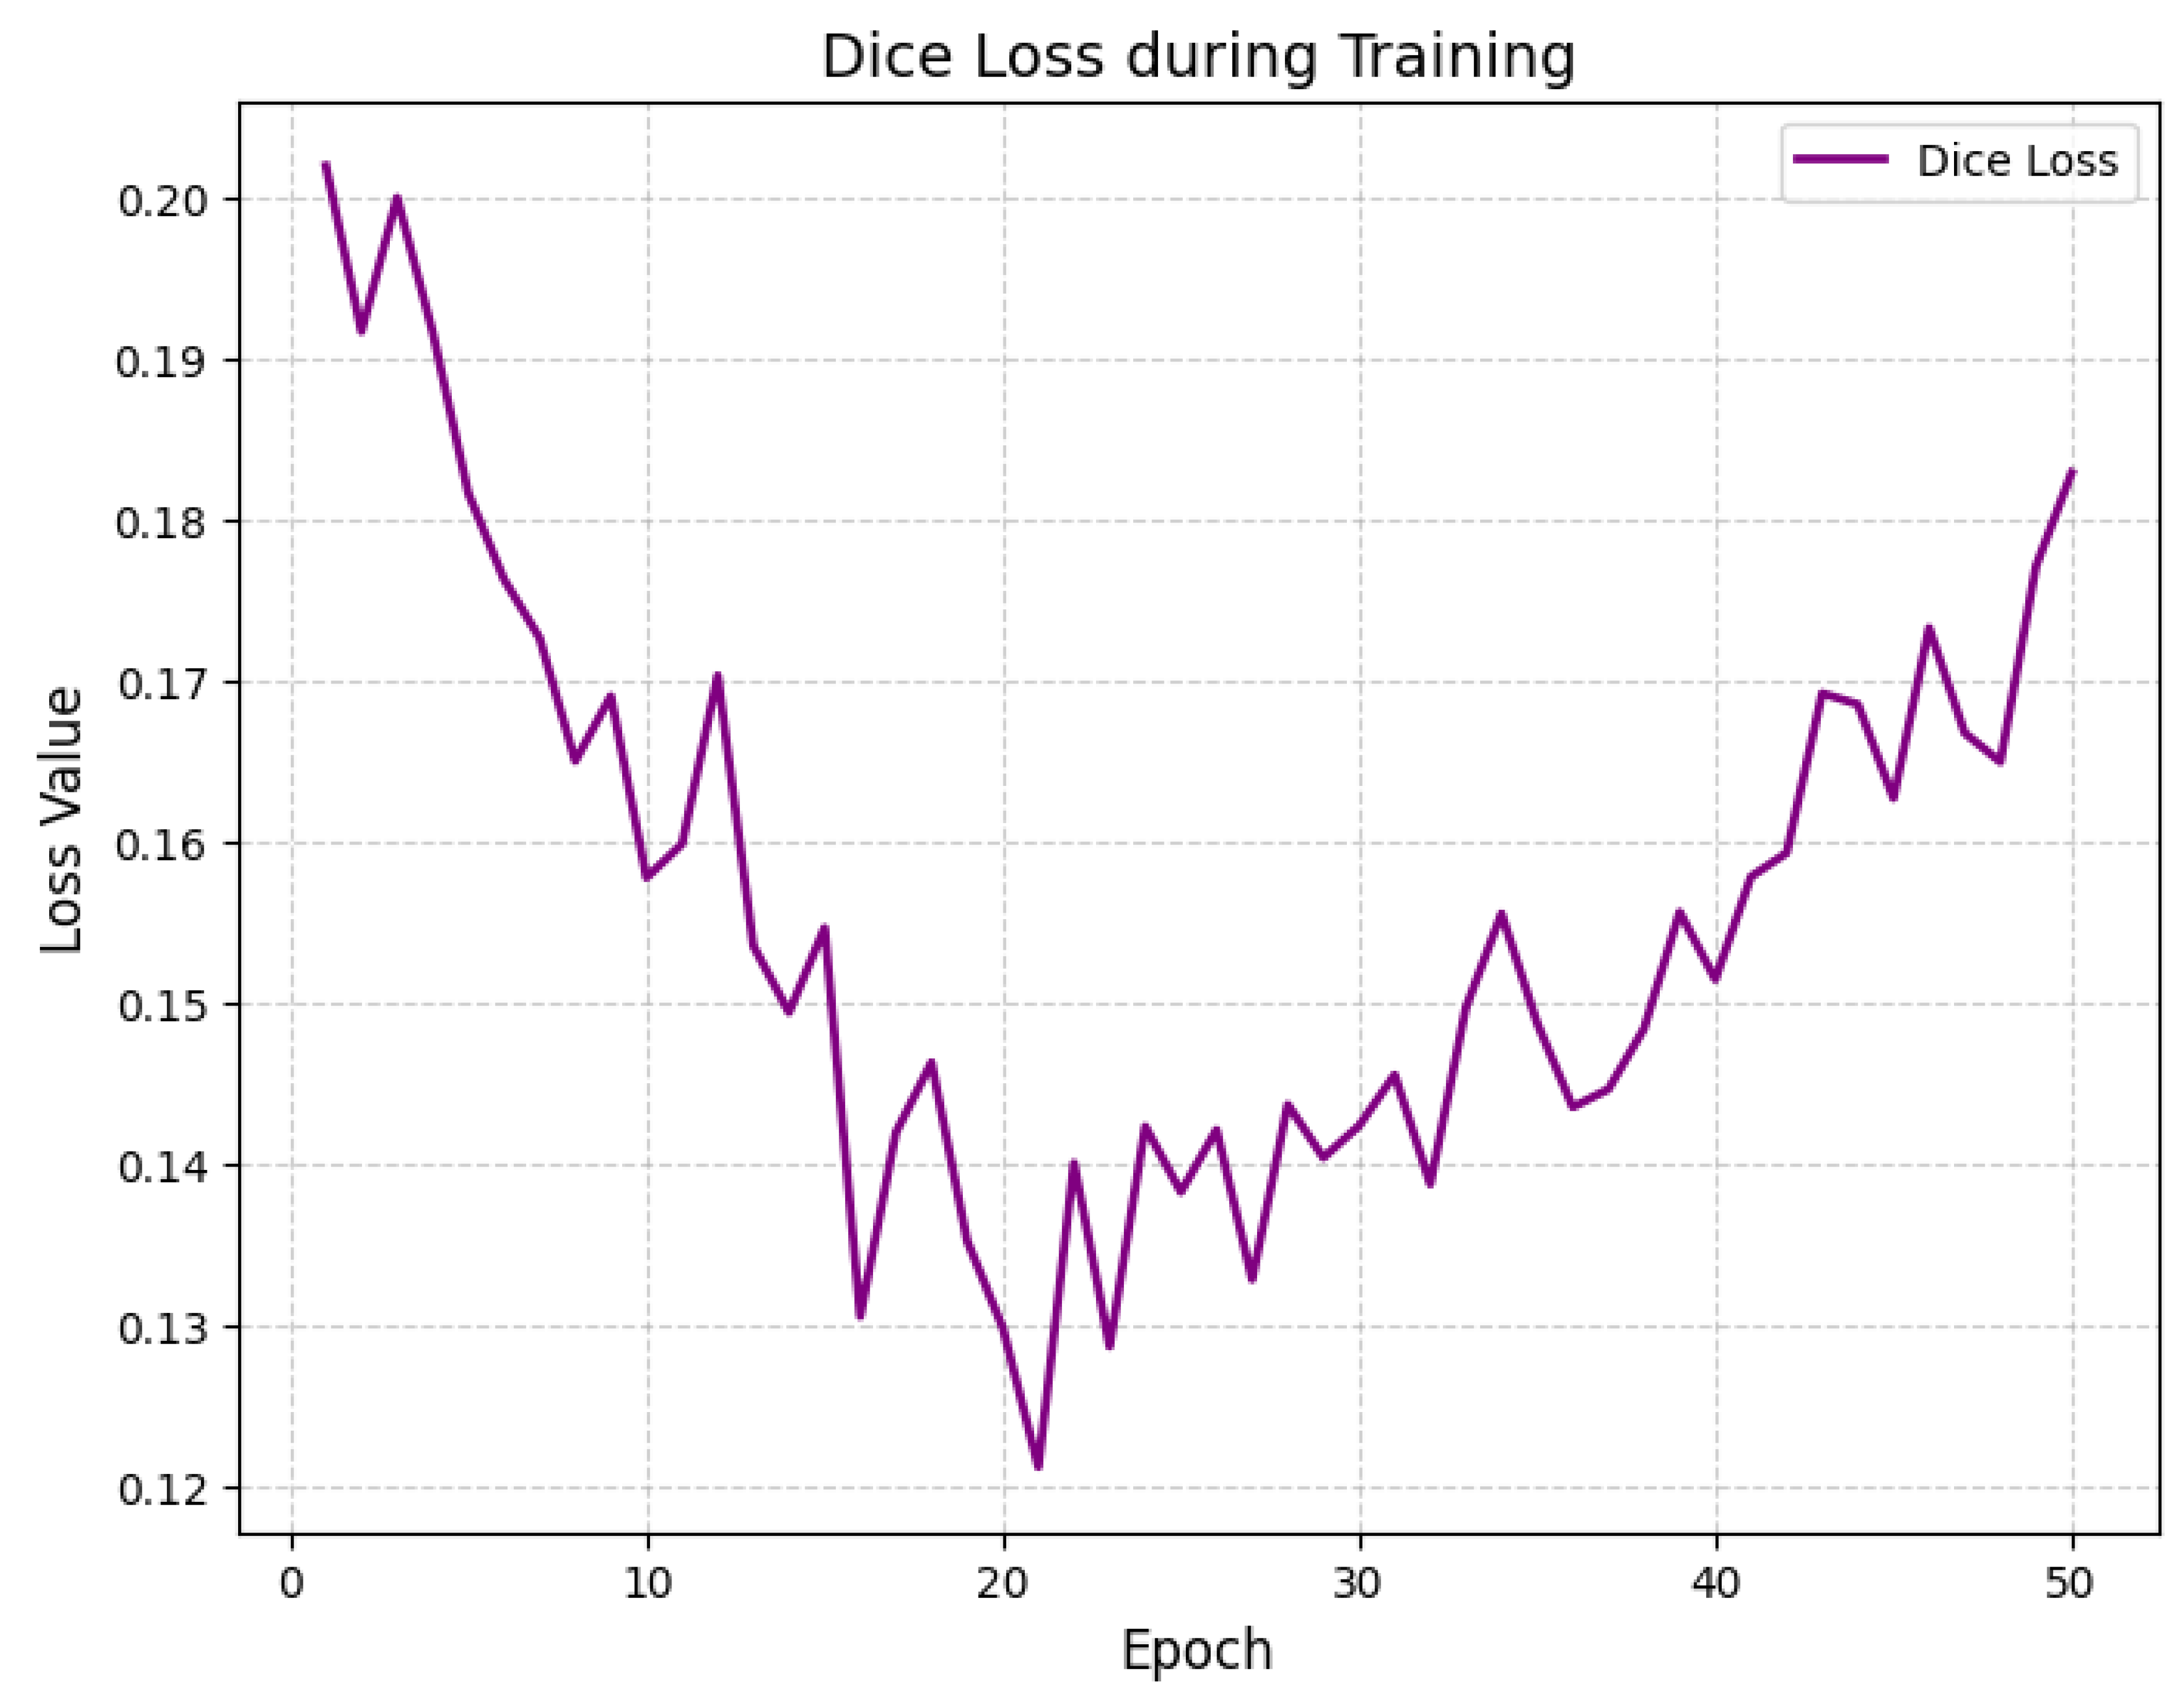
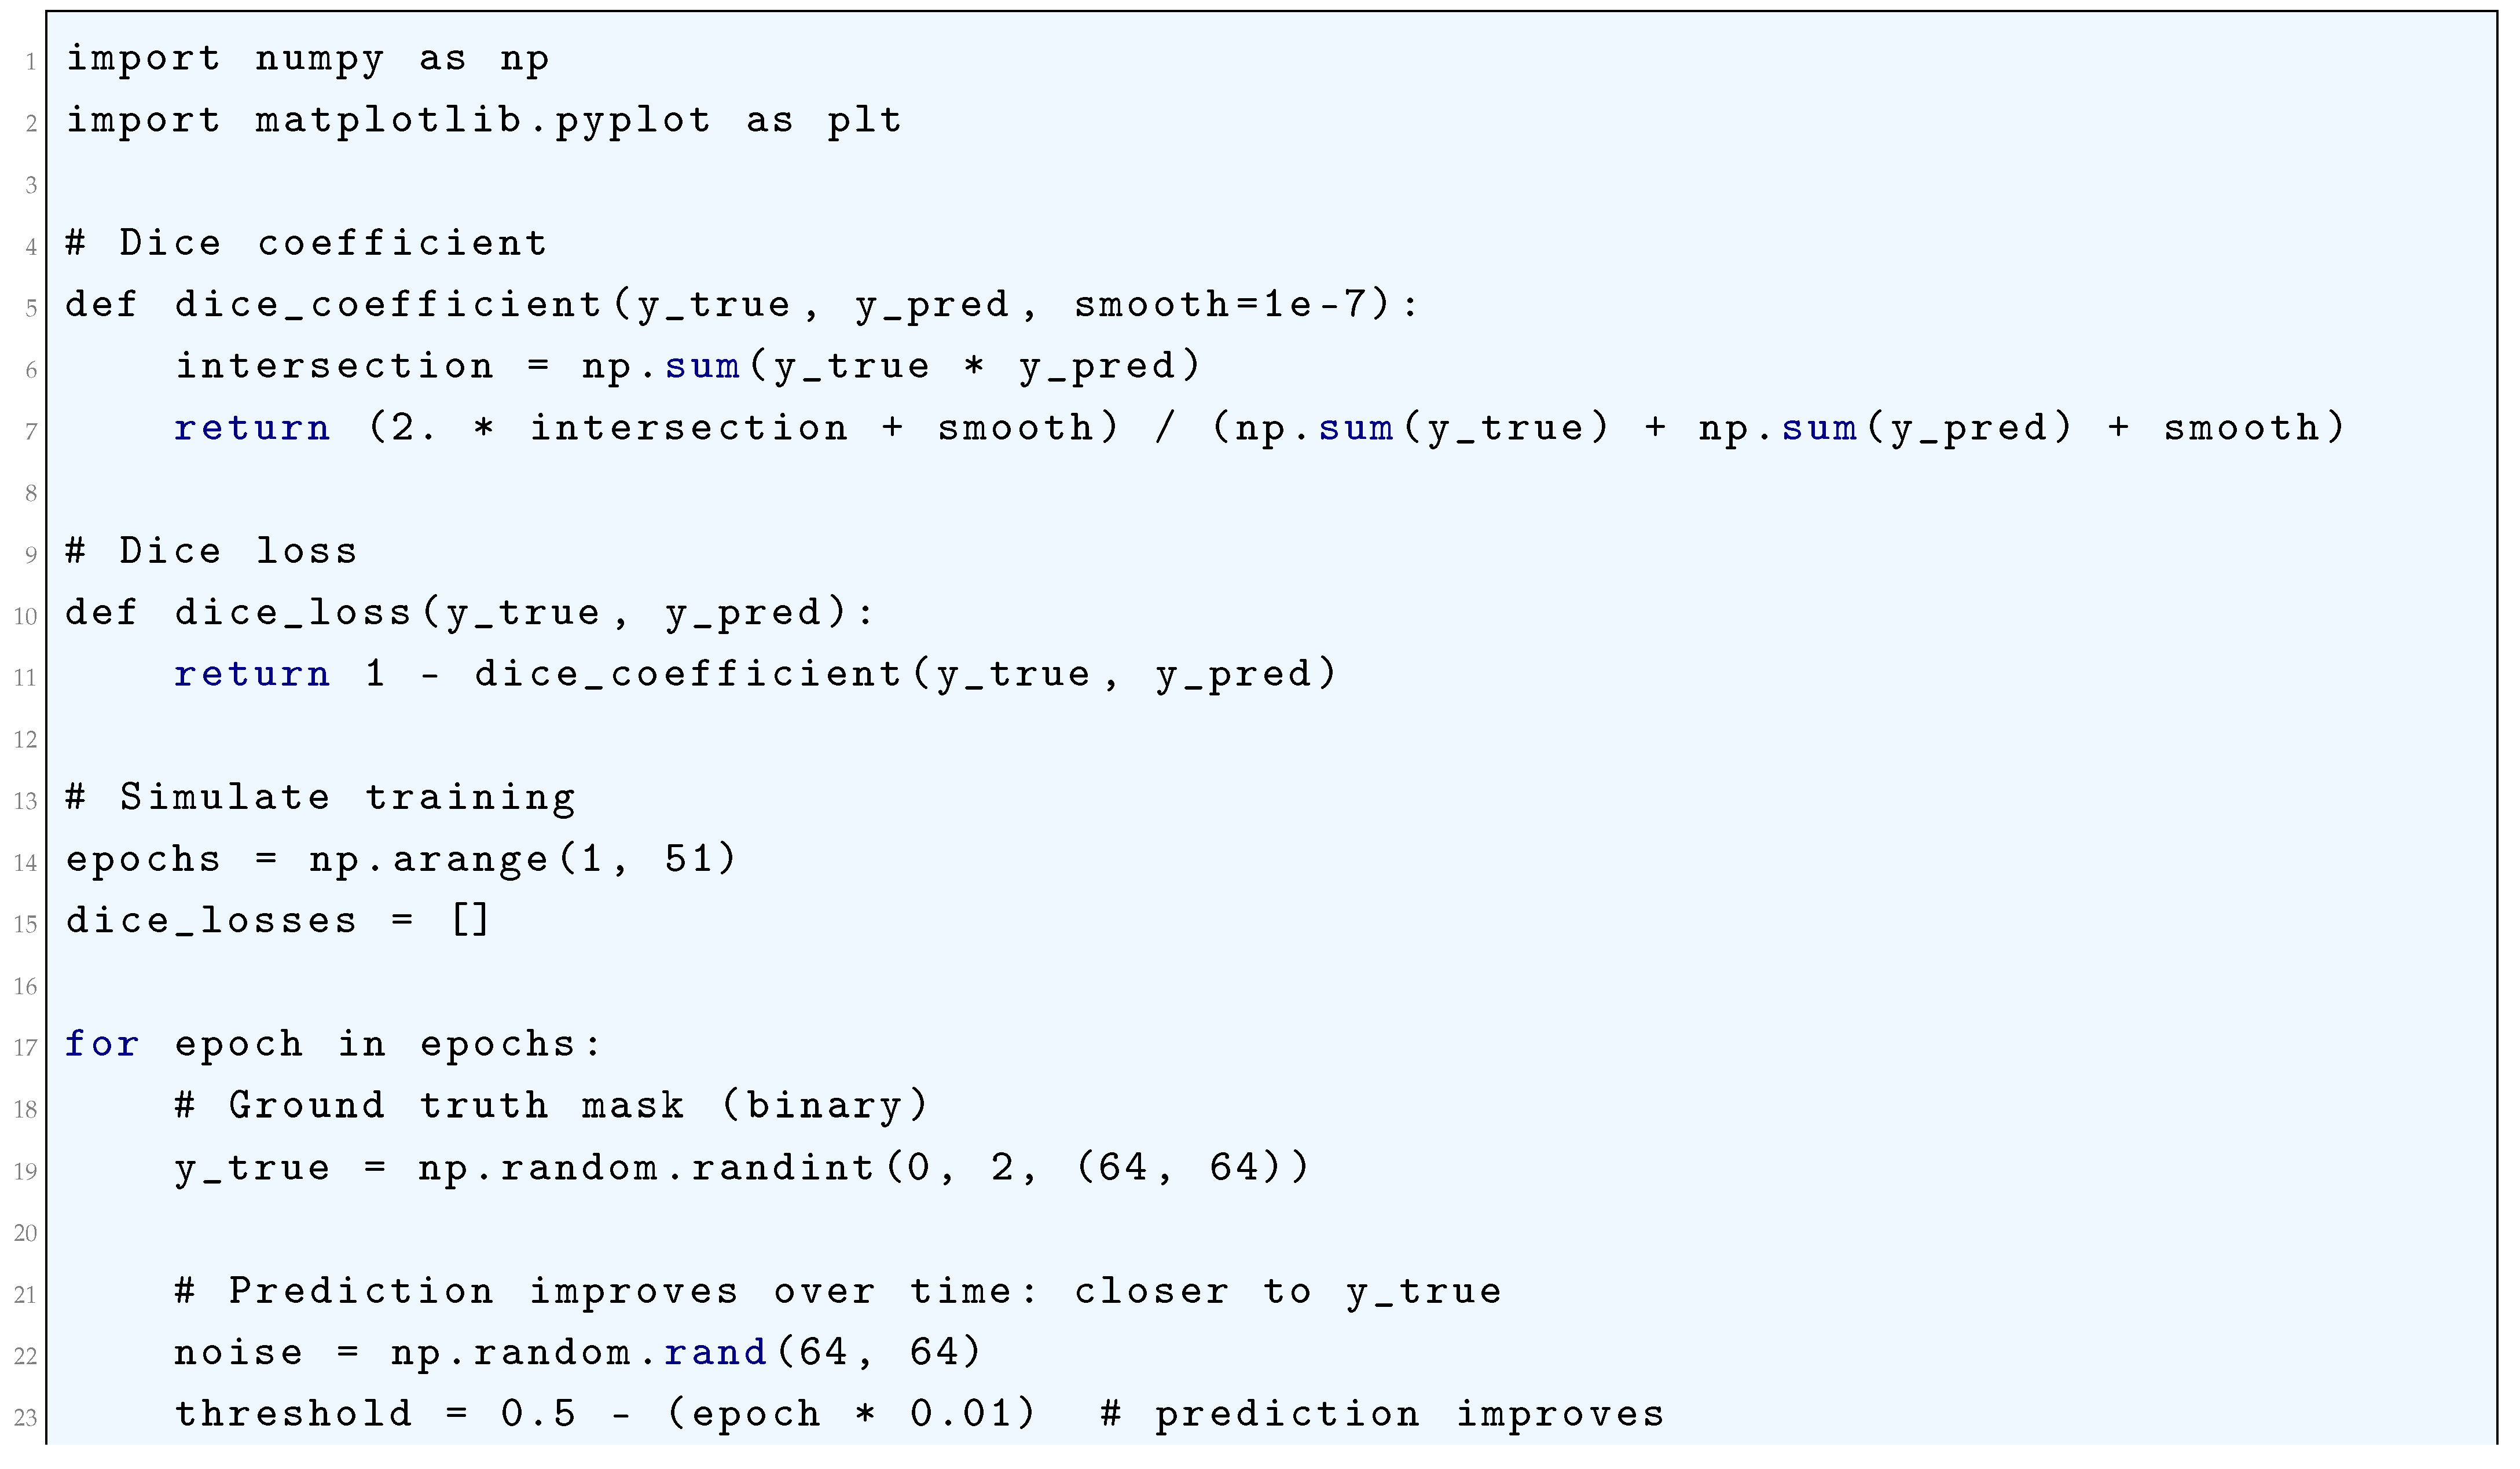
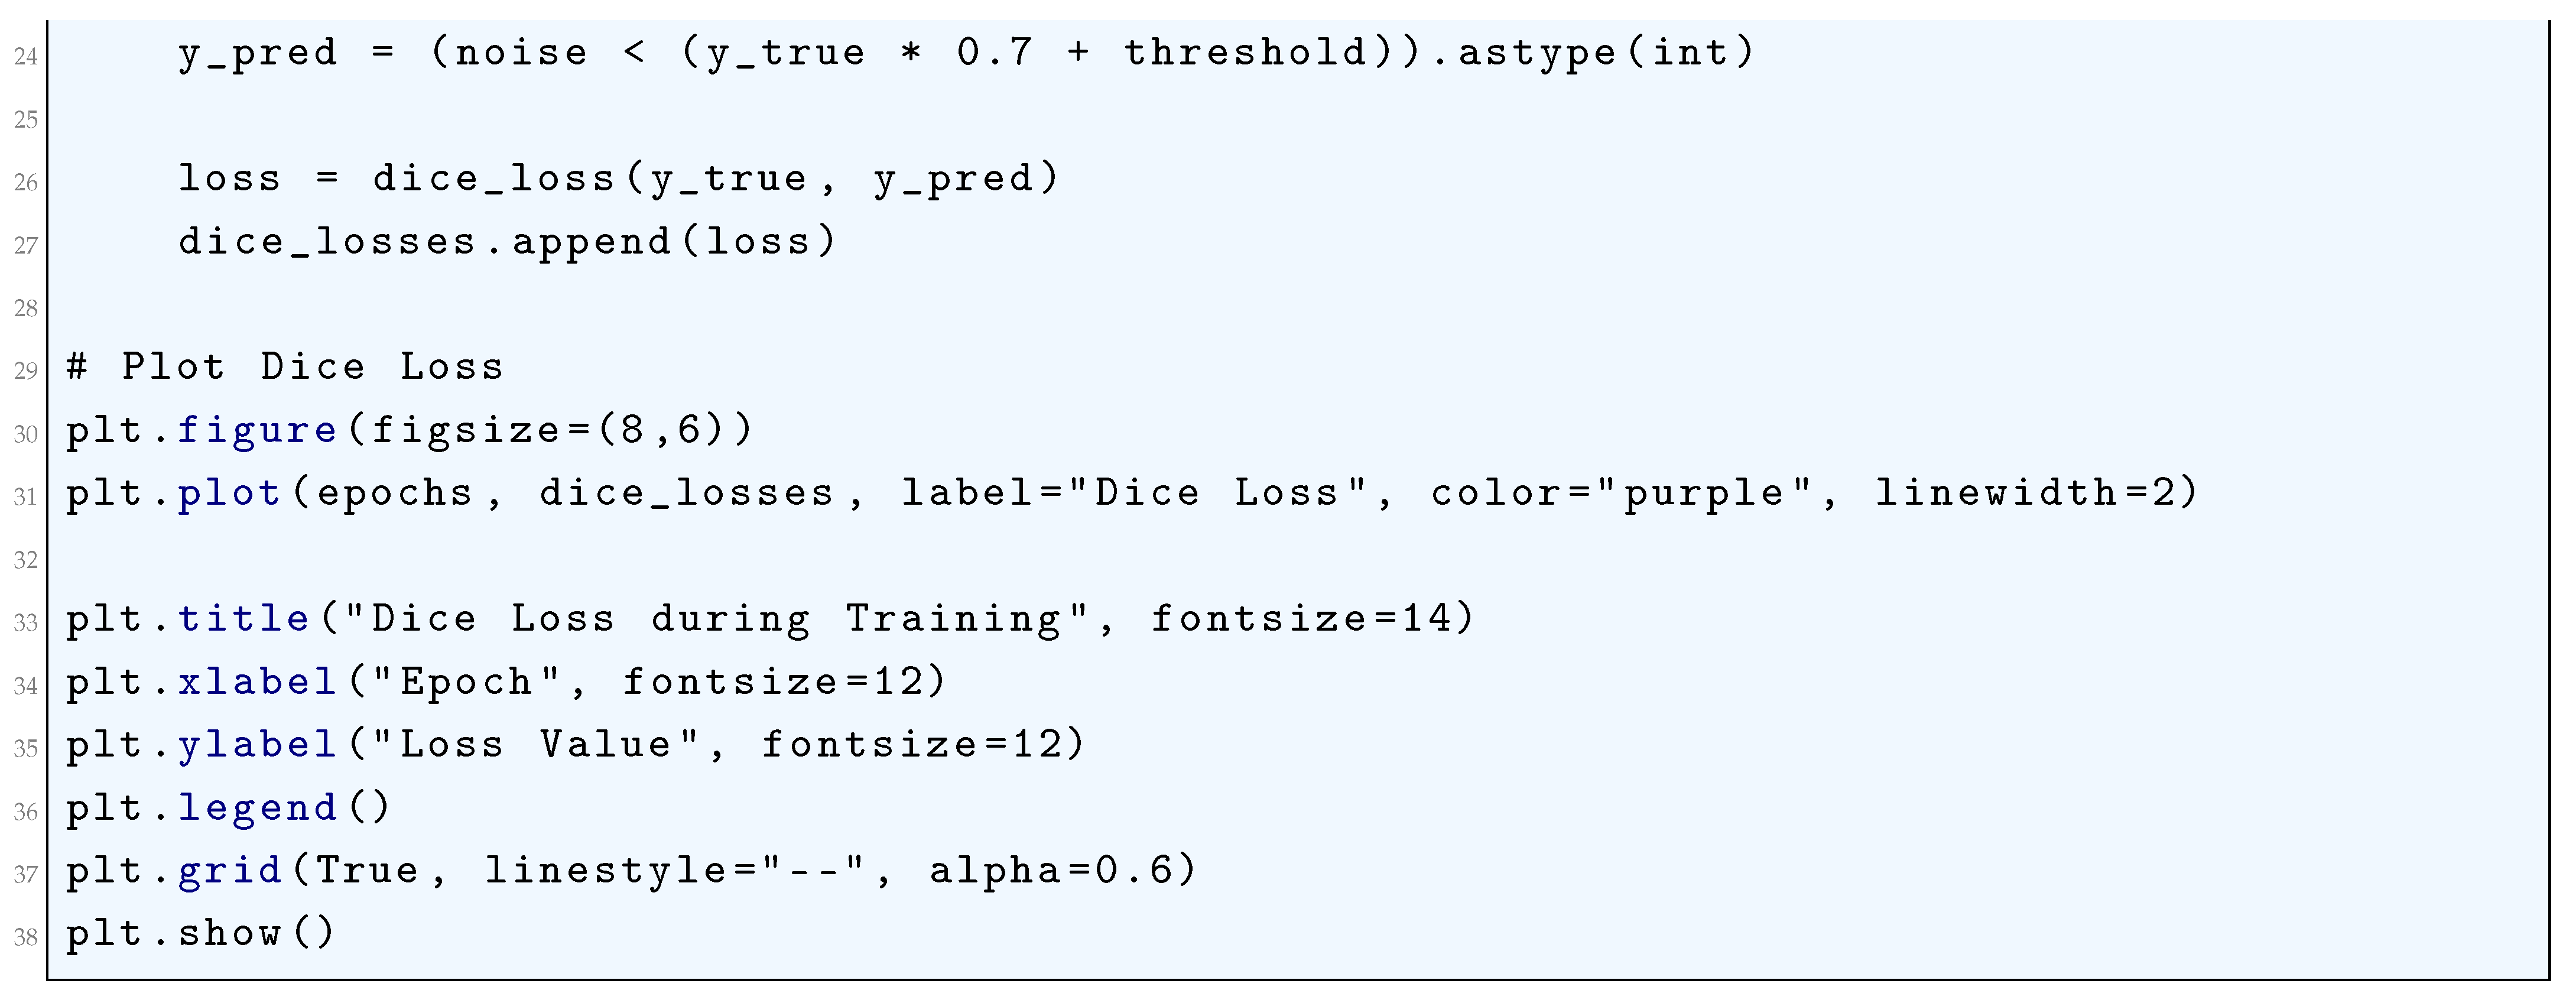
10.5.3.36 Python Code to Generate Figure 103 Illustrating Focal Loss vs Predicted Probability
The Python code below produces the Figure 103 illustrating Focal Loss vs Predicted Probability.
Figure 103.
Focal Loss vs Predicted Probability
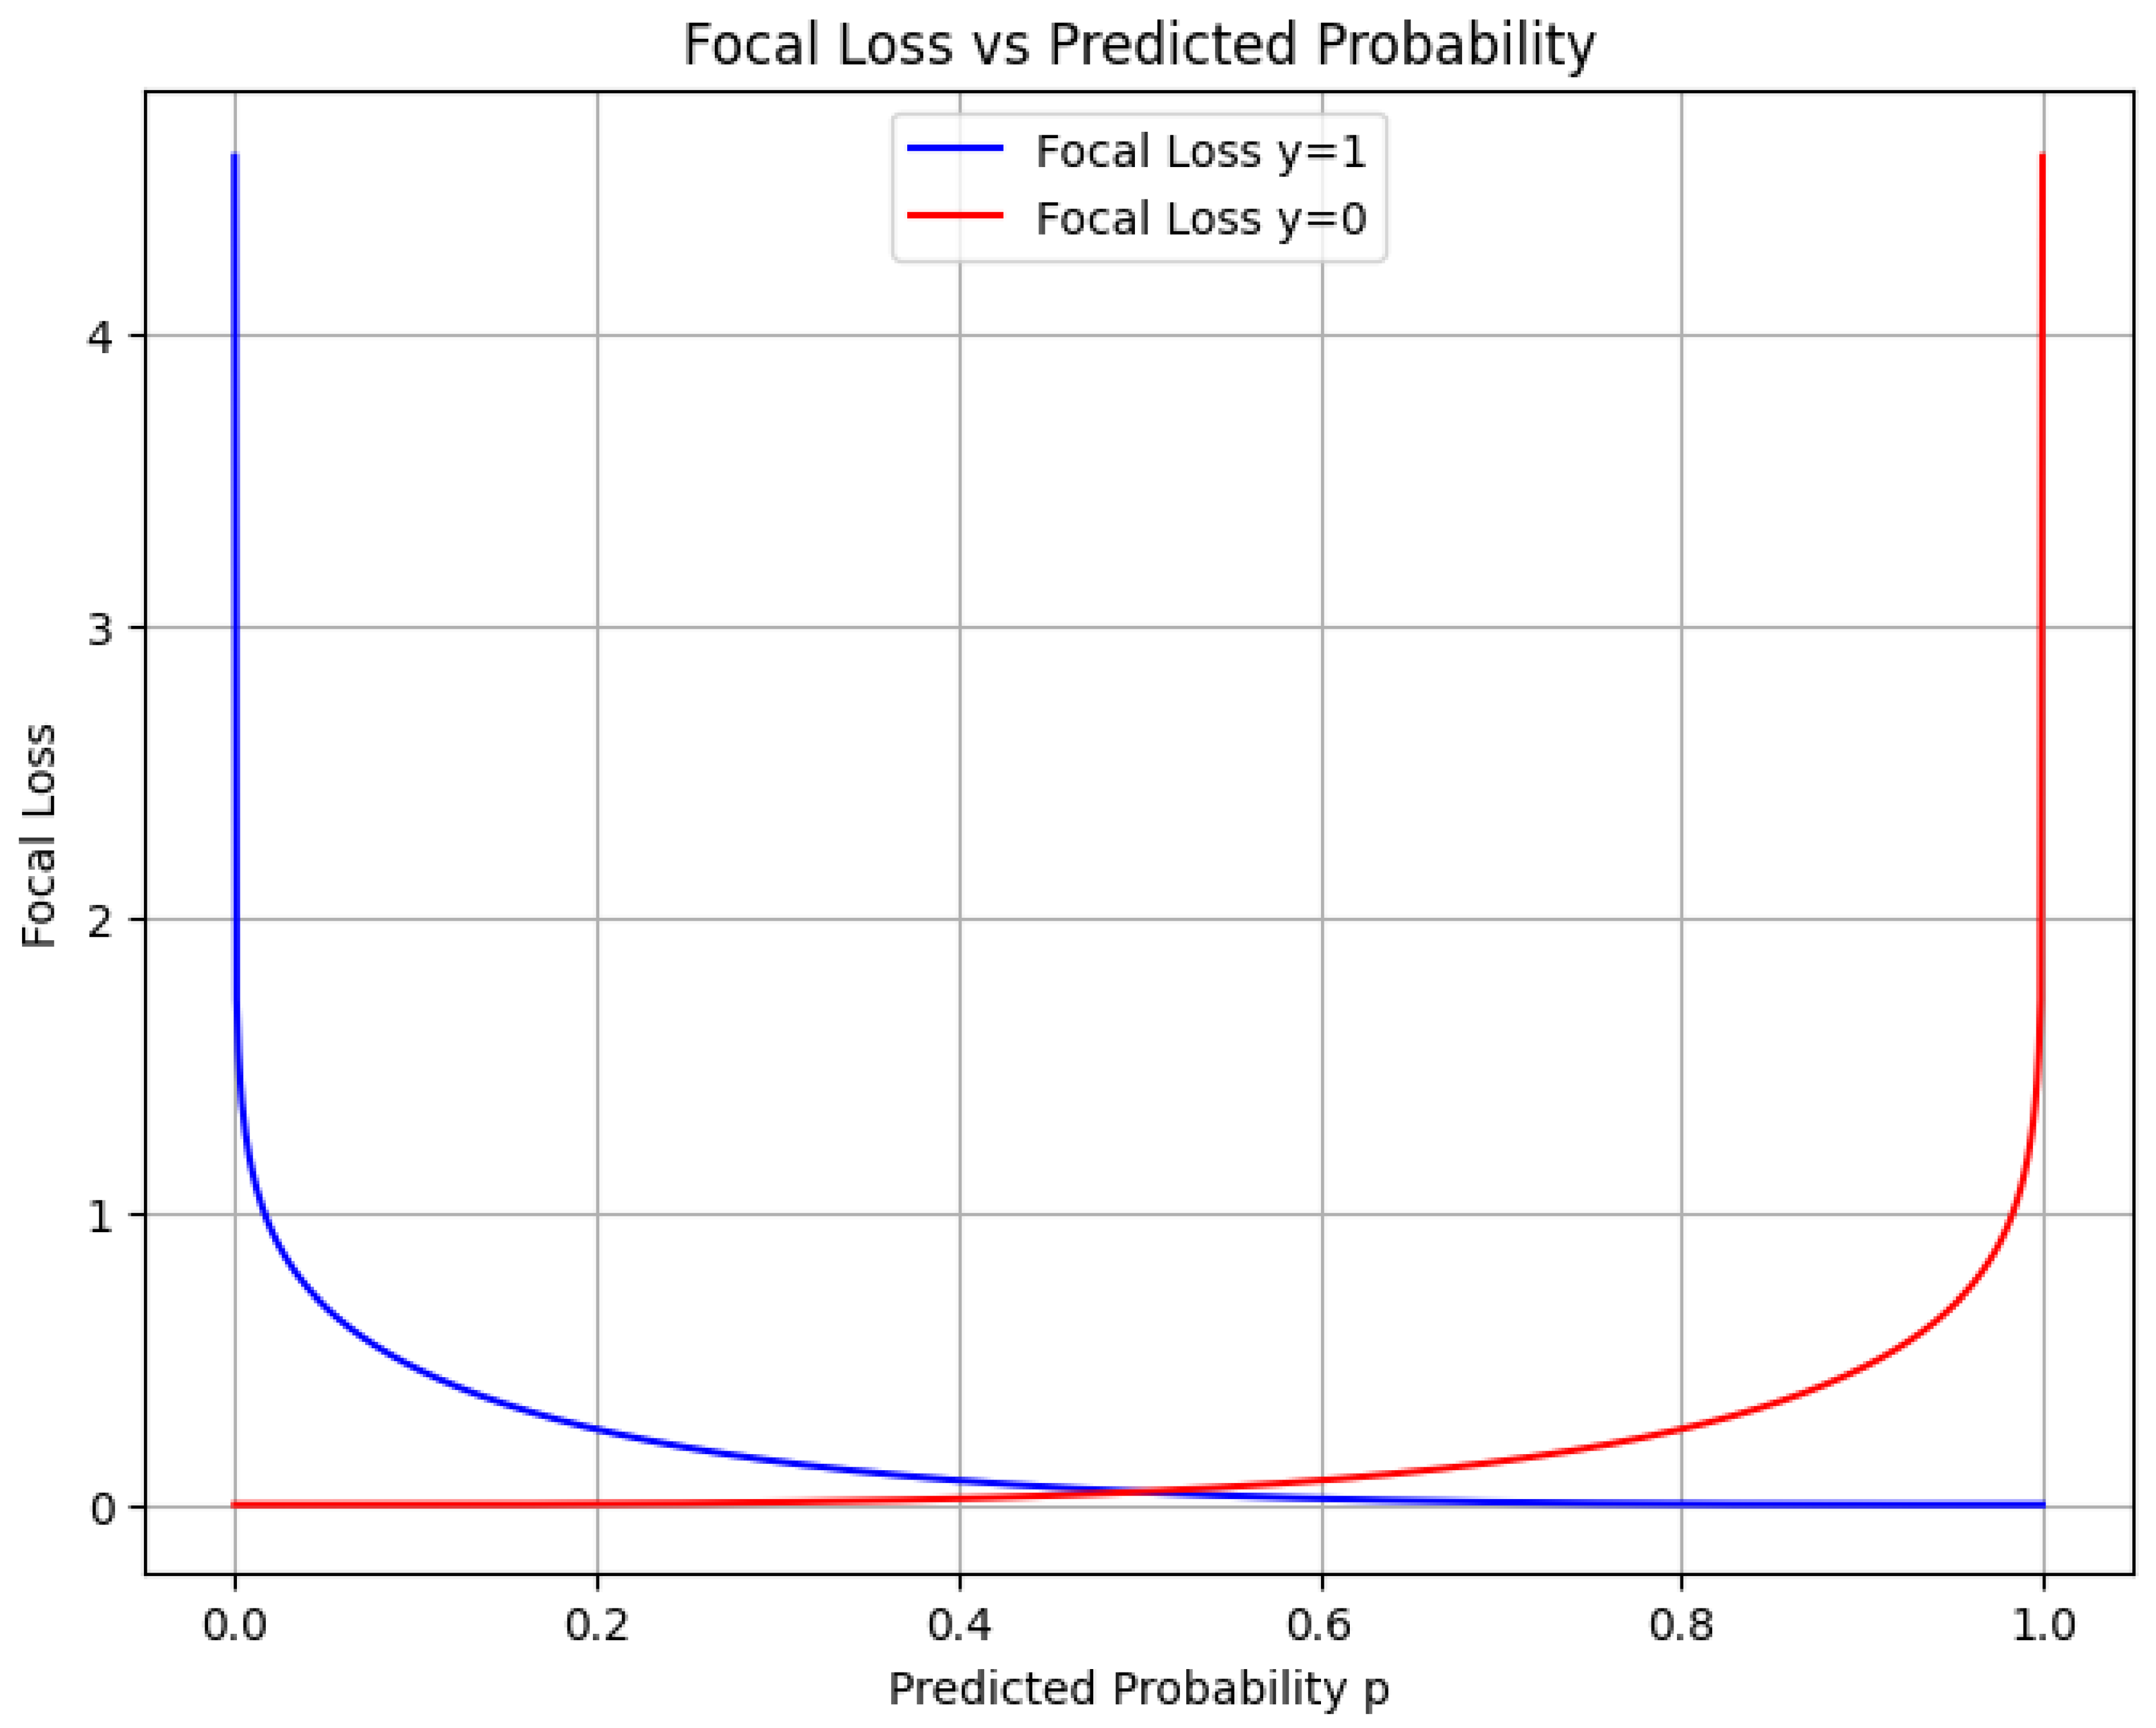
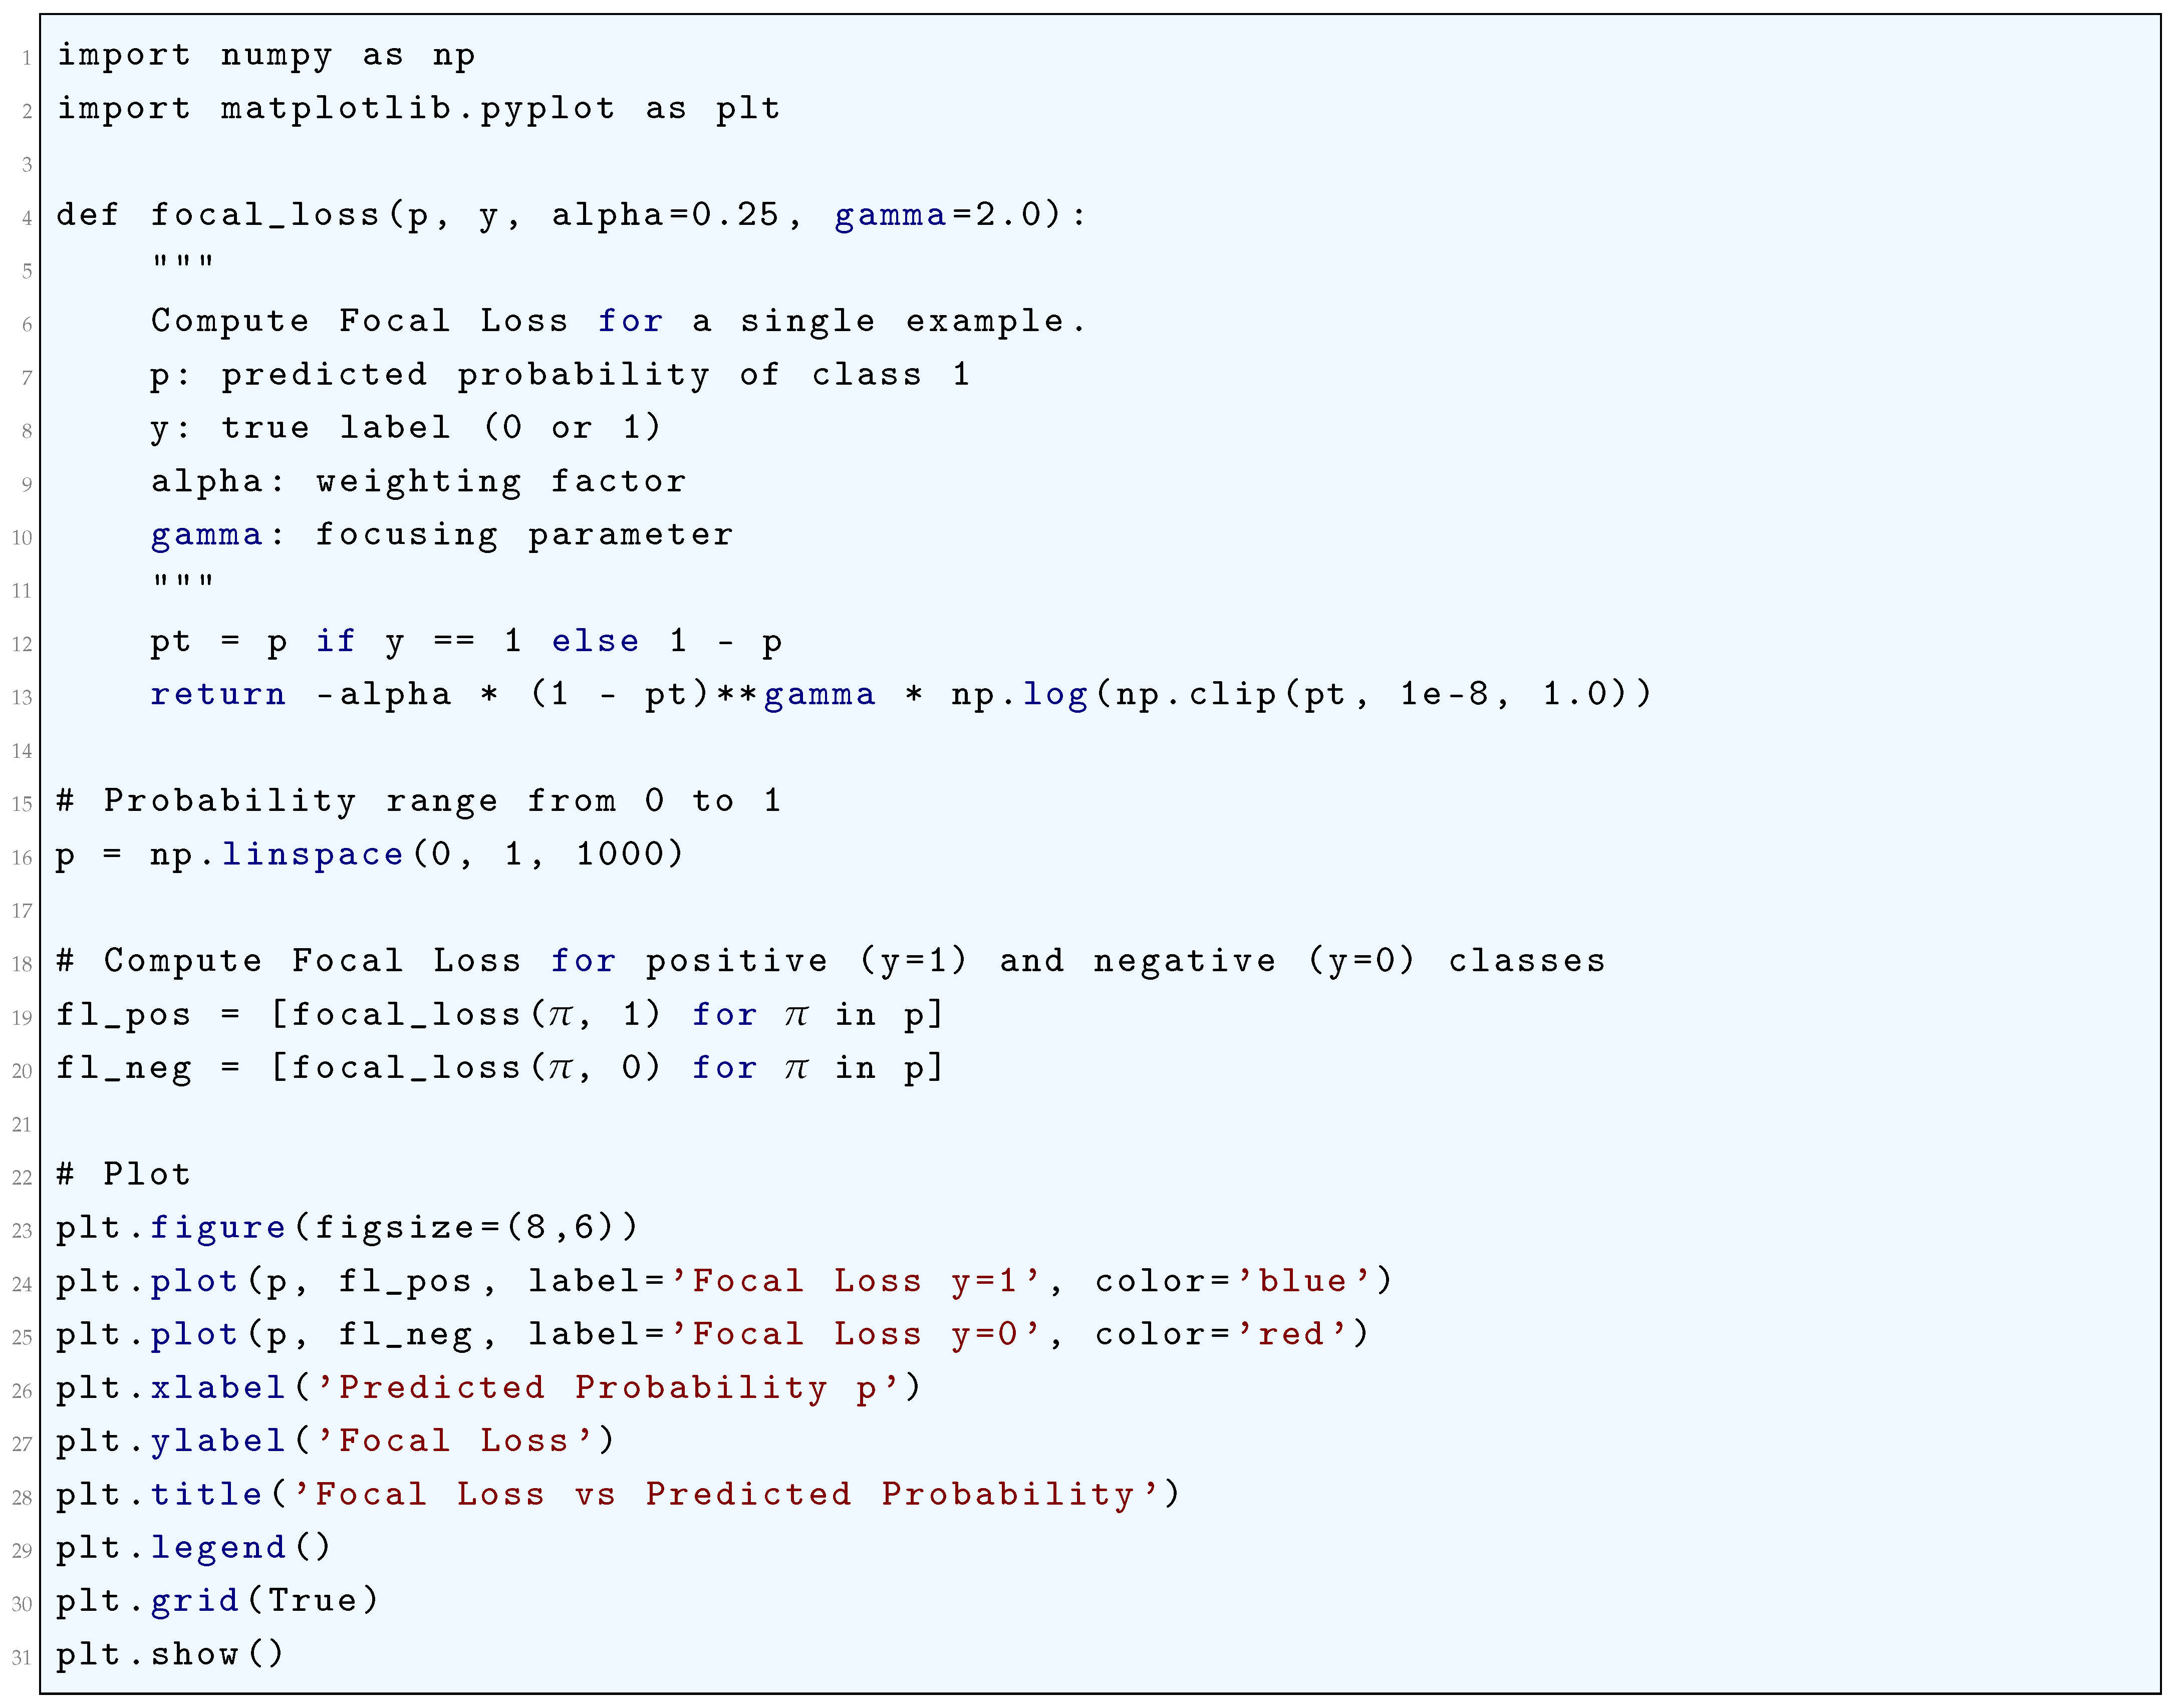
10.5.3.37 Python Code to Generate Figure 104 Illustrating Focal Loss vs Standard Binary Cross-Entropy
The Python code below produces the Figure 104 illustrating Focal Loss vs Standard Binary Cross-Entropy.
Figure 104.
Focal Loss vs Standard Binary Cross-Entropy
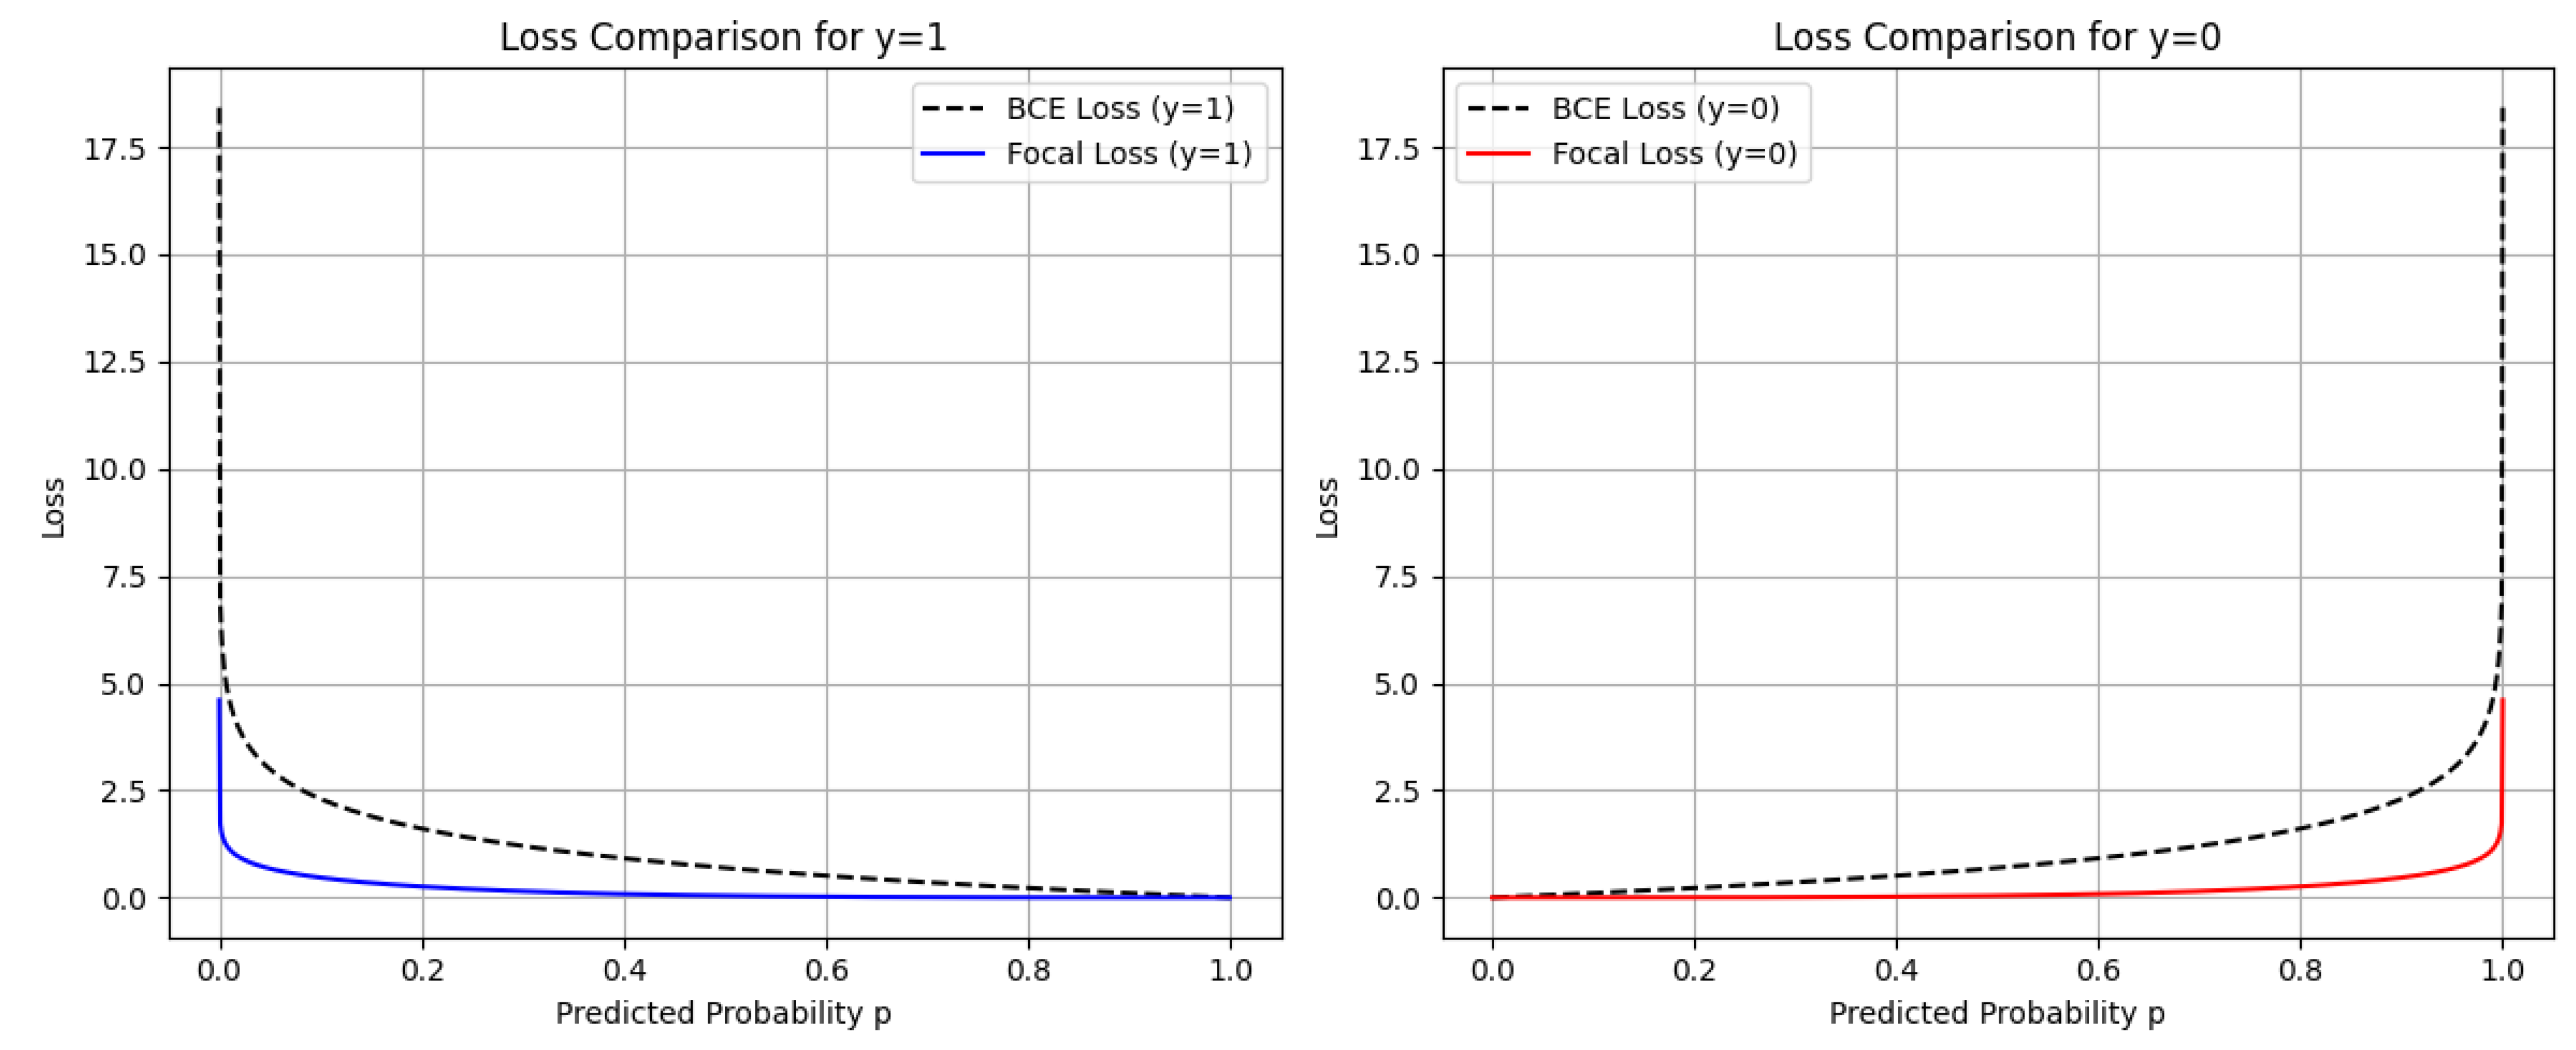
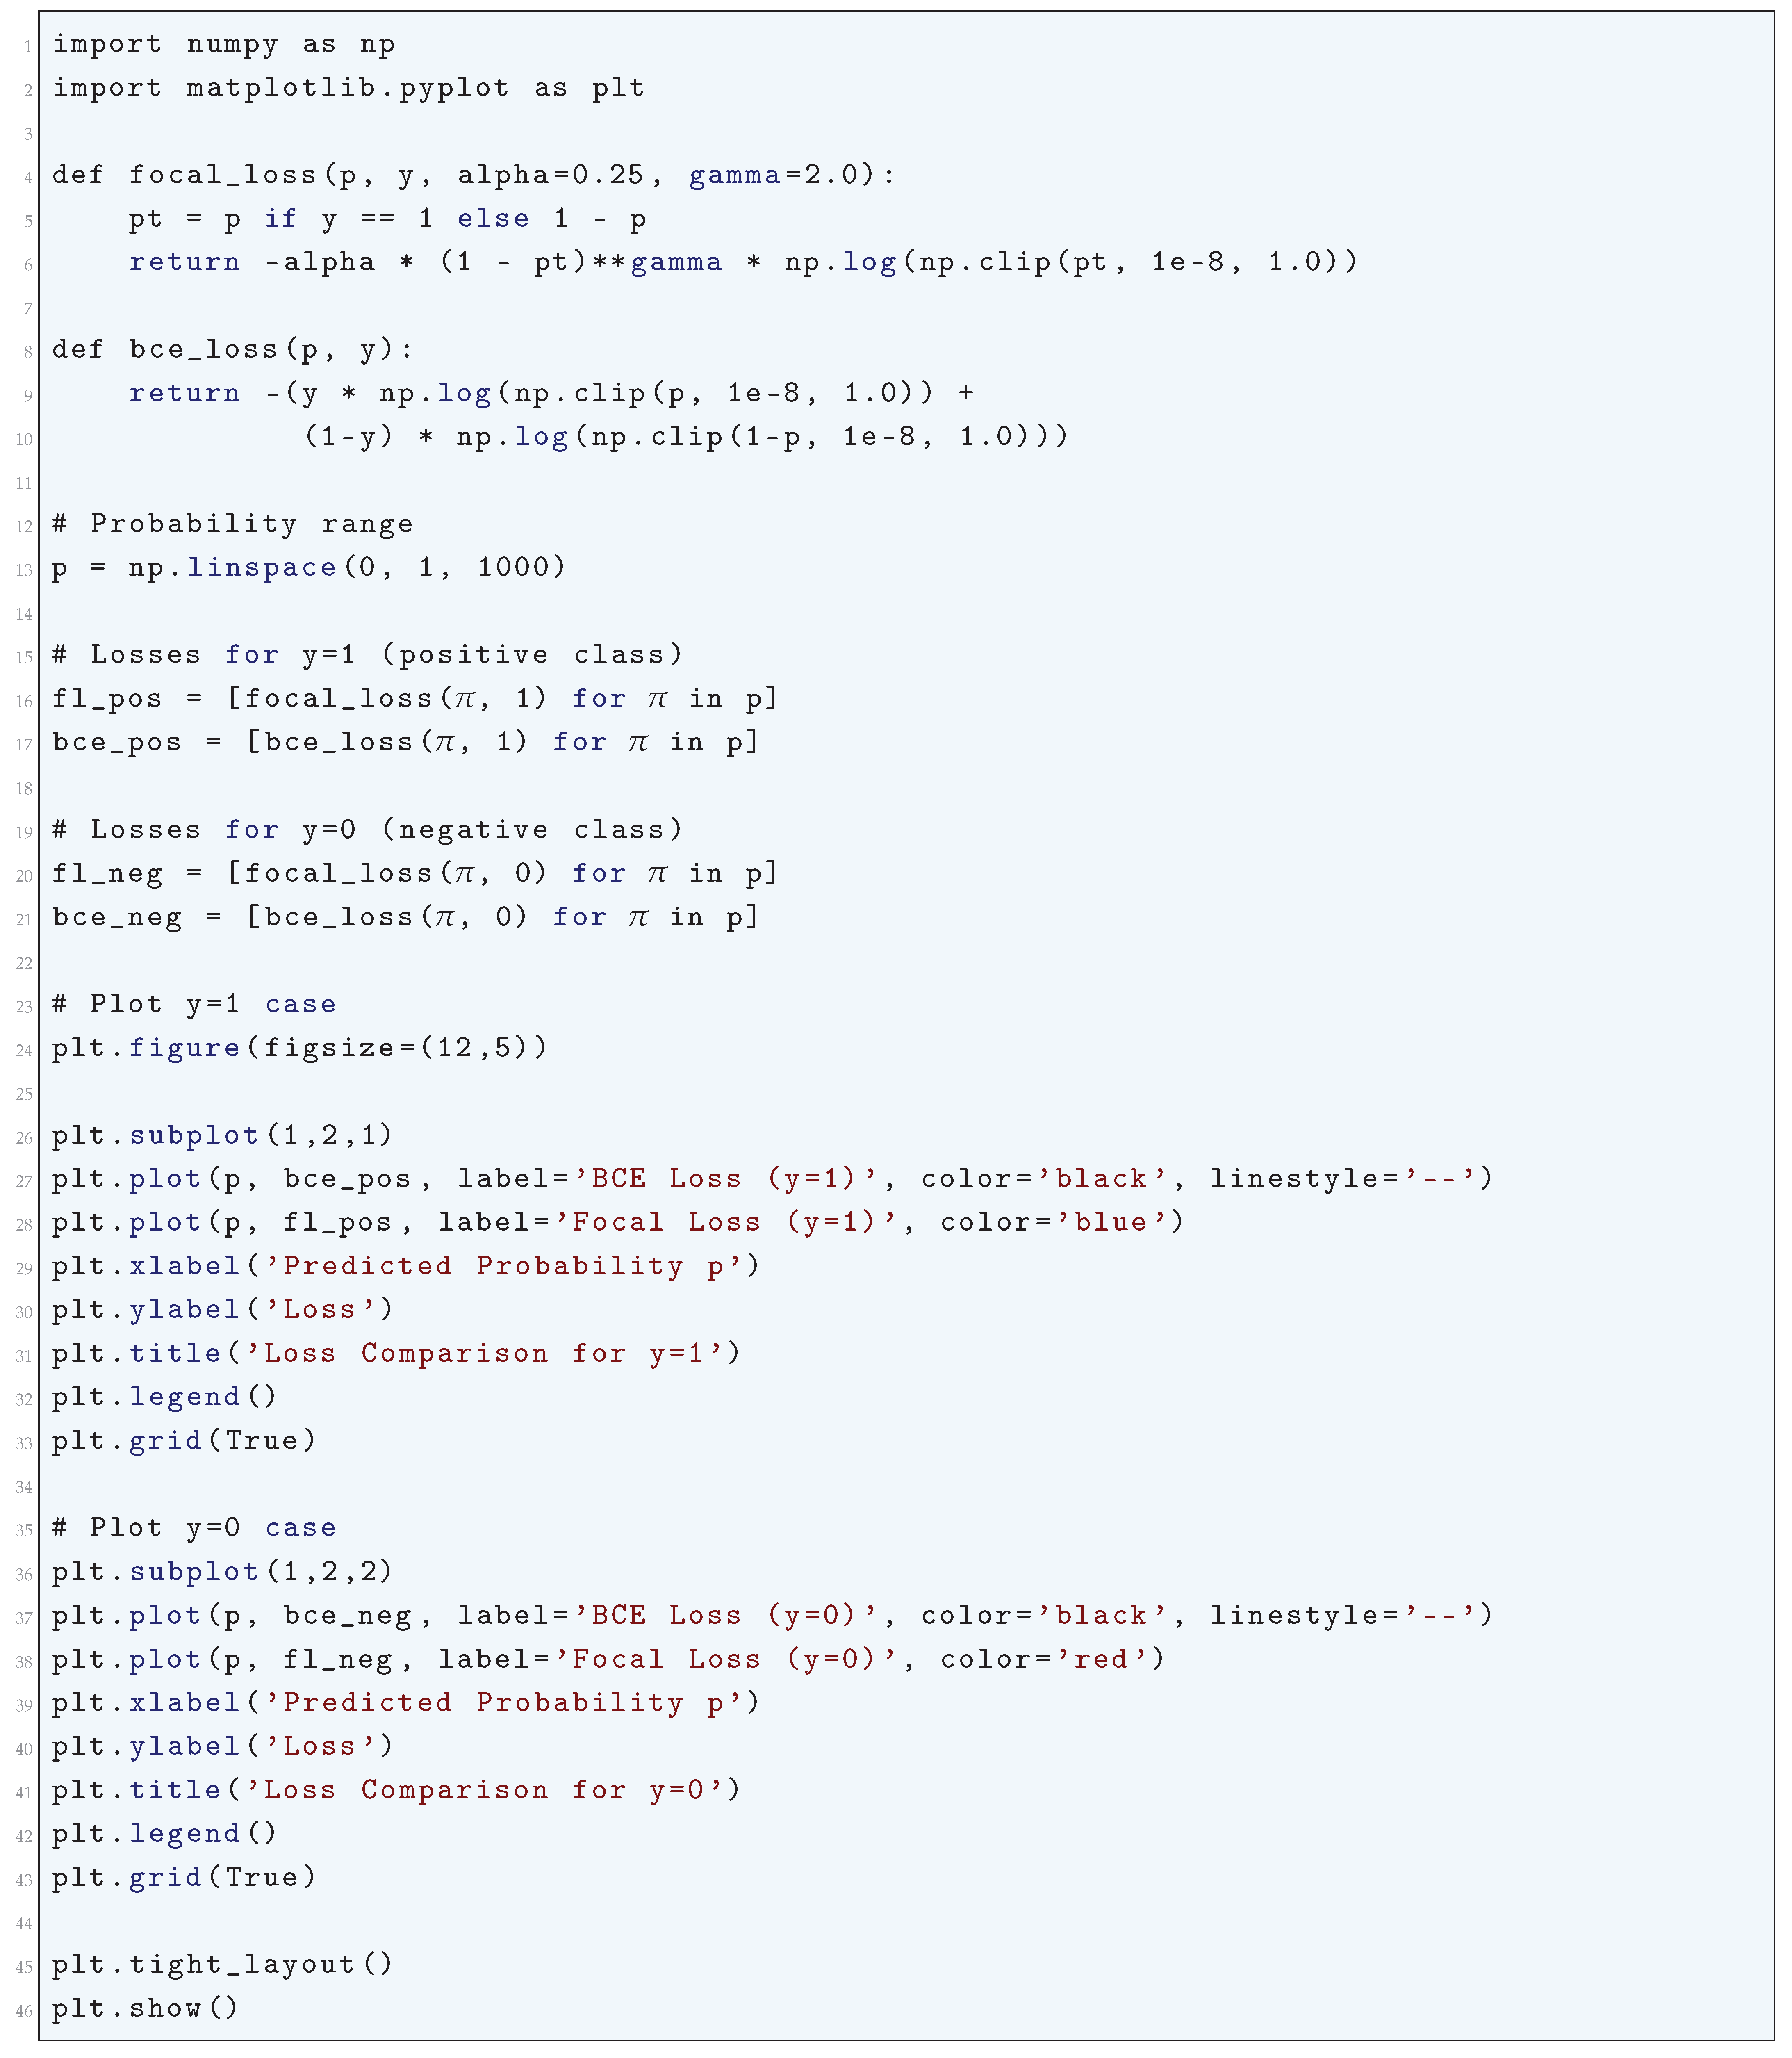
10.5.3.38 Python Code to Generate Figure 105 Illustrating Hinge Loss vs Prediction Score
The Python code below produces the Figure 105 illustrating Hinge Loss vs Prediction Score.
Figure 105.
Hinge Loss vs Prediction Score
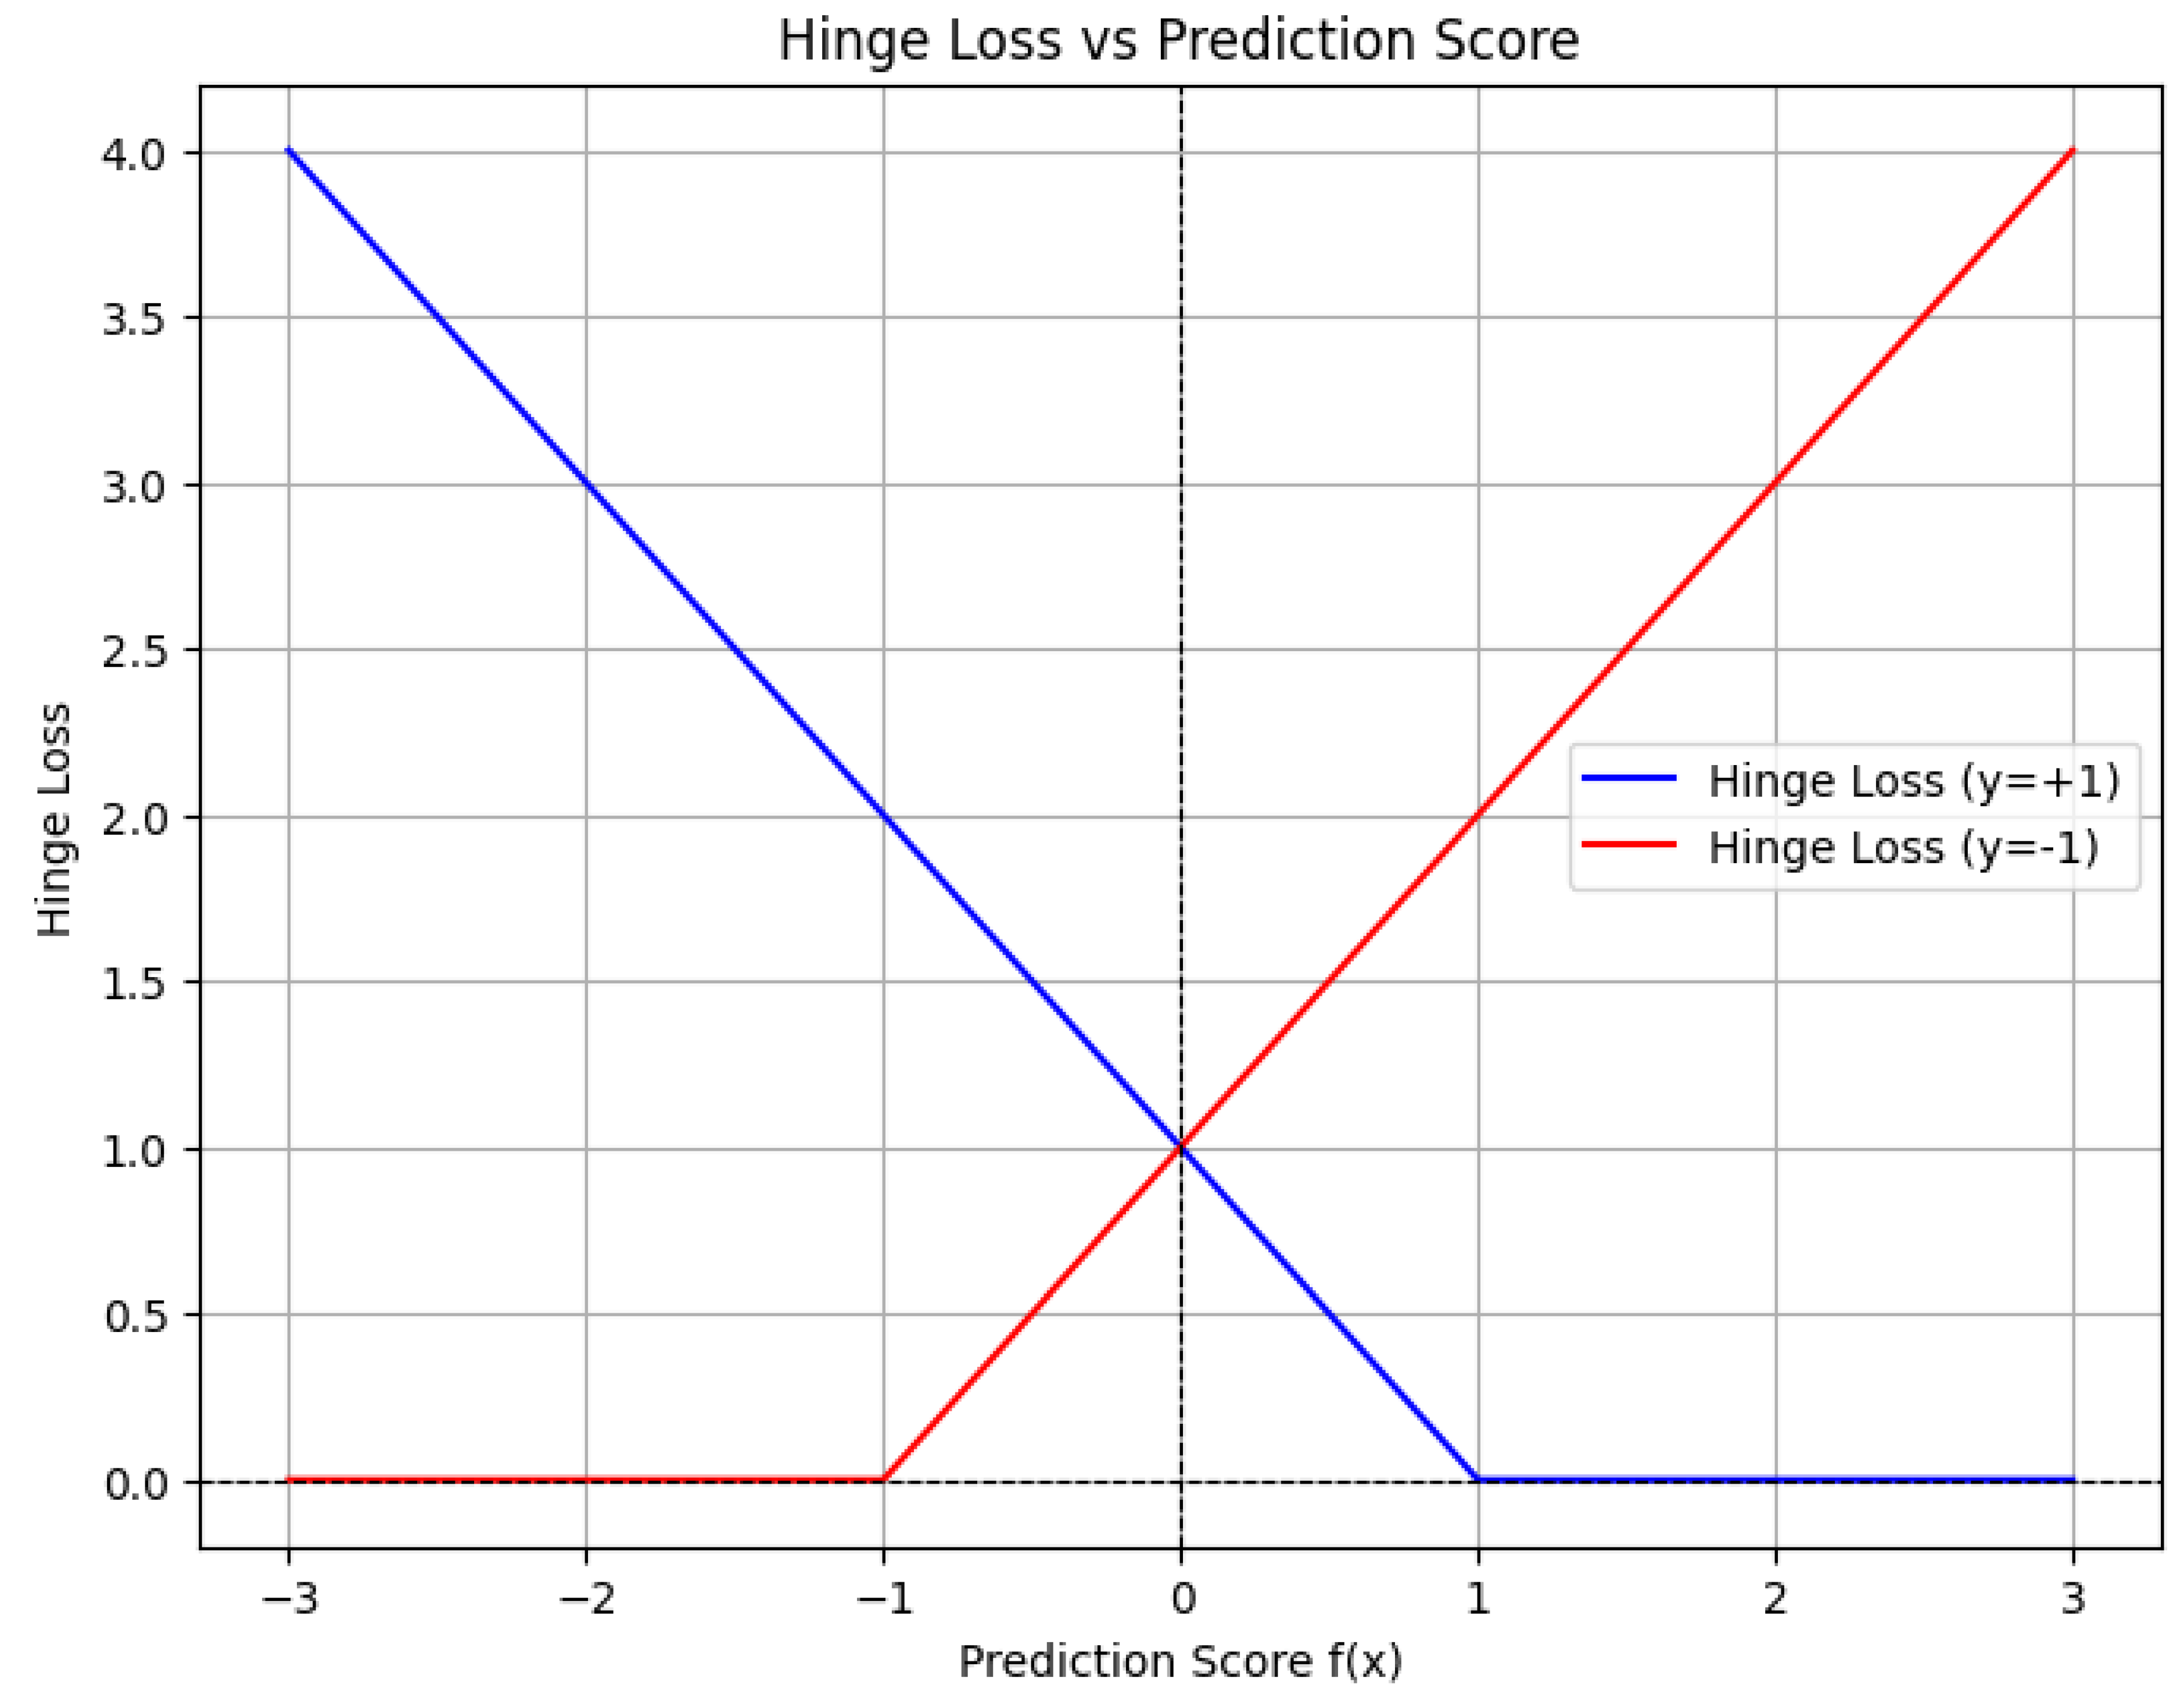
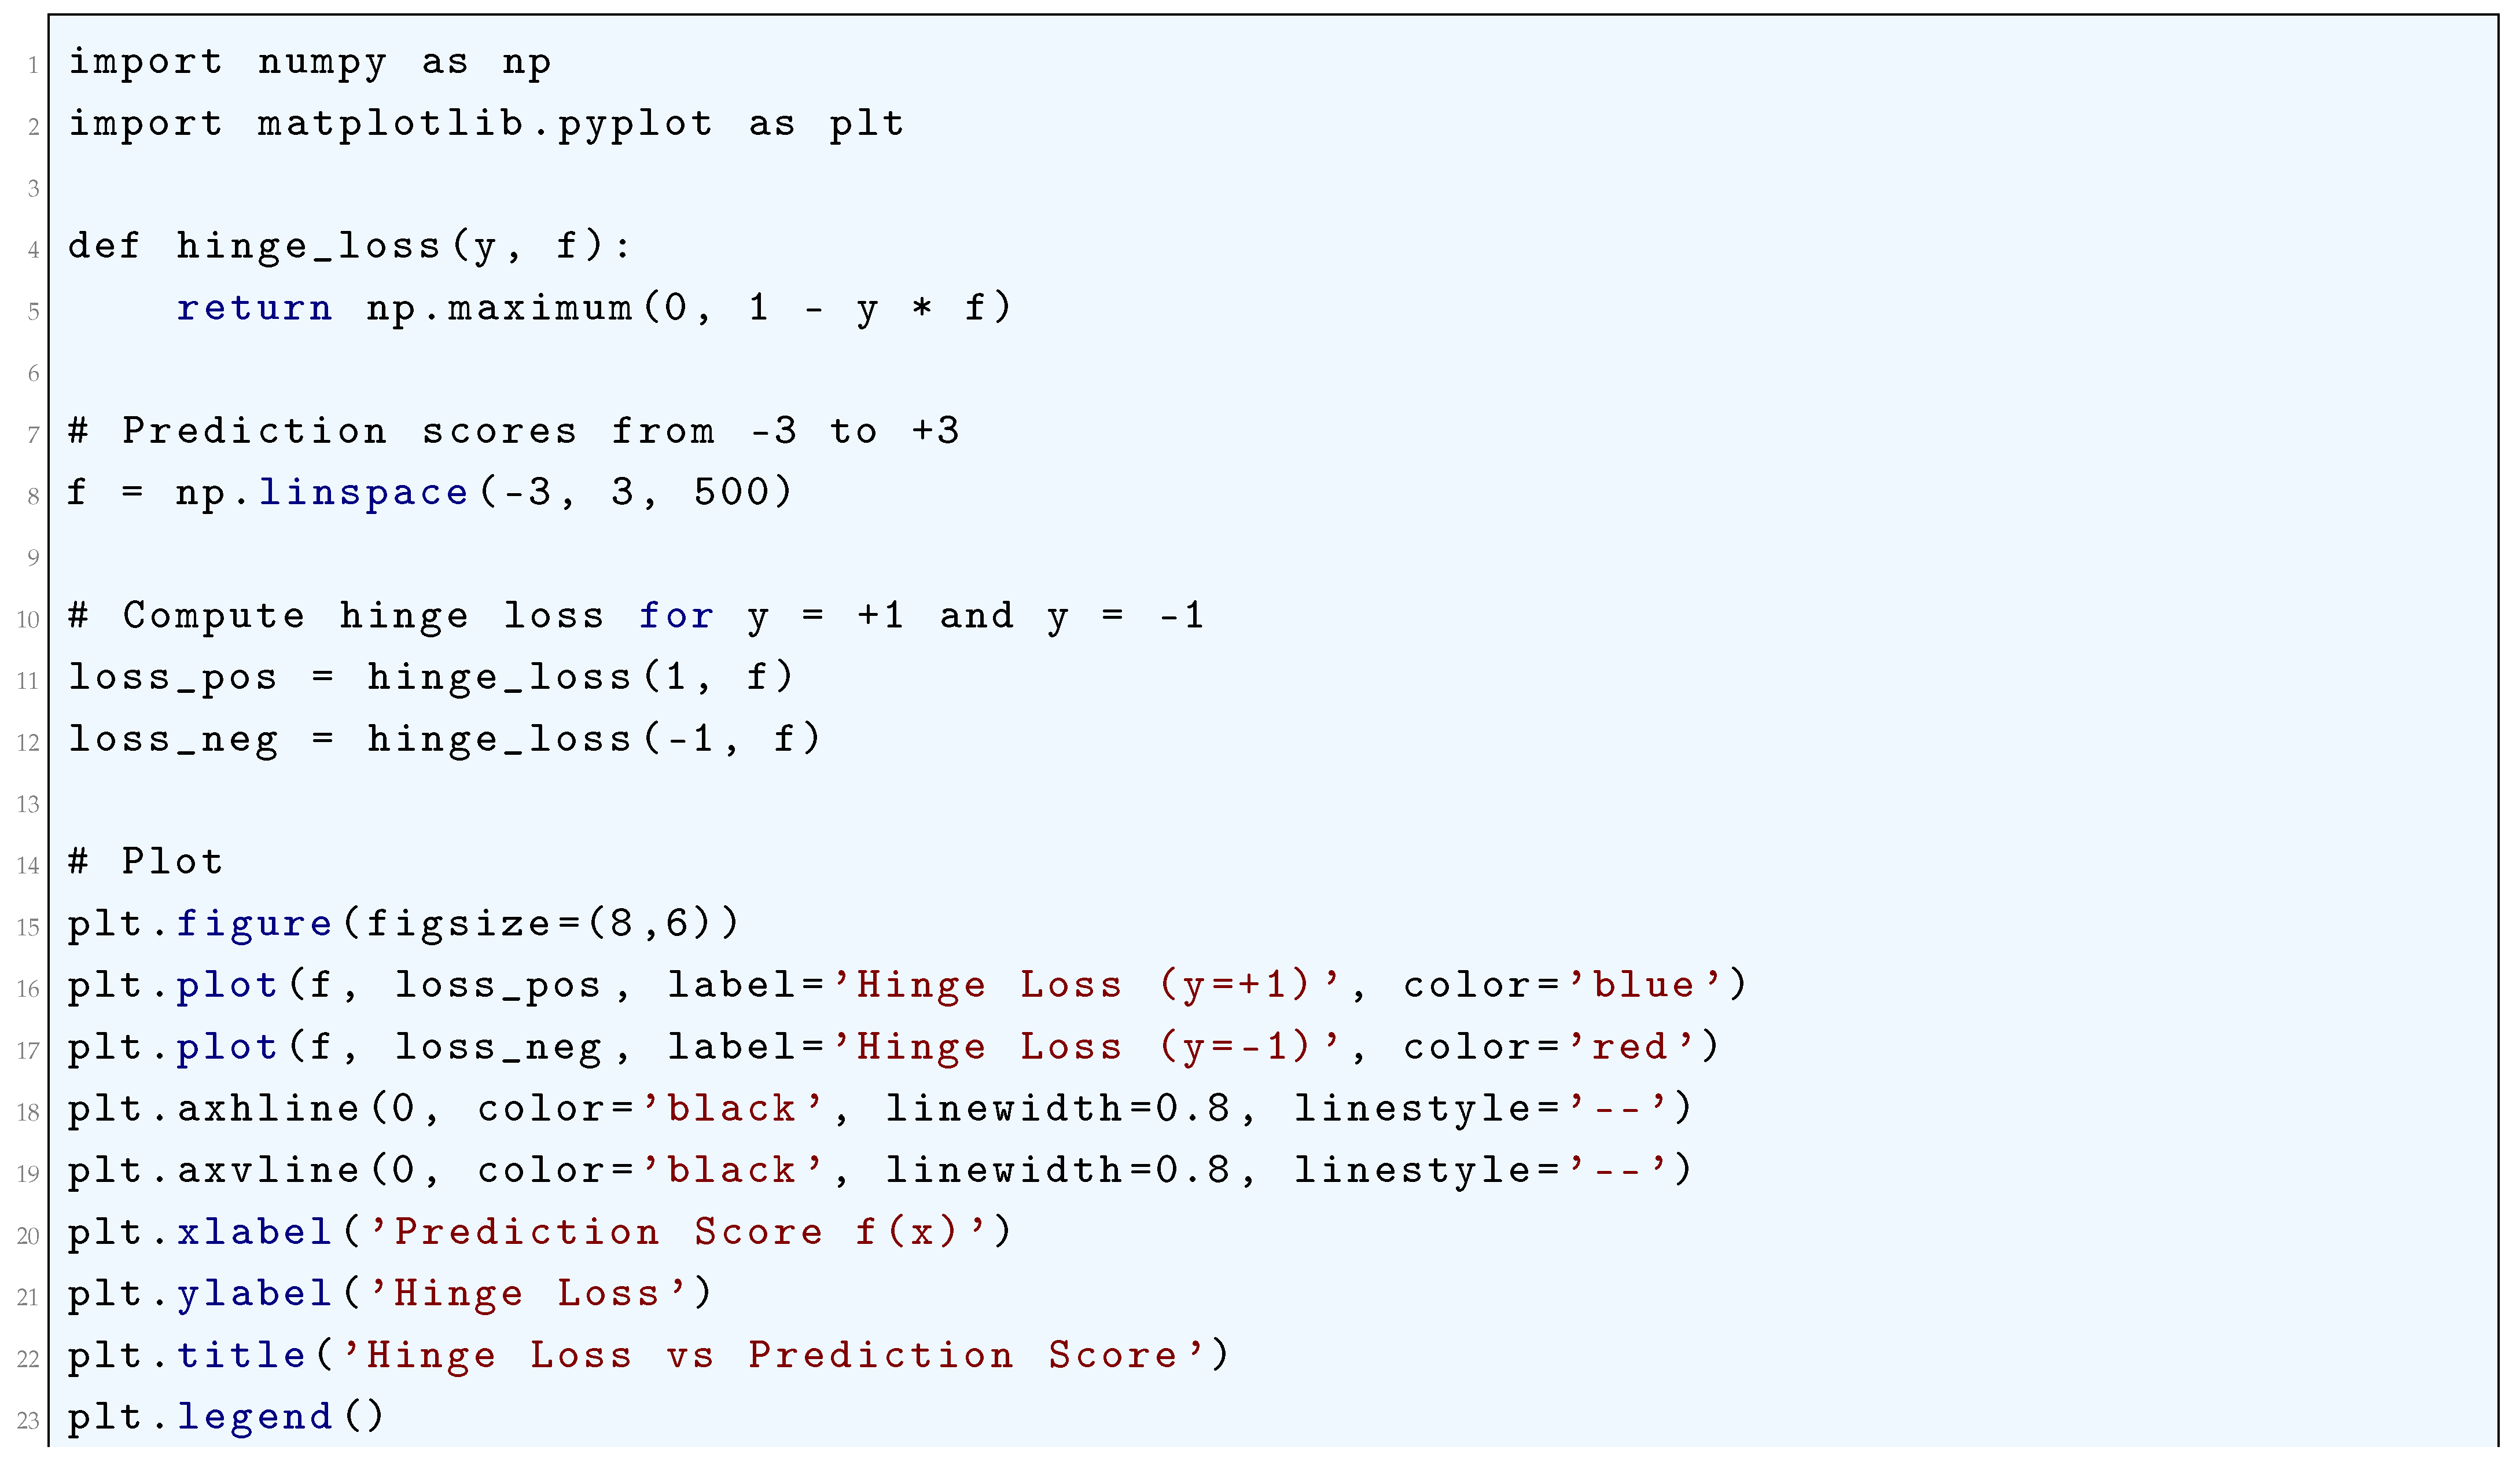

10.5.3.39 Python Code to Generate Figure 106 Illustrating Comparison of the Standard Hinge Loss and the Squared Hinge Loss
The Python code below produces the Figure 106 illustrating Comparison of the Standard Hinge Loss and the Squared Hinge Loss.
Figure 106.
Comparison of the Standard Hinge Loss and the Squared Hinge Loss
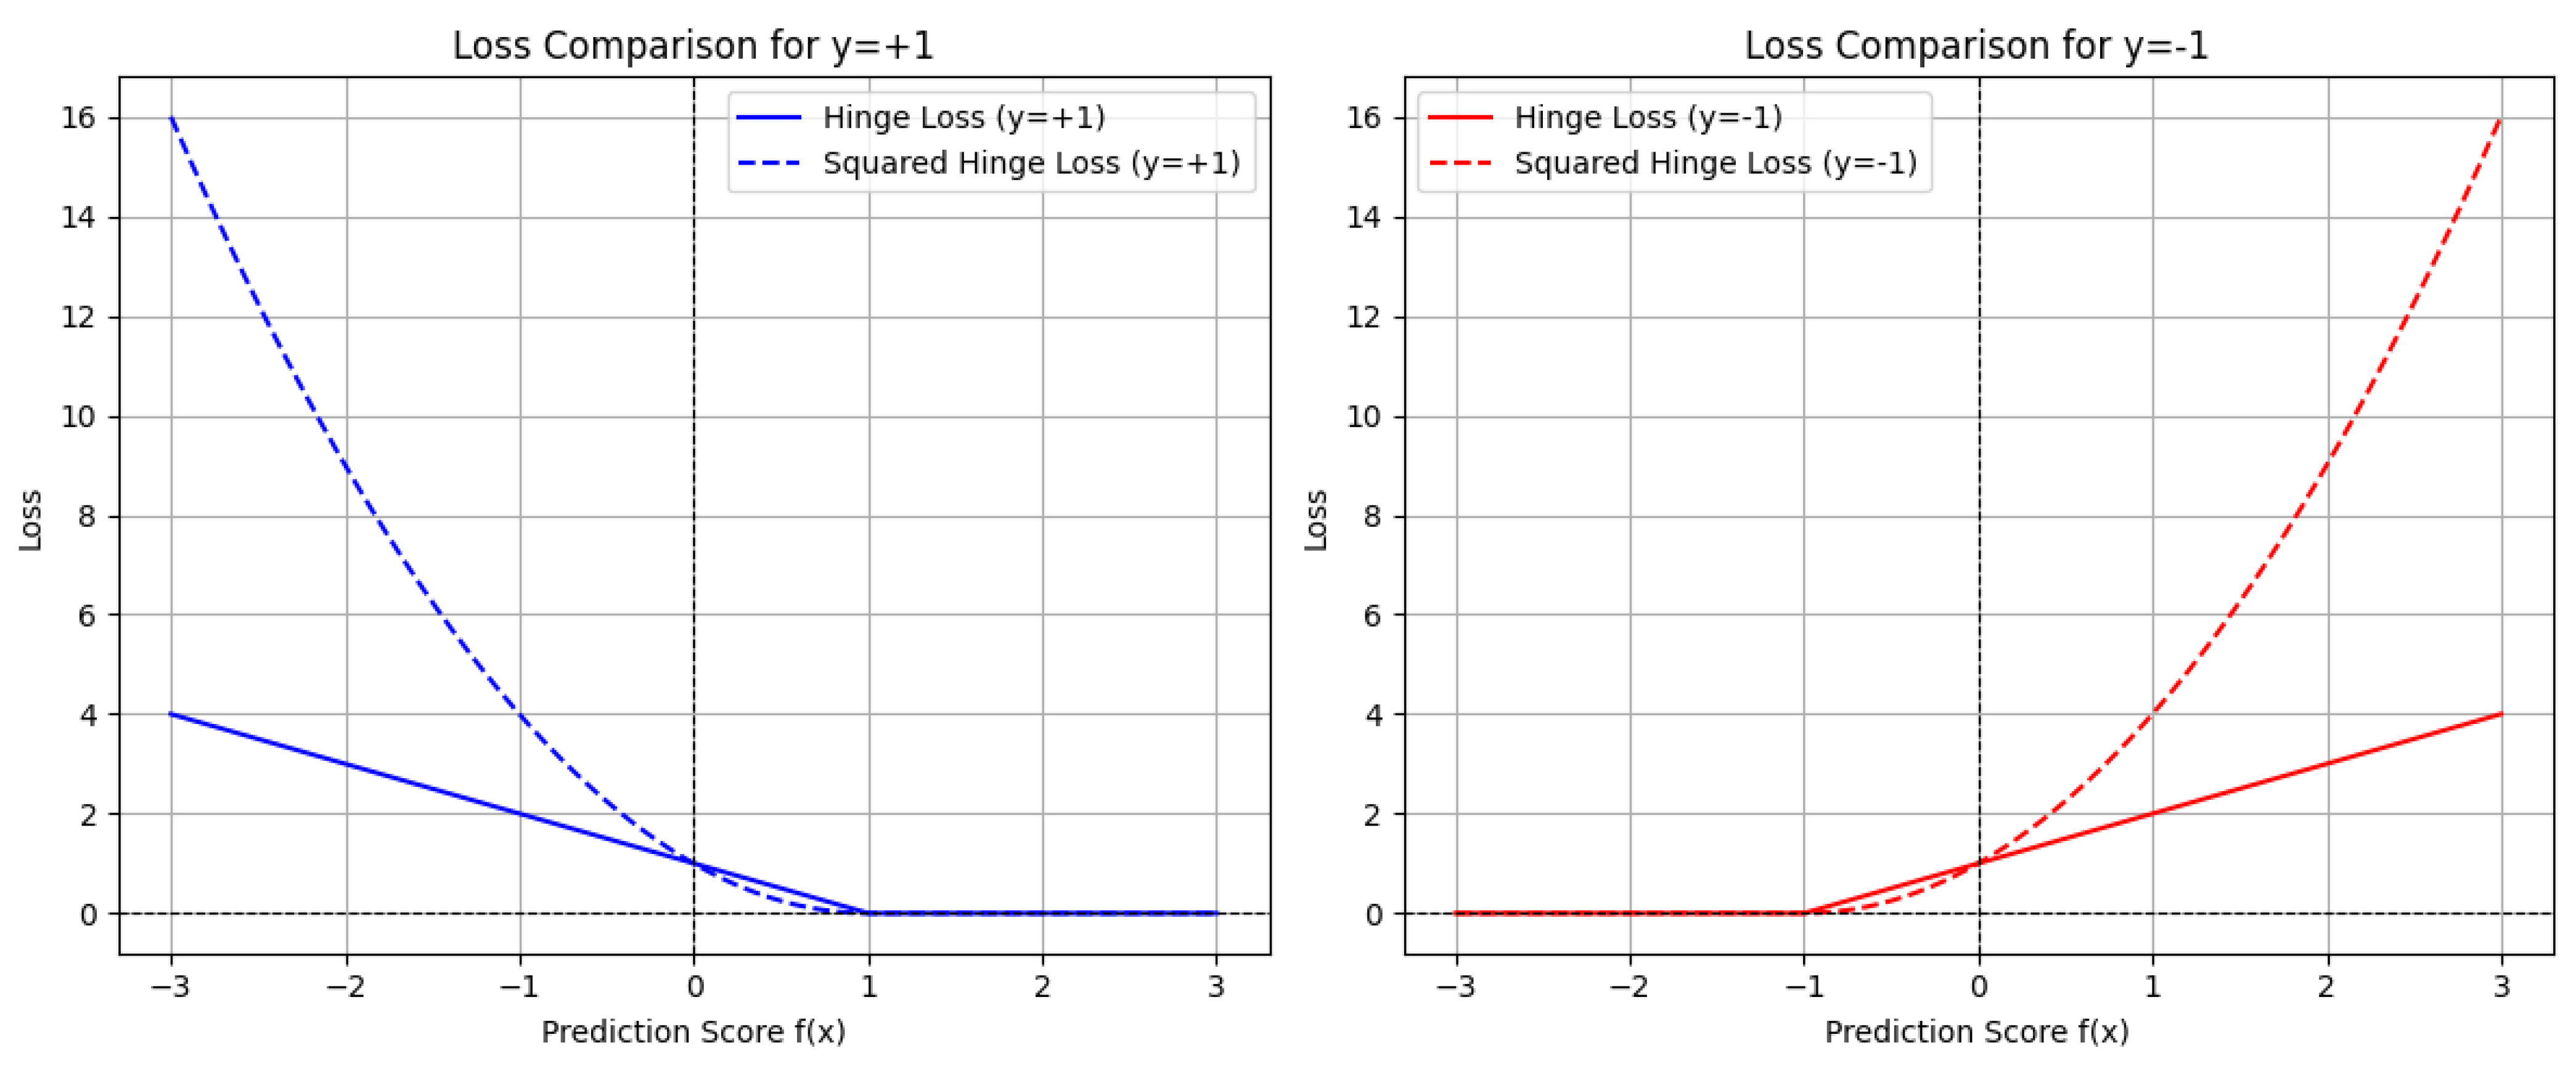
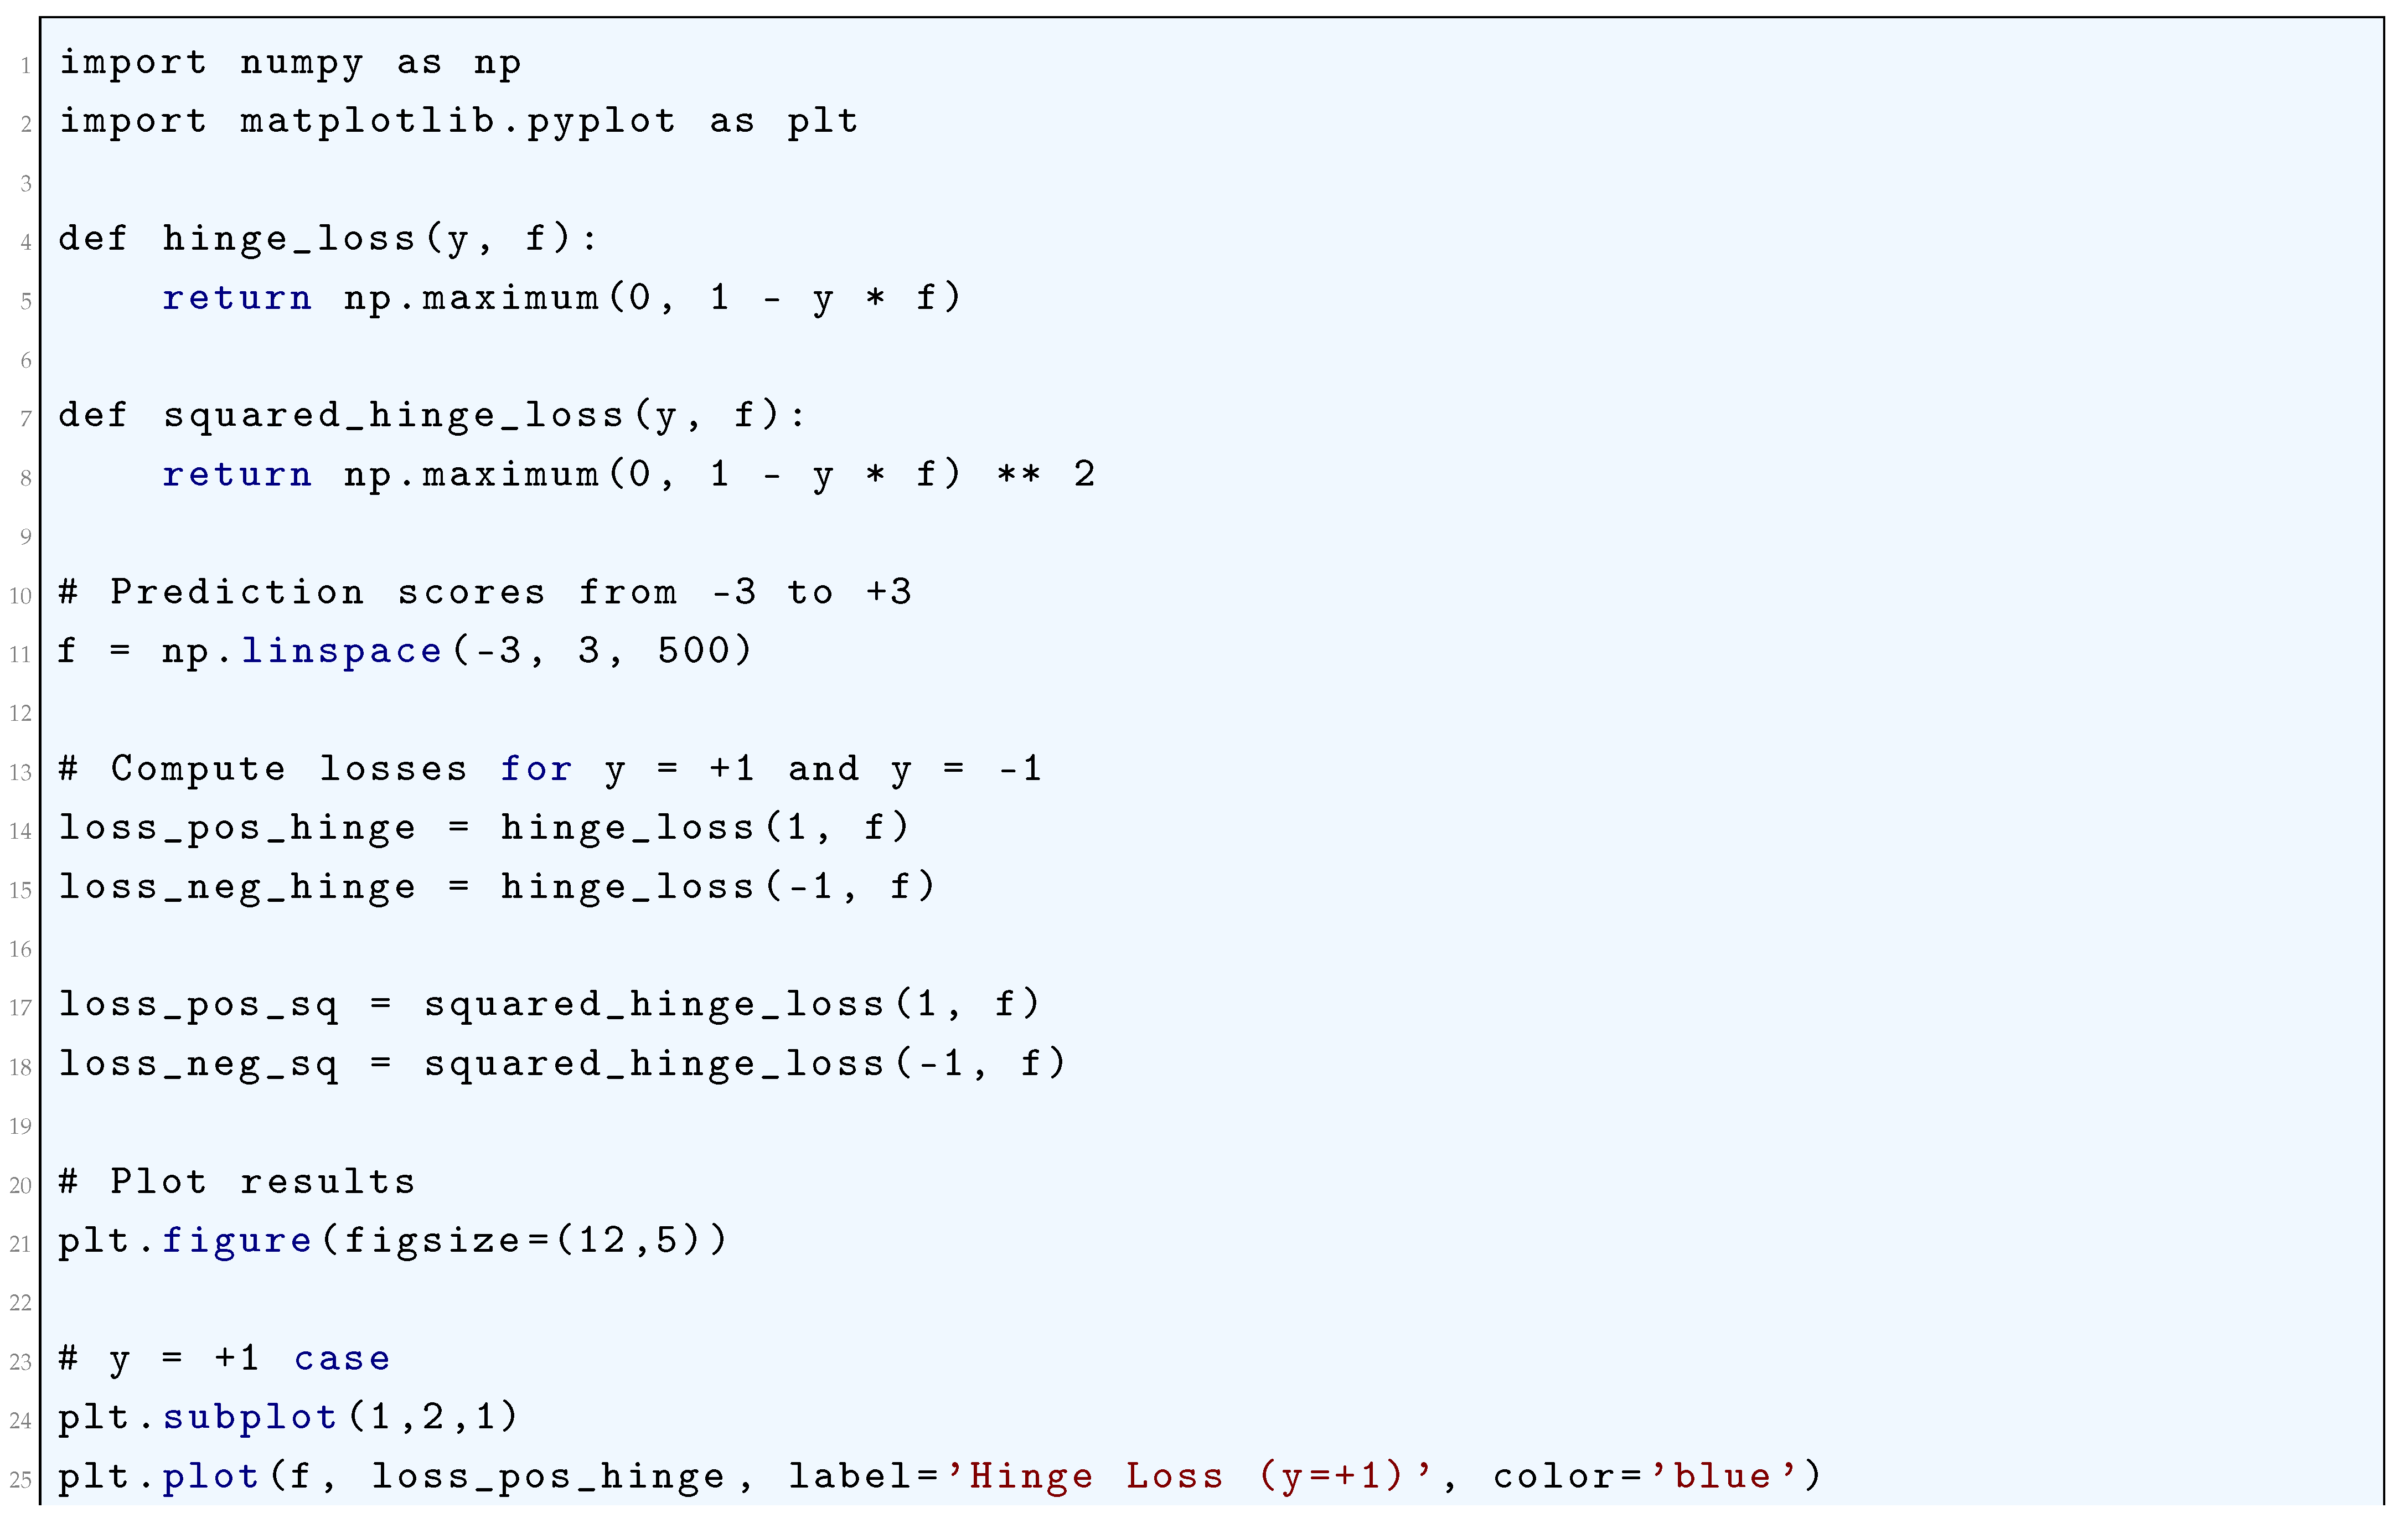
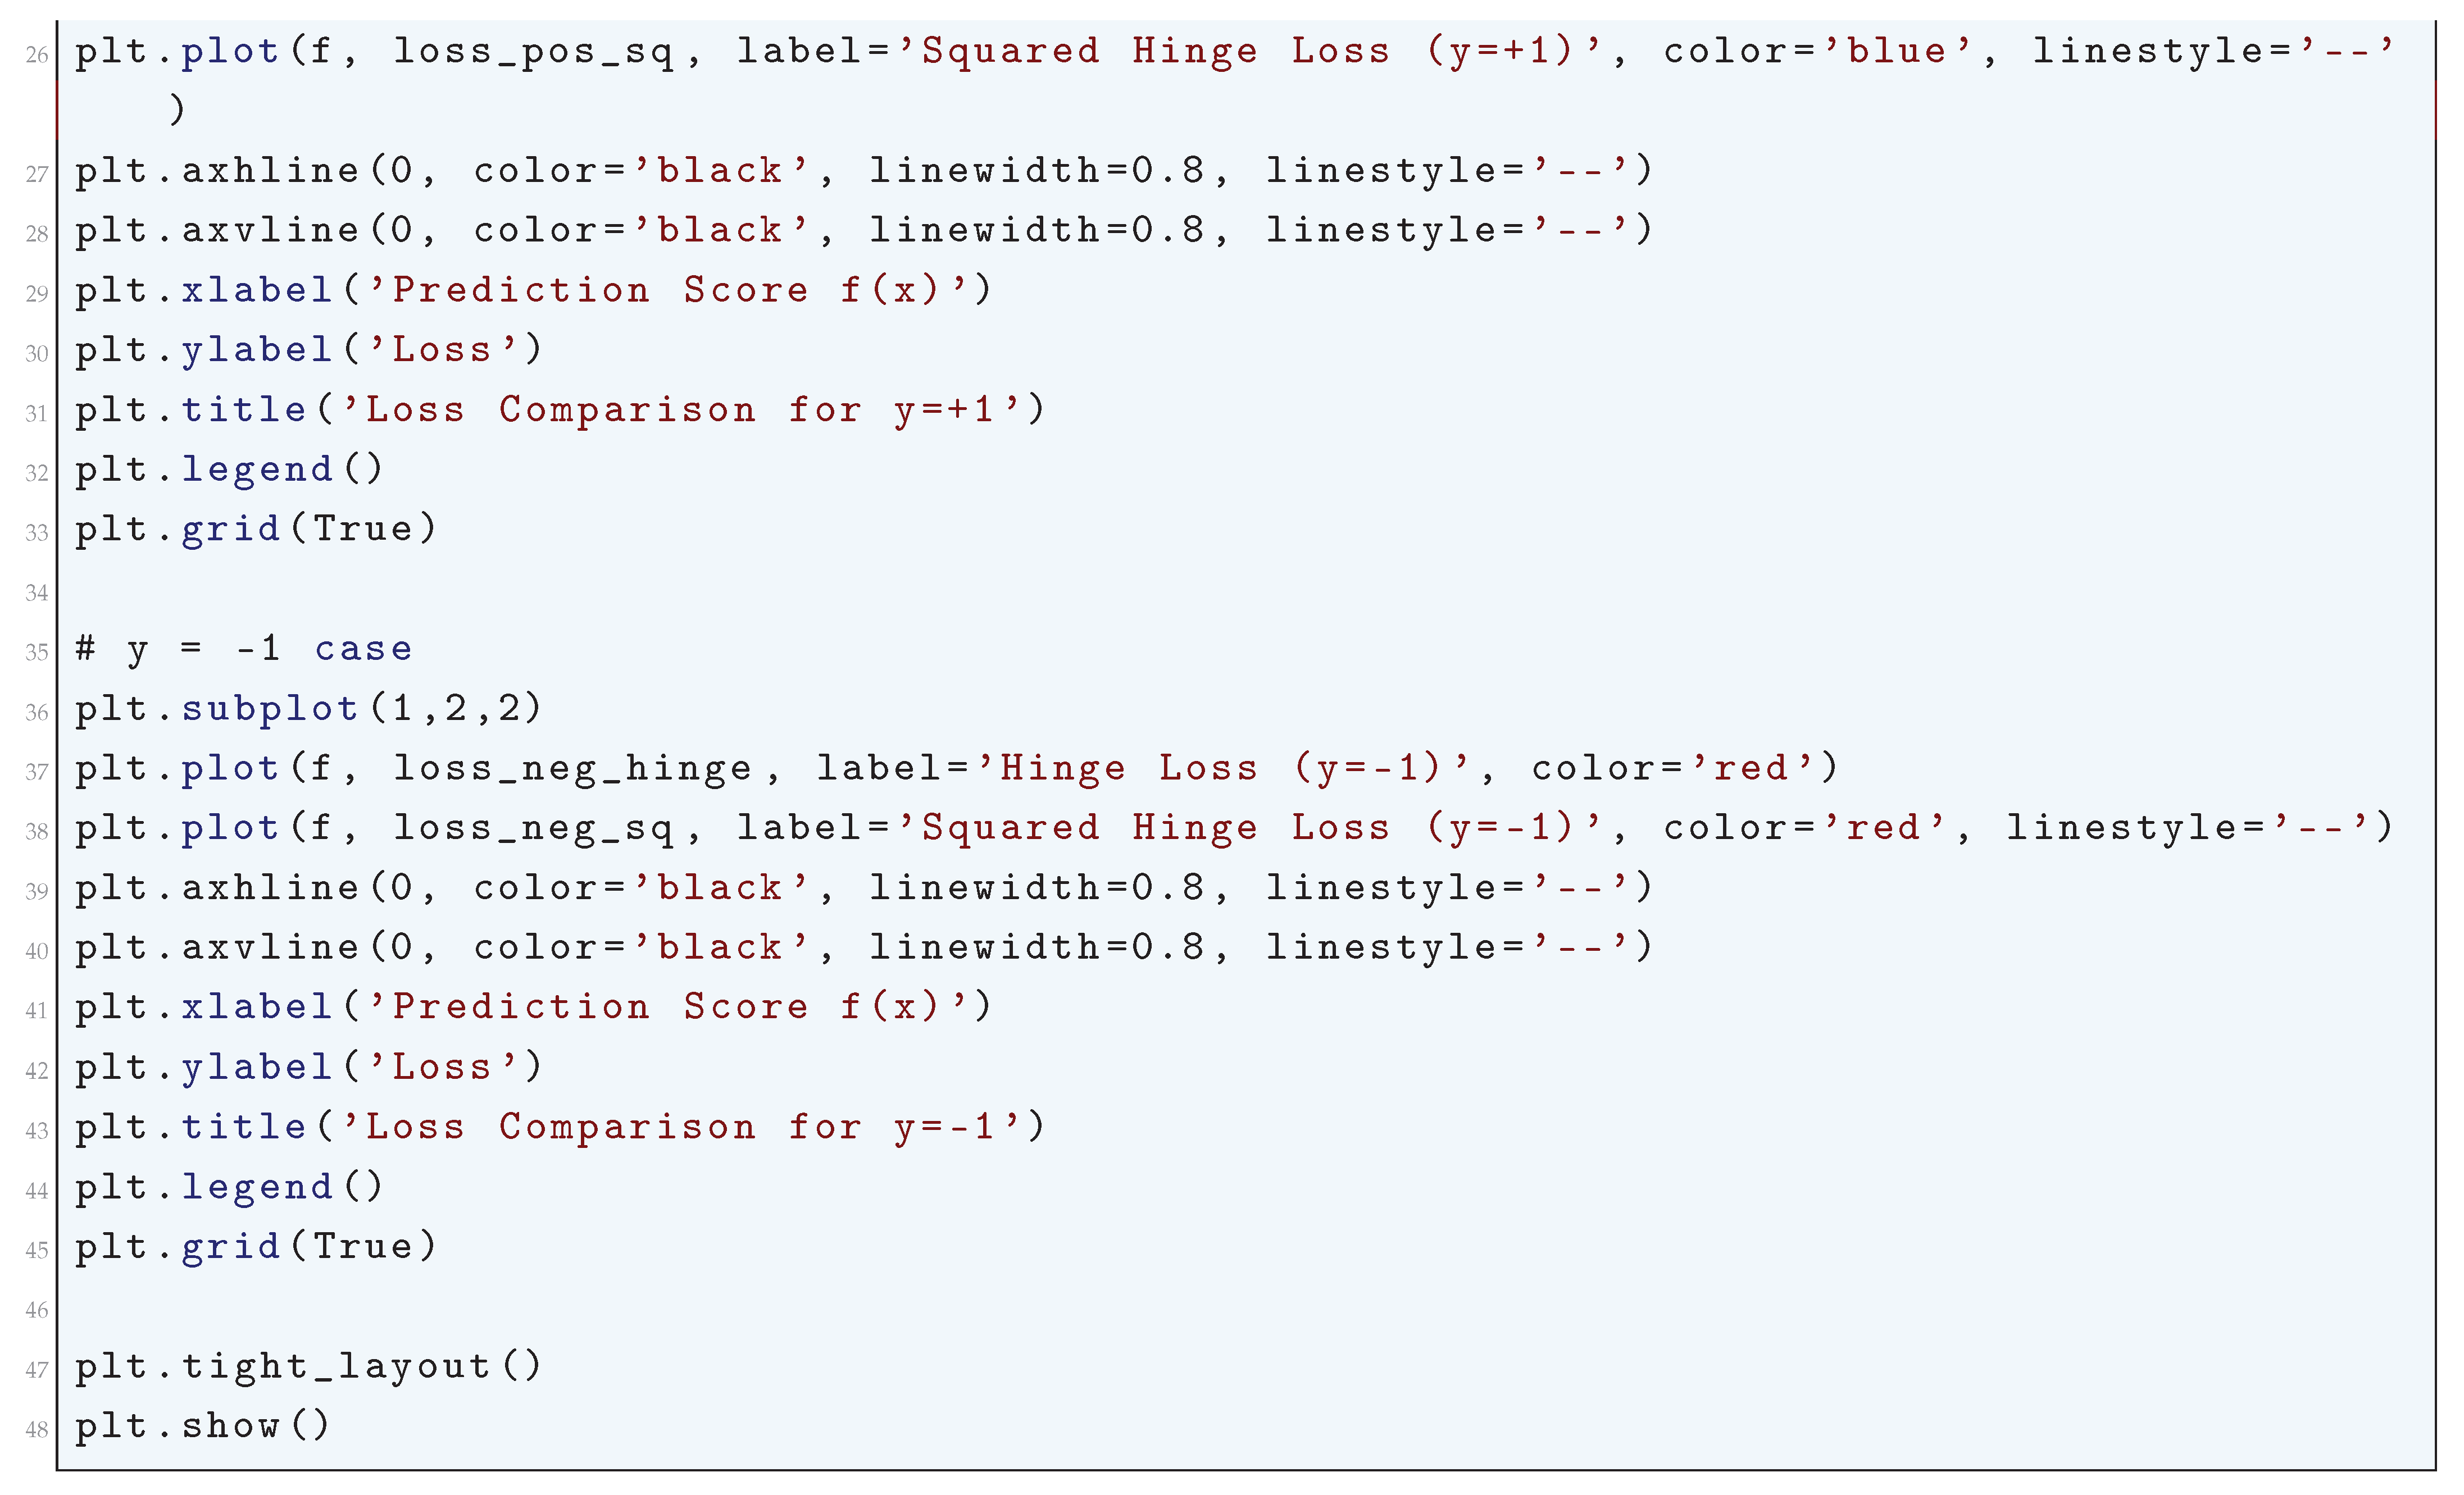
10.5.3.40 Python Code to Generate Figure 107 Illustrating Value Loss (MSE) for Different Targets
The Python code below produces the Figure 107 illustrating Value Loss (MSE) for Different Targets.
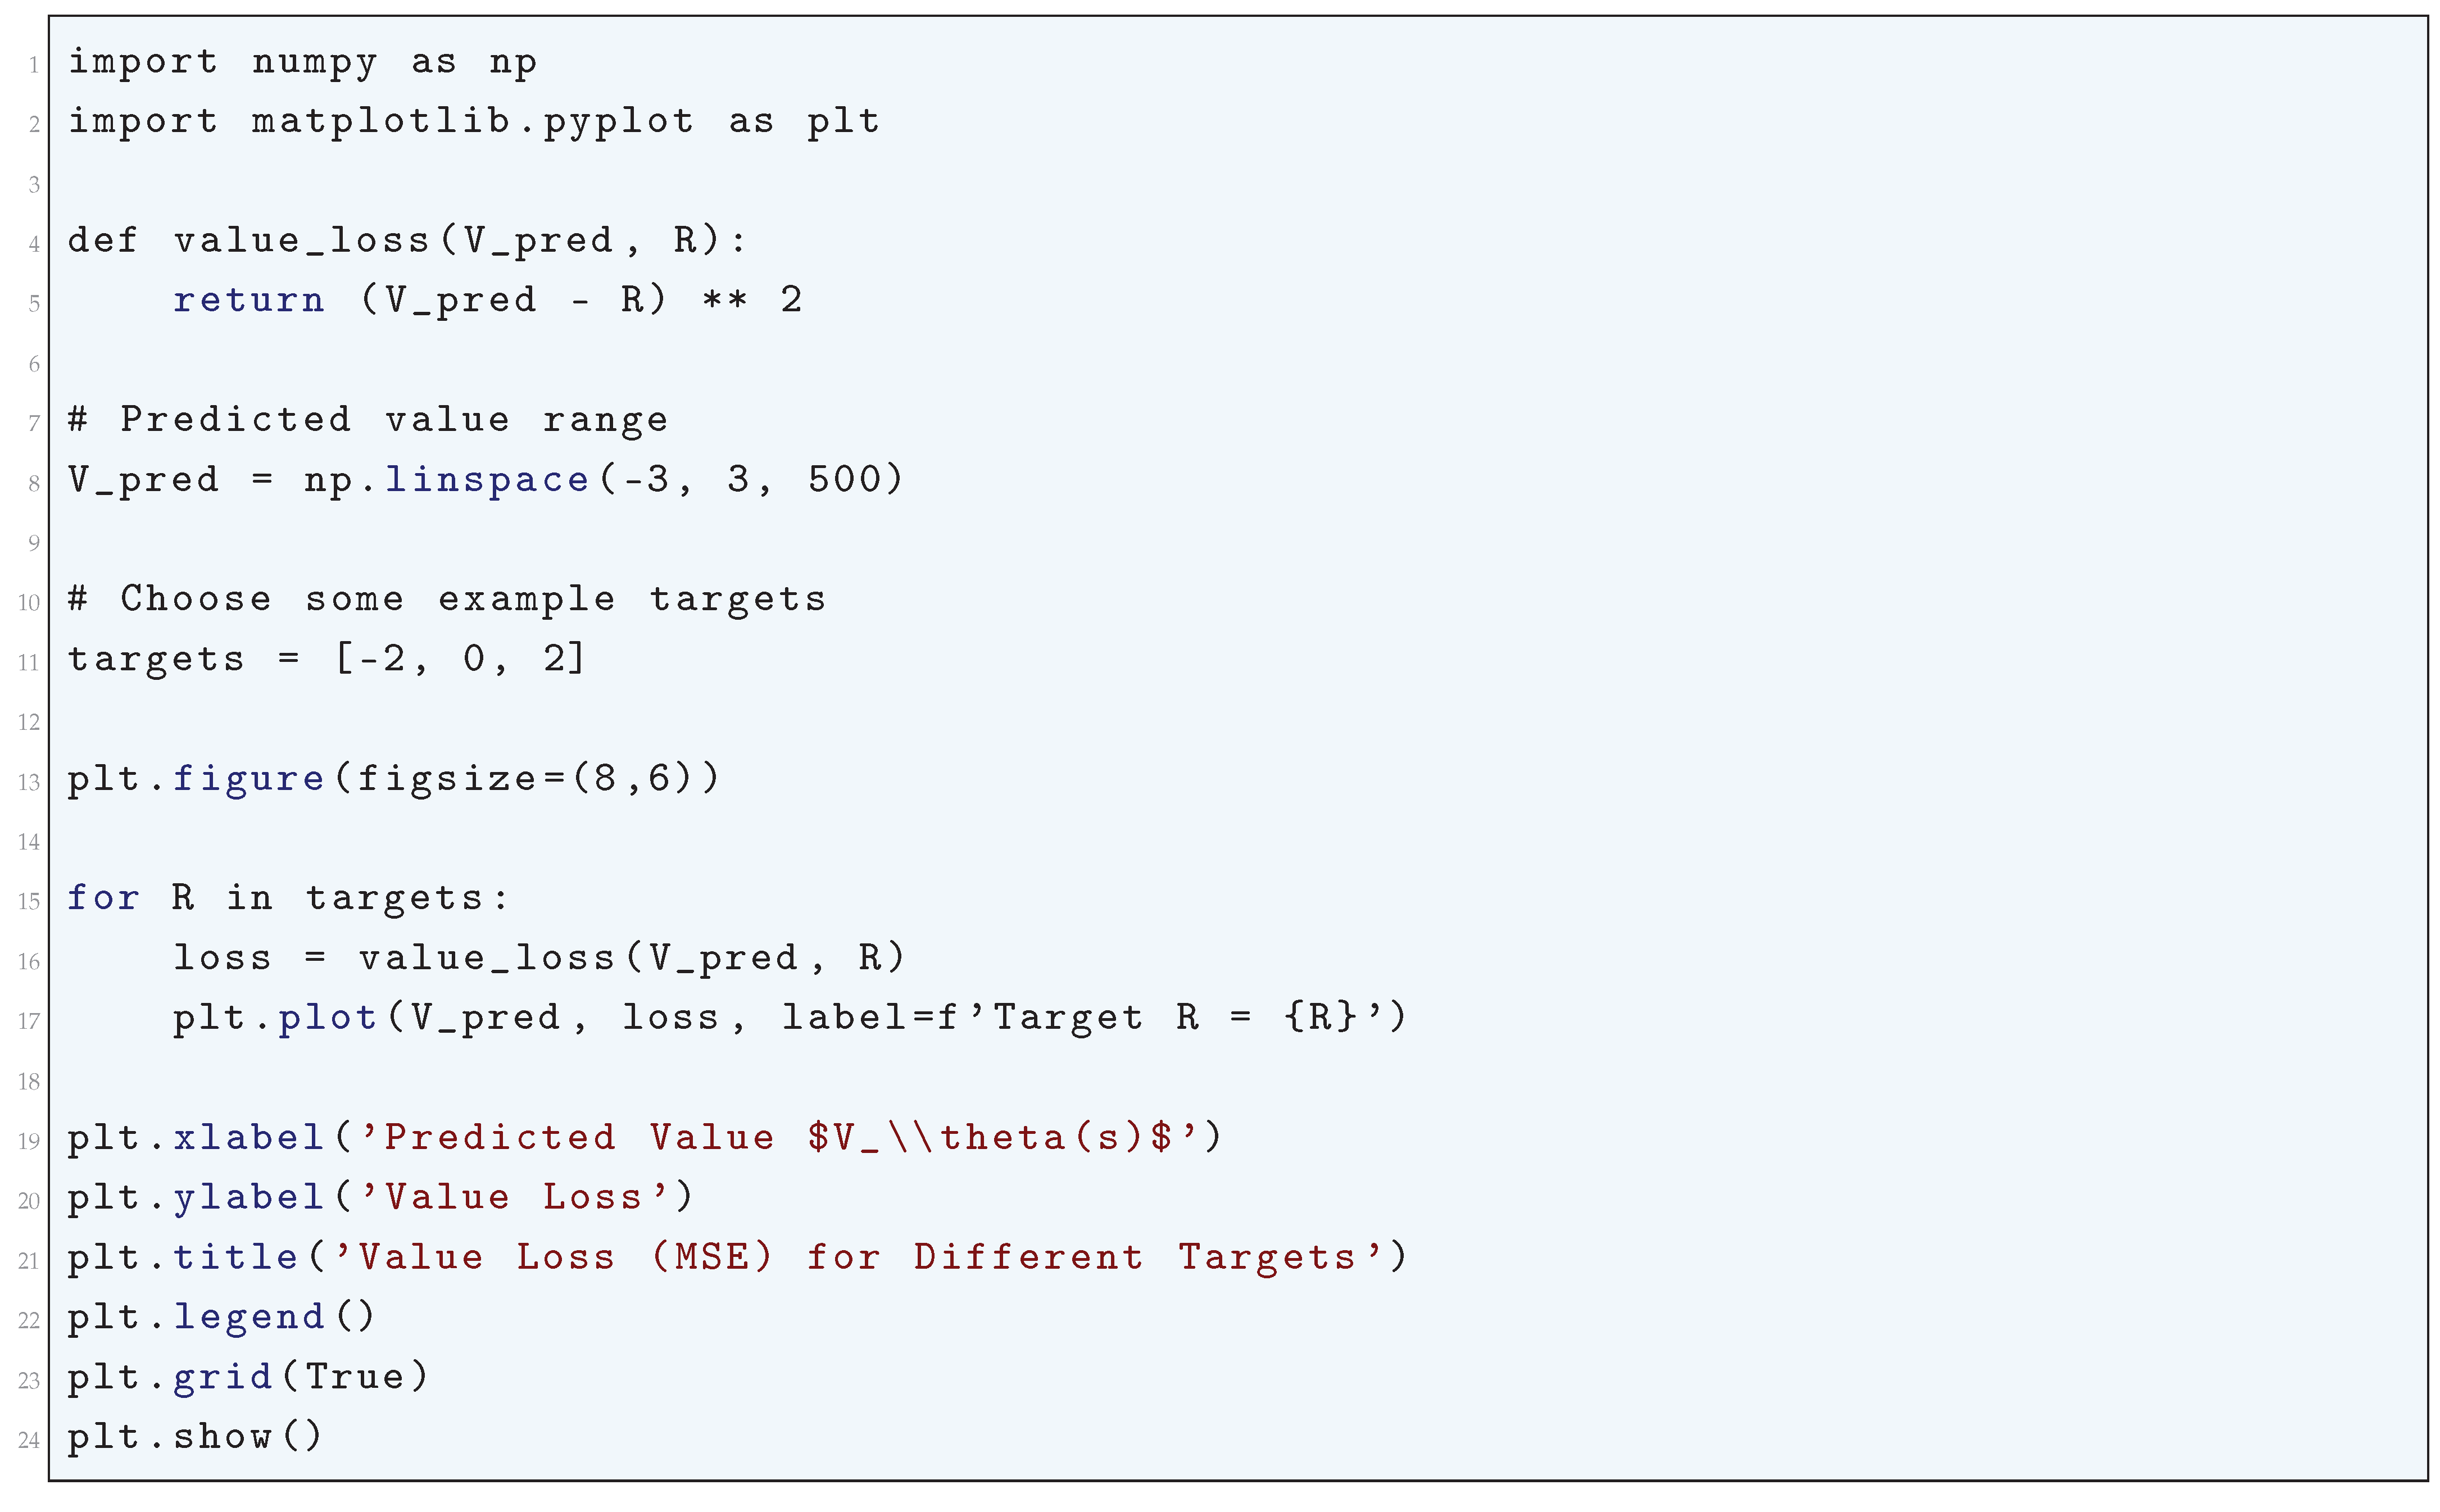
Figure 107.
Value Loss (MSE) for Different Targets
10.5.3.41 Python Code to Generate Figure 108 Illustrating Value Loss (MSE) vs Huber Loss
The Python code below produces the Figure 108 illustrating Value Loss (MSE) vs Huber Loss.
Figure 108.
Value Loss (MSE) vs Huber Loss

10.5.3.42 Python Code to Generate Figure 109 Illustrating Policy Loss vs Action Probability
The Python code below produces the Figure 109 illustrating Policy Loss vs Action Probability.
Figure 109.
Policy Loss vs Action Probability
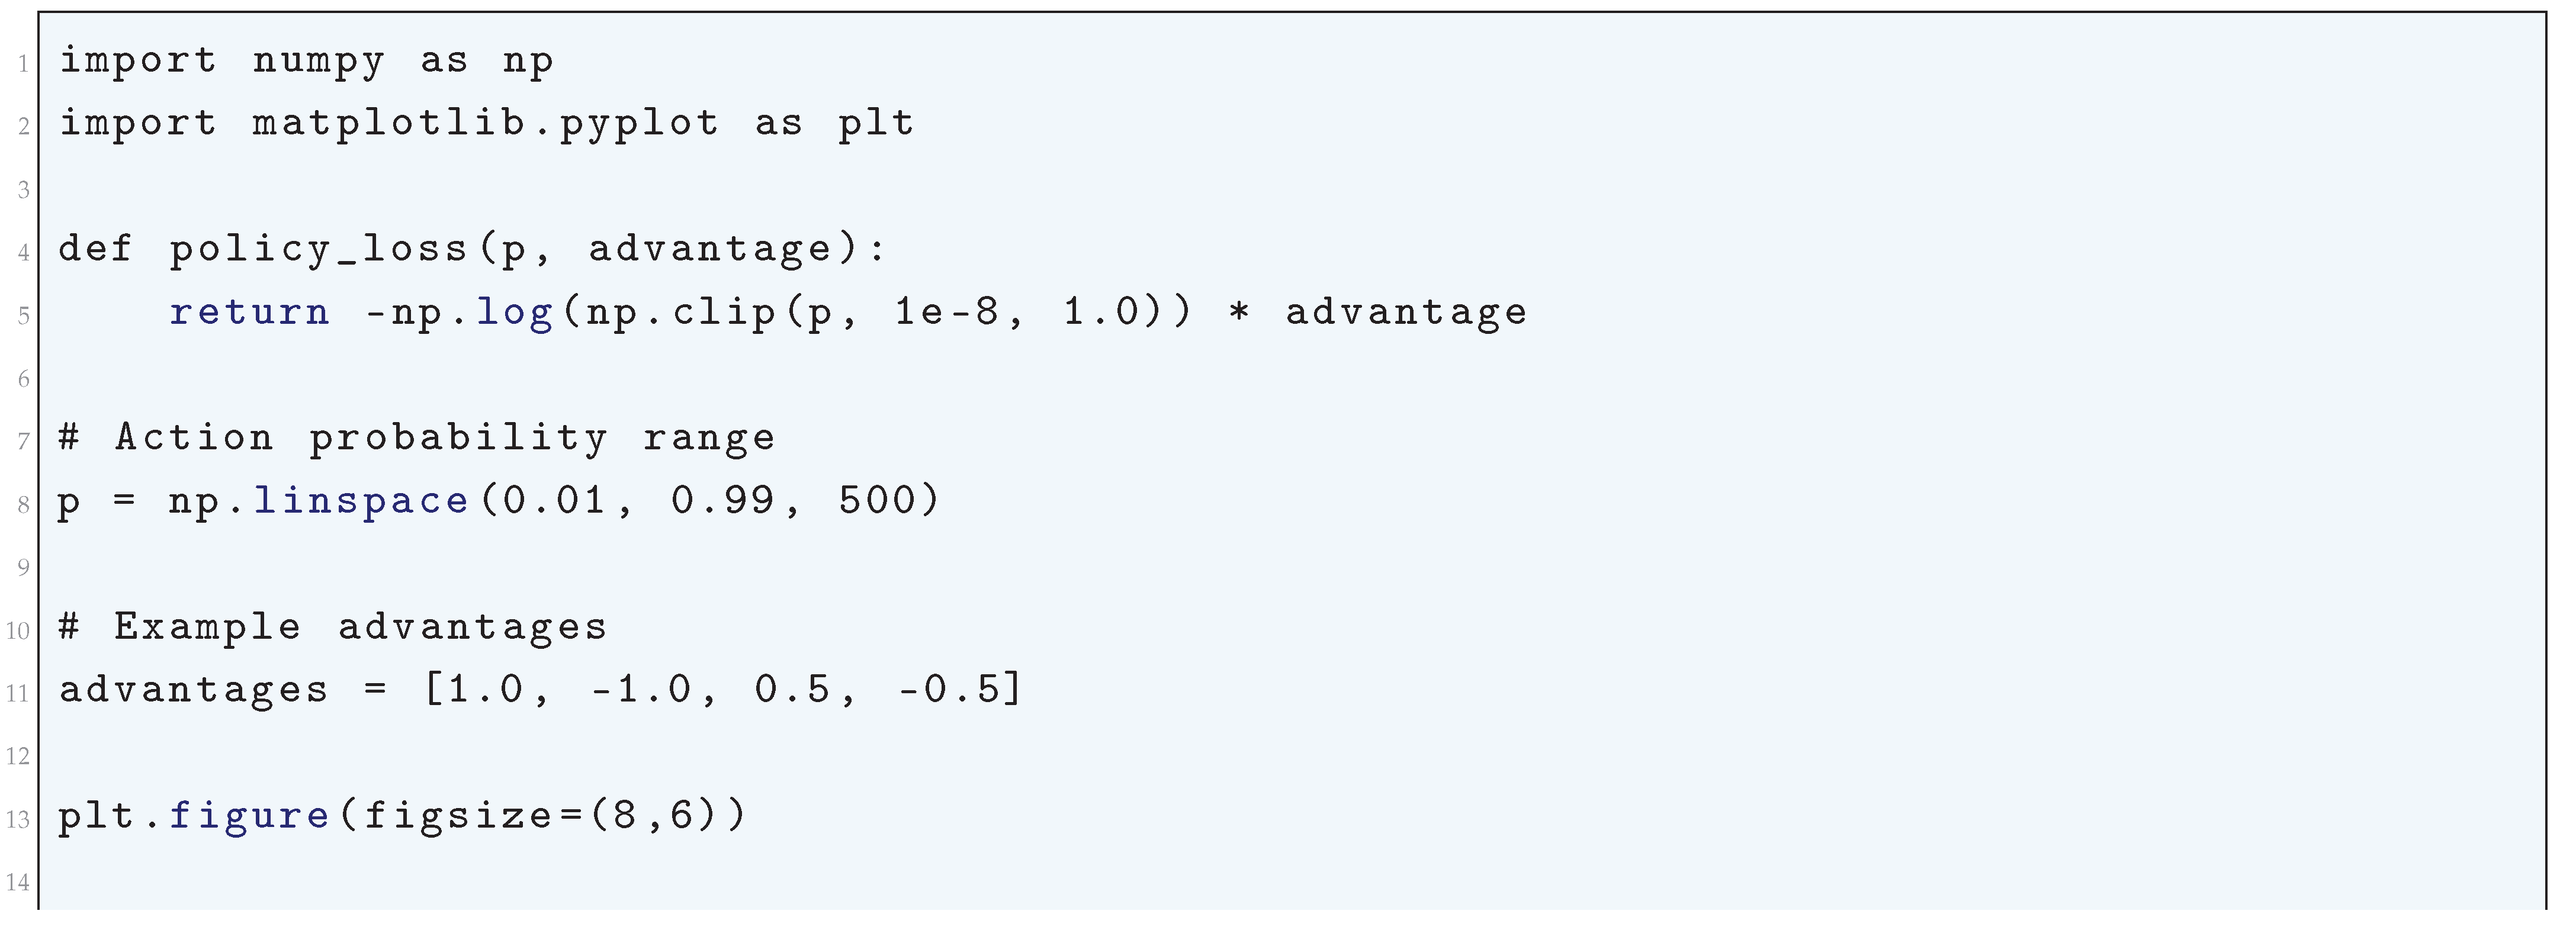
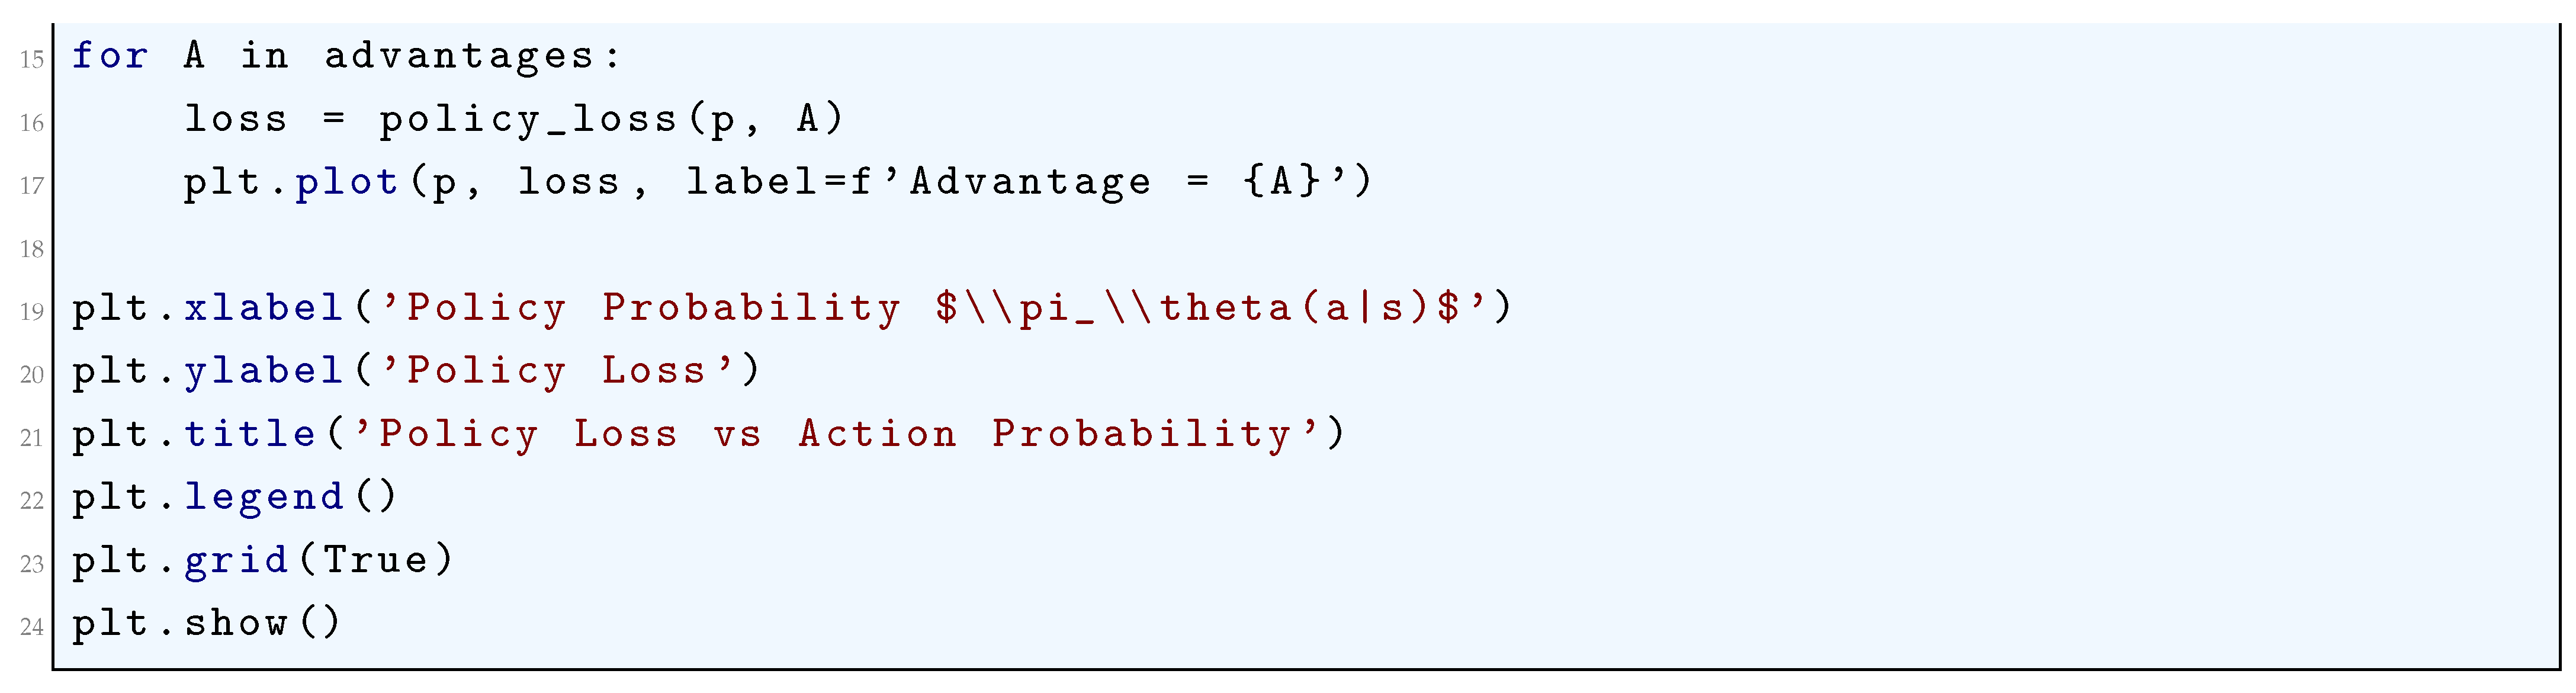
10.5.3.43 Python Code to Generate Figure 110 Illustrating PPO Clipped Surrogate Objective
The Python code below produces the Figure 110 illustrating PPO Clipped Surrogate Objective.
Figure 110.
PPO Clipped Surrogate Objective
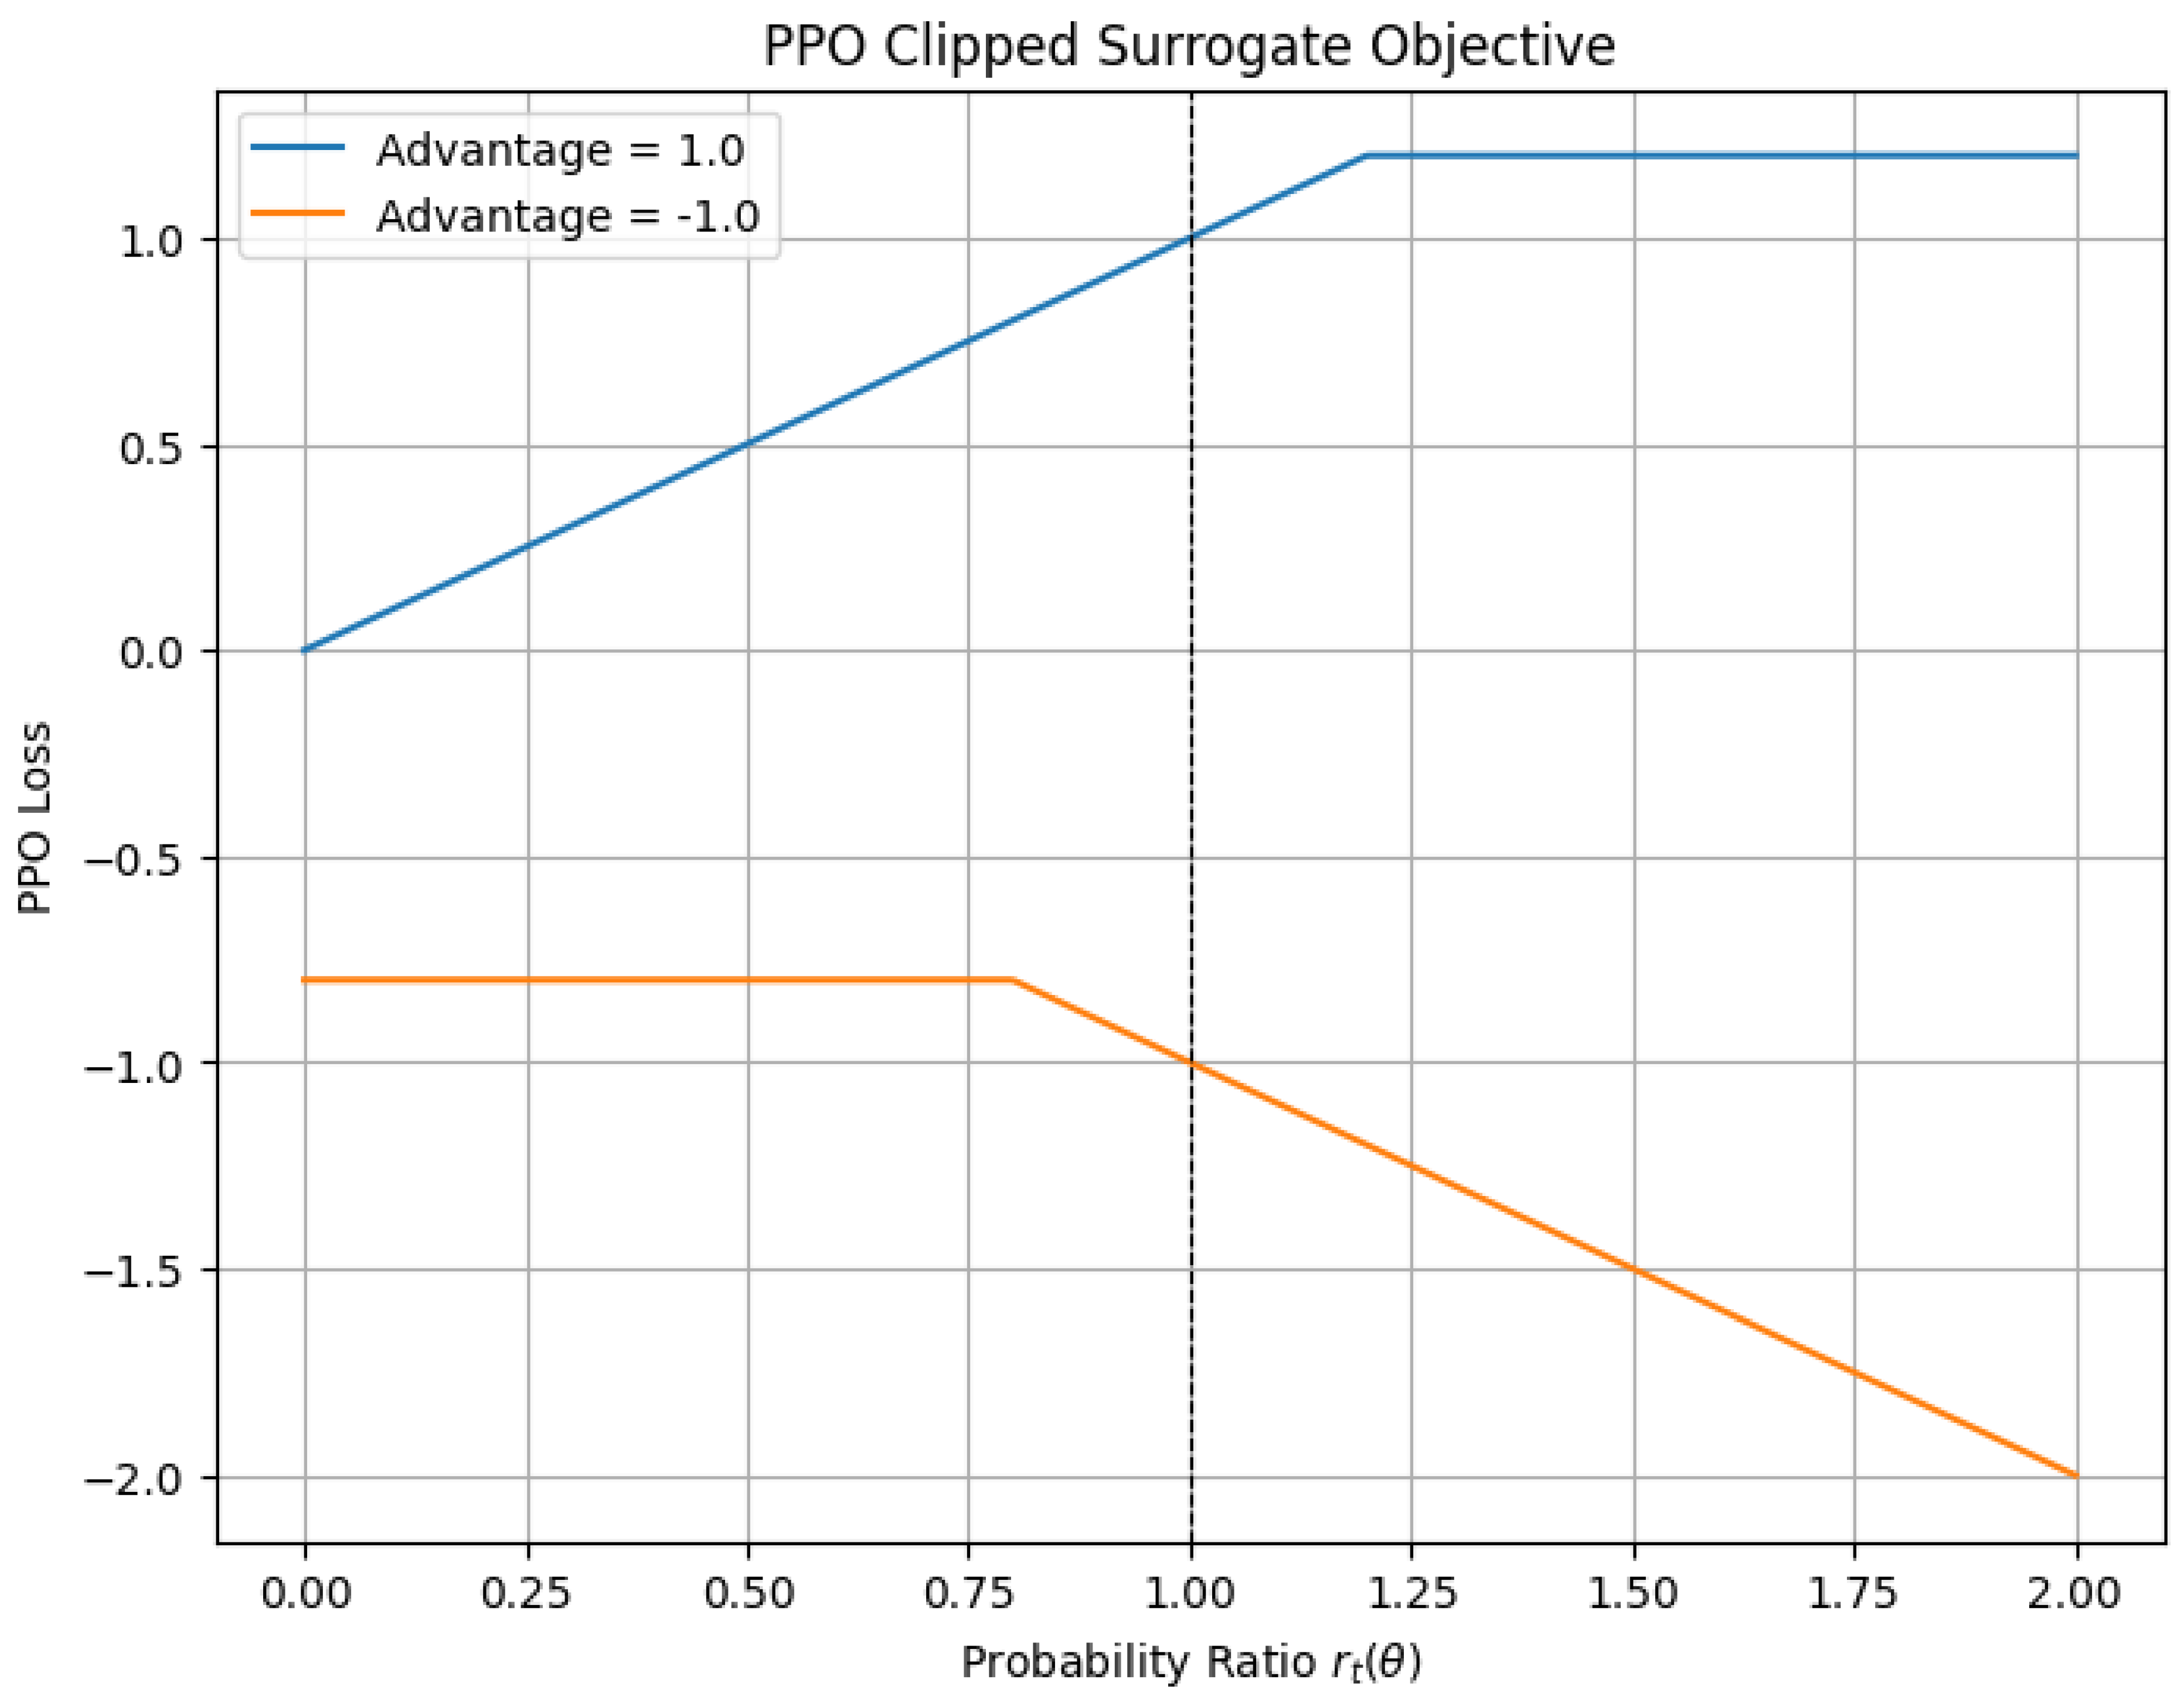
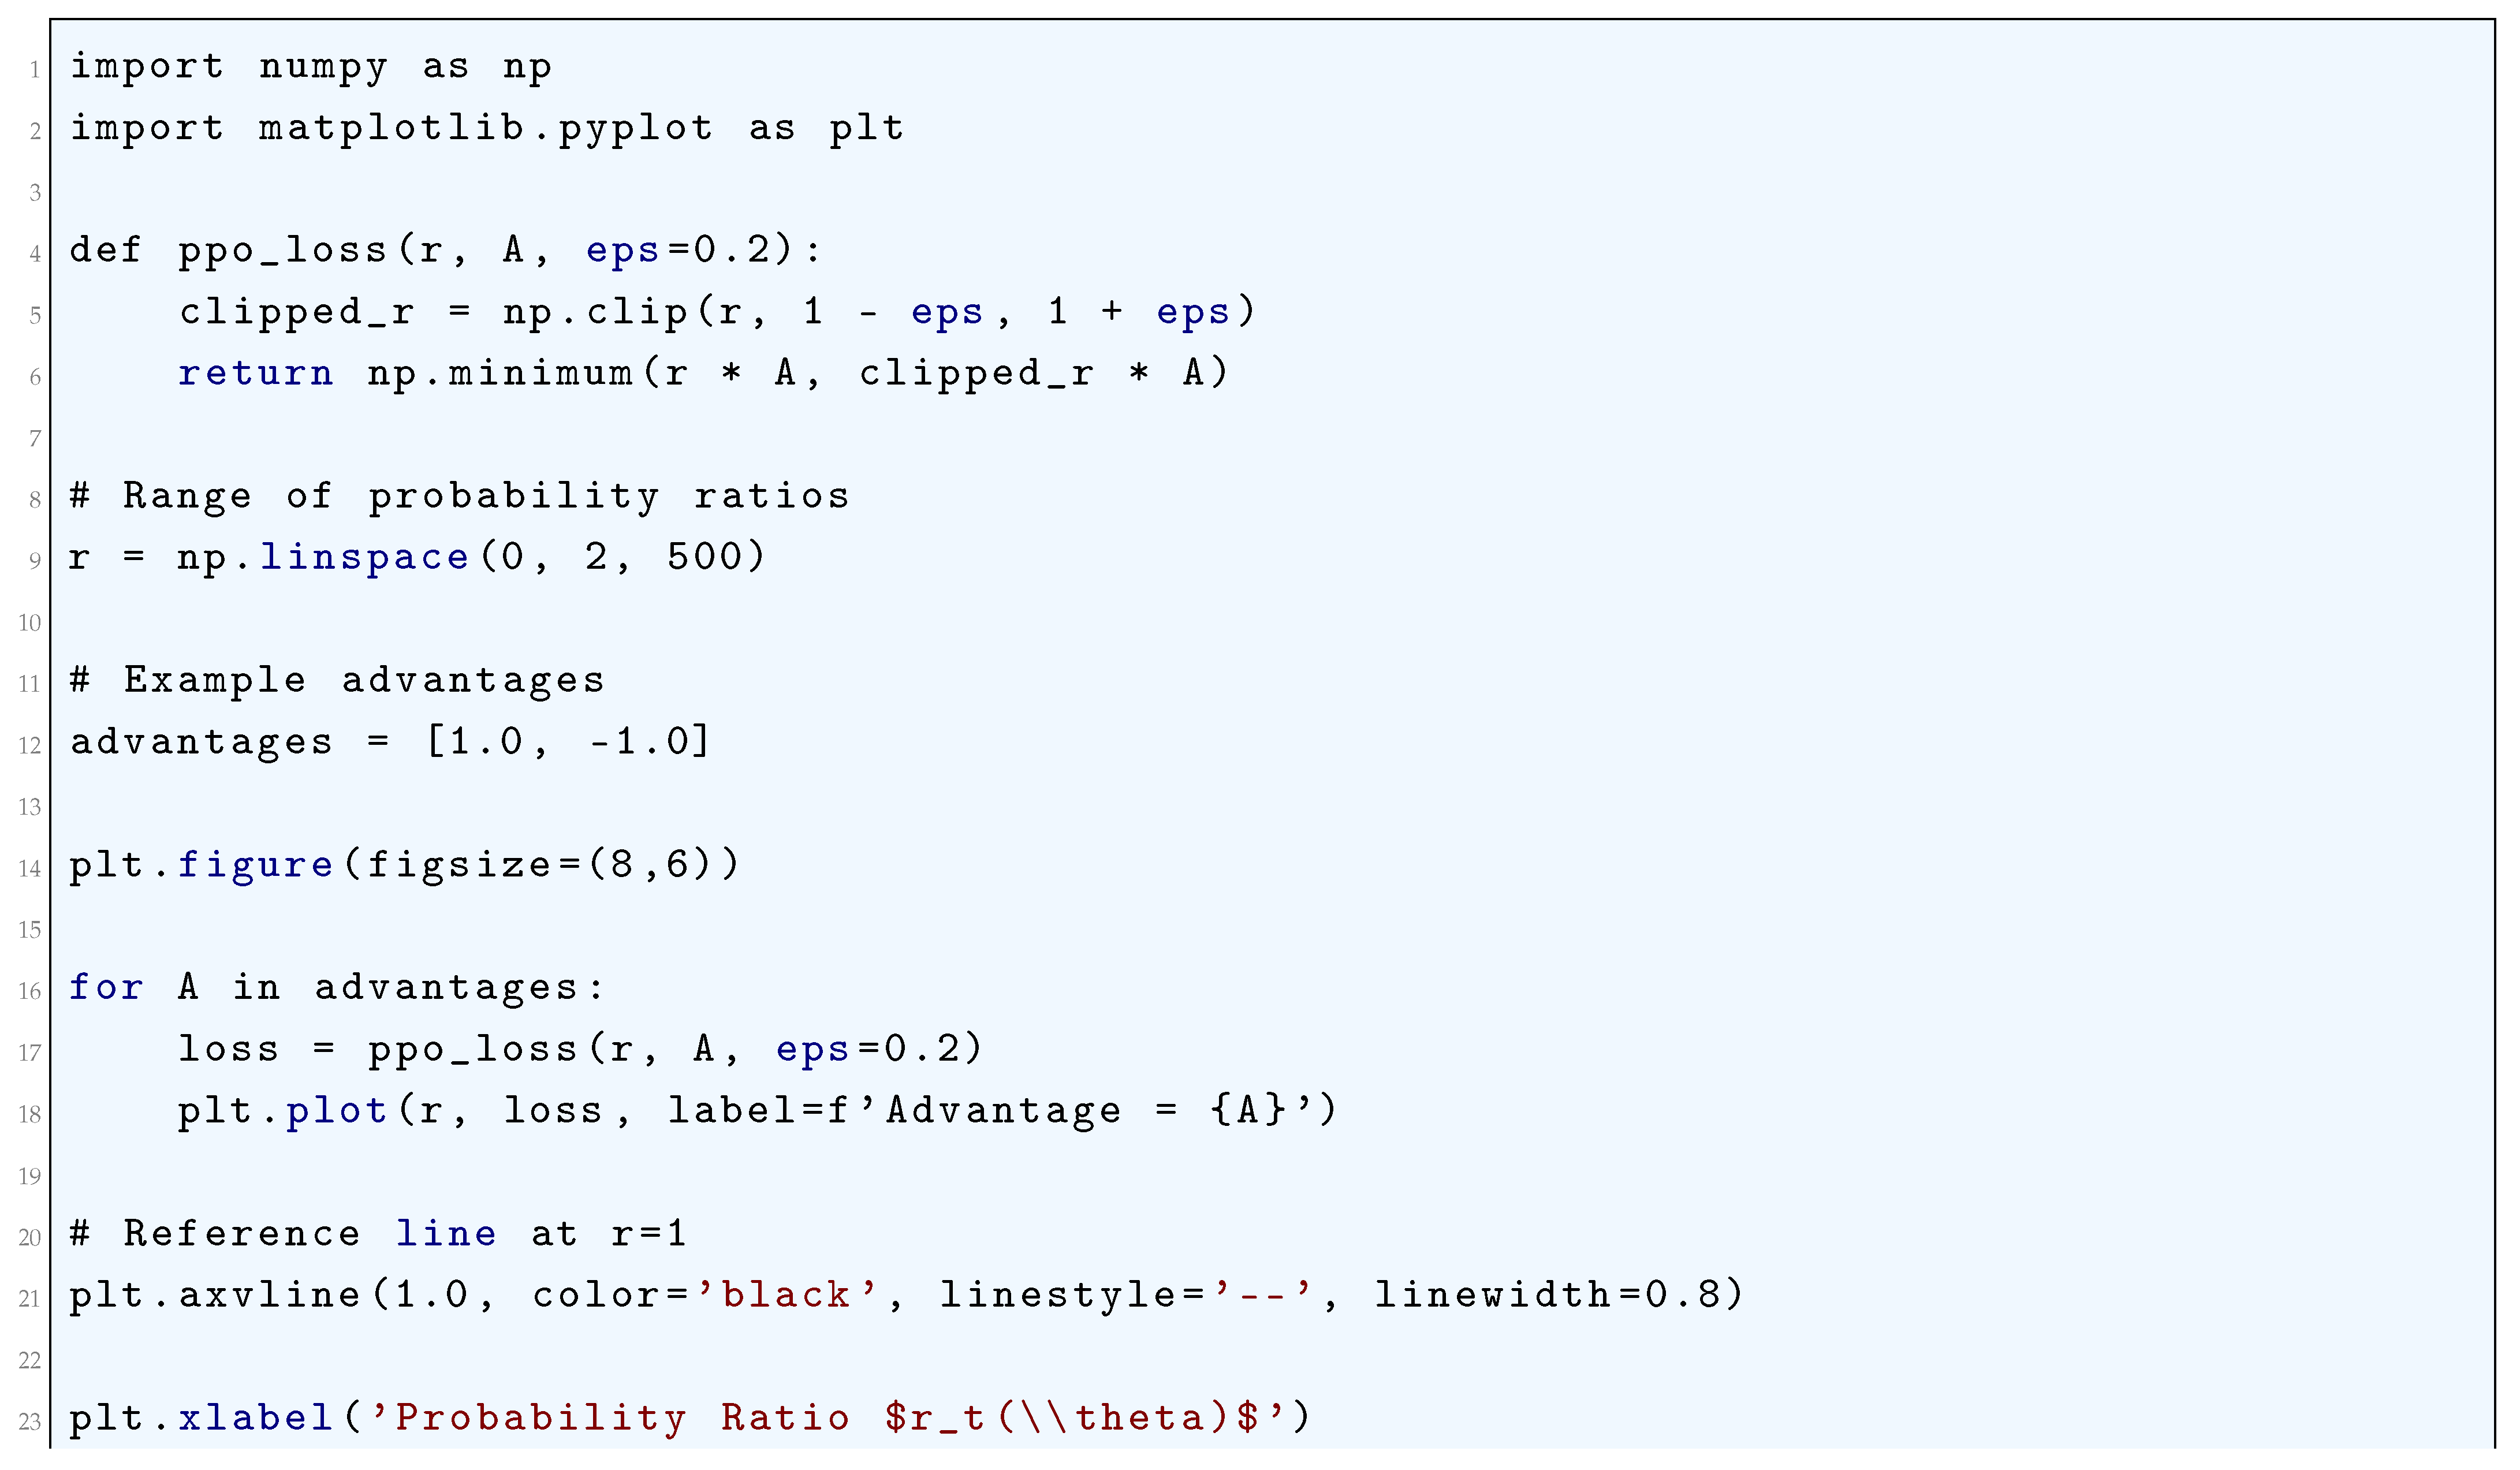
10.5.3.44 Python Code to Generate Figure 111 Illustrating PPO Loss Comparison
The Python code below produces the Figure 111 illustrating PPO Loss Comparison.
Figure 111.
PPO Loss Comparison
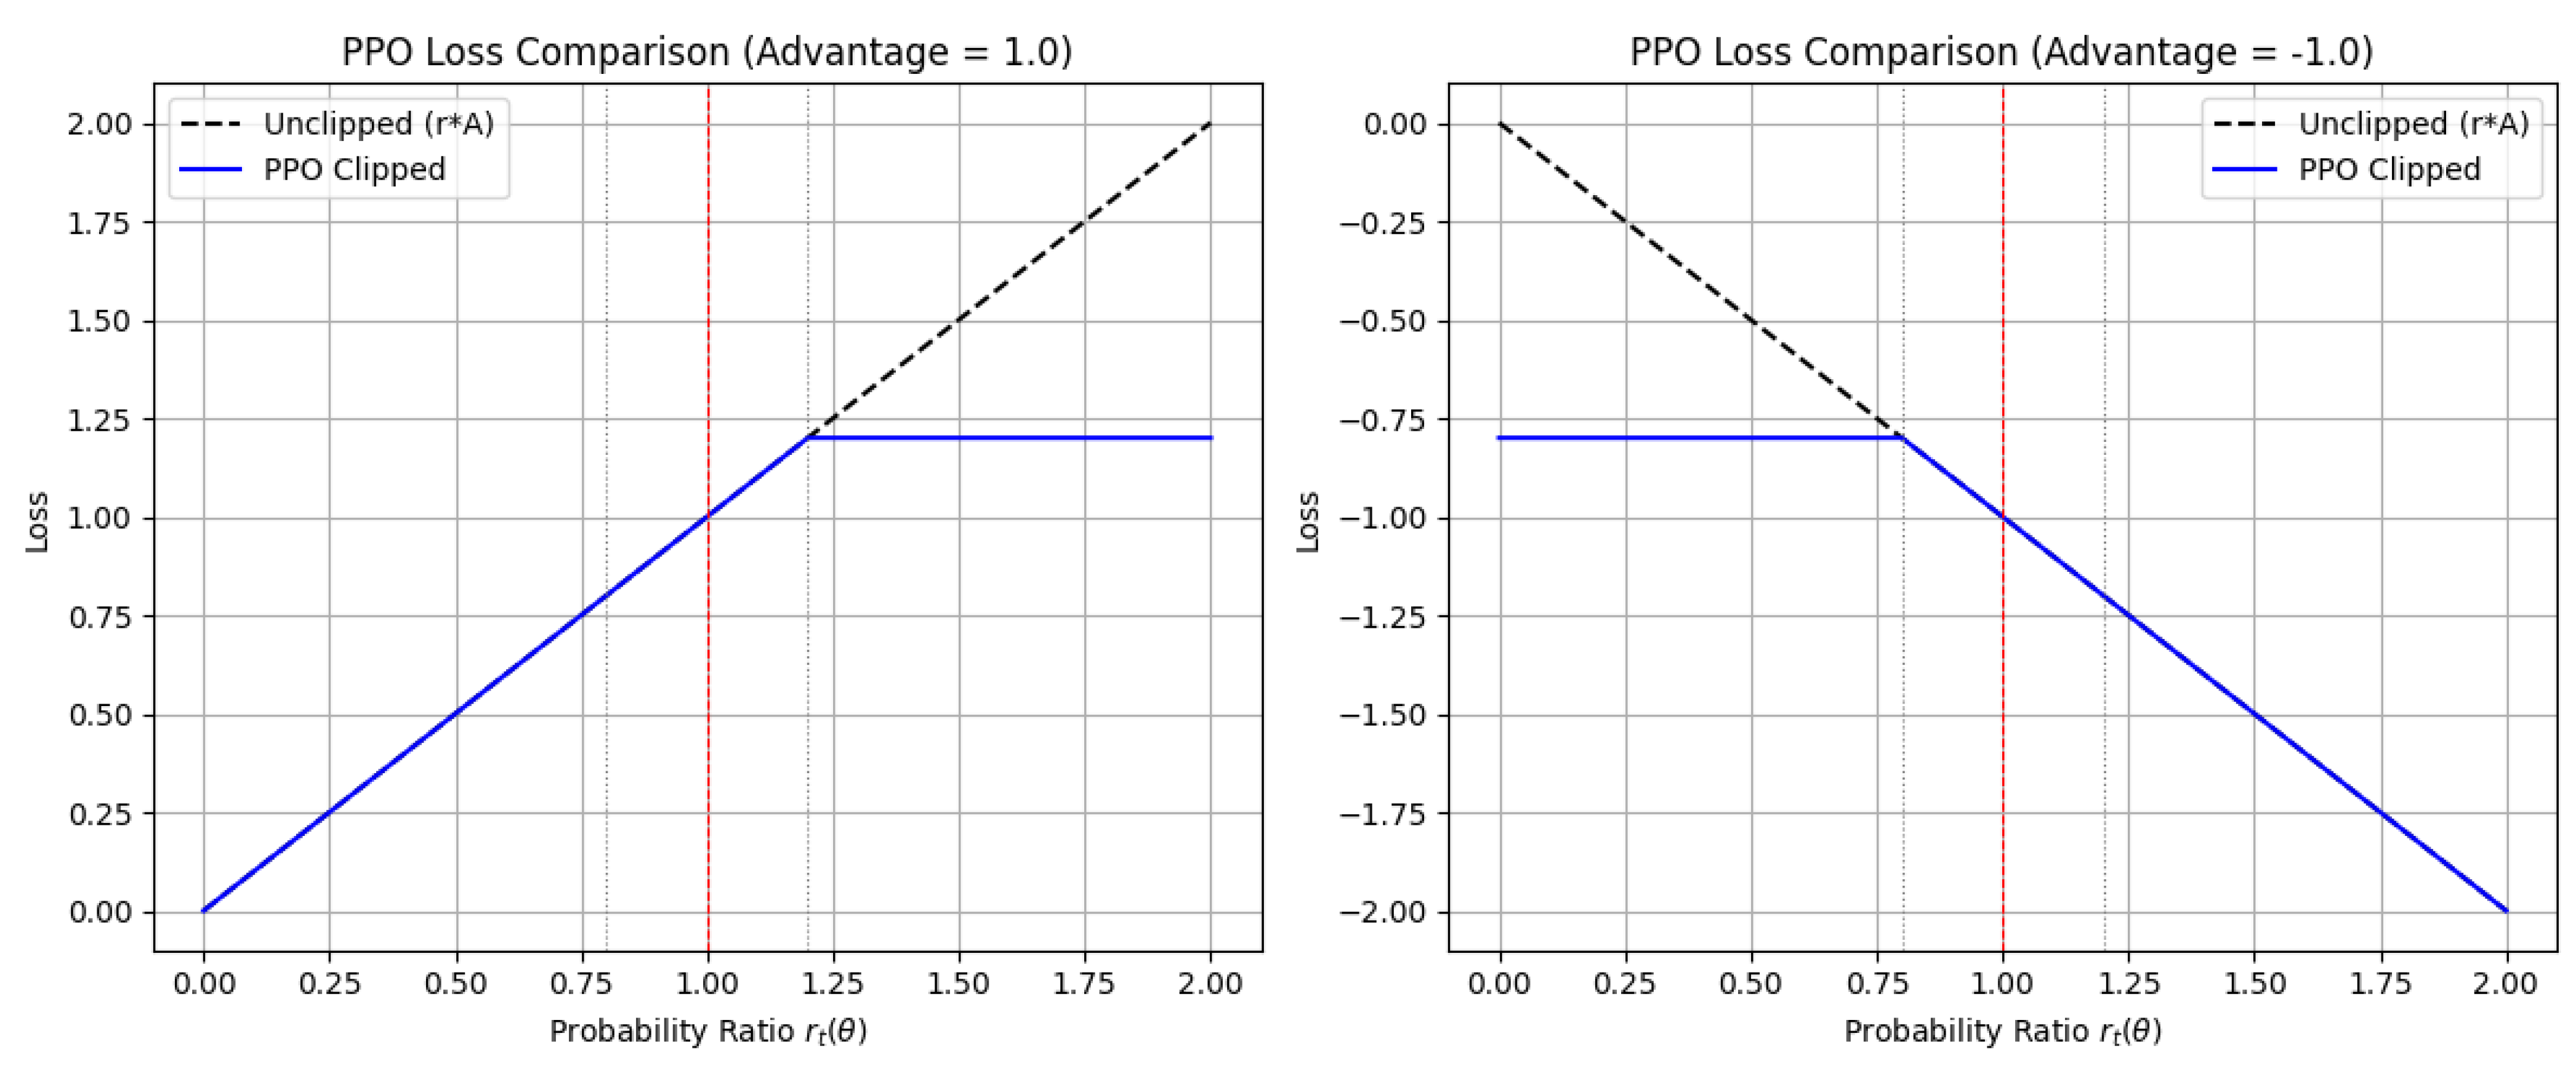
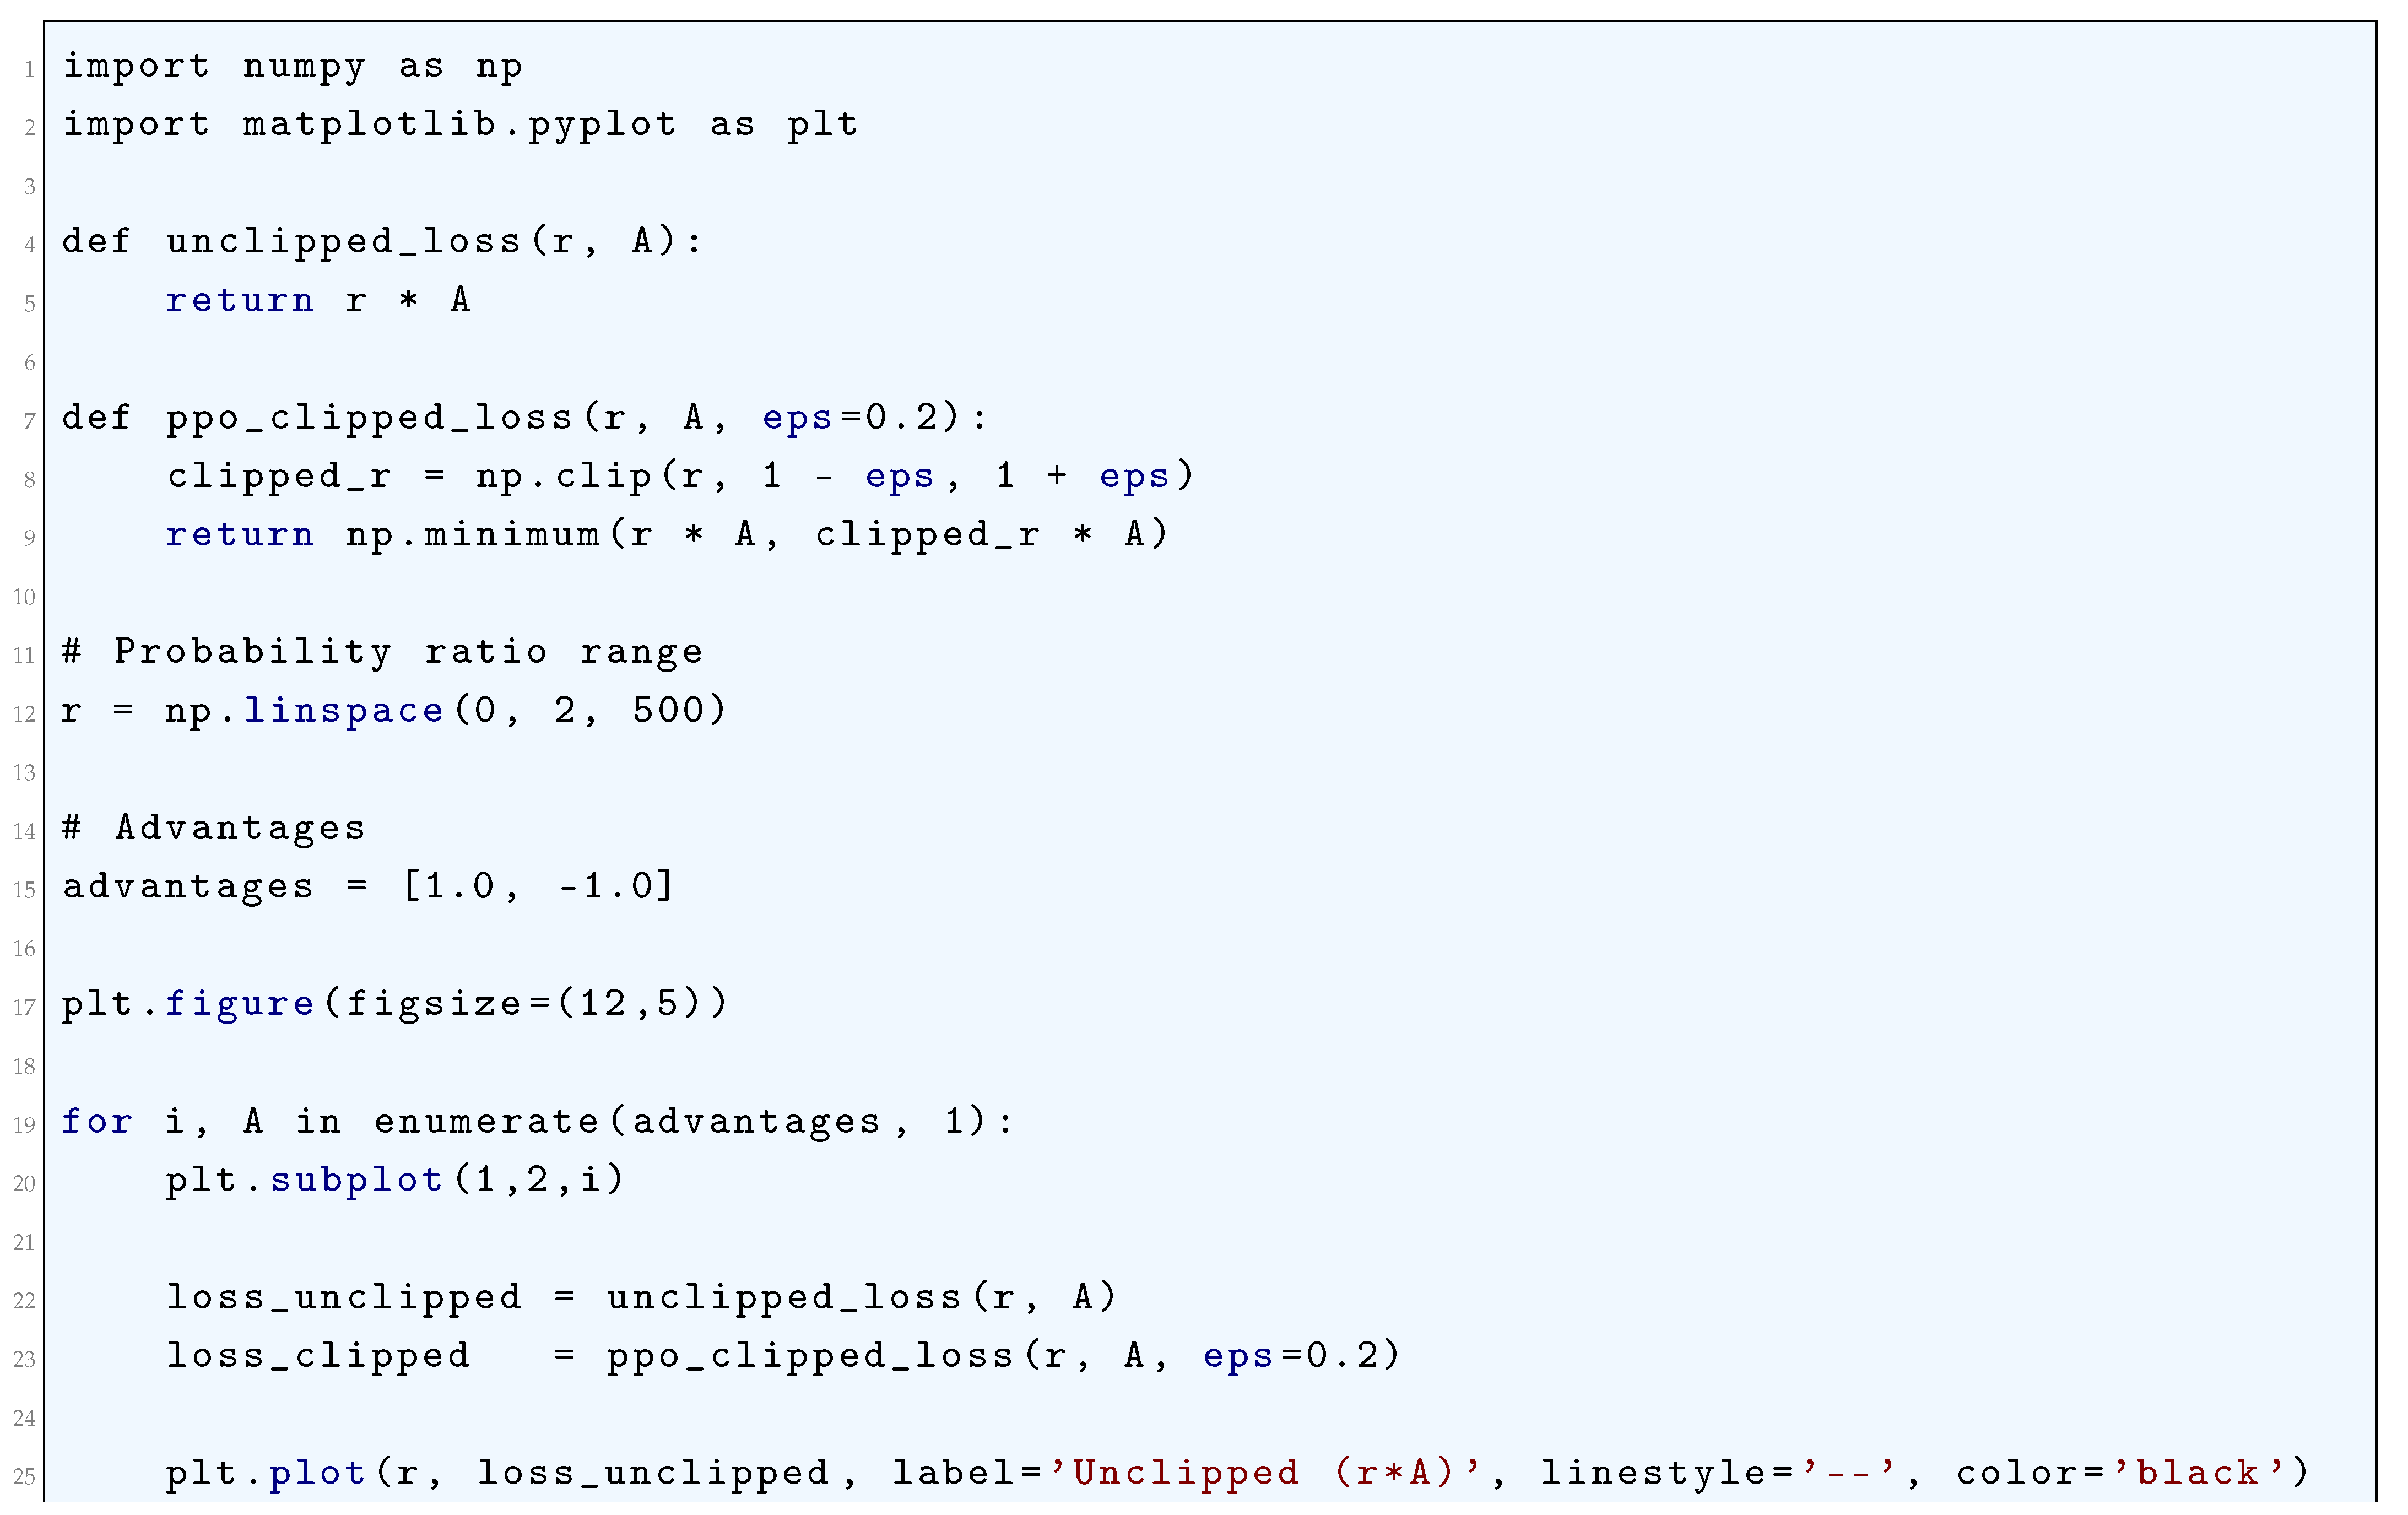
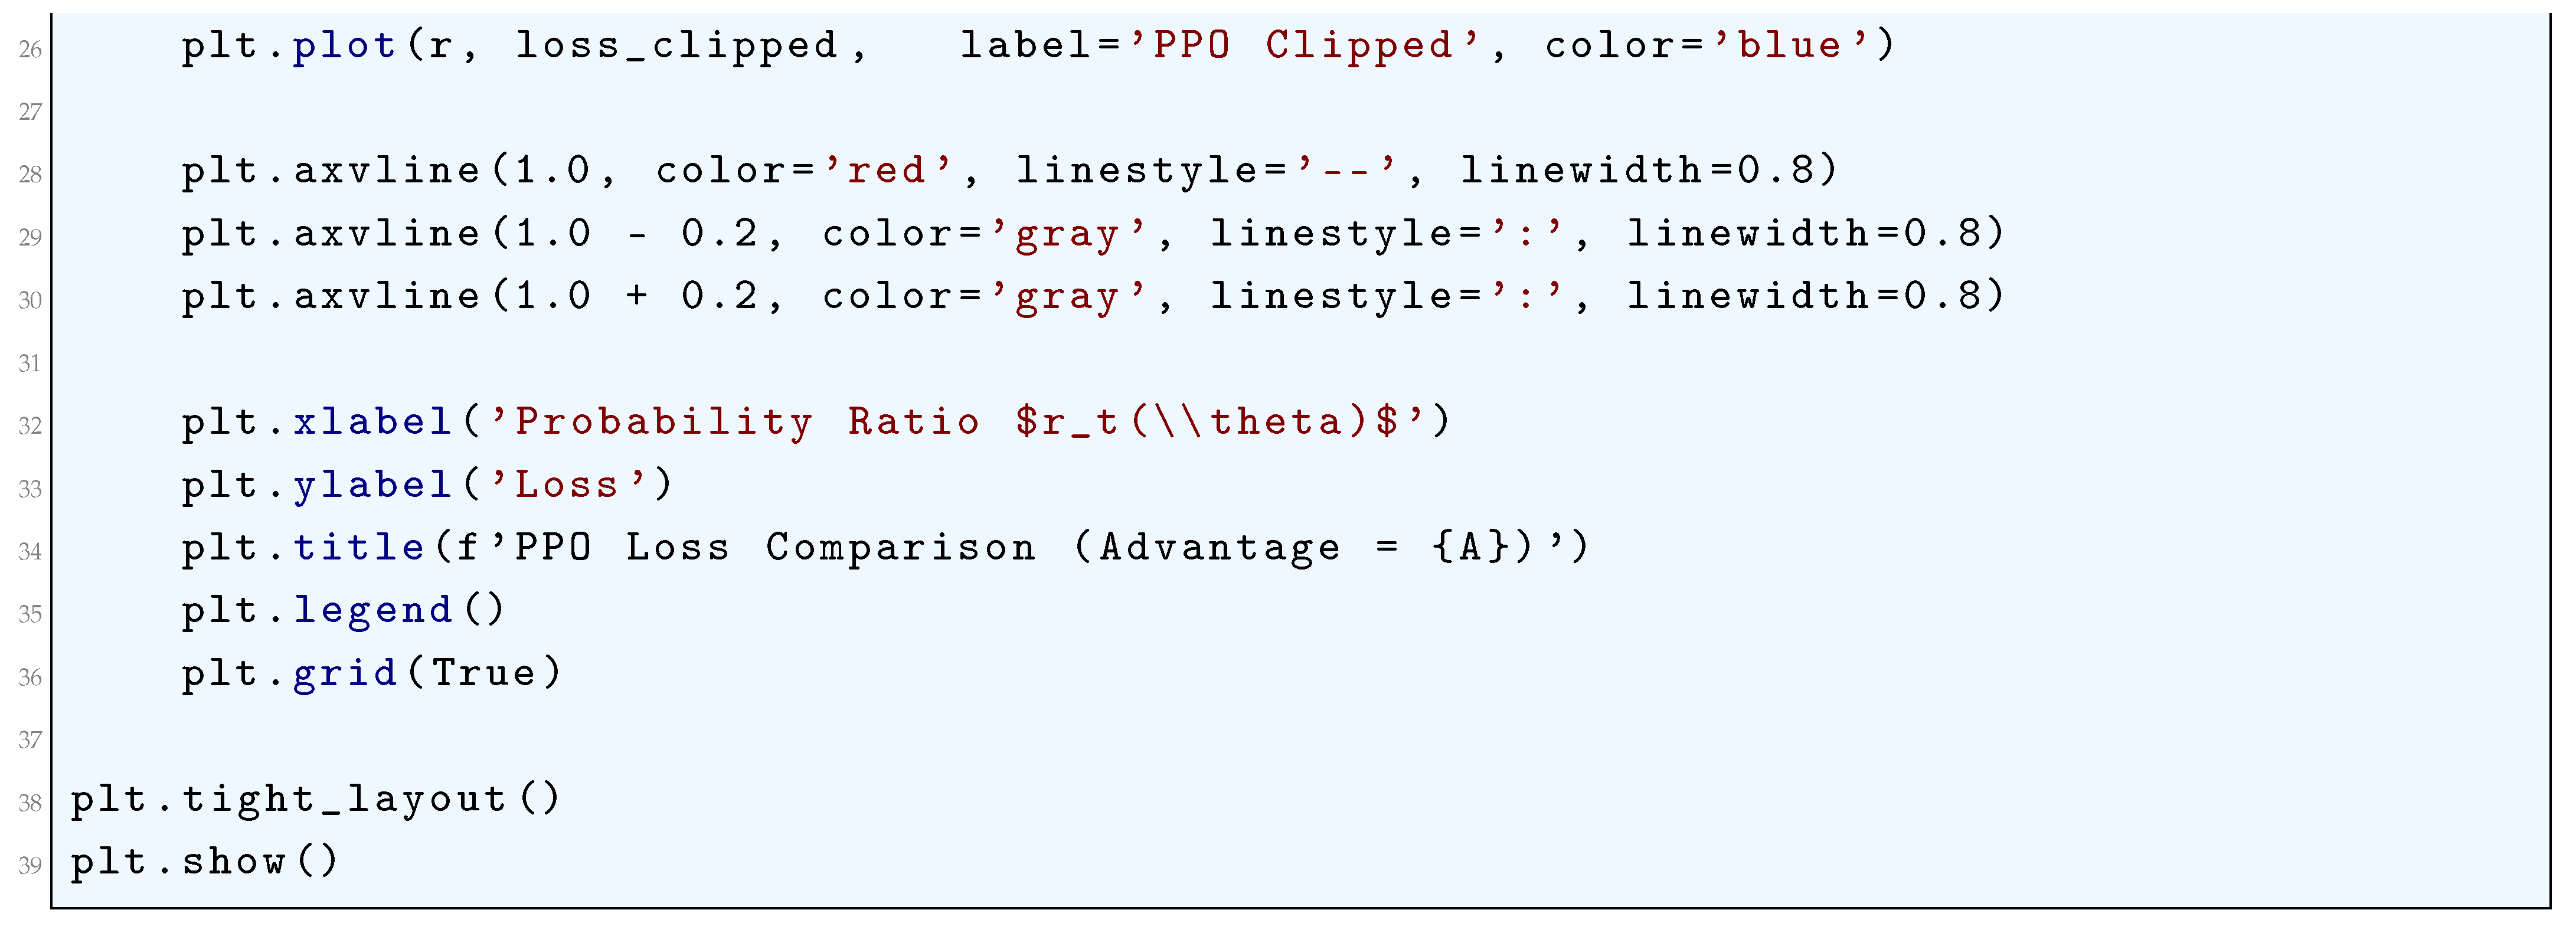
10.5.3.45 Python Code to Generate Figure 112 Illustrating PPO Clipped Surrogate Loss with Entropy Regularization
The Python code below produces the Figure 112 illustrating PPO Clipped Surrogate Loss with Entropy Regularization.
Figure 112.
PPO Clipped Surrogate Loss with Entropy Regularization
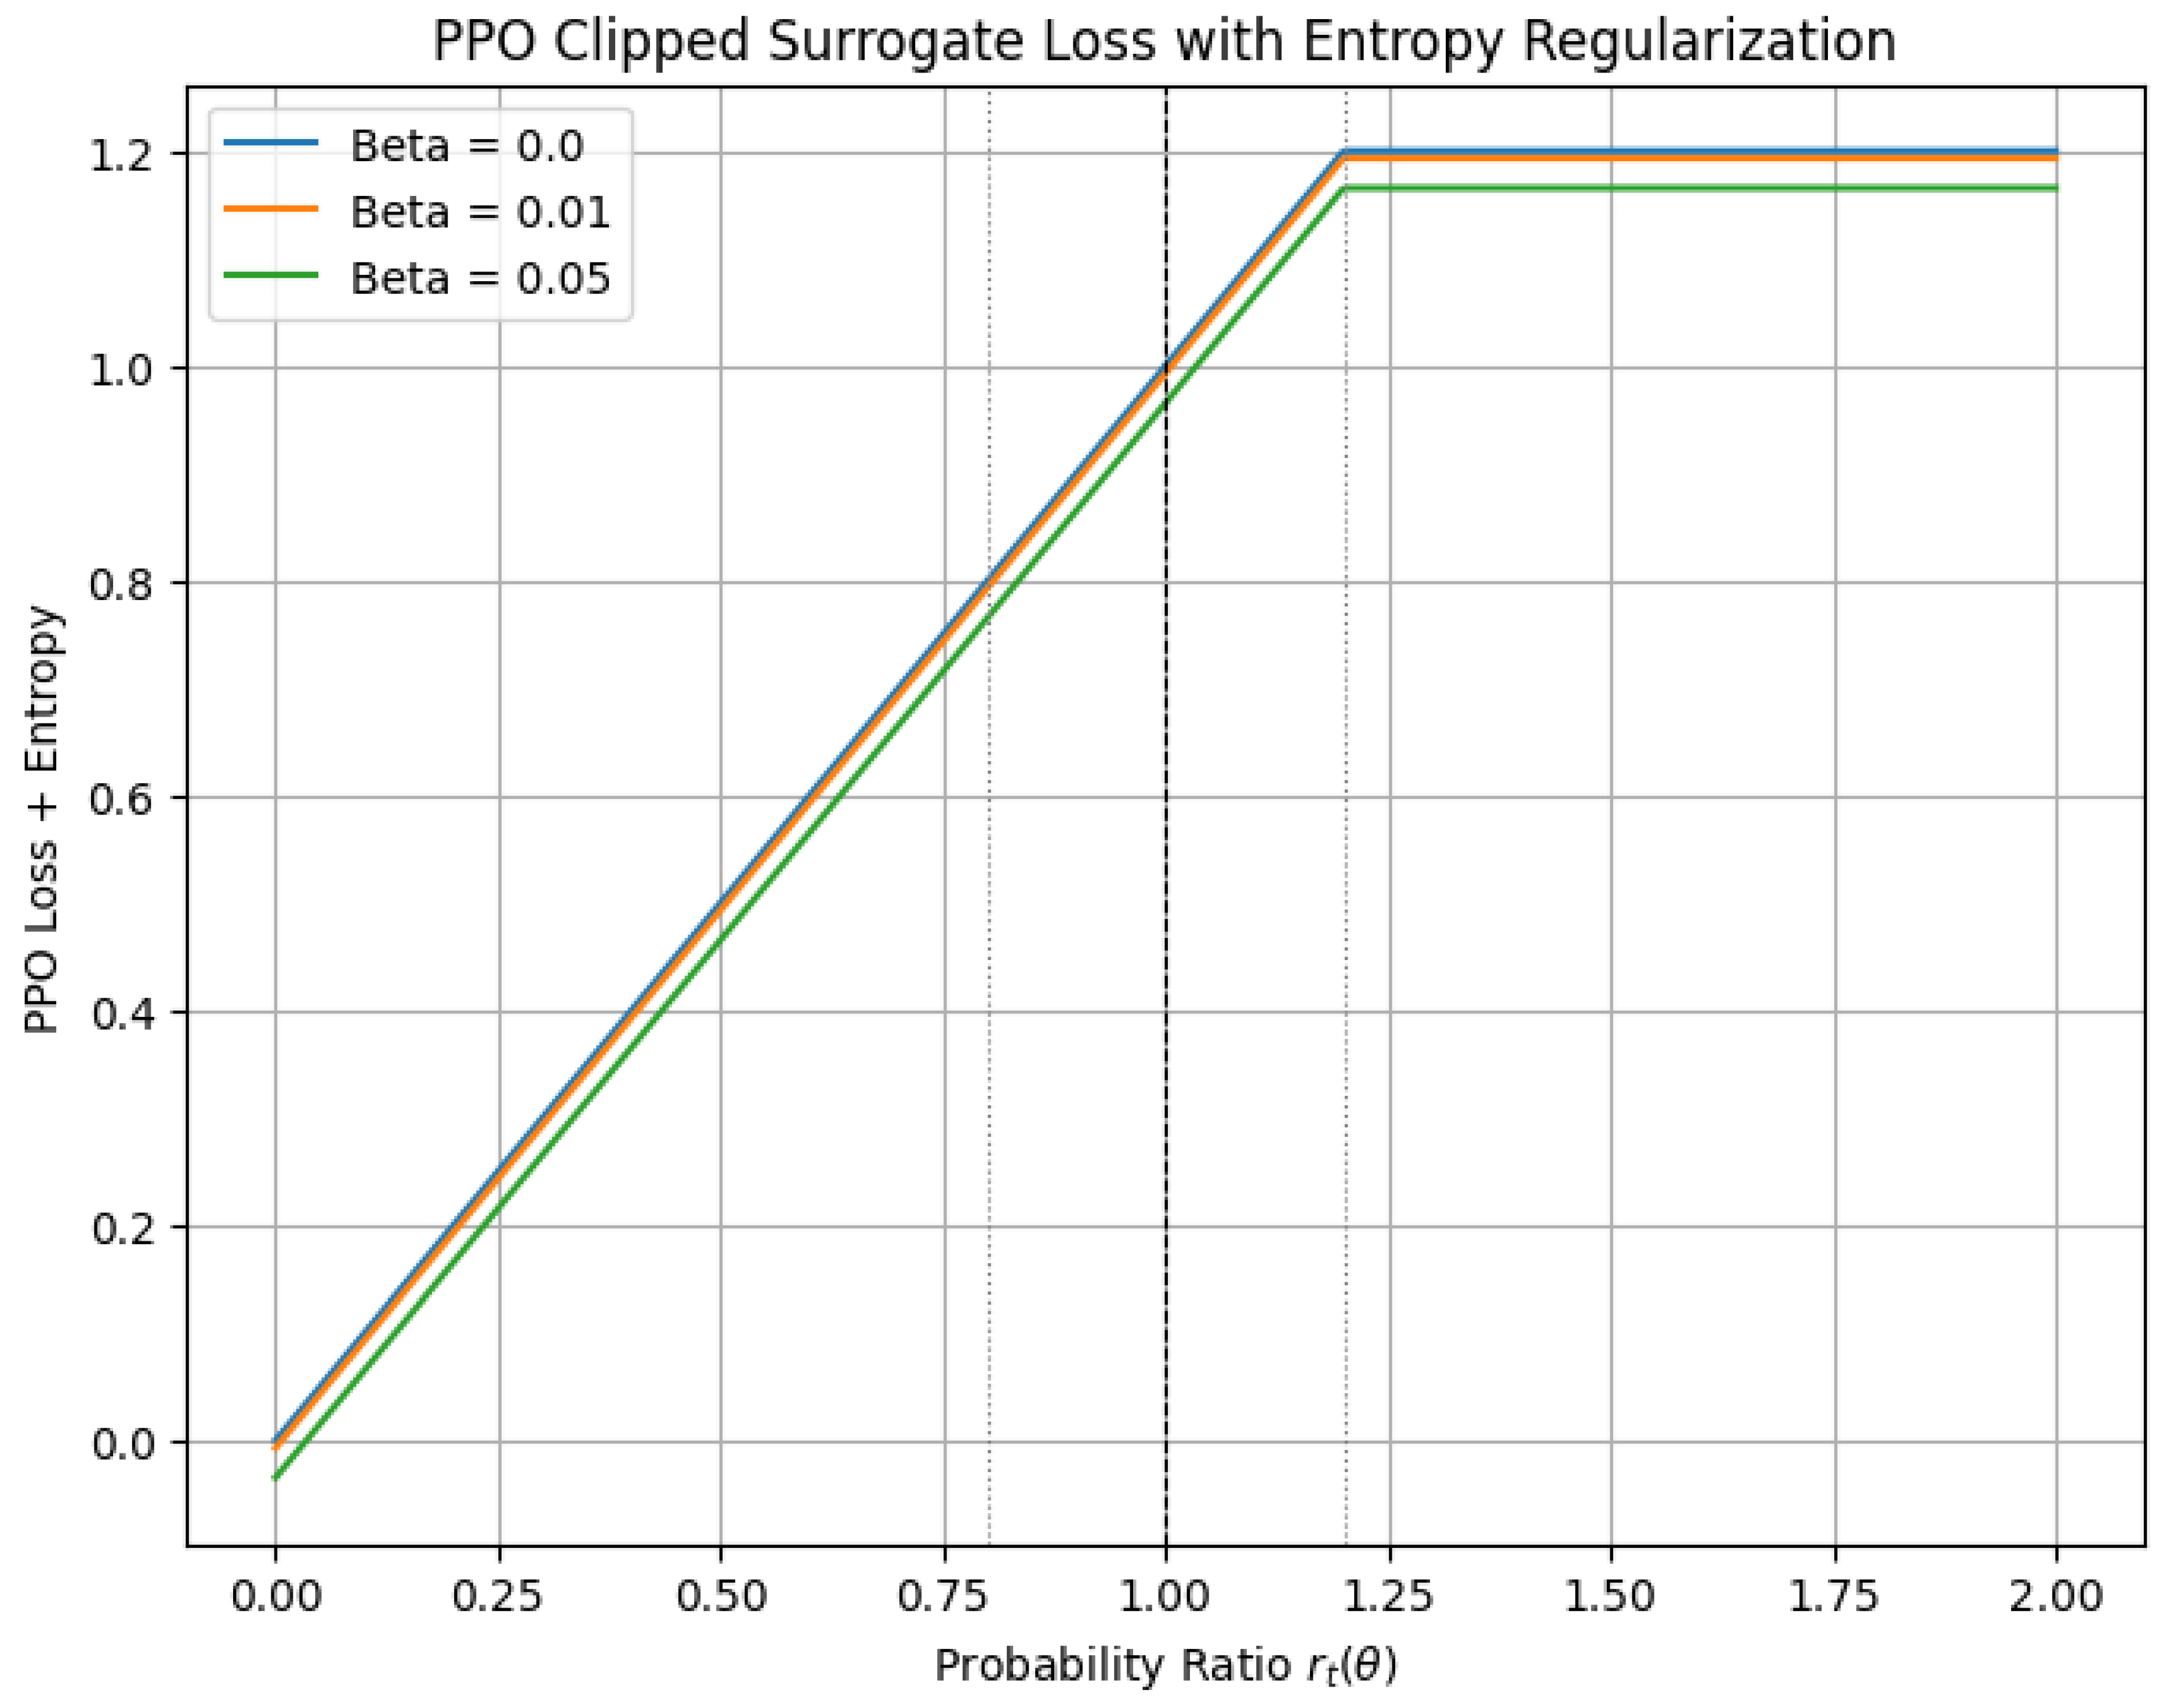
10.5.3.46 Python Code to Generate Figure 113 Comparing PPO Unclipped, PPO Clipped, PPO + Entropy
The Python code below produces the Figure 113 comparing PPO Unclipped, PPO Clipped, PPO + Entropy.
Figure 113.
Comparison: PPO Unclipped, PPO Clipped, PPO + Entropy
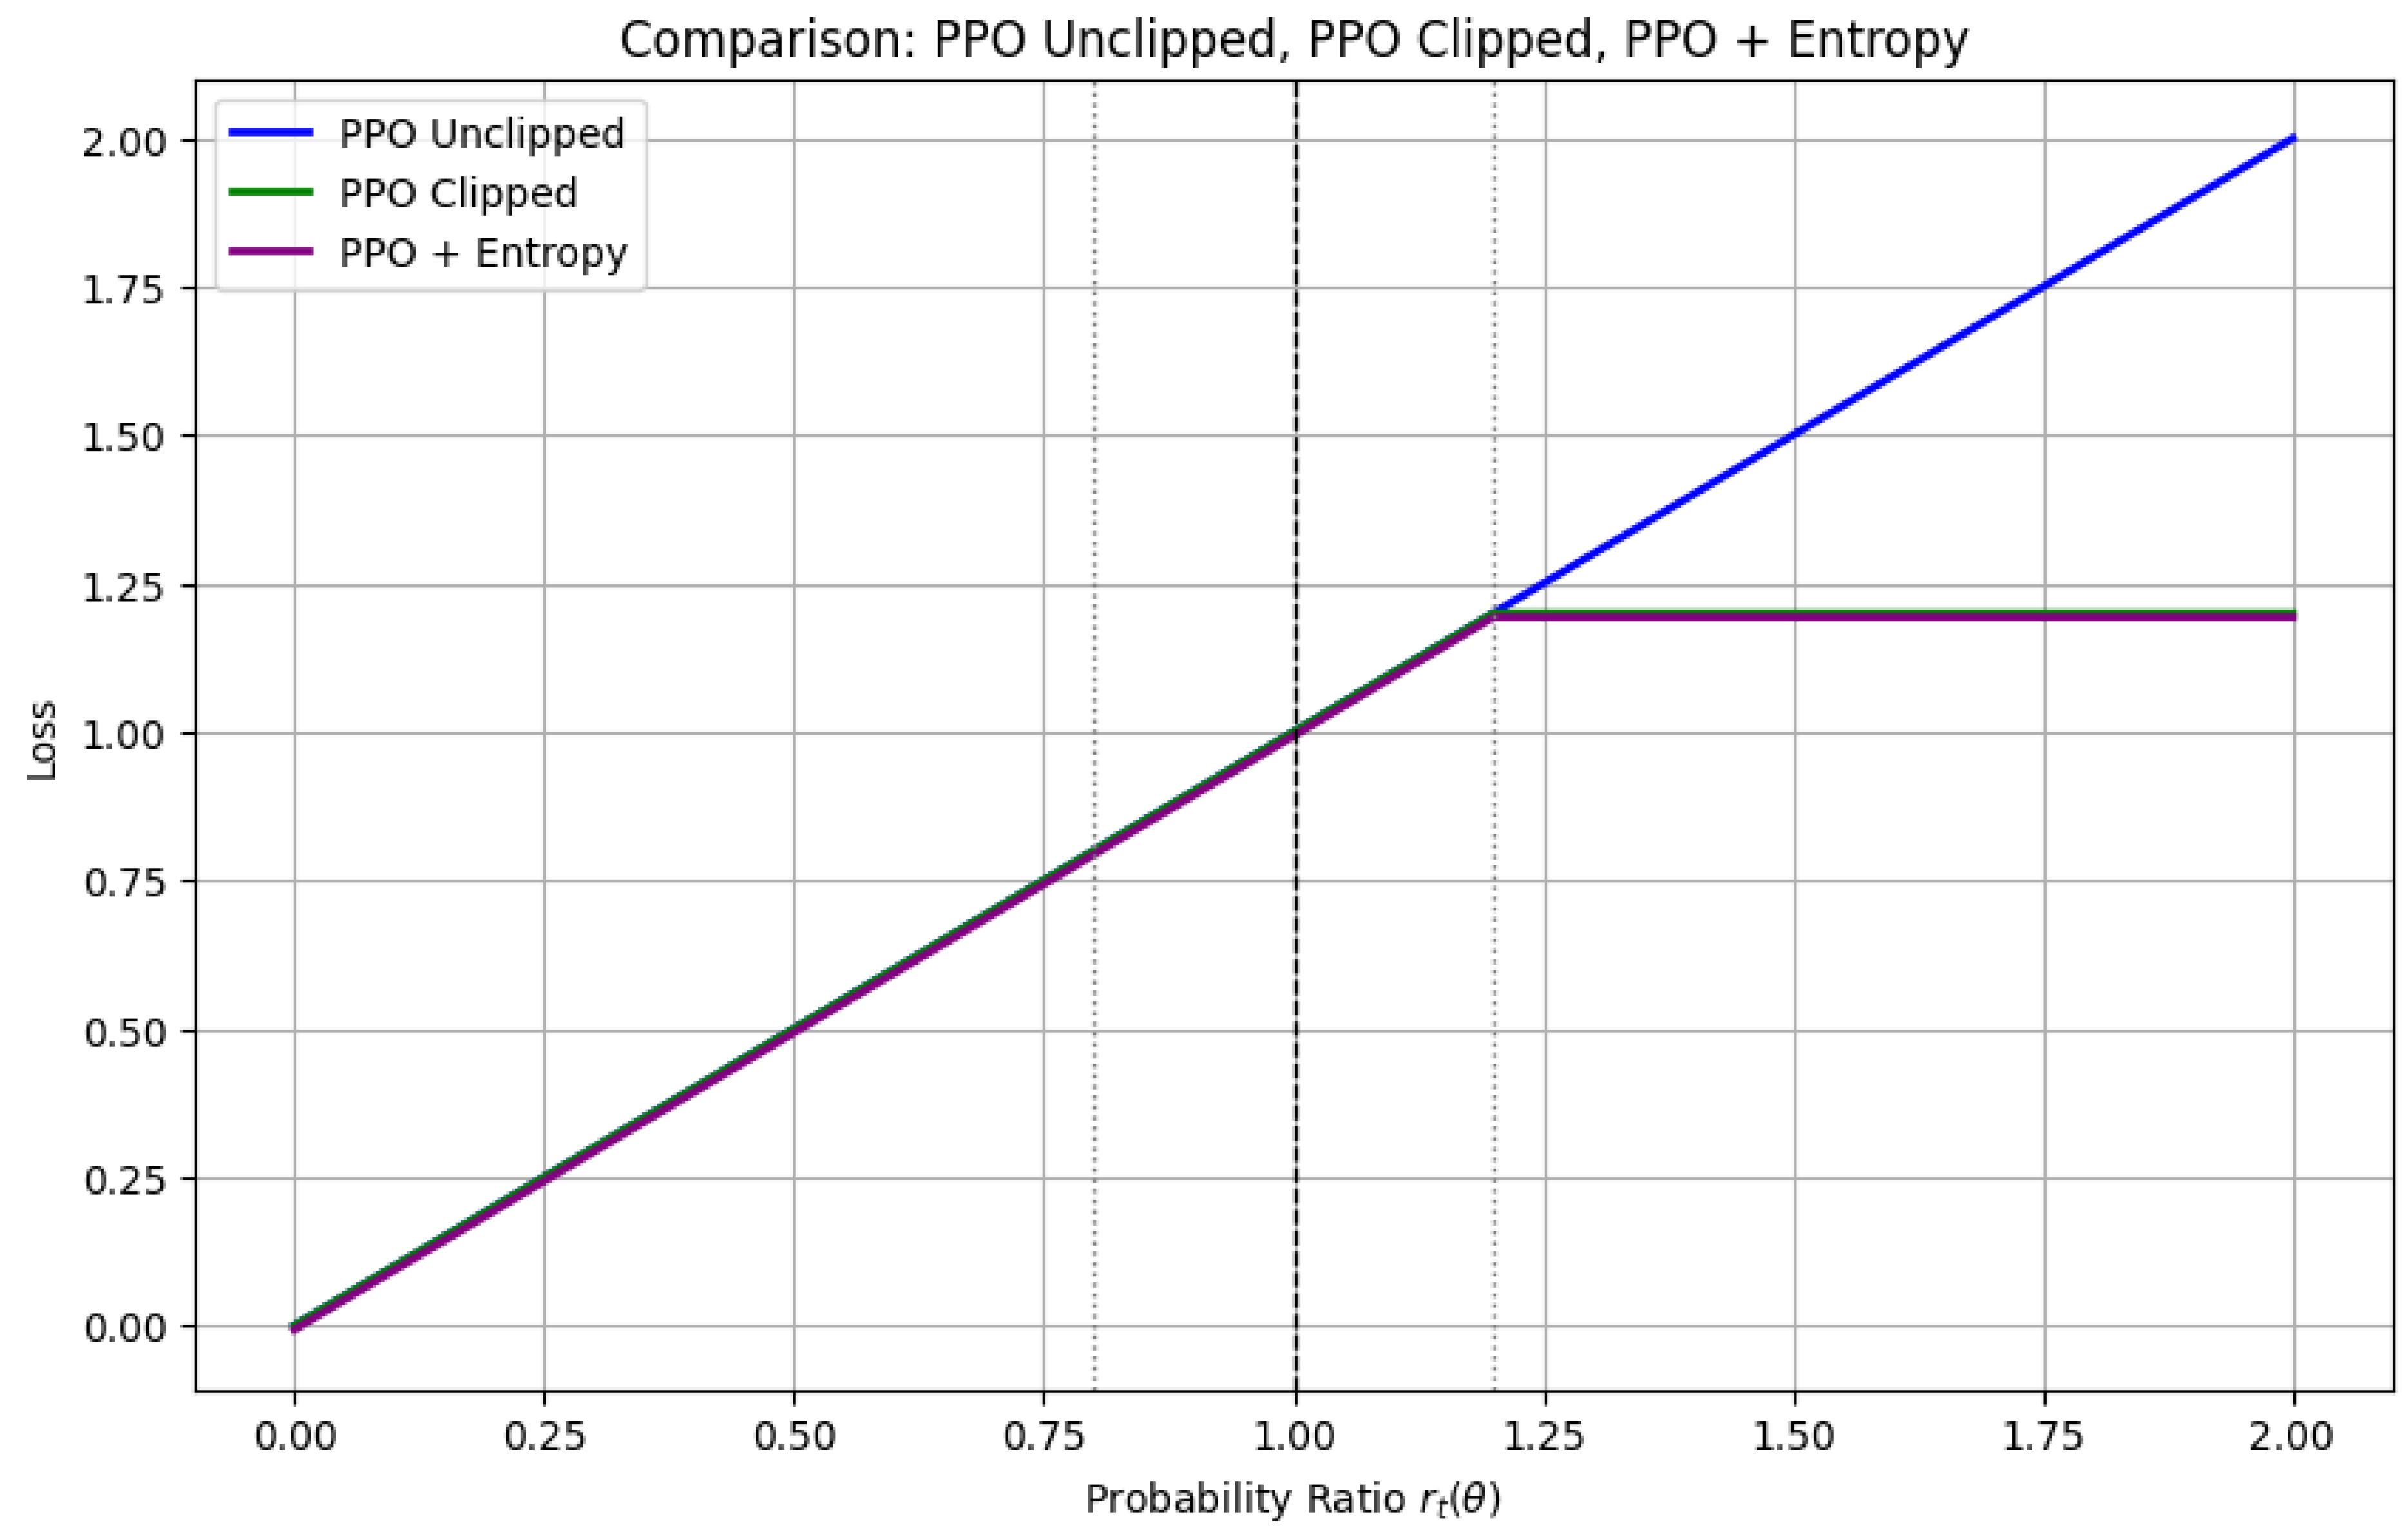
10.5.3.47 Python Code to Generate Figure 114 Illustrating Soft Actor-Critic (SAC) Policy Loss with Entropy Regularization
The Python code below produces the Figure 114 illustrating Soft Actor-Critic (SAC) Policy Loss with Entropy Regularization.
Figure 114.
Soft Actor-Critic (SAC) Policy Loss with Entropy Regularization
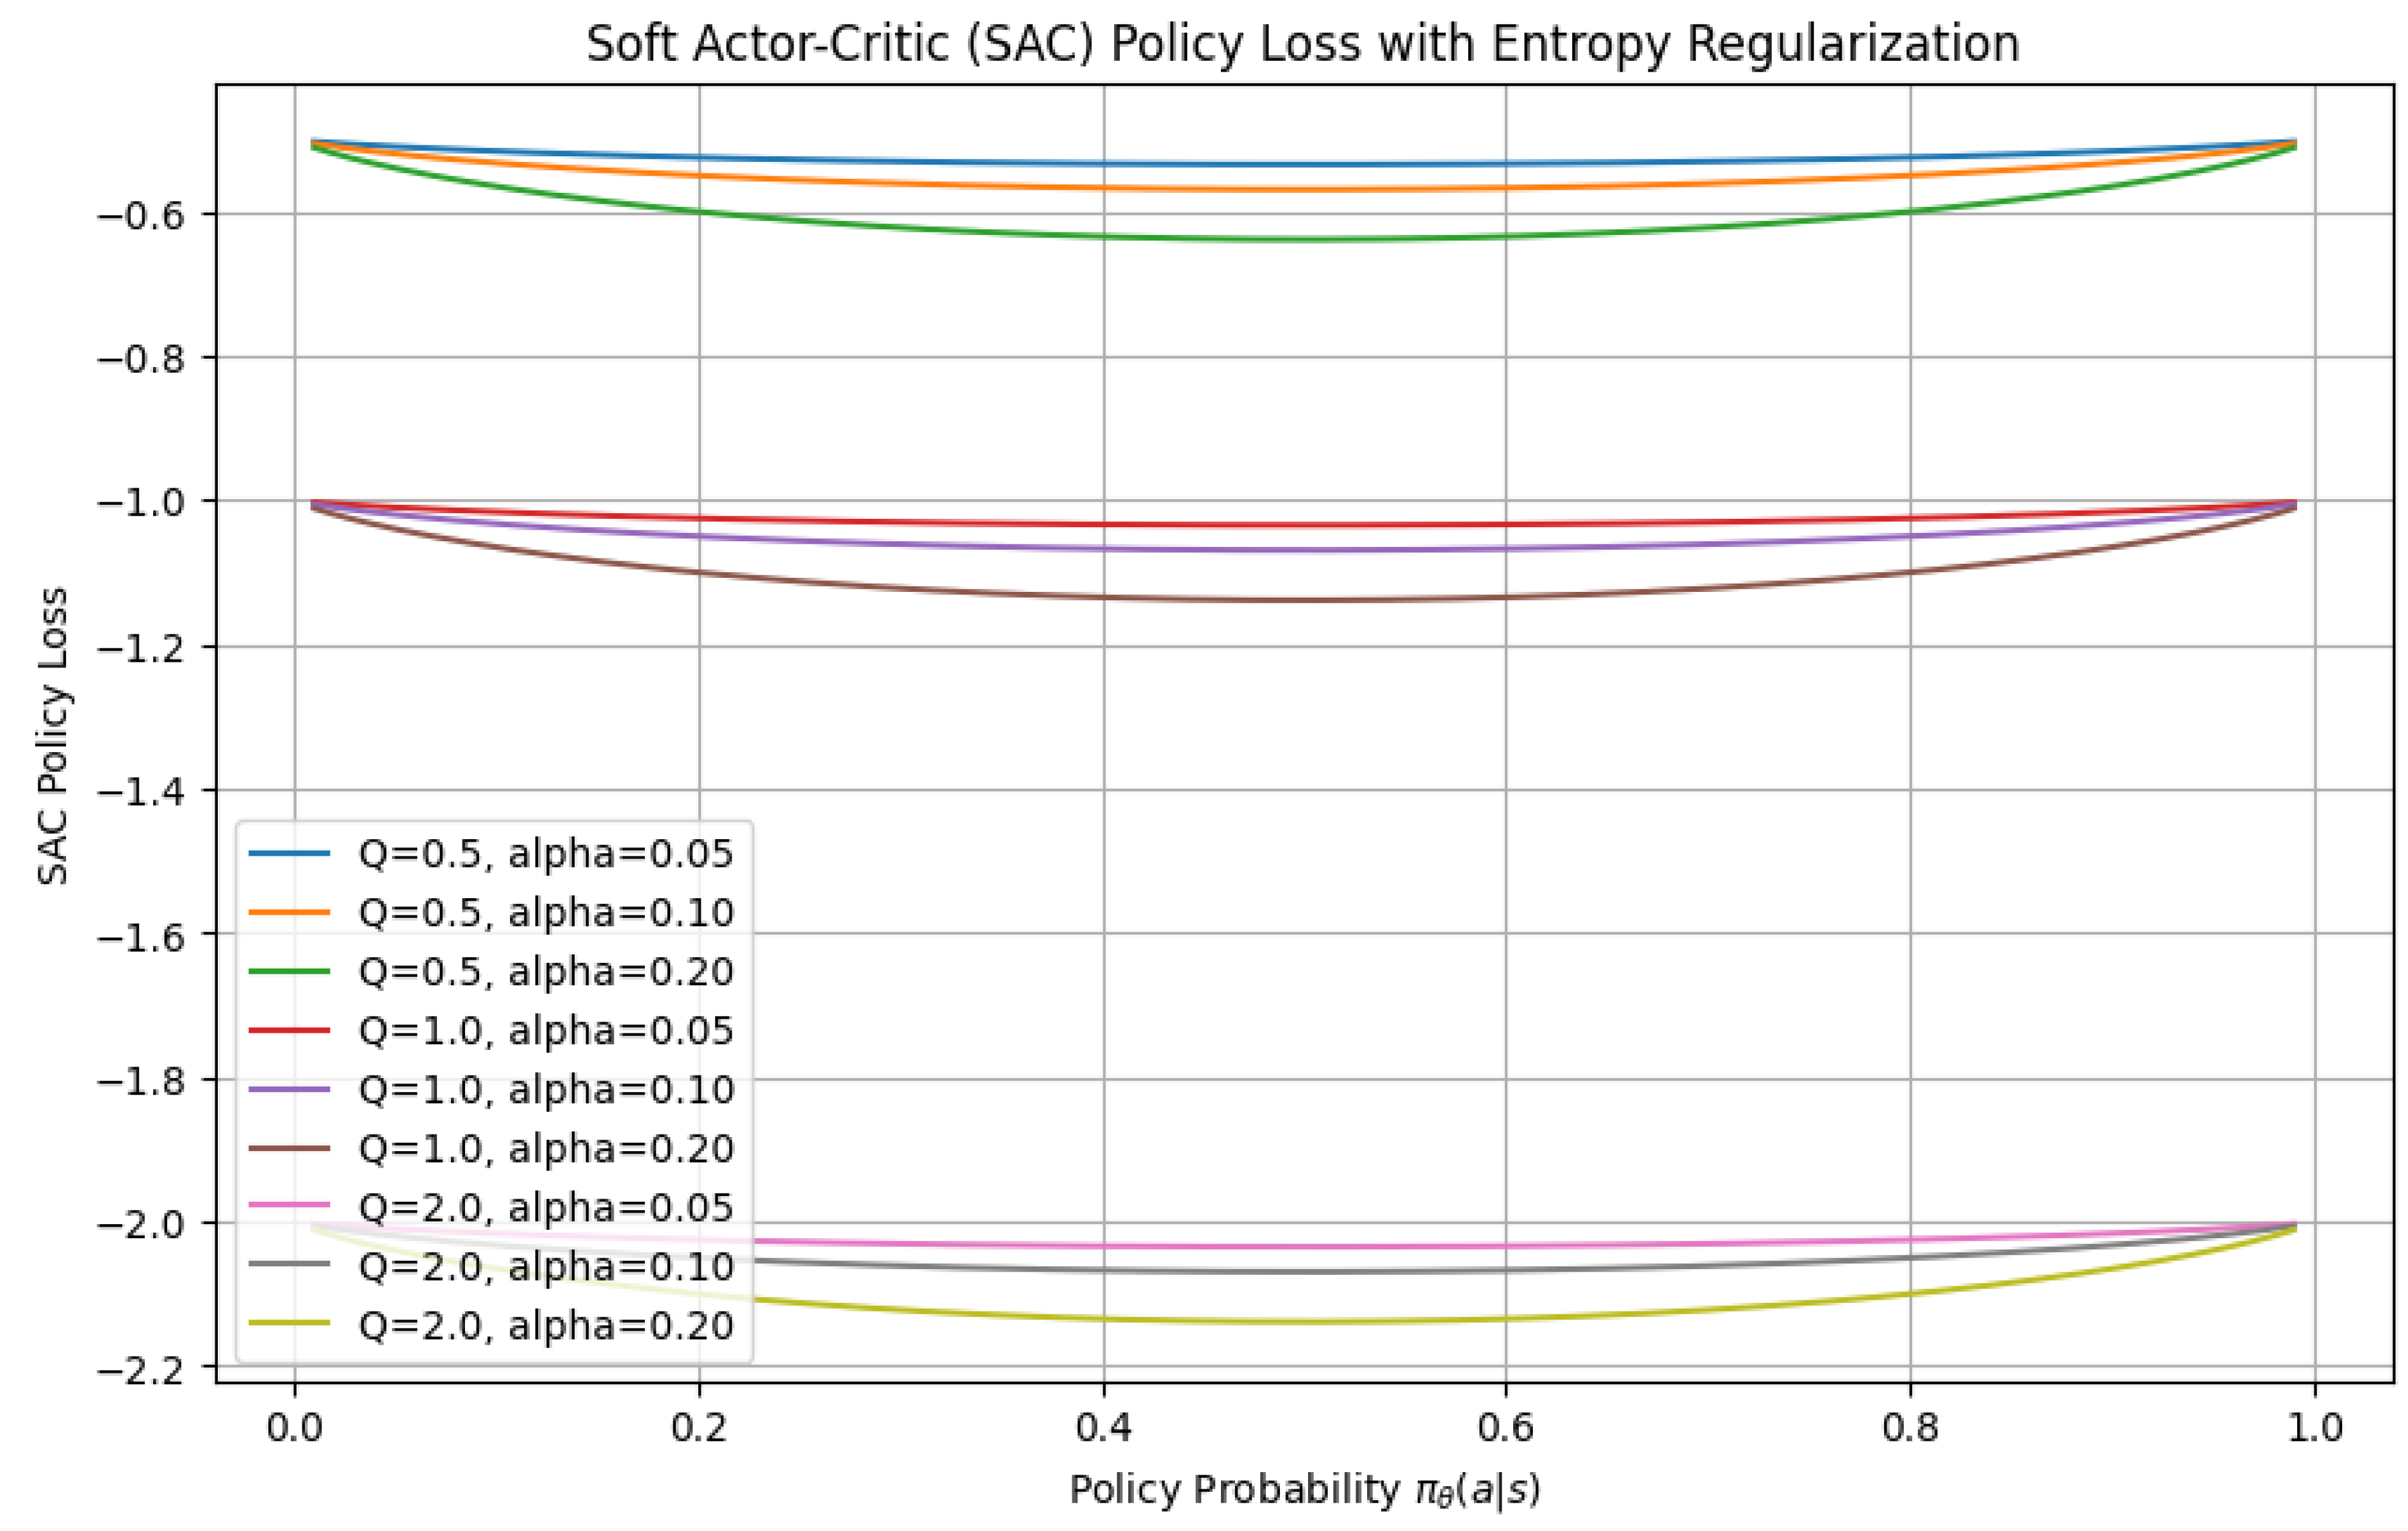
10.5.3.48 Python Code to Generate Figure 115 Illustrating KL Divergence Loss as Sparsity Constraint
The Python code below produces the Figure 115 illustrating KL Divergence Loss as Sparsity Constraint.
Figure 115.
KL Divergence Loss as Sparsity Constraint
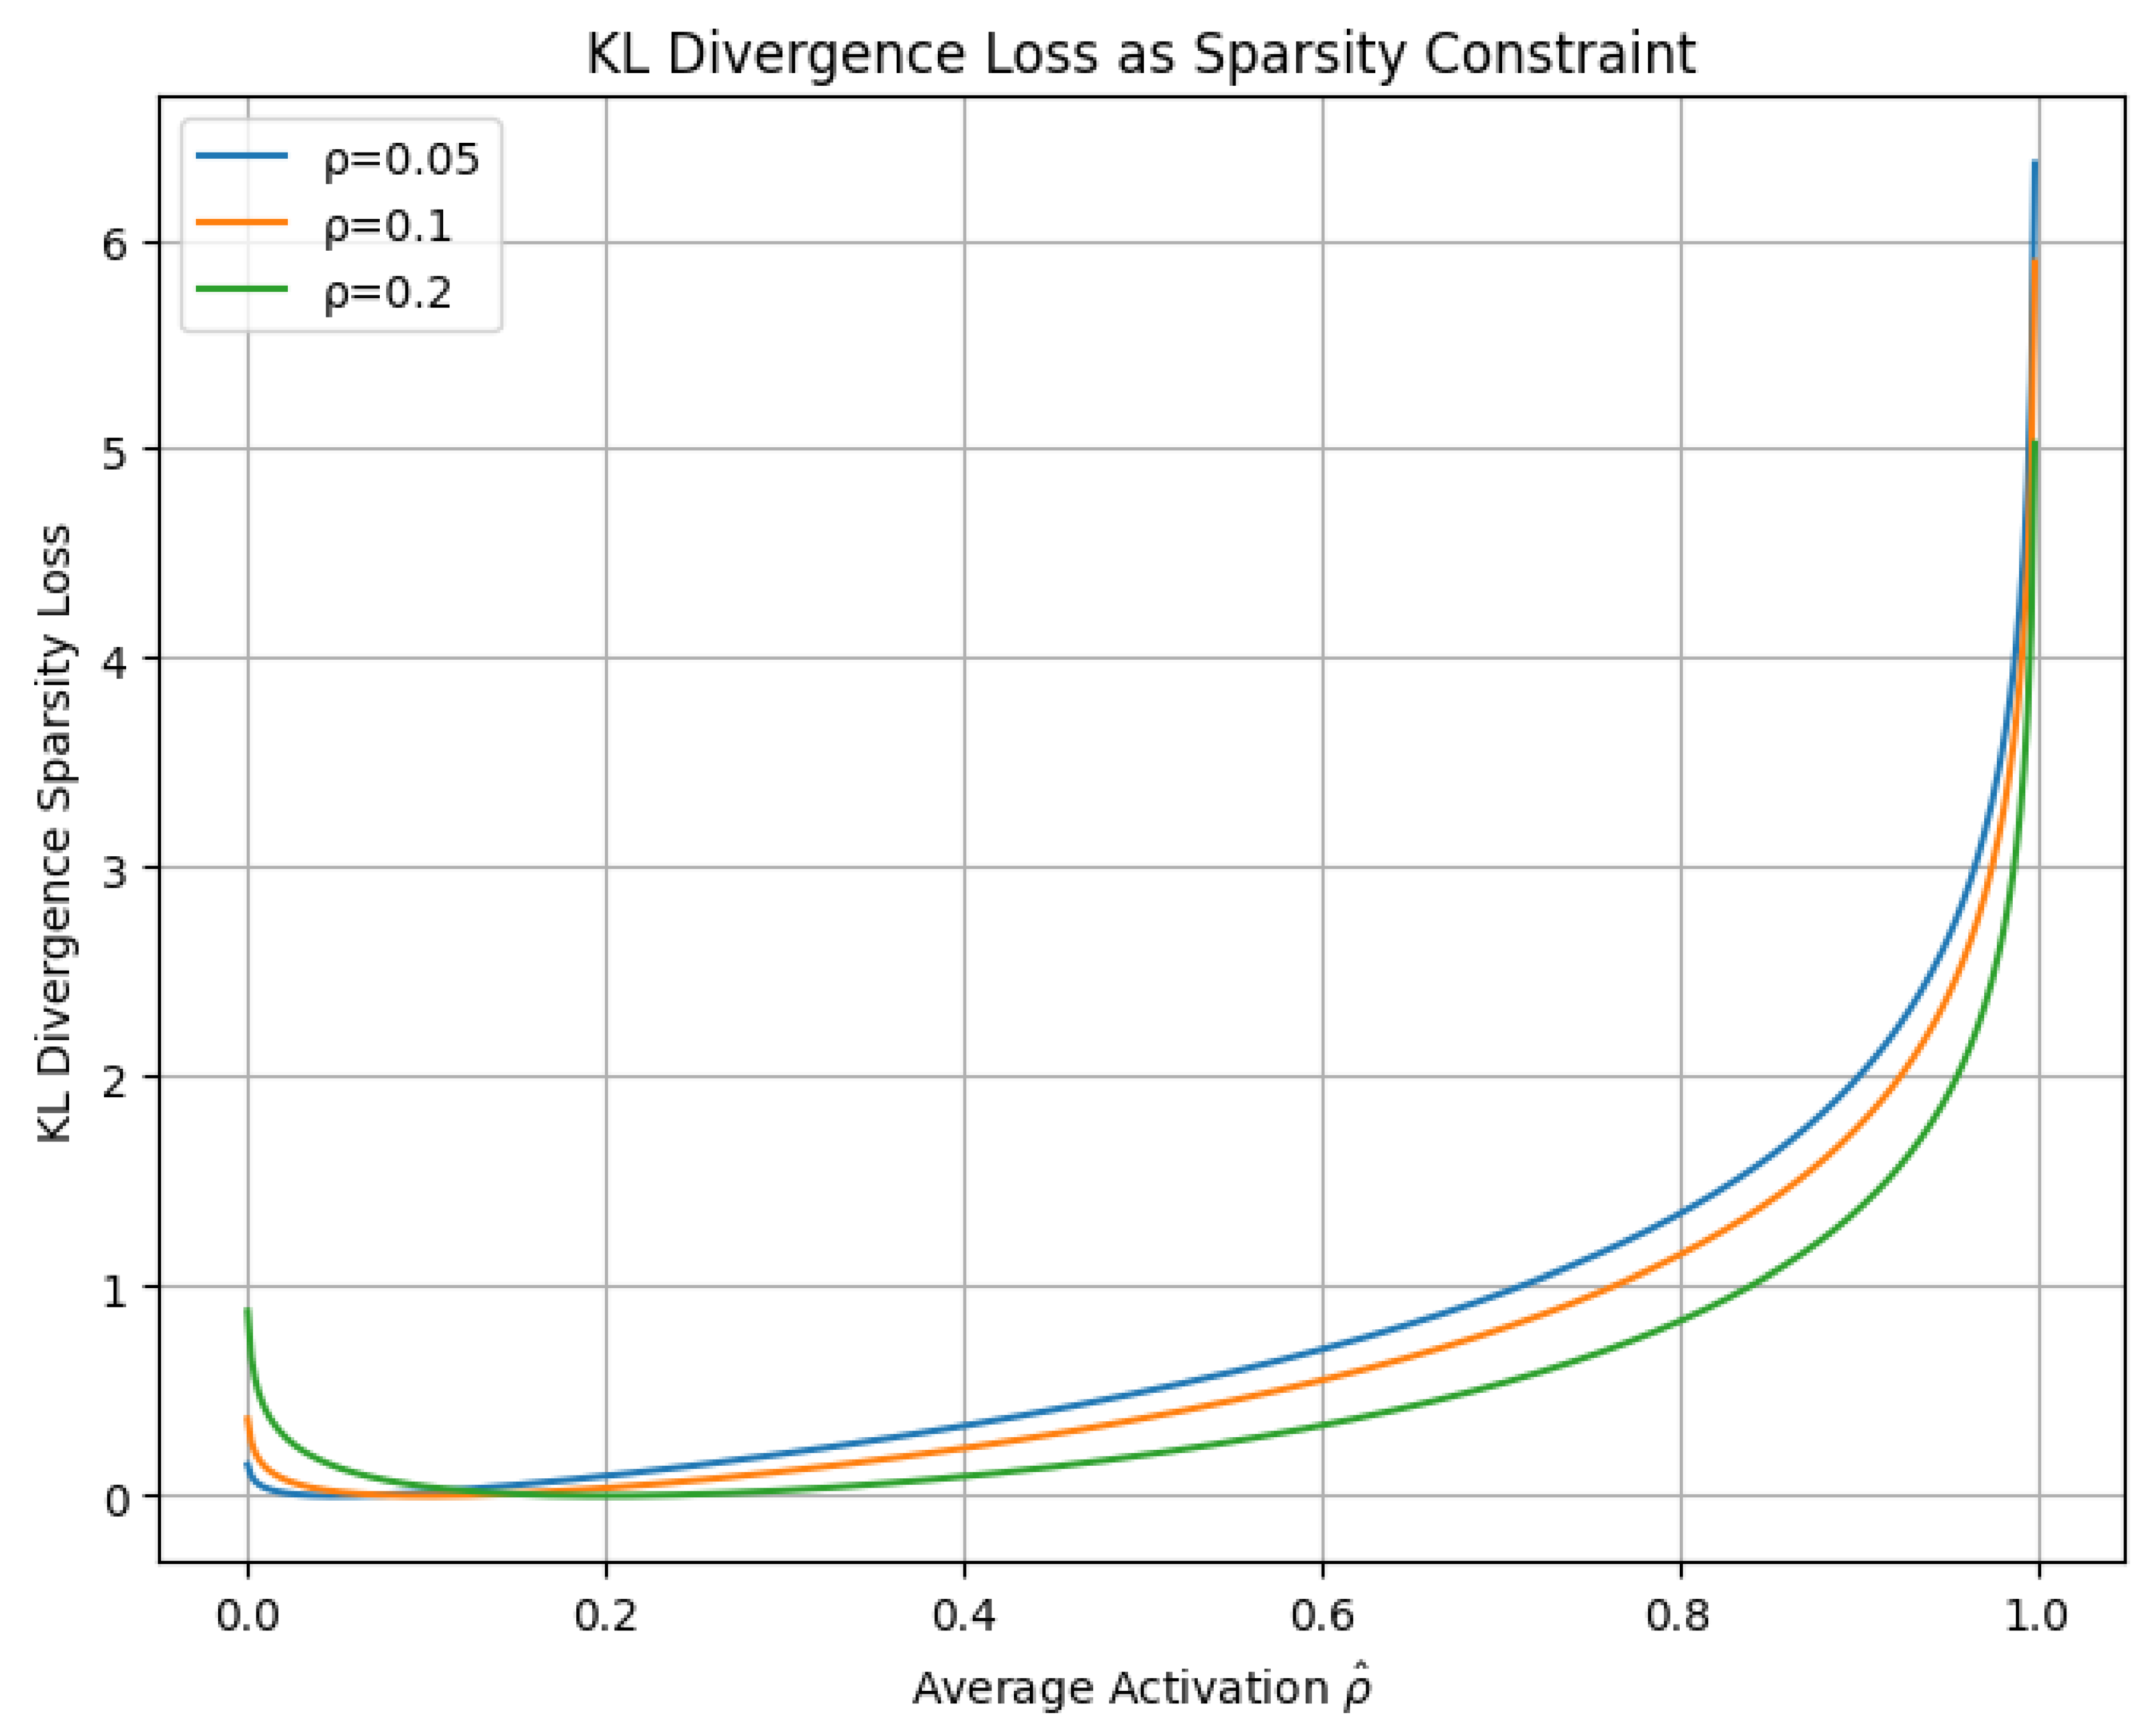
10.5.3.49 Python Code to Generate Figure 116 Illustrating Total KL Sparsity Loss for 10 Hidden Units ()
The Python code below produces the Figure 116 illustrating Total KL Sparsity Loss for 10 Hidden Units ().
Figure 116.
Total KL Sparsity Loss for 10 Hidden Units ()
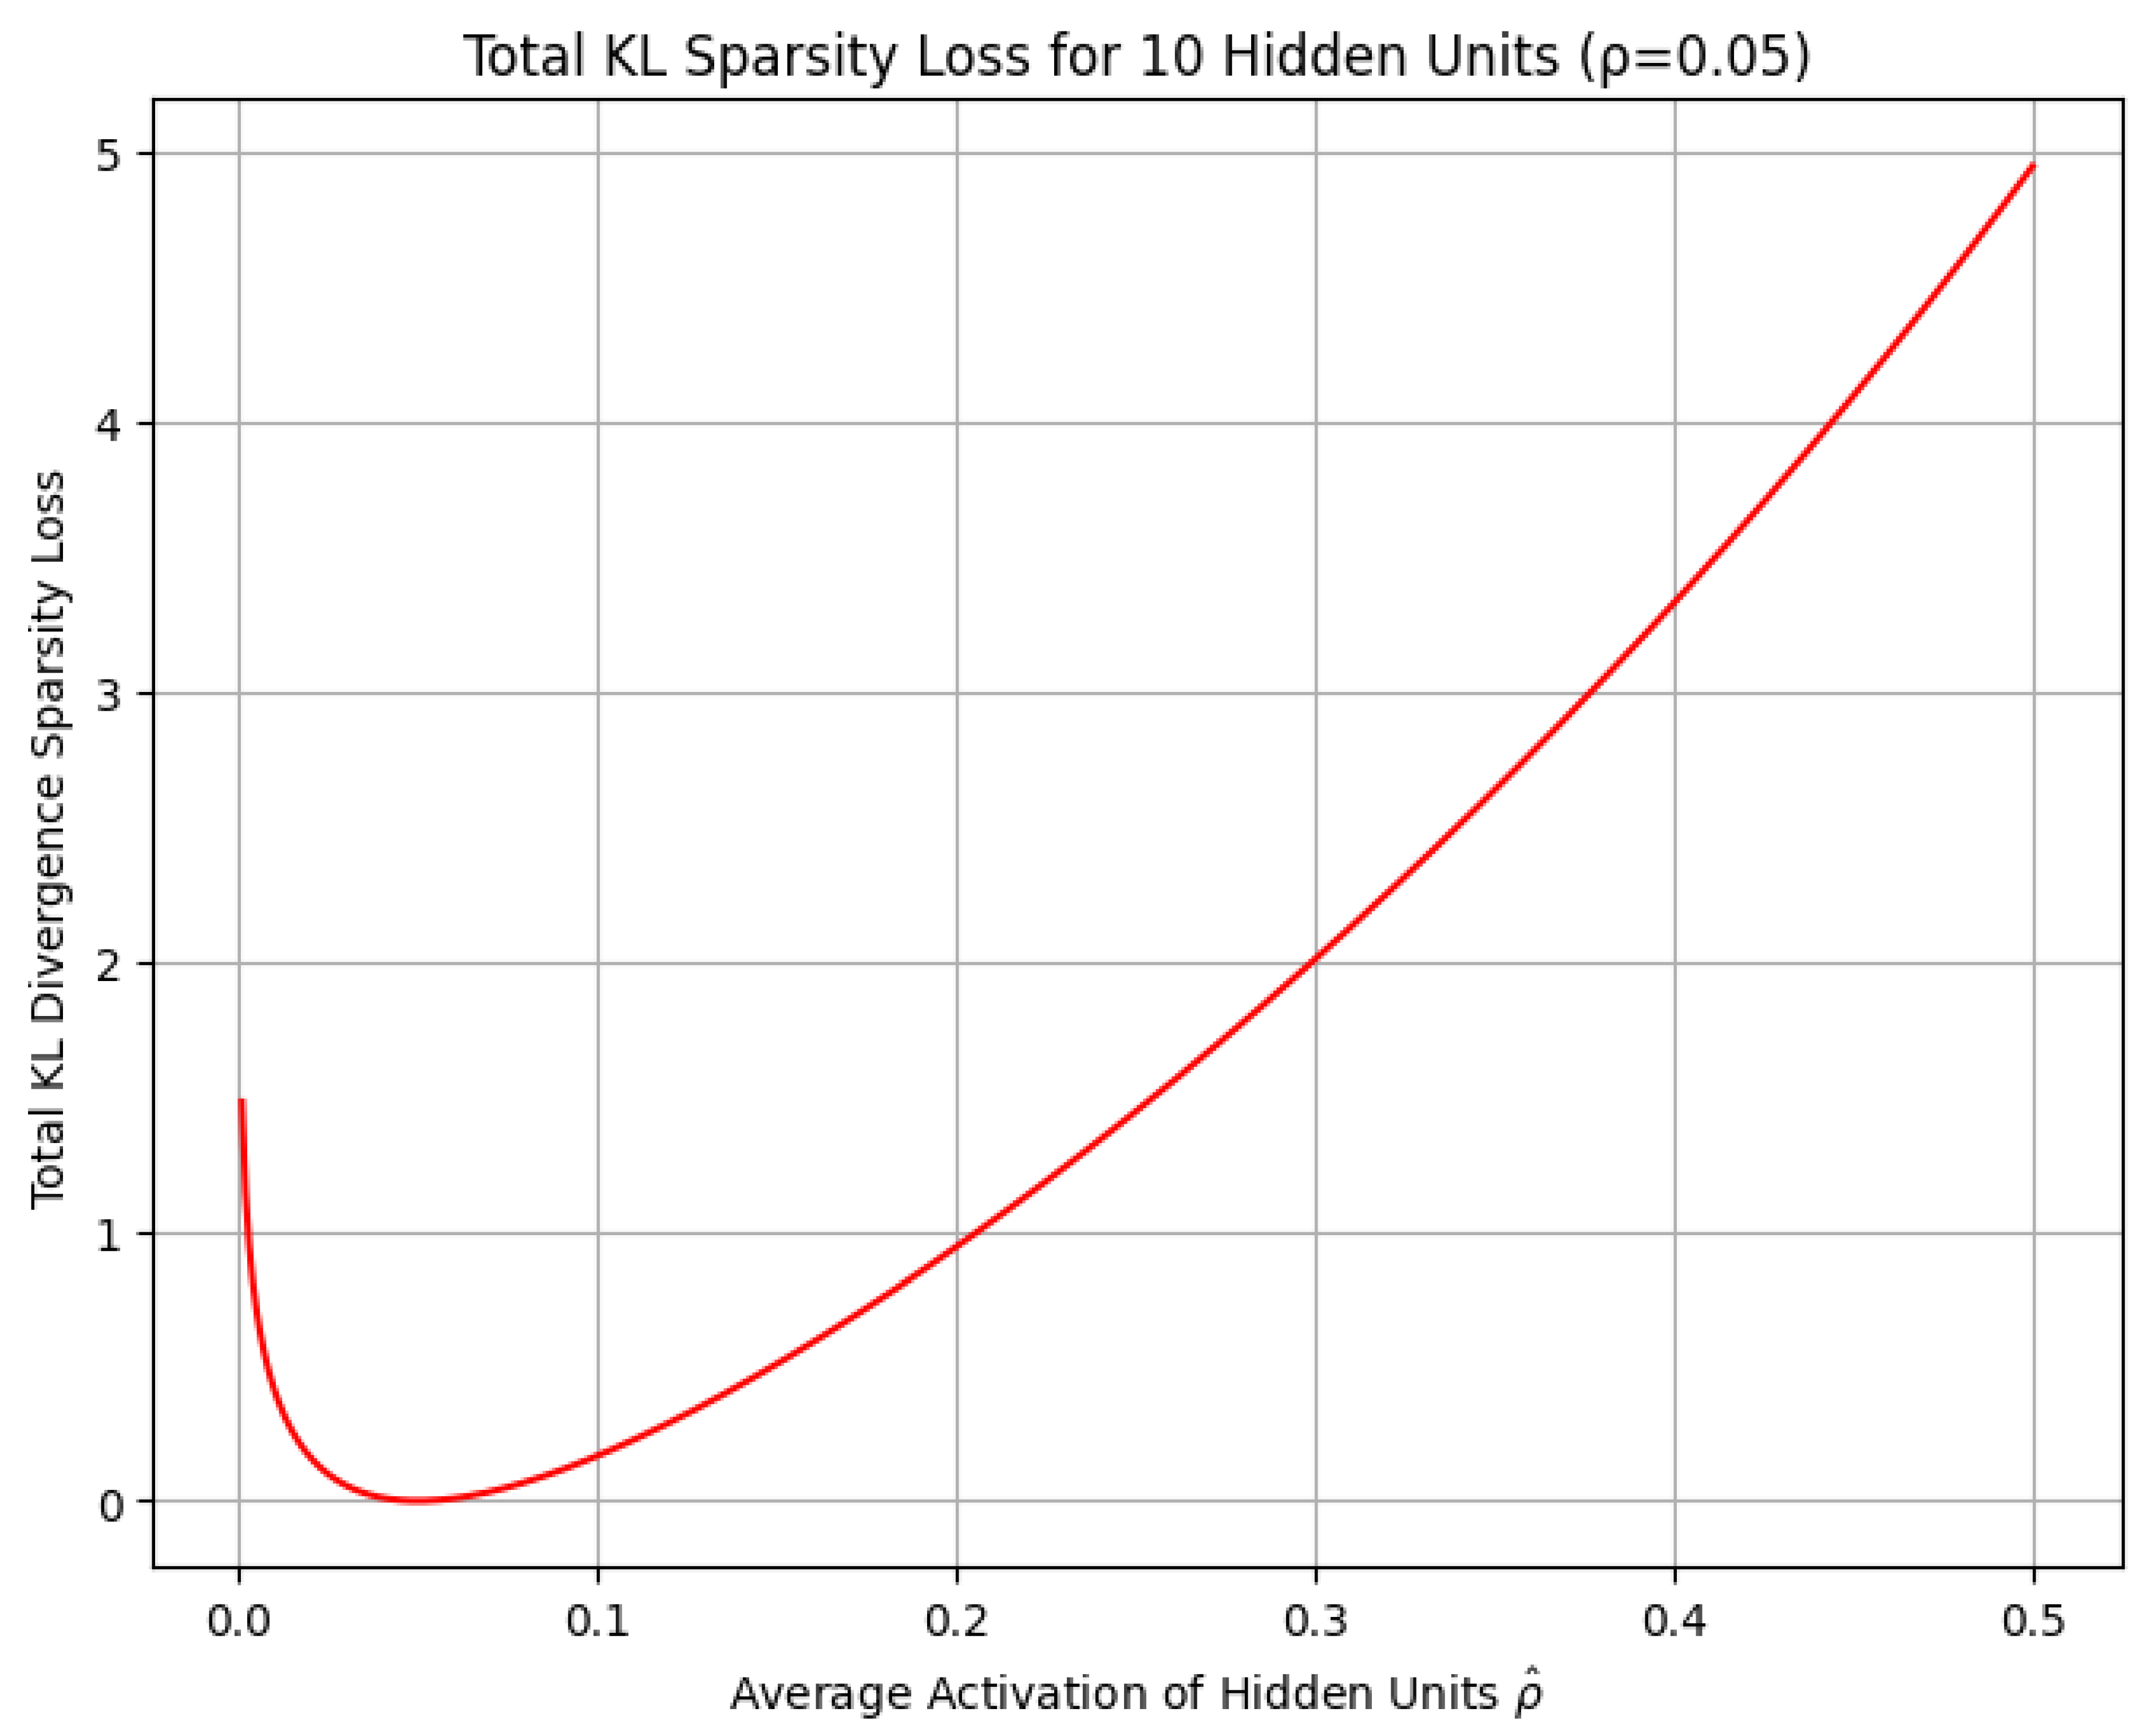
10.5.3.50 Python Code to Generate Figure 117 Illustrating Total KL Sparsity Loss for 10 Hidden Units with Random Activations ()
The Python code below produces the Figure 117 illustrating Total KL Sparsity Loss for 10 Hidden Units with Random Activations ().
Figure 117.
Total KL Sparsity Loss for 10 Hidden Units with Random Activations ()
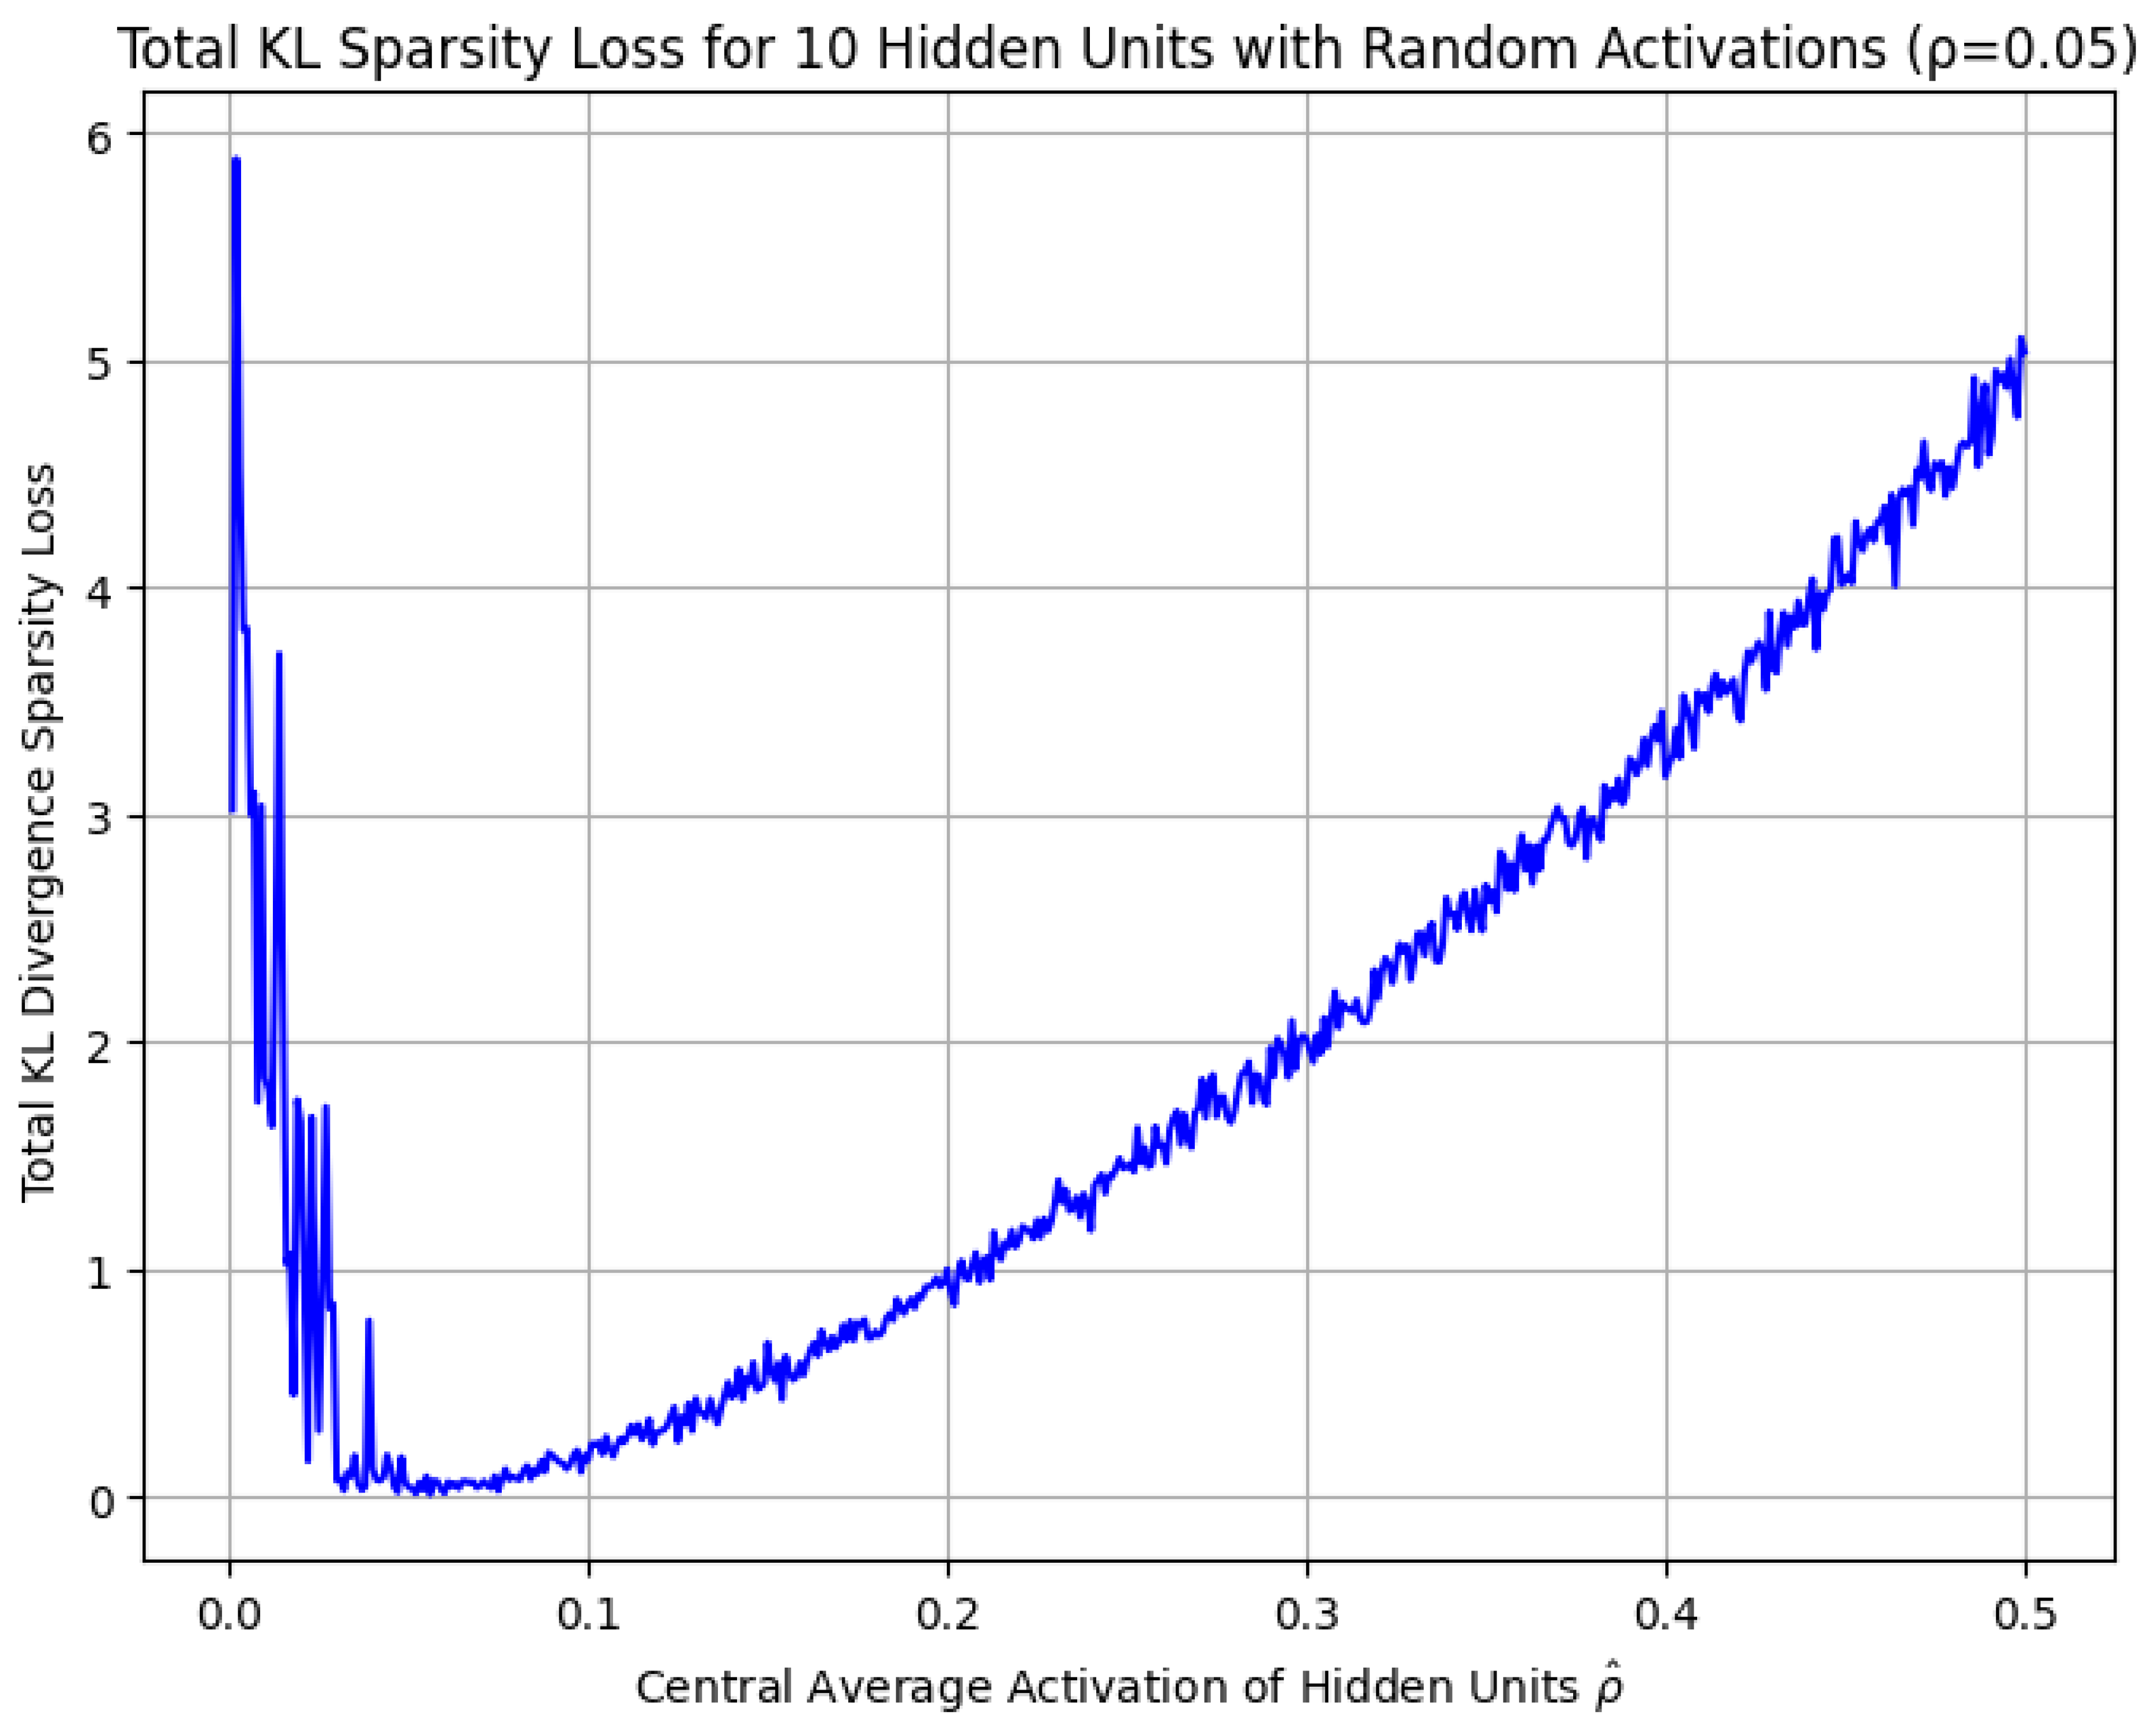
10.5.3.51 Python Code to Generate Figure 118 Illustrating Structured SVM (SSVM) Hinge Loss
The Python code below produces the Figure 118 illustrating Structured SVM (SSVM) Hinge Loss.
Figure 118.
Structured SVM (SSVM) Hinge Loss
10.5.3.52 Python Code to Generate Figure 119 Illustrating Structured SVM Loss Surface ()
The Python code below produces the Figure 119 illustrating Structured SVM Loss Surface ().
Figure 119.
Structured SVM Loss Surface ()
10.5.3.53 Python Code to Generate Figure 120 Illustrating Structured SVM Loss Contour ()
The Python code below produces the Figure 120 illustrating Structured SVM Loss Contour ().
Figure 120.
Structured SVM Loss Contour ()
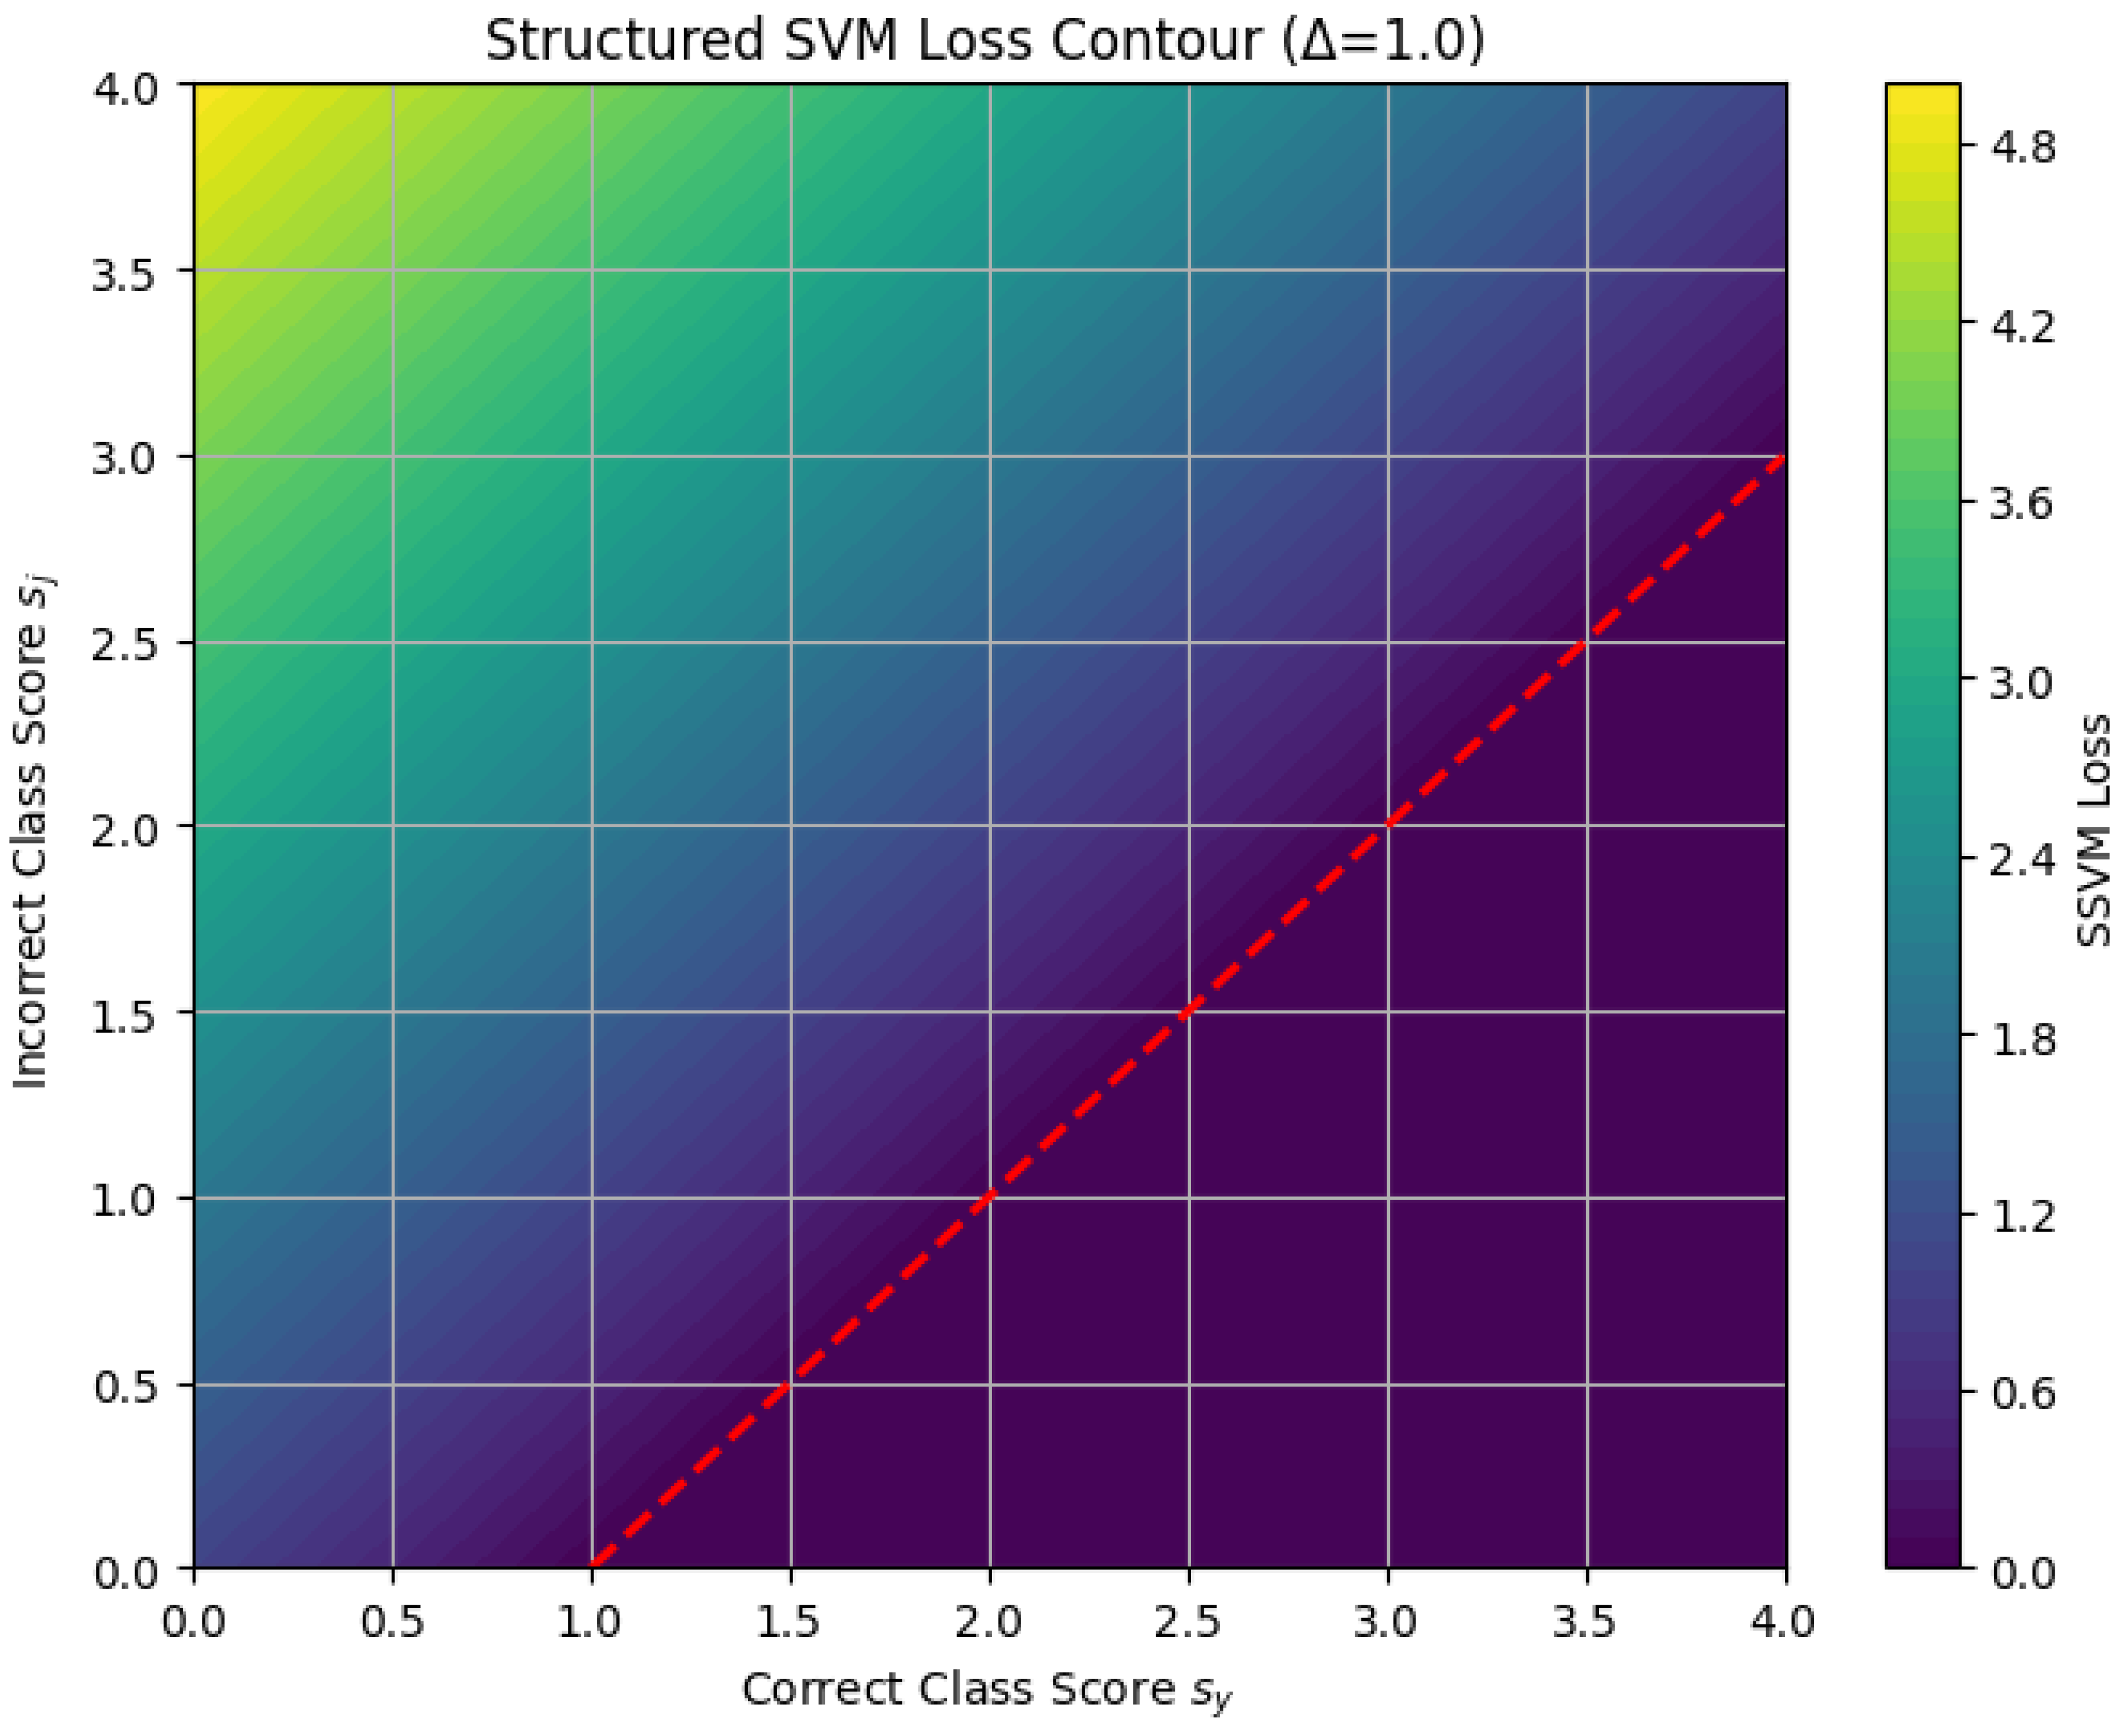
10.5.3.54 Python Code to Generate Figure 121 Illustrating Simplified CRF Loss vs Correct Label Score
The Python code below produces the Figure 121 illustrating Simplified CRF Loss vs Correct Label Score.
Figure 121.
Simplified CRF Loss vs Correct Label Score
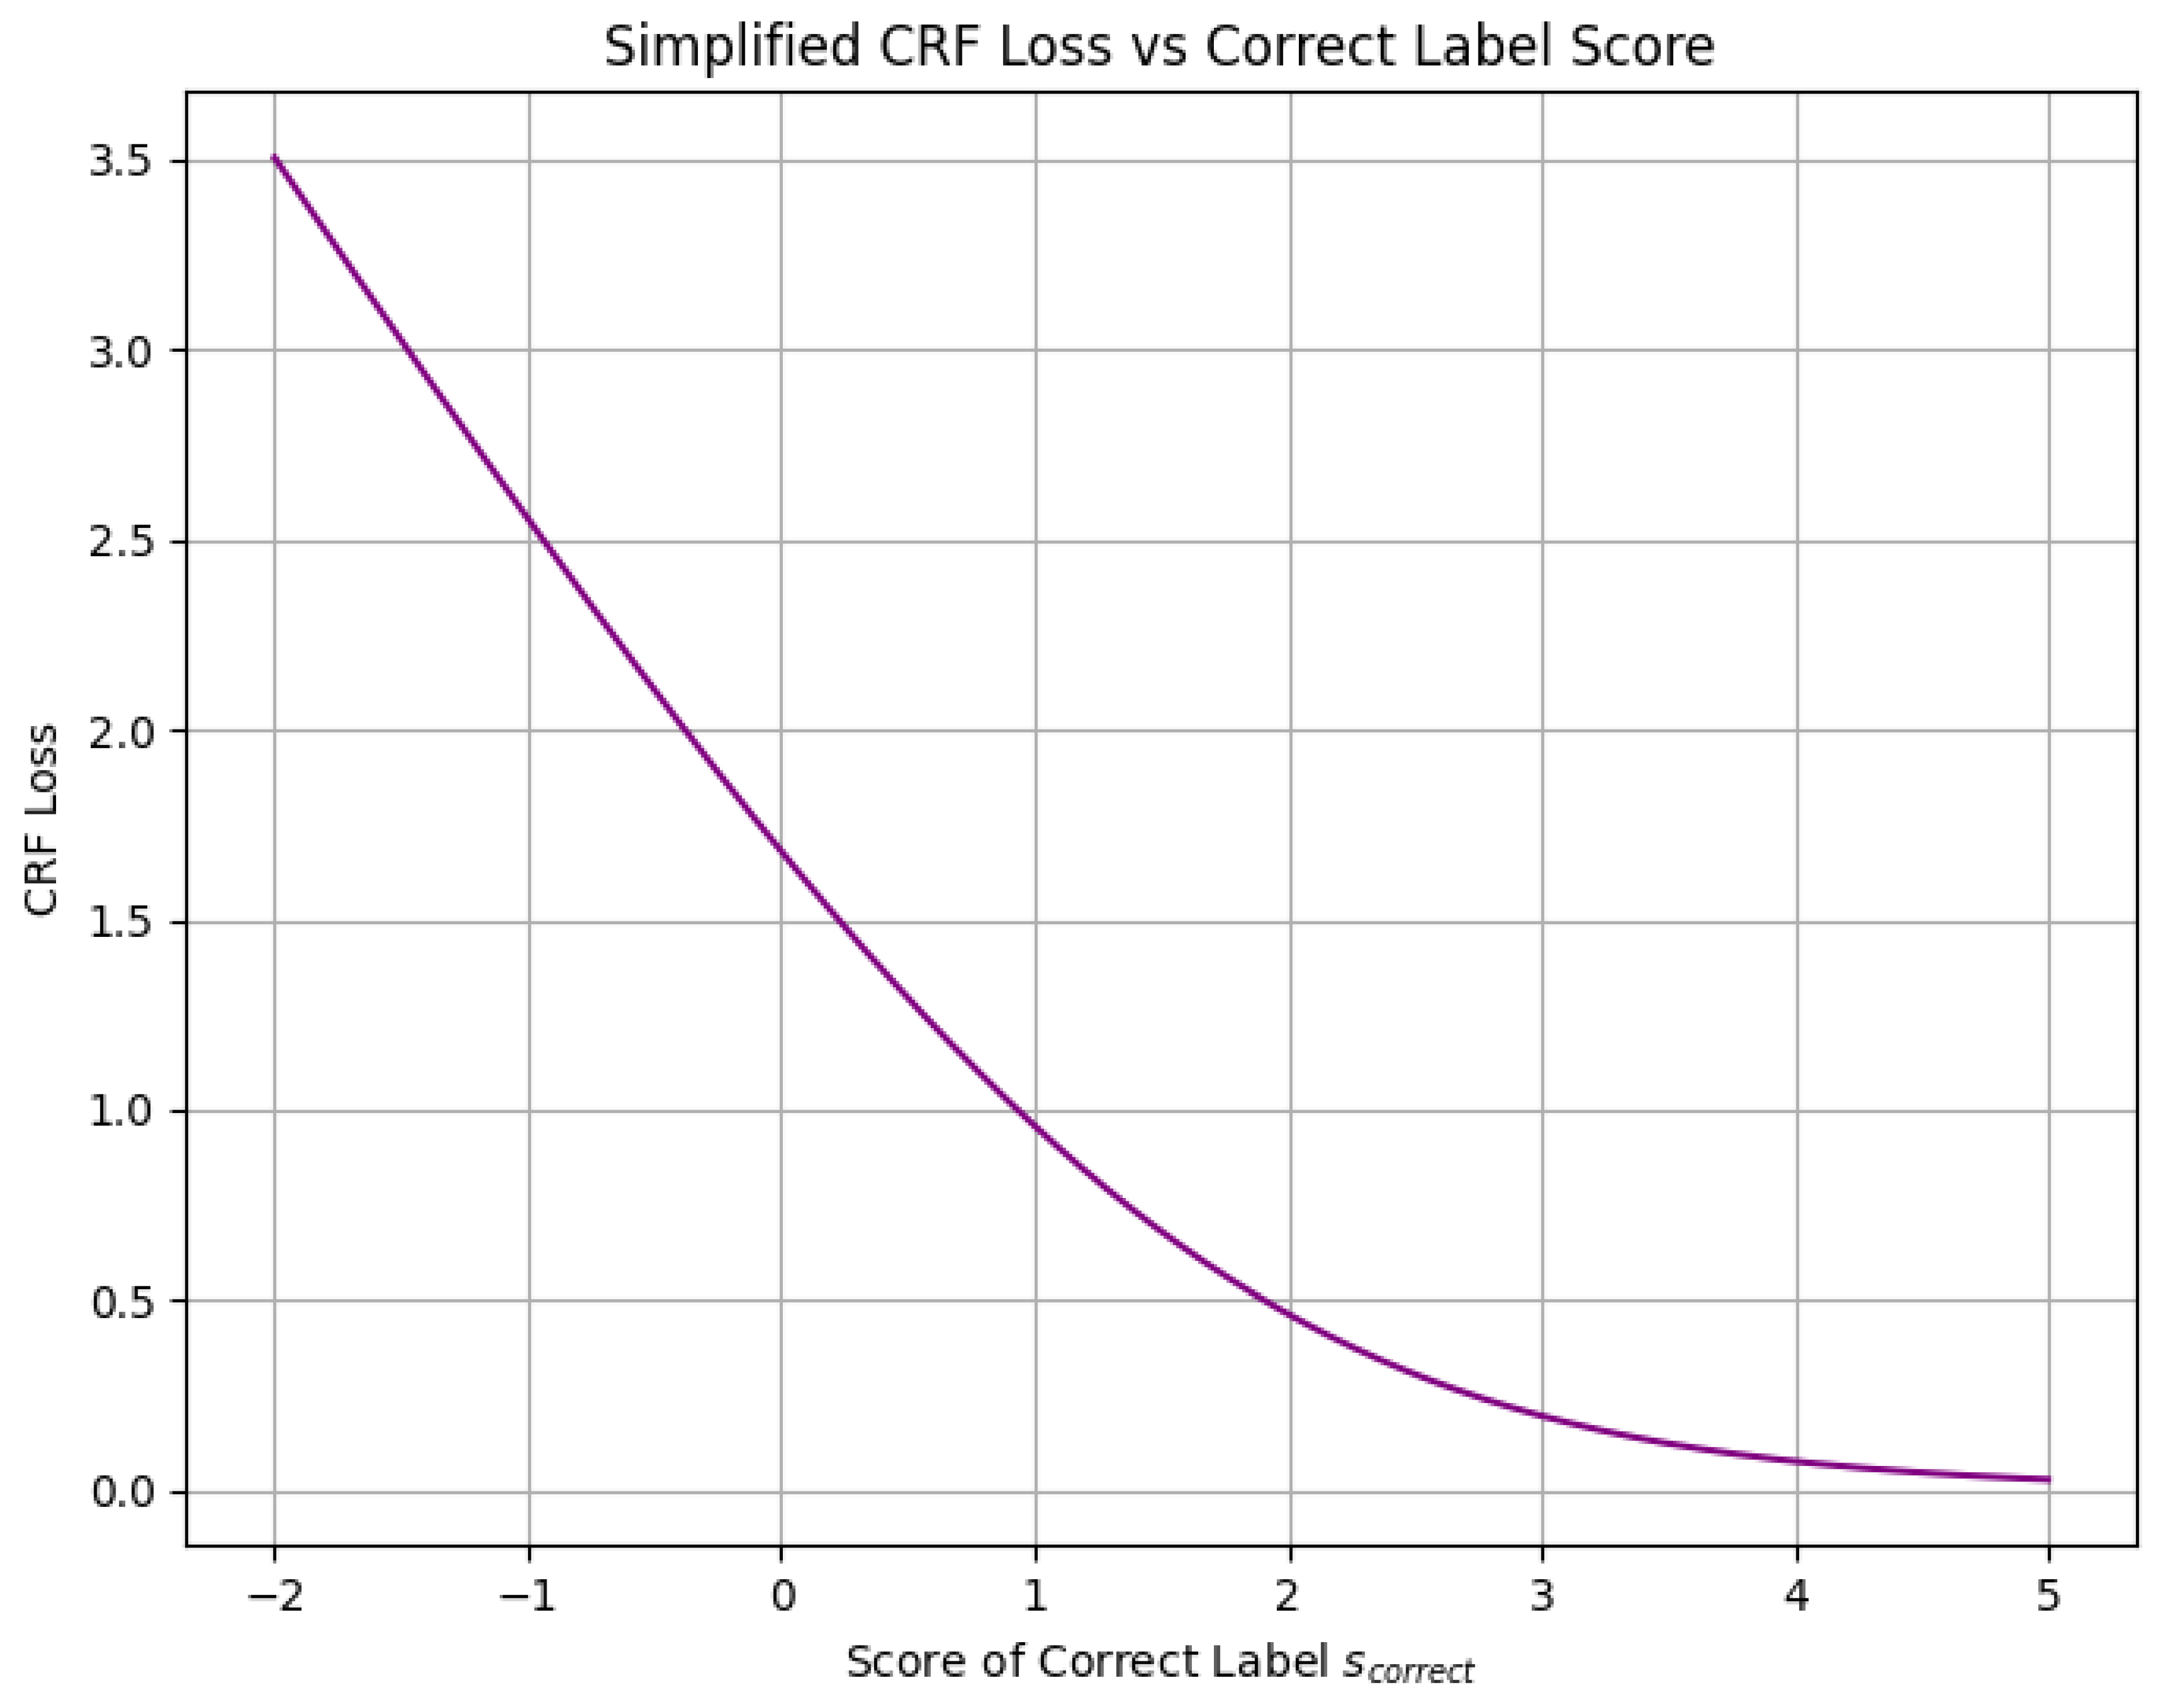
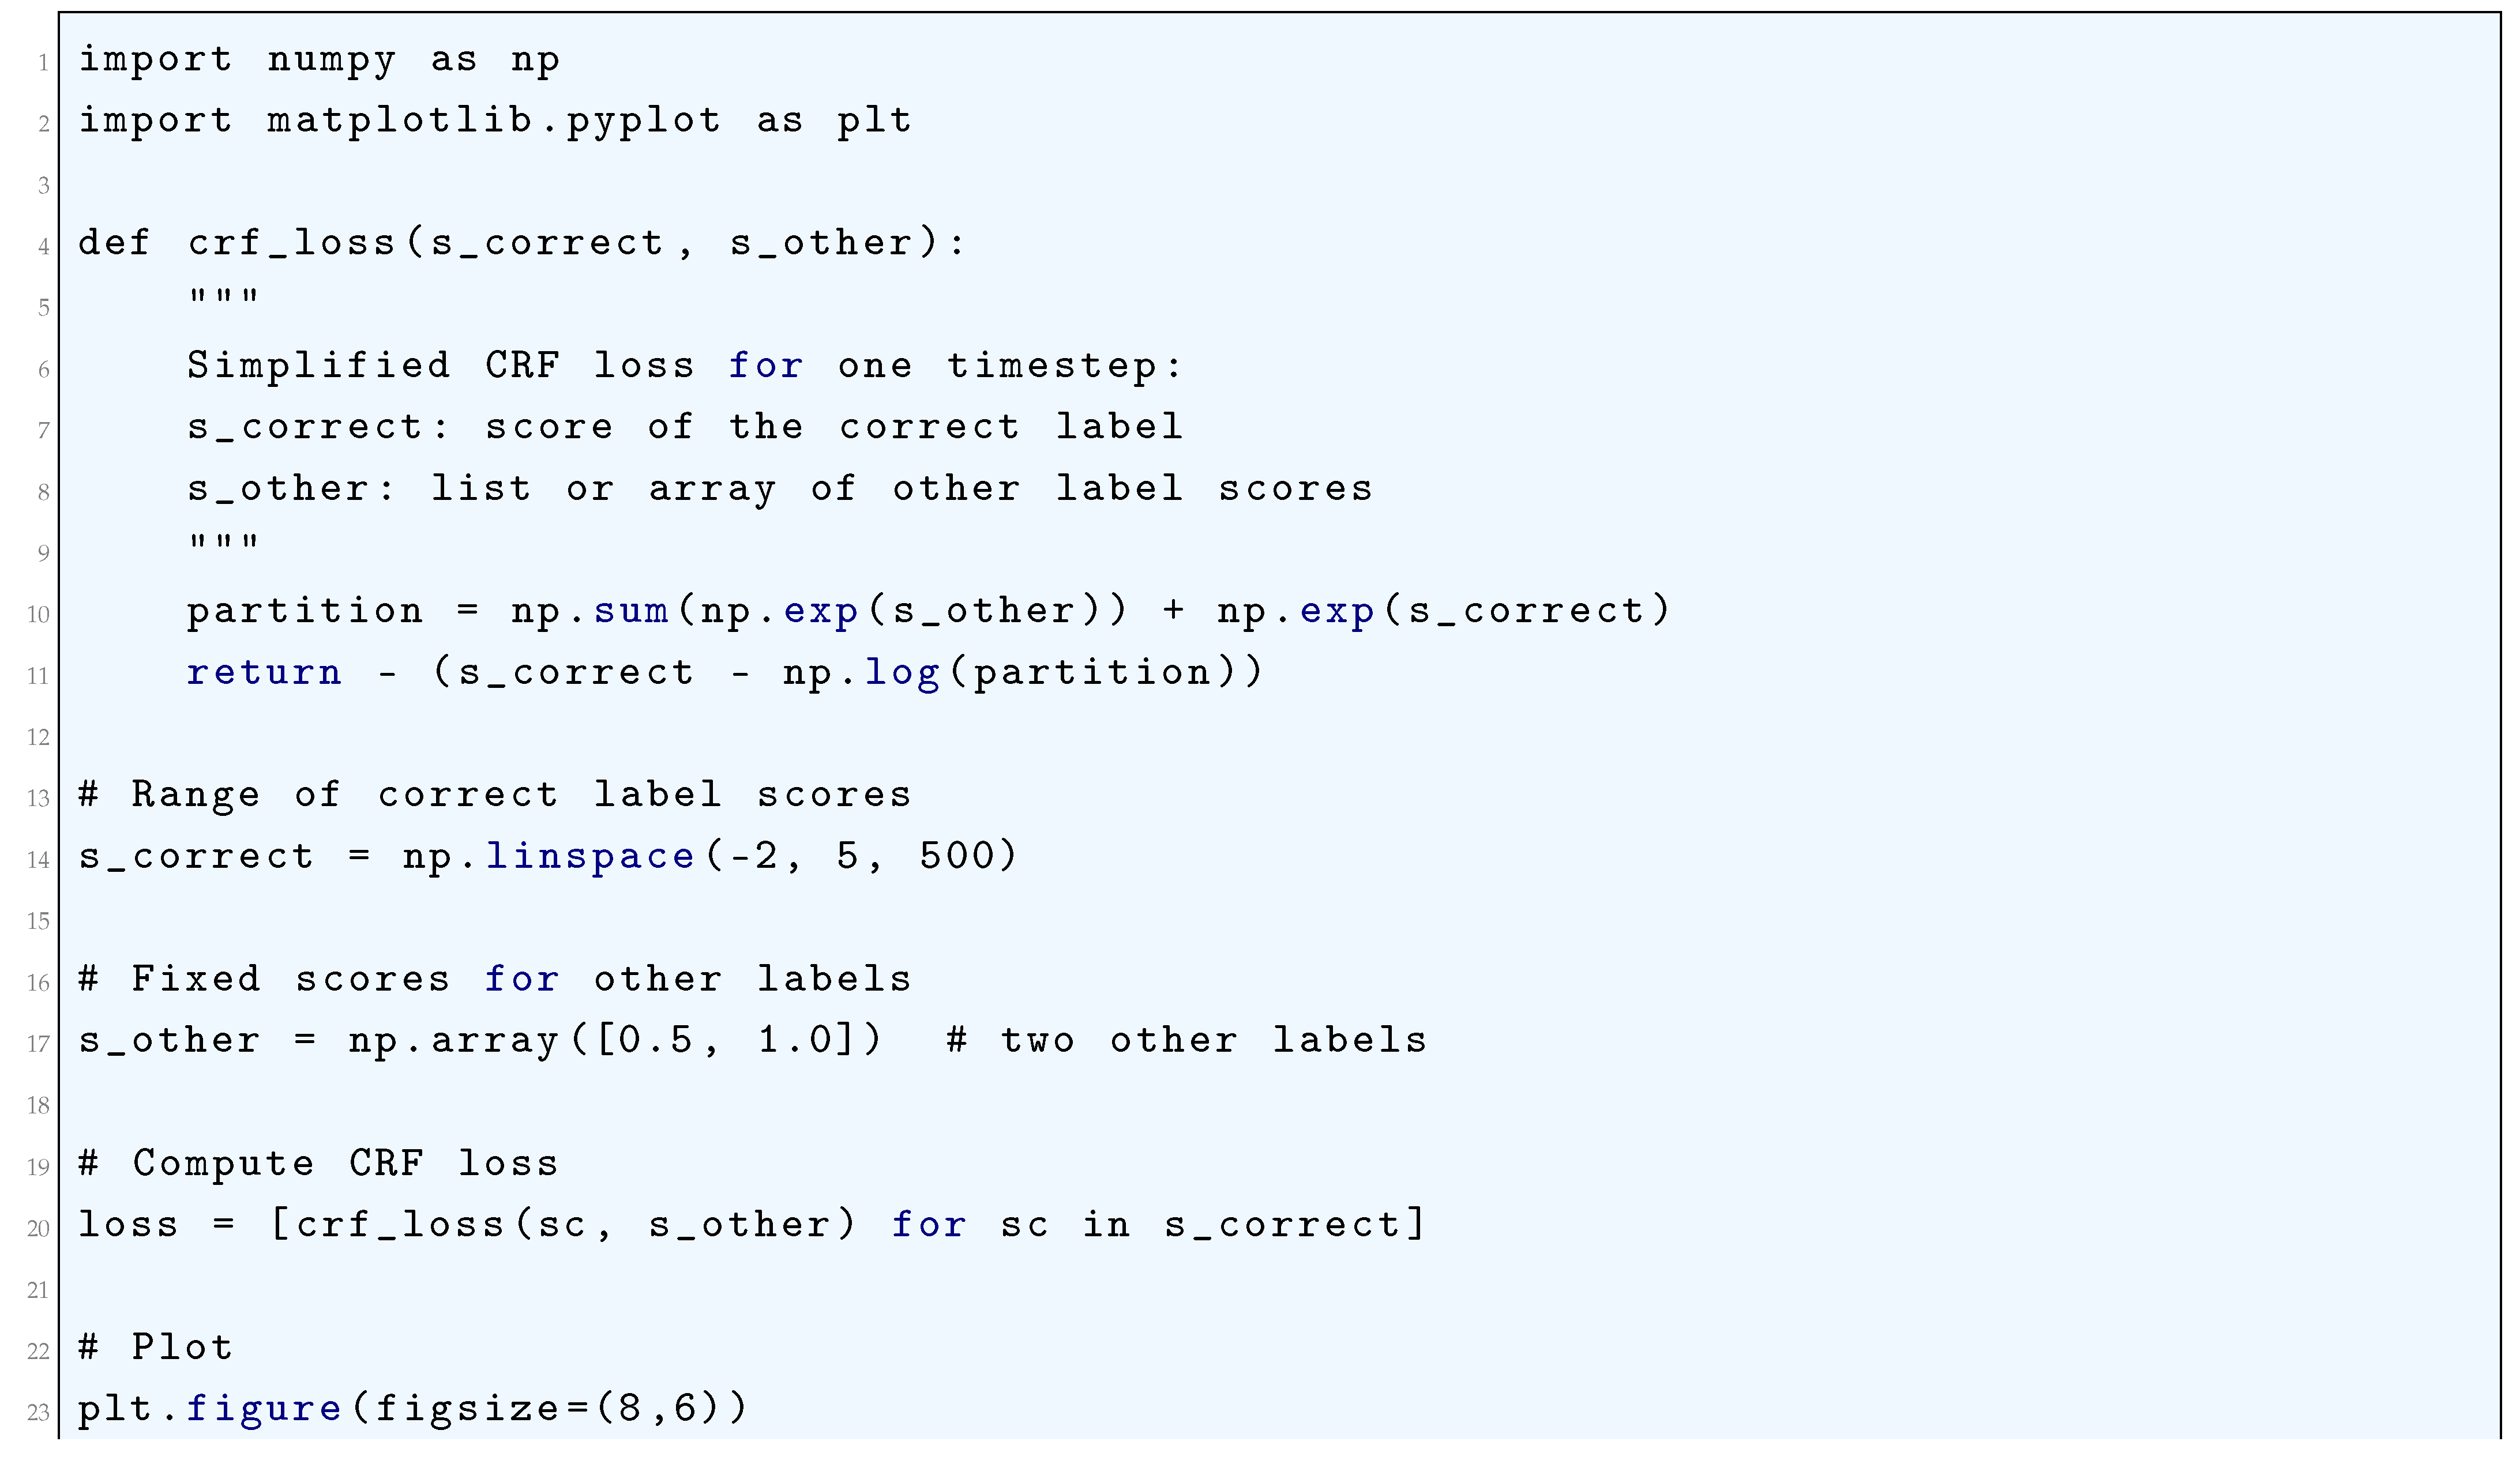
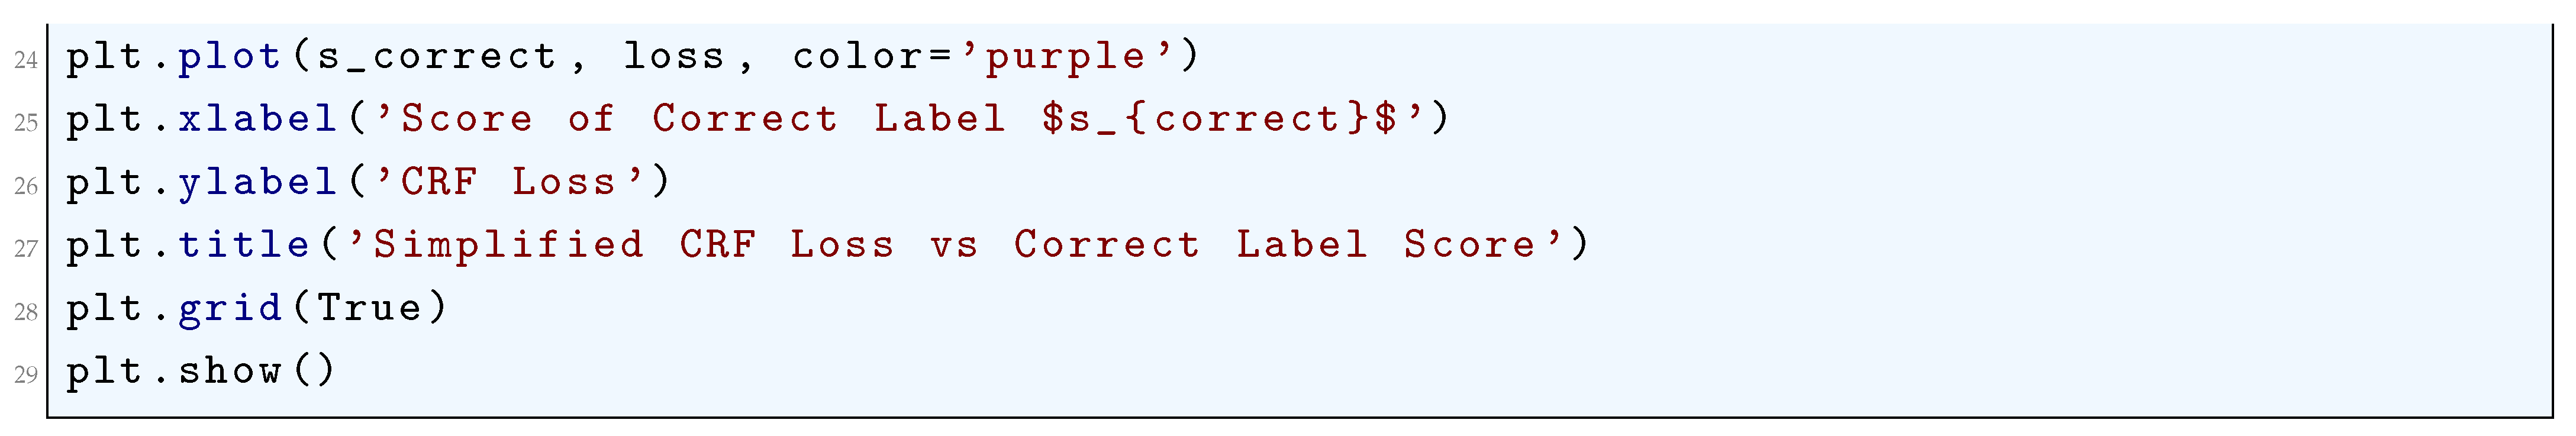
10.5.3.55 Python Code to Generate Figure 122 Illustrating CRF Loss Surface (Single Timestep, 2 Labels)
The Python code below produces the Figure 122 illustrating CRF Loss Surface (Single Timestep, 2 Labels).
Figure 122.
CRF Loss Surface (Single Timestep, 2 Labels)
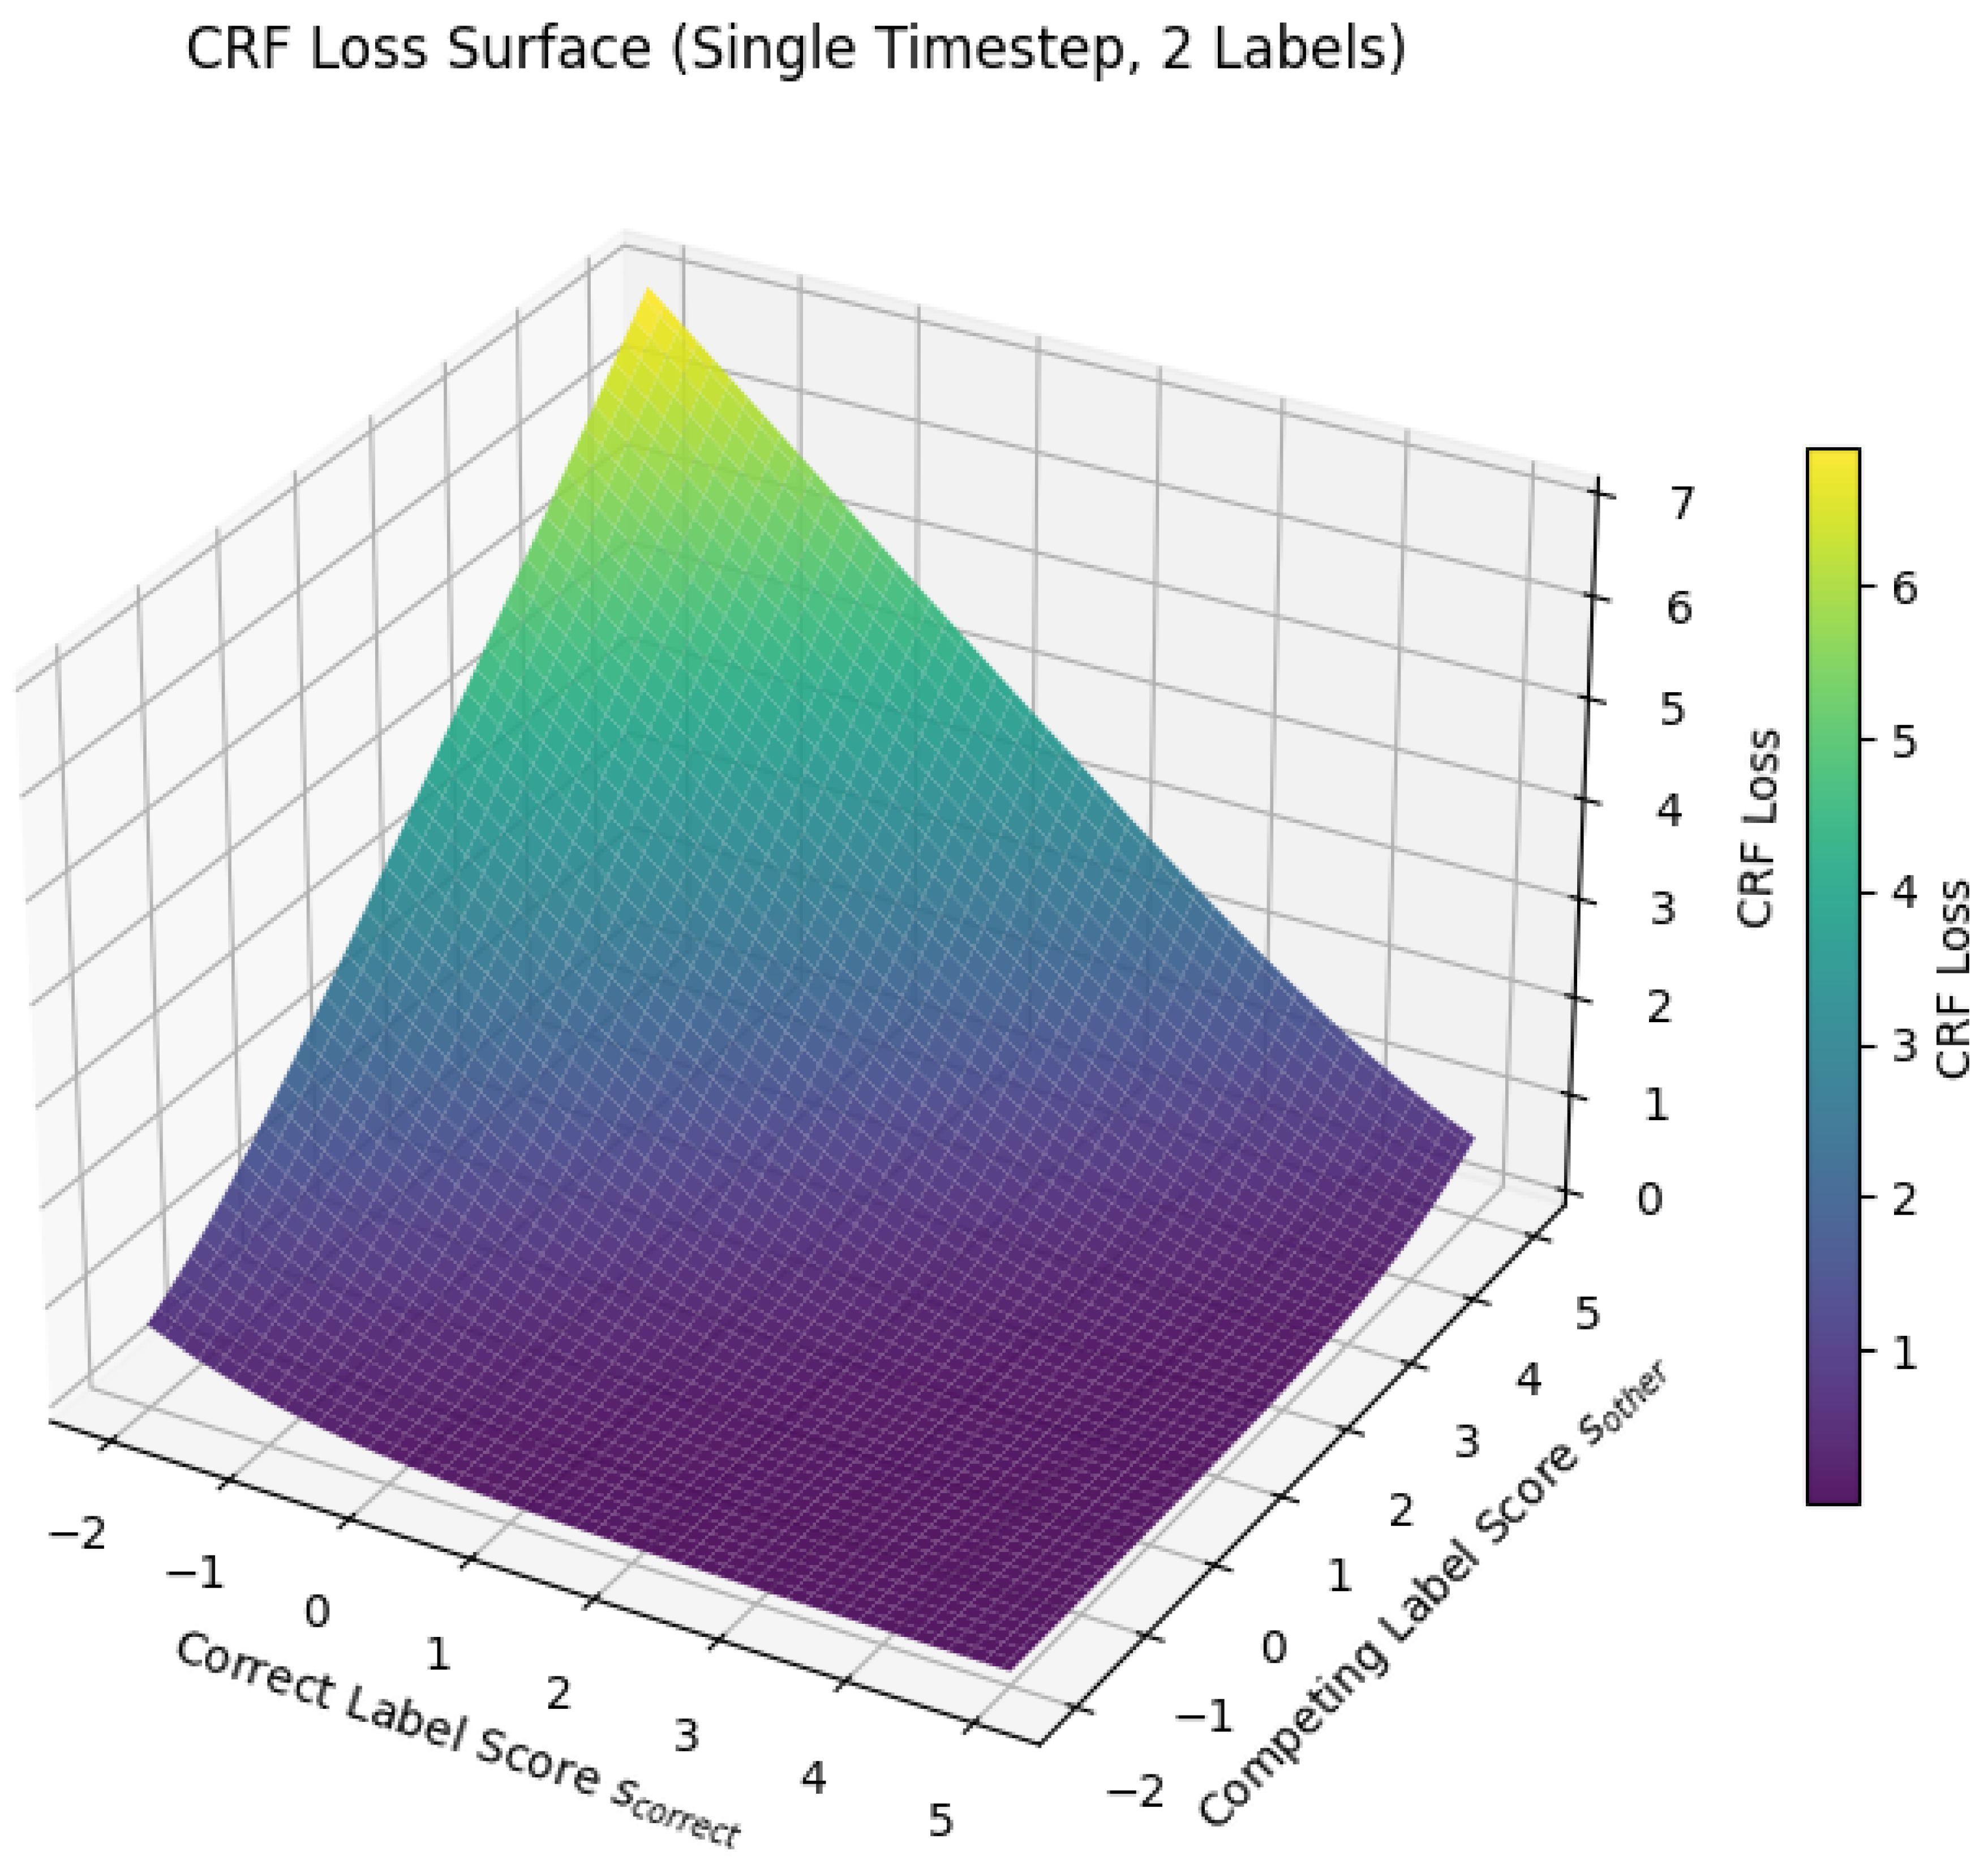
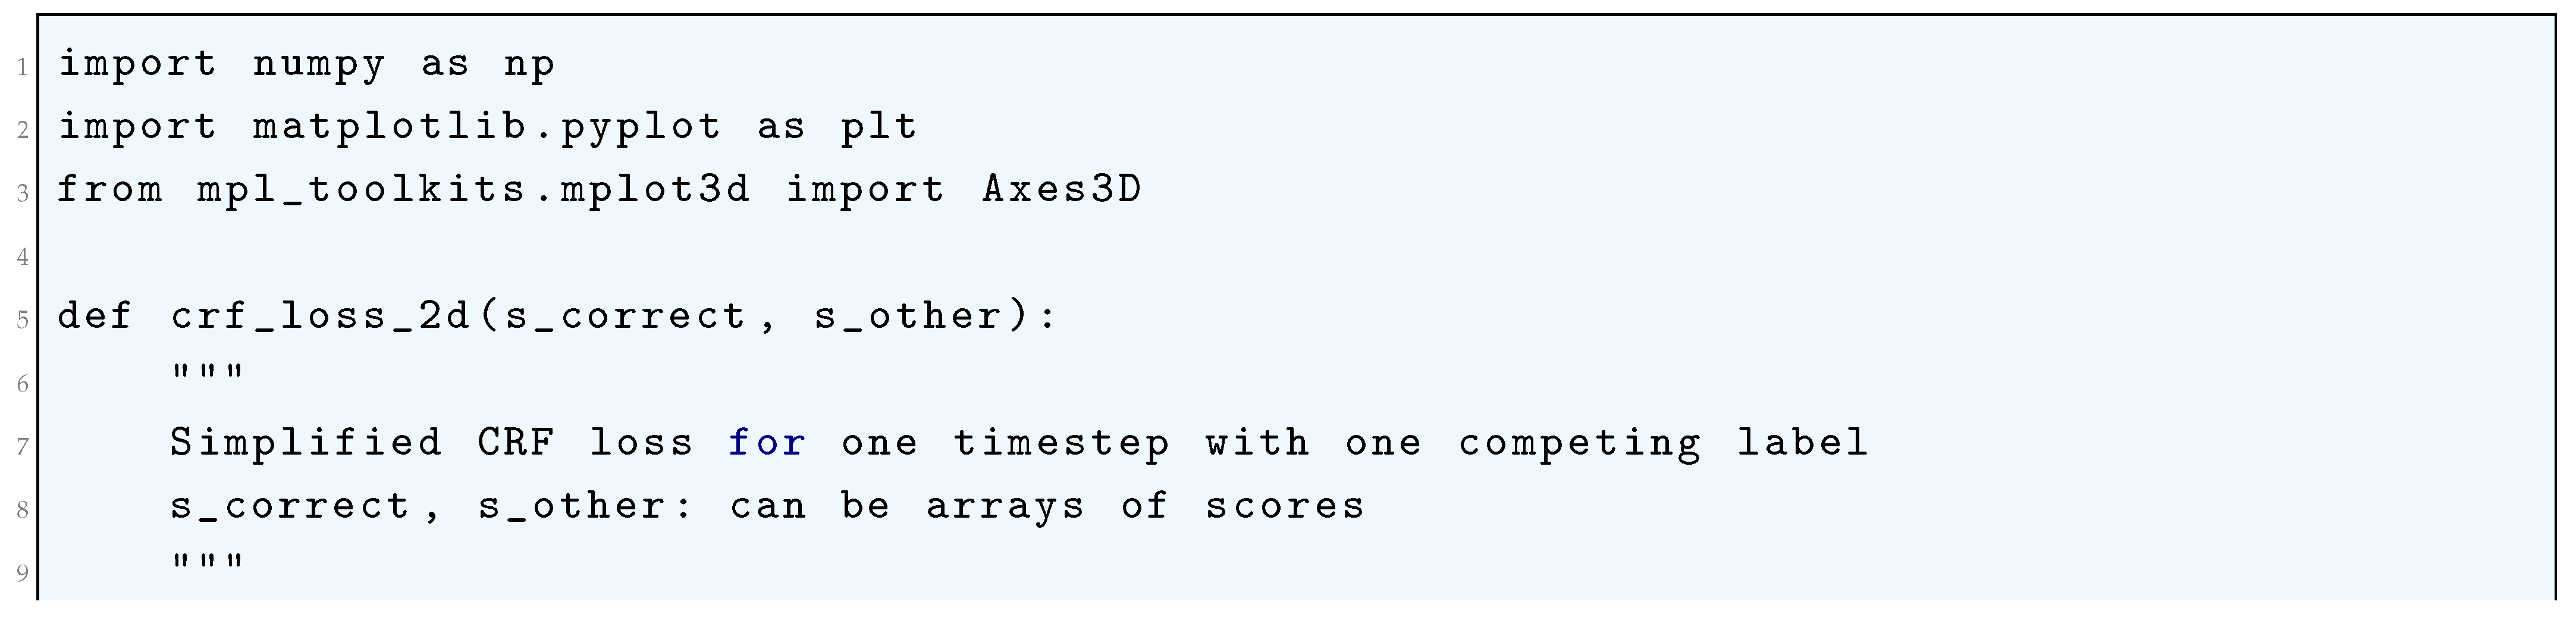
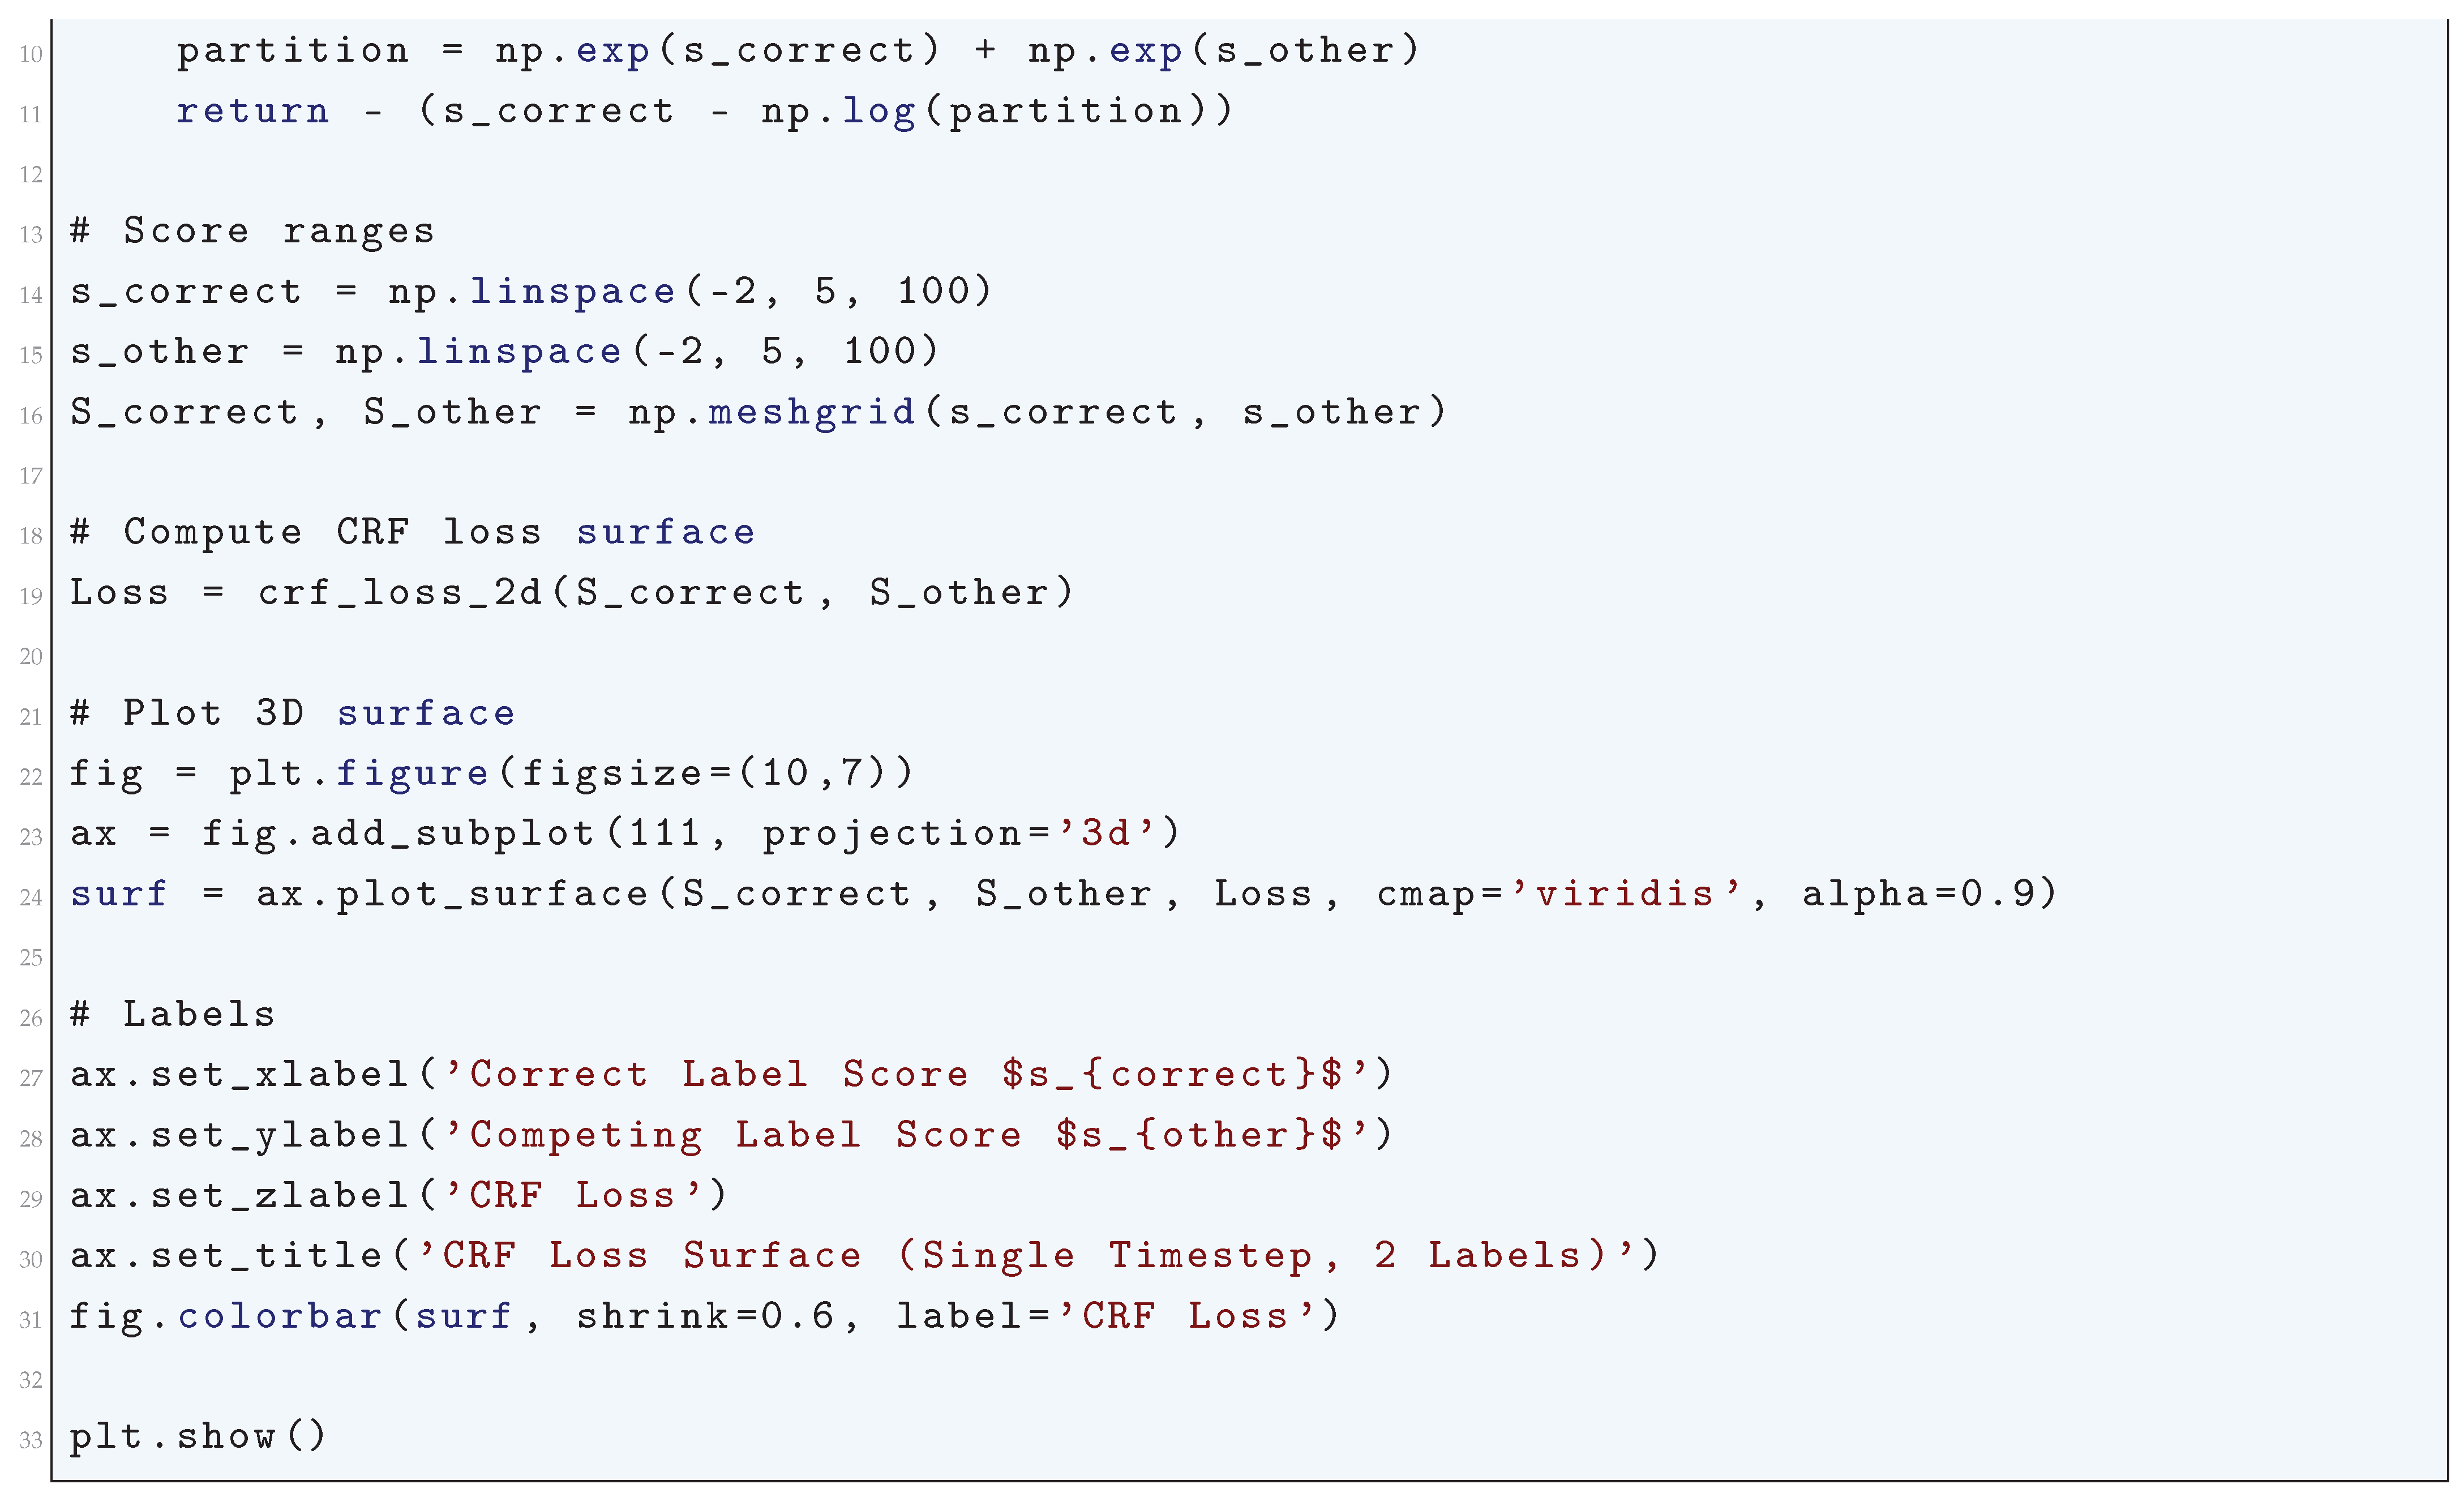
10.5.3.56 Python Code to Generate Figure 123 Illustrating CRF Loss Contour (Single Timestep, 2 Labels)
The Python code below produces the Figure 123 illustrating CRF Loss Contour (Single Timestep, 2 Labels).
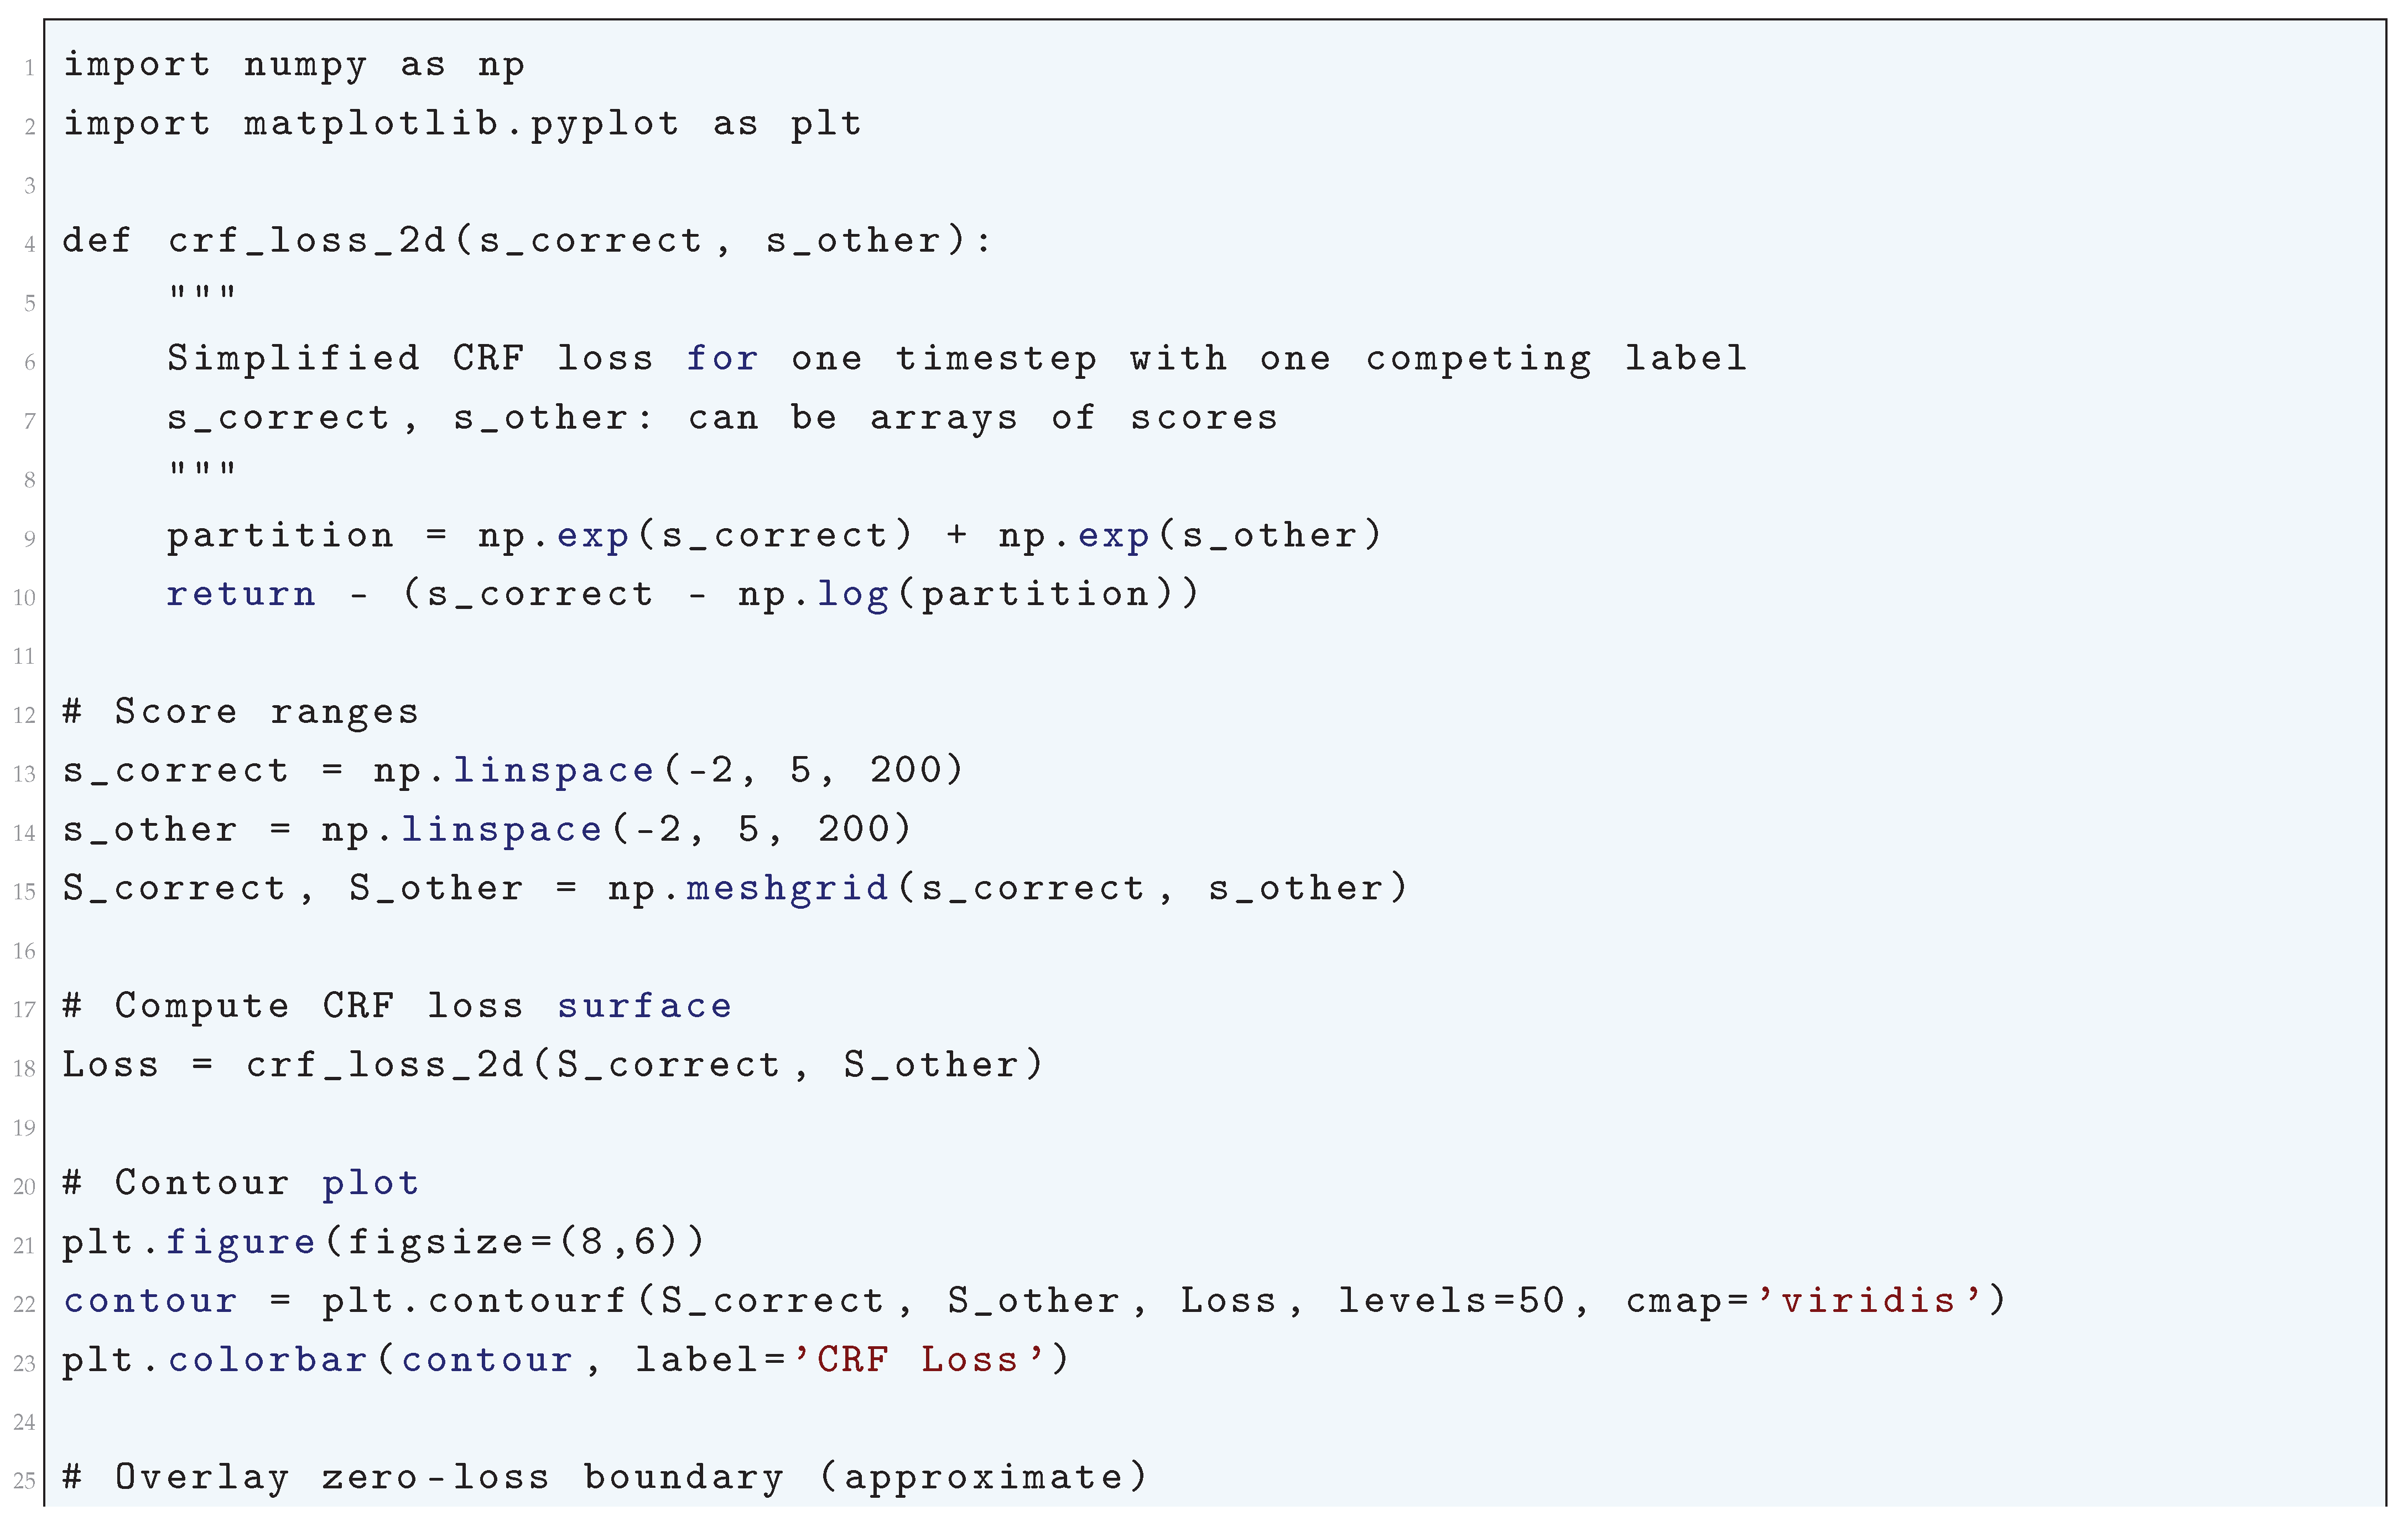
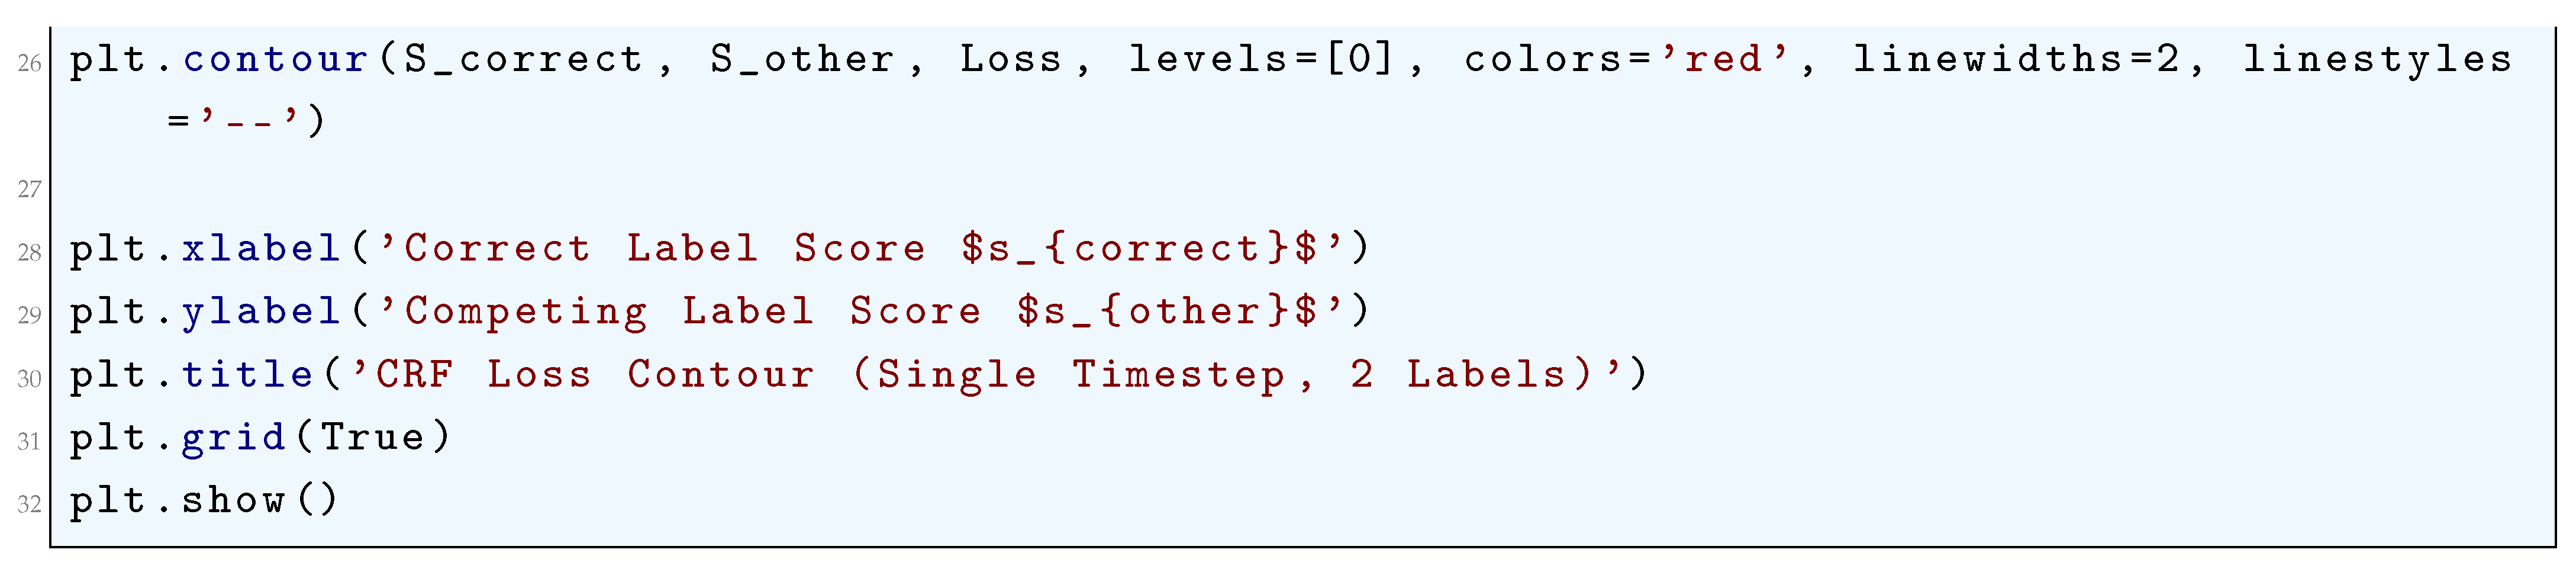
Figure 123.
CRF Loss Contour (Single Timestep, 2 Labels)
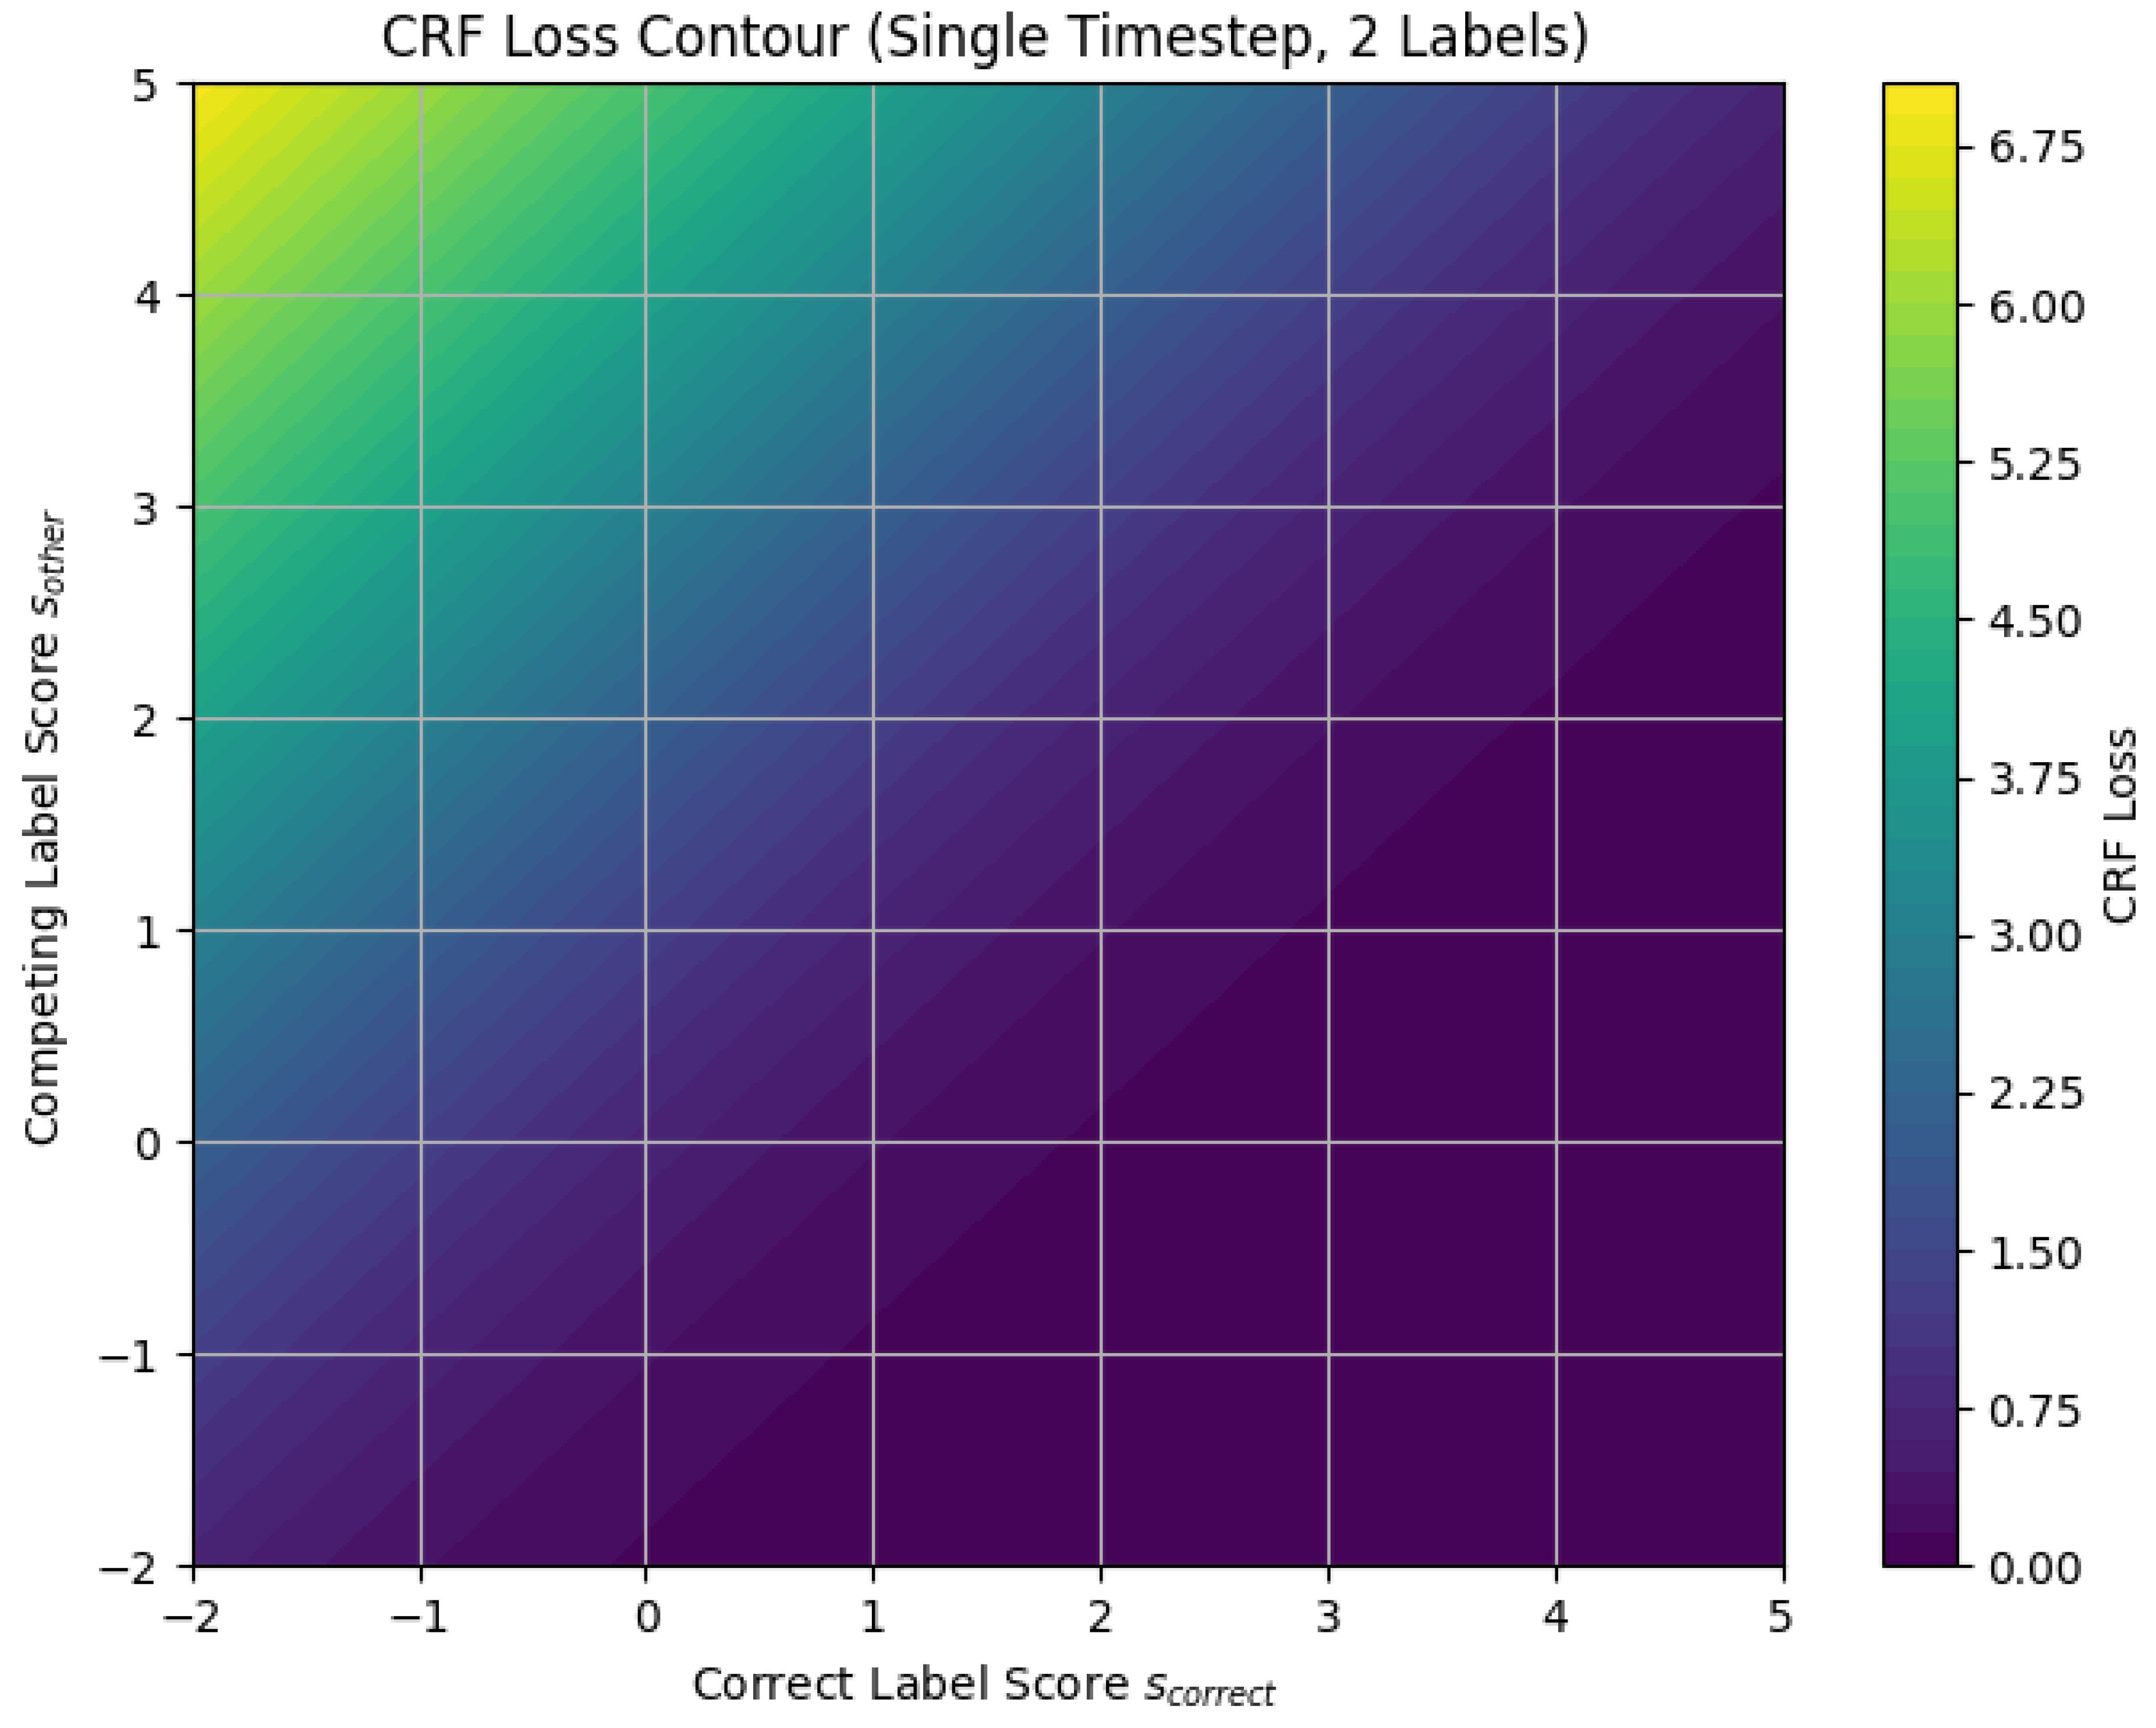
10.5.3.57 Python Code to Generate Figure 124 Illustrating CTC Loss vs Probability of Correct Sequence
The Python code below produces the Figure 124 illustrating CTC Loss vs Probability of Correct Sequence.
Figure 124.
CTC Loss vs Probability of Correct Sequence
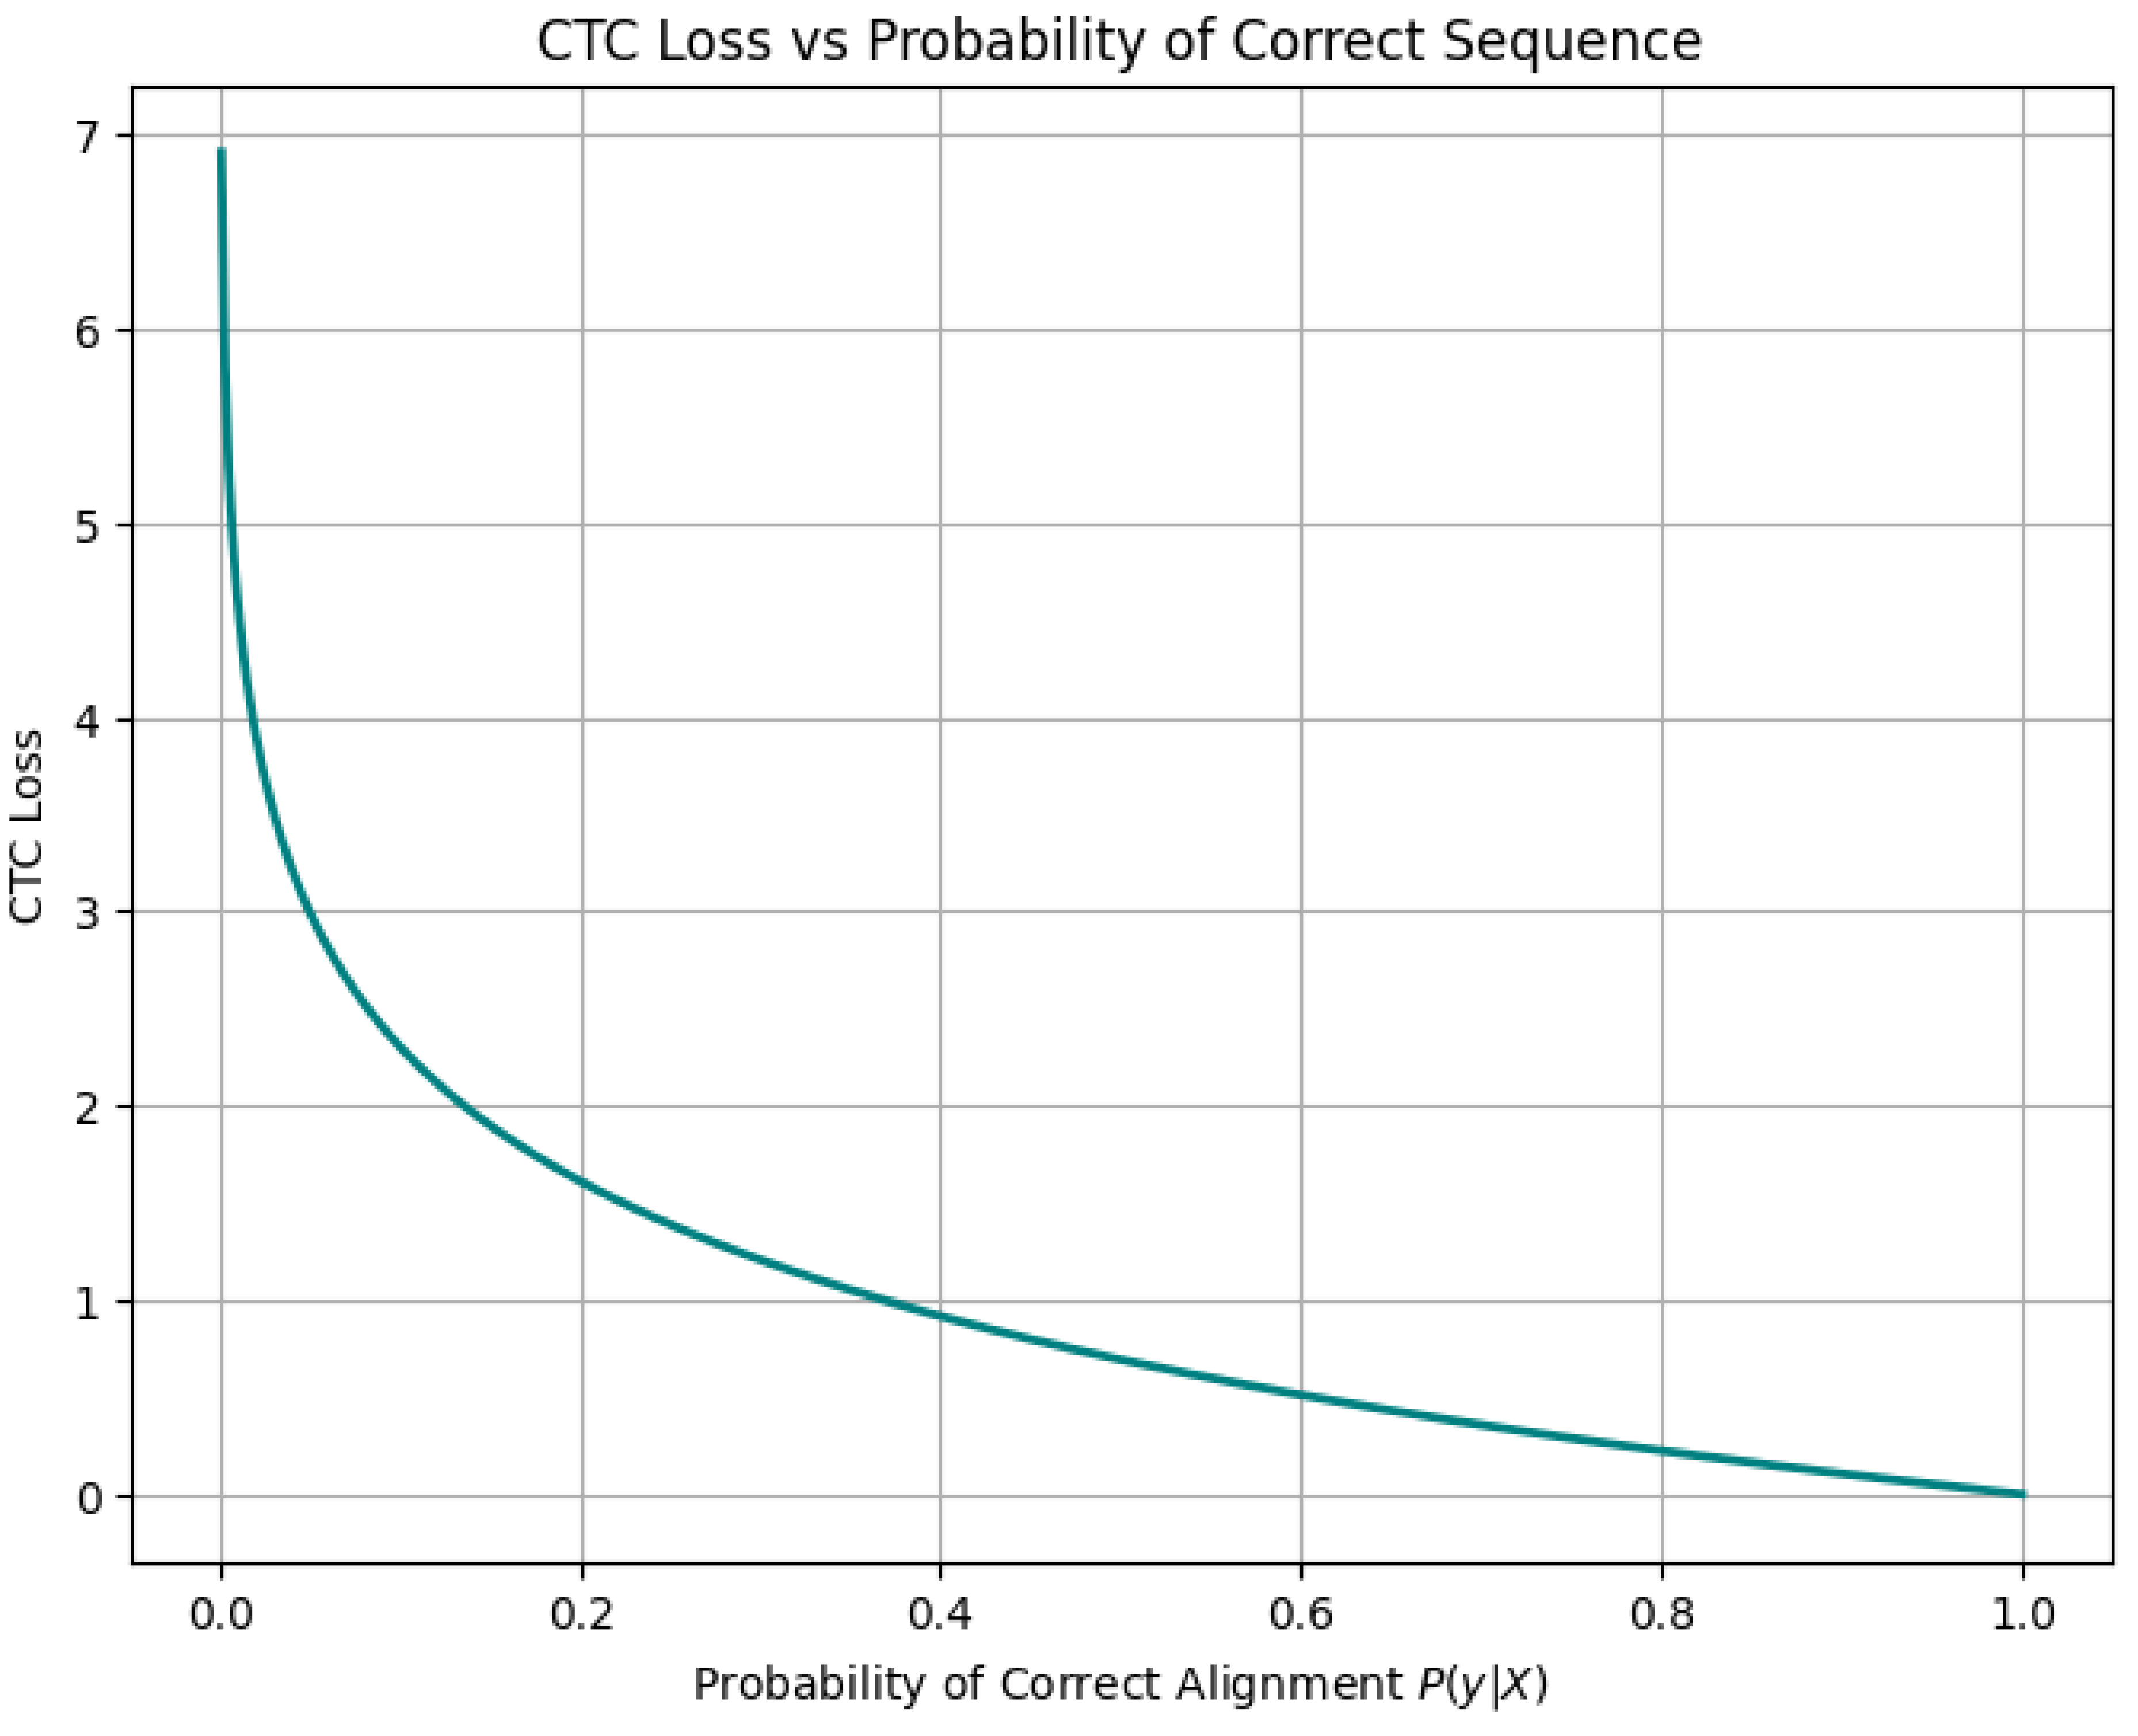
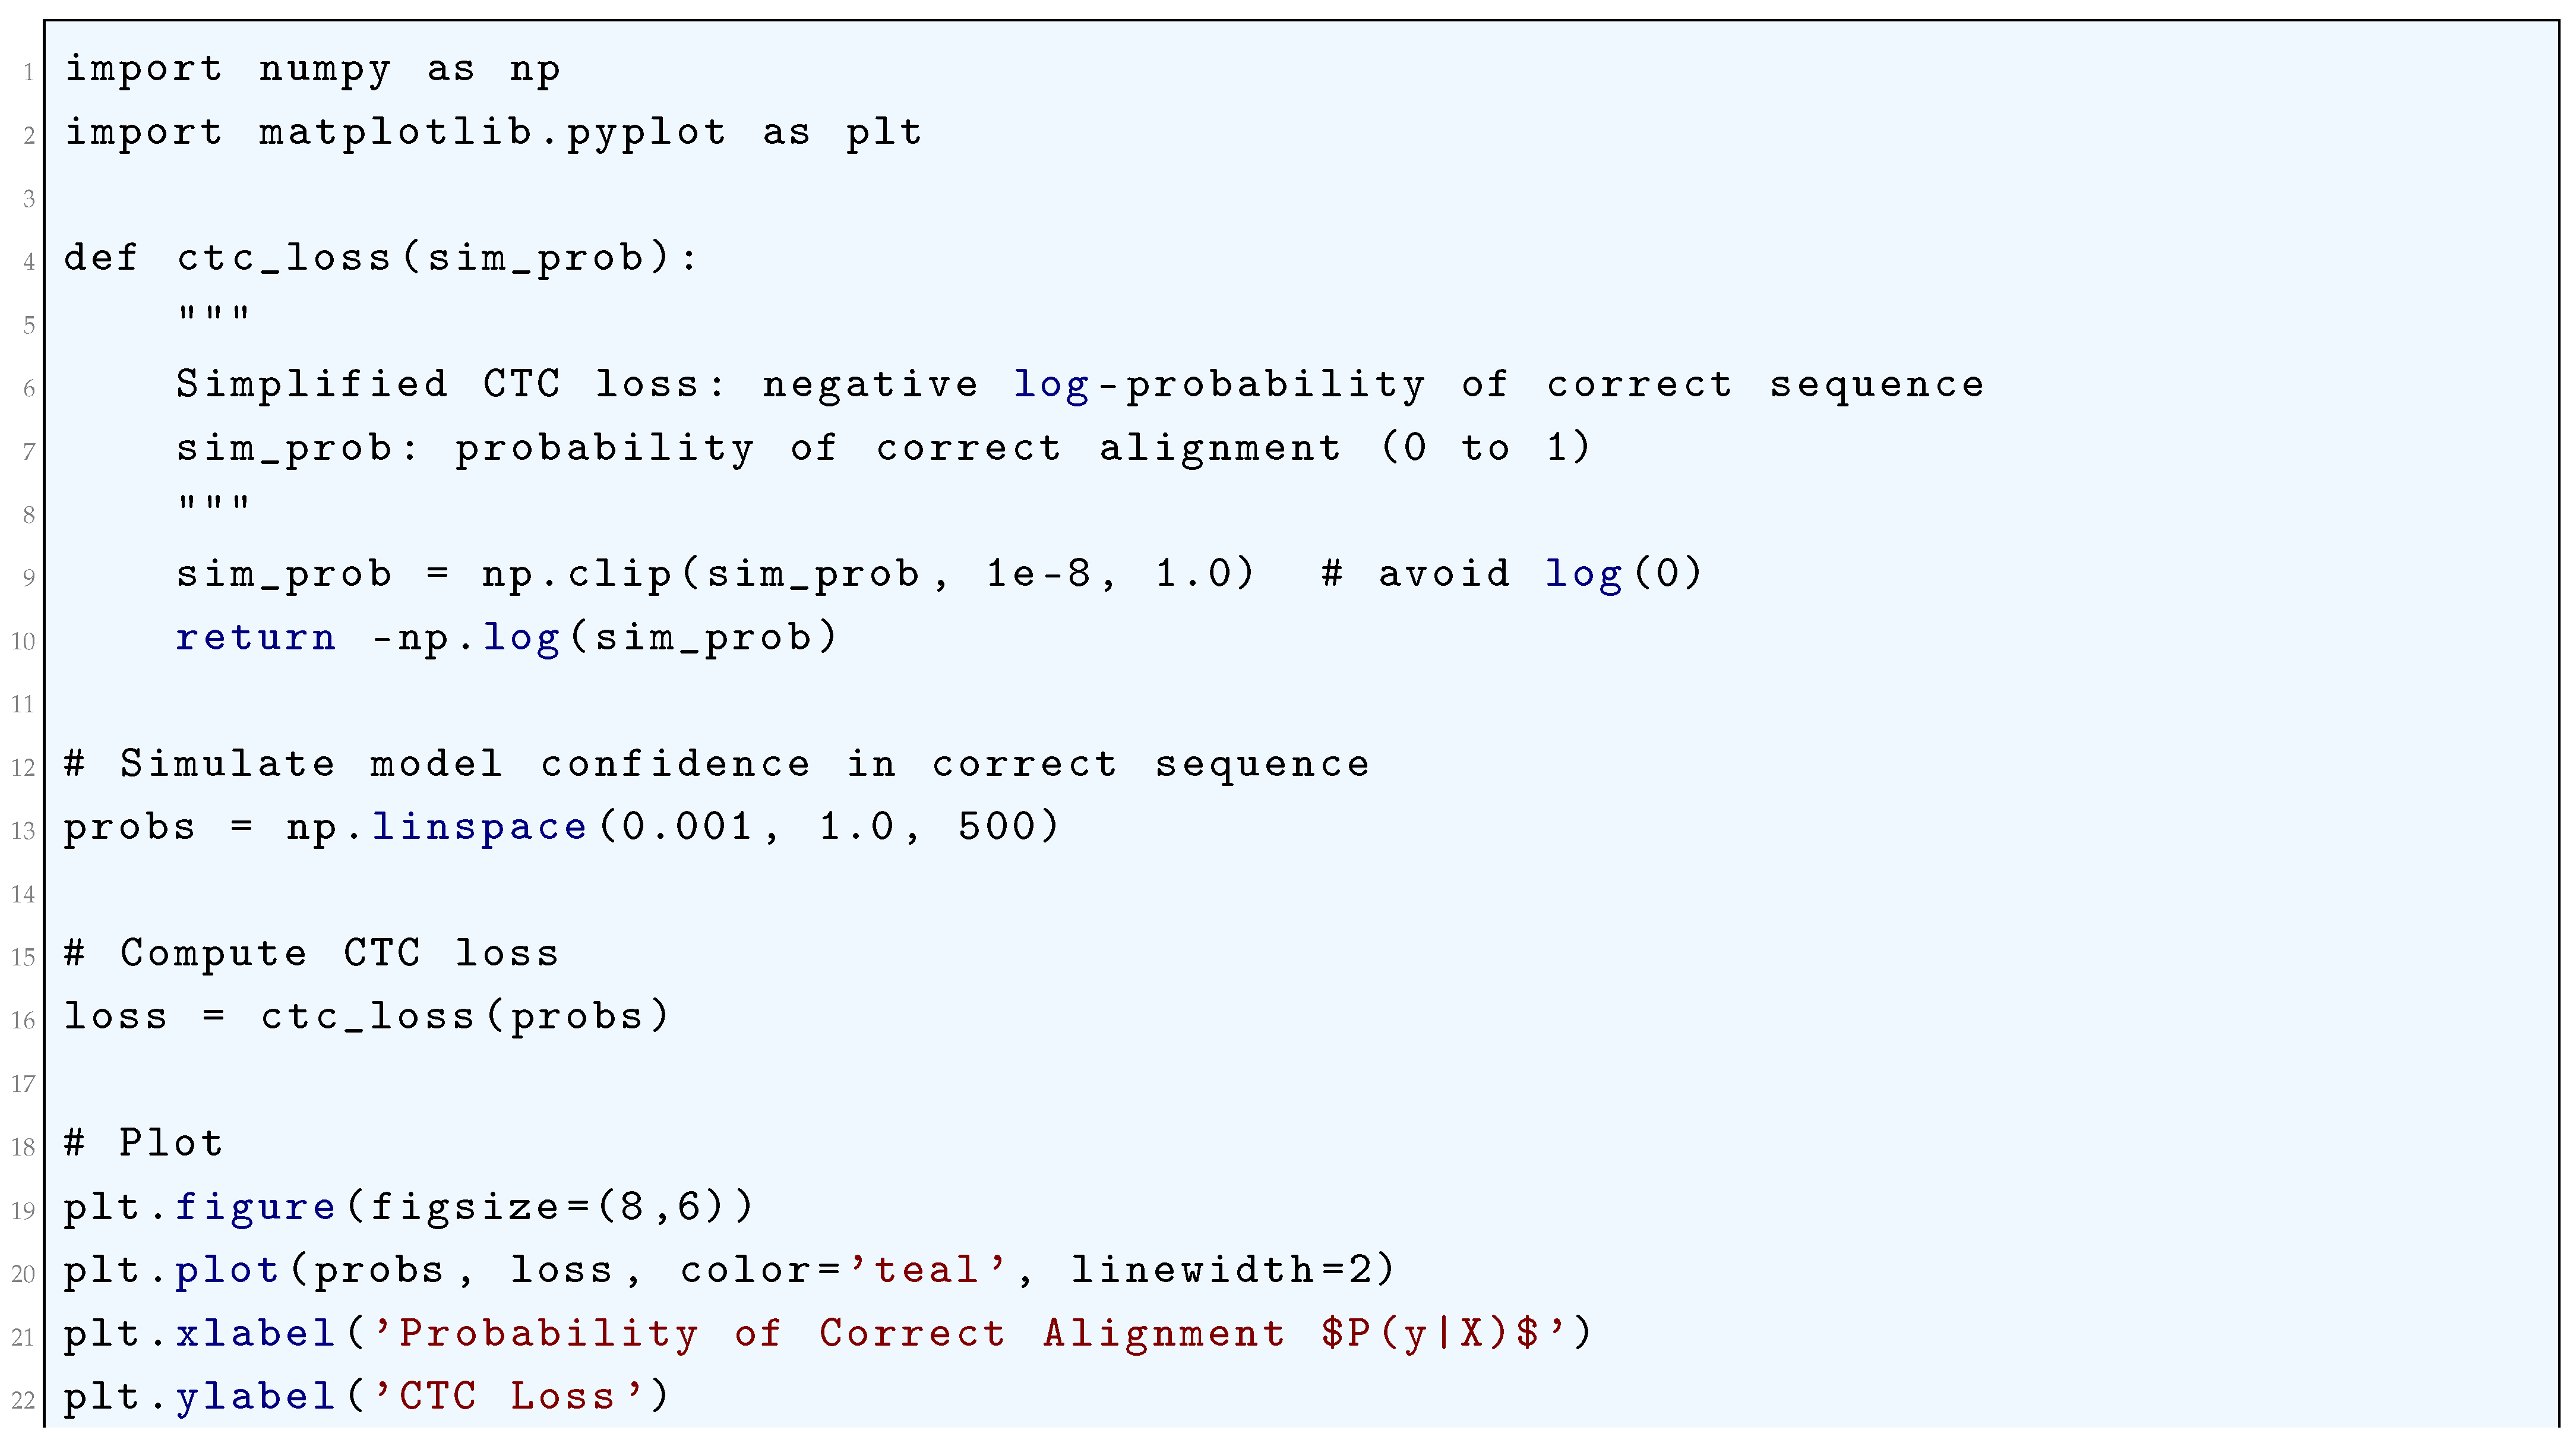

10.5.3.58 Python Code to Generate Figure 125 Illustrating Approximate CTC Loss vs Per-Timestep Probability for Different Sequence Lengths
The Python code below produces the Figure 125 illustrating Approximate CTC Loss vs Per-Timestep Probability for Different Sequence Lengths.
Figure 125.
Approximate CTC Loss vs Per-Timestep Probability for Different Sequence Lengths
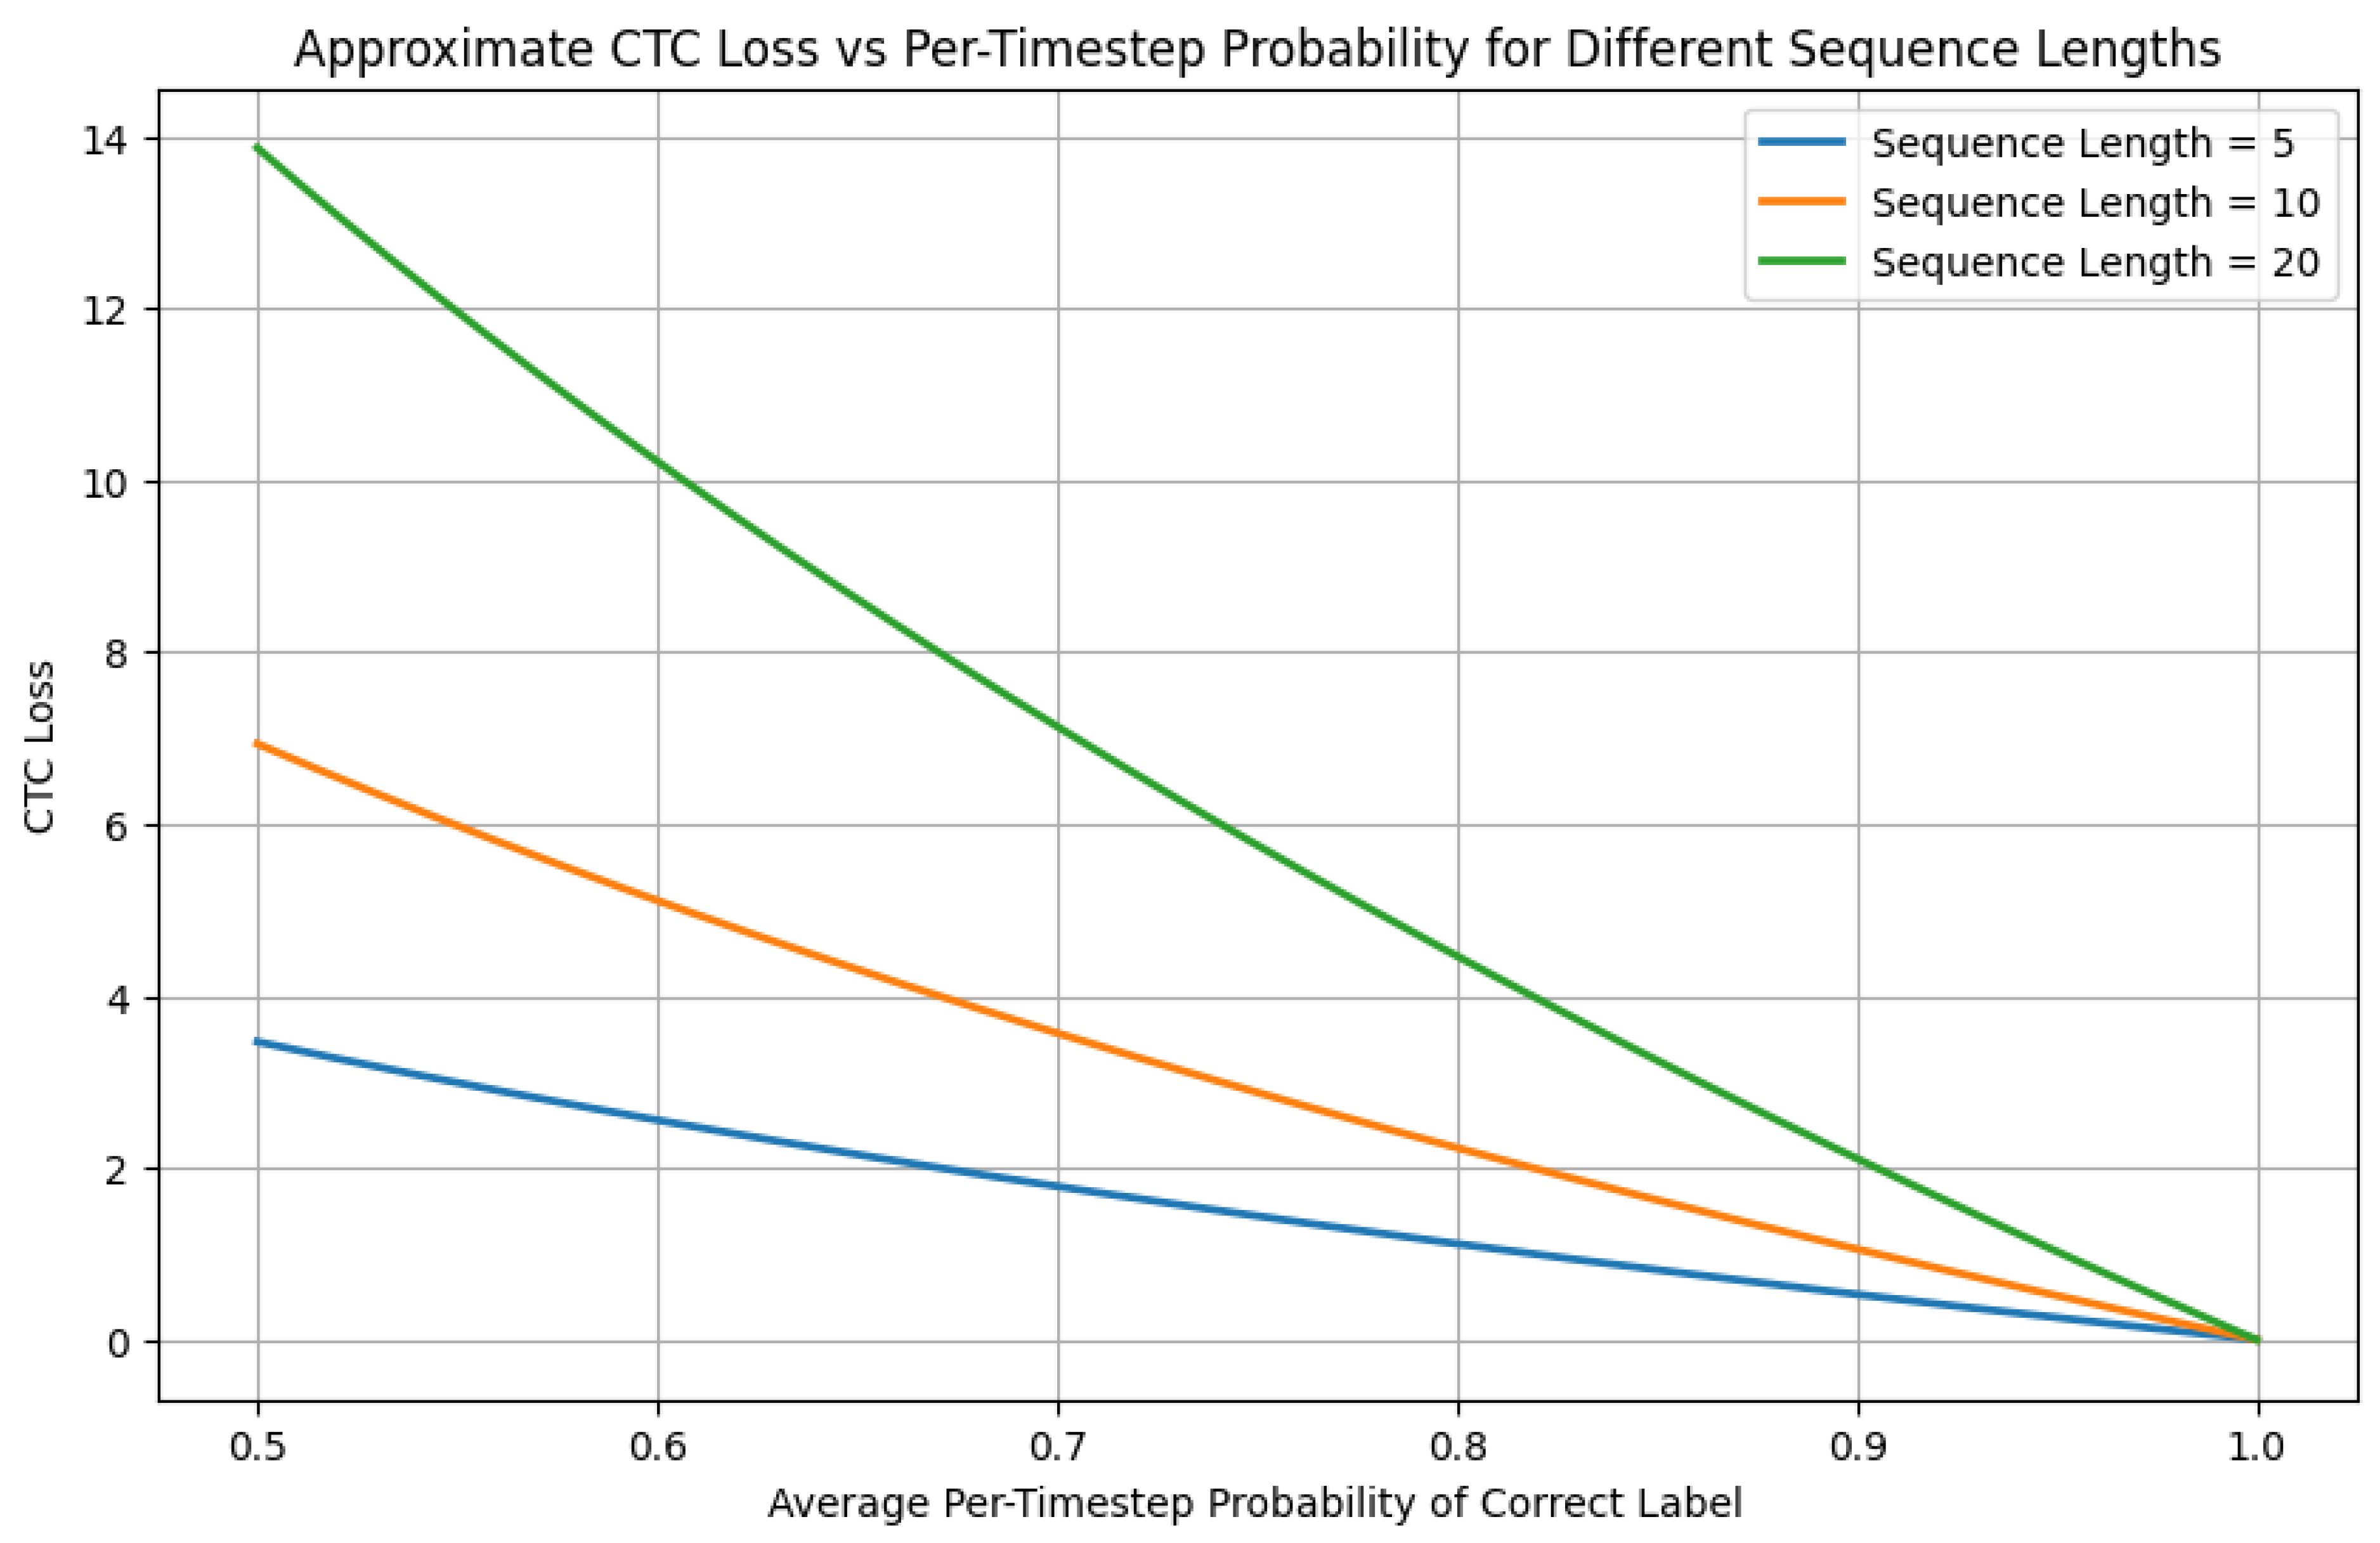
10.5.3.59 Python Code to Generate Figure 126 Illustrating CTC Loss Surface vs Sequence Length and Per-Timestep Probability
The Python code below produces the Figure 126 illustrating CTC Loss Surface vs Sequence Length and Per-Timestep Probability.
Figure 126.
CTC Loss Surface vs Sequence Length and Per-Timestep Probability
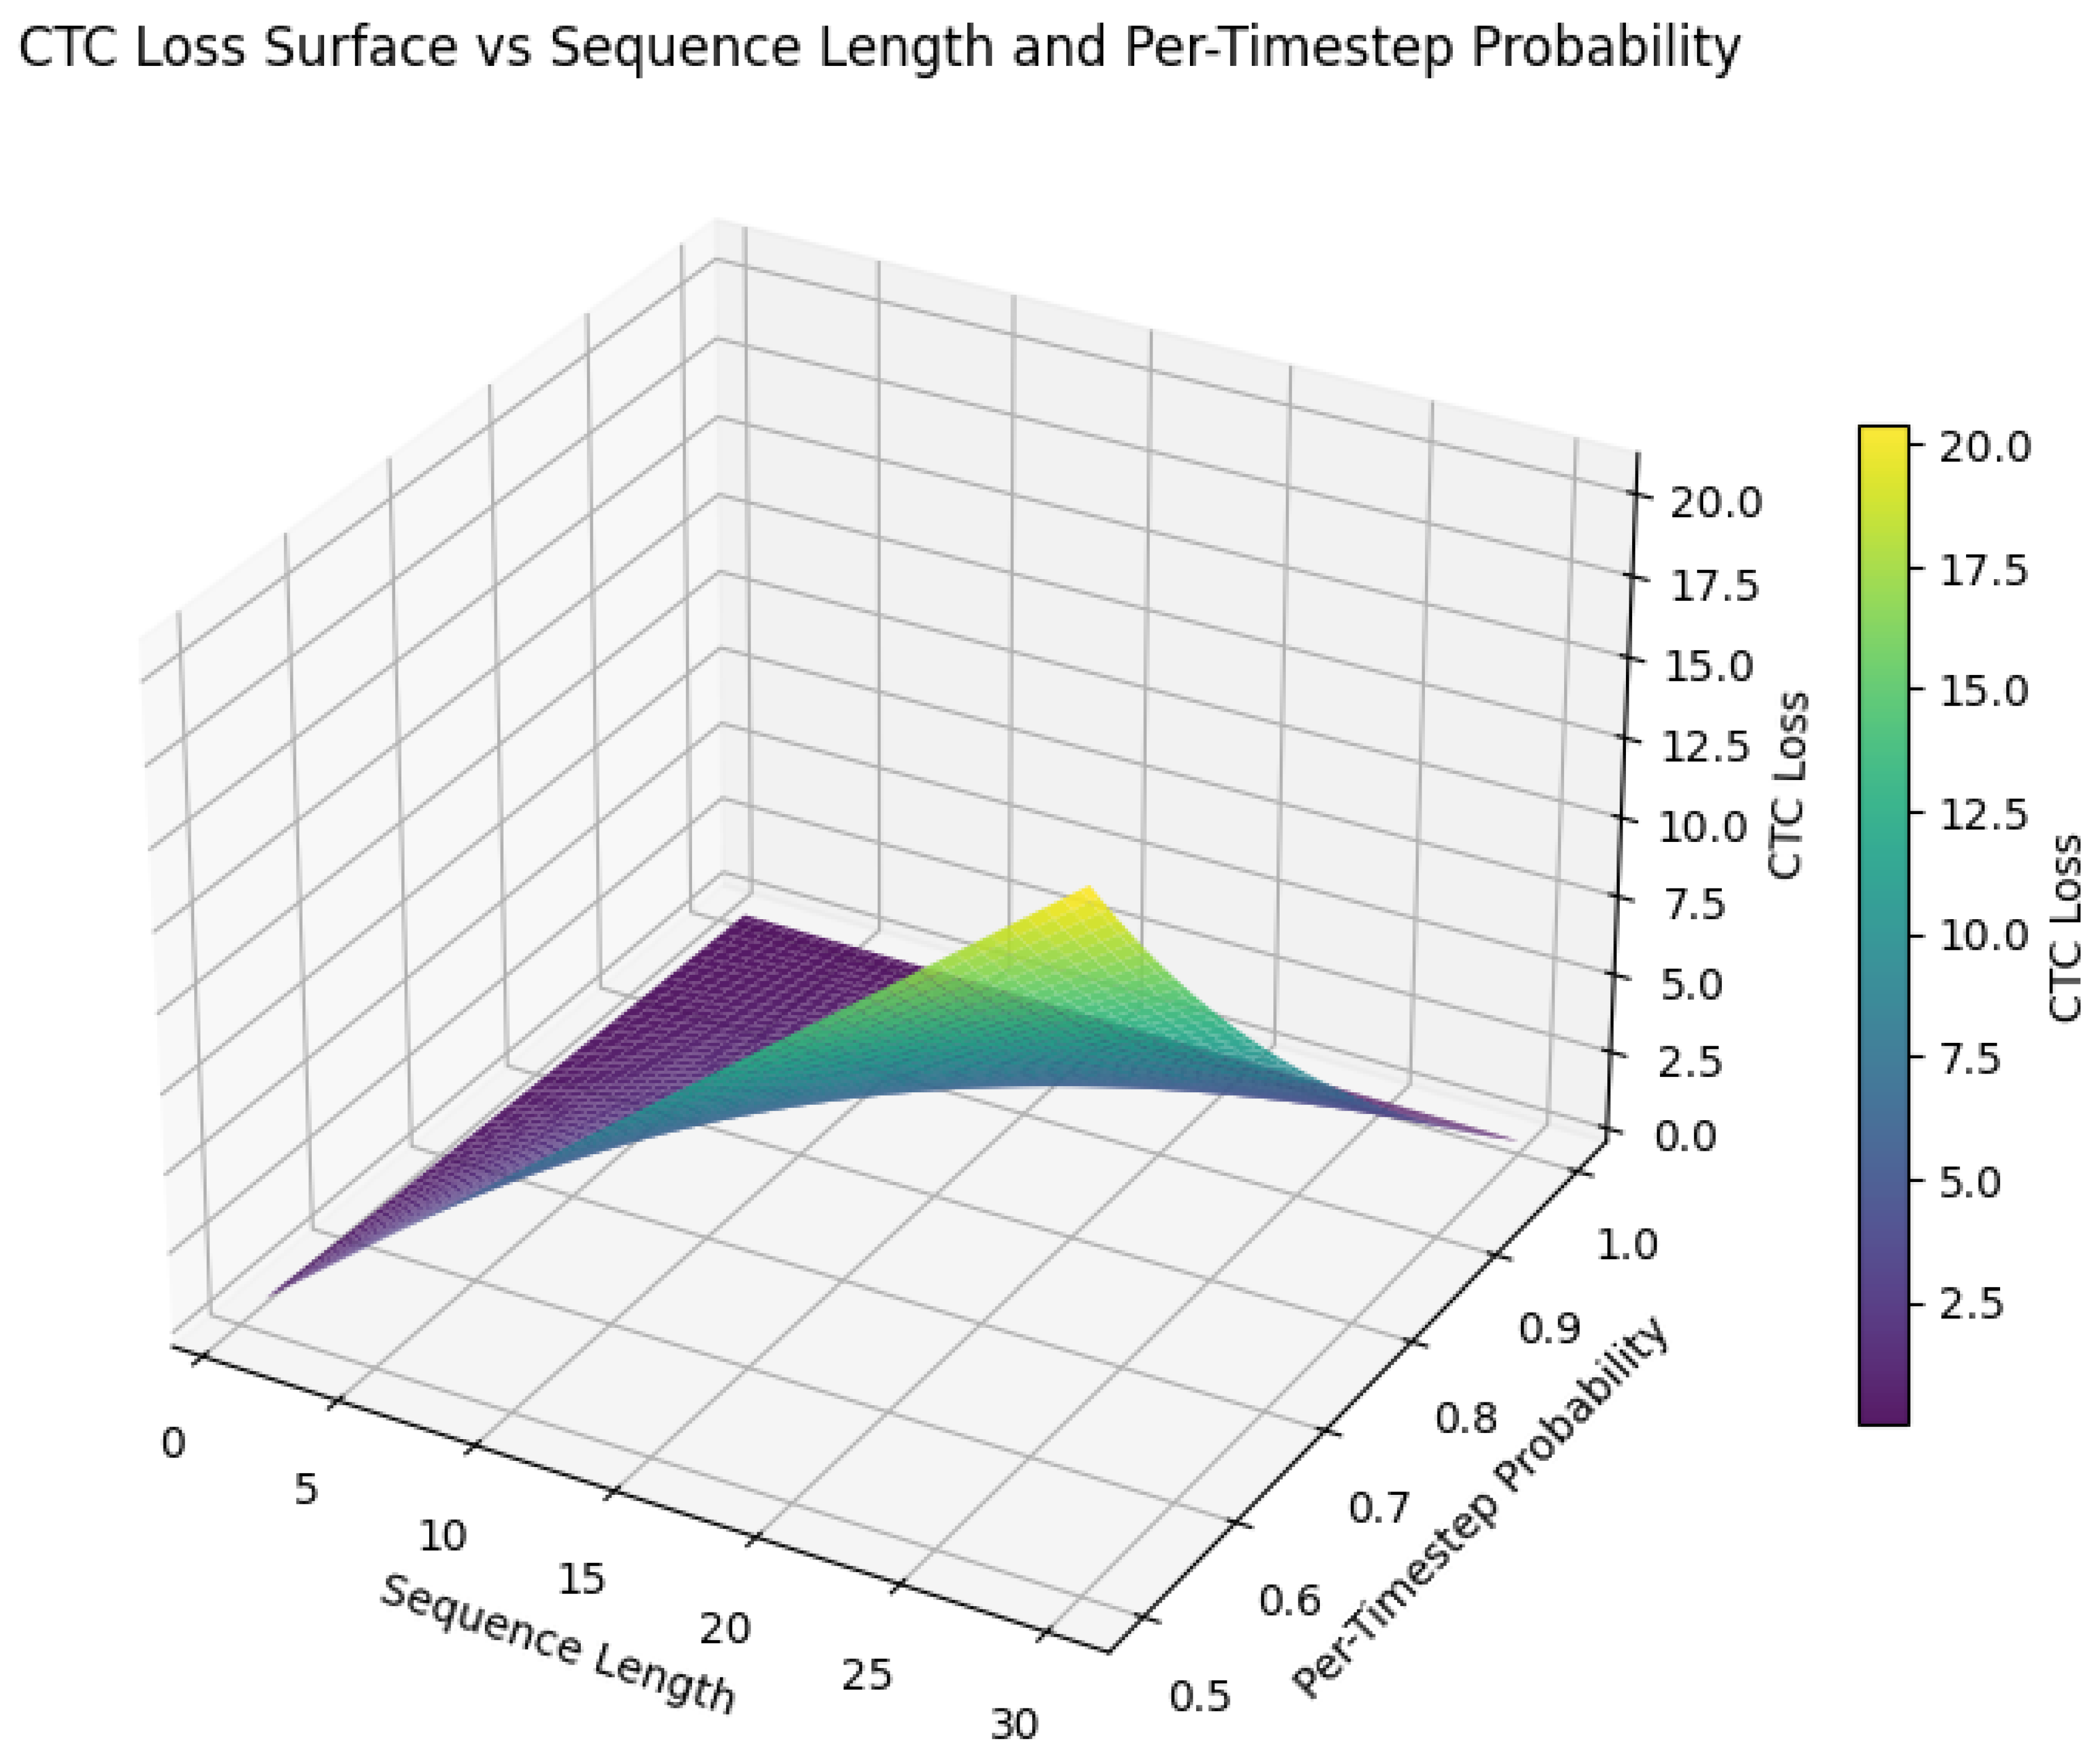
10.5.3.60 Python Code to Generate Figure 127 Illustrating CTC Loss Contour vs Sequence Length and Per-Timestep Probability
The Python code below produces the Figure 127 illustrating CTC Loss Contour vs Sequence Length and Per-Timestep Probability.
Figure 127.
CTC Loss Contour vs Sequence Length and Per-Timestep Probability
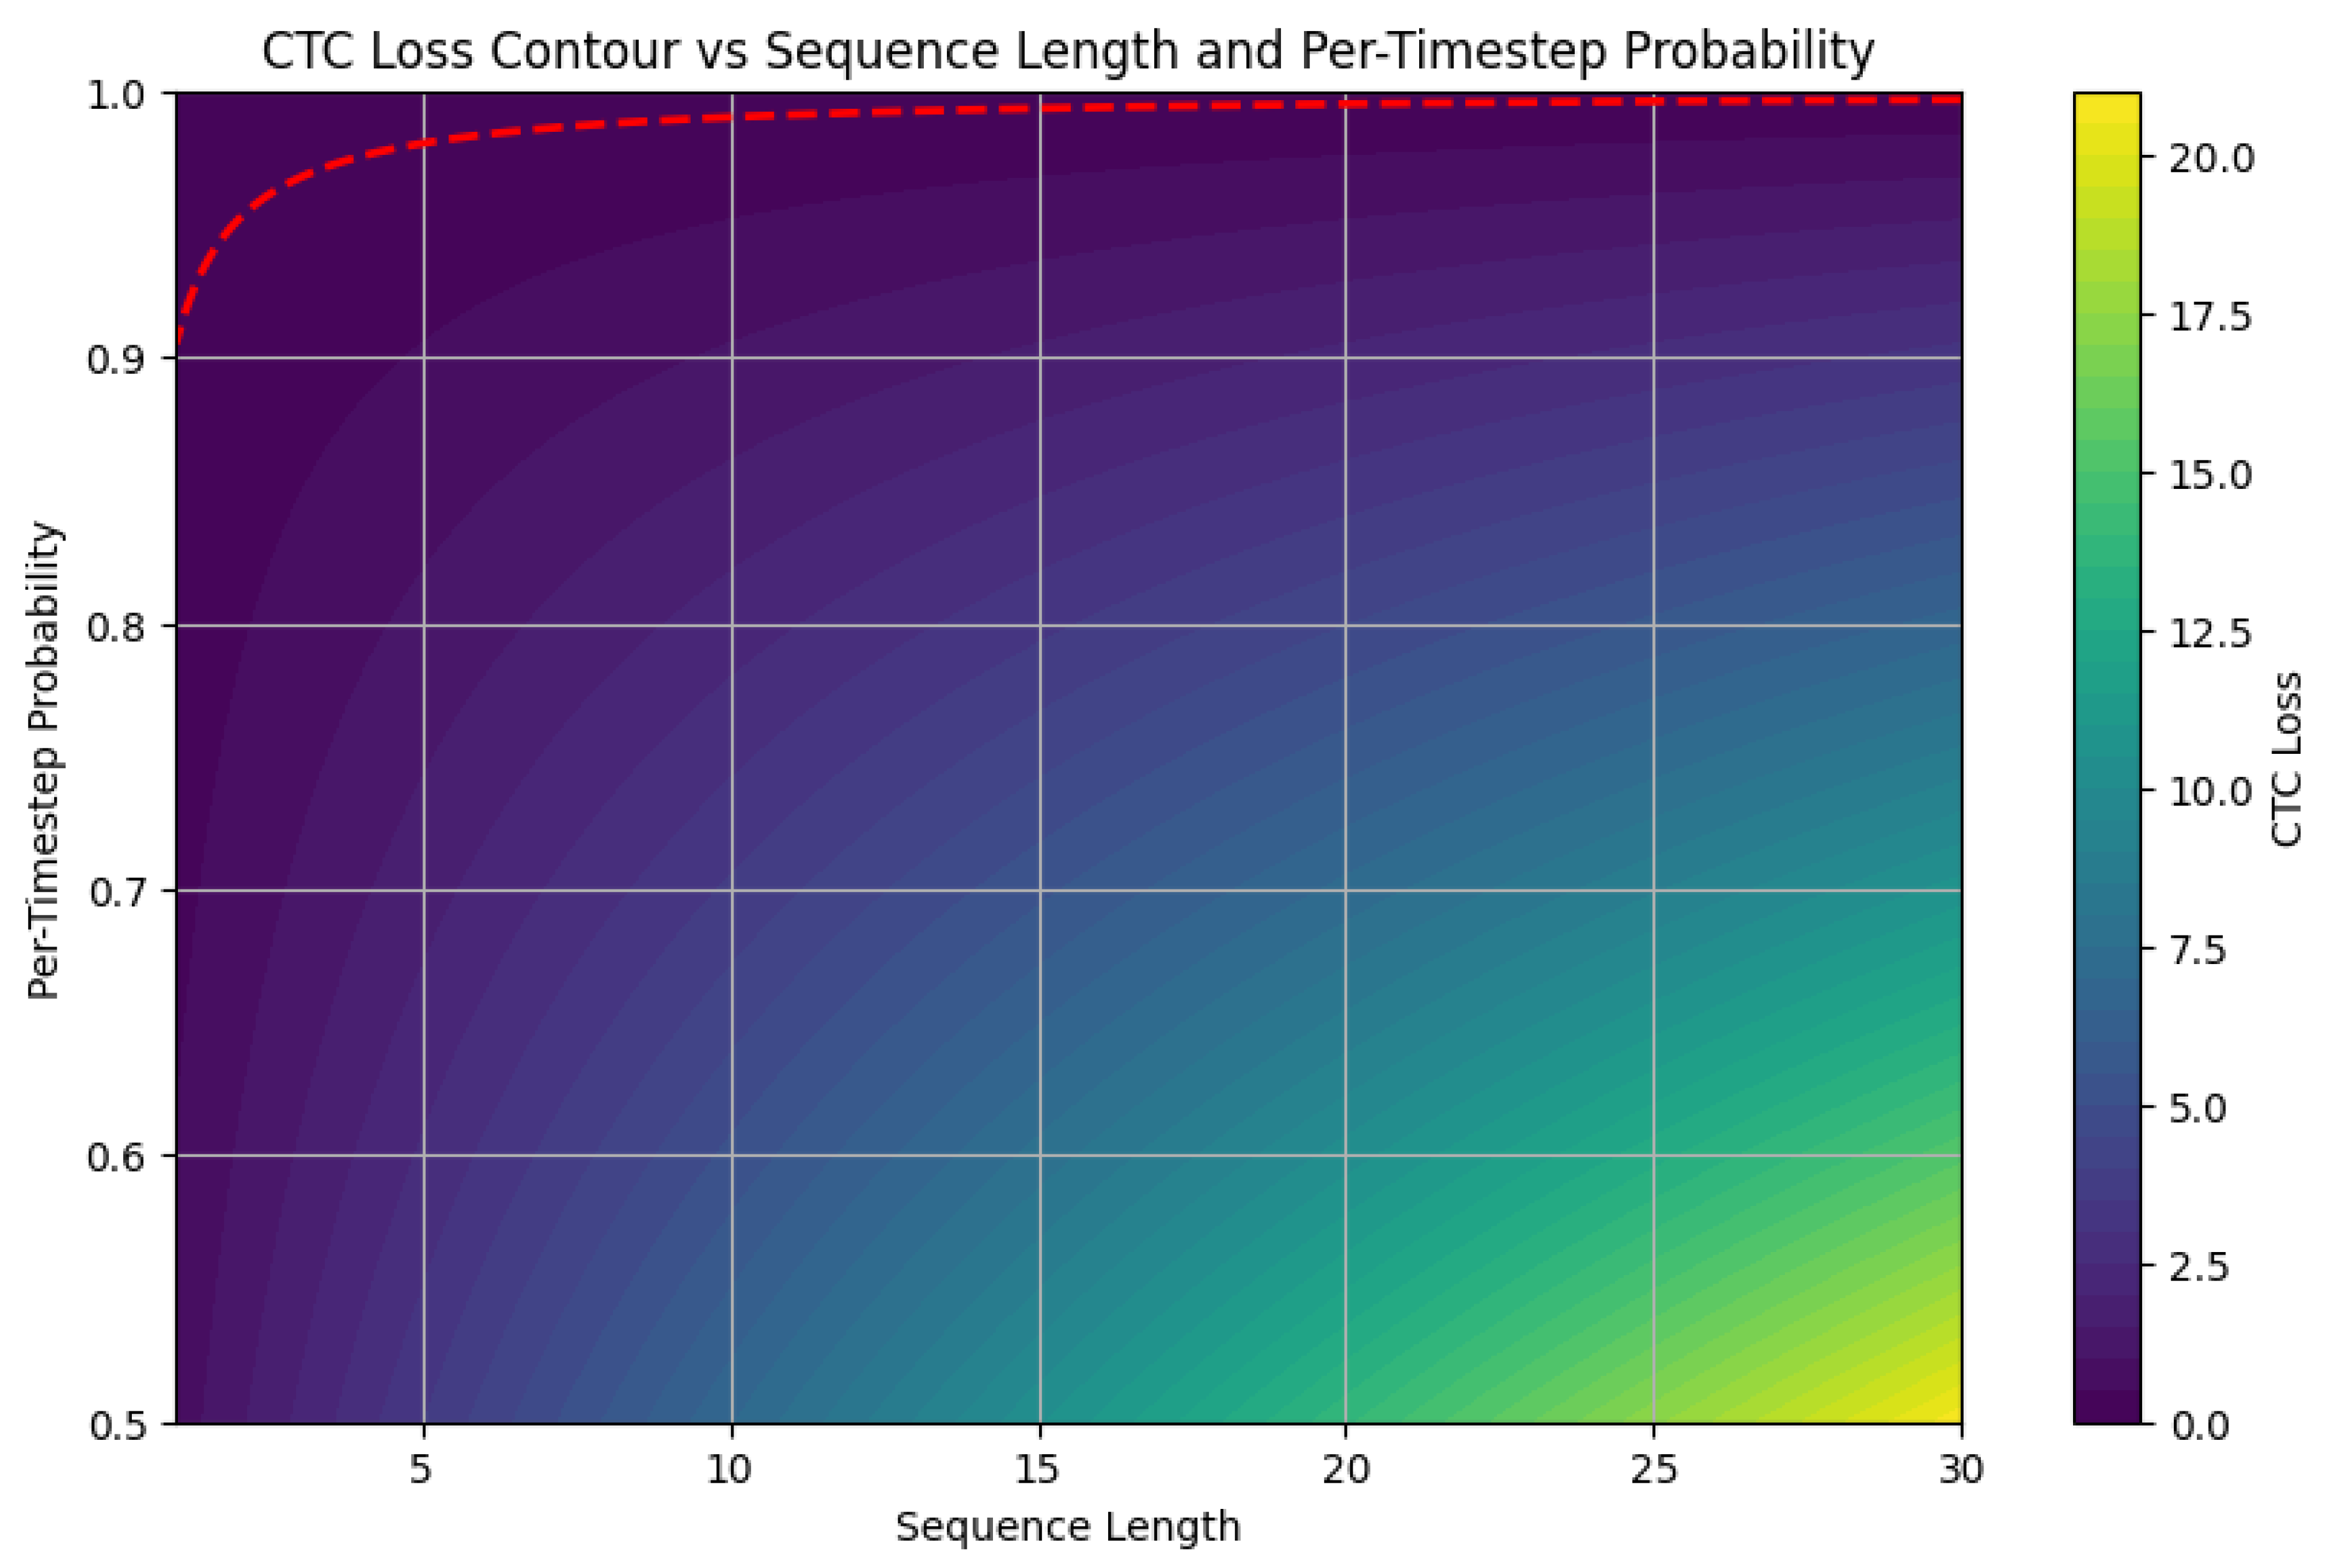
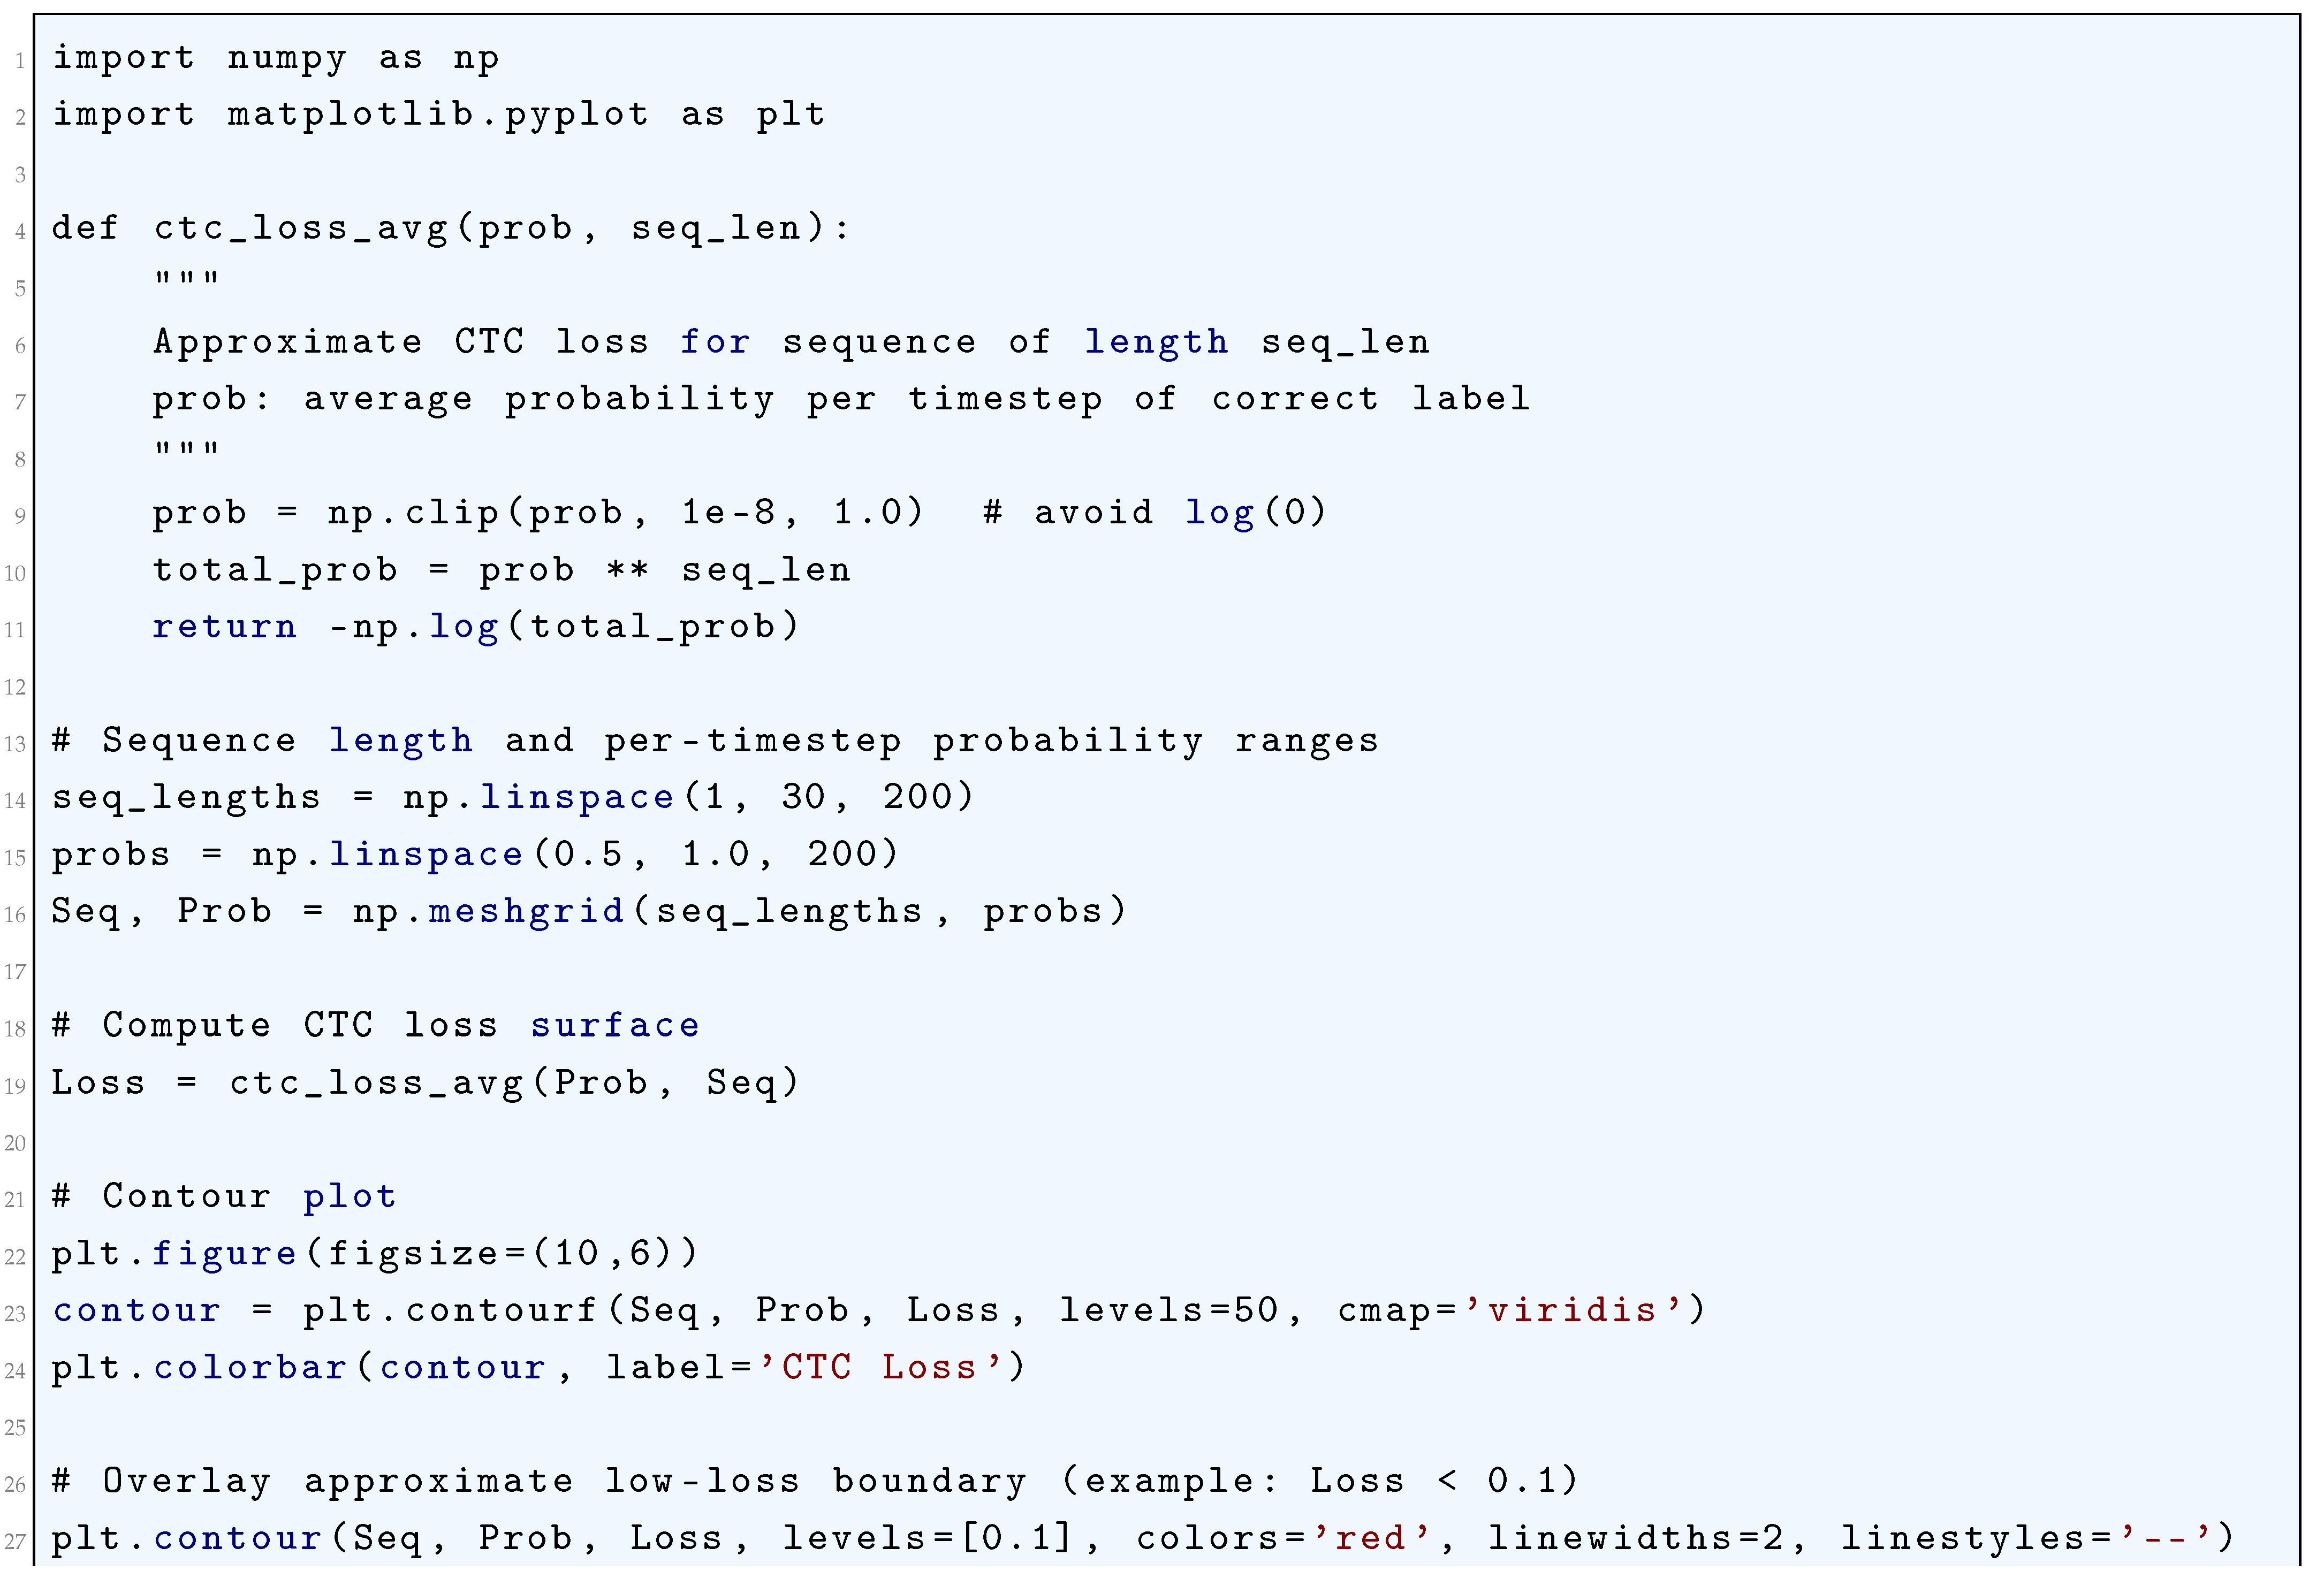
10.5.3.61 Python Code to Generate Figure 128 Illustrating Maximum Margin Markov Networks (M³N) Loss
The Python code below produces the Figure 128 illustrating Maximum Margin Markov Networks (M³N) Loss.
Figure 128.
Maximum Margin Markov Networks (M³N) Loss
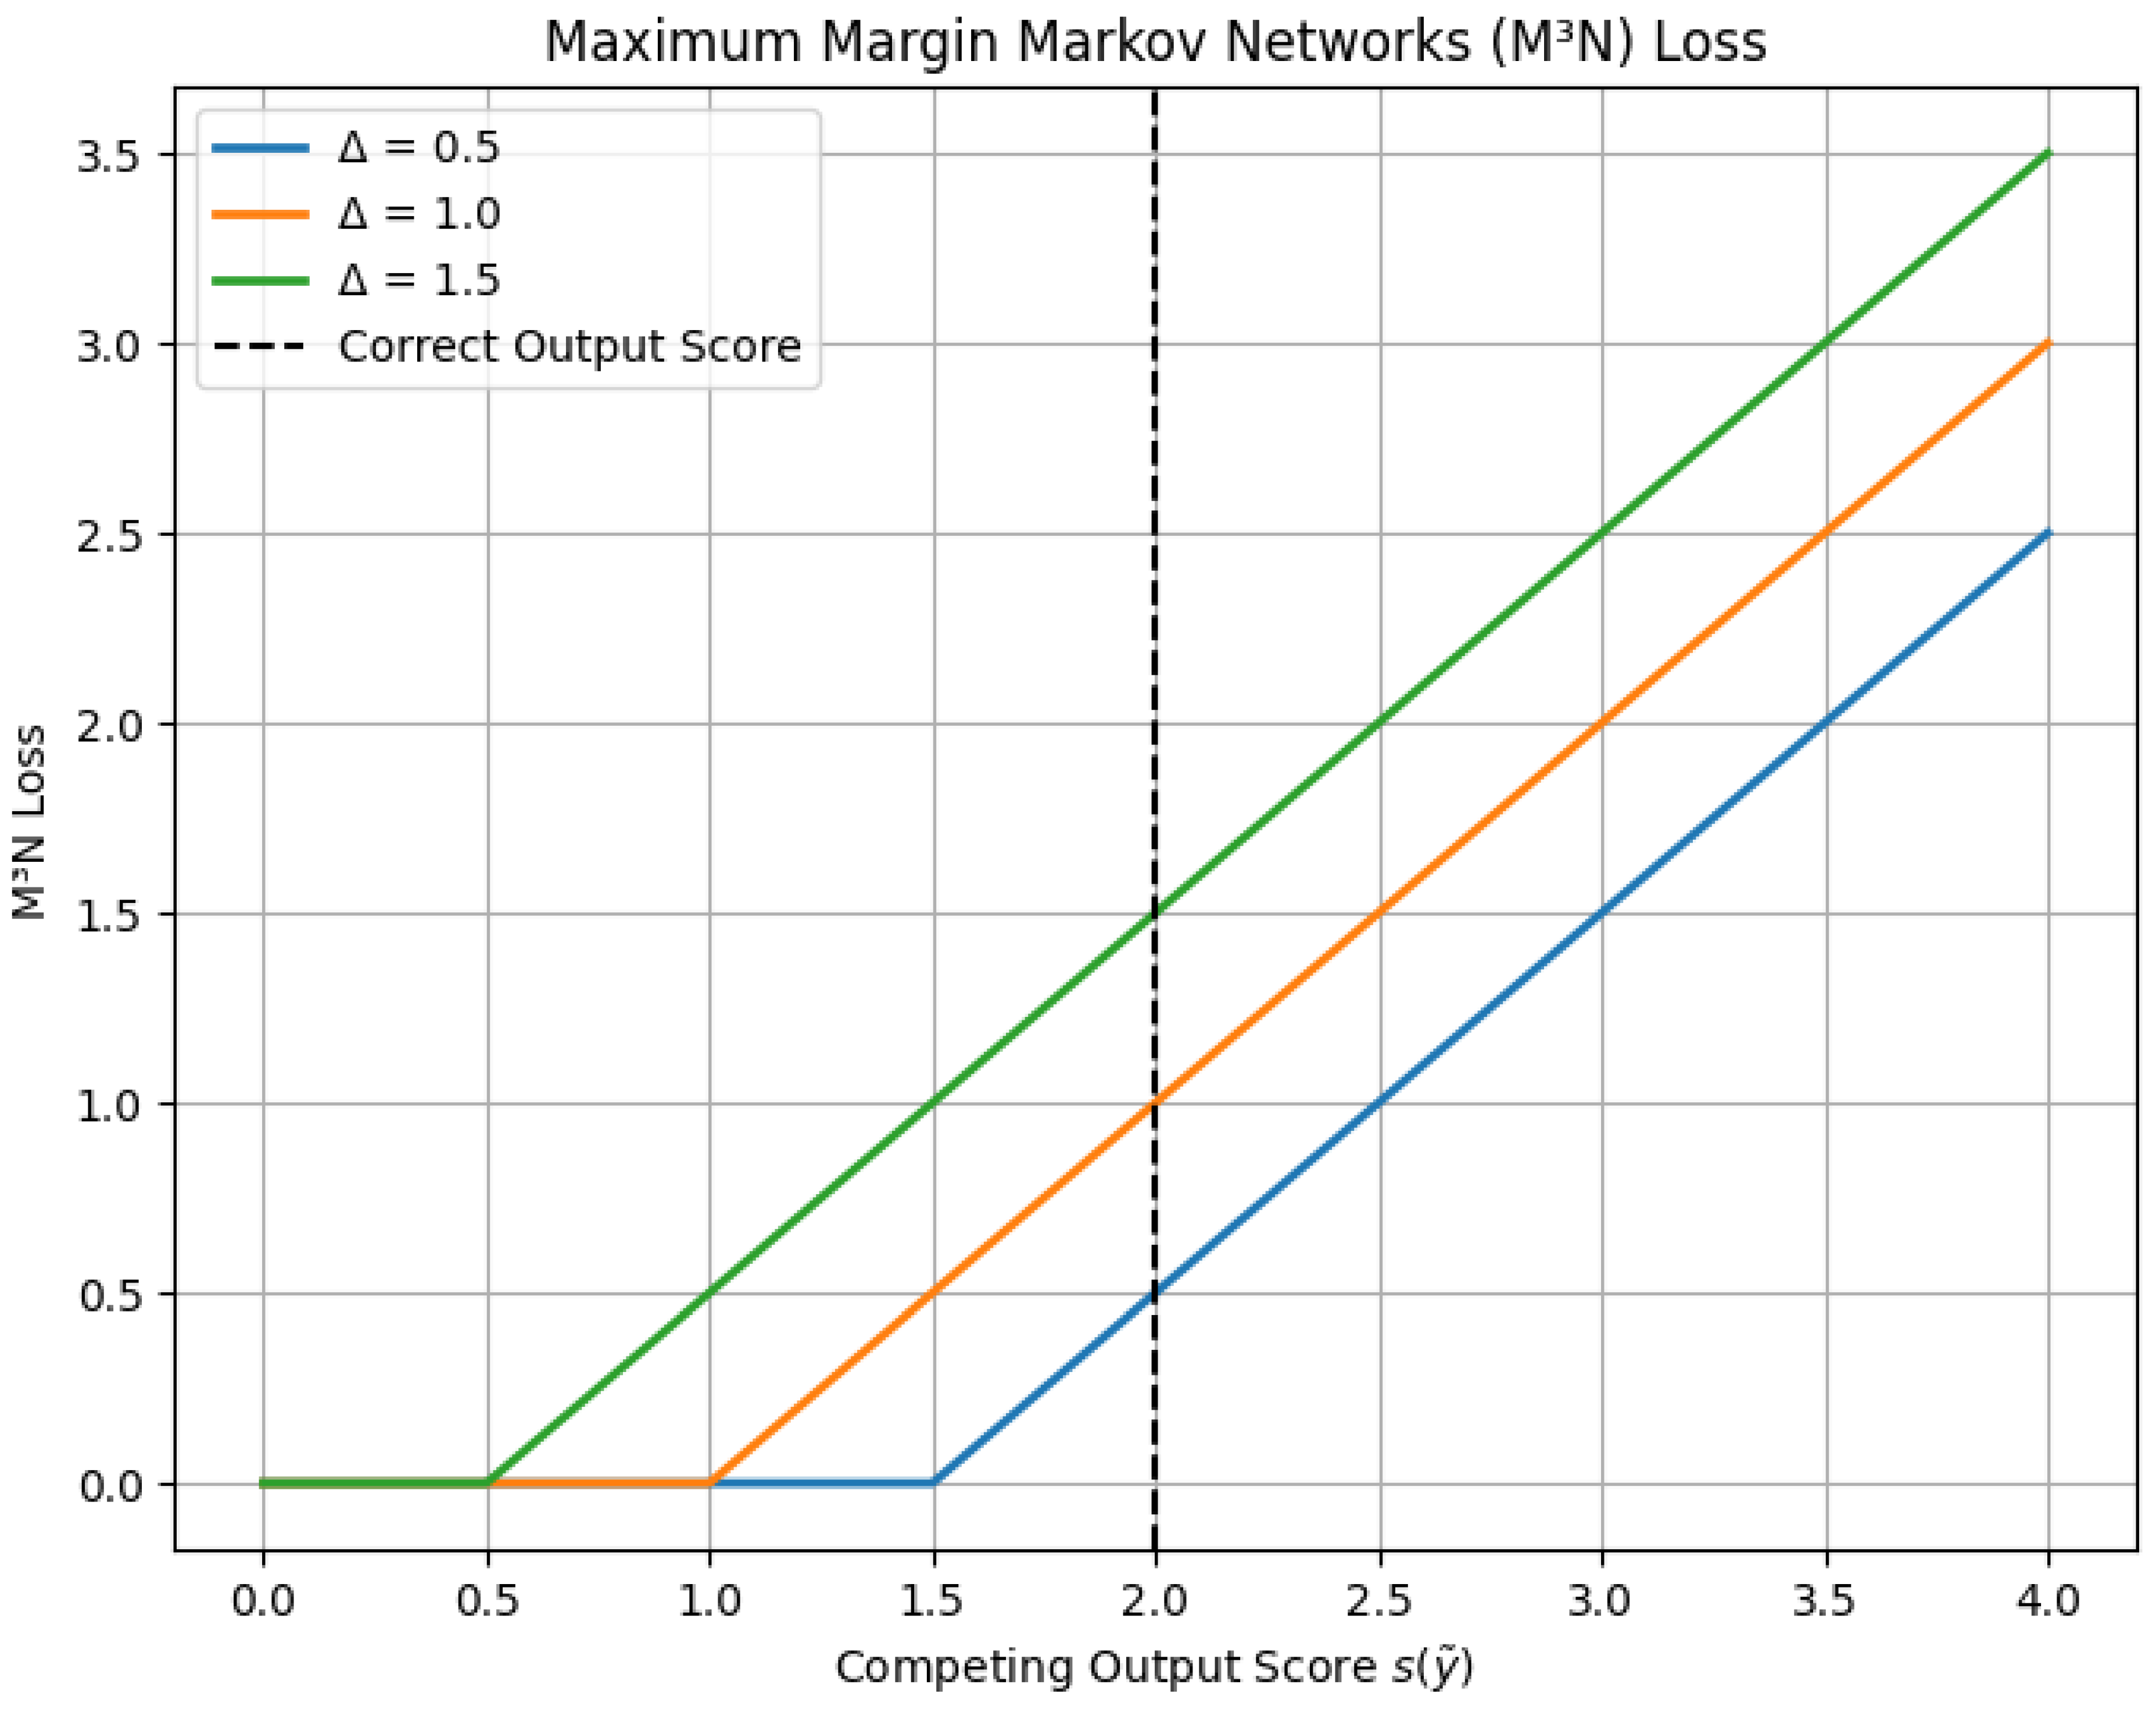
10.5.3.62 Python Code to Generate Figure 129 Illustrating M³N Loss Surface ()
The Python code below produces the Figure 129 illustrating M³N Loss Surface ().
Figure 129.
M³N Loss Surface ()
10.5.3.63 Python Code to Generate Figure 130 Illustrating Contour Plot of M³N Loss ()
The Python code below produces the Figure 130 illustrating Contour Plot of M³N Loss ().
Figure 130.
Contour Plot of M³N Loss ()
10.5.3.64 Python Code to Generate Figure 131 Illustrating Listwise Ranking Losses (ListNet vs ListMLE)
The Python code below produces the Figure 131 illustrating Listwise Ranking Losses (ListNet vs ListMLE).
Figure 131.
Listwise Ranking Losses (ListNet vs ListMLE)
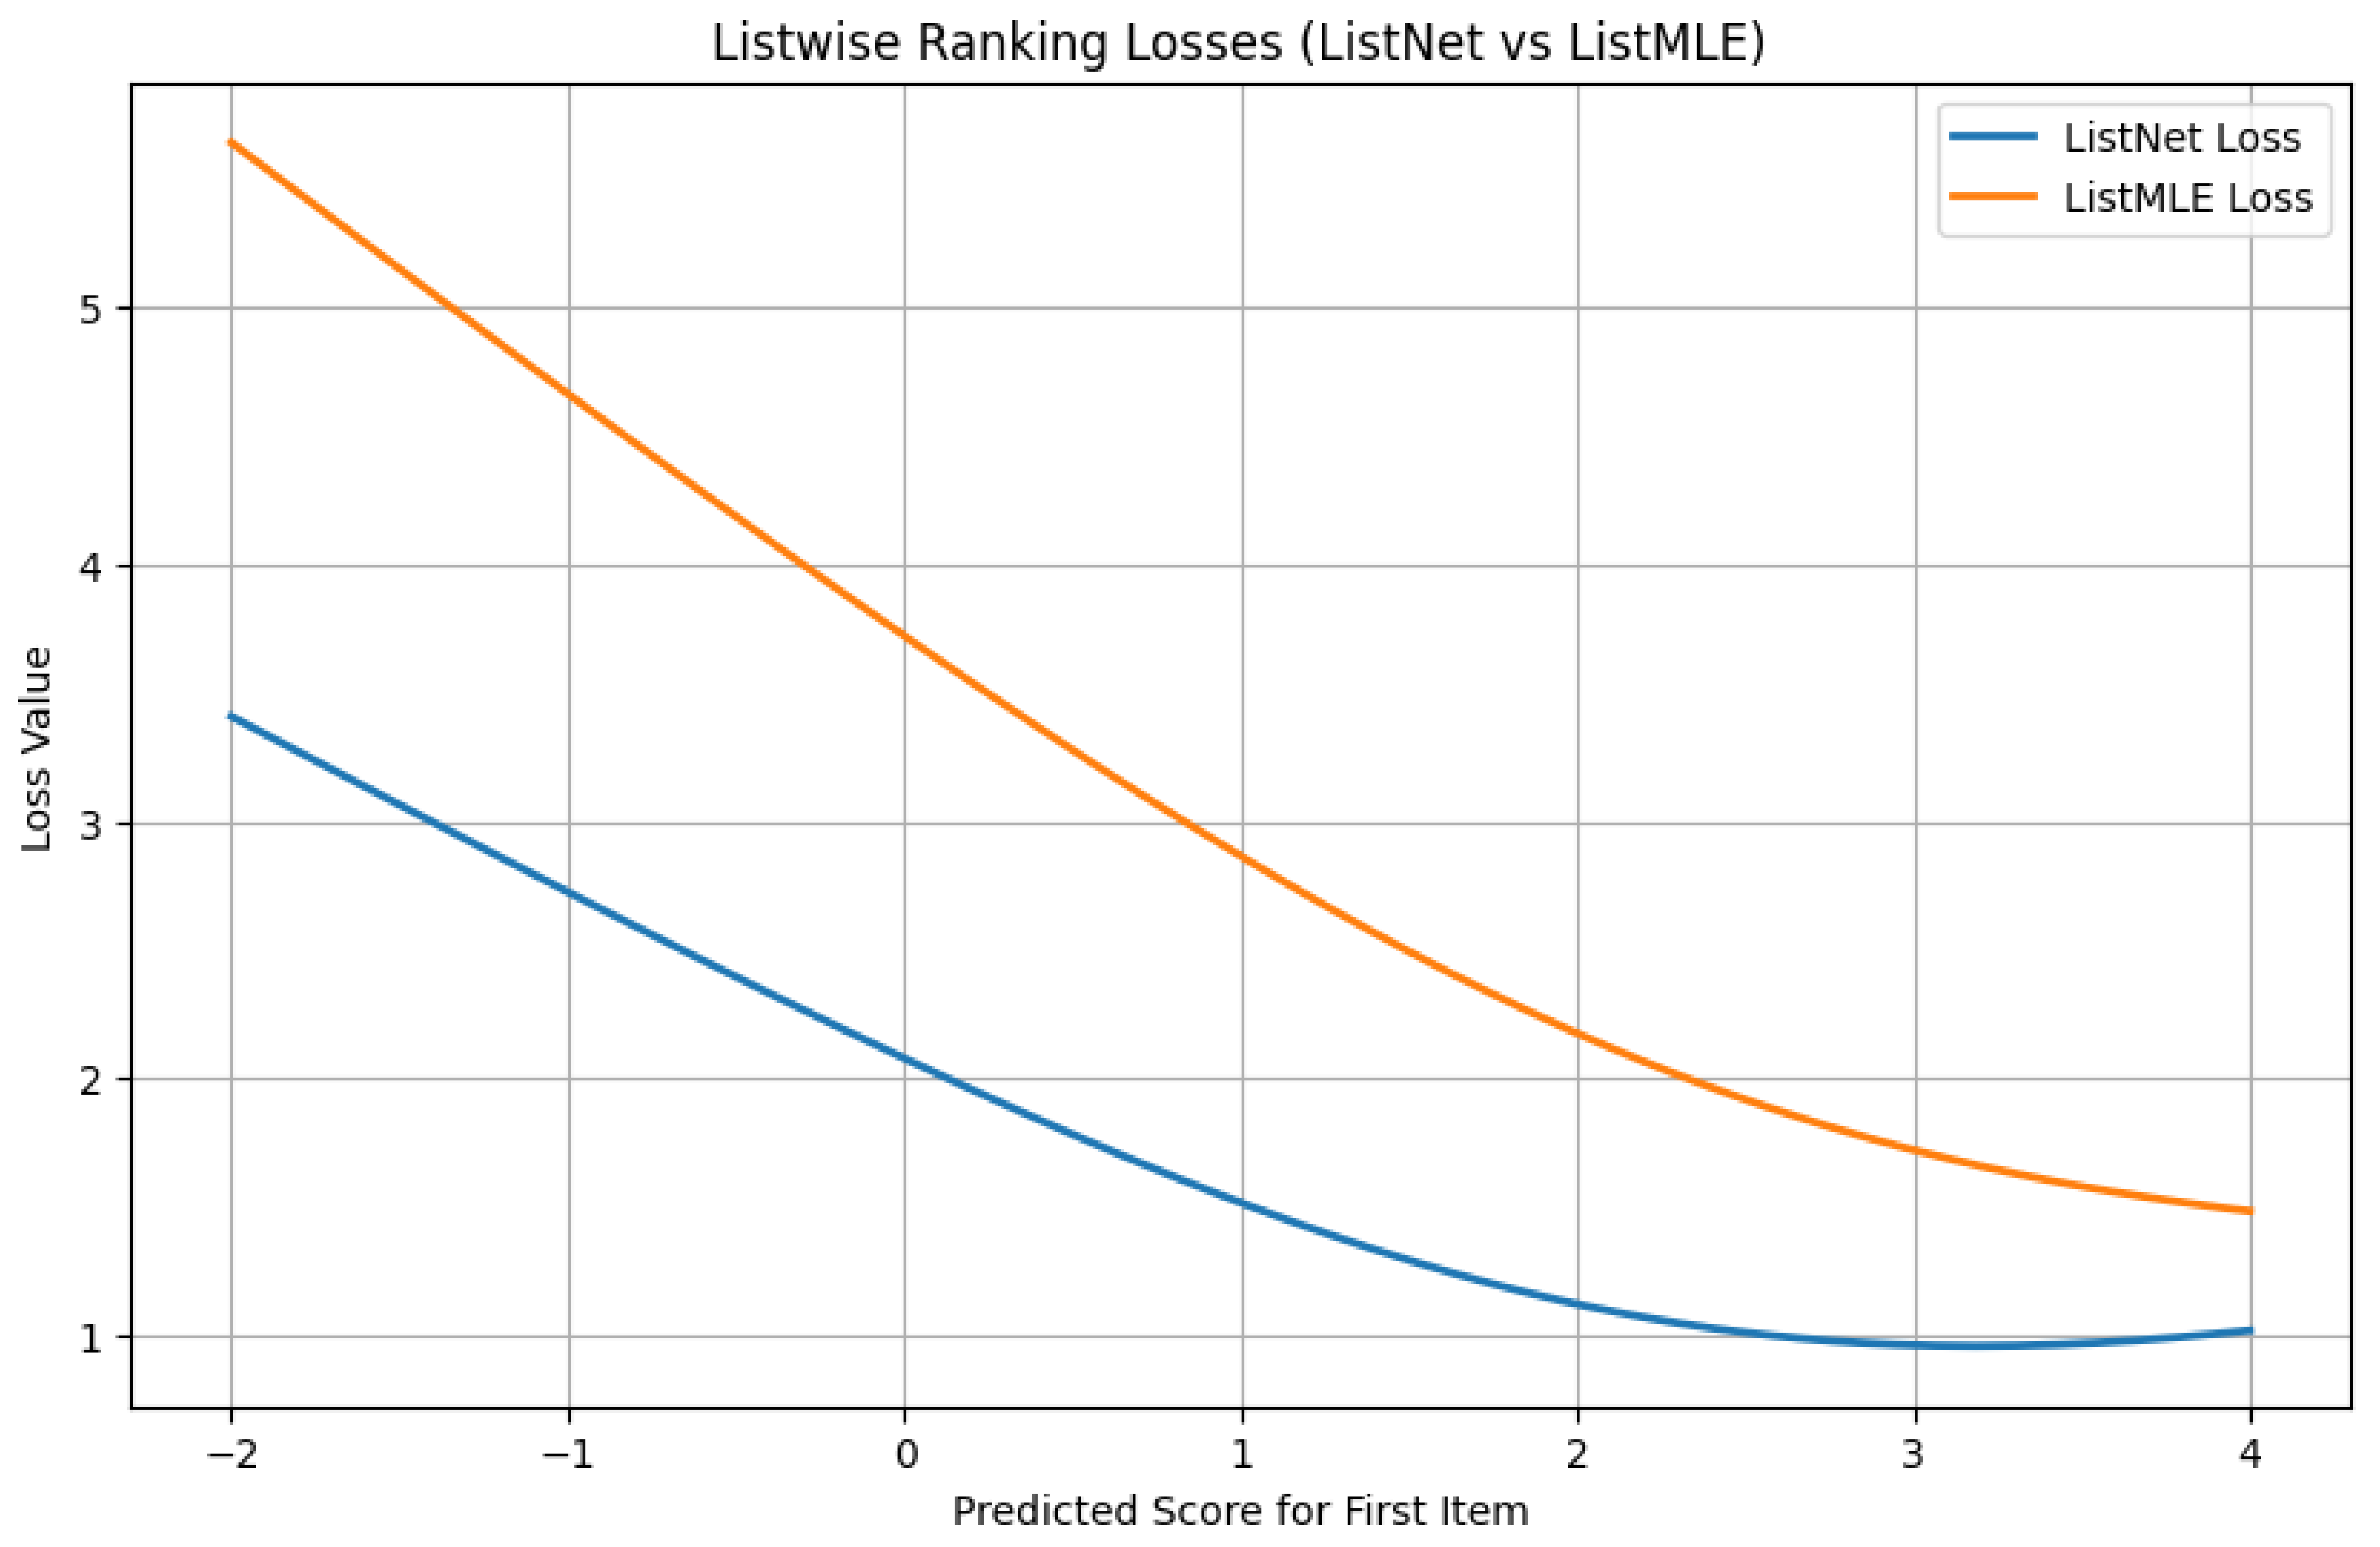
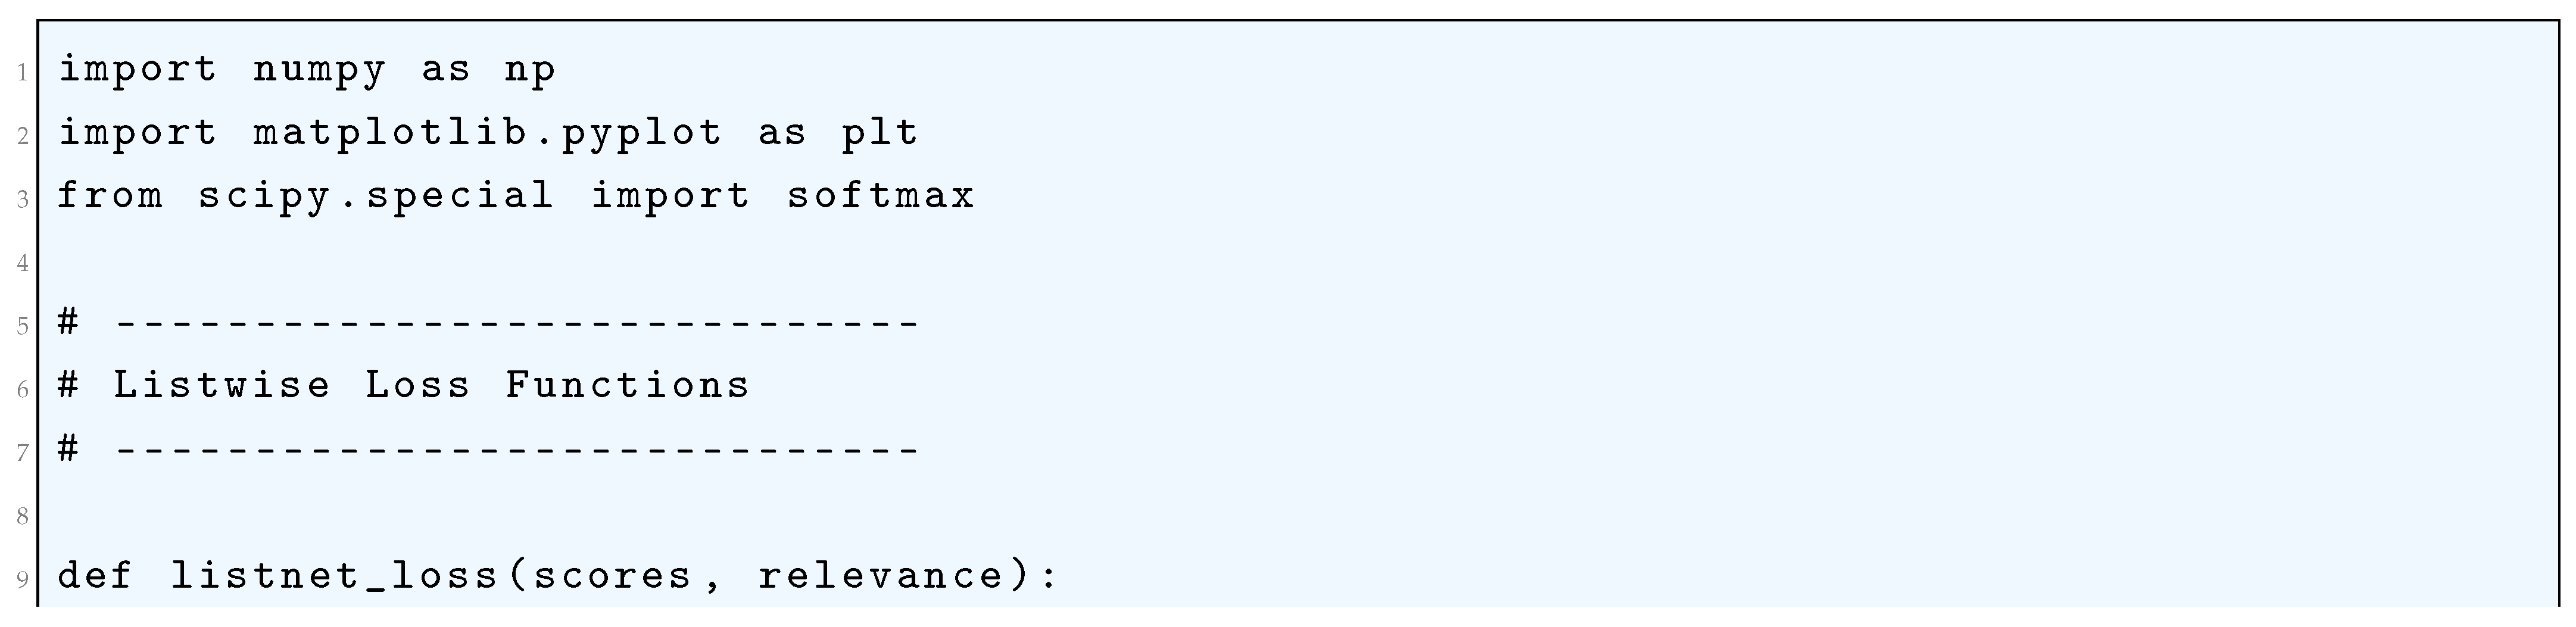
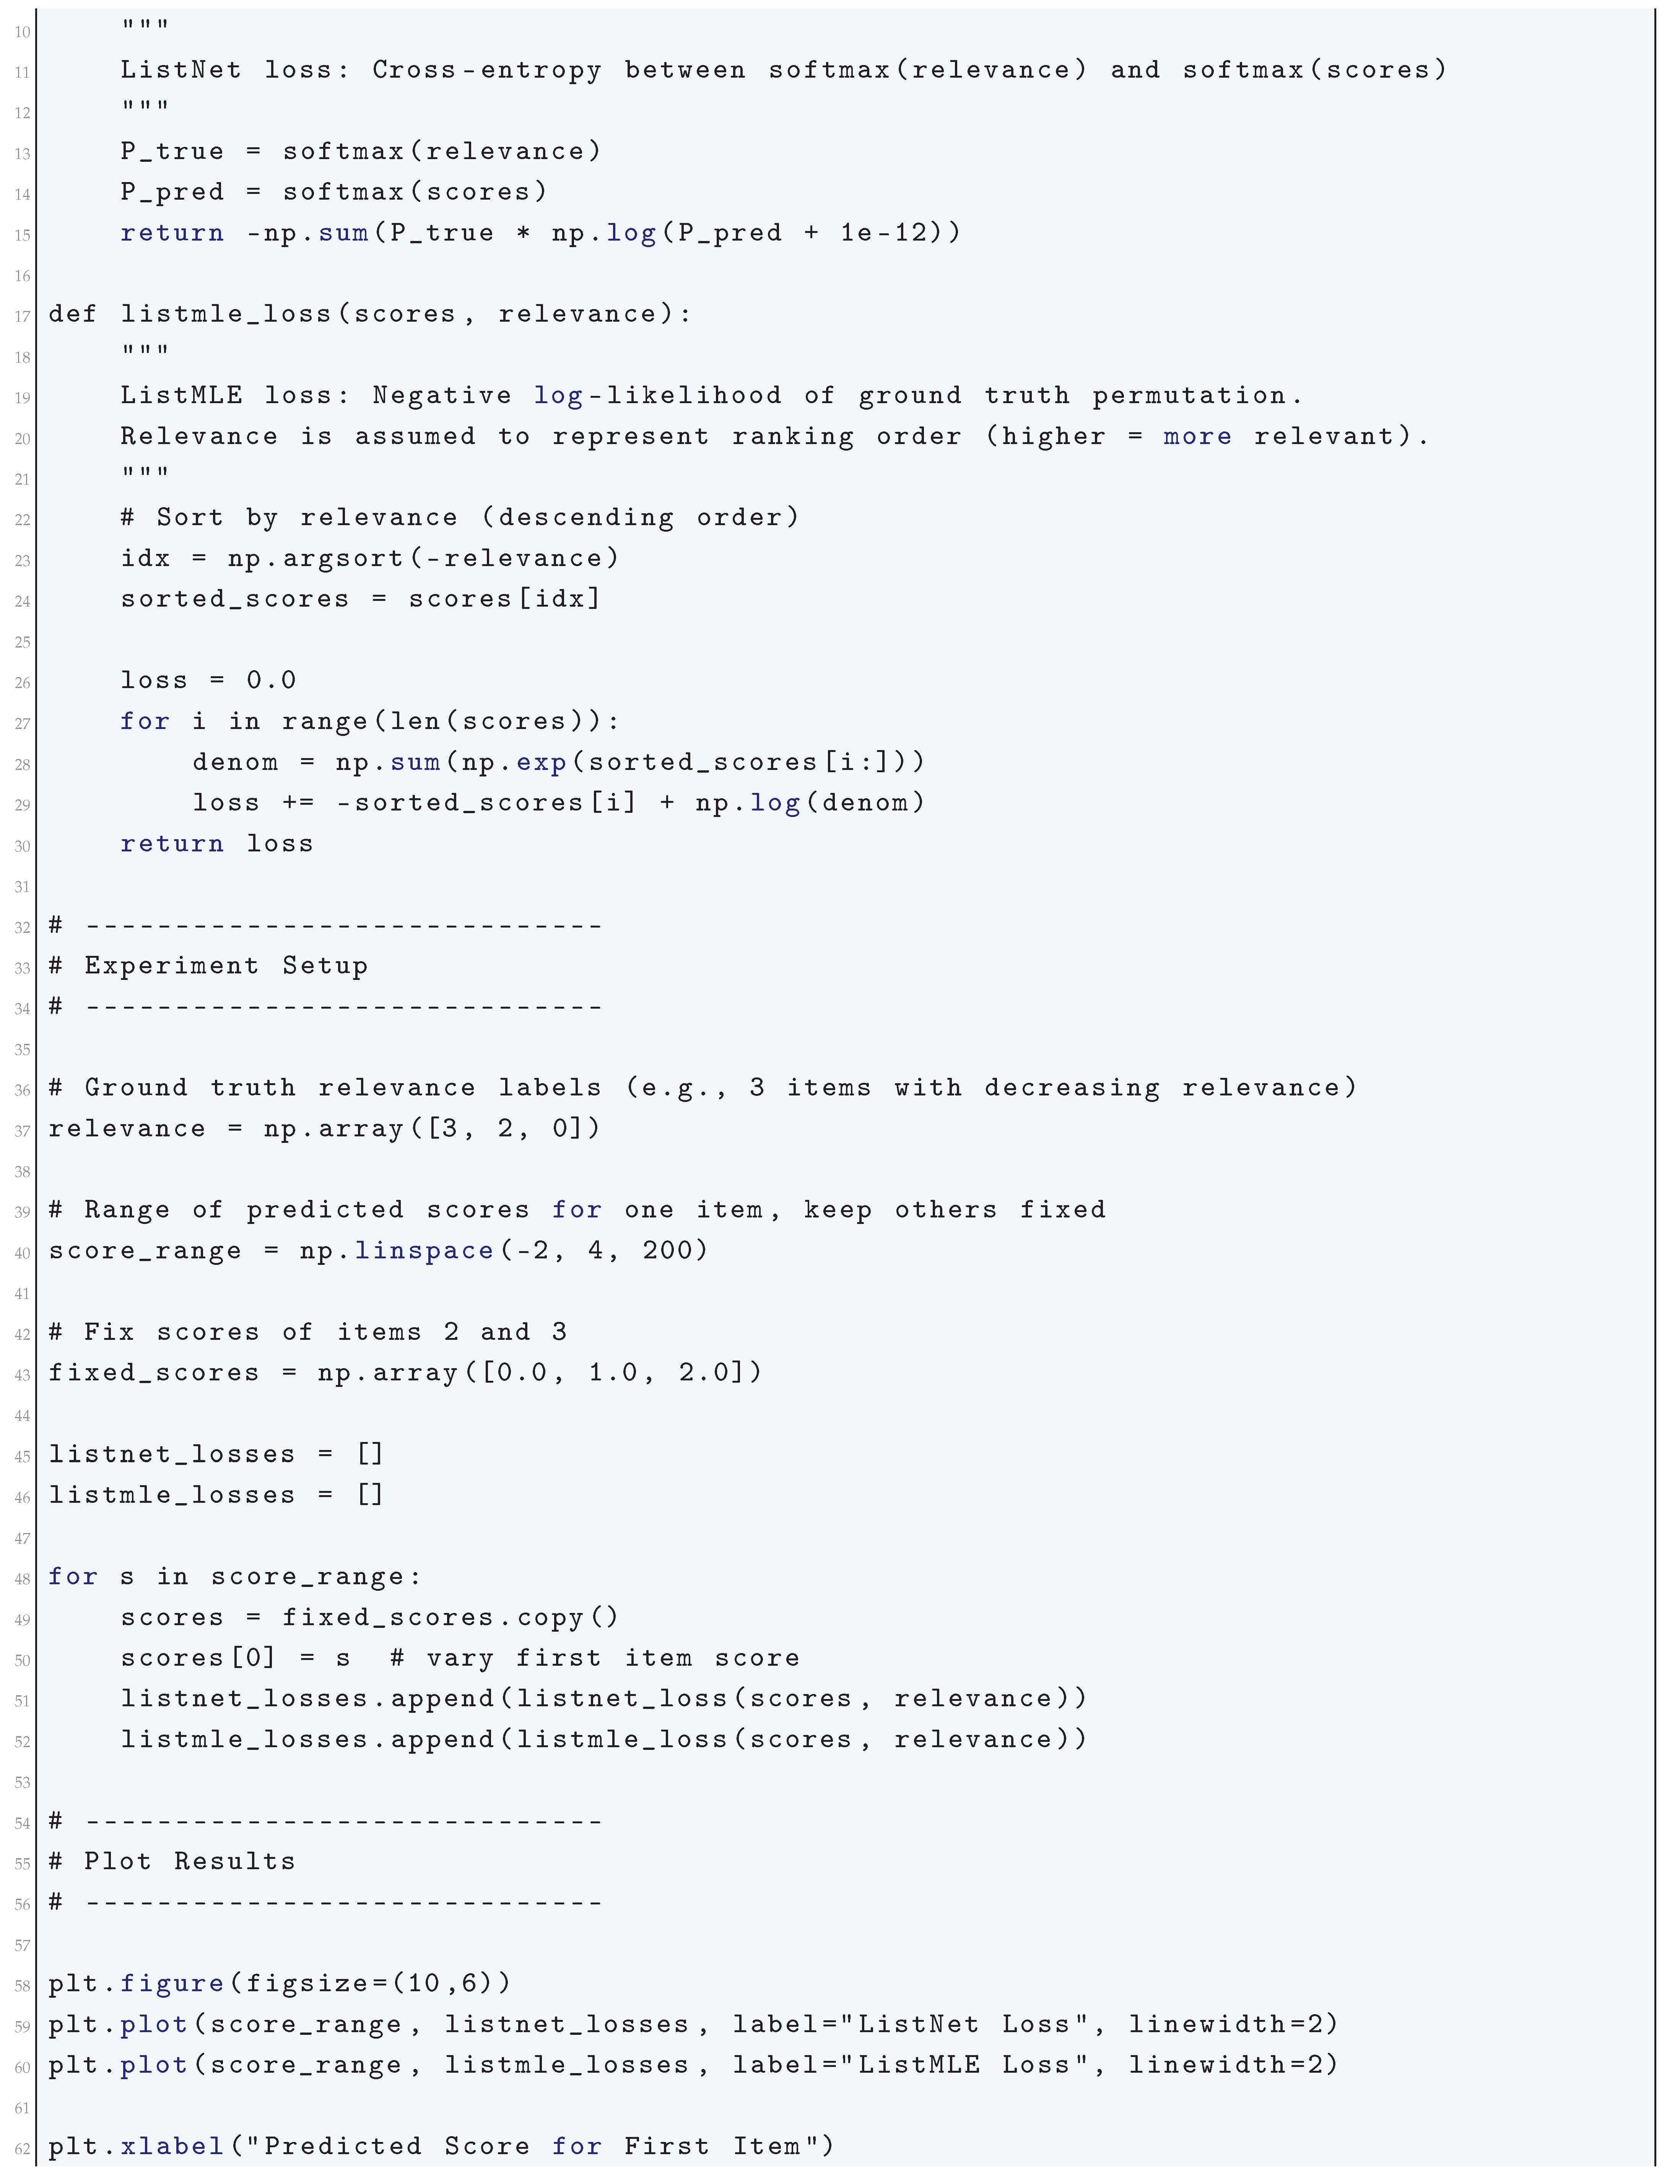
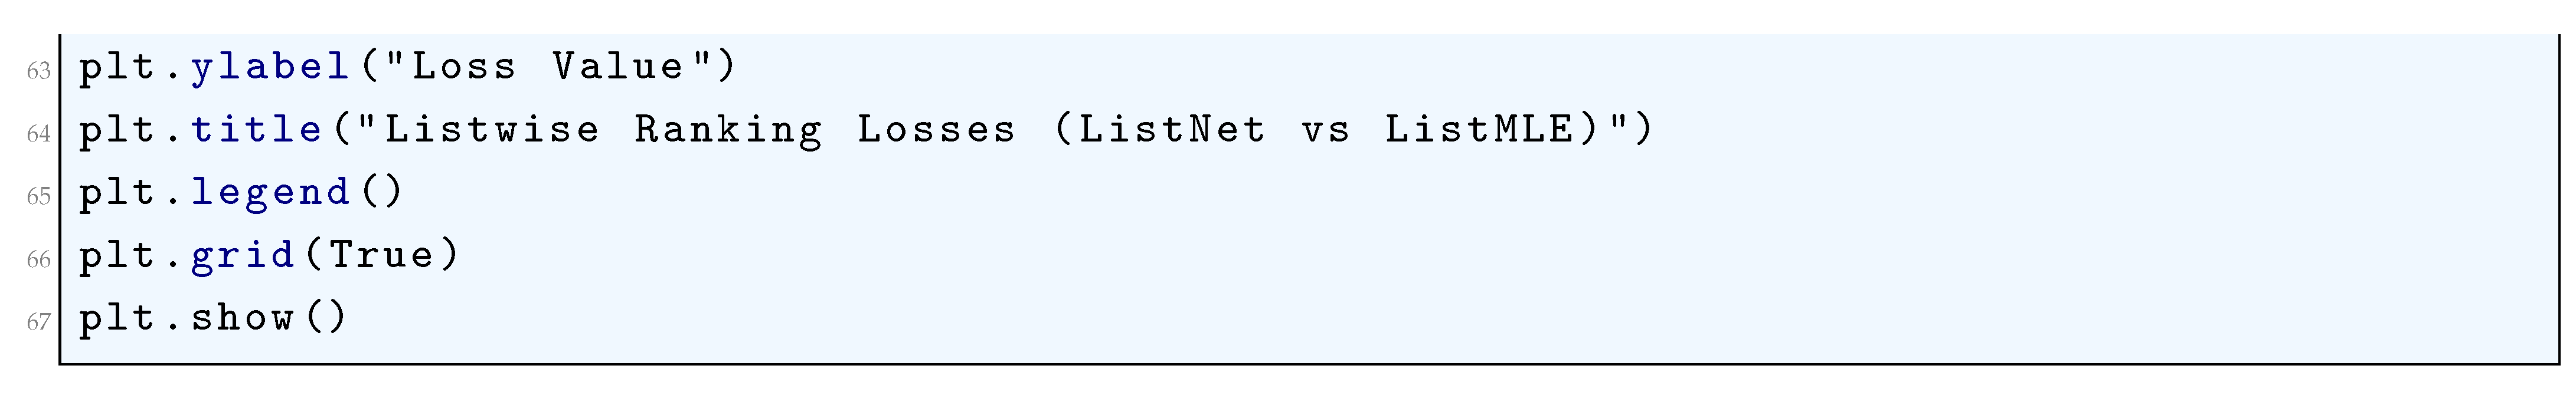
10.5.3.65 Python Code to Generate Figure 132 Illustrating Listwise Ranking Losses (3D Surfaces)
The Python code below produces the Figure 132 illustrating Listwise Ranking Losses (3D Surfaces).
Figure 132.
Listwise Ranking Losses (3D Surfaces)

10.5.3.66 Python Code to Generate Figure 133 Illustrating Listwise Ranking Loss Contours
The Python code below produces the Figure 133 illustrating Listwise Ranking Loss Contours.
Figure 133.
Listwise Ranking Loss Contours
10.5.3.67 Python Code to Generate Figure 134 illustrating Pairwise Ranking Losses
The Python code below produces the Figure 134 illustrating Pairwise Ranking Losses.
Figure 134.
Pairwise Ranking Losses
10.5.3.68 Python Code to Generate Figure 135 Illustrating Pairwise Ranking Loss Landscapes
The Python code below produces the Figure 135 illustrating Pairwise Ranking Loss Landscapes.
Figure 135.
Pairwise Ranking Loss Landscapes
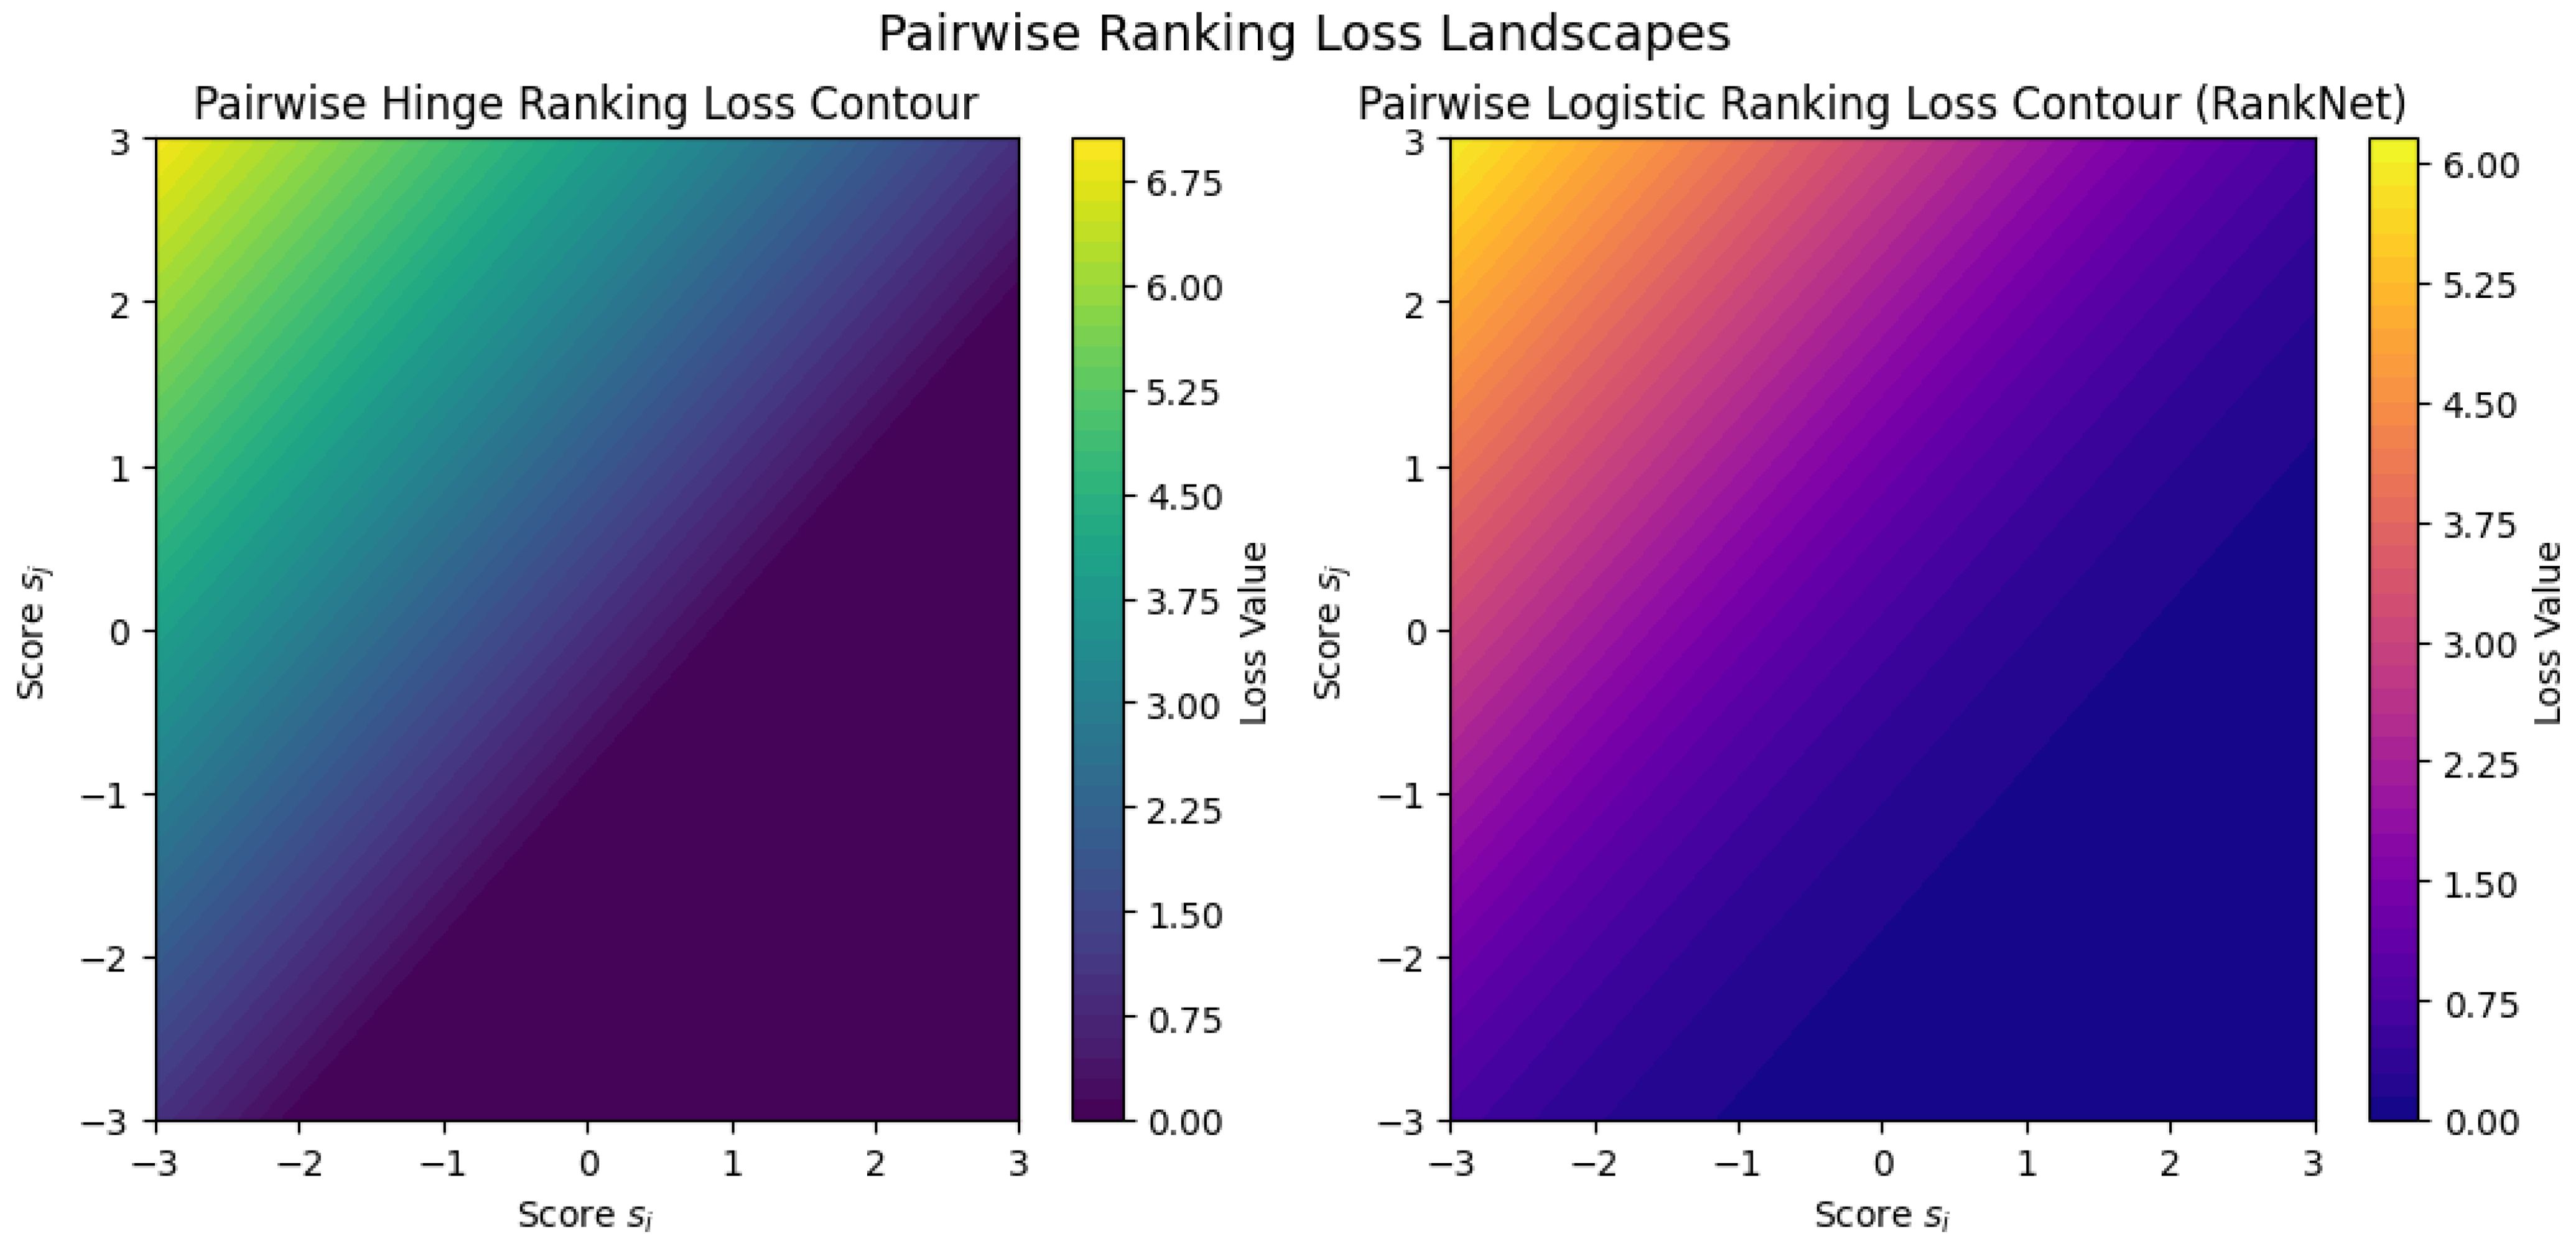
10.5.3.69 Python Code to Generate Figure 136 Illustrating 3D Surfaces of Pairwise Ranking Losses
The Python code below produces the Figure 136 illustrating 3D Surfaces of Pairwise Ranking Losses.
Figure 136.
3D Surfaces of Pairwise Ranking Losses
10.5.3.70 Python Code to Generate Figure 137 Illustrating Contrastive Divergence (CD) Loss vs Weight
The Python code below produces the Figure 137 illustrating Contrastive Divergence (CD) Loss vs Weight.
Figure 137.
Contrastive Divergence (CD) Loss vs Weight
10.5.3.71 Python Code to Generate Figure 138 Illustrating Contrastive Divergence (CD) Loss Landscape
The Python code below produces the Figure 138 illustrating Contrastive Divergence (CD) Loss Landscape.
Figure 138.
Contrastive Divergence (CD) Loss Landscape
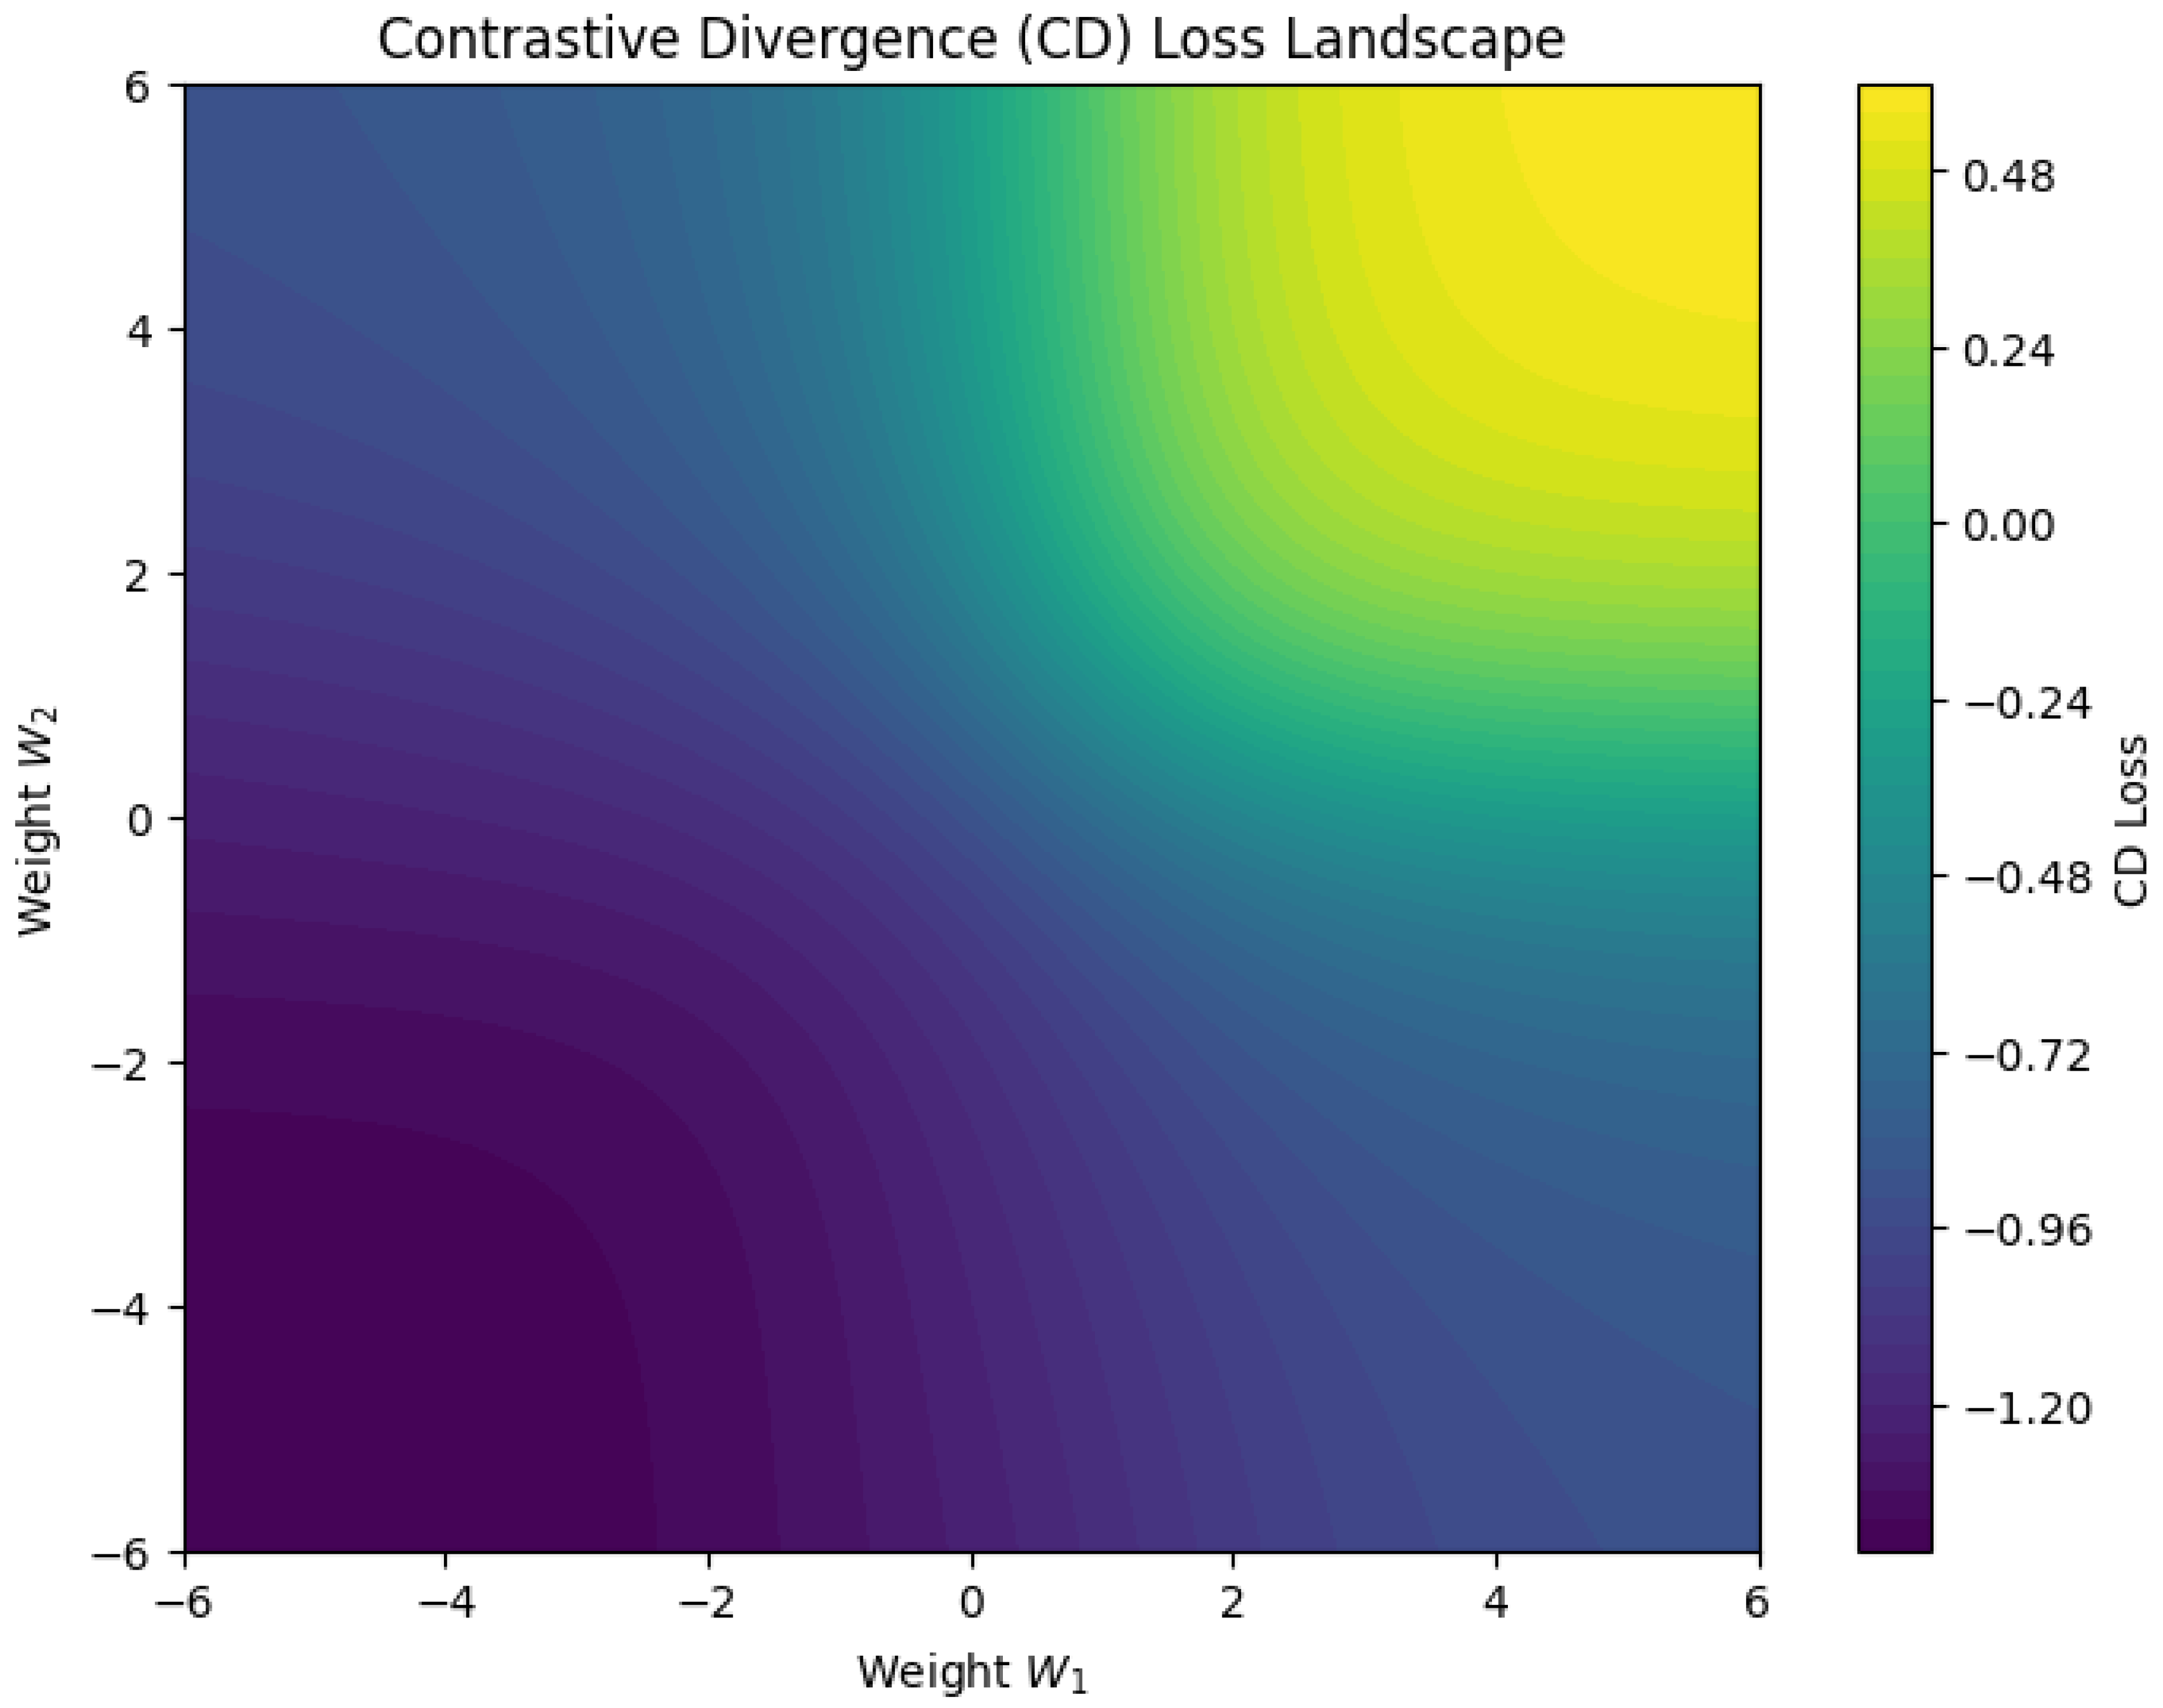
10.5.3.72 Python Code to Generate Figure 139 Illustrating Contrastive Divergence (CD) Loss Landscape (3D)
The Python code below produces the Figure 139 illustrating Contrastive Divergence (CD) Loss Landscape (3D).
Figure 139.
Contrastive Divergence (CD) Loss Landscape (3D)
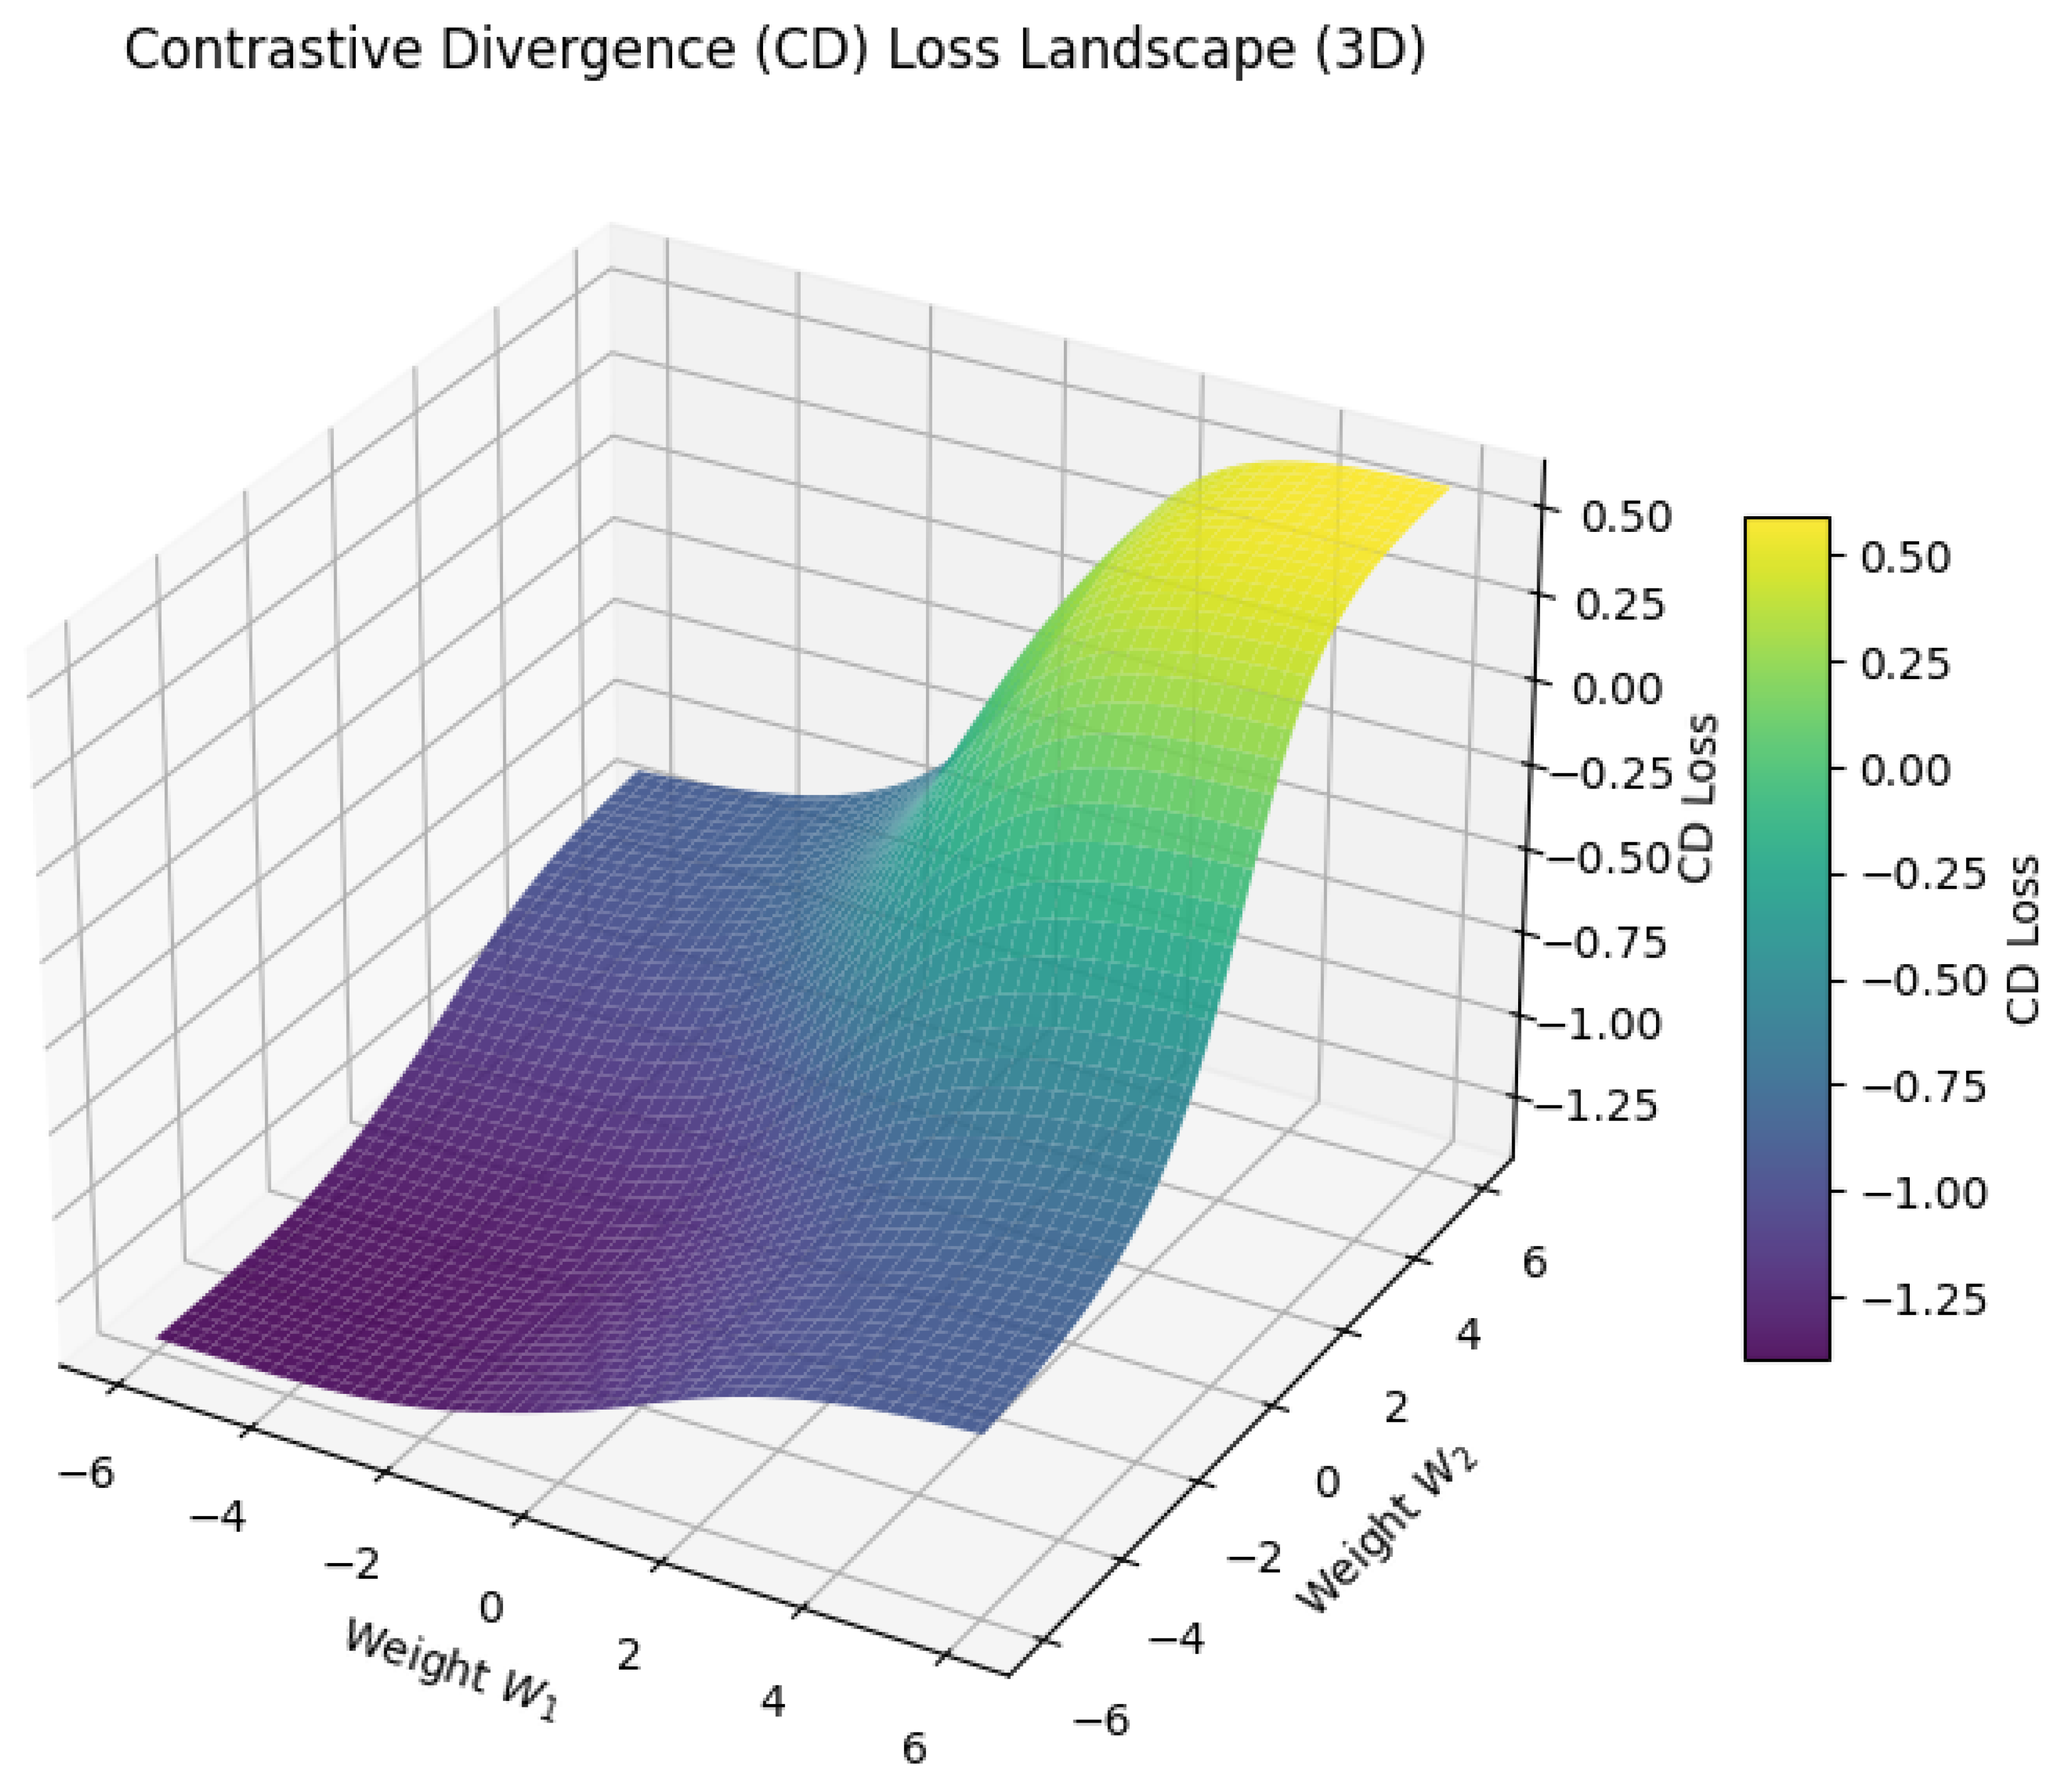
10.5.3.73 Python Code to Generate Figure 140 Illustrating Persistent Contrastive Divergence (PCD) Loss Landscape
The Python code below produces the Figure 140 illustrating Persistent Contrastive Divergence (PCD) Loss Landscape.
Figure 140.
Persistent Contrastive Divergence (PCD) Loss Landscape
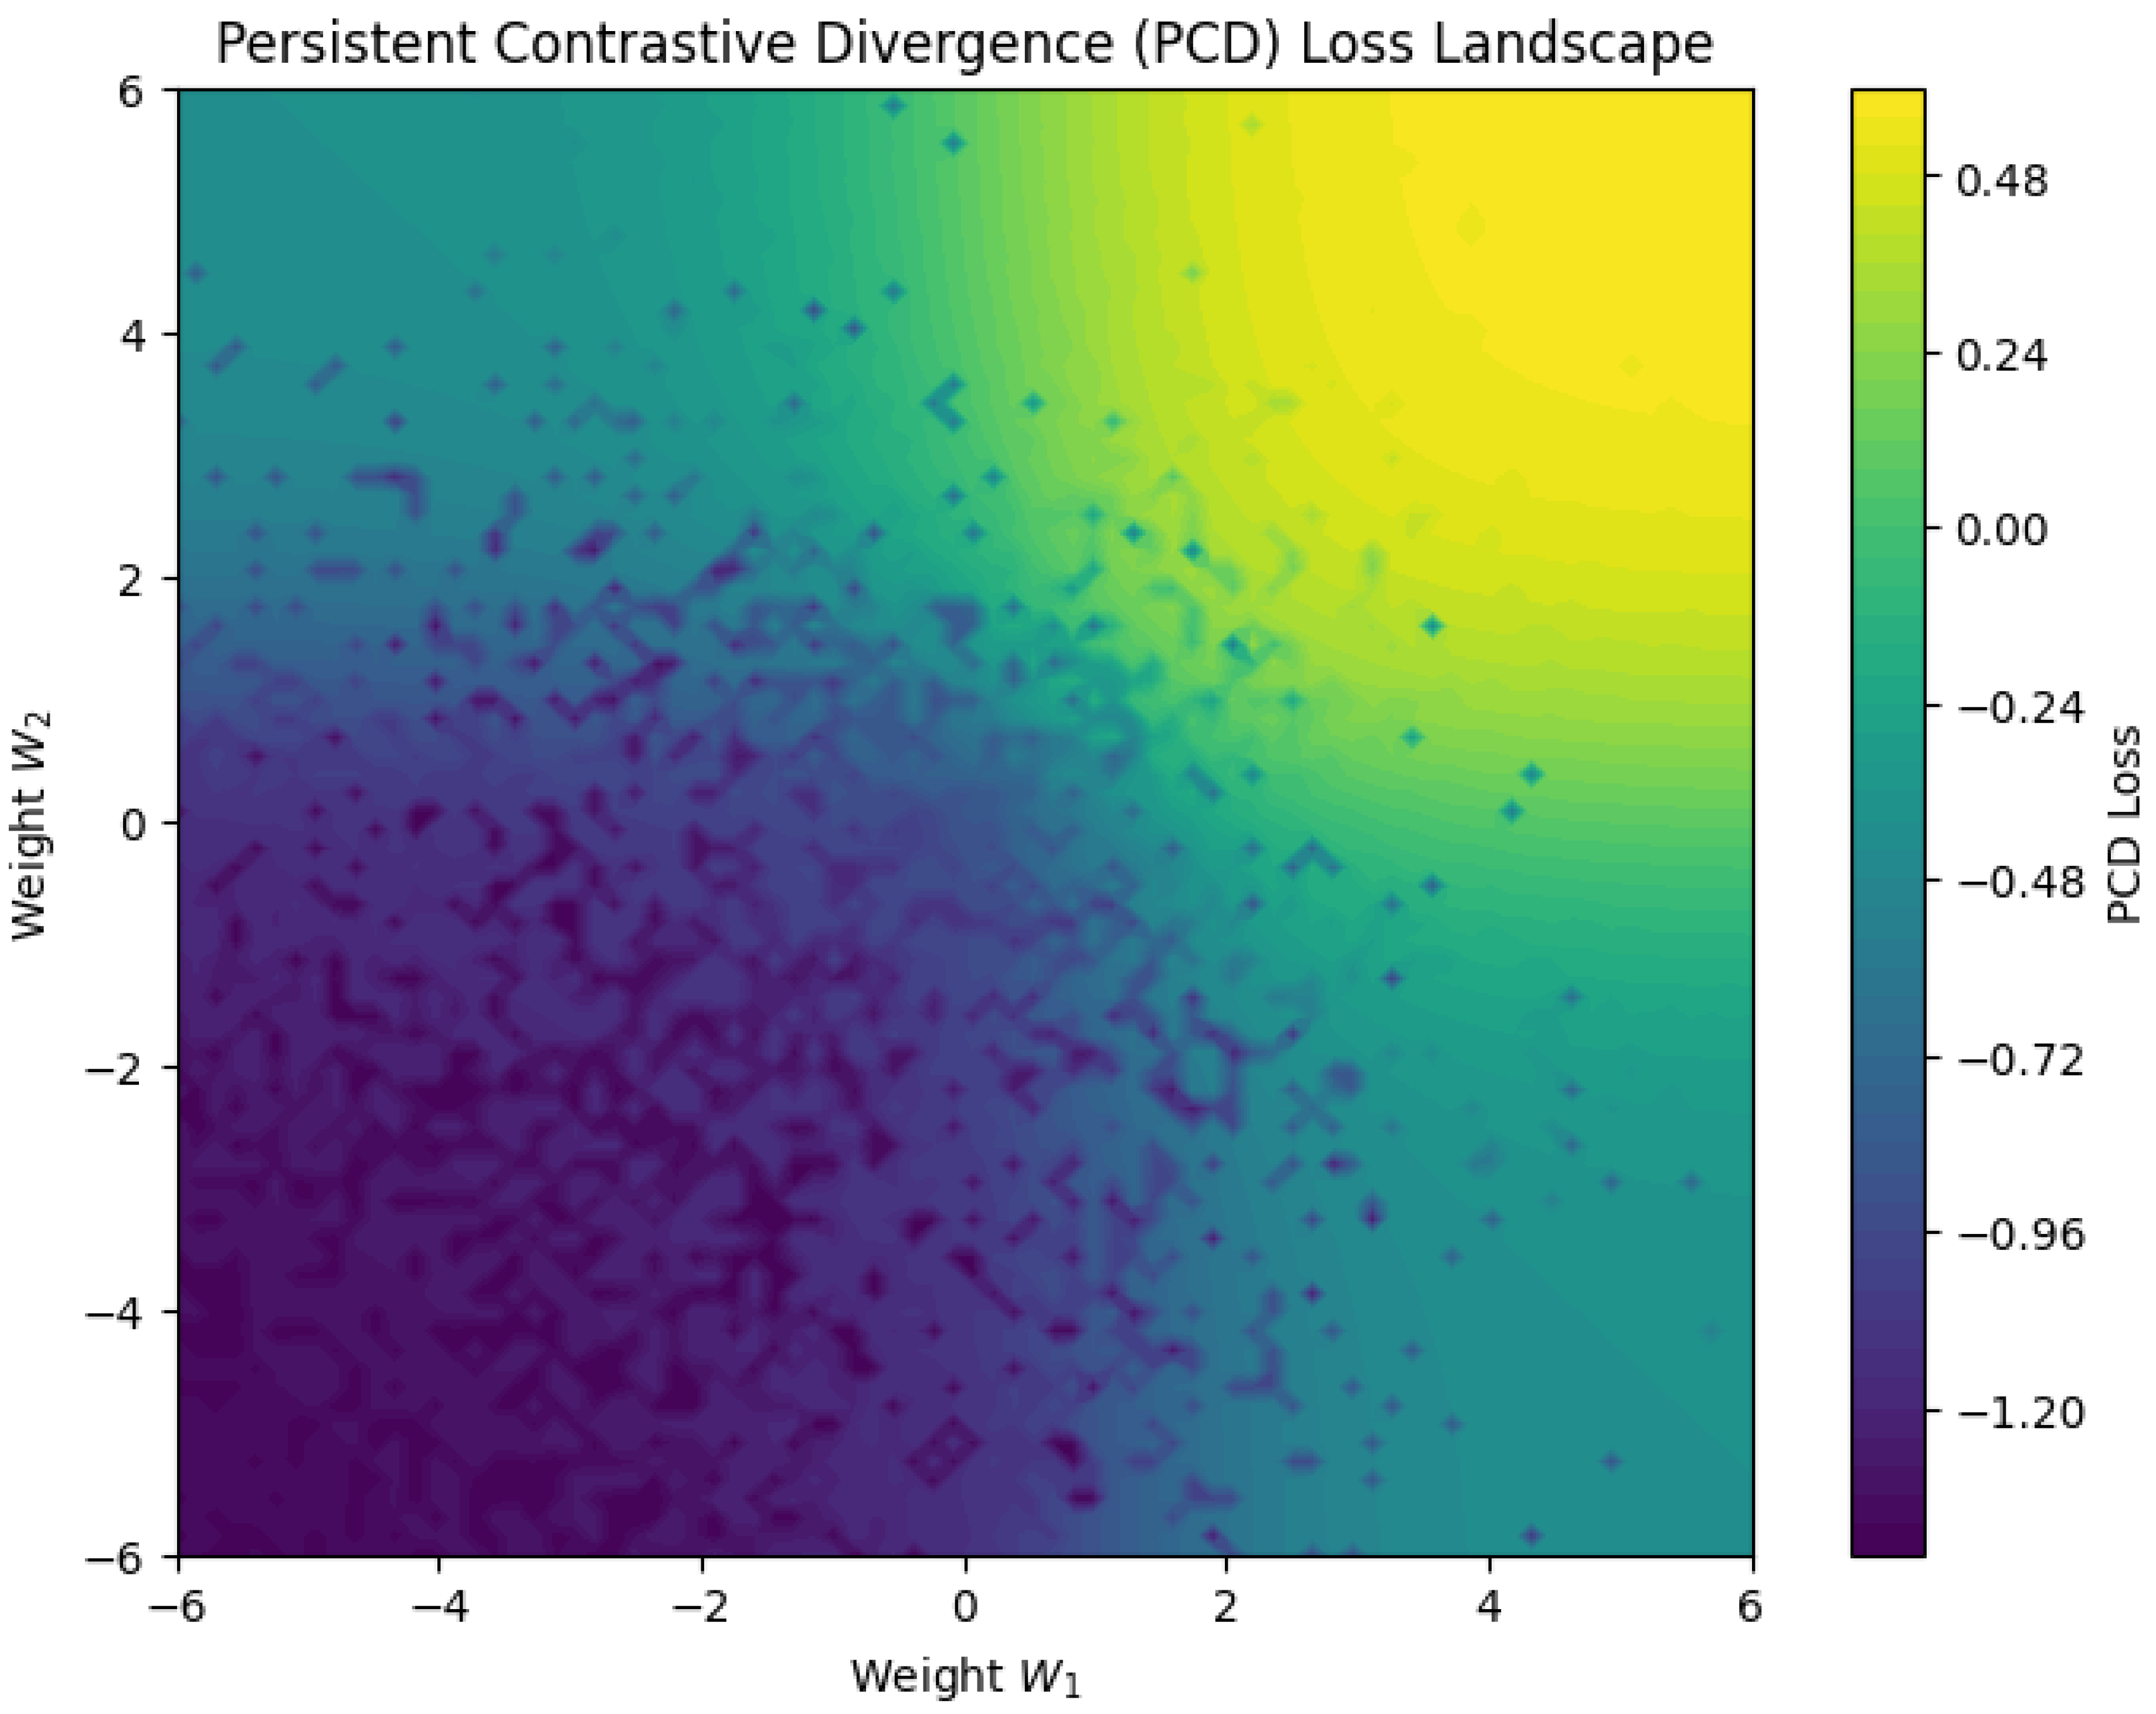
10.5.3.74 Python Code to Generate Figure 141 Illustrating Persistent Contrastive Divergence (PCD) Loss Landscape (3D)
The Python code below produces the Figure 141 illustrating Persistent Contrastive Divergence (PCD) Loss Landscape (3D).
Figure 141.
Persistent Contrastive Divergence (PCD) Loss Landscape (3D)
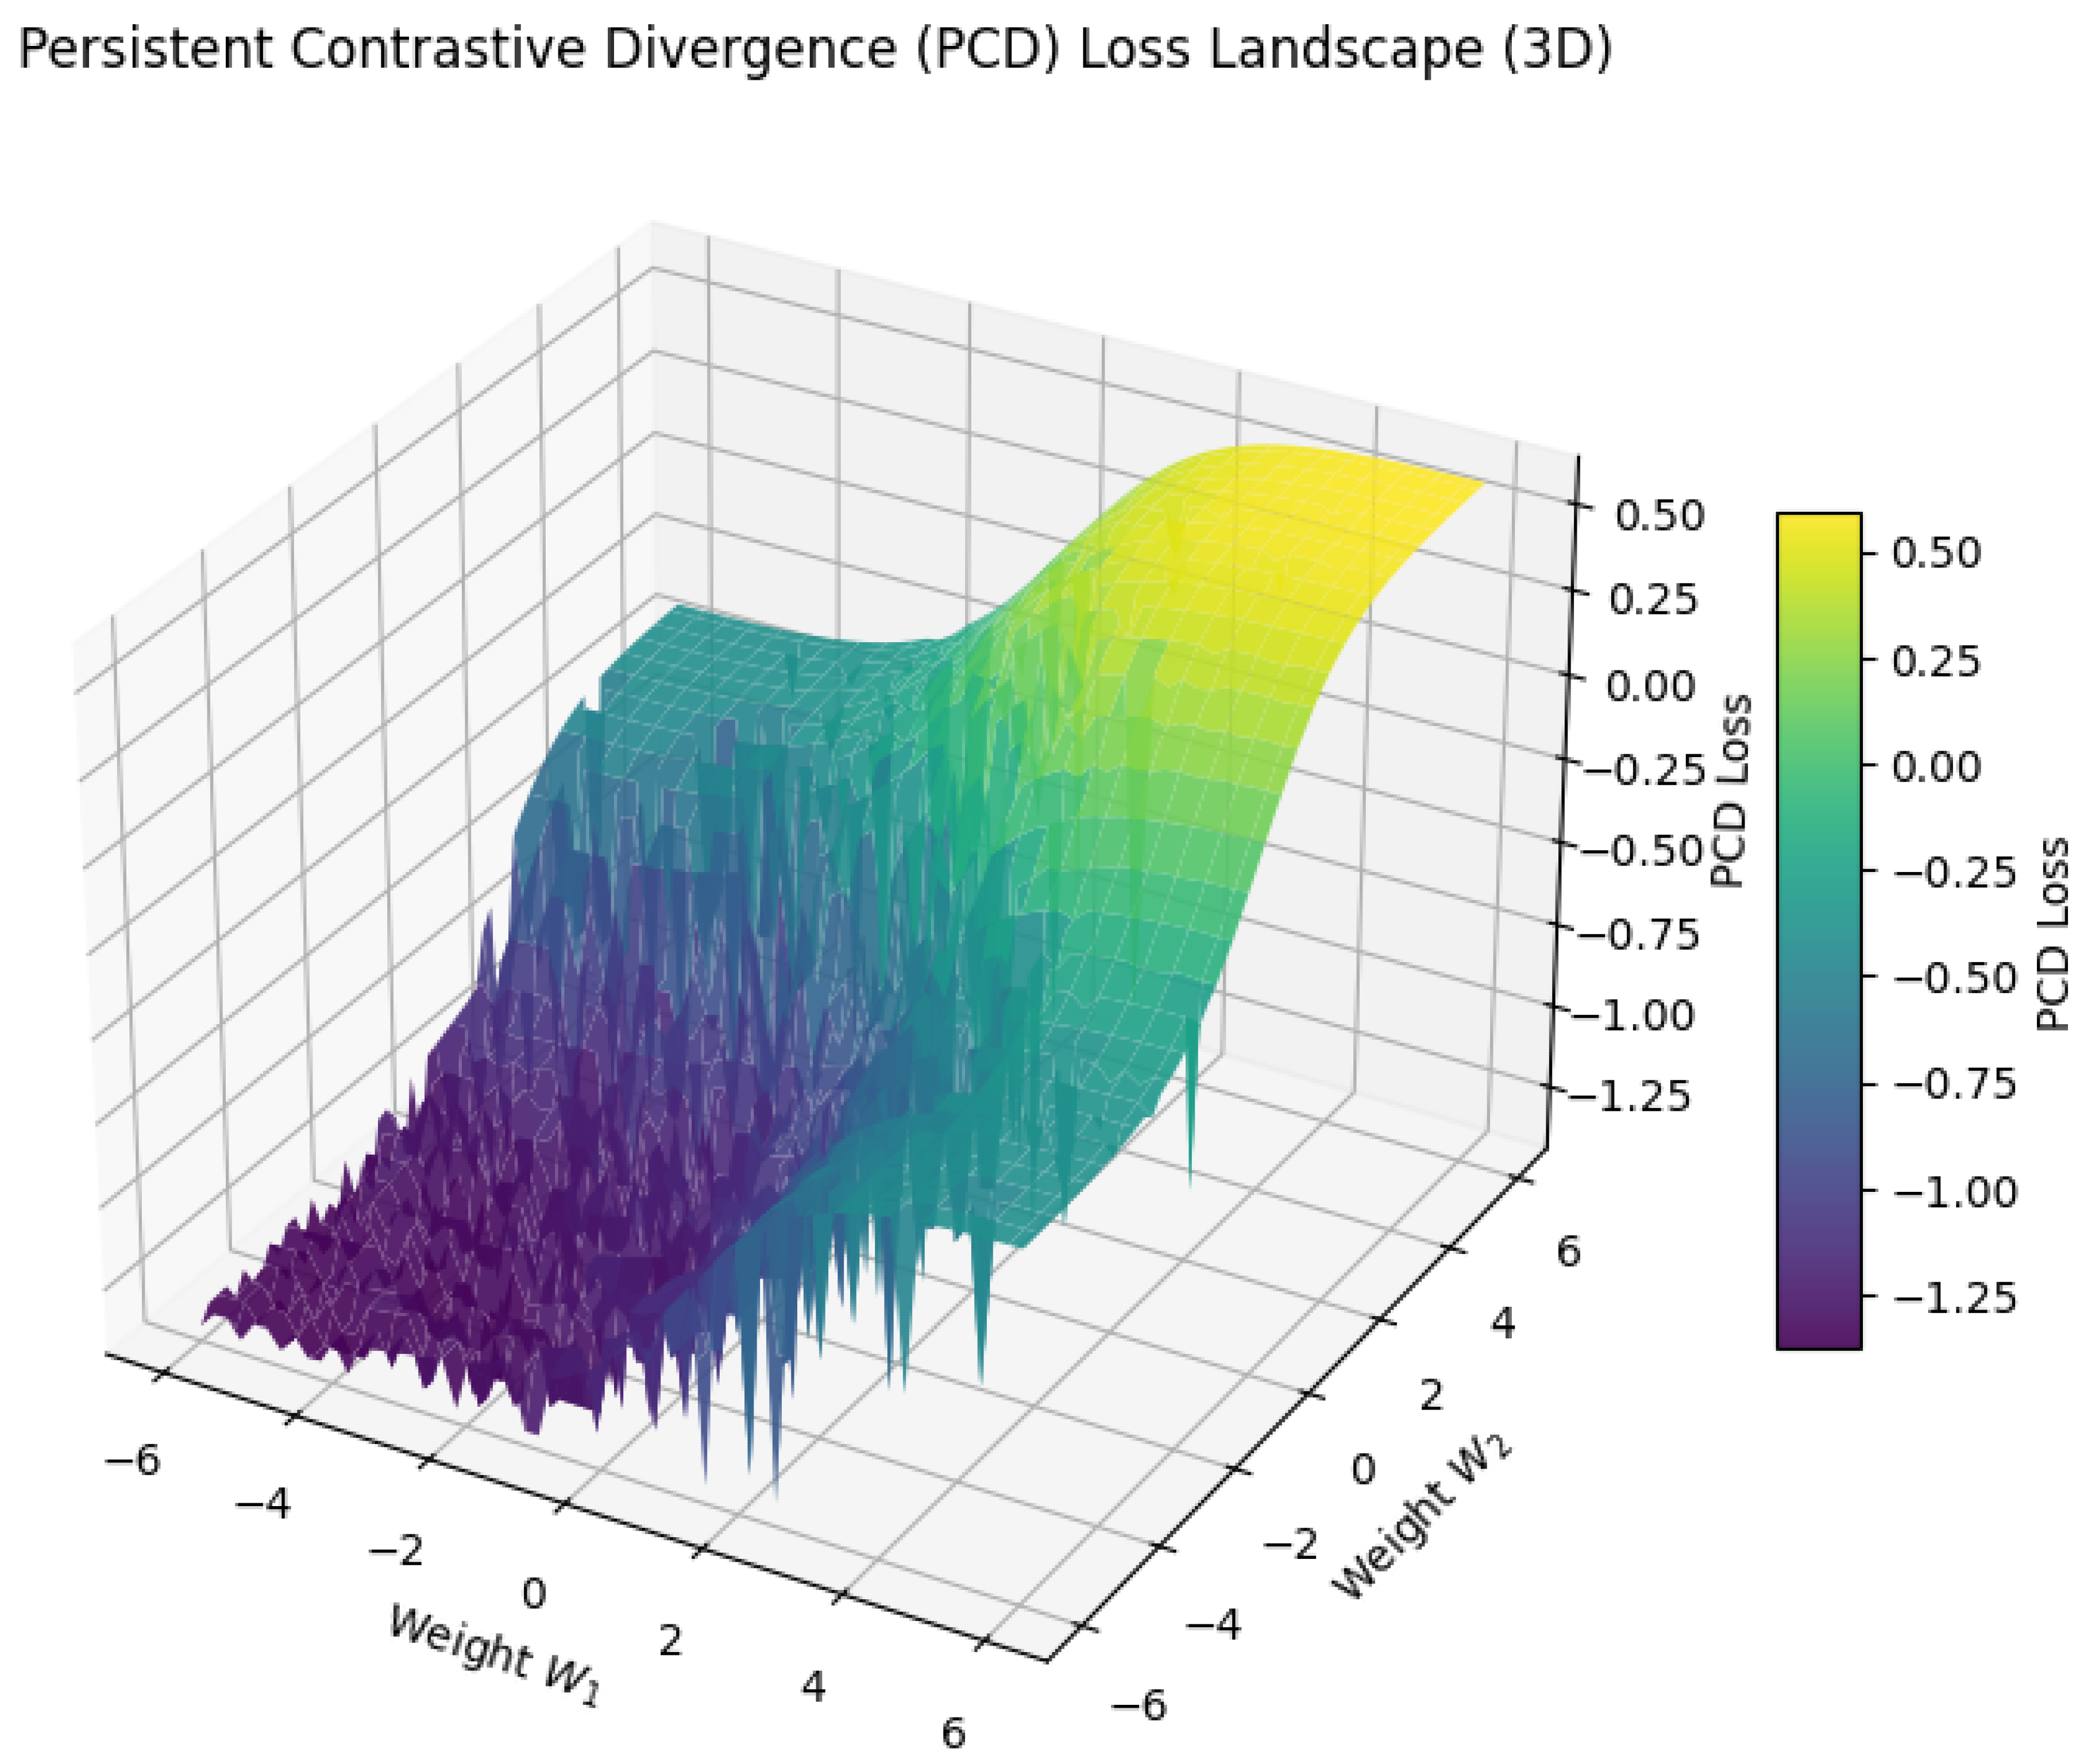
10.5.3.75 Python Code to Generate Figure 142 Illustrating Hausdorff Distance Loss Visualization
The Python code below produces the Figure 142 illustrating Hausdorff Distance Loss Visualization.
Figure 142.
Hausdorff Distance Loss Visualization
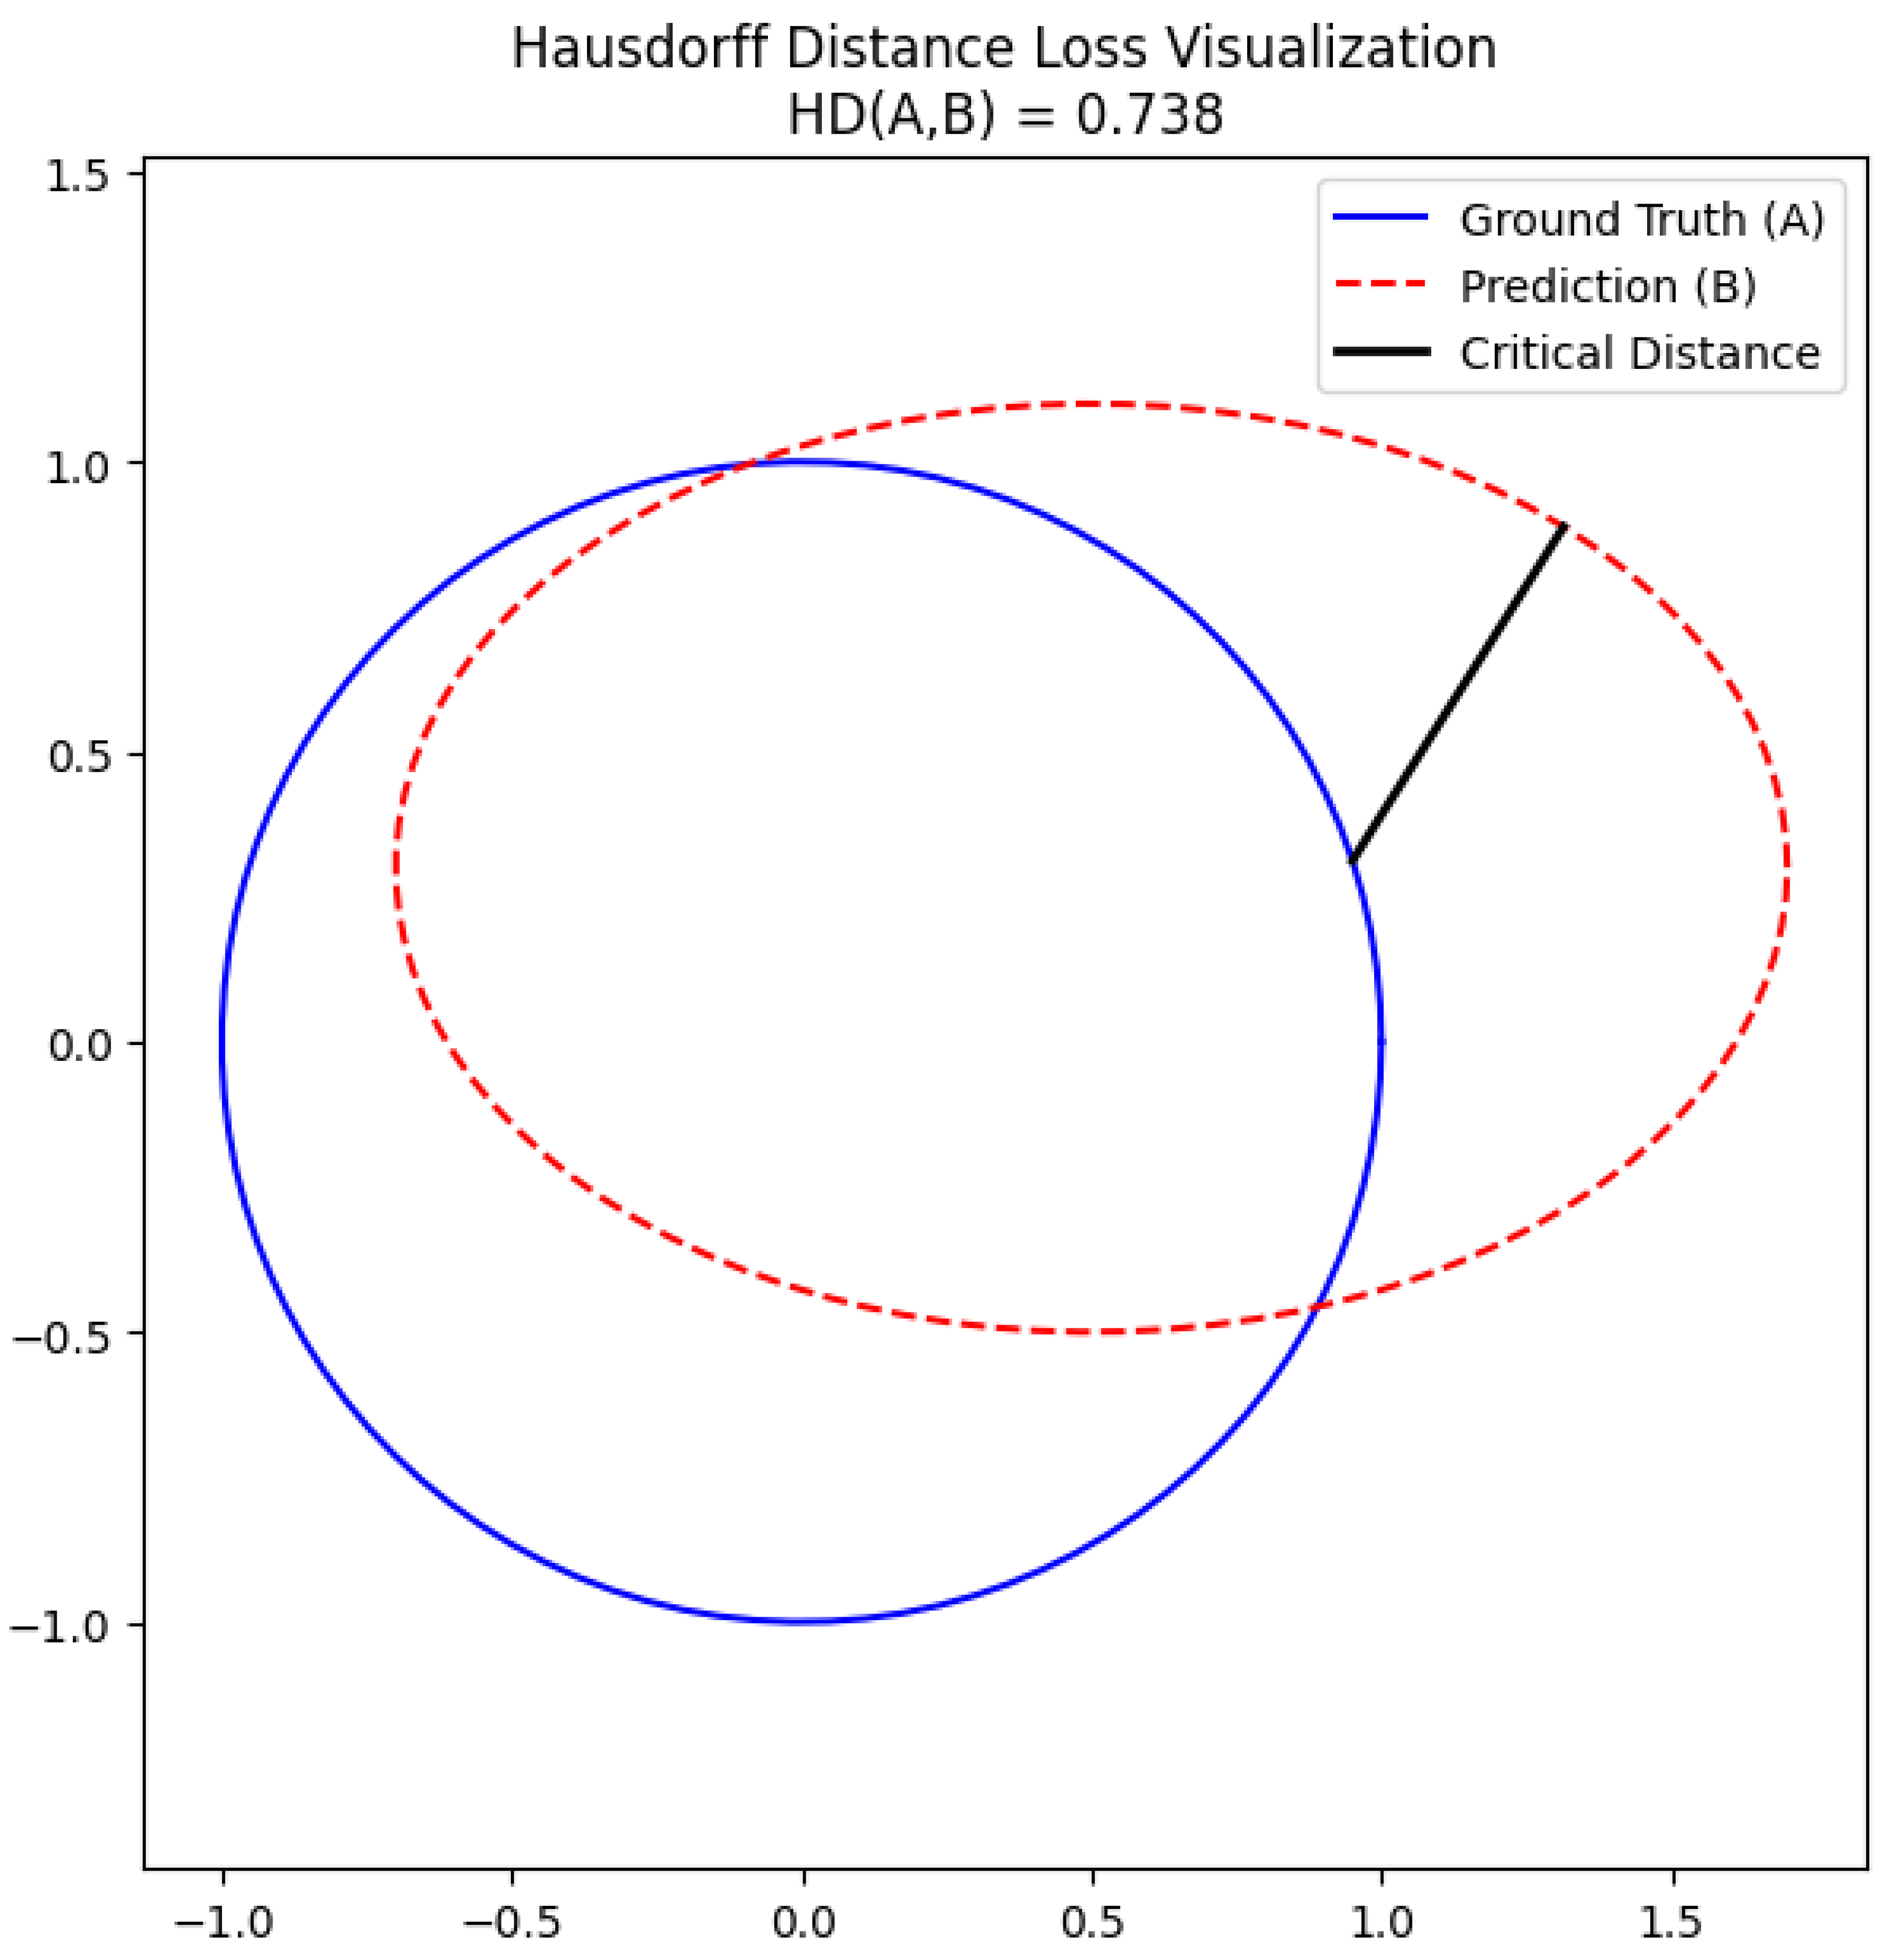
10.5.3.76 Python Code to Generate Figure 143 Illustrating Hausdorff Distance Heatmap
The Python code below produces the Figure 143 illustrating Hausdorff Distance Heatmap.
Figure 143.
Hausdorff Distance Heatmap
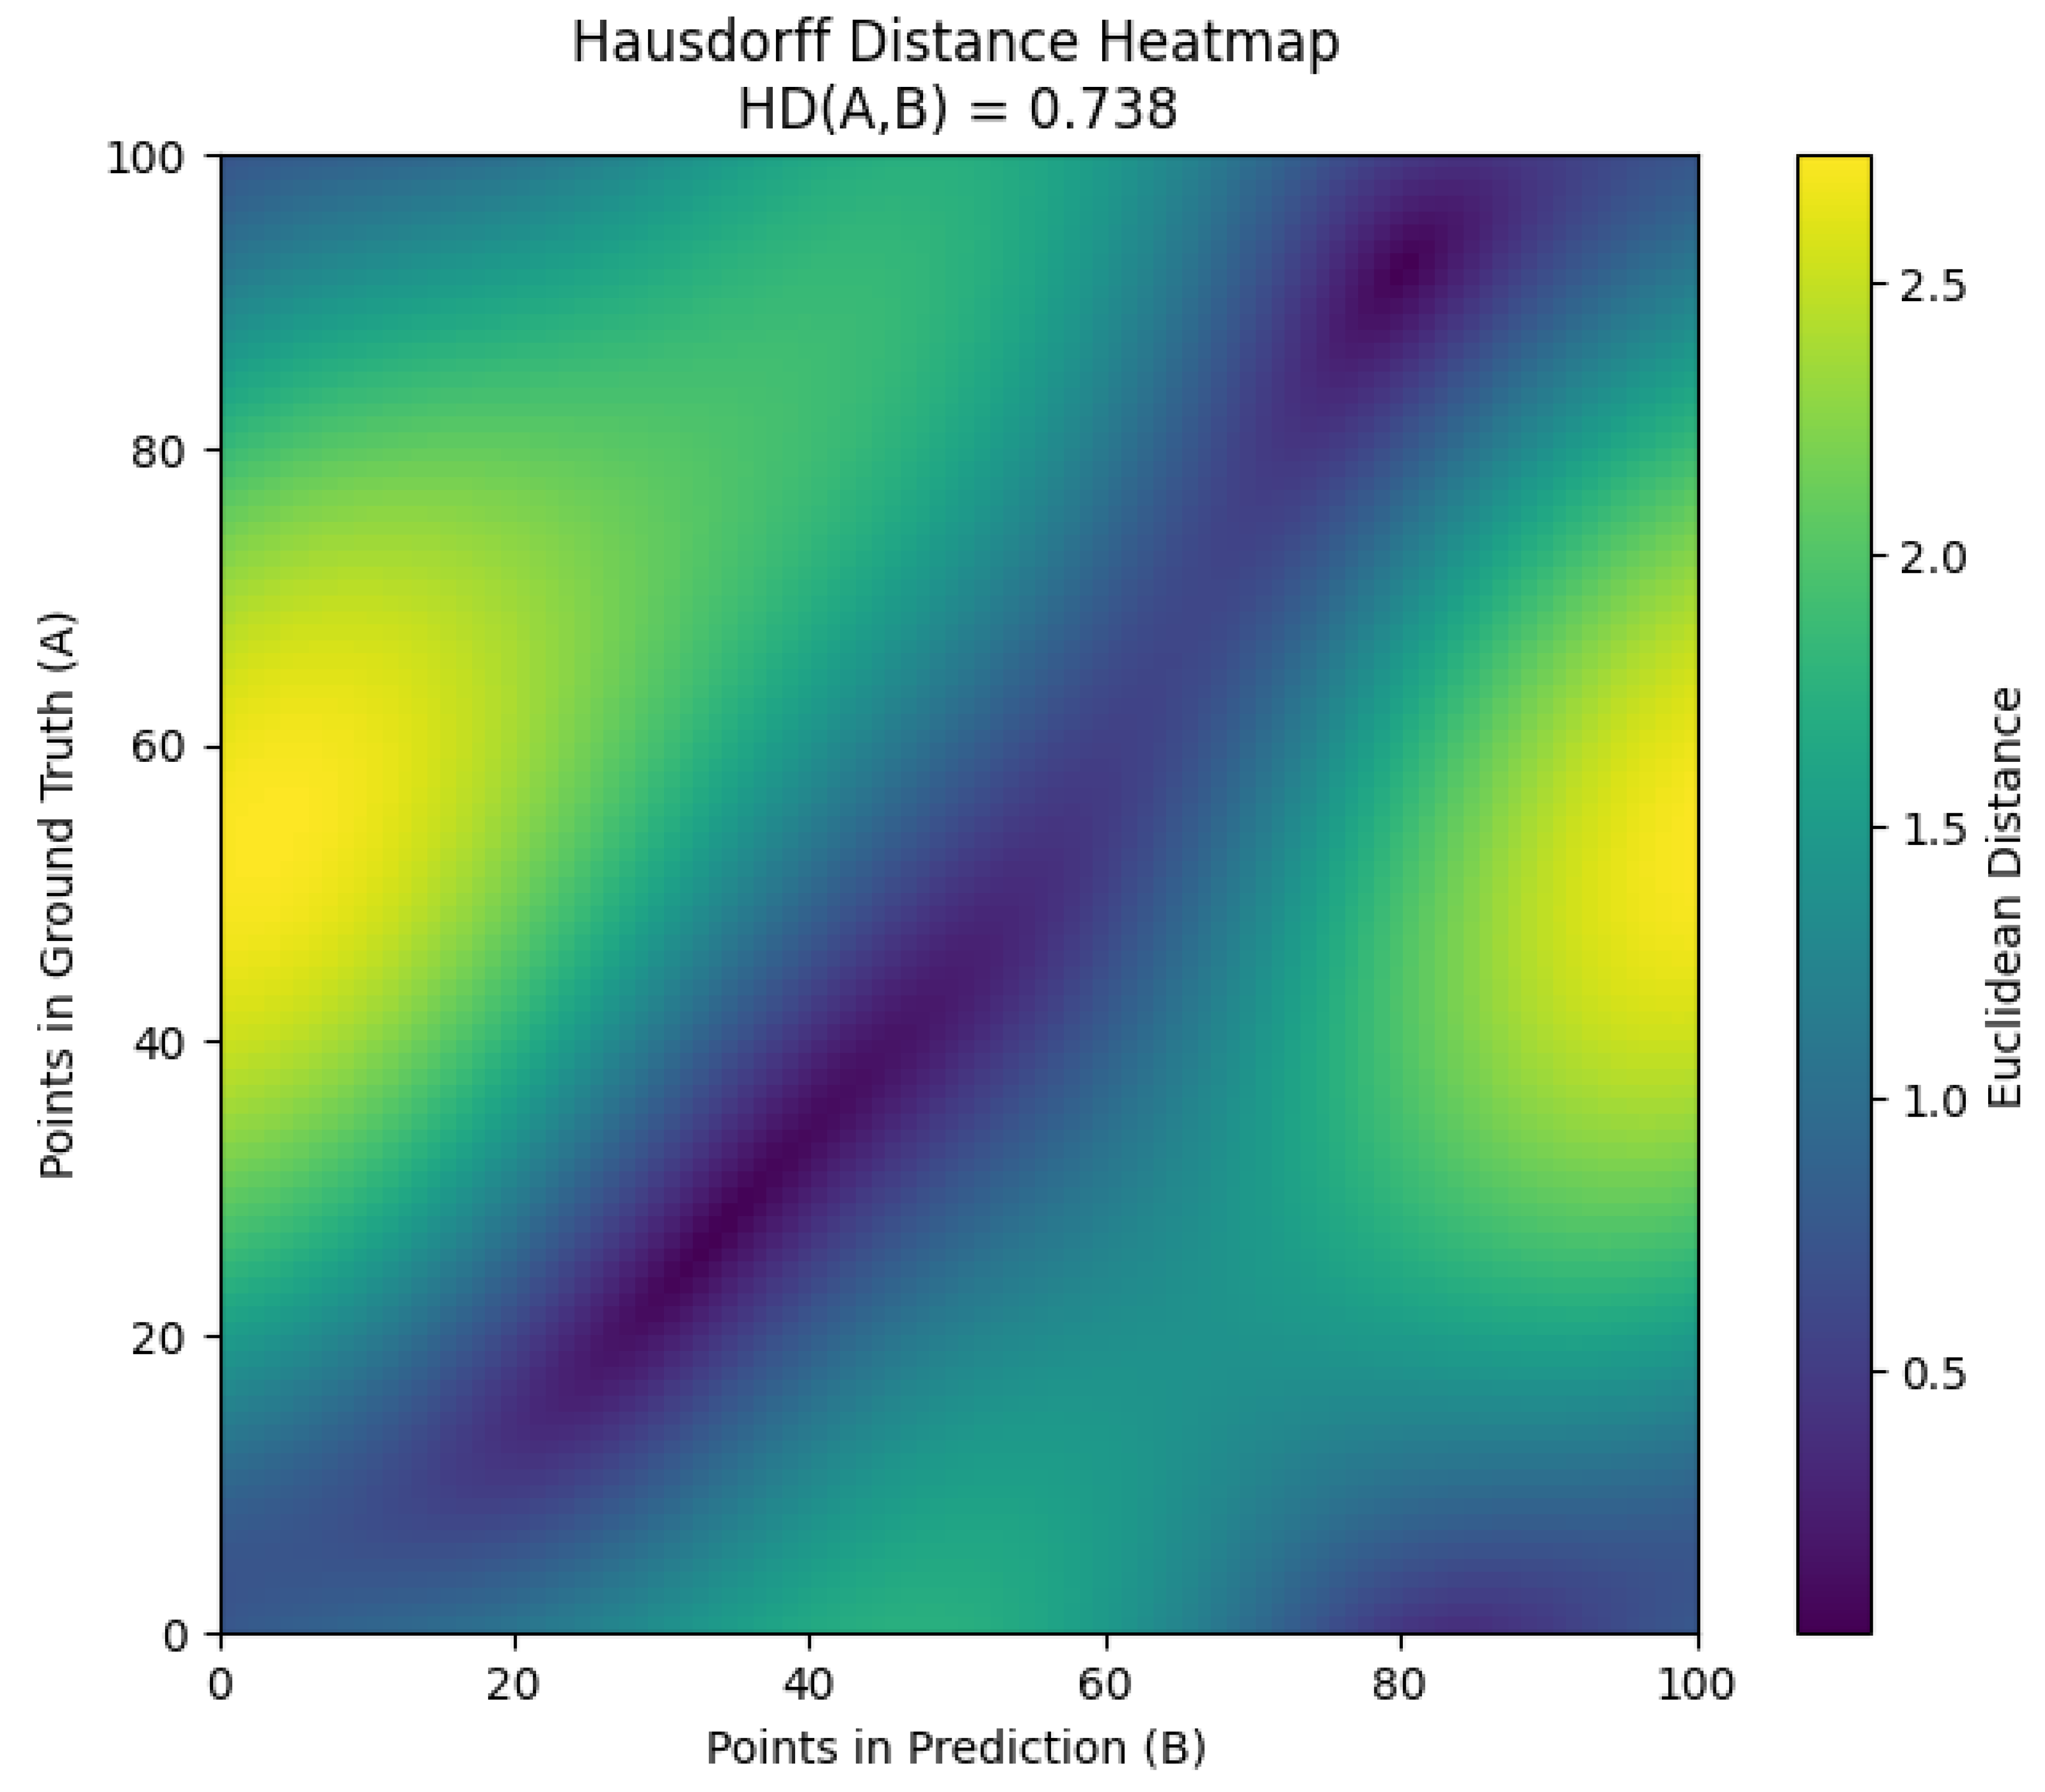
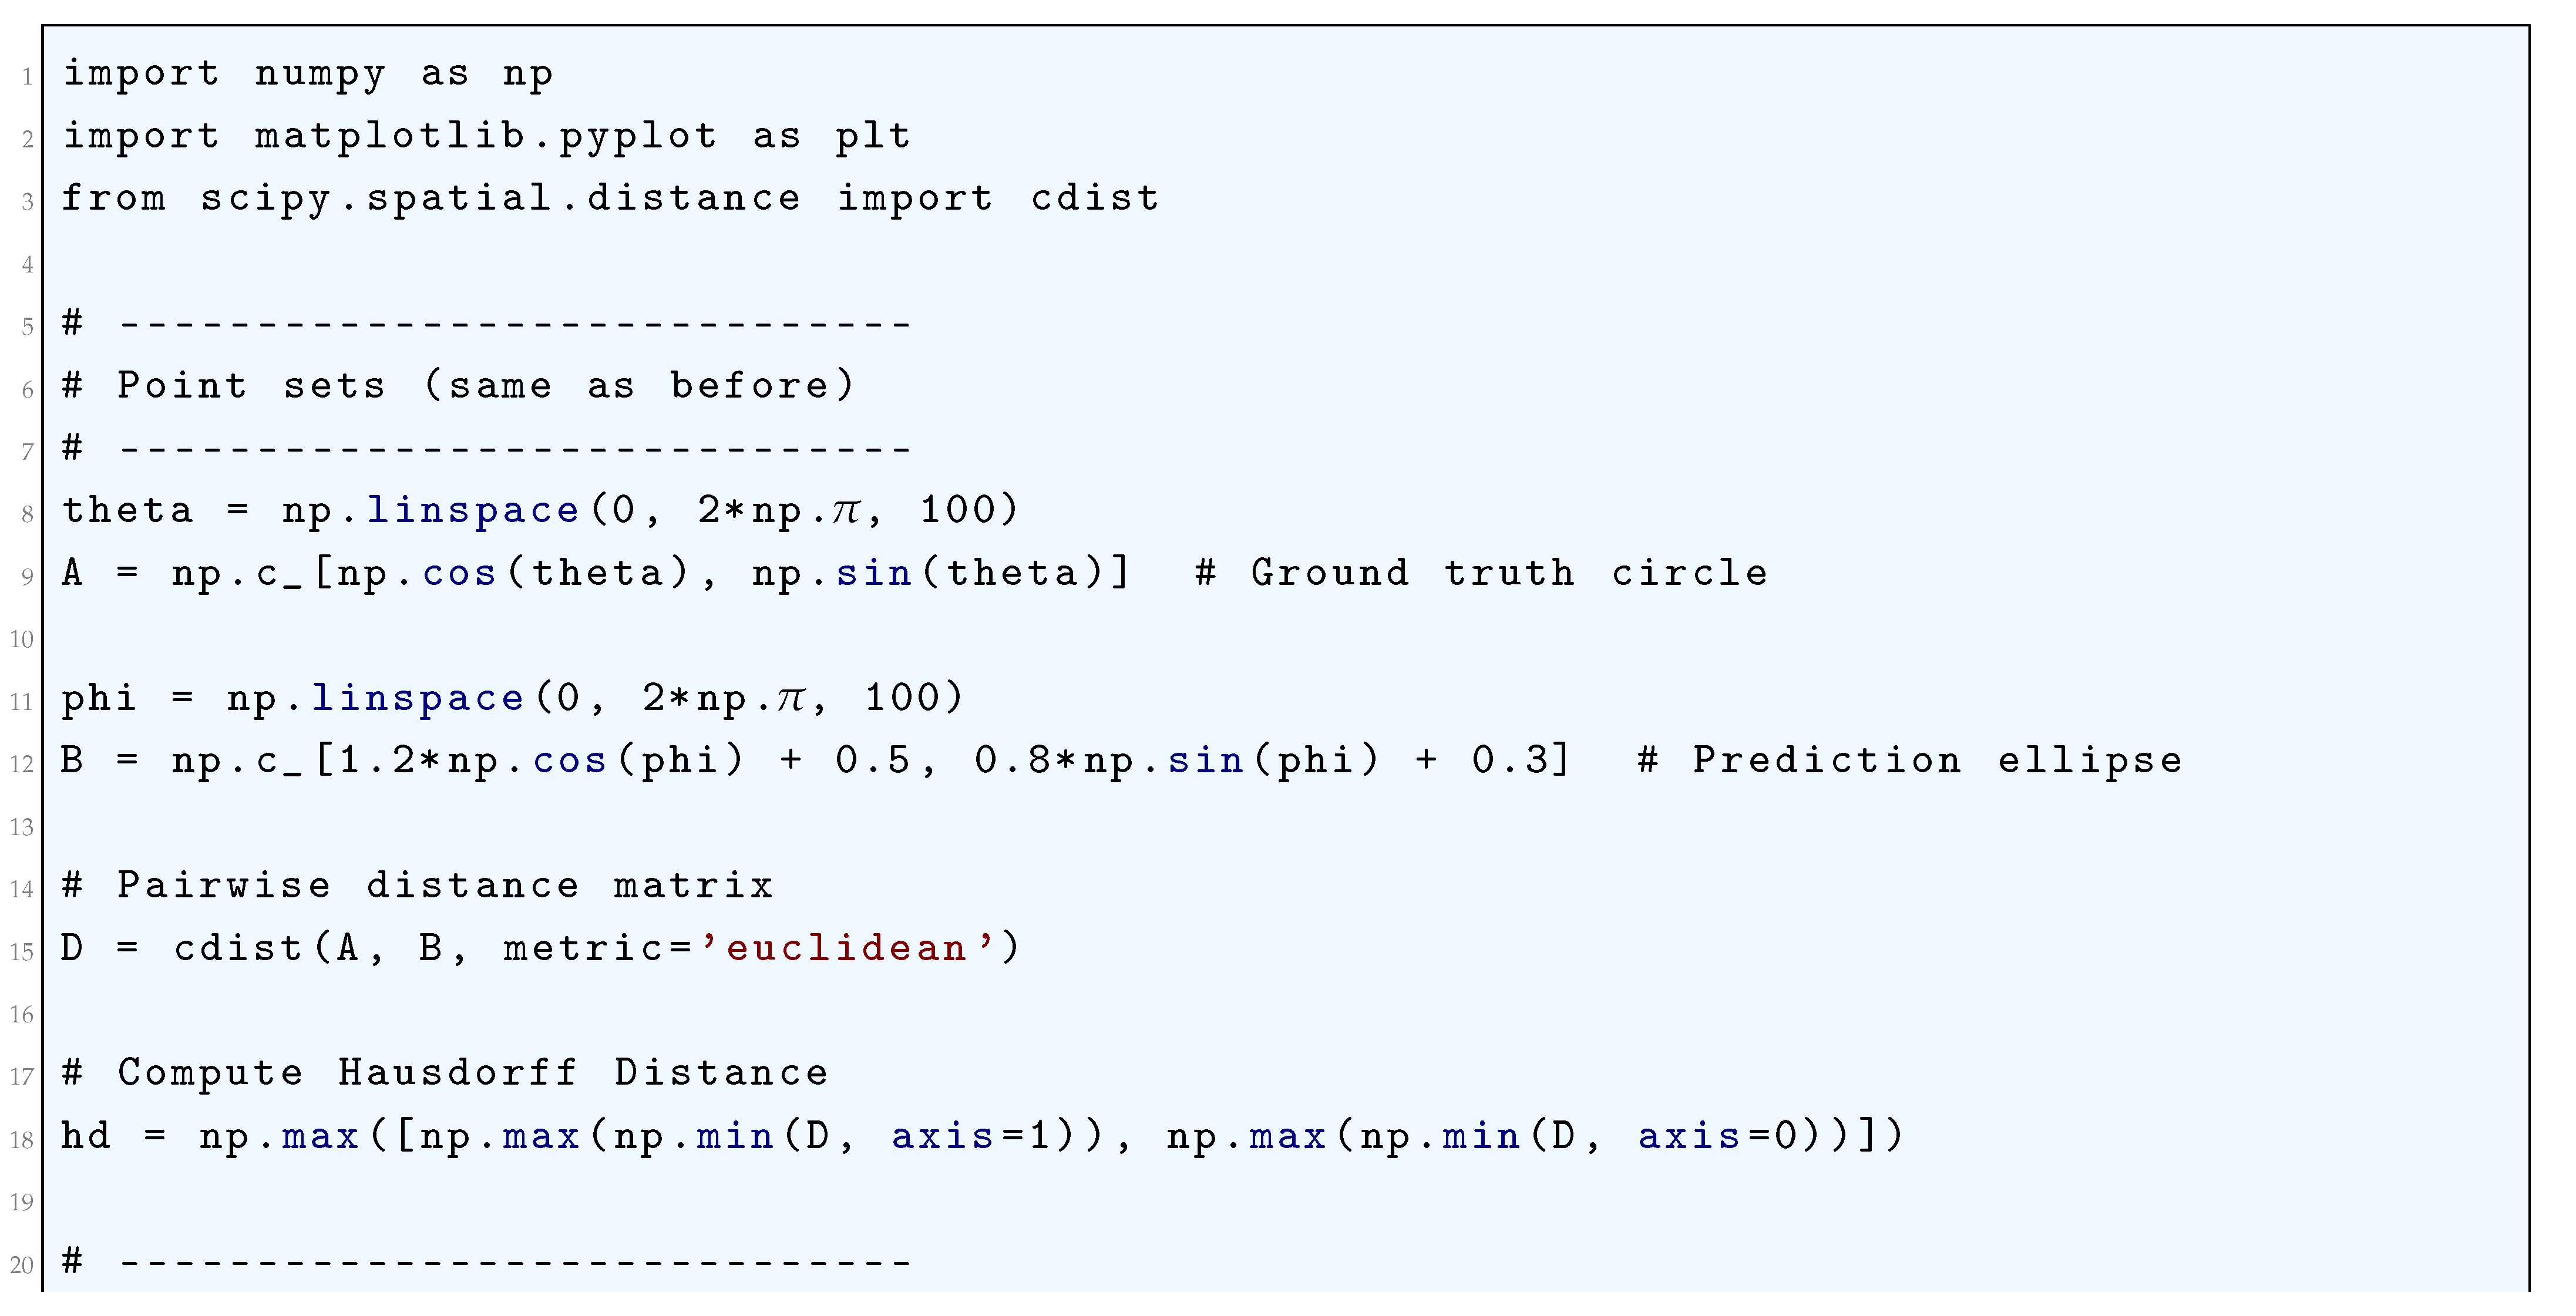
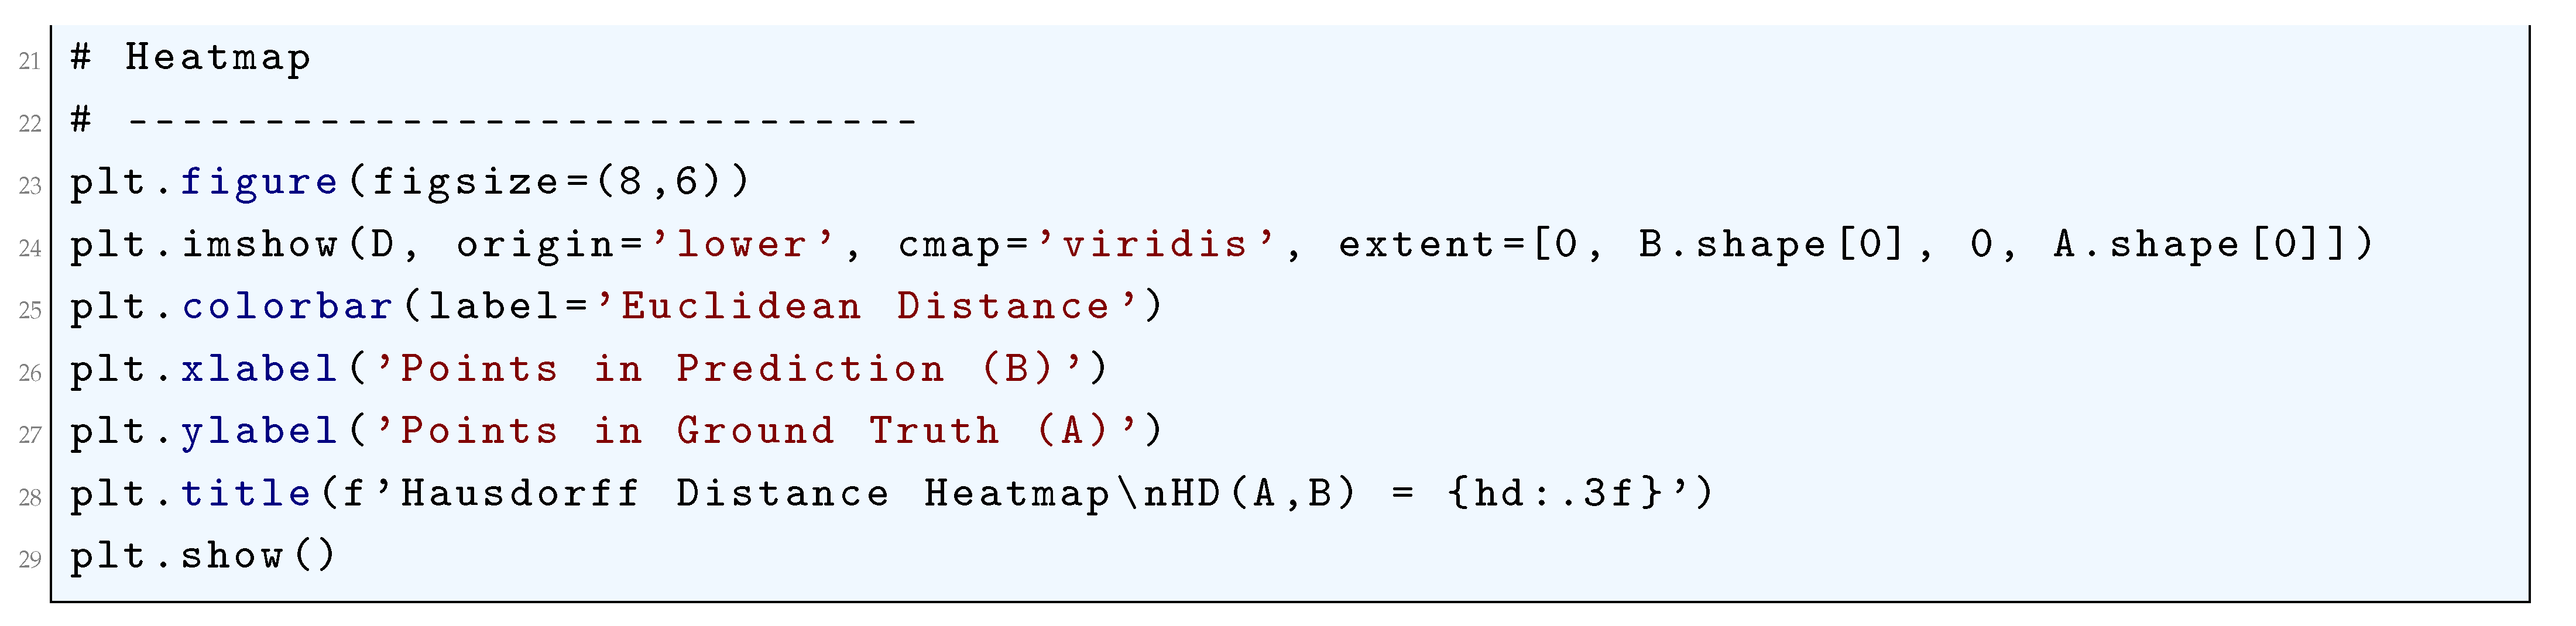
11. Few-Shot Learning
Few-shot learning (FSL) refers to the problem of training a model to generalize to new tasks using only a limited number of labeled examples. Mathematically, given a dataset consisting of N labeled instances, a conventional supervised learning model aims to learn a mapping by minimizing an empirical risk functional of the form
where is an appropriate loss function such as the cross-entropy loss
where denotes the model parameters. However, in a few-shot setting, the number of labeled examples per class is very small, typically denoted as K, where , making it challenging to generalize in a conventional learning paradigm. Few-shot learning is often formalized using meta-learning approaches where the goal is to optimize a learning algorithm itself such that it can quickly adapt to new tasks using very few labeled samples. A common meta-learning formulation involves the optimization of a meta-objective defined over a distribution of tasks . Given a distribution , a meta-learner optimizes parameters such that the expected loss over tasks is minimized:
where each task consists of a small training set (the support set) and a validation set (the query set). The loss function for a given task is typically written as:
where denotes the model adapted using the small support set . A well-known approach to FSL is Model-Agnostic Meta-Learning (MAML), where the optimization is performed by updating such that it rapidly adapts to new tasks via a few gradient updates. Specifically, MAML defines a bi-level optimization problem where an inner loop computes task-specific parameters via gradient descent:
where is the step size. The outer loop then updates based on the loss incurred on the query set:
where is another learning rate. The goal of MAML is to find an initialization such that a small number of gradient steps suffices for good generalization. Another prominent FSL approach is metric-based learning, where models learn an embedding function such that a similarity function enables effective classification in a low-data regime. A widely used method is prototypical networks, which represent each class in the support set with a prototype:
where is the subset of the support set corresponding to class k. Classification is then performed using a softmax function over distances:
where is typically the squared Euclidean distance. The training objective is the negative log-likelihood:
Bayesian methods in FSL adopt a probabilistic framework where uncertainty in model parameters is explicitly modeled using a prior . Given a support set , a Bayesian model infers a posterior over parameters:
A predictive distribution over a new query point is obtained by marginalizing over :
Ultimately, the success of FSL hinges on leveraging shared structure across tasks, designing effective adaptation mechanisms, and optimizing inductive biases to mitigate data scarcity.
11.1. Meta-Learning Formulation in Few Shot Learning
Meta-learning, particularly in the context of Few-Shot Learning (FSL), aims to train a model such that it can generalize effectively to novel tasks with very few training examples. This is accomplished by optimizing the learning process itself, enabling the model to rapidly adapt to new tasks. Given a distribution over tasks , where each task is characterized by a small support set and a corresponding query set , the objective of meta-learning is to train a model with parameters such that it minimizes the expected loss over new tasks drawn from .
where represents the loss function associated with the task , typically computed over the query set after adapting the model using the support set. One of the most widely used meta-learning approaches is Model-Agnostic Meta-Learning (MAML), which optimizes for an initial parameter set that can be quickly adapted to a new task using only a few gradient steps. The inner-loop adaptation updates the model parameters as:
where is the inner-loop learning rate. The meta-objective then minimizes the loss computed on the query set with respect to the updated parameters:
which requires computing the meta-gradient:
leading to the final meta-update:
where is the meta-learning rate. Another formulation follows metric-based meta-learning, where the model learns an embedding function that maps input samples to a feature space where classification can be performed using a simple distance metric. In Prototypical Networks, the class prototype for each class c in the support set is computed as:
where is the set of examples belonging to class c. The probability of assigning a query sample to class c is then given by:
where is a distance metric, often chosen as the squared Euclidean distance. Contrastive learning-based meta-learning methods instead optimize a loss function based on relative similarities. A common choice is the contrastive loss:
where m is a margin parameter and is an indicator function. Bayesian meta-learning approaches introduce a probabilistic treatment where the model parameters are sampled from a learned posterior distribution , updated via variational inference:
where denotes the Kullback-Leibler divergence. The expected posterior predictive distribution for a new task is then computed as:
which can be approximated using Monte Carlo sampling. Gradient-based meta-learning methods can also be formulated using recurrent neural networks, where the meta-learner is a recurrent model that updates a task-specific hidden state over a sequence of examples. Given a sequence of support set updates, the parameterized recurrence is given by:
and the model parameters for a given task are inferred as:
where and are recurrent function approximators parameterized by . These meta-learning paradigms share a common objective: to minimize the expected generalization error of a model trained over a distribution of tasks, enabling rapid adaptation to new scenarios with minimal labeled data. The fundamental mechanism across formulations involves optimizing a bi-level objective where the outer loop adjusts meta-parameters and the inner loop performs task-specific adaptation. The optimization problem governing this framework can be expressed in a general form as:
which encapsulates the core philosophy of meta-learning: learning to learn.
11.2. Bayesian Methods in Few Shot Learning
Bayesian methods in Few-Shot Learning (FSL) provide a principled probabilistic framework for reasoning about uncertainty in the context of limited data. The core objective of FSL is to train a model on a set of "base" classes with abundant data such that it can rapidly generalize to a set of novel classes, for which only a few labeled examples (the support set S) are provided. The Bayesian approach treats the model parameters, or more commonly a task-specific context, as latent random variables, enabling the quantification of epistemic uncertainty arising from the scarcity of data. This is fundamentally expressed through Bayes’ theorem. Let D represent the support set for a novel task, and let represent the model parameters or task-specific adaptation parameters. The posterior distribution over these parameters is given by
where is the prior distribution encapsulating knowledge acquired from the base classes, is the likelihood of the support data, and
is the model evidence. The intractability of this evidence integral necessitates approximate inference techniques.
A prominent Bayesian formulation for FSL involves placing a prior over the parameters of the classifier for novel classes, while the feature embedding network is considered fixed and learned during meta-training. For a N-way, K-shot task, the support set is
The goal is to infer the parameters of the novel-class classifier. A hierarchical Bayesian model posits
where are hyperparameters learned from the base classes. The prior regularizes the novel class classifier. For a linear classifier where , a common prior is an isotropic Gaussian,
The likelihood for the support set, assuming a softmax classification model, is
where W is the matrix of weight vectors and is the feature embedding function. The posterior is then used for prediction on a query point via
Direct computation of the posterior is analytically intractable due to the non-conjugacy of the softmax likelihood and the Gaussian prior. Therefore, variational inference is extensively employed. In this framework, a parameterized variational distribution is introduced to approximate the true posterior. The goal is to minimize the Kullback-Leibler (KL) divergence between the variational approximation and the true posterior, . This is equivalent to maximizing the Evidence Lower Bound (ELBO),
The parameters of the variational distribution are optimized during this inference step. For example, if
then . The expectation is typically estimated via Monte Carlo sampling,
where . The predictive distribution for a query point becomes
marginalizing over the posterior uncertainty.
An alternative and highly influential Bayesian perspective is embodied by the framework of Bayesian meta-learning, particularly through models like the Neural Process and its variants. Here, the entire context of the support set is used to define a latent variable z that represents the task. The generative model for a task is
The conditional likelihood is implemented by a decoder network. The posterior over the task variable given the support set is
Inference is again performed approximately, often using a variational inference scheme where an encoder network amortizes the inference process by mapping the entire support set to a distribution over z. The ELBO for this model is
where are the decoder parameters. The predictive distribution for a query point is
with .
Gaussian Processes (GPs) offer another rigorously Bayesian non-parametric approach to FSL. A GP defines a prior directly over functions,
where is the mean function and is the covariance kernel function. In the FSL setting, the support set S conditions this prior to yield a posterior process. The key equations for prediction are derived from the joint Gaussian distribution of the support and query points. Let and be the inputs and labels of the support set, and be the query inputs. The joint prior is
where for , and similarly for . For regression, the posterior predictive distribution is Gaussian:
with
and
For classification, a likelihood , such as a Bernoulli-logit, is introduced, and the posterior becomes non-Gaussian, requiring approximation methods like Laplace approximation or expectation propagation.
The Bayesian treatment naturally allows for the integration of uncertainty into the learning process itself, a concept formalized in Bayesian optimization for hyperparameter tuning in FSL. The acquisition function, which guides the search for optimal hyperparameters , leverages a surrogate model for the objective function . Given a prior over functions, typically a GP, and observed data , the posterior is used to compute an acquisition function such as Expected Improvement (EI),
where is the current best hyperparameter configuration. This rigorous probabilistic framework for hyperparameter selection is crucial in FSL where the risk of overfitting to the few shots is high. The unifying theme across all these Bayesian methods is the explicit representation of uncertainty through probability distributions, transforming the few-shot learning problem from a point-estimation task into one of full posterior inference, thereby enhancing robustness and calibration.
11.3. Prototypical Networks in Few Shot Learning
Prototypical networks operate within the framework of few-shot classification by learning a non-linear embedding of input data into a metric space where classification can be performed by computing distances to prototype representations of each class. The foundational assumption is that there exists an embedding function with parameters that maps inputs into a d-dimensional space such that points cluster around a single prototype representation for each class. Given a support set where is an input and is its corresponding class label, the prototype for each class k is computed as the mean vector of the embedded support points belonging to that class. This computation is formally expressed by the equation
where denotes the set of support examples labeled with class k.
For a query point x, the prototypical network produces a distribution over classes based on a softmax over the negative distances from the embedded query point to the class prototypes. The distance metric is typically the squared Euclidean distance in the embedding space, defined as
The probability that the query point x belongs to class k is then given by
This formulation aligns with the concept of a Gibbs distribution, where the negative distance acts as an energy function, making the probability proportional to the exponentiated similarity between the query embedding and the class prototype.
The training objective is to maximize the likelihood of the true class for all query points across training episodes, which is equivalent to minimizing the negative log-probability. For a single episode with support set S and a query set Q, the loss function is defined as
where is the true class label of the query point . Substituting the probability expression, the loss becomes
This can be simplified to
which is effectively a cross-entropy loss computed in the metric space.
The learning process occurs through episodic training. Each episode is constructed by randomly selecting a subset of classes , then for each class , selecting a support set and a query set . The complete support set for the episode is and the query set is . The prototypes for all are computed from S, and the parameters of the embedding network are updated by performing a gradient descent step on the loss computed on Q. The update rule is
where is the learning rate. The gradients flow through both the query point embeddings and the prototype computations, as the prototypes are functions of via the support examples. The gradient of the loss with respect to a prototype vector is
where is the indicator function. The gradient with respect to the embedding of a support point is
and the gradient with respect to the embedding of a query point is
The scientific rigor of this approach is rooted in its interpretation as a form of mixture density estimation on the embedded space. If each class-conditional distribution in the embedding space is a spherical Gaussian with a fixed, shared covariance matrix , then the probability density for a point under class k is
Assuming equal prior probabilities for all classes, the posterior probability for class k given z is
By setting , this posterior simplifies exactly to the softmax over negative squared Euclidean distances used in the prototypical network,
This probabilistic foundation provides a rigorous justification for the model’s architecture and loss function, framing it as an approximate inference procedure under a specific generative model of the data in the embedding space. The model’s efficacy is thus contingent upon the embedding network’s ability to transform the input data such that its distribution in the latent space conforms to this isotropic Gaussian assumption per class.
11.4. Model-Agnostic Meta-Learning (MAML) in Few Shot Learning
Model-Agnostic Meta-Learning (MAML) is a fundamental optimization-based approach in few-shot learning, designed to enable models to quickly adapt to new tasks with minimal data. The core idea is to learn an initialization of model parameters that facilitates rapid adaptation through gradient-based updates. Given a distribution over tasks, denoted as , MAML optimizes for a set of parameters such that for a new task , the adapted parameters after a small number of gradient steps yield high performance on the task.
For a given task , we assume a dataset composed of a support set and a query set . Let the model be parameterized by and let the task-specific loss function be . The adaptation to task involves performing one or more gradient descent steps with respect to evaluated on . The standard first-order adaptation rule for a single gradient step is given by:
where is the learning rate for task-specific updates. The meta-objective is to find an initialization such that after task-specific adaptation, the model performs well on the query set . The meta-loss is computed over the query set:
which leads to the outer-level optimization of :
where is the meta-learning rate. Expanding the gradient term using the chain rule,
with
where I is the identity matrix and is the Hessian of the loss function with respect to . The optimization process involves computing second-order derivatives, which can be computationally expensive. A first-order approximation, called First-Order MAML (FOMAML), simplifies this update by ignoring the Hessian term:
where is still obtained using the standard gradient descent update. This approximation reduces computational overhead while still achieving strong meta-learning performance. The effectiveness of MAML depends on its ability to learn an initialization that allows rapid adaptation across a diverse set of tasks. Formally, we define the expected meta-loss over the task distribution:
which represents the expectation over the loss incurred after a single adaptation step. The meta-optimization aims to minimize this expected loss, ensuring that provides an effective starting point for task-specific fine-tuning. For multiple gradient adaptation steps, the parameter update for a given task follows an iterative process:
for , where K denotes the number of inner-loop gradient updates. The final adapted parameters are then used to compute the meta-loss:
which determines the outer-loop optimization of . The full meta-gradient computation involves backpropagating through K gradient updates, leading to higher-order derivative terms:
where each term captures the second-order effects of iterative gradient updates.
11.5. Metric-Based Learning in Few Shot Learning
Metric-based learning in the context of few-shot learning is a paradigm that relies on learning a similarity metric to compare query examples against a set of labeled support examples. Given a support set , where each is an input instance and is its corresponding label, and a query instance , the goal is to predict based on a learned metric function parameterized by . The fundamental principle is that instances belonging to the same class should be mapped closer together in an embedding space, while instances from different classes should be mapped further apart. Mathematically, this can be formulated as minimizing the intra-class variance while maximizing the inter-class variance, which can be written as
where is a weighting factor that controls the relative importance of inter-class separation. The metric function is often implemented using a neural network that maps instances into an embedding space via an encoder , such that
One of the key approaches in metric-based few-shot learning is prototypical networks, where each class in the support set is represented by a prototype , computed as the mean of embedded support examples belonging to class k:
The classification of a query example is then performed by computing its similarity to each prototype, typically using the squared Euclidean distance,
Another prominent approach is relation networks, which replace the explicit distance metric with a learned similarity function , parameterized by . The probability of assigning query to class k is given by
Siamese networks approach metric learning through pairwise comparisons, where a shared encoder maps pairs of examples into an embedding space, and the similarity is computed as
where W is a learned weight vector and is the sigmoid activation function. The model is trained to minimize the binary cross-entropy loss,
Triplet networks extend this by considering an anchor example , a positive example (same class), and a negative example (different class), enforcing the constraint
where m is a margin hyperparameter. The loss function is given by
By optimizing these loss functions, metric-based few-shot learning methods enable models to generalize well to novel classes, as the learned metric encodes class-invariant representations of instances. The embedding space acts as a structured manifold where geometric distances capture semantic similarities, allowing rapid adaptation to unseen tasks with minimal labeled data.
11.6. Bayesian Methods in Few Shot Learning
Bayesian methods in Few-Shot Learning (FSL) provide a probabilistic framework to model uncertainty in learning from a small number of examples. Given a dataset with a limited number of training examples N, Bayesian approaches aim to infer a distribution over the model parameters , rather than a single deterministic estimate, allowing the model to generalize effectively despite limited data. The core idea is to use Bayes’ theorem to compute the posterior distribution over :
where is the likelihood of the data given parameters , is the prior over the parameters, and is the marginal likelihood or evidence. The posterior distribution encapsulates the uncertainty in parameter estimation, making it particularly useful for FSL where the data is scarce.
The Bayesian framework enables meta-learning by assuming that tasks in FSL are drawn from an unknown distribution over tasks . Given a set of tasks , each with a small support set and query set , the goal is to learn a distribution over task-specific parameters conditioned on the support set:
A hierarchical Bayesian model treats the task-specific parameters as drawn from a global distribution with hyperparameters :
where defines a prior distribution over . This enables the model to generalize across tasks by updating the prior using multiple tasks:
Given a new task with support set , the predictive distribution over labels for query inputs is obtained by marginalizing over :
Since exact inference of is often intractable, variational inference is commonly used. We approximate with a variational distribution , parameterized by , minimizing the Kullback-Leibler (KL) divergence:
This leads to an optimization problem where is updated via gradient descent to minimize , ensuring the learned distribution approximates the true posterior. Another approach is Bayesian nonparametrics, where the distribution over functions is modeled using a Gaussian Process (GP), providing a principled way to quantify uncertainty. Given a prior GP:
where is the mean function and is the covariance function, the posterior over functions given training data is:
where and are the posterior mean and covariance functions derived using Bayes’ rule. The predictive distribution for a new input follows:
which yields a closed-form Gaussian predictive distribution due to the properties of GPs. Another key Bayesian technique is Bayesian Neural Networks (BNNs), where instead of learning a single weight matrix W, a distribution over weights is maintained:
Inference in BNNs requires approximations like Monte Carlo Dropout, where approximate Bayesian inference is performed by applying dropout at both training and test time, yielding an empirical posterior:
where are sampled from the variational posterior . This captures uncertainty in predictions, crucial for robust few-shot learning. Bayesian optimization further refines FSL by selecting informative examples to maximize learning efficiency. Given an acquisition function based on the posterior predictive distribution:
a new query point is selected to minimize uncertainty and maximize information gain, enhancing generalization from few samples. Thus, Bayesian methods in FSL provide a mathematically rigorous probabilistic framework to model uncertainty, transfer knowledge across tasks, and make robust predictions even with limited training data.
12. Metric Learning
Metric learning is a fundamental concept in machine learning and mathematical optimization, concerned with learning a distance function or similarity measure that captures the underlying structure of data. Given a set of training samples , where each , the objective is to learn a metric function that quantifies the dissimilarity between any two points. A standard choice for is the Mahalanobis distance, which generalizes the Euclidean distance and is defined as
where is a positive semi-definite matrix, i.e., , ensuring that the distance satisfies the properties of a metric. Learning the matrix is the core challenge in metric learning. When , the metric reduces to the standard Euclidean distance:
However, metric learning seeks to optimize such that semantically similar data points have smaller distances than dissimilar points. This is typically formulated as an optimization problem where we enforce constraints on distances between pairs of points. Given a set of pairs (similar pairs) and (dissimilar pairs), the goal is to satisfy
for some thresholds u and l. One widely used approach to metric learning is Large Margin Nearest Neighbors (LMNN), which seeks to optimize by minimizing a hinge loss on triplets of points , where is closer to than , i.e.,
where the triplet loss ensures that the distance between similar points is smaller than the distance between dissimilar ones by a margin of at least 1. An alternative approach is the information-theoretic metric learning (ITML) framework, which minimizes the Kullback-Leibler divergence between two Gaussian distributions defined by different Mahalanobis distances:
Deep metric learning extends these concepts by parameterizing the metric function using a neural network with learnable parameters , leading to a learned embedding space where distances are computed as
Instead of learning a linear transformation as in Mahalanobis-based methods, deep metric learning implicitly learns a nonlinear mapping such that the Euclidean distance in the transformed space aligns with semantic similarity. The contrastive loss is commonly used in this context:
Alternatively, the triplet loss is defined as
A more recent approach, the normalized temperature-scaled cross-entropy loss (NT-Xent), utilizes a softmax formulation:
where is the cosine similarity,
By optimizing the metric under these constraints, metric learning produces feature representations that are well-structured for downstream tasks such as retrieval, verification, and clustering.
12.1. Large Margin Nearest Neighbors (LMNN) Approach to Metric Learning
The Large Margin Nearest Neighbors (LMNN) approach to metric learning is a method that aims to learn a Mahalanobis distance metric that optimizes nearest neighbor classification by ensuring that points belonging to the same class remain close while different-class points are separated by a large margin. Given a dataset , where represents a feature vector and denotes its class label, LMNN learns a transformation matrix such that the squared distance between any two points is given by
where is a positive semi-definite (PSD) matrix. The optimization problem is designed to minimize classification error by enforcing that each sample remains close to its target neighbors, denoted by , while keeping different-class points at a distance. The objective function consists of two competing terms: a pull term that encourages proximity among target neighbors and a push term that enforces a large margin separation from impostors (samples of different classes that intrude upon the local neighborhood). The pull term is formulated as
This term ensures that the squared distances between each point and its target neighbors remain small. The push term, on the other hand, ensures that impostors—points of a different class than but closer than its farthest target neighbor—are pushed away by at least a margin 1, formulated using hinge loss as
subject to the constraints
The total LMNN objective function combines these terms as
where C is a regularization parameter controlling the tradeoff between the pull and push terms. The constraint ensures that the learned metric remains a valid Mahalanobis distance. The optimization is typically solved using semidefinite programming (SDP) or projected gradient descent methods while enforcing the PSD constraint on . To interpret the impact of the learned metric, consider an eigenvalue decomposition of , given by
where is an orthonormal matrix and is a diagonal matrix of eigenvalues. The transformation effectively maps the original data space into a new space where distances are reshaped to optimize nearest-neighbor classification performance. The LMNN framework ensures that different classes are well-separated while preserving local neighborhood structures, leading to improved generalization in classification tasks.
12.2. Information-Theoretic Metric Learning (ITML) Framework Approach to Metric Learning
The Information-Theoretic Metric Learning (ITML) framework is a fundamental approach to metric learning that formulates the problem as an optimization task driven by information theory principles, particularly Kullback-Leibler (KL) divergence minimization. Given a set of data points , the goal of ITML is to learn a Mahalanobis distance metric parameterized by a positive semi-definite (PSD) matrix , so that distances between similar points are minimized while distances between dissimilar points are maintained above a certain threshold. The Mahalanobis distance between two points and under the learned metric is defined as
where is a symmetric positive semi-definite matrix, i.e., , ensuring that defines a proper distance function. The fundamental idea of ITML is to find a metric that minimizes the divergence from a given prior metric , typically the identity matrix , subject to constraints that enforce distances between pairs of points to satisfy specified conditions. To formalize this, ITML minimizes the KL divergence between the distributions parameterized by and . Given that Gaussian distributions parameterized by a Mahalanobis metric have a natural representation in terms of covariance matrices, the KL divergence between two Gaussian distributions with covariance matrices and is
where denotes the trace operator, and is the logarithm of the determinant. The optimization problem in ITML is thus formulated as
subject to pairwise constraints of the form
where and denote sets of similar and dissimilar pairs, respectively, and are predefined thresholds that control the tightness of the constraints. The use of KL divergence as the objective function ensures that the learned metric remains close to the prior while satisfying the constraints. To solve this optimization problem, a log-barrier method is commonly employed, leading to an iterative update for of the form
where is an adaptive step size chosen to satisfy the constraints. This iterative procedure ensures that remains positive semi-definite at every step. The learned metric is influenced by the data-driven constraints while maintaining a balance between adaptation and preservation of the prior structure. The ITML framework exhibits strong theoretical properties, particularly in terms of generalization and convexity. Since the optimization problem is convex in , the solution is globally optimal, ensuring robustness. Moreover, the constraint formulation allows for a natural interpretation: if the prior , then the learned metric is a transformation of Euclidean space that deforms distances according to the prescribed similarity relationships. In practice, ITML is highly effective due to its ability to incorporate prior knowledge and adapt flexibly to data distributions. The reliance on KL divergence ensures stability in learning, preventing excessive deviation from the prior. By iteratively refining the metric with convex optimization, ITML efficiently learns a Mahalanobis metric that best captures the underlying relationships within the data.
12.3. Deep Metric Learning
Deep Metric Learning (DML) is a fundamental approach in machine learning that aims to learn an embedding function that maps input data points from a high-dimensional space to a lower-dimensional space , such that semantically similar points are brought closer together while dissimilar points are pushed farther apart. Formally, given a dataset with labels , the goal is to optimize the parameters of the embedding function such that for any triplet of points where (anchor) and (positive) belong to the same class (), while (negative) belongs to a different class (), the Euclidean distance in the embedding space satisfies
where is a margin that enforces a minimum separation between positive and negative pairs. To achieve this objective, DML often employs contrastive loss, which minimizes the Euclidean distance between positive pairs while maximizing it for negative pairs. Given a pair , the contrastive loss function is
where if and belong to the same class, otherwise, is the Euclidean distance, and m is a margin parameter. Another widely used loss function in DML is the triplet loss, given by
This loss function ensures that the anchor-positive distance is always smaller than the anchor-negative distance by at least , thereby enforcing clustering of similar instances while separating dissimilar ones. In deep learning-based metric learning, the embedding function is typically parameterized by a deep neural network such as a convolutional neural network (CNN) for image data or a recurrent neural network (RNN) for sequential data. Let x be an input sample and let the network be denoted as . The network is optimized by minimizing the empirical risk
where represents the data distribution. To further refine the embeddings, methods such as hard negative mining are employed, where the negative samples are chosen such that
This strategy ensures that the network focuses on difficult examples that are closer to the anchor, making learning more effective. To generalize beyond triplet-based losses, one can also consider the N-pair loss, which extends the triplet loss by incorporating multiple negatives:
where is a positive sample corresponding to . An alternative formulation is Proxy-based Deep Metric Learning, where trainable class proxies are introduced for each class c, and each input is encouraged to be close to its respective proxy while remaining far from proxies of other classes. The softmax-based proxy loss is
Another recent improvement in deep metric learning involves contrastive learning-based methods, where positive and negative pairs are dynamically generated using a memory bank or momentum encoder. The InfoNCE loss, a contrastive loss derived from mutual information maximization, is
where is a temperature parameter that controls the distribution of distances. Furthermore, a probabilistic perspective can be adopted, where embeddings are modeled as distributions rather than point estimates. This leads to the deep variational metric learning approach, where embeddings are represented as Gaussian distributions , and the distance metric is defined using the Kullback-Leibler divergence
The corresponding loss function is formulated as
Finally, the quality of the learned embeddings can be evaluated using retrieval-based metrics such as mean average precision (mAP), recall at k (R@k), and normalized mutual information (NMI), ensuring that the learned distance metric effectively captures semantic similarity.
12.4. Normalized Temperature-Scaled Cross-Entropy Loss (NT-Xent) Approach to Metric Learning
The Normalized Temperature-scaled Cross-Entropy Loss (NT-Xent) is a fundamental loss function in contrastive learning, particularly in self-supervised representation learning. The NT-Xent loss is designed to maximize agreement between similar (positive) pairs while pushing dissimilar (negative) pairs apart in the learned feature space. Mathematically, it builds upon softmax-based similarity scoring and temperature scaling, ensuring a well-calibrated probabilistic interpretation of similarity.
Given a batch of N samples, let each data point be augmented to obtain two correlated views, denoted as and . These views are encoded into the feature space using a learned function , which is typically a deep neural network. The feature representations of the two augmented views are given by
where the output embeddings are L2-normalized to lie on a unit hypersphere:
The similarity between two representations is computed using the cosine similarity, which is given by
Since and are unit vectors, their dot product is directly the cosine of the angle between them. To define the NT-Xent loss, a temperature scaling parameter is introduced to control the sharpness of the similarity distribution. The temperature-scaled similarity is given by
This scaling prevents collapse by adjusting the entropy of the softmax distribution. The probability of matching with (its positive counterpart) over all possible samples in the batch is computed using the softmax function
The NT-Xent loss for a single positive pair is then formulated as
To compute the full batch-wise NT-Xent loss, we sum over all samples and their corresponding augmentations, leading to
The denominator in the softmax function acts as a contrastive term, where all other embeddings in the batch contribute as negative samples. Since the numerator contains only one positive pair, the loss forces these representations to be closer, while the denominator encourages separation from all other samples. A key insight into NT-Xent is its connection to InfoNCE loss (used in contrastive predictive coding), but it is fully symmetric, meaning both views of the same instance contribute equally. This symmetry helps in learning invariant representations by reinforcing consistent feature extraction across different augmentations. To ensure proper gradient flow, the temperature is crucial. If is too high, the softmax distribution becomes too uniform, leading to weak discrimination. Conversely, if is too low, the model learns overly sharp distributions, which can lead to overfitting. The gradient of NT-Xent loss with respect to the embedding can be derived using the softmax gradient formula
This update step ensures that positive pairs get pulled together while negative pairs are pushed apart in proportion to their softmax probabilities. In the large batch limit, NT-Xent can be approximated by Monte Carlo sampling of negative pairs, ensuring computational efficiency in practical self-supervised learning frameworks such as SimCLR. Thus, the NT-Xent loss serves as a fundamental tool for learning discriminative, invariant, and well-clustered embeddings in self-supervised contrastive learning frameworks.
13. Adversial Learning
Adversarial learning is a fundamental paradigm in machine learning where two models are trained in opposition to each other, leading to the generation of robust representations and improvements in generalization. The central concept underlying adversarial learning can be mathematically formulated in terms of a minimax optimization problem, where one model seeks to maximize an objective function while the other aims to minimize it. Formally, given a function parameterized by , adversarial learning can be framed as
where is the loss function, x is the input, y is the ground truth label, and represents an adversarial perturbation optimized to maximize the loss. The adversarial perturbation is constrained within a perturbation bound , ensuring that the perturbed example remains within a small neighborhood of x according to a given norm constraint:
where represents the p-norm. The most common choice is the -norm, which results in perturbations constrained as
A fundamental technique in adversarial learning is the generation of adversarial examples using gradient-based methods. The Fast Gradient Sign Method (FGSM) computes adversarial perturbations using the sign of the gradient of the loss function with respect to the input:
This results in the adversarial example:
A more refined approach is the Projected Gradient Descent (PGD) method, which iteratively updates the adversarial example using gradient ascent:
where denotes projection onto the -ball of radius around x, and is the step size. The adversarial training process modifies the learning objective by incorporating adversarially generated examples into the training procedure, leading to the following robust optimization problem:
where represents the data distribution. This formulation ensures that the model is trained on worst-case perturbations, improving robustness against adversarial attacks. A generative approach to adversarial learning is encapsulated in Generative Adversarial Networks (GANs), where a generator G and a discriminator D are trained in a two-player minimax game:
Here, the generator G aims to produce samples that are indistinguishable from real samples, while the discriminator D seeks to correctly classify real and generated samples. The optimal discriminator is given by
The equilibrium of the game is attained when , leading to the global minimum of the Jensen-Shannon divergence between real and generated distributions. Variants of adversarial learning include Wasserstein GANs (WGANs), which replace the standard GAN loss with the Wasserstein distance:
where D is constrained to be a 1-Lipschitz function. The Wasserstein distance provides a more stable training procedure by mitigating mode collapse. In reinforcement learning, adversarial learning is utilized in adversarial policy training, where an agent maximizes a reward function while an adversary perturbs the environment:
Here, is the policy, represents adversarial perturbations, and is the reward function. Mathematically rigorous guarantees for adversarial robustness involve formulating certified defenses, which provide provable bounds on a model’s robustness. For example, randomized smoothing transforms a classifier into a smoothed classifier:
A theoretical guarantee on robustness is given by
These mathematical formulations illustrate the depth of adversarial learning, emphasizing its fundamental role in improving model robustness and stability.
13.1. Fast Gradient Sign Method (FGSM) in Adversial Learning
The Fast Gradient Sign Method (FGSM) is a crucial technique in adversarial learning, a domain that investigates the vulnerability of deep learning models to adversarial perturbations. Formally, given a neural network classifier parameterized by , where is an input and y is the corresponding true label, the objective of FGSM is to generate an adversarial example by perturbing along the gradient direction that maximizes the classification loss. The adversarial perturbation is computed using the gradient of the loss function with respect to the input , given by
FGSM constructs an adversarial input by taking the sign of this gradient and scaling it by a perturbation magnitude , leading to the perturbed input
Mathematically, this attack is formulated as an optimization problem where the goal is to maximize the loss function subject to a bounded perturbation constraint:
Since computing the exact solution to this optimization problem is computationally expensive, FGSM employs a first-order approximation using Taylor series expansion:
Maximizing this expression with respect to under the -norm constraint leads to the optimal perturbation:
Substituting this into the perturbed input yields the FGSM formulation:
FGSM exploits the local linearity property of neural networks, which can be seen by considering a first-order approximation of the neural network output near :
Given that neural networks often have high-dimensional input spaces, even a small perturbation aligned with the gradient can induce significant changes in the output, leading to misclassification. If the network assigns class probabilities using a softmax function
then the FGSM attack perturbs in a way that increases the probability of an incorrect class , where
The effectiveness of FGSM depends on . A small may not cause misclassification, whereas a large may introduce perceptible distortions. The impact of FGSM is often analyzed using the decision boundary properties of neural networks. Consider a linear classifier with decision boundary defined by
Applying FGSM perturbs along the gradient direction, which in a linear setting is simply
If is initially correctly classified, then after perturbation, the new decision function evaluation is
If the perturbation shifts this beyond zero, the classification flips. This explains why FGSM can be highly effective, even for small , particularly in high-dimensional spaces where each small perturbation accumulates across dimensions. A key property of FGSM is its transferability across different models. Given two classifiers and , adversarial examples crafted for often remain adversarial for , which can be analyzed using the gradient similarity measure:
This suggests that gradients of different models are often aligned, leading to the observed transferability phenomenon. FGSM can be countered using adversarial training, where the training objective is modified to incorporate adversarial examples:
This formulation leads to robust classifiers that are less sensitive to adversarial perturbations. However, adversarial training increases computational costs, as it requires solving an inner maximization problem during training. Another defense mechanism is gradient masking, where modifications to the loss function result in non-informative gradients:
While this suppresses adversarial perturbations, it does not fundamentally resolve the adversarial vulnerability, as adaptive attacks can circumvent such defenses by using alternative optimization techniques.
13.2. Projected Gradient Descent (PGD) Method in Adversial Learning
Projected Gradient Descent (PGD) is a highly rigorous iterative optimization method employed in adversarial learning to generate adversarial examples that maximize the loss function of a given classifier while ensuring that the perturbation remains within a specified constraint set. The mathematical formulation of PGD follows directly from constrained optimization, where an adversarial perturbation is sought such that a perturbed input induces a maximal classification error while remaining within a bounded perturbation set , often defined by an -norm ball. The adversarial attack is thus formalized as
where denotes the loss function (e.g., cross-entropy loss), is the input sample, y is the corresponding label, and represents the parameters of the model. The perturbation set is commonly chosen as the -ball of radius , given by
To solve the constrained optimization problem, PGD proceeds iteratively by updating in the direction of the gradient of with respect to the input, followed by a projection step to enforce the constraint. Given a step size , the update rule for PGD at iteration t is
where denotes the projection operator that ensures remains within . The projection depends on the choice of the -norm constraint. For the commonly used -ball, the projection is simply
which clips each component of to lie within . For the -ball, projection is achieved by normalizing and scaling the perturbation as
The iterative application of this process ensures that the perturbation maximally increases the loss while adhering to the predefined perturbation budget. In the limit as the step size and the number of iterations , PGD approximates the optimal solution of the constrained maximization problem. This is in contrast to the Fast Gradient Sign Method (FGSM), which performs only a single-step update of the form
PGD is therefore considered a stronger attack, as it allows the adversarial perturbation to explore the loss landscape more effectively by iteratively refining the adversarial example. From a theoretical perspective, PGD can be interpreted as an approximate projected gradient ascent method for solving the constrained maximization problem. Formally, this corresponds to a Lagrangian formulation where the Karush-Kuhn-Tucker (KKT) conditions dictate the optimal perturbation:
where defines the boundary of the perturbation set. The iterative updates in PGD approximate this equilibrium condition numerically. Moreover, when applied iteratively with different random initializations of , PGD can better explore non-convex loss surfaces, making it an effective strategy against adversarially trained defenses.
13.3. Generative Approach in Adversarial Learning
The generative approach in adversarial learning is fundamentally rooted in the interplay between two networks: the generator G and the discriminator D, which are trained in an adversarial manner. The generator aims to synthesize data that is indistinguishable from real data, while the discriminator attempts to distinguish real data from generated data. This setup can be rigorously modeled as a minimax optimization problem, given by
where represents the true data distribution, and is the prior distribution from which latent variables are drawn. The generator learns a mapping , parameterized by , such that the distribution of generated samples approximates . The discriminator, parameterized by , learns a function , which estimates the probability that is drawn from . The training of the generator and discriminator proceeds iteratively, where D is updated by maximizing
and G is updated by minimizing
A fundamental result in adversarial learning is that, given sufficient capacity, the optimal discriminator is
Substituting into the minimax objective leads to the Jensen-Shannon divergence between and , given by
where
and denotes the Kullback-Leibler divergence
In practical settings, this divergence-based formulation leads to issues such as vanishing gradients when and do not overlap significantly. To address this, alternative formulations such as Wasserstein GANs (WGANs) optimize the Wasserstein distance
where f is constrained to be 1-Lipschitz. The Wasserstein distance provides meaningful gradients even when and have disjoint support. The optimal transport formulation of the Wasserstein distance can be rewritten as
where denotes the set of joint distributions with marginals and . A crucial extension of adversarial learning is its application to conditional generation, where the generator learns a conditional distribution . The objective function for a conditional GAN is given by
From a probabilistic standpoint, generative adversarial networks can be interpreted within the framework of energy-based models, where the discriminator implicitly defines an energy function
Minimizing this energy aligns generated samples with the modes of the true distribution, reinforcing the generative modeling capability of adversarial learning.
13.4. Interpreting Generative Adversarial Networks Within the Framework of Energy-Based Models
Generative Adversarial Networks (GANs) can be interpreted probabilistically within the framework of Energy-Based Models (EBMs) by considering their fundamental objective as a minimax optimization problem that implicitly defines an energy function governing the probability distribution of data and generated samples. The generator G and the discriminator D interact in a two-player game, which can be rigorously formulated in the language of probabilistic energy-based models. The discriminator learns to distinguish real data samples from generated ones, while the generator learns to produce samples that minimize the discriminator’s ability to differentiate them.
To formally understand this, let be the true data distribution and be the generator’s induced distribution. The discriminator is parameterized by , where outputs the probability that is a real sample. The optimal discriminator in the standard GAN formulation is derived as:
which emerges from the minimization of the following objective:
In the energy-based interpretation, we introduce an energy function that models the relative likelihood of a sample. The energy function is linked to probability distributions via the Gibbs measure:
where Z is the partition function:
We can define an energy-based discriminator as:
where is the sigmoid function. This formulation implies that minimizing the GAN objective is equivalent to learning an energy function such that:
which is precisely the log-ratio of the real and generated distributions, making GANs inherently an instance of energy-based models. From a probabilistic standpoint, the generator learns to minimize the divergence between and . Specifically, for a fixed discriminator, the generator’s objective can be rewritten as minimizing the Jensen-Shannon divergence:
where . This reveals that GANs operate within an information-theoretic framework where they reduce an energy-based measure of dissimilarity between real and generated samples. The training dynamics can be interpreted through contrastive divergence, which appears naturally in energy-based models. The generator updates its parameters to produce samples that have lower energy, thereby implicitly performing a form of Markov Chain Monte Carlo (MCMC)-like sampling in the energy landscape defined by . The gradient update of the generator is:
which aligns with the contrastive divergence updates used in training energy-based models. This equivalence suggests that GANs effectively perform energy minimization by dynamically adjusting G such that its samples reduce the energy discrepancy between real and generated distributions. Furthermore, considering a continuous-time stochastic formulation, the discriminator can be reinterpreted using a Langevin-type evolution:
where is a white noise process and controls the temperature of the energy model. This perspective suggests that adversarial training implicitly simulates diffusion in an energy-based potential field, refining the generator’s distribution over time. Thus, from a probabilistic viewpoint, generative adversarial networks fundamentally operate as an energy-based model where the discriminator estimates an energy function that guides the generator toward producing samples that match the statistics of real data. This establishes GANs as a probabilistic framework akin to energy minimization methods such as Boltzmann Machines, where adversarial training serves as an implicit mechanism for defining an energy landscape in the data space.
14. Casual Inference in Deep Neural Networks
Causal inference in deep neural networks involves the rigorous mathematical study of cause-and-effect relationships within high-dimensional representations learned by deep models. Unlike traditional statistical correlation, causal inference seeks to understand how perturbations in input variables propagate through the model to affect outcomes, disentangling spurious correlations from true causation. Given a set of random variables X, Y, and Z, a fundamental question in causal inference is whether X causally influences Y or whether their observed association is due to a confounding factor Z. The structural causal model (SCM) framework formalizes this using a set of structural equations:
where and are deterministic functions encoding the causal mechanisms, and and are exogenous noise variables, assumed to be mutually independent. The central problem in causal inference is identifying causal effects through interventions, denoted as , which replace the original structural equation of X with a fixed value x, leading to a new distribution:
This contrasts with traditional conditional probabilities , which do not eliminate confounding. In deep neural networks, causal inference is particularly challenging due to the high-dimensional, entangled nature of representations. Given a deep neural network parameterized by weights , mapping an input X to an output Y through multiple layers:
where denotes the activations at layer l, and are the weight matrices and biases, and is a nonlinear activation function, causal inference seeks to identify whether perturbations in X affect Y via a causal pathway. One approach to formalizing causality in deep networks is the use of causal feature selection, which attempts to identify a subset of features S such that:
for all in the support of , ensuring that selected features S are causally relevant to Y. This can be achieved using conditional independence tests based on the back-door criterion:
where Z blocks all back-door paths between X and Y. In deep neural networks, this translates to modifying network architectures to impose structural constraints that enforce causal dependencies. A key tool in causal inference for deep learning is the concept of counterfactual reasoning. Given an observed instance leading to output , a counterfactual query asks what would have happened had X been different:
where denotes an intervention setting X to , and reconstructs the counterfactual world. Estimating counterfactuals in deep models requires generative approaches such as variational autoencoders (VAEs) and normalizing flows, which approximate the latent space U from which counterfactual samples can be drawn. The fundamental theorem of causality states that if a probability distribution is generated from an SCM, then all counterfactual quantities are identifiable from the structural equations. Given a trained neural network with loss function , causal constraints can be imposed by regularizing for causal invariance:
where controls the strength of the causal penalty. This ensures that deep models learn representations aligned with causal mechanisms rather than spurious correlations. Another crucial aspect is the causal transportability of learned models, ensuring that a model trained in one environment generalizes to another with different distributions . This is characterized by domain adaptation techniques that minimize the divergence:
where is the distribution in the target domain, and D is a divergence measure such as KL-divergence:
In deep networks, this is achieved using domain-invariant representations through adversarial training or contrastive learning. A critical issue in causal inference is the identifiability of causal effects from observational data. The fundamental problem of causal inference states that counterfactual outcomes cannot be directly observed:
for , meaning that estimating requires additional assumptions such as unconfoundedness:
which allows estimation using propensity score matching:
Thus, deep causal inference seeks to disentangle causal structure within neural networks, ensuring that learned representations encode true causal effects rather than spurious correlations. This requires integrating structural causal models, counterfactual reasoning, domain adaptation, and invariant risk minimization, ensuring that deep models generalize to unseen domains while preserving causal mechanisms.
14.1. Structural Causal Model (SCM)
A Structural Causal Model (SCM) is a rigorous mathematical framework for representing and reasoning about causal relationships between variables. It formalizes causality using structural equations and directed acyclic graphs (DAGs) to capture cause-and-effect mechanisms. Given a set of endogenous variables and exogenous variables , an SCM is defined as a tuple , where is a set of deterministic structural equations, and is a probability distribution over exogenous variables. Each endogenous variable is determined by a function of its parents in the causal graph and the corresponding exogenous variables:
where represents the set of parent variables of in the causal graph. The causal relationships between variables are represented using a directed acyclic graph , where each edge signifies that is a direct cause of . The absence of an edge between and indicates conditional independence given other parents. The structural equations define the causal mechanism, and their functional form encodes counterfactual relationships. Given an intervention , where the variable X is forcibly set to x, the new SCM modifies the equation for X while keeping all other equations unchanged:
where represents the modified set of structural equations with X replaced by the constant x. Causal effects are quantified using interventional distributions. The post-intervention distribution of an outcome Y given an intervention on X is computed using the causal effect formula:
which integrates out all non-intervened variables. The backdoor criterion provides a criterion for identifying when a set of variables blocks all backdoor paths from X to Y, leading to the adjustment formula:
Counterfactuals are evaluated by computing potential outcomes. Given an observed world where and , the counterfactual query seeks the value Y would have taken had X been set to . This is formalized using the three-step counterfactual algorithm:
- Abduction: Infer exogenous variables using the observed data:
- Action: Modify the SCM by replacing X with :
- Prediction: Solve for in the modified SCM:
The probability of causation (PC) quantifies the likelihood that X caused Y by comparing the counterfactual and factual outcomes:
which requires structural knowledge of the system. Identification of causal effects depends on graphical conditions such as the front-door criterion, which allows inference of even when confounding is unobserved, provided an intermediate variable M satisfies:
SCMs generalize probabilistic models by encoding mechanistic relationships rather than mere statistical associations. The key distinction is that SCMs allow answering counterfactual queries, distinguishing correlation from causation, and supporting robust decision-making under interventions.
14.2. Counterfactual Reasoning in Causal Inference for Deep Neural Networks
Counterfactual reasoning in causal inference for deep neural networks is fundamentally grounded in the potential outcomes framework. Suppose we define an observed data distribution as , where represents the input features, denotes the binary treatment assignment, and represents the observed outcome. In the potential outcomes framework, each unit i has two possible outcomes: when treated and when untreated. The observed outcome is expressed as
However, the counterfactual outcome, which is the outcome corresponding to the treatment level not received, remains unobserved. The fundamental problem of causal inference lies in estimating this counterfactual quantity. The treatment effect for an individual i is given by
but due to the missing counterfactual, it is not directly observable. The average treatment effect (ATE) is expressed as
which requires estimation of both the factual and counterfactual expectations. One approach to estimating counterfactuals in deep neural networks is using representation learning to balance treatment groups. A neural network is trained to learn a latent representation such that the distributions of treated and untreated units become similar:
where is a deep neural network parameterized by . The objective function often incorporates a domain discrepancy measure such as the Integral Probability Metric (IPM):
By minimizing this term, the network ensures that the latent distributions for treated and control groups are similar, facilitating counterfactual inference. A common loss function for training the neural network includes both factual prediction loss and a regularization term for domain alignment:
A counterfactual prediction is obtained by passing through the network trained on both factual and imputed counterfactual distributions:
where is the output layer of the neural network parameterized by . To improve counterfactual estimation, techniques such as adversarial balancing loss and domain adaptation methods may be incorporated:
Here, is a discriminator network that tries to distinguish between treated and untreated units in latent space, and its adversarial training ensures treatment group similarity. Thus, counterfactual reasoning in deep neural networks is achieved by leveraging representation learning, adversarial domain adaptation, and balanced predictive modeling to estimate missing potential outcomes.
14.3. Domain Adaptation in Causal Inference Within Deep Neural Networks
Domain adaptation in causal inference within deep neural networks is fundamentally concerned with the transfer of knowledge from a source domain to a target domain , where the distributions of the input features and the causal mechanisms governing the relationships among variables differ between domains. Given an input space , a covariate space , an outcome space , and a treatment space , we consider the problem of estimating the causal effect of treatment on outcome under domain shift. Specifically, let and denote the joint distributions in the source and target domains, respectively. The key assumption in causal domain adaptation is that while the distribution of covariates and may differ, the underlying structural causal model (SCM) governing the treatment and outcome relationship remains invariant across domains. Mathematically, the invariance of causal mechanisms implies that the conditional distributions of treatment assignment and outcome given the covariates are domain-independent:
However, direct inference of the causal effect in the target domain is hindered by the discrepancy between the marginal distributions and , a phenomenon known as covariate shift. This necessitates a reweighting strategy to correct for the distributional shift. A common approach involves the use of importance weights:
which can be estimated via density ratio estimation techniques such as kernel mean matching or adversarial learning. Given these weights, the expectation of any function in the target domain can be approximated using observations from the source domain:
A deep neural network-based approach to causal domain adaptation typically parameterizes the outcome model as a neural network with parameters , trained to minimize the weighted empirical loss:
where is a suitable loss function such as mean squared error for continuous outcomes or cross-entropy loss for binary outcomes. Additionally, domain-adversarial neural networks (DANNs) introduce a domain discriminator , parameterized by , trained to distinguish between source and target samples while the feature extractor is trained to minimize the discriminator’s ability to differentiate domains, effectively promoting invariant feature representations:
By integrating the domain-invariant representation with causal inference models, the confounding bias induced by distribution shift is mitigated, allowing for unbiased estimation of the causal effect in the target domain. Furthermore, the potential outcome framework in deep learning-based causal domain adaptation estimates the counterfactual outcomes using a shared feature encoder and domain-invariant treatment-response functions and :
The individualized treatment effect (ITE) is then estimated as:
To ensure domain generalization, recent advances incorporate representation learning techniques such as contrastive learning and information bottlenecks, where the feature extractor is regularized to minimize the mutual information between domain-specific variations and the learned representations:
where represents an augmented version of X through domain-specific transformations. The overall objective function in deep causal domain adaptation thus integrates causal loss, domain invariance constraints, and representation learning regularization:
where and are hyperparameters controlling the trade-off between causal effect estimation, domain adaptation, and representation alignment. By leveraging deep learning-based approaches for domain adaptation in causal inference, robust estimation of treatment effects is achieved even in the presence of significant distributional shifts, thereby enhancing the reliability of causal effect estimation in real-world applications.
14.4. Invariant Risk Minimization (IRM) in Causal Inference for Deep Neural Networks
Invariant Risk Minimization (IRM) is a paradigm in causal inference and deep learning that aims to learn representations of data that lead to predictors that are invariant across different environments. Consider a dataset collected from multiple environments , each defined as a probability distribution , where X denotes the input features, and Y represents the target variable. The goal of IRM is to learn a predictor that maintains its predictive performance across all possible environments, thereby capturing the causal relationship between X and Y rather than spurious correlations specific to particular environments.
Mathematically, let denote the hypothesis space, which includes functions h parameterized by a deep neural network. We define an invariant predictor h that minimizes the worst-case risk over all observed environments:
where the empirical risk in environment e is given by:
with ℓ being a loss function, commonly the squared error loss for regression:
or the cross-entropy loss for classification:
A crucial observation is that empirical risk minimization (ERM), which minimizes the sum of risks over all environments,
often leads to predictors that exploit spurious correlations present in specific environments rather than capturing the invariant relationship. To address this, IRM introduces an additional constraint to enforce invariance in the predictor. Specifically, it seeks a representation function such that a classifier w trained on Z remains optimal across all environments:
subject to the invariance constraint:
To relax this constraint into a differentiable objective, the IRM penalty is introduced:
Here, the gradient term ensures that the classifier w remains optimal across all environments by enforcing that its gradient with respect to w vanishes. The hyperparameter controls the strength of this regularization. Expanding the penalty term,
ensuring that the gradients of the risks are aligned across environments. A deeper connection to causality emerges when considering the Structural Equation Model (SEM):
where Z are the causal features, S are spurious features, and is an independent noise term. An ERM-trained deep network might learn S because it improves empirical risk minimization in observed environments, while IRM discourages dependence on S by enforcing that the predictor generalizes across all environments. A theoretical justification for IRM follows from an analysis of the optimal invariant predictor. Define the optimal classifier for a given representation :
For a truly invariant representation , the classifier should be identical across all environments:
This leads to the condition:
which is precisely the IRM penalty. Empirically, training with IRM often results in improved out-of-distribution generalization compared to standard deep learning approaches. Finally, an alternative interpretation of IRM emerges from considering a variational bound on the mutual information between the learned representation and the causal variables:
IRM implicitly maximizes this information while minimizing the conditional entropy , leading to representations that capture causal relationships rather than spurious correlations.
14.5. Empirical Risk Minimization (ERM) in Causal Inference for Deep Neural Networks
Empirical Risk Minimization (ERM) is a fundamental principle in statistical learning theory, providing a framework for optimizing predictive models, particularly within deep neural networks (DNNs). In the context of causal inference, ERM is adapted to account for the complexities introduced by confounding variables, treatment assignment mechanisms, and counterfactual estimation. Given a dataset , where represents covariates, denotes the binary treatment assignment, and is the observed outcome, the goal of causal inference is to estimate the Individual Treatment Effect (ITE), defined as
The empirical risk in classical supervised learning is given by
where is the hypothesis function parameterized by a deep neural network and is a loss function, such as the squared loss
However, in causal inference, the presence of treatment assignment T necessitates a modified objective that accounts for the potential outcome framework. A common approach is to estimate the potential outcomes and using separate deep neural networks, and , parameterized by , leading to the empirical risk formulation
This objective function is a weighted empirical risk based on the observed treatment assignment, ensuring that only the factual outcome is used in training. The challenge arises due to the imbalance in treatment assignments, leading to potential covariate shift between the treated and control groups. To mitigate this, inverse propensity weighting (IPW) is often incorporated, where the empirical risk is modified as
where is the propensity score. This adjustment ensures that the empirical distribution of covariates in both treatment groups better approximates the underlying population distribution. However, direct inverse weighting can lead to high variance, motivating the use of balancing representations via domain adaptation methods such as representation learning with deep neural networks. Specifically, a feature representation function is learned such that the treated and control groups become indistinguishable in the transformed space. The empirical risk in this case is
with an additional discrepancy term penalizing differences between the distributions of under and , such as the Maximum Mean Discrepancy (MMD),
where is a kernel function and is the reproducing kernel Hilbert space. The final objective function then combines empirical risk minimization with regularization for balancing:
An alternative regularization strategy is adversarial balancing, where a discriminator is trained to distinguish between treated and control units, and is trained adversarially to make this discrimination difficult. The objective for and D is formulated as a min-max problem:
This ensures that the learned representation is treatment-agnostic, improving generalizability to counterfactual estimation. Additionally, doubly robust methods integrate both outcome modeling and inverse weighting by introducing a correction term based on residuals from a separate outcome model :
This formulation ensures consistency even when either the outcome model or the propensity score model is misspecified. Ultimately, the optimization of these empirical risk formulations in deep neural networks involves gradient-based methods, with stochastic gradient descent (SGD) or Adam optimizing , while the propensity score model is learned via logistic regression or a separate neural network. The complexity of ERM in causal deep learning thus lies in balancing factual accuracy, counterfactual generalization, and representation learning to ensure robust ITE estimation.
15. Network Architecture Search (NAS) in Deep Neural Networks
Network Architecture Search (NAS) in Deep Neural Networks (DNNs) is an optimization problem that seeks to automatically design the best neural network architecture for a given task, typically involving a search space , a search strategy , and a performance evaluation metric . Mathematically, the NAS problem can be framed as finding the optimal architecture that maximizes a performance function , which can be formally written as
where represents the dataset used for training and evaluation. The search space defines the possible neural network architectures, which can be represented as a directed acyclic graph (DAG) , where nodes V correspond to layers (such as convolutional, fully connected, or recurrent layers), and edges E represent connections between layers. The function is typically defined in terms of accuracy, loss, computational efficiency, and resource constraints. The search process can be formulated as a reinforcement learning (RL) problem, where an agent explores the architecture space and updates its policy using rewards derived from model performance. Let be a policy parameterized by , which selects an action (modifying the architecture) given state (current architecture configuration). The expected reward function is then
where is a trajectory sampled from policy , is a discount factor, and is the reward (e.g., validation accuracy). Policy gradient methods such as REINFORCE update the policy via gradient ascent,
where is the cumulative reward of a sampled trajectory. Alternatively, evolutionary algorithms model the search as a population-based optimization problem, evolving architectures through crossover and mutation operators. The fitness function in this context is given by
where is an evaluation metric such as classification accuracy or mean squared error. Another approach is gradient-based NAS, where the architecture is parameterized by continuous variables and optimized via gradient descent. If w denotes network weights and is the loss function, then the architecture optimization problem is
where are optimal weights obtained by solving
The optimization follows a bilevel formulation, where the outer optimization updates while the inner optimization solves for w. The gradient of with respect to is computed using implicit differentiation,
A continuous relaxation of discrete architectures is achieved using softmax over candidate operations ,
The optimal architecture is obtained by discretizing after training. The computational complexity of NAS is often mitigated by weight sharing across architectures, leading to one-shot NAS methods where a supernet encompasses all possible subnets , and training occurs over a shared weight space W,
After training, the best subnet is selected by evaluating candidate architectures sampled from . The performance of a neural architecture is influenced by hyperparameters , which affect layer depth, width, and activation functions. A common formulation includes multi-objective optimization,
where represents computational cost (e.g., FLOPs or latency). The search can be constrained using Lagrange multipliers,
with the optimal trade-off achieved by solving
By iteratively refining , the search converges to architectures with high performance and low computational cost. The theoretical underpinnings of NAS rely on neural tangent kernels (NTKs) to approximate training dynamics, where the NTK matrix evolves as
where is the learning rate. A stable architecture satisfies the condition
Thus, NAS systematically optimizes architectures through structured exploration of the search space, reinforcement learning, evolutionary algorithms, differentiable search, and surrogate modeling, ensuring optimality under computational constraints.
15.1. Evolutionary Algorithms in Network Architecture Search
Evolutionary Algorithms (EAs) have emerged as a powerful approach for automating Network Architecture Search (NAS) in Deep Neural Networks (DNNs), leveraging principles of natural evolution to optimize network topologies. The core idea is to represent a neural network architecture as a set of hyperparameters and connection structures, encoding them into a genetic representation that undergoes evolutionary processes such as selection, mutation, and crossover to explore the vast search space efficiently. Given a population of architectures , where each represents a candidate neural network, we define the fitness function , which evaluates the performance of a network based on metrics such as validation accuracy, computational efficiency, or robustness to perturbations.
Figure 144.
Evolution of Architectures in NAS using Evolutionary Algorithm
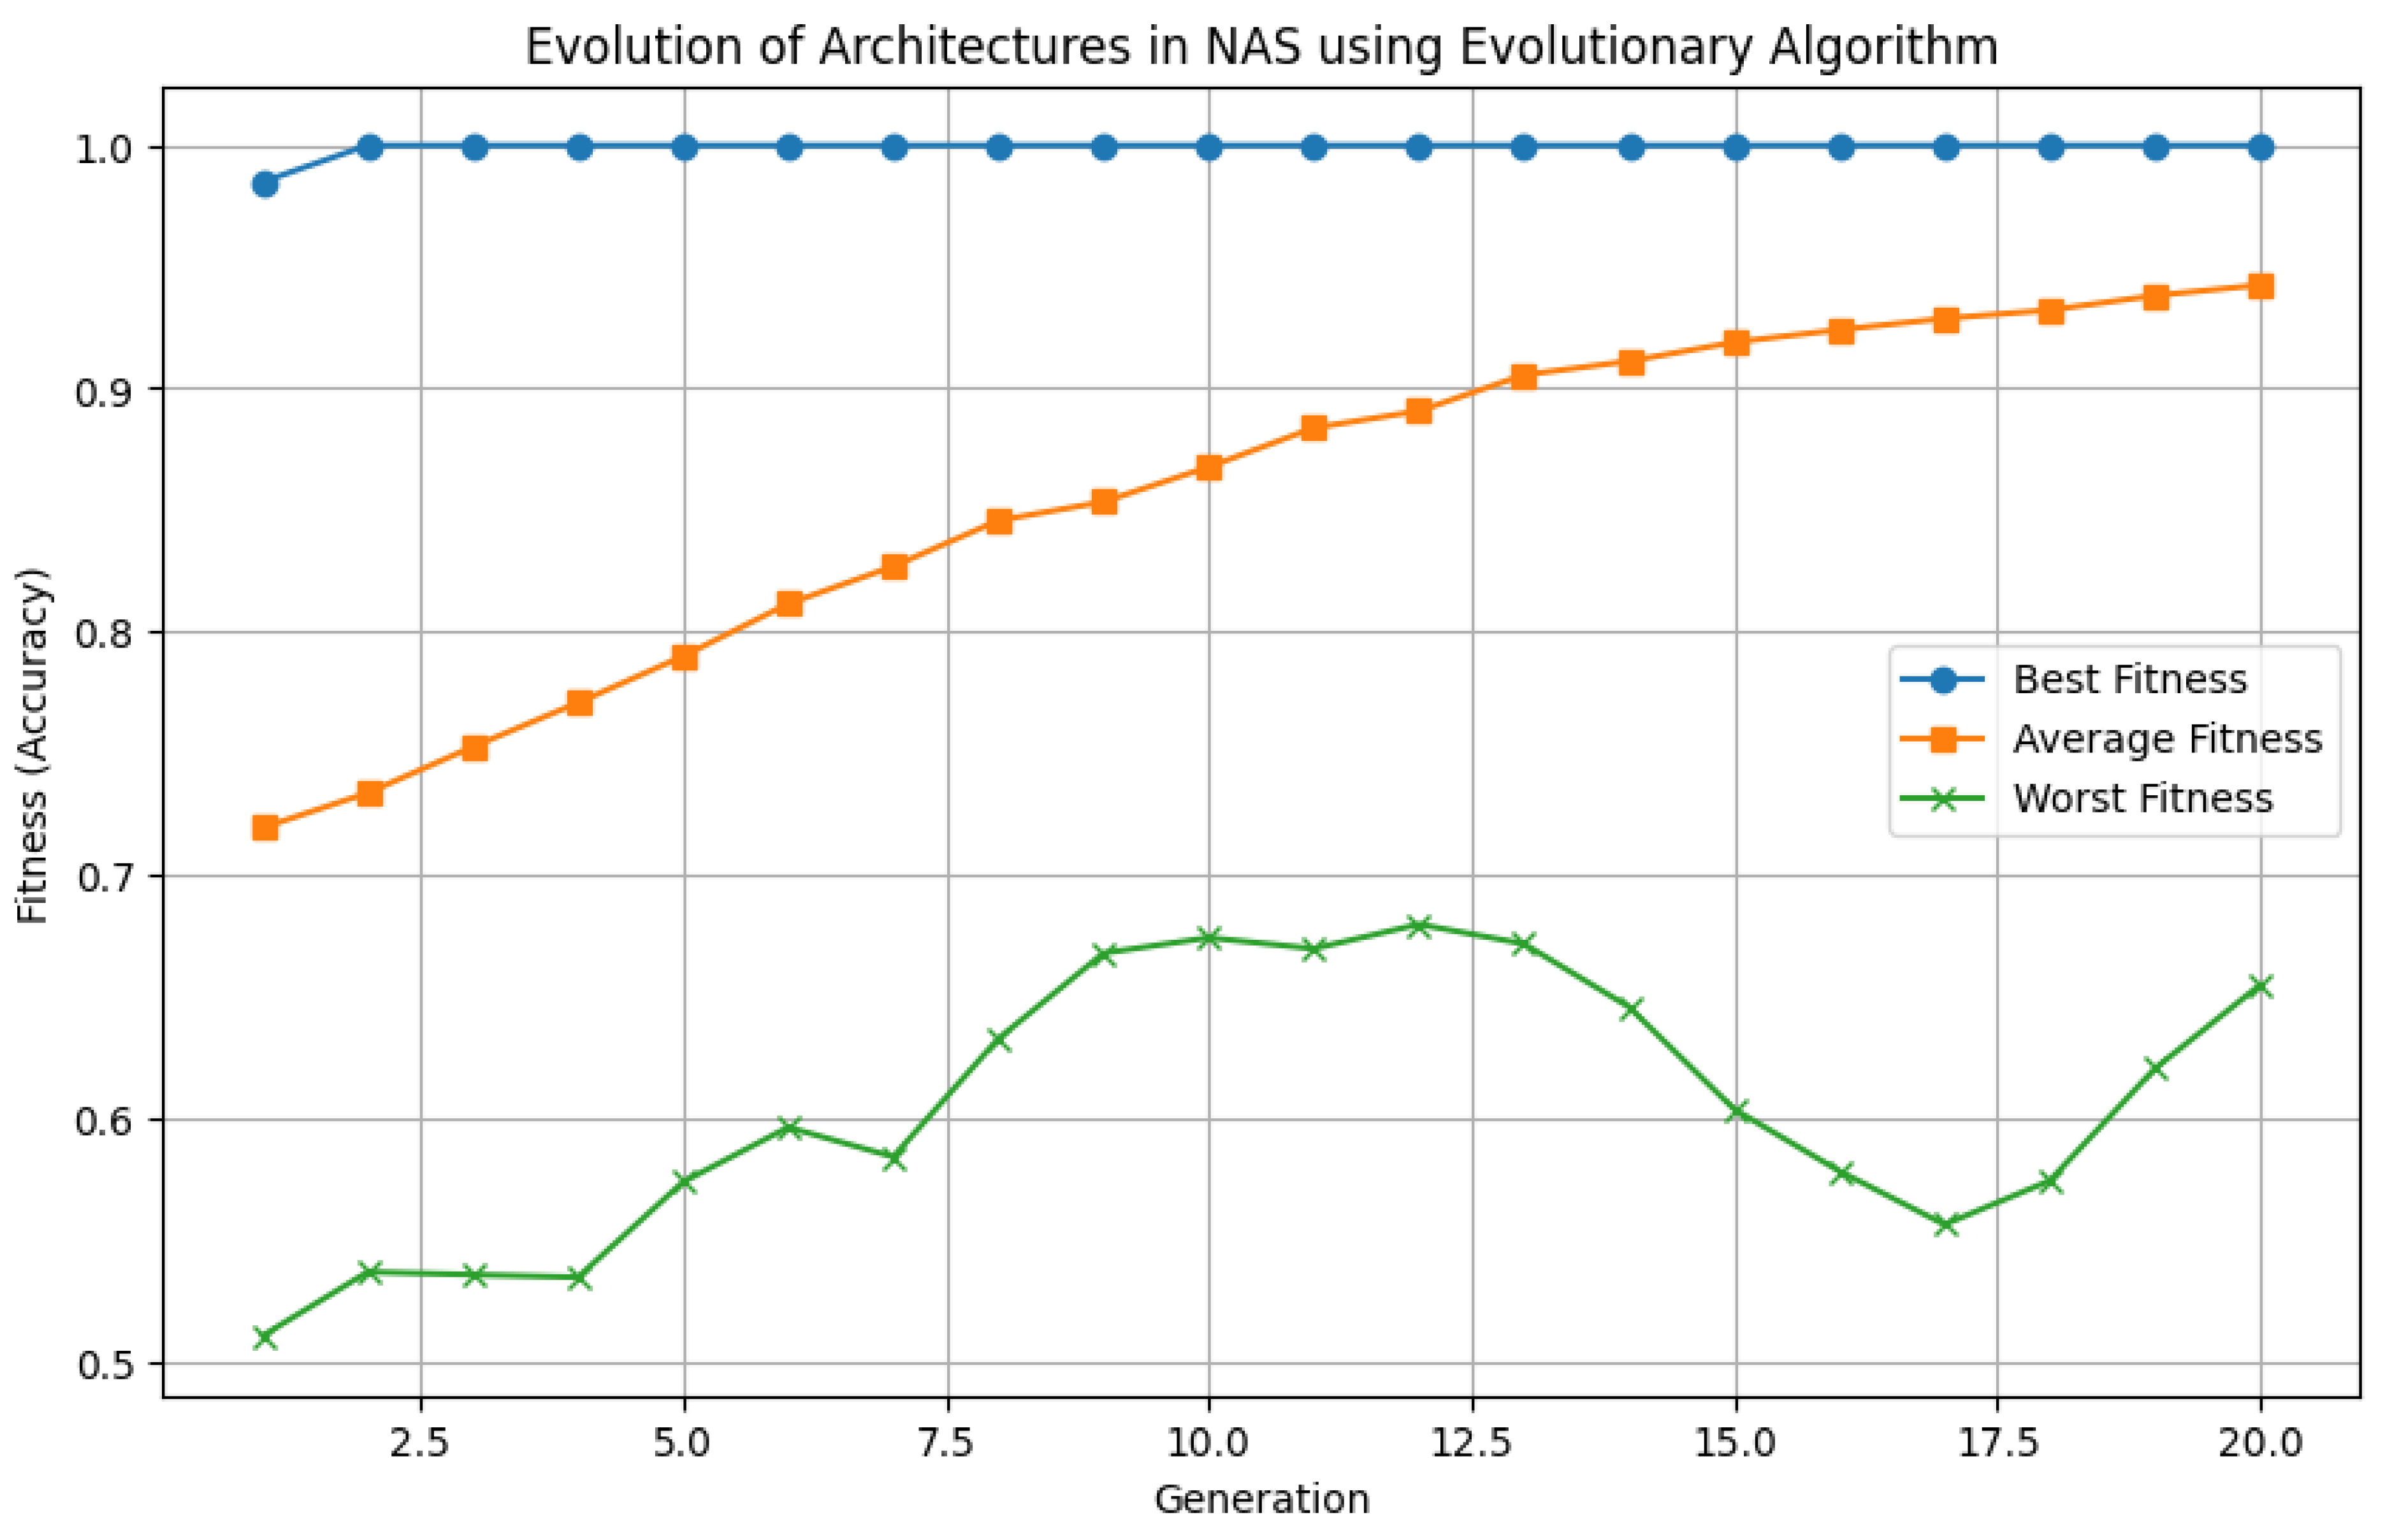
Each neural network architecture can be described by a directed acyclic graph (DAG) , where represents the set of layers (e.g., convolutional layers, pooling layers, fully connected layers), and represents the connections between them. A typical encoding scheme maps to a vector representation , where each element represents hyperparameters such as the number of filters in a convolutional layer l, kernel sizes , and activation functions . The architecture search problem can thus be formulated as an optimization problem:
where is the feasible set of architectures defined by design constraints (e.g., hardware constraints, FLOP limitations). The evolutionary process begins with the initialization of a population , where architectures are randomly generated or sampled from prior knowledge. At each generation t, a selection operator S chooses a subset of architectures based on their fitness scores:
Common selection methods include tournament selection and rank-based selection. The selected architectures undergo crossover and mutation operations. Crossover combines two parent architectures and to produce an offspring using a recombination function C:
For instance, if architectures are encoded as binary strings representing layer connections, one-point or uniform crossover can be applied:
where k is a randomly selected crossover point.
Figure 145.
Evolutionary Algorithm in Neural Architecture Search
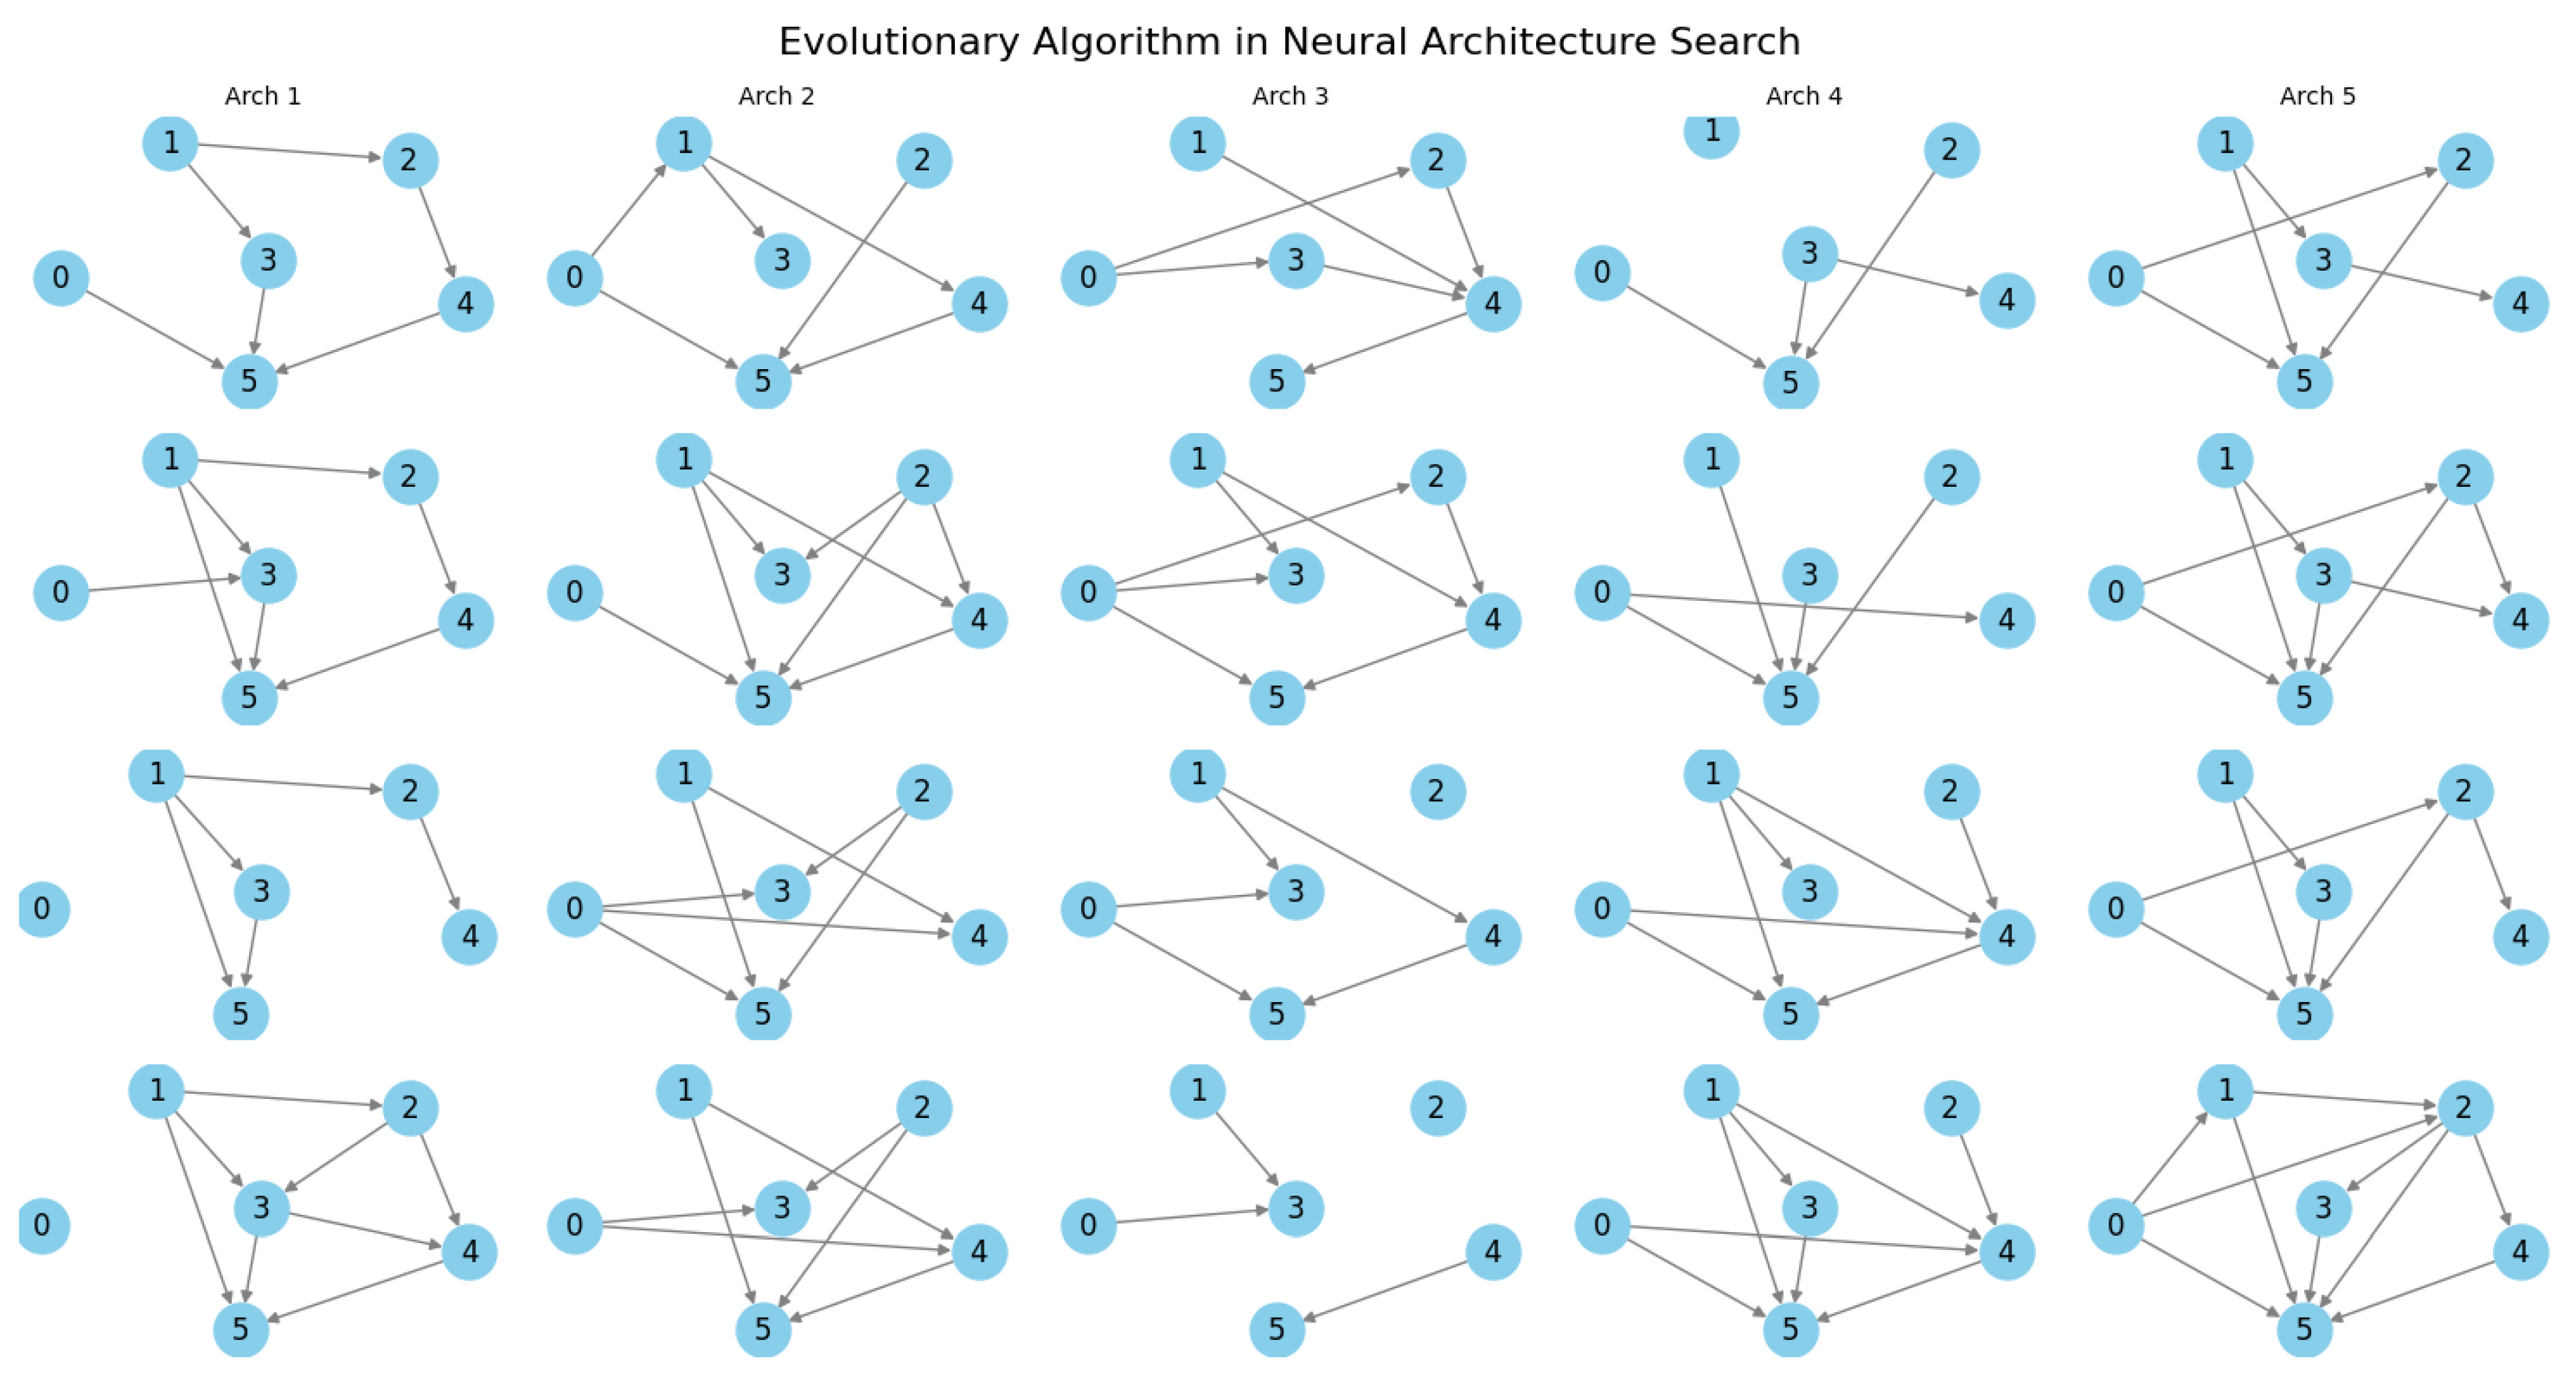
Mutation introduces random variations in the offspring architecture to maintain diversity in the population. Given a mutation rate , a mutation operator M perturbs the architecture encoding:
Common mutation operations include altering the number of filters , modifying kernel sizes , or randomly inserting/deleting layers. The updated population for the next generation is formed by selecting the top-performing architectures:
where is the set of offspring architectures and elitism ensures that the best architectures persist across generations. The process repeats until a termination criterion is met, such as a maximum number of generations T or convergence in fitness scores:
where is a predefined tolerance threshold. The search efficiency of EAs can be enhanced using surrogate models that approximate the fitness function:
where is a kernel function and are weights learned from evaluated architectures. Bayesian optimization and neural predictors are often employed to guide the search towards promising regions of . To further improve convergence speed, weight inheritance strategies transfer trained weights from parent networks to offspring, reducing the need for full training cycles. Given a parent-offspring pair , weight inheritance is expressed as:
where and denote the weight matrices of the parent and child networks, and is a transformation function that maps weights based on structural similarities. Evolutionary NAS has demonstrated competitive performance against reinforcement learning-based and gradient-based approaches, particularly in discovering novel architectures for convolutional neural networks (CNNs) and transformers. The combination of evolutionary search with differentiable search spaces, such as in Differentiable Architecture Search (DARTS), leads to hybrid methods where architectures evolve within a continuous relaxation of the search space:
where represents architecture parameters and is a softmax function ensuring differentiability. By integrating EAs with differentiable optimization, recent methods achieve state-of-the-art performance while maintaining exploration capabilities.
15.2. Reinforcement Learning in Network Architecture Search
Reinforcement Learning (RL) plays a pivotal role in Network Architecture Search (NAS) for Deep Neural Networks (DNNs) by formulating the problem as a sequential decision-making process, wherein a policy optimizes the selection of architectural components to maximize a predefined performance metric, typically validation accuracy.
Figure 146.
Reinforcement Learning in Neural Architecture Search (NAS)
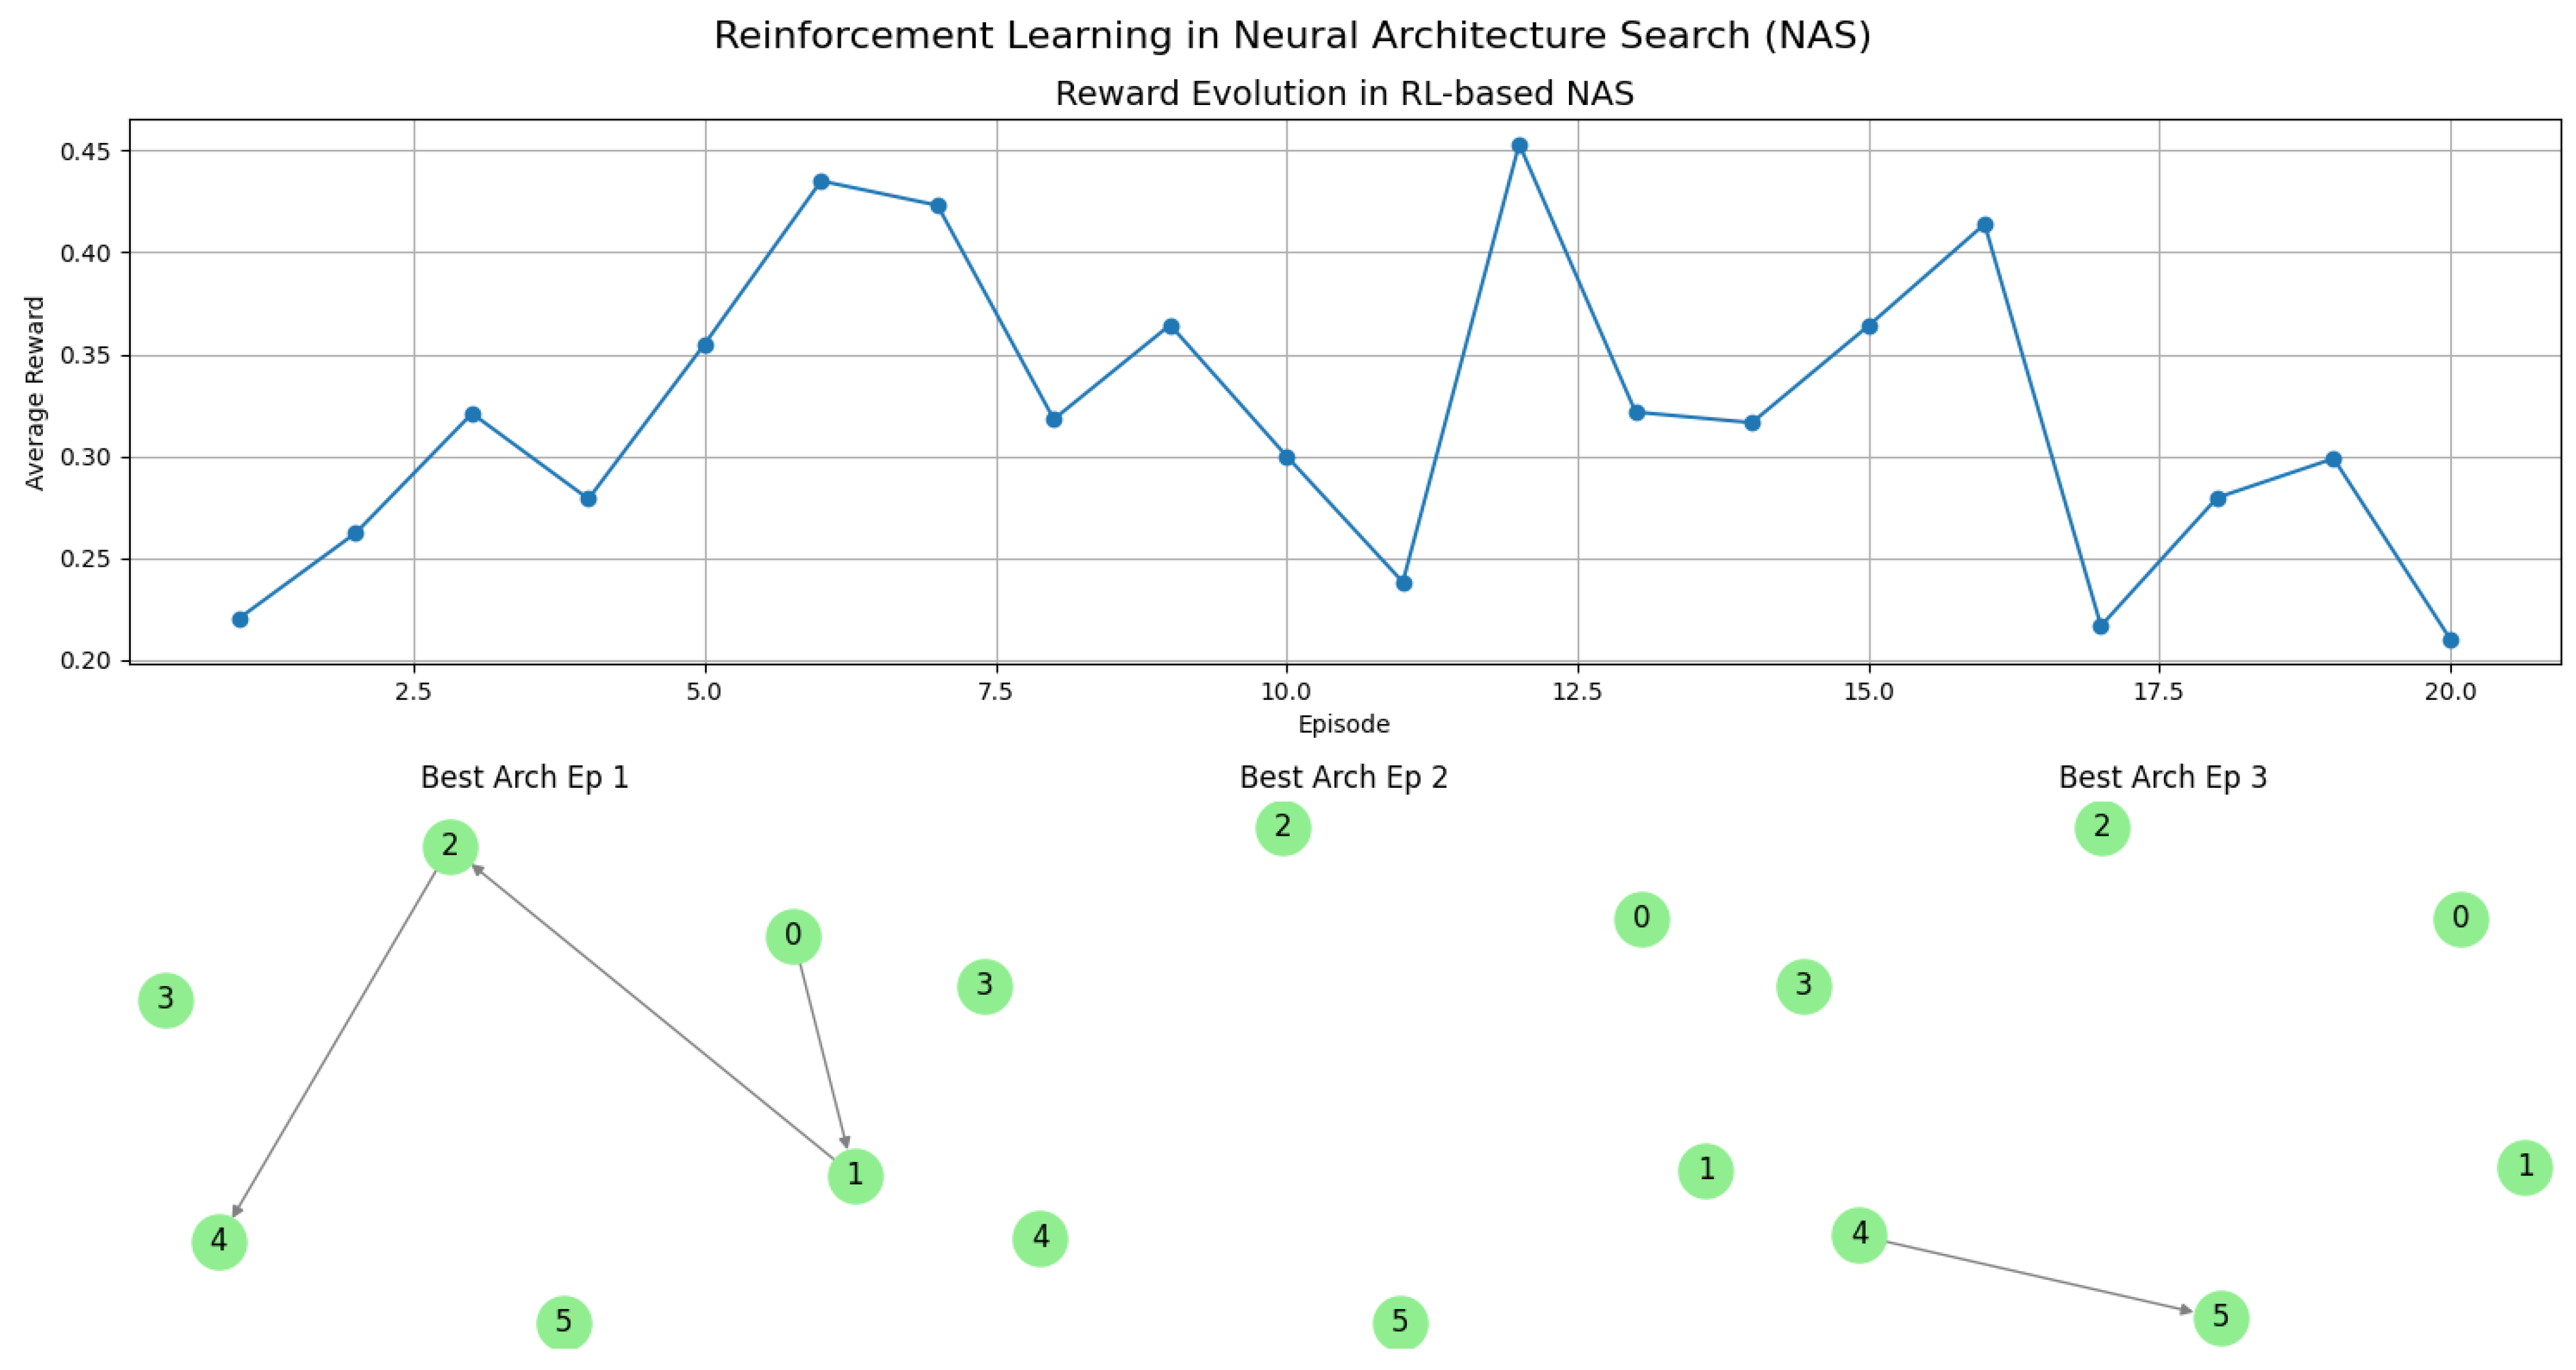
The process is modeled as a Markov Decision Process (MDP), defined by the tuple , where represents the state space corresponding to partially constructed architectures, is the action space defining possible modifications to architectures, P is the transition probability governing the evolution of architectures, R denotes the reward function that quantifies model performance, and is the discount factor controlling long-term reward contributions. The objective is to optimize the policy , parameterized by , such that the expected cumulative reward is maximized:
To optimize , policy gradient methods are employed, where the gradient of the expected reward with respect to policy parameters is given by:
Using Monte Carlo estimates, the policy parameters are updated via gradient ascent:
A common approach to implementing NAS with RL is the use of a Recurrent Neural Network (RNN)-based controller that generates candidate architectures sequentially. The hidden state of the RNN encodes information about the architecture decisions made up to step t, and the action at each step is sampled from a softmax distribution:
The reward signal is obtained by training and evaluating the generated architecture on a validation set, yielding an accuracy score A, which serves as the reward:
where b is a baseline used in variance reduction techniques such as REINFORCE. The training of the controller follows the REINFORCE algorithm with baseline subtraction:
To further stabilize learning, advantage estimation methods such as Generalized Advantage Estimation (GAE) can be employed, where the advantage function is computed using the value function :
An alternative approach is to model the NAS problem as a Q-learning task, where the Q-value represents the expected future reward given a state-action pair:
The Q-values are updated using the Bellman equation:
In practical implementations, Deep Q-Networks (DQN) are utilized, where a neural network approximates the Q-function , and updates are made using the loss function:
where represents target network parameters and D is an experience replay buffer. To address the instability of Q-learning, Double Q-learning is often employed, where two networks, and , are used to decouple action selection and evaluation:
where selects the minimum Q-value from two estimators to mitigate overestimation bias. In actor-critic methods such as Proximal Policy Optimization (PPO), the actor updates the policy while the critic evaluates its performance using the objective:
This clipped objective prevents large policy updates, ensuring stability in the RL-based NAS framework. By iteratively refining the architecture using these RL techniques, NAS can effectively discover high-performing network topologies that outperform manually designed architectures.
15.3. Policy Gradient Methods in Network Architecture Search
Policy gradient methods provide a mathematically rigorous framework for optimizing network architectures in deep neural networks by formulating the architecture search as a reinforcement learning (RL) problem. The core idea is to define a probability distribution over possible network architectures, represented as a parametric policy , where s represents the state (e.g., the current design choices or hyperparameters of the network), and a represents an action (e.g., selecting a particular layer type, activation function, or connection pattern).
Figure 147.
Policy Gradient Methods in Neural Architecture Search (NAS)
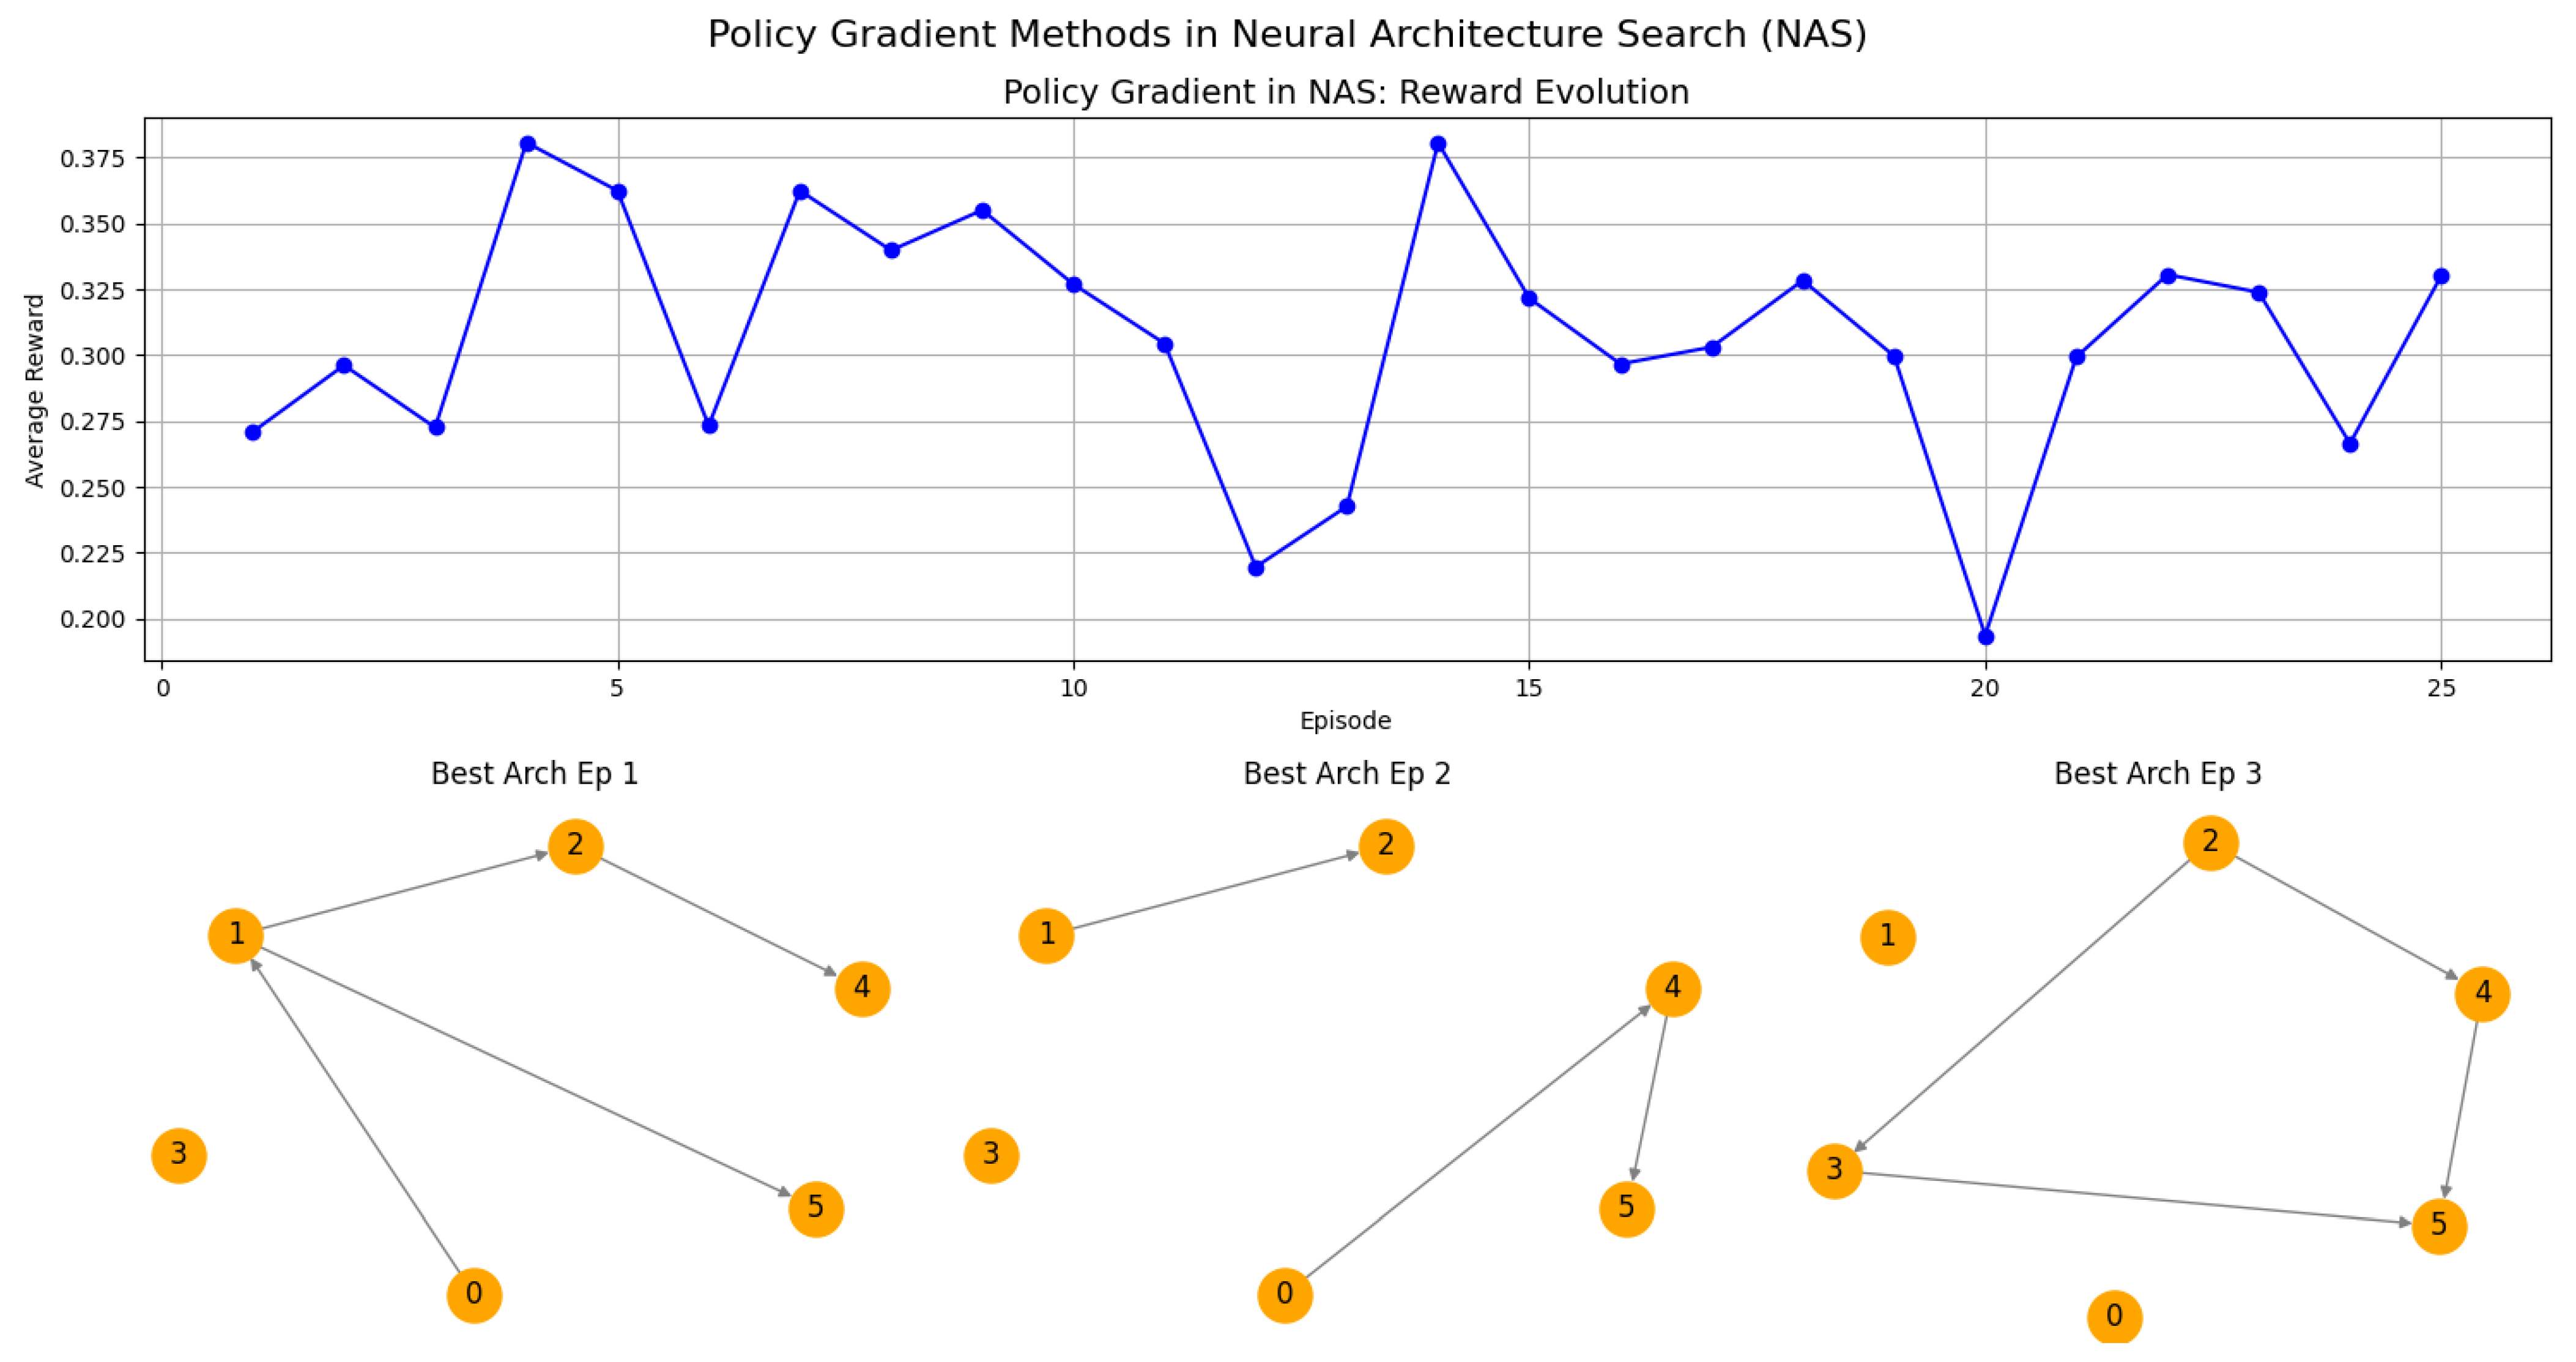
The objective is to maximize the expected performance of the architecture, which is commonly formulated as the expected reward obtained from training and evaluating the selected network:
where is a trajectory of states and actions sampled according to the policy , and represents the cumulative reward (e.g., validation accuracy of the trained architecture). The distribution over trajectories is given by
where is the environment transition function, often deterministic in the context of architecture search. To optimize , the policy gradient theorem provides an unbiased estimator of the gradient using the likelihood ratio trick:
Expanding the gradient term, we obtain
Thus, the gradient estimate simplifies to
In practice, this expectation is estimated via Monte Carlo sampling over a set of architectures, leading to the update rule:
To improve convergence, a baseline is often introduced to reduce variance:
A common choice for is a learned value function , leading to an advantage function , which forms the basis for actor-critic methods. The reward function is typically designed to reflect the generalization ability of the architecture, often incorporating the validation accuracy of the trained model:
where denotes the architecture defined by the trajectory , represents the network function, and are the trained weights obtained by minimizing the training loss
To improve exploration, entropy regularization is often added to the objective:
where
encourages diverse architecture sampling. In a real implementation, the policy is usually parameterized by a recurrent neural network (RNN) such as an LSTM, where the hidden state encodes past architecture decisions. The architecture parameters are updated using stochastic gradient descent with policy gradient updates, while the sampled architectures are trained using standard backpropagation. The convergence of policy gradient methods in architecture search relies on ensuring sufficient exploration and avoiding premature convergence to suboptimal architectures. Techniques such as proximal policy optimization (PPO), trust region policy optimization (TRPO), and natural gradient methods are often used to stabilize updates and improve sample efficiency. These methods modify the standard gradient update by introducing constraints such as
where is the Kullback-Leibler divergence, ensuring that the updated policy does not deviate too drastically from the previous policy, thereby maintaining stability in the optimization process.
15.4. Neural Tangent Kernels (NTKs) in Network Architecture Search
Neural Tangent Kernels (NTKs) have emerged as a powerful theoretical framework for understanding the training dynamics and generalization properties of deep neural networks in the infinite-width limit. In the context of Network Architecture Search (NAS), NTKs provide a mathematically rigorous way to evaluate the expressivity and trainability of different neural network architectures without explicitly training them, thereby significantly reducing computational costs associated with traditional NAS methods.
Figure 148.
NTKs, Eigenvalue Spectra, and Condition Numbers for NAS Architectures
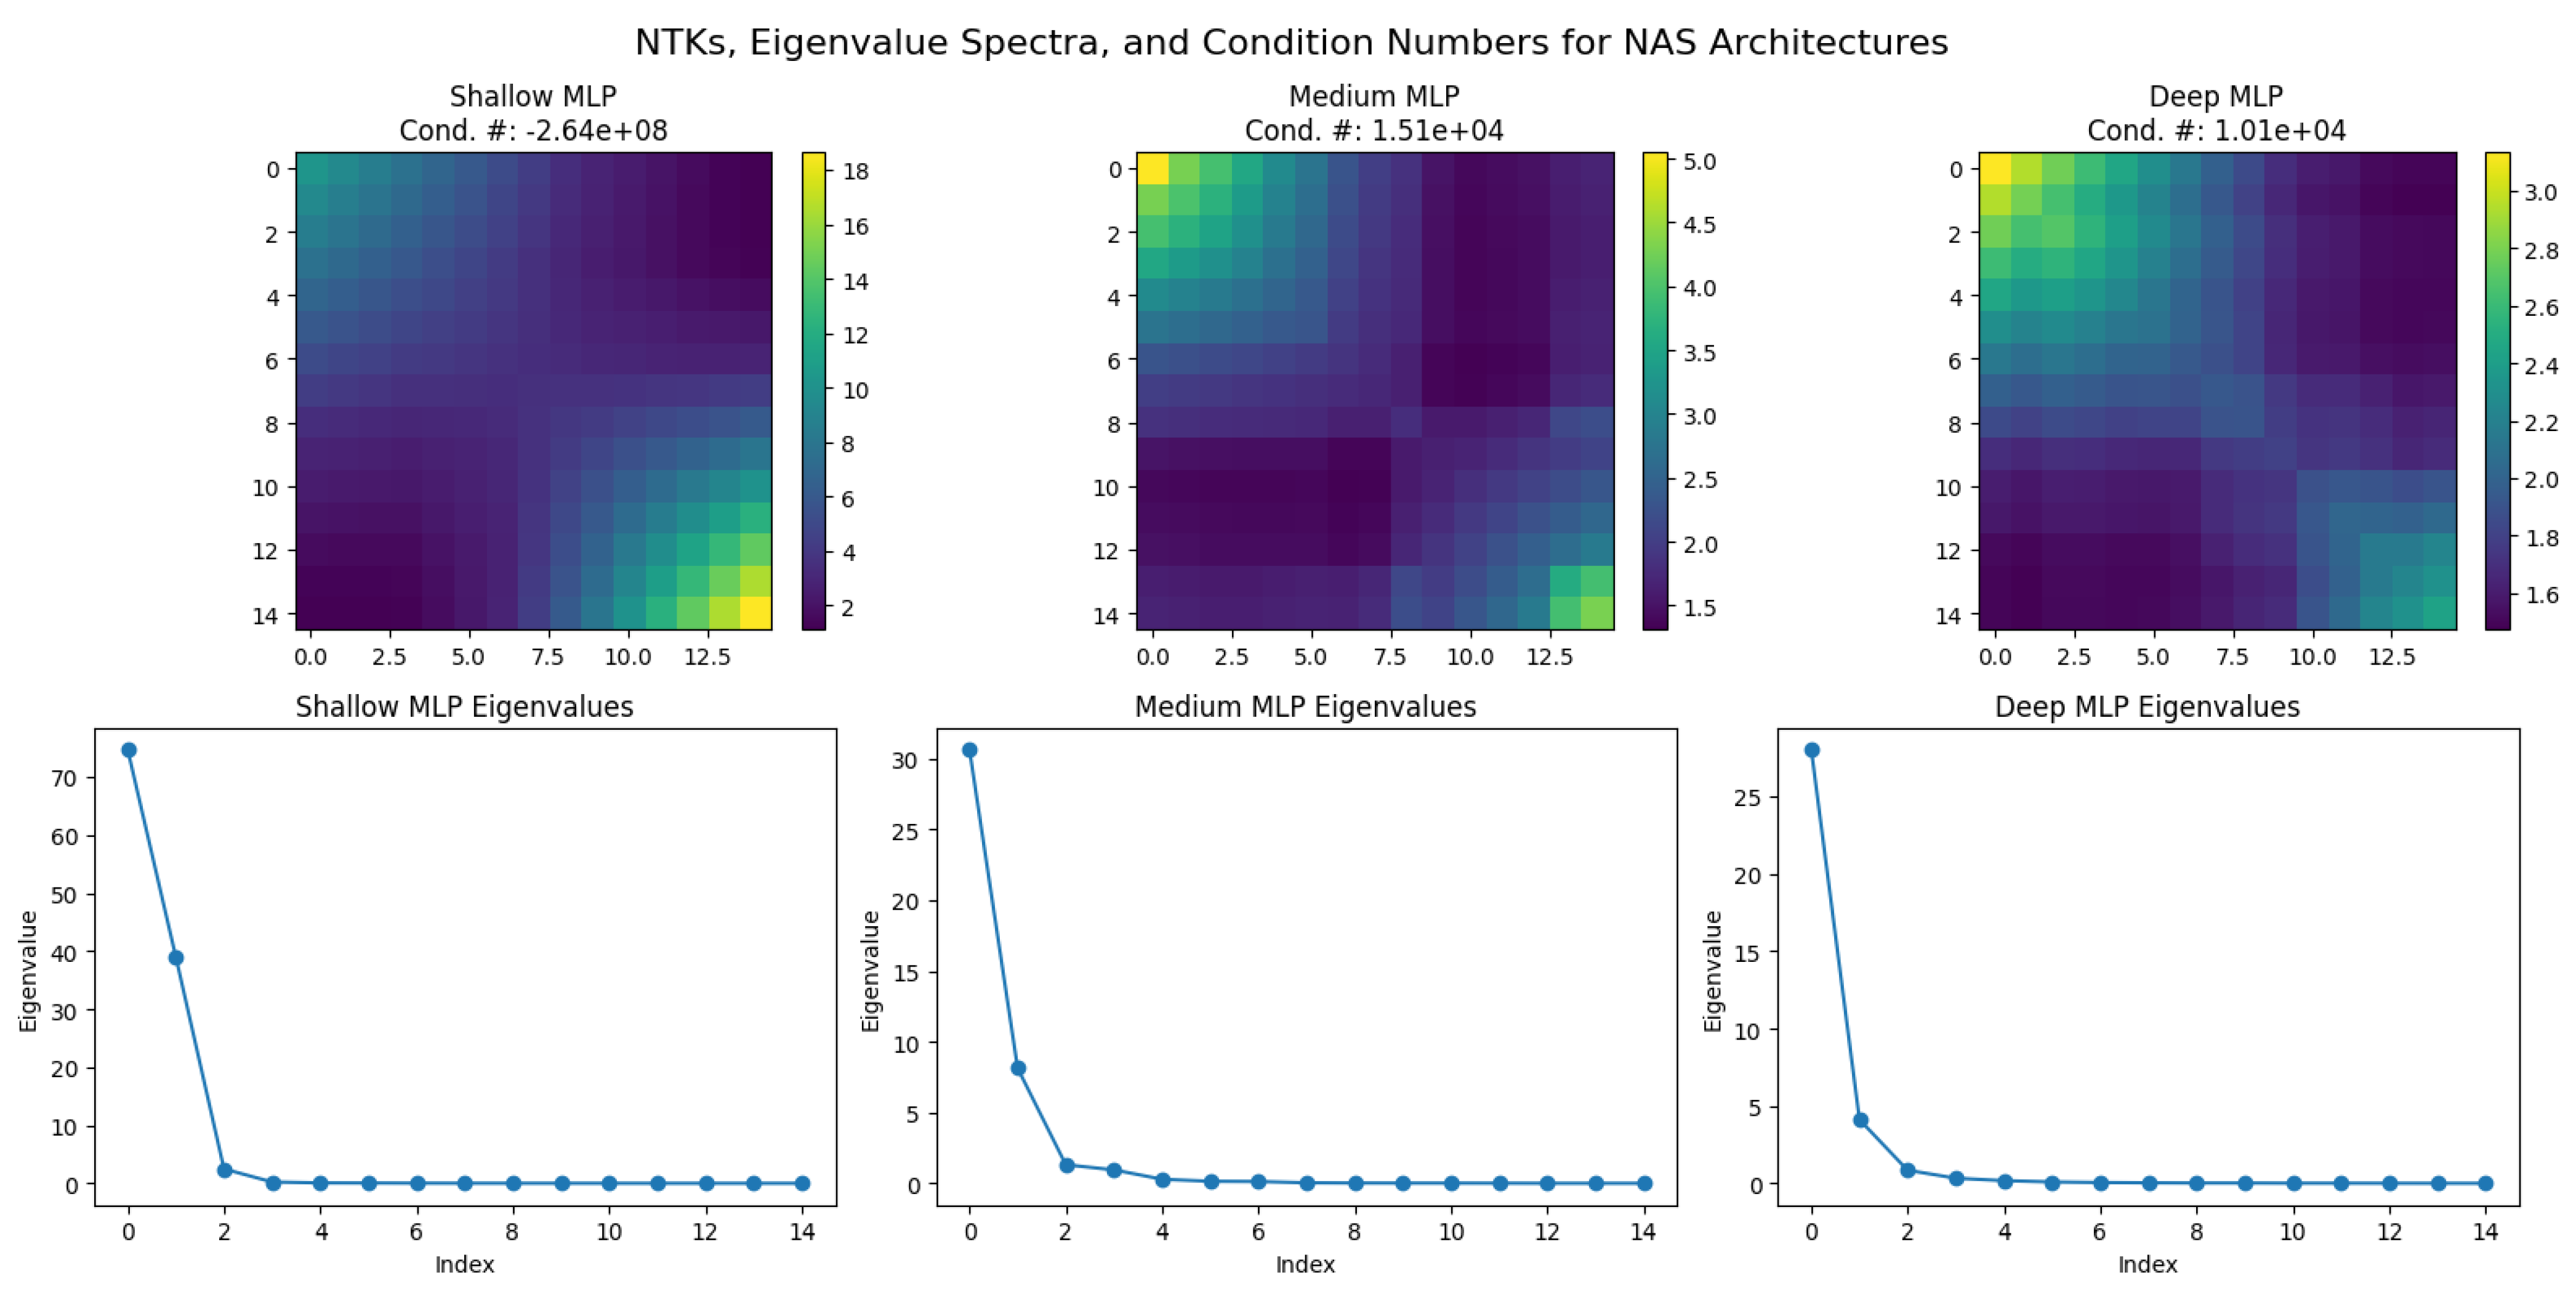
The NTK is formally defined as the Gram matrix of the Jacobian of the neural network outputs with respect to its parameters, capturing how perturbations in parameters influence the output function. Mathematically, if denotes the output of a neural network with parameters for an input x, then the NTK is given by
As the width of the network approaches infinity, the NTK remains constant during training under gradient descent, allowing the network to be effectively modeled as a Gaussian process. This property enables rapid evaluation of the convergence behavior and generalization ability of a given architecture by analyzing the eigenvalues of the NTK matrix. The training dynamics of an infinitely wide neural network can be described using the evolution of the function under gradient descent with a learning rate , which follows
Since the NTK remains constant in the infinite-width regime, this equation can be solved explicitly using
where denotes the training set inputs, and are the corresponding targets. The rate of convergence is determined by the smallest eigenvalue of , implying that architectures with larger minimum eigenvalues of their NTKs converge faster and are thus more trainable. The NTK perspective enables a principled approach to NAS by evaluating candidate architectures based on their kernel spectra, particularly the condition number , which governs the stability of gradient descent. Generalization in deep learning is often characterized by the smoothness and complexity of learned functions. The NTK controls the function space induced by a given architecture, allowing estimation of generalization error through the kernel ridge regression formula
where is the noise variance. Architectures with better generalization properties exhibit smaller trace norms of the NTK inverse.
Figure 149.
CNN NTKs and Eigenvalue Spectra for NAS Architectures
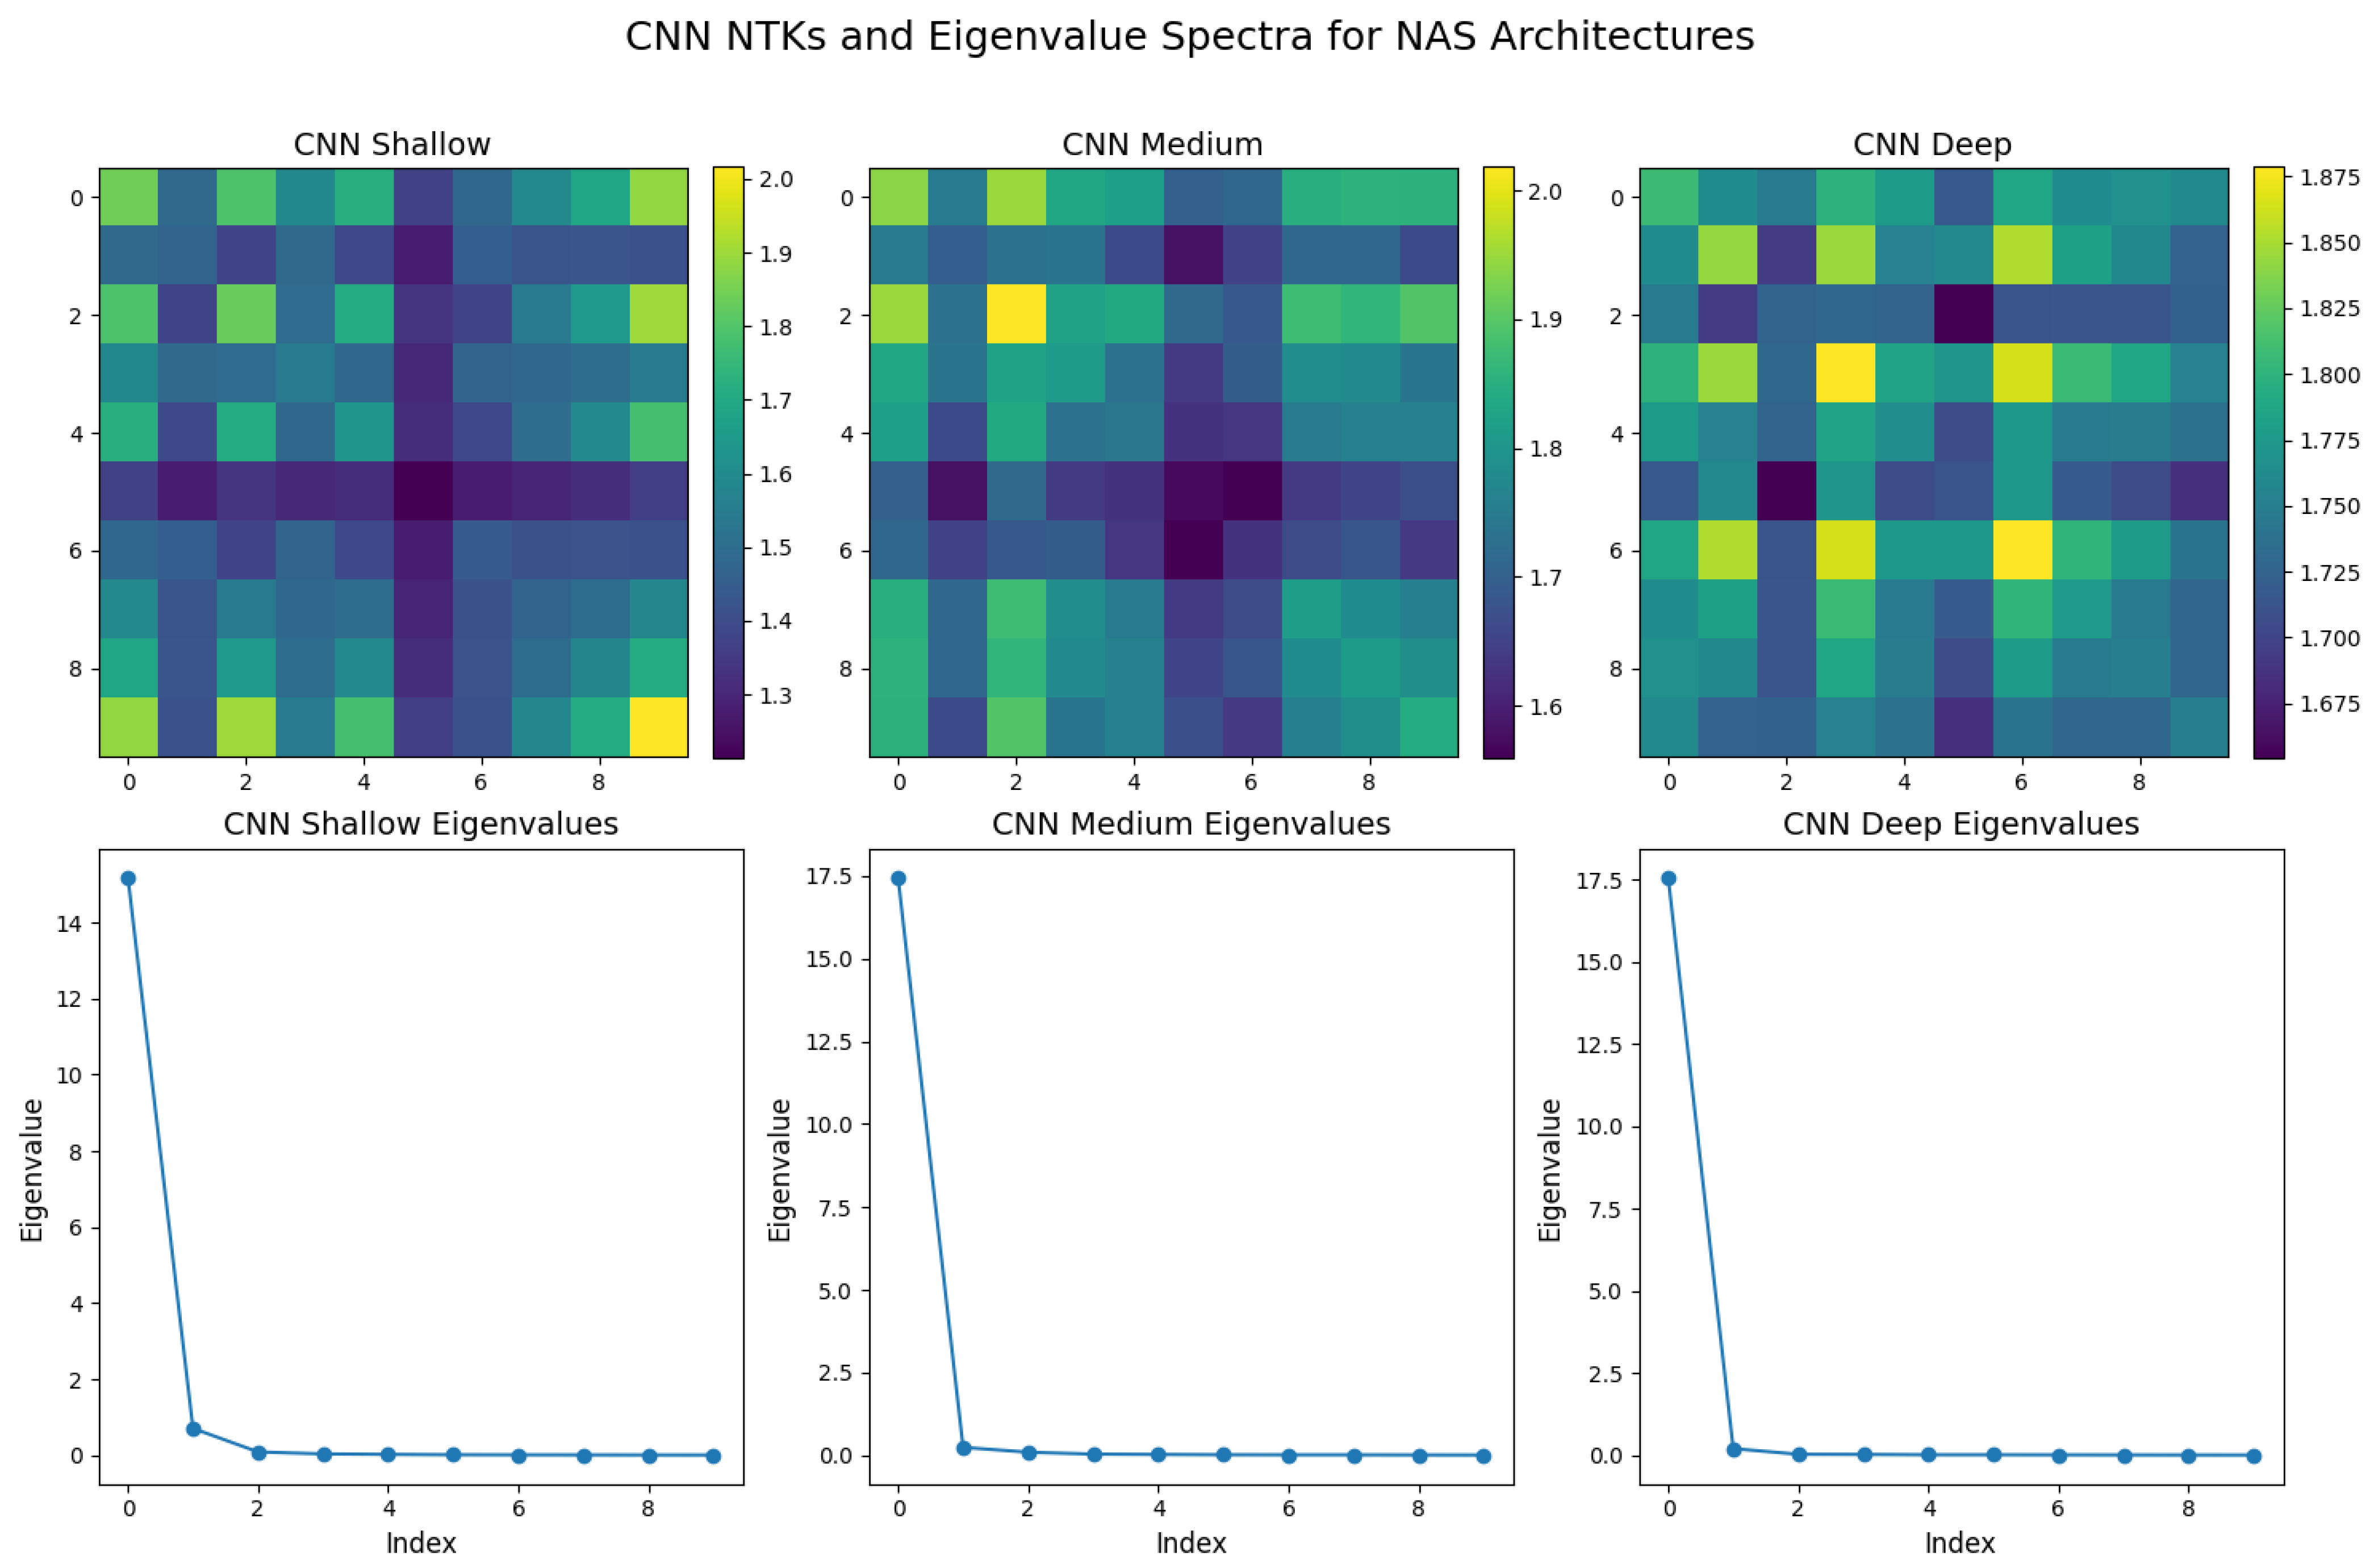
In the infinite-width limit, NTKs of different architectures can be computed analytically by considering the recursive propagation of covariance matrices through network layers. For a fully connected network with ReLU activation, the NTK at depth L is given by
where is the derivative of the activation function’s covariance kernel. Different architectures, such as convolutional neural networks (CNNs), modify this recurrence relation by incorporating weight-sharing and local connectivity constraints. The NTK for a CNN layer with filter size k is
This allows NAS to be performed analytically by evaluating how architectural choices influence the NTK and its spectral properties, bypassing the need for expensive training runs. Recent work has extended NTK-based NAS to attention-based architectures, such as transformers, where the self-attention mechanism induces a structured NTK
where are the query, key, and value matrices. The spectrum of determines the expressivity and trainability of transformer-based models, enabling NTK-based architectural optimization in sequence learning tasks. The NTK framework provides an elegant, mathematically rigorous approach to NAS by linking architectural choices to trainability and generalization through spectral analysis of the kernel.
16. Learning Paradigms
16.1. Unsupervised Learning
16.1.1. Literature Review of Unsupervised Learning
Unsupervised learning has evolved significantly through foundational contributions in clustering, probabilistic modeling, neural representations, and generative techniques. One of the earliest and most fundamental methods in clustering was introduced by MacQueen in 1967 [1035] with the k-means algorithm. This algorithm partitions a set of n observations into k clusters in such a way that the intra-cluster variance is minimized. The iterative nature of k-means, involving cluster centroid updates and reassignment of points based on their Euclidean distances, remains a cornerstone of clustering techniques. Complementing k-means, the Expectation-Maximization (EM) algorithm, rigorously formalized by Dempster, Laird, and Rubin in 1977 [1036] provided a general framework for maximizing likelihood estimates in models with latent variables. EM underpins Gaussian Mixture Models (GMMs), allowing for probabilistic clustering by modeling data as a weighted sum of Gaussian distributions. These models account for uncertainty and have led to advancements in density estimation and soft clustering.
Another major breakthrough in unsupervised learning emerged with the self-organizing maps (SOMs) developed by Kohonen in 1982 [1037]. These neural-inspired models provide a competitive learning framework where neurons adjust their weights to form low-dimensional representations of input data while preserving topological relationships. This biologically motivated approach to clustering has been instrumental in feature extraction and visualization, especially in applications involving high-dimensional data. Parallel to SOMs, spectral techniques for manifold learning and dimensionality reduction were rigorously developed, with Belkin and Niyogi [1038] introducing Laplacian Eigenmaps in 2003. This method constructs a graph Laplacian to capture local geometric properties of data manifolds and embed them into a lower-dimensional space while maintaining neighborhood relationships. This has provided a mathematically principled foundation for spectral clustering and nonlinear dimensionality reduction.
The rigorous treatment of information-theoretic principles in unsupervised learning was significantly advanced by the Information Bottleneck (IB) method proposed by Tishby, Pereira, and Bialek in 2000 [1039]. The IB principle establishes a trade-off between compression and predictive efficiency by optimizing a mutual information objective. This formulation has deeply influenced representation learning, particularly in autoencoders and deep latent variable models. A major advancement in unsupervised neural representations was introduced by Hinton and Salakhutdinov in 2006 [1040], demonstrating that deep belief networks (DBNs) could learn hierarchical representations via layer-wise training of restricted Boltzmann machines (RBMs). This work laid the foundation for the resurgence of deep learning by showing that unsupervised pretraining significantly improves the performance of neural networks. The probabilistic formulation of deep unsupervised learning was further developed by Kingma and Welling in 2013 [1041] with the introduction of variational autoencoders (VAEs). By leveraging variational inference, VAEs provide a rigorous framework for learning latent variable models, enabling efficient probabilistic generative modeling of complex data distributions.
A more adversarial approach to generative modeling was pioneered by Goodfellow et al. in 2020 [121] with the introduction of generative adversarial networks (GANs). GANs consist of a generator and discriminator competing in a minimax game, where the generator learns to produce realistic samples while the discriminator improves its ability to distinguish between real and generated data. This adversarial framework has profoundly impacted image generation, domain adaptation, and semi-supervised learning by producing high-quality synthetic data. The visualization of high-dimensional data was further enhanced by van der Maaten and Hinton in 2008 [1042] with the development of t-distributed stochastic neighbor embedding (t-SNE). This method provides a probabilistic approach to mapping data points into a lower-dimensional space by minimizing the Kullback-Leibler divergence between high- and low-dimensional distributions, preserving local similarities. t-SNE has become a widely used technique in exploratory data analysis due to its ability to reveal meaningful structure in complex datasets.
Together, these contributions have shaped the field of unsupervised learning by introducing rigorous mathematical formulations for clustering, probabilistic modeling, and representation learning. The foundational algorithms such as k-means and EM provide essential tools for unsupervised data analysis, while information-theoretic and spectral methods offer deeper insights into structure preservation and feature extraction. The integration of neural networks into unsupervised learning, through self-organizing maps, deep belief networks, and variational autoencoders, has led to a significant expansion in the capabilities of machine learning models. The development of adversarial training with GANs and the application of information bottleneck principles further illustrate the growing sophistication of unsupervised learning techniques. These advancements continue to push the boundaries of artificial intelligence, enabling models to learn rich, structured representations of data without the need for explicit supervision.
Roweis and Saul (2000) [1043] introduced Locally Linear Embedding (LLE), a nonlinear dimensionality reduction algorithm designed to uncover low-dimensional structures within high-dimensional data. The core idea behind LLE is to preserve the local geometric relationships between neighboring data points while embedding them into a lower-dimensional space. Unlike linear techniques such as Principal Component Analysis (PCA), which assume that the global structure of the data can be well represented using a linear subspace, LLE focuses on preserving the local structure by considering each data point and its nearest neighbors. The algorithm operates in three main steps. First, for each data point, LLE identifies a set of nearest neighbors based on a distance metric, usually Euclidean distance. Second, it computes local reconstruction weights by expressing each data point as a linear combination of its neighbors, minimizing the reconstruction error while enforcing the constraint that the weights sum to one. This step ensures that the local geometric structure is encoded in an invariant manner. Third, LLE determines a lower-dimensional embedding by finding a new set of coordinates that best preserves the reconstruction weights obtained in the previous step. This is achieved by minimizing a quadratic cost function that ensures the lower-dimensional representation maintains the same local linear relationships as the original high-dimensional data. The main advantage of LLE over traditional linear techniques is its ability to recover nonlinear manifolds, making it particularly effective for data sets where the underlying structure is curved or highly nonlinear. Unlike methods such as Multidimensional Scaling (MDS), which rely on pairwise distances between all points and can be computationally expensive, LLE leverages only local neighborhoods, making it more scalable to larger data sets. Additionally, since LLE does not impose any parametric assumptions on the manifold, it is capable of adapting to a wide variety of data distributions.
However, LLE also has some limitations. Its reliance on nearest-neighbor selection makes it sensitive to noise and parameter choices, particularly the number of neighbors. Furthermore, the embeddings produced by LLE are often unnormalized, meaning that distances in the lower-dimensional space may not have a straightforward interpretation. Despite these challenges, LLE has had a significant impact on machine learning and data visualization, providing a powerful tool for uncovering the intrinsic structure of high-dimensional data in applications ranging from image processing to bioinformatics. Its introduction marked a shift toward more flexible, geometry-preserving dimensionality reduction techniques, influencing the development of subsequent manifold learning methods such as Isomap and t-SNE.
Table 10.
Summary of Contributions to the Unsupervised Learning
| Authors (Year) | Contribution |
|---|---|
| MacQueen (1967) [1035] | Introduced the k-means algorithm, a foundational clustering method that minimizes intra-cluster variance through iterative centroid updates and point reassignment based on Euclidean distance. |
| Dempster, Laird, and Rubin (1977) [1036] | Developed the Expectation-Maximization (EM) algorithm, a general framework for maximizing likelihood estimates in models with latent variables, forming the basis for Gaussian Mixture Models (GMMs). |
| Kohonen (1982) [1037] | Proposed self-organizing maps (SOMs), a neural-inspired model for competitive learning, which preserves topological relationships and has been instrumental in feature extraction. |
| Belkin and Niyogi (2003) [1038] | Introduced Laplacian Eigenmaps, which use a graph Laplacian to capture local geometric properties of data manifolds, providing a foundation for spectral clustering and nonlinear dimensionality reduction. |
| Tishby, Pereira, and Bialek (2000) [1039] | Proposed the Information Bottleneck (IB) method, optimizing mutual information to balance compression and predictive efficiency, influencing representation learning in autoencoders. |
| Hinton and Salakhutdinov (2006) [1040] | Demonstrated deep belief networks (DBNs), where layer-wise training of restricted Boltzmann machines (RBMs) enables hierarchical unsupervised representation learning. |
| Kingma and Welling (2013) [1041] | Developed variational autoencoders (VAEs), leveraging variational inference for probabilistic generative modeling of complex data distributions. |
| Goodfellow et al. (2020) [121] | Introduced generative adversarial networks (GANs), an adversarial framework where a generator and discriminator compete, leading to advances in synthetic data generation. |
| van der Maaten and Hinton (2008) [1042] | Developed t-distributed stochastic neighbor embedding (t-SNE), a probabilistic approach for high-dimensional data visualization that preserves local similarities. |
| Roweis and Saul (2000) [1043] | Introduced Locally Linear Embedding (LLE), a nonlinear dimensionality reduction technique that preserves local geometric relationships and is effective for manifold learning. |
| Bell and Sejnowski (1995) [1044] | Developed Independent Component Analysis (ICA), an information-theoretic method for blind source separation, leveraging higher-order statistics to extract statistically independent signals. |
Bell and Sejnowski (1995) [1044] introduced Independent Component Analysis (ICA) as an information-theoretic approach to blind source separation (BSS), which allows for the decomposition of mixed signals into statistically independent components without prior knowledge of the mixing process. Their work was motivated by real-world scenarios where multiple signals, such as different voices in a crowded room or overlapping audio sources in a recording, become mixed together, making it difficult to recover the original sources. Unlike traditional statistical methods such as Principal Component Analysis (PCA), which rely on second-order statistics and assume orthogonality of components, ICA leverages higher-order statistical properties to separate signals that are non-Gaussian and statistically independent. The fundamental principle behind their method is the maximization of information transfer in a neural network, also known as the infomax principle. This principle is based on the idea that a system should be optimized to maximize the mutual information between its input and output, ensuring that the output representation is as statistically independent as possible. To achieve this, they formulated a neural learning rule that iteratively adjusts the network’s weight parameters using a nonlinear function, which enhances the separation of independent sources. The key insight was that statistical independence implies that the joint probability distribution of the recovered signals should factorize into the product of their individual distributions, which is not the case for mixtures of dependent signals. To enforce this independence, their method used a contrast function derived from information theory, ensuring that the recovered sources were as non-Gaussian as possible, since mixtures of independent sources tend to become more Gaussian due to the Central Limit Theorem. This approach enabled the successful separation of mixed signals in a variety of applications, including audio processing, biomedical signal analysis, and image processing. One of the most famous demonstrations of ICA, often referred to as the “cocktail party problem,” involves separating multiple overlapping speech signals recorded by different microphones. Their algorithm was able to recover individual voices from the mixed recording with remarkable accuracy, highlighting the effectiveness of ICA in practical scenarios. Additionally, ICA found significant applications in neuroscience, particularly in electroencephalography (EEG) and functional magnetic resonance imaging (fMRI), where it helped isolate meaningful brain activity patterns from background noise.
Despite its power, ICA has limitations, including its sensitivity to the choice of nonlinear functions and the assumption that the number of independent sources does not exceed the number of observed mixtures. Furthermore, ICA assumes that the sources are statistically independent, which may not always hold in real-world data. Nonetheless, Bell and Sejnowski’s work laid the foundation for subsequent advancements in unsupervised learning, influencing modern approaches in deep learning, signal processing, and latent variable modeling. Their method provided a robust mathematical framework for data decomposition that has since been expanded and refined in numerous fields, demonstrating the lasting impact of their contribution to unsupervised learning.
16.1.2. Recent Literature Review of Unsupervised Learning
Unsupervised learning has emerged as a powerful tool in various domains, offering novel solutions where labeled data is scarce or unavailable. In semiconductor manufacturing, Parmar (2020) [1045] introduced an unsupervised learning framework aimed at identifying previously unknown defects. By leveraging clustering techniques and anomaly detection, this approach enhances quality control without relying on predefined defect categories. The ability to discover novel defect patterns autonomously makes this method particularly valuable in industries where manufacturing processes constantly evolve, and new defect types emerge. In a related field, Raikwar and Gupta (2025) [1046] developed an AI-driven trust management framework for wireless ad hoc networks. This system integrates unsupervised and supervised learning to classify network nodes based on trustworthiness, helping identify potentially malicious nodes. Such frameworks are critical in decentralized environments where security threats are unpredictable and dynamically evolving. The application of unsupervised learning in this context reduces reliance on predefined attack signatures, improving network security in real-time.
Structural health monitoring has also benefited from unsupervised learning techniques. Moustakidis et al. (2025) [1047] proposed a deep learning autoencoder framework for fast Fourier transform (FFT)-based clustering, designed to analyze acoustic emission data from composite materials. This method enables automatic detection of structural damage over time, allowing for proactive maintenance and risk mitigation in infrastructure management. By employing autoencoders to extract meaningful features from raw sensor data, the approach outperforms traditional inspection methods that require extensive manual interpretation. Feature selection is another area where unsupervised learning has made a significant impact. Liu et al. (2025) [1048] introduced an unsupervised feature selection algorithm using L2, p-norm feature reconstruction. This method effectively reduces redundant features while preserving essential data structures, thereby improving the efficiency and accuracy of clustering algorithms. High-dimensional datasets, such as those used in bioinformatics and financial modeling, greatly benefit from this technique, as it enables better data representation and pattern discovery without the need for labeled guidance.
In the medical and healthcare sector, unsupervised learning has been leveraged for disease risk assessment and biomarker discovery. Zhou et al. (2025) [1049] applied clustering techniques to analyze metabolic profiles, uncovering hidden subtypes of hypertriglyceridemia associated with varying disease risks. This research demonstrates the potential of unsupervised learning in personalized medicine, where identifying metabolic subgroups can help tailor treatments to individual patients rather than applying a one-size-fits-all approach. Similarly, Lin et al. (2025) [1050] employed unsupervised learning for risk control in health insurance fund management. By analyzing claims data and identifying anomalous patterns, this approach enhances fraud detection and risk assessment, ultimately leading to better resource allocation and cost reduction. The ability to detect fraud without labeled examples is a significant advantage in an industry where fraudulent activities are often sophisticated and constantly evolving.
Beyond healthcare, unsupervised learning has shown promise in improving real-world object detection systems. Huang et al. (2025) [1051] proposed a novel unsupervised domain adaptation technique to enhance open-world object detection. Unlike traditional supervised models that require large amounts of labeled data, this approach enables object detection models to generalize across different environments with minimal supervision. Such advancements are crucial in autonomous navigation, surveillance, and robotics, where training data may not always be representative of real-world conditions. In a different engineering application, Wu and Liu (2025) [1052] introduced a VQ-VAE-2-based algorithm for detecting cracks in concrete structures. This unsupervised approach automates structural health monitoring, reducing dependence on costly manual inspections while improving the accuracy and efficiency of damage assessments.
Natural language processing and medical imaging have also seen substantial contributions from unsupervised learning. Nagelli and Saleena (2025) [1053] developed an aspect-based sentiment analysis model using self-attention mechanisms. This model enables the automatic extraction of sentiment-related features from multilingual datasets, allowing businesses to analyze customer feedback without requiring labeled sentiment data. Such models are essential for real-time sentiment analysis in global markets where user-generated content is vast and diverse. Meanwhile, Ekanayake (2025) [1054] applied deep learning techniques for MRI reconstruction and super-resolution enhancement. This research significantly reduces MRI scan times while preserving high image quality, offering a transformative solution to the challenges of medical imaging. The use of unsupervised learning in this context enables more efficient data-driven reconstruction techniques, reducing dependency on expensive and time-consuming manually labeled training datasets. These diverse applications illustrate the expanding role of unsupervised learning in solving complex real-world problems, demonstrating its adaptability and potential to drive further innovation across multiple industries.
Table 11.
Summary of Recent Contributions in Unsupervised Learning
| Authors (Year) | Contribution |
|---|---|
| Parmar (2025) [1045] | Introduced an unsupervised learning framework for identifying unknown defects in semiconductor manufacturing, leveraging clustering and anomaly detection to improve quality control in industrial settings. |
| Raikwar and Gupta (2025) [1046] | Developed an AI-driven trust management framework for wireless ad hoc networks, combining unsupervised and supervised learning to classify network nodes based on trustworthiness and detect malicious activity. |
| Moustakidis et al. (2025) [1047] | Proposed deep learning autoencoders for FFT-based clustering in structural health monitoring, enabling automated detection of temporal damage evolution in composite materials. |
| Liu et al. (2025) [1048] | Designed an unsupervised feature selection algorithm using L2, p-norm feature reconstruction, reducing redundant features and improving clustering performance for high-dimensional datasets. |
| Zhou et al. (2025) [1049] | Applied unsupervised clustering techniques to metabolic profiles, identifying hidden metabolic subtypes associated with hypertriglyceridemia and disease risks, advancing personalized medicine. |
| Lin et al. (2025) [1050] | Developed an unsupervised learning-based risk control model for health insurance fund management, effectively identifying high-risk groups and fraudulent claims through anomaly detection. |
| Huang et al. (2025) [1051] | Proposed an unsupervised domain adaptation method for open-world object detection, enabling models to generalize across different environments without extensive labeled datasets. |
| Wu and Liu (2025) [1052] | Designed a VQ-VAE-2-based unsupervised detection algorithm for concrete crack identification, automating structural health monitoring and reducing manual inspection efforts. |
| Nagelli and Saleena (2025) [1053] | Developed an aspect-based sentiment analysis model using self-attention mechanisms, enabling multilingual sentiment analysis without labeled training data. |
| Ekanayake (2025) [1054] | Applied deep learning-based unsupervised learning for MRI reconstruction and super-resolution, reducing scan times while maintaining high image quality in medical imaging. |
16.1.3. Mathematical Analysis of Unsupervised Learning
Unsupervised learning is a fundamental paradigm in machine learning, in which a model is trained on a dataset without explicit supervision in the form of labeled outputs. Mathematically, given a dataset consisting of N data points, where each is a vector in , the goal is to find an underlying structure, distribution, or latent representation of the data, often formulated as a function where k may be lower than d, capturing essential properties of the data manifold. The data is assumed to be drawn from an unknown probability distribution , and the central objective in unsupervised learning is to model or approximate this distribution using a function , where represents the parameters of the model. This can be done using probabilistic modeling, clustering, dimensionality reduction, and manifold learning.
One of the most rigorous formulations in unsupervised learning arises in the estimation of probability density functions, where the likelihood function of the observed data is given by
The optimal parameters are obtained by maximizing the log-likelihood function:
In clustering problems, an objective function is often defined to minimize intra-cluster variance while maximizing inter-cluster separation. Given a set of K cluster centers , the assignment of each point to a cluster is determined by
The objective function to minimize is given by
Expectation-Maximization (EM) algorithms generalize clustering in a probabilistic framework, where data is assumed to be generated by a mixture of distributions:
where are the mixture weights such that , and are component distributions, often taken as Gaussian:
Dimensionality reduction techniques such as Principal Component Analysis (PCA) seek to find a lower-dimensional representation that maximizes variance. Given a centered data matrix , PCA finds the eigenvectors of the covariance matrix
The principal components are obtained by solving the eigenvalue problem
Only the top k eigenvectors corresponding to the largest eigenvalues are retained, reducing the data to a lower-dimensional subspace. The transformation to the new basis is given by
where V is the matrix of top eigenvectors. More advanced methods such as autoencoders learn a mapping from input data to a latent representation using an encoder function
and reconstruct the input via a decoder function
The reconstruction loss is typically measured as
For probabilistic models, Variational Autoencoders (VAEs) extend autoencoders by introducing a latent variable model with a prior distribution , an approximate posterior , and a reconstruction likelihood . The objective function in VAEs is to maximize the evidence lower bound (ELBO):
where is the Kullback-Leibler divergence. Generative models such as Generative Adversarial Networks (GANs) learn a mapping from a simple latent space to the data distribution via a generator function , while an adversarial discriminator D learns to distinguish between real and generated samples. The objective function of a GAN is given by
16.1.4. Information Bottleneck (IB) Method
16.1.4.1 Literature Review of Information Bottleneck (IB) Method
The Information Bottleneck (IB) method, introduced by Tishby, Pereira, and Bialek (1999) [1068], provides a principled approach to extracting relevant information from a random variable X concerning another variable Y. The method formulates an optimization problem that seeks to find a compressed representation T of X that retains the maximal information about Y, while minimizing the redundancy in X. This is achieved by balancing the mutual information terms and , where a Lagrange multiplier controls the trade-off between compression and relevance. The authors derived an iterative algorithm based on variational principles to solve this optimization problem and demonstrated its utility in clustering and data representation tasks. This work laid the foundation for a vast array of subsequent research efforts that have expanded the scope of the IB method to different domains and problem settings, providing deeper insights into the nature of information-theoretic compression and representation learning.
One of the key extensions of the IB method was its application to continuous-valued variables, particularly those following a Gaussian distribution. Chechik, Globerson, Tishby, and Weiss (2005) [1069] rigorously examined the IB method in the context of jointly Gaussian random variables, deriving analytical solutions that revealed the intrinsic connections between the IB formulation and classical techniques such as canonical correlation analysis. Their results demonstrated that the optimal representation in the Gaussian case can be expressed in terms of principal component analysis (PCA)-like transformations, thereby bridging the IB method with traditional dimensionality reduction approaches. This work has had significant implications for signal processing and statistical learning, as it provides a mathematically rigorous foundation for applying the IB principle to real-world datasets that exhibit Gaussian-like characteristics. In a related extension, Chechik and Tishby (2002) [1070] introduced a variant of the IB framework that incorporates side information, allowing for the extraction of representations that retain information about one target variable while being uninformative about another. This formulation has proven particularly useful in privacy-preserving machine learning and fairness-aware representations, where one seeks to ensure that a learned representation encodes task-relevant information while obfuscating sensitive attributes.
In the context of deep learning, Tishby and Zaslavsky (2015) [1071] proposed that the training process of deep neural networks (DNNs) can be interpreted through the lens of the IB principle. They hypothesized that DNNs undergo two distinct phases during training: an initial "fitting" phase where the mutual information between successive layers and the target variable Y increases, followed by a "compression" phase where the network progressively reduces the mutual information between intermediate layers and the input variable X. This perspective provides a theoretical justification for why deep networks generalize well despite their over-parameterization, as the compression phase effectively filters out irrelevant variations in the input while preserving task-relevant features. However, Saxe et. al. (2019) [1072] critically examined this hypothesis and argued that the presence of the compression phase is highly dependent on architectural choices, particularly the activation functions used in deep networks. Their empirical findings demonstrated that the IB theory does not universally apply to all neural network architectures, suggesting that while information-theoretic compression may play a role in some settings, it is not a fundamental principle governing the training dynamics of all deep networks.
Further empirical support for the IB perspective in deep learning was provided by Shwartz-Ziv and Tishby (2017) [1073], who conducted a detailed analysis of information flow in deep neural networks. Using information plane visualizations, they showed that the training process of DNNs aligns with the two-phase description proposed in earlier work. Their findings provided strong evidence for the compression phenomenon in networks trained with stochastic gradient descent (SGD), reinforcing the argument that deep networks learn compact representations of the input. However, a major challenge in applying the IB framework to high-dimensional data is the difficulty of accurately estimating mutual information, especially in deep networks where the latent representations are highly non-Gaussian. To address this issue, Noshad et. al. (2019) [1074] introduced a novel mutual information estimator based on dependence graphs, enabling more scalable and robust estimations of information flow in deep learning models. Their approach has opened new avenues for applying the IB principle to real-world machine learning problems where traditional mutual information estimators fail due to the curse of dimensionality.
The theoretical implications of information bottleneck in neural networks were further explored by Goldfeld et. al. (2018) [1075], who developed refined techniques for estimating mutual information in deep networks. Their work provided new tools for analyzing the role of compression in neural representations, offering rigorous mathematical justifications for why certain layers in deep networks tend to exhibit strong compression effects. More recently, Geiger (2021) [1077] presented a comprehensive review of information plane analyses in neural network classifiers, evaluating the strengths and limitations of the IB framework in this setting. His analysis raised critical questions about the general applicability of IB-based insights in deep learning, highlighting cases where the information plane approach fails to provide accurate characterizations of training dynamics. Building on these theoretical developments, Kawaguchi, Deng, Ji, and Huang (2023) [1078] rigorously analyzed the generalization properties of neural networks under the IB framework, providing a mathematical link between information compression and generalization error bounds. Their results establish that controlling the information bottleneck can serve as a regularization mechanism, leading to improved generalization performance in deep learning models. Collectively, these contributions underscore the profound impact of the IB principle across a wide range of disciplines, from statistical signal processing to modern artificial intelligence.
| Authors (Year) | Contribution |
| Tishby et al. (1999) [1068] | Introduced the Information Bottleneck (IB) method, formulating an optimization problem that balances mutual information terms to extract relevant information from a random variable while minimizing redundancy. Developed an iterative variational algorithm for solving the IB problem, demonstrating its application in clustering and representation learning. |
| Chechik et al. (2003) [1069] | Extended the IB method to jointly Gaussian variables, deriving analytical solutions that connect IB with canonical correlation analysis and PCA. Provided a rigorous foundation for applying IB to real-world Gaussian data. |
| Chechik and Tishby (2002) [1070] | Developed a variant of the IB framework incorporating side information, enabling extraction of representations that retain information about one target while obfuscating another. Applied to privacy-preserving and fairness-aware machine learning. |
| Tishby and Zaslavsky (2015) [1071] | Proposed that deep neural network training follows an IB perspective, consisting of an initial fitting phase followed by a compression phase, explaining generalization through information-theoretic principles. |
| Saxe et al. (2019) [1072] | Critically examined the IB hypothesis in deep learning, showing that the presence of a compression phase depends on network architecture and activation functions, challenging the universality of IB in training dynamics. |
| Shwartz-Ziv and Tishby (2017) [1073] | Conducted empirical analysis of information flow in deep networks using information plane visualizations, providing evidence for compression in networks trained with SGD and reinforcing IB-based interpretations. |
| Noshad et al. (2019) [1074] | Developed a new mutual information estimator using dependence graphs to improve the scalability and accuracy of IB-based analyses in high-dimensional settings, addressing limitations of traditional estimators. |
| Goldfeld et al. (2018) [1075] | Provided refined mutual information estimation techniques for deep networks, offering rigorous mathematical justifications for compression effects in neural representations. |
| Geiger (2021) [1077] | Reviewed information plane analyses in neural classifiers, evaluating the strengths and weaknesses of IB interpretations, highlighting cases where IB fails to accurately characterize training dynamics. |
| Kawaguchi et al. (2023) [1078] | Analyzed generalization properties of neural networks under IB, linking information compression to generalization error bounds and establishing IB as a regularization mechanism for improved performance. |
16.1.4.2 Recent Literature Review of Information Bottleneck (IB) Method
The Information Bottleneck (IB) method has been widely applied across various disciplines, contributing significantly to fields such as machine learning, reinforcement learning, adversarial robustness, plant metabolomics, and quantum computing. One of the most notable contributions comes from Dardour et al. (2025) [1079], who introduced a novel approach to enhance adversarial robustness in stochastic neural networks. By leveraging inter-separability and intra-concentration, their study demonstrated that using the IB principle to constrain the representation space allows neural networks to learn more robust latent features, effectively mitigating the effects of adversarial perturbations. Similarly, Krinner et al. (2025) [1080] applied IB principles to reinforcement learning by designing state-space world models that accelerate learning efficiency. Their work showed that IB-based methods enable an agent to discard irrelevant environmental noise while retaining essential features, thereby improving exploration efficiency and overall performance in model-based reinforcement learning tasks. Yildirim et. al. (2025) [1081] explored how IB constraints affect StyleGAN-based image editing and demonstrated that GAN-based inversion techniques often suffer from detail loss due to excessive compression, thus proposing refined inversion methods that better preserve fine-grained information.
Yang et al. (2025) [1082] introduced a cognitive-load-aware activation mechanism for large language models (LLMs), significantly improving efficiency by dynamically activating only the necessary model parameters. Their study leveraged IB principles to ensure that LLMs retain only the most relevant contextual representations while discarding redundant computations, reducing computational overhead without sacrificing accuracy. Similarly, Liu et al. (2025) [1083] incorporated IB principles in their Vision Mamba network for crack segmentation in infrastructure, designing a structure-aware model that efficiently filters out redundant spatial information. By applying IB techniques, they achieved enhanced computational efficiency and superior segmentation accuracy, which is crucial for real-time applications in structural health monitoring. Stierle and Valtere (2025) [1084] took a different approach by applying IB theory to medical innovation, examining how bottlenecks in information access within regulatory and patent frameworks slow down gene therapy advancements. Their work provided a comprehensive analysis of how information bottlenecks in medical research and policy impede technological progress, emphasizing the necessity of optimized regulatory frameworks.
Another significant study by Chen et al. (2025) [1085] applied IB concepts to quantum computing, particularly in optimizing construction supply chains. Their work demonstrated that quantum models, when integrated with IB techniques, could efficiently compress relevant data while filtering out extraneous information, leading to improved decision-making and enhanced scheduling flexibility. Yuan et al. (2025) [1086] extended IB applications to plant metabolomics, where they proposed a novel feature selection approach to retain highly informative metabolite interactions while discarding non-essential data. This method improved interpretability in plant metabolic studies, allowing researchers to better understand metabolite interactions without being overwhelmed by excessive data complexity. In a related domain, Dey et al. (2025) [1087] utilized IB principles in spatio-temporal prediction models for NDVI (Normalized Difference Vegetation Index), a critical measure for rice crop yield forecasting. Their IB-augmented neural network significantly enhanced prediction performance by filtering out irrelevant environmental variables while maintaining the most crucial features for accurate yield assessment.
Further expanding IB applications, Li (2025) [1088] employed IB principles in robotic path planning by developing an optimized method for navigation path extraction in mobile robots. Their approach utilized IB constraints to eliminate irrelevant environmental noise while preserving the most crucial navigational data, thereby improving the efficiency and reliability of robotic movement. This research has significant implications for autonomous navigation systems, where maintaining a compact yet informative representation of the surrounding environment is essential. Finally, Krinner et al. (2025) [1080] extended IB applications to reinforcement learning, emphasizing the importance of information retention in decision-making models. Their proposed IB-based reinforcement learning framework demonstrated superior generalization capabilities compared to traditional approaches, as it effectively retained task-relevant information while discarding unnecessary complexity. This improvement in learning efficiency has the potential to enhance autonomous systems across various applications, including robotics, finance, and large-scale industrial automation.
Overall, these studies underscore the broad applicability and impact of the IB method in diverse research areas. From adversarial robustness and reinforcement learning to plant metabolomics and robotic navigation, the IB principle continues to provide a powerful framework for optimizing information processing across various domains. The ability of IB-based models to extract the most salient features while eliminating redundancies has been instrumental in enhancing computational efficiency and decision-making accuracy. Future research in IB methodologies is likely to further refine and extend its applications, unlocking new possibilities in artificial intelligence, scientific research, and complex system optimization.
Table 12.
Summary of Recent Contributions in Information Bottleneck Research
| Authors (Year) | Contribution |
|---|---|
| Dardour et al. (2025) [1079] | Introduced a novel approach to enhance adversarial robustness in stochastic neural networks. By leveraging inter-separability and intra-concentration, their study demonstrated that IB constraints help neural networks learn more robust latent features, effectively mitigating adversarial perturbations. |
| Krinner et al. (2025) [1080] | Applied IB principles to reinforcement learning by designing state-space world models that accelerate learning efficiency. Their study showed that IB-based methods help an agent discard irrelevant environmental noise while retaining essential features, leading to improved exploration efficiency. |
| Yildirim et. al. (2024) [1081] | Explored how IB constraints affect StyleGAN-based image editing. They demonstrated that GAN-based inversion techniques often suffer from excessive compression-induced detail loss, proposing refined inversion methods that better preserve fine-grained image features. |
| Yang et al. (2025) [1082] | Developed a cognitive-load-aware activation mechanism for large language models (LLMs), improving efficiency by dynamically activating only the necessary model parameters. Their study used IB principles to retain relevant contextual representations while discarding redundant computations, reducing computational overhead. |
| Liu et al. (2025) [1083] | Incorporated IB principles in a structure-aware Vision Mamba network for crack segmentation in infrastructure. Their method efficiently filters out redundant spatial information, enhancing computational efficiency and segmentation accuracy, making it crucial for real-time applications in structural health monitoring. |
| Stierle and Valtere (2025) [1084] | Applied IB theory to medical innovation, examining how information bottlenecks in regulatory and patent frameworks slow down gene therapy advancements. Their work analyzed how such bottlenecks in medical research and policy impede technological progress. |
| Chen et al. (2025) [1085] | Applied IB concepts to quantum computing, particularly in optimizing construction supply chains. Their work demonstrated that quantum models integrated with IB techniques efficiently compress relevant data while filtering out extraneous information, improving decision-making processes. |
| Yuan et al. (2025) [1086] | Extended IB applications to plant metabolomics by proposing a novel feature selection approach that retains highly informative metabolite interactions while discarding non-essential data. This method improved interpretability in plant metabolic studies. |
| Dey et al. (2025) [1087] | Utilized IB principles in spatio-temporal prediction models for NDVI (Normalized Difference Vegetation Index), which is crucial for rice crop yield forecasting. Their IB-augmented neural network improved prediction accuracy by filtering out irrelevant environmental variables. |
| Li (2025) [1088] | Applied IB principles in robotic path planning, developing an optimized method for navigation path extraction in mobile robots. Their approach eliminated irrelevant environmental noise while preserving crucial navigational data, improving robotic movement efficiency. |
16.1.4.3 Mathematical Analysis of Information Bottleneck (IB) method
The Information Bottleneck (IB) method is a highly rigorous information-theoretic framework that seeks to optimally compress an input variable X while retaining the most relevant information about an output variable Y. Mathematically, the IB method formulates the problem as one of finding a compressed representation T of X, such that T retains as much mutual information with Y as possible while minimizing the redundant information from X. This is achieved by solving an optimization problem that balances the competing objectives of compression and prediction accuracy, fundamentally rooted in Shannon’s information theory.
The IB method is expressed through the following constrained optimization problem:
where:
- is the mutual information between the input X and the compressed representation T, which measures the amount of information retained about X in T.
- is the mutual information between T and the target variable Y, ensuring that the compressed representation remains useful for predicting Y.
- is a Lagrange multiplier that controls the trade-off between compression and prediction accuracy.
The mutual information terms are given by:
and
These quantities describe the dependencies between variables, and minimizing ensures maximal compression while maximizing preserves relevant predictive information. To find the optimal encoding distribution , we introduce a variational formulation using Lagrange multipliers, leading to the following self-consistent equations:
where:
- is a normalization constant ensuring that is a valid probability distribution.
- is the Kullback-Leibler (KL) divergence between the posterior distributions and , ensuring that T retains relevant information about Y.
By iterating the above equation along with the updates:
we can numerically solve for in an iterative fashion until convergence. A crucial aspect of the IB method is the information plane, where solutions are analyzed in terms of the trade-off between and . The optimal trade-off curve is derived by maximizing:
which provides a Pareto-optimal frontier representing the most efficient trade-offs between compression and predictive power. For multivariate Gaussian variables X and Y, where follows a joint Gaussian distribution:
the IB solution can be expressed explicitly in terms of covariance matrices. The optimal bottleneck variable T satisfies:
where the optimal compression ratio is determined by the eigenvalues of the information-preserving covariance transformation. In modern applications, the IB principle has been extensively applied to deep neural networks (DNNs), where hidden layer representations T are trained to maximize information retention about the target Y. The information-theoretic loss function:
is used in variational autoencoders (VAEs) and other deep learning models to enforce minimal sufficient representations.
In conclusion, The Information Bottleneck method provides a rigorous and mathematically principled approach to optimal data compression with maximal information retention. It is deeply rooted in Shannon’s information theory and has extensive applications in signal processing, neural networks, and statistical learning. Its iterative updates, self-consistency equations, and variational derivations make it a powerful tool for understanding fundamental limits in machine learning and information processing.
16.1.5. Restricted Boltzmann machines (RBMs)
16.1.5.1 Literature Review of Restricted Boltzmann machines (RBMs)
Restricted Boltzmann Machines (RBMs) have played a fundamental role in the advancement of machine learning, particularly in the context of unsupervised learning, feature extraction, and probabilistic modeling. The origins of RBMs can be traced back to the work of Smolensky (1986)[1090], who introduced the concept of the Harmonium, a precursor to modern RBMs. This work laid the theoretical foundation for energy-based models and provided a framework for understanding how neural networks could learn representations based on statistical mechanics principles. Smolensky’s formulation established the notion that a system could be described in terms of an energy function, where lower energy states correspond to more likely configurations of the model. The importance of this contribution is underscored by its influence on subsequent developments in probabilistic graphical models and deep learning architectures. Building upon these early theoretical insights, Hinton and Salakhutdinov (2006)[1040] demonstrated how RBMs could be stacked to form Deep Belief Networks (DBNs), enabling efficient unsupervised pretraining for deep neural networks. Their work showed that RBMs could be used for dimensionality reduction in a manner analogous to Principal Component Analysis (PCA), but with the added advantage of capturing complex, non-linear dependencies in data. The significance of this approach was evident in its ability to improve the training of deep networks, reducing overfitting and making it feasible to train deep architectures without the need for vast amounts of labeled data.
One of the critical challenges in training RBMs is the efficient computation of gradients for weight updates, given the intractability of exact maximum likelihood estimation. To address this issue, Carreira-Perpiñán and Hinton (2005)[1091] analyzed the Contrastive Divergence (CD) algorithm, a popular method for approximating the likelihood gradient. Their study provided a rigorous examination of the convergence properties of CD and highlighted its strengths and limitations. While CD allows for fast and efficient training of RBMs, they showed that it does not always lead to unbiased estimates of the likelihood gradient, which can impact the learned representations. Hinton (2012)[1092] later expanded on these ideas by providing a practical guide to training RBMs, detailing essential hyperparameter selection strategies, initialization techniques, and empirical best practices. His work served as an invaluable resource for researchers and practitioners aiming to implement RBMs effectively, covering both theoretical and experimental considerations. In a broader context, Fischer and Igel (2014)[1093] presented a comprehensive introduction to the training and theoretical underpinnings of RBMs, consolidating knowledge from previous research into a structured and accessible form. Their work not only explained the fundamental mechanics of RBMs but also explored various extensions and applications, making it an essential reference for those seeking to understand both the theoretical and applied aspects of RBMs.
The versatility of RBMs extends beyond unsupervised learning, as demonstrated by Larochelle and Bengio (2008)[1094], who introduced a discriminative variant of RBMs specifically tailored for classification tasks. Their approach modified the standard RBM training objective to optimize for discriminative performance, demonstrating that RBMs could be used effectively for supervised learning tasks as well. This contribution was crucial in showcasing the adaptability of RBMs to different learning paradigms. In another important application, Salakhutdinov, Mnih, and Hinton (2007)[1095] utilized RBMs for collaborative filtering, where they modeled user-item interactions in recommender systems. Their study demonstrated that RBMs could outperform traditional approaches like matrix factorization in certain settings, particularly in handling sparse and high-dimensional data. This work provided a strong argument for the applicability of RBMs in real-world systems where interactions between entities need to be learned from limited observed data. The ability of RBMs to extract latent features from data proved useful in various domains, including recommendation systems, document modeling, and image processing.
Another significant direction in RBM research involved understanding their effectiveness in unsupervised feature learning. Coates, Lee, and Ng (2011)[1096] conducted an extensive analysis of single-layer neural networks, including RBMs, to assess their ability to learn meaningful representations from raw data. Their findings highlighted the potential of RBMs in learning hierarchical feature representations and provided empirical evidence that RBMs could achieve competitive performance compared to other feature-learning approaches. This study influenced subsequent research in deep learning by emphasizing the importance of structured feature extraction from data. In a different vein, Hinton and Salakhutdinov (2009)[1097] proposed the Replicated Softmax model, an extension of RBMs designed to model word counts in documents. Their work bridged the gap between RBMs and topic models, enabling RBMs to be applied to natural language processing tasks. This development demonstrated the flexibility of RBMs in handling different types of data distributions, further expanding their applicability beyond conventional structured data.
In recent years, RBM research has intersected with advancements in quantum computing, as explored by Adachi and Henderson (2015)[1098], who investigated the application of quantum annealing to the training of deep neural networks. Their study explored how quantum hardware could potentially accelerate the learning process in RBMs by leveraging quantum parallelism. This work opened new avenues for research at the intersection of quantum computing and machine learning, suggesting that RBMs could benefit from novel optimization techniques unavailable to classical computing paradigms. Overall, the contributions of these works collectively demonstrate the breadth of RBM research, from theoretical foundations and training methodologies to applications in diverse domains such as recommender systems, natural language processing, and quantum machine learning. The progression of RBMs from their early formulations to their modern applications underscores their significance as a foundational tool in the development of deep learning and probabilistic modeling frameworks.
Table 13.
Summary of Contributions on Restricted Boltzmann Machines (RBMs)
| Authors (Year) | Contribution |
|---|---|
| Smolensky (1986)[1090] | Introduced the concept of the Harmonium, providing the theoretical foundation for energy-based models and probabilistic representations in neural networks. |
| Hinton and Salakhutdinov (2006)[1040] | Demonstrated how RBMs could be stacked to form Deep Belief Networks (DBNs), enabling efficient unsupervised pretraining and improving deep learning architectures. |
| Carreira-Perpiñán and Hinton (2005)[1091] | Analyzed the Contrastive Divergence (CD) algorithm, providing insights into its convergence properties and limitations for RBM training. |
| Hinton (2012)[1092] | Provided a practical guide for training RBMs, detailing hyperparameter tuning, initialization strategies, and best practices. |
| Fischer and Igel (2014)[1093] | Offered a comprehensive introduction to RBMs, covering theoretical foundations, training methodologies, and practical applications. |
| Larochelle and Bengio (2008)[1094] | Introduced a discriminative variant of RBMs tailored for classification tasks, demonstrating their adaptability to supervised learning. |
| Salakhutdinov, Mnih, and Hinton (2007)[1095] | Applied RBMs to collaborative filtering, showing their effectiveness in recommender systems by capturing latent user-item interactions. |
| Coates, Lee, and Ng (2011)[1096] | Analyzed RBMs for unsupervised feature learning, demonstrating their ability to extract hierarchical representations from raw data. |
| Salakhutdinov and Hinton (2009)[1097] | Proposed the Replicated Softmax model, extending RBMs for modeling word counts in natural language processing tasks. |
| Adachi and Henderson (2015)[1098] | Investigated the use of quantum annealing for RBM training, exploring potential acceleration of learning using quantum computing techniques. |
16.1.5.2 Recent Literature Review of Restricted Boltzmann Machines (RBMs)
Restricted Boltzmann Machines (RBMs) have been extensively studied and applied across various domains, leading to significant advancements in both theoretical understanding and practical implementations. One of the most notable works in this area is by Salloum, Nayal, and Mazzara (2024) [1099], who explored the comparative performance of classical RBMs and their quantum counterparts in MNIST classification. Their study highlights how quantum annealing techniques, particularly quantum-restricted Boltzmann machines, offer improved performance over classical models in specific scenarios, mainly due to their ability to explore the solution space more effectively. This research underscores the potential for quantum machine learning to outperform traditional neural networks, particularly in complex optimization problems where classical RBMs struggle due to their inherent limitations in representing certain distributions.
Building upon the foundational aspects of RBMs, Joudaki (2025) [1100] conducted a comprehensive review of their applications in human action recognition, particularly in combination with Deep Belief Networks (DBNs). This study systematically categorizes existing research and identifies key challenges, such as overfitting and slow convergence, while also discussing how RBMs facilitate hierarchical feature extraction. A complementary perspective is provided by Prat Pou, Romero, Martí, and Mazzanti (2025) [1101], who focus on improving the computational efficiency of RBMs in evaluating partition functions using annealed importance sampling. Their work is particularly relevant in statistical physics, where accurate estimation of partition functions is crucial for modeling spin systems and understanding phase transitions. They demonstrate that their proposed initialization method enhances the robustness of the sampling process, significantly reducing variance in the estimated probabilities.
Further theoretical advancements in RBMs were made by Decelle, Gómez, and Seoane (2025) [1102], who investigated the ability of RBMs to infer high-order dependencies in complex systems. Their work presents a framework for mapping RBMs onto higher-order interactions, particularly in domains such as protein interaction networks and spin glasses, where conventional machine learning models struggle to capture intricate relationships. In a related study, Savitha, Kannan, and Logeswaran (2025) [1103] integrate RBMs within DBNs for cardiovascular disease prediction, leveraging optimization techniques such as the Harris Hawks Search algorithm. Their research emphasizes the role of RBMs in medical diagnosis, showing that the extracted features from unsupervised pretraining significantly improve classification accuracy in deep learning pipelines. These contributions highlight the versatility of RBMs in both theoretical modeling and real-world applications.
Efforts to enhance the efficiency of RBM training and sampling have been explored by Béreux, Decelle, and Furtlehner (2025) [1104], who propose a novel training strategy that accelerates convergence without compromising generalization performance. Their method is particularly effective for large-scale learning problems where traditional contrastive divergence methods are computationally expensive. Thériault et. al. (2024) [1105] further examine the structured learning properties of RBMs in a teacher-student setting, demonstrating that incorporating structured priors enhances the network’s ability to generalize beyond seen data. These studies collectively address the computational bottlenecks associated with RBM training, making them more viable for practical machine learning applications.
Another notable application of RBMs is in feature learning for non-traditional data types. Manimurugan, Karthikeyan, and Narmatha (2024) [1106] introduce a hybrid approach that combines Bi-LSTM networks with RBMs for underwater object detection, demonstrating how RBMs effectively capture spatial dependencies in sonar and optical imagery. Similarly, Hossain, Showkat Ara, and Han (2025) [1107] benchmark RBMs against classical and deep learning models for human activity recognition, finding that RBMs provide a unique advantage in extracting latent representations. Extending RBM applications to neuromorphic computing, Qin, Peng, Miao, Chen, Ouyang, and Yang (2025) [1108] integrate RBMs with magnetic tunnel junctions for enhanced magnetic anomaly detection. This interdisciplinary work bridges the gap between neuromorphic architectures and probabilistic learning models, demonstrating a path towards more energy-efficient and compact AI systems.
Collectively, these studies highlight the ongoing evolution of RBMs, from fundamental theoretical advances to diverse applications in physics, medicine, security, and beyond. The research spans improvements in training efficiency, inference capabilities, and integration with other deep learning techniques, demonstrating the continued relevance of RBMs in modern AI research. While challenges such as mode collapse and slow training persist, the integration of RBMs with quantum computing, neuromorphic architectures, and hybrid deep learning models presents promising directions for future work.
| Authors (Year) | Contribution |
| Salloum et al. (2024) [1099] | Compared classical RBMs with quantum-restricted Boltzmann machines for MNIST classification, demonstrating that quantum models exhibit superior performance in certain optimization scenarios. |
| Joudaki (2025) [1100] | Conducted a comprehensive literature review on RBMs and Deep Belief Networks (DBNs) for human action recognition, identifying key challenges such as overfitting and slow convergence. |
| Prat Pou et al. (2025) [1101] | Proposed an improved method for evaluating the partition function in RBMs using annealed importance sampling, which enhances accuracy in statistical physics applications. |
| Decelle et al. (2025) [1102] | Investigated the ability of RBMs to infer high-order dependencies in complex systems, particularly in protein interaction networks and spin glasses. |
| Savitha et al. (2025) [1103] | Integrated RBMs within DBNs for cardiovascular disease prediction, leveraging optimization techniques such as the Harris Hawks Search algorithm to improve diagnostic accuracy. |
| Béreux et al. (2025) [1104] | Developed an efficient training strategy for RBMs that accelerates convergence while maintaining strong generalization capabilities in large-scale machine learning problems. |
| Thériault et al. (2024) [1105] | Explored structured learning in RBMs within a teacher-student setting, demonstrating that incorporating structured priors enhances generalization beyond seen data. |
| Manimurugan et al. (2024) [1106] | Combined Bi-LSTM networks with RBMs for underwater object detection, showcasing the ability of RBMs to effectively capture spatial dependencies in sonar and optical imagery. |
| Hossain et al. (2025) [1107] | Benchmarked RBMs against classical and deep learning models for human activity recognition, highlighting their effectiveness in extracting latent features. |
| Qin et al. (2025) [1108] | Integrated RBMs with magnetic tunnel junctions for magnetic anomaly detection, demonstrating their potential in neuromorphic computing for energy-efficient AI systems. |
16.1.5.3 Mathematical Analysis of Restricted Boltzmann Machines (RBMs)
A Restricted Boltzmann Machine (RBM) is a generative stochastic artificial neural network that consists of a visible layer and a hidden layer, forming a bipartite graph with no intra-layer connections. This characteristic differentiates it from more general Boltzmann Machines, where visible-visible and hidden-hidden connections are allowed. Mathematically, an RBM models a joint probability distribution over a set of visible variables and hidden variables using an energy-based approach. The energy function associated with the RBM, which determines the probability of a given configuration, is given by:
where represents the state of the i-th visible unit, represents the state of the j-th hidden unit, is the weight connecting visible unit i to hidden unit j, and are the biases of the visible and hidden units, respectively. The probability distribution of a visible-hidden configuration is governed by the Boltzmann distribution, given by:
where Z is the partition function ensuring normalization:
Since the hidden units are conditionally independent given the visible units, the conditional probability distribution of a hidden unit given the visible units follows a sigmoid activation function:
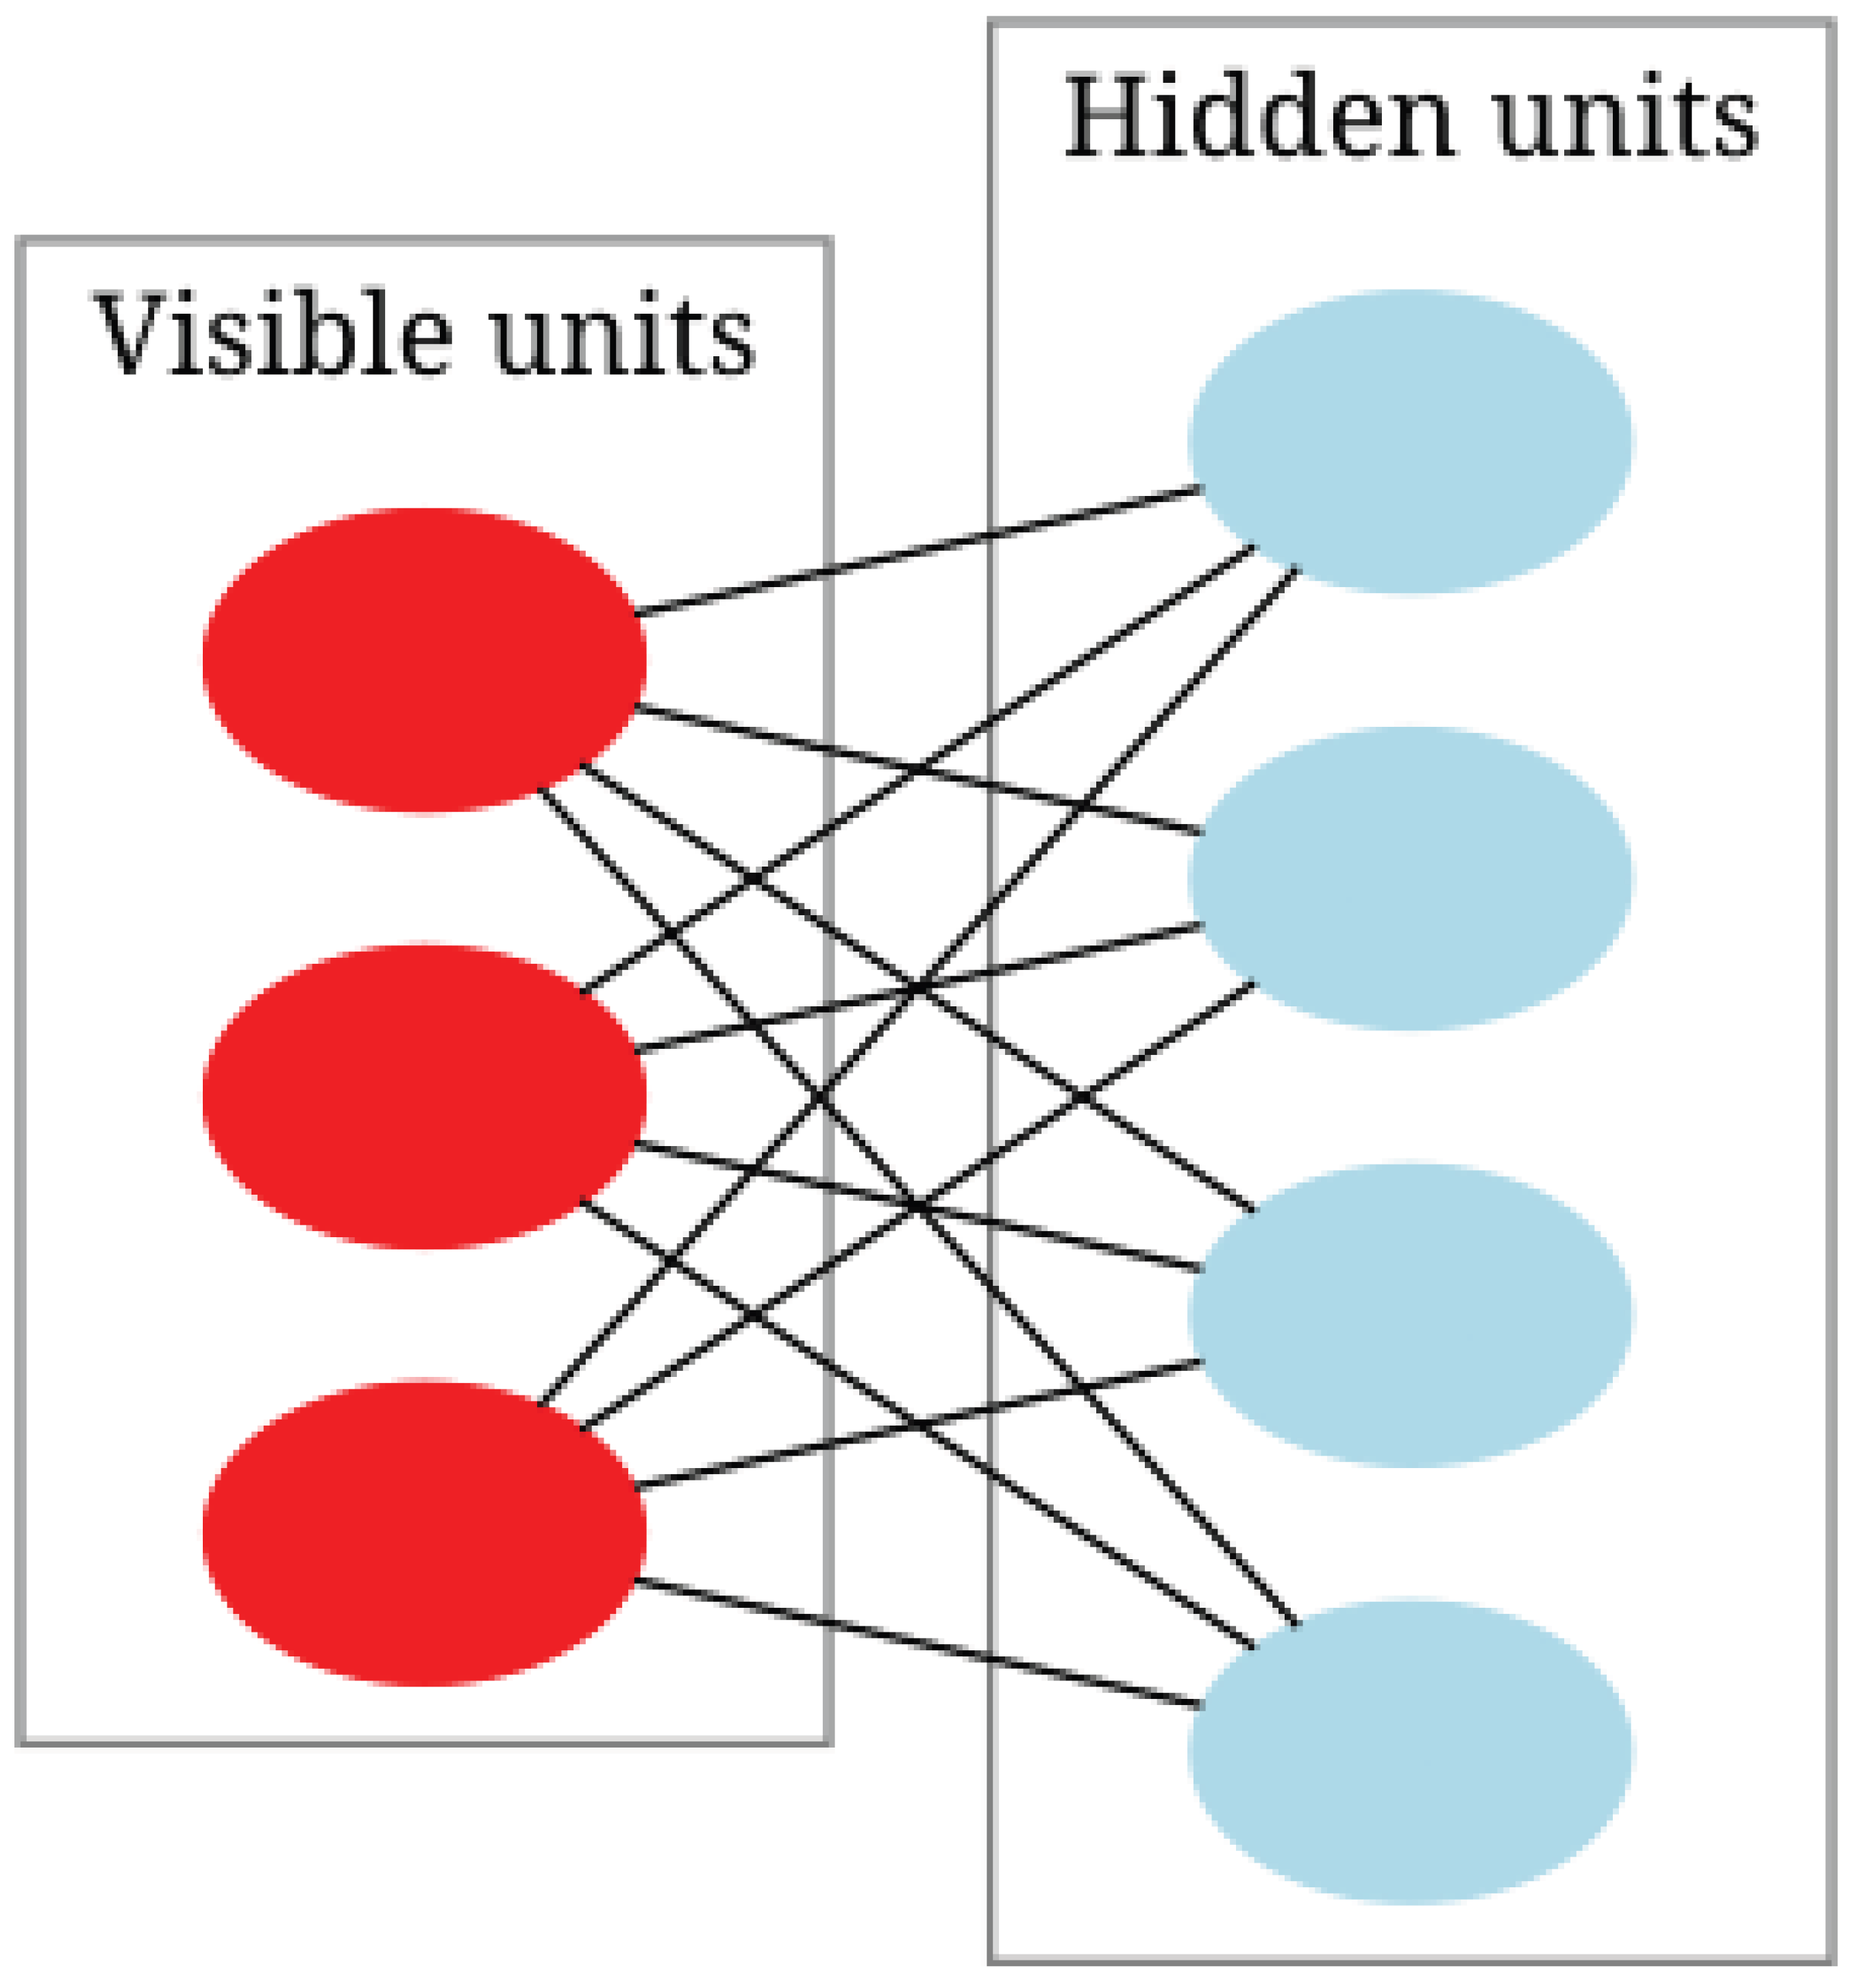 Similarly, the probability of a visible unit given the hidden units is:
The marginal probability of a visible vector is obtained by summing over all possible hidden states:
By factoring out terms dependent only on , we define the free energy function as:
which leads to:
RBMs are trained using gradient descent to minimize the negative log-likelihood:
The gradient of this likelihood function with respect to the weight matrix is given by:
where is the expectation over the training data, is the expectation under the model distribution. The weight updates are then performed using:
RBMs use stochastic gradient descent (SGD) for optimization. The weight updates in SGD follow:
RBMs serve as the building blocks for Deep Belief Networks (DBNs), where multiple RBMs are stacked to form deep architectures. Each layer is pre-trained in an unsupervised manner using contrastive divergence before fine-tuning using backpropagation.
Figure 150.
Diagram of a restricted Boltzmann machine. Image Credit: By Qwertyus - Own work, CC BY-SA 3.0, https://commons.wikimedia.org/w/index.php?curid=22717044. Illustration of a restricted Boltzmann machine featuring three observable units and four concealed units, excluding bias units
Figure 150.
Diagram of a restricted Boltzmann machine. Image Credit: By Qwertyus - Own work, CC BY-SA 3.0, https://commons.wikimedia.org/w/index.php?curid=22717044. Illustration of a restricted Boltzmann machine featuring three observable units and four concealed units, excluding bias units
16.1.6. Deep Belief Networks (DBNs)
16.1.6.1 Literature Review of Deep Belief Networks (DBNs)
Deep Belief Networks (DBNs) have played a transformative role in deep learning by enabling efficient unsupervised pre-training and hierarchical feature extraction. One of the foundational works in this area is by Hinton et al. (2006) [854], who introduced a fast learning algorithm for DBNs that leverages a greedy layer-wise pre-training strategy using Restricted Boltzmann Machines (RBMs). This work addressed the long-standing vanishing gradient problem in deep networks by initializing weights in a way that preserves meaningful feature representations before fine-tuning with supervised learning. Their contribution established DBNs as a key component of early deep learning architectures and laid the groundwork for further explorations into deep generative models. Lee et al. (2009) [1109] extended the standard DBN framework by incorporating convolutional structures, leading to the development of Convolutional Deep Belief Networks (CDBNs). By introducing local receptive fields and weight sharing, CDBNs enabled the automatic discovery of spatial hierarchies in data, making them particularly suitable for image and speech processing applications. This work demonstrated that DBNs could be adapted to structured data representations, enhancing their scalability and generalization capability.
In the domain of speech recognition, Mohamed et al. (2012) [1111] pioneered the application of DBNs for acoustic modeling, demonstrating that these networks could effectively capture complex audio patterns. Their work provided empirical evidence that DBN-based models significantly outperformed traditional Gaussian Mixture Models (GMMs) when used in conjunction with Hidden Markov Models (HMMs) for automatic speech recognition. This breakthrough accelerated the adoption of deep learning in the field of speech processing and motivated subsequent research into deep neural network-based acoustic modeling. Similarly, Zhang and Zhao (2017) [1113] explored the use of DBNs for fault diagnosis in chemical processes, highlighting their ability to model intricate dependencies within multivariate industrial datasets. Their work demonstrated that DBNs could learn compact feature representations from noisy sensor data, leading to improved fault detection accuracy. By applying DBNs to real-world industrial systems, they provided compelling evidence of their practical utility in process monitoring and control.
Further expanding the use of DBNs in fault diagnostics, Peng et al. (2019) [1112] introduced a health indicator construction framework based on DBNs for bearing fault diagnosis. Their approach enabled the automatic extraction of degradation features from vibration signals, allowing for early detection of mechanical failures. The health indicator developed in their study demonstrated superior predictive performance compared to traditional statistical methods, underscoring the power of DBNs in prognostics and health management applications. Zhang et al. (2018) [1115] extended the use of DBNs to the medical field by integrating them with feature selection and extraction methods for predicting clinical outcomes in lung cancer patients. Their study illustrated that DBNs could capture complex interactions between clinical variables, improving the interpretability and accuracy of predictive models in oncology. By leveraging deep learning for medical prognosis, this work demonstrated the potential of DBNs to advance personalized healthcare and decision support systems.
Zhong et. al. (2017) [1118] examined the problem of image classification with limited training data and demonstrated that DBNs could learn meaningful feature representations even in data-scarce settings. Their work emphasized the ability of DBNs to leverage unsupervised pre-training, enabling them to generalize well even when labeled data is insufficient. This contribution reinforced the importance of DBNs in applications where obtaining large-scale labeled datasets is challenging. Financial time series analysis is another domain where DBNs have demonstrated utility. Liu (2018) [1114] proposed a hybrid prediction model that combined DBNs with the Autoregressive Integrated Moving Average (ARIMA) model for stock trend forecasting. Their approach leveraged the pattern recognition capabilities of DBNs along with the time-series forecasting strengths of ARIMA, resulting in improved predictive performance for financial markets. This work showcased the effectiveness of deep learning in modeling complex temporal dependencies and provided insights into how hybrid models could enhance financial decision-making. Jormakka and Ghosh (2021) [1452] introduce a novel method for solving certain stochastic processes using generating functions, derive a general theorem for generating functions of a particular type, and apply this method to obtain polynomial-time algorithms for specific partitions; they further generalize the approach to a broader class of linear transformations and utilize it to develop a theoretical polynomial-time algorithm for the knapsack problem. Ghosh (2021) [1465] provides an accessible exploration of the Arithmetic Mean-Geometric Mean (AM-GM) inequality, offering both elementary and advanced proofs—including an elegant derivation using the exponential function—and demonstrates its applications through classical inequalities such as Nesbitt’s inequality, thereby enhancing understanding of fundamental inequalities in mathematics. Cox and Ghosh (2020) [1479] extend the study of the Collatz conjecture by introducing the concept of generalized dead limbs and analyzing cycles with attachment points, demonstrating that all known cycles for lie within these generalized dead limbs, and suggesting that this containment is a necessary condition for the existence of such cycles. Abhyankar et. al. (2002) [1490] provided a comprehensive overview of the Zeta function, detailing its historical development, key properties, and applications in number theory, and offered an accessible introduction to its significance in modern mathematics. Finally, Hoang and Kang (2018) [1116] developed a novel fault diagnosis framework by integrating DBNs with Dempster–Shafer evidence theory. Their study highlighted how DBNs could serve as a powerful feature extractor while Dempster–Shafer theory facilitated the fusion of information from multiple sources, enhancing fault detection accuracy. This interdisciplinary approach demonstrated the potential of combining deep learning with probabilistic reasoning for more reliable fault diagnosis in engineering systems.
Collectively, these studies illustrate the broad impact of DBNs across multiple domains, including speech recognition, industrial fault diagnosis, medical prognosis, uncertainty quantification, and financial prediction. The ability of DBNs to learn hierarchical representations from high-dimensional data has established them as a powerful tool for tackling complex machine learning problems. The advancements made in adapting DBNs to convolutional architectures, hybrid models, and ensemble methods have further expanded their applicability, ensuring their continued relevance in deep learning research. As interest in deep generative models and representation learning grows, DBNs continue to serve as a foundational framework for understanding and developing more sophisticated deep learning architectures.
Table 14.
Summary of Contributions on Deep Belief Networks (DBNs)
| Authors (Year) | Contribution |
|---|---|
| Hinton et al. (2006) [854] | Introduced a fast learning algorithm for DBNs using a greedy layer-wise pre-training strategy based on Restricted Boltzmann Machines (RBMs). Addressed the vanishing gradient problem and established DBNs as foundational deep learning architectures. |
| Lee et al. (2009) [1109] | Developed Convolutional Deep Belief Networks (CDBNs) by incorporating convolutional structures into DBNs, introducing local receptive fields and weight sharing for improved scalability in image and speech processing. |
| Mohamed et al. (2012) [1111] | Pioneered the application of DBNs for acoustic modeling in speech recognition, demonstrating superior performance over traditional Gaussian Mixture Models (GMMs) in conjunction with Hidden Markov Models (HMMs). |
| Zhang and Zhao (2017) [1113] | Applied DBNs for fault diagnosis in chemical processes, showing that DBNs effectively model dependencies in multivariate datasets and enhance fault detection accuracy. |
| Peng et al. (2019) [1112] | Developed a DBN-based health indicator construction framework for bearing fault diagnosis, enabling automatic extraction of degradation features from vibration signals for early failure detection. |
| Zhang et al. (2018) [1115] | Integrated DBNs with feature selection methods for predicting clinical outcomes in lung cancer patients, enhancing predictive accuracy and interpretability in medical prognosis. |
| Zhong et. al. (2017) [1118] | Demonstrated that DBNs could learn meaningful representations even with limited training data, reinforcing their utility in scenarios with scarce labeled datasets. |
| Liu (2018) [1114] | Combined DBNs with the Autoregressive Integrated Moving Average (ARIMA) model for stock trend forecasting, leveraging DBNs’ pattern recognition capabilities with ARIMA’s time-series forecasting strengths. |
| Hoang and Kang (2018) [1116] | Developed a novel fault diagnosis framework by integrating DBNs with Dempster–Shafer evidence theory, enhancing fault detection accuracy through probabilistic reasoning. |
16.1.6.2 Recent Literature Review of Deep Belief Networks (DBNs)
Deep Belief Networks (DBNs) have emerged as a powerful deep learning architecture capable of hierarchical feature learning and unsupervised pre-training. These networks, based on a stack of Restricted Boltzmann Machines (RBMs), have been widely used in various fields, ranging from human activity recognition and medical diagnosis to cybersecurity and agricultural applications. Joudaki (2025) [1100] provides an extensive literature review on the theoretical underpinnings of DBNs and RBMs, emphasizing their role in human action recognition. The study highlights how DBNs are particularly suited for tasks requiring high-dimensional feature extraction and learning temporal dependencies, outperforming traditional machine learning models. The hierarchical representation learned by DBNs allows them to capture complex patterns in human gestures and postures, making them ideal for applications such as motion tracking and gesture-based interface design.
Alzughaibi (2025) [1119] presents an innovative application of DBNs in pest detection, where they are integrated with a modified artificial hummingbird algorithm. The research demonstrates how deep learning-based pattern recognition models can significantly enhance the accuracy of pest classification in agricultural settings. The model is trained on large datasets of pest images, leveraging the hierarchical feature extraction capabilities of DBNs to distinguish between different species effectively. Similarly, Savitha et al. (2025) [1103] apply DBNs to cardiovascular disease prediction by integrating them with the Harris Hawks Search optimization algorithm. This approach optimizes feature selection and classification accuracy, showing that DBNs can be successfully adapted for medical diagnosis by leveraging their deep hierarchical structure. The study underscores the potential of DBNs in clinical decision support systems, where accurate and timely diagnoses are crucial.
The intrinsic hierarchical structure of DBNs has also been studied by Tausani et al. (2025) [1120], who investigate their top-down inference capabilities compared to other deep generative models. Their research explores how DBNs can simulate human-like cognition and learning, making them suitable for applications in artificial intelligence and cognitive computing. By analyzing the internal feature representations of DBNs, the study provides insights into their interpretability and efficiency in generative tasks. Kumar and Ravi (2025) [1121] further contribute to the field by introducing XDATE, an explainable deep learning framework that combines DBNs with auto-encoders. The study addresses the issue of interpretability in deep learning by employing the Garson Algorithm to improve feature attribution, demonstrating that DBNs can achieve a balance between accuracy and explainability in classification tasks.
In the field of medical image analysis, Alhajlah (2024) [1122] applies DBNs for automated lesion detection in gastrointestinal endoscopic images. The research integrates DBNs with a genetic algorithm-based segmentation technique, significantly improving diagnostic precision. By leveraging the feature extraction capabilities of DBNs, the proposed system outperforms conventional image processing techniques, reducing false positives and improving lesion classification accuracy. Hossain et al. (2025) [1107] evaluate the performance of DBNs in human activity recognition, benchmarking them against various classical and deep learning models. Their study finds that DBNs, despite being unsupervised in their initial training phase, can achieve competitive accuracy on small and medium-sized datasets, demonstrating their robustness and adaptability.
The application of DBNs extends to cybersecurity, where Pavithra et al. (2025) [1123] develop a hybrid RNN-DBN model for detecting IoT attacks. This approach captures temporal dependencies in network traffic, allowing for effective anomaly detection and threat mitigation. The fusion of DBNs with recurrent networks enables better sequence modeling, making them highly effective in cybersecurity applications. In a similar vein, Bhadane and Verma (2024) [1124] explore the role of DBNs in personality trait classification, comparing their performance with CNNs and RNNs. Their study highlights the advantages of DBNs in handling high-dimensional psychological datasets, where deep hierarchical structures enable the capture of complex personality-related patterns. Lastly, Keivanimehr and Akbari (2025) [1125] examine how DBNs can be applied in edge computing for cardiovascular disease monitoring. Their research discusses the feasibility of deploying DBN-based models in TinyML environments, where computational efficiency and real-time processing are critical.
Collectively, these studies demonstrate the versatility and efficacy of DBNs in various domains, from healthcare and cybersecurity to agricultural automation and cognitive computing. The hierarchical feature learning capabilities of DBNs, combined with their ability to leverage unsupervised pre-training, make them suitable for a wide range of complex tasks. Future research is likely to explore further hybrid architectures that integrate DBNs with more advanced deep learning models, enhancing their adaptability and efficiency in real-world applications.
Table 15.
Summary of Contributions
| Authors (Year) | Contribution |
|---|---|
| Joudaki (2025) [1100] | Provides an extensive literature review on the theoretical foundations of DBNs and RBMs, emphasizing their role in human action recognition. Demonstrates their effectiveness in capturing complex patterns in human gestures and postures for applications such as motion tracking and gesture-based interface design. |
| Alzughaibi (2025) [1119] | Applies DBNs in pest detection, integrating them with a modified artificial hummingbird algorithm. Enhances pest classification accuracy using deep hierarchical feature extraction on large image datasets. |
| Savitha et al. (2025) [1103] | Employs DBNs for cardiovascular disease prediction, integrating them with the Harris Hawks Search optimization algorithm. Demonstrates improved feature selection and classification accuracy in medical diagnosis applications. |
| Tausani et al. (2025) [1120] | Investigates the top-down inference capabilities of DBNs compared to other deep generative models. Explores their interpretability and efficiency in artificial intelligence and cognitive computing tasks. |
| Kumar and Ravi (2025) [1121] | Introduces XDATE, an explainable deep learning framework that combines DBNs with auto-encoders. Uses the Garson Algorithm to enhance feature attribution, balancing accuracy and interpretability in classification tasks. |
| Alhajlah (2024) [1122] | Applies DBNs in medical image analysis for automated lesion detection in gastrointestinal endoscopic images. Integrates DBNs with a genetic algorithm-based segmentation technique to enhance diagnostic precision and reduce false positives. |
| Hossain et al. (2025) [1107] | Benchmarks DBNs against classical and deep learning models for human activity recognition. Demonstrates DBNs’ robustness and adaptability, particularly in small and medium-sized datasets. |
| Pavithra et al. (2025) [1123] | Develops a hybrid RNN-DBN model for IoT attack detection, capturing temporal dependencies in network traffic for anomaly detection and threat mitigation. |
| Bhadane and Verma (2024) [1124] | Explores DBNs for personality trait classification, comparing their performance with CNNs and RNNs. Highlights the advantages of DBNs in processing high-dimensional psychological datasets. |
| Keivanimehr and Akbari (2025) [1125] | Investigates DBNs for edge computing applications in cardiovascular disease monitoring. Discusses feasibility in TinyML environments for computational efficiency and real-time processing. |
16.1.6.3 Mathematical Analysis of Deep Belief Networks (DBNs)
A Deep Belief Network (DBN) is a generative graphical model composed of multiple layers of stochastic latent variables, typically represented as Restricted Boltzmann Machines (RBMs) stacked hierarchically. The fundamental structure of a DBN is built upon the principles of probabilistic modeling, unsupervised pretraining, and layer-wise greedy learning to form a deep hierarchical representation of data. Mathematically, a DBN is a composition of multiple RBMs, each trained independently in a bottom-up fashion, followed by fine-tuning using backpropagation when supervised learning is required. The probabilistic nature of DBNs allows them to model complex joint probability distributions over observed and latent variables, making them highly effective for feature extraction, dimensionality reduction, and generative modeling.
Let denote the input data vector, where d is the dimensionality of the input space. A DBN consists of multiple layers of hidden variables connected in a directed fashion in the upper layers and undirected in the lower layers. The network defines a joint probability distribution over the visible units and hidden units as follows:
where:
- represents the conditional distribution of the visible layer given the first hidden layer.
- represents the conditional dependency between consecutive layers.
- represents the top-layer prior, which is modeled as a Restricted Boltzmann Machine (RBM).
Figure 151.
Diagram of a Deep belief network. Image Credit: By Qwertyus - Own work, CC0, https://commons.wikimedia.org/w/index.php?curid=30324766. Diagrammatic representation of a deep belief network, where the arrows indicate directed connections within the corresponding graphical model
Figure 151.
Diagram of a Deep belief network. Image Credit: By Qwertyus - Own work, CC0, https://commons.wikimedia.org/w/index.php?curid=30324766. Diagrammatic representation of a deep belief network, where the arrows indicate directed connections within the corresponding graphical model
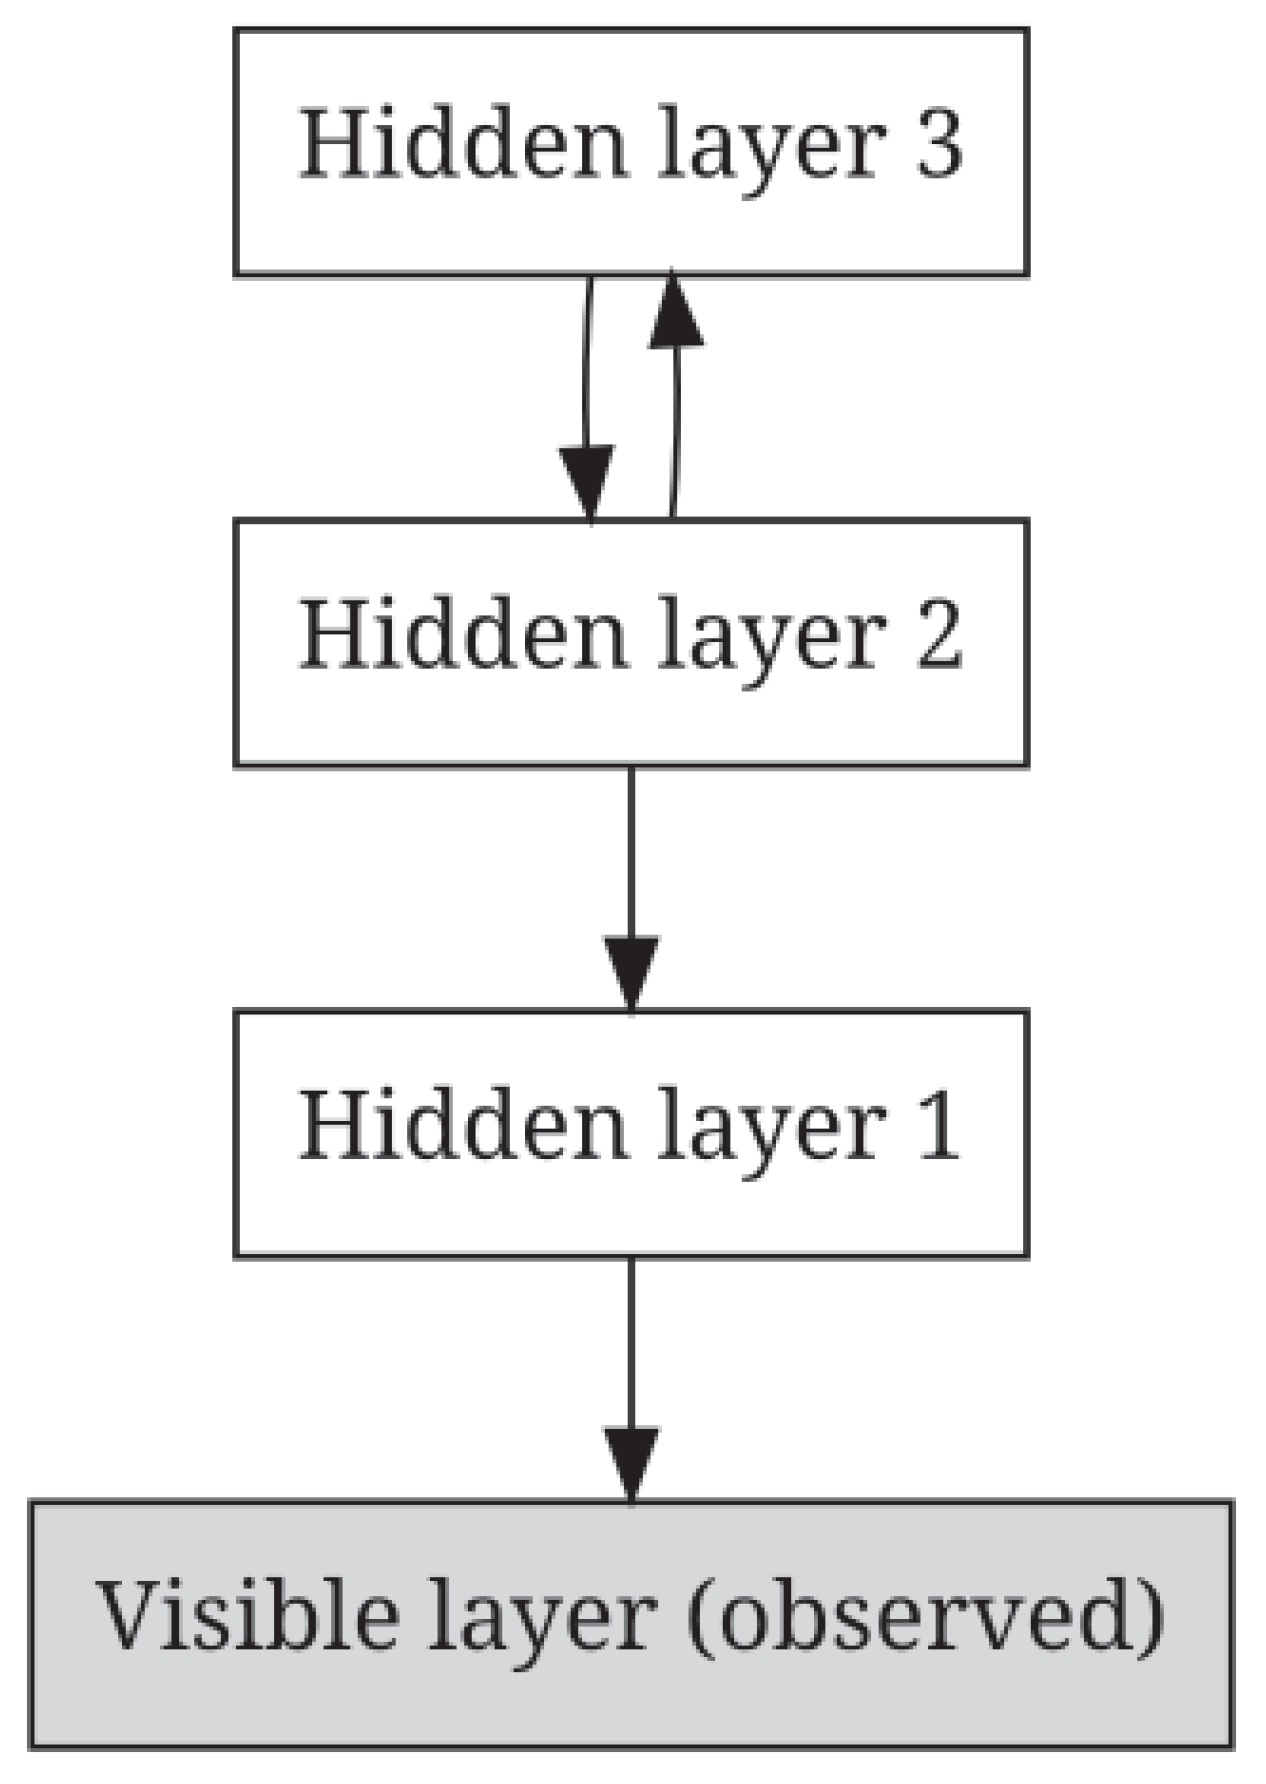
Restricted Boltzmann Machine (RBM) as a Building Block
Each RBM consists of a layer of visible units and a layer of hidden units , with energy function given by:
where are the binary visible units, are the binary hidden units, is the weight matrix connecting visible and hidden units, and are the bias terms for visible and hidden units, respectively. The probability distribution over is given by the Boltzmann distribution:
where Z is the partition function:
Since exact inference in RBMs is intractable due to the exponential summation in Z, we use Contrastive Divergence (CD) to approximate the gradient:
Layer-wise Pretraining of DBNs
DBNs are trained using a layer-wise greedy learning algorithm, which first trains each RBM independently and then stacks them hierarchically. Given an input dataset , the pretraining procedure follows:
- Train the first RBM with input to obtain hidden activations:
- Use hidden activations as input for training the second RBM:
Fine-Tuning with Backpropagation
Once pretraining is complete, DBNs can be fine-tuned using backpropagation if labeled data is available. A cost function such as cross-entropy loss is used:
The gradients are computed using:
Deep Belief Networks (DBNs) serve as powerful generative models capable of capturing hierarchical representations of data through layer-wise pretraining of RBMs.
16.1.7. t-Distributed Stochastic Neighbor Embedding (t-SNE)
16.1.7.1 Literature Review of t-Distributed Stochastic Neighbor Embedding
T-distributed Stochastic Neighbor Embedding (t-SNE) has been widely studied and refined since its introduction, with various works expanding its theoretical foundations, applications, and practical optimizations. The foundational work of van der Maaten and Hinton (2008) [1042] introduced t-SNE as an improvement over Stochastic Neighbor Embedding (SNE), primarily by incorporating a symmetric probability distribution in the low-dimensional space and replacing the Gaussian-based similarity measure with a heavy-tailed Student’s t-distribution to address the crowding problem. This innovation enabled better preservation of both local and global structures when mapping high-dimensional data into lower dimensions. The study established the mathematical formulation of t-SNE by minimizing the Kullback-Leibler divergence between joint probability distributions of data points in high and low dimensions, leading to a widely adopted visualization tool in machine learning and data science.
Several studies have analyzed and improved the robustness of t-SNE, particularly concerning its application to large datasets and biological data visualization. Kobak and Berens (2019) [1126] addressed the challenges in single-cell transcriptomics by developing "opt-SNE," an automated parameter selection framework that fine-tunes the perplexity and learning rate to enhance visualization reliability. Their study demonstrated that proper parameter tuning significantly impacts the quality of embeddings, thereby reducing the risk of misleading interpretations. Similarly, Belkina et al. (2019) [1127] proposed an automated approach for optimizing t-SNE parameters for large datasets, emphasizing the importance of reproducibility and interpretability in real-world applications. Their work provided empirical evidence that parameter selection can drastically affect the clustering structure in t-SNE visualizations, necessitating automated approaches for better standardization.
Beyond empirical studies, some researchers have sought to establish a more rigorous theoretical understanding of t-SNE’s behavior in clustering and manifold learning. Linderman and Steinerberger (2019) [1128] provided a mathematical proof that t-SNE effectively recovers well-separated clusters under certain conditions, offering a theoretical foundation for why t-SNE performs well in clustering applications despite not being explicitly designed for that purpose. Their work bridged the gap between empirical success and mathematical justification, thereby enhancing the credibility of t-SNE in scientific applications. Amorim and Mirkin (2012) [1129] extended this discussion by exploring the role of distance metrics in clustering and feature weighting, providing an alternative approach that incorporated Minkowski metrics and anomaly detection within the t-SNE-reduced space. Their work showed that selecting an appropriate distance function could further refine the clustering properties of dimensionality reduction methods, leading to improved segmentation of data points. Additionally, Wattenberg et al. (2016) [1130] provided a detailed discussion on how to use t-SNE effectively, emphasizing the interpretational pitfalls and practical considerations when applying t-SNE to real-world data. Their work highlighted the limitations of t-SNE in preserving global structure and warned against misinterpreting distance relationships in the lower-dimensional space.
In response to computational challenges, Pezzotti et al. (2016) [1131] proposed an approximation method that enabled real-time, user-steerable t-SNE for progressive visual analytics. Their work significantly reduced the computational burden of t-SNE by introducing an interactive framework that allowed users to refine embeddings dynamically, making t-SNE more practical for large-scale applications. Similarly, Kobak and Linderman (2021) [1132] investigated the importance of initialization strategies for preserving global data structures in both t-SNE and UMAP embeddings. Their findings demonstrated that different initialization schemes can lead to drastically different embeddings, underscoring the need for careful selection of initialization methods to ensure meaningful visualizations.
Finally, alternative approaches to t-SNE have been explored, with studies comparing its performance against other dimensionality reduction techniques. Becht et al. (2019) [1133] introduced Uniform Manifold Approximation and Projection (UMAP) as an alternative to t-SNE, arguing that UMAP offers improved scalability and better preservation of global structures. Their study provided empirical comparisons between UMAP and t-SNE, demonstrating that UMAP performs comparably in clustering while requiring significantly less computational time. Likewise, Moon et al. (2019) [1134] proposed PHATE (Potential of Heat-diffusion for Affinity-based Transition Embedding), which was designed to capture both local and global structures more effectively than t-SNE. Their study showcased PHATE’s ability to preserve continuous trajectories in biological data, highlighting its advantages in studying cell differentiation processes. Collectively, these studies illustrate the ongoing efforts to refine and expand upon t-SNE, both theoretically and practically, ensuring its continued relevance in high-dimensional data visualization.
Table 16.
Summary of Contributions in t-SNE Literature Review
| Authors (Year) | Contribution |
|---|---|
| van der Maaten and Hinton (2008) [1042] | Introduced t-SNE as an extension of Stochastic Neighbor Embedding (SNE) by incorporating a Student’s t-distribution to address the crowding problem. This modification improved the preservation of both local and global structures and formulated t-SNE as an optimization problem minimizing Kullback-Leibler divergence. |
| Kobak and Berens (2019) [1126] | Developed "opt-SNE," an automated parameter selection framework for fine-tuning perplexity and learning rate in t-SNE. Their work demonstrated that proper parameter selection significantly affects embedding quality and reduces misleading visualizations in single-cell transcriptomics. |
| Belkina et al. (2019) [1127] | Proposed an optimized pipeline for selecting t-SNE parameters, focusing on reproducibility and interpretability in large-scale biological datasets. Their work emphasized the importance of standardizing parameter selection to improve clustering outcomes in t-SNE applications. |
| Linderman and Steinerberger (2019) [1128] | Provided a mathematical proof that t-SNE reliably recovers well-separated clusters under specific conditions, bridging the gap between empirical observations and theoretical guarantees in clustering applications. |
| Amorim and Mirkin (2012) [1129] | Investigated the role of distance metrics in t-SNE clustering, proposing the use of Minkowski metrics and feature weighting to refine cluster separation. Their work highlighted how different distance functions influence embedding outcomes. |
| Wattenberg et al. (2016) [1130] | Analyzed interpretational pitfalls in t-SNE, cautioning against misinterpretation of distances in low-dimensional embeddings. Their study outlined best practices for applying t-SNE in real-world data visualization tasks. |
| Pezzotti et al. (2016) [1131] | Developed a real-time, user-steerable t-SNE method that enabled progressive visual analytics. Their approach reduced computational overhead and allowed for interactive exploration of embeddings in large-scale applications. |
| Kobak and Linderman (2021) [1132] | Investigated initialization strategies for t-SNE and UMAP, demonstrating that different initialization schemes lead to vastly different embeddings. Their study emphasized the importance of careful initialization to preserve global data structures. |
| Becht et al. (2019) [1133] | Introduced UMAP as an alternative to t-SNE, showing that UMAP provides improved scalability and better preservation of global structures while requiring significantly less computational time. |
| Moon et al. (2019) [1134] | Proposed PHATE as a dimensionality reduction technique designed to capture both local and global structures more effectively than t-SNE. Their study demonstrated PHATE’s superiority in visualizing continuous biological trajectories, such as cell differentiation processes. |
16.1.7.2 Recent Literature Review of t-Distributed Stochastic Neighbor Embedding
t-Distributed Stochastic Neighbor Embedding (t-SNE) has emerged as a powerful tool in high-dimensional data visualization, finding extensive applications across various domains, including biomedical sciences, material science, deep learning, and geophysics. Rivera and Deniega (2025) [1135] demonstrated the efficacy of t-SNE in automating flow cytometry gating, where the method was combined with clustering techniques such as DBSCAN and PCA. Their study highlighted how t-SNE facilitates better separation and classification of cell populations, ultimately improving computational efficiency in biomedical applications. Similarly, Chang (2025) [1136] provided a rigorous survey of dimensionality reduction techniques, discussing the advantages and limitations of t-SNE compared to traditional methods like PCA and newer alternatives like UMAP. The study outlined the scenarios where t-SNE performs optimally, particularly in non-linear data distributions, making it an essential reference for researchers selecting appropriate dimensionality reduction techniques.
In the domain of defect detection in industrial settings, Chern et al. (2025) [1137] utilized t-SNE for visualizing metal defect classification in deep learning models, improving interpretability in YOLO-based defect detection frameworks. Their study showed how t-SNE enhances the understanding of feature similarities among defect classes, leading to more refined model improvements. A similar approach was adopted by Li et al. (2025) [1138] in the field of food safety, where t-SNE was applied to olfactory sensor data to analyze aflatoxin B1 contamination in wheat. By employing t-SNE for dimensionality reduction, the researchers effectively visualized sensor response variations, demonstrating the method’s utility in complex chemical data analysis. In another domain, Singh and Singh (2025) [1139] developed a hybrid approach for medical image retrieval by integrating deep learning features with t-SNE. Their method showed that t-SNE enhances feature clustering, thereby improving the accuracy and efficiency of gastric image retrieval systems, which is particularly beneficial in computer-aided diagnosis applications.
Sun et al. (2025) [1142] explored the application of t-SNE in biomechanics, specifically in detecting muscle fatigue during lower limb isometric contraction tasks. Their study employed t-SNE to reduce the dimensionality of electromyography (EMG) data before applying machine learning-based classification, leading to improved performance in fatigue detection models. Meanwhile, Su et al. (2025) [1143] incorporated t-SNE into seismic fragility analysis for earth-rock dams, integrating it within a deep residual shrinkage network to enhance predictive accuracy. Their research illustrated how t-SNE, when combined with deep learning techniques, can refine the interpretation of heterogeneous material behavior under seismic loading conditions. In the biomedical domain, Yousif and Al-Sarray (2025) [1144] integrated t-SNE with spectral clustering via convex optimization to enhance breast cancer gene classification. Their work established that this combination yields superior clustering performance compared to conventional methods, contributing significantly to genomics research and precision medicine.
Park et al. (2025) [1145] assessed the clinical applicability of t-SNE in flow cytometry, specifically for hematologic malignancies. Their study compared t-SNE with UMAP in reducing high-dimensional cytometric data and concluded that t-SNE provides superior local structure preservation, which is crucial for identifying rare cell populations in clinical diagnostics. Qiao et al. (2025) [1146] used t-SNE to analyze cancer-associated fibroblasts (CAFs) in pancreatic ductal adenocarcinoma patients, identifying subclusters that exhibited distinct inflammatory gene expression patterns. This study underscored the value of t-SNE in uncovering hidden patterns in complex biological datasets, aiding in the stratification of cancer patients based on gene expression profiles. Furthermore, t-SNE has been utilized in aerospace engineering, as demonstrated by Su et al. (2025) [1143], who employed the technique in damage quantification for aircraft structures. Their study integrated t-SNE into an end-to-end deep learning framework to enhance defect localization, demonstrating how the method can improve structural health monitoring systems.
Overall, these studies collectively emphasize the versatility of t-SNE across diverse fields, ranging from biomedical sciences and geophysics to industrial defect detection and aerospace engineering. While t-SNE’s strength lies in its ability to preserve local structures in high-dimensional data, these studies also highlight its limitations, such as high computational cost and sensitivity to parameter tuning. Future research should focus on optimizing t-SNE’s efficiency while maintaining its robust visualization capabilities. By integrating t-SNE with deep learning architectures and hybrid clustering techniques, researchers can further expand its applications in fields requiring advanced data analysis and interpretation. The increasing adoption of t-SNE across disciplines highlights its ongoing relevance, making it a crucial tool for researchers handling complex, high-dimensional datasets.
Table 17.
Summary of Recent Contributions in t-SNE Literature Review
| Authors (Year) | Contribution |
|---|---|
| Rivera and Deniega (2025) [1135] | Demonstrated the efficacy of t-SNE in automating flow cytometry gating, improving cell population classification using clustering techniques such as DBSCAN and PCA. |
| Chang (2025) [1136] | Provided a survey of dimensionality reduction techniques, analyzing the strengths and weaknesses of t-SNE compared to PCA and UMAP, emphasizing its performance on non-linear data distributions. |
| Chern et al. (2025) [1137] | Applied t-SNE for visualizing metal defect classification in YOLO-based deep learning models, enhancing interpretability in industrial defect detection. |
| Li et al. (2025) [1138] | Utilized t-SNE for olfactory sensor data analysis in detecting aflatoxin B1 contamination in wheat, demonstrating its utility in chemical data visualization. |
| Singh and Singh (2025) [1139] | Developed a hybrid medical image retrieval approach by integrating deep learning features with t-SNE, improving clustering and accuracy in gastric image retrieval systems. |
| Sun et al. (2025) [1142] | Investigated t-SNE’s application in biomechanics, reducing the dimensionality of electromyography (EMG) data for improved muscle fatigue classification. |
| Su et al. (2025) [1143] | Incorporated t-SNE in seismic fragility analysis of earth-rock dams, enhancing predictive accuracy when integrated into a deep residual shrinkage network. |
| Yousif and Al-Sarray (2025) [1144] | Combined t-SNE with spectral clustering via convex optimization for breast cancer gene classification, achieving superior clustering performance over conventional methods. |
| Park et al. (2025) [1145] | Assessed the use of t-SNE in flow cytometry for hematologic malignancies, highlighting its superiority in preserving local structures compared to UMAP. |
| Qiao et al. (2025) [1146] | Applied t-SNE to analyze cancer-associated fibroblasts (CAFs) in pancreatic ductal adenocarcinoma, identifying gene expression subclusters for patient stratification. |
| Su et al. (2025) [1143] | Employed t-SNE for damage quantification in aircraft structures, integrating it into a deep learning framework to enhance structural health monitoring. |
16.1.7.3 Mathematical Analysis of t-Distributed Stochastic Neighbor Embedding
The t-distributed stochastic neighbor embedding (t-SNE) algorithm, developed by Laurens van der Maaten and Geoffrey Hinton, is a nonlinear dimensionality reduction technique particularly well-suited for visualizing high-dimensional datasets in lower dimensions (typically 2D or 3D). At its core, t-SNE aims to preserve the local structure of data points by modeling pairwise similarities in both high-dimensional and low-dimensional spaces and minimizing the discrepancy between these similarities. The method builds upon Stochastic Neighbor Embedding (SNE) by incorporating a Student’s t-distribution with a single degree of freedom (i.e., a Cauchy distribution) as the low-dimensional similarity function, significantly mitigating the crowding problem of SNE. The mathematical formulation of t-SNE is highly intricate and involves defining probability distributions over pairwise relationships, constructing a cost function based on Kullback-Leibler (KL) divergence, and employing gradient-based optimization methods such as gradient descent to find an embedding that best preserves local structures.
Constructing the High-Dimensional Probability Distribution
Let be a set of N data points in a high-dimensional space of dimension D. We define a conditional probability distribution that represents the similarity between points and based on a Gaussian distribution centered at . The probability that is a neighbor of is given by:
where is the perplexity-dependent bandwidth parameter for point , which controls how much influence distant points have on similarity measures.
Figure 152.
T-SNE representation of word embeddings derived from 19th-century literary texts. Image Credit: By Siobhán Grayson, CC BY-SA 4.0, https://commons.wikimedia.org/w/index.php?curid=64541584
Figure 152.
T-SNE representation of word embeddings derived from 19th-century literary texts. Image Credit: By Siobhán Grayson, CC BY-SA 4.0, https://commons.wikimedia.org/w/index.php?curid=64541584
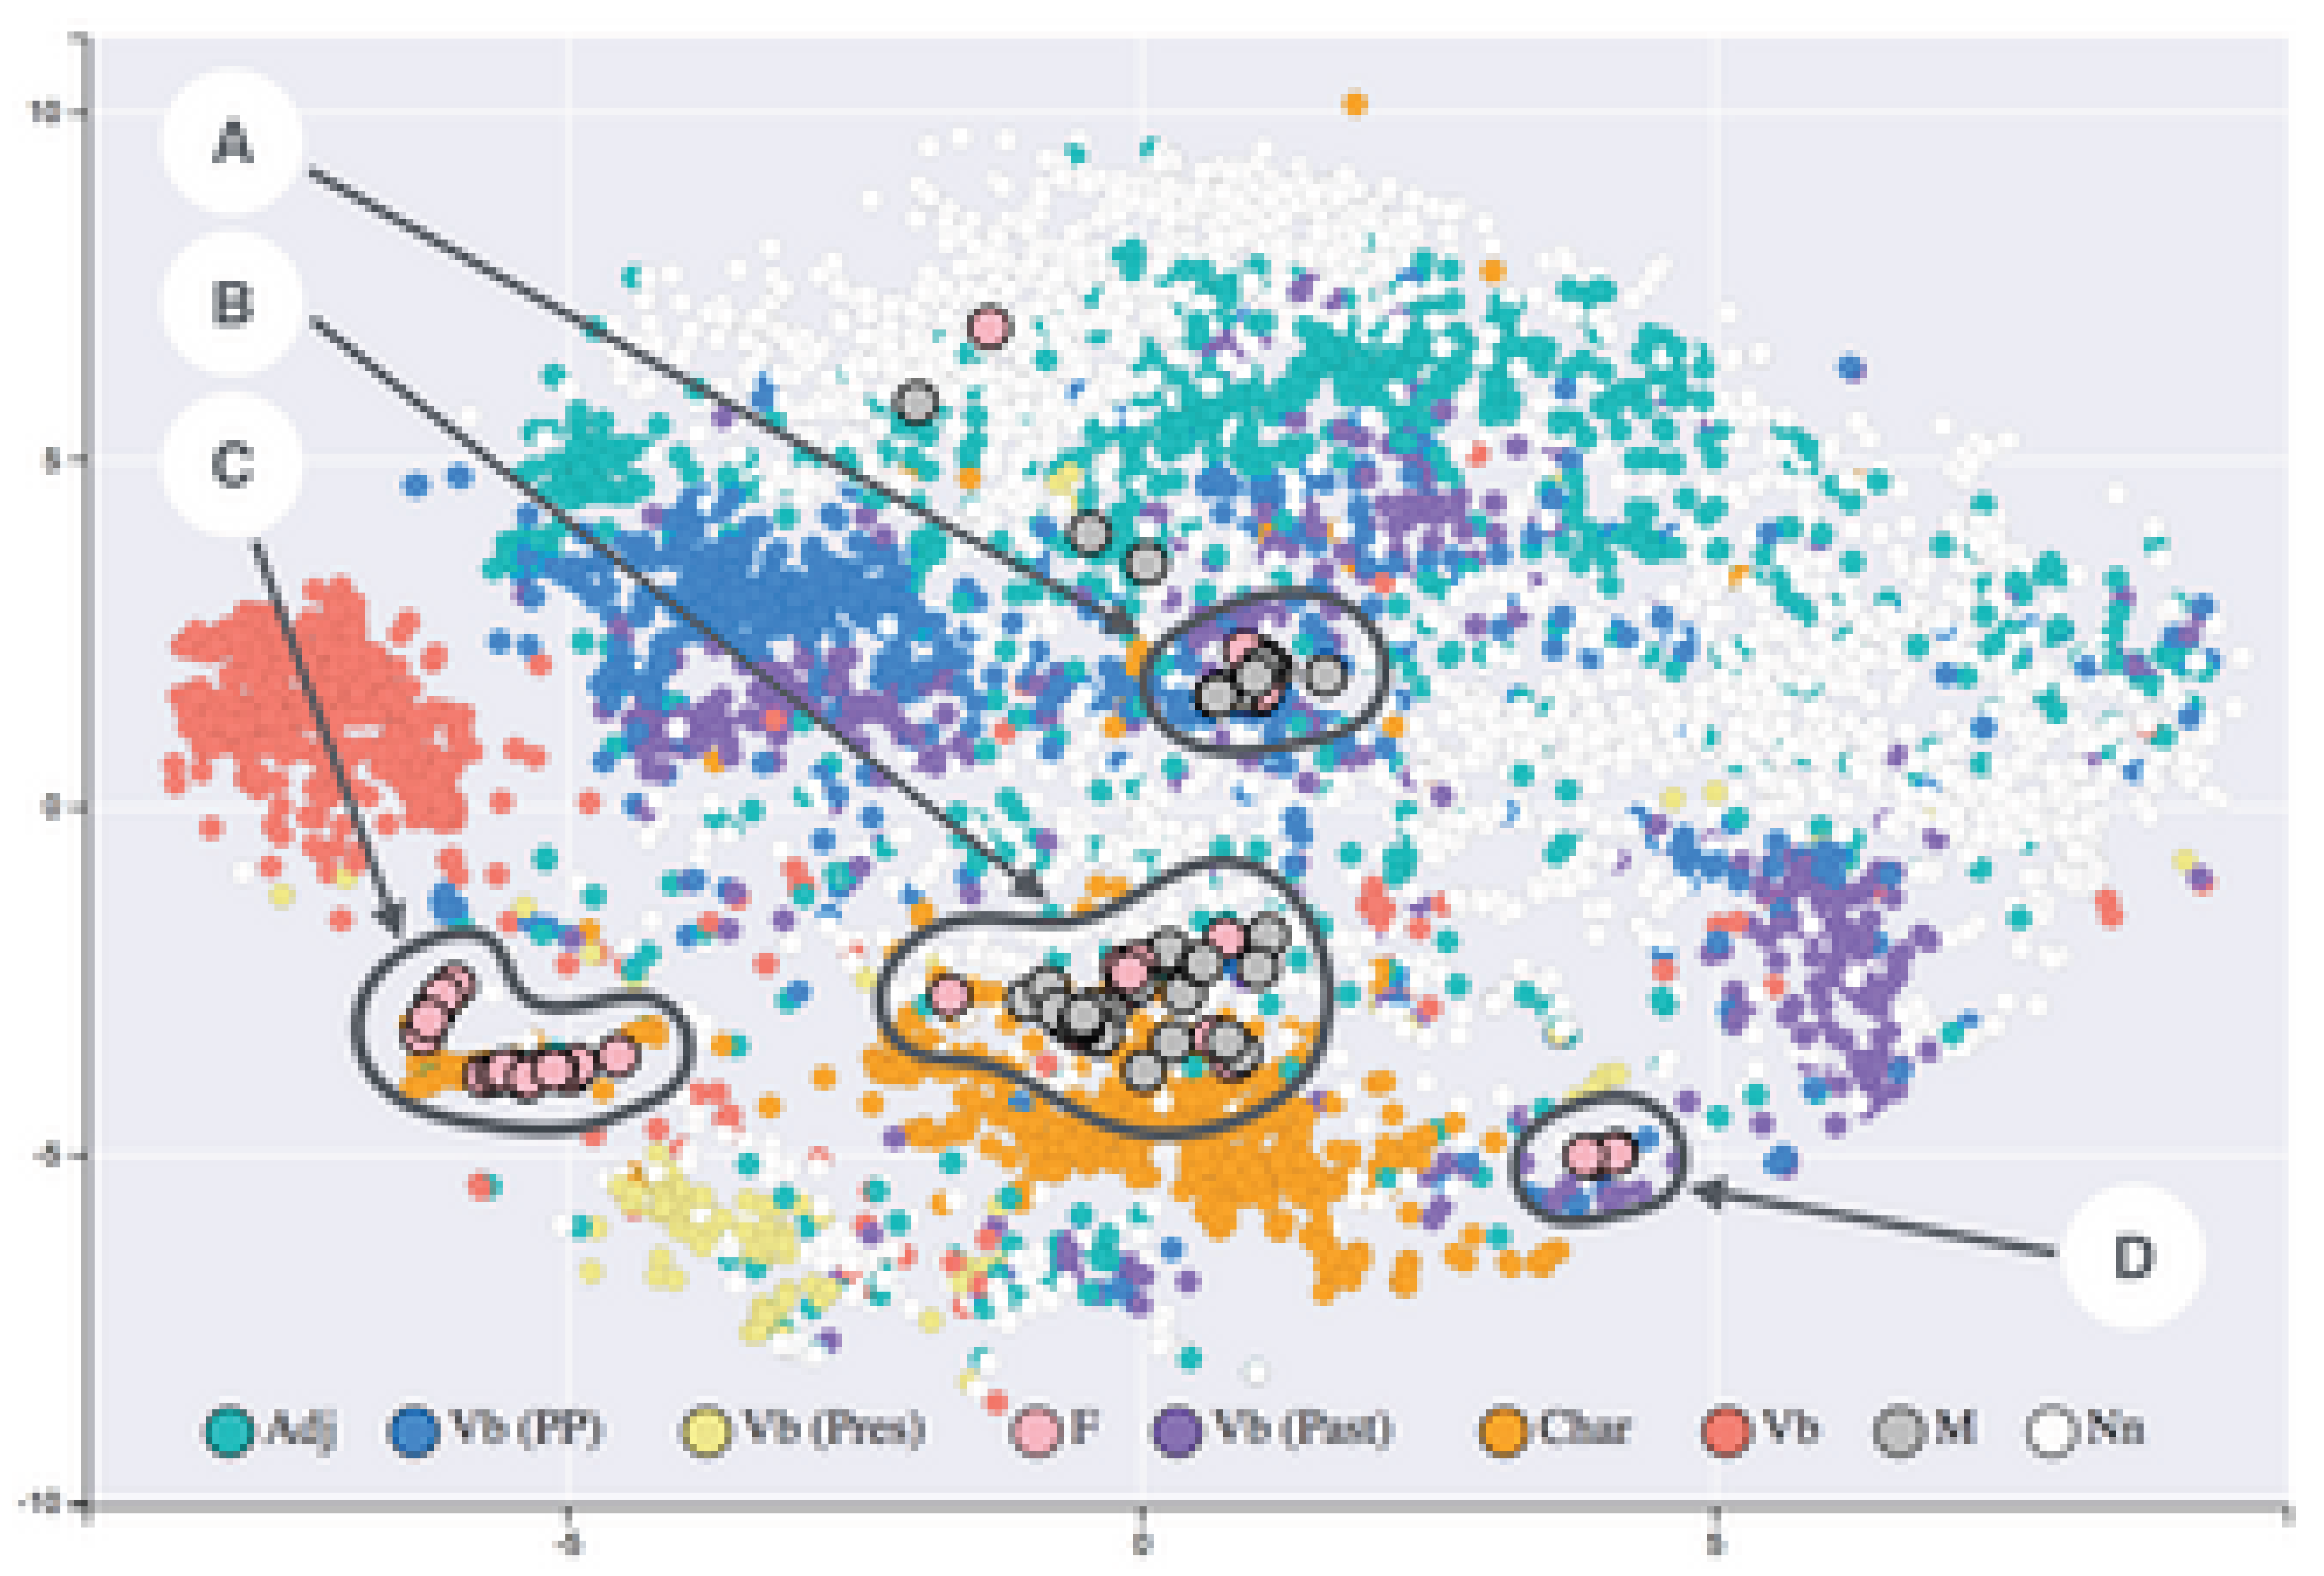
Figure 153.
T-SNE embeddings of MNIST dataset. Image Credit: By Kyle McDonald - https://www.flickr.com/photos/kylemcdonald/26620503329/, CC BY 2.0, https://commons.wikimedia.org/w/index.php?curid=115726949
Figure 153.
T-SNE embeddings of MNIST dataset. Image Credit: By Kyle McDonald - https://www.flickr.com/photos/kylemcdonald/26620503329/, CC BY 2.0, https://commons.wikimedia.org/w/index.php?curid=115726949
The perplexity, denoted as , is defined as:
where is the Shannon entropy of the probability distribution:
We then symmetrize these conditional probabilities to obtain a symmetric joint probability distribution:
This ensures that , making optimization easier and avoiding directed relationships between points.
Constructing the Low-Dimensional Probability Distribution
We now define a probability distribution in the lower-dimensional space (typically 2D or 3D) with corresponding mapped points (where ). Instead of a Gaussian kernel, t-SNE employs a Student’s t-distribution with one degree of freedom (a Cauchy distribution) to measure similarities:
This choice of the t-distribution helps mitigate the crowding problem, where points in high-dimensional space that are moderately distant tend to collapse together in low-dimensional space when using Gaussian similarities.
The Kullback-Leibler Divergence Cost Function
To ensure that the probability distributions and match as closely as possible, we minimize the Kullback-Leibler (KL) divergence, which measures how much information is lost when using to approximate :
This function is minimized using gradient descent, where the gradient with respect to each low-dimensional point is given by:
Optimization Using Momentum-Based Gradient Descent
To find an optimal configuration of points in the lower-dimensional space, we iteratively update using an adaptive learning rate and a momentum term to prevent getting stuck in local minima:
where is the learning rate, is the momentum coefficient, and represents positions at different iterations.
In summary, t-SNE is a powerful, highly nonlinear technique for dimensionality reduction that excels at visualizing high-dimensional data while preserving local structures. Its formulation relies on constructing two probability distributions, using a t-distribution kernel, and optimizing the KL divergence cost function through gradient descent. However, due to its computational complexity, improvements such as Barnes-Hut t-SNE and FIt-SNE have been developed for large datasets.
16.1.8. Locally Linear Embedding (LLE)
16.1.8.1 Literature Review of Locally Linear Embedding (LLE)
Locally Linear Embedding (LLE), introduced by Roweis and Saul (2000) [1043], is a nonlinear dimensionality reduction method that aims to preserve the local geometric properties of high-dimensional data while embedding it into a lower-dimensional space. The core idea behind LLE is to represent each data point as a linear combination of its nearest neighbors and then determine the low-dimensional representation that best preserves these local linear reconstructions. Unlike methods such as Principal Component Analysis (PCA) or Multidimensional Scaling (MDS), LLE does not assume a global linear structure but instead relies on local affine invariances to extract meaningful low-dimensional embeddings. Saul and Roweis (2000) [1147] later provided an in-depth mathematical exposition of the LLE algorithm, detailing its optimization formulation and demonstrating its capability to uncover nonlinear manifold structures. Their work emphasized that LLE effectively preserves local symmetries without requiring an explicit parametrization of the data manifold, thus making it suitable for a wide range of applications in machine learning and data analysis.
Following the introduction of LLE, Polito and Perona (2001) [1148] extended its application to the problem of clustering and dimensionality reduction, demonstrating that LLE could naturally group data points based on their intrinsic geometric properties. Their study highlighted the algorithm’s ability to perform soft clustering, where different regions of the embedded space correspond to distinct clusters in the high-dimensional space. This property is particularly useful in vision tasks where the underlying data often exhibit complex nonlinear structures. Zhang and Zha (2004) [1150] proposed an alternative approach to nonlinear dimensionality reduction known as Local Tangent Space Alignment (LTSA), which sought to align local tangent spaces rather than simply preserving locally linear relationships. By focusing on the consistency of local tangent approximations, LTSA addressed certain limitations of LLE, particularly its sensitivity to variations in neighborhood density. LTSA improved the quality of embeddings by ensuring a more faithful reconstruction of the global manifold structure, thereby making it a competitive alternative to LLE for high-dimensional data analysis.
Further refinements to LLE were made by Donoho and Grimes (2003) [1151], who introduced Hessian Eigenmaps as a variation of LLE that utilized Hessian-based quadratic forms to better capture local curvature information. Their work showed that Hessian Eigenmaps could outperform standard LLE in cases where the data exhibited significant variations in local density, thereby reducing distortion in the learned embeddings. Another modification, introduced by Zhang and Wang (2006) [1152], was the development of Modified Locally Linear Embedding (MLLE), which incorporated multiple weights in each neighborhood to address issues related to the conditioning of the local weight matrix. The authors demonstrated that by introducing multiple weight constraints, MLLE produced embeddings that were less prone to numerical instability, thus leading to improved robustness and consistency in the low-dimensional representations. These advancements collectively enhanced the stability and general applicability of LLE-based methods, reinforcing their utility in real-world machine learning tasks.
Beyond theoretical refinements, LLE found applications in natural language processing, where Liang (2005) [1153] explored its role in semi-supervised learning. By leveraging the geometric structure of unlabeled data, LLE facilitated the discovery of meaningful feature representations, which proved useful in learning linguistic patterns with limited labeled samples. Coates and Ng (2012) [1154] provided a broader perspective on feature learning by comparing LLE with other unsupervised learning techniques such as K-means clustering. Their study examined the strengths and weaknesses of LLE in the context of automatic feature extraction, highlighting its capacity to learn meaningful data representations without explicit supervision. These contributions underscored the versatility of LLE and its relevance across different domains, including computer vision, speech processing, and text analysis.
In the broader context of feature extraction and representation learning, Hyvärinen and Oja (2000) [1155] explored Independent Component Analysis (ICA) as an alternative method for learning structured representations of high-dimensional data. While ICA seeks to identify statistically independent components, LLE preserves local geometric relationships, making them complementary approaches to dimensionality reduction. Lee et al. (2006) [1156] further advanced the study of feature learning by developing efficient sparse coding algorithms, which provided insights into the underlying structures of data representations. Their work discussed the differences between sparse coding techniques and manifold learning approaches such as LLE, emphasizing the advantages of sparsity constraints in generating interpretable features. Collectively, these contributions illustrate the ongoing evolution of nonlinear dimensionality reduction techniques, with LLE serving as a foundational method that continues to inspire research in machine learning and data science.
Table 18.
Summary of Contributions in Locally Linear Embedding (LLE)
| Authors (Year) | Contribution |
| Roweis and Saul (2000) [1043] | Introduced Locally Linear Embedding (LLE), a nonlinear dimensionality reduction method that preserves local geometric properties while embedding high-dimensional data into a lower-dimensional space. LLE represents each data point as a linear combination of its nearest neighbors and determines an embedding that best preserves these local reconstructions. |
| Saul and Roweis (2000) [1147] | Provided an in-depth mathematical exposition of the LLE algorithm, detailing its optimization formulation and demonstrating its effectiveness in uncovering nonlinear manifold structures without requiring explicit parametrization of the data manifold. |
| Polito and Perona (2001) [1148] | Extended LLE to clustering and dimensionality reduction, showing that LLE naturally groups data points based on intrinsic geometric properties, allowing for soft clustering useful in vision tasks. |
| Zhang and Zha (2004) [1150] | Proposed Local Tangent Space Alignment (LTSA), which aligns local tangent spaces rather than preserving local linear relationships, addressing LLE’s sensitivity to variations in neighborhood density and improving global manifold reconstruction. |
| Donoho and Grimes (2003) [1151] | Introduced Hessian Eigenmaps, a variation of LLE utilizing Hessian-based quadratic forms to capture local curvature, reducing distortion in embeddings for data with significant variations in local density. |
| Zhang and Wang (2006) [1152] | Developed Modified Locally Linear Embedding (MLLE), incorporating multiple weights in each neighborhood to improve numerical stability and robustness in low-dimensional representations. |
| Liang (2005) [1153] | Applied LLE to semi-supervised learning in natural language processing, leveraging the geometric structure of unlabeled data to discover meaningful feature representations. |
| Coates and Ng (2012) [1154] | Compared LLE with other unsupervised learning techniques, such as K-means clustering, highlighting LLE’s strengths and weaknesses in automatic feature extraction and representation learning. |
| Hyvärinen and Oja (2000) [1155] | Explored Independent Component Analysis (ICA) as an alternative method for structured representation learning, contrasting ICA’s focus on statistical independence with LLE’s preservation of local geometric relationships. |
| Lee et al. (2006) [1156] | Developed efficient sparse coding algorithms, discussing differences between sparse coding techniques and manifold learning approaches like LLE, emphasizing the advantages of sparsity constraints in generating interpretable features. |
16.1.8.2 Recent Literature Review of Locally Linear Embedding (LLE)
Locally Linear Embedding (LLE) has been widely studied in recent years, finding applications in diverse fields such as tourism analysis, machine learning, geophysics, remote sensing, and industrial diagnostics. Yang et al. (2025) [1157] utilized LLE in the domain of international tourism competitiveness, where they integrated it with an entropy-TOPSIS and GRA model to analyze city-level data. By leveraging the ability of LLE to uncover non-linear structures in high-dimensional spaces, they were able to enhance the ranking system for assessing tourism competitiveness, which would have been difficult using traditional linear techniques. Wang et al. (2025) [1158] introduced a hybrid model that integrates LLE with Transformer and LightGBM to predict the thermal conductivity of natural rock materials, a crucial parameter for geothermal energy applications. In their study, LLE was used to perform dimensionality reduction, allowing the Transformer model to better capture latent structural patterns in the data. The combination of these methods led to improved prediction accuracy, highlighting the role of LLE in optimizing feature selection for complex geophysical modeling. Jin et al. (2025) [1159] proposed an improved version of LLE called Neighbor-Adapted LLE (NALLE) for synthetic aperture radar (SAR) image processing. Their model effectively captured the structural properties of SAR images, facilitating zero-shot learning, where models are trained without requiring large labeled datasets. By adapting LLE to work efficiently in image processing tasks, they demonstrated its applicability in remote sensing, particularly for classifying maritime objects.
In the field of optimization and algorithmic advancements, Li et al. (2024) [1160] proposed a novel variation of LLE that modifies its original L2 norm-based distance metric using the Ali Baba and The Forty Thieves Algorithm, an optimization technique inspired by metaheuristics. This modification improved LLE’s computational efficiency while maintaining accuracy in capturing data manifold structures. Similarly, Jafari et al. (2025) [1161] provided an extensive review of LLE and its variants in machine learning, emphasizing their role in feature extraction, non-linear dimensionality reduction, and data visualization. Their work serves as a valuable resource for understanding the theoretical and practical developments of LLE, particularly in the context of biological data analysis and big data applications. Additionally, Zhou et al. (2025) [1162] demonstrated the practical application of LLE in nondestructive testing (NDT) of thermal barrier coatings. Their study showed that LLE could extract useful features from terahertz imaging data, significantly improving the accuracy of stress detection in high-temperature material coatings.
Beyond scientific and industrial applications, LLE has been successfully employed in engineering diagnostics and predictive maintenance. Dou et al. (2024) [1164] proposed an LLE-based method for detecting faults in high-speed train traction systems. By transforming high-dimensional sensor data into a lower-dimensional representation, LLE allowed for the early detection of system failures, ensuring the reliability and safety of train operations. Similarly, Bagherzadeh et al. (2021) [1165] combined LLE with K-means clustering to optimize test case prioritization in software testing. Their method improved the efficiency of defect detection in software systems, reducing testing costs and accelerating the debugging process. Liu et al. (2025) [1166] proposed an intelligent recognition algorithm for analyzing substation secondary wiring diagrams using a denoised variant of LLE (D-LLE). Their approach enhanced the accuracy of connection identification in complex electrical circuits, improving power system automation and maintenance.
These studies collectively illustrate the versatility and adaptability of LLE in a wide range of fields, from fundamental algorithmic research to practical industrial applications. The continuous improvements and novel adaptations of LLE, such as the development of Neighbor-Adapted LLE for SAR images, its integration with Transformer models for geothermal applications, and its optimization using heuristic algorithms, demonstrate its evolving role in modern data science. The effectiveness of LLE in dimensionality reduction, feature extraction, and manifold learning underscores its significance in handling high-dimensional data across diverse disciplines. Whether in tourism, energy modeling, material testing, fault detection, or machine learning, LLE continues to be a powerful tool for solving complex, non-linear problems, paving the way for future advancements in data-driven decision-making.
Table 19.
Summary of Recent Contributions in Locally Linear Embedding (LLE)
| Authors (Year) | Contribution |
| Yang et al. (2025) [1157] | Utilized LLE in international tourism competitiveness analysis, integrating it with entropy-TOPSIS and GRA models to enhance ranking systems for city-level data. |
| Wang et al. (2025) [1158] | Introduced a hybrid model combining LLE with Transformer and LightGBM to predict thermal conductivity of natural rock materials, improving feature selection in geothermal energy applications. |
| Jin et al. (2025) [1159] | Proposed Neighbor-Adapted LLE (NALLE) for SAR image processing, enabling zero-shot learning and improving maritime object classification in remote sensing. |
| Li et al. (2024) [1160] | Developed a novel variation of LLE using the Ali Baba and The Forty Thieves Algorithm, enhancing computational efficiency while preserving data manifold accuracy. |
| Jafari et al. (2025) [1161] | Conducted an extensive review of LLE and its variants, focusing on feature extraction, non-linear dimensionality reduction, and data visualization in biological and big data applications. |
| Zhou et al. (2025) [1162] | Applied LLE in nondestructive testing (NDT) of thermal barrier coatings, demonstrating improved feature extraction from terahertz imaging data for stress detection. |
| Dou et al. (2024) [1164] | Proposed an LLE-based method for fault detection in high-speed train traction systems, facilitating early system failure detection and enhancing train safety. |
| Bagherzadeh et al. (2021) [1165] | Combined LLE with K-means clustering for test case prioritization in software testing, improving defect detection efficiency and reducing debugging costs. |
| Liu et al. (2025) [1166] | Developed an intelligent recognition algorithm for analyzing substation secondary wiring diagrams using a denoised LLE (D-LLE) variant, enhancing power system automation and maintenance. |
16.1.8.3 Mathematical Analysis of Locally Linear Embedding (LLE)
Locally Linear Embedding (LLE) is a manifold learning technique that seeks to uncover the intrinsic geometric structure of high-dimensional data by preserving local neighborhoods. It assumes that the data lies on or near a low-dimensional manifold embedded within a high-dimensional space. The core idea is that each data point and its nearest neighbors lie on or near a locally linear patch of the manifold. Thus, LLE constructs a low-dimensional embedding that preserves these local linear relationships. To achieve this, LLE follows three key steps: (1) finding nearest neighbors, (2) computing linear reconstruction weights, and (3) computing the low-dimensional embedding. Below, we describe these steps in an extremely rigorous, highly mathematical, and very detailed manner with maximal equations and derivations.
Step 1: Finding Nearest Neighbors
Given a dataset , where each data point belongs to (i.e., the data is embedded in a high-dimensional space of dimension D), the first step in LLE is to identify the K-nearest neighbors of each point.
Mathematically, for each point , we find a set of K nearest neighbors , such that:
where the neighbors are selected based on Euclidean distance:
Step 2: Computing Reconstruction Weights
Once the neighbors of each point are found, the next step is to compute reconstruction weights that best express each data point as a linear combination of its nearest neighbors:
The goal is to determine the weights that minimize the reconstruction error:
To ensure invariance to translations, we impose the constraint:
This leads to the local covariance matrix:
The optimal weights are obtained by solving the quadratic programming problem:
The solution is:
Step 3: Computing the Low-Dimensional Embedding
After computing the weights , we find low-dimensional coordinates such that:
This leads to the quadratic cost function:
Rewriting in matrix form:
where is the embedding cost matrix. The final embedding is obtained by solving:
The final solution is:
This ensures that the local linear relationships are preserved while capturing the global structure of the data.
16.1.8.4 Python Code to Generate Figure 154 Illustrating the Locally Linear Embedding (LLE) Applied to a Swiss Roll Dataset
The Python code below produces the Figure 154 illustrating the Locally Linear Embedding (LLE) applied to a Swiss roll dataset.
Figure 154.
Locally Linear Embedding (LLE) applied to a Swiss roll dataset. Left: original 3D Swiss roll. Right: 2D LLE embedding preserving local structure
Figure 154.
Locally Linear Embedding (LLE) applied to a Swiss roll dataset. Left: original 3D Swiss roll. Right: 2D LLE embedding preserving local structure
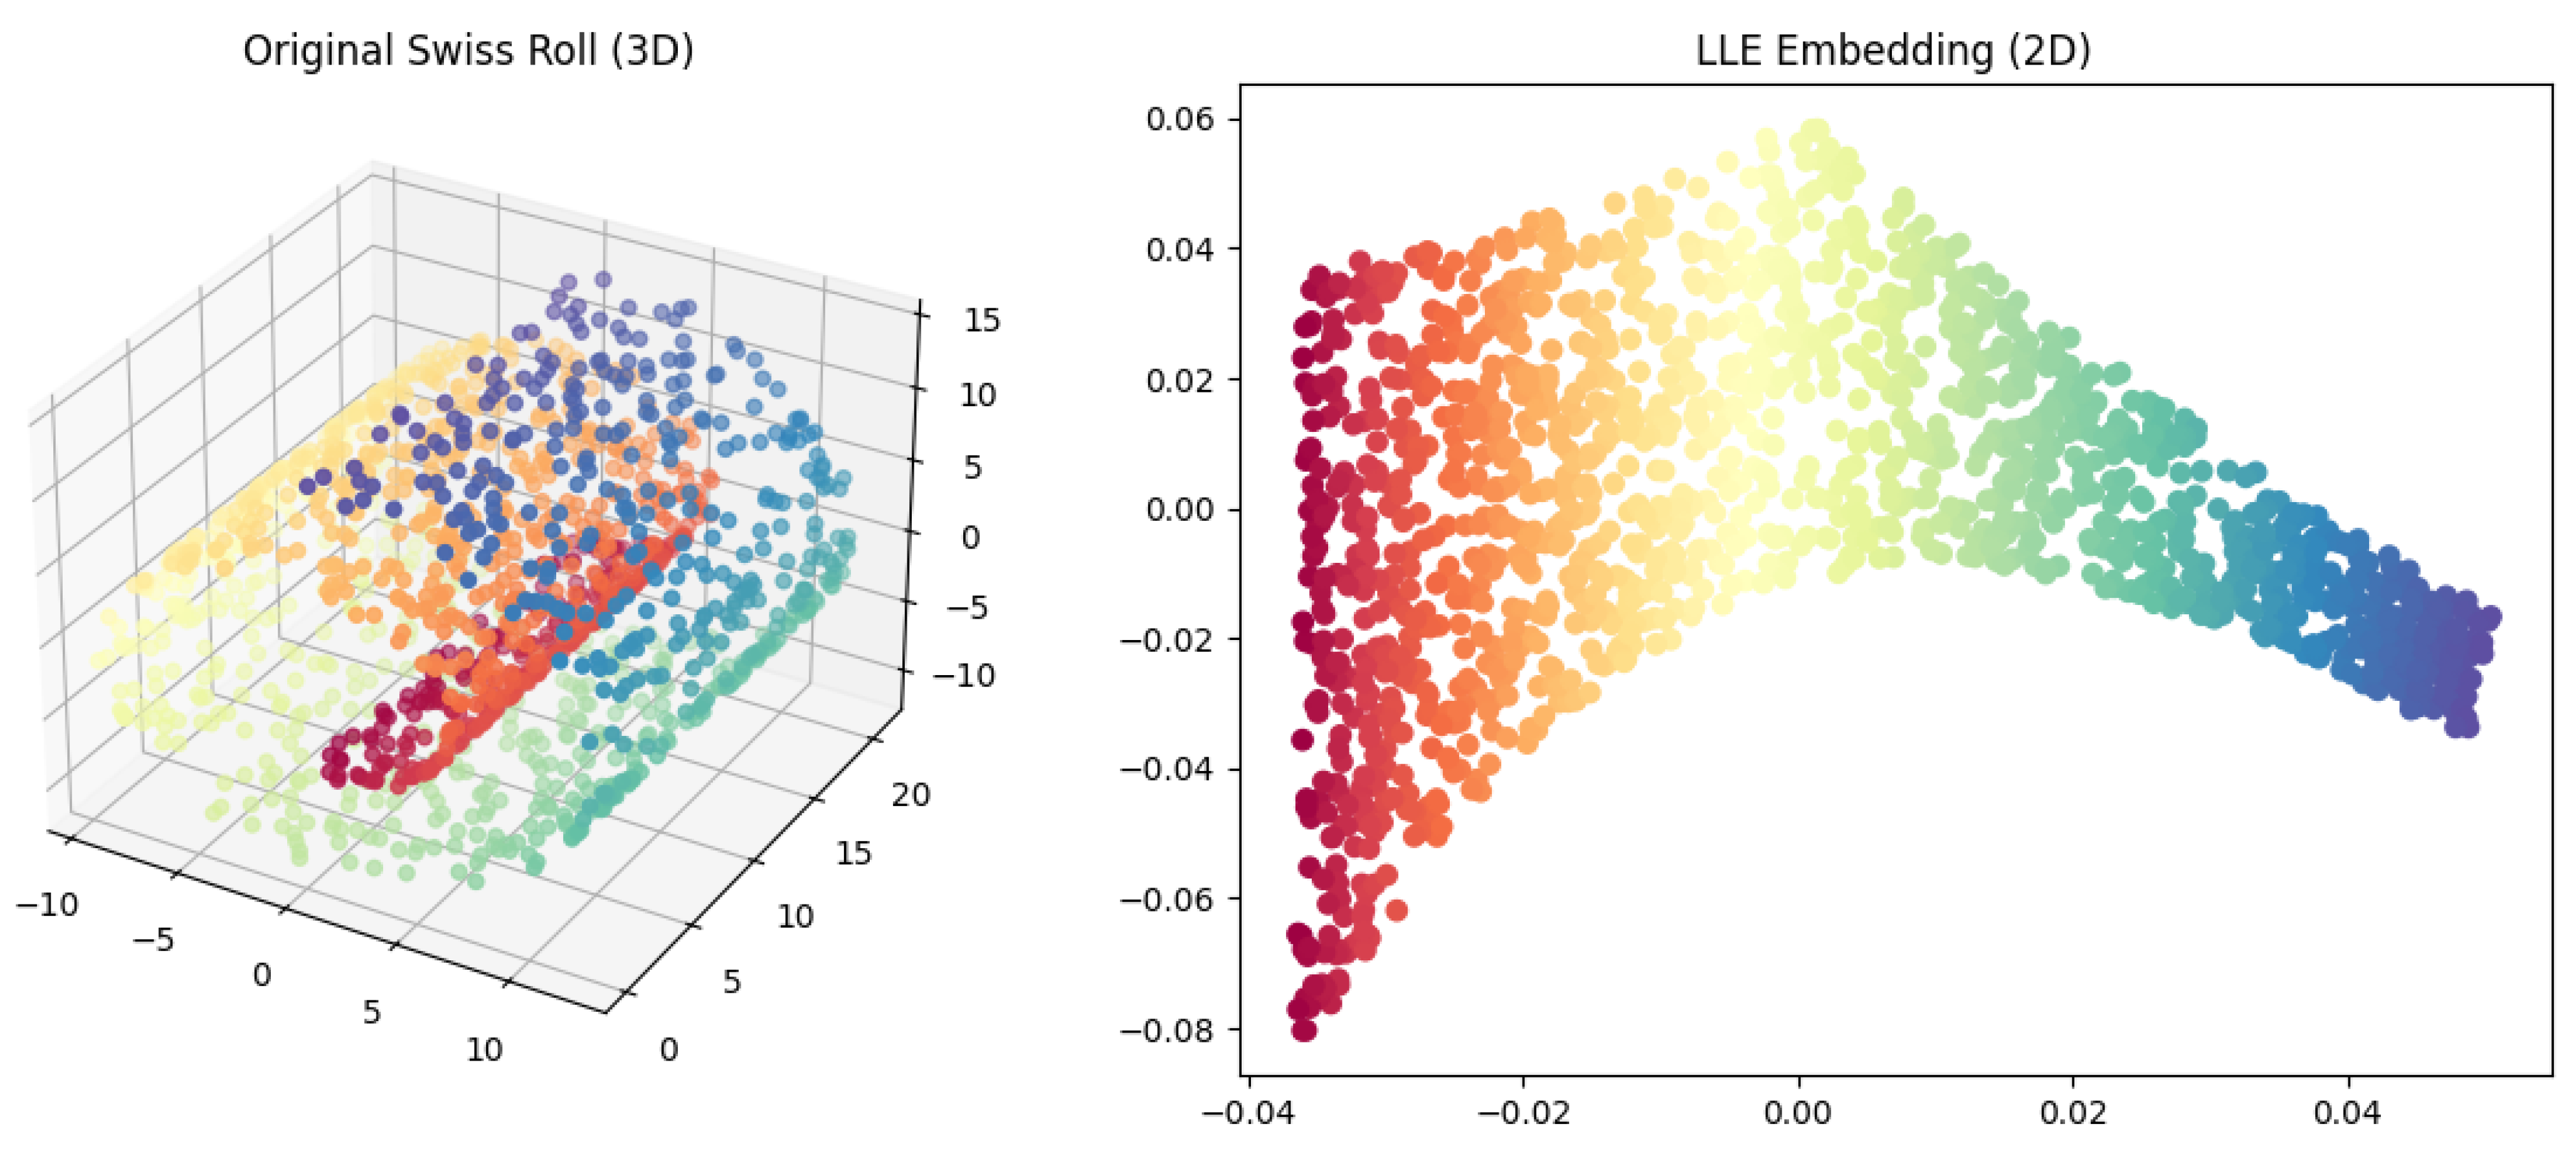
16.1.9. Independent Component Analysis (ICA)
16.1.9.1 Literature Review of Independent Component Analysis (ICA)
Independent Component Analysis (ICA) has developed into a powerful technique in signal processing, statistics, and machine learning. Its theoretical foundations were laid by Comon (1994) [1167], who rigorously introduced the concept of ICA as a method for blind source separation. He provided a detailed mathematical framework, demonstrating how statistical independence, rather than uncorrelatedness, is the key criterion for successful source separation. By linking ICA with higher-order statistics, particularly kurtosis, he established a formal justification for ICA as a generalization of Principal Component Analysis (PCA). This work also introduced the concept of mutual information minimization as a means of achieving independence, offering a theoretical perspective that would influence many later algorithms. Around the same time, Jutten and Herault (1991) [1168] developed an adaptive learning algorithm based on neuromorphic principles, which laid the groundwork for ICA as an iterative computational approach. Their method used nonlinear functions to iteratively adjust the weight matrix, leveraging higher-order statistical moments to achieve source separation, marking one of the first practical implementations of ICA in neural networks.
A major breakthrough came with the development of computationally efficient ICA algorithms, notably the FastICA method by Hyvärinen and Oja (1997) [1169]. They formulated an elegant fixed-point approach that significantly improved the convergence speed of ICA. Instead of using slow gradient-based updates, their method maximized non-Gaussianity using a negentropy approximation, which enabled rapid convergence to independent components. This algorithm incorporated a preprocessing step involving PCA-based whitening, which decorrelated the observed signals before ICA extraction, further enhancing stability and efficiency. In parallel, Bell and Sejnowski (1995) [1044] introduced an information-theoretic approach to ICA, deriving the Infomax algorithm based on maximum likelihood estimation (MLE). Their work established that maximizing the entropy of the output neurons under a nonlinear activation function naturally leads to ICA, providing a fundamental link between ICA and unsupervised neural learning. This insight positioned ICA as a biologically plausible mechanism for sensory processing, particularly in neural coding and vision research.
Several alternative approaches to ICA were also developed, focusing on different statistical principles. Cardoso and Souloumiac (1993) [1170] introduced the JADE algorithm, which employed joint approximate diagonalization of eigenmatrices to separate independent sources. By exploiting fourth-order cumulants, their method avoided gradient descent altogether, leading to a robust and efficient separation procedure, especially for overdetermined mixtures. Meanwhile, Amari et al. (1995) [1171] introduced an ICA algorithm based on natural gradient learning, drawing on concepts from information geometry. They demonstrated that a Riemannian metric on the parameter space of ICA solutions enables more efficient optimization, leading to faster convergence without suffering from the plateaus and slowdowns of traditional gradient descent methods. This information-geometric perspective provided deeper insights into the structure of the ICA optimization landscape and inspired further advances in adaptive ICA algorithms.
A significant refinement of ICA occurred with the extension of Infomax to handle both sub-Gaussian and super-Gaussian source distributions by Lee et al. (1999) [1172]. Their method introduced a nonlinear adaptive function that dynamically adjusted based on the statistical properties of the data, making ICA applicable to a broader range of real-world signals. This extension proved particularly useful in biomedical applications, where sources often exhibit mixed statistical distributions. Around the same time, Pham and Garat (1997) [1173] presented a quasi-maximum likelihood estimation (QMLE) approach to ICA, rigorously formulating the problem as an optimization task within the framework of statistical estimation theory. Their work provided a more systematic theoretical foundation for ICA and improved its robustness in practical scenarios, particularly when dealing with noisy or low-sample data environments.
More recent developments in ICA have explored probabilistic and Bayesian approaches. Højen-Sørensen et al. (2002) [1174] introduced a variational Bayesian framework for ICA, using mean-field approximations to estimate the posterior distribution of independent components. This approach allowed ICA to be extended into a probabilistic setting, making it more robust in the presence of noise and missing data. Their work was particularly influential in applications requiring uncertainty quantification, such as brain imaging and financial modeling. In addition to these algorithmic advancements, Stone (2004) [1175] provided a comprehensive textbook that rigorously detailed the mathematical principles underlying ICA. His work systematically explored the relationship between ICA, mutual information, higher-order statistics, and practical signal processing applications, serving as an authoritative reference for both theoretical research and practical implementation. Together, these contributions have solidified ICA as a fundamental tool in signal processing, machine learning, and neuroscience, with ongoing developments continuing to refine its theoretical underpinnings and expand its applications.
Table 20.
Summary of Contributions in Independent Component Analysis (ICA) Literature
| Authors (Year) | Contribution |
| Comon (1994) [1167] | Established the theoretical framework of ICA, emphasizing statistical independence over uncorrelatedness for blind source separation. Introduced mutual information minimization as a means to achieve independence and linked ICA with higher-order statistics, particularly kurtosis. |
| Jutten and Herault (1991) [1168] | Developed an adaptive learning algorithm for ICA using neuromorphic principles. Introduced nonlinear functions to iteratively adjust the weight matrix based on higher-order statistical moments. This work laid the foundation for iterative computational approaches in ICA. |
| Hyvärinen and Oja (1997) [1169] | Proposed the FastICA algorithm, a fixed-point method maximizing non-Gaussianity using negentropy approximation. Improved convergence speed and incorporated PCA-based whitening for signal decorrelation. |
| Bell and Sejnowski (1995) [1044] | Developed the Infomax algorithm using maximum likelihood estimation, linking ICA to entropy maximization in neural networks. Provided a biological perspective on ICA and its role in sensory processing. |
| Cardoso and Souloumiac (1993) [1170] | Introduced the JADE algorithm, employing joint approximate diagonalization of eigenmatrices to separate independent sources. Used fourth-order cumulants to achieve robust and efficient source separation. |
| Amari et al. (1995) [1171] | Developed an ICA algorithm based on natural gradient learning, utilizing a Riemannian metric for efficient optimization. Provided an information-geometric perspective, improving convergence speed. |
| Lee et al. (1999) [1172] | Extended the Infomax algorithm to handle both sub-Gaussian and super-Gaussian source distributions using a nonlinear adaptive function. Enhanced ICA applicability to biomedical signals with mixed statistical distributions. |
| Pham and Garat (1997) [1173] | Introduced a quasi-maximum likelihood estimation (QMLE) approach to ICA, formulating it as an optimization problem within statistical estimation theory. Improved robustness in noisy and low-sample data environments. |
| Højen-Sørensen et al. (2002) [1174] | Proposed a variational Bayesian framework for ICA using mean-field approximations. Enabled ICA to incorporate uncertainty quantification and handle missing data, extending its robustness. |
| Stone (2004) [1175] | Authored a comprehensive textbook on ICA, detailing its mathematical principles, mutual information, higher-order statistics, and applications in signal processing and machine learning. Provided a systematic exploration of ICA’s theoretical and practical aspects. |
16.1.9.2 Recent Literature Review of Independent Component Analysis (ICA)
Independent Component Analysis (ICA) has found diverse applications across multiple domains, ranging from neuroscience and medical imaging to financial modeling and power systems. Behzadfar et al. (2025) [1176] introduced a novel multi-frequency ICA-based approach to process functional MRI (fMRI) data. Their study focused on extracting meaningful components while effectively removing non-gray matter signals, thereby refining the accuracy of frequency-based brain imaging. The method demonstrated improved signal clarity and more precise voxel-wise frequency difference estimation, making it a valuable tool in neuroimaging research. Similarly, Eierud et al. (2025) [1177] developed the NeuroMark PET ICA framework, which employs ICA to decompose whole-brain PET signals into distinct networks, aiding in the construction of multivariate molecular imaging brain atlases. This technique allows researchers to analyze complex brain connectivity patterns with greater precision, enhancing the study of neurodegenerative disorders and other neurological conditions.
Expanding ICA’s application in hydrology, Wang et al. (2025) [1178] leveraged the technique to analyze terrestrial water storage anomaly (TWSA) trends in the Yangtze River Basin. Their research identified statistically independent spatial trends within hydrological data, offering insights into climate change and its impact on water resource management. By distinguishing significant patterns from background noise, ICA facilitated a more accurate assessment of water distribution and hydrological cycles over time. Similarly, Heurtebise et al. (2025) [1179] used ICA to stabilize estimators in hydrological dataset analysis, improving the reliability of multivariate mutual information measurements. These advancements underscore ICA’s utility in environmental sciences, particularly in large-scale water resource monitoring.
In the field of computational neuroscience, Ouyang and Li (2025) [1180] developed a protocol that integrates ICA with Principal Component Analysis (PCA) for semi-automated EEG preprocessing. Their approach streamlines the removal of artifacts and enhances signal quality, making it easier for researchers to conduct large-scale EEG studies with minimal manual intervention. Zhang and Luck (2025) [1181] further explored ICA’s impact on brain-computer interfaces by assessing the effect of artifact correction on the performance of support vector machine (SVM)-based EEG decoding. Their study demonstrated that ICA-based correction significantly improved classification accuracy, reinforcing its role as a crucial preprocessing tool for neurophysiological data.
ICA has also shown promise in financial modeling and power system monitoring. Kirsten and Süssmuth (2025) [1182] applied ICA to financial time-series data, demonstrating its ability to filter noise and identify independent market-driving factors in cryptocurrency price movements. Their findings indicated that ICA, combined with ARIMA modeling, improved predictive accuracy in highly volatile market environments. Meanwhile, Jung et al. (2025) [1183] developed a hybrid fault detection system that integrates ICA with auto-associative kernel regression (AAKR) for power plant monitoring. Their model effectively isolated independent fault components, enabling more accurate anomaly detection and predictive maintenance strategies.
In signal processing and acoustic applications, Wang et al. (2025) [1184] implemented ICA for noise filtering in passive acoustic localization, particularly for underwater object detection. Their method significantly enhanced the clarity of spatial positioning signals, reducing the impact of environmental noise. Luo et al. (2025) [1185] extended ICA’s utility to brain-computer interfaces (BCIs), where they used the technique to eliminate electrical noise and enhance the transmission of neural signals. Their research demonstrated ICA’s ability to improve the reliability of noninvasive BCIs, paving the way for more accurate and responsive brain-controlled devices.
These studies collectively illustrate ICA’s versatility across disciplines, from improving medical imaging and neurophysiological data analysis to enhancing hydrological assessments, financial forecasting, and fault detection. As ICA continues to evolve, its integration with machine learning techniques and its application in multi-sensor data fusion are likely to expand, offering even greater potential for scientific and industrial advancements. Future research should focus on optimizing ICA algorithms to handle increasingly complex datasets while maintaining computational efficiency.
Table 21.
Summary of Recent Contributions in Independent Component Analysis (ICA) Literature
| Authors (Year) | Contribution |
| Behzadfar et al. (2025) [1176] | Proposed a multi-frequency ICA-based approach for fMRI data processing, enhancing component extraction and eliminating non-gray matter signals for improved frequency-based brain imaging accuracy. |
| Eierud et al. (2025) [1177] | Developed the NeuroMark PET ICA framework, enabling ICA decomposition of whole-brain PET signals into networks to construct multivariate molecular imaging brain atlases. |
| Wang et al. (2025) [1178] | Applied ICA to analyze terrestrial water storage anomaly (TWSA) trends in the Yangtze River Basin, identifying independent spatial trends and improving hydrological cycle assessments. |
| Heurtebise et al. (2025) [1179] | Utilized ICA to stabilize estimators in hydrological dataset analysis, enhancing the reliability of multivariate mutual information measurements. |
| Ouyang and Li (2025) [1180] | Integrated ICA with PCA for semi-automated EEG preprocessing, facilitating artifact removal and improving signal quality in large-scale EEG studies. |
| Zhang and Luck (2025) [1181] | Investigated ICA-based artifact correction in brain-computer interfaces, demonstrating significant improvements in SVM-based EEG decoding accuracy. |
| Kirsten and Süssmuth (2025) [1182] | Applied ICA to financial time-series data, filtering noise and identifying independent market-driving factors, enhancing cryptocurrency price prediction when combined with ARIMA modeling. |
| Jung et al. (2025) [1183] | Developed a hybrid fault detection system integrating ICA with auto-associative kernel regression (AAKR) for power plant monitoring, improving anomaly detection and predictive maintenance. |
| Wang et al. (2025) [1184] | Implemented ICA for noise filtering in passive acoustic localization, significantly enhancing underwater object detection through improved signal clarity. |
| Luo et al. (2025) [1185] | Applied ICA in brain-computer interfaces (BCIs) to eliminate electrical noise and enhance neural signal transmission, improving the reliability of noninvasive BCIs. |
16.1.9.3 Mathematical Analysis of Independent Component Analysis (ICA)
Independent Component Analysis (ICA) is a powerful statistical technique used for blind source separation (BSS), where the goal is to recover a set of statistically independent source signals from their linear mixtures without any prior information about the mixing process. Mathematically, we assume that we are given an n-dimensional observation vector , which is related to an unknown set of source signals through an unknown mixing matrix as follows:
where is the observed signal vector, is the original source vector, and is the mixing matrix that describes how the sources are combined. The objective of ICA is to estimate a demixing matrix such that the transformed signals are as statistically independent as possible:
where ideally , leading to an approximate recovery of the independent source signals. The fundamental assumption that allows ICA to work is that the source signals are statistically independent, meaning their joint probability density function (PDF) factorizes:
This assumption of statistical independence is crucial because it allows the identification of the source signals based on higher-order statistical properties, such as kurtosis and negentropy.
Furthermore, ICA relies on the non-Gaussianity of the source signals, as the central limit theorem (CLT) states that the sum of independent random variables tends toward a Gaussian distribution. Thus, if the sources were Gaussian, they could not be separated from their mixtures because Gaussian distributions are completely characterized by second-order statistics (mean and variance), and higher-order statistics would provide no additional information. To estimate the demixing matrix , we must find a transformation that maximizes the statistical independence of the recovered signals . Several measures of statistical independence exist, including kurtosis, negentropy, and mutual information, which lead to different optimization formulations of ICA. One approach is to use kurtosis, which is defined as the fourth central moment of a random variable:
A Gaussian distribution has a kurtosis of zero, while non-Gaussian distributions have nonzero kurtosis. Since ICA relies on the assumption that the sources are non-Gaussian, we can maximize the absolute value of kurtosis to obtain independent components. Another widely used measure is negentropy, which is derived from information theory and defined as:
where is the differential entropy, given by:
Since entropy measures randomness, negentropy quantifies how far a given distribution is from Gaussianity. The higher the negentropy, the more non-Gaussian the distribution, making it a useful objective function for ICA. An alternative approach is to use mutual information, which measures the statistical dependence between variables:
By minimizing mutual information, we can maximize the statistical independence of the estimated sources. In practical ICA implementations, preprocessing is often necessary to improve performance. A common preprocessing step is whitening, which ensures that the observed signals are uncorrelated and have unit variance. Whitening is achieved by first computing the covariance matrix of :
Performing an eigenvalue decomposition (EVD):
where is the matrix of eigenvectors and is the diagonal matrix of eigenvalues. The whitened signals are then computed as:
This transformation ensures that the covariance of is the identity matrix:
ICA has broad applications in signal processing, including EEG and fMRI signal separation, speech and audio processing, financial time series analysis, and image processing. It is particularly useful in solving the cocktail party problem, where multiple speakers’ voices are separated from mixed audio recordings. The mathematical foundation of ICA makes it one of the most robust techniques for blind signal separation, and its various optimization formulations offer flexibility depending on the application.
16.1.9.4 Python Code to Generate Figure 155 Illustrating the Independent Component Analysis (ICA) of Mixed Signals
The Python code below produces the Figure 155 illustrating the Independent Component Analysis (ICA) of mixed signals.
Figure 155.
Independent Component Analysis (ICA) of mixed signals. The top panel shows mixed signals, the middle panel shows true sources, and the bottom panel shows ICA recovered signals
Figure 155.
Independent Component Analysis (ICA) of mixed signals. The top panel shows mixed signals, the middle panel shows true sources, and the bottom panel shows ICA recovered signals
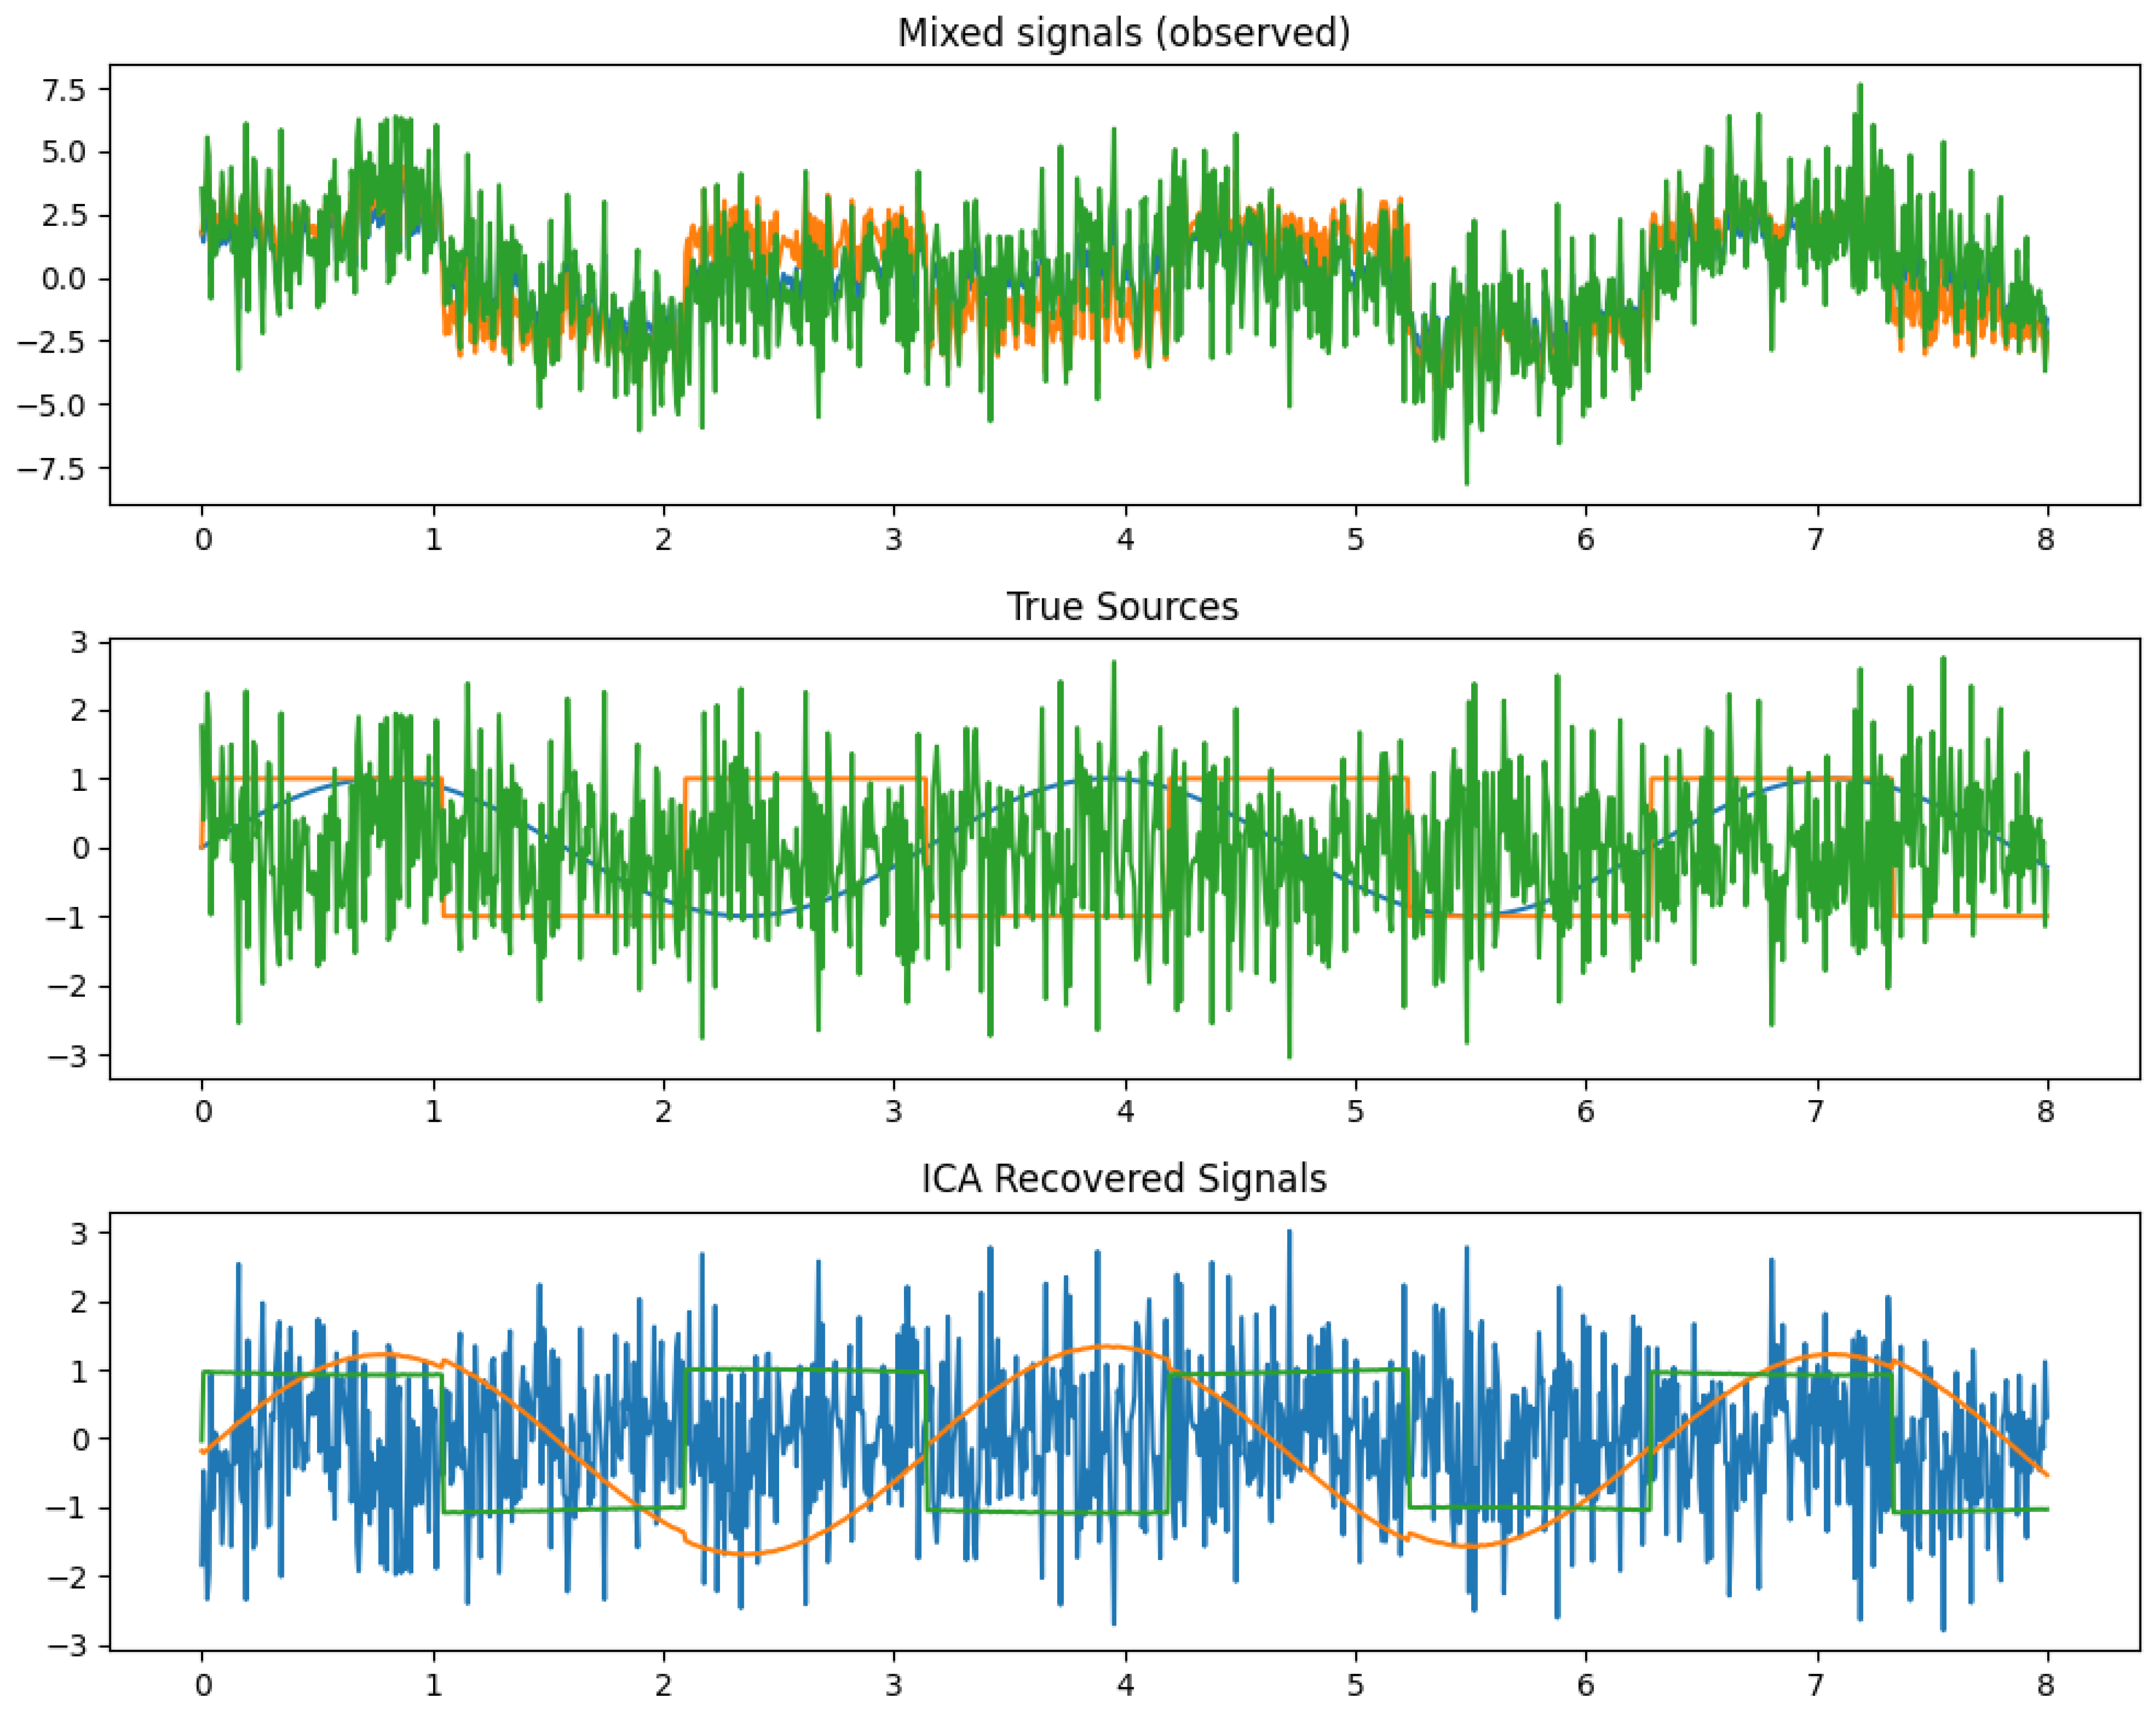
16.2. Supervised Learning
16.2.1. Literature Review of Supervised Learning
Supervised learning has been extensively studied through rigorous theoretical and empirical advancements, forming the backbone of modern machine learning. One of the foundational contributions in this domain is Vapnik (1995) [143], which introduced statistical learning theory, establishing key concepts such as the Vapnik-Chervonenkis (VC) dimension, which quantifies the capacity of a hypothesis class to shatter a given set of data points. The book also presents the principle of structural risk minimization (SRM), which provides a theoretical framework for balancing model complexity and empirical error, thereby preventing overfitting. A critical outcome of this work was the formulation of support vector machines (SVMs), which use kernel functions to transform data into higher-dimensional spaces, enabling the discovery of nonlinear decision boundaries while maintaining strong generalization guarantees. The kernel trick, introduced as a mechanism to implicitly compute inner products in high-dimensional feature spaces, remains one of the most powerful techniques in modern machine learning. Building on statistical foundations, Bishop (2006) [124] provided an extensive treatment of probabilistic models in supervised learning, with a strong emphasis on Bayesian inference. The text rigorously derives Bayesian linear regression, Gaussian processes, and probabilistic neural networks, offering a structured mathematical perspective on uncertainty quantification. The discussion of mixture models and the Expectation-Maximization (EM) algorithm in this work has had profound implications for learning in both supervised and unsupervised settings.
The field of ensemble learning has also seen significant advancements through rigorous mathematical formulations. Breiman (2001) [754] introduced the Random Forest algorithm, an ensemble method based on decision trees, and demonstrated how bootstrap aggregation (bagging) reduces variance in predictive models. The paper provided a theoretical justification for the effectiveness of decorrelating individual decision trees using random feature selection, showing that this mechanism enhances generalization. Moreover, Breiman formally defined the out-of-bag (OOB) error estimation method, an internal validation technique that provides an unbiased estimate of the model’s performance without requiring a separate validation set. Around the same time, Friedman, Hastie, and Tibshirani (2000) [1056] offered a rigorous statistical interpretation of boosting algorithms, particularly AdaBoost. Their work demonstrated that boosting can be understood as a stagewise optimization process that minimizes an exponential loss function, providing a function-space perspective on gradient boosting. By linking boosting to numerical optimization techniques, they laid the foundation for gradient boosting machines (GBMs), which remain one of the most effective supervised learning techniques today. Further theoretical contributions to boosting were made by Schapire (1990) [1058], who formally proved that weak classifiers, which perform only marginally better than random guessing, can be transformed into arbitrarily strong classifiers through the process of boosting. The paper established a precise mathematical framework for analyzing how iterative reweighting of training samples reduces error bounds, reinforcing the statistical robustness of boosting methods.
Deep learning, a subset of supervised learning, has also benefited from rigorous theoretical advancements. LeCun et al. (1998) [1055] introduced convolutional neural networks (CNNs), demonstrating their effectiveness in document recognition, particularly for handwritten digit classification in the MNIST dataset. The authors provided a mathematically rigorous derivation of the backpropagation algorithm and the gradient-based optimization techniques used in training deep networks. One of their major contributions was the concept of weight sharing, which significantly reduces the number of learnable parameters in CNNs by enforcing translational invariance in feature detection. This architecture laid the groundwork for modern deep learning-based vision systems, which have since expanded to complex image recognition tasks. More recently, Srivastava et al. (2014) [141] introduced dropout as a regularization technique for deep neural networks. The authors provided a probabilistic interpretation of dropout as an approximation to model averaging over an exponentially large ensemble of subnetworks, rigorously deriving its impact on reducing overfitting. The paper also presented empirical results demonstrating that dropout significantly improves generalization performance across a wide range of supervised learning tasks.
One of the earliest contributions to supervised learning, which laid the foundation for neural networks, was made by Rosenblatt (1958) [1057] through the introduction of the perceptron algorithm. This work rigorously proved the perceptron convergence theorem, which guarantees that if a dataset is linearly separable, the perceptron learning rule will converge to a separating hyperplane in a finite number of iterations. Although the perceptron was later shown to be limited in expressive power, particularly in its inability to solve non-linearly separable problems such as the XOR problem, it inspired the development of more advanced architectures, including multi-layer perceptrons (MLPs) and deep neural networks. Hastie, Tibshirani, and Friedman (2009) [139] provided one of the most mathematically rigorous treatments of supervised learning, covering a broad range of techniques including linear models, kernel methods, decision trees, ensemble learning, and deep learning. Their work emphasized the mathematical foundations of machine learning, particularly the bias-variance tradeoff, regularization methods such as ridge regression and Lasso, and kernelized learning methods. The authors also provided in-depth theoretical analyses of the convergence properties of various supervised learning algorithms, making their text a fundamental resource for statistical learning theory.
The optimization of deep learning models has been another area of rigorous mathematical research, with Kingma and Ba (2014) [176] introducing the Adam optimization algorithm. Their work provided a detailed mathematical derivation of Adam’s update rules, which rely on the computation of exponentially decaying moving averages of past gradients and squared gradients. The authors rigorously demonstrated how Adam effectively combines the benefits of Adagrad, which adapts learning rates based on the historical sum of squared gradients, and RMSProp, which normalizes updates using an exponentially weighted average of past squared gradients. The method has since become the default optimization algorithm for training deep neural networks, particularly due to its robustness in handling sparse gradients and noisy objective functions. Collectively, these works have profoundly shaped the landscape of supervised learning by introducing mathematically rigorous frameworks for classification, regression, deep learning, and optimization. Their theoretical contributions continue to inform modern advancements, ensuring that machine learning models remain both statistically sound and computationally efficient.
Table 22.
Summary of Contributions in Supervised Learning
| Authors (Year) | Contribution |
| Vapnik (1995) [143] | Introduced statistical learning theory, including the Vapnik-Chervonenkis (VC) dimension, structural risk minimization (SRM), and support vector machines (SVMs). Established the kernel trick for computing inner products in high-dimensional feature spaces. |
| Bishop (2006) [124] | Provided a probabilistic treatment of supervised learning, including Bayesian inference, Gaussian processes, Bayesian linear regression, and probabilistic neural networks. Discussed mixture models and the Expectation-Maximization (EM) algorithm. |
| Breiman (2001) [754] | Introduced Random Forests and bootstrap aggregation (bagging) for variance reduction. Theoretical justification of random feature selection and the out-of-bag (OOB) error estimation method. |
| Friedman, Hastie, and Tibshirani (2000) [1056] | Provided a statistical interpretation of boosting, demonstrating its connection to stagewise optimization of an exponential loss function. Established the foundation for gradient boosting machines (GBMs). |
| Schapire (1990) [1058] | Proved that weak classifiers can be transformed into strong classifiers through boosting. Developed a mathematical framework for iterative sample reweighting to reduce error bounds. |
| LeCun et al. (1998) [1055] | Introduced convolutional neural networks (CNNs) with applications to handwritten digit recognition. Provided rigorous derivations of backpropagation and weight sharing for reducing parameters. |
| Srivastava et al. (2014) [141] | Proposed dropout as a regularization technique in deep learning, providing a probabilistic interpretation as model averaging. Demonstrated improvements in generalization performance. |
| Rosenblatt (1958) [1057] | Introduced the perceptron algorithm and proved the perceptron convergence theorem for linearly separable data. Inspired the development of multi-layer perceptrons (MLPs) and deep networks. |
| Hastie, Tibshirani, and Friedman (2009) [139] | Provided a rigorous mathematical treatment of supervised learning, including regularization methods (ridge regression, Lasso), bias-variance tradeoff, kernel methods, decision trees, and ensemble learning. Theoretical analyses of algorithm convergence properties. |
| Kingma and Ba (2014) [176] | Developed the Adam optimization algorithm, combining Adagrad and RMSProp principles. Provided a mathematical derivation of Adam’s update rules for adaptive learning rates in deep learning models. |
16.2.2. Recent Literature Review of Supervised Learning
Supervised learning has found extensive applications across multiple domains, enhancing decision-making, classification, and predictive analytics through well-labeled datasets. Raikwar and Gupta (2025) [1046] developed an AI-driven trust management framework that integrates both supervised and unsupervised learning to classify security levels in wireless ad hoc networks. Their model improves the robustness of decentralized communication by leveraging machine learning-based trust computation, enhancing the detection of malicious nodes and mitigating vulnerabilities in self-organizing networks. Similarly, Rafiei et al. (2025) [1059] employed supervised multi-output classification models, including Random Forest and Support Vector Machines, to optimize lipid nanoparticle design for mRNA delivery. Their research demonstrates how machine learning can refine drug formulation by predicting the best combination of lipid components to enhance delivery efficiency. This showcases the growing role of supervised learning in biotechnology and precision medicine.
In the field of remote sensing and agriculture, Pei et al. (2025) [1060] introduced a weakly supervised learning approach for segmenting vegetation from UAV images. Traditional supervised models often struggle with limited labeled datasets in complex outdoor environments, but their model incorporates spectral reconstruction techniques to improve classification accuracy in field conditions. This advancement significantly enhances agricultural monitoring and precision farming. Likewise, Efendi et al. (2025) [1061] designed an IoT-based health monitoring system where supervised learning algorithms were used to classify and predict health anomalies in elderly patients. Their study highlights how cloud computing and machine learning can be combined to provide real-time health insights, ultimately enabling better remote patient care.
Another critical challenge in supervised learning is the scarcity of labeled data, which was addressed by Pang et al. (2025) [1062] in their research on protein transition pathway prediction. They introduced DeepPath, a framework that integrates active learning with supervised deep learning, allowing models to efficiently identify uncertain data points for labeling. This method enhances model accuracy while reducing the dependency on extensive labeled datasets, making it particularly useful for complex biological simulations. In a different application, Curry et al. (2025) [1063] explored supervised classification techniques in geoscience, comparing their effectiveness with unsupervised clustering methods for analyzing ignimbrite flare-up patterns. Their work provides insights into how machine learning models can be optimized for geological pattern detection, improving hazard assessment and geological forecasting.
In the realm of computational drug discovery, Li et al. (2025) [1064] developed a deep learning-based framework called -PhenoDrug, which employs supervised learning for phenotypic drug screening. The model utilizes transfer learning strategies and neural networks to classify drug interactions, significantly accelerating the identification of promising drug candidates. Similarly, Liu et al. (2025) [1065] integrated supervised learning with molecular docking and dynamic simulations to identify ASGR1 and HMGCR dual-target inhibitors. By combining computational chemistry with machine learning, they were able to streamline the drug discovery process, demonstrating the efficiency of supervised models in pharmaceutical research. These contributions highlight the transformative potential of supervised learning in biomedical applications.
Beyond healthcare and science, supervised learning is also playing a crucial role in business and engineering. Dutta and Karmakar (2025) [1067] investigated the application of the Random Forest algorithm in business analytics, demonstrating its superior accuracy in predictive modeling compared to other machine learning approaches. Their findings illustrate how machine learning can optimize decision-making processes in organizational contexts. Finally, Ekanayake (2025) [1054] explored the use of supervised deep learning models for enhancing Magnetic Resonance Imaging (MRI) reconstruction and super-resolution. Their study addresses the challenges of lengthy MRI scan times by leveraging artificial intelligence to improve image quality, thereby advancing medical diagnostics and reducing patient discomfort.
These studies collectively demonstrate the broad impact of supervised learning across various disciplines, from security and healthcare to remote sensing, drug discovery, and business analytics. The integration of machine learning with domain-specific challenges has led to significant breakthroughs, highlighting the adaptability and efficiency of supervised learning models. As researchers continue to refine these techniques, the future of artificial intelligence-driven decision-making appears increasingly promising. The ability of supervised learning to extract meaningful patterns from structured data is proving invaluable in solving real-world problems, paving the way for further advancements in machine learning research and its practical applications.
Table 23.
Summary of Recent Contributions in Supervised Learning
| Authors (Year) | Contribution |
| Raikwar and Gupta (2025) [1046] | Developed an AI-driven trust management framework integrating supervised and unsupervised learning to classify security levels in wireless ad hoc networks. Enhanced decentralized communication robustness and improved detection of malicious nodes. |
| Rafiei et al. (2025) [1059] | Applied supervised multi-output classification models, including Random Forest and SVMs, to optimize lipid nanoparticle design for mRNA delivery, improving drug formulation predictions. |
| Pei et al. (2025) [1060] | Proposed a weakly supervised learning approach for segmenting vegetation from UAV images, enhancing classification accuracy in precision farming. |
| Efendi et al. (2025) [1061] | Designed an IoT-based health monitoring system that uses supervised learning algorithms to classify and predict health anomalies in elderly patients, improving remote patient care. |
| Pang et al. (2025) [1062] | Introduced DeepPath, a supervised deep learning framework integrating active learning for protein transition pathway prediction, reducing dependency on extensive labeled datasets. |
| Curry et al. (2025) [1063] | Compared supervised classification techniques and unsupervised clustering in geoscience, optimizing machine learning models for geological pattern detection and hazard assessment. |
| Li et al. (2025) [1064] | Developed -PhenoDrug, a deep learning-based framework employing supervised learning for phenotypic drug screening, accelerating drug candidate identification. |
| Liu et al. (2025) [1065] | Integrated supervised learning with molecular docking and simulations to identify ASGR1 and HMGCR dual-target inhibitors, streamlining drug discovery. |
| Dutta and Karmakar (2025) [1067] | Investigated Random Forest applications in business analytics, demonstrating superior predictive modeling accuracy for optimizing organizational decision-making. |
| Ekanayake (2025) [1054] | Applied supervised deep learning models to enhance MRI reconstruction and super-resolution, improving medical diagnostics by reducing scan times. |
16.2.3. Mathematical Analysis of Supervised Learning
Supervised learning is a fundamental paradigm in machine learning wherein a model is trained using labeled data, consisting of input-output pairs . Here, represents the feature vector of the ith data point, and represents the corresponding label, which can be either continuous (regression) or discrete (classification). The goal of supervised learning is to learn a function or such that for an unseen input , the model produces an accurate prediction . Mathematically, the model aims to approximate the conditional probability distribution , i.e.,
where the expectation is taken with respect to the true underlying data distribution . The optimal function minimizes the expected loss over the data distribution,
where denotes the hypothesis space of functions and is a loss function quantifying the error between the true and predicted values.
In empirical risk minimization (ERM), the expectation is approximated using the training set, leading to
For regression tasks, common choices for include the squared loss,
which leads to the minimization of the mean squared error (MSE),
For classification, a frequently used loss function is the cross-entropy loss for a model outputting class probabilities ,
where K is the number of classes and is the indicator function that is 1 if and 0 otherwise. The classifier aims to minimize the empirical risk,
To optimize , gradient-based methods are commonly used, particularly in deep learning where f is parameterized by a neural network with weights ,
where and are weight matrices and bias vectors at layer l, and is an activation function. The optimization process follows stochastic gradient descent (SGD), updating parameters iteratively as follows,
where is the learning rate and is the loss function. The gradient is computed via backpropagation,
Regularization techniques, such as L2 regularization (ridge regression),
are used to prevent overfitting by penalizing large weights. In logistic regression, the probability of a binary label is modeled using the sigmoid function,
The loss function in this case is the binary cross-entropy loss,
Thus, supervised learning encompasses various frameworks, each employing rigorous mathematical formulations to optimize predictive performance.
16.2.4. Python Code to Generate Figure 156 Illustrating the Supervised Learning in Regression
The Python code below produces the Figure 156 illustrating the Supervised Learning in Regression.
Figure 156.
Illustration of Supervised Learning in regression. Blue points represent training data, the dashed green line is the true underlying function, and the red line is the model learned from data
Figure 156.
Illustration of Supervised Learning in regression. Blue points represent training data, the dashed green line is the true underlying function, and the red line is the model learned from data
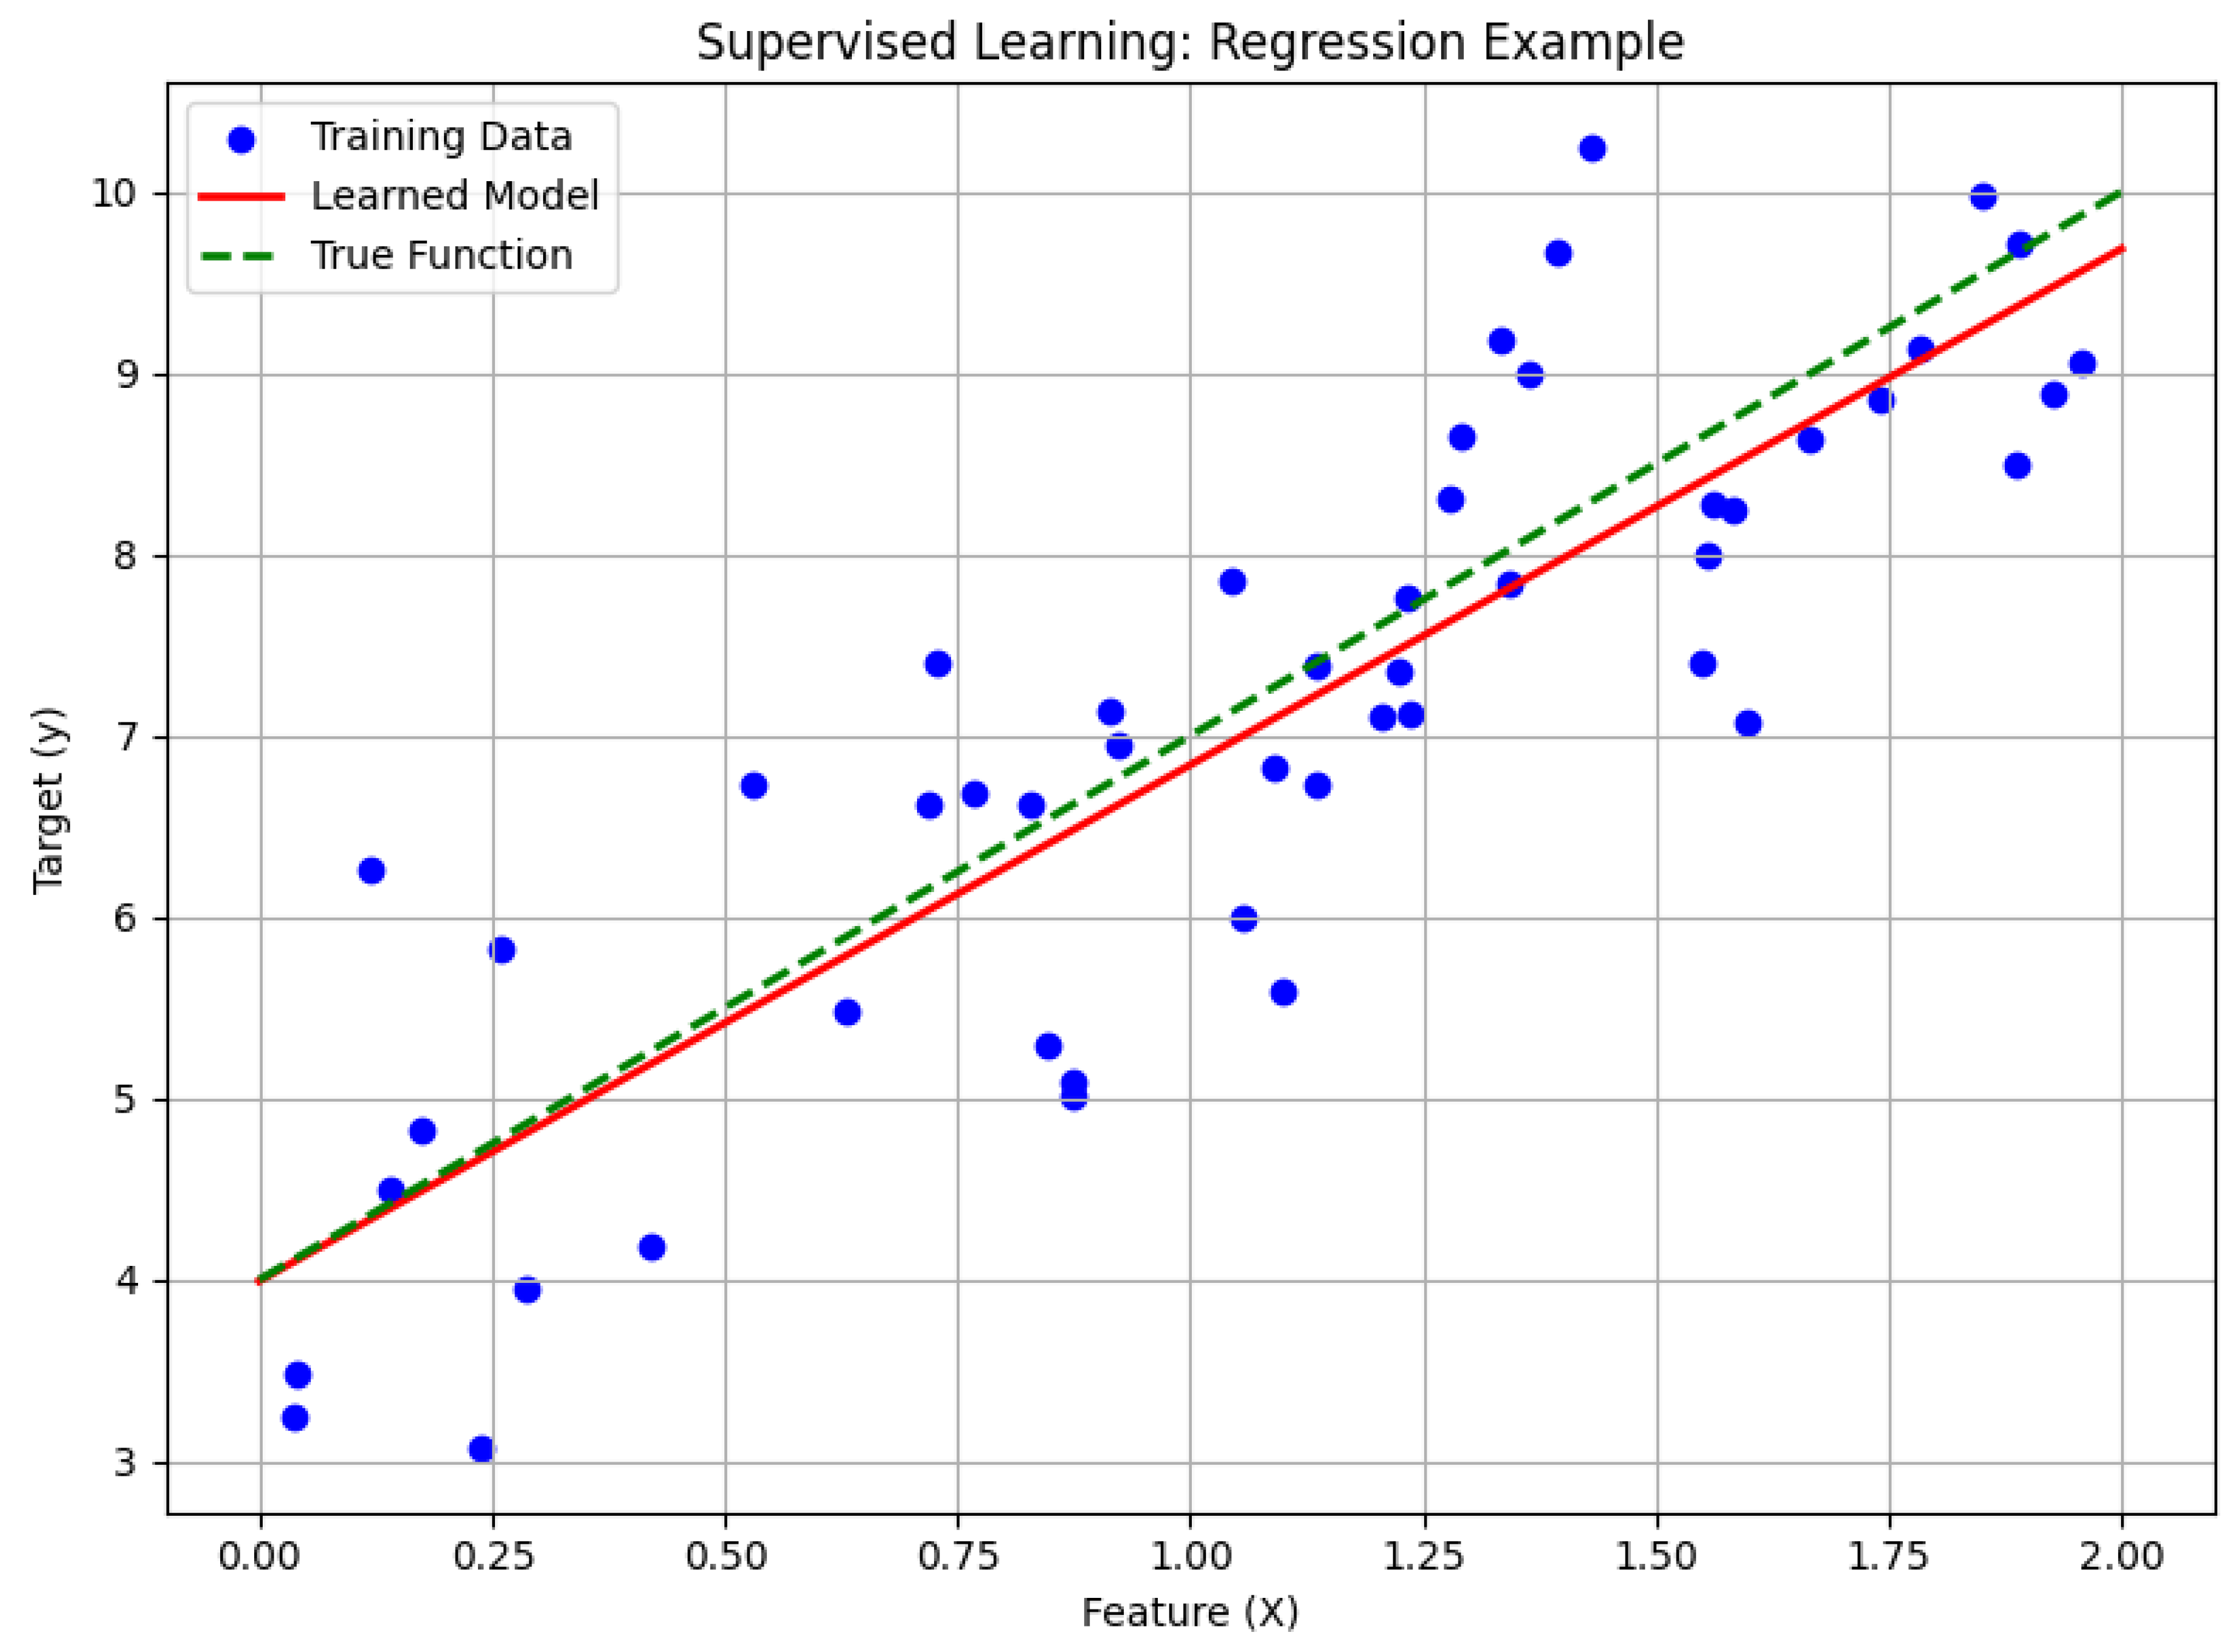
16.2.5. Bias-Variance Tradeoff of Supervised Learning
16.2.5.1 Literature Review of Bias-Variance Tradeoff of Supervised Learning
The bias-variance tradeoff is a crucial concept in supervised learning, dictating how model complexity impacts predictive performance. Geman, Bienenstock, and Doursat (1992) [882] introduced the bias-variance decomposition in the context of neural networks, rigorously establishing that overly simple models suffer from high bias due to underfitting, while excessively complex models exhibit high variance due to overfitting. This foundational work provided a theoretical framework that has guided decades of machine learning research. Hastie, Tibshirani, and Friedman (2001) [139] further expanded upon this concept in their comprehensive textbook, where they provided mathematical formulations, empirical analyses, and practical implications of the tradeoff across various learning algorithms. Their work remains one of the most widely referenced sources for understanding the balance between bias and variance in real-world applications. More recently, Belkin et al. (2019) [883] challenged the classical understanding of the tradeoff by introducing the "double descent" risk curve, demonstrating that in highly over-parameterized models, test error initially increases but eventually decreases beyond a critical complexity threshold. This counterintuitive result, grounded in empirical evidence and theoretical analysis, reshaped the conventional wisdom regarding model selection and generalization in modern machine learning.
In the context of deep learning, Neal et al. (2018) [884] revisited the bias-variance tradeoff, rigorously analyzing why larger neural networks often achieve superior generalization despite their over-parameterization. They argued that implicit regularization, induced by optimization algorithms such as stochastic gradient descent, plays a crucial role in preventing excessive variance growth. Rocks and Mehta (2020) [885] further investigated over-parameterized models using statistical physics methods, deriving explicit analytical expressions for bias and variance in settings such as linear regression and shallow neural networks. Their work provided a deeper theoretical understanding of how interpolation affects generalization, revealing a phase transition where the training error collapses to zero while test error exhibits non-trivial behavior due to the complex interaction of bias and variance. Meanwhile, Doroudi and Rastegar (2023) [886] extended the bias-variance framework beyond machine learning, applying it to cognitive science models. Their work emphasized that cognitive processes also operate under similar tradeoffs, where overly rigid or overly flexible models fail to accurately capture human learning and reasoning, thereby providing an interdisciplinary perspective on the problem.
The practical implications of the bias-variance tradeoff extend to domains such as label noise, knowledge distillation, and ensemble learning. Almeida et al. (2020) [887] focused on mitigating class boundary label uncertainty, proposing an approach that estimates label noise and adjusts training sample weights to simultaneously reduce both bias and variance. Their method provided empirical evidence that accounting for uncertainty near decision boundaries leads to improved generalization performance. Zhou et al. (2021) [888] explored the role of soft labels in knowledge distillation, demonstrating that these labels act as a form of implicit regularization that influences the bias-variance tradeoff in student-teacher learning paradigms. They proposed a novel method of weighting soft labels to dynamically balance bias and variance at the sample level. Gupta et al. (2022) [889] examined ensemble methods from a bias-variance perspective, showing that ensembling reduces variance without significantly increasing bias. Their theoretical and empirical results highlighted why ensemble-based approaches often outperform single models in practice. Finally, Ranglani (2024) [890] conducted an extensive empirical analysis across different machine learning algorithms, quantifying the bias-variance decomposition and providing insights into the tradeoff dynamics in regression and classification tasks. Their study offered practical guidelines for optimizing machine learning models by rigorously understanding how bias and variance manifest across various architectures.
Collectively, these works illustrate the evolution of the bias-variance tradeoff from its classical roots to its modern reinterpretation in deep learning and beyond. They provide rigorous theoretical insights and empirical validations that have fundamentally shaped the field of machine learning. The contributions span diverse perspectives, from statistical learning theory to interdisciplinary applications, and challenge traditional notions of model complexity and generalization. The continued exploration of this tradeoff remains a central theme in machine learning research, influencing advancements in algorithm design, optimization techniques, and real-world deployment strategies.
Table 24.
Summary of Contributions to the Bias-Variance Tradeoff in Supervised Learning
| Reference | Contribution |
| Geman, Bienenstock, and Doursat (1992) | Introduced the bias-variance decomposition in neural networks, demonstrating how model complexity influences predictive error. They formulated a theoretical framework explaining the tradeoff between underfitting (high bias) and overfitting (high variance). |
| Hastie, Tibshirani, and Friedman (2001) | Provided a comprehensive treatment of the bias-variance tradeoff in statistical learning, including rigorous mathematical derivations, practical insights, and empirical analyses across multiple machine learning models. |
| Belkin et al. (2019) | Challenged the classical U-shaped bias-variance curve by introducing the "double descent" phenomenon, showing that over-parameterized models can exhibit improved generalization after an initial increase in test error. |
| Neal et al. (2018) | Analyzed the bias-variance tradeoff in deep learning, arguing that implicit regularization induced by stochastic gradient descent prevents excessive variance growth in large neural networks, explaining their surprising generalization ability. |
| Rocks and Mehta (2020) | Derived analytical expressions for bias and variance in over-parameterized models using statistical physics, uncovering a phase transition where increasing model complexity leads to test error reduction despite interpolation. |
| Guest and Martin (2021) | Extended the bias-variance framework to cognitive science, demonstrating how cognitive models suffer from similar tradeoffs between flexibility and generalization. They argued that model complexity in human cognition follows analogous patterns. |
| Almeida et al. (2020) | Developed a method for mitigating label uncertainty near class boundaries, proposing an adaptive weighting mechanism to reduce both bias and variance, thereby improving model generalization. |
| Zhou et al. (2021) | Investigated knowledge distillation through the lens of the bias-variance tradeoff, demonstrating that soft labels act as implicit regularizers and proposing an optimal weighting scheme to balance bias and variance at the sample level. |
| Gupta et al. (2022) | Provided a rigorous analysis of ensemble methods, proving that ensembling reduces variance without substantially increasing bias, explaining why ensemble learning consistently outperforms single-model approaches. |
| Ranglani (2024) | Conducted an extensive empirical study of the bias-variance tradeoff across various supervised learning models, quantifying bias and variance components and offering practical guidelines for model optimization. |
16.2.5.2 Recent Literature Review of Bias-Variance Tradeoff of Supervised Learning
The bias-variance tradeoff is a fundamental concept in supervised learning, balancing model complexity and generalization performance. Recent literature explores its implications across various domains, including classical statistical learning, deep learning, and ensemble methods. Rahman and Rahman (2024) provide a foundational overview, discussing its role in linear classifiers and logistic regression, where regularization is used to mitigate overfitting. Tran et al. (2024) extend this idea to power systems, demonstrating how a learnable weighted-ensemble neural network optimally manages the tradeoff, particularly in handling real-world power flow optimization. Similarly, George (2024) examines how bias-variance adjustments impact handwriting recognition using the Kaggle digits dataset, emphasizing the importance of tuning model complexity for improved character classification accuracy.
In the context of statistical modeling, Polson and Sokolov (2024) rigorously analyze hierarchical linear models, showcasing how ridge and lasso regression act as regularization techniques to minimize variance while maintaining sufficient flexibility to prevent high bias. This is further explored by Jogo (2025), who provides a broader statistical perspective, linking the bias-variance tradeoff to support vector machines, unsupervised learning, and computational efficiency in high-dimensional spaces. Additionally, Du et al. (2025) introduce a mathematical framework that incorporates margin theory and optimization-based strategies to manage bias-variance tradeoffs in ensemble learning, highlighting computational trade-offs associated with different model architectures.
A particularly interesting development in deep learning is the challenge to the traditional U-shaped bias-variance curve, as presented by Wang and Pope (2025). Their work on the double descent phenomenon suggests that increasing model complexity beyond a certain threshold can actually improve generalization, contradicting classical theory. In a related vein, Chen et al. (2024) investigate the role of graph convolutional networks in regression tasks, providing a theoretical framework to understand how different convolutional layers impact the bias-variance tradeoff. Meanwhile, Obster et al. (2024) take a more interpretability-focused approach, proposing a scoring system to balance predictive accuracy and model transparency while managing the bias-variance relationship.
Finally, ensemble-based techniques continue to be a crucial area of exploration in mitigating bias-variance issues. Owen et al. (2024) revisit bagging and stochastic algorithms, extending the bias-variance decomposition to demonstrate how ensemble methods enhance generalization. Their work aligns with recent trends advocating for hybrid model selection strategies that optimize variance reduction without sacrificing interpretability. The collective findings of these studies underscore the evolving nature of the bias-variance tradeoff in supervised learning, from classical statistical interpretations to novel deep learning insights, and highlight its persistent influence on model performance across diverse applications.
| Reference | Summary of Contribution |
| Rahman & Rahman (2024) | Provides a foundational introduction to the bias-variance tradeoff in machine learning, focusing on logistic regression, linear classifiers, and regularization techniques. Discusses how adjusting model complexity impacts generalization performance. |
| Tran, Mitra, & Nguyen (2024) | Explores how an ensemble-based neural network effectively balances the bias-variance tradeoff in power system optimization. Demonstrates the model’s ability to enhance stability and accuracy in real-world energy distribution scenarios. |
| George (2024) | Investigates how different machine learning models handle the bias-variance tradeoff in character recognition. Uses the Kaggle digits dataset to optimize performance through regularization and model selection strategies. |
| Du et al. (2025) | Develops a theoretical framework linking bias-variance tradeoff to margin theory and optimization techniques. Proposes computational trade-offs to improve model selection in ensemble learning methods. |
| Polson & Sokolov (2024) | Explains the role of ridge and lasso regression in controlling the bias-variance tradeoff. Provides empirical studies demonstrating how hyperparameter tuning influences model performance and generalization. |
| Jogo (2025) | Covers the statistical foundations of the bias-variance tradeoff, linking it to support vector machines, unsupervised learning, and computational efficiency in high-dimensional spaces. |
| Wang & Pope (2025) | Challenges the traditional U-shaped bias-variance tradeoff by showing that increased complexity beyond a certain point can improve generalization in deep learning models. |
| Chen, Schmidt-Hieber, & Donnat (2024) | Analyzes the impact of graph convolutional networks (GCNs) on bias-variance tradeoff, providing a theoretical framework for evaluating convolutional layer depth in regression models. |
| Obster, Ciolacu, & Humpe (2024) | Investigates the tradeoff between predictive accuracy and interpretability in machine learning models. Introduces a scoring system for model complexity optimization while maintaining an optimal bias-variance balance. |
| Owen, Dick, & Whigham (2024) | Extends the bias-variance decomposition for stochastic learning algorithms, demonstrating how bagging-based ensemble methods improve generalization. Highlights hybrid model selection strategies for variance reduction. |
16.2.5.3 Mathematical Analysis of Bias-Variance Tradeoff of Supervised Learning
In supervised learning, the bias-variance tradeoff is a fundamental concept that governs the performance of a model in terms of its ability to generalize to unseen data. Mathematically, the total expected error of a model, often measured as the mean squared error (MSE), can be decomposed as follows:
where Y is the true response variable, X is the input feature, is the true underlying function, and is the estimated function learned by the model. The decomposition highlights three key sources of error:
- Bias: This term quantifies how far the expected prediction is from the true function . Formally, it is defined asA high-bias model makes systematic errors because it fails to capture the complexity of the data. This often occurs in underfitting, where the model is too simple to represent the underlying structure of the data.
- Variance: This term quantifies the variability of the model’s predictions around its expected value, given byA high-variance model is highly sensitive to fluctuations in the training data and does not generalize well to unseen data. This typically occurs in overfitting, where the model captures noise instead of the true signal.
- Irreducible Error: The term represents noise inherent in the data that no model can eliminate.
Since the total error is the sum of these components, an increase in one term often leads to a decrease in another.
For instance, using a more flexible model (e.g., a high-degree polynomial) can reduce bias but at the cost of increased variance. Conversely, using a simple model (e.g., linear regression) reduces variance but increases bias. This tradeoff is captured by minimizing the expected loss function
where the goal is to balance the bias and variance terms to achieve optimal generalization. To analyze this tradeoff further, consider a simple linear model where the target function is quadratic:
If we fit a linear regression model , then the bias is
For a high-degree polynomial model , the variance term increases with d, leading to:
Minimizing the expected generalization error requires selecting a model complexity d such that
To further illustrate, consider a dataset of size n and a model parameterized by . The variance of the estimator is given by
whereas the bias squared is
The total mean squared error (MSE) of the estimator is then
As the complexity of the model increases, the bias decreases, but variance increases. This behavior is described by the function
where are constants depending on the dataset and learning algorithm, and d represents model complexity. The optimal complexity satisfies
For neural networks, increasing the number of layers and neurons often leads to decreased bias but significantly increased variance due to overparameterization. The expected loss for a neural network with weights W trained on data is given by
Regularization techniques such as ridge regression introduce a penalty term , leading to the optimization problem
This reduces variance at the cost of increasing bias, effectively controlling model complexity to achieve an optimal bias-variance tradeoff.
16.2.5.4 Python Code to Generate Figure 157 Illustrating the Bias-Variance Tradeoff of Supervised Learning
The Python code below produces the Figure 157 illustrating the Bias-Variance Tradeoff of Supervised Learning.
Figure 157.
Bias-Variance Tradeoff in Supervised Learning. Bias2 decreases with model complexity, variance increases, training error decreases, and test error initially decreases then increases due to overfitting
Figure 157.
Bias-Variance Tradeoff in Supervised Learning. Bias2 decreases with model complexity, variance increases, training error decreases, and test error initially decreases then increases due to overfitting
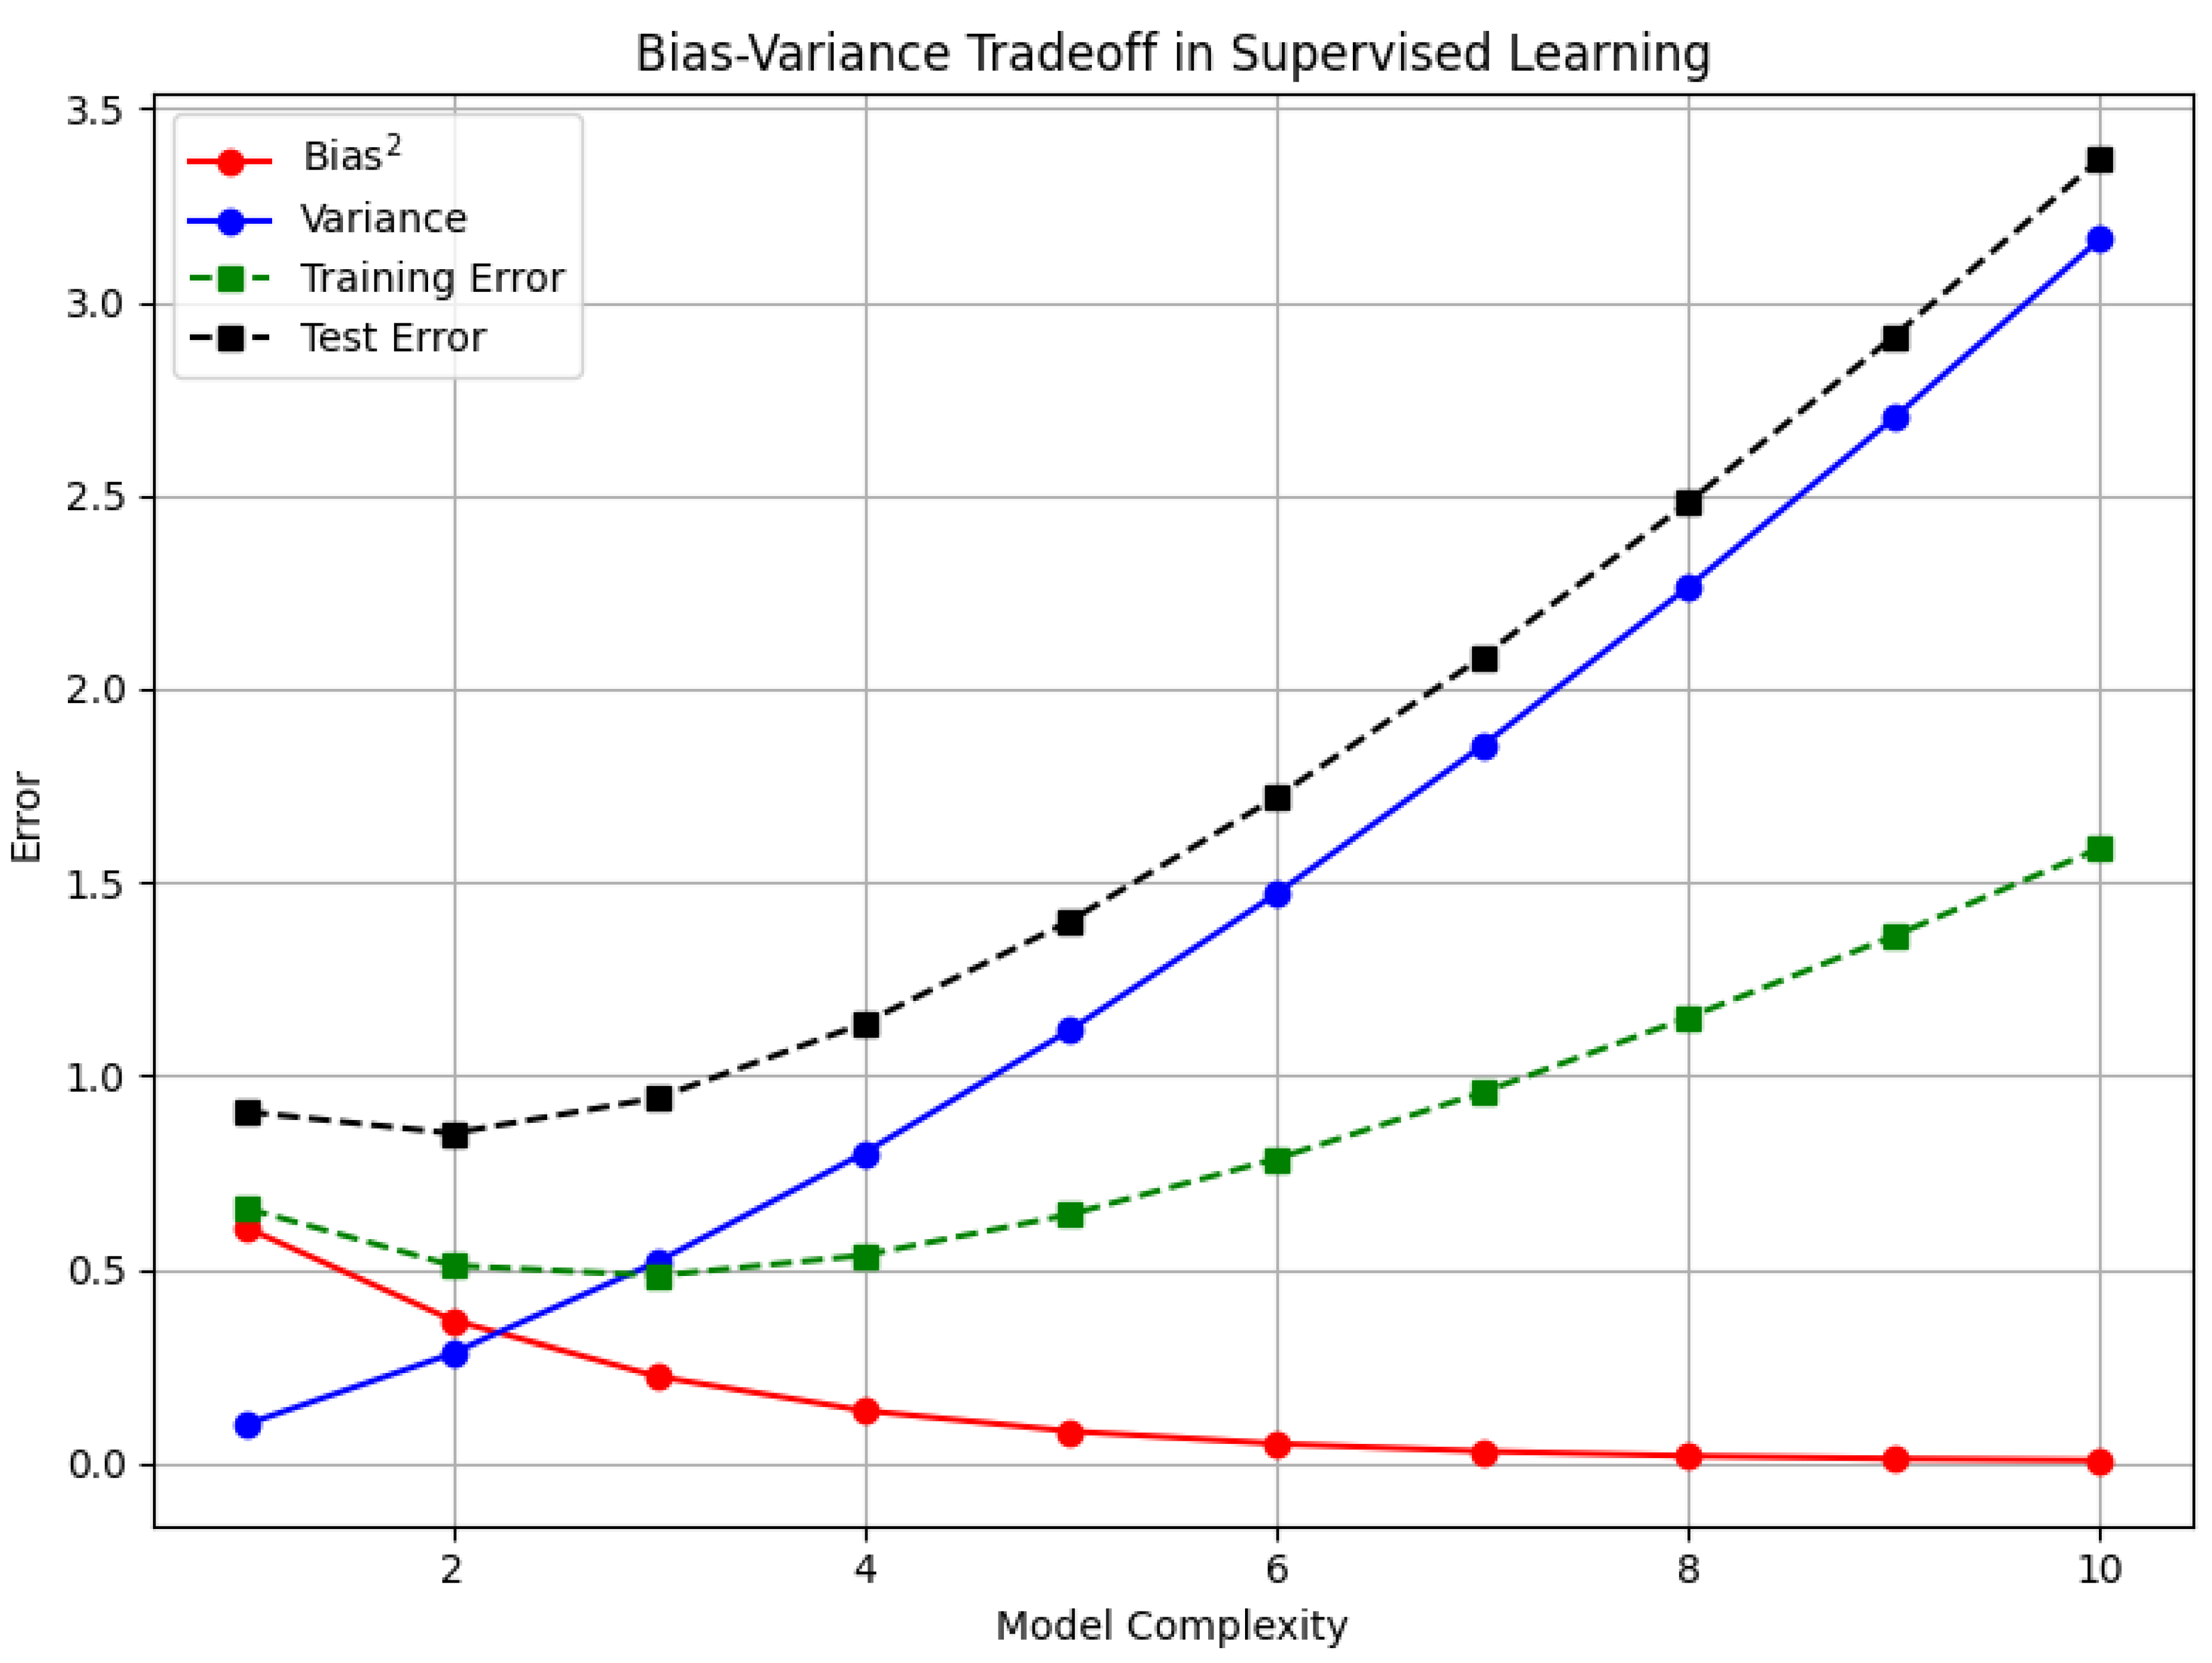
16.2.6. Support Vector Machine
16.2.6.1 Literature Review of Support Vector Machine
Support Vector Machines (SVMs) are rooted in Vladimir Vapnik’s “The Nature of Statistical Learning Theory" (1995) [143], which introduced the fundamental principle of structural risk minimization (SRM). Unlike empirical risk minimization, which solely minimizes training error, SRM aims to balance the complexity of the model and its ability to generalize to unseen data, thereby preventing overfitting. This theoretical framework laid the foundation for the development of SVMs as a powerful tool for classification and regression problems. Schölkopf and Smola’s "Learning with Kernels" (2002) [823] provided a mathematically rigorous treatment of kernel methods, which form the core of SVMs by enabling them to operate in high-dimensional feature spaces without explicit transformation via the kernel trick. This book formalized the mathematical underpinnings of reproducing kernel Hilbert spaces (RKHS), Mercer’s theorem, and various kernel functions such as Gaussian and polynomial kernels. Cristianini and Shawe-Taylor’s "An Introduction to Support Vector Machines" (2000) [824] played a crucial role in making these complex mathematical ideas accessible. It not only explained the theoretical aspects of SVMs but also provided insights into their practical implementation, making it a key reference for researchers and practitioners alike.
The statistical properties of SVMs were rigorously analyzed in Christmann and Steinwart’s "Support Vector Machines" (2008) [825], which focused on their consistency, robustness, and learning rates. This work addressed fundamental questions regarding the asymptotic behavior of SVM classifiers, including their convergence properties under different loss functions. Furthermore, the edited volume by Schölkopf, Burges, and Smola, "Advances in Kernel Methods" (1999) [826], compiled several significant advancements in SVM research, including extensions of SVMs to regression problems (Support Vector Regression, SVR), one-class SVMs for anomaly detection, and novel kernel functions suited for different applications. The book highlighted both theoretical developments and practical applications, illustrating the versatility of SVMs across various domains such as image recognition, bioinformatics, and financial modeling.
The extension of SVMs beyond binary classification was a crucial milestone. Drucker et al.’s "Support Vector Regression Machines" (1997) [827] formalized Support Vector Regression (SVR), which adapted the SVM framework to predict continuous-valued outputs by introducing an -insensitive loss function. This work demonstrated how SVMs could be effectively used for time series prediction and function approximation. Joachims’ "Transductive Inference for Text Classification" (1999) [828] introduced Transductive SVMs (TSVMs), which exploit both labeled and unlabeled data to enhance classification performance, particularly in text classification problems where labeled data is limited. By incorporating unlabeled data, TSVMs leverage the structure of the input distribution, making them particularly useful in semi-supervised learning.
Another fundamental contribution came from Schölkopf, Smola, and Müller’s "Nonlinear Component Analysis as a Kernel Eigenvalue Problem" (1998) [829], which extended Principal Component Analysis (PCA) to nonlinear settings using kernels (Kernel PCA). This demonstrated how kernel-based methods, including SVMs, could be applied beyond classification and regression to dimensionality reduction and feature extraction, which are critical for handling high-dimensional data. Burges’ "A Tutorial on Support Vector Machines for Pattern Recognition" (1998) [830] provided an intuitive yet mathematically detailed explanation of SVMs, covering Lagrange duality, convex optimization, and margin maximization. This tutorial remains an essential resource for researchers seeking to understand both the theoretical foundations and practical aspects of implementing SVMs.
Finally, Schölkopf et al.’s "Estimating the Support of a High-Dimensional Distribution" (2001)[831] introduced one-class SVMs for anomaly detection, where the goal is to find a decision boundary that encloses the majority of data points while rejecting outliers. This formulation is particularly useful in fraud detection, network security, and fault diagnosis, where anomalies are rare but significant. Collectively, these contributions have shaped the development of SVMs as a mathematically rigorous and practically powerful machine learning technique. The blend of theoretical depth, statistical robustness, and practical versatility has cemented SVMs as one of the most influential algorithms in the history of machine learning.
Table 25.
Summary of Contributions in Support Vector Machines
| Reference | Contribution |
| Vladimir N. Vapnik (1995) | Introduced Structural Risk Minimization (SRM), the foundational principle behind SVMs. Established the theoretical basis for SVMs within statistical learning theory. |
| Bernhard Schölkopf and Alexander J. Smola (2002) | Provided a rigorous mathematical treatment of kernel methods, including reproducing kernel Hilbert spaces (RKHS) and Mercer’s theorem, formalizing the kernel trick. |
| Nello Cristianini and John Shawe-Taylor (2000) | Made SVM theory accessible by providing a practical introduction to the mathematical foundations and applications of SVMs. |
| Ingo Steinwart and Andreas Christmann (2008) | Offered a statistical analysis of SVMs, covering consistency, robustness, and learning rates, providing insight into their asymptotic properties. |
| Bernhard Schölkopf, Christopher J.C. Burges, and Alexander J. Smola (1999) | Compiled major advances in kernel methods, including extensions of SVMs to regression (SVR) and novel kernel functions. Showcased applications in image processing and bioinformatics. |
| Harris Drucker et al. (1997) | Developed Support Vector Regression (SVR), adapting SVMs for continuous-valued predictions. Introduced the -insensitive loss function. |
| Thorsten Joachims (1999) | Introduced Transductive SVMs (TSVMs), which leverage both labeled and unlabeled data for improved classification, particularly in text mining applications. |
| Bernhard Schölkopf, Alexander Smola, and Klaus-Robert Müller (1998) | Developed Kernel Principal Component Analysis (Kernel PCA), extending SVM-related methods to nonlinear dimensionality reduction and feature extraction. |
| Christopher J.C. Burges (1998) | Provided an accessible and mathematically detailed tutorial on SVMs, explaining concepts such as margin maximization, convex optimization, and duality theory. |
| Bernhard Schölkopf et al. (2001) | Introduced One-Class SVMs for anomaly detection, providing a method to estimate the support of a high-dimensional distribution. Applied in fraud detection and network security. |
16.2.6.2 Recent Literature Review of Support Vector Machine
Support Vector Machines (SVMs) have demonstrated remarkable versatility across a wide range of domains, from biomedical imaging and sentiment analysis to engineering and hydrological modeling. In the medical domain, Guo and Sun (2025) [872] utilized SVMs to analyze neuroimaging data, assessing stroke rehabilitation effects in brain tumor patients. Their study emphasized SVM’s capability in clinical decision-making and biomedical imaging. Similarly, Diao et al. (2025) [873] investigated lung cancer detection by optimizing Bi-LSTM networks with hand-crafted features. Their findings revealed that SVMs achieved the highest classification accuracy when extracting Gray-Level Co-Occurrence Matrix (GLCM) features, reinforcing their robustness in medical image classification. Another pivotal study by Lin et al. (2025) [874] combined deep transfer learning with SVM-based radiomics for sinonasal malignancy detection in MRI scans, achieving an impressive 92.6 percent accuracy, underscoring SVM’s potential in computer-aided diagnosis and medical image processing. Çetintaş (2025) [875] further extended SVM applications in healthcare by employing an optimized SVM model via Grid Search for monkeypox detection, significantly improving classification performance on imbalanced datasets.
In the realm of natural language processing and text analytics, Wang and Zhao (2025) [876] compared sentiment lexicon and machine learning methods for citation sentiment identification, demonstrating SVM’s superior generalization ability in text classification tasks. Muralinath et al. (2025) [877] explored multichannel EEG classification using spectral graph kernels, where SVMs played a crucial role in robust epilepsy detection. Additionally, Hu et al. (2025) [878] addressed the class imbalance problem in sarcasm detection by leveraging an ensemble-based oversampling technique, proving SVM’s efficacy in handling skewed datasets. These studies confirm SVM’s strength in high-dimensional, sparse data environments, making it a go-to method in various text processing applications.
Engineering and applied sciences have also benefited greatly from SVM-based models. Wang et al. (2025) [879] demonstrated how Support Vector Regression (SVR) effectively predicts the tensile properties of automotive steels, validating its use in materials science and mechanical engineering. Similarly, Husain et al. (2025) [880] employed SVR to model shear thickening fluid behavior, showcasing its ability to forecast nonlinear behaviors in physics and engineering applications. Iqbal and Siddiqi (2025) [881] integrated SVM in a hybrid deep learning model to enhance seasonal streamflow prediction, proving SVM’s utility in hydrological and environmental modeling. These studies collectively highlight the adaptability of SVM-based regression techniques in predicting complex, nonlinear systems across scientific disciplines.
From biomedical diagnostics to predictive analytics in engineering, these studies illustrate how Support Vector Machines remain a fundamental tool in machine learning research. The ability of SVMs to handle high-dimensional spaces, work with limited data, and maintain strong generalization capabilities makes them highly relevant across numerous fields. Whether used for medical imaging, fraud detection, text mining, or physical modeling, SVMs continue to provide state-of-the-art solutions that rival deep learning techniques while maintaining interpretability and computational efficiency.
Table 26.
Summary of Recent Contributions in Support Vector Machines
| Study | Contribution | Domain |
| Guo & Sun (2025) | Applied SVM to analyze neuroimaging data, assessing stroke rehabilitation effects in brain tumor patients. Demonstrated SVM’s potential in biomedical imaging and clinical decision-making. | Medical Imaging, Neuroscience |
| Diao et al. (2025) | Optimized Bi-LSTM networks for lung cancer detection. Found that SVM achieved the highest classification accuracy when extracting GLCM features. | Medical Diagnosis, Deep Learning |
| Lin et al. (2025) | Integrated SVM with deep transfer learning in MRI-based sinonasal malignancy detection, achieving 92.6% accuracy. Highlighted SVM’s potential in radiomics. | Radiomics, MRI Analysis |
| Çetintaş (2025) | Used an optimized SVM model with Grid Search for monkeypox detection. Improved classification performance on imbalanced datasets. | Medical Image Classification |
| Wang & Zhao (2025) | Compared sentiment lexicon and machine learning methods for citation sentiment identification. Demonstrated SVM’s effectiveness in text classification. | NLP, Sentiment Analysis |
| Muralinath et al. (2025) | Explored multichannel EEG classification using spectral graph kernels. Showed SVM’s robustness in epilepsy detection. | EEG Analysis, Neurology |
| Hu et al. (2025) | Addressed class imbalance in sarcasm detection using ensemble-based oversampling techniques. Showed SVM’s high performance in NLP. | NLP, Social Media Analysis |
| Wang et al. (2025) | Developed an SVR-based predictive model for tensile properties of automotive steels. Proved its effectiveness in mechanical engineering. | Materials Science, Engineering |
| Husain et al. (2025) | Applied SVR for modeling shear thickening fluid behavior, showing its ability to forecast nonlinear physical behaviors. | Physics, Fluid Mechanics |
| Iqbal & Siddiqi (2025) | Integrated SVM into a hybrid deep learning model for seasonal streamflow prediction, demonstrating SVM’s utility in hydrological modeling. | Hydrology, Environmental Science |
16.2.6.3 Mathematical Analysis of Support Vector Machine
The Support Vector Machine (SVM) is a supervised learning model used for classification and regression. Given a training set , where are the feature vectors and are the class labels, the goal is to find a hyperplane that maximally separates the two classes. The hyperplane is represented as
where is the normal vector to the hyperplane and is the bias term. For linearly separable data, the constraints ensuring correct classification are
The distance from a point to the hyperplane is given by
The margin, which is the distance between the two parallel supporting hyperplanes that pass through the closest data points of each class, is given by
The optimal separating hyperplane maximizes this margin, leading to the following convex optimization problem
subject to
To solve this constrained optimization problem, the Lagrangian is introduced:
where are the Lagrange multipliers satisfying .
Taking derivatives and setting them to zero gives the Karush-Kuhn-Tucker (KKT) conditions:
Substituting into the Lagrangian yields the dual problem:
subject to
The optimal support vectors are the points for which . The bias term b is computed using any support vector as
For non-linearly separable data, the SVM allows some misclassification using slack variables , leading to the soft-margin SVM formulation
subject to
where is a regularization parameter. The corresponding dual problem remains
subject to
The final classifier is
Thus, SVM constructs an optimal decision boundary by solving a quadratic optimization problem, ensuring a maximum-margin separator, and leveraging kernel functions to extend the model to non-linearly separable cases.
16.2.6.4 Python Code to Generate Figure 158 Illustrating the Support Vector Machine (SVM) with Linear Kernel
The Python code below produces the Figure 158 illustrating the Support Vector Machine (SVM) with linear kernel.
Figure 158.
Support Vector Machine (SVM) with linear kernel. The solid line represents the decision boundary, dashed lines show the margins, and circled points are the support vectors
Figure 158.
Support Vector Machine (SVM) with linear kernel. The solid line represents the decision boundary, dashed lines show the margins, and circled points are the support vectors
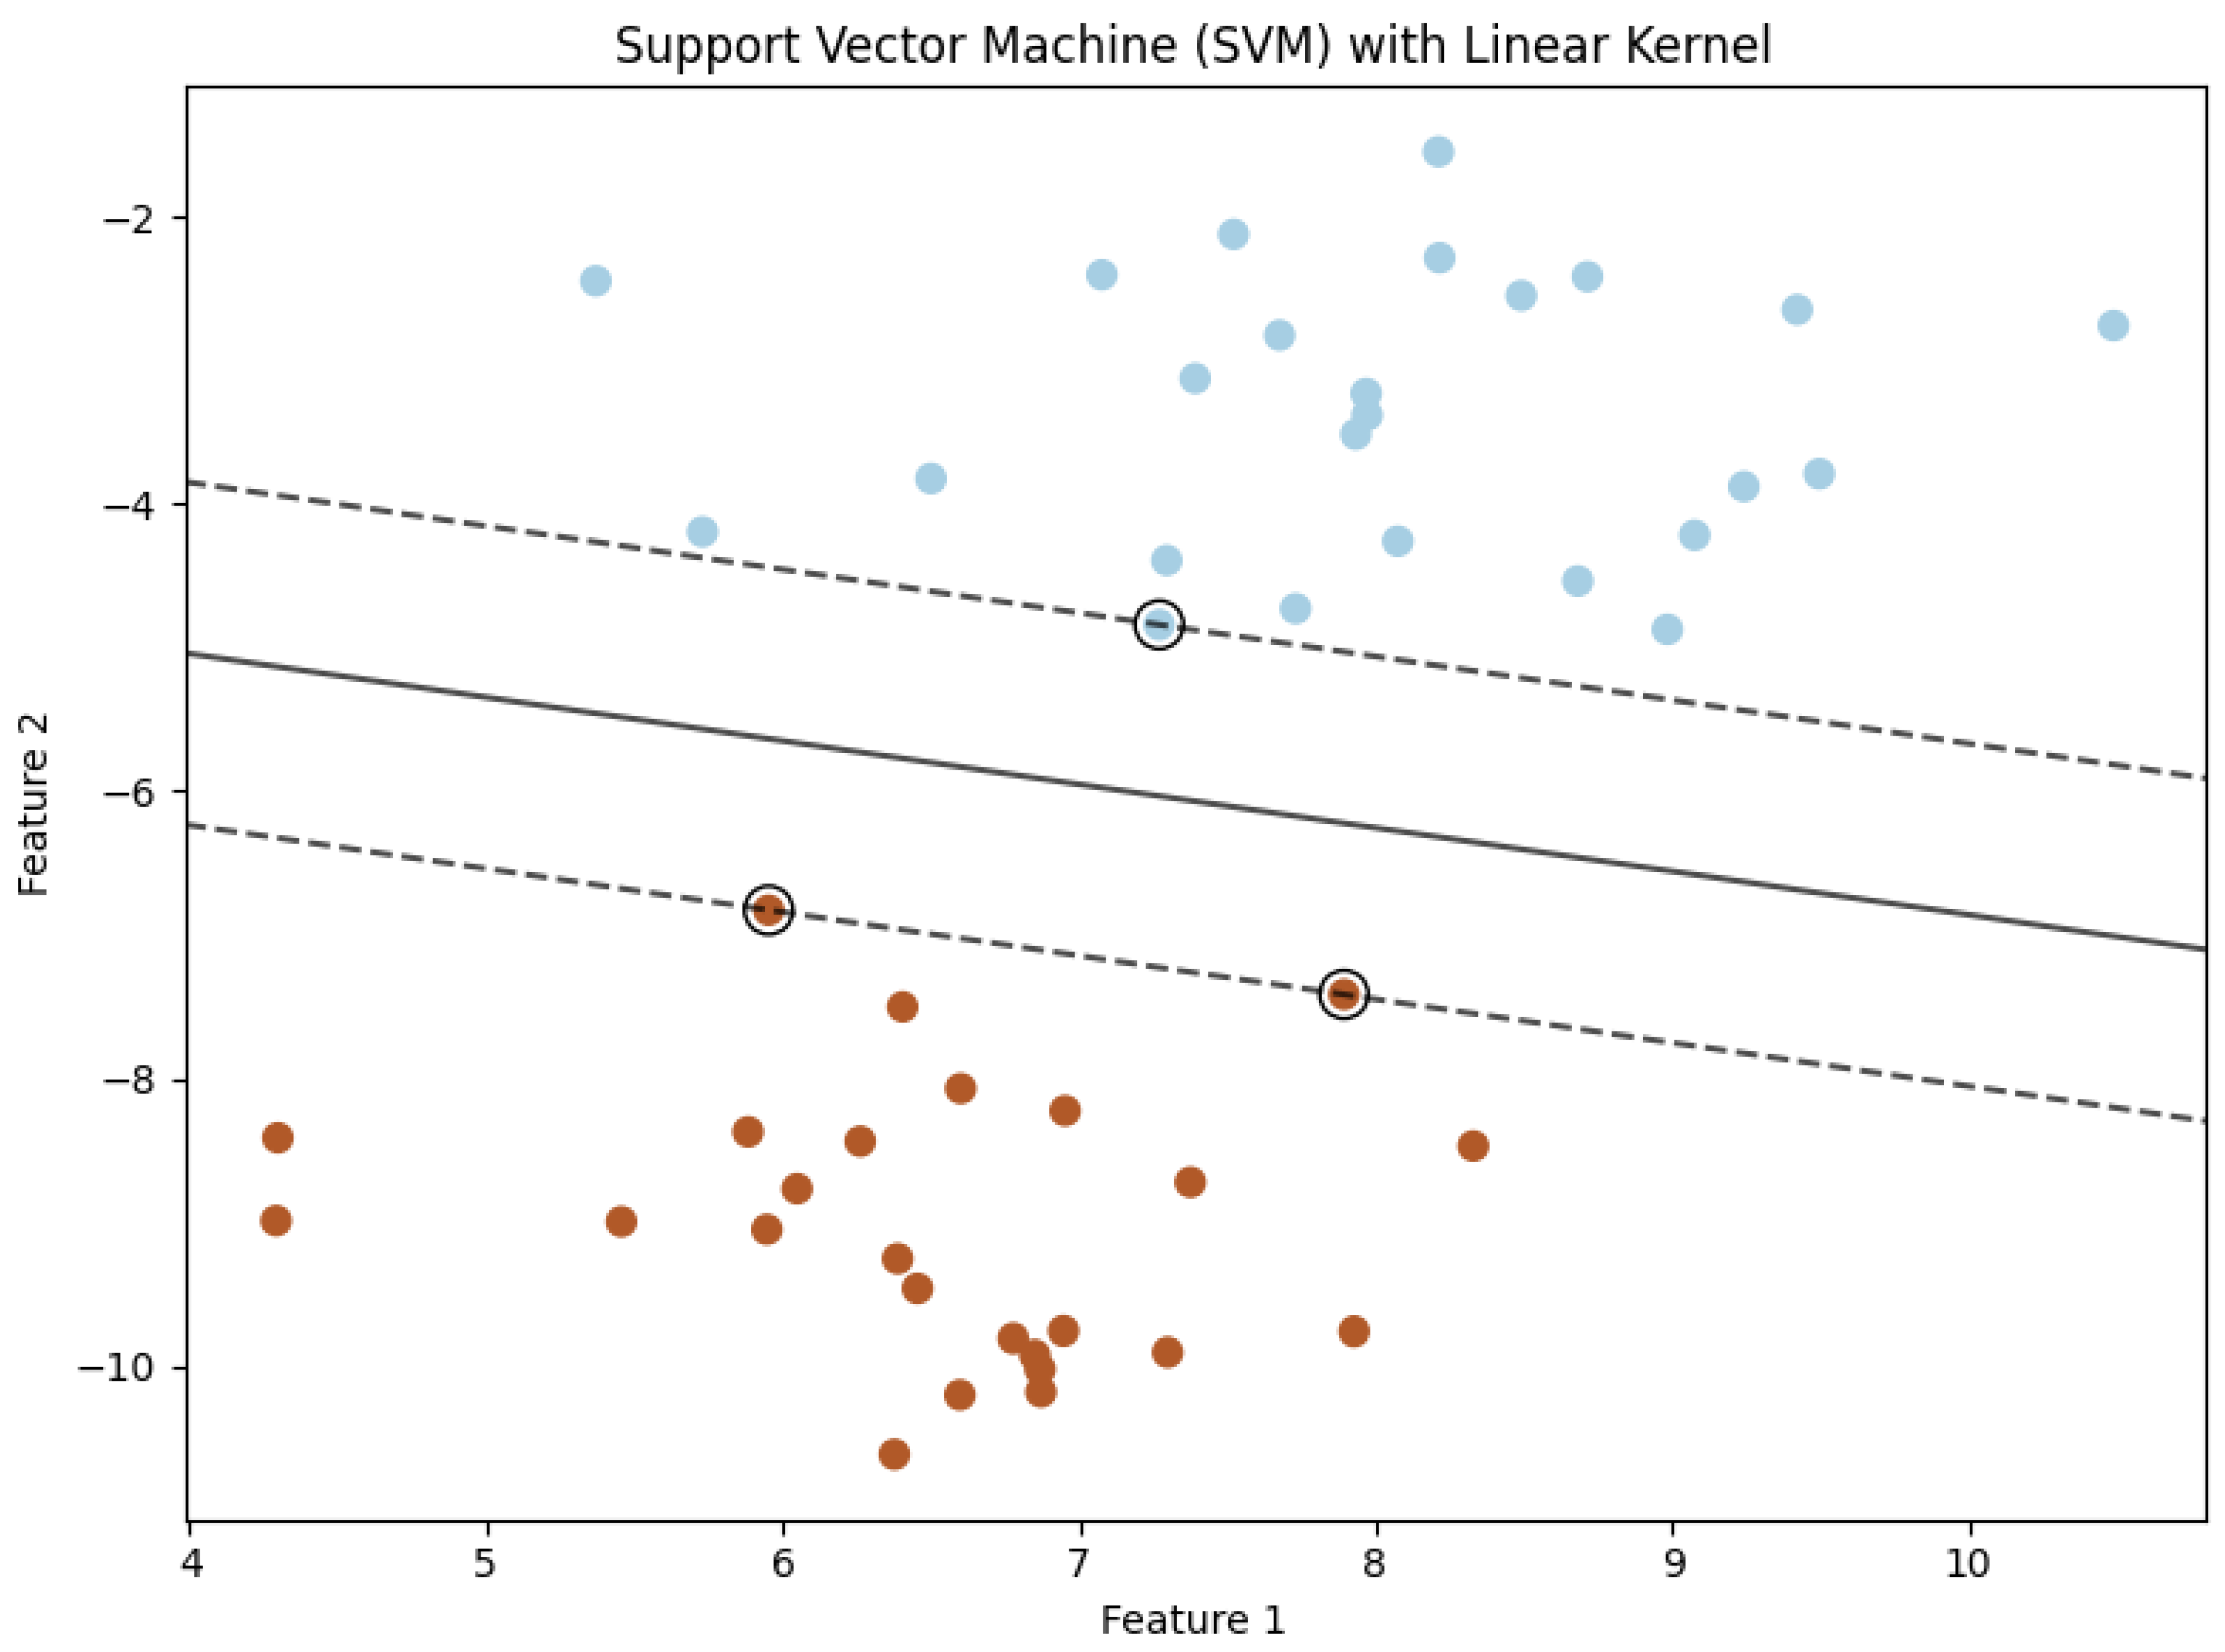
Figure 159.
Illustration of the Support Vector Machine. Image Credit: By Larhmam - Own work, CC BY-SA 4.0, https://commons.wikimedia.org/w/index.php?curid=73710028. This illustration shows an SVM trained on two-class data, highlighting the maximum-margin hyperplane and its margins. The data points that rest on the margin are referred to as support vectors
16.2.7. Linear Regression
16.2.7.1 Literature Review of Linear Regression
The development of linear regression as a rigorous statistical tool can be traced back to the foundational works of Gauss (1809) [832] and Legendre (1806) [833], who independently introduced the method of least squares. This method provides a systematic way to estimate parameters by minimizing the sum of squared residuals, ensuring the best linear fit to a given set of data points. While Legendre initially proposed the method in the context of astronomical orbit calculations, Gauss later provided a more comprehensive theoretical justification, demonstrating that under the assumption of normally distributed errors, the least squares estimators are best linear unbiased estimators (BLUE), meaning they have the lowest variance among all linear unbiased estimators. This result was later formalized in what is now known as the Gauss-Markov theorem. Additionally, Gauss extended these ideas to incorporate the normality assumption, which established a strong probabilistic foundation for regression analysis by linking least squares estimation to maximum likelihood estimation (MLE) in the presence of Gaussian errors.
The geometric interpretation of regression was further expanded by Pearson (1901) [834], who developed principal component analysis (PCA) as a method for dimensionality reduction and data compression. Pearson’s work highlighted the connection between linear regression and orthogonal projections, providing insights into how regression techniques relate to eigenvalue decomposition and singular value decomposition (SVD). Fisher (1922) [835] played a crucial role in rigorously formulating the statistical inference framework for linear regression, developing methods for estimating standard errors, constructing confidence intervals, and conducting hypothesis tests on regression coefficients. Fisher’s approach introduced key concepts such as the sampling distribution of regression estimators and the use of likelihood-based inference, which remain central to modern regression analysis.
Building upon these foundational principles, Koopmans (1937) [836] extended linear regression techniques to time series analysis, addressing challenges such as serial correlation, heteroskedasticity, and multicollinearity in economic forecasting. This laid the groundwork for the generalized least squares (GLS) method, which was later formalized by Goldberger (1991) [837]. Goldberger provided a rigorous treatment of violations of ordinary least squares (OLS) assumptions, particularly when dealing with correlated error structures and non-constant variance in regression models. Rao (1973) [838] further expanded the theory of regression by introducing ridge regression, a technique that stabilizes coefficient estimates in the presence of multicollinearity by introducing a penalty term to control variance. His work unified linear regression within the broader framework of multivariate statistical inference, contributing to the development of generalized regression models.
Huber (1992) [839] introduced a significant advancement by developing robust regression techniques, which addressed the sensitivity of classical least squares estimation to outliers and departures from normality. His work on M-estimation provided a framework for obtaining regression estimates that remain stable under heavy-tailed distributions and heteroskedastic errors. Finally, modern developments in regression analysis were driven by Hastie, Tibshirani, and Friedman (2009) [139], who introduced regularized regression techniques such as ridge regression and LASSO (Least Absolute Shrinkage and Selection Operator). These methods added penalization terms to the least squares objective function, effectively preventing overfitting and improving model generalization in high-dimensional settings.
Collectively, these contributions transformed linear regression from a simple numerical fitting method into a rigorous statistical and mathematical framework with broad applicability across various scientific and engineering disciplines. The integration of inferential statistics, robustness techniques, and regularization strategies has ensured that linear regression remains a cornerstone of modern statistical analysis and predictive modeling.
Table 27.
Summary of Contributions to Linear Regression
| Reference | Contribution |
| Legendre (1805) | Introduced the least squares method for estimating parameters by minimizing the sum of squared residuals, initially applied to astronomical data. |
| Gauss (1809, 1821) | Formally justified the least squares method under normal error assumptions, proving its best linear unbiased estimation (BLUE) property and laying the foundation for the Gauss-Markov theorem. Developed statistical inference for regression. |
| Pearson (1901) | Developed principal component analysis (PCA), establishing the geometric relationship between regression and orthogonal projections, which later connected to singular value decomposition (SVD). |
| Fisher (1922) | Formalized the statistical inference framework for regression, deriving the sampling distributions of regression coefficients, hypothesis testing procedures, and maximum likelihood estimation (MLE) methods. |
| Koopmans (1937) | Extended regression to time series analysis, addressing issues such as serial correlation, heteroskedasticity, and multicollinearity, which are critical in econometric models. |
| Goldberger (1964) | Developed generalized least squares (GLS) to handle correlated errors and non-constant variance, providing a rigorous treatment of assumption violations in ordinary least squares (OLS). |
| Rao (1973) | Expanded regression theory by introducing ridge regression to handle multicollinearity, unifying regression within the broader framework of multivariate statistical inference. |
| Huber (1964) | Developed robust regression techniques, particularly M-estimation, which mitigates the impact of outliers and non-Gaussian error distributions, improving model stability. |
| Hastie, Tibshirani, and Friedman (2009) | Introduced regularized regression techniques such as ridge regression and LASSO, incorporating penalization terms to prevent overfitting and improve generalization in high-dimensional data. |
16.2.7.2 Recent Literature Review of Linear Regression
Linear regression, as a foundational statistical tool, has been extensively employed across various disciplines, from environmental monitoring and healthcare research to economic policy and agricultural sciences. Recent advancements illustrate how traditional regression techniques have been adapted and integrated with modern methodologies to enhance analytical precision and predictive power. Ramadhan and Ali (2025) [840] propose a novel multivariate wavelet shrinkage approach in quantile regression models, effectively improving estimation accuracy in high-dimensional data scenarios. Their work highlights how wavelet-based methods refine traditional regression by addressing noise reduction and variability, making it particularly useful in financial modeling and risk assessment. Similarly, Zhou et al. (2025) [841] leverage linear regression within a hybrid machine learning framework that combines Partial Least Squares (PLS) and Decision Trees (DT) for real-time chemical degradation monitoring. This application underscores regression’s role in environmental science, where predictive analytics can optimize industrial and ecological interventions.
Healthcare research has also significantly benefited from linear regression models, particularly in understanding human behavior and institutional efficiency. Zhong et al. (2025) [842] employ multiple linear regression to analyze factors influencing nurses’ attitudes and practices in postural management for premature infants. Their study highlights how regression can quantify behavioral determinants, aiding in the design of targeted medical training programs. Likewise, Liu et al. (2025) [843] use regression analysis to assess the research capabilities of pediatric clinical nurses, identifying key skill gaps and the variables influencing scientific output in medical institutions. These findings emphasize the importance of regression-based methodologies in human resource optimization and professional development within healthcare. A crucial addition to the healthcare research stream is the study by Dietze et al. (2025) [845], which was previously omitted. Their research examines the impact of the UNODC/WHO SOS (Stop Overdose Safely) training program on opioid overdose knowledge and attitudes. Using multivariable linear regression, they analyze the relationship between demographic characteristics and training effectiveness. Their findings reveal how linear regression can provide deep insights into behavioral interventions, policy evaluations, and addiction treatment effectiveness.
In the economic and policy domain, regression techniques serve as powerful tools for evaluating regulatory frameworks and socioeconomic disparities. Ming-jun and Jian-ya (2025) [844] construct multiple linear regression models to examine the Porter hypothesis in environmental taxation, revealing complex interdependencies between tax policies and corporate behavior. This application of regression provides empirical support for policy decisions aimed at balancing environmental sustainability with economic growth. Cox et. al. (2022) [1468] extended Halbeisen’s and Hungerbühler’s optimal bounds for Collatz cycle lengths to the more general 3n + c sequences, where c is an odd integer not divisible by 3. It analyzes the structure of these cycles using parity vectors derived from ceiling and floor functions to identify relationships between the smallest and largest odd elements within each cycle. The study reveals rotational and congruential properties of these parity vectors, suggesting underlying uniformity in the distribution of elements across generalized Collatz cycles. Hasan and Ghosal (2025) [846] extend this approach to public health, using regression to quantify inequities in healthcare access across different regions in West Bengal, India. Their findings contribute to the formulation of equitable healthcare policies by identifying key determinants of accessibility, such as affordability and geographical distribution.
Agricultural and biomedical research have also leveraged linear regression for predictive modeling and diagnostic improvements. Zeng et al. (2025) [848] employ LASSO (Least Absolute Shrinkage and Selection Operator) regression to enhance maize yield predictions under stress conditions. By integrating regression with remote sensing data, they improve crop forecasting models, demonstrating the method’s importance in precision agriculture. In orthopedic research, Baird et al. (2025) [849] use regression to analyze long-term trends in surgical procedures, particularly in anterior cruciate ligament reconstruction and hip arthroscopy. Their work demonstrates how regression-driven AI analysis can refine medical decision-making by identifying treatment patterns and patient outcomes over time.
Finally, the application of regression in veterinary and agronomic sciences further highlights its interdisciplinary utility. Overton and Eicker (2025) [850] analyze milk production and fertility trends in Holstein dairy cows using a combination of linear and logistic regression models. Their study provides critical insights into dairy farm efficiency, showing how regression techniques can optimize breeding programs and livestock management strategies. Collectively, these studies illustrate the remarkable adaptability of linear regression, as it continues to evolve through integration with machine learning and modern statistical techniques, further solidifying its relevance in both academic research and practical applications.
Table 28.
Summary of Recent Contributions on Linear Regression
| Paper | Key Contribution |
| Ramadhan & Ali (2025) | Introduces a multivariate wavelet shrinkage approach for quantile regression, improving accuracy in high-dimensional data. |
| Zhou et al. (2025) | Integrates linear regression with machine learning techniques (PLS, DT) for real-time environmental monitoring of chemical degradation. |
| Zhong et al. (2025) | Uses multiple linear regression to analyze factors influencing nurses’ attitudes and practices in postural management of premature infants. |
| Liu et al. (2025) | Applies regression analysis to evaluate research capabilities of pediatric clinical nurses, identifying key influencing factors. |
| Dietze et al. (2025) | Examines the impact of opioid overdose prevention training using multivariable regression, evaluating demographic influences on knowledge retention. |
| Ming-jun & Jian-ya (2025) | Constructs multiple linear regression models to analyze the economic effects of environmental taxation policies. |
| Hasan & Ghosal (2025) | Uses regression techniques to quantify inequities in healthcare access, identifying determinants like affordability and availability. |
| Zeng et al. (2025) | Employs LASSO regression for maize yield prediction, integrating remote sensing data for enhanced agricultural forecasting. |
| Baird et al. (2025) | Uses AI-driven regression to analyze orthopedic surgery trends, particularly in ACL reconstruction and hip arthroscopy. |
| Overton & Eicker (2025) | Applies linear and logistic regression to assess fertility and milk production efficiency in Holstein dairy cows. |
Figure 160.
Framework of the Linear Regression. Image Credit: By Krishnavedala - Own work, CC BY-SA 3.0, https://commons.wikimedia.org/w/index.php?curid=15462765. In linear regression, an underlying relationship (blue) exists between the dependent variable (y) and the independent variable (x), with the observed data points (red) resulting from random variations (green) around this trend
16.2.7.3 Mathematical Analysis of Linear Regression
Linear regression is a fundamental statistical method used to model the relationship between a dependent variable y and one or more independent variables . The goal of linear regression is to determine the best-fitting linear function that describes this relationship by minimizing the error between the predicted values and the actual observations. In its most general form, the linear regression model can be written as
where y is the dependent variable, are the independent variables, is the intercept term, are the regression coefficients corresponding to each independent variable, and represents the error term, which accounts for the variability in y that is not explained by the independent variables. If there is only one independent variable, the model reduces to simple linear regression:
In matrix notation, for a dataset consisting of m observations, we define
 Thus, the linear regression model can be written compactly as
The fundamental objective of linear regression is to estimate the coefficient vector in such a way that the sum of squared errors (SSE) is minimized. The sum of squared errors is given by
In matrix form, the sum of squared errors can be written as
To find the optimal , we take the derivative of with respect to and set it equal to zero:
Solving for , we obtain the normal equation:
 If is invertible, the solution for is
The coefficient of determination is given by
The ridge regression estimate of is given by
while the Lasso regression estimate is obtained by solving
The linear regression model can also be extended to a probabilistic framework:
which allows for Bayesian interpretations where a prior distribution is placed on and updated using observed data to obtain a posterior distribution, leading to Bayesian linear regression.
Figure 161.
Simple Linear Regression. Image Credit: By Sewaqu - Own work, Public Domain, https://commons.wikimedia.org/w/index.php?curid=11967659. This is an example of simple linear regression, characterized by having only one independent variable.
Figure 161.
Simple Linear Regression. Image Credit: By Sewaqu - Own work, Public Domain, https://commons.wikimedia.org/w/index.php?curid=11967659. This is an example of simple linear regression, characterized by having only one independent variable.
Figure 162.
Cubic Polynomial Regression. Image Credit: By Skbkekas - Own work, CC BY 3.0, https://commons.wikimedia.org/w/index.php?curid=6457163. This example demonstrates cubic polynomial regression, which falls under the category of linear regression. Although it models data with a curved function, it is considered statistically linear because the regression function depends linearly on the unknown parameters being estimated. Therefore, polynomial regression is recognized as a specific form of multiple linear regression
16.2.8. Logistic Regression
16.2.8.1 Literature Review of Logistic Regression
Logistic regression has evolved through a rigorous theoretical foundation established by key contributions in statistics, probability modeling, and machine learning. The earliest seminal work by Cox (1958) [804] introduced the logistic function as a probability model for binary outcomes, rigorously deriving the logit transformation to linearize the probability structure and enable the use of maximum likelihood estimation (MLE) for parameter inference. This foundational work not only formalized the statistical methodology but also provided a justification for using logistic regression over linear probability models, addressing issues such as non-linearity and heteroskedasticity. Later, Nelder and Wedderburn (1972) [806] expanded upon this foundation by introducing Generalized Linear Models (GLMs), of which logistic regression is a specific case. Their work rigorously defined the role of exponential family distributions, formalizing the link function approach and introducing a unified statistical framework where regression models could be generalized beyond normally distributed response variables. This pivotal development allowed logistic regression to be understood within a broader statistical paradigm, establishing it as a standard technique for binary classification.
Subsequent research focused on model assessment and diagnostic methods to ensure the reliability of logistic regression results. Haberman (1990) [807] rigorously developed deviance-based tests, allowing analysts to assess goodness-of-fit and compare nested models using likelihood ratio tests. This work introduced the notion of model adequacy beyond traditional R-squared metrics used in linear regression. Similarly, Hosmer and Lemeshow (1980) [808] introduced the Hosmer-Lemeshow test, which rigorously quantified calibration errors by partitioning observations into quantile groups and comparing predicted and observed probabilities. Their methodology provided a practical yet statistically rigorous tool for validating logistic regression models in real-world applications. The rigorous mathematical structure of logistic regression was further explored by McCullagh (2019) [809], who formalized the theory of iteratively reweighted least squares (IRLS) for estimating model parameters and proved asymptotic properties of logistic regression coefficients. Their contributions solidified logistic regression as a theoretically sound and computationally efficient method in statistical modeling.
With the increasing complexity of datasets and computational advancements, logistic regression was further extended into machine learning and regularization frameworks. Hastie, Tibshirani, and Friedman (2001) [139] rigorously analyzed logistic regression as a classification tool, comparing it with support vector machines (SVMs) and decision trees. They introduced regularization techniques, such as ridge regression (L2 penalty) and LASSO (L1 penalty), to combat issues of overfitting and multicollinearity. In parallel, Green and Silverman (1994) expanded logistic regression to nonparametric settings, developing methods for spline smoothing and kernel-based regression, allowing the model to capture nonlinear relationships without relying on rigid parametric assumptions. Another significant computational advancement came from Firth (1993) [810], who proposed a bias reduction method using penalized maximum likelihood estimation (PMLE). This technique, known as Firth’s logistic regression, rigorously mitigates the small-sample bias that arises in rare event classification by modifying the score equations of MLE, thereby preventing infinite estimates in perfectly separated data.
Finally, extensions of logistic regression into hierarchical and Bayesian settings have been rigorously explored to account for structured data and uncertainty in parameter estimation. King and Zeng (2001) [811] addressed a fundamental issue in rare event data, where traditional logistic regression tends to underestimate event probabilities due to data imbalance. Their corrected probability estimation approach adjusted the likelihood function to provide more accurate parameter estimates in imbalanced datasets, such as those found in epidemiology and fraud detection. Gelman and Hill (2007) [812] extended logistic regression into Bayesian hierarchical models, introducing random effects logistic regression to handle grouped data structures. They rigorously developed Bayesian priors for logistic regression coefficients, allowing for shrinkage estimation and improved parameter stability in small-sample settings. These contributions have collectively transformed logistic regression from a simple binary classification method into a statistically rigorous, computationally efficient, and widely applicable tool used in fields ranging from biomedical sciences to artificial intelligence.
Table 29.
Summary of Contributions in Logistic Regression
| Reference | Contribution |
|---|---|
| Cox (1958) | Formulated logistic regression using the logit function and MLE. |
| Nelder & Wedderburn (1972) | Introduced GLMs, formalizing logistic regression in a unified |
| statistical framework. | |
| Haberman (1973) | Developed deviance tests for logistic regression goodness-of-fit. |
| Hosmer & Lemeshow (1980) | Introduced the Hosmer-Lemeshow test for model calibration. |
| McCullagh & Nelder (1983) | Provided a rigorous theoretical foundation for GLMs, including |
| logistic regression. | |
| Hastie, Tibshirani & Friedman (2001) | Discussed regularization methods and logistic regression in the |
| context of statistical learning. | |
| Green & Silverman (1994) | Extended logistic regression to nonparametric settings. |
| Firth (1993) | Proposed bias reduction techniques for small-sample logistic |
| regression (Firth’s correction). | |
| King & Zeng (2001) | Addressed logistic regression’s biases in rare event data. |
| Gelman & Hill (2007) | Developed Bayesian and hierarchical logistic regression models. |
16.2.8.2 Recent Literature Review of Logistic Regression
Logistic regression is widely used across diverse fields for modeling binary outcomes, and the latest research underscores its broad applicability. For instance, Sani et al. (2025) [813] applied logistic regression to analyze sociodemographic factors affecting contraceptive use among Nigerian women, revealing significant regional disparities. Their findings indicate that education and economic status strongly influence contraceptive intent, offering insights for public health interventions. Similarly, Dorsey et al. (2025) [814] employed logistic regression to investigate how piping plovers select nesting sites, demonstrating that broader viewsheds enhance predator detection and nest survival. This study contributes to ecological conservation by highlighting the role of visibility in avian habitat selection. In the realm of linguistics, Slawny et al. (2025) [815] leveraged logistic regression to explore the impact of language dominance and ability on bilingual parent-child communication, showing that linguistic environments significantly shape language transmission patterns within families.
In medical research, logistic regression plays a crucial role in identifying risk factors for diseases and treatment outcomes. Waller et al. (2025) [815] utilized logistic regression to examine the association between maternal diarrhea during the periconceptional period and birth defects, identifying key risk factors for fetal abnormalities. Similarly, Beyeler et al. (2025) [817] investigated the susceptibility vessel sign (SVS) in stroke patients undergoing thrombectomy, demonstrating that certain SVS characteristics significantly influence treatment efficacy. Another notable study by Yedavalli et al. (2025) [818] applied logistic regression to assess the relationship between hypoperfusion intensity and stroke recovery, revealing that a hypoperfusion intensity ratio below 0.4 correlates with favorable patient outcomes. These findings are critical in guiding clinical decisions for ischemic stroke treatment. Ghosh (2020) [1385] discussed an attempted proof of the Riemann Hypothesis, a central unsolved problem in number theory concerning the nontrivial zeros of the Riemann zeta function. It aimed to provide a theoretical justification for why all nontrivial zeros should have a real part equal to one-half. The work reflects an effort to contribute to one of mathematics’ most significant and long-standing open problems. Additionally, Yang et al. (2025) [820] explored the link between left ventricular function and cerebral small vessel disease, showing that cardiac health can serve as a biomarker for neurological risks. This research advances our understanding of cardiovascular-neurological interactions and their implications for stroke prevention.
Beyond healthcare, logistic regression is instrumental in behavio