

Submitted:
26 October 2026
Posted:
27 October 2026
You are already at the latest version
Abstract
Students receive assessment deadlines inside course syllabi, usually as PDFs, and a growing number of tools use large language models (LLMs) to turn these documents into calendars. A common cost-saving design runs cheap rules first and calls the LLM only when the rules appear to fail. We test whether this saves money without losing accuracy. We compare five strategies on 16 public syllabi from eight institutions (151 hand-verified deadlines): regular-expression rules, a general-purpose date library, an LLM given the native PDF, an LLM given text extracted from the PDF, and a rule-first hybrid that calls the LLM only when the rules find fewer than three events. Each LLM strategy was run three times with gemini-3.1-flash-lite. The LLM strategies reached F1 scores of 0.708 (native PDF) and 0.657 (extracted text); the difference was not significant (p = 0.13), and the native-PDF input used fewer tokens with this model. The rule-first hybrid used 57.8% fewer tokens than the text-based LLM but lowered F1 to 0.370, a significant loss (p = 0.002). Rules alone scored 0.186, and 58% of their correctly placed month-day matches carried the wrong year. A sweep of the hybrid's routing threshold shows that every token saved cost accuracy. We release the code, labels, and all predictions.
Keywords:
large language models
; information extraction
; PDF processing
; cost-efficient inference
; LLM cascades
; temporal expressions
1. Introduction
Course syllabi are the main source of assessment deadlines for university students, but they arrive in inconsistent formats: tables, week-by-week schedules, calendar grids, slides, and prose. Several student tools now extract deadlines automatically by sending syllabus content to an LLM. Because LLM calls cost money per token, a natural engineering choice is a cheap-first design: run deterministic rules first, and call the LLM only when the rules seem to fail. The same idea underlies LLM cascades, which route easy queries to cheaper models [1].
Whether cheap-first works depends on two things: how much the rules save, and how reliably the system can tell when the rules have failed. We found no controlled study that measures both cost and accuracy for syllabus deadline extraction. Practitioner write-ups claim large savings from sending extracted text instead of native PDFs, but without matched accuracy measurements.
This paper makes three contributions:
- 1.
- A labelled benchmark of 16 public syllabi from eight North American institutions with 151 hand-verified deadlines, including deliberately difficult cases (calendar grids, a syllabus with no fixed dates, and source-document errors).
- 2.
- A controlled comparison of five extraction strategies on token cost, latency, and accuracy, with three repeats per LLM strategy and significance tests.
- 3.
- An error analysis showing that wrong-year inference dominates rule-based failures, that text extraction loses dates printed in calendar grids, and that a rule’s output size is a poor signal of its correctness.
The extraction code under test comes from GRYPH OS, an open-source student planning tool built during a 24-hour hackathon. Strategies B and C reuse its code unchanged so that the results describe a real deployed design.
2. Related Work
LLM cascades. FrugalGPT [1] routes queries through a sequence of models of increasing cost and stops when a learned scorer judges an answer reliable, reporting large cost reductions. RouteLLM [7] likewise learns routers from preference data to choose between a stronger and a weaker model. Our hybrid strategy is a simpler cascade whose first stage is a rule system and whose stopping rule is a fixed threshold rather than a learned scorer. We test whether such a simple rule is enough.
Temporal expression extraction. Rule-based temporal taggers such as HeidelTime [2] and SUTime [3] recognise and normalise date expressions in text. We include the Python library dateparser [4] as a runnable general-purpose baseline. Deadline extraction is harder than temporal tagging because a document contains many dates that are not deadlines.
LLM extraction from PDFs. Recent work extracts structured metadata from scientific PDFs with LLMs and compares parsers on speed and accuracy [5], and hybrid OCR–LLM pipelines show that parser choice trades speed against accuracy, with tables breaking fast parsers [6]. Docling [8] is an open-source toolkit that converts PDFs into structured text with layout and table recognition. These studies do not compare native-PDF LLM input with extracted-text input on both cost and accuracy.
LLM information extraction and prompt cost. A survey of generative information extraction with LLMs [9] reviews how LLMs are used to extract structured information from text, and LLMLingua [10] reduces inference cost by compressing prompts. We do not compress prompts; we compare input formats and routing rules for one concrete extraction task.
Syllabus tools. We found no academic work on syllabus deadline extraction. Practitioner reports list common parser failures, including dates hidden in week labels, exam windows, and multi-part projects [12].
3. Strategies
All strategies output a list of events, each with a due date and a type (assignment, quiz, midterm, final, project, reading, or other).
- A: PDF→LLM. The binary PDF is sent to the model with GRYPH OS’s extraction prompt.
- B: text→LLM. Text is extracted with pypdf and sent to the model with the same prompt (capped at 30,000 characters). This is the pipeline GRYPH OS ships.
- C: regex. GRYPH OS’s rules: every line of extracted text is scanned with date patterns, and assessment keywords on the line set the event type. No LLM call.
- D: regex→LLM. Run C; if it finds fewer than three events, run B instead. This is the cheap-first design.
- E: dateparser. The same line loop as C, but dates are found with dateparser’s search_dates (day and month required). No LLM call.
The prompt asks the model to return JSON and to “infer the most likely upcoming year” when a year is missing. The rules (C, E) fill a missing year with the current calendar year. Both behaviours are inherited unchanged from GRYPH OS.
4. Method
4.1. Dataset
We collected 16 publicly accessible syllabi (Table 1) from Carleton University, the University of Calgary, Western University, the University of Texas at Austin, Midwestern State University, Richland Community College, Lamar State College Port Arthur, and the University of Wisconsin–Madison. They cover terms from 2016 to 2026, one to nine pages, and formats including tables, week-by-week schedules, calendar grids, lecture slides, and prose. The PDFs are not redistributed; the release lists each source URL with its SHA-256 checksum.
4.2. Labels
Gold labels contain only graded items with a specific date. Readings, lectures, withdrawal and refund dates, “no late work after” cut-offs, items marked TBD, and implicit recurring deadlines (“due every Sunday”) are excluded. For a window (“opens Feb 17, closes Feb 23”) the close date is used, and the year is taken from the stated term. Labels were pre-annotated by an LLM that is not under test (Anthropic Claude) and then checked against each PDF and corrected by the author. One syllabus (Wisconsin) prints no year; its year was taken from the source URL.
4.3. Metrics
We report precision, recall, and F1 on the set of due dates per syllabus, then average across syllabi. Because both the prompt and the rules guess missing years, which penalises past syllabi, we also report month-day F1, which ignores the year. For the syllabus with no fixed dates, F1 is 1 if nothing is predicted and 0 otherwise. Cost is measured as input plus output tokens from the API’s usage metadata; latency is wall-clock time.
4.4. Setup
All LLM calls used gemini-3.1-flash-lite, a model from Google’s Gemini family [11], through the google-genai SDK (2.33.0), with pypdf 6.21.2 and dateparser 1.4.3. All 240 jobs (16 syllabi × 5 strategies × 3 repeats) completed without errors on 25 October 2026. Differences are tested with a paired sign-flip permutation test (two-sided, 20,000 permutations) on per-syllabus F1, with bootstrap 95% confidence intervals (seed 0).
4.5. Use of AI Tools
Anthropic’s Claude (through Claude Code) was used in three ways: to pre-annotate the gold labels, which the author then checked line by line against each PDF and corrected; to write and run the benchmark code under the author’s direction; and to draft the text of this paper. Google’s Gemini model is the system under study. The author reviewed all text, checked every reported number against the saved outputs in the released repository, and is responsible for the final content. AI tools are not listed as authors.
5. Results
Native PDF versus extracted text. Over the 16 syllabi, strategy A used 43,360 tokens and strategy B used 57,490, so sending extracted text cost 32.6% more than sending the PDF. A scored 0.051 higher in F1, but this difference was not significant (Table 3). In a pilot on five syllabi with a different model (gemini-3.8-flash), text input was about 8% cheaper, so the direction of the cost difference depends on the model.
Cheap-first routing. The hybrid D used 57.8% fewer tokens than B, because the rules were trusted in 69% of runs. Its F1 fell from 0.657 to 0.370, a significant loss. When the rules were trusted, F1 was 0.179; when the hybrid fell back to the LLM, F1 was 0.789. The rules’ event count therefore did not indicate whether the rules were right.
Routing threshold. Because D’s fallback is exactly B, we simulated D for other thresholds k from the saved predictions of B and C, without new API calls. At the simulation reproduces the measured D (F1 0.369 versus 0.370). Table 4 and Figure 2 show that F1 rises steadily as more syllabi are sent to the LLM: no threshold achieves both low cost and high accuracy. Adding a cheap check that all rule-extracted dates fall in one calendar year raises F1 at from 0.369 to 0.441 while calling the LLM on 44% of runs.
Stability. Across the three repeats, the mean standard deviation of per-syllabus F1 was 0.010 for A and 0.029 for B, so the LLM results were stable.
6. Error Analysis and Discussion
Wrong year. Counting predicted dates whose month and day match a gold deadline, the year was wrong for 58% of matches from the rules (66 of 114) and 85% from dateparser (261 of 306), compared with 2% for A and B (9 of 415 and 9 of 385) and 18% for D. Missing years are filled with the current year, so a Spring 2025 syllabus processed in 2026 receives 2026 dates. The rules’ output therefore changes with the day they are run.
Rule failures. The rules also read a week range as a year (“11/24–28” became 24 November 2028), did not match year-less numeric dates such as “9/26” at all, misread day-first dates such as “17 February”, and kept only one event per date. dateparser found dates more often but could not tell deadlines from other dates, giving the lowest precision (0.049).
Calendar grids. Two Carleton syllabi print assignment due dates only inside a calendar grid. Text extraction keeps the label “Due Friday” but loses the date. Recall on these two syllabi was 0.78 for A against 0.52 and 0.11 for B, and 0 for every rule-based strategy.
False precision. One syllabus contains no fixed dates: tests are “TBD between October 16–18” and “November 27–29”, and the final is “TBD December 12–23”. In every repeat, all three LLM strategies returned exactly one date per window: B and D always chose the first day of each window, and A chose the last day in two of three repeats and the first day in the third. These dates are not invented, but they present an uncertain window as a fixed deadline, and which day is chosen varies with the input format and between runs. The rules correctly returned nothing.
Definition of a deadline. On the two Richland syllabi the LLM strategies also returned withdrawal and refund dates, and on the Lamar syllabus they returned implied weekly deadlines. Our labels exclude both, which lowered LLM precision; scores are sensitive to how “deadline” is defined.
Robustness to source errors. One schedule is headed “Spring 2025” but lists only August–December dates, and contains a typo (“9/30/1”). Strategies A and B still scored 1.00 and 0.98 on it.
Engineering observations. GRYPH OS’s default model (gemini-2.0-flash) had been retired by the time of the study, and its fallback to rules only covers rate-limit errors, so the deployed pipeline fails rather than degrading. Changing the pypdf version from 6.14.2 to 6.21.2 changed the number of rule-extracted events on the same PDFs several-fold (for example, from 2 to 27), because line breaks in the extracted text changed.
7. Limitations
The benchmark is small (16 syllabi), labelled by one annotator, mostly from computer science and science courses, in English, and from Canada and the United States. We tested one LLM family and one model in the main study; free-tier quotas and retired models limited the choice. Latency was measured on a free tier and is noisy. Implicit recurring deadlines were excluded from the labels, and one syllabus’s year came from its URL rather than its text. The hybrid’s fallback is fixed to one threshold rule; learned routers [1] may perform differently.
8. Conclusion
For syllabus deadline extraction, cheap-first routing was not free: running rules first saved 57.8% of tokens but lowered F1 from 0.657 to 0.370, and no routing threshold avoided this trade-off because the rules’ output size did not reveal when they had failed. Rule-based extraction failed mostly on years and layouts. Sending the native PDF to the LLM was at least as accurate as sending extracted text and, with the model tested, used fewer tokens. Systems that use rules to save LLM cost need a confidence signal that actually tracks correctness, such as the single-year check that improved the hybrid here.
Data and Code Availability
Code, labels, all predictions, and source URLs with checksums: https://github.com/SoumyA4348/syllabus-extraction-benchmark.
Author Contributions
S.P. conceived the research question, directed the project, validated the labels, and reviewed and edited the paper. Software development, data analysis, and the first draft of the text were carried out with Claude under the author’s direction (see Section IV-E). All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Acknowledgments
GRYPH OS was developed by the author and Manas Verma. The author used Anthropic’s Claude, an AI system, to pre-annotate labels, to write and run the benchmark code, and to draft the text of this paper. The author verified the labels, reviewed the paper, and takes responsibility for its content.
Conflicts of Interest
The author declares no conflicts of interest.
References
- Chen, L.; Zaharia, M.; Zou, J. FrugalGPT: How to use large language models while reducing cost and improving performance. arXiv 2023, arXiv:2305.05176. [Google Scholar]
- Strötgen, J.; Gertz, M. HeidelTime: High quality rule-based extraction and normalization of temporal expressions. Proc. 5th Int. Workshop on Semantic Evaluation (SemEval), 2010; pp. 321–324. [Google Scholar]
- Chang, A. X.; Manning, C. D. SUTime: A library for recognizing and normalizing time expressions. Proc. Language Resources and Evaluation Conf. (LREC), 2012. [Google Scholar]
- Scrapinghub, “dateparser: Python parser for human readable dates,” version 1.4.3. Available online: https://github.com/scrapinghub/dateparser.
- Alyafeai, Z.; Al-Shaibani, M. S.; Ghanem, B. MOLE: Metadata extraction and validation in scientific papers using LLMs. arXiv 2025, arXiv:2505.19800. [Google Scholar]
- Wang, Z.; Shen, X. Hybrid OCR-LLM framework for enterprise-scale document information extraction under copy-heavy task. arXiv 2025, arXiv:2510.10138. [Google Scholar]
- Ong, I.; et al. RouteLLM: Learning to route LLMs with preference data. arXiv 2024, arXiv:2406.18665. [Google Scholar]
- Auer, C.; et al. Docling technical report. arXiv 2024, arXiv:2408.09869. [Google Scholar]
- Xu, D.; et al. Large language models for generative information extraction: A survey. arXiv 2023, arXiv:2312.17617. [Google Scholar]
- Jiang, H.; Wu, Q.; Lin, C.-Y.; Yang, Y.; Qiu, L. LLMLingua: Compressing prompts for accelerated inference of large language models. arXiv 2023, arXiv:2310.05736. [Google Scholar]
- Gemini Team, Google, et al., Gemini 1.5: Unlocking multimodal understanding across millions of tokens of context. arXiv 2024, arXiv:2403.05530.
- Coursicle. Syllabus formats that break parsers. Available online: https://www.coursicle.com/blog/syllabus-formats-that-break-parsers/.
Figure 1.
Mean tokens per syllabus against mean F1 (± standard error across syllabi), with the full date (left) and month and day only (right).
Figure 1.
Mean tokens per syllabus against mean F1 (± standard error across syllabi), with the full date (left) and month and day only (right).
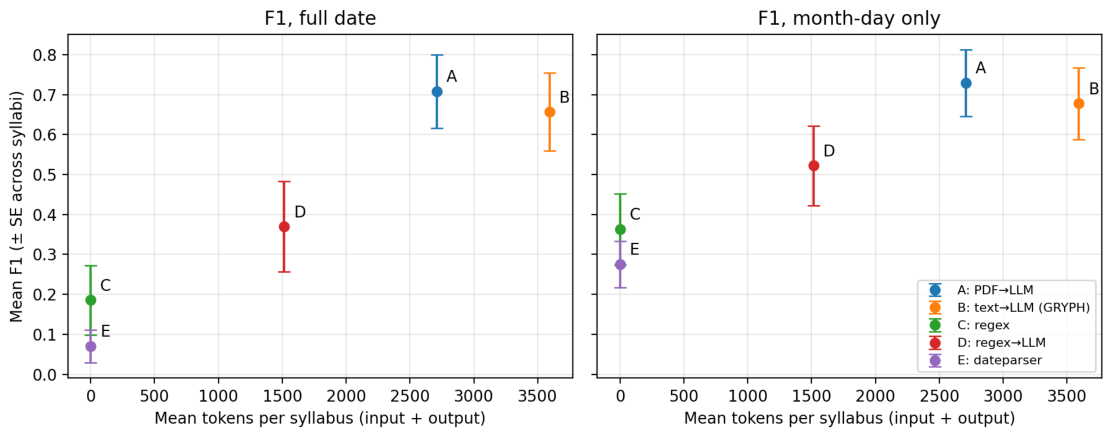
Figure 2.
Cost and accuracy of the simulated hybrid router for different thresholds.
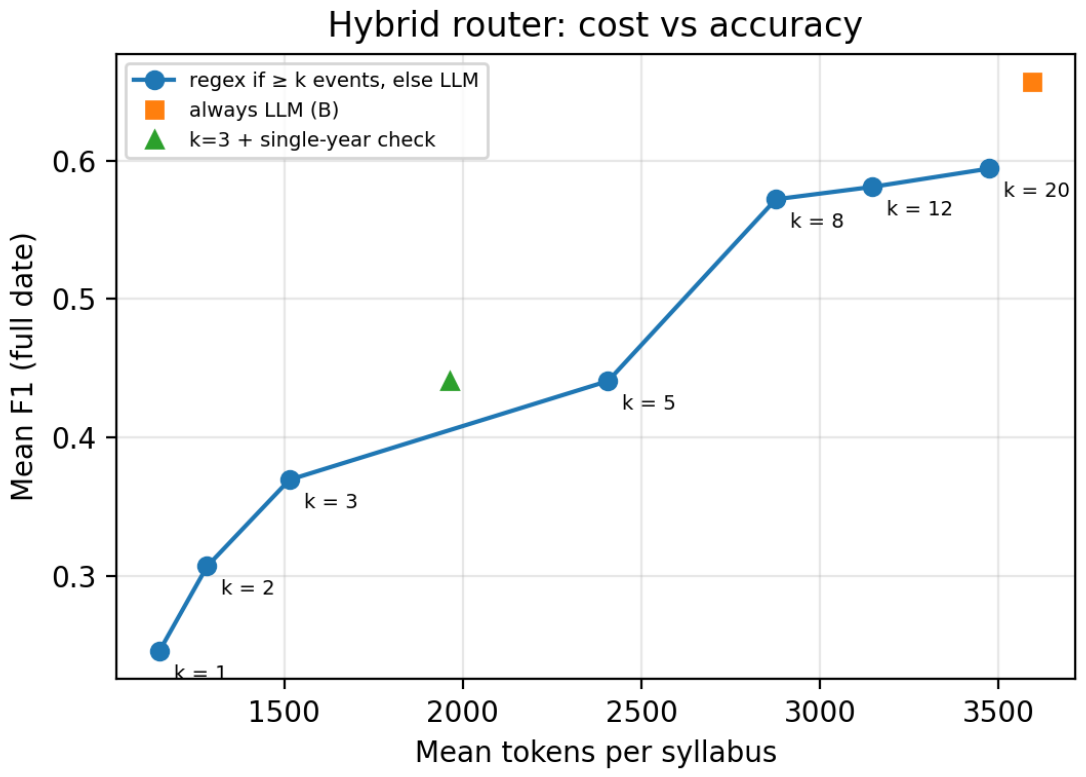

Table 1.
Dataset: 16 syllabi, 151 labelled deadlines (150 distinct dates).
| Syllabus | Pages | Events | Notable Feature |
|---|---|---|---|
| Carleton COMP 1005 (S25) | 5 | 7 | table |
| Carleton COMP 1405 (W25) | 6 | 9 | calendar grid |
| Carleton COMP 1405 (F25) | 6 | 9 | calendar grid |
| Carleton COMP 2401 (W25) | 5 | 3 | table |
| Carleton COMP 2402 (F26) | 9 | 0 | no fixed dates |
| Lamar BCIS 1305 (Su25) | 1 | 1 | weekly implicit |
| MSU Texas Biology (S25) | 2 | 15 | week windows |
| MSU Texas Schedule (F25) | 2 | 29 | mislabelled term |
| Richland Math 121 (F24) | 2 | 1 | prose |
| Richland Math 122 (S25) | 2 | 1 | prose |
| Calgary CPSC 217 (F25) | 4 | 2 | table |
| Calgary CPSC 217 (Su25) | 4 | 6 | table |
| UT Austin CS 303E (F25) | 2 | 22 | year-less m/d |
| UT Austin CS 303E (S25) | 2 | 24 | year-less m/d |
| Western CS 1033 (2026) | 6 | 19 | slides, 2 sections |
| Wisconsin Chem 345 (S16) | 1 | 3 | no year printed |
Table 2.
Results (mean over 16 syllabi; ± SD across syllabi).
| F1 | F1 | Tokens | LLM | Time | |
|---|---|---|---|---|---|
| Strategy | (Full Date) | (Month-Day) | /syll. | Called | (s) |
| A: PDF→LLM | 0.708±0.367 | 0.729 | 2,710 | 100% | 24.4 |
| B: text→LLM | 0.657±0.389 | 0.678 | 3,593 | 100% | 15.5 |
| D: regex→LLM | 0.370±0.453 | 0.522 | 1,515 | 31% | 2.0 |
| C: regex | 0.186±0.349 | 0.363 | 0 | 0% | 0.0 |
| E: dateparser | 0.070±0.163 | 0.275 | 0 | 0% | 0.7 |
Table 3.
Paired differences in per-syllabus F1 (full date).
| Comparison | Mean Diff. | 95% CI | p |
|---|---|---|---|
| A − B | [, ] | 0.126 | |
| B − D | [, ] | 0.002 | |
| A − D | [, ] | 0.001 | |
| D − C | [, ] | 0.377 | |
| C − E | [, ] | 0.126 |
Table 4.
Simulated hybrid router: trust rules if they find events.
| Router | F1 | F1 (m-d) | Tokens | LLM |
|---|---|---|---|---|
| 0.246 | 0.423 | 1,151 | 19% | |
| (measured D) | 0.369 | 0.522 | 1,514 | 31% |
| + year check | 0.441 | 0.531 | 1,963 | 44% |
| 0.441 | 0.574 | 2,407 | 50% | |
| 0.572 | 0.606 | 2,877 | 75% | |
| 0.594 | 0.645 | 3,474 | 94% | |
| Always LLM (= B) | 0.657 | 0.678 | 3,593 | 100% |
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (http://creativecommons.org/licenses/by/4.0/).
Copyright: This open access article is published under a Creative Commons CC BY 4.0 license, which permit the free download, distribution, and reuse, provided that the author and preprint are cited in any reuse.