

Submitted:
15 October 2026
Posted:
20 October 2026
You are already at the latest version
Abstract
The revised United States guidance on model risk management, issued in April 2026, applies its principles to traditional statistical and quantitative models and to non-generative, non-agentic AI models, and places generative and agentic AI explicitly outside its scope. This survey follows the models used against fraud and financial crime across that line, from rules, scorecards, and statistical tests, through non-generative machine learning, to generative models and language-model agents, across six fraud types. Unlike prior surveys, we place all three generations in one decision-theoretic frame: we restate in one notation known results on cost-optimal and capacity-constrained alerting, undersampling calibration, and the identifiability of recall from alert feedback, express each generation's model, explanation, and validation quantity in that frame, and add two stylized models, one showing why mean aggregation dilutes the neighborhood signal of camouflaged fraudsters and one showing how verifier independence bounds the residual errors in a generated narrative. We find that statistical models and non-generative machine learning have mature validation practice anchored in supervisory guidance, that generative AI now appears both as a tool of fraudsters and as a component of defenses, and that in hybrid pipelines the generative component can write what an analyst or examiner reads although no dedicated supervisory framework covers it. We therefore formalize the evidence-traceability controls that can supply this missing validation as a division of verification labor, between the drafting agent, a deterministic field check, an independent verifier and the human examiner, governed by three parameters an institution can estimate; we then compare the generations quantity by quantity and close with a research agenda.
Keywords:
fraud detection
; anti-money laundering
; model risk management
; machine learning
; large language model agents
; evidence traceability
; survey
1. Introduction
Fraud detection is one of the oldest applications of statistical learning in finance. Bolton and Hand reviewed the statistical tools in use more than two decades ago [1]; tree ensembles, sequence models, and graph neural networks then became standard for card fraud and money laundering [2,3,4]; and generative models and language-model agents have since entered both the defenses [5,6,7] and the attacks [8,9]. Each generation has been absorbed into the cooperative work of fraud operations, in which models raise alerts, analysts investigate them, and supervisors examine both.
In April 2026 the US banking agencies replaced their model-risk guidance [10,11]; the revision places generative and agentic AI outside its scope and applies to traditional statistical models and non-generative, non-agentic AI models [10]. This boundary separates the generations by how they are governed as well as by how they work.
Existing surveys cover one generation or one fraud type: statistical detection [1], computational intelligence for financial fraud [2], anomaly detection [3], graph neural networks [4] and machine learning for anti-money laundering [12]. They describe methods but rarely state the decision problem the methods solve, which makes generations hard to compare. We therefore ask: RQ1, where does each generation fall relative to the April 2026 model-risk boundary, and across which fraud types is each documented? RQ2, placed in one decision-theoretic frame, what can validation measure for each generation and what can it not? RQ3, which controls, and which division of verification labor between agent, checker, verifier and examiner, can supply the validation the third generation lacks? Figure 1 and Table 1 answer RQ1, Table 2 RQ2, and Section VI RQ3. The review contributes a bounded synthesis in one notation, restating known results with their sources and adding two stylized models of recurring failures, one of them locating the errors that survive into a filing in the information flow between drafter, verifier and examiner, rather than a new detection method.
Scope and method. We searched the ACL Anthology, ACM and IEEE digital libraries, NeurIPS, ICML and ICLR proceedings, statistics and accounting journals, arXiv, and supervisory publications, combining fraud-type terms (card fraud, money laundering, application fraud, scam, insurance fraud, financial-statement fraud) with model terms (rule, scorecard, logistic, boosting, sequence, graph neural network, language model, agent). We retained peer-reviewed work and official publications that propose, evaluate or govern a fraud model, admitting preprints only for generative and agentic systems where peer-reviewed work is still scarce. The resulting corpus is 51 works from 1952 to September 2026: 34 peer-reviewed papers, 8 supervisory or official publications and 9 preprints, each checked against its publisher or archive record. The survey is selective rather than exhaustive.
2. Fraud Types and Governance Regimes
We distinguish six fraud types by the data that reveal them. Card and payment fraud appears in transaction streams and is decided in real time. Money laundering appears in flows across accounts and leads to suspicious-activity reporting [33,34]. Application and identity fraud occurs at onboarding, increasingly with forged documents and synthetic media [25,26]. Scams and social engineering trick customers into authorizing payments themselves; the UK regulator defines authorized push payment fraud this way and has mandated victim reimbursement [35]. Insurance fraud appears in claims [28] and financial-statement fraud in accounting data [29,30].
The 2011 guidance defined a model as a quantitative method applying statistical, economic, financial or mathematical theories to produce quantitative estimates, including approaches whose inputs rest partly or wholly on expert judgment [11]. Its 2026 replacement, which is explicitly non-binding, narrows this to complex quantitative methods, excludes simple calculations and deterministic rule-based processes without an underlying theory, retains effective challenge by objective experts, and organizes expectations around development, validation, outcomes analysis, monitoring and governance [10]. Because it superseded the 2021 statement on anti-money-laundering systems without replacement [20], whether a transaction-monitoring system is a model is now judged only against the general definition. The EU AI Act requires oversight of high-risk systems but its credit-scoring category expressly excepts systems used to detect financial fraud [36]. Generative components of fraud pipelines thus fall outside the US guidance and outside the EU high-risk obligations, and are left to banks’ general risk governance, to which the 2026 guidance expressly defers [10].
3. A Common Decision-Theoretic Frame
Let a case (a transaction, account, claim, or filing) have features and label , with for fraud and prior . A model produces a score , ideally the posterior , and the alert policy sends a case to an analyst. Let be the cost of a missed fraud, the cost of a false alert, and k the number of cases the analysts can review per period.
Proposition 1
(Cost-optimal alert rule [37]). Suppose an alert on a legitimate case costs , an alert on a fraud costs nothing, and a missed fraud costs . Without a capacity limit, the policy minimizing expected cost alerts exactly when
Proof.
For a fixed x, alerting costs in expectation and not alerting costs . Alerting is no worse iff , i.e., ; since the choice for each x is separable, the pointwise rule minimizes the total expected cost. □
Proposition 2
(Capacity-constrained alerting, a standard exchange argument). Among n cases with posteriors and at most k reviews, the expected number of frauds reviewed, , is maximized by reviewing the k cases with the largest . If fraud i carries loss , the expected loss prevented is maximized by ranking on .
Proof.
Swapping a reviewed j for an unreviewed i with raises the objective by ; likewise with . □
Proposition 1 explains why fraud thresholds sit far below , since , and Proposition 2 explains why operations rank rather than threshold when analysts are the bottleneck. Both require to order, and for (1) to be calibrated to, the true posterior. We evaluate every generation by how it produces s, how s is explained, and how its quality is validated, using precision at k, for the alerted set A with , and recall, .
4. Generation 1: Rules and Statistical Models
Rules. A rule is a conjunction of thresholds, , an axis-aligned region fixed by experts. Its explanation is the rule itself, and it is also its weakness: because the rule fires only if every condition holds, a fraudster who infers one threshold can keep just below it, for example by structuring amounts, avoiding detection at the cost of splitting or capping the transaction rather than abandoning it; Bolton and Hand stress that fraudsters adapt to the methods used against them [1]. Ghosh and Reilly benchmarked an early neural network against an issuer’s rules and reported substantially more fraud detected with fewer false positives [13].
Statistical scores. Logistic models write the log-odds as linear,
which in scorecard practice is rescaled to points as with , so that every PDO points double the odds, and each coefficient is a per-feature explanation. Viaene et al. found such models as accurate as more complex classifiers on insurance claims [28]. For financial statements, the M-score fits a probit, , on accounting ratios [29], and the F-score a logistic model [30]. Benford tests compare the first-digit frequencies of reported figures with , [31], for example through . Under the 2026 guidance, statistically estimated scores would typically meet the definition of a model, whereas deterministic rules without an underlying theory do not [10].
5. Generation 2: Non-Generative Machine Learning
Boosted trees and aggregation. Aggregating a card’s transactions over time windows improved detection over single transactions, with random forests best [14], and gradient-boosted trees became widely used [38]. Boosting builds by minimizing a second-order expansion of the regularized loss. With and at , a tree with leaves and weights minimizes with and , giving
by setting the derivative in each to zero [38]; for the logistic loss and with . Bao et al. showed that ensemble learning on raw accounting data outperformed ratio-based statistical models for financial-statement fraud [32].
Imbalance and calibration. Because is tiny, practitioners undersample legitimate cases, which distorts the scores that (1) needs.
Proposition 3
Proof.
By Bayes’ rule on the sample, . Rearranging gives , which is (4). □
Because is increasing in p, the unweighted top-k of Proposition 2 is unchanged, but the value-weighted ranking on requires the corrected p of (4), and thresholds set by (1) on uncorrected scores alert too often, because with a gap that widens as .
Feedback, drift, and the limits of validation. Dal Pozzolo et al. modeled card fraud with imbalance, drift, and verification latency, where investigators label only alerted transactions [15]. This feedback structure limits what outcomes analysis can establish.
Proposition 4
(Recall is not identifiable from alert feedback [40]). If labels are observed only on the alerted set A, then is identified but, without assumptions on the unalerted cases, R is not. If additionally each unalerted case is audited independently with probability , then , summed over the audited set , is unbiased for the number of missed frauds , and , with , satisfies in probability as with and the fraud rate in held fixed.
Proof.
Two populations that agree on and differ only in the labels of produce identical observations and identical , yet differs whenever M differs, so R is not a function of the observations. With audit indicators , , the Horvitz–Thompson argument. Since the are independent, , so in probability by Chebyshev’s inequality as M grows linearly in n, and follows by continuity. □
Without audits, R is identified only if scores are calibrated on , which alert feedback cannot test. Hence audits or synthetic data with complete labels [22,25] are needed before a detector’s miss rate can be validated in outcomes analysis [10].
Sequences and graphs. An LSTM over transaction sequences detected consistently different frauds from a random forest [16], and TabFormer applied BERT-style transformers to transaction sequences, with a GPT-style variant for synthetic data [17]. Graph neural networks update node v as , which Weber et al. benchmarked on the Elliptic Bitcoin graph [21]. Fraudsters respond by connecting to legitimate accounts.
Proposition 5
(Camouflage dilutes the neighbor term). Let neighbor embeddings have mean for fraudulent and for legitimate neighbors, unaffected by the camouflage, and let a fraudulent node have f fraudulent and b legitimate neighbors, . The expected neighbor term of the update is with , so its separation from that of a node with is , which decays as as the fraudster adds b legitimate neighbors; the self term is unaffected.
Proof.
By linearity of expectation, the mean over neighbors has expectation ; subtracting and applying the linear map gives the result. The statement concerns expectations only. □
Dou et al. identified this camouflage as a failure of graph fraud detectors and countered it in CARE-GNN by filtering neighbors by similarity, on review and e-commerce fraud data [41].
Attribution as explanation. Opaque models are explained post hoc, most often by SHAP [42], assigning feature i the Shapley value
where is the expected model output given the features in S, and satisfies local accuracy, . The attribution is thus an exact decomposition of for the chosen definition of , computed exactly for trees and approximately by sampling methods, which makes it checkable against the model, although about half of the machine-learning methods in anti-money-laundering work were not interpretable [12] and fraud analysts did not benefit from post-hoc explanations in a realistic study [43].
6. Generation 3: Generative and Agentic Models
As an attack tool. FinCEN alerted institutions to deepfake media used against identity verification [8], and identity-document attacks have moved from manual forgery to foundation models [26]. In a 112-participant study, fully LLM-generated phishing emails drew more clicks than generic ones, and those built on a designed template more still [9]. Such attacks move fraud to payments the victim authorizes and identities that pass verification, where from transaction features carries little signal because the payment itself looks legitimate.
As a defense. A payment network reported a foundation model pre-trained on large transaction streams [7]. LLMs on serialized fraud tables still trailed specialized classifiers [18] but were combined with rules or classifiers against evolving scam calls [27], and agents reached the investigation stage, drafting suspicious-activity narratives [5], investigating card-fraud cases [6] and triaging alerts under evidence constraints [23].
The hybrid pipeline. A common pattern stacks a generative component on a second-generation detector. Zhang et al. turned SHAP attributions of a money-mule classifier into narratives in a live deployment [24], and Sharma found on 60 balanced synthetic cases that an added investigation agent decided less accurately than a threshold on the classifier score while producing coherent rationales [19]. The detector is within model-risk guidance and the narrator outside it, yet the narrative is what the analyst reads. Unlike (5), whose terms sum exactly to the score, a generated rationale need not reflect the computation that produced the decision [44], so its faithfulness must be measured from outside.
7. Formalizing Evidence Traceability
Definition 1
(Traceability metrics). A report contains claims , emitted as structured tuples, each citing a record and asserting field values . Let be the set of records the agent’s tool calls returned, the record store, and the reference evidence set. Define grounding , field accuracy , and evidence recall .
With claims emitted as structured (record, field, value) tuples, G and are computable without labels and without a model; extracting them from free text would itself need a model. Only needs a reference set, which synthetic generators with known laundering patterns supply [22]. Torres et al. already checked that cited identifiers exist [23], a test of G; adds the field-level comparison. Neither checks inferential claims, such as whether a set of flows constitutes a typology, nor whether the rationale is faithful to the process that produced the decision. Within those limits they play the role of outcomes analysis for a component whose output is text, and retrieval alone does not guarantee them: commercial retrieval-based legal research tools still hallucinated in 17% to 33% of queries [45].
How much can verification remove? Self-correction without external feedback often failed [46] while debate among agents improved factuality [47]; a stylized model makes independence explicit.
Proposition 6
(Residual error under a stylized verification model). Assume that each of m claims is erroneous with probability ε, regardless of type; that a fraction κ of claims are record-level and checked exactly against ; that each remaining erroneous claim is missed by the verifier with probability , where with probability ω the verifier adopts the drafter’s conclusion and otherwise detects the error with miss rate η; and that an analyst, independently of the verifier, catches a surviving error with probability α. Then the expected number of errors reaching the filing is
Proof.
Under these assumptions an erroneous record-level claim is removed with probability one. For any other erroneous claim, conditioning on whether the verifier adopts the drafter’s conclusion gives a miss probability by the law of total probability; the independent analyst stage multiplies by . Summing over m claims by linearity of expectation yields (6). □
Corollary 1.
If self-verification is modeled as , it removes nothing beyond exact checks and the analyst, and (6) becomes . Reducing ω, for example by withholding the drafter’s trace and conclusion, helps only if it does not raise η proportionally, which is an empirical question; raising κ by making claims record-level helps without that caveat.
The corollary restates effective challenge by objective experts [10] as a requirement on information flow. The term deserves equal care: automation bias causes errors training alone does not prevent [48] and explanations raised acceptance whether or not the advice was correct [49], so a fluent narrative can lower it. Execution provenance, the typed graph of an agent’s run [50], is what lets an examiner recompute G and afterwards.
The three parameters are measurable. Each of , and in (6) names a quantity an institution can estimate: by withholding the drafter’s trace and comparing agreement rates, by injecting known field errors, by seeding flagged drafts into a review queue. None is reported in the work surveyed, though the surrounding facts are: investigators’ decisions are a fraud model’s only labels [15], and fraud analysts did not benefit from post-hoc explanations in a realistic study [43].
8. Comparative Analysis
Table 2 summarizes the comparison and answers RQ2; three patterns follow from it.
Explanations lose their guarantee. From the model itself, to an exact decomposition of the score, to text with no such identity, each step gains readability and loses verifiability, so validation must move from the explanation to the evidence it cites, which G and measure.
Validation is bounded by feedback. Calibration and precision are measurable from reviewed alerts but recall is not (Proposition 4), so every generation needs audits or complete synthetic labels to be validated on misses.
9. Open Challenges and Research Agenda
Validation concepts for generative components. Conceptual soundness, outcomes analysis, monitoring and effective challenge need counterparts for narrative outputs; G, , , consistency across runs and the verifier independence are candidates, and a narrator should be tested against the detector it describes, for example by checking that the features it names carry the largest in (5).
Detection and benchmarks across generations. When from transactions is uninformative, models must combine transaction, document, voice and communication evidence; generators with complete labels [22] could add reference evidence and narratives so all generations are compared on the same cases, recall included.
10. Conclusion
Placing all three generations in one decision frame shows what each can validate: thresholds and precision for the first, calibration and, with audits, recall for the second, and for the third only the evidence its narratives cite. Because the 2026 US boundary leaves the third generation outside its scope, grounding, field accuracy and verifier independence are controls the field must build and measure itself.
References
- Bolton, R.J.; Hand, D.J. Statistical Fraud Detection: A Review. Stat. Sci. 2002, 17, 235–249. [Google Scholar] [CrossRef]
- West, J.; Bhattacharya, M. Intelligent Financial Fraud Detection: A Comprehensive Review. Comput. Secur. 2016, 57, 47–66. [Google Scholar] [CrossRef]
- Hilal, W.; Gadsden, S.A.; Yawney, J. Financial Fraud: A Review of Anomaly Detection Techniques and Recent Advances. Expert Syst. With Appl. 2022, 193, 116429. [Google Scholar] [CrossRef]
- Cheng, D.; Zou, Y.; Xiang, S.; Jiang, C. Graph Neural Networks for Financial Fraud Detection: A Review. Front. Comput. Sci. 2025, 19, 199609. [Google Scholar] [CrossRef]
- Naik, P.V.; Dintakurthi, N.K.; Hu, Z.; Wang, Y.; Qiu, R. Co-Investigator AI: The Rise of Agentic AI for Smarter, Trustworthy AML Compliance Narratives. arXiv 2025, arXiv:2509.08380. [Google Scholar]
- Shuster, S.; Zloof, E.; Shabtai, A.; Puzis, R. FAA Framework: A Large Language Model-Based Approach for Credit Card Fraud Investigations. arXiv 2025, arXiv:2506.11635. [Google Scholar]
- Yeh, C.C.M.; Saini, U.S.; Dai, X.; et al. TREASURE: The Visa Payment Foundation Model for High-Volume Transaction Understanding. arXiv 2025. [Google Scholar]
- Network, Financial Crimes Enforcement. FinCEN Alert on Fraud Schemes Involving Deepfake Media Targeting Financial Institutions. FIN-2024-Alert004; U.S. Dept. of the Treasury. 13 Nov. 2024, 2024. [Google Scholar]
- Heiding, F.; Schneier, B.; Vishwanath, A.; Bernstein, J.; Park, P.S. Devising and Detecting Phishing Emails Using Large Language Models. IEEE Access 2024, 12, 42131–42146. [Google Scholar] [CrossRef]
- Board of Governors of the Federal Reserve System. SR 26-2: Revised Guidance on Model Risk Management. Superv. Regul. Lett. (jointly with OCC and FDIC) 17 Apr. 2026, 2026. [Google Scholar] [CrossRef]
- Board of Governors of the Federal Reserve System.; Office of the Comptroller of the Currency. SR 11-7: Guidance on Model Risk Management superseded by SR 26-2, Apr. 2026. Superv. Regul. Lett. 2011. [Google Scholar]
- Kute, D.V.; Pradhan, B.; Shukla, N.; Alamri, A. Deep Learning and Explainable Artificial Intelligence Techniques Applied for Detecting Money Laundering–A Critical Review. IEEE Access 2021, 9, 82300–82317. [Google Scholar] [CrossRef]
- Ghosh, S.; Reilly, D.L. Credit Card Fraud Detection with a Neural-Network. In Proceedings of the Proc. 27th Hawaii International Conference on System Sciences (HICSS), 1994; pp. 621–630. [Google Scholar] [CrossRef]
- Whitrow, C.; Hand, D.J.; Juszczak, P.; Weston, D.J.; Adams, N.M. Transaction Aggregation as a Strategy for Credit Card Fraud Detection. Data Min. Knowl. Discov. 2009, 18, 30–55. [Google Scholar] [CrossRef]
- Dal Pozzolo, A.; Boracchi, G.; Caelen, O.; Alippi, C.; Bontempi, G. Credit Card Fraud Detection: A Realistic Modeling and a Novel Learning Strategy. IEEE Trans. Neural Netw. Learn. Syst. 2018, 29, 3784–3797. [Google Scholar] [CrossRef] [PubMed]
- Jurgovsky, J.; Granitzer, M.; Ziegler, K.; Calabretto, S.; Portier, P.E.; He-Guelton, L.; Caelen, O. Sequence Classification for Credit-Card Fraud Detection. Expert Syst. With Appl. 2018, 100, 234–245. [Google Scholar] [CrossRef]
- Padhi, I.; Schiff, Y.; Melnyk, I.; Rigotti, M.; Mroueh, Y.; Dognin, P.; Ross, J.; Nair, R.; Altman, E. Tabular Transformers for Modeling Multivariate Time Series. In Proceedings of the Proc. IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), 2021; pp. 3565–3569. [Google Scholar]
- Tan, X.; Ma, Y.; Zhang, X. Understanding Structured Financial Data with LLMs: A Case Study on Fraud Detection. In Proceedings of the Proc. 64th Annual Meeting of the Association for Computational Linguistics (ACL), Long Papers, 2026; pp. 23375–23390, [2512.13040. [Google Scholar] [CrossRef]
- Sharma, R. Toward Auditable Fraud Detection: Combining Graph Features, Model Explanations, and Agentic Case Investigation. arXiv 2026, arXiv:2607.19266. [Google Scholar]
- Board of Governors of the Federal Reserve System.; Federal Deposit Insurance Corporation.; Office of the Comptroller of the Currency. SR 21-8: Interagency Statement on Model Risk Management for Bank Systems Supporting Bank Secrecy Act/Anti-Money Laundering Compliance. Superv. Regul. Lett. 9 Apr. 2021 (superseded by SR 26-2, Apr. 2026), 2021. [Google Scholar]
- Weber, M.; Domeniconi, G.; Chen, J.; Weidele, D.K.I.; Bellei, C.; Robinson, T.; Leiserson, C.E. Anti-Money Laundering in Bitcoin: Experimenting with Graph Convolutional Networks for Financial Forensics. KDD 2019 Workshop Anom. Detect. Financ. 2019, arXiv:1908.02591. [Google Scholar] [CrossRef]
- Altman, E.; Blanuša, J.; von Niederhäusern, L.; Egressy, B.; Anghel, A.; Atasu, K. Realistic Synthetic Financial Transactions for Anti-Money Laundering Models. In Proceedings of the Advances in Neural Information Processing Systems 36 (NeurIPS), Datasets and Benchmarks Track, 2023; pp. 29851–29874, [2306.16424. [Google Scholar]
- Torres, D.; Cheng, W.; Hu, K. Explainable AML Triage with LLMs: Evidence Retrieval and Counterfactual Checks. arXiv 2026, arXiv:2604.19755. [Google Scholar]
- Zhang, Y.; Zhang, Y.; Jin, Y.; Razis, K.A.M.; Choo, N.Q.A.; Wong, K.Y.A.; Tang, X.; Ke, K.Z.; Lee, W.K.D.; Zhao, J. Detection, Attribution, Narration: An End-to-End Pipeline for Explainable Money Mule Identification. arXiv 2026, arXiv:2607.17586. [Google Scholar]
- Jesus, S.; Pombal, J.; Alves, D.; Cruz, A.; Saleiro, P.; Ribeiro, R.; Gama, J.; Bizarro, P. Turning the Tables: Biased, Imbalanced, Dynamic Tabular Datasets for ML Evaluation. In Proceedings of the Advances in Neural Information Processing Systems 35 (NeurIPS), Datasets and Benchmarks Track, 2022; pp. 33563–33575. [Google Scholar]
- Das, G.; C, P.K.; Ramachandra, R. From Forgeries to Foundation Models: A Systematic Survey of Identity Document Attack and Detection. arXiv 2026. [Google Scholar]
- Ma, H.; Su, Q.; Huang, M.; Wu, K. Detecting Continuously Evolving Scam Calls under Limited Annotation: A LLM-Augmented Expert Rule Framework. Proc. Find. Assoc. Comput. Linguist. EMNLP 2025, 2025, 5047–5068. [Google Scholar] [CrossRef]
- Viaene, S.; Derrig, R.A.; Baesens, B.; Dedene, G. A Comparison of State-of-the-Art Classification Techniques for Expert Automobile Insurance Claim Fraud Detection. J. Risk Insur. 2002, 69, 373–421. [Google Scholar] [CrossRef]
- Beneish, M.D. The Detection of Earnings Manipulation. Financ. Anal. J. 1999, 55, 24–36. [Google Scholar] [CrossRef]
- Dechow, P.M.; Ge, W.; Larson, C.R.; Sloan, R.G. Predicting Material Accounting Misstatements. Contemp. Account. Res. 2011, 28, 17–82. [Google Scholar] [CrossRef]
- Nigrini, M.J.; Mittermaier, L.J. The Use of Benford’s Law as an Aid in Analytical Procedures. Audit. A J. Pract. Theory 1997, 16, 52–67. [Google Scholar] [CrossRef]
- Bao, Y.; Ke, B.; Li, B.; Yu, Y.J.; Zhang, J. Detecting Accounting Fraud in Publicly Traded U.S. Firms Using a Machine Learning Approach. J. Account. Res. 2020, 58, 199–235. [Google Scholar] [CrossRef]
- Financial Action Task Force. International Standards on Combating Money Laundering and the Financing of Terrorism & Proliferation: The FATF Recommendations. FATF; Adopted. Paris, Feb. 2012, last updated June 2026, 2012.
- Financial Crimes Enforcement Network. Guidance on Preparing a Complete & Sufficient Suspicious Activity Report Narrative; U.S. Dept. of the Treasury, Nov. 2003, 2003. [Google Scholar]
- Regulator, Payment Systems. Fighting Authorised Push Payment Fraud: A New Reimbursement Requirement. Policy Statement PS23/3. London, U.K., Jun. 2023, 2023. [Google Scholar]
- European Parliament and Council of the European Union. Regulation (EU) 2024/1689 of the European Parliament and of the Council of 13 June 2024 Laying Down Harmonised Rules on Artificial Intelligence (Artificial Intelligence Act). Off. J. Eur. Union OJ L 2024, 2024/1689, 2024. [Google Scholar]
- Elkan, C. The Foundations of Cost-Sensitive Learning. In Proceedings of the Proceedings of the Seventeenth International Joint Conference on Artificial Intelligence (IJCAI), Seattle, WA, USA, 2001; pp. 973–978. [Google Scholar]
- Chen, T.; Guestrin, C. XGBoost: A Scalable Tree Boosting System. In Proceedings of the Proc. 22nd ACM SIGKDD International Conference on Knowledge Discovery and Data Mining (KDD), 2016; pp. 785–794. [Google Scholar] [CrossRef]
- Dal Pozzolo, A.; Caelen, O.; Johnson, R.A.; Bontempi, G. Calibrating Probability with Undersampling for Unbalanced Classification. In Proceedings of the Proceedings of the 2015 IEEE Symposium Series on Computational Intelligence (SSCI), 2015; pp. 159–166. [Google Scholar] [CrossRef]
- Horvitz, D.G.; Thompson, D.J. A Generalization of Sampling Without Replacement from a Finite Universe. J. Am. Stat. Assoc. 1952, 47, 663–685. [Google Scholar] [CrossRef]
- Dou, Y.; Liu, Z.; Sun, L.; Deng, Y.; Peng, H.; Yu, P.S. Enhancing Graph Neural Network-Based Fraud Detectors against Camouflaged Fraudsters. In Proceedings of the Proc. 29th ACM International Conference on Information and Knowledge Management (CIKM), 2020; pp. 315–324. [Google Scholar] [CrossRef]
- Lundberg, S.M.; Lee, S.I. A Unified Approach to Interpreting Model Predictions. In Proceedings of the Advances in Neural Information Processing Systems 30 (NeurIPS), 2017; pp. 4765–4774. [Google Scholar]
- Amarasinghe, K.; Rodolfa, K.T.; Jesus, S.; Chen, V.; Balayan, V.; Saleiro, P.; Bizarro, P.; Talwalkar, A.; Ghani, R. On the Importance of Application-Grounded Experimental Design for Evaluating Explainable ML Methods. Proc. Proc. AAAI Conf. Artif. Intell. 2024, Vol. 38, 20921–20929. [Google Scholar] [CrossRef]
- Turpin, M.; Michael, J.; Perez, E.; Bowman, S.R. Language Models Don’t Always Say What They Think: Unfaithful Explanations in Chain-of-Thought Prompting. Proc. Adv. Neural Inf. Process. Syst. 2023, 36 (NeurIPS), 2305.04388. [Google Scholar]
- Magesh, V.; Surani, F.; Dahl, M.; Suzgun, M.; Manning, C.D.; Ho, D.E. Hallucination-Free? Assessing the Reliability of Leading AI Legal Research Tools. J. Empir. Leg. Stud. 2025. [Google Scholar] [CrossRef]
- Huang, J.; Chen, X.; Mishra, S.; Zheng, H.S.; Yu, A.W.; Song, X.; Zhou, D. Large Language Models Cannot Self-Correct Reasoning Yet. In Proceedings of the Proc. International Conference on Learning Representations (ICLR), 2024; p. 2310.01798. [Google Scholar]
- Du, Y.; Li, S.; Torralba, A.; Tenenbaum, J.B.; Mordatch, I. Improving Factuality and Reasoning in Language Models through Multiagent Debate. Proc. Proc. 41st Int. Conf. Mach. Learn. (ICML) 2024, Vol. 235, PMLR, 11733–11763. [Google Scholar]
- Parasuraman, R.; Manzey, D.H. Complacency and Bias in Human Use of Automation: An Attentional Integration. Hum. Factors 2010, 52, 381–410. [Google Scholar] [CrossRef] [PubMed]
- Bansal, G.; Wu, T.; Zhou, J.; Fok, R.; Nushi, B.; Kamar, E.; Ribeiro, M.T.; Weld, D. Does the Whole Exceed its Parts? The Effect of AI Explanations on Complementary Team Performance. In Proceedings of the Proc. CHI Conference on Human Factors in Computing Systems, 2021; pp. 1–16. [Google Scholar] [CrossRef]
- Wang, Y.; Zhang, J.; Wu, Z.; Cai, T.; Liu, Z.; Sun, Z.; Dong, M.; Zheng, M.; Duan, Y.; Yin, X.; et al. From Agent Traces to Trust: A Survey of Evidence Tracing and Execution Provenance in LLM Agents. arXiv 2026, arXiv:2606.04990. [Google Scholar]
Figure 1.
Three generations of anti-fraud models and the US model-risk boundary drawn in April 2026 [10]. Scorecards and statistical models of the first generation and non-generative machine-learning models that meet its definition fall within the guidance; deterministic rule engines fall outside its definition of a model, and generative and agentic AI fall outside its scope. The generations coexist in practice, often within a single pipeline.
Figure 1.
Three generations of anti-fraud models and the US model-risk boundary drawn in April 2026 [10]. Scorecards and statistical models of the first generation and non-generative machine-learning models that meet its definition fall within the guidance; deterministic rule engines fall outside its definition of a model, and generative and agentic AI fall outside its scope. The generations coexist in practice, often within a single pipeline.
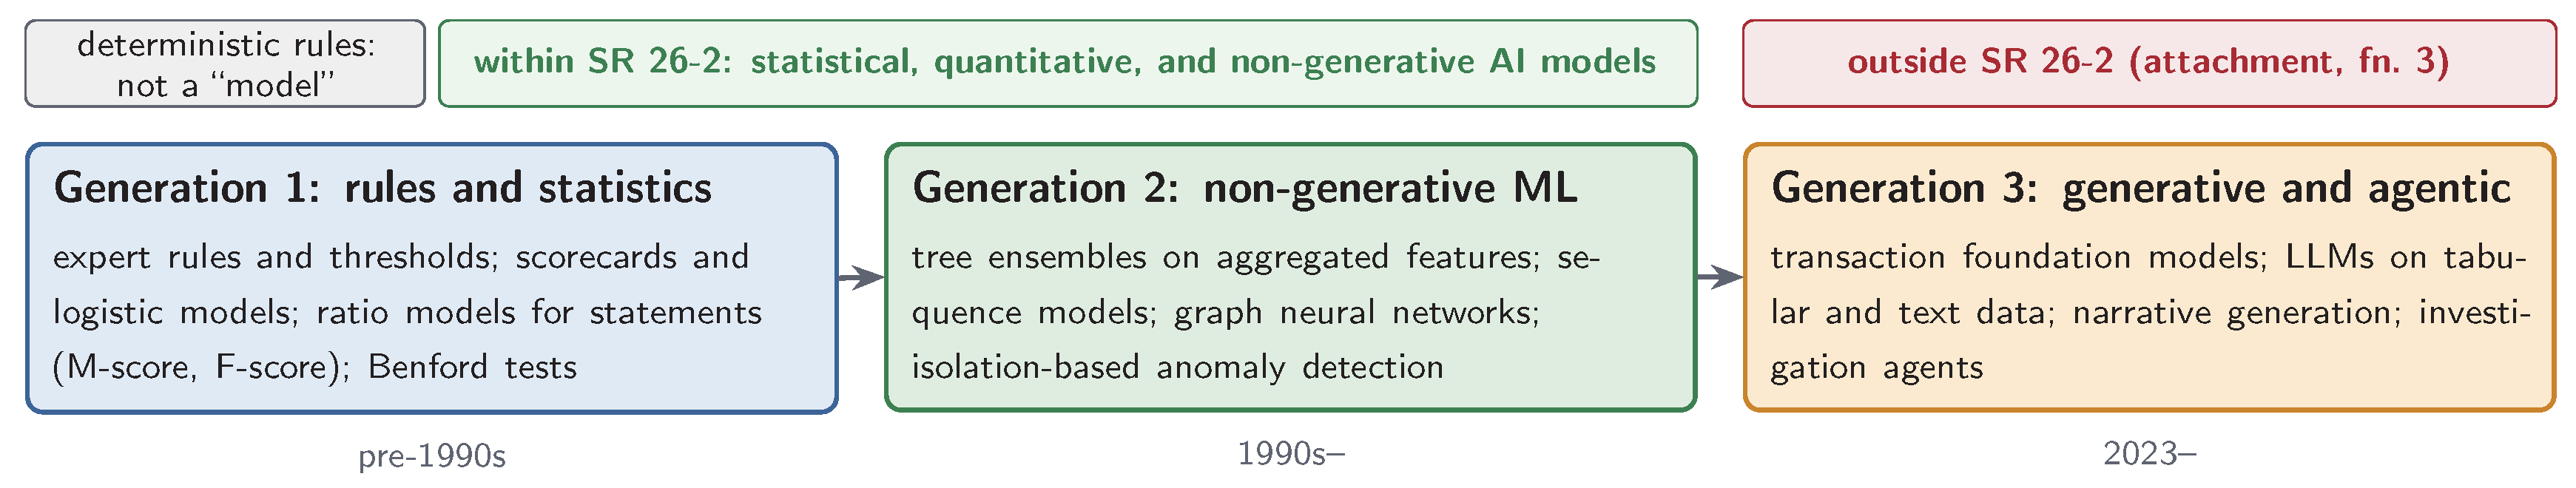

Table 1.
Representative work by fraud type and model generation. Of the 18 cells, 13 are populated and 5 are outside this survey’s selection (“not covered”); the second generation appears across 5 of the 6 fraud types, the first and the third across 4 each, and only card fraud and money laundering are documented in all three. The third generation mixes defenses with attack types that generative AI enables (marked a, with detection work where cited).
Table 1.
Representative work by fraud type and model generation. Of the 18 cells, 13 are populated and 5 are outside this survey’s selection (“not covered”); the second generation appears across 5 of the 6 fraud types, the first and the third across 4 each, and only card fraud and money laundering are documented in all three. The third generation mixes defenses with attack types that generative AI enables (marked a, with detection work where cited).
| Fraud type | Gen. 1: rules and statistics | Gen. 2: non-generative ML | Gen. 3: generative and agentic |
|---|---|---|---|
| Card and payment | rules vs. neural network [13]; statistical review [1] | aggregation and ensembles [14]; drift and feedback [15]; LSTM [16]; TabFormer [17] | transaction foundation model [7]; LLMs on fraud tables [18]; investigation agents [6,19] |
| Money laundering | threshold-based transaction reports [20] | graph learning [21]; synthetic data [22] | report-drafting agents [5]; evidence-constrained triage [23]; mule narration [24] |
| Application and identity | not covered | tabular models on bank-account-opening data [25] | deepfake mediaa [8]; document forgerya [26] |
| Scams and social engineering | not covered | not covered | LLM phishinga [9]; scam-call detection with LLMs [27] |
| Insurance | logistic regression [28] | classifier comparison [28] | not covered |
| Financial statements | M-score [29]; F-score [30]; Benford [31] | ensemble learning on raw accounts [32] | not covered |
Table 2.
The three generations compared in the frame of Section III: how the score is produced, how it is explained, what validation can measure, and what can be guaranteed.
Table 2.
The three generations compared in the frame of Section III: how the score is produced, how it is explained, what validation can measure, and what can be guaranteed.
| Gen. 1: rules and statistics | Gen. 2: non-generative ML | Gen. 3: generative and agentic | |
|---|---|---|---|
| Score | ; in (2); | additive trees (3); sequence and message-passing encoders | generated verdict and narrative; foundation-model embeddings |
| Explanation | the rule or itself (exact) | SHAP (5), decomposition of | generated rationale, not tied to the computation |
| Validation quantity | thresholds; | calibration (4); ; R only with audits (Prop. 4) | G, , ; residual error (6) |
| Typical failure | evasion by staying below thresholds | drift, delayed labels, camouflage (Prop. 5) | fabrication; verifier anchoring ; low |
| SR 26-2 status | estimated scores in; deterministic rules out | in scope if a model | out of scope |
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (http://creativecommons.org/licenses/by/4.0/).
Copyright: This open access article is published under a Creative Commons CC BY 4.0 license, which permit the free download, distribution, and reuse, provided that the author and preprint are cited in any reuse.