

Submitted:
12 October 2026
Posted:
13 October 2026
You are already at the latest version
Abstract
Machine learning is increasingly applied to midstream oil and gas pipelines, yet reported performance rarely establishes readiness for field use. This narrative review organizes peer-reviewed and industry sources from 2015–2025 using a five-level operational maturity framework (sensing and detection, diagnosis, prediction, decision and optimization, and human-supervised closed-loop automation), defined by a rubric of decision authority, operator role, and the validation evidence each level requires. A second axis records where each study’s performance was demonstrated, from simulation to closed-loop use. Applications include leak and anomaly detection, defect and corrosion assessment, hard spots, pump cavitation, predictive maintenance, failure-risk modeling, scheduling, and digital twins. Cross-classifying the coded sources on both axes shows that validation realism does not keep pace with claimed operational responsibility. Peer-reviewed evaluations are concentrated at Levels 1–3 and rely largely on laboratory, simulated, or retrospective data; the only operational Level 4 example is a practitioner case, and no coded source demonstrates Level 5 closed-loop control. The corpus thus shows a validation gap at the lower levels and an evidence-coverage gap at the upper ones; beyond the performance shown in controlled evaluations, validation, transferability, and governance remain major unresolved barriers to deployment. A ranked agenda led by graduated field validation follows.
Keywords:
machine learning
; midstream oil and gas
; pipeline integrity
; leak detection
; predictive maintenance
; digital twins
; operational maturity
; validation
1. Introduction
Pipelines are a critical component of energy infrastructure worldwide. They transport crude oil from production sites to refineries, move refined products to distribution terminals, and deliver natural gas to power plants, industrial users, and residential customers. These functions are performed continuously over long distances and often through remote, environmentally sensitive, or difficult-to-access terrain. The midstream sector, which comprises transportation, storage, compression, and related logistics, therefore occupies a central position between upstream exploration and production and downstream refining and marketing. Failures in this sector can have severe consequences, including soil and water contamination, threats to personnel and public safety, unplanned shutdowns, and cascading disruptions across the supply chain. As pipeline networks age and operating conditions become more variable, integrity management and operational optimization remain major engineering and economic priorities [1].
Historically, pipeline operators have relied on physical inspection, rule-based monitoring, and the expertise of experienced engineers. These practices remain essential, but the volume, velocity, and heterogeneity of modern pipeline data exceed what manual analysis alone can support. Pressure, flow, temperature, vibration, and acoustic measurements are collected continuously along the pipeline. In-line inspection (ILI) tools generate detailed records of wall thickness, metal loss, cracking, dents, and other integrity features. Compressor and pump stations produce rotating-equipment data, while drones, satellites, and field crews provide right-of-way and environmental observations. These data streams contain early indicators of leaks, corrosion, equipment degradation, geohazards, and operational anomalies. Machine learning techniques have been increasingly used to identify such indicators to support timely intervention.
This survey reviews recent applications of machine learning to midstream pipeline operations. Existing studies are often organized either by algorithmic family or by a narrowly defined application area, which can obscure the progression from monitoring to operational decision-making. The literature is organized by the degree of operational responsibility assigned to the model. The resulting five-level maturity continuum begins with sensing and detection, proceeds through diagnosis, prediction, and decision optimization, and culminates in human-supervised automation. The framework also clarifies why the most difficult challenges arise at the higher levels, where algorithmic performance must be accompanied by trust, auditability, safety assurance, and cybersecurity.
The review draws on peer-reviewed studies, conference proceedings, industry white papers, and technical reports, including material from the Pipeline Research Council International and the Pipeline and Hazardous Materials Safety Administration. The objective is to synthesize both academic developments and practice-oriented evidence. The survey compares methods, data sources, sensor modalities, reported performance, validation settings, and stated limitations across the reviewed work. Particular attention is given to the recurring difference between controlled experimental performance and field deployment under realistic operating conditions.
Rachman et al. [2] survey machine learning in pipeline integrity management, noting that these programs generate high-volume data from sources such as magnetic flux leakage and ultrasonic inspection, and that learning methods can help interpret inspection data, characterize corrosion defects, and inform maintenance decisions. Our survey differs in four respects. The first is how the literature is organized. Rachman et al. sort it by pipeline life-cycle element (inspection, monitoring, integrity assessment, risk planning); we sort it by the degree of operational responsibility a model is given. Applied systematically to midstream machine learning, this lens brings out a pattern: as a model moves from detection toward closed-loop action, trust, auditability, and safety assurance become increasingly important. Second, each study is also classified by the environment in which its performance was actually demonstrated, which separates analytical capability from operational maturity. Third, the scope here is broader, extending beyond integrity management to include throughput optimization, batch scheduling, pump cavitation, and digital twins. Fourth, the corpus is more up to date. It runs from 2015 to 2025, includes industry evidence as well as peer-reviewed work, and covers recent methods, including transformers, physics-informed networks, gradient boosting, and explainability tools.
The review makes four contributions. It defines the five maturity levels with an explicit rubric of capability, decision authority, operator role, and required validation evidence (Table 1), and it positions them against maturity models from adjacent fields (Section 4.1). It adds a second axis, the validation environment, and cross-classifies the representative studies on both axes (Section 4.7). From that cross-classification it identifies where the evidence is thin: in the coded corpus, validation realism does not keep pace with claimed operational responsibility, and at the top of the continuum the limitation shifts from weak validation to a lack of eligible studies. Finally, it turns that finding into a ranked research agenda (Section 6).
The remainder of the survey is organized as follows. Section 2 describes midstream operations and the data ecosystem that supports pipeline analytics. Section 3 summarizes the principal families of machine learning methods. Section 4 introduces the maturity framework and the validation-environment axis, relates them to existing maturity models, and reviews the literature level by level, from sensing and detection (Section 4.2) to action and automation (Section 4.6), with focused discussions of hard spots and pump cavitation; Section 4.7 then cross-classifies the reviewed studies. Section 5 examines cross-cutting barriers to adoption, Section 6 sets out the research agenda, and Section 7 concludes.
1.1. Review Methodology
The review proceeded in four phases: developing the search strategy, selecting studies, extracting data, and synthesizing the results.
Multiple databases, including IEEE Xplore, ScienceDirect, and Google Scholar, were searched, using combinations of terms such as machine learning, AI oil gas midstream, leak detection neural network, pipeline integrity machine learning, and corrosion prediction ML, along with related variants. Industry sources were also examined, including reports from the Pipeline Research Council International, technical documents from the Pipeline and Hazardous Materials Safety Administration, and vendor white papers from organizations such as Baker Hughes and ENTEGRA, to capture practical implementation perspectives alongside academic results. Figure 1 summarizes this process. The review is a structured narrative review, not a systematic review. Its sources, search terms, and screening criteria are reported so that the selection can be followed, and the corpus is described by its size and composition rather than by record counts at each screening stage. The final corpus comprises 24 sources: 20 peer-reviewed studies and reviews and 4 industry or practitioner reports. Of these, 16 sources that evaluate a machine learning model or document a deployed ML-enabled system are coded by maturity level and validation environment (Section 4.7). These coded evidence sources comprise 14 peer-reviewed evaluations, one vendor source, and one practitioner case report, which do not carry the same independent verification. The five reviews, one expert-based factor analysis, and two vendor inspection services that document no machine learning component are contextual sources: they inform the synthesis but are not coded. Table 3 summarizes the coded evidence sources, the two vendor services, two of the reviews, and three context studies from outside the corpus, Figure 1 shows how each kind of source enters the review, and Appendix A accounts for every source. The counts in Section 4.7, Table 4 and Table 5, and the conclusions rest on the 16 coded evidence sources, whereas the discussion of applications and methods in Section 4.2, Section 4.3, Section 4.4, Section 4.5 and Section 4.6 draws on the full corpus. The remaining references supply background on methods, standards, regulations, and adjacent maturity models.
Primary evaluations were included if they addressed midstream pipeline operations (transportation, storage, or compression), applied machine learning or artificial intelligence, were published between 2015 and 2025, and reported quantitative performance metrics or substantive case-study evidence. Studies that focused exclusively on upstream exploration or downstream operations were excluded unless they addressed pipeline-specific applications; non-English publications were also excluded. Studies evaluated outside midstream service were also eligible when the equipment and failure mode are ones that midstream operators manage, such as leaks in pressurized pipes, cavitation in centrifugal pumps, and faults in rotating machinery. Three coded evidence sources qualify on this criterion rather than the midstream one: a cavitation study on general industrial pumps, leak-detection tests on a laboratory viscoelastic pipe system, and a machine-health pilot at a nylon plant. Appendix A labels them transferable, and Section 4.7 shows that the findings do not depend on them. Reviews, expert-based analyses, and vendor documents without a documented machine learning component were retained for contextual synthesis but excluded from the maturity–validation cross-classification. Studies published before 2015 and non-pipeline methodological illustrations are used only as background; they are marked in Table 3 and identified separately in Appendix A.
The selected studies were analyzed along several dimensions: application domain, machine learning technique, data sources and sensors, reported performance, validation approach, and identified limitations, together with the maturity level and validation environment defined in Section 4. This multi-dimensional analysis enables cross-study comparisons consolidated in the summary table and supports the identification of research trends and persistent gaps. The review has four limitations. It draws primarily on North American and global English-language publications, which may underrepresent developments elsewhere, and, because AI methods evolve quickly, some recent advances may not yet appear in the peer-reviewed literature. Proprietary industry implementations also tend to lack the methodological transparency of academic work, which limits the extent to which their performance can be assessed. Finally, as a narrative review it does not claim exhaustive coverage. Its search terms center on detection, integrity, and corrosion, so studies of scheduling, optimization, and control may be underrepresented, and the counts at Levels 4 and 5 in Section 4.7 are best read as a lower bound.
Vendor white papers and similar technical documents are included because they are often the only public record of field deployment. They are not peer reviewed, however, and they rarely describe the dataset, the baseline, or any third-party verification. They are therefore cited only as evidence that a technology is in commercial use. Their performance figures are not reproduced, and the sources are marked with a dagger (†) in Table 3 and in the reference list. A vendor document enters the maturity–validation cross-classification only when it documents the use and evaluated function of a machine learning model; otherwise it is discussed as contextual evidence of commercial inspection or condition-monitoring capability and is not counted as an evaluated ML deployment.
The corpus is also concentrated. Three research groups account for nine of the cited studies: three acoustic leak-detection studies with J.-M. Kim as corresponding author [3,4,5], evaluated on test lines of the same specification (Section 4.2); two reviews and an in-line inspection study co-authored by T. Zhang [2,6,7]; and two incident-database studies and a review of weather-related failure co-authored by Y. Huang and N. Yodo [8,9,10]. Independent work is cited alongside these clusters where it exists, and the concentration is treated as a property of a young literature that limits how far its results can be generalized.
2. Midstream Operations and the Data Ecosystem
2.1. What Midstream Operations Involve
The oil and gas supply chain is commonly divided into upstream, midstream, and downstream activities. Upstream operations involve exploration and production; downstream operations include refining, distribution, and retail delivery; and midstream operations provide the transportation, storage, compression, and handling functions that connect the two. For this review, midstream comprises the gathering systems that collect oil and gas from producing sites, long-distance transmission (trunk) pipelines, the compressor and pump stations that maintain pressure and flow along them, and storage assets such as tank farms and terminals. Well-site equipment that belongs to upstream operations and downstream internal or retail distribution systems are excluded unless a study addresses a pipeline-specific problem shared with midstream operations. Although midstream activities receive less public attention than drilling or refining, they concentrate many of the industry’s transport-related safety, reliability, and environmental risks and generate a substantial portion of the operational data used for modern analytics.
Pipeline transportation is the dominant midstream function. Hydrocarbons and refined products are transported under pressure over long distances, often through environments that are difficult to inspect continuously. Storage terminals and tank farms introduce additional requirements for inventory management, overfill prevention, containment, and product quality. Compressor and pump stations maintain the pressure and flow needed for continuous operation and must themselves be monitored for reliability and efficiency. These assets generate large volumes of data that have historically supported control, reporting, and compliance. The current shift is toward using the same data streams to support prediction, risk assessment, and operational decision-making.
2.2. The Data Midstream Systems Generate
Midstream operations are data-intensive, and their data streams can be grouped into several categories. This classification is important because model performance depends not only on the algorithm but also on the relevance, resolution, calibration, and completeness of the underlying measurements.
The most immediate stream comes from the pipelines themselves. Sensors placed along the line measure pressure, flow rate, vibration, and temperature, sometimes across hundreds or thousands of miles. A pressure drop can signal a leak or a blockage. A fall in flow that is not matched by a change at the inlet may indicate that the product is escaping. Vibration patterns in pumps and pipeline structures shift when components are wearing out or when flow becomes unstable, and temperature provides the context needed to interpret thermal expansion and degradation, especially in extreme climates.
A second, richer stream comes from in-line inspections. Operators send intelligent tools, known in the industry as pigs, traveling inside the pipe to examine the wall from within. Magnetic flux leakage tools detect metal loss from corrosion. Ultrasonic sensors measure wall thickness and locate cracks. Optical and laser tools directly image the internal surface. The result is substantial and complex, a mixture of waveform signals, three-dimensional scans, and tabular logs that demands signal processing and machine learning to interpret, classify, and size the defects it reveals.
Equipment and facility monitoring form a third stream. Compressors and pumps, the rotating machinery that maintains pressure and flow, carry sensors for vibration, torque, speed, bearing temperature, and energy use. These readings enable immediate control, but they also feed into predictive maintenance models that can anticipate failures days or weeks in advance, catching subtle shifts in behavior that a human operator might never notice. Storage and inventory data make up a fourth stream, drawn from level sensors, pressure relief systems, and chemical analyzers at terminals and tank farms, and used to track volume, prevent overfilling, and assess product quality. Environmental and regulatory data make up a fifth, gathered from methane detectors and infrared cameras for emissions, from ground sensors and satellite imagery for soil and geohazard conditions, and from weather records that bear on corrosion and maintenance. Integrating this last stream with operational measurements supports compliance and, increasingly, a more risk-aware approach to managing the line.
2.3. How the Data Are Collected
Gathering such varied and voluminous data depends on a mix of fixed infrastructure, mobile tools, and newer digital methods, and each part of that mix introduces its own difficulties.
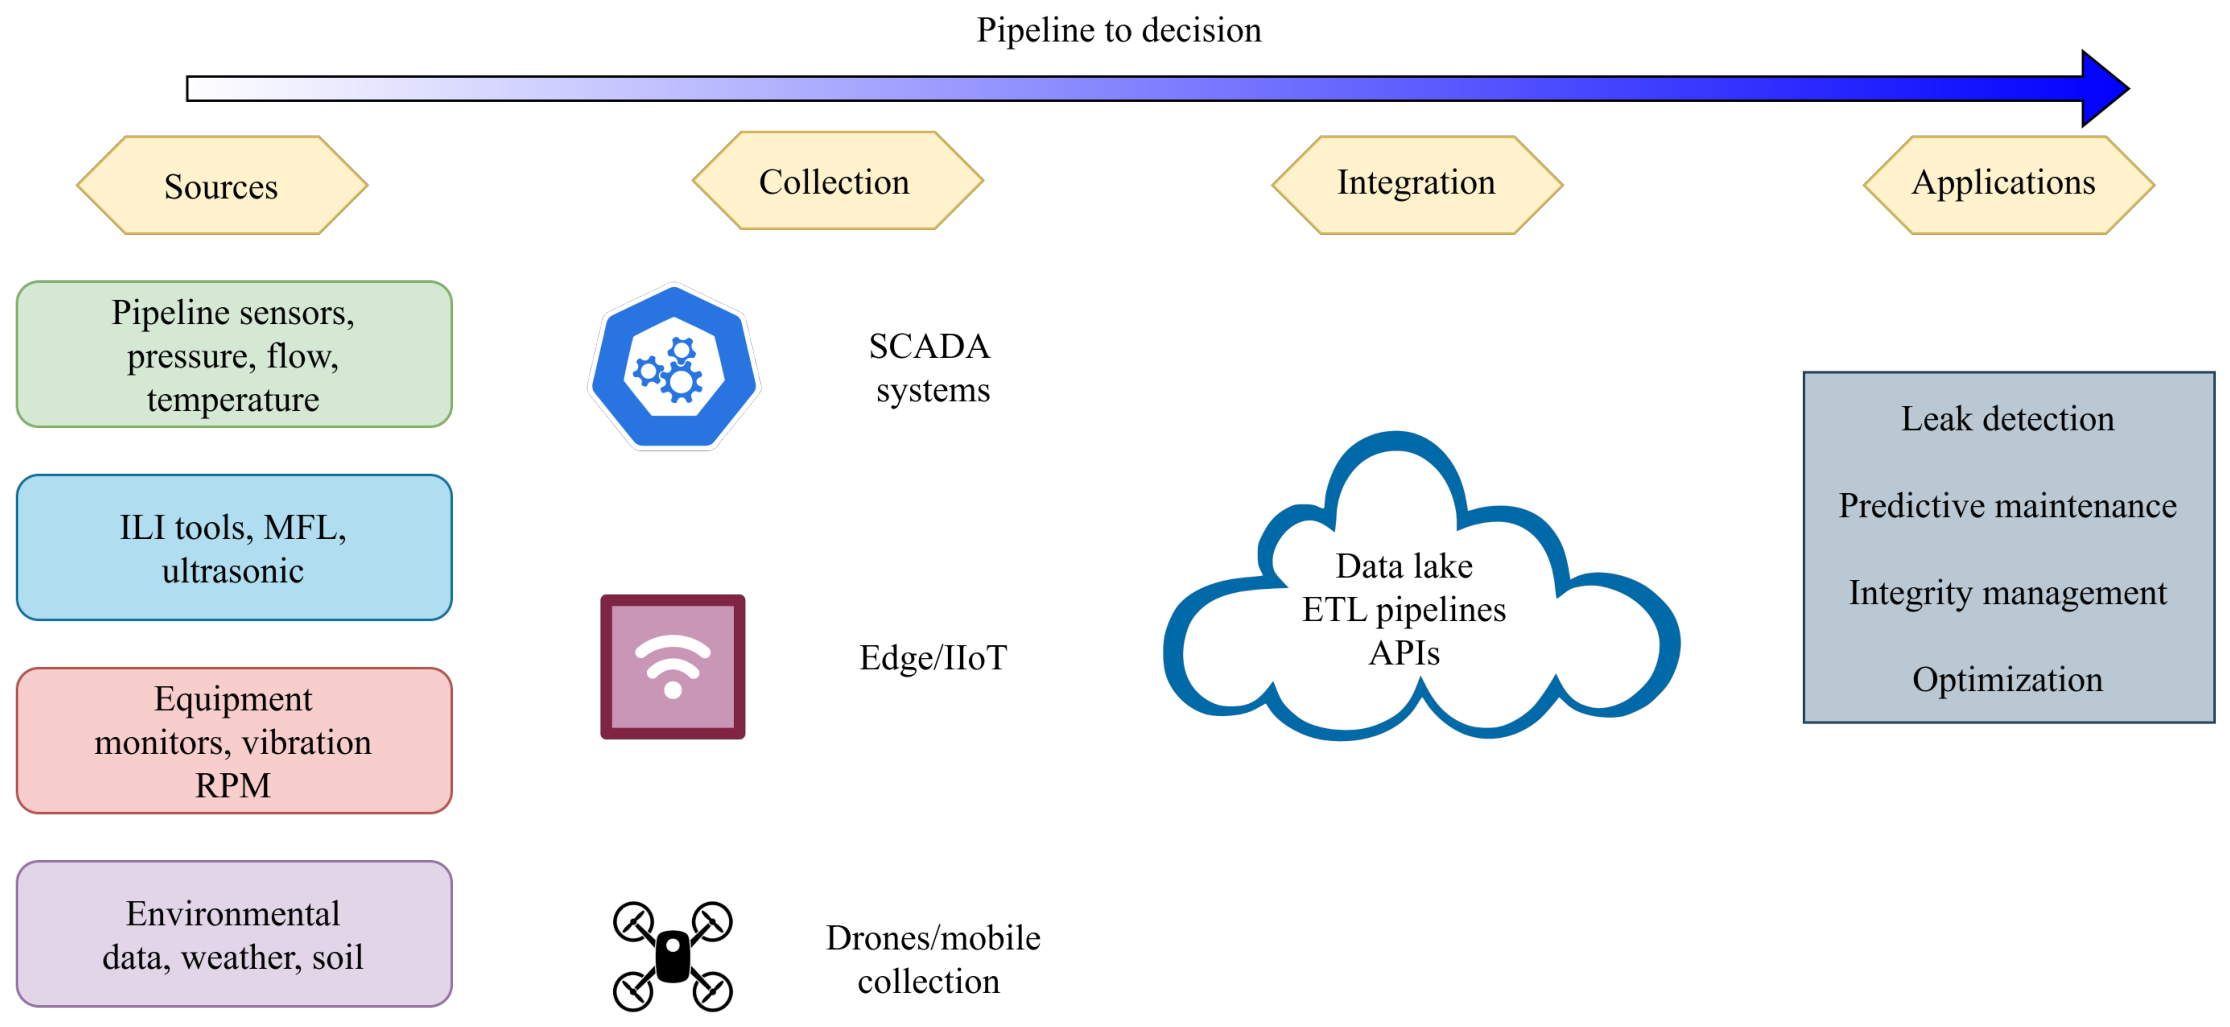
The backbone is the Supervisory Control and Data Acquisition system (SCADA). It links field devices, sensors, actuators, and programmable logic controllers to central control rooms over secure communication channels. It provides time-stamped streams that support anomaly and leak detection, as well as throughput optimization. Layered on top of SCADA, modern facilities increasingly adopt industrial Internet of Things architectures, in which smart sensors at the edge of the network preprocess data locally and transmit only the relevant features or alarms. An edge-mounted acoustic sensor might flag a suspicious frequency and raise an alert immediately, rather than continuously streaming raw waveforms, thereby saving bandwidth and reducing latency. For areas that SCADA does not reach, drones and field crews fill the gap, with uncrewed aircraft carrying thermal or hyperspectral cameras to spot surface anomalies and workers entering inspection results, photographs, and notes that natural language processing and computer vision can later analyze. All of this ultimately flows into centralized, often cloud-based platforms that store time-series data, inspection logs, and emissions records and provide models with the scalable computing they need for training and real-time inference.
Significant challenges accompany these capabilities. The sheer volume and velocity of the data strain ordinary architectures, since thousands of sensors reporting every second can produce terabytes of data per day and demand specialized streaming and processing tools. Latency matters for time-sensitive tasks like leak detection, where a delayed signal can lead to a safety incident, and this pressure is driving the move toward edge analytics. Data quality, the integration of heterogeneous records, and security are treated with the other cross-cutting challenges in Section 5. Because pipeline data belong to critical infrastructure, protecting them is a design requirement from the outset.
Figure 2.
The midstream data ecosystem.
3. Machine Learning Techniques in Pipeline Operations
Machine learning contributes to midstream operations by converting high-volume pipeline data into classifications, forecasts, risk estimates, and operational recommendations. The methods most relevant to pipeline applications fall into four broad families: supervised learning, unsupervised learning, reinforcement learning, and deep learning. A fifth strand, hybrid and physics-informed modeling, cuts across these families by combining data-driven learning with engineering knowledge. This section summarizes the main methodological options and their strengths and limitations.
3.1. The Four Method Families
Four method families recur in pipeline applications. Supervised learning (support vector machines, random forests, and gradient boosting such as XGBoost or CatBoost) maps labeled inputs to outputs, for example whether a leak is present or how deep a defect is. Its reach is limited by the scarcity of labeled failures, which also makes overfitting a constant risk. Unsupervised learning (k-means, DBSCAN, principal component analysis, and autoencoders [11]) needs no failure labels and flags departures from normal operation, but its alarms must be calibrated to keep false positives in check. Reinforcement learning [12] suits sequential control decisions for pumps, compressors, and valves, although learning by exploration conflicts with safe operation and demands careful validation. Deep learning (convolutional networks, long short-term memory networks [13], and deep belief networks [14]) learns representations directly from multichannel signals and images at the cost of interpretability, which is why explanation methods such as SHAP [15] are increasingly paired with deep models. Specific architectures are discussed with the applications that use them in Section 4.2, Section 4.3, Section 4.4, Section 4.5 and Section 4.6.
3.2. Hybrid and Physics-Informed Approaches
A major recent direction combines data-driven learning with physics-based and engineering knowledge rather than treating them as competing approaches. Hybrid and physics-informed models fold engineering knowledge, the equations that govern fluid flow, corrosion, and material failure, into the structure of a learning model to improve generalization when data are limited. A physics-informed neural network, for example, constrains its outputs to respect known physical laws, which constrains predictions in regions where training data are sparse. Domain-guided models for leak detection have used hydraulic transient theory to shape how the network represents a leak, and other work has paired burst-pressure formulas with machine learning to predict failure risk. The thread running through these efforts is that physical principles guide feature selection or constrain model outputs, and the result tends to be both more accurate and more interpretable than a purely data-driven model of the same task. This pattern recurs across the maturity levels, and it is one of the clearest signals of where the field is heading.
This advantage is conditional rather than guaranteed. Where training data are plentiful and representative, a well-tuned data-driven model can match or beat a physics-informed one, and encoding physical constraints adds its own cost in development and tuning effort. Hybrid models earn their keep mainly where data are sparse or operating conditions drift, which is the situation most pipeline problems present.
4. A Five-Level Operational Maturity Framework
The midstream machine learning literature catalogs algorithms and applications but often obscures the degree of operational responsibility assigned to the models. A leak detector that raises an alarm is doing something fundamentally different from a control system that adjusts a compressor on its own, even if both use a neural network. To bring that difference to the surface, the field is presented along a continuum of operational maturity, a five-level progression that runs from sensing to autonomous action. The levels are not rigid bins; a single study can span more than one. Still, the continuum captures a real arc in capability and ambition, and it tracks the path operators tend to follow as they grow comfortable handing more responsibility to a model.
The five levels are defined as follows.
- Level 1, sensing and detection. The model identifies an abnormal condition. It answers the question Is something wrong? Leak and anomaly detection are examples of this.
- Level 2, diagnosis and condition assessment. The model evaluates where the problem is, how severe it is, and what caused it. It answers the questions Where is it, how bad is it, and what caused it? Defect sizing, corrosion characterization, and failure-cause classification belong at this level.
- Level 3, prediction. The model forecasts future conditions and failure risk. It answers the questions What will happen, and when? Corrosion growth prediction and failure-risk prediction sit here.
- Level 4, decision and optimization. The model determines what operational action to take. It answers the question What should be done to improve safety, reliability, and performance? Throughput optimization and maintenance scheduling fall here.
- Level 5, action and automation. The model executes operational decisions in a closed loop under human supervision. It answers the question Can the system act on its own conclusions safely? Closed-loop control defines this level, and digital twins belong to it only when they act on the plant.
Read from bottom to top, the continuum describes a shift from reactive to proactive to autonomous management, as illustrated in Figure 3. At the lower levels, a model detects problems, and a human makes all decisions. At the higher levels, the model begins to decide and even to act, with the human supervising rather than driving. This shift is also where the difficulty concentrates. Detection is comparatively mature and widely deployed, although the deployed detection capability documented in this corpus rests on conventional and commercial inspection technology rather than on published machine learning (Section 4.7). Autonomous control is rare, hemmed in by safety requirements, regulatory expectations, and cybersecurity risk. Most systems that reach toward it stop at a human-in-the-loop configuration where the model proposes, and a person approves. Mapping the literature onto these five levels is important from two points of view: it organizes what has been done, and it makes visible where the open problems lie, which is overwhelmingly at the top of the continuum, where trust, verification, and governance join model generalization as major barriers.
The right choice of a model depends on the task, the data, and the operational constraints; hence, no single technique dominates. Supervised learning is well-suited to well-defined problems with labeled data, such as leak detection and defect sizing. Unsupervised learning is appropriate for anomaly detection in data-rich settings where failures are not labeled in advance. Reinforcement learning is built for optimization and control. Deep learning handles the complex sensor and image data that defeats hand-crafted features. These tendencies are not rigid rules, and in practice, the strongest systems often combine families. Still, they map cleanly onto the progression of operational maturity that organizes this survey, from detecting that something is wrong to deciding which action to take. Figure 4 summarizes these tendencies as a conceptual map of which technique families suit each level. The next sections elaborate on each level, along with the specific problems and techniques used to address them.
To separate analytical capability from operational maturity, the studies summarized in Section 4.7 are also classified by the setting in which their performance was actually measured. Six validation environments are distinguished, in increasing order of realism: (V1) simulation, in which data are generated by hydraulic, corrosion, or other physical models; (V2) laboratory, in which models are tested on controlled rigs or benchmark datasets; (V3) historical field data, in which models are fitted and tested offline on real inspection or incident records; (V4) pilot, a limited deployment on an operating asset; (V5) operational, in which the system is in routine use; and (V6) closed-loop, in which the model’s output triggers an action on the asset without per-action approval. Reading the maturity level against the validation environment is the central analytical step of this review: the level states what a model is meant to do in operation, and the environment states what has been shown.
The rubric in Table 1 is applied as a two-part code. Each study is first assigned the highest level whose capability and decision-authority criteria its reported results demonstrate, not the highest it claims or defers to future work. It is then assigned the most realistic environment of its primary evaluation; supplementary checks on other data are recorded separately as external validation. A study meets its level’s evidence benchmark when that environment reaches the minimum listed in Table 1. The minimum rises with decision authority because the cost of an unverified error rises with it: a false alert at Level 1 costs operator attention, whereas an unverified action at Level 5 acts directly on the line. Section 4.7 applies the code to the studies summarized in Table 3.
The minimum environments in Table 1 are evidence benchmarks proposed by this review for comparing studies. They are not regulatory approval thresholds, and reaching one is not sufficient for deployment. Each follows from what a level’s output must be checked against. A detector can be tested on a rig with controlled leaks, so Level 1 calls for laboratory evidence. Localization, sizing, and prognosis need field ground truth, such as excavation findings or recorded failures, so Levels 2 and 3 call for historical field data, held out from training at Level 3. A recommendation can be judged only by its outcome on an operating asset within real constraints, which requires a pilot at Level 4, and an action taken without per-action approval requires closed-loop evaluation of its safety and fail-safe behavior at Level 5. Because level and environment are coded separately, a defect-sizing method tested only in simulation can demonstrate Level 2 capability while falling below the Level 2 benchmark. A deployment decision also depends on the safety case, robustness, system integration, and the regulatory requirements of the particular asset.
4.1. Relation to Existing Maturity Models
Graded maturity scales are common in adjacent fields, and the present framework borrows their logic while changing what is graded. SAE J3016 classifies driving automation by how much of the driving task the system performs and by who must supervise or take over [16]. Features that only warn or intervene momentarily sit at its Level 0, and its higher levels are distinguished by execution authority. In those terms, Levels 1–4 of the present framework all fall within SAE Level 0, because none of them executes an action, and only Level 5 corresponds to SAE Levels 2–3, in which the system acts while a person supervises or stands ready to intervene. Gamer et al. [17] carry the SAE ladder over to process plants, where it grades the autonomy of plant operation as a whole; a machine learning model at Levels 1–4 informs an operation without changing that autonomy level. The acatech Industrie 4.0 Maturity Index grades an organization’s progress through six stages, from computerization and connectivity through visibility, transparency, and predictive capacity to adaptability [18]. In condition monitoring, ISO 13374 divides processing into blocks that run from data acquisition and manipulation through state detection, health assessment, and prognostic assessment to advisory generation [19], and the capability levels proposed for digital twins run from standalone and descriptive through diagnostic, predictive, and prescriptive to autonomous [20]. Table 2 aligns these schemes with the present levels.
Two features distinguish the present framework. First, the unit it grades is an individual model or study, whereas the other schemes grade a vehicle feature, a plant, an organization, a monitoring system, or a twin; it can therefore classify the reviewed literature directly. Second, it specifies for each level the validation evidence, and the minimum validation environment, required before field use (Table 1). None of the schemes in Table 2 ties its levels to such evidence, and the evidence requirement is what allows the framework to test the literature rather than only sort it. The framework also subdivides the region that SAE J3016 treats as a single level. Nearly all pipeline machine learning informs or advises people without acting, and the four levels below automation separate detection, diagnosis, prediction, and recommendation within that region.
4.2. Level 1: Sensing and Detection
The first operational requirement is to identify whether an abnormal condition exists, and detection is the area in which machine learning has produced some of its earliest and most visible pipeline applications. Two threats dominate this level. Leaks release product into the environment and must be caught fast, and operational anomalies signal equipment trouble, flow deviations, or even cyber intrusions. Conventional leak detection, built on pressure and flow monitoring, struggles with sensitivity and false alarms. Machine learning has been widely applied to improve sensitivity and reduce false alarms by recognizing subtle patterns in sensor data that indicate a leak or incipient failure. Most of the work at this level corresponds to detection in its purest form, with the strongest studies beginning to extend into localization and severity, and then into diagnosis.
4.2.1. Leak Detection
Three sensing approaches recur across the leak-detection literature, and they differ in the physical signal they exploit. Acoustic emission methods listen for the high-frequency sound a leak makes. Hydraulic transient methods read the pressure waves that travel along the pipe. Multi-sensor fusion methods combine signals from multiple sensors. Each approach has produced strong results, and each carries the same caveat: laboratory accuracy has not yet translated cleanly to the field. Acoustic approaches have reported some of the strongest controlled-test results. Ullah et al. [3] attached acoustic emission sensors along a laboratory pipeline to capture the high-frequency signals emitted by small pinhole leaks, extracted features from those signals, and tested a range of supervised classifiers, including an artificial neural network, k-nearest neighbors, decision trees, and random forests. The classifiers separated leak from no-leak conditions with roughly 99 percent accuracy for pinholes of 0.5 to 1 mm at 13 and 18 bar, demonstrating that acoustic methods can detect very small leaks in a controlled setting. It should be noted, however, that field conditions introduce background noise and signal attenuation with distance, and that operating variables such as pressure and product type still need to be incorporated into the model.
The hydraulic transient approach addresses a harder problem: detecting multiple leaks simultaneously. Waqar and colleagues [21] built a domain-guided framework that detects multiple simultaneous leaks from transient pressure data, and a notable element of their method is the choice of target variable: a leak function whose pulse-like signature allows a single neural network to handle varying numbers of leaks without retraining for each case. They sharpened the model against operational uncertainty through iterative refinement, incorporating factors such as valve closure time and pre-transient flow, and validated it on numerical simulations and lab-scale experiments with viscoelastic pipes, including branched and series configurations. The result demonstrates something conventional methods struggle with: that physical domain knowledge built into the model can enable the detection of multiple leaks.
Deep learning has further improved sensitivity by transforming the signal before classification. Siddique et al. [4] converted acoustic and vibration signals into time-frequency images using the continuous wavelet transform, then applied a deep belief network for feature extraction, optimized the network with a genetic algorithm, and classified the results with a least-squares support vector machine. The combination, a DBN-GA-LSSVM model based on the deep belief network described in [14], separated leak signatures from normal conditions with high accuracy and reliability, even in noisy conditions, and the authors argue that it can support real-time early warning. The cost is computational, since the wavelet transform and the deep network are demanding, so real-time performance on edge hardware remains to be shown.
Hybrid deep architectures extend the same acoustic approach. Ullah et al. [5] paired a one-dimensional convolutional network, which extracts local features from filtered acoustic emission signals, with a long short-term memory network that models how those features evolve in time. On a laboratory line carrying gas or water at 13 and 18 bar, the model reached 99.86 percent accuracy and outperformed two recurrent baselines. Its spatial features are patterns within each acoustic record rather than relationships among sensors spread along a line, and it embeds no hydraulic model, so detection and localization across long networks remain open problems. These recent results rest on earlier groundwork in classical machine learning. Zadkarami et al. [22] combined wavelet-based feature extraction from pressure signals with a multilayer perceptron to detect and locate leaks, thereby isolating the leaking section. Abdulla et al. [23] built an artificial neural network for the same task, and Chen et al. [24] applied support vector machines to leak detection and localization. These studies showed that machine learning classifiers can outperform or complement traditional threshold-based detection, particularly in handling sensor noise and varying operating conditions, and they typically reported high detection rates with reduced false alarms in experimental setups. One lesson recurs throughout: feature engineering matters, and wavelet transforms or statistical features of pressure transients help the algorithms identify leak-related signatures.
Several of these studies span levels, and the placement rule of Table 1 decides where each is counted. Zadkarami et al. [22] detect leaks and isolate the leaking section of a simulated line, so their work reaches Level 2 as well as Level 1. Ullah et al. [3] state that their platform identifies leak size and location, but the reported results are leak versus no-leak classifications at fixed pinhole sizes, so the study remains at Level 1. Layouni et al. [25], discussed under Level 2, size defects and propose using the estimates to decide whether urgent repair is warranted, which would be a Level 4 recommendation; because that step is not evaluated, the study is placed at Level 2. In each case the study is credited only with what its results demonstrate.
The complexity of these architectures should be weighed against what it buys. Three of the Level 1 studies come from one group and were evaluated on test lines of the same specification, a 114.3 mm steel pipe operated at 13 and 18 bar [3,4,5]. Feature-based classifiers (k-nearest neighbors, decision trees, and random forests) had already reported about 99 percent accuracy on that specification [3], so the accuracies later reported for deep architectures on similar rigs are near saturation. These are cross-study values from different test sets and partitions, not a controlled head-to-head comparison, so they suggest rather than show that the CNN-LSTM’s 99.86 percent [5] adds little; its own reported comparison is with two recurrent models rather than with those classifiers. The DBN-GA-LSSVM of Siddique et al. [4] stacks wavelet imaging, a deep belief network, and genetic-algorithm tuning on the same problem, and the computational cost of those stages weighs against deployment on edge hardware. The WA-SRF ensemble of Tan et al. [26], discussed under Level 3, cannot be assessed in this way, because the source of its data is not stated. Hasanpour et al. [27] provide the clearest test in the corpus. On the Grundfos cavitation data, per-pump support vector machines on three engineered features matched a small CNN (about 92 against 91 percent), but a single SVM serving all seven pumps fell to about 81 percent while a single CNN kept its accuracy, and the CNN, quantized to 8-bit integers, still ran on a Cortex-M4 microcontroller in under a second. There the added complexity bought fleet-level generalization and demonstrably fit the target hardware. A more complex model is justified only when it beats a simpler one under the same validation and still fits the compute and latency budget of the intended hardware; few of the studies surveyed here show either.
4.2.2. Anomaly Detection in Operational Data
Operators use machine learning not only to detect physical leaks but also to identify operational anomalies in real-time data. Such anomalies can signal malfunctioning equipment, flow deviations, or cyber intrusions. Here, the natural tools are unsupervised because the anomalies of interest lack labels and often lack precedent. Autoencoders and clustering methods have been tested on pipeline SCADA data to surface out-of-the-ordinary behavior without any explicit leak signature, learning what normal looks like, and flagging departures from it. The advantage is that these methods do not require labeled failures, which is important in a domain where failures are rare. The persistent difficulty is the false positive, since a model tuned too sensitively raises alarms that do not pan out and erodes the operator’s trust, on which the whole system depends.
4.2.3. Detection of Hard Spots
Hard spots constitute a specialized detection problem because the threat is localized, the integrity consequences can be significant, and the relevant inspection data differ from those used for more common metal-loss defects. A hard spot is a localized region of elevated hardness in the pipe steel. The regulation that governs gas pipelines, 49 CFR 192.3, defines it as an area on steel pipe material with a minimum dimension greater than two inches in any direction and a hardness at or above Rockwell 35 HRC, equivalently Brinell 327 HB or Vickers 345 HV10 [28,29]. These regions originate during manufacturing, including through uneven quenching and related thermal processes, and they are integrity-relevant because they can be susceptible to hydrogen-induced cracking and stress corrosion cracking under operational stress. They are difficult to detect because they are often subsurface, which makes high-quality inspection methods and rigorous interpretation of inspection signals essential. Non-destructive testing supplies the raw signal, chiefly magnetic flux leakage, eddy current array, and ultrasonic testing, and these produce a mix of categorical, numerical, and image data that machine learning can work with.
Hard-spot assessment draws on several numerical, categorical, and contextual data sources. Magnetic flux leakage tools measure the magnetic disruption caused by a hard spot and report parameters such as axial length, circumferential width, and peak hardness. Commercial services already target this problem. Vendor material describes ultra-high-resolution MFL in-line inspection for detecting and characterizing hard spots [30], and eddy-current array probes, which respond to the microstructural changes of localized quenching, for confirming them in the ditch [31]. These sources document commercial use, but their performance figures are vendor claims without independent verification and are not reproduced here. Neither source documents a machine learning component: one describes automated analysis reviewed by analysts, the other threshold-based detection. They show that the inspection workflow is deployed operationally, which does not establish the field maturity of machine learning models, so they are discussed as context and are not counted among the coded evidence sources in Section 4.7. Beyond the inspection signal itself, pipeline attributes such as manufacturer, vintage, and seam-type feed susceptibility ranking, as well as operational and environmental factors such as soil pH, cathodic protection level, and pressure cycling, bear on the risk posed by a given hard spot. Figure 5 traces this workflow from inspection to remediation and marks the maturity level of each analytical step.
On the modeling side, supervised methods are the most natural choice when labeled hard-spot examples are available. Support vector machines and tree-based classifiers can operate on structured features such as hardness, anomaly dimensions, vintage, seam type, and operating history. Convolutional and residual networks, building on deep residual learning [33], are better suited when inspection responses are represented as image-like arrays or spatial signal maps rather than as low-dimensional tabular features. Where labeled examples are scarce, which is the usual situation given how rare documented hard spots are, semi-supervised methods that exploit unlabeled data become attractive. Reported performance for hard-spot classification should be interpreted cautiously, particularly when derived from vendor studies, limited datasets, or controlled validation conditions rather than independent field trials. The Pipeline Research Council International has invested directly in this problem through its hard-spot work, including a prioritization methodology that evaluates predicted failure pressure for cracking that initiates in pipe-body hard spots and ranks anomalies for excavation and remediation using a deterministic process keyed to hard-spot size, pressure, temperature, and base-material toughness [32].
The evidence suggests that hard-spot detection is more mature on the sensing side, where commercial inspection tools and analytic workflows are developing, than on the machine-learning side, where the literature remains thinner than it is for leak detection. The non-destructive testing technologies involved (ultra-high-resolution MFL arrays, eddy-current arrays, and ultrasonic testing) are more mature than the machine learning applied to their output, so a reported capability may reflect the maturity of the sensor and its analysis workflow more than that of the learning model. Limited historical data complicates model training; models may not generalize across pipe materials and soil environments, and most published machine learning research still targets general defect detection rather than hard spots specifically. The subsurface nature of the threat is the underlying difficulty, and it explains why hybrid methods that combine magnetic flux leakage with machine learning may be more promising than either approach used in isolation.
4.2.4. Detection of Cavitation in Pumps
Pump cavitation is another specialized detection problem requiring separate treatment because the underlying fluid dynamics are complex and the diagnostic signals are indirect. When local pressure in a pump drops below the vapor pressure, vapor bubbles form. As the flow carries them into higher-pressure regions, they collapse, producing vibration, noise, pressure fluctuations, loss of hydraulic performance, and progressive damage to the impeller and casing. Whether cavitation occurs depends on flow rate, suction head, temperature, pump geometry, and transient behavior, making it difficult to predict and control. It is also difficult to detect because background vibration, ambient noise, and other mechanical faults can produce similar signal changes, which is exactly why the field has turned to data-driven methods that learn cavitation’s signature directly from measurements.
Detection rests on indirect sensing because the bubbles themselves cannot be observed directly in an operating pump. Vibration is the most widely used signal, since accelerometers are easy to mount on the casing or bearing housing, and cavitation manifests as increased impulsiveness and broadband energy that can be examined in the time, frequency, and time-frequency domains. Vibration is not a perfect indicator, though, because signal transmission depends on structural paths and mounting, and the same cavitation state can look different across pumps. Acoustic emission offers a complementary view, sensitive to the high-frequency impulses generated by bubble collapse and useful for early detection, at the cost of careful coupling and rapid signal decay. Pressure pulsation ties more directly to the internal flow field and tracks hydraulic instability at its source, but sensing it is intrusive. Electrical signals, such as motor current, are attractive in fleet settings precisely because they are non-intrusive and easy to scale across many assets, even though they observe cavitation only indirectly through their effects on loading. The operational implication is that no single signal channel is sufficient in all settings; robust detection generally requires combining multiple channels with operating context, such as flow, suction conditions, speed, and temperature.
The modeling methods are divided into three groups, mirroring the broader landscape of techniques. Conventional signal-based approaches identify cavitation through characteristic changes in statistical and spectral features such as root-mean-square, kurtosis, spectral entropy, and wavelet coefficients. They remain valuable because they are transparent, computationally cheap, and easy to implement, though they rely on hand-crafted features and fixed thresholds. Feature-based machine learning trains supervised models on labeled data, using support vector machines, decision-tree methods, artificial neural networks, and k-nearest neighbors. A comparative study on the Grundfos cavitation dataset, which collected vibration data from 297 recordings across seven centrifugal pumps, examined both support vector machines and deep learning and tested deployment on embedded industrial hardware [27]; the pumps are general industrial units rather than part of a midstream installation, so the study is counted as transferable evidence (Section 1.1). Its findings reveal that support vector machines are computationally efficient, effective with limited data, and strong when well-designed feature sets are used. Still, they generalize less well across different pumps, which is the central challenge in a fleet setting where a single model must serve many types of machines.
Deep learning is the third group and is increasingly the default when the signal is complex and manual feature extraction becomes difficult. Convolution-based models, including convolutional neural networks, residual networks [33], densely connected networks [34], and the lightweight MobileNet [35] and ShuffleNet [36] architectures, learn features directly from raw signals and offer strong performance, with the lightweight variants especially suited to deployment because they trade modest accuracy for much lower memory and computation. Recurrent models such as long short-term memory [13] and gated recurrent units [37] are well-suited to cases where the temporal evolution of the signal carries diagnostic information. However, their use in pump monitoring remains narrower than that of convolutional models. Transformer architectures [38] have recently entered cavitation studies, particularly for time-frequency signals with complex global structure, and they show promise for challenging signal conditions, even as their computational cost and data requirements keep them less established than feature-based and convolutional methods.
Whatever the model, its value depends on operators trusting its alarms enough to act on them; the false-alarm and alarm-fatigue problem is treated with the other cross-cutting challenges in Section 5.
4.3. Level 2: Diagnosis and Condition Assessment
Once an abnormal condition is detected, the next task is to determine its type, location, and severity. This is the role of diagnosis and condition assessment. At this level, data from inspection and monitoring are used to locate defects, characterize them, and assess the extent of degradation. Pipelines degrade over time through corrosion, erosion, mechanical stress, and environmental action, and integrity management programs monitor and assess this decline before it leads to failure. Modern pipelines, instrumented with in-line inspection tools and sensors, generate substantial datasets for this purpose.
A central application at this level is the automatic identification and sizing of metal-loss defects from in-line inspection data. Layouni et al. [25] developed a technique for analyzing magnetic flux leakage data using pattern-adapted wavelets and an artificial neural network to predict defect depth. The method first applies wavelet-based signal processing to isolate defect signatures in the sensor data, then feeds the extracted features into a feedforward network to estimate corrosion depth, and proposes using the estimated depth and length to assign a severity rating that indicates whether urgent repair is warranted, a step the paper describes but does not evaluate. Tested on about 1300 defects simulated with analytical MFL models, the network estimated depth within ±10 percent of the true depth at a signal-to-noise ratio of 10 dB (at 80 percent certainty), against ±35 percent for linear regression; application to field MFL data is left to future work. The approach handled a range of defect shapes and was computationally efficient enough to be considered for large inspection datasets. A notable strength is that it does not require explicit analytical models of the magnetic field because the network learns the mapping directly. More recent work continues to automate defect recognition, and the development of computer vision for inspection imagery is one active thread, with convolutional neural networks showing early success at identifying corrosion patches and cracks from image data [39].
Hussain and Zhang [7] addressed noise filtering in in-line inspection data by directly developing a machine learning approach for outlier detection, applying random forest regression, linear regression, and nearest-neighbor methods to flag abnormal points that deviate from expected corrosion-growth trends. They tested the approach on a longitudinal dataset of oil-pipeline corrosion measurements spanning 22 years. They validated it against the statistical Z-score method, finding that the machine learning models identified essentially the same outliers as the statistical check and as each other; on this record the learned models matched the simple statistical check but did not improve on it. The result is a robust way to automatically clean inspection data, which matters because every downstream predictive model inherits the quality of the data it trains on. As inspection tools move to higher resolution, outlier-detection methods will need to be revalidated on the new data.
Failure-cause classification from incident records also belongs at this level. The two incident-database studies discussed in Section 4.4.3 assign a cause to failures that have already occurred: one identifies which natural force caused each recorded incident on gas transmission pipelines, and the other assigns cause categories to oil-pipeline accidents. Both are trained and tested on failure records alone, so neither forecasts whether or when a segment will fail. Explaining why a recorded failure happened is a diagnostic task in the rubric of Table 1, so Table 4 codes both studies at Level 2, although their authors describe the task as prediction.
4.4. Level 3: Prediction
4.4.1. Corrosion Growth and Remaining Life
Learning models have been applied to predict corrosion, metal fatigue, cracking, and the factors that drive degradation. Forecasting corrosion growth and remaining pipe life is a natural regression problem, and models trained on historical inspection measurements and operating data can predict future corrosion rates or the time until a defect reaches a critical threshold. Hussain and colleagues [6] emphasize that integrating real-time sensor data, such as pressure, flow, and chemical composition, with maintenance records enables a proactive approach that detects corrosion trends before they lead to failure. Ensemble regressors such as random forests and gradient boosting suit the prediction of internal corrosion rates from parameters such as fluid composition, temperature, and pipe material, and such predictions could guide where and when to inspect and to apply corrosion inhibitors. The challenge is the familiar one of generalization, since a model tuned to one pipeline may not transfer to another pipeline under different conditions, which is why adaptive models that update with new inspection data are of active interest.
A related strand predicts the residual strength or failure pressure of corroded pipe sections, aiming to reproduce the results of computational models such as finite element analysis or established burst-pressure formulas with far less calculation. Xiao and colleagues studied this problem in depth. In one study, they generated a large dataset of corrosion scenarios from industry standards and a physics-based probabilistic model. They compared six machine learning models to predict failure outcomes, finding that an artificial neural network (ANN) was the most accurate and recommending it as the optimal model for the task, with the best model assigning failure-risk levels more rapidly than the physics-based computation it replaced [40]. The computational speed is operationally important because it enables risk assessment closer to real time. A separate study by the same group predicts failure pressure directly [41], with models trained on burst-test data compiled from the literature and explained with SHAP so that engineers can see which inputs drive each prediction. Both studies check their models retrospectively against pipeline incidents reported to PHMSA, which makes them among the more field-grounded predictive studies in the corpus, but prospective validation on operating lines and integration with integrity-management software remain the next steps.
Hybrid approaches extend this work by folding uncertainty and expert knowledge into the prediction. Adabavazeh and colleagues [42] used a fuzzy cognitive map drawing on expert opinion to identify and analyze the factors that most influence the corrosion of natural gas pipelines. There is also growing interest in digital-twin concepts for pipelines, in which a virtual replica is continuously updated with real-time data and model predictions to forecast integrity issues.
Environmental conditions also bear directly on pipeline integrity, and machine learning helps assess those risks. Weather and geohazard factors such as heavy rainfall, temperature extremes, and seismic activity can worsen corrosion, trigger landslides, or impose mechanical stress, and Ahmed and colleagues [10] review how weather-related external forces and climate change combine to propagate pipeline failures through corrosion, erosion, and mechanical damage, and examine the maintenance strategies that can mitigate these effects. Correlating environmental factors such as soil moisture and precipitation with pipeline condition supports a proactive approach, for example, adjusting cathodic protection before corrosion accelerates, and integrating environmental data with operational metrics serves both safety and compliance.
4.4.2. Predictive Maintenance of Rotating Equipment
Commercial machine-health systems, such as the one Baker Hughes markets with Augury, use AI-based software on condition data from rotating equipment to predict machine failures, so that degradation can be addressed during scheduled downtime instead of by reactive repair. The deployment the vendor documents is a pilot: from September 2022 the system monitored more than 50 pumps, agitators, extruders, blowers, fans, and conveyors at INVISTA’s nylon plant in Kingston, Ontario, with vibration analysts reviewing its alerts, and the program was then extended into 2023 [43]. The plant lies outside midstream service, so the source is counted as transferable evidence (Section 1.1) and coded as a pilot rather than routine operation; its savings figures are vendor claims and are not reproduced here. Techniques such as long short-term memory networks [13] and probabilistic models are well-suited to the temporal patterns that precede equipment faults. Cavitation in pumps also figures here as a degradation mechanism, since cavitation-induced erosion is difficult to detect early with threshold-based monitoring and benefits from the same machine-learning pattern recognition. Looking ahead, reinforcement learning offers a way to optimize maintenance policies directly, learning the best times to intervene to maximize availability while minimizing cost, and transfer learning offers a way to apply a model trained on one station’s machines to another’s.
Predictive maintenance and failure-risk modeling are both predictive, but they differ in object, data, and evidence, and treating them together hides a difference in maturity. Predictive maintenance forecasts the remaining life of a specific machine, such as a pump, compressor, or bearing, from condition-monitoring streams; its outputs are asset-level, and vendor material reports a field pilot of a commercial machine-health system [43]. Failure-risk modeling, discussed next, estimates the failure pressure or failure risk of pipeline segments; it is evaluated offline, on simulated or experimental data or against incident records that may not reflect current operating conditions, and it remains largely retrospective.
4.4.3. Failure-Cause Classification and Failure-Risk Prediction
A distinct and growing area uses machine learning on pipeline incident databases, such as the PHMSA (Pipeline and Hazardous Materials Safety Administration) incident and annual-report data to classify failure causes from pipeline and operational features. Ensemble classifiers can assign failure causes from imbalanced historical records and can be paired with explanation tools such as SHAP values to check that a model’s logic agrees with engineering judgment. Awuku et al. [9], for example, benchmarked nine machine and deep learning models on PHMSA oil pipeline accident records, countered class imbalance with oversampling and cost-sensitive learning, added features extracted from unstructured report text, and used SHAP to identify the factors behind the predicted causes; their best model (LightGBM) reached an F1 score of 86 percent. This supports operators and regulators in identifying systemic risks and targeting prevention. However, the quality and quantity of historical failure data remain limited, and natural language processing of textual incident reports is one promising way to extract more from the record. Classifying failure causes from incident records is difficult because failures are uncommon, cause categories are imbalanced, and reports vary in completeness, so headline accuracy should be read alongside per-class recall, precision, and the validation design, and performance on one incident dataset cannot be assumed to transfer to another. The label problem is visible even in the stronger results. In an earlier study, Awuku et al. [8] began with 1321 PHMSA natural gas pipeline incident records from 2010–2022 and modeled the 81 usable natural-force incidents among them, so the 92.3 percent accuracy of their best model (XGBoost) is estimated from a small number of held-out cases. Because both studies assign causes to incidents that have already occurred, they are coded at Level 2 (Section 4.3).
Real-time monitoring systems move failure prediction closer to operations. Tan et al. [26] proposed an integrated pipeline management system that fuses pressure, flow, and temperature data to monitor pipeline health and detect impending failures, introducing a custom ensemble they call WA-SRF, a Wombat-Algorithm-driven scalable random forest, to improve accuracy and scalability for streaming data. The system applies Z-score normalization and extracts frequency-domain features using the fast Fourier transform before feeding the data into the model. In testing, it reported 98.7 percent accuracy in predicting failures and anomalies, along with an area under the receiver operating characteristic curve (AUC) of 0.98 for anomaly detection, although the source of the sensor data (simulated, laboratory, or field) is not stated. As with other streaming systems, its performance depends on sensor quality, the operating environment, and integration with SCADA, which are discussed in Section 5.
4.5. Level 4: Decision and Optimization
The applications here focus on the economics and efficiency of pipeline transport, recommending ways to move more product through the system, sequence batches, and schedule maintenance based on predicted risk. Here, optimization uses estimates from predictive models, together with operating constraints and business objectives, to recommend actions that improve safety, reliability, throughput, or cost.
4.5.1. Throughput and Scheduling
A representative application is throughput optimization, where models learn from historical operations to recommend how a network should be operated within pressure, capacity, equipment, and contractual constraints. Saboo [44] reports, in a practitioner conference paper, a North American gas pipeline case study in which a machine-learning-backed business intelligence application used historical operational data, including pressures, flows, and compressor settings, together with operator knowledge, to support daily operating decisions. The system provided optimization recommendations and anomaly detection support via a dashboard. The case study reports operational improvements and cost benefits, while also emphasizing that data quality, system integration, workforce training, regulatory compliance, and explainability are prerequisites for broader adoption.
Batch scheduling in multi-product pipelines is a more difficult combinatorial problem. Such systems transport different refined products in sequential batches, must satisfy delivery schedules, and must minimize interface mixing and contamination. Operations research has traditionally dominated this area, but machine learning is increasingly being examined as a way to accelerate batch planning, forecast demand and capacity, track interface movement, and monitor operating conditions. Tu et al. [45] review these emerging applications and identify batch planning, interface tracking, mixed-oil monitoring, demand prediction, and operating-condition identification as key opportunities. Full automation remains limited because scheduling decisions must satisfy hydraulic, commercial, inventory, and safety constraints, but machine learning can still provide decision support and speed up schedule preparation.
Energy efficiency is a closely related target, pursued mainly through improved compressor and pump operation. Reinforcement learning is relevant because it can learn control policies that balance energy consumption, flow requirements, and equipment constraints. However, such policies require rigorous validation against safety and operating limits before deployment. For this reason, reinforcement-learning-based systems are more likely to first appear as advisory tools or as human-approved controllers. Robustness under demand variation, equipment outages, and changing boundary conditions remains a central research need.
A further prescriptive application optimizes when and where to perform maintenance by using predicted risk as an input to scheduling. In this workflow, segments or assets with higher predicted failure probability are prioritized for inspection, excavation, repair, or replacement. At the same time, lower-risk work may be deferred or grouped to reduce cost. Some optimization frameworks in the broader infrastructure literature, such as the resilience-optimization work of Fang and Zio [46], show how predictive risk estimates can be converted into prescriptive resource-allocation decisions. In pipeline integrity management, this pattern provides the bridge from Level 3 prediction to Level 4 decision support.
4.6. Level 5: Action and Automation
At the top of the continuum, sensing, prediction, and control are integrated in real time, and the system begins to implement or initiate operational actions under human supervision. This is the frontier of digital transformation in pipelines, and it answers the hardest question: whether a system can implement operational decisions safely on its own. Closed-loop control of this kind aims to maintain safe and optimal operating conditions while reducing human workload. Still, the balanced assessment is that it remains largely aspirational, constrained by the safety, regulatory, and cybersecurity realities of critical infrastructure.
4.6.1. Closed-Loop Control and Digital Twins
Early forms of closed-loop operation are most plausible in bounded pump and compressor applications, where monitoring data and system models can adjust operating set-points within predefined limits. In practice, these systems typically remain semi-automated: automated logic may recommend or execute limited adjustments, while operators retain authority over major changes and abnormal conditions. This architecture demonstrates the feasibility of connecting condition monitoring to operational control, but it also reflects the caution required when the controlled equipment is part of critical infrastructure.
Digital twins are the foundation most likely to carry pipelines toward genuine automated control, because a virtual replica, continuously updated with real-time data, can estimate conditions and predict behavior in a form that connects directly to control systems. Wang and colleagues [47] present what they describe as a real-world case study of pipeline condition monitoring built on a digital-twin framework that integrates damage detection, quantification, and degradation prediction, achieving real-time synchronization between the physical and virtual pipeline through an ensemble of physics-based, signal-processing, finite-element, data-driven, and probabilistic models. The platform is designed to let operators continuously evaluate system health and assess risk. The system was applied to predict the reliability of a set of pipes with fatigue cracking damage, and the authors present the results as showing potential for real-world application; no deployment on an operating asset is reported. The authors suggest that digital-twin systems may serve as a foundation for future closed-loop monitoring and control. This represents the expected direction of development: digital twins first inform human decision-making, then support semi-automated control, and only later may participate in closed-loop operation at scale.
A digital twin is not inherently a Level 5 technology; its level is set by the function it performs. A twin that visualizes condition sits at Levels 1–2, one that forecasts degradation at Level 3, one that recommends operating changes at Level 4, and only a twin that closes the control loop reaches Level 5, a gradation that matches the capability levels proposed for digital twins generally [20]. The twin of Wang et al. [47] monitors condition and predicts degradation to support operators’ decisions, and it leaves closed-loop control to future work, so it is placed at Levels 2–3, and its evaluation on physical pipes rather than an operating line is coded as laboratory evidence. Classifying digital twins by their claimed capability would overstate the state of the art.
4.6.2. Constraints on Full Automation
Fully autonomous pipeline control remains limited, and the constraints extend beyond algorithmic performance. Regulatory requirements, safety considerations, and cybersecurity risks all argue for keeping a human in the loop, and most current systems operate in exactly that configuration, where automated recommendations or preliminary actions are subject to operator review. An AI-driven control system is also a potential target for cyberattack, which raises the stakes on validation and fail-safes well above what a purely advisory system would require [48]. As sensing reliability, data integration, and modeling accuracy improve, semi-autonomous and closed-loop operation may become more feasible. The transition will necessarily be gradual because errors at this level affect safety, environmental protection, and public trust. The higher the operational maturity, the more trust and verification weigh alongside algorithmic capability. The cross-classification in Section 4.7 is consistent with this: no coded source reaches Level 5, the only Level 4 evidence is a practitioner case report, and no coded source at any level reports closed-loop validation.
4.7. Cross-Classification of the Reviewed Studies
Table 3 consolidates the representative studies discussed throughout this survey and organizes them by maturity level, validation environment, external validation, and deployment status, with each study’s data source and, where the source reports it, the size of its dataset. Where a study reports performance under controlled or laboratory conditions, this is noted because the recurring theme of this review is that such figures do not translate cleanly to field deployment. Entries marked as qualitative give no single headline metric that could be verified against a primary source, or come from vendor material whose figures are not reproduced.

Table 3.
Representative studies by maturity level, validation environment, external validation, and deployment status, ordered by level and year. Metrics are as reported by the cited source and are not comparable across rows, because validation environments differ.
Table 3.
Representative studies by maturity level, validation environment, external validation, and deployment status, ordered by level and year. Metrics are as reported by the cited source and are not comparable across rows, because validation environments differ.
| Study | Year | Level | Method | Data source and size | Validation env. | Reported metric | Ext. val. | Deployment |
|---|---|---|---|---|---|---|---|---|
| Chen et al. [24]‡ | 2004 | L1 | Support vector machine | Negative pressure waves | Laboratory | Early SVM leak detection and localization | No | Research prototype |
| Abdulla et al. [23]‡ | 2013 | L1 | Artificial neural network | Pressure and flow signals | Laboratory | Robust on noisy signals | No | Research prototype |
| Eddyfi [31]† | 2021 | L1 | Eddy-current array (Spyne); threshold-based detection, no ML documented | In-ditch ECA scans | Operational (in-ditch) | In-ditch hard-spot detection (vendor; qual.) | Not rep. | Commercial |
| Ullah et al. [3] | 2023 | L1 | ANN, KNN, DT, RF on AE features | AE; laboratory line (gas and water, 13–18 bar, 0.5–1 mm pinholes); 360 samples per test | Laboratory | ∼99% acc. (leak vs. no leak) | No | Research prototype |
| Siddique et al. [4] | 2024 | L1 | DBN-GA-LSSVM on CWT images | AE; laboratory line (13–18 bar) | Laboratory | High acc. in noise (qual.) | No | Research prototype |
| Ullah et al. [5] | 2024 | L1 | Hybrid 1D CNN-LSTM | AE; laboratory line (gas and water); 4 sets of 360 samples | Laboratory | 99.86% acc.; above TD-LSTM and BiGRU | No | Research prototype |
| Hasanpour et al. [27] | 2024 | L1 | SVM vs. CNN; microcontroller deployment | Grundfos laboratory set: 297 recordings, 7 pumps | Laboratory (benchmark) | SVM 92% per pump, 81% fleet; CNN ∼91% | No | Research prototype |
| ENTEGRA [30]† | 2024 | L1 | UHR-MFL with automated analysis; no ML documented | In-line MFL, field run | Operational | Hard-spot detection and characterization (vendor; qual.) | Not rep. | Commercial |
| Waqar et al. [21] | 2025 | L1 | Domain-guided FFNN | Transient pressure; simulation and laboratory viscoelastic rig | Simulation + laboratory | Multi-leak detection (qual.) | No | Research prototype |
| Zadkarami et al. [22] | 2016 | L1–L2 | MLP on statistical and wavelet features | Inlet pressure and outlet flow; OLGA simulation of a 20 km line | Simulation | Detects leaks and isolates the leaking section (qual.) | No | Research prototype |
| Layouni et al. [25] | 2017 | L2 | Pattern-adapted wavelets + ANN | Simulated MFL signals; ∼1300 defects | Simulation | Depth ±10% at 10 dB SNR; linear ±35% | No | Research prototype |
| Rachman et al. [2] | 2021 | Review | Review of ML across PIM | MFL and ultrasonic records | n/a (review) | Maps gaps (qual.) | — | — |
| Awuku et al. [8] | 2023 | L2 | Five classifiers of natural-force cause; XGBoost best | PHMSA 2010–2022: 81 natural-force incidents of 1321, plus climate data | Historical field data | 92.3% acc. | No | Research prototype |
| Awuku et al. [9] | 2024 | L2 | Nine ML and DL models classifying failure cause; LightGBM best; cost-sensitive learning; SHAP | PHMSA oil pipeline accident records, highly imbalanced; features from report text | Historical field data | F1 86%; Cohen’s 0.82 | Not rep. | Research prototype |
| Hussain and Zhang [7] | 2025 | L2 | RF, linear regression, KNN | 22-year ILI record, oil pipeline | Historical field data | Matches Z-score outliers | No | Research prototype |
| Baker Hughes [43]† | 2023 | L3 | AI-based machine-health diagnostics | Vibration data from 50+ machines at a nylon plant | Pilot (nylon plant) | Machine-health monitoring (vendor; qual.) | Not rep. | Commercial; pilot |
| Xiao et al. [41] | 2024 | L3 | ML regressors | Burst-test data from the literature | Laboratory | Failure-pressure prediction (qual.) | Partial (PHMSA) | Research prototype |
| Xiao et al. [40] | 2024 | L3 | Six ML models (ANN best) | Generated from standards and a probabilistic model | Simulation | Risk classes; ANN best | Partial (PHMSA) | Research prototype |
| Wang et al. [47] | 2024 | L2–L3 | Ensemble (physics, FE, data-driven) | Digital twin of a set of fatigue-cracked pipes | Laboratory (physical pipes) | Reliability prediction (qual.) | Not rep. | Research prototype |
| Tan et al. [26] | 2025 | L3 | WA-SRF (metaheuristic-tuned RF) | Pressure, flow, and temperature sensors; origin not stated | Not reported | 98.7% acc.; AUC 0.98 | No | Research prototype |
| Fang and Zio [46] | 2019 | L4 | Adaptive robust optimization (not ML) | Interdependent-infrastructure risk data | Simulation (non-pipeline) | Risk-to-allocation illustration | No | Conceptual |
| Saboo [44]§ | 2024 | L4 | ML-backed BI and anomaly detection | Historical pressures, flows, and compressor settings | Operational (single case) | Operational and cost gains (case) | Not rep. | Deployed (case) |
| Tu et al. [45] | 2024 | Review | Review of ML in batch planning | Multi-product scheduling data | n/a (review) | Identifies opportunities | — | — |
Industrial implementations and real-case reports are marked by provenance, here and in the reference list: † vendor material (ENTEGRA, Eddyfi, Baker Hughes); § practitioner case report (Saboo). ENTEGRA and Eddyfi document no machine learning component and are not coded in Table 4. Three coded evidence sources evaluated outside midstream service are labeled transferable in Appendix A. Vendor performance figures are not reproduced; the practitioner case is reported as stated and was not independently verified. ‡ Published before the 2015–2025 review window and cited as background. Ext. val.: external validation on data independent of the training source; “Partial (PHMSA)” marks a retrospective check against PHMSA incident records. Abbreviations are listed at the end of the paper.
The figures reported across these studies are not directly comparable, and Table 3 should not be read as a ranking. A 99 percent leak-detection accuracy on a controlled acoustic test, a 92.3 percent accuracy estimated from 81 natural-force incidents in an incident database, and an AUC of 0.98 on sensor data of unstated origin measure different quantities, on different denominators, under conditions that are not the same. Class balance makes this worse. Leaks and failures are rare, so a model can post a high headline accuracy and still miss most of the cases that actually matter. Per-class recall, precision, and false-alarm rate, and for leak detection the detection delay, say more than raw accuracy does, and under severe imbalance a precision-recall curve is more informative than the ROC curve [49]. Studies that report accuracy alone are therefore difficult to judge. The record also skews positive: work with strong results is more likely to be published, so the literature probably overstates typical field performance, and the real gap between reported and deployed accuracy is wider than any single paper shows.
For this reason, each figure in Table 3 is paired with its validation environment and external-validation status, and figures should be compared only within the same environment. A 99 percent laboratory accuracy and a 92.3 percent accuracy estimated from 81 incidents describe different worlds, and placing them in one column records them without ranking them. The same heterogeneity rules out a formal meta-analysis: the studies differ in task definition, class balance, denominator, and validation setting, so a pooled estimate would have no clear referent. The structured comparison adopted instead is the cross-classification in Table 4, which counts studies by level and environment instead of averaging their metrics.
Table 4.
Cross-classification of the 16 coded evidence sources in Table 3 (14 peer-reviewed evaluations, one vendor source, and one practitioner case report) by maturity level (highest level demonstrated) and validation environment (most realistic setting of the primary evaluation). The two reviews, the two vendor inspection services that document no machine learning component, the non-pipeline optimization study, and the two pre-2015 studies are excluded. Shaded cells lie below the proposed minimum environment for the row’s level (Table 1).
Table 4.
Cross-classification of the 16 coded evidence sources in Table 3 (14 peer-reviewed evaluations, one vendor source, and one practitioner case report) by maturity level (highest level demonstrated) and validation environment (most realistic setting of the primary evaluation). The two reviews, the two vendor inspection services that document no machine learning component, the non-pipeline optimization study, and the two pre-2015 studies are excluded. Shaded cells lie below the proposed minimum environment for the row’s level (Table 1).
| Level | V1 Simulation | V2 Laboratory | V3 Historical field data | V4 Pilot | V5 Operational | V6 Closed-loop | Not reported | Total |
|---|---|---|---|---|---|---|---|---|
| L1 Detection | — | 5 [3,4,5,21,27] | — | — | — | — | — | 5 |
| L2 Diagnosis | 2 [22,25] | — | 3 [7,8,9] | — | — | — | — | 5 |
| L3 Prediction | 1° [40] | 2 [41]°,47] | — | 1† [43] | — | — | 1 [26] | 5 |
| L4 Decision | — | — | — | — | 1§ [44] | — | — | 1 |
| L5 Action | — | — | — | — | — | — | — | 0 |
| Total | 3 | 7 | 3 | 1 | 1 | 0 | 1 | 16 |
† Vendor material; § practitioner case report (Table 3). ° Results also checked retrospectively against PHMSA incident records.
Table 4 supports four observations about the coded corpus. First, no coded source reaches Level 5, and none at any level reports closed-loop validation. Second, the field evidence comes from outside the peer-reviewed literature: the only result from routine operation (V5) is a practitioner case report, and the only field pilot (V4) is a vendor’s machine-health pilot at a plant outside midstream service. No peer-reviewed study reports a field pilot; the digital-twin study [47] was evaluated on physical pipes rather than on an operating asset. Third, the realism of peer-reviewed validation does not rise enough to meet the evidence that higher levels demand. All five peer-reviewed Level 1 studies meet the laboratory benchmark set for alerts that a person reviews. At Level 2, three of the five peer-reviewed studies meet the field-data benchmark in their primary evaluation. At Level 3, none of the four does, although two check their results retrospectively against PHMSA incidents. At Levels 4 and 5 the limitation changes character: the coded corpus contains no peer-reviewed, pipeline-specific study at all, so the shortfall there concerns evidence coverage, not validation quality, and the search may undercount such studies (Section 1.1). The framework therefore exposes two gaps, a validation gap among the evaluated Level 1–3 models and an evidence-coverage gap at Levels 4 and 5. Fourth, the field-grounded peer-reviewed studies are those with access to field records, chiefly the PHMSA incident database and an operator’s in-line inspection history [7,8,9], which suggests that data access, more than algorithmic progress, governs how realistic validation can be. All three are coded at Level 2: they use field records to diagnose, by assigning causes to recorded incidents or cleaning inspection data, and none uses them to forecast. Forecasting whether and when a segment will fail requires records of segments that did not fail as well as of those that did, which incident databases alone do not provide. Excluding the three transferable sources identified in Section 1.1 changes none of these observations. The coded set falls from 16 to 13 sources, distributed 3, 5, 4, 1, and 0 across Levels 1–5 instead of 5, 5, 5, 1, and 0, and the only field pilot drops out, so the V4 column falls from one source to none while V5 keeps its single practitioner case. A taxonomy built on application areas alone would not reveal these patterns, because each is a relation between the two axes rather than a property of any one application.
Read by publication year, Table 3 also shows how the field has moved. The 2016–2017 studies apply classical classifiers and shallow networks to simulated pressure and MFL signals at Levels 1–2 [22,25]. From 2023, deep architectures raised Level 1 accuracy on laboratory rigs, cause classifiers trained on PHMSA incident records appeared at Level 2, and Level 3 filled with failure-pressure, failure-risk, and degradation models evaluated mostly on simulated or experimental data. In the coded corpus, Level 4 is represented only by a 2024 practitioner case, and Level 5 not at all. Research has climbed the levels faster than its validation has followed: the 2023–2025 studies are validated in the same simulation, laboratory, and retrospective settings as the earlier ones.
Table 5 condenses this evidence level by level, setting the applications and methods reviewed beside the validation they reach, their deployment status, and the main open problem at each level.
Table 5.
Synthesis of the evidence by maturity level. Validation reached summarizes the peer-reviewed studies in Table 4; deployment status is taken from Table 3.
| Level | Applications reviewed | Typical methods | Validation reached | Deployment status | Main open problem |
|---|---|---|---|---|---|
| L1 Detection | Leak detection (acoustic, transient, multi-sensor); operational anomalies; hard spots; pump cavitation | SVM, RF, and KNN on engineered features; CNN, CNN-LSTM, DBN-GA-LSSVM; autoencoders and clustering | Laboratory rigs and benchmark data; all five peer-reviewed studies meet the laboratory benchmark | ML models are research prototypes; deployed detection rests on commercial inspection tools that document no ML component | Field validation under noise and attenuation; false alarms; generalization across assets |
| L2 Diagnosis | Leak isolation; metal-loss sizing from MFL; cleaning of ILI records; failure-cause classification from incident records | MLP and ANN on wavelet features; RF, linear regression, and KNN for outliers; gradient boosting (XGBoost, LightGBM) for cause classes | Simulation (two studies); historical field data (a 22-year ILI record and PHMSA incident records); three of five peer-reviewed studies meet the field-data benchmark | Research prototypes | Sizing validated on field MFL data against excavation results; cause classifiers tested on independent incident data |
| L3 Prediction | Corrosion growth and failure pressure; failure risk; predictive maintenance; degradation prediction in a digital twin | ANN and other ML regressors; WA-SRF; AI-based machine-health monitoring; physics-based and data-driven ensembles | Simulation, burst tests, and physical pipe tests, two with retrospective PHMSA checks; none of the four peer-reviewed studies meets the field-data benchmark | Research prototypes; one vendor-reported machine-health pilot outside midstream service | Prospective validation on operating lines; failure records paired with data on segments that did not fail |
| L4 Decision | Throughput optimization; batch scheduling; risk-based maintenance scheduling | ML-backed decision support; reinforcement learning as an advisory tool; optimization on predicted risk | No peer-reviewed pipeline study; one practitioner case in operation | One deployed case (practitioner report) | Peer-reviewed pilots with success criteria agreed in advance |
| L5 Action | Closed-loop pump and compressor control; digital twins that act on the plant | Reinforcement-learning control; twin-based control | None | None; operators keep authority over major changes | Closed-loop validation, fail-safe verification, cyber-hardening, regulatory approval |
5. Challenges and Limitations
The applications surveyed here demonstrate real potential, but several challenges limit their wider deployment, spanning technical, operational, regulatory, and organizational grounds. By drawing them together here, it becomes clear why so much of the field’s reported success remains confined to controlled settings. Data quality and availability sit at the foundation. Sensor data can be noisy due to environmental interference, sensor degradation, or calibration drift, and inspection data may contain outliers that require robust preprocessing, making outlier detection itself an active application. More fundamentally, labeled data for rare events such as failures and leaks is scarce, which limits the use of supervised learning and pushes operators toward simulated data or historical incident databases that may not fully represent real conditions, thereby raising the risk of overfitting and poor generalization. Data silos compound the problem, since maintenance logs, inspection reports, and SCADA streams reside in different systems and formats, and integrating them into model-ready datasets remains an ongoing obstacle, which the industry is beginning to address with semantic data models and digital twins.
Which data limitation dominates depends on the application. In incident-based failure modeling, scarce positive examples, incomplete labels, and distribution shift across products, pipe vintages, and geographies largely determine what a model can learn and how well it transfers; Awuku et al., for example, began with 1321 PHMSA incident records and could model only the 81 usable natural-force incidents among them [8]. In acoustic and transient leak detection, signal attenuation, operating variability, and background noise can matter as much. The limitations also interact: filtering can reduce measurement noise but cannot supply missing failure cases or close the gap between laboratory and field operating conditions, and calibration drift and inconsistent labeling in historical records compound both problems. Validation should therefore target the failure modes that matter for each sensing modality, asset, and prediction task.
Model generalization and robustness form a second challenge, closely tied to the first. Models often struggle to transfer across pipeline configurations, operating conditions, and fluid types, and environmental factors such as temperature swings and soil chemistry further degrade performance. The dynamic nature of operations introduces concept drift, in which the assumptions a model was trained on become stale as conditions change, necessitating continual retraining. Building models robust to this variation, especially for real-time applications, remains genuinely difficult, and it is the technical root of the laboratory-to-field gap.
Computational complexity is a third constraint. Many advanced methods, particularly deep learning with transforms such as the continuous wavelet transform, are computationally intensive and may not suit real-time deployment on edge devices with limited processing power, even though low-latency inference is exactly what time-sensitive tasks like leak detection and surge prevention require. More capable edge processors are making real-time deployment increasingly feasible. Quantization already brings small convolutional models within reach of microcontroller-class hardware [27]. Balancing accuracy against computational efficiency is a persistent tension, especially on networks with hundreds or thousands of sensors generating high-velocity data.
Integration with legacy systems poses practical difficulties that are easy to underestimate. Many pipeline systems run on outdated hardware or proprietary data formats, which complicates the deployment of modern analytics. Interfacing new systems with existing SCADA infrastructure requires careful planning to ensure compatibility and minimize disruption. Cybersecurity concerns arise whenever AI systems connect to critical infrastructure, as these systems become potential targets, making encryption and access control integral to the design. Machine learning adds attack surfaces of its own. Manipulated sensor streams or false data injected into SCADA can poison training data or trigger missed and false alarms, and a model that acts on the line, as at Level 5, can turn such an attack into a physical event [48]. Defenses therefore extend beyond encryption and access control to plausibility checks of inputs against physical models, signed and versioned model artifacts, and adversarial testing before deployment.
Regulatory and ethical considerations add further constraints. AI systems must align with the standards set by bodies such as the Pipeline and Hazardous Materials Safety Administration and the Environmental Protection Agency. The opacity of some models raises real concern about interpretability, since operators must justify their decisions to regulators. Sharing incident data across organizations to build more robust models raises questions about the privacy of sensitive operational information, and transparency and accountability must be reconciled with regulatory compliance.
Workforce adoption and trust may be the most underappreciated barrier. Successful deployment requires that human operators accept some level of automated recommendations, and skepticism rooted in concerns about reliability or job displacement is common. Workforce training has been a significant hurdle in real deployments, and false positives in predictive models breed the alarm fatigue that erodes confidence. Explainable models and thorough training are essential to overcoming these barriers, but both require time and resources, and human factors must be integral to the solution for wider adoption. Finally, cost and scalability can limit the scale of adoption. Implementation demands substantial investment in sensors, cloud infrastructure, and skilled personnel, which can put it out of reach for smaller operators. Scaling pilot projects to enterprise deployments is complicated by the variation across pipeline networks. Cost-effective solutions that adapt across different systems remain a critical need.
5.1. Post-Deployment Model Management
Most of the reviewed studies stop once a model is trained, yet keeping a deployed model reliable raises issues that the literature rarely addresses. Pipeline conditions change, so a deployed model must be monitored for performance decay and retrained when detected drift calls for it, not on a fixed calendar. Each update should be versioned and re-validated against safety requirements before it can influence operational decisions; in critical infrastructure this re-validation is a governance decision, not a routine software push. Compute and latency constraints complicate all of this. Edge inference for leak detection and surge prevention must run within tight latency and power budgets, so a model retrained in the cloud may be servable centrally but not at the asset. The near absence of MLOps discussion in the reviewed studies is itself a gap that separates published results from deployable systems.
6. Future Research Directions
The cross-classification in Section 4.7 implies an order of priority, because the evidence is thinnest where operational responsibility is greatest. The first priority is graduated field validation for Level 3–5 systems: pilots with success criteria agreed in advance and external validation across several pipelines, reported with the validation-environment and external-validation fields used in Table 3. Shared field datasets, such as labeled leak and inspection records released by operators or regulators, would make such validation possible beyond the few groups that now have access to field data. The second priority is physics-informed and hybrid modeling, a promising route to generalization from sparse and shifting data at every level. The third is transfer learning with standardized feature representations, which would let smaller operators use these methods without large proprietary datasets. The fourth is the post-deployment machinery of Section 5.1 (drift detection, retraining, and edge serving), because a system that does not stay validated after deployment delivers little lasting value. Explainability and security cut across all four, since both are preconditions for the regulatory approval that Level 4 and 5 systems need.
The directions below expand on this agenda; most aim to reduce the gap between controlled validation and field deployment. Hybrid models that combine physics with data address generalization at its root. Folding domain knowledge of fluid dynamics, corrosion mechanics, and operational constraints into learning models improves accuracy and robustness across diverse conditions, and the physics-informed approaches that surfaced in this survey, from domain-guided leak detection to physics-constrained failure prediction, are the clearest examples.
Transfer learning addresses data scarcity and generalization together by adapting a model trained on one pipeline to others with minimal retraining. This is especially promising for smaller operators with limited data, since fine-tuning a pre-trained network on a small pipeline-specific dataset could let them use machine learning effectively without the data volumes that larger operators command, and standardized feature representations would make such transfer more practical across diverse networks. Edge computing and real-time analytics directly address computational and latency constraints. Advances in edge AI, including specialized hardware, enable real-time inference for leak detection and anomaly monitoring without a round trip to the cloud, which also limits how much operational data leaves the site. Research directions here include compressed models such as pruned networks and optimized data-streaming protocols, building on edge-AI foundations [50].
Advanced sensor fusion and deeper integration of the industrial Internet of Things [51] offer another avenue, combining diverse sensor data through multimodal models that fuse structured SCADA data with unstructured drone imagery and incorporate additional sources such as satellite imagery and soil sensors to provide a fuller picture of pipeline health. Digital twins could evolve into comprehensive platforms that integrate real-time data with predictive models to enable dynamic risk assessment and operational optimization, thereby advancing the field along the maturity continuum. Explainable AI is critical for both regulatory acceptance and operator trust, and broader adoption of techniques such as SHAP, LIME, and attention mechanisms could improve transparency in complex models. Frameworks tailored to pipeline applications are particularly important for compliance with regulations that require auditable decisions, as they directly address the workforce-trust barrier.
Sustainability applications will grow as the industry shifts toward lower-carbon operations, with machine learning supporting emissions reduction and the management of carbon capture and storage pipelines, which present distinct fluid dynamics and corrosion profiles. Cybersecurity will demand continued attention as AI systems become integral to operations, with techniques such as adversarial training to harden models and secure data-sharing approaches to enable collaboration without compromising privacy. Across all of these, collaboration between operators, data scientists, and technology providers, together with investment in workforce training, will determine how quickly these advances move from research into practice.
7. Conclusions
The central finding of this survey concerns the evidence more than the applications. When the coded evidence sources are placed on the maturity continuum and read against their validation environments, validation realism does not keep pace with claimed operational responsibility. In this corpus, detection and diagnosis are supported by laboratory, simulated, and some historical field evidence, and the deployed detection tools it describes are commercial inspection services that document no machine learning component. Prediction is validated offline in the peer-reviewed studies: none at Level 3 is evaluated primarily on field data, two check their results retrospectively against incident records, and the only field pilot in the corpus is a vendor-reported machine-health deployment outside midstream service. Decision support rests on a single practitioner case, and no coded source demonstrates closed-loop operation validated in the field. Two gaps follow: a validation gap among the evaluated Level 1–3 models and an evidence-coverage gap at Levels 4 and 5, where eligible pipeline-specific studies are scarce. This is the specific, practical conclusion that the existing literature leaves implicit: beyond the model performance shown in controlled evaluations, validation, transferability, and governance are major unresolved barriers to operational deployment. Progress at the upper levels will depend on pilots completed, fail-safes verified, and regulatory approvals obtained, as well as on models that generalize across assets, which is why graduated field validation heads the agenda in Section 6.
Over the past decade, midstream operators and researchers have tested machine learning on a widening range of pipeline tasks. The literature reviewed here shows a wide range of working applications: leak detectors that are highly accurate on laboratory rigs, models that size defects and predict corrosion growth and failure risk, and tools that support the daily operation of pipeline networks. Commercial tools show that some sensing, assessment, and monitoring workflows are already deployed, but they establish the field maturity of machine learning only when an ML component and its evaluation are documented.
Machine learning is becoming a necessary complement to traditional engineering in midstream operations, but its further advance depends on evidence as much as on algorithms. When deployed carefully, these methods support a shift from reactive to proactive management by predicting problems before they occur, recommending actions, and improving system visibility. As operators, regulators, and researchers build the shared datasets and staged validation that the upper levels require, machine learning will play an even larger role in keeping the world’s pipelines safe, reliable, and efficient.
Author Contributions
Conceptualization, C.N.S., J.Y. and A.P.; methodology, C.N.S., J.Y., A.P. and P.G.; formal analysis, C.N.S., J.Y., A.P. and P.G.; investigation, C.N.S., J.Y., A.P. and P.G.; writing—original draft preparation, C.N.S., J.Y., A.P. and P.G.; writing—review and editing, C.N.S., J.Y., A.P., J.K.K. and P.G.; supervision, C.N.S. and J.Y. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
No new experimental data were generated in this review. The study-level coding used for the maturity and validation synthesis is provided in Table 3 and Table 4 and Appendix A.
Acknowledgments
The authors acknowledge the researchers, agencies, and industry organizations whose published work and technical reports informed this survey.
Conflicts of Interest
The authors declare no conflicts of interest.
Abbreviations
The following abbreviations are used in this manuscript:
| AE | Acoustic emission | MFL | Magnetic flux leakage |
| AI | Artificial intelligence | ML | Machine learning |
| ANN | Artificial neural network | MLOps | Machine learning operations |
| AUC | Area under the receiver operating characteristic curve | MLP | Multilayer perceptron |
| BI | Business intelligence | NDT | Non-destructive testing |
| BiGRU | Bidirectional gated recurrent unit | PHMSA | Pipeline and Hazardous Materials Safety Administration |
| CNN | Convolutional neural network | PIM | Pipeline integrity management |
| CWT | Continuous wavelet transform | PRCI | Pipeline Research Council International |
| DBN | Deep belief network | RF | Random forest |
| DT | Decision tree | SCADA | Supervisory control and data acquisition |
| ECA | Eddy-current array | SHAP | Shapley additive explanations |
| FE | Finite element | SNR | Signal-to-noise ratio |
| FFNN | Feedforward neural network | SVM | Support vector machine |
| GA | Genetic algorithm | TD-LSTM | LSTM on time-domain features |
| ILI | In-line inspection | UHR-MFL | Ultra-high-resolution magnetic flux leakage |
| KNN | k-nearest neighbors | WA-SRF | Wombat-algorithm-driven scalable random forest |
| LSSVM | Least-squares support vector machine | XGBoost | Extreme gradient boosting |
| LSTM | Long short-term memory |
Appendix A. Corpus Ledger
Table A1 and Table A2 account for each of the 24 corpus sources and for the three context studies from outside the corpus that appear in Table 3. The 16 coded evidence sources in Table A1 enter Table 4 at the highest level their results demonstrate and at the most realistic environment of their primary evaluation. The eight uncoded corpus sources and the three context studies in Table A2 are discussed in the text but are not counted.
Table A1.
Coded evidence sources in Table 4 (16). Scope: Pipeline for oil, gas, or product pipelines and their test rigs; Transferable for studies evaluated outside midstream service that meet the criterion of Section 1.1. Symbols as in Table 3.
Table A1.
Coded evidence sources in Table 4 (16). Scope: Pipeline for oil, gas, or product pipelines and their test rigs; Transferable for studies evaluated outside midstream service that meet the criterion of Section 1.1. Symbols as in Table 3.
| Source | Type | Year | Level | Scope | Validation env. | Coding note |
|---|---|---|---|---|---|---|
| Ullah et al. [3] | Peer-reviewed study | 2023 | L1 | Pipeline | Laboratory | Binary detection; size and location claimed, not reported |
| Siddique et al. [4] | Peer-reviewed study | 2024 | L1 | Pipeline | Laboratory | Same rig specification as Ullah et al. |
| Ullah et al. [5] | Peer-reviewed study | 2024 | L1 | Pipeline | Laboratory | Same rig specification as Ullah et al. |
| Hasanpour et al. [27] | Peer-reviewed study | 2024 | L1 | Transferable | Laboratory | Public benchmark of general industrial pumps |
| Waqar et al. [21] | Peer-reviewed study | 2025 | L1 | Transferable | Laboratory | Viscoelastic test pipes; simulation also used |
| Zadkarami et al. [22] | Peer-reviewed study | 2016 | L2 | Pipeline | Simulation | Detection and isolation of the leaking section |
| Layouni et al. [25] | Peer-reviewed study | 2017 | L2 | Pipeline | Simulation | Proposed repair-severity step not evaluated |
| Awuku et al. [8] | Peer-reviewed study | 2023 | L2 | Pipeline | Historical field data | Natural-force cause of PHMSA incidents; failure records only |
| Awuku et al. [9] | Peer-reviewed study | 2024 | L2 | Pipeline | Historical field data | Cause of PHMSA oil accidents; failure records only |
| Hussain and Zhang [7] | Peer-reviewed study | 2025 | L2 | Pipeline | Historical field data | 22-year in-line inspection record |
| Xiao et al. [40] | Peer-reviewed study | 2024 | L3 | Pipeline | Simulation | Retrospective PHMSA check |
| Xiao et al. [41] | Peer-reviewed study | 2024 | L3 | Pipeline | Laboratory | Burst-test data; retrospective PHMSA check |
| Wang et al. [47] | Peer-reviewed study | 2024 | L3 | Pipeline | Laboratory | Fatigue-cracked test pipes; no operating-asset deployment |
| Tan et al. [26] | Peer-reviewed study | 2025 | L3 | Pipeline | Not reported | Origin of sensor data not stated |
| Baker Hughes [43]† | Vendor material | 2023 | L3 | Transferable | Pilot | 50+ machines at a nylon plant from September 2022, extended into 2023; figures not reproduced |
| Saboo [44]§ | Practitioner case report | 2024 | L4 | Pipeline | Operational | Single case; reported as stated |
Table A2.
Corpus sources not coded (8) and context studies from outside the corpus (3). Symbols as in Table 3.
Table A2.
Corpus sources not coded (8) and context studies from outside the corpus (3). Symbols as in Table 3.
| Source | Type | Year | In Table 3 | Reason not coded |
|---|---|---|---|---|
| Corpus sources not coded | ||||
| ENTEGRA [30]† | Vendor material | 2024 | Yes | Commercial inspection service; automated analysis, no ML documented |
| Eddyfi [31]† | Vendor material | 2021 | Yes | Commercial inspection probe; threshold-based detection, no ML documented |
| Adabavazeh et al. [42] | Peer-reviewed study | 2024 | No | Expert-based factor analysis; no model performance evaluated |
| Rachman et al. [2] | Review | 2021 | Yes | Review |
| Tu et al. [45] | Review | 2024 | Yes | Review |
| Hussain et al. [6] | Review | 2024 | No | Review |
| Ahmed et al. [10] | Review | 2024 | No | Review |
| Casas et al. [39] | Review | 2025 | No | Review |
| Context studies outside the corpus | ||||
| Chen et al. [24]‡ | Peer-reviewed study | 2004 | Yes | Published before 2015; background |
| Abdulla et al. [23]‡ | Peer-reviewed study | 2013 | Yes | Published before 2015; background |
| Fang and Zio [46] | Peer-reviewed study | 2019 | Yes | Non-pipeline optimization, not ML; illustration |
References
- U.S. Department of Transportation. USDOT Pipeline Safety Data Report Index. https://www.phmsa.dot.gov/data-and-statistics/pipeline/pipeline-safety-data-report-index, 2026.
- Rachman, A.; Zhang, T.; Ratnayake, R.M.C. Applications of machine learning in pipeline integrity management: A state-of-the-art review. International Journal of Pressure Vessels and Piping 2021, 193, 104471. [CrossRef]
- Ullah, N.; Ahmed, Z.; Kim, J.M. Pipeline leakage detection using acoustic emission and machine learning algorithms. Sensors 2023, 23, 3226. [CrossRef]
- Siddique, M.F.; Ahmad, Z.; Ullah, N.; Ullah, S.; Kim, J.M. Pipeline leak detection: A comprehensive deep learning model using CWT image analysis and an optimized DBN-GA-LSSVM framework. Sensors 2024, 24, 4009. [CrossRef]
- Ullah, S.; Ullah, N.; Siddique, M.F.; Ahmad, Z.; Kim, J.M. Spatio-temporal feature extraction for pipeline leak detection in smart cities using acoustic emission signals: A one-dimensional hybrid convolutional neural network–long short-term memory approach. Applied Sciences 2024, 14, 10339. [CrossRef]
- Hussain, M.; Zhang, T.; Chaudhry, M.; Jamil, I.; Kausar, S.; Hussain, I. Review of prediction of stress corrosion cracking in gas pipelines using machine learning. Machines 2024, 12, 42. [CrossRef]
- Hussain, M.; Zhang, T. Machine learning-based outlier detection for pipeline in-line inspection data. Reliability Engineering & System Safety 2025, 254, 110553. [CrossRef]
- Awuku, B.; Huang, Y.; Yodo, N. Predicting natural gas pipeline failures caused by natural forces: An artificial intelligence classification approach. Applied Sciences 2023, 13, 4322. [CrossRef]
- Awuku, B.; Huang, Y.; Yodo, N.; Asa, E. Interpretable machine learning models for failure cause prediction in imbalanced oil pipeline data. Measurement Science and Technology 2024, 35, 076006. [CrossRef]
- Ahmed, T.; Mahmood, Y.; Yodo, N.; Huang, Y. Weather-related combined effect on failure propagation and maintenance procedures towards sustainable gas pipeline infrastructure. Sustainability 2024, 16, 5789. [CrossRef]
- Hastie, T.; Tibshirani, R.; Friedman, J. The Elements of Statistical Learning: Data Mining, Inference, and Prediction, 2nd ed.; Springer-Verlag, 2009.
- Sutton, R.S.; Barto, A.G. Reinforcement Learning: An Introduction, 2nd ed.; MIT Press, 2018.
- Hochreiter, S.; Schmidhuber, J. Long short-term memory. Neural Computation 1997, 9, 1735–1780. [CrossRef]
- Hinton, G.E.; Osindero, S.; Teh, Y.W. A fast learning algorithm for deep belief nets. Neural Computation 2006, 18, 1527–1554. [CrossRef]
- Lundberg, S.M.; Lee, S.I. A unified approach to interpreting model predictions. In Proceedings of the Advances in Neural Information Processing Systems 30 (NIPS 2017), Long Beach, CA, USA, 2017; pp. 4765–4774.
- SAE International. J3016: Taxonomy and definitions for terms related to driving automation systems for on-road motor vehicles. SAE standard, SAE International, 2021.
- Gamer, T.; Hoernicke, M.; Kloepper, B.; Bauer, R.; Isaksson, A.J. The autonomous industrial plant—Future of process engineering, operations and maintenance. Journal of Process Control 2020, 88, 101–110. [CrossRef]
- Schuh, G.; Anderl, R.; Dumitrescu, R.; Krüger, A.; ten Hompel, M. Industrie 4.0 Maturity Index: Managing the digital transformation of companies (Update 2020). acatech study, acatech, 2020.
- ISO. ISO 13374-1:2003. Condition Monitoring and Diagnostics of Machines—Data Processing, Communication and Presentation—Part 1: General Guidelines. International Organization for Standardization, 2003.
- San, O.; Rasheed, A.; Kvamsdal, T. Hybrid analysis and modeling, eclecticism, and multifidelity computing toward digital twin revolution. GAMM-Mitteilungen 2021, 44, e202100007. [CrossRef]
- Waqar, M.; Memon, A.M.; Louati, M.; Ghidaoui, M.S.; Alhems, L.M.; Meniconi, S.; Brunone, B.; Capponi, C. Pipeline leak detection using hydraulic transients and domain-guided machine learning. Mechanical Systems and Signal Processing 2025, 224, 111967. [CrossRef]
- Zadkarami, M.; Shahbazian, M.; Salahshoor, K. Pipeline leakage detection and isolation: An integrated approach of statistical and wavelet feature extraction with multi-layer perceptron neural network. Journal of Loss Prevention in the Process Industries 2016, 43, 479–487.
- Abdulla, M.B.; Herzallah, R.O.; Hammad, M.A. Pipeline leak detection using artificial neural network: Experimental study. In Proceedings of the 5th International Conference on Modelling, Identification and Control (ICMIC), Cairo, Egypt, 2013; pp. 328–332.
- Chen, H.; Ye, H.; Lv, C.; Su, H. Application of support vector machine learning to leak detection and location in pipelines. In Proceedings of the IEEE Instrumentation and Measurement Technology Conference (IMTC), Como, Italy, 2004; pp. 2273–2277. [CrossRef]
- Layouni, M.; Hamdi, M.S.; Tahar, S. Detection and sizing of metal-loss defects in oil and gas pipelines using pattern-adapted wavelets and machine learning. Applied Soft Computing 2017, 52, 247–261. [CrossRef]
- Tan, J.; Song, Z.; Li, H.; Zhang, J.; Liu, J.; Lu, Y. Data analysis and modeling of gas pipeline intelligent management system based on machine learning algorithm. Journal of Computational Methods in Sciences and Engineering 2025, 25, 3652–3666. [CrossRef]
- Hasanpour, M.A.; Engholm, R.; Fafoutis, X. Pump cavitation detection with machine learning: A comparative study of SVM and deep learning. In Proceedings of the 2024 IEEE Annual Congress on Artificial Intelligence of Things (AIoT), Melbourne, Australia, 2024; pp. 219–225.
- Pipeline and Hazardous Materials Safety Administration. Pipeline safety: Identification and evaluation of potential hard spots, in-line inspection tools and analysis. Advisory Bulletin, Federal Register, vol. 89, no. 222, 2024.
- U.S. Code of Federal Regulations. 49 CFR 192.3: Definitions. https://www.ecfr.gov/current/title-49/part-192/section-192.3. Electronic Code of Federal Regulations.
- ENTEGRA Solutions. UHR-MFL in-line inspection; Case study: putting hard-spot history in context. https://entegrasolutions.com/solutions/services/uhr-mfl-in-line-inspection/; https://entegrasolutions.com/case-study-putting-hard-spot-history-in-context/, 2024. † Vendor material (industrial implementation).
- Eddyfi Technologies. Pipeline hard spots: Spyne, the proven solution for in-ditch detection. https://www.eddyfi.com/en/product/spyne-array-pipeline-crack-assessment, 2021. Eddyfi Technologies technical resource. † Vendor material (industrial implementation).
- Pipeline Research Council International. PR335-233813-R01: Prioritization methodology for hard spot manufacturing anomalies (MAT-7-2A). PRCI technical report, Pipeline Research Council International, 2025.
- He, K.; Zhang, X.; Ren, S.; Sun, J. Deep residual learning for image recognition. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition (CVPR), Las Vegas, NV, USA, 2016; pp. 770–778. [CrossRef]
- Huang, G.; Liu, Z.; van der Maaten, L.; Weinberger, K.Q. Densely connected convolutional networks. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition (CVPR), Honolulu, HI, USA, 2017; pp. 2261–2269. [CrossRef]
- Howard, A.G.; Zhu, M.; Chen, B.; Kalenichenko, D.; Wang, W.; Weyand, T.; Andreetto, M.; Adam, H. MobileNets: Efficient convolutional neural networks for mobile vision applications. arXiv preprint arXiv:1704.04861 2017. [CrossRef]
- Zhang, X.; Zhou, X.; Lin, M.; Sun, J. ShuffleNet: An extremely efficient convolutional neural network for mobile devices. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition (CVPR), Salt Lake City, UT, USA, 2018; pp. 6848–6856. [CrossRef]
- Cho, K.; van Merrienboer, B.; Gulcehre, C.; Bahdanau, D.; Bougares, F.; Schwenk, H.; Bengio, Y. Learning phrase representations using RNN encoder–decoder for statistical machine translation. In Proceedings of the Conference on Empirical Methods in Natural Language Processing (EMNLP), Doha, Qatar, 2014; pp. 1724–1734. [CrossRef]
- Vaswani, A.; Shazeer, N.; Parmar, N.; Uszkoreit, J.; Jones, L.; Gomez, A.N.; Kaiser, L.; Polosukhin, I. Attention is all you need. In Proceedings of the Advances in Neural Information Processing Systems 30 (NIPS 2017), Long Beach, CA, USA, 2017; pp. 5998–6008.
- Casas, E.; Ramos, L.T.; Romero, C.; Rivas-Echeverría, F. A review of computer vision applications for asset inspection in the oil and gas industry. Journal of Pipeline Science and Engineering 2025, 5, 100246. [CrossRef]
- Xiao, R.; Zayed, T.; Meguid, M.; Sushama, L. Rapid failure risk analysis of corroded gas pipelines using machine learning. Ocean Engineering 2024, 313, 119433. [CrossRef]
- Xiao, R.; Zayed, T.; Meguid, M.A.; Sushama, L. Predicting failure pressure of corroded gas pipelines: A data-driven approach using machine learning. Process Safety and Environmental Protection 2024, 184, 1424–1441. [CrossRef]
- Adabavazeh, N.; Nikbakht, M.; Amindoust, A.; Tabrizi, S.A.H. The identification and analysis of pivotal factors influencing the corrosion of natural gas pipelines using fuzzy cognitive map. Engineering Failure Analysis 2024, 166, 108806. [CrossRef]
- Baker Hughes. Someone to watch over machines. Baker Hughes company story, 15 March 2023. https://bakerhughes.com/company/energy-forward/someone-watch-over-machines, 2023. † Vendor material (industrial implementation).
- Saboo, S. Optimizing gas pipeline operations with machine learning: A case study of a North American energy company. In Proceedings of the SPE Conference at Oman Petroleum and Energy Show, Muscat, Oman, 2024. Paper SPE-218564-MS. § Practitioner case report (industrial implementation). [CrossRef]
- Tu, R.; Zhang, H.; Xu, B.; Huang, X.; Che, Y.; Du, J.; Wang, C.; Qiu, R.; Liang, Y. Machine learning application in batch scheduling for multi-product pipelines: A review. Journal of Pipeline Science and Engineering 2024, 4, 100180. [CrossRef]
- Fang, Y.P.; Zio, E. An adaptive robust framework for the optimization of the resilience of interdependent infrastructures under natural hazards. European Journal of Operational Research 2019, 276, 1119–1136. [CrossRef]
- Wang, T.; Feng, K.; Ling, J.; Liao, M.; Yang, C.; Neubeck, R.; Liu, Z. Pipeline condition monitoring towards digital twin system: A case study. Journal of Manufacturing Systems 2024, 73, 256–274. [CrossRef]
- McLaughlin, S.; Konstantinou, C.; Wang, X.; Davi, L.; Sadeghi, A.R.; Maniatakos, M. The cybersecurity landscape in industrial control systems. Proceedings of the IEEE 2016, 104, 1039–1057. [CrossRef]
- Saito, T.; Rehmsmeier, M. The precision-recall plot is more informative than the ROC plot when evaluating binary classifiers on imbalanced datasets. PLoS ONE 2015, 10, e0118432. [CrossRef]
- Hua, H.; Li, Y.; Wang, T.; Dong, N.; Li, W.; Cao, J. Edge computing with artificial intelligence: A machine learning perspective. ACM Computing Surveys 2023, 55, 1–35. [CrossRef]
- Sisinni, E.; Saifullah, A.; Han, S.; Jennehag, U.; Gidlund, M. Industrial Internet of Things: Challenges, opportunities, and directions. IEEE Transactions on Industrial Informatics 2018, 14, 4724–4734. [CrossRef]
Figure 1.
The study selection process of this narrative review. Records from the database searches and industry sources pass language and scope screens; the scope screen admits midstream studies and studies of the same equipment and failure mode outside midstream service. Data are extracted from all 24 corpus sources. The 16 coded evidence sources, 13 pipeline-specific and 3 transferable, are also coded by maturity level and validation environment, while the 8 contextual sources inform the synthesis but are not coded. The three context studies outside the corpus are listed in Appendix A.
Figure 1.
The study selection process of this narrative review. Records from the database searches and industry sources pass language and scope screens; the scope screen admits midstream studies and studies of the same equipment and failure mode outside midstream service. Data are extracted from all 24 corpus sources. The 16 coded evidence sources, 13 pipeline-specific and 3 transferable, are also coded by maturity level and validation environment, while the 8 contextual sources inform the synthesis but are not coded. The three context studies outside the corpus are listed in Appendix A.
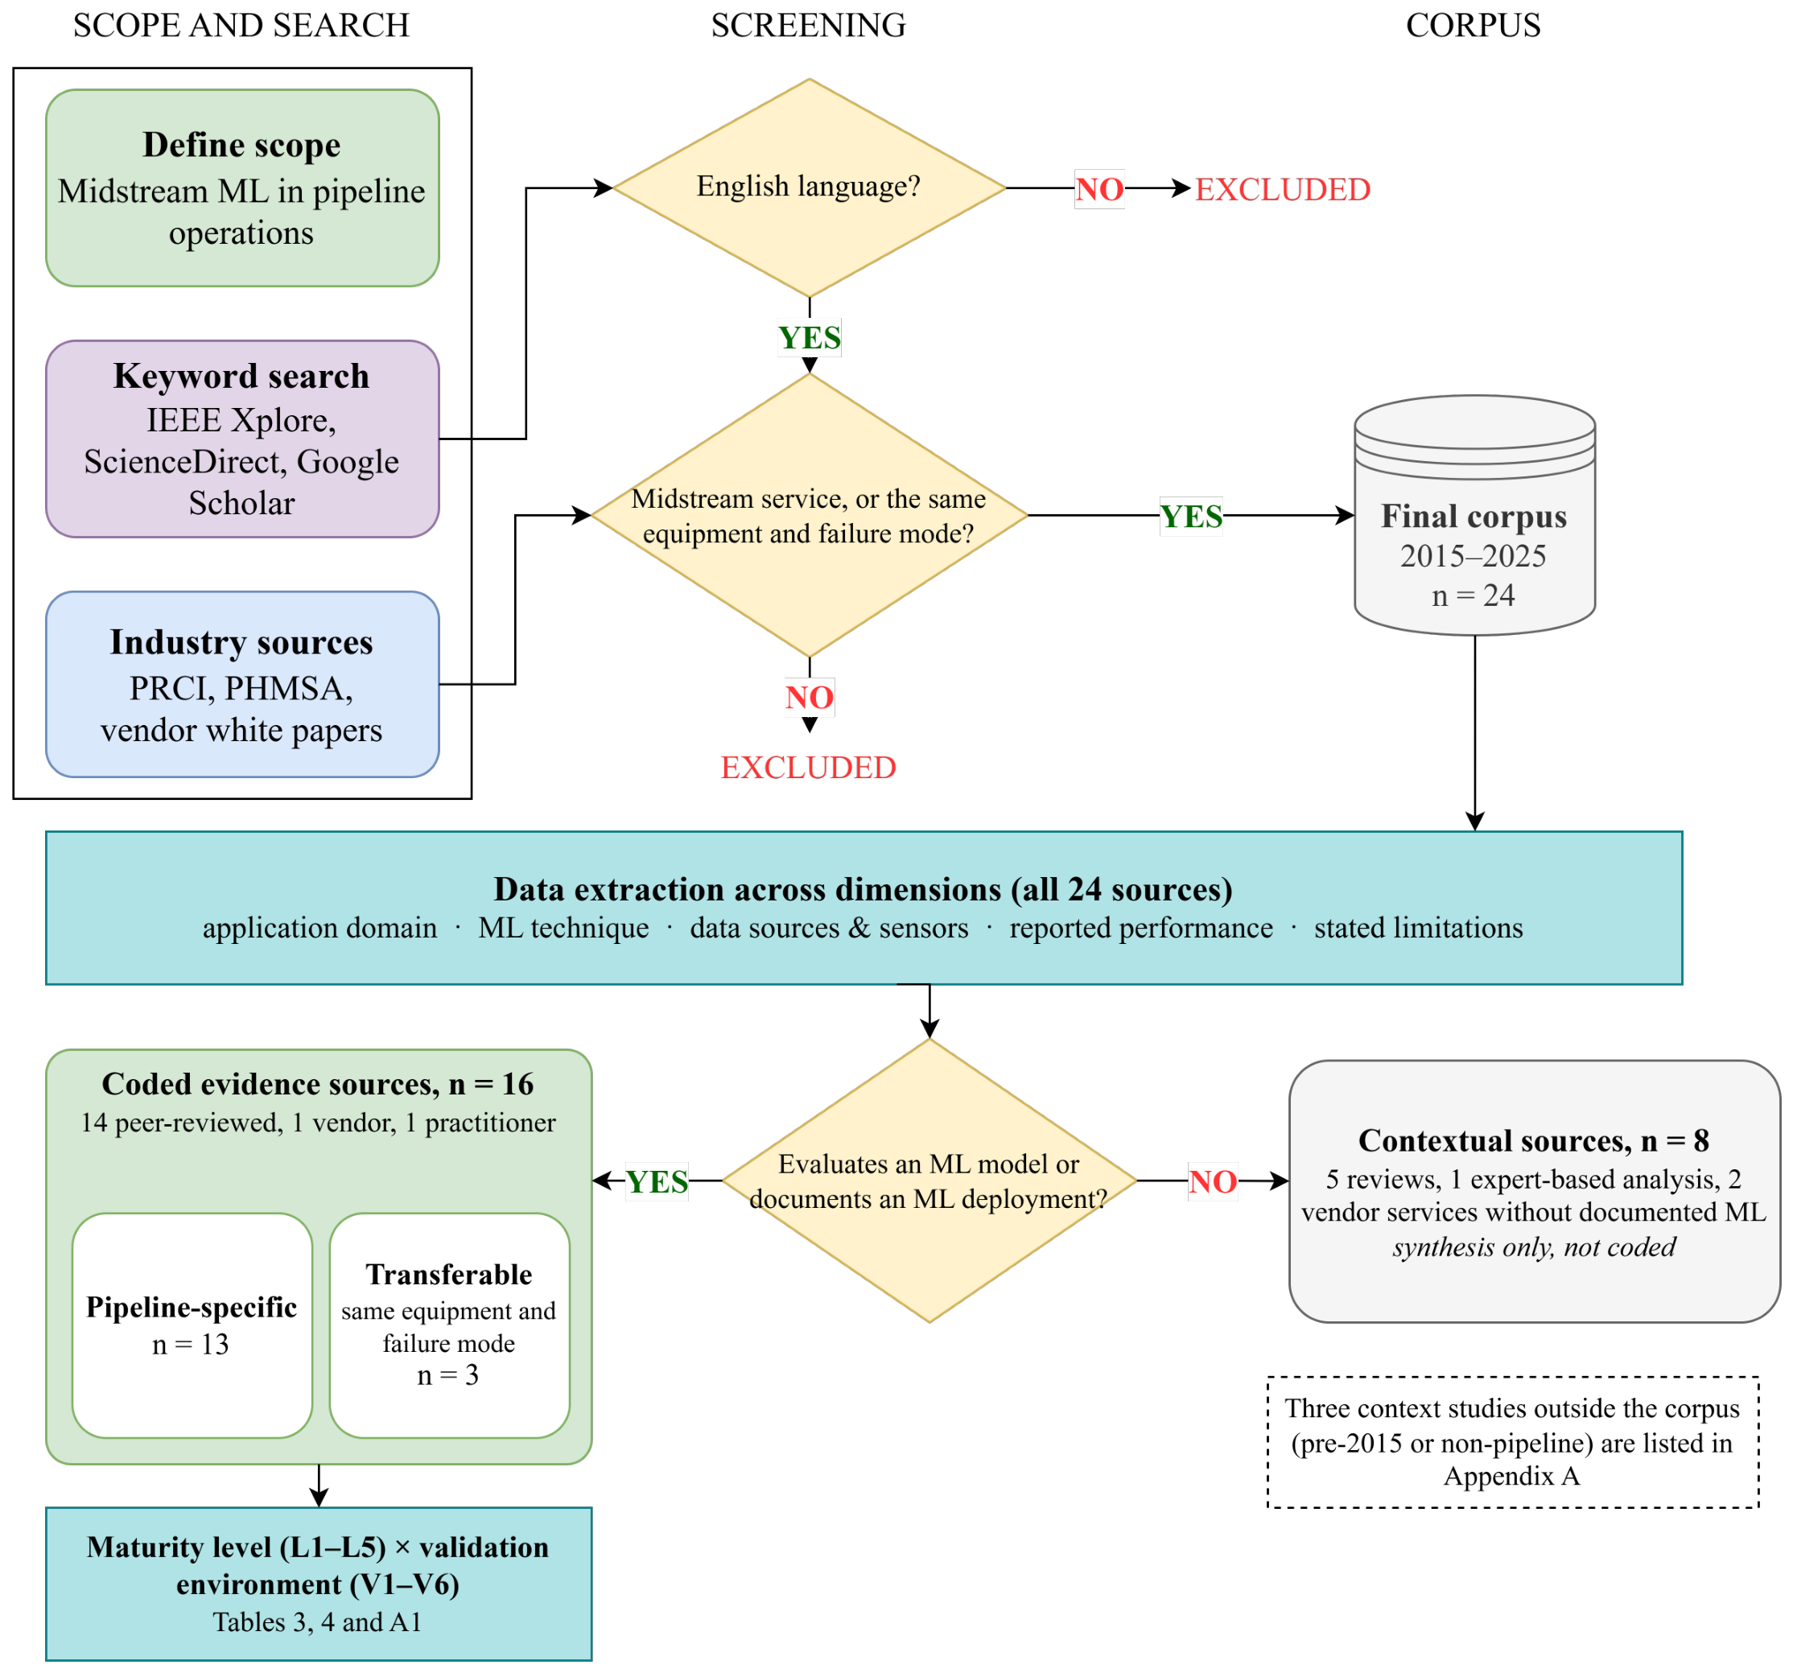
Figure 3.
The five-level operational maturity continuum. Each level is defined by the question it answers and illustrated by typical applications; responsibility shifts from the operator to the model as the levels rise.
Figure 3.
The five-level operational maturity continuum. Each level is defined by the question it answers and illustrated by typical applications; responsibility shifts from the operator to the model as the levels rise.
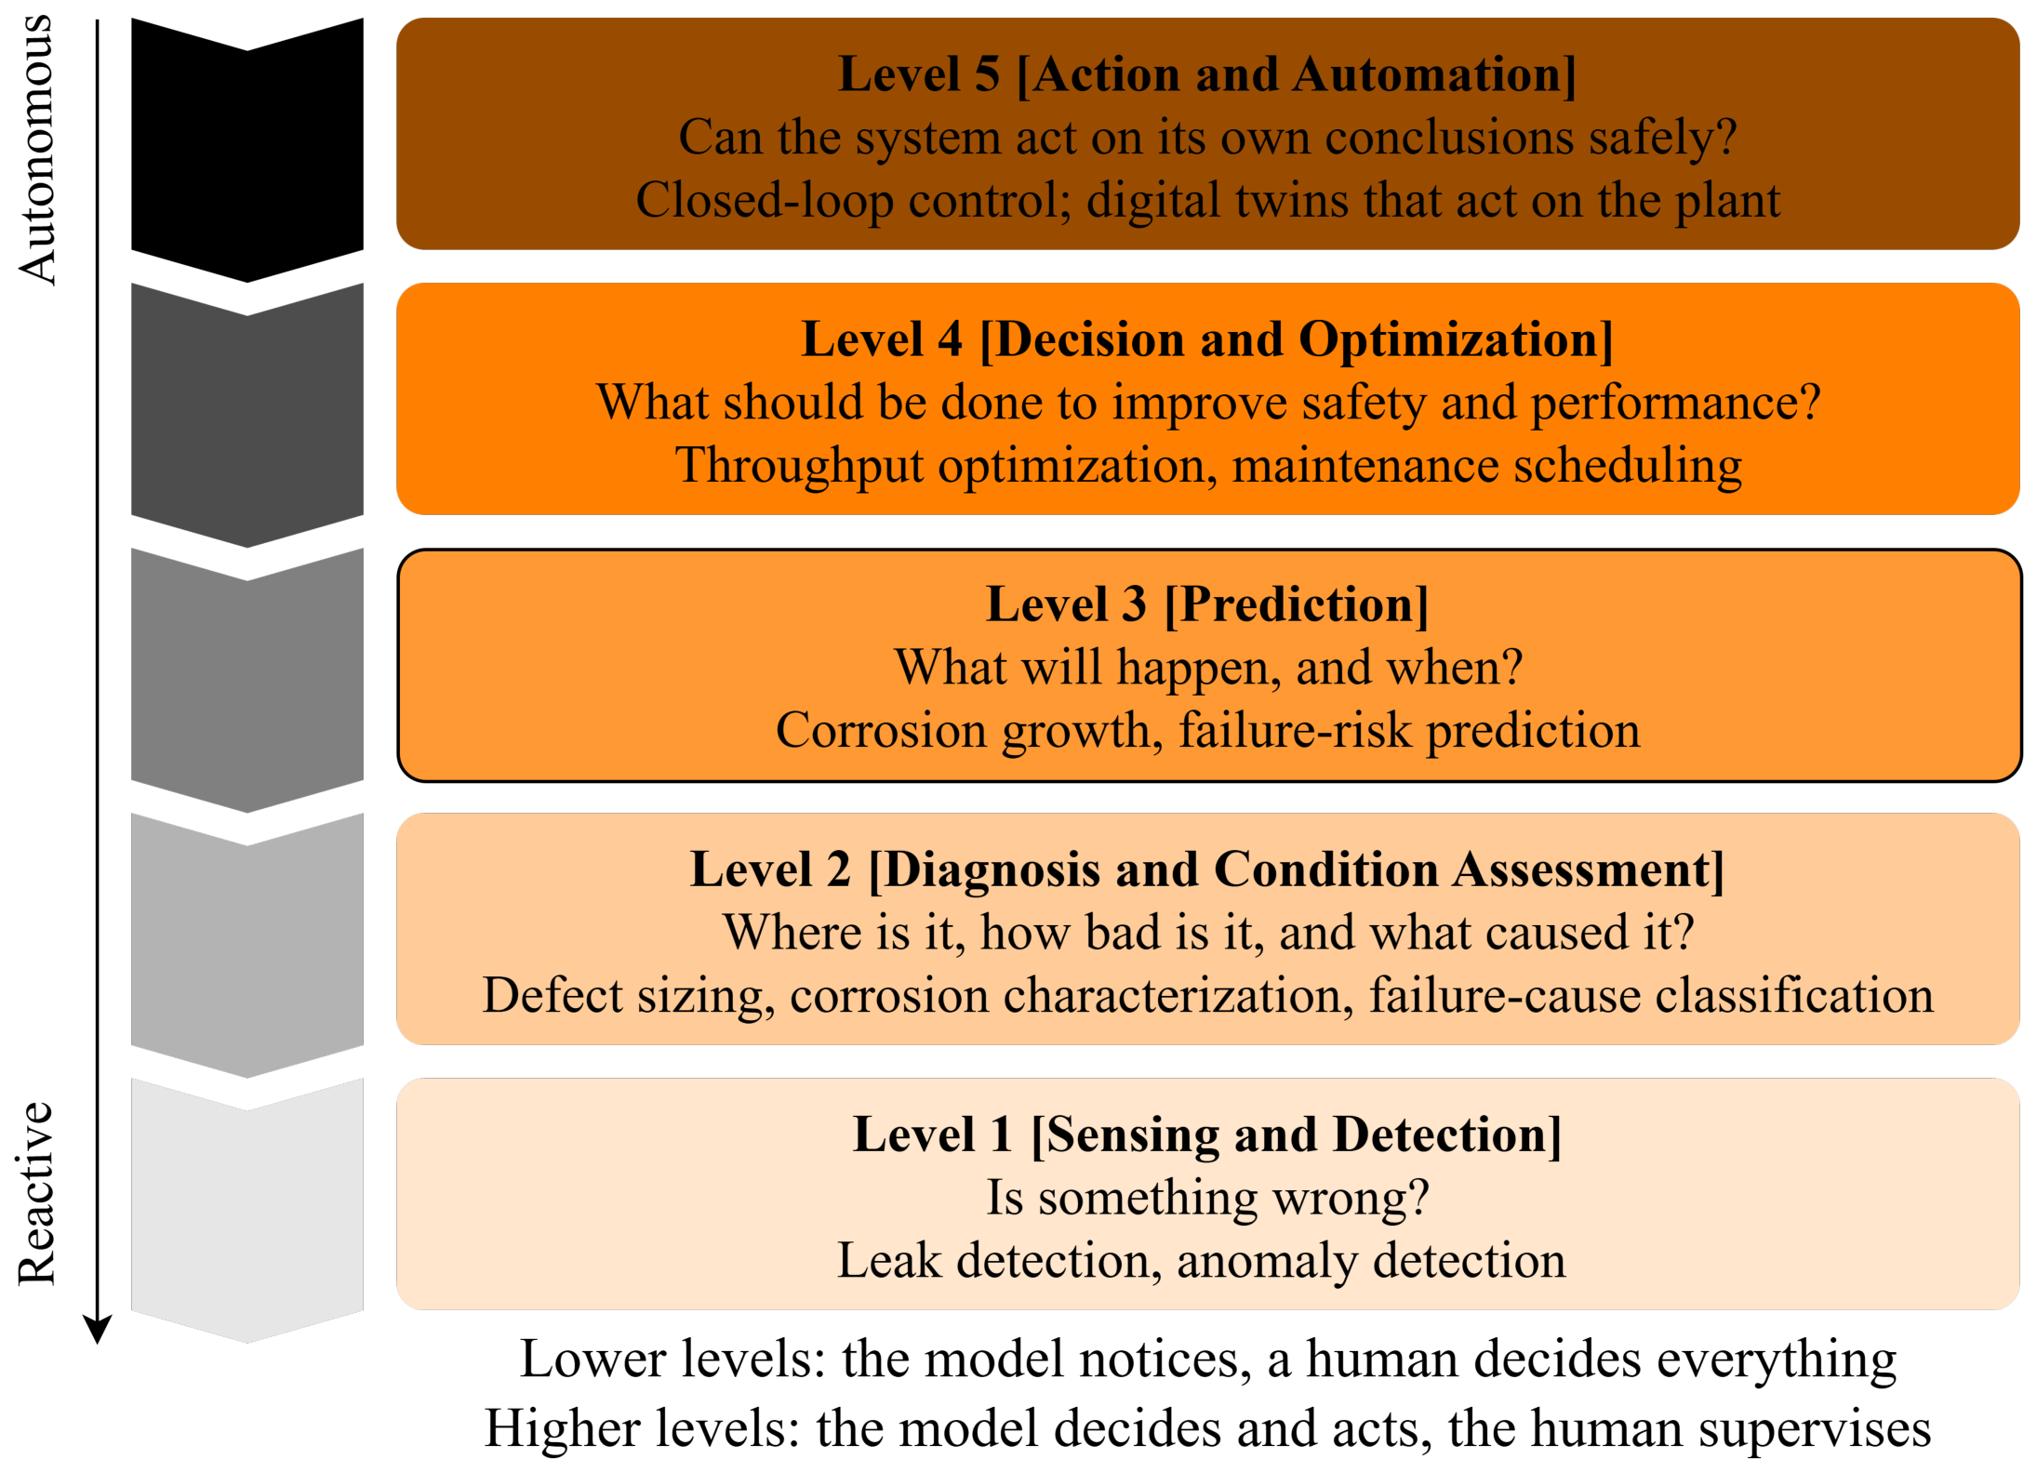
Figure 4.
Conceptual suitability of machine learning method families for the functions associated with each maturity level. Cell labels indicate potential methodological roles, not the frequency of use or the demonstrated maturity of the reviewed studies; the observed distribution of studies appears in Table 4.
Figure 4.
Conceptual suitability of machine learning method families for the functions associated with each maturity level. Cell labels indicate potential methodological roles, not the frequency of use or the demonstrated maturity of the reviewed studies; the observed distribution of studies appears in Table 4.
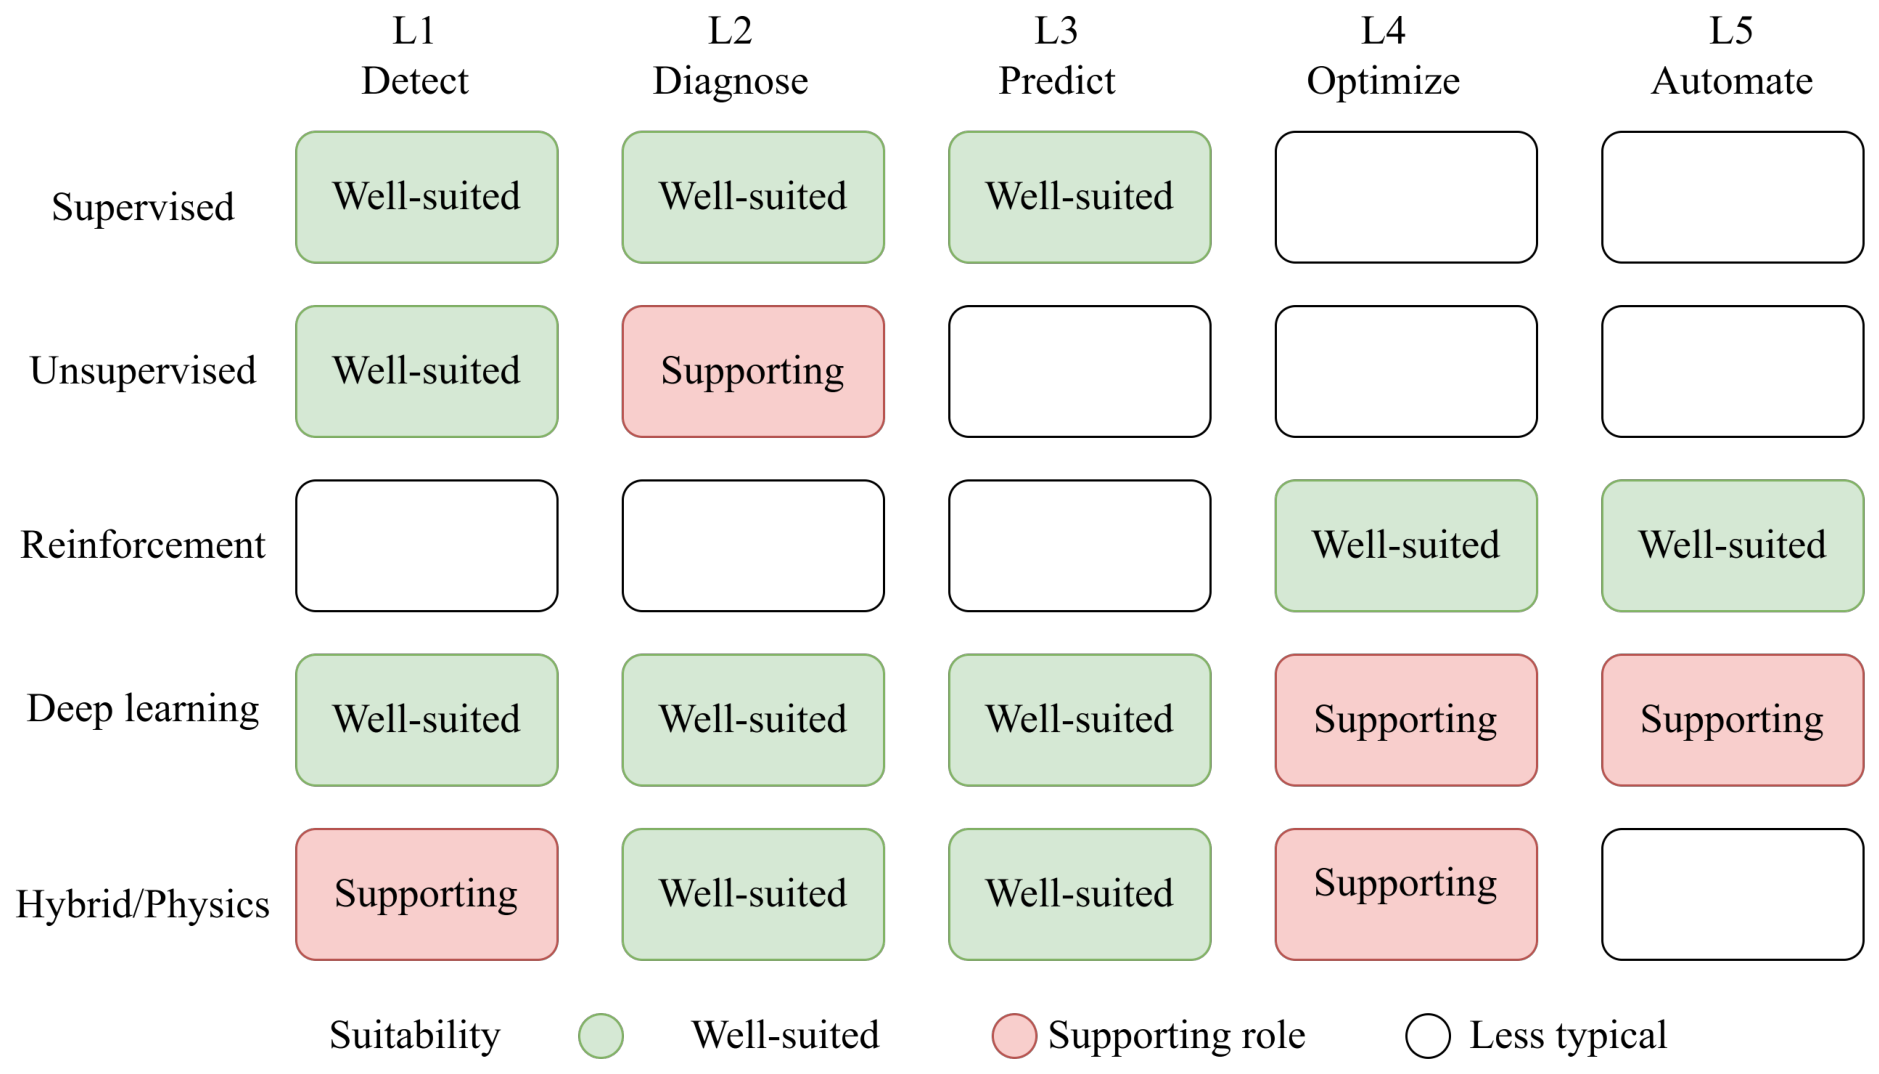
Figure 5.
Hard-spot workflow from in-line inspection to remediation, annotated with the maturity level of each analytical step. Inspection features are fused with pipe attributes and operating context and ranked by learned classifiers, and a deterministic failure-pressure ranking sets excavation priority [32]. In-ditch verification against the 49 CFR 192.3 definition supplies the scarce training labels. Dashed outlines mark steps whose reported performance rests mainly on vendor evidence.
Figure 5.
Hard-spot workflow from in-line inspection to remediation, annotated with the maturity level of each analytical step. Inspection features are fused with pipe attributes and operating context and ranked by learned classifiers, and a deterministic failure-pressure ranking sets excavation priority [32]. In-ditch verification against the 49 CFR 192.3 definition supplies the scarce training labels. Dashed outlines mark steps whose reported performance rests mainly on vendor evidence.
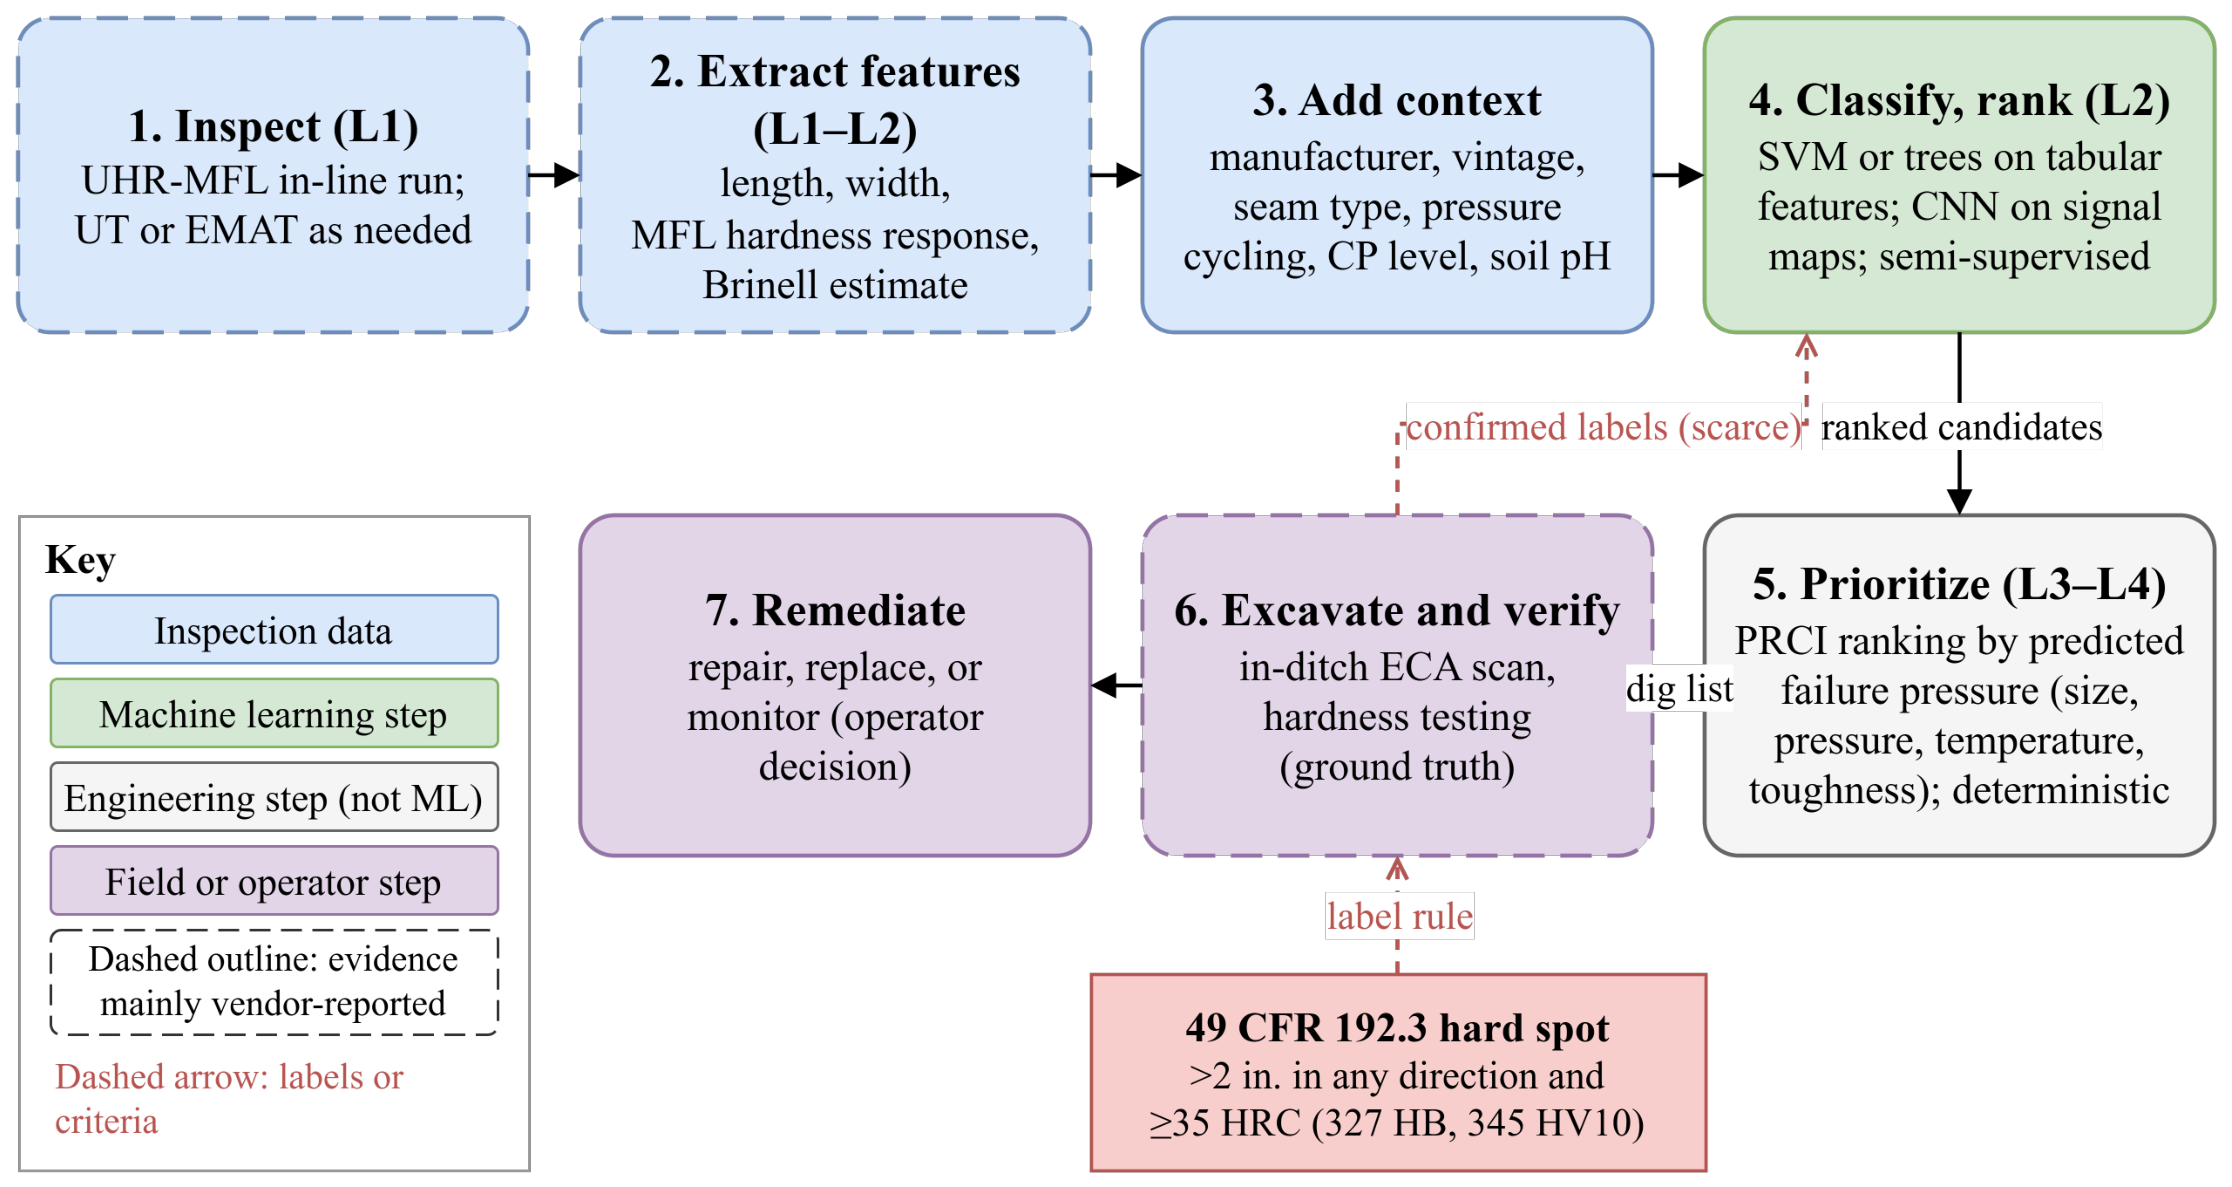
Table 1.
Operational maturity levels defined by capability, decision authority, human role, and the validation evidence expected before field use. A study is placed at the highest level whose capability and decision-authority criteria its reported results demonstrate, not the highest it claims, and it meets the level’s evidence benchmark when its validation environment (V1, simulation, to V6, closed-loop; defined below) reaches the minimum in the last column. The minima are benchmarks proposed by this review, not regulatory criteria.
Table 1.
Operational maturity levels defined by capability, decision authority, human role, and the validation evidence expected before field use. A study is placed at the highest level whose capability and decision-authority criteria its reported results demonstrate, not the highest it claims, and it meets the level’s evidence benchmark when its validation environment (V1, simulation, to V6, closed-loop; defined below) reaches the minimum in the last column. The minima are benchmarks proposed by this review, not regulatory criteria.
| Level | Core question / capability | Automation & decision authority | Human role | Validation expected | Proposed minimum environment |
|---|---|---|---|---|---|
| L1 Sensing & detection | Is something wrong? Flags an abnormal condition | None; output is an alert | Interprets and acts on every alert | Detection metrics (recall, precision, false-alarm rate) on labeled laboratory or field data | V2 Laboratory |
| L2 Diagnosis & assessment | Where is it, how bad, what caused it? Locates and characterizes | None; output is an estimate or description | Judges severity and response | Sizing, localization, or cause-classification error vs. inspection or incident ground truth | V3 Historical field data |
| L3 Prediction | What will happen, when? Forecasts condition or risk | None; output is a forecast | Plans around the forecast | Predictive skill on held-out field outcomes; calibration | V3 Historical field data, out-of-sample |
| L4 Decision & optimization | What should be done? Recommends an action | Advisory; model proposes, human disposes | Reviews and approves recommendations | Decision quality vs. baseline; constraint satisfaction; back-testing | V4 Pilot |
| L5 Action & automation | Can it act safely alone? Executes in a closed loop | Executes within bounds; no per-action approval | Supervises, sets limits, intervenes on exception | Closed-loop validation, fail-safe verification, cyber-hardening, regulatory sign-off | V6 Closed-loop |
Table 2.
Approximate alignment of the proposed levels with maturity schemes in adjacent fields. Each scheme grades a different unit, so the correspondence is only indicative.
Table 2.
Approximate alignment of the proposed levels with maturity schemes in adjacent fields. Each scheme grades a different unit, so the correspondence is only indicative.
| This framework | SAE J3016 (driving automation) | acatech Industrie 4.0 Maturity Index | ISO 13374 (condition monitoring) | Digital-twin capability levels |
|---|---|---|---|---|
| L1 Detection | Level 0 (warnings) | Visibility | State detection | Descriptive to diagnostic |
| L2 Diagnosis | Level 0 | Transparency | Health assessment | Diagnostic |
| L3 Prediction | Level 0 | Predictive capacity | Prognostic assessment | Predictive |
| L4 Decision / optimization | Level 0 (advice, no execution) | Predictive capacity to adaptability | Advisory generation | Prescriptive |
| L5 Action / automation | Levels 2–3 (system acts; person supervises or intervenes) | Adaptability | Outside scope (no actuation) | Autonomous |
| Unit graded: model or study | Vehicle feature | Organization | Monitoring system | Digital twin |
| Evidence per level: specified (Table 1) | Not specified | Not specified | Not specified | Not specified |
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (http://creativecommons.org/licenses/by/4.0/).
Copyright: This open access article is published under a Creative Commons CC BY 4.0 license, which permit the free download, distribution, and reuse, provided that the author and preprint are cited in any reuse.