

Submitted:
19 September 2026
Posted:
21 September 2026
You are already at the latest version
Abstract
The E80 is an open-source, 8-bit, single-cycle soft processor written in VHSIC Hardware Description Language (VHDL) from gates, multiplexers, and flip-flops, without an arithmetic package. Its 39 instructions were derived from 371 program samples in eight sources of introductory computer architecture material. They cover almost 80% of the operations recorded, averaged per source. A toolchain takes an assembly program to a simulation waveform with one keystroke. Presets cover three low-cost field-programmable gate array (FPGA) boards, one on a fully open-source flow. This extended version removes a false combinational loop from the datapath, so the design passes timing analysis on all three flows without workarounds. A serial light-emitting diode (LED) matrix mirrors the simulation signals on the board. Execution can be slowed or stepped one instruction at a time. A self-checking program decides the conformance of every instruction from the final program counter alone. The largest program in the surveyed material, a recursive maze search written for a 16-bit machine, was ported without abridgement into 208 of the 255 memory words. The effect on learning remains unmeasured.
Keywords:
soft processor
; single-cycle processor
; instruction set architecture
; VHDL
; computer architecture education
; digital design education
; FPGA
; microworld
; constructionism
1. Introduction
Educational soft processors have emerged from textbook hypothetical models such as Mano’s Basic Computer [1], presented as register-transfer descriptions and taught through third-party simulators; the classic Simple-As-Possible computer [2], a gate-level schematic of discrete parts that enthusiasts still carry to physical hardware [3]; and the Little Computer 3 (LC-3) [4], an instruction-set specification supported by a software simulator.
Introducing computer architecture concepts through hardware-description languages (HDLs) improves student learning [5,6,7], and “lab-at-home” arrangements built on free electronic-design-automation (EDA) tools and low-cost field-programmable gate array (FPGA) boards have made building a processor at home broadly accessible [8,9,10].
Thirty years ago the same exercise would require a laboratory. Li and Chu built Aizup, a four-stage pipelined processor, for a computer architecture exercise at the University of Aizu in 1996 [11], where each of more than sixty equipment sets paired a workstation running the vendor design tools with an evaluation board and a logic analyzer. Instructions and data were both eight bits wide so that the processor and both memories would fit on a single XC4006PC84, and even then the design needed 541 function generators against the chip’s 512, so both memories were reduced from 256 to 224 bytes. Aizup was drawn as schematics over the vendor’s own component library. Design entry has since moved to hardware description languages, which express the same circuit as text that can be read, diffed, and carried between tools.
VHDL (VHSIC Hardware Description Language) is a formal notation intended for use in all phases of the creation of electronic systems [12]. It supports multiple levels of abstraction that are commonly described using three modeling styles [13]: Behavioral modeling employs an abstract, algorithmic description of a circuit’s operation; the circuit itself is left to the synthesizer to infer. Dataflow modeling uses concurrent signal assignment statements to describe functionality through Boolean equations. Structural modeling interconnects components to form a more complex circuit. Structural and dataflow models can map onto logic diagrams when they rely on primitives a digital-design textbook builds from gates. We call such descriptions gate-transparent. Addition performed with an arithmetic operator such as Sum <= A + B is not gate-transparent; a full adder such as the one shown in Figure 1 is.
In this paper we present the E80, an 8-bit processor in gate-transparent VHDL, and an integrated toolchain. The work began as an undergraduate thesis at the Hellenic Open University (HOU) [14] and was reported at the 8th Panhellenic Conference on Electronics & Telecommunications (PACET) [15]. This paper extends the conference report in the following ways. It removes a false combinational loop from the datapath and reports the resulting gain in maximum clock frequency on three toolchains. It adds a fully open synthesis flow on the OSS CAD Suite. It replaces the parallel light-emitting diode (LED) interface with a serial LED matrix that mirrors the simulation signals and supports single-step execution. It rewrites the memory description as a clocked process. It extends the instruction survey with the LC-3 textbook. It adds a directed test suite, including a self-checking sweep of the instruction set and a port of the largest program in the surveyed material. It reports the first deployment of the platform in a remote lab classroom. Our focus remains on the engineering rather than on learning outcomes.
The remainder of this paper is organized as follows. Section 1.1 reviews related educational processors and the availability of their sources; Section 1.2 outlines the trade-offs inherent in these approaches and states the contributions of this work; Section 2 presents the design methodology, the instruction set and its derivation, the datapath and the elimination of the combinational loop, the memory, the assembly language, the toolchain, and the hardware interface; Section 3 reports the cross-platform synthesis results, the critical-path improvement, the test suite, and the lab-classroom deployment; and Section 4 and Section 5 discuss the findings and conclude.
The complete E80 processor design, including its VHDL source code, custom assembler, and hardware presets, is maintained as an open-source project at https://github.com/Stokpan/E80. The instruction set survey, the synthesis metrics, and the protocols for reproducing both are deposited at https://doi.org/10.5281/zenodo.22757255.
1.1. Related Work
It is easier to define what is related to this project by stating what it is not, and two widely used educational platforms mark the boundary. RVfpga [16] is a pair of courses built on a two-way superscalar and nine-stage RISC-V core, with a branch predictor and an instruction cache. The teaching materials are free for non-commercial teaching under terms that reserve republication and forbid sharing for competitive analysis [17]. The BBC Microbit [18] is a physical board, developed on an explicitly constructionist approach and distributed to schools in the millions, on which a learner writes programs in a block editor, in JavaScript, or in Python. Neither offers a simple central processing unit (CPU) design that a student can read, modify, and rebuild.
Ellard et al. [19] declined to survey the field of such designs in 2002, calling the attempt futile within a five-page paper. They counted at least twenty-five Special Interest Group on Computer Science Education (SIGCSE) papers in the preceding decade, and suspected a dozen designs never publicized outside their own courses for every one documented. Two decades on, those numbers can only have grown, so we take a published comparison as our starting point; Yıldız et al. [20] compared their VSCPU against thirteen educational processors, scoring each for an assembler, a simulator, a compiler, and web access. We surveyed the designs with a public repository or otherwise obtainable artifacts, and added six more outside that comparison. Table 1 summarizes the description method for each design, its hardware target, its software toolchain and license. We record what each design offers, not how well it works. The file-level findings behind every cell are deposited with the data archive.
The VSCPU repository is public and MIT-licensed. The main VerySimpleCPU.v unit is empty, inviting students to fill it. The compiler and the simulator are distributed as Windows executables without source. We ran both, providing a small C program as input; the compiler emitted an assembly listing, which the simulator parsed, producing a step-by-step execution trace to stdout.
XSOC [21] offers a complete toolchain and a test suite, together with a Verilog description of the processor and an earlier schematic version. The flow, however, requires the discontinued Xilinx Foundation 1.5, so it cannot be run today, and its custom license forbids distributing modified versions.
TINYCPU [22] provides a complete stack architecture in 274 lines of Verilog-95, with an assembler and a C compiler. The assembler outputs Verilog assignment lines that the user must paste into the memory module by hand. The authors report improved student satisfaction and enrollment in classroom use, but note that a simple processor may not adequately show modern issues [23].
Sweet-16 [24] was drawn in vendor capture tools, partly using a core generator. Its authors state that schematic entry is the easiest way into digital design, and that designers who have worked only with an HDL have difficulty moving from software thinking to hardware thinking, “having been never in touch with the real gates and flip-flops”. Their students build small adders and counters from gates before assembling the processor, and more than six hundred processors were completed over nine years. No hardware description was published, and the schematics that exist are held in vendor formats.
Baby8 [25] and drv16 [26] avoid that dependency: both are drawn in the Digital circuit simulator [27], and, in addition to Digital’s native Extensible Markup Language (XML) format, both commit rendered images of their sheets and machine-generated Verilog exports, so the circuit can be read in a browser and synthesized without the tool. Baby8 documents an assembler in its slides but it’s absent from the repository; drv16 keeps the RISC-V mnemonics and defines its instruction set in a macro include file for the external GNU assembler, and a script carries the output to the Intel HEX the simulator loads.
Freeman’s SimpleCPU v1a [28] has eleven instructions, a single 8-bit accumulator, and a three-phase cycle. It is built from small components wired together by name and mostly gate-transparent, although its adder/subtractor component relies on an arithmetic package. A single bus serves both instructions and data, and because a data value must also fit an instruction’s immediate field, a data word fills only half of a 16-bit cell. The whole design comprises only about 440 statements.

Table 1.
Educational processor designs whose artifacts we examined, ordered by date of the artifact where obtained, or the cited publication otherwise. Description gives hardware description method and the abstraction level according to Section 1. Hardware is the target FPGA, and Toolchain the supporting software. License dictates both the design and the toolchain; BY requires attribution, NC restricts use to non-commercial purposes, ND forbids distributing modifications, and SA requires same-term propagation for modifications. A dash marks an artifact we could not obtain.
Table 1.
Educational processor designs whose artifacts we examined, ordered by date of the artifact where obtained, or the cited publication otherwise. Description gives hardware description method and the abstraction level according to Section 1. Hardware is the target FPGA, and Toolchain the supporting software. License dictates both the design and the toolchain; BY requires attribution, NC restricts use to non-commercial purposes, ND forbids distributing modifications, and SA requires same-term propagation for modifications. A dash marks an artifact we could not obtain.
| Design | Description | Hardware | Toolchain | License |
|---|---|---|---|---|
| XSOC/xr16 (Gray, 2000) [21] | Verilog, behavioral | XESS XS40 | Assembler, CPU Emulator, Compiler | Custom NC-ND |
| Simple-CPU (Pinault, 2005) [29] | VHDL, behavioral | Spartan-3 | — | GPLv2 |
| TINYCPU (Nakano, 2008) [22] | Verilog, behavioral | Spartan-3 | Assembler, Compiler | GPLv2 |
| Sweet-16 (Angelov, 2009) [24] | — | ACEX | — | — |
| VSCPU (Yıldız, 2018) [20] | Verilog (incomplete) | Nexys | Compiler, CPU Emulator (binaries only) | MIT |
| SimpleCPU (Freeman, 2019) [28] | VHDL, behavioral | Artix-7 | — | CC BY-NC-ND |
| Hack (Nisan & Schocken, 2021) [30] | Custom HDL, gate-transparent | — | Assembler, Compiler, CPU Emulator, HDL Simulator | CC BY-NC-SA |
| Robin (Kalomiros, 2021) [31] | — | MAX 10 | — | — |
| Baby8 (Gazziro, 2024) [25] | Digital (Java), gate-transparent | — | — | MIT |
| drv16 (Assumpção, 2024) [26] | Digital (Java), gate-transparent | Gowin | Macros for the GNU Assembler | MIT |
The simplicity of Freeman’s design and its small instruction set are contrasted by Pinault’s Simple-CPU [29], which comprises about 1700 statements and specifies the richest instruction set we surveyed: thirty-two 32-bit registers, eleven condition flags, and twenty-two encoded instructions that the assembler expands into sixty mnemonics, among them signed and unsigned multiplication, division yielding both quotient and remainder, and seventeen conditional jumps. Its announced assembler, simulator, and compiler were never released, and its data cache and code memory instantiate Xilinx UNISIM primitives directly, binding the design to one vendor.
The Hack computer, part of the NAND to Tetris framework [30], carries gate structure further than any other design we examined. Every chip is composed upward from NAND gates in a custom hardware description language, and its assembler, compiler, CPU emulator, and HDL simulator carry a program to a circuit within the distribution. The composition stops at the flip-flop, which is a primitive rather than a gate network. Wherever a chip’s description file is missing, the simulator substitutes a built-in implementation [32].
The Robin soft-core [31] is the closest published design to our aim: 8-bit, written in standard VHDL, non-pipelined, and described together with an assembler. Its paper announces the Robin-SoC repository on GitHub, but it is empty. The scarcity of published descriptions follows from the pedagogical purpose of those designs: students are expected to build the CPU themselves, and a published implementation would nullify that exercise.
Each design is labeled by the gate-transparency of its arithmetic-logic unit (ALU). Three of the seven available descriptions are gate-transparent. Hack composes its adder from NAND gates. Baby8 and drv16 draw their datapath logic by hand and place the simulator’s adder as a component. The exported form of that component is a single arithmetic operator. The distinction we apply is between placing an adder and writing the operator. The other four designs write the operator directly. In VHDL this comes from an arithmetic package; in Verilog it’s part of the language.
1.2. Motivation and Contributions
The review above exposes three recurring gaps—legal, cognitive, and operational—all of which are related to accessing the design:
- Legal: a learner or an educator can seldom obtain a core in a form they may read, modify, and rebuild.
- Cognitive: where source is available, it is usually abstracted, hiding the gate-level logic that a digital-design course teaches.
- Operational: a ready-to-use toolchain is rarely provided, so a newcomer must configure a simulation or an EDA flow [33] before even running their first program.
We frame the E80 as a constructionist microworld [34] to close these gaps. Against the legal gap, it releases its complete source. Against the cognitive gap, it prefers gate-transparency over behavioral abstraction and arithmetic packages, so the textbook gate-level details (such as the carry propagation of an adder) remain visible in the source. Against the operational gap, it provides an integrated toolchain that carries assembly through to a waveform without requiring the user to configure an EDA command line.
Typical objects-to-think-with, such as the LOGO turtle or the Microbit, are opaque: the learner programs the object and watches it respond without ever seeing its internals. The E80 is built so that a student versed in elementary digital logic can open it, read it as an ordinary gate-level circuit, and modify it. Educational cores usually pay for that readability with a restricted instruction set, or vice versa, as seen in Freeman’s simple design vs Pinault’s rich instruction set in Section 1.1. Our own motivation was to combine a textbook-complete instruction set with gate logic a student can still read. The contributions of this work are thus framed in a design philosophy—the processor as an accessible and modifiable microworld,
- described in gate-transparent VHDL with an instruction set derived from an empirical survey of how assembly is taught (Section 2.2) rather than asserted,
- and accompanied by a toolchain that combines an editor, assembler, simulator, and waveform display, including a fully open synthesis path, released under the GNU General Public License (GPL) on GitHub;
The novelty here is therefore pedagogical and integrative rather than microarchitectural, aligning with Bell and Newell’s note on their own 8-bit theoretical computer: “We have violated our principle of showing ‘real’ computers by designing this computer. We think it is typical of a small processor, but slightly more interesting.” ([35] p. 185).
2. Materials and Methods
Our toolchain provides assembly, VHDL simulation and waveform display using free open-source software:
We provide an all-in-one installer of the toolchain for Windows 10 or later. GHDL, GTKWave, and SciTE, of which Sc1 is the Windows build, are all available for Linux, where the same Lua scripts drive the editor.
We tested the design on the following boards and provide preconfigured settings for each, paired with their EDA software:
Specific details of the required materials for the hardware implementation, such as versions and prices, are given in Section 2.8.
2.1. The Choice of Gate-Transparent VHDL
Established textbooks such as Harris and Harris [41] or Mano and Ciletti [13] treat VHDL and Verilog (or its SystemVerilog extension) side by side. To describe E80, we have chosen VHDL even though Harris and Harris call it “more verbose and cumbersome, as you might expect of a language developed by committee” [41]. The judgment has stood since their first edition of 2007, although the most offending verbosity—component declaration before each instantiation—has been remediable since VHDL’93 [42]. VHDL-2008 added many features to reduce verbosity [43], and the code in Figure 1 uses one of these features—expressions in port maps. We prefer VHDL over Verilog for using textbook names for logic gates, but syntax matters little in any case. In a course-based comparison, two groups of comparable prior grade point implemented the components of a small CPU, one group in VHDL and the other in Verilog. No significant difference was found in either laboratory or final course grades [44].
Although Mano and Ciletti state that students who exploit the possibilities offered by either HDL type enjoy a kinesthetic learning experience ([13] p. 11), Angelov and Lindenstruth chose schematic entry for Sweet-16 on the grounds quoted in Section 1.1: a designer who has worked only in an HDL has never handled the gates and flip-flops that the description stands for. Their students build small adders and counters from gates before they assemble the processor [24].
We accept that objection, and gate-transparency is our answer to it—a description that keeps the gates and flip-flops in front of the reader, as they appear in elementary digital design knowledge. The processor therefore relies on ieee.std_logic_1164 alone, without a numeric package. An example of what we try to avoid is the following one-line assignment ([45] p. 693), which performs subtraction using such a package:
(C_out, result) := (’0’ & a) - (’0’ & b);
Unlike the textbook adder of Figure 1, this assignment uses an arithmetic operator and recovers C_out by widening the operands. The extra bit in b is complemented by the subtraction, and the Carry arriving at that position is reversed by it; C_out is therefore a Borrow, set to 1 when a is less than b. Such an approach would overload the meaning of our JC/JNC mnemonics between addition and subtraction, which could worsen the documented difficulty of borrow and carry for students ([46] p. 305).
We also avoided behavioral abstractions where we could. Apart from the 8-bit D-type flip-flop, the datapath uses no PROCESS block, so it reads as a network of signal assignments and flip-flops rather than an algorithm of nested conditional statements. Again, this costs the code some brevity, and we took three measures against it. We instantiate entities directly, so no component declaration precedes an instance. We use the verbosity-reducing features of VHDL-2008 [43], as far as Quartus Prime Lite allows (Appendix A). We also wrote a support package that names the recurring types and supplies an overloaded match function, substituting for the VHDL-2008 matching relational operators that Quartus Prime Lite rejects.
2.2. Deriving the Instruction Set
The instruction set was derived from a survey of university-level introductory assembly materials. We applied the methodology from the thesis ([14] pp. 18–19, 146–151) but with additional sources and updated tallying. Eight sources were surveyed: three modules of course and exercise material from the Hellenic Open University, the assembly exercises of two course pages from Harvard and Maryland, a Greek exercise book on Computer Architecture, a translated 8086 tutorial from the University of Western Macedonia, and the LC-3 textbook (Table 2).
An operation such as “jump when the result is zero” appears under different mnemonics across architectures; we therefore classified each instruction by category, inspired by the functional classification of Hayes ([54] p. 195). Sources built from worked examples or exercises were scored by the number of distinct samples in which a category appears rather than by its raw count of occurrences, which limits the weight of any single long listing. Two of the sources teach one instruction at a time rather than through programs, so for those we counted distinct instances. Percentages were computed within each source and then averaged with equal weight, so that a 25-sample course page counts as much as a 124-sample textbook. The extraction of every instruction from the sources is logged with the data archive.
The supported operations marked in Table 3 are almost 80% of the surveyed weight, and 63.2% of it once the five most common operations—addition, move, load, store, and jump on zero—are set aside. The table records which operations get hardware support, to settle which circuits to build. We left out a complementor, an incrementer, and a comparator. We also left out register pairs by reducing the address size to the word size.
Multiplication and division were left out for the same reason RISC-V places them in a separate extension [55]: simplicity. They are provided as assembly routines instead. They also fall past the edge of a first digital-design course: Mano gives binary multiplication two pages ([13] pp. 187–188) and leaves the HDL description to a much later section. Keeping the set small results in short opcodes, which conserves the limited memory and, more importantly, reduces cognitive load [56].
2.3. Instruction Set Architecture
Deriving the instruction set left a few decisions before the architecture could be specified. First, we adopted a Load/Store organization for its regularity ([57] p. 422). Second, we chose the von Neumann model, because, with the exception of the 8086 material, the sources surveyed in the previous Section make no architectural distinction between program and data.
The most consequential decision was to implement the E80 as a single-cycle processor, which is the design Harris and Harris build first; every instruction is fetched, decoded, and executed on one clock edge. Beyond the simplicity of the design, a clock edge corresponds to a program step, so a waveform reads as a trace of the program. Salazar and Birrer report improved comprehension among students who instrumented and extended a reduced single-cycle datapath [58].
A single-cycle design sets the clock period by the slowest instruction, but speed is not important for an educational CPU. It also requires a separate adder for the program counter, which is likewise an insignificant cost for our purposes.
The memory is the real cost. Because of the von Neumann model, it has to access a data word and fetch an instruction on one cycle. We also wanted the firmware to reload on reset, which no vendor block random-access memory (RAM) offers, so all three EDAs translate the memory into registers behind wide selection logic. That logic sets both the resource usage (Section 3.1) and the critical path (Section 3.2) of the design.
The memory therefore had to stay small; we set the address at 8 bits, which spans 256 words—enough for what the survey of Section 2.2 asks: its largest program is 37 instructions. This does not take the LC-3 textbook into account because it was added after these widths were fixed; we return to it in Section 3.3, where its largest program serves as an independent check on the memory size.
We set the data word at 8 bits as well. An address then fits in a single register and a single memory word, so the machine needs no register pairs. To use the small memory space efficiently, we opted for a variable-length encoding of one or two 8-bit words. Instructions take up to two operands and support immediate, direct, register, and register-indirect addressing. To ensure hexadecimal legibility, the opcodes are nibble-aligned into the five formats shown in Figure 2.
A small register file with six general-purpose registers (R0–R5), a flags register (R6/FLAGS), and a stack pointer (R7/SP) requires 3 bits of addressing and fits the encoding’s nibble alignment. The flags register holds Carry, Zero, Sign, and oVerflow in its four most-significant bits, and Halt in its least-significant bit.
Only the instructions marked in the last column of Table 4 update the flags: the arithmetic, logic, shift, and rotate operations. MOV and LOAD leave them unchanged, for the reason given in Section 2.4. An explicit write to the flags register takes precedence over the implicit update, so an instruction such as OR FLAGS, 0b01000000 forces Z to 1 even when the computed result is non-zero. Setting the Halt flag by such means freezes the program counter from the next cycle, but the HLT instruction sets the Halt flag and freezes the program counter on the current one, as explained in Section 2.5.
LSHIFT and RSHIFT are logical rather than arithmetic shifts, so the vacated bit is filled with zero. ROR rotates the operand right by a programmable number of positions. Only the three low bits of the count are used, so a right rotation by n is equivalent to a left rotation by .
The stack is full-descending and supports PUSH, POP, CALL, and RETURN. The stack pointer is initialized to 0xFF on reset, so the first PUSH writes to 0xFE. Address 0xFF is therefore never written, which is why it was selected to return user input from the board, through dual in-line package (DIP) switches, instead of memory.
Table 5 lists the twelve operations of the ALU. Its operation code is the high nibble of the first instruction word, so the first hex digit of an instruction in Table 4 is also its row in Table 5; the four codes missing from the table belong to the control, move, and memory instructions, which bypass the ALU. One adder, the FA8 of Figure 1, serves addition, subtraction, compare, and stack-pointer arithmetic. Rotation is an eight-way selector on the three low bits of the second operand, each input a fixed rewiring of the first. CMP and BIT compute their result for the flags and output the first operand unchanged, so the destination register is rewritten with its own value. The flags are formed from the selected result and the adder: Z when the result is zero, S from its most-significant bit, C from the adder’s carry out or the bit shifted out by a shift, and V from the adder’s signed overflow or a change of the sign bit by a shift. The whole unit is signal assignments and one adder instance, with no PROCESS.
2.4. Datapath and the Elimination of the Combinational Loop
The datapath is built around a two-operand format, instruction reg, op2 (Figure 3). The destination register (reg) is both read and written, while the second operand (op2) is either an immediate value or another register. This general-purpose register arrangement accommodates the varied instruction effects ([35] pp. 61–62) expected of such a machine, allowing us to align the underlying circuit directly with the target assembly syntax.
All state is held in the register file and the program-counter flip-flop, so one clock edge completes one instruction (Section 2.3). The register file exposes three ports so that a register–register instruction such as ADD R0,R1 can complete in one cycle: a read/write port for the first operand (A_reg), a read-only port for the second operand (B_reg), and a write-only port for the flags register (W_reg). We describe the datapath through three representative instructions—an arithmetic operation, a stack pop, and a load from a direct memory address—each shown as it exercises the same shared hardware.
ADD exercises the full compute path (Figure 4). One bit of the opcode (designated op2isReg) decides whether op2 is a register or an immediate. The ALU takes its operation from the high nibble of the opcode, along with the accumulator value A_val and op2, and produces a result and a new set of flags. The result is written to the accumulator, and the flags to the Flags Register. In parallel, an 8-bit full adder forms PC + Size, which becomes the next program counter. Since ADD is a 2-word instruction, PC + 2 points to the next memory address.
A note on reading these figures: a priority multiplexer written as OUT <= A WHEN X ELSE B WHEN Y ELSE C is drawn as a rectangle whose inputs enter on the left in source order—from the top, A, X, B, Y, C—and whose output OUT leaves at the top right. This compact symbol packs the multiple multiplexers of a single-cycle datapath more tightly than the classic trapezoidal symbol with its select lines entering from below.
POP exercises the most hardware in one cycle (Figure 5). As a stack operation it points the accumulator port at the stack pointer (R7); on one edge the CPU presents that pointer to the memory address input, reads the word at the top of the full-descending stack into the destination register through the write port, and increments the stack pointer through the ALU back onto the accumulator port—two register writes and a memory read in a single cycle.
LOAD moves a word from memory into a register (Figure 6). The direct address is taken from the second instruction word to the memory address input, and the word returned by the RAM is driven straight onto the destination register’s write input, without passing through the ALU. That direct path is the most consequential change from the conference version.
In the conference datapath, MOV and LOAD also updated the sign and zero flags—a convenience borrowed from the MOS 6502 that lets a load be tested by a following conditional jump without an intervening compare, improving code density. Generating those flags meant routing the loaded word through the ALU (Figure 7), since the ALU is where flags are formed. At the same time, PUSH and CALL route the ALU output—the decremented stack pointer—to the memory address input. Chaining these two unrelated paths closes a cycle in the netlist: the ALU output feeds the stack memory address, the memory read feeds the data bus, and the data bus feeds the ALU input, forming a purely combinational loop with no flip-flop anywhere along it.
The loop is a false one. Its two legs are never active in the same instruction: the ALU output reaches the memory address only for PUSH and CALL, the data bus reaches the ALU input only for LOAD, and no opcode is at once a load and a stack push. The cycle therefore never carries a live signal, and the processor is functionally correct. Synthesis and place-and-route tools, however, identify combinational loops from the topology of the netlist rather than by proving the two multiplexers mutually exclusive; the wire from the data bus to the ALU input is present whether or not a load selects it. The tools accordingly reported the cycle. In Gowin, applying the syn_keep attribute bypassed the error but forced the tool to withhold optimizations, returning a pessimistic critical path. This attribute had no effect on Quartus, which instead generated some five thousand combinational-loop warnings.
The fix removes one leg of the cycle at its source. By giving LOAD the direct path of Figure 6—routing memory data straight to the register write input—the ALU no longer sees memory data, the offending wire disappears, and the loop cannot form. The consequence is that MOV and LOAD no longer update the sign and zero flags: the 6502-style flag update, and the slightly denser code it allowed, are traded for an acyclic datapath and the timing closure reported in Section 3.2.
With the loop resolved, the earlier workarounds were removed. For Gowin, it was the syn_keep attribute that heavily penalized clock frequency. For Nextpnr, the place-and-route tool of the OSS CAD Suite, it was command-line switches to bypass critical warnings. These compromises are now unnecessary: the design passes timing analysis natively, and the resulting gain in maximum clock frequency is reported in Section 3.2.
In addition to the updated flag behavior, two instruction set architecture (ISA) changes accompanied the fix. The experimental jump-to-register-indirect instruction, added late in the original work, was removed to retain the architecture’s intended simplicity. Meanwhile, CALL and RETURN were relocated next to PUSH and POP so that their opcodes map directly to the decrement and increment ALU operations for the stack pointer. This simplification is visible when comparing Figure 4 and Figure 7: the ALUop multiplexer required to drive the correct opcode for these instructions in the latter is completely eliminated in the former.
2.5. Behavioral Memory
The program/data memory in the conference version was described as an explicit array of 256 D-type flip-flops: a FOR...GENERATE loop instantiated the individual flip-flops and a conditional assignment selected each cell’s next value, giving the appearance of being built from the same gate-level primitives as the datapath. That structure was only apparent. The addressing was already behavioral—the read ports index the array arithmetically (RAM(PC), RAM(PC+1), RAM(MemAddr)), and the + that forms PC+1 to fetch the second word of an instruction is a computed operation rather than wired logic—so behavioral selection and address arithmetic (even without an arithmetic package present) already sat inside the flip-flop wrapper. Presenting that abstraction as an explicit flip-flop array served only to bury it under a declaration, at odds with the transparency the rest of the design pursues. We therefore now describe the memory with a clocked process that states its behavior openly: the synchronous reset-to-firmware, the single-port write, and the multiport read that single-cycle execution requires. This is also the honest place to mark where the design stops being gate-level, since the memory is not part of the processor proper. The change is purely descriptive: the memory still maps to flip-flops rather than to vendor block RAM on all three platforms (Table 6).
On a synchronous reset, the entire memory is reloaded from the firmware package, with the unprogrammed region left at the undefined value U. In simulation, the custom matching function treats U as logic 0, which coincides with the HLT opcode (0x00); a jump into uninitialized memory therefore halts deterministically—a useful fail-fast property for debugging. On hardware, this behavior is not guaranteed. Quartus and Gowin almost always clear uninitialized cells to zero (again yielding HLT), whereas the OSS CAD Suite on the GateMateA1 does not. We regard this discrepancy as pedagogically desirable, since it exposes a read from uninitialized memory as a genuine hazard rather than masking it.
2.6. Assembly Language
The assembly language is defined as a context-free grammar in Backus–Naur form and uses a hybrid syntax drawn from common assemblers and from the generic assembly pseudocode introduced by Hayes ([54] p. 195) and used by Stallings ([59] p. 450). The full grammar along with a testing suite is available on the project’s repository at Assembler/bnf.md. Register naming (R0–R5) and the second operand follow ARM conventions, the conditional jumps follow x86 naming, and numeric literals follow GNU Assembler rules: hexadecimal and binary use the 0x and 0b prefixes while decimals take no prefix and forbid leading zeros, which keeps the notation close to textbook pseudocode while remaining unambiguous (GNU reserves the leading zero for octal literals; the E80 assembler has no octal format but keeps the rule). The flags register and stack pointer can be written as the aliases FLAGS and SP.
In addition to labels and the mnemonics specified in Table 4, a small set of directives is provided to configure the generated code:
- .TITLE names the generated package.
- .LABEL binds a constant to a name.
- .DATA appends a labeled comma-separated series of strings or bytes after the program.
- .SIMDIP defines the DIP switch input for simulation runs (ignored on hardware).
- .SPEED sets the initial CPU clock as one of seven levels (ignored on simulation).
- .MONITOR designates an eight-word block of memory to be shown as bits on the hardware display and as American Standard Code for Information Interchange (ASCII) characters in simulation.
2.7. Toolchain
The toolchain assembles a program and simulates it without leaving the editor. Its components are the E80 assembler, the Scintilla-based Sc1 editor with its strong Lua scripting support, and GHDL with GTKWave for simulation and waveform inspection. Synthesis is left to the vendor tools of Section 2.8, which read the same generated package.
The assembler is written in standard C99 and uses no external parser generator; the grammar served as a design blueprint rather than being used internally, which let us prioritize context-aware error messages over generic syntax diagnostics. It reads the source from stdin and writes the VHDL package to stdout, with any error messages on stderr. The generated package replaces Program.vhd and is read by:
- the RAM component, to provide the machine code as an array to load on reset;
- the hardware interface, to provide the .SPEED and .MONITOR constants;
- the simulation scripts, for the .MONITOR and .SIMDIP constants.
The editor is configured to add syntax highlighting for .e80asm programs and to bind specific flows to function keys. The rest of this section demonstrates the toolchain through hello.e80asm (Figure 8), a compact program that exercises every directive and reaches the stack, the memory, and the DIP input; it will serve as an example for both assembly and simulation, and the hardware interface that follows.
Pressing F7 runs a Lua script that passes the active tab’s buffer to the assembler. Errors are redirected to the editor’s output pane and the caret moves to the respective line to point to the error. If there are no errors, the output is written to Program.vhd, which is opened in a new tab as shown in Figure 8. The program’s VHDL code is formatted so that a reader can track each line of the source, the generated machine code, and the simulated signals together. Each instruction occupies one or two columns according to its size and is annotated with its hexadecimal form, its disassembled mnemonic, and the signed equivalent of any immediate value exceeding 127. The mnemonics are regenerated from the encoded words rather than copied from the source, so labels appear as resolved addresses. Bytes placed by .DATA carry their decimal value, and their character if declared as a quoted string. The remaining words are left undefined as OTHERS => "UUUUUUUU" to serve the memory model of Section 2.5.
Pressing F5 performs similarly to F7, but no new tab is opened. Instead, the Lua script continues through a batch file that imports the VHDL sources, elaborates the simulation entity via GHDL, and runs it until the Halt flag rises or a time limit expires, writing a waveform trace. A saved GTKWave view supplies the signal order and grouping as seen in Figure 9.
Pressing F8 performs similarly to F5, running the same program through ModelSim (Figure 10). Because ModelSim is slow to start, a running instance is detected through a semaphore file and reused, recompiling and re-running the project without restarting the tool. Beyond the waveforms, which are limited to the signals selected in advance, ModelSim also prints the final memory contents to the transcript window in rows of 32 words, giving the complete state of the machine at the end of the run.
In each case hello.e80asm ends with its Halt flag raised, the string at address 14 reading hello in the monitored block, the DIP input decremented by 100 in R0, and the character pushed before the call recovered into R1.
2.8. Hardware Interface
Regardless of the board, the following materials are required to inspect and control the execution:
- an 8-bit DIP switch for data input.
- four buttons, two for speed control, one for pause and one for reset. We prefer a 5D Rocker Joystick with set and reset, both for ease of setup and usability.
- a 4-in-1 module of four daisy-chained MAX7219-driven 8×8 LED matrices. The module sells for between EUR 4 and EUR 12. These are retail prices from several sellers and their value added tax (VAT) treatment varies.
- a breadboard and jumper wires.
- twelve 10 kΩ pull-down resistors.
The Tang Primer 25K Basic Package, which pairs the core board with the dock board, costs EUR 35.74. The GateMateA1-EVB costs EUR 50.00. Both figures exclude VAT. The DSD-i1 is not sold commercially. All prices were retrieved on 7 September 2026, and the captures behind them are deposited with the data archive. The remaining materials are trivial in cost and we did not price them.
The visual interface was rebuilt around a serial display (Figure 11) implemented by four daisy-chained, MAX7219-driven 8×8 LED matrices. The matrices are addressed over just three signal lines [60], which significantly reduces the input/output pin count compared to the previous 24-LED parallel interface.
The expanded display shows the selected speed, the clock, the program counter, the current instruction word, the flags, the register file, the highest area of the RAM (stack region and the mapped DIP switch at 0xFF), and the program-selected .MONITOR block. This allows for a quick comparison with the GTKWave results that display the same information. Since all registers are visible, the user no longer needs to manually select which one to view. Consequently, the UP and DWN joystick inputs from the conference version have been rendered obsolete.
To maintain consistent execution speeds across different FPGAs, each board preset includes a minimal configuration package (Board.vhd) that defines its onboard oscillator frequency. The clock generator uses this constant to divide the board’s incoming clock down to a normalized 2 MHz with a binary counter. By selecting different bits of this counter, the generator provides an internal 1 MHz clock for the hardware interface and six execution speed levels ranging from 0.24 Hz to 4 kHz, alongside a 0 Hz halted state.
The current speed level, selected by the Left and Right buttons, is visually indicated on the top row of the first LED matrix via a one-hot encoding on the seven most-significant bits, while the least-significant bit follows the CPU clock. This transparent display, combined with the reduction to a few speed levels, replaces the complex semi-logarithmic speed system of the conference version. Because the current speed is always visible and easily adjustable, the old “Speed Reset” function is no longer necessary, rendering the joystick’s MID input obsolete as well.
This arrangement natively supports single-step execution. The Pause button is configured to gate the CPU clock low while depressed. Because the 0 Hz speed level gates the clock high, pressing and then releasing Pause produces a rising edge. This advances the processor by one clock cycle, which, given the machine’s single-cycle architecture, corresponds to one program step.
2.9. Open-Source Flow
A fully open-source flow was added for synthesis on the GateMateA1 using the OSS CAD Suite on Windows, driven by a single batch file as shown in Figure 12. The OSS CAD Suite does not include the GHDL-Yosys plugin on Windows; an intermediate step was therefore added to convert the VHDL to Verilog using GHDL. The design is then passed to Yosys for synthesis, to Nextpnr for place and route, and to the OpenFPGALoader for the bitstream upload, leading to execution on the board as shown in Figure 13.
Taken together, Figure 8, Figure 9, Figure 10, Figure 11, Figure 12 and Figure 13 showcase an assembly program followed end to end on free open-source software and open hardware: from its syntax-colored source, the annotated machine code in VHDL by the assembler, the simulation and waveform display by GHDL and GTKWave, and finally to the board through the OSS CAD Suite.
3. Results
Before we detail the synthesis and timing results, two methodological notes are in order. First, the Xilinx Vivado toolchain was excluded from this comparison. We were unable to source a compatible board at a price point matching the educational targets of our other hardware, and we chose not to report performance figures based solely on EDA timing reports without physical hardware validation. Second, the pre-fix baseline measured here is Version 2.0, the first release following the conference paper. It differs from the design described there only in its revised clock generation: the original frequency generator failed place-and-route with Nextpnr, so the discrete divider of Section 2.8 had to precede any measurement on the open flow, making Version 2.0 the earliest release synthesizable on all three toolchains. Its metrics accordingly differ slightly from the figures printed in the conference paper, both for this reason and because the measurement procedure has since been standardized in the data extraction protocol of the Zenodo deposit.
One further limit of this evaluation should be stated up front. A resource or efficiency comparison in the style of [25] would mean measuring the E80’s minimal datapath apart from the rest of the design. Such a ranking would flatter the E80 unfairly, ignoring the non-inferable memory it is built around, which dominates the area, timing, and power of the whole system. Still, we estimated power in Quartus and Gowin—Nextpnr provides no power estimator—and both put the complete FPGA at roughly 54–71 mW at the 2 MHz timebase. But this figure does not take into account the display the board drives. Per the MAX7219 data sheet [60], each driver draws 8 mA of control logic, plus up to eight times its peak segment current (ISEG, capped at 40 mA) for the one eight-LED row lit at a time. Four fully lit matrices at 5 V therefore draw about two orders of magnitude more than the whole FPGA: .
A power or thermal analysis therefore misses the point of the design. The E80’s value as an open, modifiable object-to-think-with is available only on a reconfigurable FPGA board with its hardware interface, instead of a fixed chip like the Microbit; our results accordingly focus on how the design runs within the limits of low-cost FPGAs, how we verify its instruction set, and how it held up in one classroom session.
3.1. Cross-Platform Synthesis
The VHDL sources compile and run unchanged across all platforms listed in Section 2, apart from the per-board configuration package described in Section 2.8. That package plays an identical role in both design versions, so it does not affect Table 6, which contrasts E80 versions on the same board and toolchain rather than the boards against each other.
The memory shapes both resource columns. Its three asynchronous read ports and computed read addresses, both resolved in a single cycle, fall outside any synchronous, dual-port RAM primitive, so all three tools translate the array to 256×8 registers rather than block RAM.
The logic column tells the same story. Its cost is the wide multiplexers a single-cycle, multiport memory needs to reach every word on one edge, together with the network that reloads all 256 words from firmware on reset. Reset-to-firmware is a deliberate choice, and the less obvious one: reloading the program on reset is what lets a class run the same code over and over. Against these, the CPU and ALU logic is minor.
Between the two versions the resource cost barely moves: registers are essentially unchanged, since the memory that dominates them is the same, and the logic rises modestly to support the new hardware interface. The one clear shift is in the pins, which fall from 39 to 16 as the parallel LED rows give way to the serial MAX7219 display.
3.2. Critical Path and the Loop-Fix Improvement
For this design, the maximum clock frequency is a functional floor rather than a benchmark. Although the processor runs at user-selectable speeds with a very low 4 kHz ceiling, the button-debouncing logic and the serial LED display (along with a serial input planned for future work) require a 1 MHz internal timebase, which is derived from a hardware clock input of at least 2 MHz. Nextpnr uses a single global clock constraint, so the entire design must meet this 2 MHz minimum. Version 2.0 barely met that floor, at 2.26 MHz, and only after place-and-route was forced past the loop’s critical warnings. Removing the loop was therefore a question of the design working reliably on the open flow, not of speed for its own sake.
Removing the false combinational loop of Section 2.4 changed the maximum clock frequency sharply, and unevenly, across the three flows (Figure 14). Where the loop had hurt, the gain is large: Gowin rises from 8.79 to 30.84 MHz (about 3.5×) and the OSS CAD Suite from 2.26 to 10.49 MHz (about 4.6×). This lifts the GateMate well clear of its previous floor, bringing it close to the practical ceiling imposed by the board’s 12 MHz crystal oscillator. The DSD-i1 is the exception, moving from 16.94 to 16.09 MHz—consistent with the loop being a false path that its timing engine had already absorbed.
The critical-path reports explain both the magnitude of these gains and their unevenness. In Version 2.0, the three tools disagreed sharply on the severity of the loop because each handles a topological cycle differently. The open flow’s router interpreted the loop literally, routing it as a single 441.8 ns path—with only 74 ns spent in logic and the remainder lost to routing across the die—which explains the severe frequency collapse. Gowin closed the same cycle at a logic depth of thirty-eight levels. Quartus, by contrast, broke the false path despite its own warnings and reported only the worst genuine register-to-register path at 59 ns. Because the loop never entered its timing analysis, removing it left the Quartus results essentially unchanged, apart from a slight lengthening to 62 ns caused by the logic added for the new serial LED display.
With the loop removed, the critical path on all three platforms runs through the wide multiplexer that reads a word from the 256-word flip-flop memory, not through any arithmetic circuit. On Quartus it is the instruction fetch (62 ns). On Gowin it is a nineteen-level register-file datapath that also crosses that multiplexer. On the GateMate flow it is the display interface scanning memory through the same read path (95 ns). This display path was hidden beneath the loop’s 441.8 ns of routing; removing the loop exposed it as the new bottleneck.
3.3. Verification and Test Suite
The strictly single-cycle core holds no pipeline or hazard state between instructions, so the behavior to verify is the closed space of each opcode producing its defined result and flags.
Verification covers the whole path from source text to running board: the hardware’s conformance to the documented instruction set, the assembler’s robustness against oversized or malformed input, corner cases of the assembly syntax, the behavior of a program on hardware, and the usability of the editor and simulator front ends. The tests are directed rather than random—each checks a chosen part of the toolchain against hand-computed expected values—and progress from the smallest possible input to a self-checking sweep of the instruction set. They double as development aids: hello.e80asm drove the GTKWave and ModelSim configurations that surface the .MONITOR block, which the simulation entity publishes both as an eight-character string and as its eight bytes separately. The test sources ship with the toolchain, in its installation folder.
- 1.
- Empty program: Pressing F5 on an empty editor tab assembles a valid program where all RAM is set to undefined. It is expected to halt on the first cycle in simulation (Section 2.5) and run with an undefined behavior on hardware.
- 2.
- hello.e80asm: A nine-instruction “hello world” exercising the load/store, stack, and arithmetic paths, the DIP input, and the .MONITOR directive. It is expected to leave the modified string in the monitored block and the DIP input, decremented, in R0.
- 3.
- divmul.e80asm: Unsigned division and multiplication routines that drive the rotator, bitwise logic, and nested loops. It is expected to finish with the quotient, the remainder, and the product in registers R0–R2.
- 4.
- ISAtest.e80asm: A single self-checking program covering the entire instruction set, its addressing combinations, flag behavior, and quirks. It is expected to finish with the Halt flag raised and NOP as the last fetched instruction, or to fail with the Halt flag raised and HLT as the last fetched instruction.
- 5.
- fibonacci.e80asm: Doubly-recursive evaluation on the hardware stack. It is expected to finish with the nth number of the Fibonacci series in R0, where n is taken from the DIP switches or the .SIMDIP directive.
- 6.
- LC3maze.e80asm: The recursive maze-exit subroutine of Patt & Patel [4], the largest sample of our survey, ported to E80 Assembly and run on a harder maze. It fits the available 255-word memory with room to spare.
The empty program is intended to track the execution of undefined instructions. Running it on the GateMateA1, the undefined cells came up as ones, so every fetch returned 0xFFFF, which the instruction decoder handles as a default two-word instruction. The high nibble of the first word is therefore passed as the ALUop, mapping to increment by 1 (Table 5); bit 3 is set, so the operands are taken as registers (Type 4), naming R7 (111)—the stack pointer—as the accumulator. The rest follows from the datapath: the increment discards its flags so the Halt flag never rises; memory is never written and no jump condition is met, so the program counter takes its default two-word step. The machine therefore settles into a stable loop, incrementing the stack pointer by one and the program counter by two on every cycle, sweeping the even addresses up to 254 and wrapping indefinitely back to 0 as seen in Figure 15. Our flow omits Yosys’s setundef command, which would pin every undefined bit to a specific value, allowing us to demonstrate the difference between an undefined run on hardware and the deterministic halt of Section 2.5.
The ISA Compliance Suite is a single self-checking program that exercises the whole instruction set in one run: core bring-up, all four load/store addressing forms round-tripped through memory, every conditional branch in both its taken and not-taken directions, the flag rules (logic and rotate operations leaving carry and overflow intact, CMP and BIT setting flags without writing their register, an explicit FLAGS write overriding the computed result), last-in-first-out stack order, stack underflow wrapping to the DIP-mapped top of memory, and nested recursion. Every check guards a comparison that branches to a fail halt on mismatch, so a correct run ends at a single pass address and conformance is decided by the final program counter alone, without reading the waveform. Figure 16 shows the closing cycles of a passing run. The recursive calls unwind without the program counter moving: because each activation’s return address is the word following the call, the same RETURN at address 225 executes on four successive cycles while the stack pointer climbs back to an empty stack. The underflow check then wraps the stack pointer to zero, reading the DIP-mapped word, and the program halts at the pass address.
fibonacci.e80asm computes with thirteen activations of fib alive at once, each holding four words of the single run-time stack: the two registers fib saves (R0 and R1), the return link pushed by CALL, and the parameter n the caller pushed. After the two saves, n sits three words above the stack pointer, so fib reads it with ADD SP,3 / LOAD R0,[SP] / SUB SP,3. The displacement is fixed but the stack pointer is not, so each activation reads its own copy. Each activation saves R0 and R1 on entry and restores them before RETURN, so a callee never disturbs its caller’s registers. That is what lets fib call itself: after the first recursive call returns, R0 still holds , and a second SUB R0,1 produces for the second call. The two results come back in R1 and R0; fib adds them and writes the sum through the same stack slot the parameter came from, which the caller’s POP R0 then retrieves. On the LC-3 ([4] pp. 580–581) the same algorithm takes a different form: JSR keeps the return address in a link register and the convention keeps a frame pointer, so each activation must save both and reserve a separate slot for its result. The E80’s hardware-stacked CALL and RETURN fold that bookkeeping into the instructions, giving a shorter routine for the same computation. A complete run exceeds the default simulation limit. The program therefore sets the highest .SPEED and finishes on the board in a few seconds (Figure 17).
The maze subroutine of Patt & Patel [4], Figure 8.24, is the largest sample of the survey: 62 instructions, and 131 words once its mask table, its 36-cell maze and its stack are counted. On the LC-3, where instructions and data are 16-bit words, it’s 262 bytes—more than the E80 has. LC3maze.e80asm nonetheless ports the algorithm in full. The five door bits of a cell are unchanged and the breadcrumb moves from bit 15 to bit 7, clear of the five door bits, mirroring the LC-3’s use of the sign bit. The four directions are tried in the same order, guarded by the same two questions, and each activation saves the same three items: the cell data, the cell address, and the return link. BIT, PUSH/POP and immediate masks remove fifteen instructions from the original; the absence of register-plus-offset addressing adds eight back, leaving 55 against 62. With the probe instrumentation the program occupies 134 words of code, 36 of maze and 8 of monitored data, and peaks at 30 words of stack: 208 of the 255 available.
We altered the maze to be harder than the textbook’s (Figure 18). The original leads the search out without once entering a branch it has to abandon; the altered maze forces two dead ends before the exit is found, and deepens the chain of calls at cell 0 from seven activations to ten. That is one more than the original can produce from any of its 36 starting cells, whose deepest chain is nine. The program halts with R1 = 1, and the monitored byte holds the index of the cell each check is aimed at, so the search can be followed on the board as it runs. With 178 words of code and data fixed, 77 remain for the stack; at three words per activation, that is 25 levels, fifteen more than the altered maze uses.
3.4. Lab-Classroom Deployment
We have used the E80 in teaching once, and we report that first use for what it was: a single, qualitative session rather than a controlled study of learning outcomes. The platform was introduced in the Embedded Systems course at the University of Western Macedonia (ROBIS lab, 2025–2026), in a session titled “VHDL with the E80 processor” and delivered in a remote lab classroom.
The session turned on two exercises. In the first, the students added a parity flag to the processor: an XOR reduction across the bits of a result, wired into the ALU, latched in the flags register, and exposed to software through a new pair of conditional jumps, jump-on-parity and jump-on-no-parity, which they then encoded, assembled, and ran. This is the entire vertical slice of the microworld—logic gate, datapath, flag, instruction encoding, assembler, and program—and the students closed it in under ten minutes. That a new instruction can travel from a gate to a running program inside one short exercise is, to us, the clearest sign that the processor is genuinely modifiable and not merely readable: the object-to-think-with of Section 1.2 was opened, changed, and rebuilt within a single classroom task.
The second exercise asked for a short program with the option of using an artificial intelligence (AI) assistant. One student’s solution returned MIPS-like assembly syntax. Because the E80’s syntax resembles mainstream conventions, a large language model (LLM) operating without the explicit ISA context defaults to the architectures it was trained on [15]. This left the student to read the generated code and translate it into the E80 ISA by hand. While this zero-shot hallucination inadvertently created a manual translation exercise that validates our observations in the conference paper, LLM capabilities are advancing rapidly. We should therefore consider this mismatch an artifact of incomplete prompting rather than an inherent “resistance” of the architecture.
We are wary of over-reading one session. The group was small, the meeting was a single remote one, we administered no formal assessment instrument, and we kept neither recordings nor a dataset. What this session does show is how easily the platform can be deployed. The toolchain was installed and ready to use on every student computer within the eight minutes before class started.
4. Discussion
The loop fix cost the 6502-style flag update on moves and loads (Section 2.4), and the cost is stylistic but real: the E80 is meant to read like the assembly pseudocode of digital-design textbooks, where testing a register just written is natural, and the 6502 convention is itself an asset, given the enthusiast community that still programs that processor. Recovering those flag updates without reopening the cycle—by forming them off the loop-carrying path while keeping the design simple—is the clearest item of future work.
We do not claim that the entire circuit can be read gate by gate. The processor is gate-transparent, but the hardware interface and the memory are described behaviorally (Section 2). The synthesis results place that boundary: the behavioral memory maps to flip-flops on every platform (Table 6), and the same memory sets the clock through its wide read multiplexer (Section 3.2).
Several features are provided as debugging aids. Execution stops when running an HLT instruction, or at the first jump into uninitialized memory; the assembler answers a mistake with a context-aware message rather than a bare line number; and the one-click flow puts a waveform in front of the student without an EDA command line. A real VHDL simulator also has a practical advantage over the assembly simulators most educational CPUs ship with: GTKWave can export a whole run as TimingAnalyzer data, which an LLM can read to follow every signal change and suggest architectural VHDL improvements.
The exposed architecture was also the key to resolving the combinational-loop episode, and it warrants a brief disclosure regarding generative AI. The fix surfaced during the preliminary prompt formation for a separate benchmark study where Google Gemini (June 2026) was asked to reconstruct the datapath from the ISA specification and the remaining components. The model produced an almost valid VHDL reconstruction that simply omitted the combinational loop. E80 was originally designed without using AI input; that a structural defect troubling the design for over a year could be isolated by analyzing a language model’s correct reconstruction highlights the importance of applying modern tools in HDL design.
What the E80 offers a course is a single artifact a student can follow the whole way down: an assembly program, the machine code generated by the assembler, the datapath that runs it, and the gates that datapath is built from, all open and all modifiable through a toolchain and hardware presets and scripts.
One limit of the toolchain is that it is released for Windows only. The issue is not as simple as packaging: GHDL, GTKWave, and SciTE run on Linux, where the same Lua scripts drive the editor (Section 2), and the Linux build of the OSS CAD Suite includes the GHDL plugin for Yosys, so Yosys reads the VHDL directly and the conversion step of Section 2.9 is not needed there. A Linux release needs the same testing before it can be offered. With the Windows toolchain finished, a tested Linux toolchain is the next step.
5. Conclusions
This paper shows that a processor can stay gate-transparent while providing a textbook-complete instruction set. Its single-cycle design is resource-intensive but stays well within the reach of low-cost hardware. Even without hardware, a free open-source toolchain lets students simulate the machine running an assembly program and modify it.
This extended version matures a working educational prototype into a portable and fully open hardware platform. The addition of the serial LED matrix interface allows the user to directly map the simulation to the hardware: the program counter, the running instruction, the register file, the stack area, and a selected eight-word section of the RAM can be monitored step-by-step.
The most critical technical improvement was the elimination of a false combinational loop in the datapath, which raised the maximum clock frequency on the Gowin and OSS CAD Suite flows and lifted the latter well above the floor required by the serial display and input interfaces. The fix cost the 6502-style flag behavior—restoring it without reopening the cycle is the next design step—but it lets the E80 be deployed end-to-end on low-cost FPGAs without proprietary software.
Its clearest limitation is that the platform’s effect on learning remains unmeasured. However, the processor, toolchain, and design files are functional and released openly under the GPL, inviting educators to deploy and adapt the platform to specific classroom requirements.
Supplementary Materials
No supplementary material is published with this article. The conference version [15] is supplied to the editorial office with the submission, as required for extended versions.
Author Contributions
Conceptualization, P.S. and V.F.; methodology, P.S.; software, P.S.; validation, P.S., V.F. and K.G.; formal analysis, P.S.; investigation, P.S. and M.D.; resources, A.F. and M.D.; data curation, P.S.; writing—original draft preparation, P.S.; writing—review and editing, V.F., K.G., A.F. and M.D.; visualization, P.S.; supervision, V.F. and M.D.; project administration, V.F. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Institutional Review Board Statement
This educational activity was conducted as part of regular university coursework; no personal data were collected and no recordings were made. Ethical review and approval were therefore waived for this study.
Informed Consent Statement
Not applicable—no personal data were collected and no individuals are identifiable in this work.
Data Availability Statement
The VHDL source code, assembler, and hardware configurations for the E80 processor are openly available on GitHub at https://github.com/Stokpan/E80. A complete archive is deposited at https://doi.org/10.5281/zenodo.22757255. It holds the raw source files for both measured versions, the packaged toolchain, and the reproducibility protocols for the synthesis and place-and-route results. It holds the instruction set survey as well: the tagged extraction of every instruction from each of the eight sources, the spreadsheet that aggregates them, and the program sizes drawn from the same samples. The file-level findings behind Table 1 and the price captures behind Section 2.8 are deposited with them. No classroom dataset was generated. Further inquiries can be directed to the corresponding author.
Use of Artificial Intelligence
Google Gemini 3.1 Pro was used during 7–12 June 2026 to help identify the combinational loop described in Section 2.4; the fix was implemented, simulated, and verified on hardware by the authors, who take full responsibility for the design. During the preparation of this manuscript, the authors used DeepSeek for language editing and grammar suggestions on author-written text. Anthropic Claude Opus 5 was used during 30 August–1 September 2026 to review the structure and claims of several sections, to typeset the survey data of Table 2 and Table 3, to draft the bibliography entries for the surveyed sources, and to check the aggregated survey figures against the extraction files. The authors have reviewed and edited the output and take full responsibility for the content of this publication.
Conflicts of Interest
The authors declare no conflicts of interest.
Abbreviations
The following abbreviations are used in this manuscript:
| AI | Artificial Intelligence |
| ALU | Arithmetic Logic Unit |
| ASCII | American Standard Code for Information Interchange |
| CPU | Central Processing Unit |
| DIP | Dual In-line Package |
| EDA | Electronic Design Automation |
| FPGA | Field-Programmable Gate Array |
| GPL | GNU General Public License |
| HDL | Hardware Description Language |
| HOU | Hellenic Open University |
| ISA | Instruction Set Architecture |
| LC-3 | Little Computer 3 |
| LED | Light-Emitting Diode |
| LLM | Large Language Model |
| PC | Program Counter |
| RAM | Random-Access Memory |
| SP | Stack Pointer |
| VAT | Value Added Tax |
| VHDL | VHSIC Hardware Description Language |
Appendix A. Quartus Prime Lite 20.1.1 Limitations for VHDL-2008
Although Intel’s documentation states that Quartus Prime Lite does not support VHDL-2008 [62], during development it became evident that a subset of the standard, such as PROCESS(ALL), is actually supported. Through a process of trial and error, we established the following list of confirmed incompatibilities:
- Relational matching operators with don’t-care conditions (e.g., x ?= "10--1") are not supported.
- Unary reduction logic operators on vectors (e.g., NOR vector) are not supported.
- Conditional assignments using WHEN inside a sequential process are not permitted.
- While VHDL-2008 allows reading output ports directly in assignment statements, Quartus Prime Lite requires these ports to be explicitly declared as BUFFER.
- Native shift and rotate operators (e.g., ROR) are not supported.
References
- Mano, M.M. Computer System Architecture, 3rd ed.; Prentice-Hall: Englewood Cliffs, NJ, USA, 1993; Available online: https://archive.org/details/computer-system-architecture-morris-mano-third-edition.
- Malvino, A.P.; Brown, J.A. Digital Computer Electronics, 3rd ed.; Glencoe/McGraw-Hill: New York, NY, USA, 1993; Available online: https://archive.org/details/digital-computer-electronics-albert-paul-malvino-and-jerald-a-brown.
- Eater, B. Build an 8-bit computer from scratch. Available online: https://eater.net/8bit (accessed on 2 July 2026).
- Patt, Y.N.; Patel, S.J. Introduction to computing systems: from bits & gates to c/c++ & beyond, 3rd ed.; McGraw-Hill Education: New York, NY, USA, 2020. [Google Scholar]
- Calazans, N.L.V.; Moraes, F.G. Integrating the teaching of computer organization and architecture with digital hardware design early in undergraduate courses. IEEE Trans. Educ. 2001, 44, 109–119. [Google Scholar] [CrossRef]
- Nestor, J.A. Teaching computer organization with HDLs: An incremental approach. In Proceedings of the IEEE International Conference on Microelectronic Systems Education (MSE’05), Anaheim, CA, USA, June 2005; pp. 77–78. [Google Scholar] [CrossRef]
- Rodriguez-Ponce, R.; Rodriguez-Resendiz, J. Integrating VHDL into an undergraduate digital design course. In Proceedings of the IEEE International Conference on Teaching, Assessment and Learning for Engineering (TALE), Bali, Indonesia, August 2013; pp. 172–177. [Google Scholar] [CrossRef]
- Corter, J.E.; Nickerson, J.V.; Esche, S.; Chassapis, C. Remote versus hands-on labs: A comparative study. In Proceedings of the 34th Annual Frontiers in Education (FIE), Savannah, GA, USA, October 2004; pp. F1G–17–F1G–21. [Google Scholar] [CrossRef]
- Fanariotis, A.; Orphanoudakis, T.; Fotopoulos, V.; Kitsos, P. DSD-i1: A mixed functionality development board geared towards digital systems design education. In Proceedings of the 22nd Euromicro Conference on Digital System Design (DSD), Chalkidiki, Greece, August 2019; pp. 152–159. [Google Scholar] [CrossRef]
- Etcheverry, L.; Oliver, J.; Acle, J.P. A soft-core based lab for an introductory microprocessors course. In Proceedings of the Technologies Applied to Electronics Teaching (TAEE), Vigo, Spain, June 2012; pp. 72–76. [Google Scholar] [CrossRef]
- Li, Y.; Chu, W. Aizup – A pipelined processor design and implementation on Xilinx FPGA chip. In Proceedings of the IEEE Symposium on FPGAs for Custom Computing Machines, Napa Valley, CA, USA, April 1996; pp. 98–106. [Google Scholar] [CrossRef]
- IEEE Std 1076-2008; IEEE Standard VHDL Language Reference Manual. Institute of Electrical and Electronics Engineers: New York, NY, USA, 2008. [CrossRef]
- Mano, M.M.; Ciletti, M.D. Digital Design: With an Introduction to the Verilog HDL, VHDL, and SystemVerilog, 6th ed.; Pearson: New York, NY, USA, 2019. [Google Scholar]
- Stokas, P. Design and programming in VHDL of a new CPU for educational purposes. Bachelor’s thesis, Hellenic Open University, Patras, Greece, 2025. Available online: https://apothesis.eap.gr/archive/item/222454.
- Stokas, P.; Fotopoulos, V.; Giannakopoulos, K. E80: An Open-Source 8-bit CPU and Toolchain Based on Textbook Digital Design Theory. In Proceedings of the 8th Panhellenic Conference on Electronics and Telecommunications (PACET), Patras, Greece, April 2026; pp. 1–4. [Google Scholar] [CrossRef]
- Harris, S.L.; Chaver, D.; Piñuel, L.; Gomez-Perez, J.I.; Liaqat, M.H.; Kakakhel, Z.L.; Kindgren, O.; Owen, R. RVfpga: Using a RISC-V core targeted to an FPGA in computer architecture education. In Proceedings of the 31st International Conference on Field-Programmable Logic and Applications (FPL), Dresden, Germany, August–September 2021; pp. 145–150. [Google Scholar] [CrossRef]
- Imagination Technologies. End-User License Agreement for Imagination University Programme Teaching Materials, v3, 2022. [CrossRef]
- Austin, J.; Baker, H.; Ball, T.; Devine, J.; Finney, J.; Halleux, P.D.; Hodges, S.; Moskal, M.; Stockdale, G. The BBC micro:bit: from the U.K. to the world. Commun. ACM 2020, 63, 62–69. [Google Scholar] [CrossRef]
- Ellard, D.; Holland, D.; Murphy, N.; Seltzer, M. On the design of a new CPU architecture for pedagogical purposes. In Proceedings of the Workshop on Computer Architecture Education, Anchorage, AK, USA, May 2002; p. 6–es. [Google Scholar] [CrossRef]
- Yıldız, A.; Ugurdag, H.F.; Aktemur, B.; İskender, D.; Gören, S. CPU design simplified. In Proceedings of the 3rd International Conference on Computer Science and Engineering (UBMK), Sarajevo, Bosnia and Herzegovina, September 2018; pp. 630–632. [Google Scholar] [CrossRef]
- Gray, J. Hands-on computer architecture: teaching processor and integrated systems design with FPGAs. In Proceedings of the Workshop on Computer Architecture Education (WCAE), Vancouver, BC, Canada, June 2000; p. 17. [Google Scholar] [CrossRef]
- Nakano, K.; Kawakami, K.; Shigemoto, K.; Kamada, Y.; Ito, Y. A Tiny Processing System for Education and Small Embedded Systems on the FPGAs. In Proceedings of the IEEE/IFIP International Conference on Embedded and Ubiquitous Computing (EUC), Shanghai, China, December 2008; pp. 472–479. [Google Scholar] [CrossRef]
- McLoughlin, I.; Nakano, K. A Perspective on the Experiential Learning of Computer Architecture. In Proceedings of the IEEE/ACM International Conference on Green Computing and Communications & International Conference on Cyber, Physical and Social Computing, Hangzhou, China, December 2010; pp. 868–872. [Google Scholar] [CrossRef]
- Angelov, V.; Lindenstruth, V. The educational processor Sweet-16. In Proceedings of the 19th International Conference on Field Programmable Logic and Applications, Prague, Czech Republic, August–September 2009; pp. 555–559. [Google Scholar] [CrossRef]
- Gazziro, M.; de Assumpção Junior, J.M.; Junior, O.H.A.; Cavallari, M.R.; Carmo, J.P. Design and Evaluation of Open-Source Soft-Core Processors. Electronics 2024, 13. [Google Scholar] [CrossRef]
- de Assumpção, J.M.; Ando, O.H.; de Araújo, H.P.; Gazziro, M. An Educational RISC-V-Based 16-Bit Processor. Chips 2024, 3, 395–407. [Google Scholar] [CrossRef]
- Neemann, H. Digital: A digital logic designer and circuit simulator. Available online: https://github.com/hneemann/Digital (accessed on 6 September 2026).
- Freeman, M. A Hardware Description Language SimpleCPUv1a. Available online: https://simplecpudesign.com/simple_cpu_v1 (accessed on 5 July 2025).
- Pinault, P. The Simple CPU project. Available online: https://www.simple-cpu.com/free-cpu-project-presentation-en.php (accessed on 5 July 2025).
- Nisan, N.; Schocken, S. The Elements of Computing Systems: Building a Modern Computer from First Principles, 2nd ed.; MIT Press: Cambridge, MA, USA, 2021. [Google Scholar]
- Kalomiros, J.; Vourvoulakis, J. The Robin Soft-Core: A paradigm for studying VHDL and computer architecture. In Proceedings of the 11th IEEE International Conference on Intelligent Data Acquisition and Advanced Computing Systems: Technology and Applications (IDAACS), Cracow, Poland, September 2021; pp. 124–129. [Google Scholar] [CrossRef]
- Schocken, S. Nand to Tetris: Building a Modern Computer System from First Principles. Commun. ACM 2024, 67, 76–85. [Google Scholar] [CrossRef]
- Markettos, A.T.; Moore, S.W.; Jones, B.D.; Spliet, R.; Gavrila, V.A. Conquering the complexity mountain: Full-stack computer architecture teaching with FPGAs. In Proceedings of the 11th European Workshop on Microelectronics Education, Southampton, UK, May 2016; pp. 1–6. [Google Scholar] [CrossRef]
- Papert, S. Mindstorms: Children, Computers, and Powerful Ideas, 2nd ed.; Basic Books: New York, NY, USA, 1993; Available online: https://media.mit.edu/publications/mindstorms.
- Bell, G.; Newell, A. Computer Structures: Readings and Examples; Computer Science Series; McGraw-Hill: New York, NY, USA, 1971. [Google Scholar]
- Stokas, P. E80: Educational VHDL computer with a single-click toolchain for assembly, simulation, and execution on FPGAs. Available online: https://github.com/Stokpan/E80 (accessed on 2 July 2026).
- Gingold, T. GHDL: VHDL 2008/93/87 simulator. Available online: https://github.com/ghdl/ghdl (accessed on 9 September 2026).
- Bybell, A. GTKWave: fully featured wave viewer for debugging Verilog or VHDL simulation models. Available online: https://gtkwave.sourceforge.net/ (accessed on 9 September 2026).
- Hodgson, N. Sc1: static-linked portable version of SciTE, a Scintilla-based text editor. Available online: https://scintilla.org/SciTE.html (accessed on 9 September 2026).
- Open Source Hardware Association (OSHWA). OLIMEX GateMateA1-EVB, Certification Date February 02, 2024. Available online: https://certification.oshwa.org/bg000117.html (accessed on 15 September 2026).
- Harris, S.L.; Harris, D. Digital Design and Computer Architecture: RISC-V Edition; Morgan Kaufmann: Cambridge, MA, USA, 2021. [Google Scholar] [CrossRef]
- Bergé, J.M.; Fonkoua, A.; Maginot, S.; Rouillard, J. Direct instantiation. In VHDL’92; Casey, M., Ed.; Springer: New York, NY, USA, 1993; pp. 39–45. [Google Scholar] [CrossRef]
- Lewis, J. VHDL-2008: The End of Verbosity! Presented at the Single Event Effects (SEE) Symposium and Military and Aerospace Programmable Logic Devices (MAPLD) Workshop. 2013. Available online: https://www.seesocs.org/archives/2013/0412FRI/14_1440_S4-Fri-1440-Lewis-VHDL%202008.pdf.
- Tatas, K.; Tsolaki, E. A Comparative Study of VHDL versus Verilog for Teaching Digital Systems Design. In Proceedings of the 15th International Conference on Modern Circuits and Systems Technologies, Palma, Spain, June 2026; pp. 1–4. [Google Scholar] [CrossRef]
- Ashenden, P.J. The Designer’s Guide to VHDL, 3rd ed.; Systems on Silicon; Morgan Kaufmann: Burlington, MA, USA, 2008. [Google Scholar]
- Herman, G.L.; Zilles, C.; Loui, M.C. How do students misunderstand number representations? Comput. Sci. Educ. 2011, 21, 289–312. [Google Scholar] [CrossRef]
- Alexiou, G.; Vergos, H.; Efstathiou, C.; Theodoridis, G.; Kavousianos, C.; Koufopavlou, O.; Lambrinoudakis, C.; Liotopoulos, F.; Moshovos, A.; Bakalis, D.; et al. Microprocessors: Exercises from Written Assignments and Examinations. Course material for module PLI21; Hellenic Open University, 2013. (In Greek) [Google Scholar]
- Harvard University. CS 61: Assembly Exercises. Available online: https://cs61.seas.harvard.edu/site/2025/AsmEx/ (accessed on 21 August 2026).
- Alexiou, G.; Vergos, H.; Efstathiou, C.; Theodoridis, G.; Kavousianos, C.; Koufopavlou, O.; Lambrinoudakis, C.; Liotopoulos, F.; Moshovos, A.; Bakalis, D.; et al. Computer Architecture: Exercises from Written Assignments and Examinations. Course material for module PLI21; Hellenic Open University, 2013. (In Greek) [Google Scholar]
- Nikolos, D. Computer Architecture Exercises; Gkiourdas: Athens, Greece, 2010; Available online: https://catalogue.nlg.gr/cgi-bin/koha/opac-detail.pl?biblionumber=470584. (In Greek)
- University of Maryland. CMSC 430, Chapter 3: a86, a Little Assembly Language. Available online: https://www.cs.umd.edu/class/spring2025/cmsc430/a86.html (accessed on 21 August 2026).
- Carati, E.G. 8086 Assembler Tutorial for Beginners; Greek translation by M. Dasygenis; University of Western Macedonia, 2013. Greek translation by;Original published 2008. [Google Scholar]
- Voyiatzis, I.; Manis, G.; Giaglis, G. Introduction to the Assembly Language of the MIPS Processor. Course material for module PLI10, Hellenic Open University, 2015. File: Week3-MIPS-Processor-June2015.doc.
- Hayes, J.P. Computer Architecture and Organization, 3rd ed.; WCB/McGraw-Hill: Dubuque, IA, USA, 1998; Available online: https://archive.org/details/computerarchitec0003edhaye.
- RISC-V International. Extension for Integer Multiplication and Division. Available online: https://docs.riscv.org/reference/isa/v20260120/unpriv/m-st-ext.html (accessed on 15 September 2026). Version 20260120.
- Coulter, N.S.; Kelly, N.H. Computer instruction set usage by programmers: an empirical investigation. Commun. ACM 1986, 29, 643–647. [Google Scholar] [CrossRef]
- Tanenbaum, A.S.; Austin, T. Structured computer organization, 6th ed.; Pearson Education: Upper Saddle River, NJ, USA, 2013. [Google Scholar]
- Salazar, C.; Birrer, B. Instrumentation and extension of reduced, simulated single-cycle MIPS architecture to improve student comprehension. In Proceedings of the IEEE Frontiers in Education Conference (FIE), Uppsala, Sweden, October 2020; pp. 1–5. [Google Scholar] [CrossRef]
- Stallings, W. Computer Organization and Architecture: Designing for Performance, 10th ed.; Pearson Education Limited: Harlow, UK, 2015. [Google Scholar]
- Maxim Integrated. MAX7219/MAX7221 Serially Interfaced, 8-Digit LED Display Drivers. Datasheet 19-4452, Rev. 6, Analog Devices, San Jose, CA, USA. 2021. Available online: https://analog.com/media/en/technical-documentation/data-sheets/max7219-max7221.pdf.
- Dijkstra, E.W. Recursive Programming. Numer. Math. 1960, 2, 312–318. [Google Scholar] [CrossRef]
- Intel Corporation. Quartus Prime Design Software: Compare Pro, Standard, and Lite Editions. Available online: https://www.intel.com/content/dam/www/central-libraries/us/en/documents/quartus-prime-compare-editions-guide.pdf (accessed on 7 July 2026). Document SS-1006-21.3.
Figure 1.
Standard diagram of an 8-bit ripple-carry adder/subtractor described by gate-transparent VHDL code. All signals from the diagram can be traced to the code.
Figure 1.
Standard diagram of an 8-bit ripple-carry adder/subtractor described by gate-transparent VHDL code. All signals from the diagram can be traced to the code.
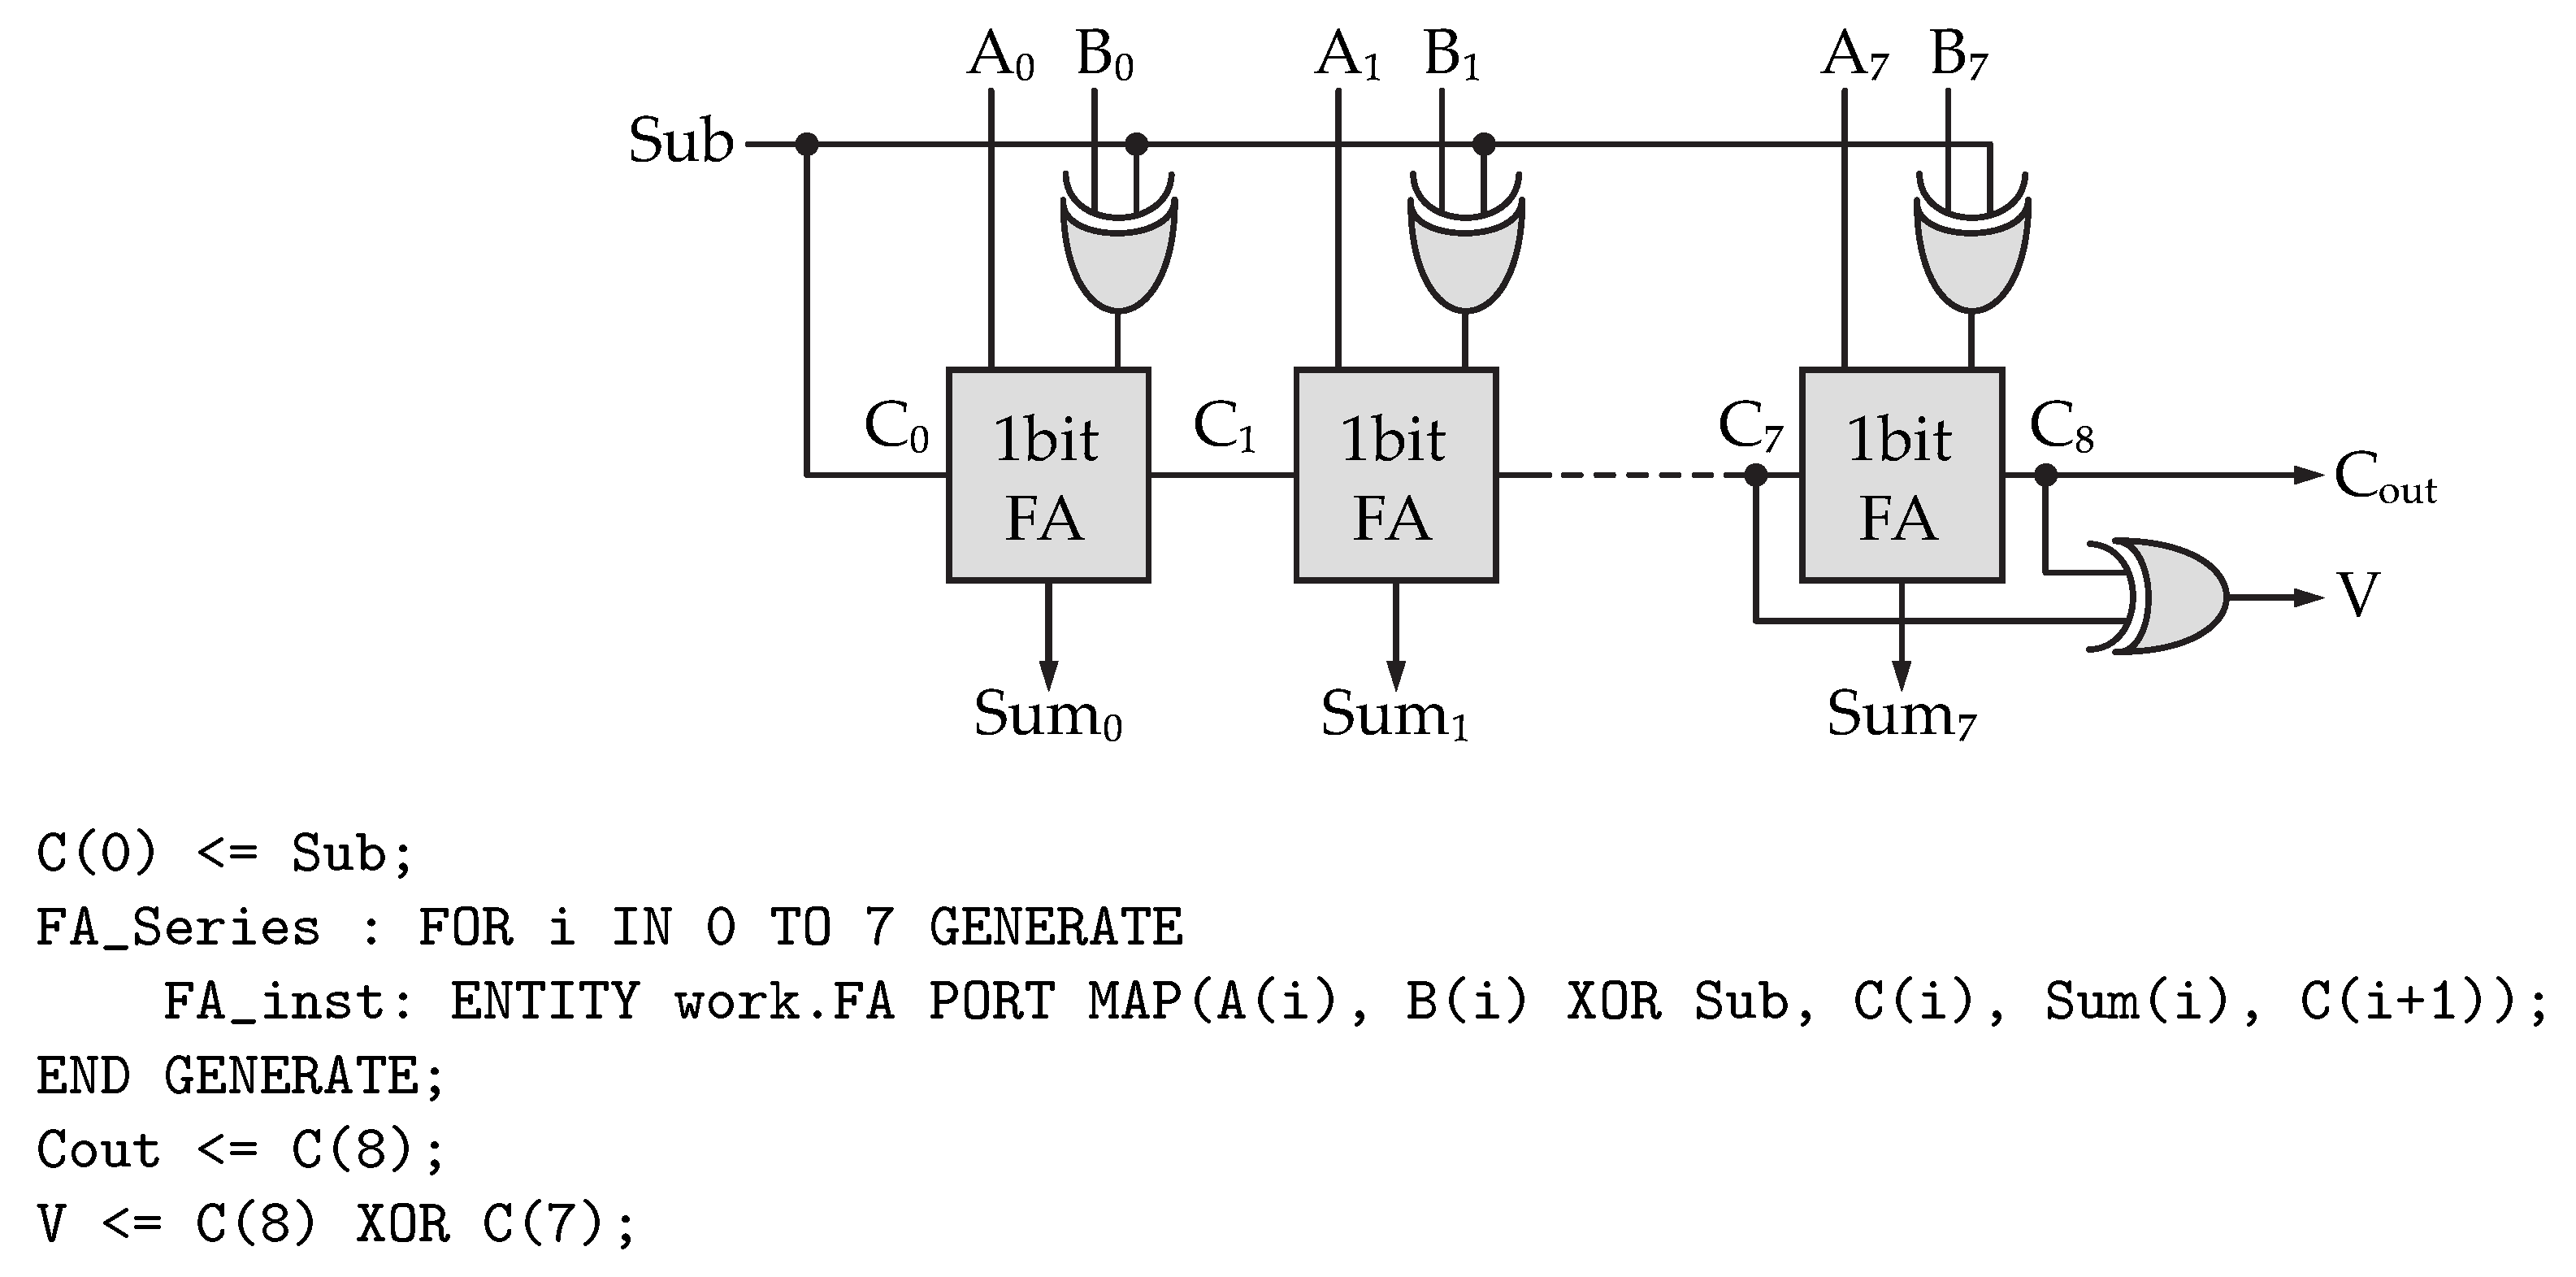
Figure 2.
Expanding opcode instruction types of the E80. Both instruction parts are fetched in a single cycle, and the second part is ignored for single-word instructions.
Figure 2.
Expanding opcode instruction types of the E80. Both instruction parts are fetched in a single cycle, and the second part is ignored for single-word instructions.
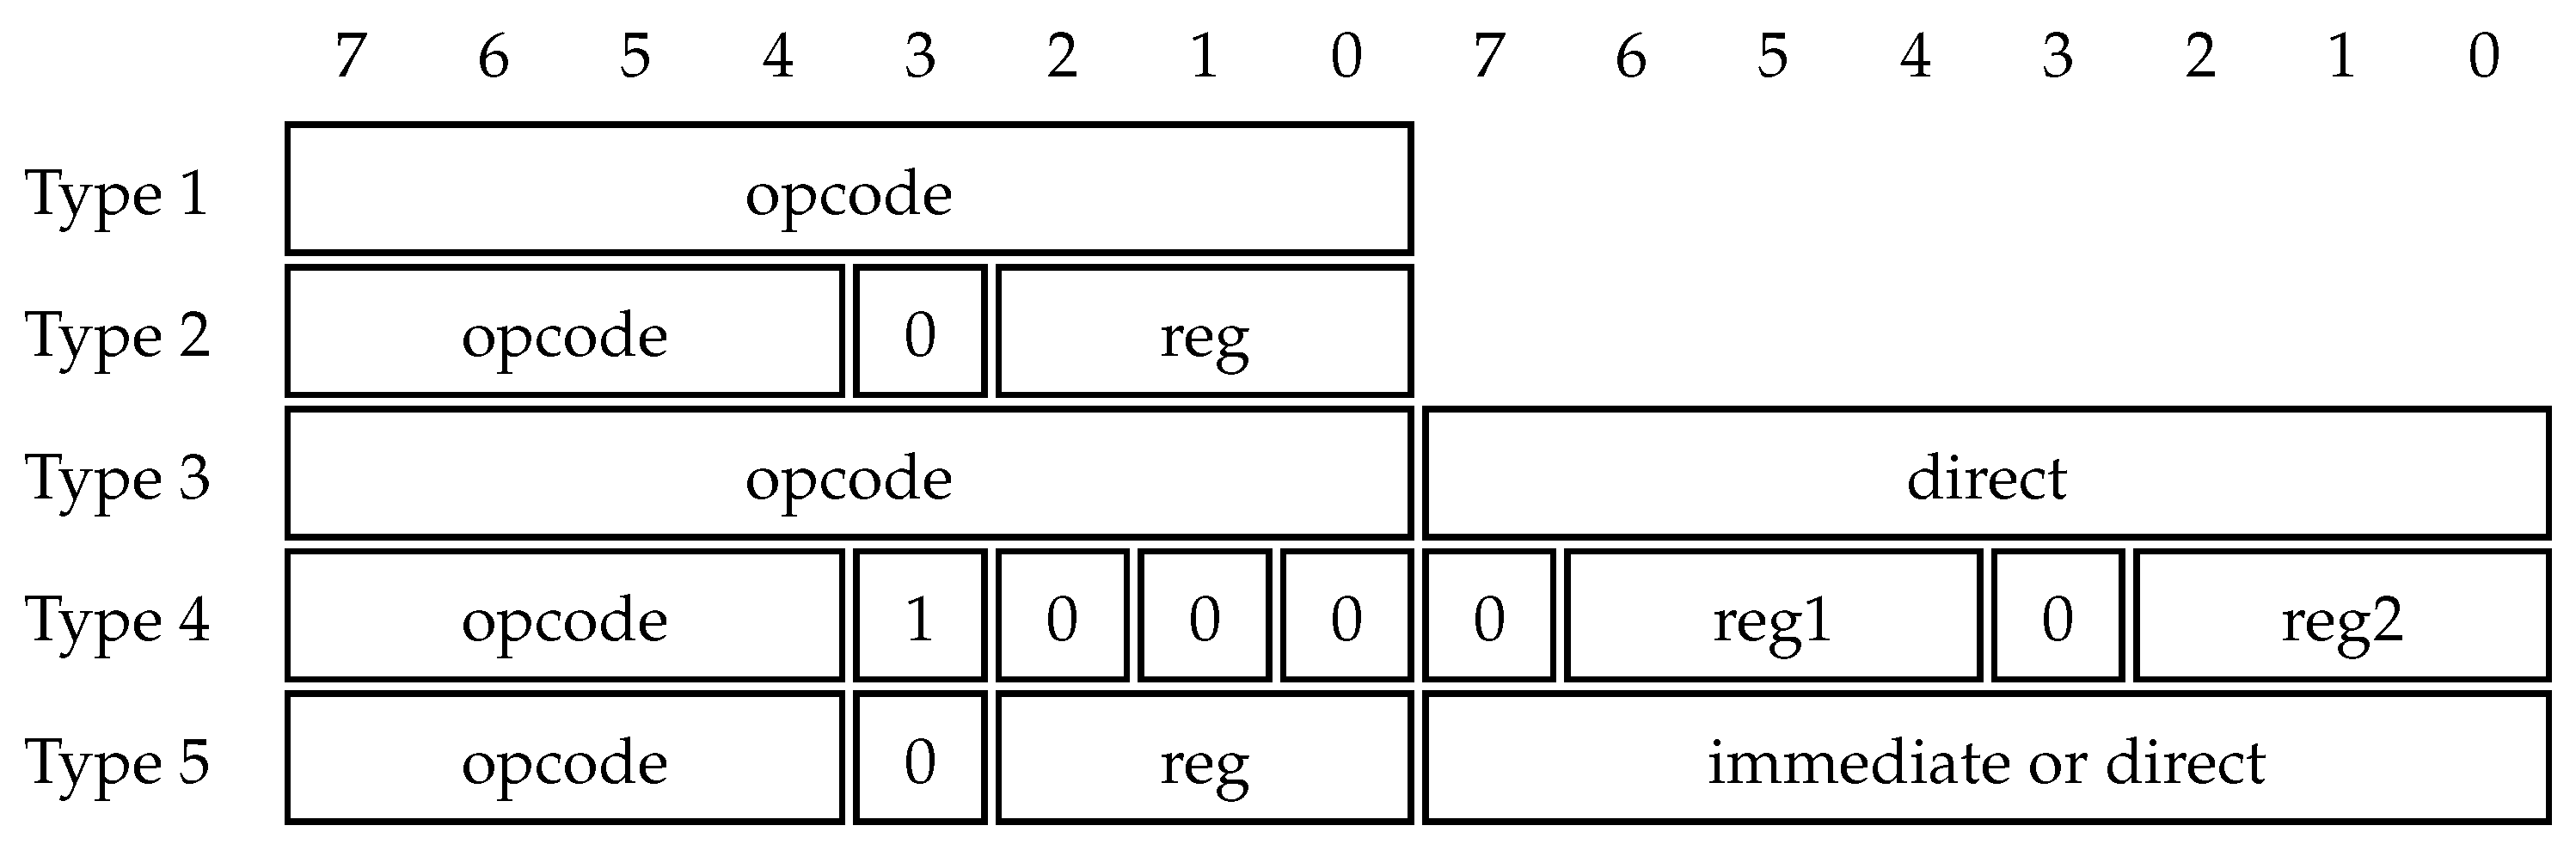
Figure 3.
The core datapath architecture: a general-purpose register, selected to act as an accumulator, provides input A to the ALU, while the second operand (op2) provides input B from an immediate value or another register. The ALU result is written back to the accumulator.
Figure 3.
The core datapath architecture: a general-purpose register, selected to act as an accumulator, provides input A to the ALU, while the second operand (op2) provides input B from an immediate value or another register. The ALU result is written back to the accumulator.
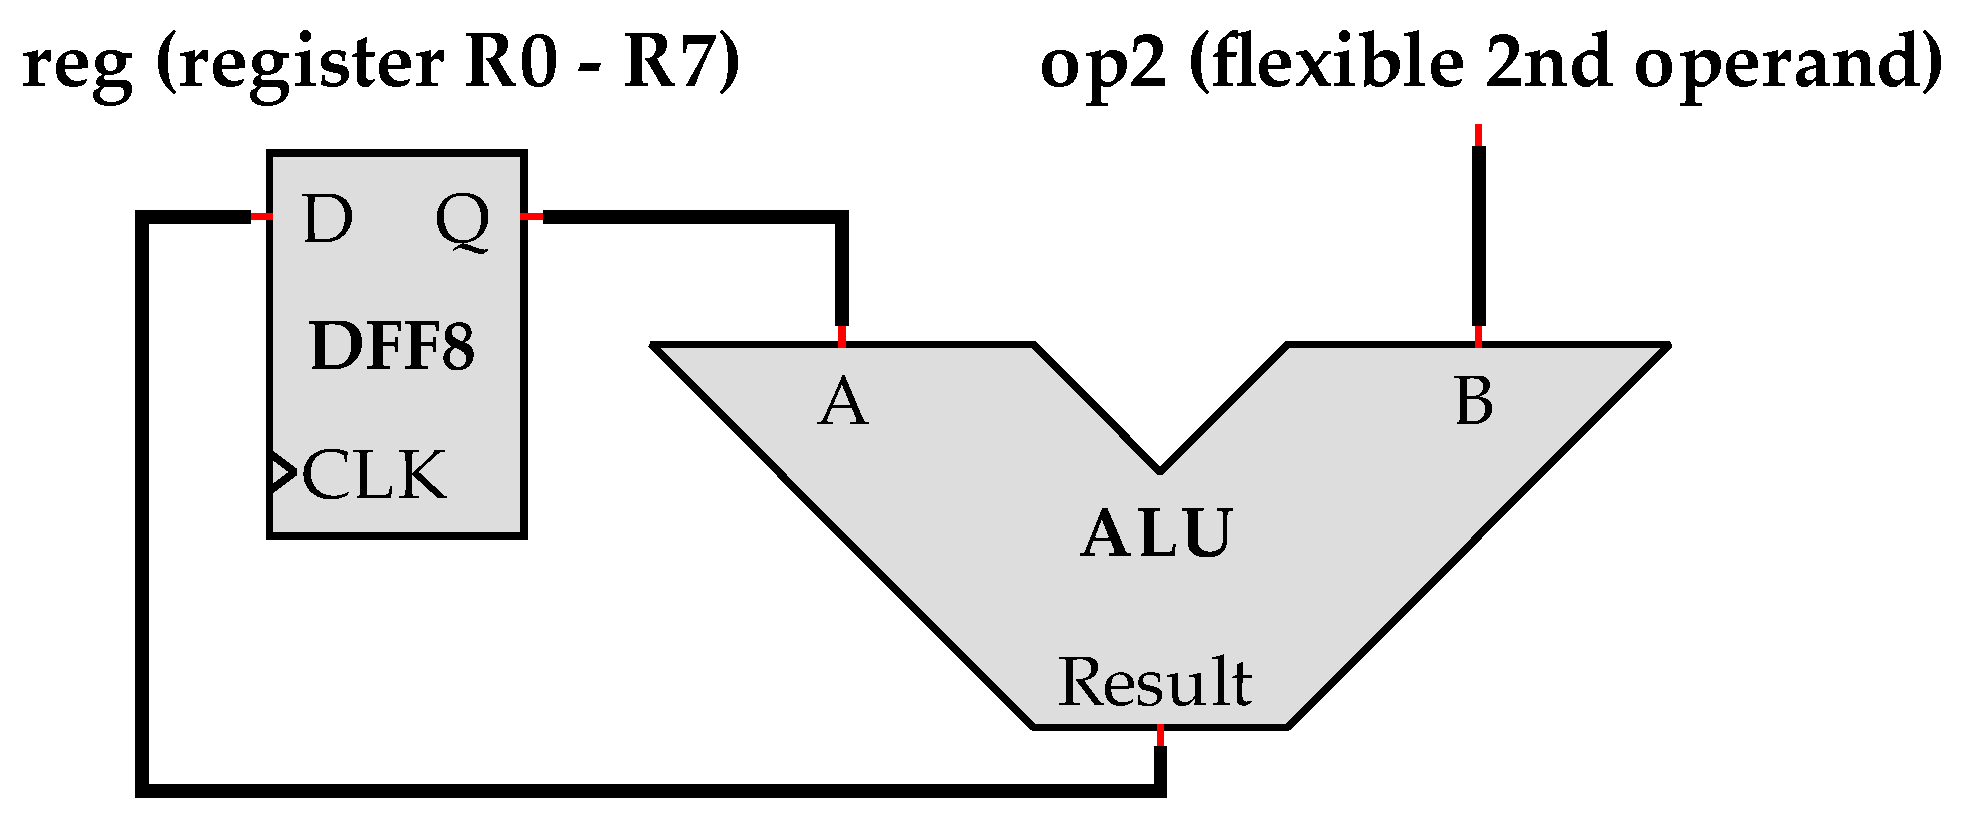
Figure 4.
The datapath exercised by ADD reg,op2. Depending on op2isReg, op2 is either a register or an immediate.
Figure 4.
The datapath exercised by ADD reg,op2. Depending on op2isReg, op2 is either a register or an immediate.
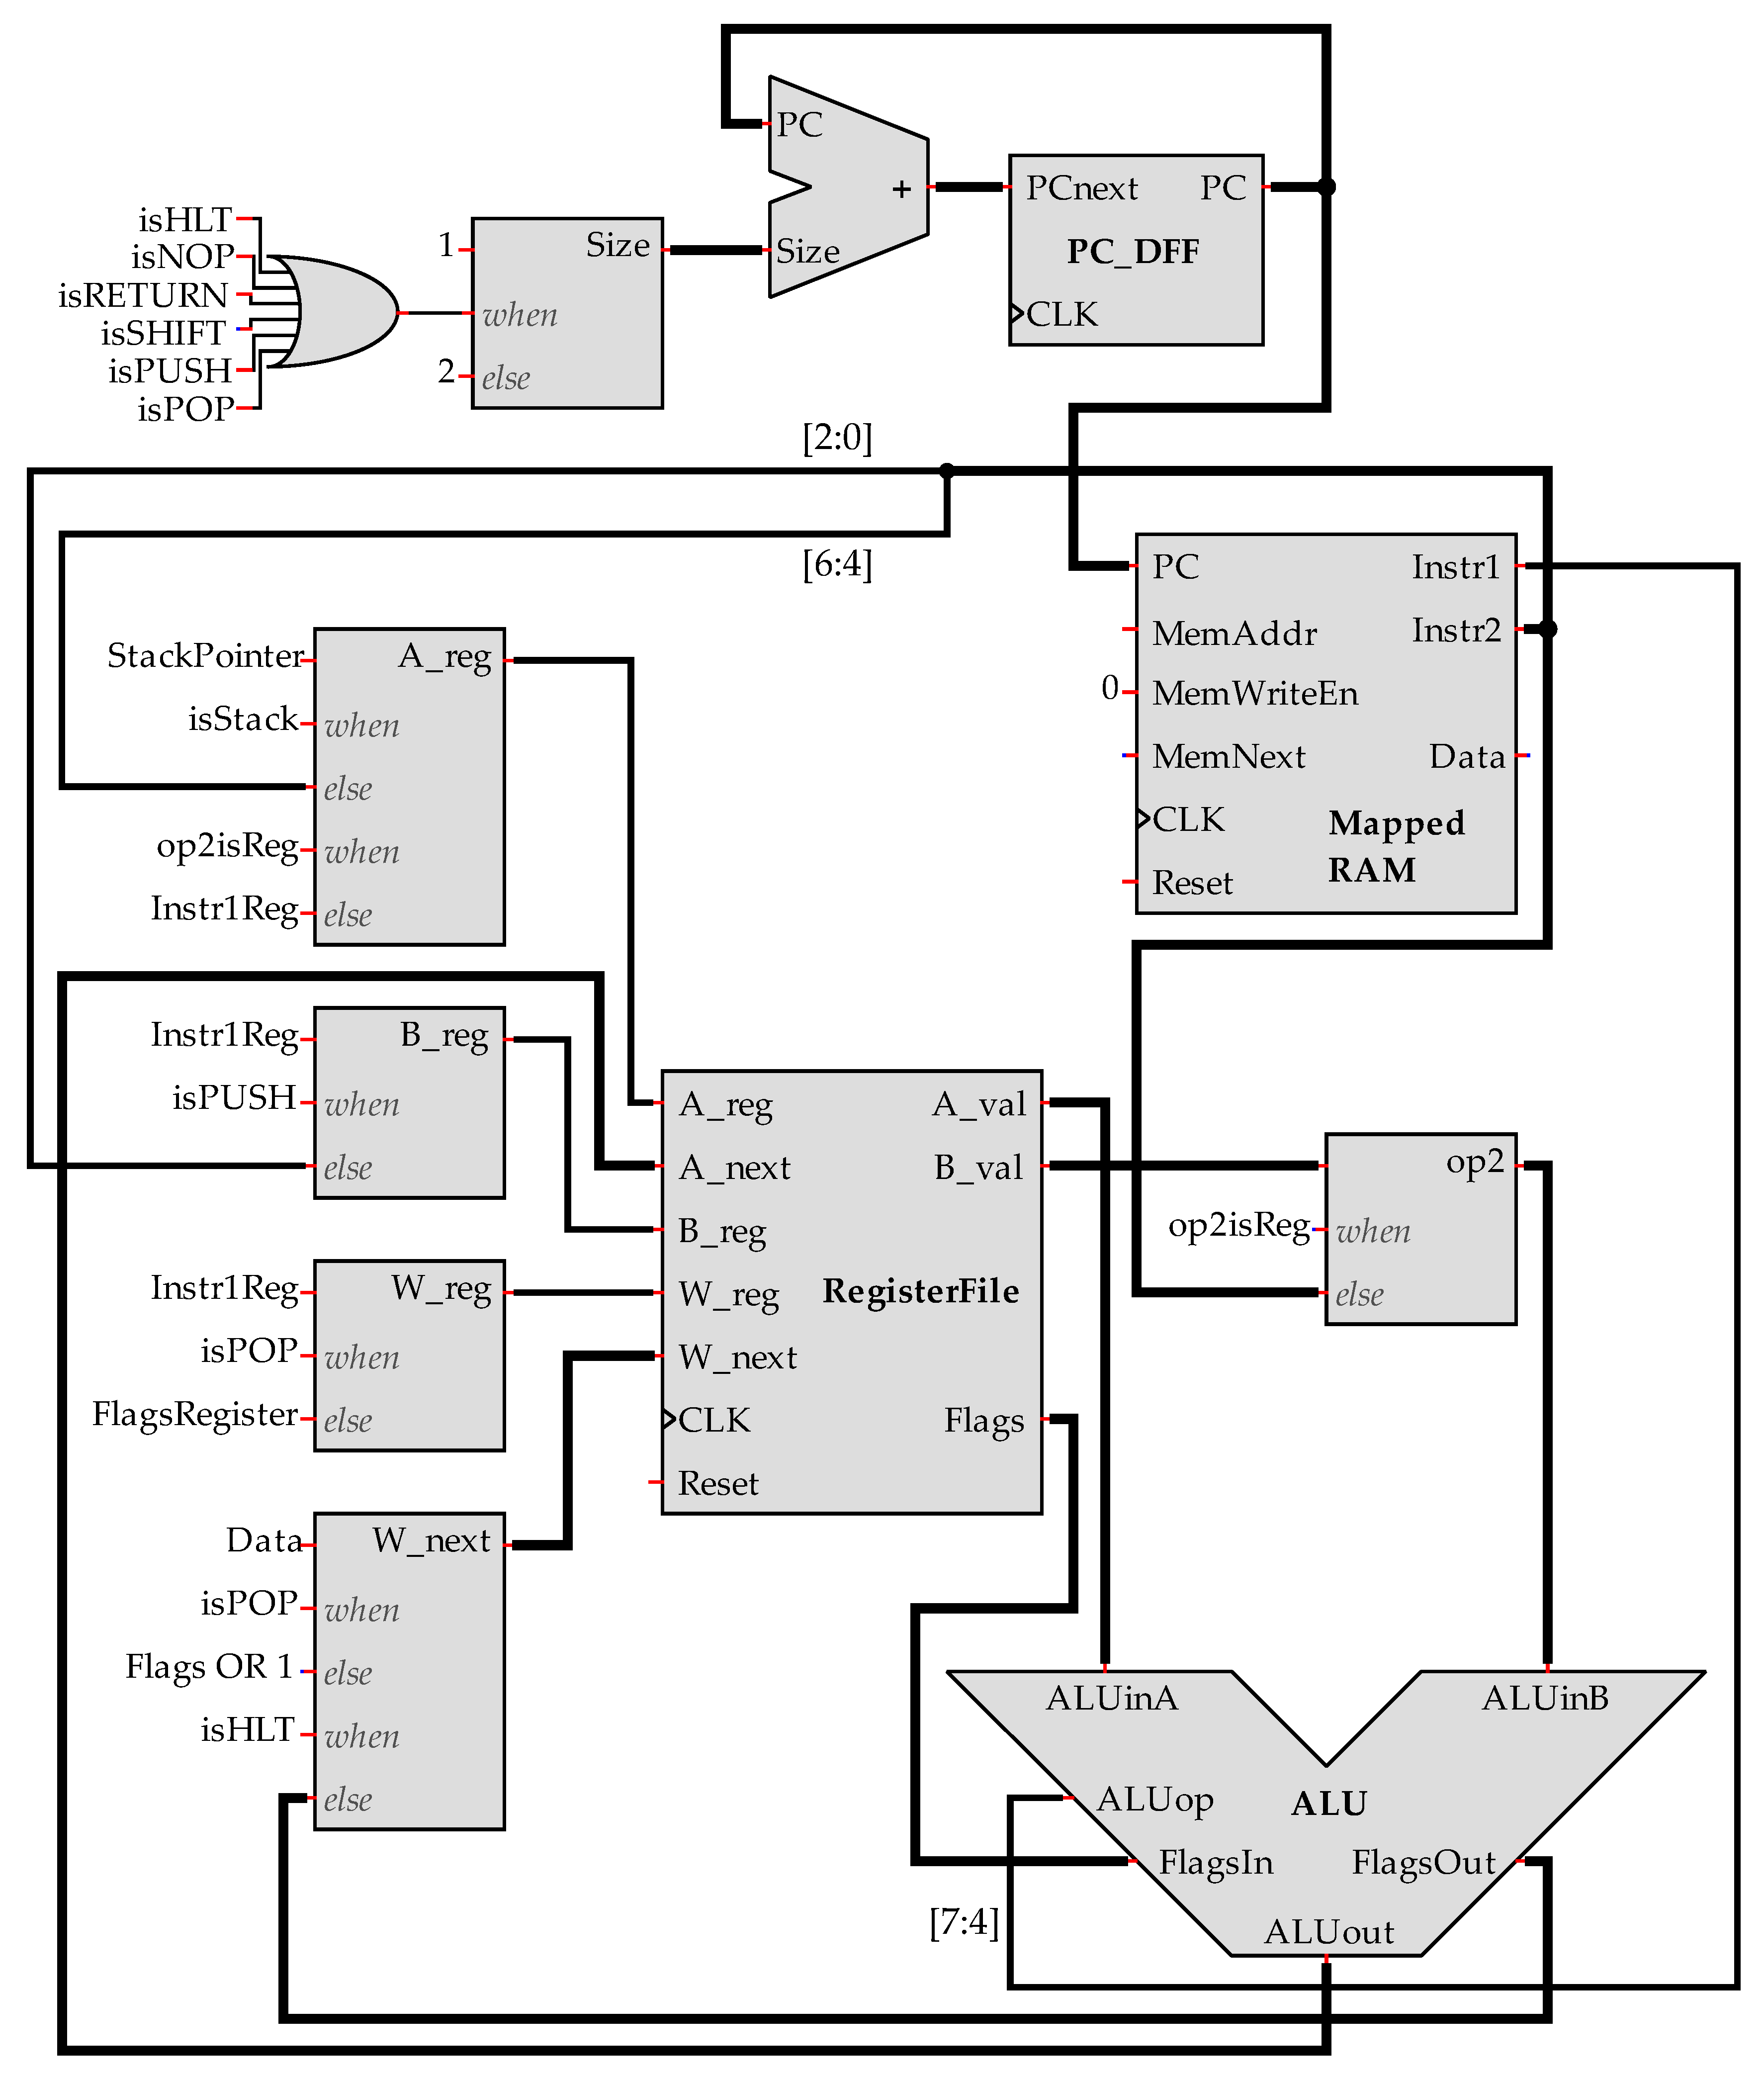
Figure 5.
The datapath exercised by POP: two register writes and a memory read in one cycle. The current value of the stack pointer addresses the word at the top of the full-descending stack to be written to the destination register while the ALU increments the stack pointer’s next value by 1.
Figure 5.
The datapath exercised by POP: two register writes and a memory read in one cycle. The current value of the stack pointer addresses the word at the top of the full-descending stack to be written to the destination register while the ALU increments the stack pointer’s next value by 1.
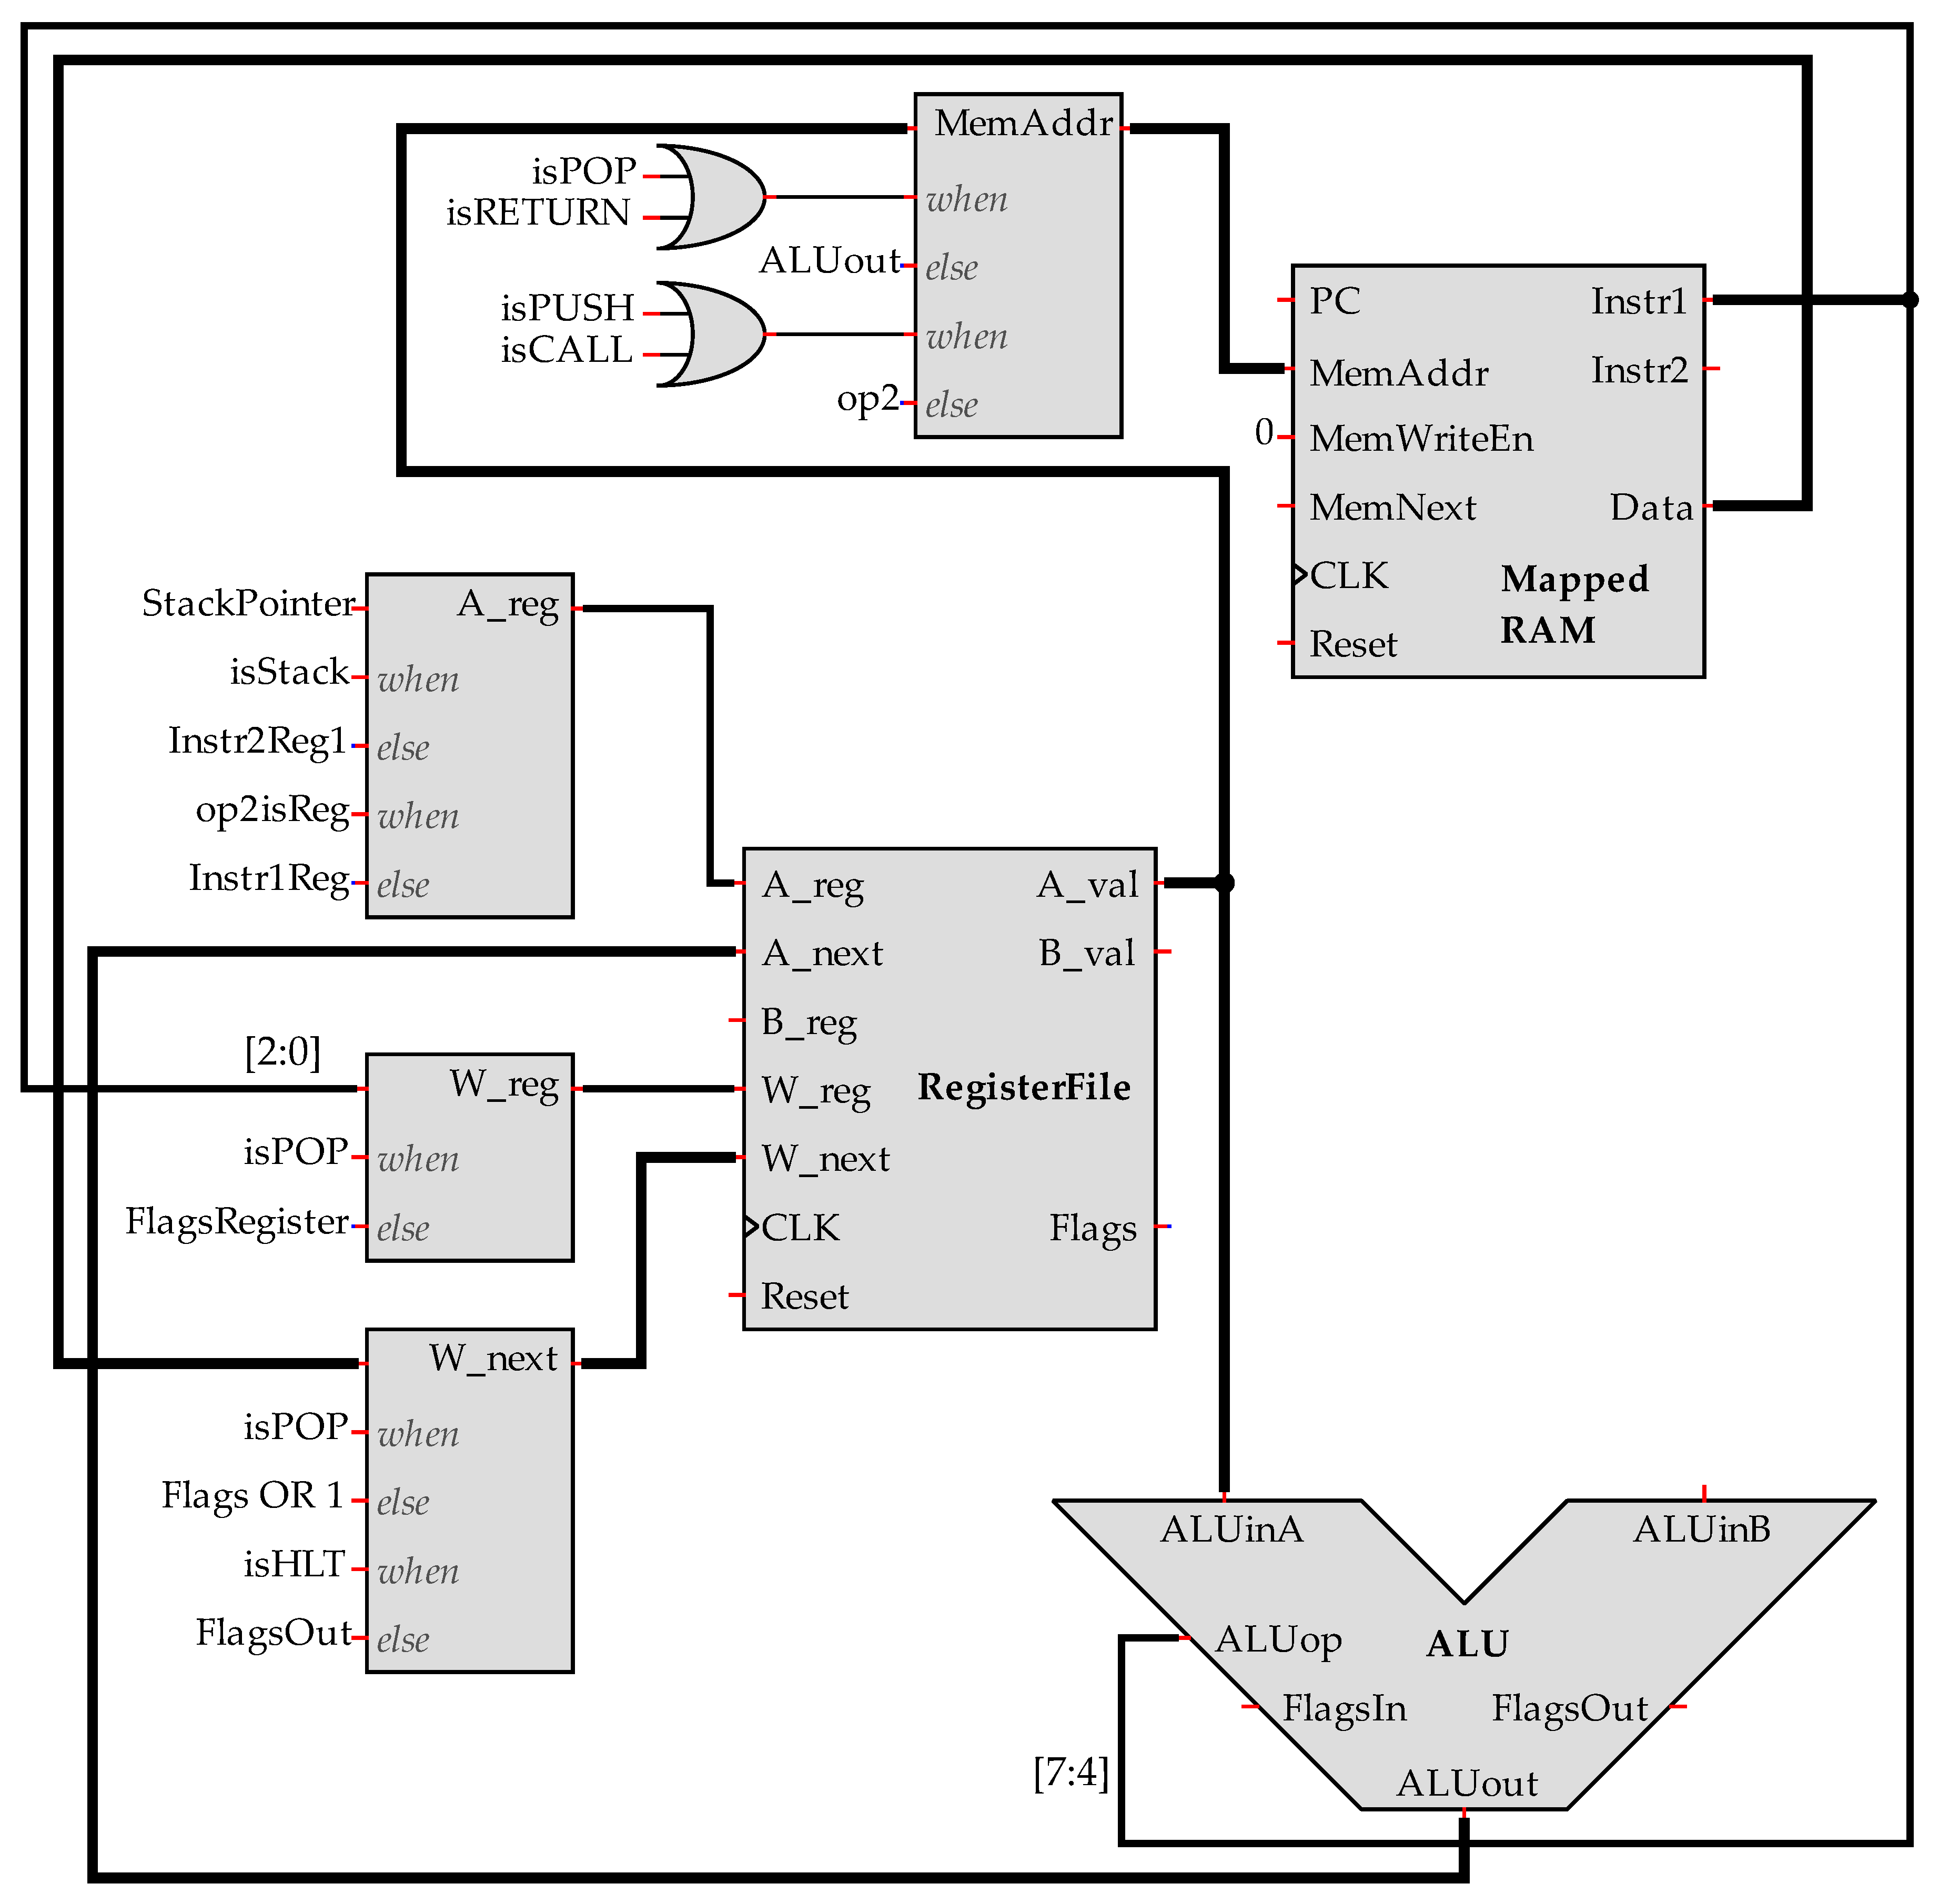
Figure 6.
The datapath exercised by LOAD after the revision: the word read from memory is driven directly onto the destination register’s write input, bypassing the ALU, and the flags are left unchanged.
Figure 6.
The datapath exercised by LOAD after the revision: the word read from memory is driven directly onto the destination register’s write input, bypassing the ALU, and the flags are left unchanged.
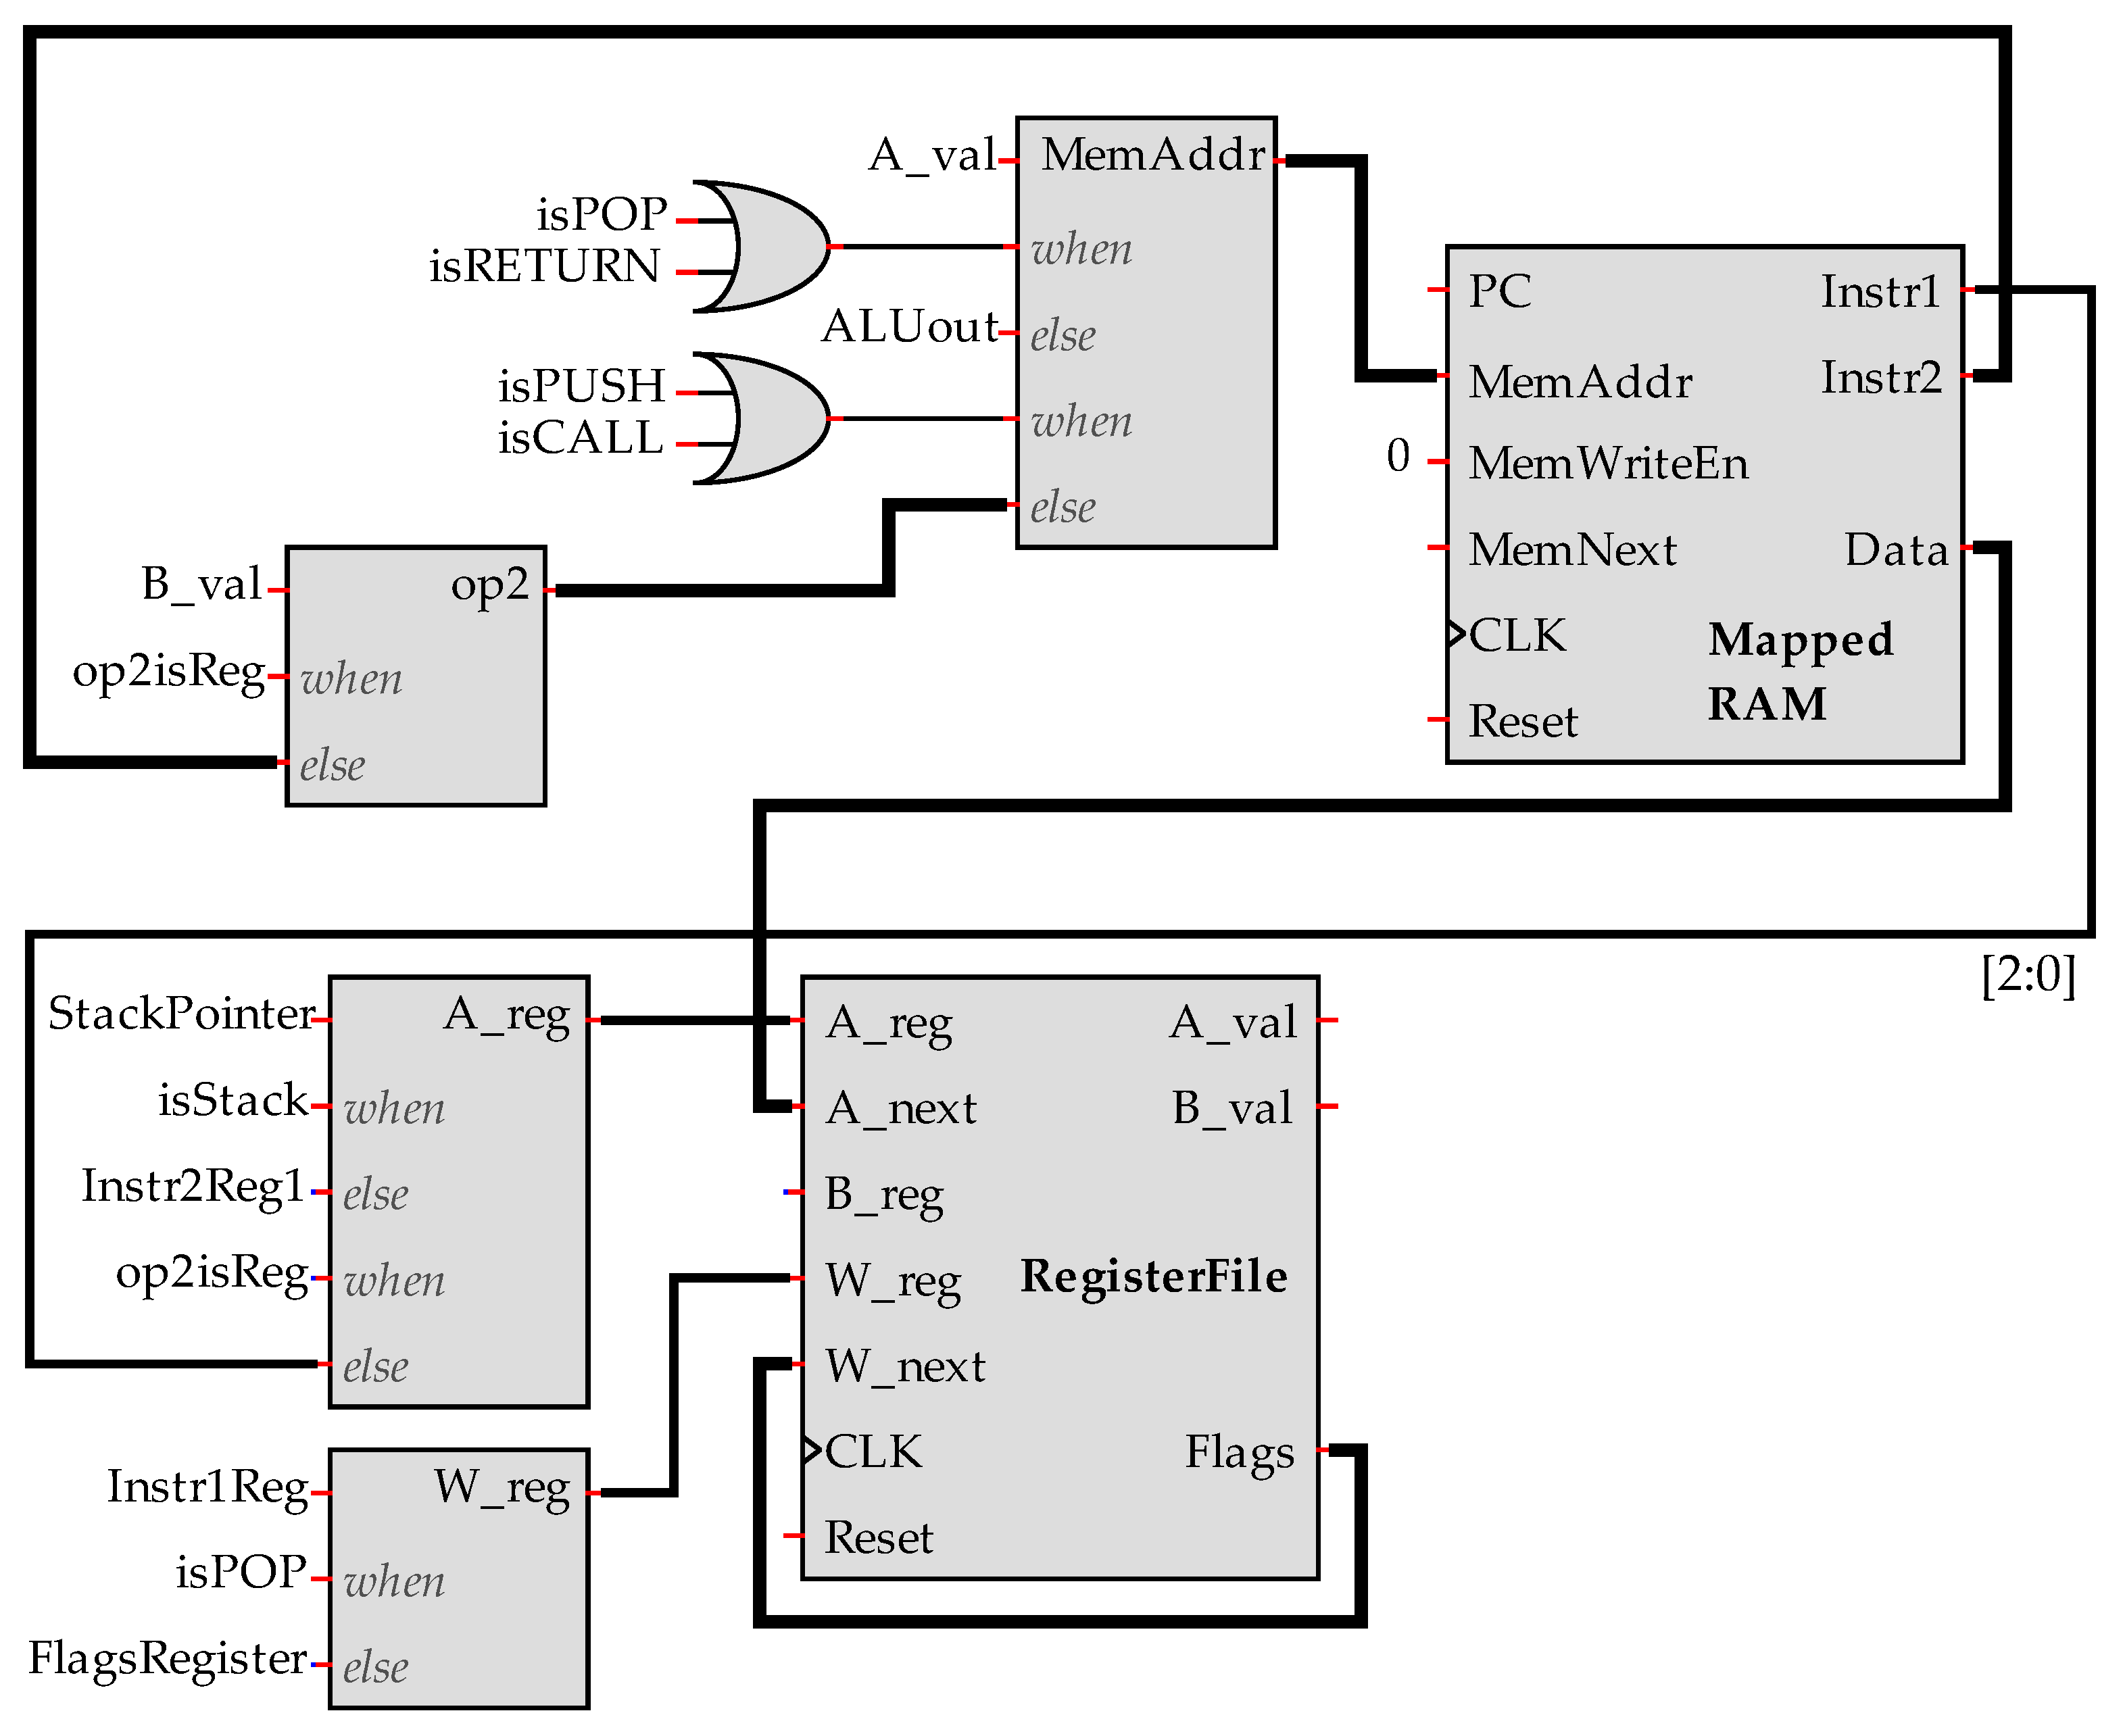
Figure 7.
The LOAD datapath in the conference version: the loaded word passed through the ALU so that the sign and zero flags could be produced. Together with the stack path that routes the ALU output to the memory address, this closed the false combinational loop discussed in the text.
Figure 7.
The LOAD datapath in the conference version: the loaded word passed through the ALU so that the sign and zero flags could be produced. Together with the stack path that routes the ALU output to the memory address, this closed the false combinational loop discussed in the text.
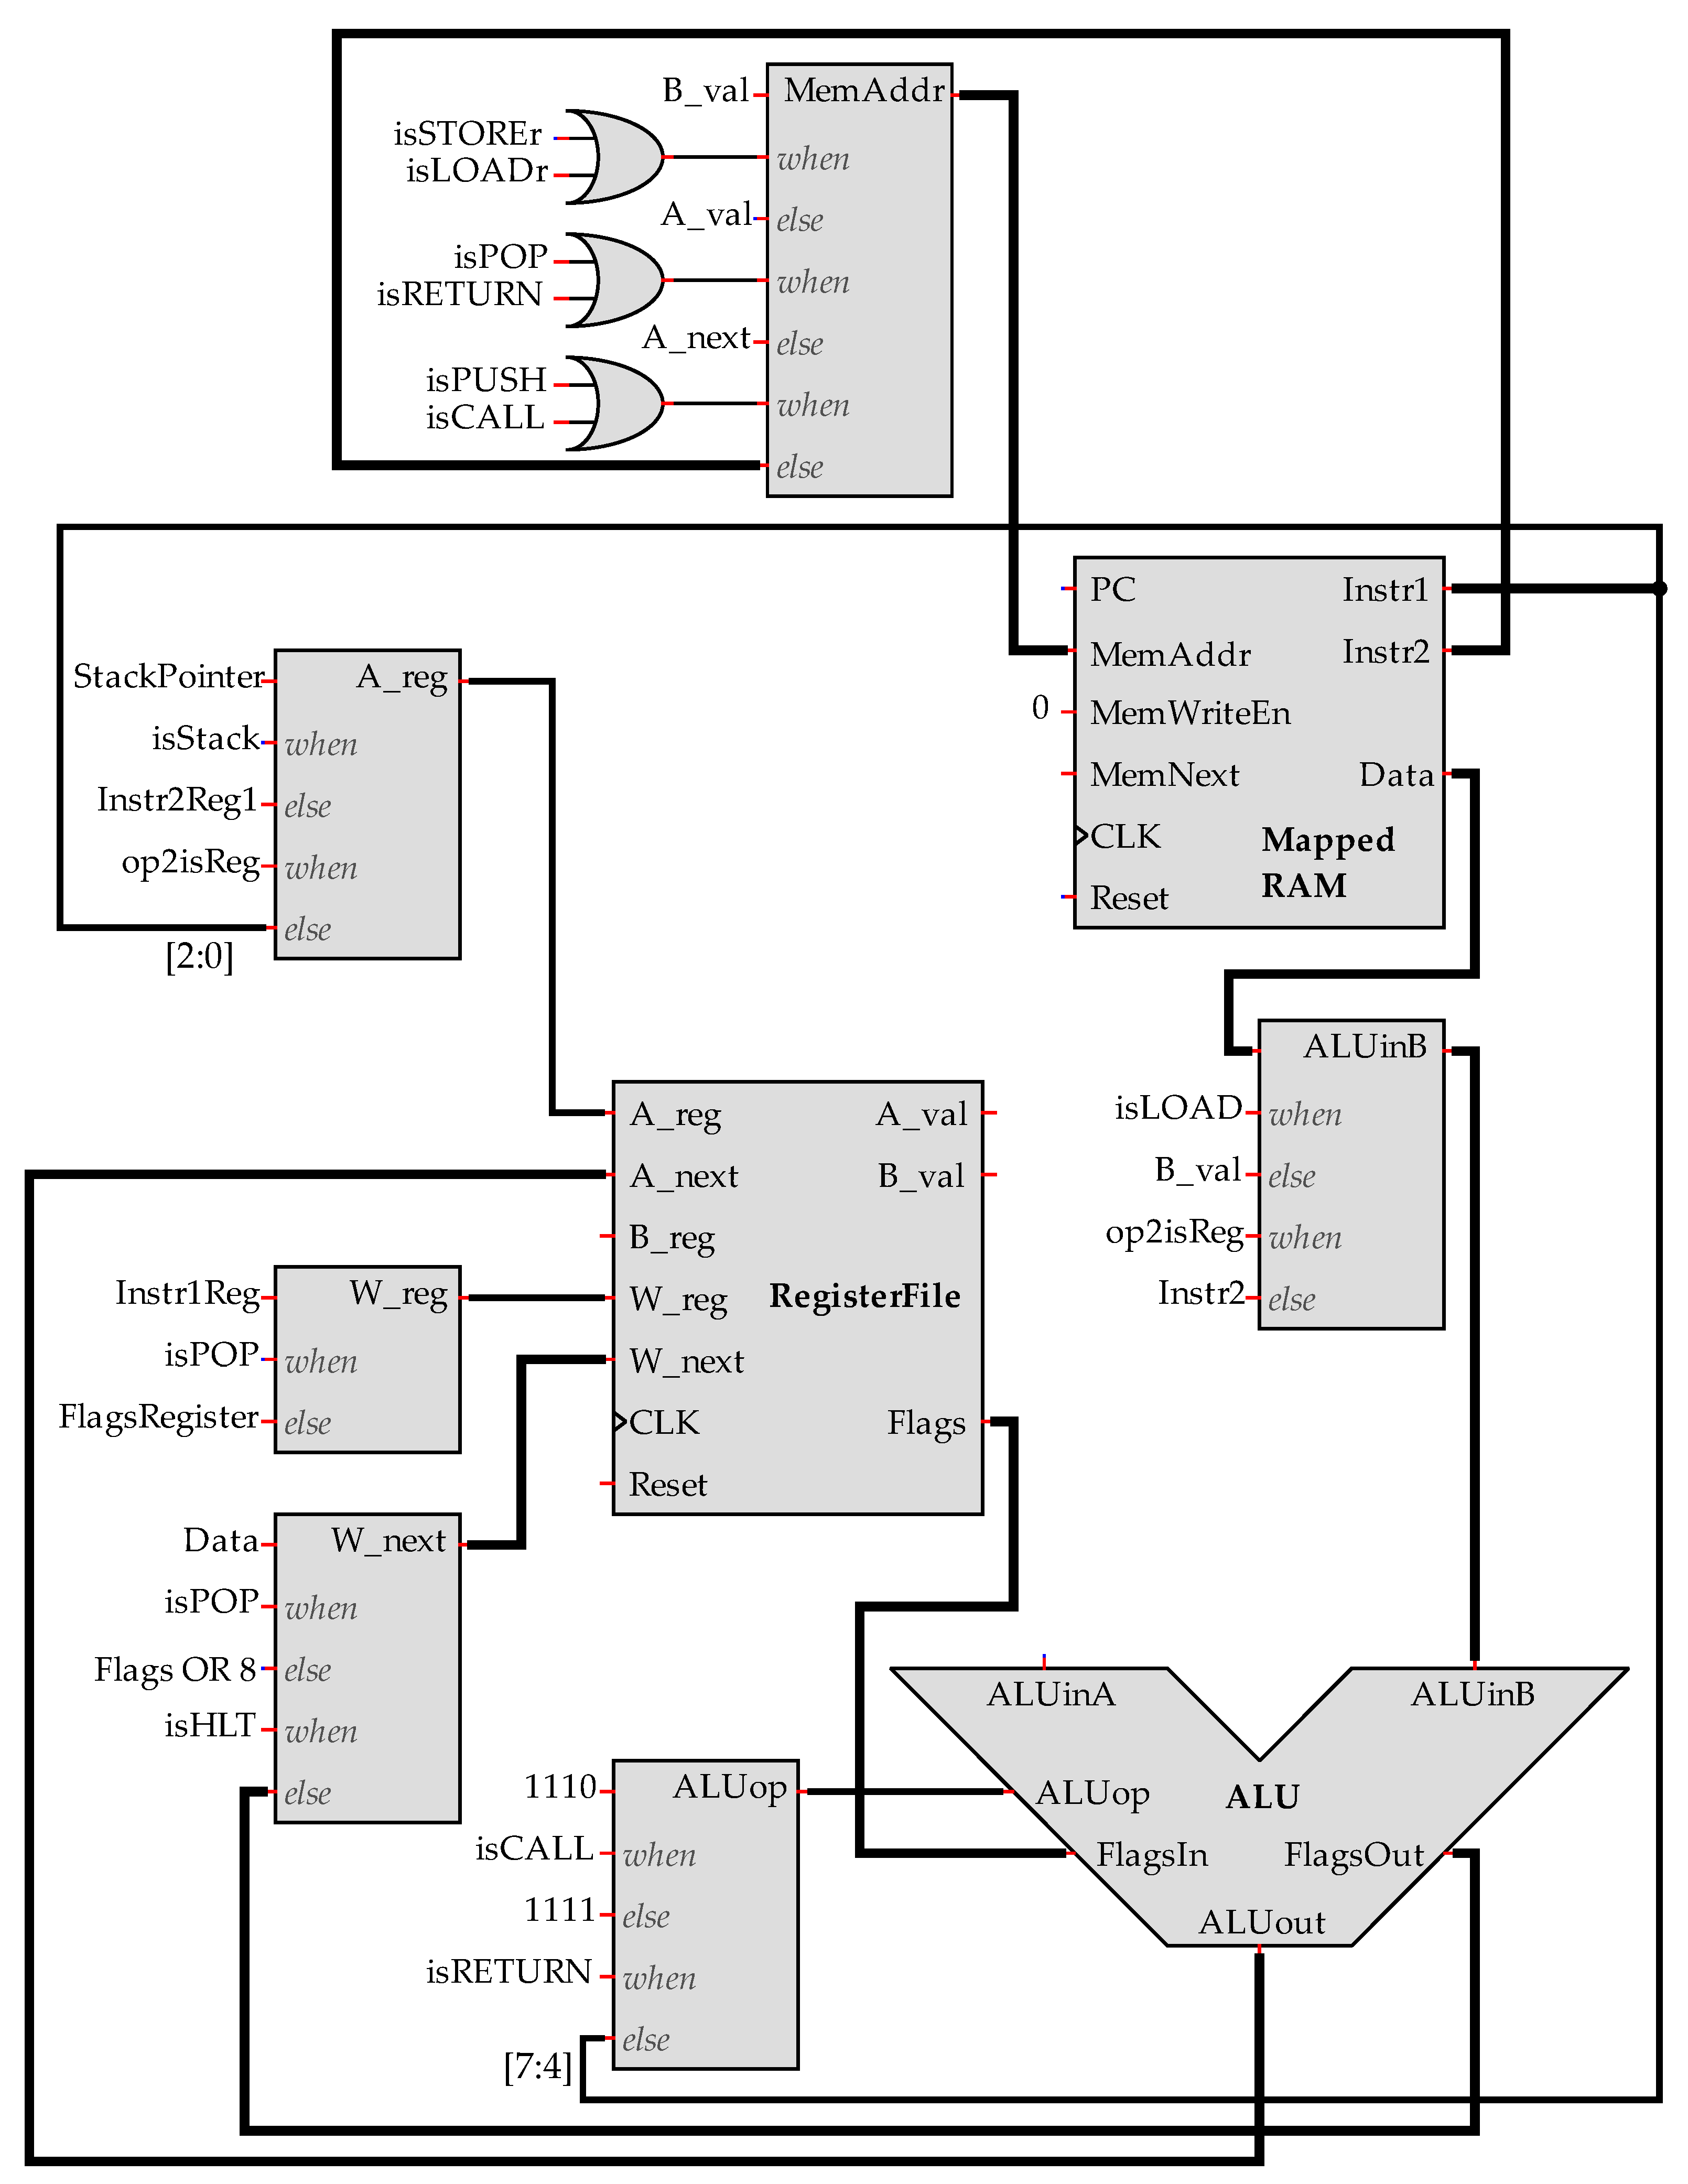
Figure 8.
The Sc1 editor showing hello.e80asm (a) and the Program.vhd (b) package generated from it by pressing F7.
Figure 8.
The Sc1 editor showing hello.e80asm (a) and the Program.vhd (b) package generated from it by pressing F7.
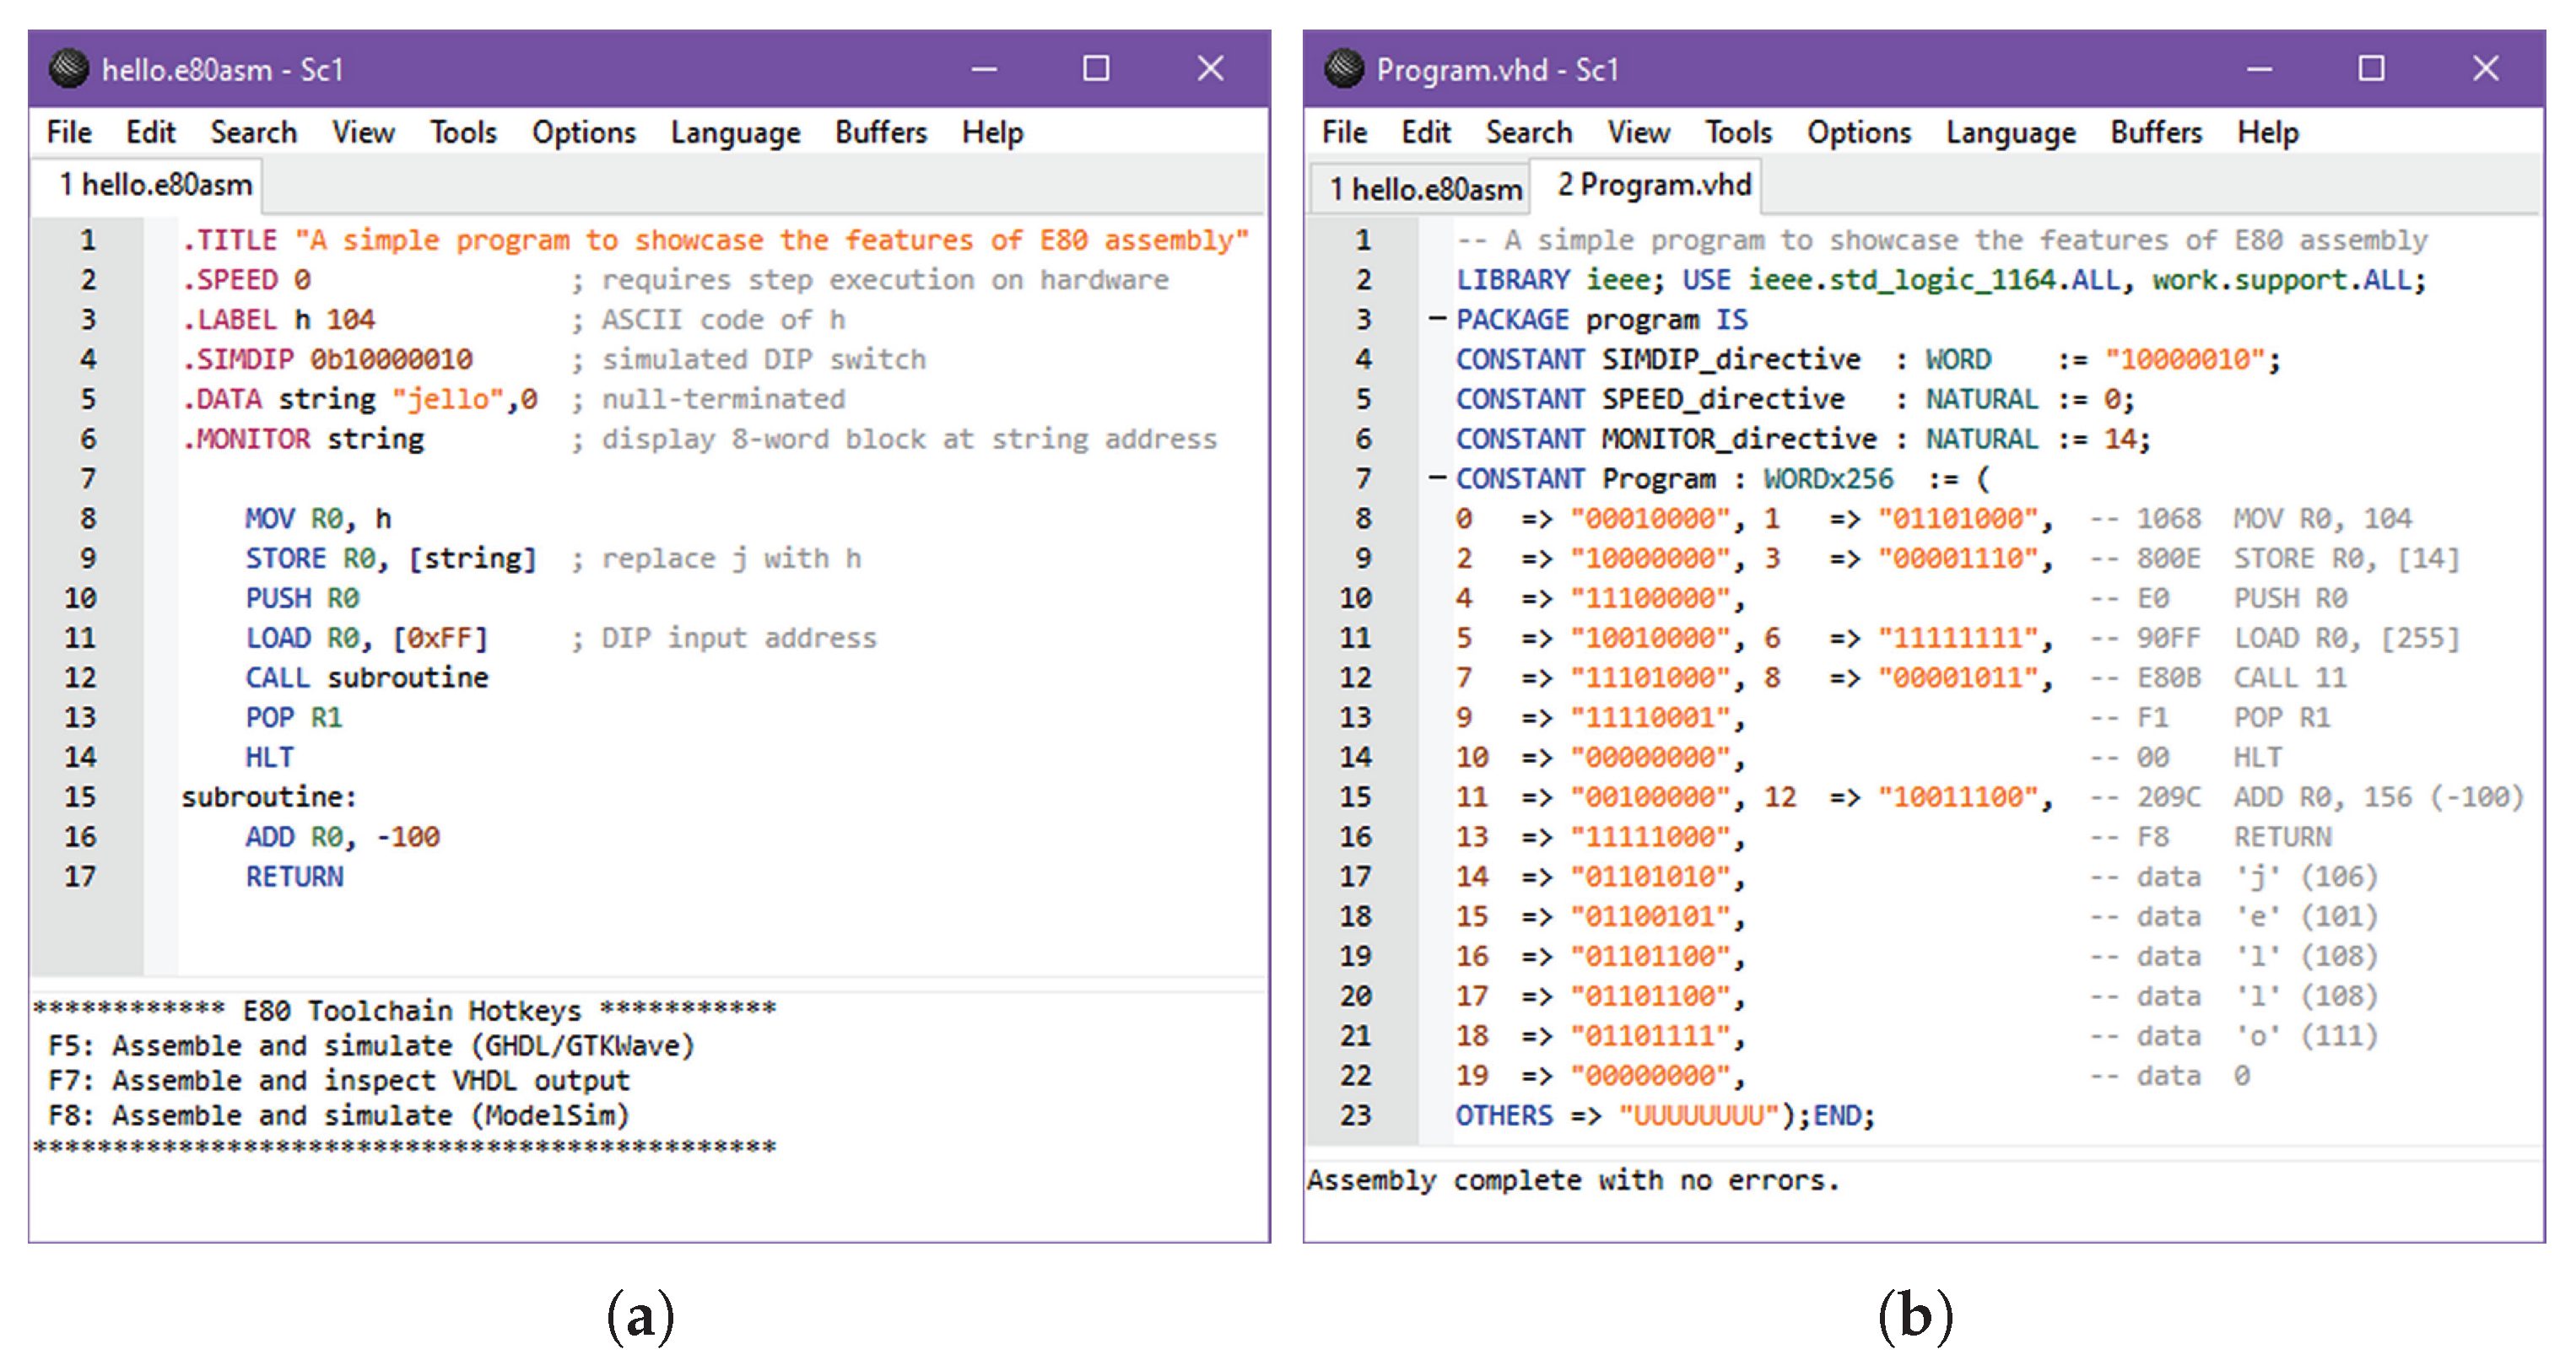
Figure 9.
A GHDL run of hello.e80asm in GTKWave. Instr1 and Instr2 are the parts of the current instruction, with the latter ignored for one-word instructions. The highest RAM addresses show the stack space. The Monitor string and the eight rows correspond to the .MONITOR directive. The trace stops automatically where Halt is raised. All vectors have been manually set to binary.
Figure 9.
A GHDL run of hello.e80asm in GTKWave. Instr1 and Instr2 are the parts of the current instruction, with the latter ignored for one-word instructions. The highest RAM addresses show the stack space. The Monitor string and the eight rows correspond to the .MONITOR directive. The trace stops automatically where Halt is raised. All vectors have been manually set to binary.
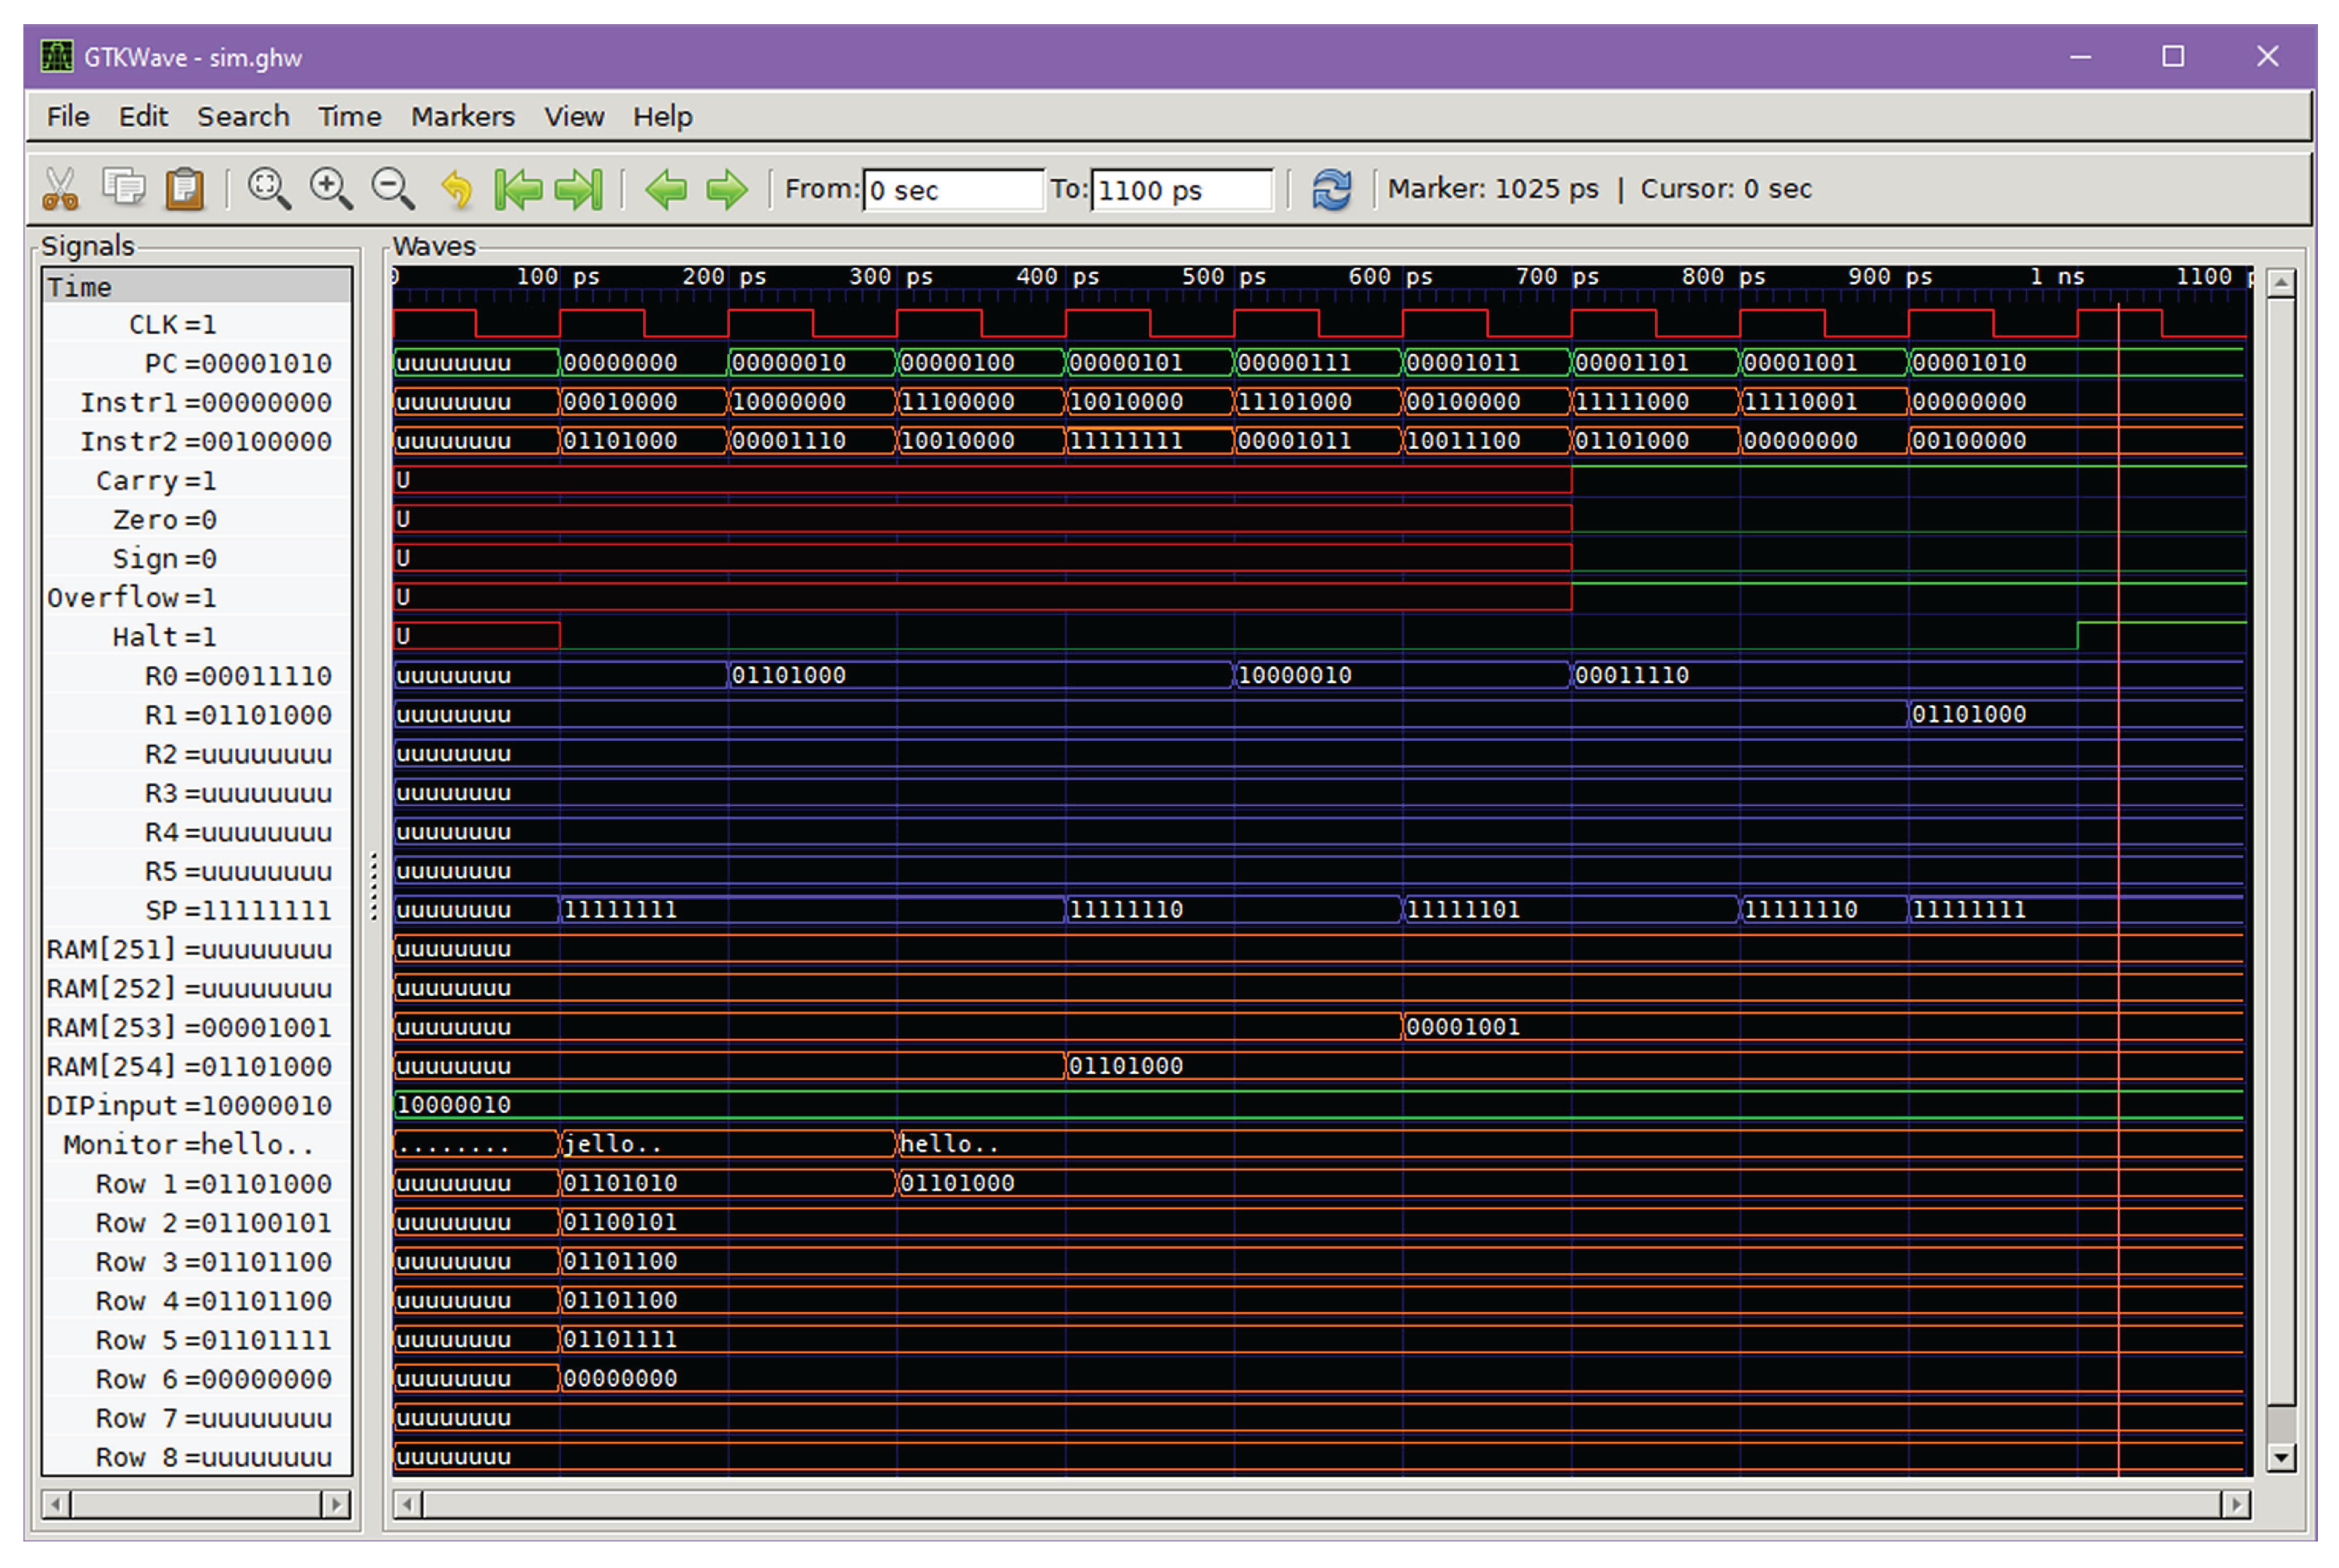
Figure 10.
hello.e80asm running in ModelSim, showing the same signals as Figure 9 in the default decimal and hexadecimal radices. The .MONITOR block appears in both ASCII and binary radices. The run stops when the Halt flag rises, and the transcript below lists the whole memory in rows of 32 words, where the string at address 14 can be read as modified.
Figure 10.
hello.e80asm running in ModelSim, showing the same signals as Figure 9 in the default decimal and hexadecimal radices. The .MONITOR block appears in both ASCII and binary radices. The run stops when the Halt flag rises, and the transcript below lists the whole memory in rows of 32 words, where the string at address 14 can be read as modified.
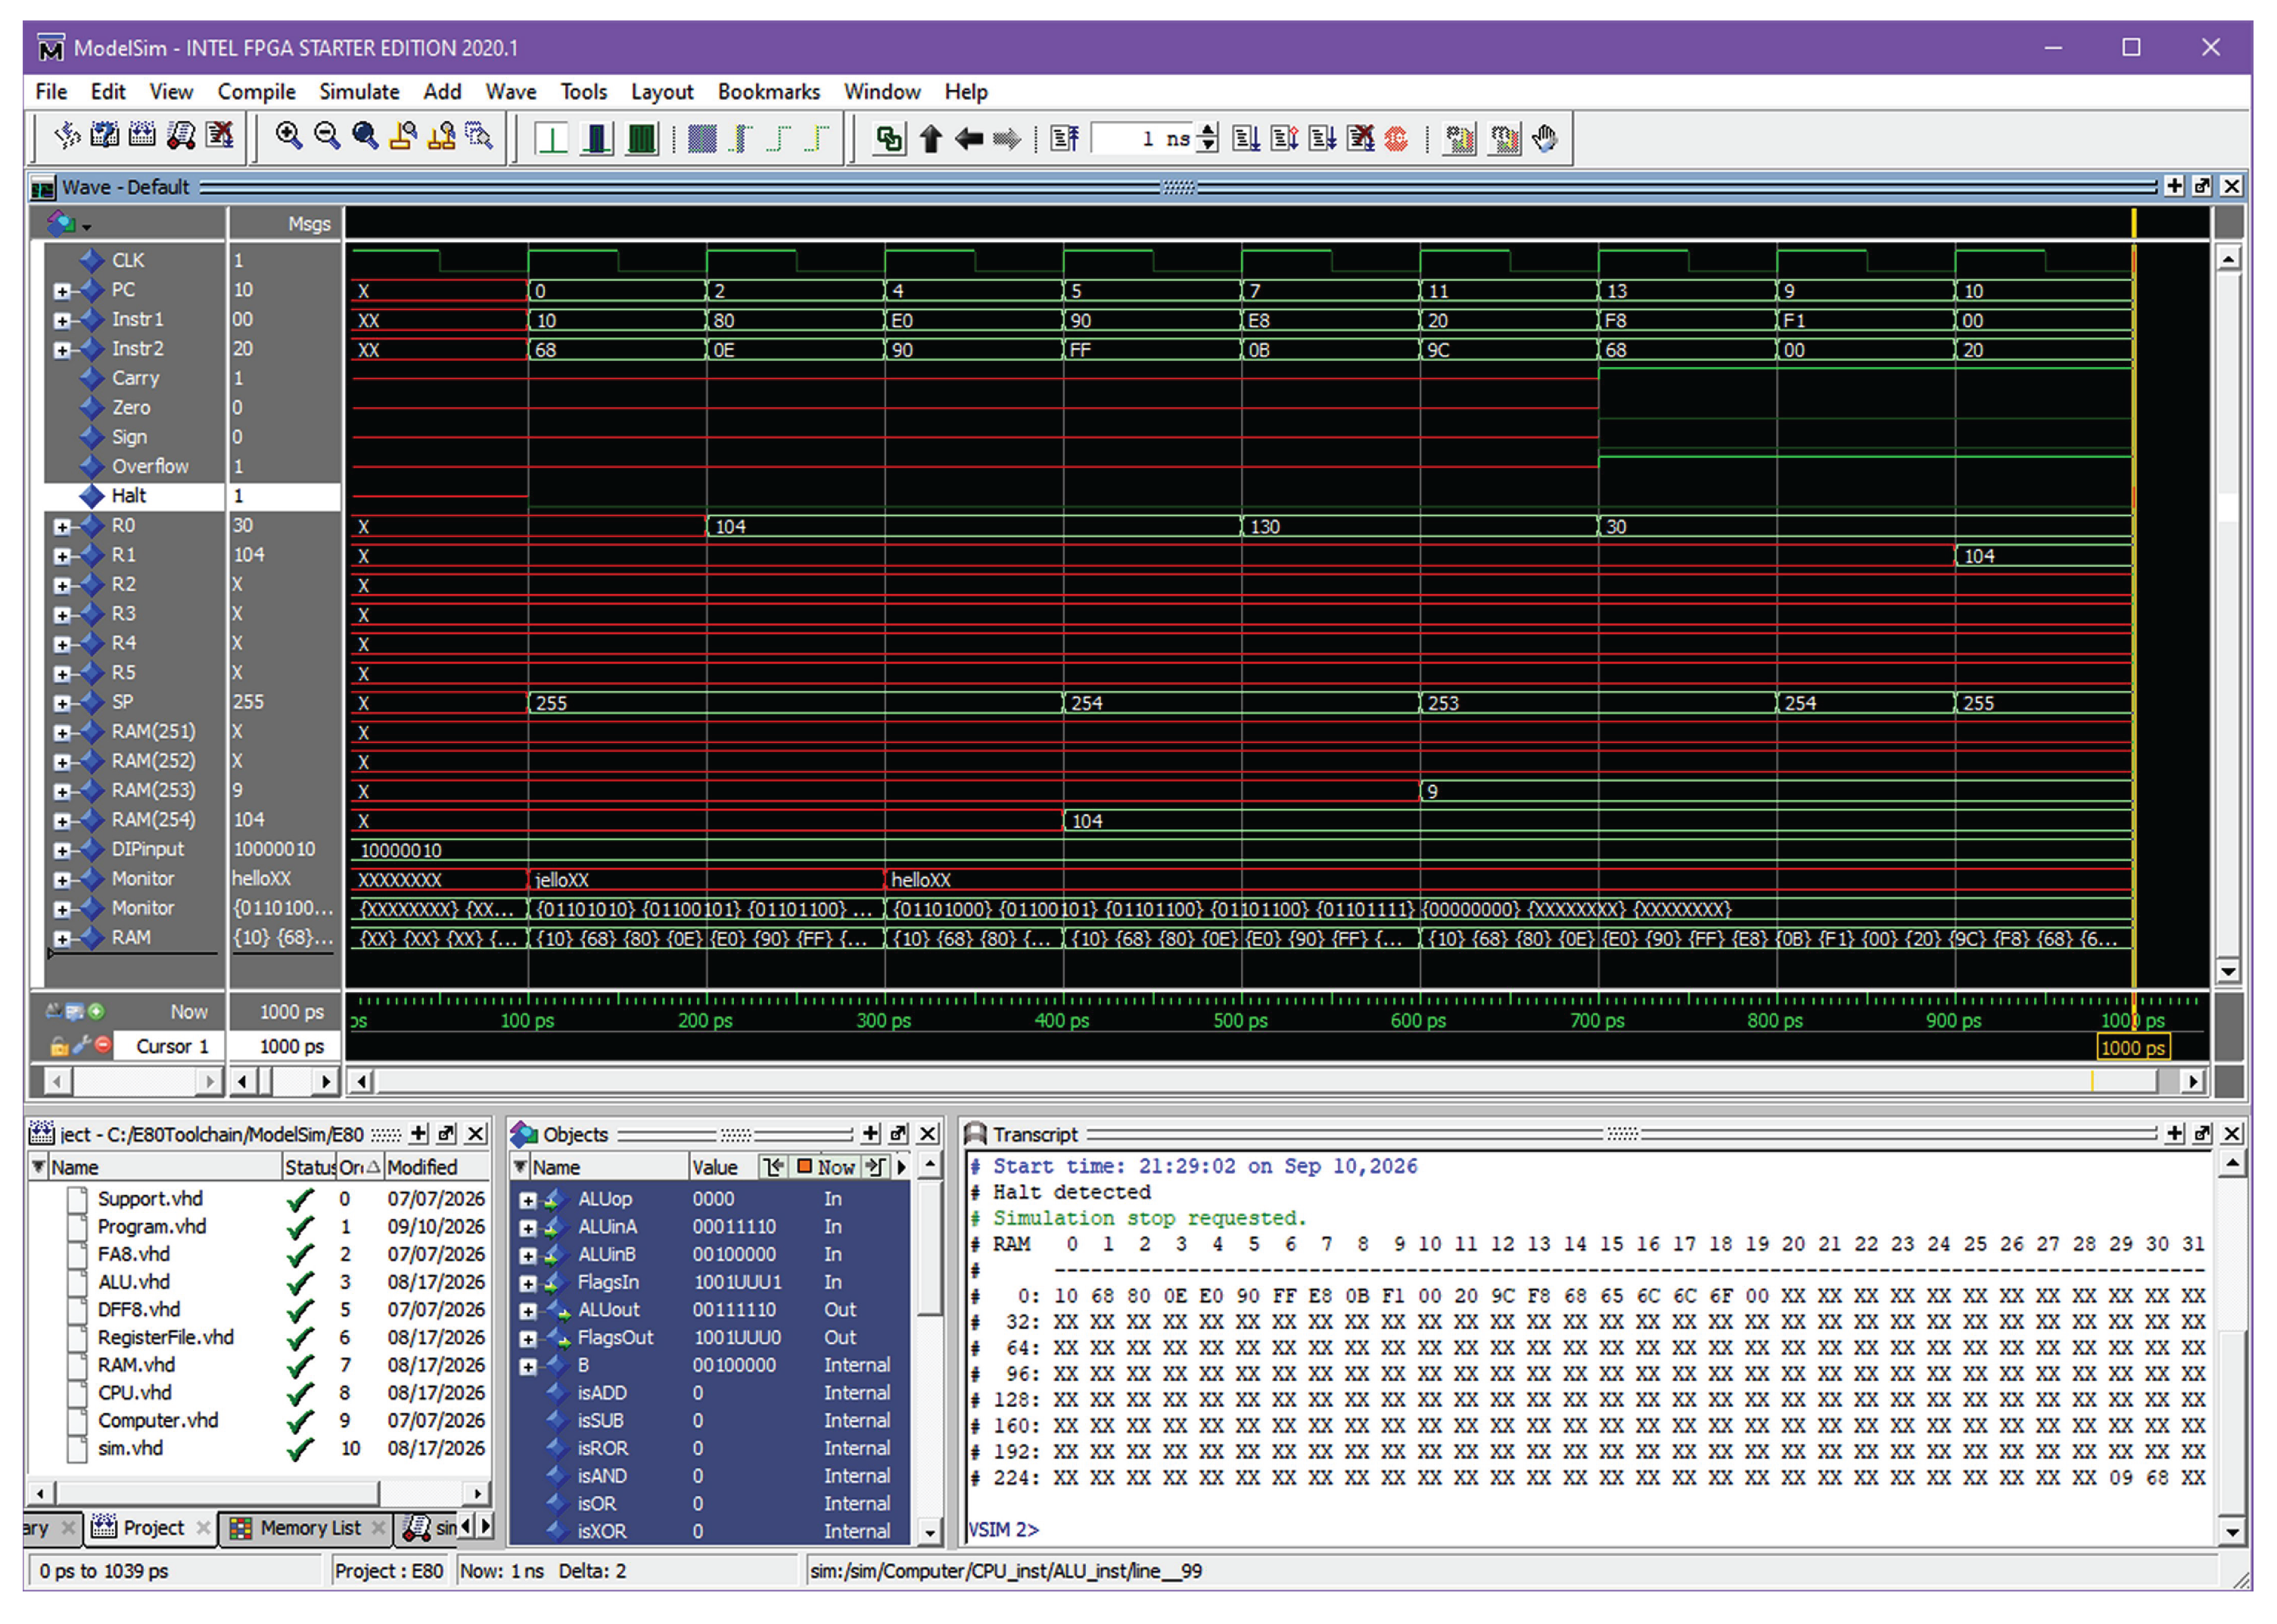
Figure 11.
Four daisy-chained 8×8 matrices mapping the state of execution shown in GTKWave in Figure 9. GTKWave displays undefined values as u and, in this example (copied from the Tang Primer 25K), they are set to zeros.
Figure 11.
Four daisy-chained 8×8 matrices mapping the state of execution shown in GTKWave in Figure 9. GTKWave displays undefined values as u and, in this example (copied from the Tang Primer 25K), they are set to zeros.
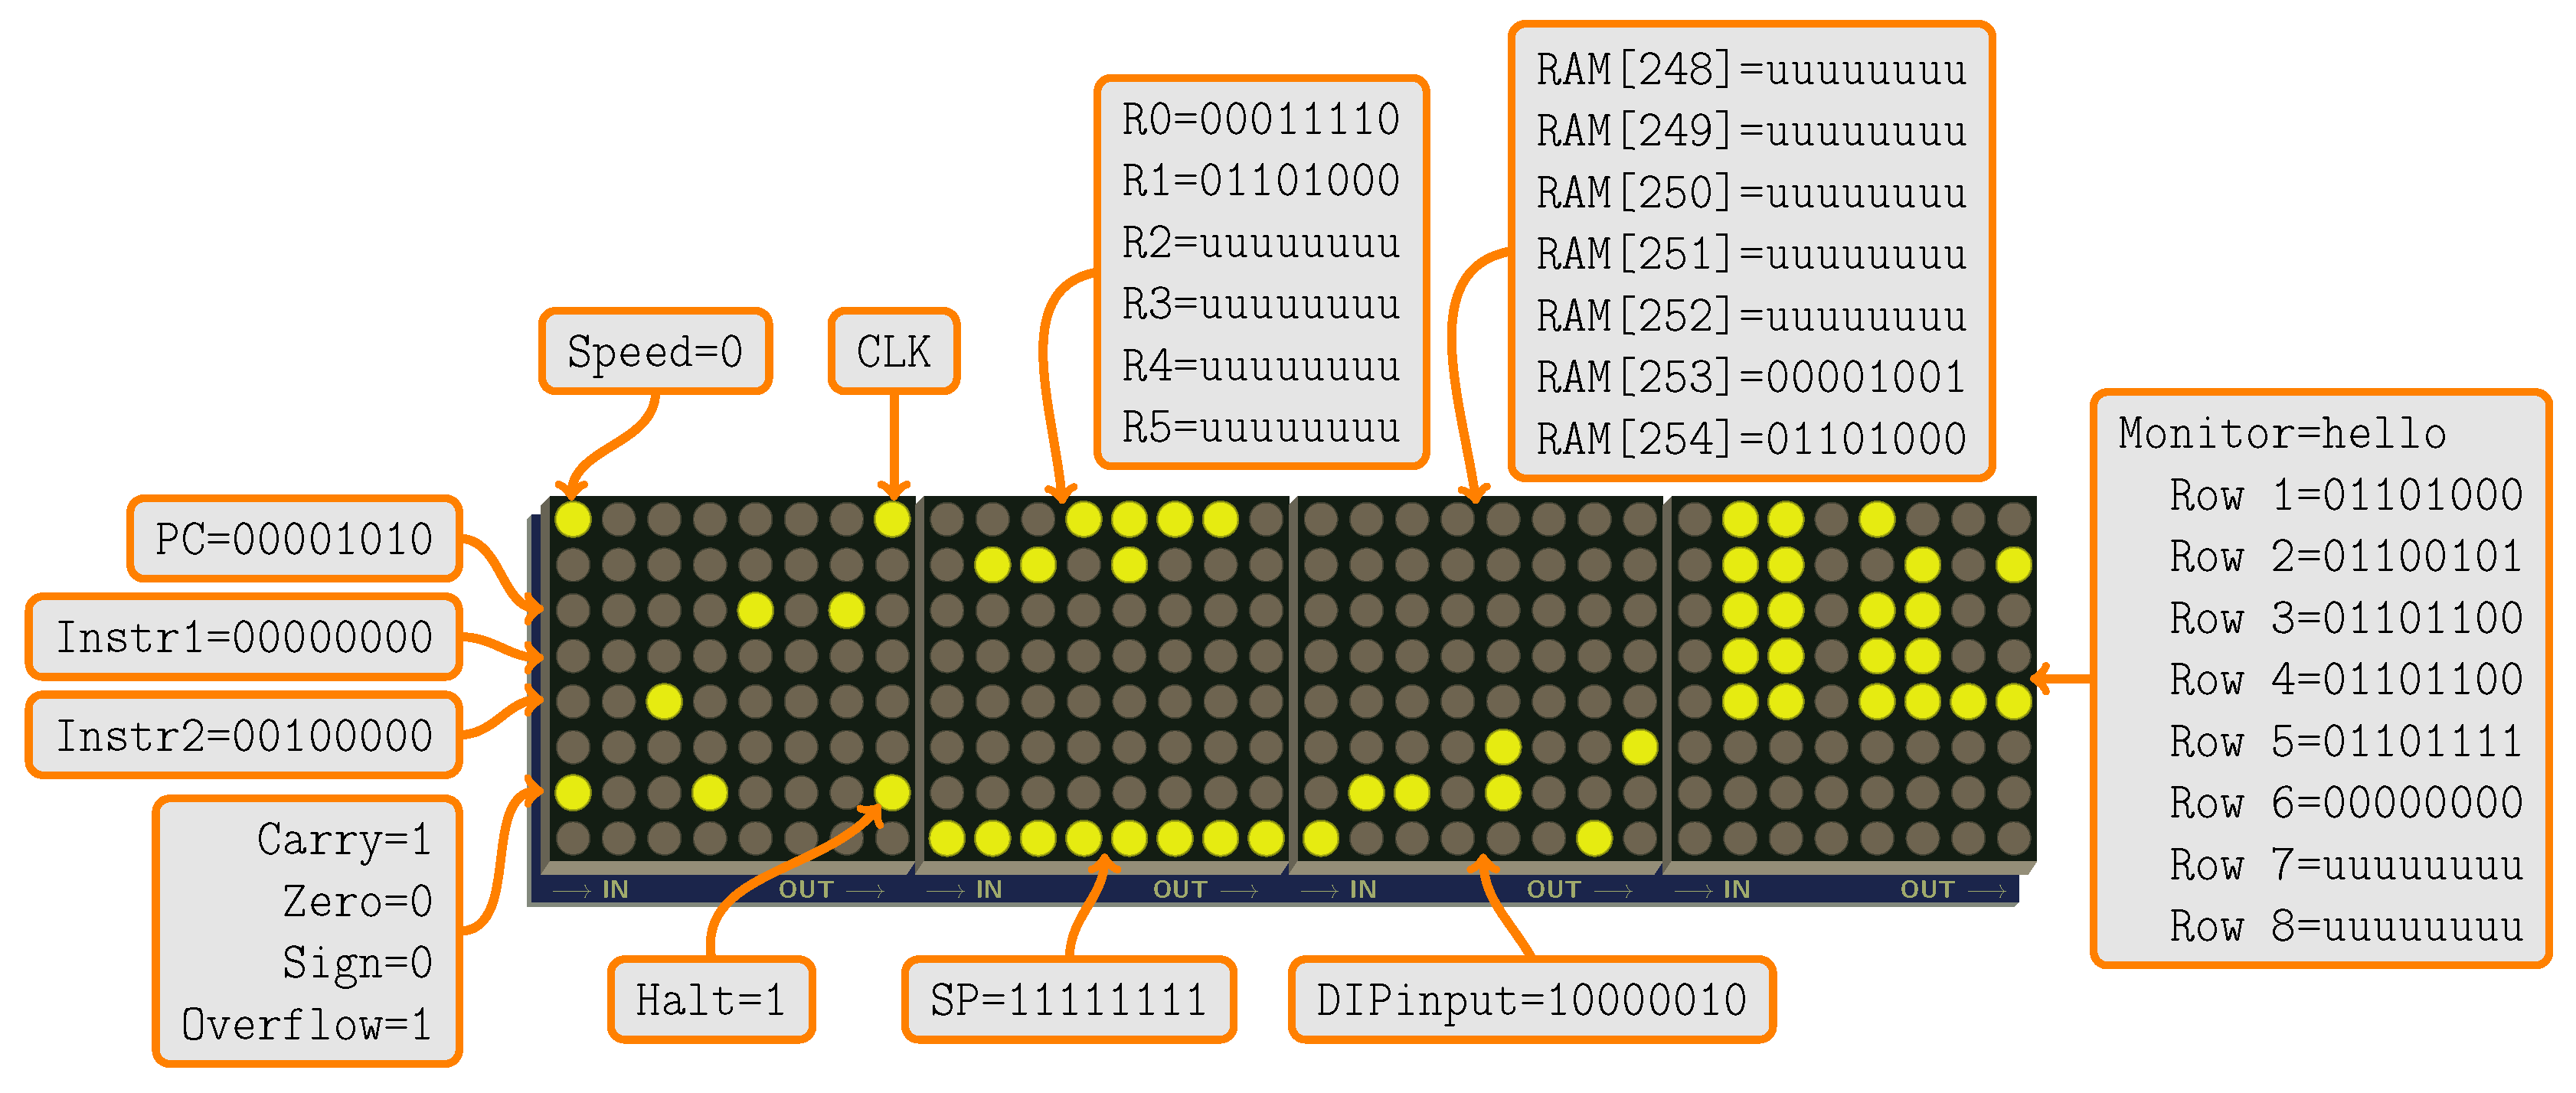
Figure 12.
GHDL and the OSS CAD Suite (Yosys, Nextpnr, OpenFPGALoader) for the GateMateA1, driven by one batch file. The user connected the cable before step 5.
Figure 12.
GHDL and the OSS CAD Suite (Yosys, Nextpnr, OpenFPGALoader) for the GateMateA1, driven by one batch file. The user connected the cable before step 5.
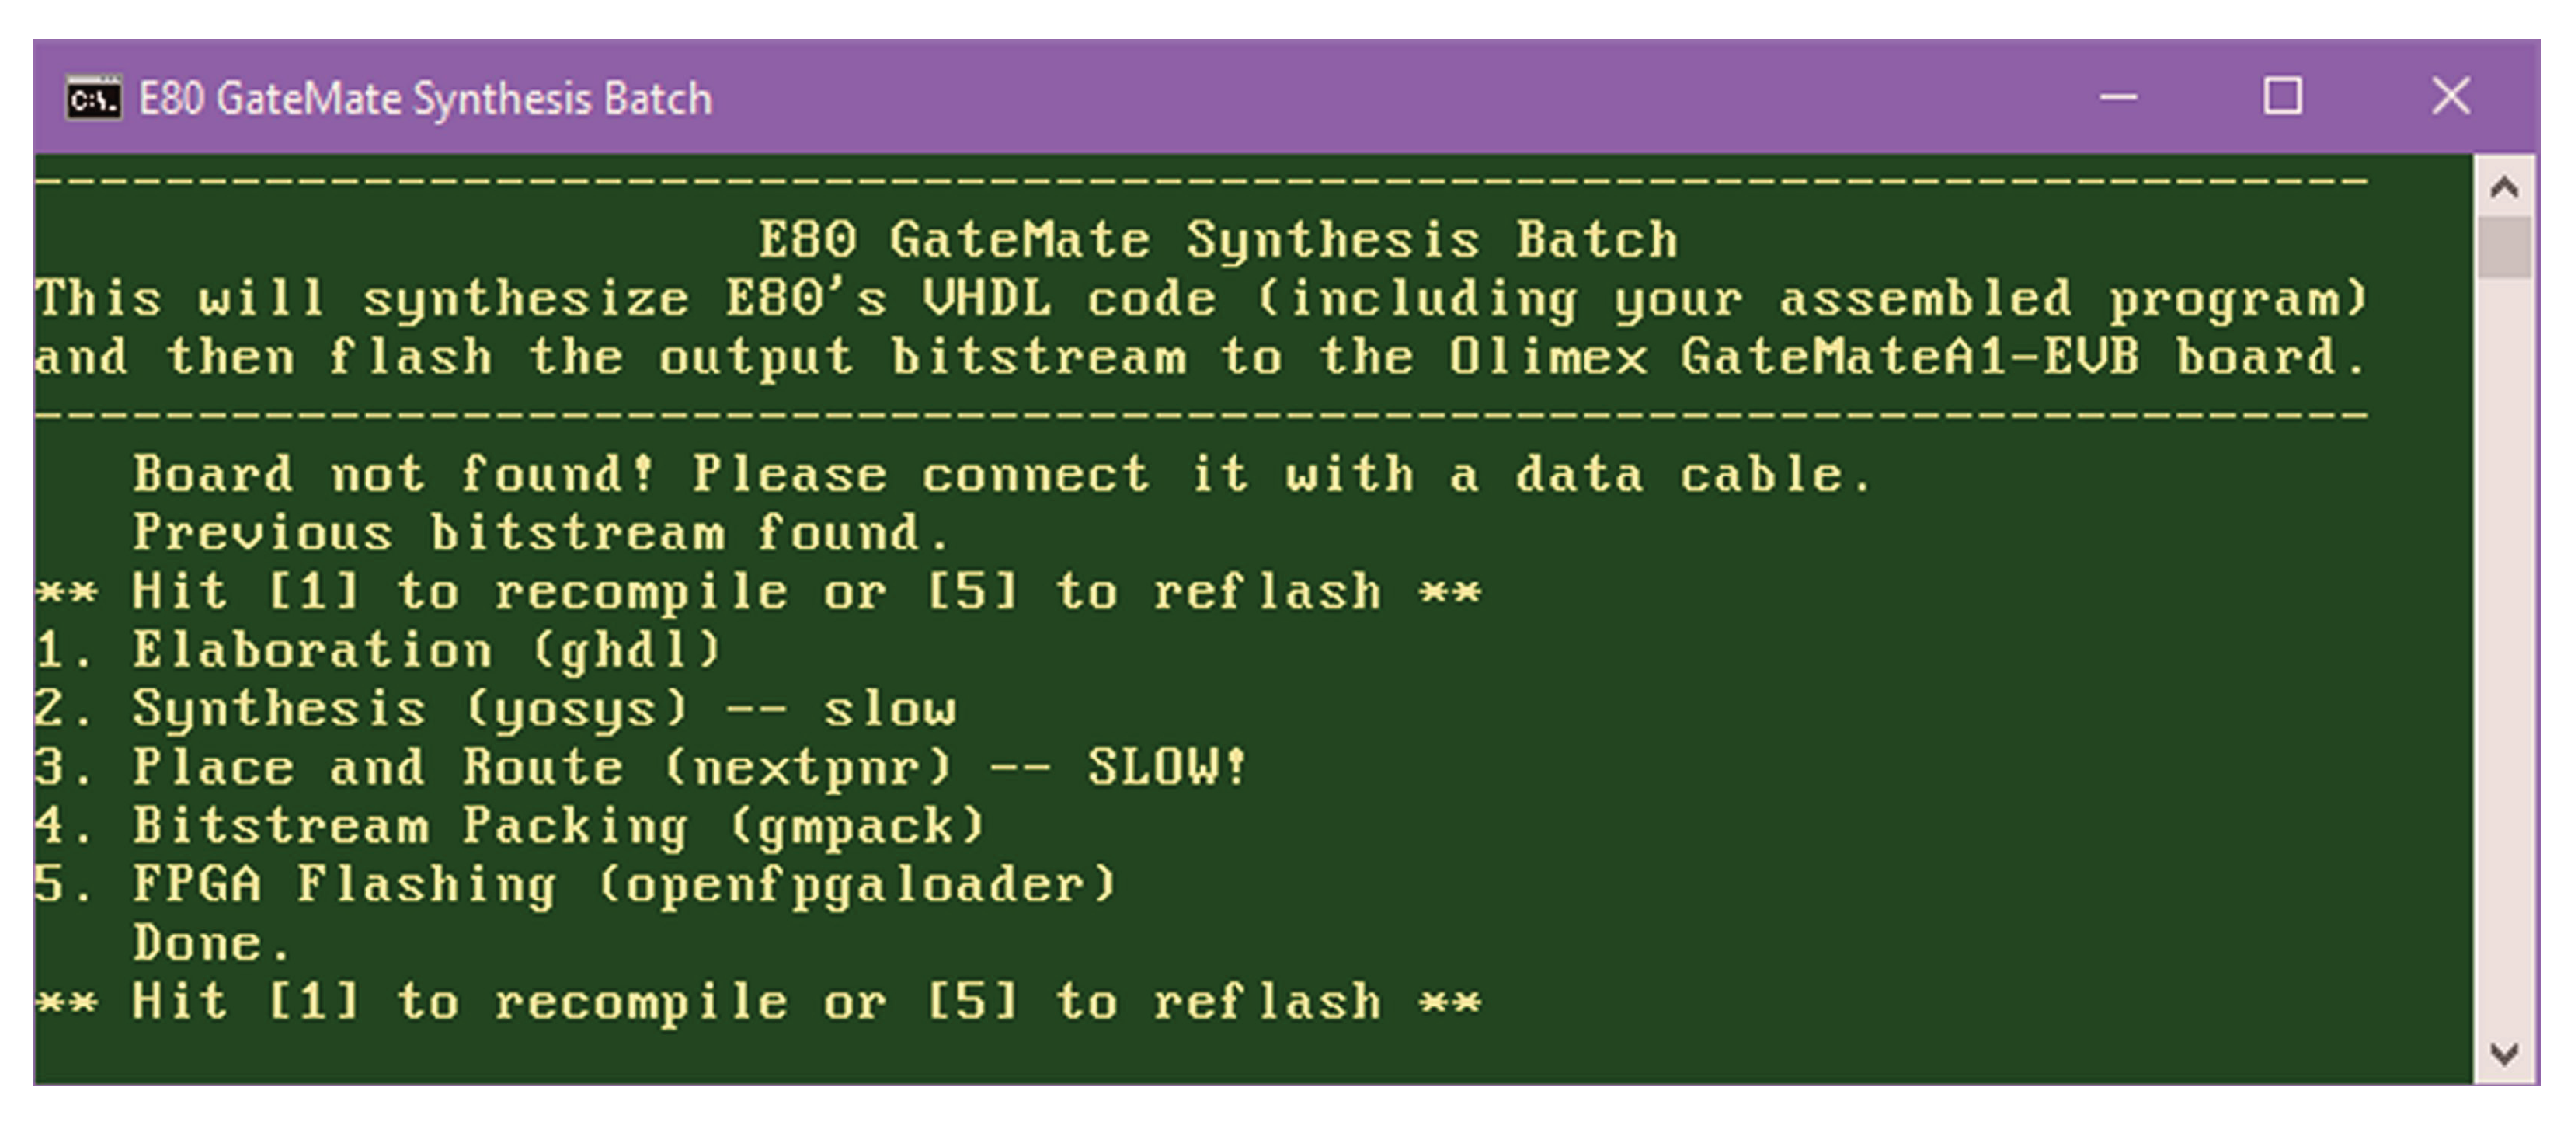
Figure 13.
The E80 running on the GateMateA1, driving the four MAX7219 matrices over three signal lines. The joystick provides step execution, pause, reset and speed control. UP, DWN and MID are not connected, as explained in Section 2.8. Following the non-deterministic nature of hardware, undefined bits here are set to ones unlike in Figure 11 where they were set to zeros.
Figure 13.
The E80 running on the GateMateA1, driving the four MAX7219 matrices over three signal lines. The joystick provides step execution, pause, reset and speed control. UP, DWN and MID are not connected, as explained in Section 2.8. Following the non-deterministic nature of hardware, undefined bits here are set to ones unlike in Figure 11 where they were set to zeros.
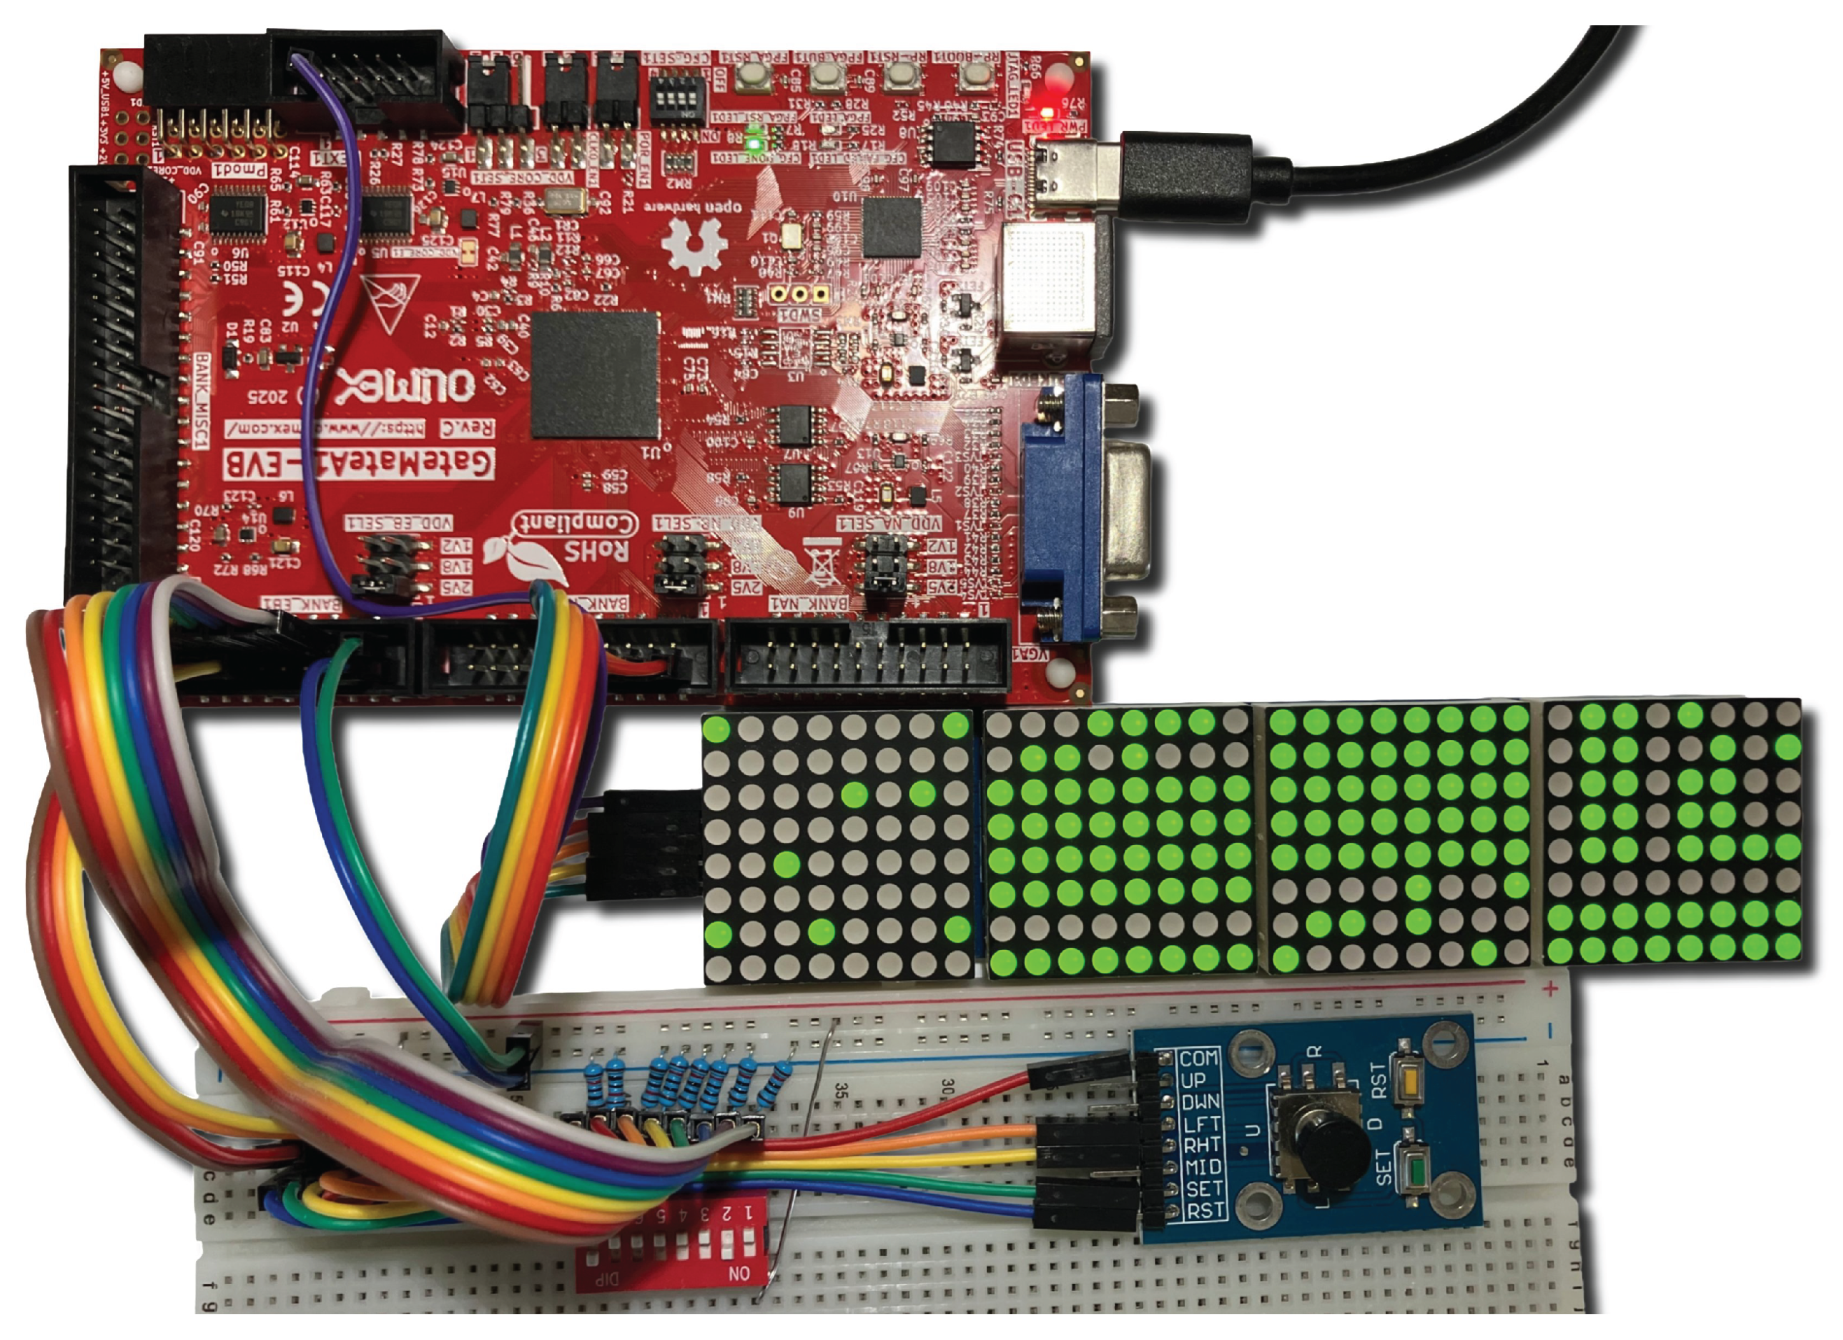
Figure 14.
Maximum clock frequency before and after removing the combinational loop, for each board and toolchain. The open GateMate and Gowin flows, which had reported or been forced past the loop, gain about 4.6× and 3.5×; the Quartus flow, which had already tolerated the false path, is essentially unchanged.
Figure 14.
Maximum clock frequency before and after removing the combinational loop, for each board and toolchain. The open GateMate and Gowin flows, which had reported or been forced past the loop, gain about 4.6× and 3.5×; the Quartus flow, which had already tolerated the false path, is essentially unchanged.
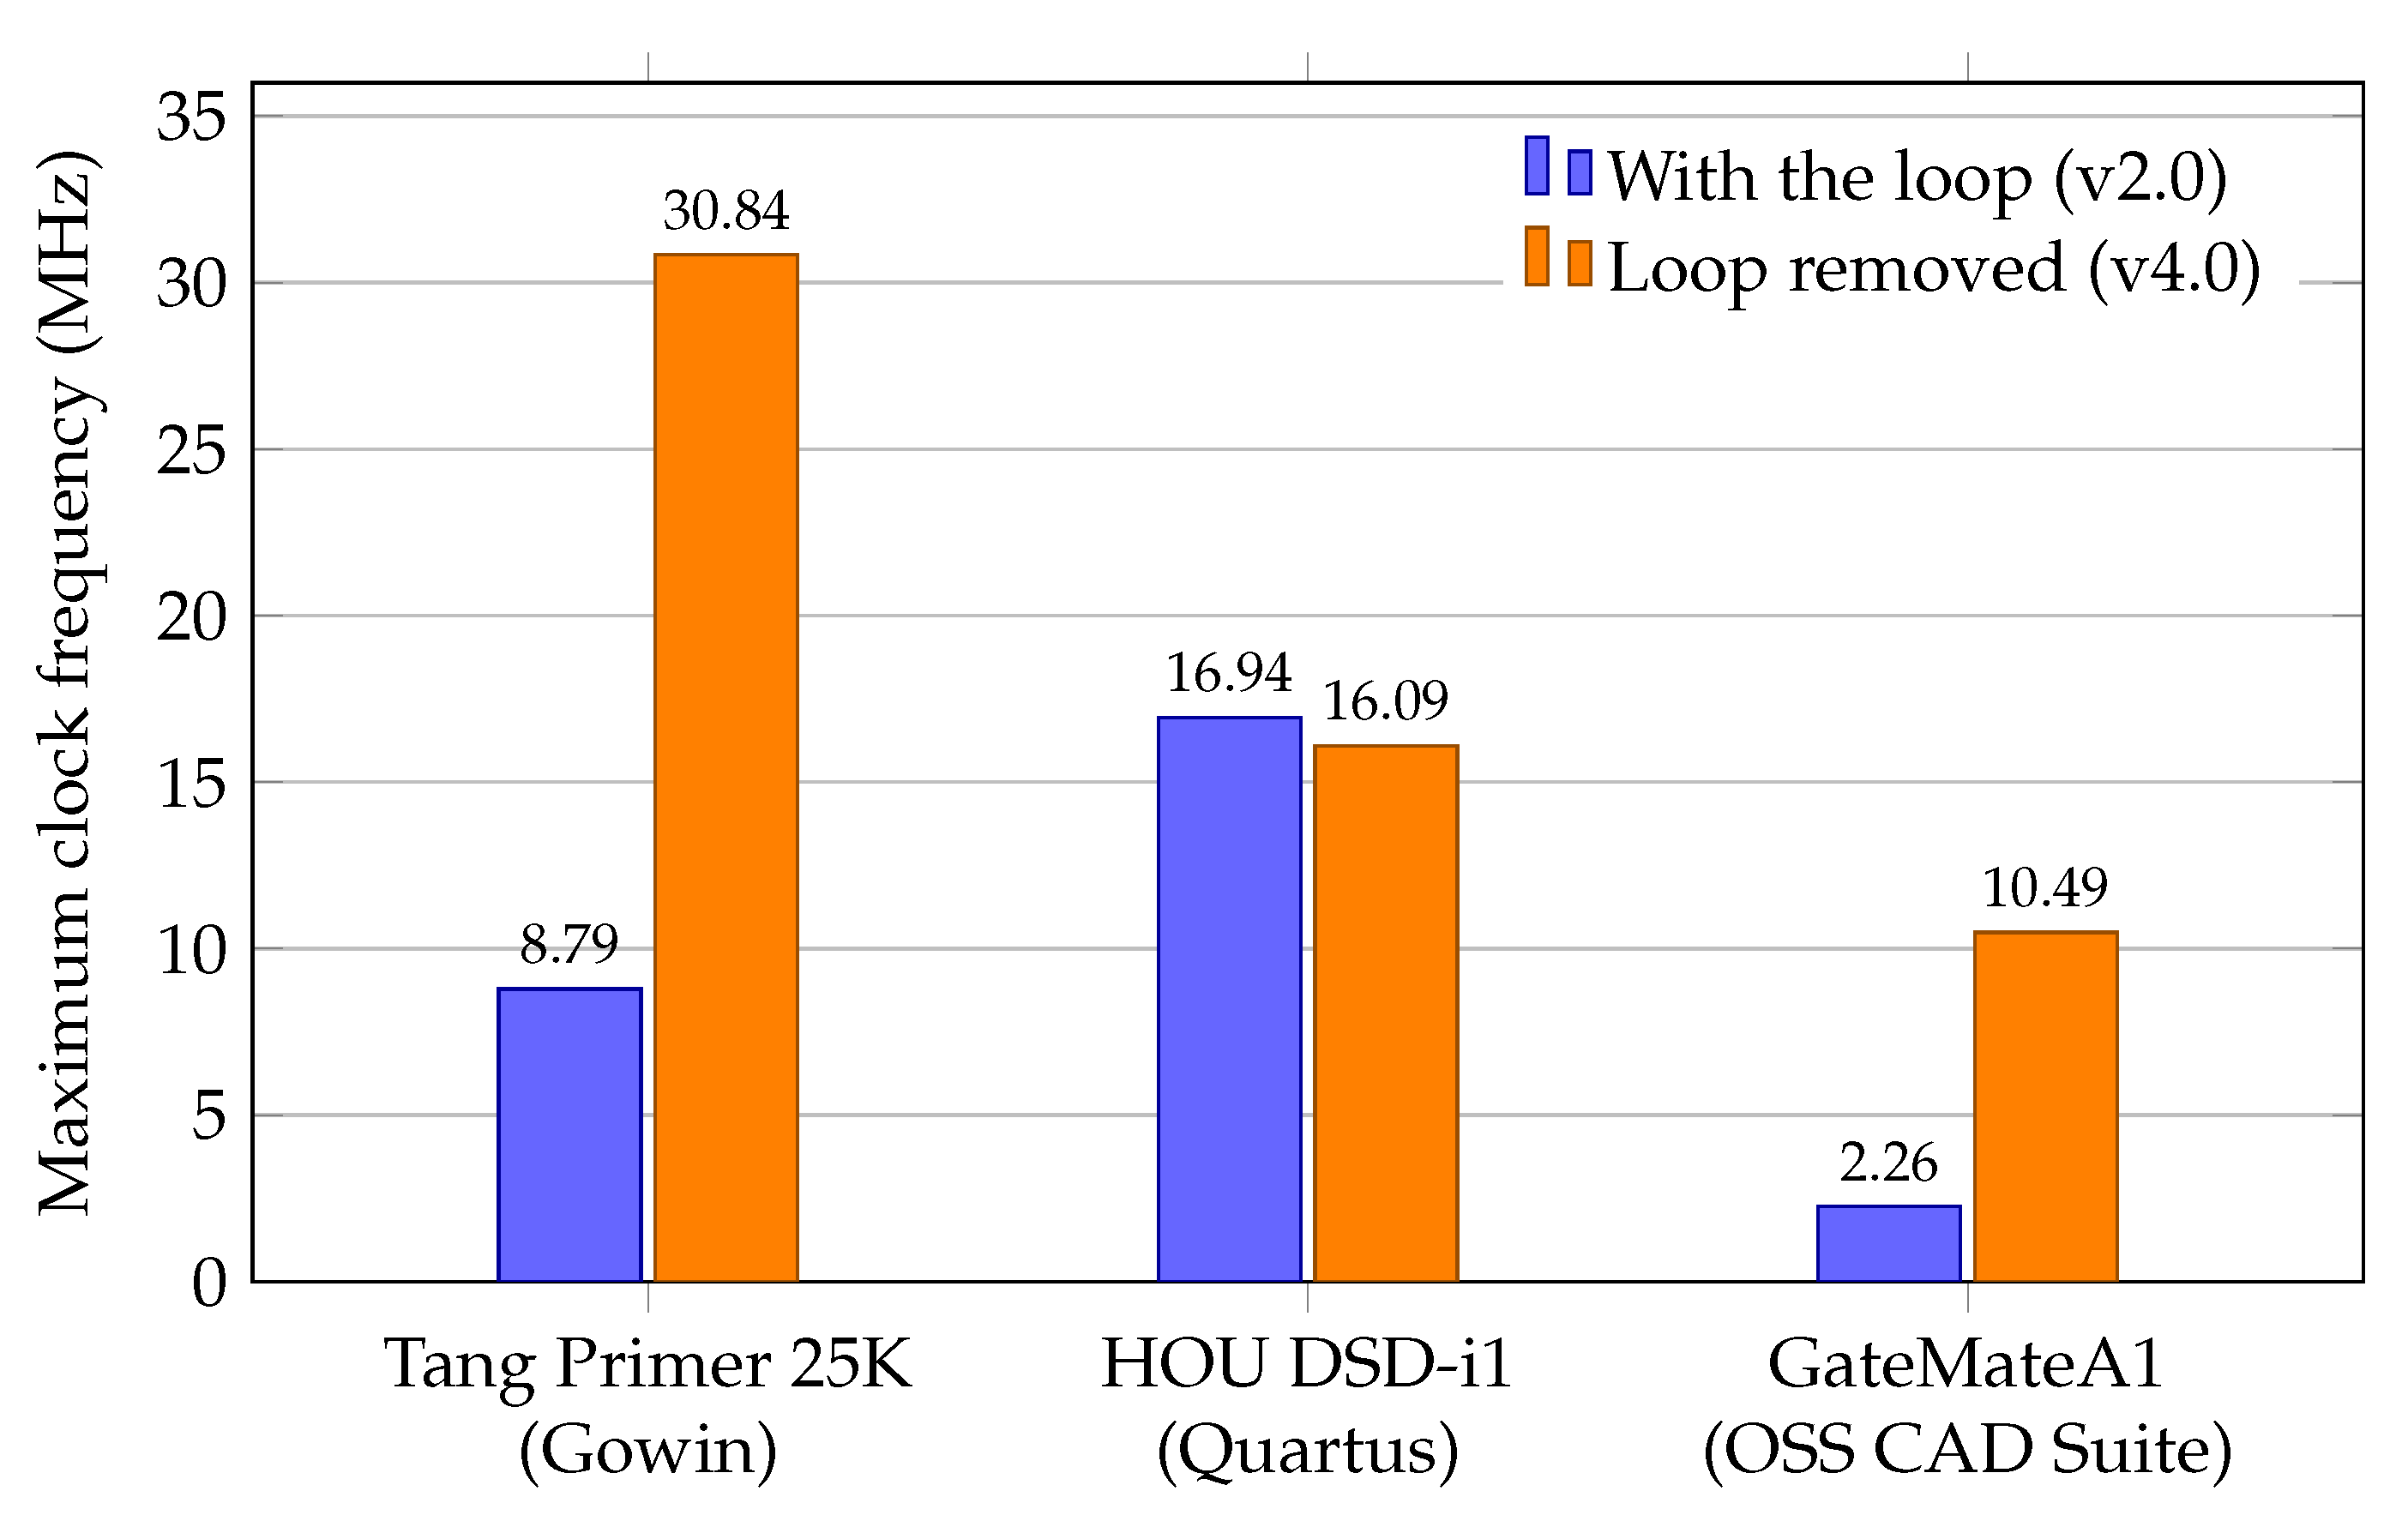
Figure 15.
LED matrix displaying the execution of an empty program. Everything was set to undefined except for the PC, the Halt flag and the SP. Undefined was translated as 0xFF, so every instruction was decoded as 0xFFFF, resulting in the SP being increased by 1 on every cycle. This fill is not specified by the design: a subsequent reset, or a rerun of the same bitstream, initializes undefined memory to different values.
Figure 15.
LED matrix displaying the execution of an empty program. Everything was set to undefined except for the PC, the Halt flag and the SP. Undefined was translated as 0xFF, so every instruction was decoded as 0xFFFF, resulting in the SP being increased by 1 on every cycle. This fill is not specified by the design: a subsequent reset, or a rerun of the same bitstream, initializes undefined memory to different values.
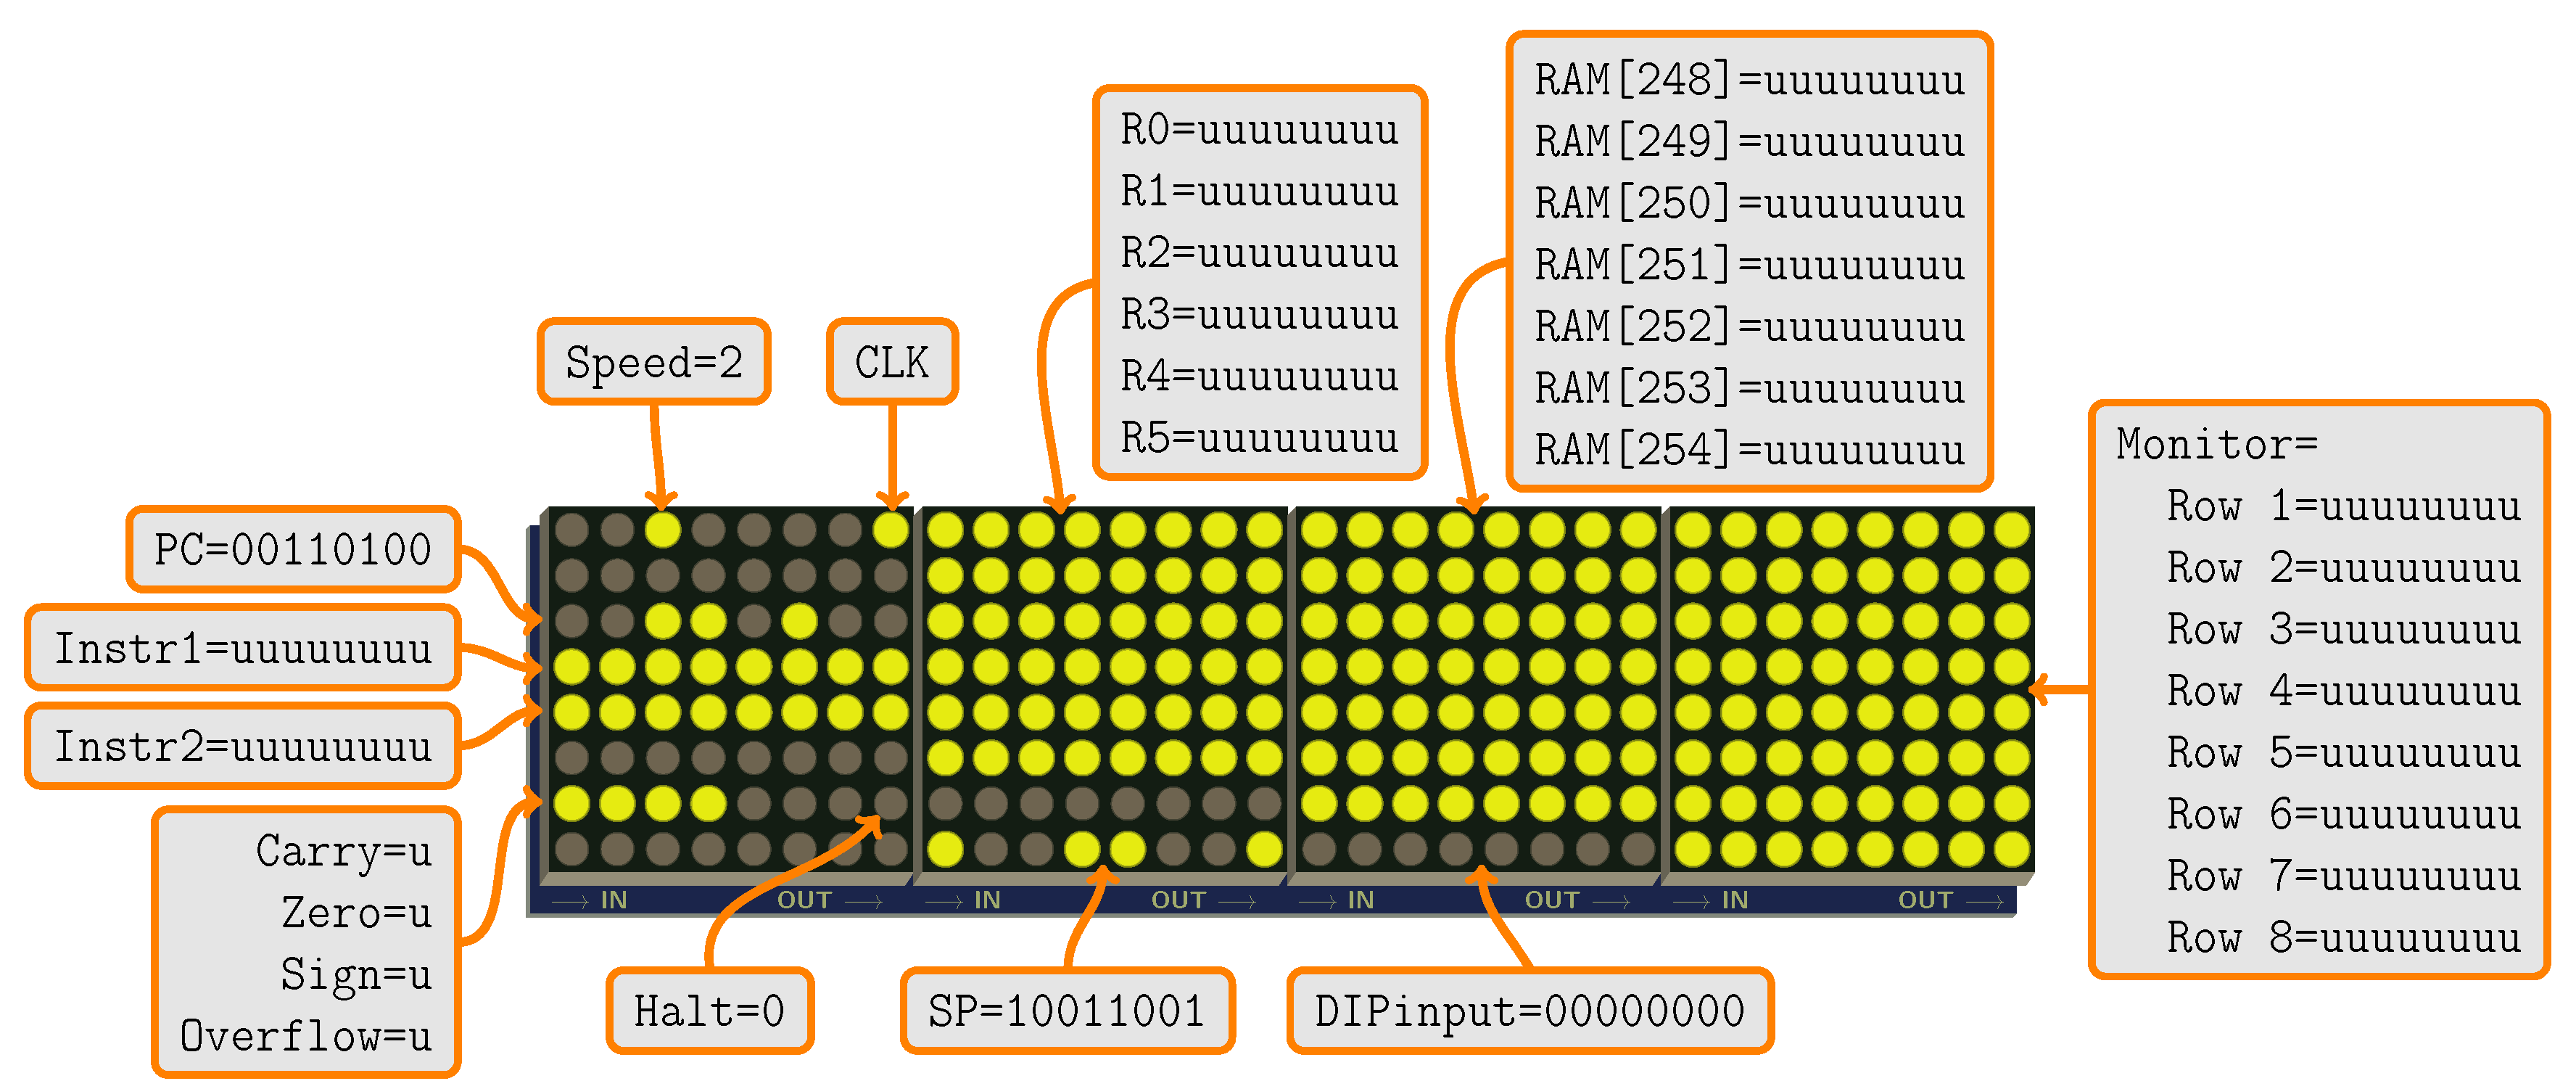
Figure 16.
PostScript output from GTKWave showing the closing cycles of the ISA Compliance Suite. The recursion unwinds with the program counter held at address 225—the same RETURN executing four times over—while the stack empties. The final POP forces an underflow, returning the DIP-mapped word; the run then sets the Halt flag, and the following instruction (a NOP) is fetched.
Figure 16.
PostScript output from GTKWave showing the closing cycles of the ISA Compliance Suite. The recursion unwinds with the program counter held at address 225—the same RETURN executing four times over—while the stack empties. The final POP forces an underflow, returning the DIP-mapped word; the run then sets the Halt flag, and the following instruction (a NOP) is fetched.
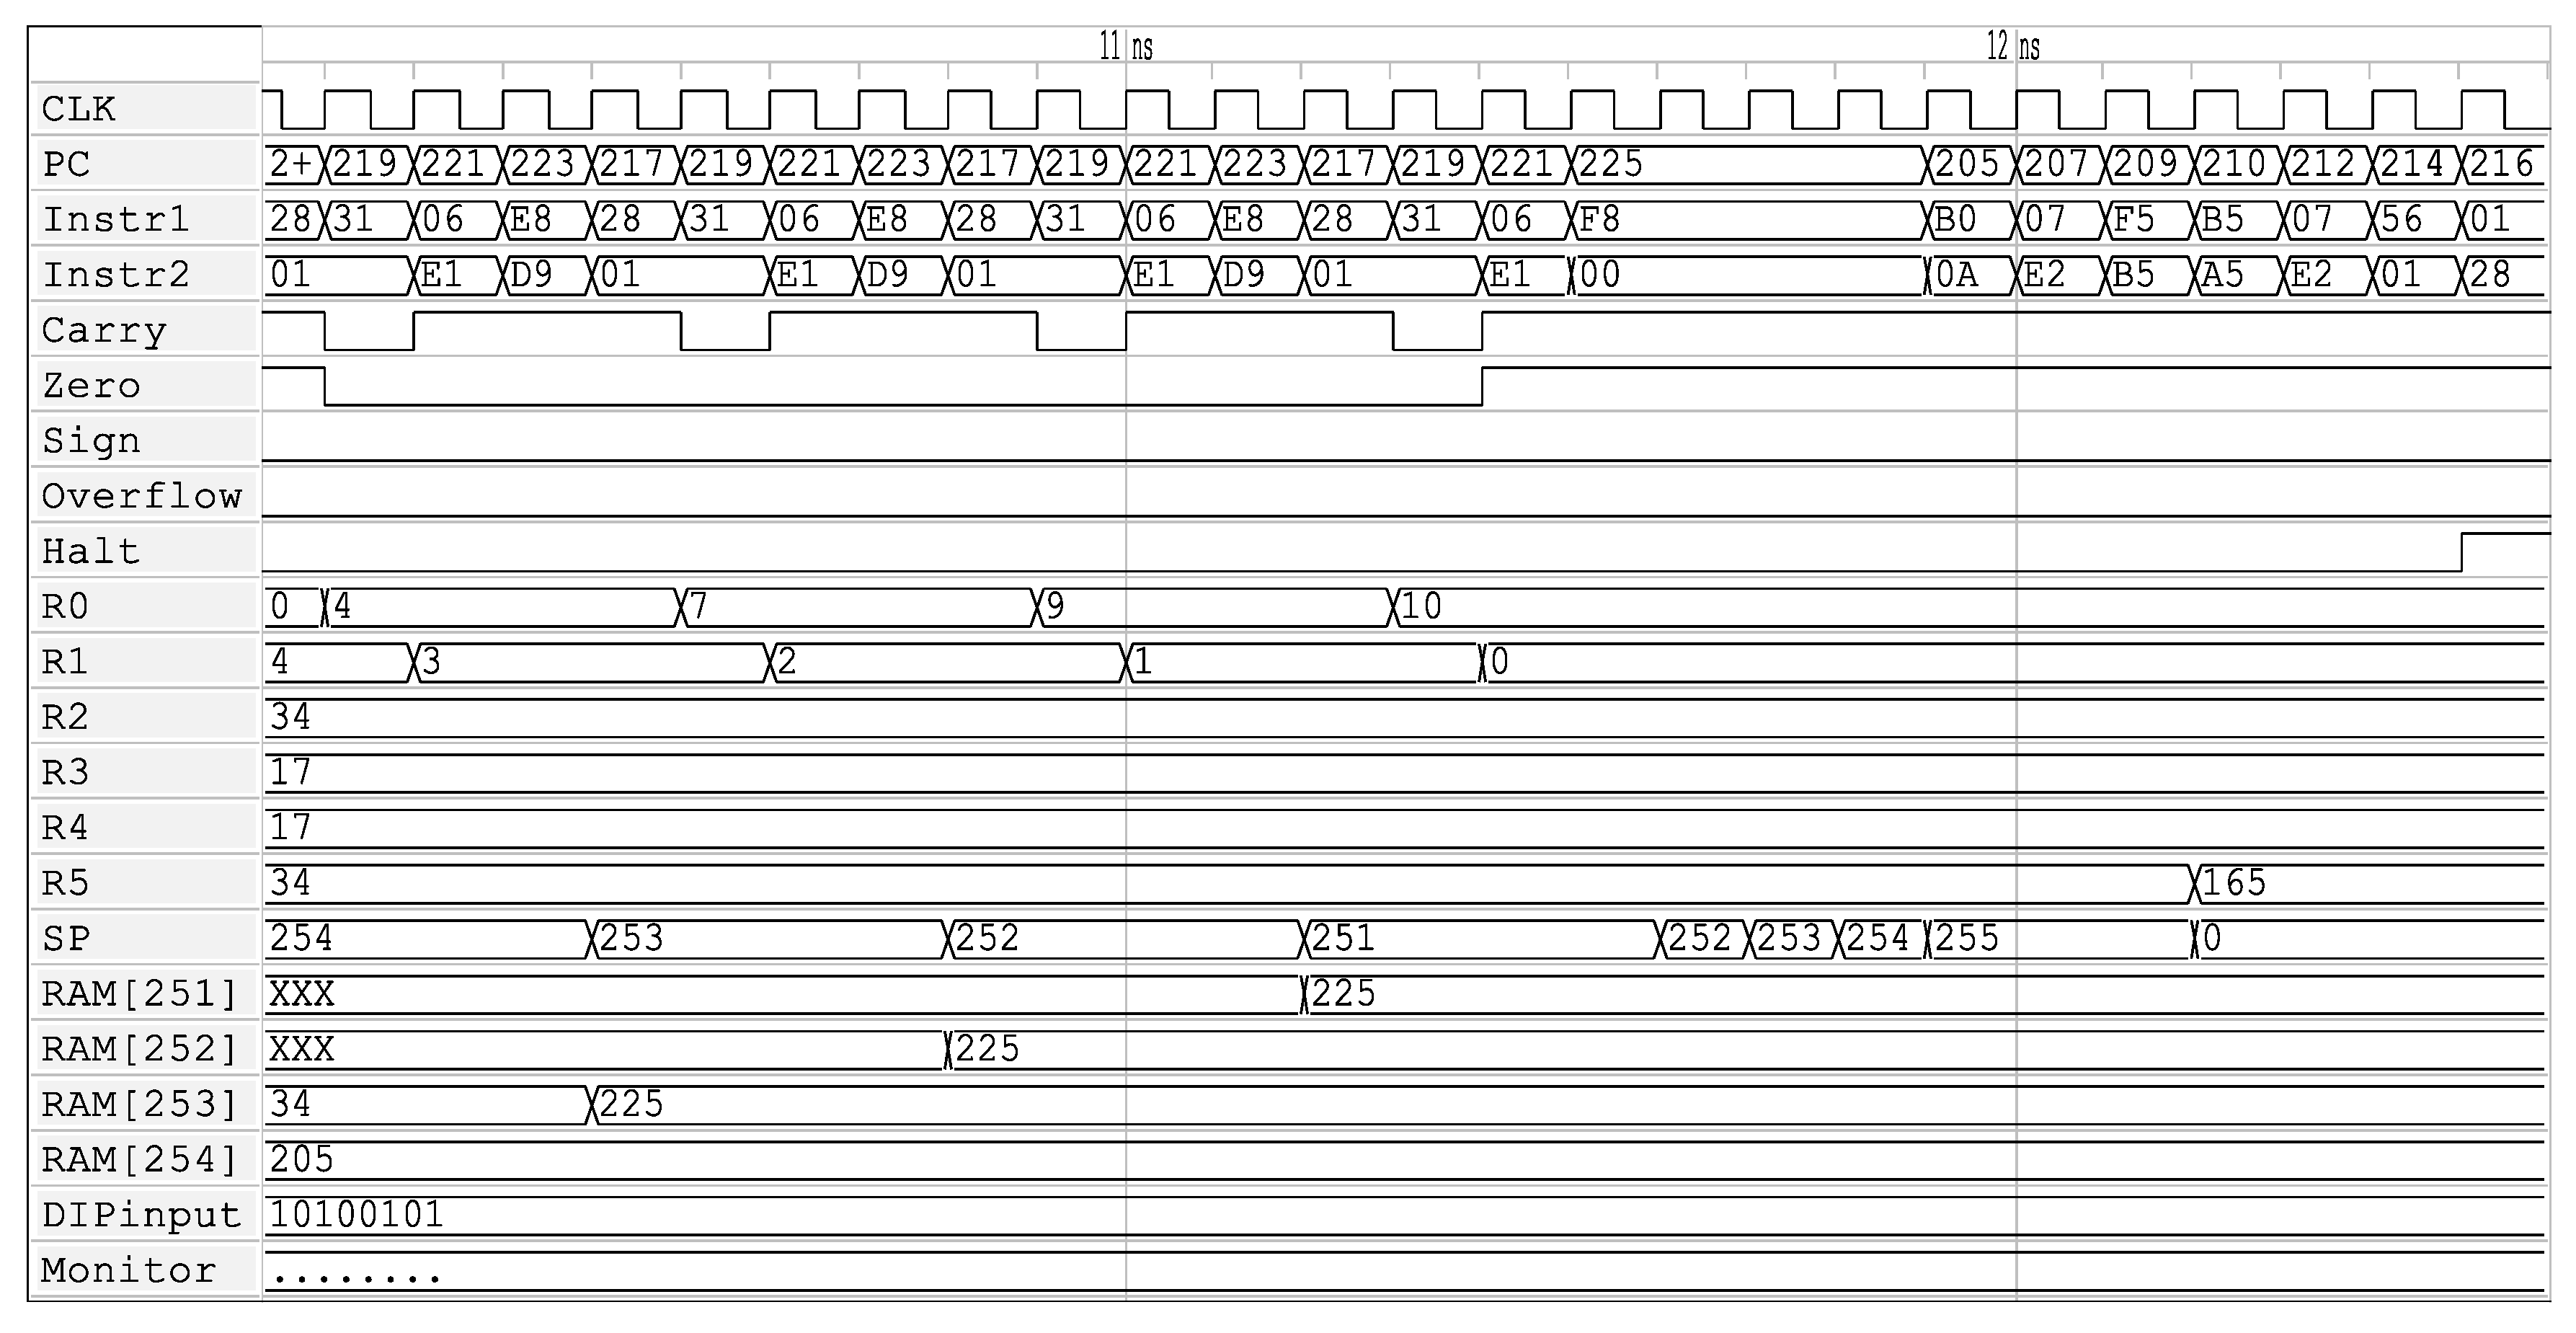
Figure 17.
Successful completion of fibonacci.e80asm with on the DIP switches, matching the .SIMDIP preset. The 13,179-cycle run is set to .SPEED 6 (∼4 kHz) to finish in seconds rather than minutes. The monitored words are the remains of the activation records left on the single stack, following Dijkstra’s [61] calling method, with returned to R0.
Figure 17.
Successful completion of fibonacci.e80asm with on the DIP switches, matching the .SIMDIP preset. The 13,179-cycle run is set to .SPEED 6 (∼4 kHz) to finish in seconds rather than minutes. The monitored words are the remains of the activation records left on the single stack, following Dijkstra’s [61] calling method, with returned to R0.
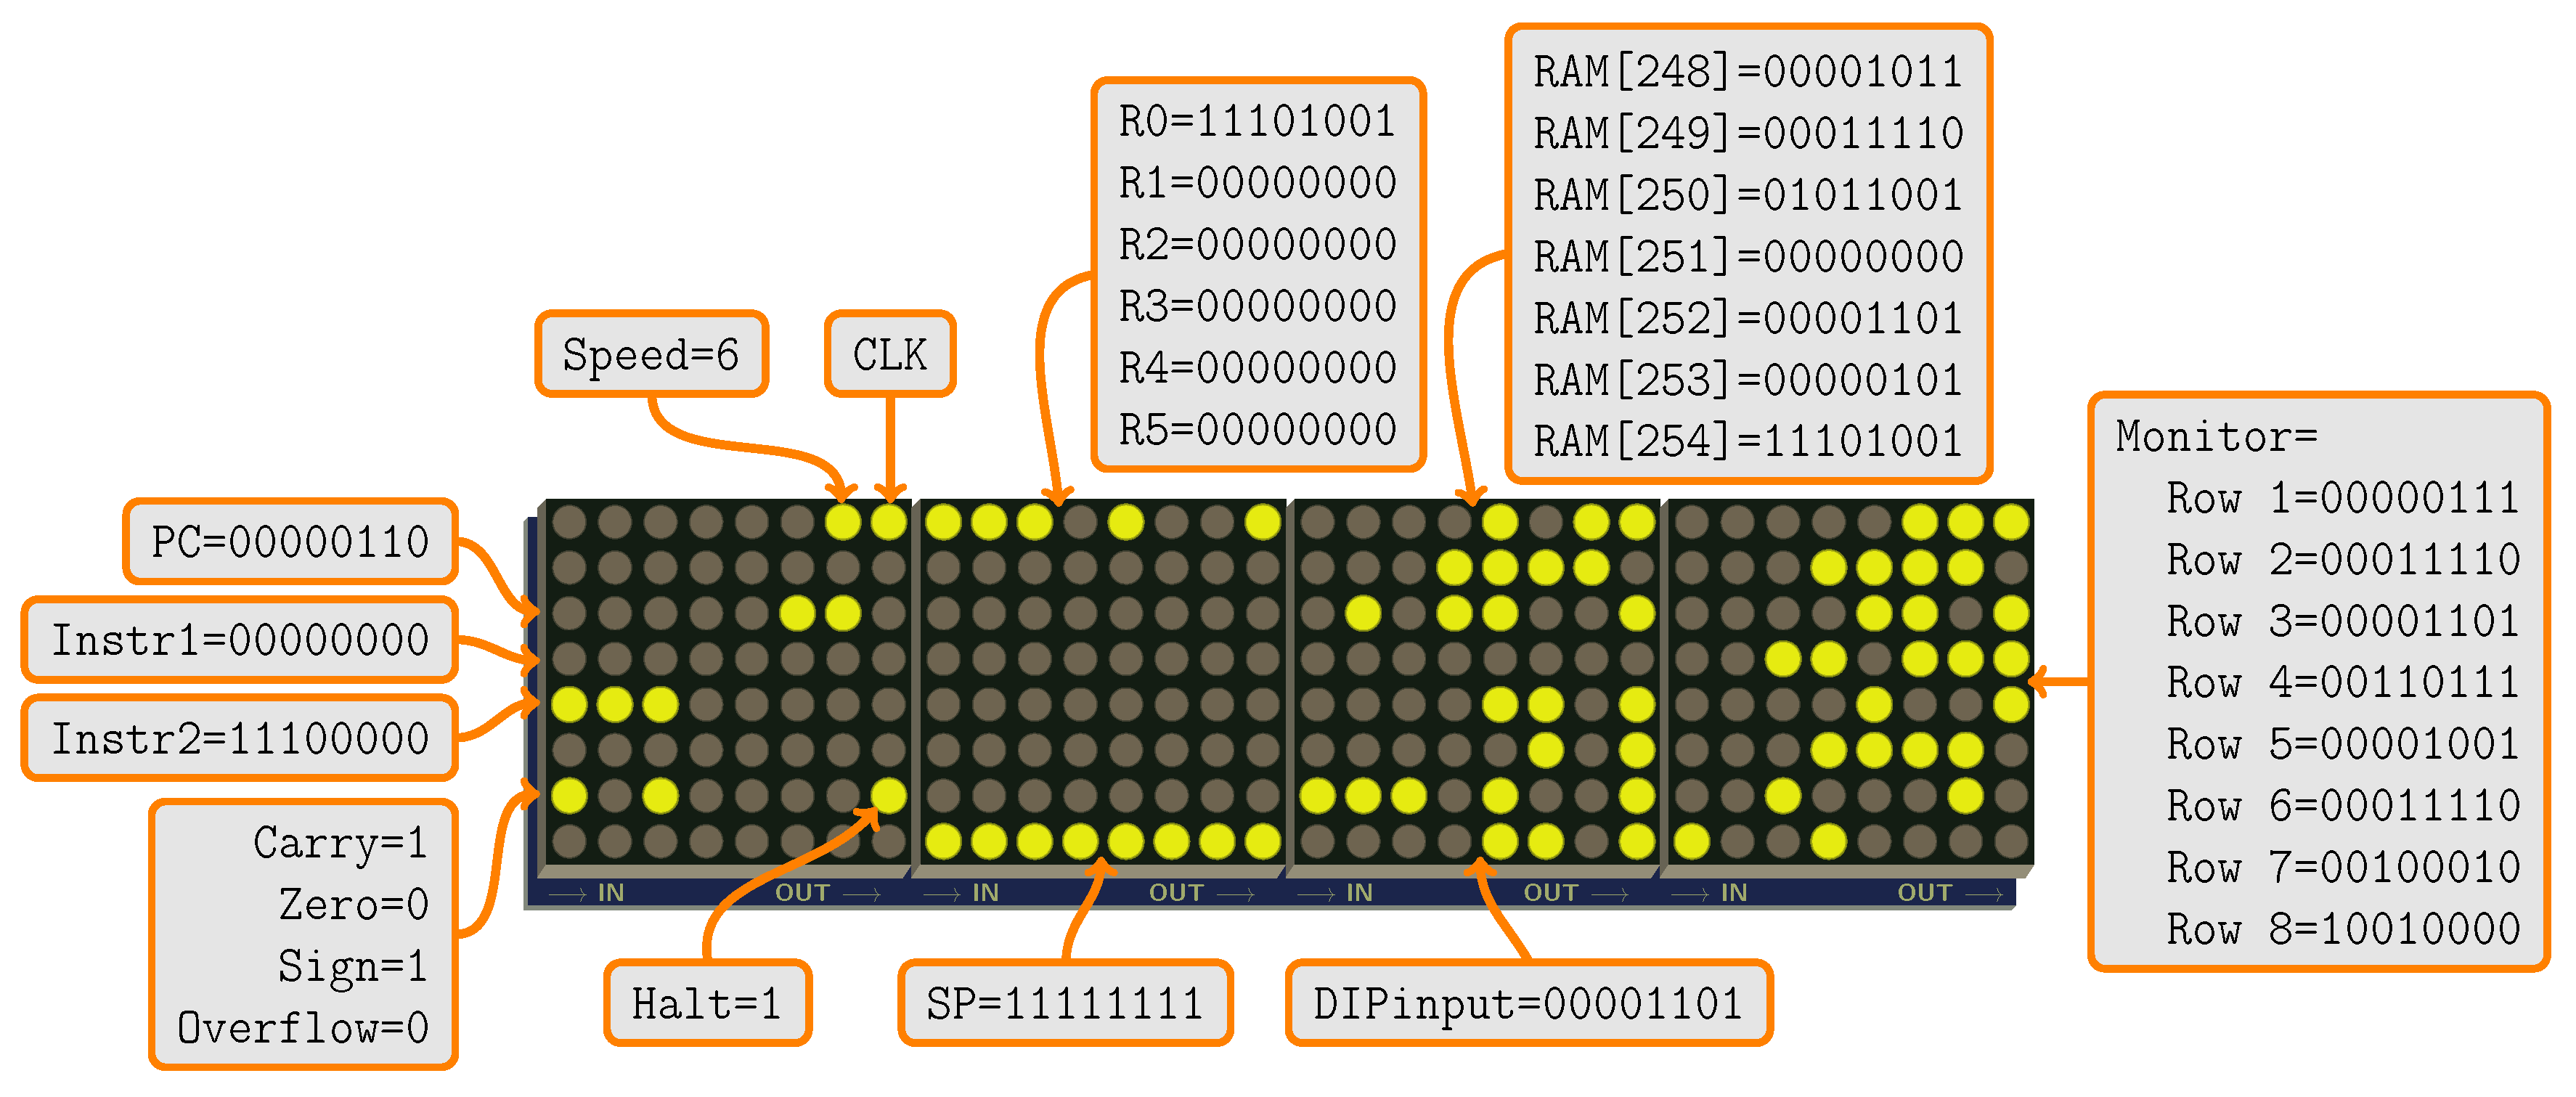
Figure 18.
The search on the original maze (a) and on the harder one of LC3maze.e80asm (b), both starting at cell 0 and ending at the arrowhead. Attempts to move onto a breadcrumb are not drawn, but they appear on the first address of the .MONITOR block.
Figure 18.
The search on the original maze (a) and on the harder one of LC3maze.e80asm (b), both starting at cell 0 and ending at the arrowhead. Attempts to move onto a breadcrumb are not drawn, but they appear on the first address of the .MONITOR block.
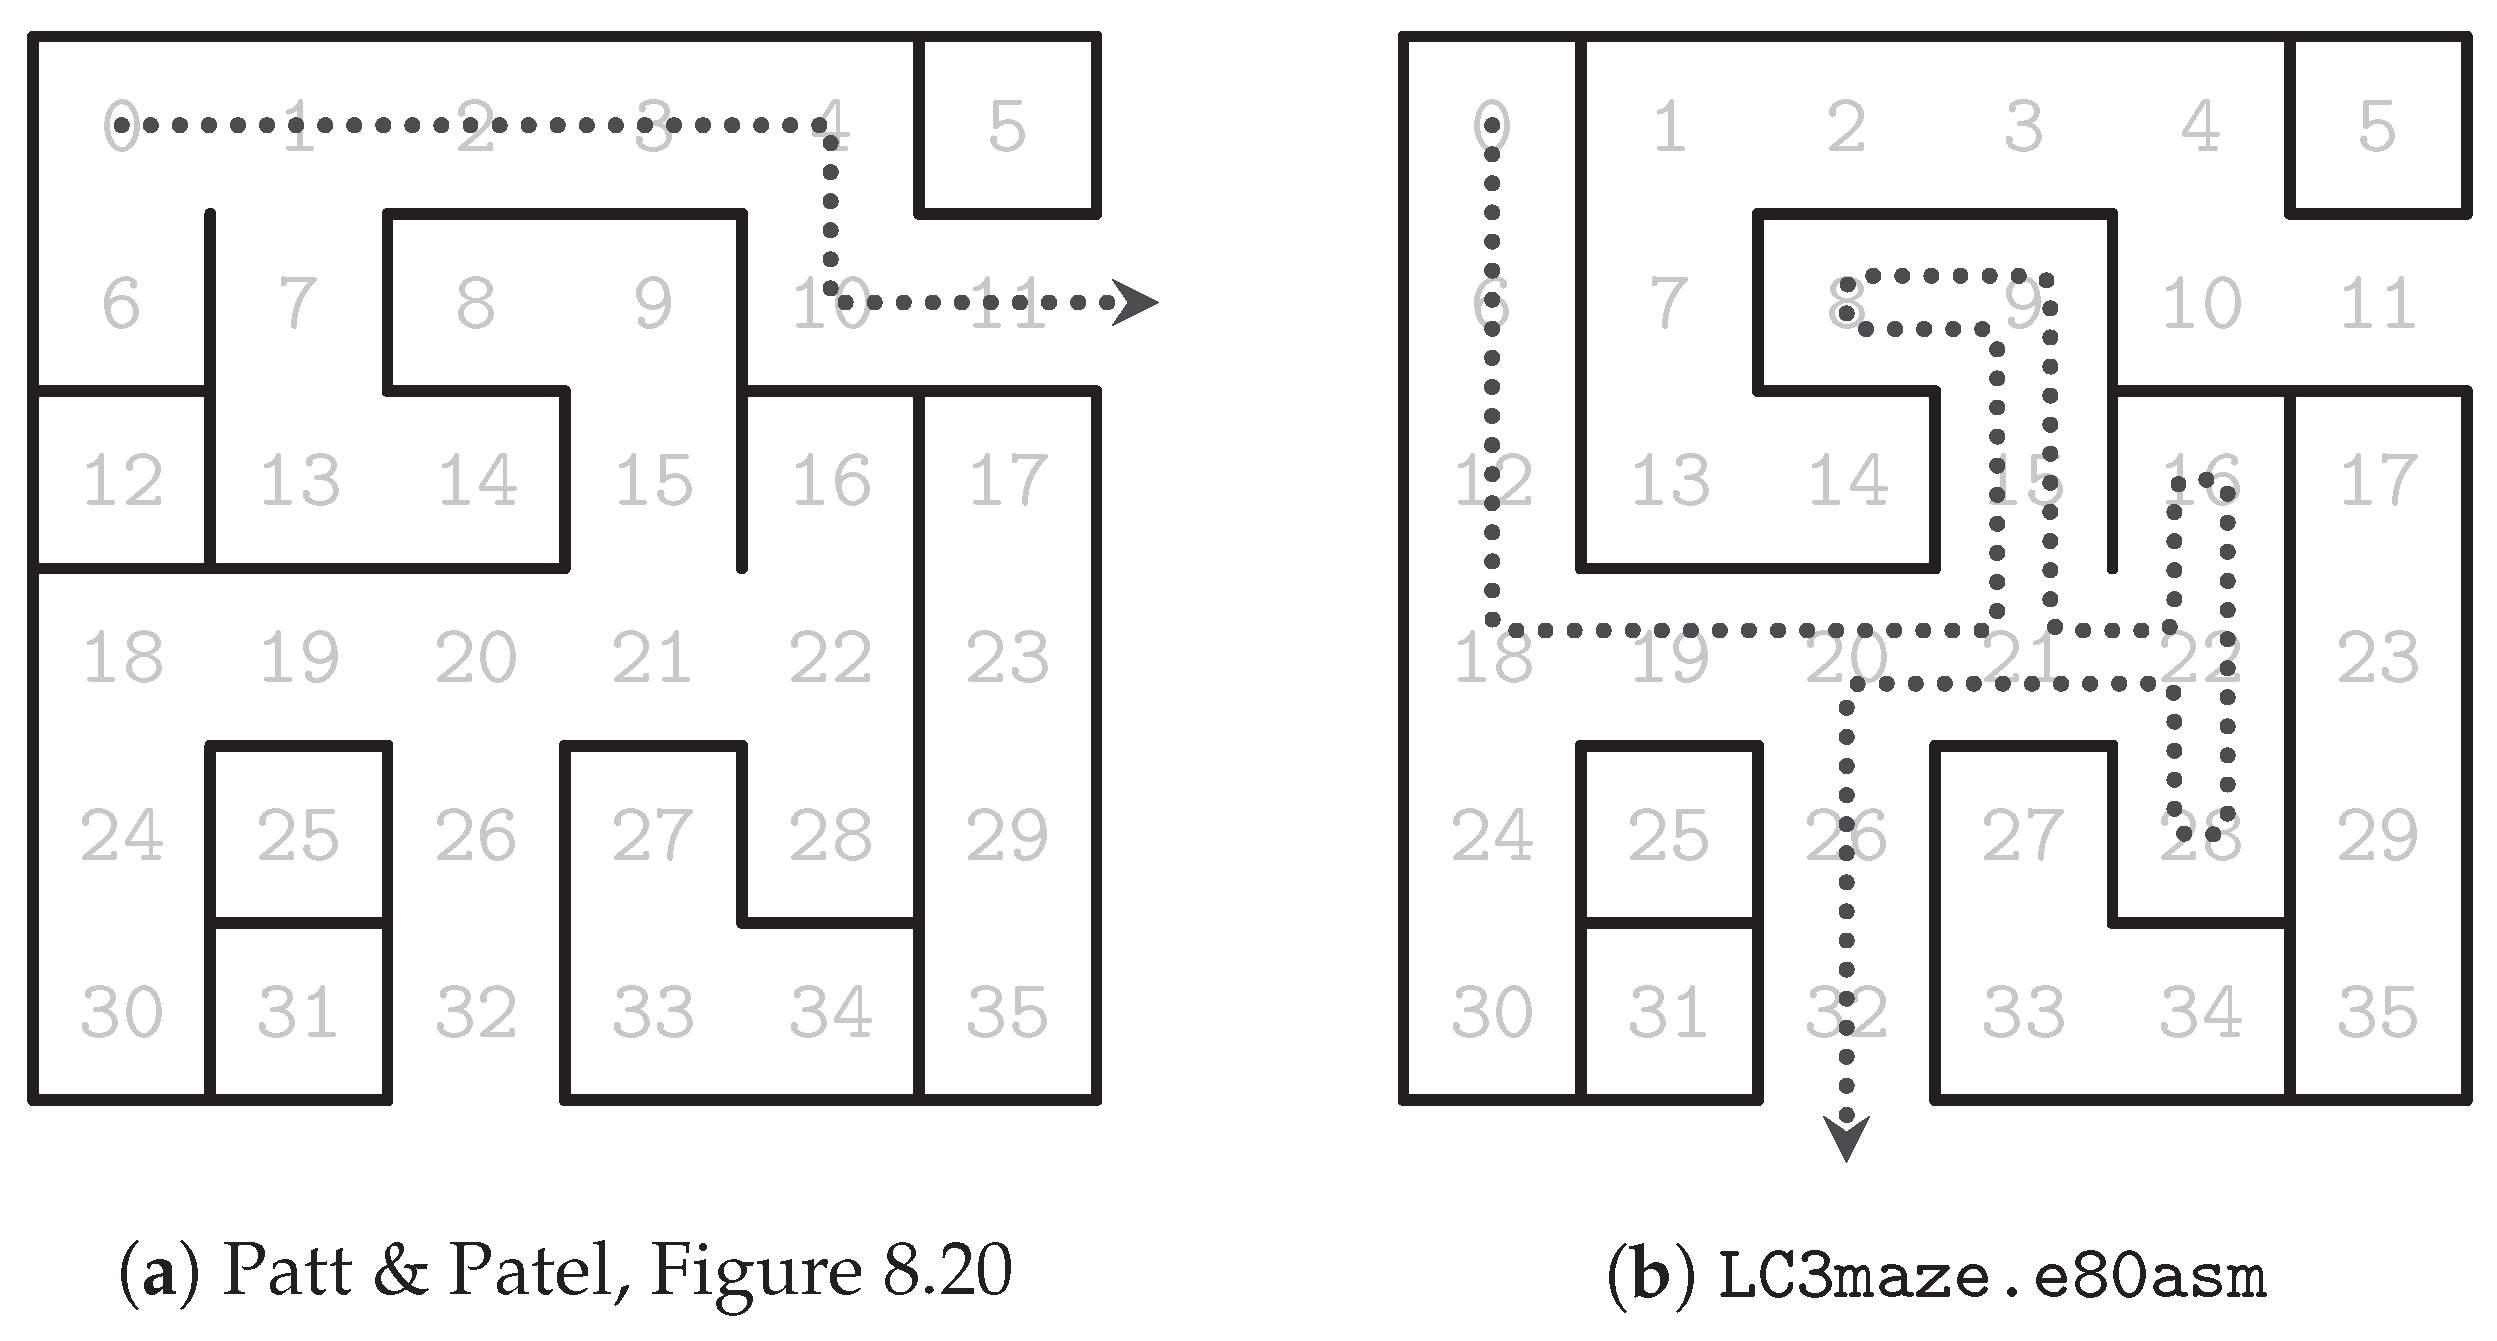
Table 2.
The surveyed material. Sources built from worked examples or exercises are counted by document frequency, so a category is tallied once per sample however often it recurs inside it; the two tutorial sources present one instruction at a time rather than in programs, and are tallied by distinct instance shown, which is why no sample count is given for them.
Table 2.
The surveyed material. Sources built from worked examples or exercises are counted by document frequency, so a category is tallied once per sample however often it recurs inside it; the two tutorial sources present one instruction at a time rather than in programs, and are tallied by distinct instance shown, which is why no sample count is given for them.
| Source | Material | Samples | Tallies |
|---|---|---|---|
| Patt and Patel, LC-3 [4] | Textbook | 124 | 758 |
| HOU, PLI21 Microprocessors [47] | Exercises | 70 | 637 |
| Harvard CS61 [48] | Course | 63 | 469 |
| HOU, PLI21 Computer Architecture [49] | Exercises | 58 | 295 |
| Nikolos, Architecture Exercises [50] | Exercises | 31 | 158 |
| Maryland CMSC 430 [51] | Course | 25 | 119 |
| Carati, 8086 tutorial [52] | Tutorial | — | 189 |
| HOU, PLI10 MIPS Assembly [53] | Course | — | 79 |
| Total | 371 | 2704 |
Table 3.
Operations recorded in the survey, ranked by normalized frequency. Percentages are the unweighted mean of the eight per-source shares. The last column marks the decision to support an operation in hardware without workarounds or macros.
Table 3.
Operations recorded in the survey, ranked by normalized frequency. Percentages are the unweighted mean of the eight per-source shares. The last column marks the decision to support an operation in hardware without workarounds or macros.
| Operation | Frequency (%) | Support |
|---|---|---|
| Addition | 11.71 | ✓ |
| Move to register from register or immediate | 10.86 | ✓ |
| Load to register from memory | 8.60 | ✓ |
| Store to memory from register | 8.11 | ✓ |
| Jump on zero (equal or not equal) | 6.34 | ✓ |
| Return from subroutine | 5.92 | ✓ |
| Subtraction | 4.98 | ✓ |
| Compare (arithmetic, set flags on outcome) | 3.28 | ✓ |
| Unsigned multiplication | 3.14 | |
| Jump (unconditional) | 3.12 | ✓ |
| Jump on signed condition (composite flags check) | 2.67 | |
| AND | 2.57 | ✓ |
| Call subroutine | 2.30 | ✓ |
| Push to / pop from stack and modify the stack pointer | 2.19 | ✓ |
| Halt | 2.08 | ✓ |
| Increment by 1 | 1.95 | |
| Jump on carry | 1.79 | ✓ |
| Unsigned division | 1.76 | |
| Logical shift left/right | 1.51 | ✓ |
| Decrement by 1 | 1.50 | |
| Load/compute effective address into register (LEA) | 1.33 | |
| NOT | 1.23 | |
| XOR | 1.21 | ✓ |
| Load address to register pair | 0.94 | |
| Trap (software interrupt / enter supervisor mode) | 0.91 | |
| Load from memory, addressed by register pair | 0.88 | |
| No operation | 0.74 | ✓ |
| Jump on sign | 0.74 | ✓ |
| Jump on unsigned condition (composite flags check) | 0.66 | |
| OR | 0.66 | ✓ |
| Store to memory, addressed by register pair | 0.65 | |
| Bit test (AND-based, set flags on outcome) | 0.51 | ✓ |
| Rotate left/right | 0.50 | ✓ |
| No taxonomy fit | 0.42 | |
| NAND | 0.40 | |
| Exchange (swap contents) | 0.40 | |
| NOR | 0.36 | |
| Signed arithmetic (including signed multiply and division) | 0.29 | |
| Jump on overflow | 0.26 | ✓ |
| Arithmetic shift (left/right, preserving sign bit) | 0.17 | |
| Return from interrupt | 0.16 | |
| Clear (set destination to 0) | 0.16 | |
| Add with carry | 0.06 |
Table 4.
The E80 instruction set. Instruction types per Figure 2. Operand n is an 8-bit immediate value or direct address; r, r1, r2 are 3-bit register selectors (R0–R7); brackets denote memory data; flags abbreviated as C (carry), Z (zero), S (sign), V (overflow), H (halt).
Table 4.
The E80 instruction set. Instruction types per Figure 2. Operand n is an 8-bit immediate value or direct address; r, r1, r2 are 3-bit register selectors (R0–R7); brackets denote memory data; flags abbreviated as C (carry), Z (zero), S (sign), V (overflow), H (halt).
| Mnemonic | Type | Encoding | Hex | Operation | Flags |
|---|---|---|---|---|---|
| HLT | 1 | 00000000 | 00 | PC ← PC (halt) | H |
| NOP | 1 | 00000001 | 01 | — | — |
| JMP n | 3 | 00000010 nnnnnnnn | 02 nn | PC ← n | — |
| JC n | 3 | 00000100 nnnnnnnn | 04 nn | If C=1 then PC ← n | — |
| JNC n | 3 | 00000101 nnnnnnnn | 05 nn | If C=0 then PC ← n | — |
| JZ n | 3 | 00000110 nnnnnnnn | 06 nn | If Z=1 then PC ← n | — |
| JNZ n | 3 | 00000111 nnnnnnnn | 07 nn | If Z=0 then PC ← n | — |
| JS n | 3 | 00001000 nnnnnnnn | 08 nn | If S=1 then PC ← n | — |
| JNS n | 3 | 00001001 nnnnnnnn | 09 nn | If S=0 then PC ← n | — |
| JV n | 3 | 00001010 nnnnnnnn | 0A nn | If V=1 then PC ← n | — |
| JNV n | 3 | 00001011 nnnnnnnn | 0B nn | If V=0 then PC ← n | — |
| MOV r, n | 5 | 00010rrr nnnnnnnn | 1r nn | r ← n | — |
| MOV r1, r2 | 4 | 00011000 0rrr0rrr | 18 rr | r1 ← r2 | — |
| ADD r, n | 5 | 00100rrr nnnnnnnn | 2r nn | r ← r + n | CZSV |
| ADD r1, r2 | 4 | 00101000 0rrr0rrr | 28 rr | r1 ← r1 + r2 | CZSV |
| SUB r, n | 5 | 00110rrr nnnnnnnn | 3r nn | r ← r + NOT n + 1 | CZSV |
| SUB r1, r2 | 4 | 00111000 0rrr0rrr | 38 rr | r1 ← r1 + NOT r2 + 1 | CZSV |
| AND r, n | 5 | 01000rrr nnnnnnnn | 4r nn | r ← r AND n | ZS |
| AND r1, r2 | 4 | 01001000 0rrr0rrr | 48 rr | r1 ← r1 AND r2 | ZS |
| OR r, n | 5 | 01010rrr nnnnnnnn | 5r nn | r ← r OR n | ZS |
| OR r1, r2 | 4 | 01011000 0rrr0rrr | 58 rr | r1 ← r1 OR r2 | ZS |
| XOR r, n | 5 | 01100rrr nnnnnnnn | 6r nn | r ← r XOR n | ZS |
| XOR r1, r2 | 4 | 01101000 0rrr0rrr | 68 rr | r1 ← r1 XOR r2 | ZS |
| ROR r, n | 5 | 01110rrr nnnnnnnn | 7r nn | Rotate r right by n | ZS |
| ROR r1, r2 | 4 | 01111000 0rrr0rrr | 78 rr | Rotate r1 right by r2 | ZS |
| LSHIFT r | 2 | 10100rrr | Ar | Left shift r by 1 bit, C ← shifted bit, V ← sign flip | CZSV |
| RSHIFT r | 2 | 11010rrr | Dr | Right shift r by 1 bit, C ← shifted bit, V ← sign flip | CZSV |
| CMP r, n | 5 | 10110rrr nnnnnnnn | Br nn | SUB r, n (flags only, discard result) | CZSV |
| CMP r1, r2 | 4 | 10111000 0rrr0rrr | B8 rr | SUB r1, r2 (flags only, discard result) | CZSV |
| BIT r, n | 5 | 11000rrr nnnnnnnn | Cr nn | AND r, n (flags only, discard result) | ZS |
| BIT r1, r2 | 4 | 11001000 0rrr0rrr | C8 rr | AND r1, r2 (flags only, discard result) | ZS |
| STORE r, [n] | 5 | 10000rrr nnnnnnnn | 8r nn | r → [n] | — |
| STORE r1, [r2] | 4 | 10001000 0rrr0rrr | 88 rr | r1 → [r2] | — |
| LOAD r, [n] | 5 | 10010rrr nnnnnnnn | 9r nn | r ← [n] | — |
| LOAD r1, [r2] | 4 | 10011000 0rrr0rrr | 98 rr | r1 ← [r2] | — |
| PUSH r | 2 | 11100rrr | Er | r → [--SP] | — |
| CALL n | 3 | 11101000 nnnnnnnn | E8 nn | PC+2 → [--SP]; PC ← n | — |
| POP r | 2 | 11110rrr | Fr | r ← [SP++] | — |
| RETURN | 1 | 11111000 | F8 | PC ← [SP++] | — |
Table 5.
The E80 ALU operations. The 4-bit ALUop selects the function; operands are 8-bit words A and B (unless otherwise noted). Flags are denoted C (carry), Z (zero), S (sign), V (overflow); unmarked flags are passed through unchanged.
Table 5.
The E80 ALU operations. The 4-bit ALUop selects the function; operands are 8-bit words A and B (unless otherwise noted). Flags are denoted C (carry), Z (zero), S (sign), V (overflow); unmarked flags are passed through unchanged.
| ALUop | ALUout | Flags |
|---|---|---|
| 0010 | A + B | C, Z, S, V |
| 0011 | A - B (two’s complement) | C, Z, S, V |
| 0100 | A AND B | Z, S |
| 0101 | A OR B | Z, S |
| 0110 | A XOR B | Z, S |
| 0111 | A, rotated by B mod 8 bits | Z, S |
| 1010 | A, left shifted by 1 bit | C (shifted bit), Z, S, V (sign flip) |
| 1011 | A | Same as A - B |
| 1100 | A | Same as A AND B |
| 1101 | A, right shifted by 1 bit | C (shifted bit), Z, S, V (sign flip) |
| 1110 | A - 1 (used by PUSH & CALL) | — |
| 1111 | A + 1 (used by POP & RETURN) | — |
Table 6.
Resource usage of the E80 before (Version 2.0) and after (Version 4.0) the loop fix. Counts are the post-place-and-route totals for the complete system, with device utilization in parentheses; no block RAM or hardware multiplier is inferred on any platform. The logic column is in each vendor’s native element (Gowin Look-Up Table & ALU, Quartus logic element, Cologne Programmable Element) and is not comparable across rows.
Table 6.
Resource usage of the E80 before (Version 2.0) and after (Version 4.0) the loop fix. Counts are the post-place-and-route totals for the complete system, with device utilization in parentheses; no block RAM or hardware multiplier is inferred on any platform. The logic column is in each vendor’s native element (Gowin Look-Up Table & ALU, Quartus logic element, Cologne Programmable Element) and is not comparable across rows.
| Board (toolchain) | Pins | Logic | Registers |
|---|---|---|---|
| Version 2.0 | |||
| Tang Primer 25K (Gowin) | 39 (46%) | 4261 (19%) | 2212 (10%) |
| HOU DSD-i1 (Quartus) | 39 (42%) | 4157 (66%) | 2212 (35%) |
| GateMateA1 (OSS CAD Suite) | 39 (24%) | 8134 (19%) | 2210 (5%) |
| Version 4.0 | |||
| Tang Primer 25K (Gowin) | 16 (19%) | 5480 (24%) | 2287 (10%) |
| HOU DSD-i1 (Quartus) | 16 (17%) | 4444 (71%) | 2287 (36%) |
| GateMateA1 (OSS CAD Suite) | 16 (9%) | 8523 (20%) | 2285 (5%) |
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.
Copyright: This open access article is published under a Creative Commons CC BY 4.0 license, which permit the free download, distribution, and reuse, provided that the author and preprint are cited in any reuse.