

Submitted:
02 September 2026
Posted:
03 September 2026
Read the latest preprint version here
Abstract
Multimodal large language models (MLLMs) have been used to support dental image interpretation, but their accuracy may depend on how visual analysis is organized in the prompt. We proposed Hierarchical Reasoning Gates (HRG), a prompt-level protocol that divides image interpretation into sequential stages and requires validation before the model can progress. Thirty anonymized panoramic reconstructions derived from CBCT scans of impacted mandibular molars were analyzed with three prompt architectures: P1, zero-shot natural language; P2, structured sections with local checks; and P3, HRG with 10 macro-stages and 35 control mechanisms. Each output was compared with a pre-existing radiology report using five predefined image-interpretation variables. Total Score was analyzed with the Friedman test and Full Accuracy with Cochran’s Q test. Mean Total Score increased from 3.47 ± 1.33 for P1 to 4.77 ± 0.68 for P3, while Full Accuracy increased from 23.3% to 86.7%. Failures involving three or more image-interpretation variables decreased from 20.0% to 3.3%. Significant differences were observed for Tooth Number, Tooth Angulation, and Anatomical Relationship. In this dental imaging benchmark, HRG was associated with higher accuracy and more consistent multimodal image interpretation, with fewer multi-components error patterns. Our results support gated prompt design as a method for controlling dependent steps in AI-based image analysis. Clinical use still requires expert supervision.
Keywords:
artificial intelligence
; image interpretation
; multimodal large language models
; prompt engineering
; Hierarchical Reasoning Gates
; dental radiography
1. Introduction
Multimodal Large Language Models (MLLMs) combine the capability to process and interpret visual information with the ability to understand natural language. [1,2,3,4,5]. In multimodal tasks involving multiple related judgments, accurate outputs depend on the consistent integration of visual and textual evidence [2,6]. Task decomposition and verification mechanisms can help coordinate the intermediate decisions required in these complex tasks [7,8].
Natural language prompts can usually produce the desired output, but they do not necessarily control the order of analytical steps. Such instructions may be insufficient for complex problem-solving tasks because natural language can be ambiguous and models are sensitive to small variations, which may lead to semantic shortcuts, logical errors, and hallucinations [9,10,11,12,13]. Prompt design can influence how an MLLM approaches an image. Structured prompts, such as Chain-of-Thought (CoT), Analogical prompting, and Tree-of-Thought, can divide a task into sections and encourage the use of intermediate reasoning steps [8], but these instructions do not necessarily enforce logical precedence between dependent inference stages, and longer reasoning chains tend to increase hallucination rates [5,7].
Different studies of AI systems have examined prompt-based interaction, reasoning decomposition, and output consistency. Schellaert et al. [1] argue that large prompt-driven multimodal models should be evaluated as human-centred cognitive aids, since their performance depends on the interaction among the task, the user’s prompting choices, and the system’s responses. Plaat et al. [7] propose that LLMs can become agents able to decompose complex objectives into smaller steps. Qasim et al. [14] introduced the Recursive Decomposition of Logical Thoughts (RDoLT), a prompting framework that organizes reasoning into hierarchical steps and evaluates possible responses using multi-feature scoring. These studies indicate that prompt structure, decomposition strategy, and verification mechanisms can affect model performance. In reasoning chains, early failures in perception or interpretation may affect subsequent conclusions and allow inaccuracies to propagate through later stages [7,14].
Hierarchical and staged approaches shown potential to improve MLLM reasoning by decomposing perception and inference into staged steps, separating recognition from reasoning, and preserving dependencies between low-level evidence and higher-level conclusions [8,15,16,17]. However, the effectiveness of these approaches depends on the structure of the reasoning task and the difficulty of the benchmark datasets used [8,18].
Anatomical image interpretation provides a useful benchmark setting for examining hierarchical prompting because it requires the coordination of perceptual recognition, spatial reasoning, symbolic labeling, and domain-specific constraints, a combination that exposes failure modes not captured by standard language benchmarks [18,19]. Although the literature has not yet established a mature hierarchical prompting framework for dental imaging, this domain can provide a controlled and challenging setting for evaluating whether intermediate validation gates can reduce errors across dependent analytical steps.
We examine whether the use of validation gates to enforce dependencies among intermediate decisions reduces the incidence of downstream and co-occurring errors in a controlled visual-symbolic task. The contribution is therefore methodological: a prompt-level experimental framework for studying dependency control in multimodal inference. The methodology may provide a reproducible approach for investigating other anatomical interpretation tasks that require consistency across dependent analytical stages and for assessing how control structures may influence error propagation and output reliability in MLLMs.
2. Materials and Methods
2.1. Experimental Design
A benchmark dataset of anonymized dental panoramic reconstruction images derived from cone-beam computed tomography (CBCT) was used to compare three progressively developed prompt architectures. The architecture ranged from basic natural-language instructions to structured hierarchical prompts incorporating validation gates. Each image was assessed using all three prompt architectures, allowing within-image comparisons. The output generated for each radiograph was compared with its corresponding pre-existing radiographic report, which served as the image-specific reference standard. The central hypothesis was that a hierarchical prompting framework incorporating validation gates would improve output consistency and overall accuracy.
2.2. Ethical Considerations
The study followed the principles of the Declaration of Helsinki. Ethical approval was granted for the retrospective analysis of pre-existing anonymized CBCT data. All images were obtained from the Oral and maxillofacial surgery (OMFS) Lab imaging database, NMSK, IREC, Cliniques universitaires saint Luc, UCLouvain, Brussels, Belgium, and were anonymized prior to analysis. The study was covered by the approval granted by the UCLouvain University and Hospital Ethics Committee (B403/2019/03DEC/542). No new data collection or patient contact was involved. No personally identifiable information was present in the radiographic images or associated metadata. To preserve data confidentiality, before image submission, the “Improve the model for everyone” setting was disabled for the account. According to the provider’s data-control documentation, new conversations generated while this setting is disabled are not used to improve the provider’s models. The data were processed in accordance with the institutional procedures established under Regulation (EU) 2016/679 of the European Parliament and of the Council (GDPR).
2.3. Benchmark Dataset and Reference Standard
Dataset. The experiment used 30 anonymized panoramic reconstructions reformatted from CBCT acquisitions obtained from a UCLouvain institutional repository. The images were obtained from an internal clinical repository rather than from a named public dataset and are not distributed under a public license. Images were included when they showed an impacted mandibular molar requiring assessment of tooth identity, position, orientation, and relationships with adjacent anatomical structures, and when a corresponding radiology report was available. Images were excluded when image quality was inadequate for interpretation, distortion involved the mandibular molar region, or the region of interest was not fully visualized. No attempt was made to balance the dataset according to Lateralization, Tooth Number, Tooth Angulation, Eruption Status, or Anatomical Relationship. The benchmark retained the naturally occurring case-level anatomical variability present in the eligible institutional examinations. Consequently, the distribution of radiographic characteristics reflected the biological heterogeneity of the included cases rather than an experimentally imposed sampling pattern.
Region of Interest Definition. For each panoramic reconstruction, a region of interest (ROI) was manually delineated using Microsoft Paint for Windows. The ROI limits were adjusted to accommodate anatomical variation across cases and included the impacted mandibular molar and the adjacent structures required for radiographic interpretation. After manual delineation, each image was saved in PNG format and submitted to the MLLM without additional enhancement, augmentation, or automated preprocessing. The same ROI image was used across all three prompt architectures, ensuring consistent visual input between experimental conditions.
Reference Standard. The reference standard was the original radiology report for each image, prepared by one oral and maxillofacial radiologist before the prompt-comparison experiment and without access to the model outputs. This provided a pre-existing, clinically grounded reference independent of the prompt conditions. Every model-generated report was compared with the corresponding reference report using five predefined variables: Tooth Number, Lateralization, Tooth Angulation, Eruption Status, and Anatomical Relationship.
2.4. Development of Prompt Architectures
The study followed a two-phase design:
- 1.
- Discovery phase: A discovery set of five panoramic radiographs (excluded from the final benchmark) was analyzed to identify recurrent MLLM errors, including incorrect image orientation and subsequent errors in tooth identification. The recurring errors identified in this development guided the design of three prompt architectures:
- Prompt 1 (P1) - baseline: A zero-shot, unstructured natural-language prompt directing the MLLM to act as a radiologist to produce a formal radiographic report without specifying an analytical sequence or validation procedure. It relies on standard descriptive instructions to identify teeth, describe position, and assess anatomical relationships, using general guidelines to avoid assumptions and classify non-visible features as "not assessable".
- Prompt 2 (P2) - structured: A systematic architecture that divides the diagnostic workflow into five sequential steps, followed by a final and mandatory ’Internal Validation’ checkpoint to verify consistency and eliminate unsupported assumptions before generating a structured report in a predefined format.
- Prompt 3 (P3) - Hierarchical Reasoning Gates (HRG): The prompt follows a hierarchical, sequential, and auditable workflow built around 10 macro-stages. The framework includes 35 control mechanisms, comprising gates, checkpoints, tests, locks, and audits. Gates define the conditions for moving forward. Checks confirm that the required criteria have been verified. Locks prevent unvalidated progression or changes to previously validated decisions. If the final audit identifies an inconsistency, the result is considered invalid, and the process returns to the relevant stage for correction. Figure 1 provides a conceptual overview of HRG architecture
The complete operational structure and verbatim wording of P1, P2 and P3 are provided in Supplementary Material S1.
- 2.
- Prompt Application and Evaluation Phase: The resulting prompt architectures were tested on a benchmark of 30 panoramic reconstructions using a paired repeated-measures design, where each image served as its own control across all experimental conditions.
A schematic overview of the complete experimental pipeline, including dataset allocation, ROI processing, inference generation, and expert-based reference reports, is provided in Figure 2.
2.5. Experimental Protocol and MLLM Configuration
Conversational User Interface (CUI) and Agent Configuration. All multimodal model inferences were performed through the ChatGPT web interface (chat.openai.com) using the model option displayed as “GPT-5.5 High” at the time of data collection. Three separate Custom GPT configurations were created, one for each prompt architecture: P1, P2, and P3. The Custom GPT is a specialized version of ChatGPT that can be configured to perform a defined task. Every agent was assigned only one prompt architecture, and no agent was allowed to access the prompts assigned to the other experimental conditions. The same image and fixed task command were submitted for each case within each condition. The complete verbatim versions of the three prompt architectures and the fixed task command used for every inference are provided in Supplementary Material S1.
Inference Conditions. A new chat session was opened for each image with each AI agent (prompt condition). ChatGPT memory was disabled to limit the influence of information from previous cases. Web browsing, external retrieval, and additional tools were disabled during inference. The multimodal assistant generated a radiographic report according to the prompt used.
Parameter Availability. The experiment was conducted through the ChatGPT web. Standard sampling parameters, including temperature, top-p, random seed, and token limits, were not exposed to the user and could not be manually fixed. Detailed internal model-version information and provider-side computational infrastructure were also unavailable through the interface. All inferences were performed using the same account, Windows operating system, Google Chrome browser, and model option displayed in the interface. No fixed order was imposed for the application of the three prompt conditions, and their sequence varied across cases.
Data-Control Settings. ChatGPT memory was disabled, and each inference was performed in a separate chat session. The data-control setting permitting submitted content to be used for service improvement was disabled before the images were uploaded. These settings limited information transfer between sessions and prevented the voluntary contribution of the submitted content for service improvement.
2.6. Evaluation Criteria and Scoring Method
Prompt output performance was assessed using five image-interpretation variables: Tooth Number, Lateralization, Tooth Angulation, Eruption Status, and Anatomical Relationship.
- Binary Scoring Rubric. The individual interpretation items received a score of 1 when the model-generated output agreed with the reference report and 0 when the information disagreed with the reference report or was absent, ambiguous, or internally inconsistent. Tooth Number was considered correct when the number matched the reference report. Lateralization was considered correct when the mandibular side was correctly assigned. Tooth Angulation was considered correct when the reported angulation or positional description agreed with the reference. Eruption Status was considered correct when the presence of impaction and its description were consistent with the expert report. Anatomical Relationship was scored as correct when the reported relationship of the impacted molar with the mandibular canal and adjacent structures agreed with the reference report.
- The Total Score: Each of the five image-interpretation variables was scored as 0 for an incorrect response or 1 for a correct response. The Total Score was calculated as the sum of these scores, ranging from 0 to 5.
- Full Accuracy (Error-free): A binary outcome coded as 1 when all five variables were correctly identified in the same report and 0 otherwise.
- Error Pattern Analysis: Incorrect outputs were classified according to whether the error affected a single or multiple variables.
- Operationalization of Error Propagation: Error propagation was not directly observed within the model’s internal reasoning process. The presence of multiple errors in the same model-generated report was used as an indirect indicator that one error may have affected other related decisions.
- Output Archiving. All model-generated outputs were archived immediately after inference. The final dataset comprised 90 outputs: 30 images evaluated under three prompt architectures. The outputs were used without modification during scoring.
2.7. Statistical Analysis
Descriptive statistics summarized overall performance. For inferential analysis, Total Score was compared across architectures using the Friedman test, with Wilcoxon signed-rank post hoc tests (Holm-adjusted). Binary outcomes were analyzed using Cochran’s Q test, followed by exact McNemar pairwise comparisons with Holm adjustment. Kendall’s coefficient of concordance was calculated as the effect-size measure for the Friedman test. A significance level of 5% (p < 0.05) was adopted for all analyses. Statistical analyses were performed using Jamovi version 2.6 and R version 4.4.
3. Results
Ninety model-generated reports were obtained from 30 panoramic reconstructions, with each image evaluated under all three prompt architectures. Descriptive statistics for the Total Score are presented in Table 1. The mean Total Score increased progressively across prompt conditions, from 3.47 ± 1.33 for P1 to 4.37 ± 1.03 for P2 and 4.77 ± 0.68 for P3. The median score was 4.0 for P1 and 5.0 for both P2 and P3. The standard deviation decreased from 1.33 in P1 to 0.68 in P3, suggesting lower score variability under the more structured prompt architectures. The distribution of individual Total Scores across prompt architectures is shown in Figure 3
Paired repeated-measures analyses were performed to determine whether Total Score and Full Accuracy differed significantly across prompt architectures (Table 2). Full Accuracy was defined as an error-free report in which all five diagnostic variables were correctly identified. Total Score differed significantly among prompts according to the Friedman test ( = 21.217, p = 2.47 ×). The corresponding effect size was Kendall’s W = 0.354. Holm-adjusted pairwise Wilcoxon signed-rank tests showed significantly higher Total Scores for P2 than for P1 (p = 0.0125), for P3 than for P1 (p = 0.000921), and for P3 than for P2 (p = 0.0199). Full Accuracy also differed significantly across prompts by Cochran’s Q test (Q = 27.70, p = 9.66 ×). Holm-adjusted exact pairwise McNemar tests showed significant differences between P1 and P2 (p = 0.00366), P1 and P3 (p = 0.0000114), and P2 and P3 (p = 0.0156). The more structured prompt architectures were associated with higher total scores and a greater proportion of fully correct reports. Descriptive frequencies of error-free reports, corresponding to Full Accuracy, are presented in Table 4.
Image-interpretation variables accuracy and paired comparisons are presented in Table 3. Correct identification of Tooth Number increased from 60.0% in P1 to 86.7% in P2 and 96.7% in P3. The overall difference remained significant after Holm adjustment, with a significant pairwise difference between P1 and P3 (p = 0.0103). Tooth Angulation accuracy increased from 66.7% in P1 to 90.0% in P3, with a significant difference between P1 and P3 (p = 0.0469). Anatomical Relationship showed the largest improvement, increasing from 33.3% in P1 to 76.7% in P2 and 90.0% in P3. Significant differences were observed between P1 and P2 (p = 0.00195) and between P1 and P3 (p = 0.000229). No significant differences were found for Lateralization or Eruption Status. The variables accuracy rates across prompt architectures are illustrated in Figure 4.
Error-pattern analyses further differentiated the prompting conditions (Table 4). P1 showed a heterogeneous error profile, ranging from isolated errors to errors affecting multiple variables. Most errors involved Anatomical Relationship, either in isolation (23.3%) or in combination with Tooth Number (20.0%). P2 showed fewer and less complex errors, with 63.3% of reports classified as error-free. P3 had the highest proportion of error-free reports, with 26 of 30 reports (86.7%). Among the remaining four reports, two had a single diagnostic error, one had errors in two components, and one had errors in three or more. Overall, the frequency of reports with errors in three or more variables decreased from 20.0% with P1 to 3.3% with P3.

Table 4.
Distribution of errors across prompt conditions (n = 30)
| Error pattern | Prompt 1, n (%) | Prompt 2, n (%) | Prompt 3, n (%) |
|---|---|---|---|
| Full Accuracy (Error-free) | 7 (23.3%) | 19 (63.3%) | 26 (86.7%) |
| Anatomical Relationship only | 7 (23.3%) | 2 (6.7%) | 1 (3.3%) |
| Tooth Angulation only | 3 (10.0%) | 3 (10.0%) | 1 (3.3%) |
| Tooth Number only | 0 (0.0%) | 1 (3.3%) | 0 (0.0%) |
| Tooth Number + Anatomical Relationship only | 6 (20.0%) | 1 (3.3%) | 0 (0.0%) |
| Tooth Angulation + Anatomical Relationship only | 1 (3.3%) | 2 (6.7%) | 1 (3.3%) |
| ≥3 variable errors | 6 (20.0%) | 2 (6.7%) | 1 (3.3%) |
Error patterns were classified based on the combination of incorrect diagnostic per case. Cases with three or more simultaneous errors were grouped as ≥3 variable errors.
Overall, performance differed significantly across prompt architectures. Total Scores and the proportion of error-free reports increased progressively from P1 to P3, while multi errors became less frequent.
4. Discussion
A hierarchical structure allows prompts and intermediate decisions to be processed in sequential stages, while explicit gates require each stage to be verified before the MLLM proceeds. This principle supports the conceptual basis of the HRG framework examined in the present study. HRG produced the highest accuracy in the image-interpretation task. Reports with errors in three or more interpretation components analyzed by AI decreased from 20.0% to 3.3%. This pattern is relevant because HRG was designed to control linked image-analysis decisions through sequential validation. P1 showed the lowest scores, the greatest variability, and the highest frequency of multi- variables errors; P2 improved these outcomes; and P3 achieved the highest mean score with the largest proportion of fully correct outputs and the lowest variability. Performance improved progressively as prompt architecture incorporated stronger structural and validation constraints.
The results of this study support the hypothesis that progressively stronger reasoning control is associated with improved accuracy and consistency. The mean Total Score increased from P1 to P3 and Full Accuracy rose from 23.3% to 86.7%, an increase of 63.4 percentage points. Tooth Number, Toth Angulation, and Anatomical Relationship changed significantly across prompt conditions, while Lateralization and Eruption Status did not. These effects were most pronounced in the components of the image-analysis task that required more complex visual and spatial reasoning. Anatomical Relationship showed the largest gain, increasing from 33.3% in P1 to 90.0% in P3. Between P2 and P3, no significant difference was observed, but both achieved significantly better results than P1. This suggests that gated prompting may be particularly useful when later image-interpretation decisions depend on information established in earlier steps of the analysis. For Tooth Number, the clearest pairwise improvement was observed between Prompt 3 and Prompt 1. The difference between Prompt 1 and Prompt 2 did not remain significant after Holm correction. A similar pattern was observed for Tooth Angulation, with P3 performed significantly better than P1 (p = 0.0469). No significant differences were observed for Lateralization or Eruption Status. P3 also produced fewer failures involving multiple variables, suggesting more consistent reporting. These findings are consistent with previous studies linking structured, sequential prompting to more stable reasoning and less ambiguous LLM outputs [20,21]. The improvement in consistency from P1 to P3 is also consistent with the results reported by Qasim et al. [14], where ChatGPT achieved performance ranging from 83.2% to 88.9% across benchmarks using chain-of-thought prompting. The gains observed in Tooth Number and Anatomical Relationship may also reflect the anatomical reasoning difficulties previously described in LLM-based dental image analysis [20,22].
The transition from P2 to P3 produced a modest increase in mean Total Score but a larger increase in Full Accuracy. HRG can be interpreted as an external control mechanism for multimodal image analysis that helped reduce residual errors. Across P1, P2, and P3, the prompts differed in the amount of information provided and the inclusion of mandatory verification steps. In P3, HRG architecture required verification before the analysis could proceed to the next, which was associated with fewer errors across dependent stages. Because hierarchical sequencing and explicit validation were introduced simultaneously, their individual contributions cannot be determined from the present study. The observed differences should therefore be interpreted as the overall effect of the HRG architecture, which imposed logical precedence between decisions.
These findings are compatible with the premise that sequential validation may limit the downstream consequences of early errors, a mechanism that may also be relevant to other MLLM applications involving interdependent analytical steps. The explanation is that multimodal performance depends on the information included in a prompt as well as on the order in which that information is processed and controlled. By requiring stages to be checked and locked before the analysis proceeded, the framework limited unsupported conclusions and reduced the possibility of errors. This strategy is consistent with prompt-engineering principles that emphasize sequential prompting, precise task specification, and logical reasoning [23]. Probing-based frameworks complement this approach by investigating how different layers of the model represent and process information [24]. The use of an orientation gate at an early stage is also supported by previous work on prompt programming, which suggests that early contextual guidance can improve the consistency of later reasoning steps [25]. A model may have the internal skills to process images and data, but this capability is useful only if the model produces accurate and consistent results when prompted [1,26]..
To find a correct instruction, instead of relying only on user intuition to construct a single prompt, a discovery phase was used to identify recurrent failure types and interactively refine and construct the prompts. This phase created an important preliminary step to guide the design of the three prompt architectures. P1 resembled a conventional zero-shot interaction, P2 incorporated structured reporting and local validation procedures, and P3 implemented HRG framework with ten macro-stages with covering gates, checkpoints, tests, locks, and a final audit stage. The HRG framework separated the analytical procedure into successive phases: orientation assessment, structure identification, Lateralization determination, local Tooth Angulation analysis, Anatomical Relationship evaluation, and final consistency verification.
The development of the proposed HRG framework followed the concept of human-centred generality proposed by Schellaert et al. [1]. The authors argue that the effectiveness of multimodal systems depends on the interaction among users, tasks, and prompting practices. This view also reflects the notion of AI systems as cognitive extenders, since model performance is shaped by how users organize and refine their interactions with the system. Thus, HRG architecture transforms recurrent failures into explicit validation gates and assessed accuracy and co-occurring error patterns across prompting conditions in a context-sensitive approach.
Qasim et al. [14] proposed RDoLT to improve LLM reasoning through hierarchical task decomposition and multi-feature evaluation of candidate thoughts. Their Knowledge Propagation Module (KPM) improves accuracy and reduces error propagation. HRG shares the principle that multimodal reasoning can be improved by breaking the task into steps and validating each step before moving to the next before conclusions are formulated. Thus, HRG uses prompt architecture as a mechanism to control the order of dependent steps progress during multimodal analysis, instead of simply guiding the final output.
In our study, the benchmark dataset provides a suitable testbed for hierarchical prompting because dental images require sequential decisions about localization, tooth identification, and anatomical relationships, and an error in an early decision may therefore affect later conclusions [14,18,27]. The anatomical relationship between an impacted mandibular molar and the inferior alveolar nerve varies among individuals, reflecting a patient-specific anatomical formation that cannot be reduced to a fixed template. This variability makes the task particularly demanding for MLLMs, while a mature hierarchical gating framework has not yet been established in the dental literature. Mogadala et al. [28] emphasized the importance of robust evaluation measures across different tasks and datasets. Their findings demonstrated that model accuracy can vary according to the dataset and evaluation context.
Several studies have evaluated MLLMs across clinical and healthcare applications. These evaluations have documented responses that appeared clinically plausible but contained inaccurate or fabricated information, such as invented surgical histories, fictitious symptoms [27,29], incorrect radiologic information [9], and nonexistent specialized medical equipment [12]. Although hierarchical gating has not yet been established as a standard framework for MLLMs, the literature suggests that performance can improve when prompts organize multimodal inference into defined stages, limit irrelevant context, and link low-level evidence to higher-level conclusions [30,31,32].
Our approach substantially improved accuracy in Tooth Number and Anatomical Relationship, suggesting more reliable anatomical reasoning in LLM-based dental image analysis. In comparison with previous studies, Suárez et al. [33] reported an accuracy of 38.44% using a short, non-specialist prompt. In the present study, the Full Accuracy rate reached 86.7%, while the proportion of failures involving three or more variables decreased from 20.0% to 3.3% with the use of the HRG framework. This difference suggests that the performance of general purpose MLLMs in dental image interpretation is sensitive to task formulation. Salmanpour and Akpınar [34] reported an accuracy of 37.1% when using chain-of-thought (CoT) prompting to determine the labiolingual position of impacted canines. Their findings suggest that the effectiveness of structured prompting varies with task complexity and the degree of visual ambiguity. In contrast, the higher accuracy achieved in our experimental settings may result from the combination of hierarchical reasoning control and precise selection of the relevant anatomical region of interest. ROI restrictions may possibly reduce irrelevant visual information and support more reliable anatomical interpretation. This is consistent with Moncher et al., that found ROI selection can influence model behavior in dental radiographic analysis [35].
To minimize unsupported clinical inferences, our analysis followed a structured design to isolate prompt architecture as the sole experimental variable. We used a retrospective observational dataset with expert radiology reference reports completed before model evaluation, thereby establishing an independent evaluation standard, as detailed in our scoring methodology. No new radiographic interpretation was performed, and the reports remained independent of the model-generated output. The HRG framework was evaluated using a single MLLM and a controlled dental imaging benchmark because the study was designed exclusively to examine the effect of prompt architecture under standardized experimental conditions. A controlled setting minimized confounding factors, allowing a direct assessment of how prompt architecture influenced the results.
A further experimental control was the isolation of each inference in a separate Custom GPT conversation. According to OpenAI’s documentation, Custom GPTs do not use saved memory, custom instructions, or previous conversations, and each new conversation starts fresh [36]. Memory and personalization features were also disabled at the account settings as an additional precaution. After each inference, the chat was closed, and the next analysis was performed in a new conversation using one of the other two Custom GPTs. These procedures were adopted to minimize the possibility that information from a previous analysis could influence subsequent model outputs.
The present results show that HRG provides a structured way to organize dependent decisions in multimodal dental image interpretation and explicit validation between these stages can improve accuracy under the conditions tested. Whether the same effect occurs in other imaging modalities and clinical tasks still requires direct evaluation.
4.1. Limitations
The HRG framework substantially improved Full Accuracy and reduced multiple errors, supporting the value of structured prompt architecture for improving the accuracy and consistency of MLLM outputs. These findings also suggest that the principles underlying the framework may be applicable beyond the specific conditions tested. However, the evaluation was conducted using a limited dataset, a controlled dental image interpretation task, and a single MLLM. Validation with larger and more diverse datasets, different models, imaging modalities, and clinical settings will be important to confirm the robustness and broader applicability of these improvements.
The use of manually selected regions of interest may also have influenced model performance. The visual restriction to the impacted mandibular molar and adjacent anatomical structures reduced irrelevant information and ensured that the same image was used across all prompt conditions. However, this procedure may have simplified the interpretation task compared with a full panoramic-image workflow. Therefore, the effects of ROI restriction and prompt architecture cannot be completely separated in the present design.
The experiment was conducted through the ChatGPT web interface rather than through an application programming interface. As a result, sampling parameters such as temperature, top-p, random seed, and token limits were not exposed and could not be manually controlled. Detailed internal model-version information and provider-side computational infrastructure were also unavailable. Although the same account, operating system, browser environment, and model option were used throughout the experiment, unobserved provider-side variation and random variation between model outputs cannot be excluded.
Only one output was generated for each image under each prompt condition. This design allowed direct comparison among the three prompt architectures but did not assess model repeatability or response variability when the same image was analyzed repeatedly using the same prompt. Future studies should generate multiple independent outputs for each image and prompt combination to evaluate repeatability and within-model variability.
Another limitation is that the P3 prompt combined hierarchical sequencing, validation gates, checks, locks, and a final audit within a single HRG architecture. Because these elements were evaluated together, the present study cannot determine the individual contribution of each component. Ablation studies comparing hierarchical sequencing, local validation, mandatory gating, and final auditing as separate conditions would help determine which elements are most responsible for the observed improvements.
The evaluation dataset included 30 panoramic reconstructions. This sample was sufficient to detect the overall difference observed among the three prompt architectures. However, studies with larger independent samples would provide more precise effect estimates and greater sensitivity to smaller differences between prompting conditions.
5. Conclusions
This study demonstrates the efficacy of the Hierarchical Reasoning Gates (HRG) framework as a robust, reproducible prompt architecture designed to control inferential dependencies in multimodal large language models. Moving beyond simple static instructions, the sequential validation gates of the HRG framework increased Full Accuracy by 63.4 percentage points and produced an 83.3% relative reduction in reports with three or more incorrect diagnostic components compared with the standard prompt condition. Clinically, these findings support the integration of structured reasoning to enhance diagnostic reliability in complex image interpretation tasks, although expert human supervision remains indispensable for clinical decision support. HRG should be viewed as a prompt-level procedure for controlled multimodal image interpretation, with potential application to other structured imaging tasks.
Future work should validate the HRG framework across additional MLLMs, larger and more diverse imaging datasets, different modalities, and repeated inference conditions to assess its robustness, generalizability, and stability.
Supplementary Materials
The following supporting information accompanies the manuscript: Preprints.org. Supplementary Material S1, complete operational structure and verbatim wording of P1, P2, and P3, including the fixed task command used for every inference.
Author Contributions
Conceptualization, M.D.M.; methodology, M.D.M., O.M., C.P.S. and R.O.; formal analysis, M.D.M., O.M. and G.-A.O.; investigation, M.D.M.; resources, R.O.; data curation, M.D.M.; writing—original draft preparation, M.D.M.; writing—review and editing, all authors; project administration, M.D.M.; supervision, R.O. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Institutional Review Board Statement
The study was conducted in accordance with the Declaration of Helsinki and was covered by the approval granted by the Cliniques universitaires saint Luc, UCLouvain, University and Hospital Ethics Committee (B403/2019/03DEC/542) for the retrospective analysis of pre-existing anonymized CBCT data.
Informed Consent Statement
Patient consent was waived due to the retrospective design and the use of anonymized radiographic data archived in accordance with the ethics committee approval.
Data Availability Statement
The clinical images belong to an internal UCLouvain institutional repository and are not publicly distributed under a public license. Access is subject to institutional data-confidentiality and data-protection requirements. The dataset source, selection criteria, ROI preparation, reference standard, and experimental workflow are described in the article; the complete prompt architectures and fixed task command are provided in Supplementary Material S1.
Acknowledgments
The authors would like to thank Cliniques universitaires Saint-Luc, UCLouvain, Brussels, Belgium, for providing access to the imaging database used in this study and for its institutional and ethical support for the collection and use of the data for research.
Conflicts of Interest
The authors declare no conflicts of interest.
Abbreviations
The following abbreviations are used in this manuscript:
| AI | Artificial intelligence |
| CBCT | Cone-beam computed tomography |
| CoT | Chain-of-thought |
| CUI | Conversational user interface |
| EU | European Union |
| GDPR | General Data Protection Regulation |
| GPT | Generative Pre-trained Transformer |
| HRG | Hierarchical Reasoning Gates |
| InTheRNA | Innovative Therapies and Nanomedicine |
| Inserm | National Institute of Health and Medical Research |
| IREC | Institut de Recherche Expérimentale et Clinique |
| KPM | Knowledge Propagation Module |
| LLM | Large language model |
| MLLM | Multimodal large language model |
| NMSK | Neuro Musculo Skeletal Lab |
| OMFS | Oral and maxillofacial surgery |
| P1 | Prompt architecture 1 (baseline) |
| P2 | Prompt architecture 2 (structured) |
| P3 | Prompt architecture 3 (Hierarchical Reasoning Gates) |
| PNG | Portable Network Graphics |
| Q1 | First quartile |
| Q3 | Third quartile |
| RDoLT | Recursive Decomposition of Logical Thoughts |
| ROI | Region of interest |
| SD | Standard deviation |
| UCLouvain | Université catholique de Louvain |
References
- Schellaert, W.; Martínez-Plumed, F.; Vold, K.; Burden, J.; Casares, P.A.M.; Loe, B.S.; Reichart, R.; Ó hÉigeartaigh, S.; Korhonen, A.; Hernández-Orallo, J. Your prompt is my command: On assessing the human-centred generality of multimodal models. J. Artif. Intell. Res. 2023, 77, 377–394. [Google Scholar] [CrossRef]
- Yin, S.; Fu, C.; Zhao, S.; Li, K.; Sun, X.; Xu, T.; Chen, E. A survey on multimodal large language models. Natl. Sci. Rev. 2024, 11, nwae403. [Google Scholar] [CrossRef]
- Caffagni, D.; Cocchi, F.; Moratelli, N.; Sarto, S.; Cornia, M.; Baraldi, L.; Cucchiara, R. Wiki-LLaVA: Hierarchical retrieval-augmented generation for multimodal LLMs. In Proceedings of the 2024 IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW), 2024; pp. 1818–1826. [Google Scholar] [CrossRef]
- Shao, M.; Basit, A.; Karri, R.; Shafique, M. Survey of different large language model architectures: Trends, benchmarks, and challenges. IEEE Access 2024, 12, 188664–188706. [Google Scholar] [CrossRef]
- Mohanty, A.; Parthasarathy, V.B.; Shahid, A. The future of MLLM prompting is adaptive: A comprehensive experimental evaluation of prompt engineering methods for robust multimodal performance. Trans. Mach. Learn. Res. 2025. Available online: https://openreview.net/forum?id=B1L8HrjoA1 (accessed on 24 August 2026).
- Yang, Y.; He, X.; Pan, H.; Jiang, X.; Deng, Y.; Yang, X.; Lu, H.; Yin, D.; Rao, F.; Zhu, M.; Zhang, B.; Chen, W. R1-Onevision: Advancing generalized multimodal reasoning through cross-modal formalization. In Proceedings of the 2025 IEEE/CVF International Conference on Computer Vision (ICCV), Honolulu, HI, USA, 19–23 October 2025; pp. 2376–2385. [Google Scholar] [CrossRef]
- Plaat, A.; van Duijn, M.; van Stein, N.; Preuss, M.; van der Putten, P.; Batenburg, K.J. Agentic large language models: A survey. J. Artif. Intell. Res. 2025, 84, 29. [Google Scholar] [CrossRef]
- Son, M.; Lee, S. Advancing multimodal large language models: Optimizing prompt engineering strategies for enhanced performance. Appl. Sci. 2025, 15, 3992. [Google Scholar] [CrossRef]
- Siepmann, R.; Huppertz, M.; Rastkhiz, A.; Reen, M.; Corban, E.; Schmidt, C.; Wilke, S.; Schad, P.; Yüksel, C.; Kuhl, C.; Truhn, D.; Nebelung, S. The virtual reference radiologist: Comprehensive AI assistance for clinical image reading and interpretation. Eur. Radiol. 2024, 34, 6652–6666. [Google Scholar] [CrossRef]
- Hao, S.; Gu, Y.; Luo, H.; Liu, T.; Shao, X.; Wang, X.; Xie, S.; Ma, H.; Samavedhi, A.; Gao, Q.; Wang, Z.; Hu, Z. LLM reasoners: New evaluation, library, and analysis of step-by-step reasoning with large language models. arXiv 2024, arXiv:2404.05221. [Google Scholar] [CrossRef]
- Al-Haj Ali, S.N. Emergency management of permanent tooth avulsion: Comparative performance of dental students and artificial intelligence using a multimodal clinical vignette across Bloom’s taxonomy domains. Int. Endod. J. advance online publication. 2025. [Google Scholar] [CrossRef]
- Kim, J.; Podlasek, A.; Shidara, K.; Liu, F.; Alaa, A.; Bernardo, D. Limitations of large language models in clinical problem-solving arising from inflexible reasoning. Sci. Rep. 2025, 15, 39426. [Google Scholar] [CrossRef]
- Liu, J.; Zhu, D.; Bai, Z.; He, Y.; Liao, H.; Que, H.; Wang, Z.; Zhang, C.; Zhang, G.; Zhang, J.; et al. A comprehensive survey on long context language modeling. arXiv 2025, arXiv:2503.17407. [Google Scholar] [CrossRef]
- Qasim, K.U.; Zhang, J.; Alsahfi, T.; Butt, A.U.R. Recursive decomposition of logical thoughts: Framework for superior reasoning and knowledge propagation in large language models. J. Artif. Intell. Res. 2025, 83, 27. [Google Scholar] [CrossRef]
- Wang, C.; Huang, T.; Sun, C.; Ning, X.; Wang, D.; Tang, H. Let Geometry GUIDE: Layer-wise unrolling of geometric priors in multimodal LLMs. arXiv 2026, arXiv:2604.05695. [Google Scholar] [CrossRef]
- Lo, R.; Sridhar, A.; Xu, F.F.; Zhu, H.; Zhou, S. Hierarchical prompting assists large language model on web navigation. In Findings of the Association for Computational Linguistics: EMNLP 2023; Association for Computational Linguistics: Singapore, 2023; pp. 10217–10244. [Google Scholar] [CrossRef]
- Wang, G.; Li, J.; Sun, Y.; Chen, X.; Liu, C.; Wu, Y.; Lu, M.; Song, S.; Abbasi-Yadkori, Y. Hierarchical reasoning model. arXiv 2025, arXiv:2506.21734. [Google Scholar] [CrossRef]
- Li, X.; Ma, X.; Zhao, Y.; Hu, J.; Liu, J.; Yang, Z.; Han, F.; Zhang, J.; Liu, W.; Zhou, Z. A multi-center dental panoramic radiography image dataset for impacted teeth, periodontitis, and dental caries: Benchmarking segmentation and classification tasks. J. Imaging Inform. Med. 2024, 37, 831–841. [Google Scholar] [CrossRef]
- Kaveevorayan, V.; Pitakaso, R.; Srichok, T.; Nanthasamroeng, N.; Kaewta, C.; Luesak, P. Neuro-geometric graph transformers with differentiable radiographic geometry for spinal X-ray image analysis. J. Imaging 2026, 12, 59. [Google Scholar] [CrossRef]
- Sahoo, H.S.; Kumar, A.R.P.; Durvasulu, A.; Ravichandran, A. Comparative analysis of diagnostic prediction and clinical reasoning of large language models in complex endodontic case scenarios. J. Dent. 2026, 166, 106309. [Google Scholar] [CrossRef]
- Zhu, B.; Ning, M.; Jin, P.; Lin, B.; Huang, J.; Song, Q.; Zhang, J.; Tang, Z.; Pan, M.; Zhou, X.; Yuan, L. LLMBind: A unified modality-task integration framework. arXiv 2024, arXiv:2402.14891. [Google Scholar] [CrossRef]
- Silva, T.P.; Andrade-Bortoletto, M.F.S.; Ocampo, T.S.C.; Alencar-Palha, C.; Bornstein, M.M.; Oliveira-Santos, C.; Oliveira, M.L. Performance of a commercially available generative pre-trained transformer (GPT) in describing radiolucent lesions in panoramic radiographs and establishing differential diagnoses. Clin. Oral Investig. 2024, 28, 204. [Google Scholar] [CrossRef]
- Bozkurt, A. Tell me your prompts and I will make them true: The alchemy of prompt engineering and generative AI. Open Prax. 2024, 16, 111–118. [Google Scholar] [CrossRef]
- Yu, Z.; Lee, Y.J. How multimodal LLMs solve image tasks: A lens on visual grounding, task reasoning, and answer decoding. In Proceedings of the Conference on Language Modeling (COLM), 2025; Available online: https://openreview.net/forum?id=kjNJYWvfPA (accessed on 24 August 2026).
- Reynolds, L.; McDonell, K. Prompt programming for large language models: Beyond the few-shot paradigm. In Extended Abstracts of the 2021 CHI Conference on Human Factors in Computing Systems; Association for Computing Machinery: New York, NY, USA, 2021; Volume Article 314, pp. 1–7. [Google Scholar] [CrossRef]
- Zhang, M.; Shen, Y.; Li, Z.; Sha, H.; Hu, B.; Wang, Y.; Huang, C.; Liu, S.; Tong, J.; Jiang, C.; Chai, M.; Xi, Z.; Dou, S.; Gui, T.; Zhang, Q.; Huang, X. LLMEval-Med: A real-world clinical benchmark for medical LLMs with physician validation. Find. Assoc. Comput. Linguist. EMNLP 2025, 4888–4914. [Google Scholar] [CrossRef]
- He, Z.; Feng, Y.; Yang, S.; Zhu, Y.; Zhang, X.; Tai, P.C.P.; Lo, H.Y.; Wu, S.; Yang, W.; Yu, L. Dental-TriageBench: Benchmarking multimodal reasoning for hierarchical dental triage. arXiv 2026, arXiv:2604.13060. [Google Scholar] [CrossRef]
- Mogadala, A.; Kalimuthu, M.; Klakow, D. Trends in integration of vision and language research: A survey of tasks, datasets, and methods. J. Artif. Intell. Res. 2021, 71, 1183–1317. [Google Scholar] [CrossRef]
- Asgari, E.; Montaña-Brown, N.; Dubois, M.; Khalil, S.; Balloch, J.; Au Yeung, J.; Pimenta, D. A framework to assess clinical safety and hallucination rates of LLMs for medical text summarisation. npj Digit. Med. 2025, 8, 274. [Google Scholar] [CrossRef]
- Liu, L.; Yang, X.; Shen, Y.; Hu, B.; Zhang, Z.; Gu, J.; Zhang, G. Think-in-memory: Recalling and post-thinking enable LLMs with long-term memory. arXiv 2023, arXiv:2311.08719. [Google Scholar] [CrossRef]
- Zhou, Q.; Xu, H.; Gu, Y.; Wang, Y.; Li, S.; Zhang, H. Evolutionary multimodal reasoning via hierarchical semantic representation for intent recognition. arXiv 2026, arXiv:2603.03827. [Google Scholar] [CrossRef]
- Zhong, M.; Wang, Y.; Zhang, L.; An, A.; Zhang, R.; Liang, H.; Lu, M.; Shen, Y.; Zhang, W. VCU-Bridge: Hierarchical visual connotation understanding via semantic bridging. arXiv 2025, arXiv:2511.18121. [Google Scholar] [CrossRef]
- Suárez, A.; Arena, S.; Herranz Calzada, A.; Castillo Varón, A.I.; Diaz-Flores García, V.; Freire, Y. Decoding wisdom: Evaluating ChatGPT’s accuracy and reproducibility in analyzing orthopantomographic images for third molar assessment. Comput. Struct. Biotechnol. J. 2025, 28, 141–147. [Google Scholar] [CrossRef]
- Salmanpour, F.; Akpınar, M. Performance of Chat Generative Pretrained Transformer-4.0 in determining labiolingual localization of maxillary impacted canine and presence of resorption in incisors through panoramic radiographs: A retrospective study. Am. J. Orthod. Dentofac. Orthop. 2025, 168, 220–231. [Google Scholar] [CrossRef]
- Moncher, M.; Traboulsi, V.; Kofler, F.; Müller, S.; Steinbauer, F.; von See, C. AI-based detection of osteoporosis on dental radiographs: Influence of region-of-interest selection on classification performance. J. Imaging 2026, 12, 285. [Google Scholar] [CrossRef]
- OpenAI. GPTs in ChatGPT. Available online: https://help.openai.com/en/articles/8554407-gpts-in-chatgpt (accessed on 24 August 2026).
Figure 1.
Architecture of the Hierarchical Reasoning Gates (HRG) Framework.
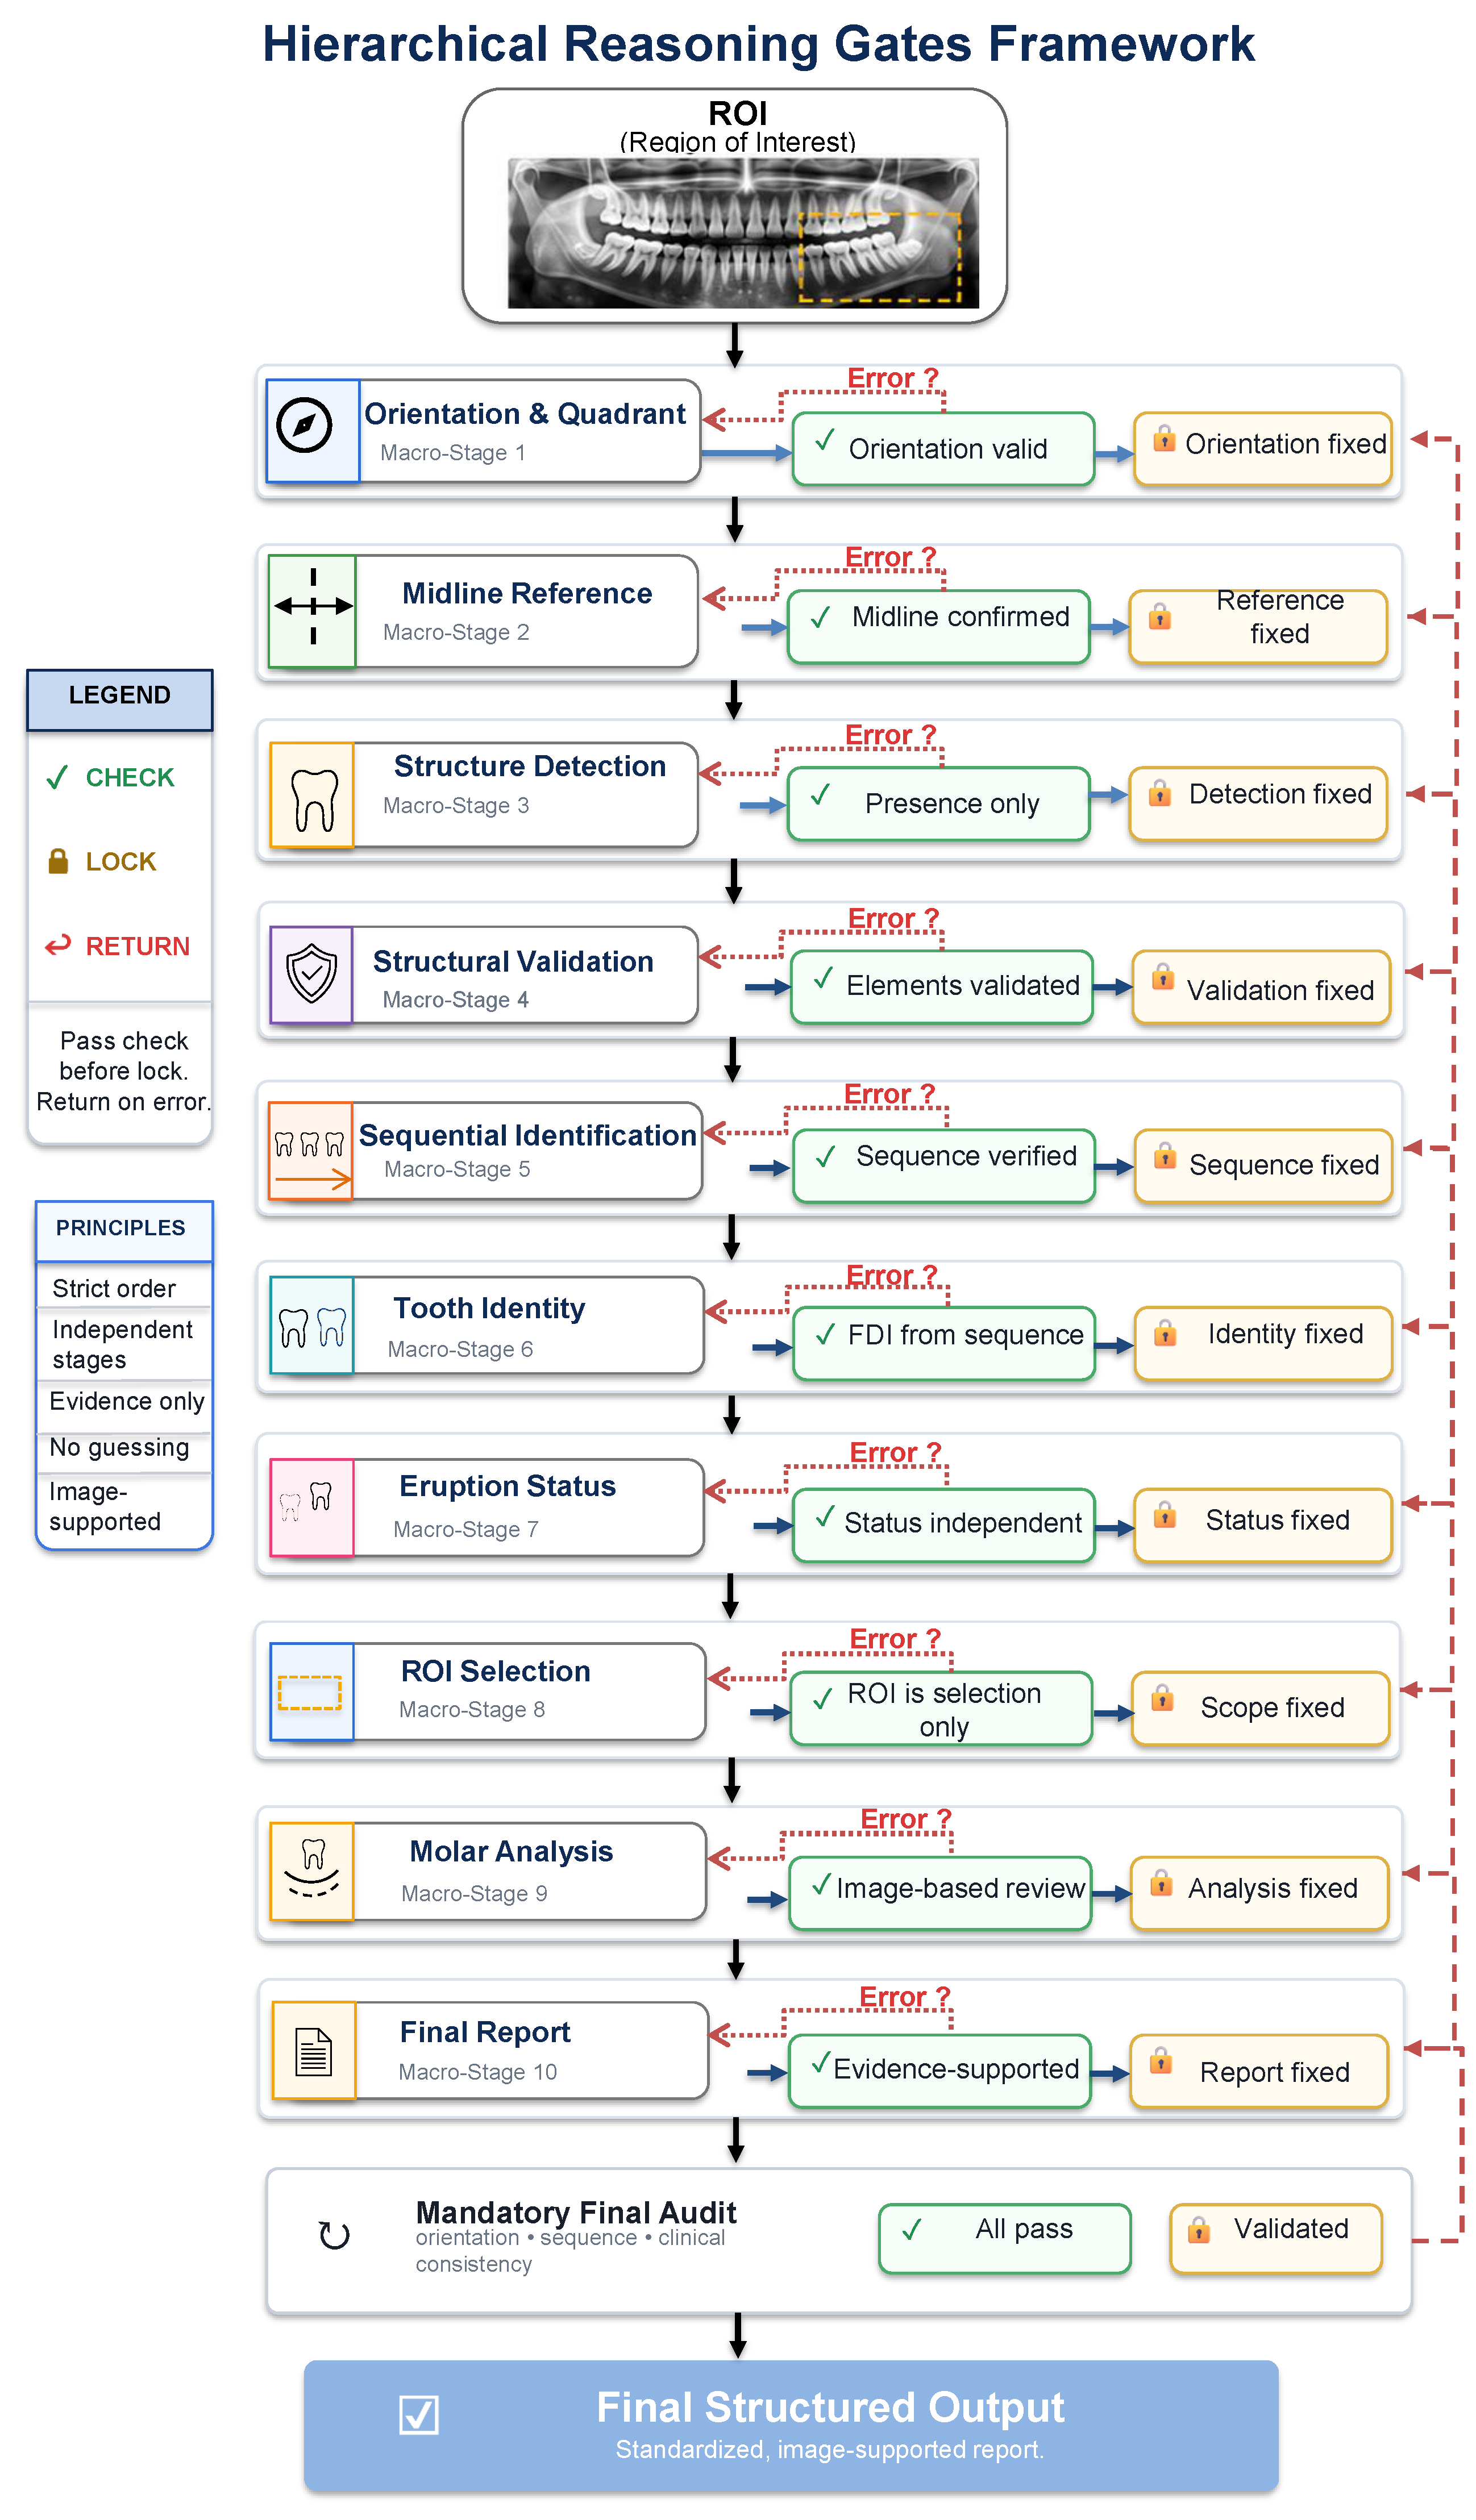
Figure 2.
Experimental workflow showing dataset allocation, ROI preparation, assignment of prompt conditions, model inference, comparison with the expert reports, and statistical analysis.
Figure 2.
Experimental workflow showing dataset allocation, ROI preparation, assignment of prompt conditions, model inference, comparison with the expert reports, and statistical analysis.
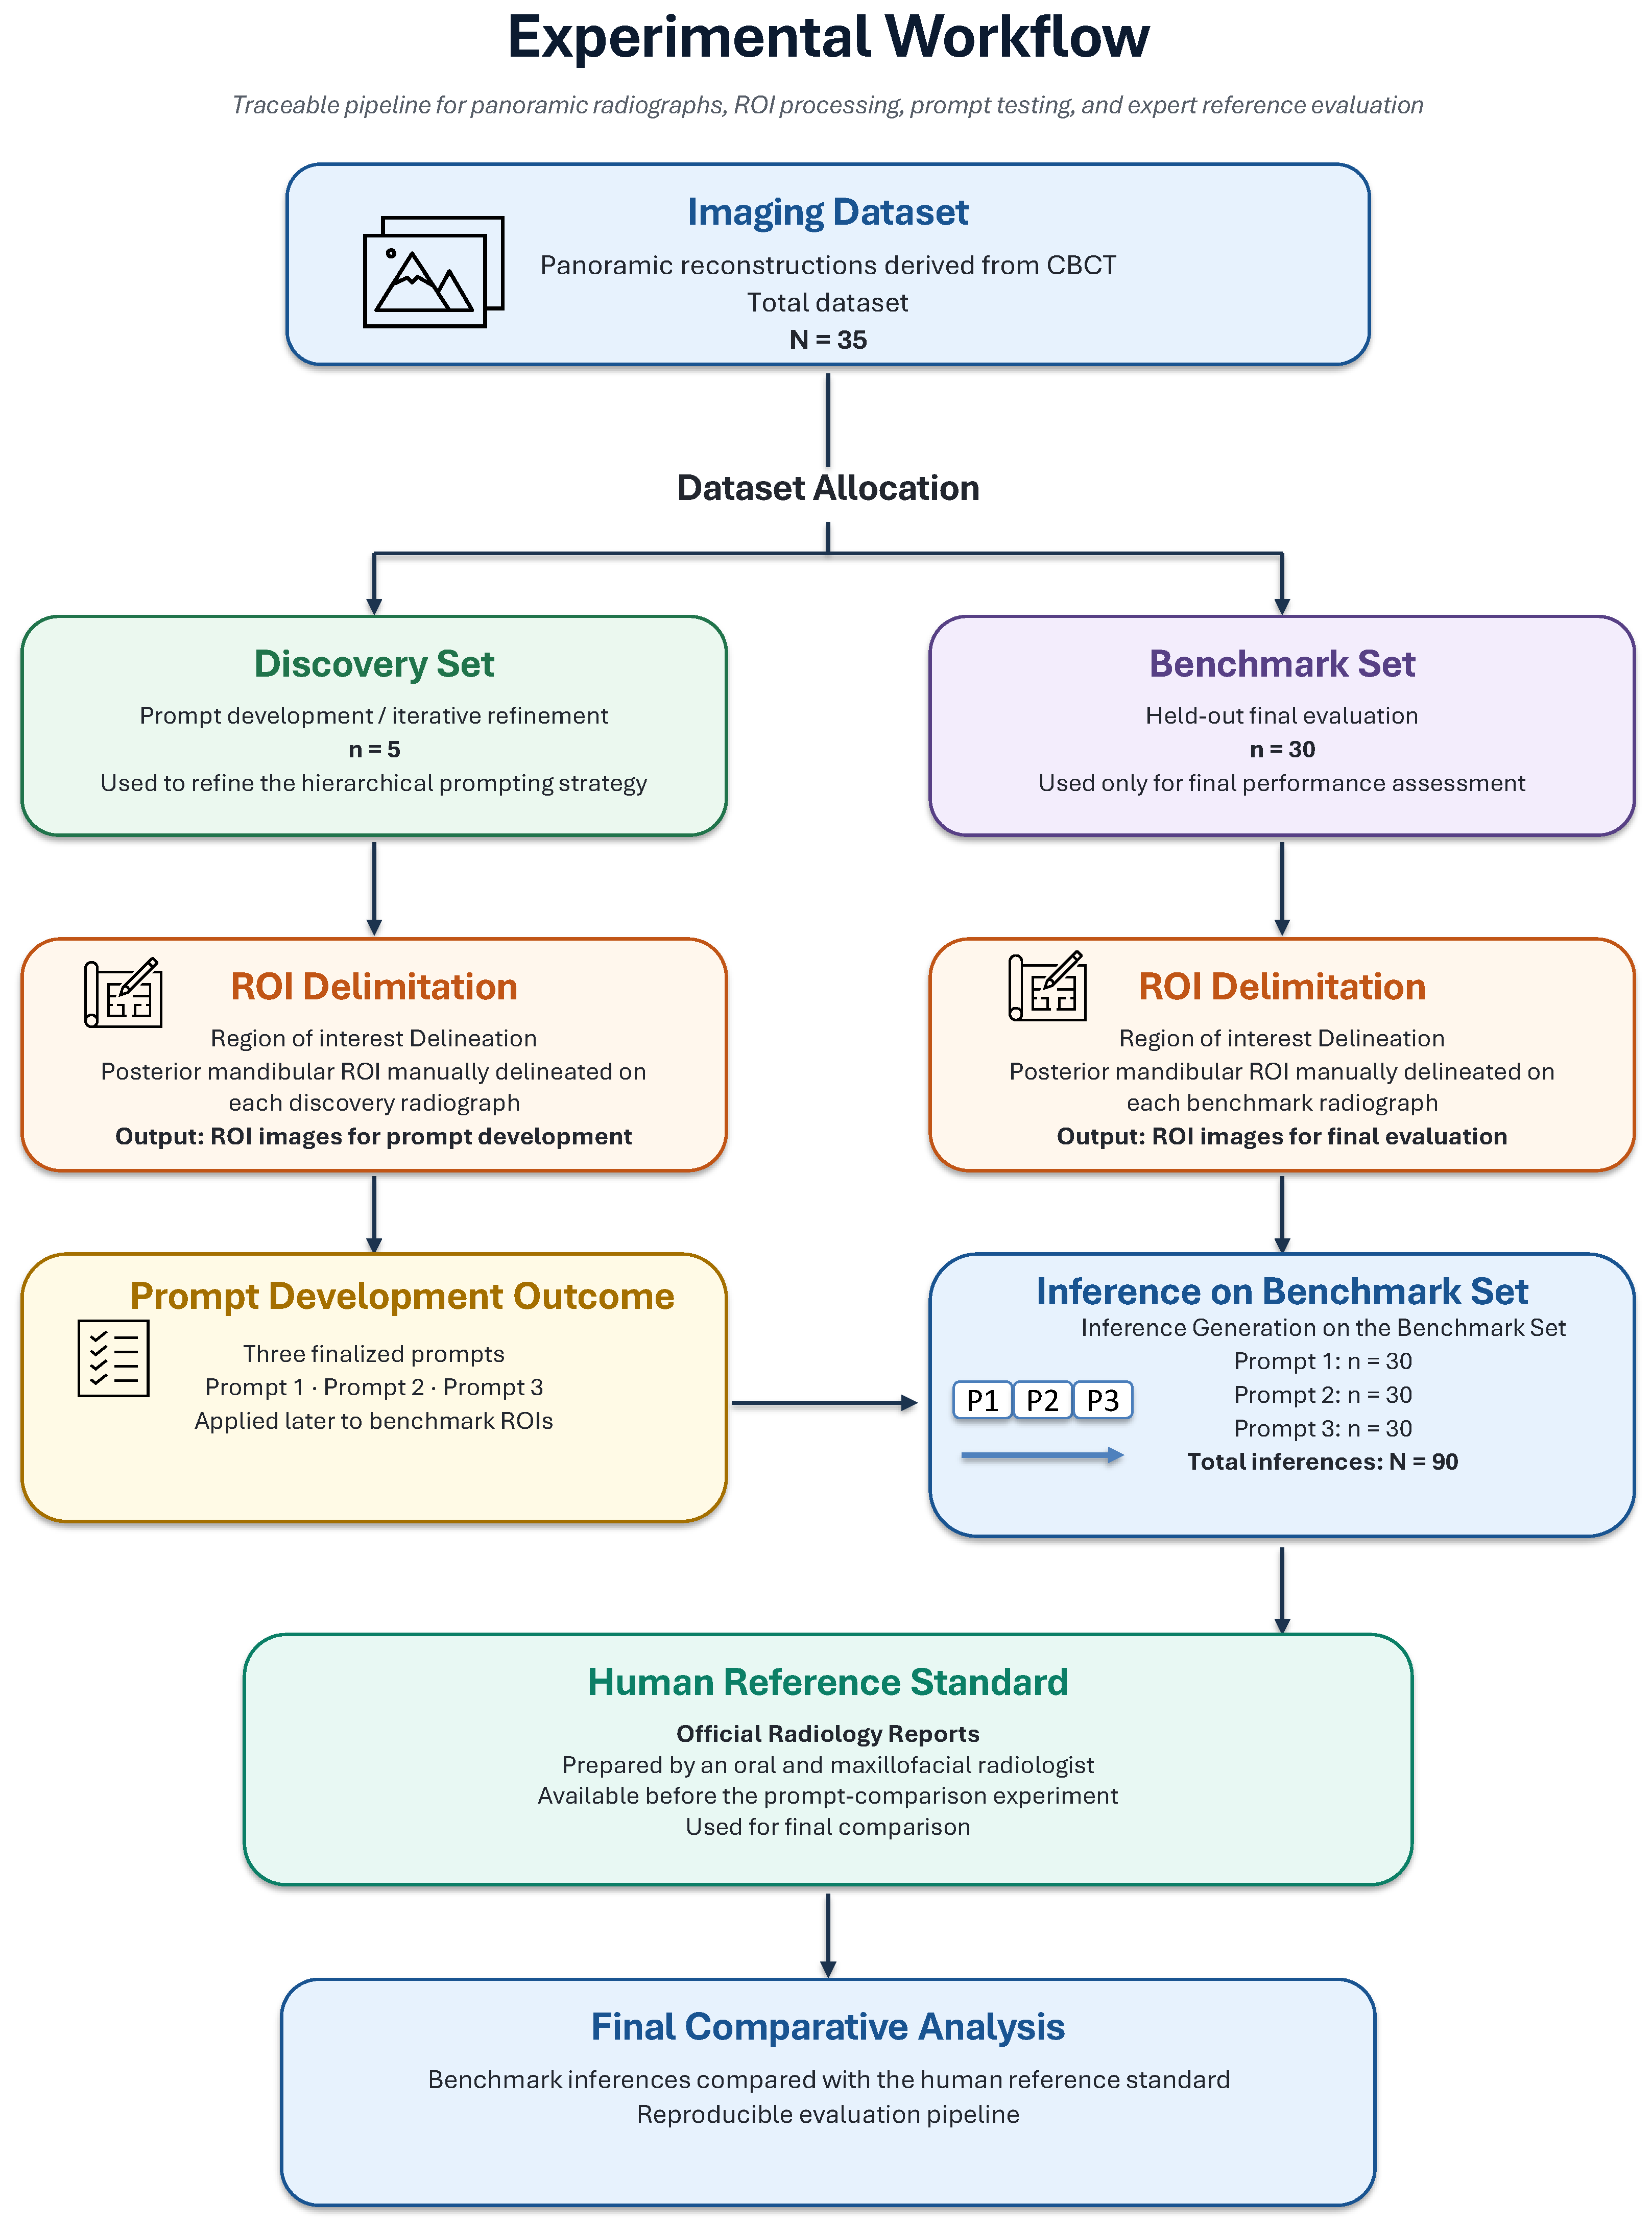
Figure 3.
Distribution of Total Scores across prompt architectures.
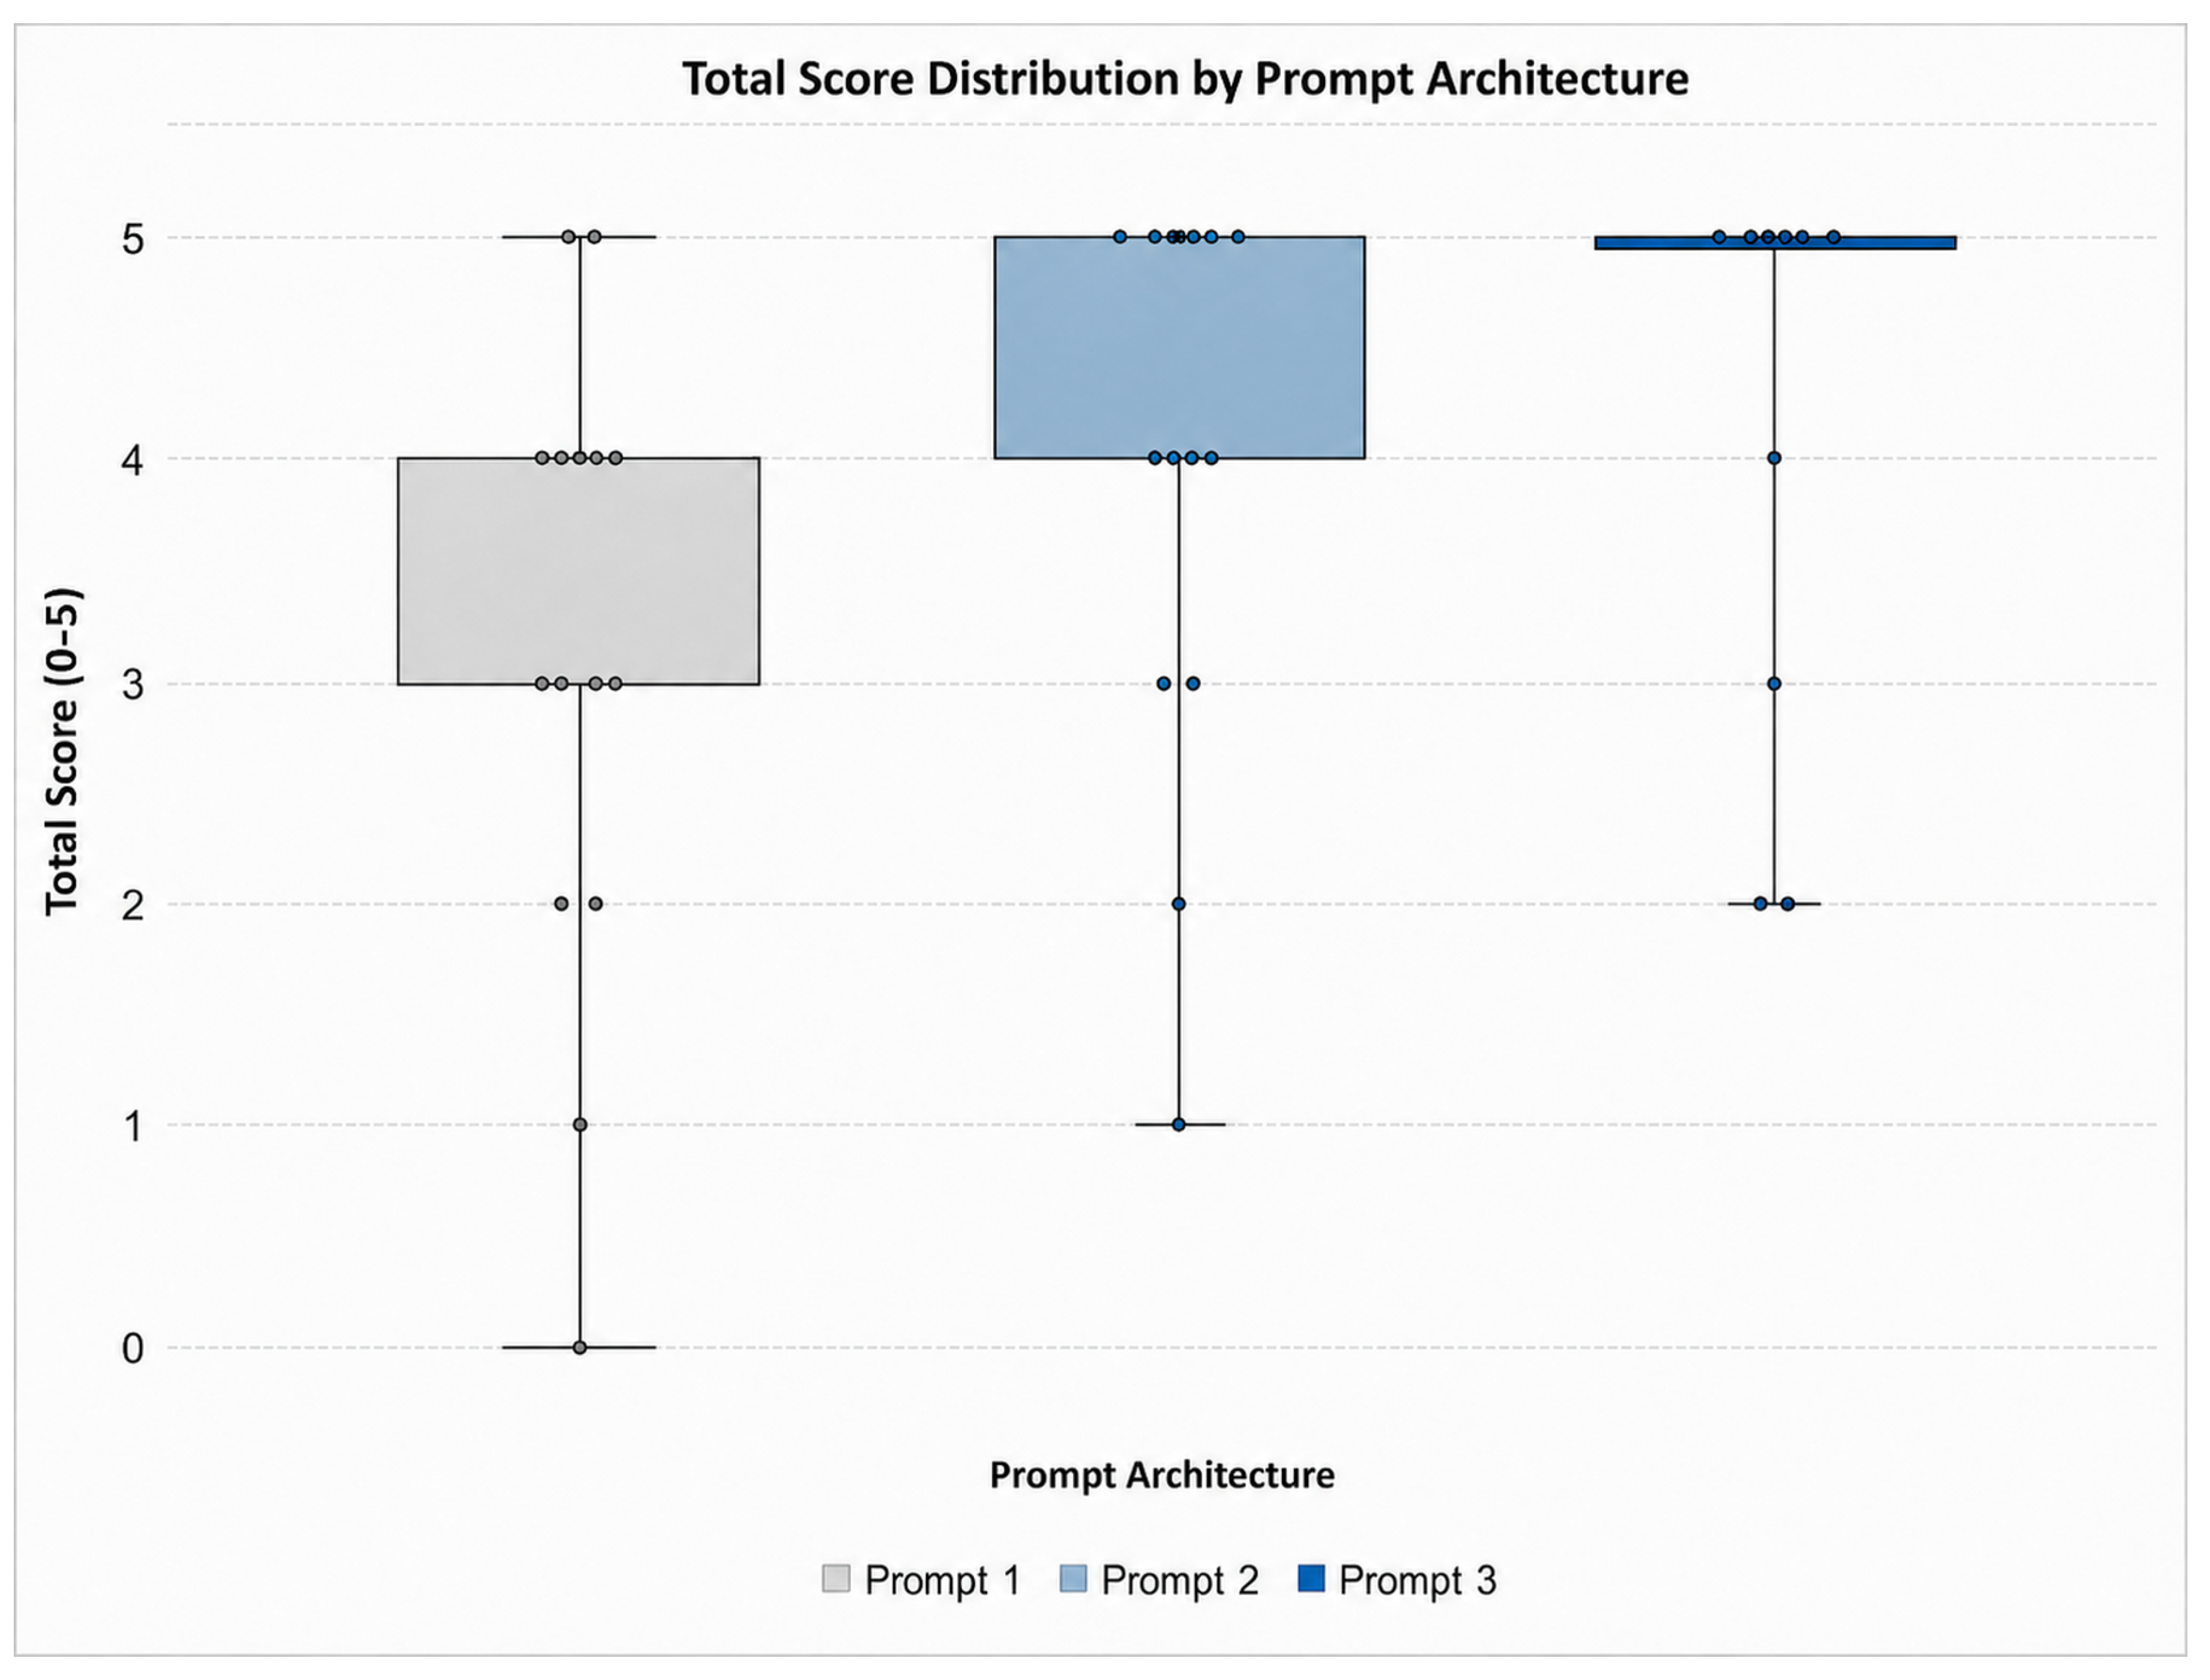
Figure 4.
Image-interpretation variables accuracy across prompt architectures.
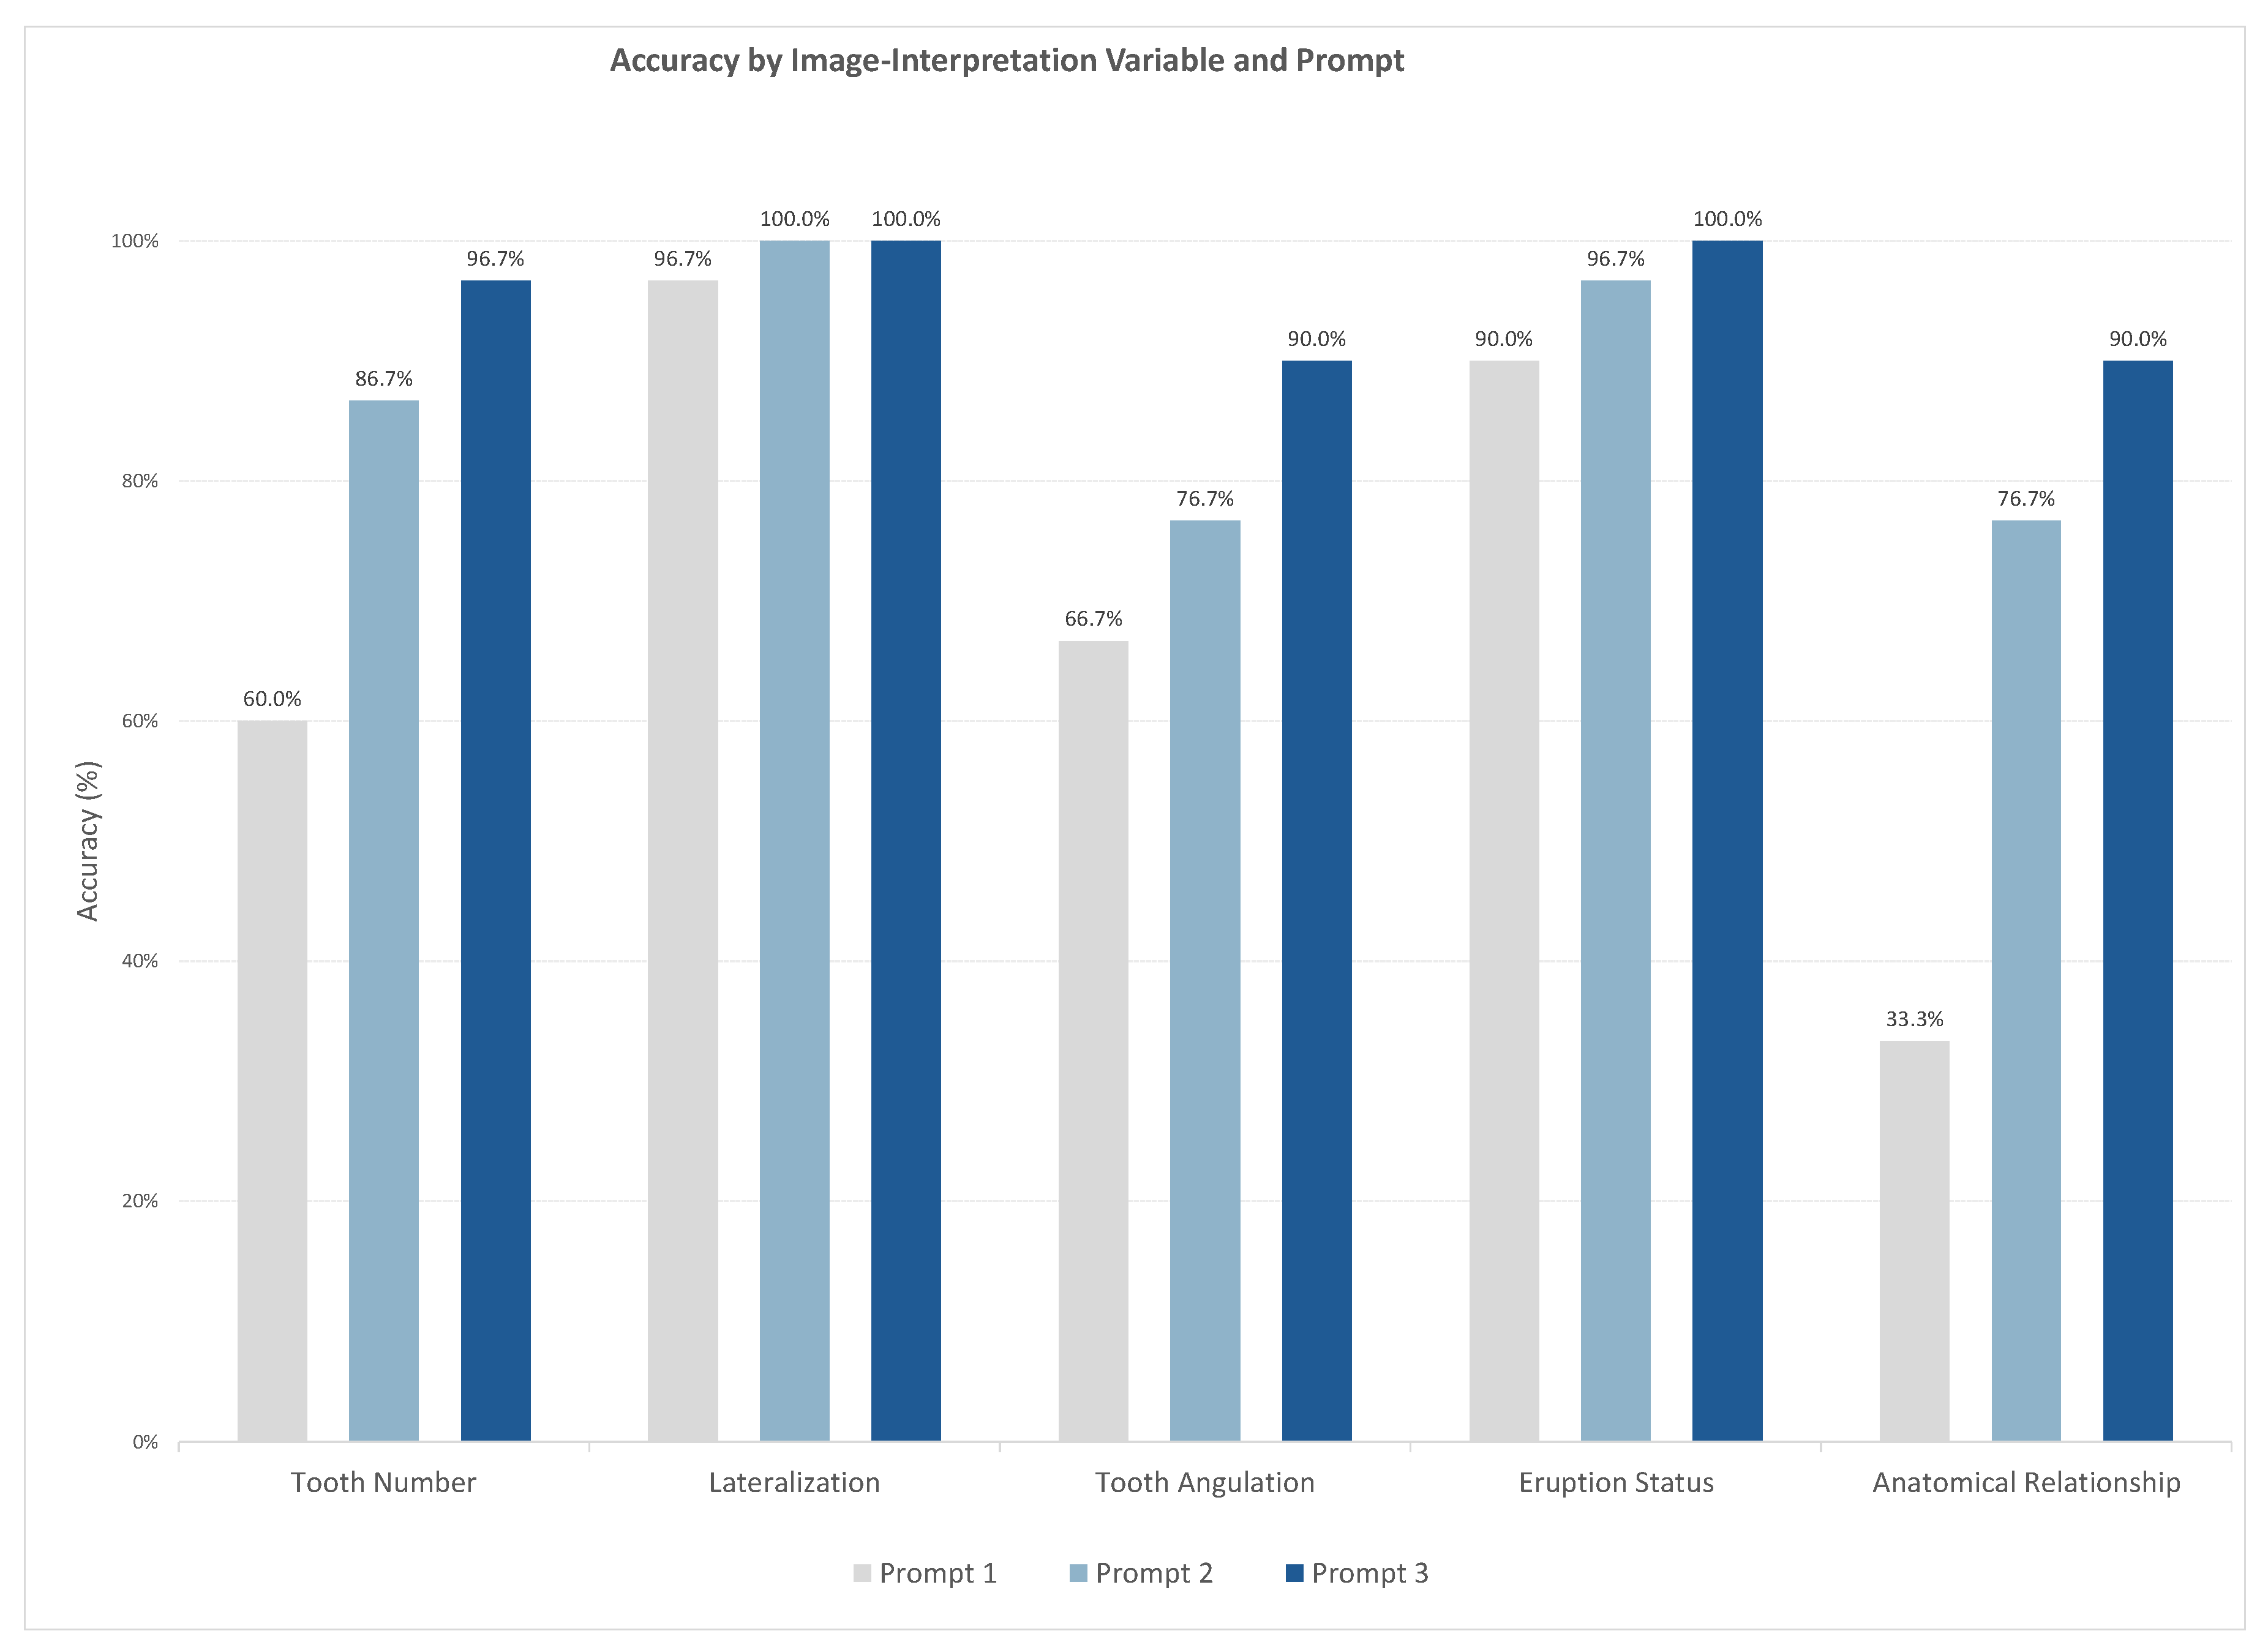
Table 1.
Descriptive statistics for Total Score across prompt architectures
| Prompt architecture | n | Mean ± SD | Median (Q1–Q3) | Minimum–maximum |
|---|---|---|---|---|
| P1 | 30 | 3.47 ± 1.33 | 4.0 (3.0–4.0) | 0–5 |
| P2 | 30 | 4.37 ± 1.03 | 5.0 (4.0–5.0) | 1–5 |
| P3 | 30 | 4.77 ± 0.68 | 5.0 (5.0–5.0) | 2–5 |
Note: SD, standard deviation; Q1, first quartile; Q3, third quartile. Total Score ranged from 0 to 5. The same 30 images were evaluated with each prompt architecture.
Table 2.
Overall paired performance analysis across prompt architectures
| Outcome | Overall test | Statistic | Overall p-value | Pairwise comparison (Holm-adjusted p) |
|---|---|---|---|---|
| Total Score | Friedman | = 21.217 | P1 vs P2: p = 0.0125 P1 vs P3: p = 0.000921 P2 vs P3: p = 0.0199 |
|
| Full Accuracy | Cochran’s Q | Q = 27.70 | P1 vs P2: p = 0.00366 P1 vs P3: p = 0.0000114 P2 vs P3: p = 0.0156 |
Note: Total Score was analyzed using the Friedman test followed by pairwise Wilcoxon signed-rank tests with Holm adjustment. Full Accuracy was analyzed using Cochran’s Q test followed by exact McNemar pairwise comparisons with Holm adjustment.
Table 3.
image-interpretation variables accuracy and paired comparisons across prompt architectures
| Variables | P1, n (%) | P2, n (%) | P3, n (%) | Q | Holm p | Pairwise comparisons |
|---|---|---|---|---|---|---|
| Tooth Number | 18 (60.0%) | 26 (86.7%) | 29 (96.7%) | 12.93 | 0.0062 | P1 vs P3: p = 0.0103* |
| Tooth Angulation | 20 (66.7%) | 23 (76.7%) | 27 (90.0%) | 8.22 | 0.0492 | P1 vs P3: p = 0.0469* |
| Anatomical Relationship | 10 (33.3%) | 23 (76.7%) | 27 (90.0%) | 24.95 | P1 vs P2: p = 0.00195*; P1 vs P3: p = 0.000229* | |
| Lateralization | 29 (96.7%) | 30 (100.0%) | 30 (100.0%) | 2 | 0.3679 | None |
| Eruption Status | 27 (90.0%) | 29 (96.7%) | 30 (100.0%) | 3.5 | 0.3475 | None |
Q = Cochran’s Q statistic. Holm p = overall p-value adjusted across variables. Pairwise p-values correspond to exact McNemar tests with Holm adjustment. Only statistically significant pairwise comparisons are shown. *p < 0.05.
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (http://creativecommons.org/licenses/by/4.0/).
Copyright: This open access article is published under a Creative Commons CC BY 4.0 license, which permit the free download, distribution, and reuse, provided that the author and preprint are cited in any reuse.