
Submitted:
01 September 2026
Posted:
02 September 2026
You are already at the latest version
Abstract
Falls represent a critical public health concern, particularly for older adults and individuals with disabilities, often resulting in serious injuries, loss of independence, and increased mortality. Traditional fall detection systems suffer from high false positive rates, privacy concerns, and limited real-world applicability. This study presents an improved non-wearable fall detection method integrating YOLOv8-based skeletal pose estimation with load distribution sensing through decision-level sensor fusion. The system employs YOLOv8 for real-time human posture analysis and skeletal motion-based fall recognition, addressing limitations of simple presence-based or LiDAR-only approaches. A distributed Force-Sensitive Resistor (FSR) array embedded in the sensing surface monitors relative floor-loading patterns and impact-related changes. Decision-level fusion with temporal filtering combines skeletal postural and motion information with floor-load evidence, enabling accurate fall detection with substantially fewer false positives than the vision-only configuration. Key methodologies include detailed load sensor calibration, time-domain filtering to distinguish intentional lying from falls, and fusion logic leveraging the complementary strengths of visual and floor-based FSR sensing. Experimental evaluation in a controlled indoor environment configured to represent a residential setting achieved an F1-score of 0.935, specificity of 97.5%, and an 82% reduction in false-positive count compared with the vision-only configuration. This modular ROS2-based system provides a practical, non-intrusive framework with potential for future deployment in residential and assisted-living settings, while supporting extension to broader assistive monitoring applications.
Keywords:
fall detection
; sensor fusion
; YOLOv8
; pose estimation
; force-sensitive resistor
; RGB vision
; ambient assisted living
; human activity recognition
; ROS2
; smart healthcare
1. Introduction
1.1. Background and Motivation
Falls represent one of the leading causes of injury-related mortality and disability worldwide, particularly among older adults and individuals with impaired mobility. According to the World Health Organization, falls are the second leading cause of unintentional injury deaths worldwide, after road traffic injuries, with adults over 60 years of age experiencing the greatest number of fatal falls [1]. Beyond the immediate physical injuries, falls frequently result in prolonged immobilisation, loss of independence, psychological trauma, reduced quality of life, and substantial healthcare expenditure. Falls impose a substantial economic burden on healthcare services in the United Kingdom, costing the National Health Service (NHS) more than £2.3 billion annually [2]. Delayed recognition of falls further increases the risk of secondary complications, including dehydration, hypothermia, pressure ulcers, rhabdomyolysis, and increased mortality associated with prolonged periods spent on the floor, commonly referred to as the “long lie”. Consequently, reliable and timely fall detection has become an important research challenge within ambient assisted living, intelligent healthcare, and smart home monitoring systems.
A wide range of sensing technologies has been investigated for automatic fall detection over the past two decades. Wearable systems based on inertial measurement units (IMUs) have demonstrated high sensitivity by monitoring characteristic acceleration and angular velocity patterns associated with falls. However, their effectiveness depends on continuous user compliance, regular battery charging, and correct device placement, making them less suitable for older adults and individuals with cognitive impairment [3]. Vision-based approaches provide richer contextual information through continuous observation of human activities without requiring wearable devices. Nevertheless, RGB camera systems remain sensitive to illumination changes, occlusions, camera positioning, and privacy concerns, which can limit their deployment in residential environments [4]. Ambient sensing approaches, including floor vibration sensing, acoustic monitoring, and pressure-sensitive flooring, provide unobtrusive monitoring while preserving user privacy. However, these methods often lack sufficient contextual information to distinguish genuine falls from normal activities of daily living (ADLs), resulting in increased false alarm rates [5].
Although considerable progress has been achieved, current fall detection systems continue to face a fundamental trade-off between sensitivity and specificity. Systems designed to maximise sensitivity frequently generate false alarms during normal daily activities such as rapidly sitting down, bending, kneeling, or intentionally lying on the floor [6]. Conversely, methods designed to minimise false positives may fail to detect genuine falls, particularly slow collapses or falls occurring during transitional movements. Achieving both high detection accuracy and a low false alarm rate therefore remains one of the principal challenges in automatic fall detection.
These limitations arise primarily because individual sensing modalities provide only partial information about a fall event. Vision-based systems can accurately estimate body posture but may struggle under poor lighting conditions, occlusions, or cluttered environments. Wearable sensors require long-term user adherence, which is often impractical for vulnerable populations. Similarly, floor-based FSR sensing systems can detect impact forces and weight distribution but cannot independently distinguish between a person falling and an external object striking the floor. Consequently, increasing attention has been directed towards multimodal sensing approaches that exploit complementary information from different sensor modalities to improve overall robustness.
Recent advances in deep learning have significantly improved real-time human pose estimation through lightweight object detection architectures such as YOLOv8 [7]. Unlike conventional object detection approaches that rely primarily on bounding box analysis, skeletal pose estimation provides detailed information regarding body configuration, joint movement, and postural dynamics. Simultaneously, advances in force-sensing technologies have enabled accurate monitoring of force-related floor response and load distribution during human movement. The integration of these complementary sensing modalities provides an opportunity to improve fall-detection performance by combining physical floor-interaction evidence with visual posture information, while local processing can reduce the exposure of captured image data.
1.2. Related Work and Research Gap
Automatic fall detection has attracted considerable research attention over the past two decades, resulting in a wide range of wearable, vision-based, ambient sensing, and multimodal approaches. Wearable systems based on accelerometers and gyroscopes have demonstrated high sensitivity by detecting characteristic acceleration and orientation changes during falls. However, their performance depends on continuous user compliance, correct device placement, and regular maintenance, making them less suitable for long-term monitoring of older adults and individuals with cognitive impairment [3].
Vision-based methods have evolved from conventional image processing techniques to modern deep learning approaches capable of recognising human activities directly from image sequences. Early systems relied on silhouette extraction, bounding-box aspect ratios, optical flow, or handcrafted geometric features to distinguish falls from normal activities. More recently, convolutional neural networks and human pose estimation models have improved recognition performance by extracting semantic representations of human posture and movement [4]. Among these approaches, YOLOv8-based pose estimation provides an attractive balance between computational efficiency and localisation accuracy by simultaneously detecting human subjects and estimating anatomical keypoints in real time [7]. Compared with conventional bounding-box methods, skeletal pose estimation provides a richer representation of human posture and movement, including body orientation, joint configuration, relative body position, and limb dynamics, which are particularly valuable for recognising fall events.
Ambient sensing approaches offer an alternative privacy-preserving solution by monitoring environmental changes associated with falls. Pressure-sensitive flooring, vibration sensors, acoustic sensors, and radio-frequency sensing have demonstrated promising results without requiring wearable devices or continuous image recording [5]. Nevertheless, these systems generally lack sufficient contextual information regarding human posture and movement, making it difficult to distinguish falls from other high-impact events such as dropped objects or abrupt furniture movement.
Despite these advances, existing fall detection systems continue to face a fundamental challenge in balancing detection sensitivity with false alarm reduction. Vision-based approaches frequently generate false alarms when normal activities of daily living, such as bending, kneeling, rapidly sitting down, or intentionally lying on the floor, exhibit motion characteristics similar to accidental falls [6]. Conversely, approaches employing conservative detection thresholds to minimise false positives may fail to recognise genuine falls, particularly slow collapses or transitional movements. This trade-off remains one of the principal challenges preventing widespread deployment of automatic fall detection systems in residential and assisted living environments.
Recent research has increasingly explored multimodal sensor fusion to exploit the complementary strengths of different sensing technologies. Data fusion can be performed at the signal, feature, or decision level, each presenting different computational requirements and robustness characteristics [8,9]. Decision-level fusion is particularly attractive because each sensing modality can operate independently while contributing complementary evidence to the final decision, improving robustness against sensor failure, environmental variability, and measurement uncertainty.
Although multimodal approaches have demonstrated improved performance, relatively few studies have combined modern real-time skeletal pose estimation with distributed floor-based force sensing using a decision-level fusion strategy. Furthermore, many existing systems employ computationally demanding pose estimation frameworks, expensive sensing hardware such as LiDAR, or require wearable devices that reduce user acceptance. Limited attention has also been given to integrating temporal reasoning with complementary physical evidence obtained from floor-based force and load measurements, despite the potential of such information to reduce false alarms associated with normal daily activities.
These limitations reveal an important research gap. There remains a need for a practical, low-cost fall detection framework capable of combining accurate skeletal posture estimation with floor-based force sensing while maintaining real-time performance and high detection reliability. Addressing this gap motivates the development of the multimodal sensor fusion framework presented in this study. To further position the proposed framework within the current state of the art, Table 1 summarises representative fall detection approaches and compares them with the proposed system. The comparison highlights the sensing modality, pose estimation capability, sensor fusion strategy, real-time suitability, and principal limitations of each approach. It demonstrates that while many studies have investigated individual sensing modalities, relatively few have combined real-time skeletal pose estimation with distributed floor-based force sensing using a decision-level fusion framework.
1.3. Proposed Approach
To address the limitations of existing single-modality fall detection systems, this study proposes a real-time, non-wearable multimodal fall detection framework that combines vision-based skeletal pose estimation with floor-based force sensing through a decision-level sensor fusion strategy. The proposed framework integrates complementary information from both sensing modalities to improve detection robustness while maintaining low computational complexity and supporting privacy-conscious local processing for deployment in residential care environments.
The vision subsystem employs an Intel RealSense D435 RGB-D camera together with the YOLOv8n-pose network to continuously estimate human skeletal keypoints. Unlike conventional fall-detection methods that rely primarily on bounding-box geometry, the proposed approach exploits anatomical keypoint locations to derive skeletal postural and motion descriptors. These include torso inclination, body orientation, normalized trunk-centroid position, trunk-centroid velocity, and postural transitions, providing a more informative representation of fall dynamics than simple silhouette or bounding-box analysis [7,10].
In parallel, a distributed floor-mounted Force Sensitive Resistor (FSR) array continuously monitors relative floor-loading measurements generated during human movement. The floor-based FSR sensing subsystem measures total load, impact intensity, and spatial load distribution, providing complementary physical evidence that cannot be inferred reliably from vision alone. While vision-based systems may misclassify intentional lying or rapid sitting as falls, floor-based force sensing can identify characteristic impact patterns associated with genuine fall events. Conversely, floor-based FSR sensing alone lacks information regarding body posture and movement, making it difficult to distinguish falls from dropped objects or other environmental disturbances [5].
Rather than merging raw sensor measurements or extracted features, the proposed framework performs decision-level fusion by allowing each sensing modality to independently analyse the observed event before combining their outputs through a temporal finite-state decision model. Decision-level fusion offers several advantages, including modular system design, robustness to temporary sensor failure, reduced computational complexity, and improved scalability for future integration of additional sensing modalities [8,9]. Temporal reasoning is incorporated to model the natural sequence of a fall event, enabling the framework to distinguish accidental falls from normal activities of daily living by considering both movement dynamics and the persistence of the final posture.
The complete system is implemented within a Robot Operating System 2 (ROS2) architecture, allowing asynchronous communication between sensing modules while supporting real-time processing. The modular design enables each sensing component to operate independently, facilitating future system expansion and straightforward deployment in smart home and assisted living environments.
The proposed framework was evaluated using representative indoor fall scenarios and activities of daily living performed by healthy volunteers. Experimental evaluation considered detection sensitivity, specificity, precision, accuracy, F1-score, detection latency, and comparative performance against vision-only and load-only configurations. Through this comprehensive evaluation, the study investigates whether integrating complementary skeletal-pose and floor-load information can reduce false alarms while maintaining reliable fall detection performance in real-time indoor monitoring applications.
1.4. Contributions and Paper Organisation
This paper presents a practical multimodal fall-detection framework that combines skeletal pose estimation with distributed floor-based force sensing for real-time indoor monitoring. Unlike conventional single-modality approaches, the proposed framework exploits complementary visual postural information and floor-interaction evidence through a decision-level sensor-fusion strategy to improve detection robustness while maintaining computational efficiency.
The principal scientific contributions of this work are summarised as follows:
- 1.
- A decision-level multimodal sensor fusion framework integrating YOLOv8 skeletal pose estimation with a distributed Force Sensitive Resistor (FSR) sensing platform for real-time indoor fall detection. The proposed framework combines complementary visual postural information and floor-load evidence to improve detection robustness compared with individual sensing modalities.
- 2.
- A temporal finite-state decision model that combines human posture, normalized trunk-centroid motion, torso orientation, impact detection, and spatial load distribution to distinguish accidental falls from activities of daily living while reducing false-positive detections.
- 3.
- The design, implementation, and calibration of a low-cost floor-based sensing platform capable of continuously monitoring relative floor-loading measurements, impact events, and load distribution, providing complementary information to vision-based posture estimation without requiring wearable devices.
- 4.
- A comprehensive experimental evaluation using representative fall scenarios and activities of daily living performed in a controlled indoor environment configured to represent a residential setting. The proposed framework achieved an F1-score of 0.935, a sensitivity of 90.0%, a specificity of 97.5%, and reduced false-positive count by 82% compared with a vision-only configuration while maintaining real-time performance.
- 5.
- An experimental comparison between vision-only, load-only, and multimodal fusion approaches, demonstrating the effectiveness of decision-level sensor fusion for improving the balance between detection sensitivity and specificity in practical indoor monitoring applications.
The remainder of this paper is organised as follows. Section 2 presents the materials and methods, including the sensing platform, skeletal and floor-sensor feature extraction, temporal fusion framework, experimental protocol, ground-truth labelling, and statistical analysis. Section 3 reports the experimental results, including classification performance, modality comparisons, failure analysis, and computational performance. Section 4 discusses the findings, practical implications, and study limitations. Finally, Section 5 concludes the paper and identifies directions for future research.
2. Materials and Methods
2.1. Overall System Architecture
The proposed multimodal fall detection framework combines vision-based skeletal pose estimation with floor-based force sensing through a decision-level sensor fusion strategy. The system is non-wearable and supports privacy-conscious local processing; however, the use of RGB imagery means that privacy remains an important consideration for real-world deployment. An overview of the proposed architecture is presented in Figure 1.
The framework consists of three principal modules: (i) an RGB-D vision subsystem responsible for estimating human skeletal posture, (ii) a floor-based sensing subsystem that monitors floor-load response and impact events using a distributed Force Sensitive Resistor (FSR) array, and (iii) a decision-level fusion module that combines the outputs of both sensing modalities to determine whether a fall has occurred.
The vision subsystem acquires image data using an Intel RealSense D435 RGB-D camera. In the implementation evaluated in this study, the RGB stream is processed using the YOLOv8n-pose network to estimate human skeletal keypoints. These two-dimensional keypoint coordinates are subsequently used to derive image-based skeletal descriptors, including torso inclination, normalized trunk-centroid position, and trunk-centroid velocity. Although synchronised depth data are available from the D435 platform, depth measurements are not directly incorporated into the present fall-classification algorithm.
In parallel, the floor-based FSR sensing subsystem continuously acquires relative load measurements from the distributed FSR array. The acquired signals are processed to estimate the total applied load, spatial load distribution, load centroid, and impact intensity. These load-based features provide complementary information regarding human interaction with the floor surface and enable the identification of high-impact events associated with falls.
Rather than combining heterogeneous sensor measurements directly, the proposed framework adopts a decision-level fusion strategy. Independent decisions generated by the vision and force sensing subsystems are integrated using a temporal finite-state model that exploits the complementary strengths of both sensing modalities. This approach improves robustness to temporary sensor degradation, simplifies system modularity, and allows each sensing modality to operate independently while contributing evidence towards the final fall detection decision.
The complete processing pipeline begins with concurrent acquisition of RGB-D images and FSR measurements. Sensor-specific features are extracted independently before being evaluated by their respective detection modules. The resulting decisions are subsequently fused within the temporal decision model, producing the final classification of each activity as either a fall or an activity of daily living (ADL).

Table 2.
Summary of the proposed multimodal fall detection pipeline.
| Stage | Input | Output |
|---|---|---|
| Image acquisition | RGB stream (depth available) | RGB image frames |
| YOLOv8 pose estimation | RGB image | 17 skeletal keypoints |
| Vision feature extraction | Keypoints | Torso angle, trunk centroid, velocity |
| FSR acquisition | Raw voltages | Load measurements |
| Load feature extraction | FSR measurements | load centroid, total load, impact score |
| Decision-level fusion | Vision + load decisions | Fall / ADL classification |
The overall decision generated by the proposed framework is obtained by combining the independent outputs of the vision and floor-based FSR sensing according to
where and denote the decisions generated by the vision and force sensing subsystems at time t, respectively, and represents the temporal decision-level fusion function.
2.2. Hardware Platform
The proposed multimodal fall detection framework integrates complementary vision and floor-based sensing technologies within a unified real-time monitoring platform. The hardware configuration consists of three principal components: (i) an RGB-D vision subsystem for skeletal pose estimation, (ii) a custom-built floor-mounted Force Sensitive Resistor (FSR) sensing platform for monitoring floor-load response, and (iii) a workstation responsible for real-time sensor processing and decision-level fusion. The complete experimental configuration is illustrated in Figure 2.
The vision subsystem continuously captures synchronised RGB-D images that are processed using the YOLOv8n-pose network to estimate human skeletal posture. Simultaneously, the floor-sensing subsystem measures dynamic loading generated during human movement and extracts complementary load-related features including total load, voltage-weighted load centroid, and impact intensity.
Data from both sensing modalities are processed independently before being combined through the proposed decision-level fusion framework. Communication between sensing modules is implemented using the Robot Operating System 2 (ROS2), providing modularity, asynchronous data acquisition, and straightforward integration of additional sensing modalities.
Table 3.
Hardware components used in the proposed multimodal fall detection framework.
| Component | Model | Purpose |
|---|---|---|
| RGB-D Camera | Intel RealSense D435 | RGB-D image acquisition |
| Pose Estimation | YOLOv8n-pose | Human pose estimation |
| Force Sensors | Force Sensitive Resistors (FSRs) | Floor-load and impact sensing |
| Microcontroller | Arduino Mega 2560 | FSR data acquisition |
| Processing Unit | Desktop workstation with NVIDIA RTX GPU | Real-time processing |
| Software Framework | ROS2 | Communication and integration |
2.2.1. RGB-D Vision System
Human movement was monitored using an Intel RealSense D435 RGB-D camera. The camera simultaneously acquires synchronised RGB and depth images at a spatial resolution of 640 × 480 pixels and a frame rate of 30 frames per second. During all experiments, the camera was mounted approximately 1.9 m above the floor with a downward inclination to maximise coverage of the monitored area while minimising self-occlusion.
RGB images acquired by the Intel RealSense D435 were processed using the YOLOv8n-pose network for real-time skeletal pose estimation. Although the D435 provides synchronised RGB and depth streams, the fall-detection algorithm evaluated in the present study uses the RGB stream for pose estimation and derives the proposed skeletal descriptors from two-dimensional image-plane keypoint coordinates. The depth stream was available through the acquisition platform but was not used directly in the decision-level fusion algorithm evaluated in this study. Accordingly, the vision-derived features reported in this work should be interpreted as image-based postural descriptors rather than metric three-dimensional biomechanical measurements. The camera was selected because of its real-time image acquisition capability, compact form factor, and ROS2 compatibility [11].
Table 4.
Intel RealSense D435 camera configuration and data usage.
| Parameter | Value |
|---|---|
| Camera model | Intel RealSense D435 |
| RGB resolution | pixels |
| RGB frame rate | 30 FPS |
| Available depth technology | Active stereo |
| Stream used for pose estimation | RGB |
| Pose representation | 2-D skeletal keypoints |
| Depth used in fall classification | No |
| Mounting height | 1.9 m |
| Camera orientation | Downward-facing |
2.2.2. Floor-Based Force Sensing Platform
Force-related floor responses were measured using a custom-designed sensing platform consisting of a distributed array of Force Sensitive Resistors (FSRs) positioned beneath a rigid floor surface. The sensing platform continuously monitored dynamic loading generated during human movement, enabling detection of impact events and spatial load distribution associated with both falls and activities of daily living.
Each FSR was connected to an Arduino Mega 2560 microcontroller through analogue input channels. Sensor voltages were sampled at 50 Hz and transmitted to the processing workstation via a serial communication interface.
2.2.3. Processing Hardware
Real-time processing was performed on a desktop workstation equipped with an NVIDIA RTX-series graphics processing unit (GPU). Vision processing, skeletal feature extraction, force sensing, and decision-level fusion were implemented within the Robot Operating System 2 (ROS2), allowing independent execution of sensing modules while maintaining real-time performance and supporting monitoring. The modular processing architecture enables each sensing modality to operate asynchronously, facilitating future integration of additional sensing technologies without modification of the existing processing pipeline.
2.3. Vision-Based Skeletal Pose Estimation
The vision subsystem continuously estimates human posture from RGB images acquired using the Intel RealSense D435 camera. Human skeletal pose estimation is performed using the YOLOv8n-pose network, which simultaneously detects human subjects and predicts anatomical keypoints in real time. Compared with conventional fall-detection approaches based solely on bounding-box geometry, skeletal pose estimation provides a richer representation of body posture by explicitly estimating anatomical keypoint locations. These descriptors include torso inclination, body orientation, normalized trunk-centroid position, and trunk-centroid velocity, which together provide a robust representation of postural transitions associated with both falls and activities of daily living.
2.3.1. YOLOv8 Pose Estimation
Human skeletal pose estimation was performed using the YOLOv8n-pose architecture [7]. The network simultaneously performs human detection and anatomical keypoint localisation using a single-stage deep learning framework, supporting real-time skeletal pose estimation.
For each detected subject, the network predicts a bounding box together with seventeen anatomical keypoints corresponding to the major joints of the human body. Each detected keypoint is represented by its image coordinates and an associated confidence score, which quantifies localisation reliability. Only keypoints exceeding a predefined confidence threshold were retained for subsequent feature extraction. Each YOLOv8n-pose inference produces detected persons . For each detected person, the model estimates a bounding box , a detection confidence , and skeletal keypoints , where denote image coordinates and represents the corresponding keypoint confidence.
The observed skeletal keypoints are modelled as
where represents localisation noise arising from image uncertainty, partial occlusion, and detector variability. Keypoints with confidence values below the threshold given in Table 7 were discarded prior to feature extraction.
2.3.2. Skeletal Feature Extraction
The estimated skeletal keypoints were used to derive a set of image-based postural and motion descriptors representing body configuration and movement throughout each activity. Unlike conventional approaches that rely solely on body orientation or bounding-box geometry, the proposed framework combines multiple complementary posture descriptors to improve robustness under varying movement conditions.
The torso inclination angle provides a direct measure of upper-body orientation relative to the vertical axis. Increasing torso inclination is typically associated with the transition from an upright posture towards a fall event.
The torso inclination angle was used as one of the posture descriptors within the decision-level fusion framework. Based on empirical evaluation during the pilot experiments, three posture regions were defined. Torso inclination angles below were classified as upright, angles between and were considered transitional, and angles greater than were classified as lying or near-horizontal. These thresholds were selected to provide reliable discrimination between normal standing activities, transitional movements, and fall-related postures while maintaining robustness across participants.
where and represent the image coordinates of the neck and hip midpoints, respectively. Larger absolute values of indicate increasingly horizontal body posture.
A normalized image-plane trunk-centroid position was estimated using the four principal trunk keypoints corresponding to the left and right shoulders and hips. This descriptor provides a two-dimensional representation of vertical trunk position and is used to characterize body movement during standing, walking, sitting, and falling activities.
where denotes the set of left and right shoulder and hip keypoints, is the corresponding keypoint confidence, is the vertical image coordinate of keypoint j, and H is the image height. Normalization by H produces a dimensionless image-plane vertical-position descriptor.
Rapid downward movement is quantified by differentiating consecutive trunk-centroid estimates:
where corresponds to the image acquisition interval. A value of exceeding the threshold listed in Table 7 indicates rapid downward image-plane motion consistent with a potential fall. Since the position descriptor is normalized by image height, represents normalized image-plane velocity rather than metric physical velocity in .
Table 5.
Vision-based skeletal descriptors extracted from the estimated human pose.
| Feature | Symbol | Purpose |
|---|---|---|
| Torso inclination | Body orientation | |
| Normalized trunk centroid | Vertical trunk position | |
| Trunk-centroid velocity | Rapid downward motion | |
| Keypoint confidence | Measurement reliability |
The extracted skeletal descriptors constitute the visual evidence used by the proposed decision-level fusion framework. These posture-related features are subsequently combined with complementary load and floor-interaction information obtained from the FSR sensing platform to improve fall-detection robustness while reducing false-positive detections during activities of daily living.
2.4. Floor-Based Force Sensing
The floor-sensing subsystem provides complementary physical information by continuously monitoring load changes generated during human interaction with the instrumented floor surface. Unlike vision-based sensing, which primarily characterises body posture, the distributed Force Sensitive Resistor (FSR) platform directly provides relative measurements of physical interaction between the participant and the instrumented floor surface. The sensing platform consists of a distributed array of Force Sensitive Resistors embedded beneath a rigid monitoring surface. Each sensor measures the local pressure applied to the floor and transmits analogue voltage measurements to an Arduino Mega 2560 microcontroller operating at a sampling frequency of 50 Hz. The acquired measurements are subsequently transmitted to the processing workstation through a serial communication interface for feature extraction and sensor fusion.
- Total load
- load centroid
- Impact score
These descriptors provide complementary evidence regarding floor interaction during both falls and activities of daily living, improving robustness when combined with visual posture information. The total load is computed by summing the outputs of all active sensors,
where denotes the voltage measured by the i-th FSR sensor and is the total number of sensors. The spatial distribution of the applied load is represented by the voltage-weighted load centroid,
where denotes the spatial location of the i-th sensor within the instrumented floor area. Because the weighting is based on calibrated relative FSR outputs rather than absolute force measurements, is interpreted as a voltage-weighted load-centroid descriptor rather than a biomechanical centre-of-pressure measurement.
where is the FSR sampling interval. An impact score exceeding the threshold listed in Table 7 is interpreted as evidence of floor impact.
Table 6.
Load-based features extracted from the distributed FSR sensing platform.
| Feature | Symbol | Purpose |
|---|---|---|
| Total Load | Overall applied load | |
| Load centroid | Spatial load distribution | |
| Impact Score | I | Rapid impact detection |
2.5. FSR Calibration
Accurate and repeatable load measurements require calibration of the FSR sensing platform to compensate for manufacturing variability and nonlinear sensor response. Prior to experimental evaluation, each FSR sensor was calibrated individually using a series of known static reference loads.
Known calibration masses were sequentially applied directly above each sensing element while the corresponding analogue voltage output was recorded. Measurements were repeated three times for each load level, and the mean response was used to characterise the sensor behaviour.
Because the proposed framework relies primarily on relative load-based descriptors rather than absolute force estimation, calibration was performed to improve consistency between sensors rather than to obtain high-precision force reconstruction. The resulting calibration coefficients were subsequently applied during online processing to compensate for sensor-to-sensor variability. The calibrated sensor output is expressed as
where and represent the calibration coefficients determined for the i-th sensor.
2.6. Decision-Level Sensor Fusion
The proposed framework adopts a decision-level sensor fusion strategy to combine complementary information obtained independently from the vision and floor-sensing subsystems. Unlike signal-level or feature-level fusion, decision-level fusion allows each sensing modality to operate independently while contributing evidence towards the final classification decision.
The vision branch converts the extracted skeletal descriptors into a binary visual transition decision , while the floor-sensing branch converts the load-derived descriptors into a binary floor-event decision . These modality-specific decisions, together with their temporal histories, are evaluated by the finite-state model.
The overall fusion process is expressed as
where and represent the vision-based and force-based decisions at time t, respectively.
A fall decision is not generated from a single-frame conjunction of the two sensing modalities. Instead, the proposed framework integrates temporally accumulated visual and force-based evidence within the finite-state decision model. The vision subsystem identifies a candidate fall transition when rapid downward trunk-centroid motion, increasing torso inclination, or another substantial postural change is detected. A fall is subsequently confirmed only when the temporal sequence of observations satisfies the transition and persistence criteria defined by the state machine.
Accordingly, the fused fall decision can be expressed as
where denotes whether visual evidence of an upright-to-floor transition has been detected within the fall window , denotes whether corroborating floor-sensor evidence has been detected, and denotes whether the required floor-level or lying-posture persistence criterion has been satisfied. These criteria are evaluated over a temporal interval and are therefore not required to occur simultaneously within a single image frame. Consequently, the fusion rule represents the logical evidence required for fall confirmation, whereas the temporal ordering of these observations is governed by the finite-state model described in the following subsection.
2.7. Temporal State Machine
To improve robustness against transient posture changes and isolated sensor events, the fused observations are evaluated using a temporal finite-state machine. Rather than relying on instantaneous measurements, the state machine models the sequential evolution of posture, motion, and floor-interaction evidence throughout a potential fall event.
Four states are defined:
- 1.
- Standing,
- 2.
- Transitioning,
- 3.
- Fallen, and
- 4.
- Recovery.
The system normally remains in the Standing state while the subject exhibits an upright posture without substantial downward trunk-centroid motion. A transition to the Transitioning state occurs when rapid downward trunk-centroid motion, increasing torso inclination, or another substantial postural change provides visual evidence of a potential fall.
During the Transitioning state, the system searches for corroborating evidence from the FSR sensing platform, including an impact event or a load-distribution pattern consistent with body–floor contact. The candidate fall transition must occur within the maximum fall interval . If the required evidence is not observed within this interval, the event is rejected and the system returns to the Standing state.
Following floor contact, the system evaluates whether the subject remains in a floor-level or lying configuration for at least the minimum persistence duration . Once the required visual transition evidence, floor-sensor corroboration, and postural persistence have been observed, the system enters the Fallen state and generates a fall alarm. Importantly, the individual criteria are not required to occur simultaneously within a single frame; rather, evidence is accumulated over the fall sequence.
The Fallen state is maintained while the subject remains in the detected floor-level posture. When the visual subsystem indicates a sustained transition away from the floor-level configuration towards an upright posture, the system enters the Recovery state. Once an upright posture is re-established, the state machine returns to Standing and resumes monitoring for subsequent events.
The temporal state evolution can be represented as
where denotes the current system state, and represent the recent histories of vision-derived and floor-sensor observations, respectively, and denotes the elapsed time since entry into the current state. The transition function evaluates the accumulated observations together with the temporal constraints and to determine the subsequent state.
This temporal reasoning reduces false alarms caused by transient activities such as rapid sitting, kneeling, bending, or intentional lying by requiring an appropriate sequence of postural transition, floor-interaction evidence, and sustained floor-level posture before a fall is confirmed.
2.8. Decision Thresholds
The proposed fall-detection framework employs a small number of empirically selected thresholds to distinguish fall events from activities of daily living. These parameters were determined during preliminary experiments using a separate pilot dataset collected prior to the main evaluation and were subsequently fixed for all experimental trials. Table 7 summarises the thresholds used by the proposed framework.
Table 7.
Decision thresholds and system parameters used by the proposed fall detection framework.
| Parameter | Symbol | Value | Purpose |
|---|---|---|---|
| Keypoint confidence | 0.50 | Reject unreliable skeletal keypoints | |
| Upright posture | Upper limit for upright posture | ||
| Lying posture | Identify near-horizontal posture | ||
| Trunk-centroid velocity | Detect rapid downward image-plane motion | ||
| Impact | 0.30 | Detect significant floor impact | |
| Minimum lying duration | 2.0 s | Confirm sustained lying posture | |
| Fall transition window | 3.0 s | Maximum fall-to-lying duration | |
| Ground-truth association window | 5.0 s | Associate a generated alarm with the corresponding annotated fall event | |
| Camera frame rate | 30 Hz | RGB image acquisition frequency | |
| FSR sampling rate | 50 Hz | Force sensor sampling frequency |
The decision thresholds were determined empirically during preliminary experiments using a pilot dataset collected prior to the main evaluation. The pilot dataset was excluded from the final experimental evaluation. Multiple candidate threshold values were investigated to achieve an appropriate balance between sensitivity and false-positive rate. Once selected, all thresholds remained fixed throughout the experimental evaluation and were not adjusted using the test data.
2.9. Detection Latency
The temporal architecture of the proposed framework involves two distinct time points following fall onset that must be carefully distinguished.
The candidate-fall detection time denotes the moment the fusion node first accumulates sufficient evidence to identify a potential fall transition — specifically, when rapid downward trunk-centroid motion and increasing torso inclination satisfy the visual transition criterion and are corroborated by a positive FSR impact event. At this point the system enters the Transitioning state. No alarm is issued yet.
The final alarm time denotes the moment the system enters the Fallen state and publishes the fall alarm. This occurs only after the floor-level posture has been sustained for the minimum persistence duration s following . Therefore, by construction:
where accounts for any additional frame-level delay in posture confirmation. The minimum possible alarm latency relative to fall onset is thus s.
The detection latency reported in this study is defined as the candidate-fall detection latency:
where is the manually annotated timestamp at which the participant initiated the fall transition from the preceding upright or stable posture. This metric captures how quickly the system identifies the onset of a fall event from sensor evidence, independently of the mandatory persistence confirmation window.
The mean candidate-fall detection latency is calculated as
where is the number of true-positive fall trials. Detection latency was calculated only for true-positive fall trials.
This two-stage timing model means the reported mean candidate-fall detection latency of s is fully consistent with the s persistence requirement: the candidate detection occurs on average s after fall onset, after which the system waits a further s before issuing the alarm. The total elapsed time from fall onset to alarm is therefore approximately s on average, which remains within the clinically acceptable window given that secondary complications from prolonged floor contact develop over minutes.
2.10. Experimental Protocol
The proposed multimodal fall-detection framework was evaluated under controlled indoor conditions. Eight healthy participants (four male and four female), aged 19–34 years, were recruited from the Anglia Ruskin University staff and student population. Participants reported no musculoskeletal, neurological, or mobility impairments that would affect their ability to perform the experimental activities. Ethical approval was obtained from the Anglia Ruskin University Research Ethics Committee (ETH2526-3122), and written informed consent was obtained from all participants prior to data collection. Activity order was fixed rather than randomised; therefore, potential order or familiarisation effects cannot be excluded. Experimental trials were conducted in an indoor environment designed to represent a residential living space. The monitored area included a tiled floor, domestic furniture, and natural illumination. An Intel RealSense D435 camera was mounted at a height of approximately 1.9 m and inclined downward by approximately . The distributed FSR sensing platform was positioned beneath a thin rubber mat within the monitored floor area.
Each participant completed five simulated fall scenarios:
- 1.
- forward fall;
- 2.
- lateral fall;
- 3.
- backward fall;
- 4.
- slow collapse; and
- 5.
- stumble fall.
To evaluate false-positive performance, five activities of daily living (ADLs) were also performed:
- 1.
- intentional lying down;
- 2.
- rapid sitting to the floor;
- 3.
- bending to pick up an object;
- 4.
- kneeling followed by returning to standing; and
- 5.
- walking through or exiting the monitored area.
Each activity was repeated twice by each participant. Consequently, each participant completed 20 trials, comprising 10 simulated-fall trials and 10 ADL trials. Across the eight participants, the complete evaluation dataset therefore consisted of 160 trials: 80 simulated falls and 80 ADL trials.
Before data collection, participants completed a structured warm-up and received instructions regarding the safe execution of the simulated fall activities. During each trial, the vision and floor-sensing streams were acquired concurrently and timestamped within the ROS2 framework. Participant characteristics are summarised in Table 8.
For real-time operator visualisation, system telemetry was overlaid on the display feed, as illustrated in Figure 3. This visualisation was used for monitoring only and did not alter the RGB-based pose-estimation and decision-fusion pipeline.
2.10.1. Ground-Truth Labelling
Each experimental trial was assigned a ground-truth activity label according to the predefined experimental protocol. Trials corresponding to the five simulated fall scenarios were labelled as falls, whereas trials corresponding to the five activities of daily living were labelled as non-fall events.
For temporal evaluation, recorded RGB sequences were reviewed manually to identify the onset of each simulated fall. The ground-truth fall-onset time, , was defined as the timestamp at which the participant initiated the fall transition from the preceding stable or upright posture. This timestamp was used as the temporal reference for calculating detection latency. A fall alarm generated within 5 s of the manually annotated fall onset was associated with that ground-truth event and classified as a true positive. Fall trials without an alarm within this interval were classified as false negatives.
A system output was classified as a true positive (TP) when a fall alarm was generated for a ground-truth fall trial, and as a false negative (FN) when no fall alarm was generated for that trial. For ADL trials, the absence of a fall alarm was classified as a true negative (TN), whereas an incorrectly generated fall alarm was classified as a false positive (FP).
2.11. Statistical Analysis
Fall-detection performance was evaluated using sensitivity, specificity, precision, accuracy, F1-score, false-positive rate, and detection latency. The classification metrics were calculated from the numbers of true positives (TP), false positives (FP), true negatives (TN), and false negatives (FN).
Sensitivity was calculated as
Specificity was calculated as
Precision was calculated as
Accuracy was calculated as
The F1-score was calculated as the harmonic mean of precision and sensitivity:
The false-positive rate was calculated as
For sensitivity, specificity, precision, and accuracy, 95% confidence intervals were estimated using the Wilson score method. This method was selected because it provides more reliable interval estimates for binomial proportions, particularly when the observed proportion is close to zero or one.
Detection latency was calculated for true-positive fall trials according to Equation 15 and is reported as mean ± standard deviation. Differences in detection latency between fall types were analysed descriptively due to the limited sample size.
2.12. Software Implementation
The proposed multimodal fall detection framework was implemented on Ubuntu 22.04 LTS using Robot Operating System 2 (ROS2) Humble as the communication and process-management middleware. All processing nodes were written in Python 3.10, with vision processing performed using OpenCV 4 and the Ultralytics YOLOv8 framework. GPU-accelerated inference was enabled through NVIDIA CUDA Toolkit 12 on the host workstation’s NVIDIA RTX-series GPU.
2.12.1. Node Architecture
The complete processing pipeline is realised as four independent ROS2 nodes communicating over named topics, as summarised in Table 9. This architecture maintains a clear separation of concerns: each node encapsulates a single sensing modality or processing stage, enabling independent development, testing, and future replacement without modifying the remainder of the pipeline.
2.12.2. Vision Processing Node
The pose_estimator_node subscribes to the RGB image topic and performs YOLOv8n-pose inference on each received frame. The YOLOv8n-pose (nano) model variant was selected to balance keypoint localisation accuracy against inference speed, supporting real-time operation at the 30 Hz camera acquisition rate. Inference was configured with a detection confidence threshold of and an intersection-over-union threshold of for non-maximum suppression. When multiple persons were detected within a single frame, the subject occupying the largest bounding-box area was selected as the primary monitoring target.
For each detected subject, the node extracted the skeletal descriptors defined in Section 2.3.2 — torso inclination , normalised trunk-centroid position , and trunk-centroid velocity — and published them as a custom PoseFeatures message on /pose_features, stamped with the ROS2 system clock for downstream temporal association. Keypoints with confidence below were excluded from all feature computations. When fewer than four core trunk keypoints (bilateral shoulders and hips) met this threshold, the posture classification was set to uncertain and velocity features were zeroed to prevent spurious state-machine transitions under heavy occlusion.
A majority-vote filter over a sliding window of consecutive frames was applied to raw per-frame posture classifications before the state machine received posture updates, suppressing single-frame mis-classifications arising from transient detection failures.
2.12.3. Load Sensor Node
The load_sensor_node established a serial connection to the Arduino Mega 2560 at 115,200 baud and read comma-separated FSR voltage strings at 50 Hz. Each received string was parsed, offset corrected, and sensitivity normalised using the per-sensor calibration coefficients (Section 2.5). The node then computed the load features defined in Section 2.4 — total load , voltage-weighted load centroid , and impact score — and published them as a custom LoadFeatures message on /load_features, stamped with the ROS2 system clock.
To mitigate electrical noise on the Arduino’s analogue input channels, a 10-sample moving-average filter was applied in firmware prior to serial transmission, introducing a worst-case additional latency of 200 ms at 50 Hz — negligible relative to the s persistence window.
2.12.4. Temporal Association in the Fusion Node
The fusion_node subscribed to both /pose_features (30 Hz) and /load_features (50 Hz) simultaneously. Because the two sensing modalities operate at different update rates and communicate asynchronously, strict frame-level synchronisation was neither required nor imposed. Instead, the fusion node maintained an internal cache of the most recently received message from each topic. On receipt of any new PoseFeatures message, the node evaluated the current state-machine transition conditions using that message together with the cached LoadFeatures values. This latest-value association strategy is appropriate because the FSR sampling rate (50 Hz) exceeds the camera frame rate (30 Hz), ensuring that floor-sensor evidence is always fresher than the vision evidence it is paired with.
State transitions, feature values, and timestamps were logged continuously to a ROS2 bag file during all experimental sessions, enabling complete post-hoc replay and trial-level analysis.
2.12.5. Fall Alarm and Suppression
Upon entering the Fallen state, the fusion node immediately published a stamped Boolean alarm message on /fall_alarm, minimising output latency. A 30-second suppression timer prevented repeated alarms for the same fall event during the post-fall lying period. The current state-machine state was simultaneously published on /system_state as a string message to support real-time operator monitoring and post-hoc analysis.
2.12.6. Visualisation
A lightweight visualisation node subscribed to /camera/color/image_raw and /pose_features and overlaid the detected skeleton, posture classification label, current state-machine state, and key feature values on the live RGB feed using OpenCV. This overlay — illustrated in Figure 3 — was used for real-time operator monitoring during experimental trials and for diagnostic inspection of detection errors; it did not influence the RGB-based pose estimation or decision-fusion pipeline.
3. Results and Analysis
3.1. Feature Progression Across Fall Phases
The system’s response during a fall event is illustrated by the representative telemetry shown in Figure 3, captured during a forward fall trial performed by participant P3. During the standing phase immediately preceding the fall, the torso tilt angle remained below , the normalized trunk-centroid position was approximately 0.35–0.40 (upper portion of the frame), and the FSR array registered a relative total-load value of approximately 85 a.u., distributed across a narrow contact footprint consistent with single-stance loading.
During the falling phase, three features responded in rapid succession. The normalized trunk-centroid velocity increased sharply, reaching at the frame shown, indicating rapid downward descent. During the transition phase, the torso inclination increased from the upright region () into the transitional region (–).
The summed FSR response is reported in arbitrary units (a.u.) because the sensing platform was calibrated for relative sensor consistency rather than absolute force reconstruction. Following floor contact, the accumulated visual evidence became consistent with a sustained floor-level posture, with reaching 0.745 and the relative total-load descriptor stabilising at approximately 109.1 a.u., distributed across a wider contact footprint characteristic of the observed lying posture. The fusion node entered the Fallen state upon confirming:
- A lying posture sustained beyond the minimum duration s;
- A standing-to-lying transition within the fall window s;
- A positive impact flag from the load sensor array.
3.2. YOLOv8 Skeletal Tracking in Fallen Posture
Visual inspection of the representative frame in Figure 3 indicates that YOLOv8n-pose maintained detectable upper-body skeletal keypoints in the lying posture, including the shoulders, elbows, and wrists. Similar qualitative behaviour was observed across the experimental trials; however, keypoint localisation accuracy was not independently evaluated against manually annotated skeletal ground truth.
3.3. Confusion Matrix
Table 10 presents the confusion matrix for the proposed fused system across all experimental trials.
The confusion matrix shows that the proposed system correctly detected 72 of 80 fall trials and correctly rejected 78 of 80 activities of daily living. The low number of false positives demonstrates the benefit of requiring complementary evidence from both skeletal pose estimation and floor-based force sensing before confirming a fall event.
3.4. Quantitative Performance Results
3.4.1. Per-Participant Detection Performance
Table 11 summarises fall detection performance for each participant individually. Each participant completed 2 repetitions of each of the 5 fall scenarios (10 fall trials per participant; 80 total).
Overall sensitivity across all participants was 0.900 (72 of 80 fall trials detected). Participants P3 and P5—both male with higher body mass (85.1 kg and 92.3 kg respectively)—achieved perfect detection sensitivity, generating impact scores consistently above threshold across all fall types. Participants P2 and P4 exhibited the lowest per-participant sensitivity (0.800) and also produced relatively low FSR impact responses during several slow-collapse trials. These observations suggest that low-impact fall dynamics may reduce the likelihood of satisfying the fixed impact threshold. Although both participants were among the lighter members of the cohort, the small sample size does not permit conclusions regarding an independent relationship between body mass and detection sensitivity. Similarly, participant-level differences in detection latency are reported descriptively and should not be interpreted as evidence of a mass-dependent effect.
Two participants (P2 and P6) each generated one false alarm, both from rapid intentional lying-down trials. These are discussed further in Section 3.7.
3.5. Performance by Fall Type
Detection performance varied across the five simulated fall scenarios, as summarised in Table 12. Forward and stumble falls were detected with perfect sensitivity in the present dataset, whereas lateral and backward falls each achieved a sensitivity of 0.875. Slow-collapse events were the most challenging, with a sensitivity of 0.750. Lower detection performance was observed primarily during slow-collapse, lateral, and backward fall scenarios, whereas forward and stumble falls were detected with perfect sensitivity in the present dataset.
Overall, the proposed framework demonstrated encouraging performance across the evaluated simulated fall scenarios, indicating that the complementary sensing modalities effectively capture both rapid and gradual fall dynamics.
Forward falls and stumble falls achieved perfect sensitivity (1.000), producing consistent and pronounced feature responses across all participants: large , rapid torso-inclination transition, and clearly supra-threshold impact scores. Lateral and backward falls yielded sensitivity of 0.875; the four missed detections (two lateral, two backward) occurred when participants fell partially outside the FSR array footprint, yielding load sensor responses below the impact threshold and precluding fusion confirmation despite correct vision-based skeletal posture classification.
Slow collapse falls produced the lowest sensitivity (0.750), as the gradual floor descent generated impact scores below in four trials—three involving lighter participants (P2, P4) and one involving a particularly controlled slow descent by P8. Detection latency was longest for slow collapse events ( s), reflecting the extended transition time before lying posture was confirmed.
3.5.1. False Positive Performance Across ADL Scenarios
Table 13 presents false alarm results across the five ADL scenarios. Each ADL was performed twice by each of 8 participants, yielding 16 trials per ADL type (80 ADL trials total).
The overall false positive rate was 0.025 (2 false alarms in 80 ADL trials). Both false alarms arose from the intentional lying-down scenario and were associated with rapid, forceful descents to the floor by participants P2 and P6, which transiently exceeded both and . All other ADL scenarios produced zero false alarms in the present experimental dataset, suggesting that the minimum lying-duration filter and fall time window contributed to suppressing transient postural changes associated with bending, kneeling, sitting, and walking.
3.5.2. Overall System Performance Metrics
Table 14 presents the aggregated performance metrics across all 160 experimental trials, comprising 80 simulated fall trials and 80 activities of daily living (ADLs).
The proposed fusion framework achieved a sensitivity of 0.900 (95% CI: 0.815–0.948), specificity of 0.975 (95% CI: 0.913–0.993), precision of 0.973 (95% CI: 0.907–0.993), accuracy of 0.938 (95% CI: 0.889–0.966), and an F1-score of 0.935.
The mean candidate-fall detection latency — defined as the elapsed time from ground-truth fall onset to the fusion node’s first identification of a fall transition event () — was s across true-positive detections. This is distinct from the final alarm latency, which additionally includes the mandatory s posture persistence window and is approximately s on average. This two-stage design is deliberate: the candidate detection triggers the internal persistence timer, whilst the alarm is published only once sustained floor-level posture confirms a genuine fall. Both latency values remain within the clinically acceptable range, given that secondary complications of prolonged floor contact develop over minutes rather than seconds.
The high specificity indicates that the multimodal fusion strategy effectively limited false-positive detections. Fall confirmation required an appropriate temporal sequence of visual transition evidence, corroborating floor-sensor evidence, and sustained floor-level posture, thereby reducing false alarms from ADLs that produced postural transitions visually similar to falls.
3.5.3. Participant-Level Variability Analysis
Inter-participant variability in detection performance provides insight into the influence of individual characteristics on system reliability. Table 15 summarises the mean feature values recorded at the frame of fall confirmation for true positive detections, aggregated by participant.
Descriptive differences in the recorded features were observed across participants. In particular, participants with lower body mass tended to exhibit lower FSR impact scores, whereas several higher-body-mass participants produced larger impact responses. For example, the mean impact scores for P2, P4, and P8 were , , and , respectively, compared with , , and for P3, P5, and P7. The lower impact responses observed for some participants approached the detection threshold and may have contributed to missed detections, particularly during slow-collapse events. However, these observations are descriptive only. Given the small sample size (), the present study was not designed or statistically powered to establish body mass as an independent determinant of impact response or fall-detection performance.
3.6. Sensor Fusion Contribution Analysis
To quantify the contribution of each modality, two single-modality baseline configurations were evaluated against the same 160-trial dataset:
- 1.
- Vision-only: Fall declared from skeletal pose-derived postural and temporal evidence without requiring FSR corroboration.
- 2.
- Load-only: Fall declared on impact score and spatial load-distribution evidence alone, without pose estimation.
Table 16.
Comparison of fused system against single-modality baselines (160 trials, 8 participants)
| Configuration | Sensitivity | Specificity | Precision | F1 | FP Count |
|---|---|---|---|---|---|
| Vision only | 0.938 | 0.863 | 0.872 | 0.904 | 11 |
| Load only | 0.838 | 0.938 | 0.9306 | 0.882 | 5 |
| Fused (proposed) | 0.900 | 0.975 | 0.973 | 0.935 | 2 |
The vision-only configuration achieves the highest sensitivity (0.938), as it does not require load corroboration and therefore detects falls that occur outside the FSR array footprint. However, specificity drops to 0.863 with 11 false alarms—primarily from participants performing rapid intentional lying-down and fast floor-sitting—scenarios where posture transition alone is insufficient to discriminate from genuine falls. The load-only configuration achieves moderate sensitivity (0.838), failing primarily on slow-collapse events and falls outside the array boundary, but produces fewer false alarms (specificity 0.938) as impact dynamics and spatial load-distribution evidence together provide stronger physical discrimination.
The fused system achieves the highest F1-score (0.935), reducing false alarms from 11 (vision-only) to 2, an 82% reduction, whilst maintaining a sensitivity of 0.900. The 3.8-percentage-point sensitivity reduction relative to vision-only reflects cases where load sensor coverage was incomplete. This sensitivity reduction was primarily associated with incomplete FSR coverage in the present experimental configuration.
3.7. Failure Mode Analysis
3.7.1. False Negatives
Eight missed fall detections were identified and categorised across the cohort. Cross-referencing the per-participant detection table (Table 11) with each trial record confirms the following attribution:
Falls outside FSR array boundary (4 cases): Participants P1 (1 FN), P6 (1 FN), P7 (1 FN), and P8 (1 FN) each had one lateral or backward fall trial in which the subject landed partially or wholly outside the instrumented floor zone. In these cases, the FSR array registered an impact score below and insufficient load to satisfy the lying-like load-distribution criterion. Fusion confirmation was therefore not achieved despite correct vision-based skeletal posture classification. This failure mode is attributable to the finite spatial coverage of the FSR array and is independent of participant body mass.
Slow collapse with insufficient impact (4 cases): Participants P2 (2 FN) and P4 (2 FN) each had two slow-collapse trials in which the gradual floor descent generated a trunk-centroid velocity below and an FSR impact score below , leaving the fusion node in the Transitioning state beyond the fall window . In all four cases, the vision-only classifier correctly identified a lying posture, confirming that the FSR impact criterion was the binding constraint. Both participants are among the lightest cohort members (58.4 kg and 61.7 kg respectively), and their mean impact scores (Table 15: and ) were closest to , consistent with reduced impact force during controlled slow descents. Given the small sample size, these observations are descriptive and should not be interpreted as establishing body mass as an independent determinant of detection performance.
3.7.2. False Positives
Two false alarms were recorded, both during intentional lying-down trials:
- P2 (Trial 2, intentional lying): Participant descended unusually rapidly, generating a transient normalized trunk-centroid velocity slightly above the threshold , coincident with an impact score of , marginally above . Post-hoc telemetry inspection revealed that the spatial load-distribution pattern did not provide sufficiently strong evidence of sustained floor contact prior to alarm generation.
- P6 (Trial 1, intentional lying): Similar mechanics to the P2 case; a forceful descent generated impact score . The participant’s movement speed was atypically high relative to the calibration dataset, placing the event in a region of parameter space not well-represented during threshold determination.
Both false alarms share a common root cause: rapid intentional floor descent that falls within the parameter overlap region between fast ADLs and genuine falls. This overlap is irreducible to some degree by any threshold-based system. These observations suggest that incorporating an additional spatial load-distribution criterion may help reduce false alarms arising from rapid intentional floor descent. However, this modification requires prospective evaluation to determine its effect on both specificity and sensitivity.
3.8. Computational Performance
YOLOv8n-pose inference on the host GPU averaged FPS across all experimental sessions, comfortably exceeding the 30 FPS camera acquisition rate and confirming that pose estimation introduced no processing bottleneck. End-to-end pipeline latency from camera frame acquisition to /fall_alarm publication averaged ms per frame. Peak CPU utilisation across all ROS2 nodes reached 34% during concurrent inference and load sensor processing, indicating that the processing workload remained well within the capabilities of the host workstation and motivating future evaluation on more resource-constrained embedded hardware.
Table 18 summarises per-node computational contributions.
The pose estimator node dominates CPU utilisation (19.4%), as expected given the convolutional inference workload. The fusion node contributes minimal overhead (2.9%), reflecting the computational simplicity of the state machine logic relative to the perception tasks. The total pipeline latency of 47 ms is well within real-time constraints and substantially below the detection latency of 1.80 s, confirming that computational performance is not a limiting factor for detection responsiveness.
4. Discussion
The experimental results demonstrate that integrating vision-based skeletal pose estimation with floor-based force sensing through decision-level fusion provides a promising approach for non-wearable fall detection under the evaluated experimental conditions. The proposed framework achieved an overall F1-score of 0.935, with a sensitivity of 90.0%, specificity of 97.5%, and an 82% reduction in false-positive count relative to the evaluated vision-only baseline. These findings indicate that the complementary sensing modalities successfully compensate for the limitations of individual sensors, improving both reliability and robustness under the evaluated controlled indoor conditions.
4.1. Interpretation of Results
The experimental evaluation demonstrates that the proposed multimodal framework improves fall detection by combining complementary skeletal postural and motion information from the vision subsystem with physical floor-interaction evidence from the FSR sensing platform. Vision-based skeletal tracking captures changes in body orientation and normalized trunk-centroid motion, whereas the distributed FSR sensing platform provides information regarding impact and spatial load distribution during human movement. The combination of these complementary sensing modalities enables reliable discrimination between genuine falls and activities of daily living that often produce similar visual appearances.
One of the principal advantages of the proposed framework is the adoption of decision-level fusion rather than feature-level or signal-level fusion. Independent processing of the vision and floor-based sensing branches enables each modality to contribute evidence without requiring sample-level alignment of the heterogeneous sensor measurements. This modular architecture also improves robustness to temporary degradation of individual sensing modalities, such as partial body occlusion within the camera field of view or temporary fluctuations in force sensor measurements.
The temporal state machine further contributes to the observed performance by incorporating temporal consistency into the decision process. Instead of relying on instantaneous posture estimates, fall decisions are confirmed only when the required sequence of visual and floor-sensor evidence satisfies the temporal transition criteria. Consequently, rapid activities such as sitting, kneeling, bending, or intentional lying are less likely to generate false alarms, explaining the substantial reduction in false-positive detections observed during experimental evaluation.
4.2. Comparison with Existing Work
Existing fall detection systems generally rely on wearable inertial sensors, vision-based monitoring, or ambient sensing technologies. Wearable systems typically achieve high detection sensitivity but require continuous user compliance and regular maintenance, limiting long-term deployment among older adults. Vision-based approaches provide richer contextual information but remain susceptible to lighting variations, occlusions, and difficulties distinguishing falls from intentional floor activities. Ambient sensing methods preserve user privacy but often lack sufficient contextual information to distinguish accidental falls from normal daily activities.
The proposed framework addresses these limitations by integrating complementary information from both vision and floor-based sensing. Unlike conventional vision-only approaches, the additional FSR-derived floor-load measurements provide complementary evidence of floor interaction and impact-related changes, substantially reducing false-positive detections. Compared with wearable solutions, the proposed system operates entirely without body-mounted devices, improving user acceptance and reducing dependence on user compliance.
Although the obtained performance is encouraging, direct quantitative comparison with published fall-detection systems should be interpreted cautiously because of differences in participant populations, sensing modalities, activity protocols, dataset sizes, and evaluation procedures.
4.3. Practical Implications
The proposed multimodal architecture has potential for future deployment in residential homes, assisted living facilities, rehabilitation centres, and hospital environments where continuous, unobtrusive monitoring is required. Because the system does not rely on wearable devices, it avoids common problems associated with user compliance, charging requirements, and device removal. Furthermore, the distributed sensing architecture enables continuous monitoring without requiring users to modify their daily routines.
The modular design of the framework also facilitates future integration with smart home technologies and healthcare monitoring systems. Additional sensing modalities, including radar, thermal imaging, inertial sensing, or environmental sensors, could be incorporated within the existing decision-level fusion framework with minimal modification to the current system architecture. Consequently, the proposed framework provides a flexible platform for future intelligent ambient assisted living applications.
4.4. Limitations and Future Work
Several limitations should be considered when interpreting the present findings. First, the experimental evaluation was conducted using healthy adult volunteers rather than older adults or individuals with impaired mobility. Although this approach is commonly adopted during the initial validation of fall-detection systems for ethical and safety reasons, movement characteristics observed during simulated falls may differ from those occurring during genuine accidental falls. Future studies should therefore evaluate the proposed framework in populations more representative of its intended users.
Second, the experimental evaluation was performed within a controlled indoor environment. Although the test environment incorporated variations in lighting and partial occlusions, further validation in occupied residential and assisted-living environments is required to assess long-term robustness under unconstrained conditions.
Third, the current implementation relies on empirically selected decision thresholds derived from a pilot dataset. Although these thresholds were fixed before evaluation and were not adjusted using the test data, their generalisation to populations with different movement characteristics, body sizes, or environmental configurations has not yet been established. Future work should therefore investigate adaptive or participant-independent threshold selection using larger and more diverse development datasets.
Fourth, the present evaluation was restricted to single-participant scenarios. The behaviour of the proposed fusion framework in multi-occupant environments has not yet been established, particularly where visual skeletal observations must be associated with spatially overlapping floor-sensor responses. Future work should therefore investigate multi-person tracking and sensor-to-person association strategies.
Fifth, the finite spatial coverage of the floor-mounted FSR array affected detection performance. Four false-negative detections occurred when participants landed partially outside the instrumented region, reducing the availability of floor-sensor corroborating evidence. Larger or modular sensing surfaces, together with fusion strategies capable of maintaining reliable operation when floor-sensor coverage is incomplete, should therefore be investigated.
Beyond addressing these limitations, future work will investigate adaptive threshold optimisation and machine-learning-based decision fusion to improve generalisation across different users and environments. Additional sensing modalities, including millimetre-wave radar, thermal imaging, and wireless sensing technologies, could also be explored to improve robustness under challenging environmental conditions.
Larger-scale validation involving older adults and individuals with mobility impairments will be required to establish the clinical and real-world applicability of the proposed framework. Longer-term deployment in residential and assisted-living environments should also examine system reliability, user acceptability, privacy considerations, and integration with remote healthcare platforms for timely intervention following detected fall events. Finally, activities were performed in a predefined rather than randomised sequence. Although thresholds were fixed prior to the main evaluation, a fixed activity order may introduce familiarisation or order effects. Future evaluations should therefore randomise or counterbalance activity order
5. Conclusions
This paper presented a real-time, non-wearable multimodal fall detection framework that integrates YOLOv8-based skeletal pose estimation with a distributed floor-mounted Force Sensitive Resistor (FSR) sensing platform through a decision-level sensor fusion strategy. By combining complementary skeletal postural information with load-based floor-interaction evidence, the proposed framework addresses several limitations associated with vision-only and single-sensor fall-detection approaches. Experimental evaluation involving eight healthy participants and 160 trials demonstrated that the proposed system provides reliable fall detection under representative indoor conditions, achieving an F1-score of 0.935, sensitivity of 90.0%, specificity of 97.5%, and a mean candidate-fall detection latency of s. The decision-level fusion framework reduced false-positive detections by 82% compared with the vision-only configuration, demonstrating the benefit of combining independent sensing modalities with temporal reasoning. Furthermore, computational evaluation confirmed that the complete framework operates in real time, supporting the technical feasibility of real-time continuous monitoring. Although the current study involved healthy adult participants and was conducted under controlled indoor conditions, the results demonstrate the technical feasibility of the proposed approach within the evaluated setting. The modular architecture provides a foundation for further development, including the integration of additional sensing modalities and future evaluation in residential homes, rehabilitation facilities, and healthcare environments.
Future work will focus on large-scale clinical validation involving older adults and individuals at increased risk of falling, evaluation in real-world residential environments, and the investigation of adaptive decision thresholds and learning-based sensor fusion strategies to further improve robustness and generalisation across diverse users and environmental conditions.
Author Contributions
Conceptualization, Mifal Jacob and Utkaarsh Saha; methodology, Mifal Jacob; software, Utkaarsh Saha; validation, Mifal Jacob and Utkaarsh Saha; formal analysis, Mifal Jacob; investigation, Mifal Jacob; resources, Shabnam Sadeghi Esfahlani; data curation, Mifal Jacob and Utkaarsh Saha; writing—original draft preparation, Mifal Jacob; writing—review and editing, Utkaarsh Saha and Shabnam Sadeghi Esfahlani; visualization, Mifal Jacob and Utkaarsh Saha; supervision, Shabnam Sadeghi Esfahlani. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding
Institutional Review Board Statement
The study was conducted in accordance with the Declaration of Helsinki and approved by the Anglia Ruskin University Research Ethics Committee (protocol code ETH2526-3122; approved on 1 February 2026).
Informed Consent Statement
Written informed consent was obtained from all subjects involved in the study.
Data Availability Statement
The data supporting the findings of this study are available from the corresponding author upon reasonable request, subject to applicable ethical and data-protection requirements.
Conflicts of Interest
None.
References
- World Health Organization. Falls. Accessed. 2021. (accessed on 14 August 2026).
- British Geriatrics Society. AACE and BGS Launch National Falls Governance Framework to Strengthen Community Response and Prevent Hospital Admissions. Accessed. 2025. (accessed on 14 August 2026).
- Bagalà, F.; Becker, C.; Cappello, A.; Chiari, L.; Aminian, K.; Hausdorff, J.M.; Zijlstra, W.; Klenk, J. Evaluation of Accelerometer-Based Fall Detection Algorithms on Real-World Falls. PLoS ONE 2012, 7, e37062. [Google Scholar] [CrossRef]
- Mubashir, M.; Shao, L.; Seed, L. Fall detection systems for elderly care: A survey. Pattern Recognit. 2013, 41, 2863–2883. [Google Scholar]
- Alwan, M.; Rajendran, P.J.; Kell, S.; Mack, D.; Dalal, S.; Wolfe, M.; Felder, R. A Smart and Passive Floor-Vibration Based Fall Detector for Elderly. Proc. 2nd Int. Conf. Inf. Commun. Technol. 2006, Vol. 1, 1003–1007. [Google Scholar] [CrossRef]
- Noury, N.; others. Simulation-based evaluation of fall detection systems. IRBM 2011. [Google Scholar] [CrossRef]
- Jocher, G.; Chaurasia, A.; Qiu, J. YOLO by Ultralytics. 2023. [Google Scholar] [CrossRef]
- Dasarathy, B.V. Decision fusion strategies in multisensor environments. IEEE Trans. Syst. Man. Cybern. 1991, 21, 1140–1154. [Google Scholar] [CrossRef]
- Khaleghi, B.; Khamis, A.; Karray, F.; Razavi, S. Multisensor data fusion: A review of the state-of-the-art. Inf. Fusion 2013, 14, 28–44. [Google Scholar] [CrossRef]
- Kwolek, B.; Kepski, M. Human fall detection on embedded platform using depth maps and wireless accelerometer. Proc. Comput. Methods Programs Biomed. 2014, Vol. 117, 489–501. [Google Scholar] [CrossRef]
- Intel Corporation. Intel. RealSense D435 Product. Datasheet 2023. [CrossRef]
Figure 1.
Overall architecture of the proposed multimodal fall detection framework. Images acquired using the Intel RealSense D435 camera are processed using the YOLOv8n-pose network to estimate human skeletal keypoints and derive posture-related skeletal descriptors. Simultaneously, measurements acquired from the distributed FSR sensing platform are processed to estimate load-related features including relative total load, voltage-weighted load centroid, and impact intensity. Independent decisions generated by the vision and force-sensing subsystems are subsequently combined using a temporal decision-level fusion module to classify activities as falls or activities of daily living (ADLs).
Figure 1.
Overall architecture of the proposed multimodal fall detection framework. Images acquired using the Intel RealSense D435 camera are processed using the YOLOv8n-pose network to estimate human skeletal keypoints and derive posture-related skeletal descriptors. Simultaneously, measurements acquired from the distributed FSR sensing platform are processed to estimate load-related features including relative total load, voltage-weighted load centroid, and impact intensity. Independent decisions generated by the vision and force-sensing subsystems are subsequently combined using a temporal decision-level fusion module to classify activities as falls or activities of daily living (ADLs).
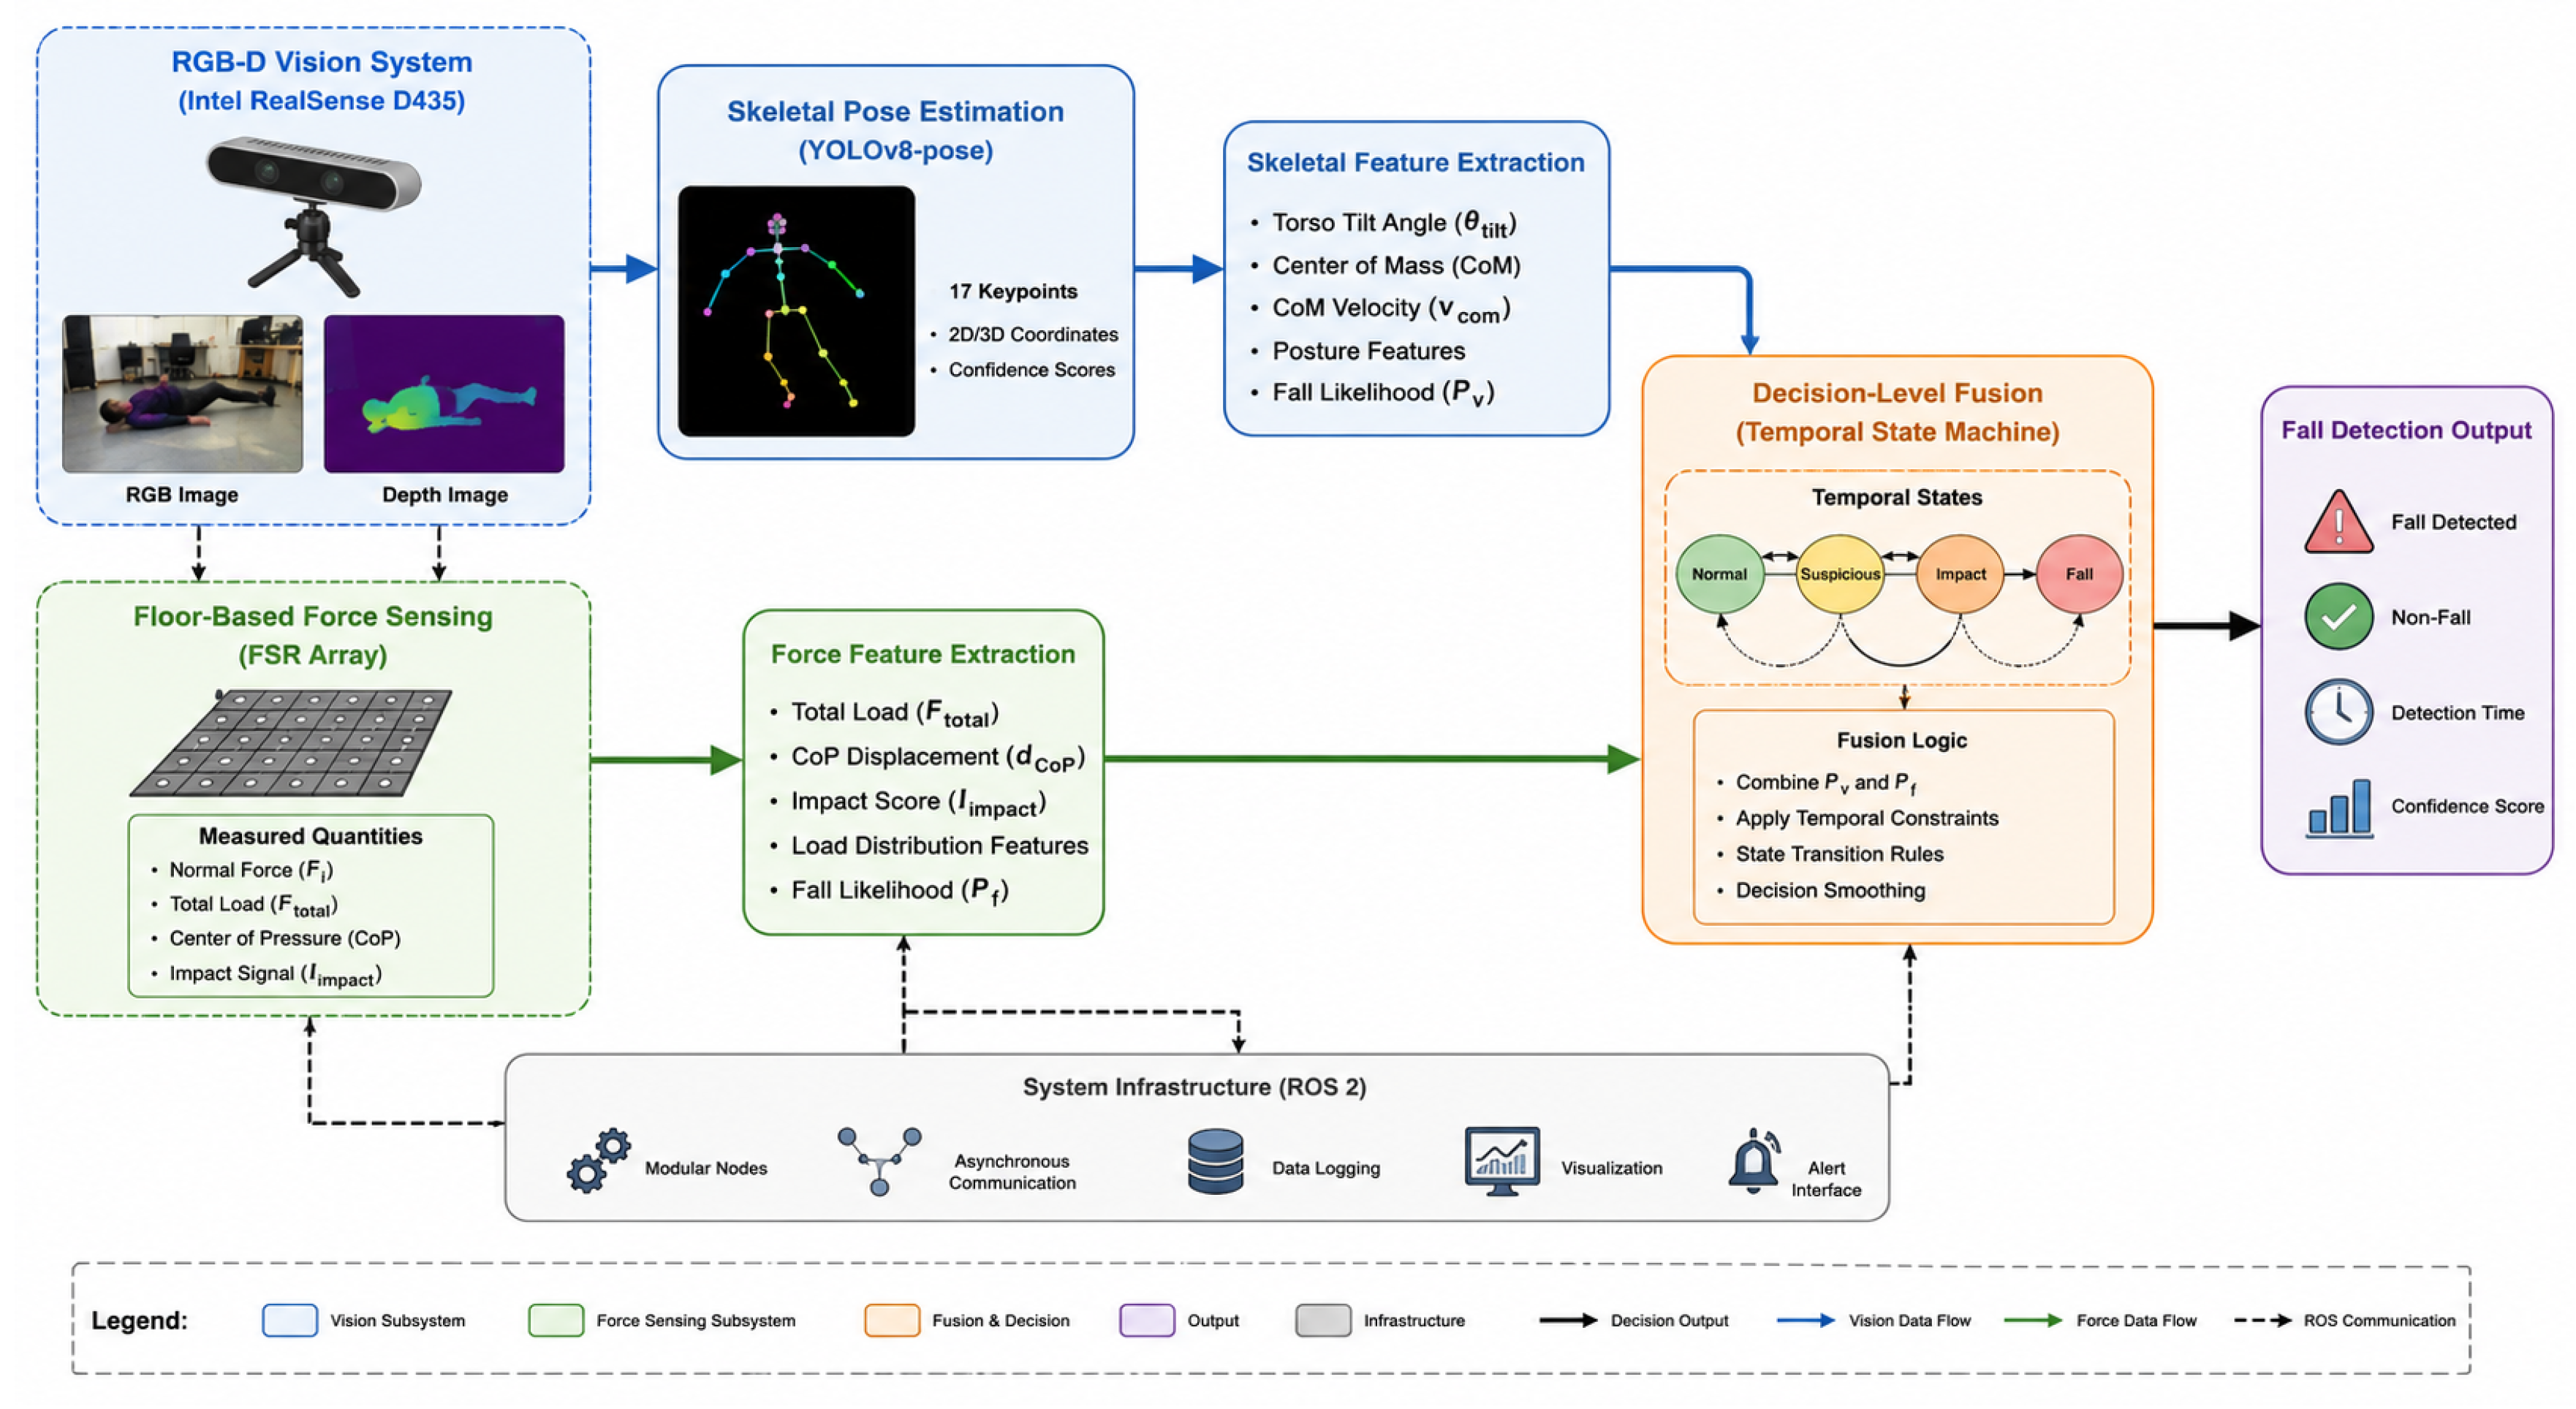
Figure 2.
Experimental setup showing the Intel RealSense D435 camera mounted above the monitored area together with the floor-mounted FSR sensing platform used during data collection.
Figure 2.
Experimental setup showing the Intel RealSense D435 camera mounted above the monitored area together with the floor-mounted FSR sensing platform used during data collection.
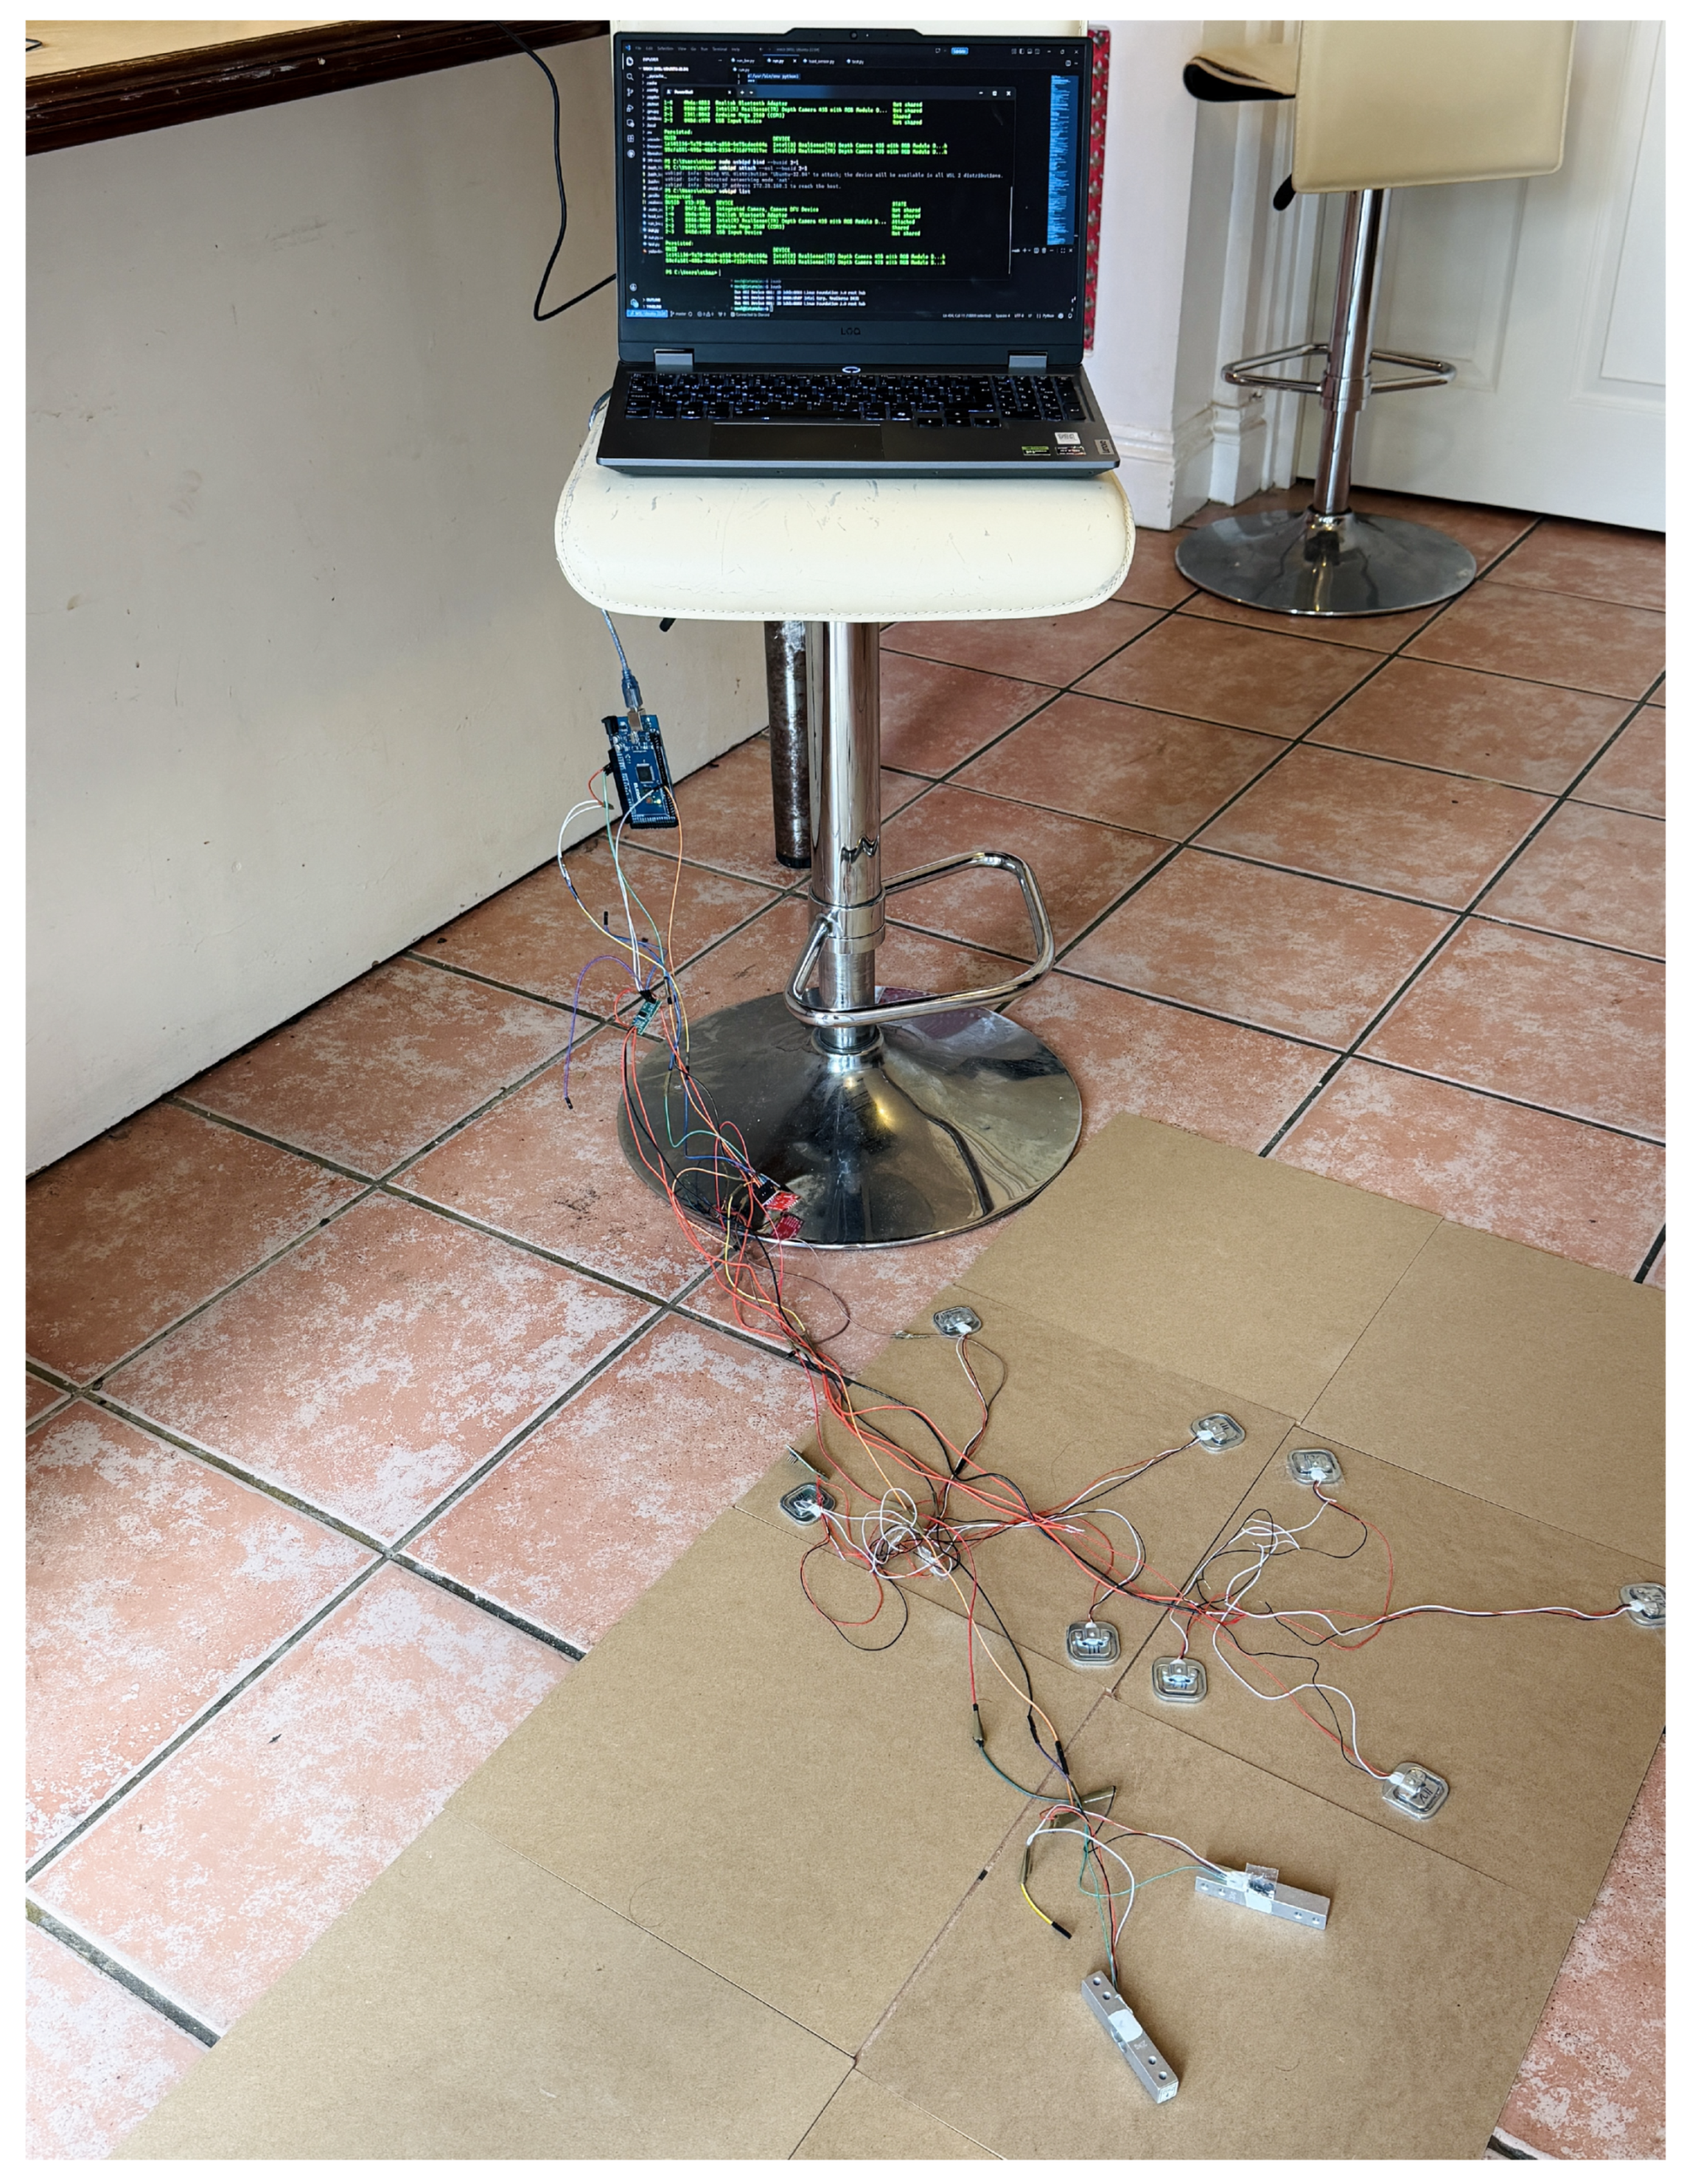
Figure 3.
System output during a confirmed fall-detection event (Participant P3, forward-fall trial). At the displayed frame, the fusion node reports STATE: FALLEN, with normalized trunk-centroid velocity , instantaneous torso inclination , normalized trunk-centroid position , and a positive FSR impact flag. The Fallen state reflects temporally accumulated evidence from the preceding fall sequence rather than the instantaneous torso-angle value alone. The labels “CoM-y” and “” shown in the software overlay correspond to the normalized trunk-centroid position and velocity defined in Equations 5 and 6, respectively.
Figure 3.
System output during a confirmed fall-detection event (Participant P3, forward-fall trial). At the displayed frame, the fusion node reports STATE: FALLEN, with normalized trunk-centroid velocity , instantaneous torso inclination , normalized trunk-centroid position , and a positive FSR impact flag. The Fallen state reflects temporally accumulated evidence from the preceding fall sequence rather than the instantaneous torso-angle value alone. The labels “CoM-y” and “” shown in the software overlay correspond to the normalized trunk-centroid position and velocity defined in Equations 5 and 6, respectively.
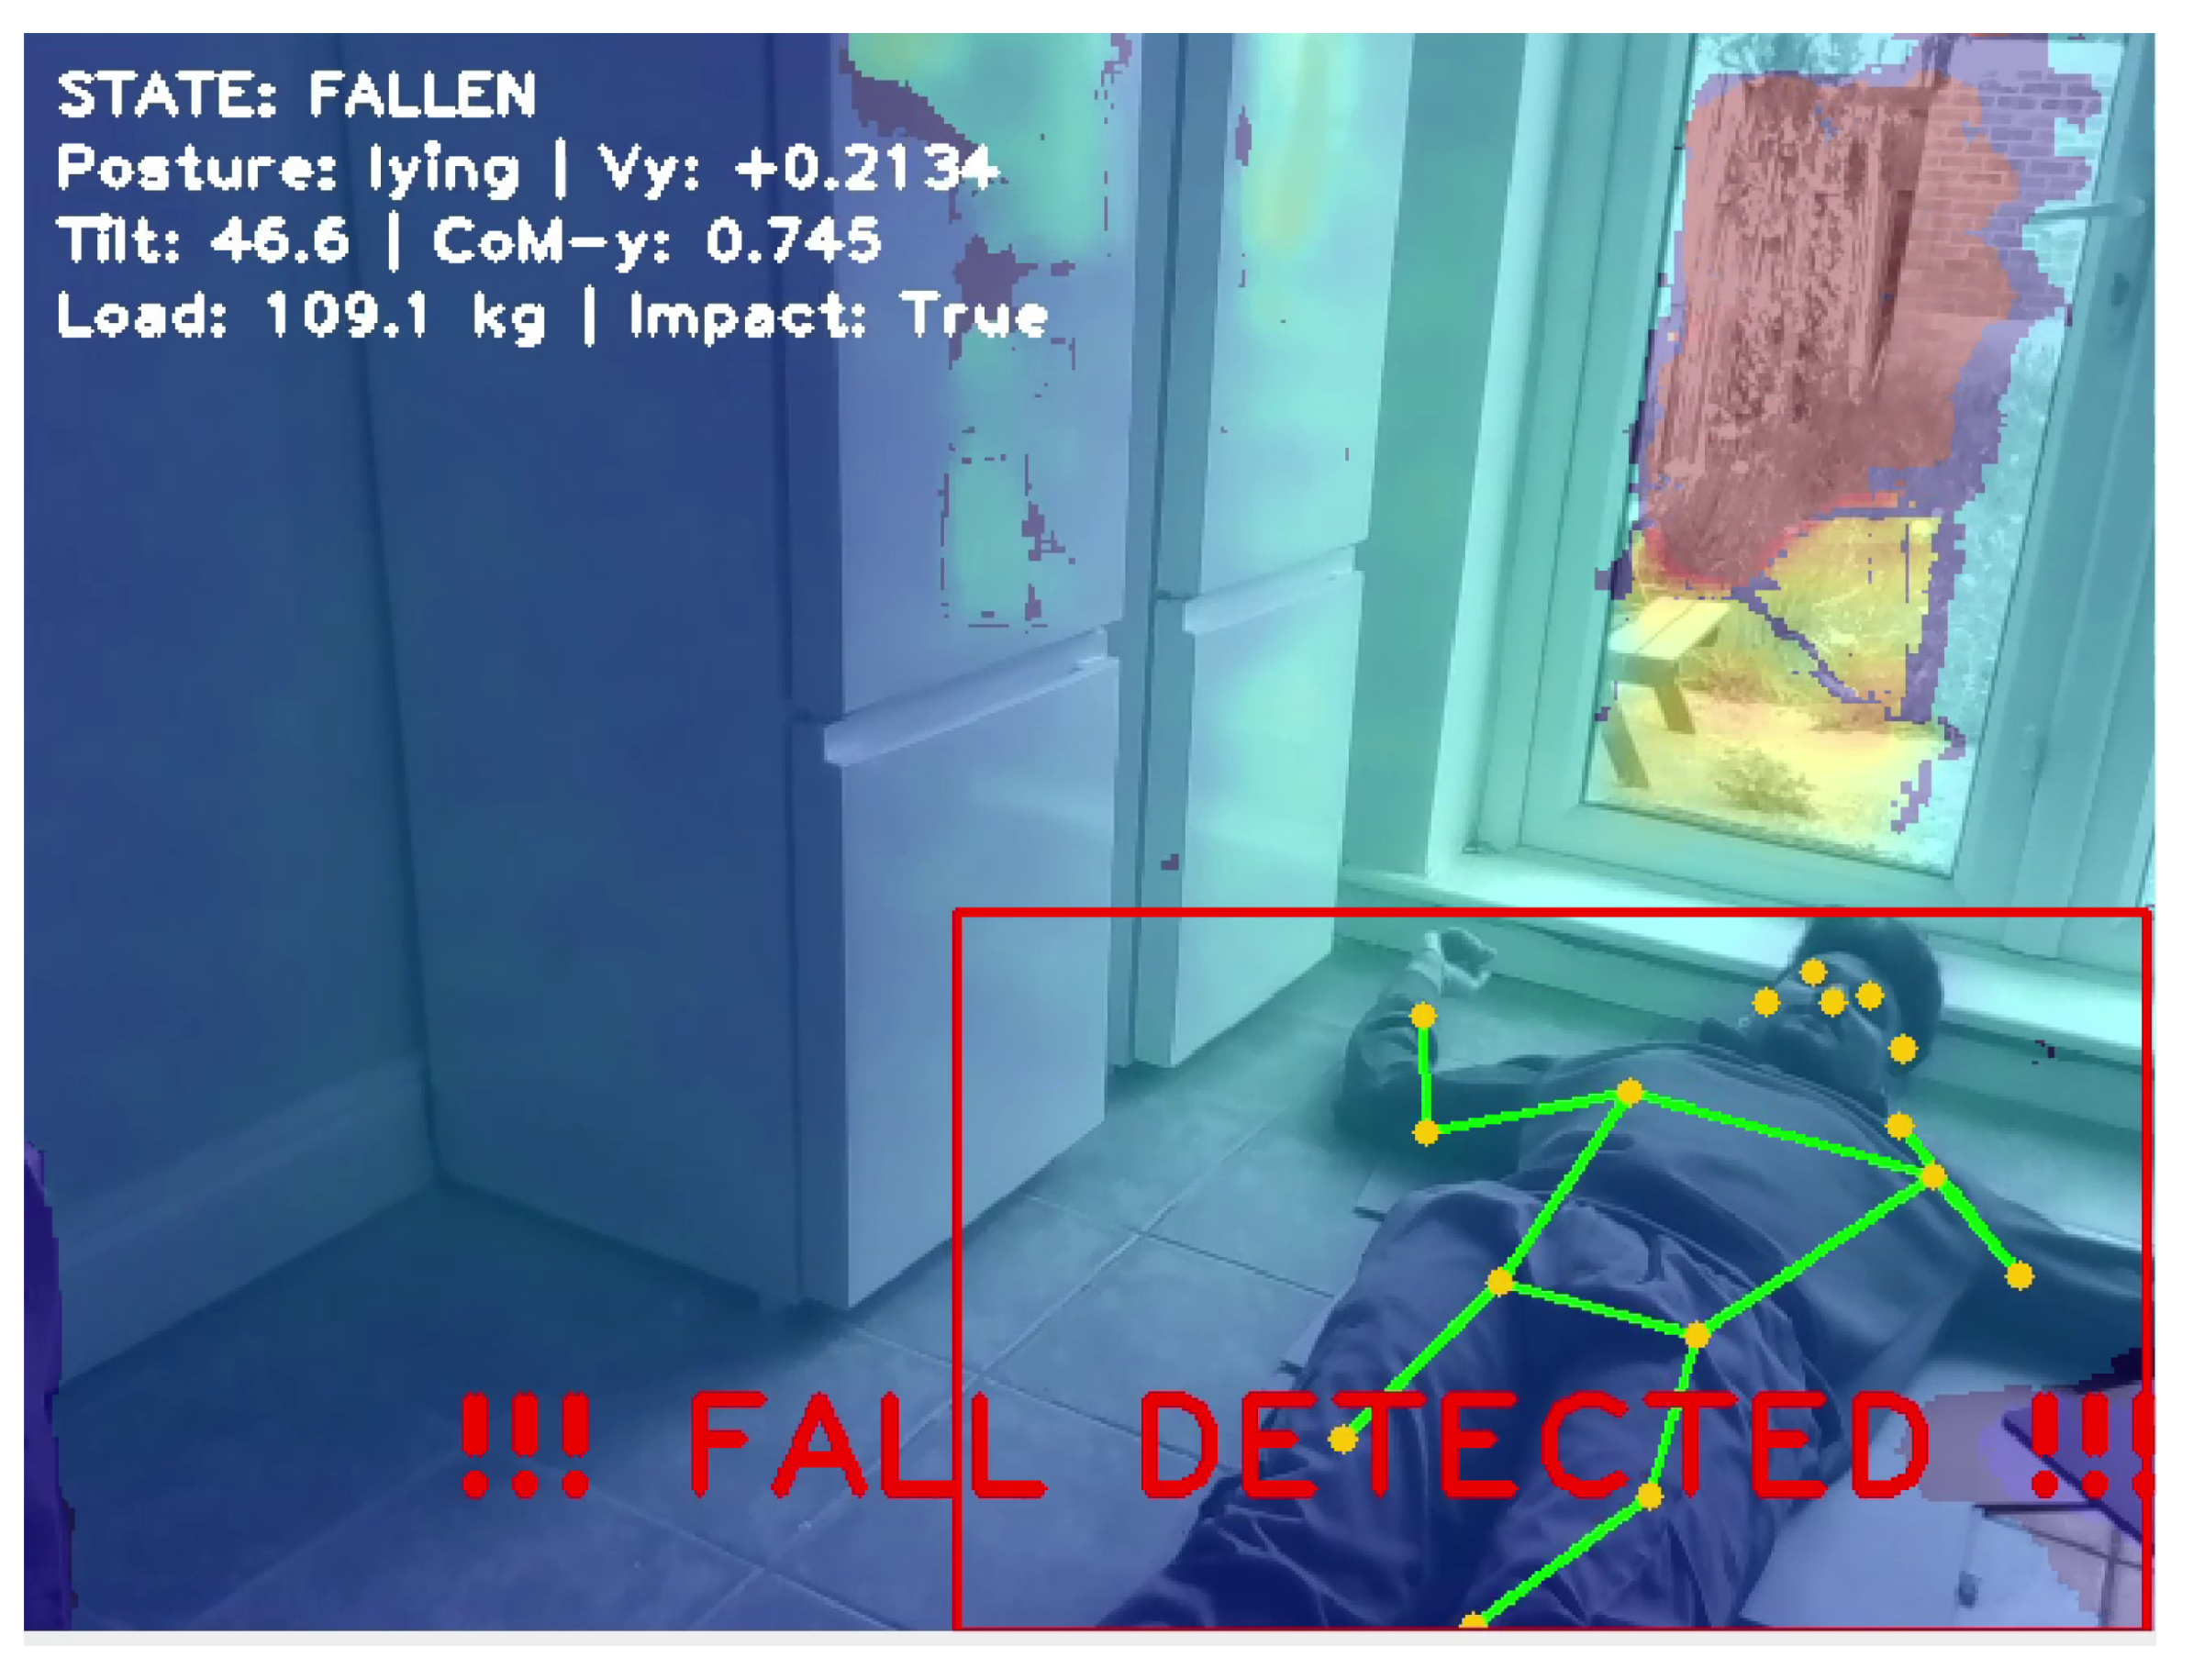
Table 1.
Conceptual comparison of representative fall-detection sensing approaches and the proposed framework.
Table 1.
Conceptual comparison of representative fall-detection sensing approaches and the proposed framework.
| Approach | Primary Sensor(s) | Pose Estimation | Sensor Fusion | Real-Time | Main Limitations |
|---|---|---|---|---|---|
| Wearable IMU systems [3] | Accelerometer / IMU | No | No | Yes | Require continuous user compliance, charging, and correct device placement. |
| Vision-based methods [4] | RGB camera | Limited | No | Moderate | Sensitive to lighting variation, occlusion, camera placement, and privacy concerns. |
| Ambient sensing approaches [5] | Floor vibration / acoustic / pressure sensors | No | No | Yes | Limited contextual information and difficulty distinguishing falls from other impact events. |
| YOLOv8 pose estimation [7] | RGB / RGB-D camera | Yes | No | Yes | Provides accurate posture estimation but cannot directly measure impact forces. |
| General multisensor fusion approaches [8,9] | Multiple sensors | Dependent | Feature / decision level | Dependent | Often require careful synchronisation, calibration, and application-specific optimisation. |
| Proposed framework | RGB-D camera + FSR array | YOLOv8 skeletal pose | Decision-level fusion | Yes | Limited by floor sensor coverage, but improves robustness through complementary skeletal-pose and floor-based force sensing. |
Table 8.
Participant characteristics
| ID | Sex | Age | Mass (kg) | Height (cm) |
|---|---|---|---|---|
| P1 | M | 24 | 78.2 | 181 |
| P2 | F | 22 | 58.4 | 165 |
| P3 | M | 31 | 85.1 | 178 |
| P4 | F | 19 | 61.7 | 162 |
| P5 | M | 28 | 92.3 | 185 |
| P6 | F | 26 | 64.0 | 169 |
| P7 | M | 34 | 80.5 | 176 |
| P8 | F | 23 | 59.8 | 164 |
| Mean | – | 25.9 | 72.5 | 172.5 |
Table 9.
ROS2 node graph: nodes, topics, and update rates.
| Node | Publishes | Rate | Purpose |
|---|---|---|---|
| realsense_node | /camera/color/image_raw | 30 Hz | RGB-D acquisition |
| pose_estimator_node | /pose_features | 30 Hz | YOLOv8 inference and skeletal feature extraction |
| load_sensor_node | /load_features | 50 Hz | Arduino serial parsing and load feature computation |
| fusion_node | /fall_alarm, /system_state | Event-driven | Temporal state machine and fall alarm generation |
Table 10.
Confusion matrix for the proposed multimodal fall detection system.
| Predicted Fall | Predicted Non-Fall | |
|---|---|---|
| Actual Fall | 72 | 8 |
| Actual Non-Fall | 2 | 78 |
Table 11.
Per-participant fall detection performance (10 fall trials each)
| Participant | Mass (kg) | TP | FN | Sensitivity | FP | Candidate latency† (s) |
|---|---|---|---|---|---|---|
| P1 | 78.2 | 9 | 1 | 0.900 | 0 | |
| P2 | 58.4 | 8 | 2 | 0.800 | 1 | |
| P3 | 85.1 | 10 | 0 | 1.000 | 0 | |
| P4 | 61.7 | 8 | 2 | 0.800 | 0 | |
| P5 | 92.3 | 10 | 0 | 1.000 | 0 | |
| P6 | 64.0 | 9 | 1 | 0.900 | 1 | |
| P7 | 80.5 | 9 | 1 | 0.900 | 0 | |
| P8 | 59.8 | 9 | 1 | 0.900 | 0 | |
| Total | – | 72 | 8 | 0.900 | 2 |
† Latency values represent candidate-fall detection latency (), not the final alarm latency. The final alarm is issued after an additional s posture persistence window; see Section.
Table 12.
Fall detection results by fall type (8 participants × 2 repetitions = 16 trials per type)
| Fall Type | Trials | TP | FN | Sensitivity | Mean candidate latency (s) |
|---|---|---|---|---|---|
| Forward fall | 16 | 16 | 0 | 1.000 | |
| Lateral fall | 16 | 14 | 2 | 0.875 | |
| Backward fall | 16 | 14 | 2 | 0.875 | |
| Slow collapse | 16 | 12 | 4 | 0.750 | |
| Stumble fall | 16 | 16 | 0 | 1.000 | |
| Overall | 80 | 72 | 8 | 0.900 |
Table 13.
False positive results across ADL scenarios (8 participants × 2 repetitions = 16 trials per type)
Table 13.
False positive results across ADL scenarios (8 participants × 2 repetitions = 16 trials per type)
| ADL Scenario | Trials | TN | FP | FPR |
|---|---|---|---|---|
| Intentional lying down | 16 | 14 | 2 | 0.125 |
| Rapid sitting to floor | 16 | 16 | 0 | 0.000 |
| Bending to pick up object | 16 | 16 | 0 | 0.000 |
| Kneeling and standing | 16 | 16 | 0 | 0.000 |
| Walking through / exiting | 16 | 16 | 0 | 0.000 |
| Overall | 80 | 78 | 2 | 0.025 |
Table 14.
Overall system performance metrics across 160 experimental trials.
| Metric | Value |
|---|---|
| Total trials | 160 |
| Fall trials | 80 |
| ADL trials | 80 |
| True Positives (TP) | 72 |
| False Negatives (FN) | 8 |
| True Negatives (TN) | 78 |
| False Positives (FP) | 2 |
| Sensitivity (Recall) | 0.900 (95% CI: 0.815–0.948) |
| Specificity | 0.975 (95% CI: 0.913–0.993) |
| Precision | 0.973 (95% CI: 0.907–0.993) |
| Accuracy | 0.938 (95% CI: 0.889–0.966) |
| F1-Score | 0.935 |
| Mean candidate-fall detection latency | |
| Mean final alarm latency (approx.) |
Table 15.
Mean feature values at fall confirmation across participants (true positives only)
| ID | Tilt (°) | Relative total load (a.u.) | Impact Score | ||
|---|---|---|---|---|---|
| P1 | |||||
| P2 | |||||
| P3 | |||||
| P4 | |||||
| P5 | |||||
| P6 | |||||
| P7 | |||||
| P8 |
Table 17.
False-negative attribution by participant and cause.
| Participant | FN (total) | FSR boundary | Slow collapse |
|---|---|---|---|
| P1 | 1 | 1 | 0 |
| P2 | 2 | 0 | 2 |
| P4 | 2 | 0 | 2 |
| P6 | 1 | 1 | 0 |
| P7 | 1 | 1 | 0 |
| P8 | 1 | 1 | 0 |
| Total | 8 | 4 | 4 |
Table 18.
Computational performance by ROS2 node
| Node | Rate (Hz) | Mean CPU (%) | Mean latency (ms) |
|---|---|---|---|
| realsense_node | 30 | 8.1 | 5 |
| pose_estimator_node | 30 | 19.4 | 26 |
| load_sensor_node | 50 | 3.2 | 6 |
| fusion_node | 30 | 2.9 | 10 |
| Total pipeline | – | 33.6 | 47 |
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (http://creativecommons.org/licenses/by/4.0/).
Copyright: This open access article is published under a Creative Commons CC BY 4.0 license, which permit the free download, distribution, and reuse, provided that the author and preprint are cited in any reuse.