

Submitted:
02 September 2026
Posted:
02 September 2026
You are already at the latest version
Abstract
Karlin, Klein, and Oveis Gharan introduced a randomized better-than-\(3/2\) approximation algorithm for metric TSP [KKO21] and subsequently established the corresponding improvement in the integrality gap of the subtour-elimination LP [KKO22], with an explicit constant \(\varepsilon>1.00000\cdot10^{-36}\). Gurvits, Klein, and Leake subsequently improved the certified saving to \(2.18000\cdot10^{-34}\) [GKL24]. We further obtain a randomized polynomial-time $(3/2-\varepsilon)$-approximation for every fixed \(\varepsilon<\varepsilon_\star\), where \(\varepsilon_\star>2.05522\cdot10^{-30}\), and consequently the subtour-elimination LP has integrality gap at most \(3/2-\varepsilon_\star\).
Keywords:
TSP
; LP
; approximation algorithm
1. Introduction
The traveling salesperson problem is among the oldest and most extensively studied problems in combinatorial optimization; formulations of the routing question go back to the nineteenth century [ABCC07, Chapter 1]. The modern polyhedral theory began with the cutting-plane work of Dantzig, Fulkerson, and Johnson [DFJ54. Held and Karp subsequently developed the linear-programming lower bound now called the subtour-elimination or Held–Karp relaxation [HK70. Metric TSP remains APX-hard [KLS15. In particular, it is NP-hard to approximate within . Thus the central algorithmic question has long been how closely a polynomial-time algorithm can approach the optimum.
The classical -approximation was discovered independently by Christofides and Serdyukov in the 1970s [Chr76,Ser78. Their method combines a minimum spanning tree with a minimum-cost parity correction on its odd-degree vertices. Wolsey later showed that the same guarantee holds relative to the subtour LP [Wol80, which also established the long-standing upper bound on its integrality gap. The widely studied conjecture predicts that the true integrality gap is . A related conjecture of Schalekamp, Williamson, and Zuylen asserts that the largest gap is attained by a half-integral vertex of the subtour polytope [SWZ14]; this made half-integral instances a particularly important testing ground for progress below .
Substantial improvements were obtained earlier for restricted metrics. Euclidean TSP admits polynomial-time approximation schemes due independently to Arora [Aro98] and Mitchell [Mit99. For graph metrics, Oveis Gharan, Saberi, and Singh introduced a randomized rounding method based on maximum-entropy spanning trees and obtained the first -approximation [GSS11. Mömke and Svensson then gave a combinatorial -approximation [MS11]; Mucha improved the factor to 13/9 [Muc12], and Sebo and Vygen reached 7/5 [SV14]. This graphic-TSP line demonstrated that parity correction could be made cheaper than half the optimum, while the maximum-entropy approach suggested a possible route for general metrics.
For instances with a half-integral optimum subtour-LP solution, [KKO20] gives a -approximation. For general metric TSP, [KKO21] proves the first randomized approximation with ratio and gives the explicit scale . The subtour-LP analysis in [KKO22] proves that its integrality gap is strictly below and also gives a better-than- result for the 2-edge-connected multi-subgraph problem. The conditional-expectation method in [KKO23] derandomizes the max-entropy algorithm.
Gurvits, Klein, and Leake later revisited the probabilistic part of the KKO analysis using new capacity bounds for real stable polynomials [GKL24]. Their estimates raised the controlling common-event probability from to [GKL24, Section 4.2], and yielded the explicit approximation constant [GKL24, Corollary 4.6]. This refinement preserved the max-entropy algorithm and the combinatorial framework while sharpening the quantitative probability bounds used in its analysis.
1.1. Our Result
We state our result as follows.
Theorem 1
(Informal version of Theorem 2). For some absolute constant , there exists a randomized polynomial-time algorithm that, on every metric TSP instance, returns a tour whose expected cost is at most . Consequently, the integrality gap of the subtour-elimination LP is at most .

Table 1.
Comparison of previous results with Theorem 1.
| Year | Authors | Reference | Certified lower bound on |
|---|---|---|---|
| 2022 | Karlin, Klein, and Oveis Gharan | [KKO22 | |
| 2024 | Gurvits, Klein, and Leake | [GKL24 | |
| 2026 | This work | Theorem 1 |
Organization.Section 2] reviews the KKO and GKL frameworks and summarizes the refinements that yield our improved constant. Section 3] introduces the notation, records the max-entropy reduction and its finite-precision guarantee, and gives the conversion from slack vectors to tours. Section 4] establishes the probability, payment, and parity-correction estimates, constructs the layered slack vector, and proves the main result of this paper.
2. Technique Overview
Section 2.1, Section 2.2] and Section 2.3] review the KKO21 framework, explain GKL24’s probability refinement, and summarize how our retuned probability, payment, and repair estimates yield the improved constant.
2.1. The KKO21 Framework
Step 1: Max-entropy tree and parity correction. Here KKO21 refers to the max-entropy framework of Karlin, Klein, and Oveis Gharan [KKO21]; we also use its subtour-LP extension [KKO22. Start with an optimum subtour-LP solution and perform the standard vertex-splitting reduction, introducing a zero-cost edge of value one. After deleting , the remaining vector x lies in the spanning-tree polytope. The algorithm samples a maximum-entropy spanning tree T with marginals x, lets O be the set of odd-degree vertices of T, and augments T by a minimum-cost O-join. The zero-cost edge is used only in the LP reduction and the fractional-join bookkeeping. Thus the tree has expected cost , and the problem is to construct a feasible fractional O-join of expected cost strictly below ; see [KKO22, Sections 2 and 6].
Step 2: Structure of near-minimum cuts. The vector already satisfies every odd-cut constraint except possibly when is extremely close to two. KKO therefore focus on the -near-minimum cuts. Crossing components of these cuts admit polygon representations, while the remaining relevant cuts can be organized into a laminar hierarchy. This approximate-uncrossing description is what prevents one edge from being charged by an unbounded number of near-minimum cuts. It also separates cuts crossed on both sides, cuts crossed on at most one side, and the degree, triangle, and outer-polygon cuts appearing in the hierarchy. The extension in [KKO22] replaces charging to edges of an optimum tour by repair sets extracted from the polygon representation. Consequently the entire comparison is against , which is the key step needed for an integrality-gap bound rather than only an approximation guarantee.
Step 3: Happiness events and payment. The quantitative heart of the method is a random signed slack vector. A hierarchy edge bundle is declared good when one of several local tree events has a uniform positive probability. These events say, for example, that prescribed boundary sets contain exactly one or two tree edges; they are called happiness events. On a happiness event, KKO decrease the slack of the corresponding bundle. A max-flow matching distributes the burden of an upward boundary among good horizontal bundles, and the payment theorem proves that every good edge receives a negative expected contribution. The common probability p is the minimum of six local happiness estimates, so the payment coefficient is proportional to p.
Step 4: Feasibility repair and parameter balance. Negative slack cannot be used without repairing the odd cuts on which it may create a deficit. KKO construct nonnegative repair vectors for cuts crossed on both sides and for the one-sided polygon configurations. Their support is chosen so that each relevant odd cut receives enough positive slack and every edge has bounded expected repair. In the notation of [KKO22, Theorem 6.1], the signed vector contributes a decrease of order , whereas the repair costs order . Choosing proportional to makes the net saving quadratic in , hence quadratic in p. This architecture—max-entropy tree, near-minimum-cut hierarchy, happiness events, matching and payment, and bounded-congestion repair—is the part retained by all subsequent work.
2.2. The GKL24 Refinement
Steps 1, 2, and 4 in Section 2.1] are reused directly. GKL use the same max-entropy spanning-tree algorithm and parity correction from Step 1, the same hierarchy and polygon structure from Step 2, and the same repair vectors and parameter balancing from Step 4. Within Step 3 they also retain the definitions of good bundles and happiness events, as well as the KKO matching and payment arguments. Thus GKL do not change the sampled tree, the combinatorial architecture, or the final O-join construction.
Only the probability certification in Step 3 is modified. A maximum-entropy spanning-tree distribution is strongly Rayleigh. Therefore its multivariate generating polynomial is real stable. If count tree edges in disjoint edge sets, then the probability of an exact pattern is a coefficient of this polynomial, while the expectations of the are entries of its gradient at the all-ones vector. GKL prove new capacity bounds that convert control of these expectations, including the expectations of partial sums, into a lower bound for the desired coefficient [GKL24, Theorem 4.1 and Corollary 4.2]. This replaces several case-specific Bernoulli-sum estimates in KKO by one multivariate stable-polynomial inequality. For the harder configurations, GKL first use capacity to reduce to a structured special case and then combine it with the original log-concavity and stochastic-dominance arguments.
How the modified probability argument works. The contrast with the KKO probability lemma is especially useful here. That lemma turns lower-tail and upper-tail estimates for every partial sum into a joint exact-count estimate, but its dependence on the tail parameter is doubly exponential in the number of counted sets. KKO observed that suitable expectation bounds imply the required tail estimates, yet the resulting generic constant was too small for their final analysis, so they proved the important happiness estimates by ad hoc arguments. GKL instead show, under the slightly stronger condition that every partial-sum expectation stays a fixed distance from the neighboring integer, that the exact-count probability has a simply exponential lower bound, with the correct dependence on that distance [GKL24, Theorems 2.5 and 2.6]. Their proof productizes a stable polynomial into affine factors, reduces the associated matrices to extreme points supported on bipartitioned forests, and inducts on forest leaves [GKL24, Section 3]. Removing the dependence on the total degree is what makes this capacity bound effective for the TSP events.
Quantitative effect of the modification. For events 2–5, the KKO coefficients of are , , , and , respectively. GKL replace them by , , , and GKL24, Section 4.2]; the first event is unchanged. At , the KKO and GKL lower bounds for the first five events are, respectively,
The sixth event is far from the bottleneck; GKL note that its threshold changes slightly when p is raised and record that it remains above the new common value. Thus the minimum rises from to , an improvement by a factor of GKL24, Section 4.2].
How the modification improves . Nothing after this substitution requires a new TSP construction. The KKO payment theorem still makes linear in p, and the final choice of still makes the approximation saving quadratic in p. Consequently, the -fold improvement in p becomes a factor of : the same parameterized formula changes from to . GKL package this dependence as and report GKL24, Lemma 4.5 and Corollary 4.6]. Comparing the displayed theorem guarantees and gives a factor of [KKO21, Theorem 1.1]. This ratio is larger than because the KKO theorem states its final constant conservatively: against the sharper pre-GKL bound quoted by GKL, the ratio is about 53 [GKL24, Sections 2 and 4.2]. In short, KKO supply the combinatorial mechanism that turns local happy events into a cheap O-join, whereas GKL supply a stronger real-stable-polynomial method for proving that those same events occur often enough.
2.3. Summary of Our Approach
Steps 1 and 2 retain the structural framework of Section 2.1. We use the same KKO algorithm and combinatorial framework: the subtour-LP reduction, the max-entropy spanning-tree law, the hierarchy and polygon representation of near-minimum cuts, and the conversion of a feasible slack vector into a cheap tour. Thus Section 4] concentrates on obtaining a stronger quantitative slack certificate under the exact max-entropy law; the finite-precision transfer is applied only after all layers have been combined (see Lemmas 1 and 2).
Section 4] first isolates the reusable payment and repair ingredients. The preliminary estimates separate the synchronized reduction and matching setup from the later edgewise payment replay (see Lemmas 4 and 24). They also keep the one-sided and two-sided cut-correction vectors distinct until their final combination (see Lemma 10). This organization identifies which inequalities and constants must be rechecked at the refined parameter point, allowing the later numerical choices to be retuned module by module without rebuilding the full argument.
Step 3 replays the probability, matching, and payment bounds at the refined parameters. We begin by strengthening the probability estimates for half top bundles. At the active parameter choice , sufficiently large upward mass forces the new goodness condition, and every atom is incident to at most one bad half bundle (see Lemmas 14 and 15). These facts preserve the structural control of bad bundles while allowing the larger value of r that drives the final improvement.
For the mixed event, we prove a same-side lower-tail bound with enough reserve at the active parameter point. Feeding this bound into the GKL window argument produces the required 2–1–1 happiness event with probability greater than (see Lemmas 17 and 18).
The paired-bundle route requires finer control of the successive conditionings. A rank-aware marginal-shift bound keeps the relevant counts within their required intervals, which yields the joint 2–2–2 event; combining this with the other event estimates gives all six required happiness events at the same probability p (see Lemmas 20, 21, and 19). These estimates also yield the structural trichotomy used in the bottom-edge payment analysis (see Lemma 22).
We independently thin the happiness events to a common probability so that the two reductions arising from a paired event are pointwise identical. We then recheck every source–sink cut of the auxiliary max-flow network for the stronger goodness threshold and the new matching capacities (see Lemmas 4 and 16). This produces exactly the synchronized matching data required by the edgewise payment calculation.
The payment analysis is also replayed at the new parameters rather than imported from the earlier parameter regime. We first bound the endpoint burden uniformly over the hierarchy cases, including the fractional and small-upward-mass regimes, and then combine this bound with the top-edge, small-endpoint, and bottom-edge calculations (see Lemmas 23 and 24). The resulting vector satisfies the coordinate and deterministic cut inequalities, decreases every good edge in expectation with coefficient , and gives every bottom edge the stronger coefficient .
Two repair vectors turn these payment inequalities into parity guarantees for all near-minimum cuts. Joint accounting of the two directional failure modes reduces the two-sided expectation coefficient from 18 to 10, while the one-sided vector retains coefficient 44 and is supported only on bottom edges (see Lemmas 9 and 10). The stronger bottom-edge payment can therefore absorb the entire one-sided cost instead of charging it globally.
Step 4 combines the vectors and layers the cut thresholds. At the final stage, we combine the payment, a deterministic good–bad correction, and the two repair vectors at each threshold , where . We realize one million such certificates on the same sampled tree, so their coordinate losses telescope, their cut guarantees cover every relevant odd cut, and their expected savings add (see Lemmas 25 and 26).
How the modifications improve . The gain comes from using in the probability chain, replaying the matching and payment inequalities at that scale, sharpening the two-sided bad-event accounting, and charging the one-sided vector only on bottom edges. The first numerical changes are
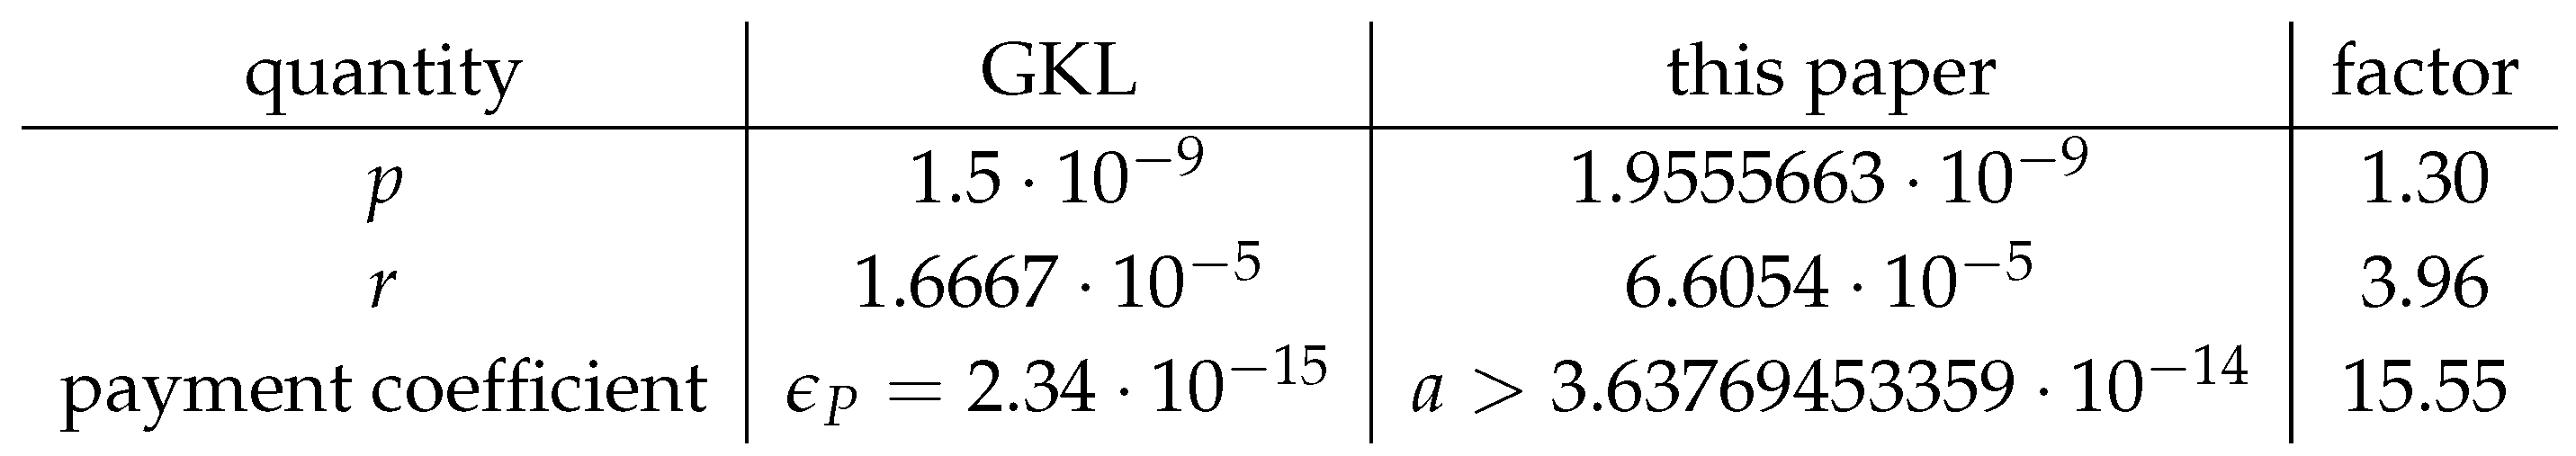 where the GKL payment coefficient is from [GKL24. Thus the improvement in p alone is only a factor of . The improvements in p and r contribute a factor of to , and the replayed payment inequalities supply the remaining factor of about , giving the total factor in the payment coefficient.
Both analyses turn the payment decrease into a quadratic saving. For GKL, the repair and conversion comparison is
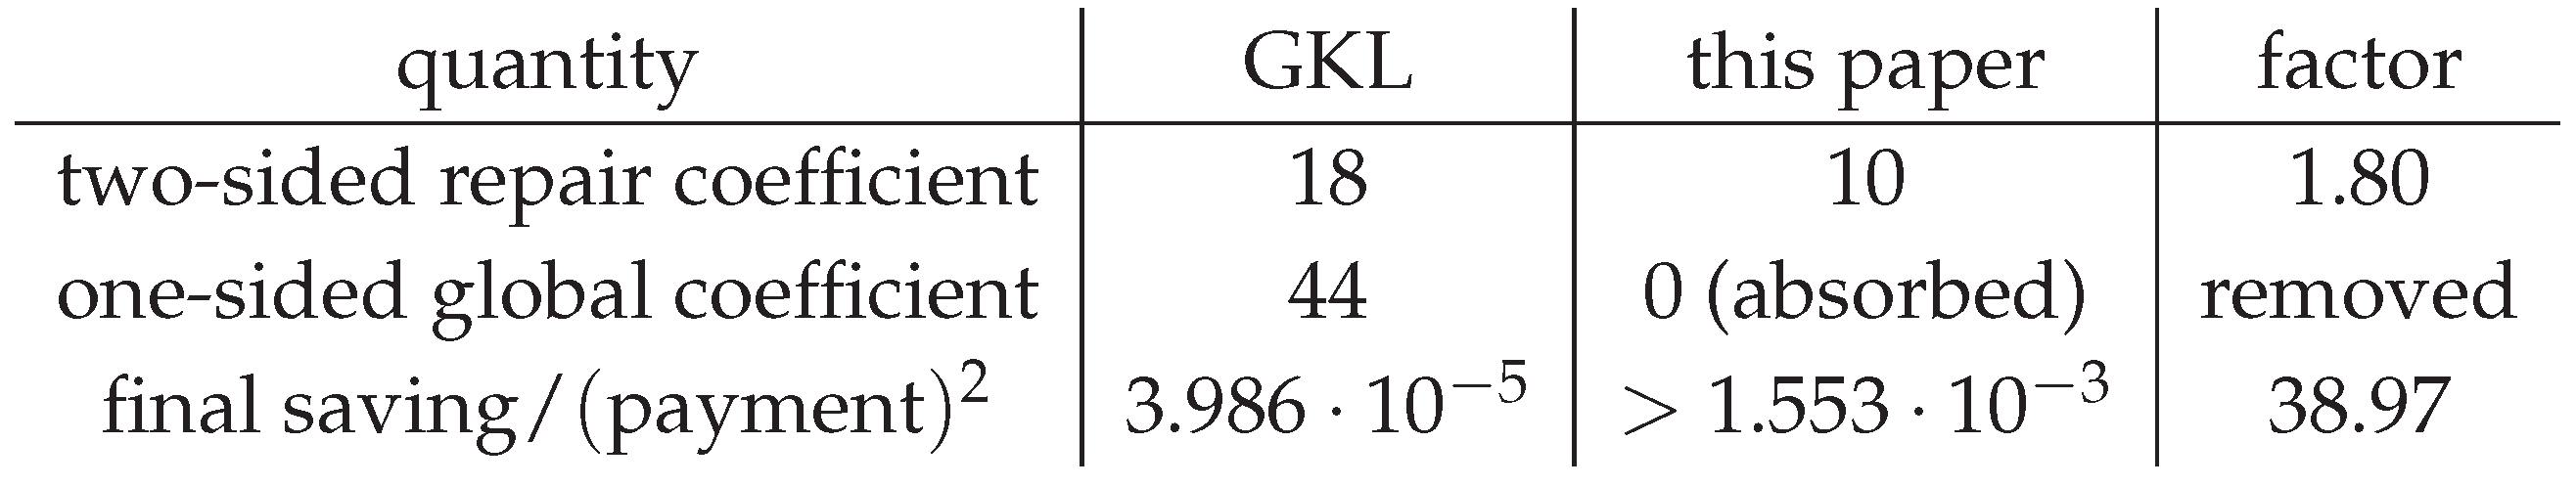
The one-sided vector still has coefficient 44, but the stronger bottom-edge payment absorbs its entire cost, so it contributes no global coefficient. The factor in the last row is the total improvement from the separated repair and layered conversion; it already includes the first two rows and should not be multiplied by again. Consequently, the payment gain contributes using the unrounded ratio, and the complete gain is approximately . Numerically, the GKL value becomes (see Lemmas 24 and 26). This is the claimed improvement of order .
3. Preliminaries
Section 3.1] introduces the notation for the subtour-LP solution, cuts, the KKO hierarchy, and the exact and approximate max-entropy distributions. Section 3.2] records the standard reduction to the spanning-tree polytope and the finite-precision max-entropy guarantee. Finally, Section 3.3 converts feasible slack vectors into a tour-cost bound while accounting for the approximation error.
3.1. Notation
Throughout the paper, references to numbered statements in [KKO21, [KKO22, and [GKL24] use, respectively, the full versions arXiv:2007.01409v6, arXiv:2105.10043v3, and arXiv:2311.09072v2.
Let denote a feasible subtour-LP solution after adjoining the zero-cost edge , and set . Let x be the restriction of to E, let , and write . We use for the optimum subtour-LP value.
For a vector and an edge set , write and . For a nonnegative edge-cost vector c, write .
For a vertex set , let and . If is a spanning tree and , write . In particular, is the number of tree edges crossing the cut S.
When invoking the KKO hierarchy and polygon classification, we identify and . Thus every classified cut satisfies ; cuts with are handled separately by setting . A cut S with is η-near-minimum if .
We use the hierarchy and polygon terminology of [KKO22, Appendix B]. The construction in the proof of [KKO22, Theorem B.3], together with [KKO22, Theorem 6.2 and Fact B.4], produces for every x and a valid hierarchy whose root is , whose one-sided and two-sided classes exhaust the relevant -near-minimum cuts, and whose added hierarchy cuts are -near-minimum. In the payment estimates we use the conservative uniform envelope , consistent with [KKO21, Fact 4.34]; the one-sided repair estimate retains the sharper bound. For a non-root hierarchy cut S, write for its parent, , and . The children of a hierarchy cut are called its atoms. For disjoint atoms , the set is the edge bundle with one endpoint in each. Hierarchy cuts are classified as degree cuts or near-cycle cuts. Following [KKO22, Definition B.1], a triangle cut is a hierarchy cut with exactly two children. Separately, the three-atom degree configuration in [KKO21, Case 1 in the proof of Lemma 7.6] will always be called a three-atom degree configuration. The KKO polygon classification partitions the relevant near-minimum cuts into those crossed on both sides and those crossed on at most one side. When applying the KKO payment theorem, we follow [KKO21, Definition 4.31] and regard a triangle cut as a degenerate polygon cut with .
Whenever a KKO hierarchy is used, write d for the uniform error envelope just described. The one-sided repair theorem retains its sharper error .
We use for the exact max-entropy distribution on spanning trees with marginals x, and for a computable -uniform approximation. Unless a subscript is displayed, probabilities and expectations are taken over the current random spanning tree and any auxiliary randomness in the slack vectors.
3.2. Setup and Max-Entropy Approximation
We first record the standard reduction that places the subtour-LP solution in the spanning-tree polytope, together with the finite-precision max-entropy guarantee.
Lemma 1
(Subtour-LP reduction and max-entropy approximation). An optimal extreme point may be written in the form above so that x belongs to the spanning-tree polytope and
Every positive coordinate of is at least . For every rational , one can compute, in time polynomial in n and , a λ-uniform spanning-tree distribution satisfying
Moreover, there is an explicitly computable universal constant , independent of the instance, such that, for , the exact and approximate distributions satisfy
Proof.
The reduction and the spanning-tree-polytope assertion are from [KKO22, Section 2.1 and Fact 2.2]. The approximation algorithm is [KKO22, Theorem 2.1], and the coordinate bound is recorded in [KKO22, Section 6.2]. Let be the marginal vector of , and define . Since for , every spanning-tree law with marginals is supported on trees contained in . On this support,
Thus, for every spanning-tree law with marginals ,
because and have the same expectation of the preceding display. Hence is the maximum-entropy law with marginals , also when some weights vanish. Since and both marginal vectors have coordinate sum ,
Apply the quantitative form [SV19, Theorem 10] to the spanning-tree polytope. Its ambient dimension is at most , its unary facet complexity is one, the diameter of its vertices is smaller than , and the number of spanning trees is at most . Substitution in that theorem gives
after increasing one universal constant. The proof of the cited theorem is effective, so we fix any computable value supplied by that proof; no optimization of this value is needed here. □
3.3. From Slack Vectors to Tours
Finally, we record the standard conversion from feasible slack vectors to a tour-cost bound, including the approximation loss.
Lemma 2
(Slack-to-tour conversion and change of tree law). Let denote the cost of a minimum join for the odd vertices of T. Let and satisfy and whenever S is η-near-minimum and is odd. If , then the vector y defined by
is a feasible fractional join for the odd vertices of T.
Consequently, if satisfies , then
More generally, if satisfy
then
For the law in Lemma 1,
Proof.
Since , all coordinates of y are nonnegative. Cuts crossed by satisfy the join constraint because . For the remaining cuts, the fractional-join construction and the calculation for cuts that are not -near-minimum are given in [KKO22, Section 6.2]. Hence , and the two conclusions under follow from and the stated coordinatewise expectation bounds.
It remains to compare the two tree laws. For every spanning tree T, the vector that equals on E and one on the zero-cost edge is a feasible fractional join for the odd vertices of T. Therefore
Moreover,
Using gives
Adding the tree- and join-cost comparisons proves the claim. □
4. Proof of Upper Bound
Section 4.1 converts the payment and parity-correction construction into the final approximation bound. Section 4.2 introduces the tuned parameters and summarizes the payment construction. Section 4.3 establishes synchronized reduction events and controls the burden passed through hierarchy ancestors. Section 4.4 derives the expected decrease on good top edges and bottom edges. Section 4.5 establishes the deterministic inequalities needed on polygon cuts and degree cuts. Section 4.6] constructs the two parity-correction components and combines them with the payment vector. Section 4.7 develops the tail bounds and good-bundle thresholds for the improved parameters. Section 4.8 verifies matching feasibility and the common-event probability estimates. Section 4.9 controls marginal changes under conditioning and obtains the paired-bundle probability estimate. Section 4.10 derives the payment bounds for the selected parameters. Section 4.11 converts these bounds into the layered slack vector and the final improvement.
4.1. Proof of the Main Theorem
The layered slack-vector construction supplies the improvement under the exact max-entropy law. The finite-precision comparison then transfers this bound to the polynomial-time implementation and yields the main result.
Theorem 2
(Formal version of Theorem 1). There exists an explicitly computable constant such that, for every fixed and every metric TSP instance, there is a randomized polynomial-time implementation of the max-entropy algorithm whose expected tour cost is at most . Consequently, the integrality gap of the subtour-elimination LP is at most .
Proof.
Solve the subtour LP and choose an optimal extreme point . Apply Lemma 1, and let x be the resulting vector in the spanning-tree polytope. Then
Apply Lemma 26 and define . For the sampled tree T, define for and . Since , every coordinate of y is nonnegative. A cut crossed by has y-value at least one, and every other cut containing an odd number of tree edges has y-value at least one by the same lemma. Thus y is a feasible fractional join for the odd vertices of T. The minimum join is no more expensive than y, so under the exact max-entropy law the expected tour cost is at most
It remains to control the computable approximation. Fix and define
Define
and choose the largest number of the form , , satisfying . Then . Since and ,
Lemma 1 therefore gives
The running time is polynomial because
The comparison in Lemma 2 is applied once to the output-cost function ; the one million layers incur no separate change-of-law loss. Combining that lemma with the exact-law estimate above gives
The integrality-gap conclusion follows because the expectation is an average over tours. Taking proves the final claim. □
4.2. Retuned Payment Theorem
We first define the numerical parameters of the retuned KKO payment construction. The sharper expected-decrease coefficient entering Theorem 2 is established separately in Lemma 24.
Definition 1
(Retuned payment parameters). Define
let , and set
For every , define
Finally, define
Throughout the payment construction, whenever , define the KKO degree-cut increase . Matching conservation then forces every corresponding to vanish, so this convention is the continuous zero-mass case of the usual formula and no quotient by zero occurs.
By [GKL24, Section 4.2], each of the six common events has probability at least p. With the parameters in Definition 1, the KKO construction gives the following payment theorem.
Lemma 3
(Retuned KKO payment theorem). Let and the relation be as defined in Definition 1. For every KKO hierarchy with error and every , the KKO main payment construction can be carried out. More precisely, it produces a partition
and a random payment vector with the following properties:
- ()
- every bottom edge belongs to ;
- ()
- for and for ;
- ()
-
for every . Moreover, there is a coefficient satisfyingsuch that every bottom edge satisfies ;
Proof.
The conclusion follows from the four lemmas below. Lemma 4 supplies the synchronized events, and the matching coefficients are supplied by [KKO21, Lemma 6.2] with the parameters checked below. Lemma 5 verifies the endpoint burden required by the KKO construction. Lemmas 6 and 7 give the two expected-decrease bounds. The partition, bottom-edge support, and coordinate lower bounds are the unchanged pointwise parts of the KKO payment construction. Hence a–c follow. □
4.3. Matching and Ancestor Estimates
The synchronized reduction events and the ancestor estimate provide, respectively, the matching data and the endpoint-burden bound required for the edgewise payment estimates.
Lemma 4
(Synchronized reduction events). Let . If every happiness event used by the KKO payment construction has probability at least p, then all reduction events may be chosen to have probability exactly p. The two reductions arising from one paired 2–2–2 event may moreover be chosen pointwise identical.
Proof.
Use exactly the reduction-event coupling from [KKO21, Section 7]. For an ordinary happiness event of probability , let be an auxiliary Bernoulli event of probability that is independent of the tree, and define the reduction event to be . It has probability p and, conditional on , the auxiliary coin reveals no tree information.
In Case 3 of [KKO21, Theorem 5.28], let be the joint 2–2–2 happiness event for the fixed paired bundles at u. Define , use one Bernoulli event of probability independent of the tree, and set
pointwise. Thus the simultaneous-reduction identity required in the proof of [KKO21, Lemma 7.8] is retained without biasing the conditional tree law. All reduction events below use this synchronized convention.
These auxiliary coins define only the payment vector used in the analysis. The passage from to is made directly at the level of by Lemma 2; it does not require the reduction events or layered slack vectors to be reconstructed under .
□
For Lemma 3, use the max-flow matching of [KKO21, Lemma 6.2] with
The four hypotheses of that lemma are satisfied exactly as stated:
Consequently, the matching coefficients exist. They satisfy the capacity inequality and conservation identity in [KKO21, Eqs. (26)–(27)], with
and with the factor from [KKO21, Lemma 6.2].
The principal probabilistic calculation is the following uniform bound on the burden assigned to one hierarchy atom. Fix and define as in Definition 1.
Fix an atom u and write
Partition the upward edges at u into the good top edges , the bad top edges , and the bottom edges . For a good top edge , define
For a bottom edge g whose polygon parent is P, define
The complete normalized endpoint burden in [KKO21, Eq. (36)] is
The payment analysis requires this normalized burden to be dominated uniformly by the upward mass available at u.
Lemma 5
(Retuned ancestor estimate). For every and every hierarchy atom u with , the burden satisfies .
Proof.
Write and . Since
and [KKO21, Corollary 5.9(iii)], applied as in the proof of [KKO21, Corollary 5.10], gives a Bernoulli-sum parameter. Here and in the cited KKO estimate, define as in [KKO21, Definition 5.8]. Then
Consequently, [KKO21] gives
For the last inequality, the degree-eighteen Taylor polynomial at gives
Direct subtraction now shows that the claimed ancestor inequality follows from
This is the precise sufficient inequality used below.
Suppose first that . If , then Eq. (2) follows from
because .
We use the hierarchy levels from [KKO21, proof of Lemma 7.3]: j is the last level whose intersection mass is at least , while k and ℓ are the last levels whose intersection masses are at least and , respectively. The relations and the same three main cases therefore remain unchanged. Only the numerical split inside Case 1 is moved from to .
Suppose first that . For the degree partition at level j, the hierarchy identities give , and hence
By the published bound in [KKO21, the mass in this set that is good but not 2–1–1 good is at most . Therefore either the bad edges or the 2–1–1 good edges have mass at least
In the former case, each such edge supplies one full unit of saving in Eq. (2). In the latter case, [KKO21, Claim 7.4] supplies average saving at least per unit. At , the two respective margins are
If , Eq. (3) handles bottom mass at least . Otherwise, define
The level sets are nested and
By the definitions of j and ℓ,
Since and ,
Every edge in is a top edge at a level between and ℓ. At each such level the intersection mass is less than , because j is the last level at which it is at least , and is at least , by the definition of ℓ. Thus [KKO21] applies with parameter r to every good edge of . A bad edge supplies one full unit of saving in Eq. (2), while a good edge supplies at least . Hence every unit of supplies at least , and
In Case 2, define
Here , while the definition of ℓ gives
Since in the case not already handled by Eq. (3),
Moreover, Case 2 has , and every retained level has intersection mass at least . Thus [KKO21, Claim 7.5] applies with parameter r to every good retained edge, while every bad retained edge supplies one full unit of saving. The resulting margin is
In Case 3, , so the right side of Eq. (2) is at most . The three alternatives in [KKO21, Case 3 of the proof of Lemma 7.3] now give the desired inequality directly. If , then
If , then, using ,
Otherwise the top-edge set has mass at least . A bad top edge contributes one full unit to Eq. (); for every good top edge, conditioning first on the parent of u exactly as in that proof and then applying [KKO21, Claim 7.5] gives saving at least per unit. Thus every edge of the top set contributes at least this amount. Hence
Thus the bottom, bad-top, and parity alternatives each imply Eq. (2). Eq. (3) through Eq. (9) prove the claimed ancestor inequality whenever .
It remains to treat . Suppose and let . By the definition of the upward bundle,
Fix a good top bundle above u and one of its reduction events , where . The reduction event makes both bundle endpoints trees. Since , the factorization argument below together with the marginal-distortion estimate of [KKO21, Lemma 2.23] gives
We next justify the additional conditioning. By Lemma 4, the auxiliary thinning coin is independent of the tree. After the endpoint is made a tree, [KKO21, Fact 2.8] factors its internal tree from the contracted tree. Relative to , the remaining tree conditions and boundary-count conditions defining the happiness event of f depend only on the contracted tree and on ; they do not reveal the remaining internal edges of . Conditioning further on being a tree and applying Fact 2.8 once more therefore leaves the tree-conditioned law inside used in [KKO21, Claim 7.5], possibly conditioned on the displayed boundary count. The internal edges of and these contracted-tree variables are disjoint after contraction, so this is the literal factorization of [KKO21, Fact 2.8], not an independence assumption about overlapping tree events. Since the claim is uniform over every value of that count, it remains valid under . Applying it with parameter U and then conditioning on whether is a tree gives
Here and , so each good top edge contributes saving at least . Moreover, each bad top edge contributes one unit to the left side of Eq. (2), and each bottom edge contributes at least . Since
and , every unit of contributes at least . Thus Eq. (2), and hence the claimed ancestor inequality, holds for . □
4.4. Edgewise Payment Estimates
The ancestor estimate gives a uniform decrease when both endpoints are above the cutoff. We treat smaller endpoints by the KKO matching factor and a separate three-atom calculation.
Lemma 6
(Good top-edge decrease). Let a be as defined in Definition 1. Fix a KKO hierarchy with and , define , and let be the vector given directly by the synchronized KKO payment formulas for these data. Every good top edge e in the synchronized construction satisfies .
Proof.
If both endpoints have upward mass at least , the endpoint estimate and the matching capacity identity give the normalized decrease
whenever both endpoint estimates apply. If a small endpoint lies in a degree cut with at least four atoms, halves its crude burden, and gives the same conclusion.
Only the three-atom degree configuration in [KKO21, Case 1 in the proof of Lemma 7.6] remains. By [KKO21, Lemma 6.4], all three internal bundles in this configuration are good, so all their matching coefficients are defined. Let its atoms be , suppose
and write
The degree and parent-cut equations give
The nested-cut bound gives . It follows from Eq. (13) that
The subtour constraint at u gives
Combining this with and the two upper bounds yields
Hence , so and .
Define . Conservation at , followed by matching capacity for the f- and g-bundles, yields
Using Eq. () and the preceding bounds, we obtain
Since ,
At u use the crude KKO burden, and at v use Lemma 5. Subtracting the total burden from the top-edge reduction gives normalized decrease at least
The expression is minimized at , and direct rational substitution gives
Thus every good top edge has expected decrease at least . □
The three KKO bottom configurations admit a stronger coefficient.
Lemma 7
(Bottom-edge decrease). Fix a KKO hierarchy with and , and let be the vector given directly by the synchronized KKO payment formulas for these data. There is a constant satisfying
such that every bottom edge e satisfies .
Proof.
Use the exact degree-parent Case 3 saving in the proof of [KKO21, Lemma 7.8]. Let be the polygon partition and let be the degree partition. By [KKO21, Remark 5.20], , , and . [KKO21, Definition 5.18 and Eq. (25)] gives . The paired half bundles supplied by [KKO21, Theorem 5.28(iii)] satisfy and . Define
Since both bundles are half bundles, the preceding inclusions give
Indeed,
and the same argument applies to v. Let . The synchronized construction makes the two reductions at the degree parent pointwise identical and gives each of the three reduction events in the Case 3 calculation probability p. Therefore the exact estimate in that proof is
Relative to the trivial contribution on D, the saved coefficient is consequently
Define
The other two alternatives of [KKO21, Theorem 5.28] save at least and , respectively, both of which exceed . Thus [KKO21, Eq. (50) and Lemma 7.8], together with , gives the normalized increase
when the parent is a degree cut. If the parent is a polygon cut and P is a boundary atom, [KKO21] bounds the horizontal contribution by and , giving
For an interior atom, [KKO21, Lemma 7.11] gives and the hierarchy gives , yielding
Each is increasing on . At , subtracting both and the target decrease from 1 leaves margins greater than
respectively. Thus every bottom edge has expected decrease at least
and direct rational substitution gives the displayed bounds on . □
4.5. Deterministic Payment Inequalities
The pointwise cut inequalities are independent of the numerical decrease estimates.
Lemma 8
(Deterministic payment inequalities). Fix a KKO hierarchy with uniform error envelope and a parameter , and let be the payment vector from the synchronized construction for these data. For a polygon cut P, including a triangle cut viewed as a degenerate polygon with , let be its polygon partition and call a set F admissible for P if for every and .
- ()
- if P is not left happy, then for every admissible edge set F for P, ; the symmetric inequality holds when P is not right happy;
- ()
- if S has a degree-cut parent and is odd, then .
Proof.
The proof uses no numerical payment estimate. Use the zero-mass convention fixed before Lemma 3. If a polygon cut P (possibly a triangle) with partition is not left happy, then its reduction event does not occur and the reduction is zero on every admissible set F. Writing r and for the unchanged KKO reduction and increase vectors, the definition of gives
The right-happy inequality is symmetric. If S has a degree-cut parent and is odd, the horizontal reductions vanish. If , there is no upward reduction to compensate and all remaining increases are nonnegative, so the conclusion is immediate. Otherwise, matching conservation gives , and hence
These are precisely [KKO21. This proves both conclusions. □
4.6. Repair and Combined-Vector Estimates
We first separate the one- and two-sided repair vectors and record the good-edge mass needed for their combination. We then assemble these ingredients with the retuned payment vector.
The following lemma sharpens the expectation estimate in the KKO two-sided repair theorem. The construction and its pointwise guarantee are unchanged; the improvement comes from accounting jointly for the two failures defining each directional bad event.
Lemma 9
(Sharpened two-sided KKO repair). Let be a feasible subtour-LP solution with support , let x be its restriction to E, and let μ be any spanning-tree distribution with marginals x. Let . For every , there is a random vector such that:
- ()
- if an η-near-minimum cut S is crossed on both sides and is odd, then ;
- ()
- for every edge e, .
Proof.
We use the KKO construction from [KKO22. Fix a cut L crossed on both sides, and let and be the left and right crossing cuts chosen by that construction. Define
and, for every proper cut side X, define
The cuts are -near-minimum cuts. The four cut sides are proper and avoid the endpoints of the added edge; in particular,
They are also -near-minimum cuts by [KKO22.
The KKO edge sets partition as
where
The disjointness is also recorded in [KKO22. For disjoint cut sides , the cut identity gives
Consequently,
and hence
The right bad event is
By [KKO22,
By [KKO22,
Adding these bounds and substituting the exact expression for gives
Here we used and . The symmetric calculation gives
We now use the same increase sets and the same vector as in the proof of [KKO22. Lemma 5.3 there triggers the relevant event, Lemma 5.1 places its increase set inside the cut boundary, and Lemma 5.6 supplies mass at least ; together they give a. Fact 4.9 gives the unique relevant polygon, and Lemma 5.4 with the final pigeonhole mapping shows that an edge belongs to at most two right-event and two left-event increase sets. Thus it belongs to the increase sets of at most four directional bad events. Therefore the union bound gives
which proves b. □
The two-sided vector does not cover the one-sided near-minimum cuts. We therefore keep the two components separate so that the one-sided vector remains supported on bottom edges and can be absorbed by their stronger payment decrease.
Lemma 10
(Separated KKO repair vectors). Fix the exact max-entropy tree law with marginals x and the KKO hierarchy for the η-near-minimum cuts, where , and let . Let be a partition in which every bottom edge belongs to , and let satisfy the deterministic inequalities in Lemma 8. Assume in addition that
Then there are nonnegative random vectors such that
- ()
- if an η-near-minimum cut S is crossed on both sides and is odd, then
- ()
- if an η-near-minimum cut S in the KKO one-sided classification is not the root and is odd, then
- ()
- for every edge,
- ()
- pointwise, is supported only on bottom edges, and hence only on .
Proof.
Apply Lemma 9 with parameter
and apply the construction in [KKO22] with parameter
to obtain and . Lemma 9 gives a and the first expectation bound in c. Theorem A.12 and Lemma A.13 give b together with the published one-sided estimate
which is the second expectation bound in c.
We verify b without invoking [KKO22] as a black box. If S is a hierarchy cut whose parent is a degree cut, Lemma 8-b gives
whenever is odd. For an interior cut or atom in a one-sided near-cycle component, [KKO22] gives
The last inequality is exactly where the coordinate hypothesis is used:
The same conclusion holds for a leftmost or rightmost cut when the corresponding side is happy. Suppose instead, without loss of generality, that S is leftmost and its polygon P is not left happy. Let be the union of the non-root atoms of P and define
By [KKO22, . Every edge joins distinct children of P, and hence satisfies . Thus Lemma 8-a applies. Since and the worst possible contribution from the remaining C-edges is ,
The rightmost case is symmetric. If the parent is a triangle cut P with children , use . Lemma A.13 of [KKO22] gives the happy-case repair. For the non-happy case, the identity
and the subtour constraints for , together with , give . Therefore Lemma 8-a applies by the same displayed calculation. These are Types 4 and 5 in the proof of [KKO22, and together with the degree-parent and interior cases they exhaust the one-sided classification.
For d, the construction in [KKO22] assigns repair only to sets between consecutive non-root atoms; the triangle construction in [KKO22] assigns repair only to . In each case the atoms are distinct children of the same near-cycle or triangle cut. Their smallest common hierarchy ancestor is therefore their parent, so these edges are bottom edges. The hypothesis of the lemma makes every such edge good. □
Combining these vectors with the payment construction also requires a uniform lower bound on the good-edge mass of every relevant one-sided cut. The published threshold provides this bound.
Lemma 11
(Published-threshold good-edge mass). For the KKO good-edge set produced by Lemma 3, define
If the hierarchy error satisfies , then every η-near-minimum cut crossed on at most one side in the KKO classification, other than , satisfies
Proof.
First let S be a non-root hierarchy cut whose parent is a degree cut, and write . The published threshold in [KKO21] implies that if , every horizontal bundle in is good. The hierarchy cut identity then gives
If , the same theorem allows at most one bad horizontal bundle, of mass at most . Since every subtour cut has value at least 2,
Now let S be an atom or another one-sided cut represented by a near-cycle component, and let be the union of the non-root atoms of that component. By [KKO22,
Every edge of is a bottom edge and hence belongs to by Lemma 3-a. Therefore
This includes the triangle-cut case. The root is excluded from the good-mass assertion and is handled by parity. Indeed, and , so . Every spanning tree has positive degree at both vertices, so the two degree random variables, each having expectation one, are equal to one almost surely. Connectivity prevents their two unique tree edges from joining directly to , since that would isolate from the remaining vertices. Hence the two unique incident edges both cross , and almost surely. Thus the root never creates an odd-cut constraint. □
The combined-vector calculation, including the reparameterized probability input and the final constant, is proved in Lemma 25.
4.7. Tail Bounds and Good-Bundle Thresholds
This subsection begins the final parameter chain by establishing the tail estimates and good-bundle thresholds. The next four subsections establish matching feasibility, control marginal shifts and paired-bundle probabilities, derive the payment estimates, and construct the final slack vectors.
Definition 2
(Parameters for the refined analysis). We define
All probability statements refer to the exact max-entropy spanning-tree law. The finite-precision transfer is separate.
The paired-bundle calculation requires converting concentration at a central rank into a bound on the corresponding mean. The following estimate provides this conversion for strongly Rayleigh laws.
Lemma 12
(Central-rank mean bound). Let X be the cardinality of a fixed set of coordinates under a strongly Rayleigh law, let be an integer, and suppose
Define and
Then .
Proof.
Projection preserves the strongly Rayleigh property, and [GKL24] shows that the rank sequence is the law of a Bernoulli sum. In particular, it is log-concave. For the upper tail, and
Log-concavity implies
Therefore, using first the total upper-tail mass and then log-concavity,
For the lower tail, log-concavity similarly gives for . Its total mass is at most , and hence
Finally, follows by direct subtraction. □
For non-half top bundles and bottom bundles, we retain [KKO21]; only the half-top-bundle threshold changes. A half bundle is called good here when its conditional 2–2 probability is at least .
Lemma 13
(Reparameterized two-tail estimate). In the setting of [KKO21, if a half bundle is good, then
where Z is the sum of the two residual boundary counts used in that lemma. Let C be the leftover set in the degree partition, so . If the lower-tail variable is subsequently conditioned as in [GKL24, first on and then on the endpoint bundle containing one edge, its lower-tail probability remains greater than .
Proof.
Define and . Goodness gives , and the first-moment and log-concavity argument in [KKO21] gives
If , the right side is smaller than , whereas , a contradiction.
For the other tail, suppose . The mass at three is at least , so the ratio of successive upper-tail masses is at most . The upper-tail first-moment bound in [KKO21] is
Substitution in the lower first-moment inequality from the source proof gives
contradicting .
For the last assertion, write and , so the lower-tail variable is . Intersecting the event with loses at most . After this conditioning, the surviving residual set is disjoint from the bundle . Under the endpoint-tree conditioning one has , so the exact-one condition is the increasing event . By [KKO21, the endpoint-tree conditional law is strongly Rayleigh, and deletion of the coordinates in C preserves this property. Negative association for the two disjoint coordinate sets shows that conditioning on this event can only decrease the probability of the increasing event , and hence can only increase the required lower-tail probability. Consequently
□
The endpoint-mass calculation below shows that sufficiently large upward mass forces a half bundle to meet this strengthened threshold.
Lemma 14
(Reparameterized good-bundle threshold). In the setting of [KKO21, if , then the half bundle incident to u is good.
Proof.
Follow the conditioning and notation of the source proof, and define . The outer event has probability at least , so it suffices to show that the internal event has probability greater than .
Define . Suppose first that . The four tail probabilities used in the first case of [KKO21] give
The two-variable specialization of [KKO21] therefore gives
This comparison has a rational certificate. Indeed,
so . The function is increasing on . The alternating Taylor bound gives, for , . Substituting gives a value greater than . Consequently,
Suppose instead that . We first justify the mean range used in the second case of the source proof. The expectation bounds in [KKO21] give . If , the three explicit branches in [KKO21, applied with target value two, give
contrary to the present assumption. Hence , and the same lemma gives , exactly as in the source proof. Log-concavity now gives
Moreover, . Since
KKO21, with , bounds each upper-tail first moment by
The two expectation intervals in [KKO21] now imply
Here the first inequality follows exactly as in the source: restrict to , lose at most R, and use stochastic dominance; the second is the symmetric statement for Y.
Conditioned on , X is a sum of two Bernoulli variables. Minimizing its probability of being one subject to the preceding two tail bounds gives
Thus
The outer factor proves the claim. For completeness, the terminal comparisons above follow from
and
□
The stricter definition of goodness must also be propagated through the lemma that limits the number of bad half bundles at one atom.
Lemma 15
(Reparameterized competing half bundles). In the setting of [KKO21, one of two half bundles incident to the same atom is good under the present definition. Consequently, each atom is incident to at most one bad half bundle.
Proof.
Use the same dichotomy and conditioning as in the source proof. In its first branch, the conditional probability of the required 2–2 event is at least
In its second branch, the corresponding probability is at least
The proof of [KKO21] uses no relation between r and h, so these are the only threshold comparisons that change. Applying the lemma to every pair of incident half bundles gives the final assertion. □
4.8. Matching Feasibility and Common Events
The modified threshold changes the endpoint bound in the matching network. The following lemma performs that replay rather than invoking the published matching lemma with different parameters.
Lemma 16
(Reparameterized matching). For every hierarchy error , the matching construction of [KKO21] remains valid with
Proof.
Lemma 14 replaces the published endpoint threshold by , while Lemma 15 supplies the source fact that an atom is incident to at most one bad bundle. We check every cut family in the max-flow proof of [KKO21.
For a three-atom degree cut, a hypothetical bad bundle forces the third atom to have degree at least . Thus the contradiction in [KKO21] remains valid because
The corresponding source-only max-flow cut has capacity margin
For the source cuts with at least five atoms, Eqs. (28)–(29) of the source give, with ,
Its coefficient in n is positive, so the worst case is , where . For a four-atom cut with at most one bad bundle, the corresponding margin is
These are the two places where the source used only , , and . In the four-atom case with two bad bundles, the argument forcing every upward mass to be -fractional remains valid because
The remaining capacity comparison is exactly
It remains to check the nontrivial max-flow cut in [KKO21. Let and let be the number of bad bundles adjacent to W. Replacing the source endpoint constant 9 by , Eqs. (30)–(31) reduce to
For , the slack in (*) is minimized at and , where
Now suppose and define
Since
the worst value of d is . At that value,
Increasing w by one increases S by , while increasing k by one increases S by . Hence for every . Thus every source–sink cut has the required capacity, and the matching exists with the required capacity inequality and conservation identity. □
When a top bundle is not already known to be 2–1–1 good, the GKL window argument requires a same-side lower-tail event. The following bound supplies that event with room above .
Lemma 17
(Same-side mixed-bundle lower tail). In the setting of [KKO21, let and be good half top bundles, and let be the degree partition of with . With and , one of the two bundles satisfies
after interchanging and if necessary.
Proof.
The dichotomy in [KKO21] is independent of r and gives, after interchanging the two bundles if necessary,
The conditioning event has probability at least . Define and . Since , , and
the degree-partition and half-bundle inequalities give the r-dependent estimate
Therefore
Since , the conditional mean of is at most . Writing for the event that and are trees, Markov’s inequality for the nonnegative integer-valued variable X gives
All numerical inequalities remain strict for and . □
The preceding lower-tail event is the premise needed for the GKL window argument. The next estimate converts that premise into 2–1–1 happiness at the common probability scale p.
Lemma 18
(Reparameterized GKL window estimate). In the setting of [GKL24, replace by , and write for the residual boundary set in that lemma. If , then the bundle is 2–1–1 happy with probability greater than p.
Proof.
The reparameterized tail calculation gives
To verify the rank estimate at the present value of r, define . The same conditional-marginal calculation as in the source can be written without the old ratio assumption. Before conditioning, the mean is . The two endpoint-tree conditions change it by at most . Apply the source marginal estimate jointly to the subsequent conditions and : after separating the possible overlap of C with Y and , their combined downward change is at most , and their upward change is at most . Since , and , this gives
Moreover, because it is the boundary size of the conditioned subtree . Hence one Bernoulli in its rank law is forced to one, and the remaining Bernoulli sum has mean in . Substitution in [KKO21, with target two, gives : over this interval its branches with zero, one, and two additional forced coordinates are bounded below by , , and , respectively. These bounds follow by monotonicity of the three explicit branch formulas on the displayed mean interval. The rank sequence is log-concave as well. If its mass at two were smaller than , its entire lower tail would be at most
a contradiction. Thus the central mass used in the proof of [GKL24] is at least .
We now repeat all tail estimates in that proof with r left explicit. Let be its conditional law. The conditioning has probability greater than , and its loss from the assumed lower-tail event is at most . Thus
Moreover, the conditional-marginal inequalities used in the source proof give
For example, the lower-tail applications use mean at least , while the Markov applications use mean at most ; these give respectively and . The and bounds follow from the source applications with mean lower bounds and , respectively. Finally, the displayed upper bound on and Markov’s inequality give the bound.
Define . One application of [GKL24] gives
Indeed, write s for the displayed conditional probability. If , the claim is immediate. Otherwise the special case of that corollary gives a conditional mode of mass at least , and its second inequality gives the displayed lower bound on s. Lemma A.10 of [GKL24] gives
where the latter uses . Similarly,
Writing , the same application of [GKL24] to and gives
To justify the mode estimate used next, project to and truncate this projected law to total rank three. Projection and full-ground-set truncation preserve the strongly Rayleigh property [KKO21. Project the resulting law to and truncate it to total rank two. This is again a full-ground-set truncation, and under the preceding total-rank-three condition it is exactly the law conditioned on and . Consequently the rank sequence of in this law is log-concave. If the final conditional probability that is already greater than , the preceding central-mass and splitting bounds give a happiness probability greater than p. Otherwise log-concavity on the support gives and , so its mode is greater than . Define
Since , a final application of [GKL24] gives the product
All factors are terminating decimals, so the first strict inequality follows by multiplying integers after clearing the powers of ten. □
The polygon, small-, large-, mixed-, and paired-bundle estimates must share one probability before their reduction events can be synchronized. The following bound supplies that common value p.
Lemma 19
(Reparameterized common-event probability). With , all six KKO–GKL happiness events have probability at least .
Proof.
For the polygon event, define . For each polygon cut S, define by the same construction as in [KKO21, except that Proposition 5.6 there is invoked with its parameters and . The unchanged polygon conditioning gives a homogeneous strongly Rayleigh law with , which is the remaining premise of that proposition. Proposition 5.6 gives the conditional event probability. Repeating the proof of [KKO21, rather than invoking its specialization , multiplies this probability by the probability that and the polygon cut is a tree. The latter probability is at least . Consequently the unconditional probability is at least
The source proposition requires . Both inequalities hold, and we also have , as required later by [KKO21. Its marginal conclusions are therefore unchanged. For the small-bundle event, the exact capacity product from [GKL24] becomes
The exponential is bounded by the following rational estimate. Since the ratios of successive terms after are at most ,
The last inequality is an integer comparison after clearing denominators, and it gives . This rational lower bound proves both capacity-product inequalities displayed in this proof. Here is the bookkeeping. In the conditional law used in that proof, , , and . The conditional-marginal estimate from [GKL24] loses at most . Therefore
and, since ,
The cut represented by V has under the conditional law. After collapsing the coordinates of V to one variable, its stable generating polynomial is therefore divisible by that variable. Dividing it out preserves stability and replaces by . Polarizing the quotient in the V-coordinate preserves stability and realizes as the rank of a disjoint block [GKL24. We apply [GKL24] to the disjoint counts with target . The required seven-row table is equivalently
The fifth row is symmetric to the displayed calculation for the sixth row. For completeness, write . The conditional-marginal calculation in [KKO21] says that conditioning can decrease any displayed union by at most and can increase it by at most . Using
and , its seven substitutions give
At and , these intervals imply, row by row, all fourteen inequalities in the table; in particular the last upper deviation from four is smaller than . Thus every nonempty subset required by the corollary has distance from the relevant integer boundary at least , , or according to its cardinality. Also , so the conditioning event still has probability at least . Thus [GKL24, with
gives the displayed product.
For the large-bundle event, the exact product from [GKL24] becomes
Indeed, , and conditioning on the two endpoint trees, , and one edge of loses at most . Hence the conditioning event has probability at least
Keeping the same losses in the two upper expectation inequalities used in the source gives
The complete table in this case is
The fifth row is symmetric to the displayed sixth-row calculation. To check the other rows without importing , use the conditional-marginal intervals in [KKO21. With , their endpoints are bounded by
Substitution of and proves each of the fourteen inequalities in the large-bundle table, including the two small-slack pairs and the triple. Hence all subset hypotheses of the capacity corollary hold. Thus [GKL24, with , gives . Since these bounds are monotone in d, substituting proves the second displayed product. Thus neither calculation invokes the published shortcut . The exact margins over p are respectively greater than and .
For the mixed-bundle event, Lemma 17 supplies the premise of Lemma 18: after orienting from v to u, its residual set V is the set U used there, and . Its resulting bound is greater than p. The two-sided mixed event in [GKL24] retains the bound : the changed expectation intervals satisfy
and the endpoint-selection probability is bounded directly by
It remains to replace the central lower-tail step in the proof of [GKL24. Write in the conditional law of that proof. If , the first branch of the source proof gives , which already implies the desired happiness bound. We may therefore assume . The four expectation intervals above and the log-concavity argument in the source proof then give .
The published proof next used , which is not positive for . Lemma 13 gives instead
Here . If , log-concavity would imply
a contradiction. Therefore
The conditional-splitting argument in the final paragraph of [GKL24, which uses only the four displayed expectation intervals and the strongly-Rayleigh property, then gives
Combining this with the endpoint choice and the outer conditioning event gives
Thus the two-sided mixed event is reparameterized without the shortcut . The sixth event is the paired event in Lemma 21; its proof uses Lemma 18 with . Thus all six events are above p. The remaining printed numerical premise of [KKO21] also holds, since . □
4.9. Marginal Shifts and Paired-Bundle Probabilities
Conditioning on threshold-dependent bundle events changes the relevant marginals. We first bound this change for a nearly deterministic rank set, which is the input needed for the paired-bundle calculation.
Lemma 20
(Monotone marginal-shift bound). Let be a strongly Rayleigh law on E, let , and let be the law obtained by conditioning on . Let , let , and suppose and
Then
If instead almost surely under and is the law obtained by conditioning on , the reversed inequality satisfies
For the zero conditioning, the same upper bound remains valid when and ; in this extension no lower sign is asserted for the change of .
Proof.
By [KKO21, every coordinate outside F has nonnegative marginal change under the downward conditioning. In particular, every coordinate in also has nonnegative marginal change. Consequently, the change on D is bounded by the change on the containing set L, and hence
Lemma 12, with central value j, bounds the right side by
which is the first assertion. The upward-conditioning part of [KKO21] reverses all marginal changes and gives the second. For the stated extension, is disjoint from F, so its marginal can only increase. Hence the change of is at most the change of , and the same central-rank estimate applies. The two conditionings used here preserve real stability. The event is deletion. For , write the generating polynomial as according to its degree in the variables indexed by F. Positive rescaling preserves stability, and as . Closure of real stability under locally uniform limits shows that , the full generating polynomial of the conditioned law, is stable. It remains homogeneous because the original law is supported on spanning trees. Thus is strongly Rayleigh in both cases; no arbitrary rank truncation is used. □
The marginal-shift bound controls each change of the nearly deterministic rank variables along the paired-bundle conditioning sequence. It yields the joint 2–2–2 probability estimate needed for the sixth common event.
Lemma 21
(Reparameterized paired-bundle estimate). In the setting of [KKO21, take and use p as the definition of a good 2–1–1 event. If the two bundles are not 2–1–1 good, then their joint 2–2–2 happiness event has probability greater than p.
Proof.
Orient from v to u, so the residual set V in Lemma 18 is the present set U. By that lemma, non-goodness implies
Thus each of the two central-rank identities in [KKO21] fails with probability at most .
We next make explicit the dichotomy that precedes Eq. (57) of the source. Condition on being trees, an event of probability at least , and define . By [KKO21, each tree conditioning factorizes the law into -uniform spanning-tree laws and therefore preserves the strongly Rayleigh property. Then . Applying the log-concavity calculation in [KKO21] to the two central identities gives
Since , either or . We treat both alternatives.
Suppose first that . Use the source conditioning order
and call the full event . Define
Because on , the counts of agree with those of throughout this branch, while are pairwise disjoint. Define
The union bound proving [KKO21] gives the first factor, and the last factor follows from ; all preceding zero conditionings only increase this marginal. Let
Before and after conditioning , each of and has central value two except on a set of conditional probability at most . Lemma 20 with bounds the increase of by
The same upper bound applies to any increase of by the extension in that lemma, because . Likewise the final exact-one conditioning on decreases the marginal by at most
All laws here are strongly Rayleigh: the zero conditions are deletions and, after the endpoint atoms are trees, , so the last condition is exact coefficient extraction.
For completeness, bound the two residual marginals without the old shortcut. The half-bundle and degree-partition bounds, the endpoint-tree loss, and the successive marginal shifts above give
Here is the possible increase caused by deleting Z, and is the loss caused by deleting the overlap . Thus , while both residual marginals are smaller than .
Write , , , and . Condition only on , and denote the resulting law by . This is a deletion and therefore preserves the strongly Rayleigh property. Markov’s inequality gives
Under , each of differs from two with probability at most . Lemma 12, negative association, and [GKL24] now give
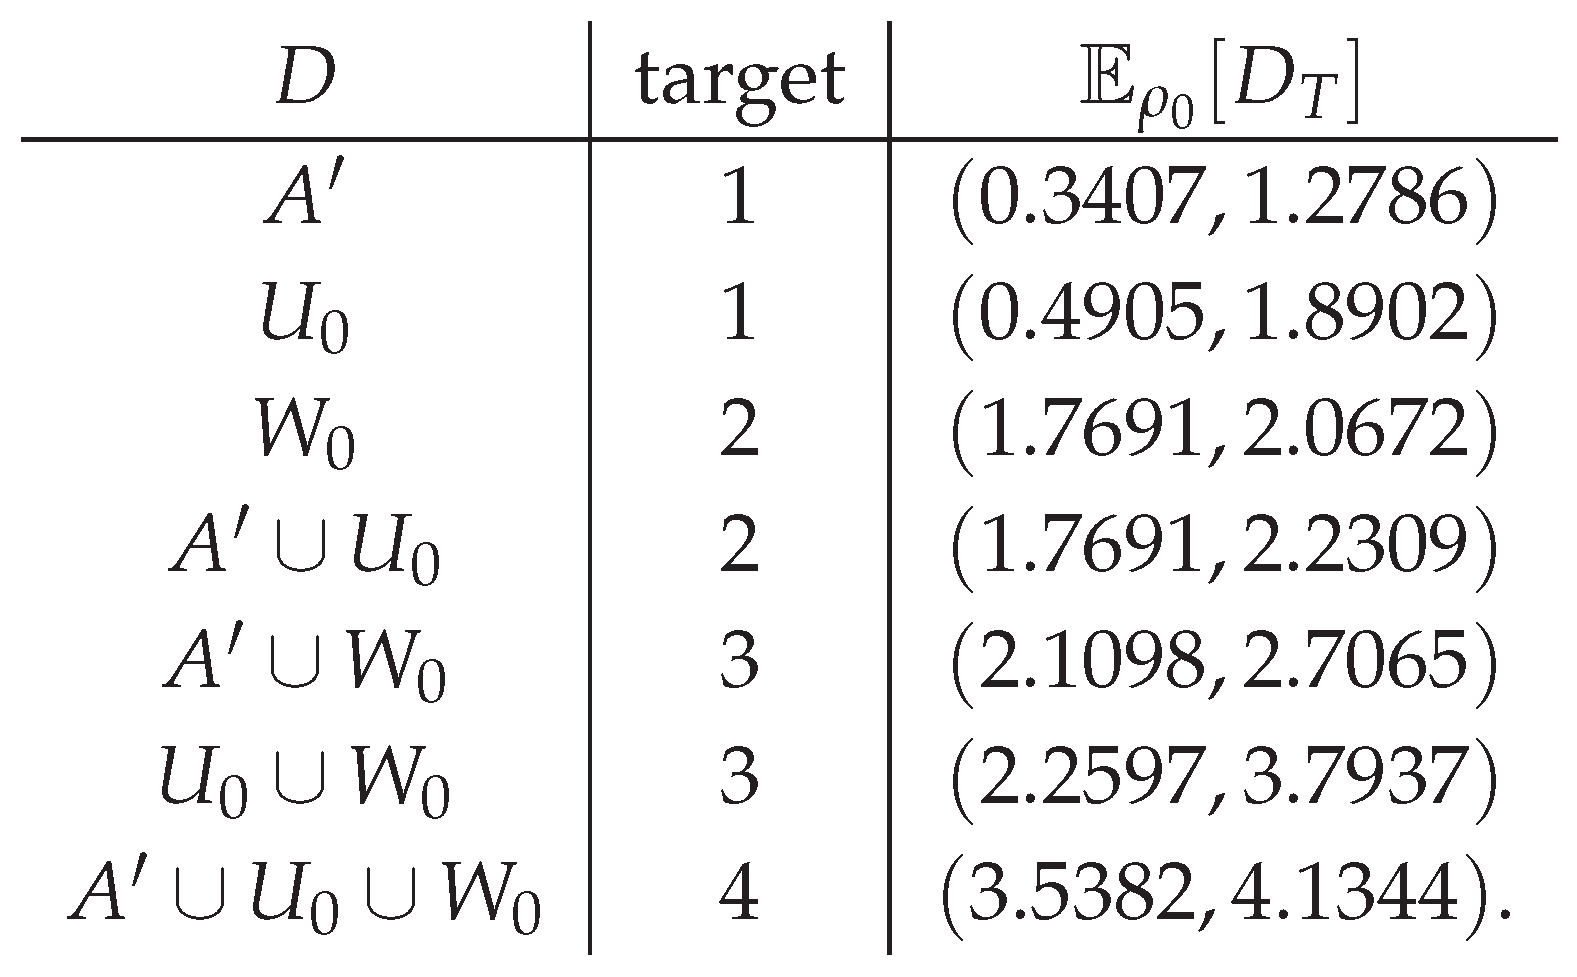
For example, before deleting , both central ranks have mean at most , and [GKL24] yields
The other aggregate rows follow in the same way. Every nonempty subset mean is within one of the corresponding subset sum of the target , and all three capacity parameters in [GKL24] exceed . Since , the unconditional probability of the target is greater than
It remains to treat . Condition first on and define and . The two high-probability central identities now have central value one:
Before conditioning on , failure of the first of these statements is contained in the union of a central-identity failure and ; after the conditioning only the former remains. Thus the two failure bounds are
Here Z is disjoint from , and , so it is also disjoint from every containing set L and residual set D used in Lemma 20 below. The exact-one part of Lemma 20, with , shows that conditioning on decreases the marginal by at most
After , impose and then ; call the full event . Each of the three zero sets is disjoint from Z, so negative association with the exact-one selection from Z decreases their marginals. Before selecting Z, their sum under the endpoint-tree law is at most . A union bound therefore gives
Consequently
Furthermore
because the unconditional endpoint-tree marginal is at least and the discarded event has probability at most ; the intervening zero conditions only increase it. Hence
Define
Since the central value is now one, conditioning increases by at most
and the extension in Lemma 20 gives the same upper bound for any increase of , because again the whole intersection with is . The final exact-one conditioning decreases by at most
The selected Z can only decrease the upper marginals. The same explicit bookkeeping as above, now without the deletion loss, gives
The lower estimate must also account for deleting and for the exact-one selection from Z. Consequently
Thus , while both residual marginals are smaller than . Let , , , and . Condition on and call the resulting law . This deletion preserves the strongly Rayleigh property, and
The same calculation as above, now with central value one, gives
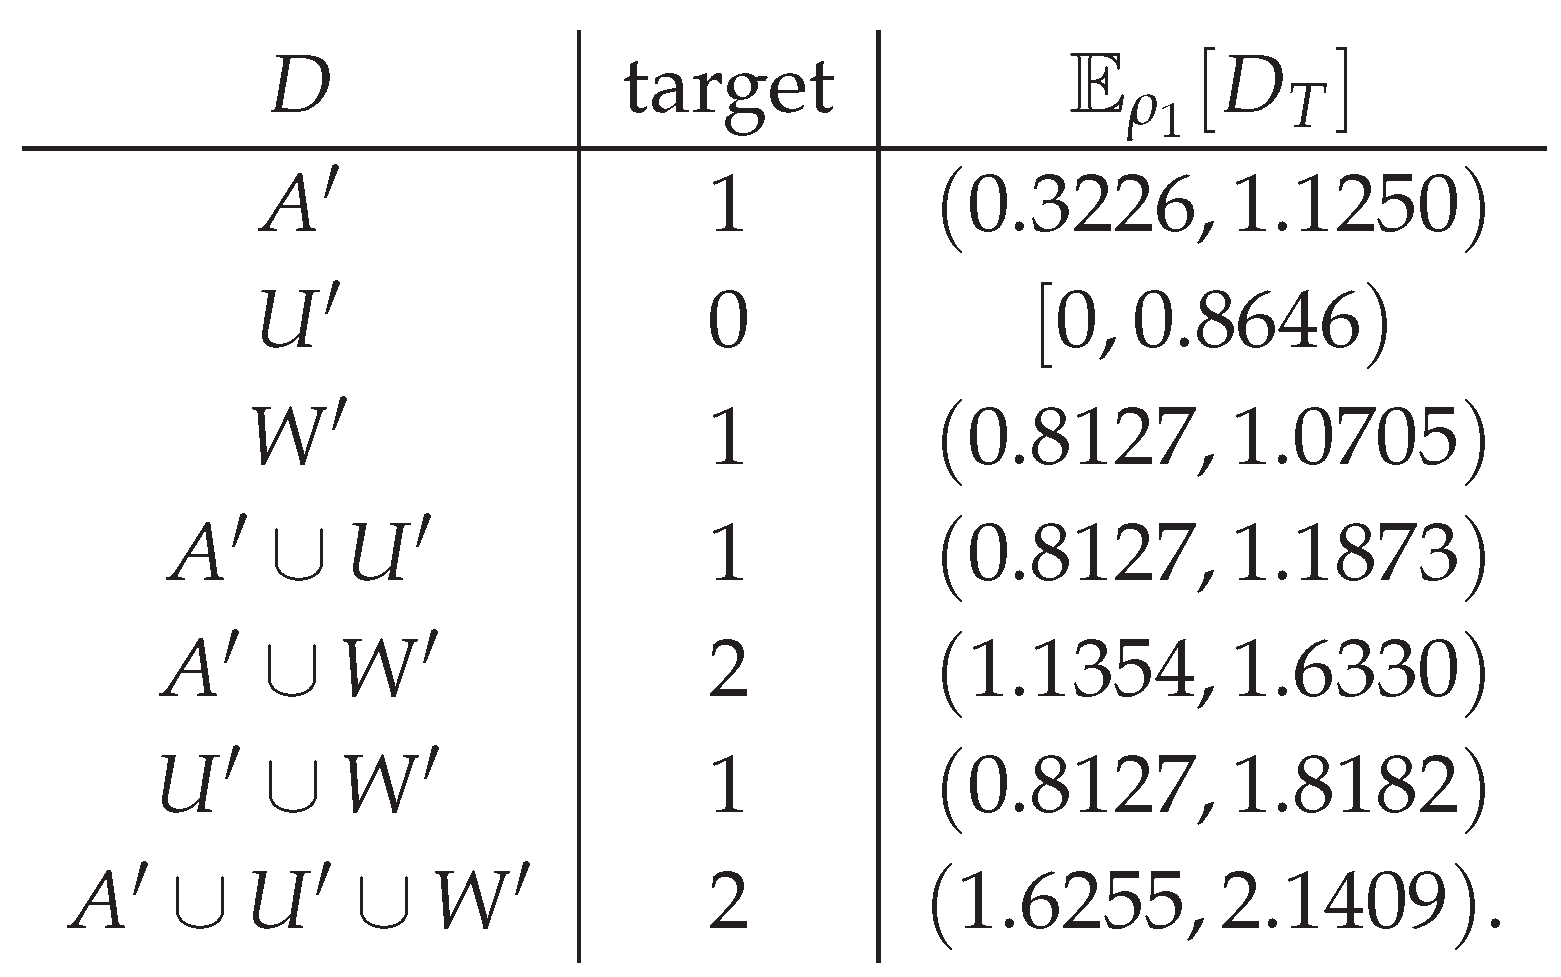
Every subset mean is within one of its target sum, and all three parameters in [GKL24] are greater than . Since the target is , that corollary and give the unconditional bound
In this branch , so the target gives and ; in the first branch these identities hold directly. Together with the fixed endpoint choices, the three boundary degrees are two in both branches.
All conditioning used in the coefficient step is extremal. The event is deletion. In the high-Z branch, , so coefficient extraction gives the stable polynomial of the event . We then project the selected Z-coordinates by setting their variables to one; projection preserves stability and gives the strongly Rayleigh law on the residual coordinates. No non-extremal exact-rank conditioning is used. The bounds and follow from the finite Taylor estimate used earlier for . Both alternatives prove the lemma. □
The common-event and paired-bundle estimates give the following explicit replacement for the structural classification at the refined parameters.
Lemma 22
(Reparameterized structural trichotomy). Let v be a non-root hierarchy atom with parent S, let be the degree partition of , and suppose . At least one of the following holds:
- (a)
- the x-mass of bad top edges in is at least ;
- (b)
- the x-mass of top edges in that are 2–1–1 good with respect to v is at least ;
- (c)
- there are two top half bundles in such that , , and their joint 2–2–2 happiness event has probability at least p.
Proof.
The small- and large-bundle estimates in Lemma 19 make every non-half top bundle 2–1–1 good. Inspecting the proof of [KKO21, its only probabilistic inputs are the four individual happiness bounds supplied by the same lemma; the rest of its argument only partitions incident bundle mass. Its conclusion, including the threshold , is therefore unchanged.
We now repeat the proof of [KKO21. If the first alternative fails, there is no bad half bundle, because every half bundle has mass at least . If there is at most one half bundle, all remaining mass is non-half; since , that mass is at least , and the second alternative follows. Otherwise choose two good half bundles . If either is 2–1–1 good, its mass alone proves the second alternative. If neither is, the two-sided mixed-bundle estimate included in Lemma 19 implies that each bundle has at least one of its A- and B-masses at most h, while Lemmas 17 and 18 rule out the two small masses lying in the same degree part. After exchanging or if necessary, this leaves . Lemma 21 then gives the third alternative. These are exactly the uses of [KKO21] in the source proof; after their replacement, no step uses the old inequality . □
4.10. Payment Estimates
The preceding lemma supplies the paired event without any non-extremal rank conditioning. We next derive the downstream payment estimates.
Definition 3
(Refined payment parameters).
Also define , , , , and .
These constants balance the parity burden from bottom edges against the savings supplied by good top edges. The following estimate verifies this balance uniformly at every hierarchy atom.
Lemma 23
(Reparameterized ancestor estimate). Let and be the parameters defined in Definition 2. Let and be the parameters defined in Definition 3. Fix a KKO hierarchy with error and , and define . Use the synchronized reduction events with probability p and the matching from Lemma 16. For a hierarchy atom u, define and partition its upward edges into good top, bad top, and bottom sets . Define and as in the proof of Lemma 5, using the present reduction events, and define . For , , where when U is -fractional and otherwise.
Proof.
We replay the proof of [KKO21, Lemma 7.3] rather than invoke the old-parameter statement. The event defined in the proof of Lemma 19 and the corresponding replay of [KKO21, Corollary 5.9(iii)], followed by [KKO21, Corollary 2.17], give, for every bottom edge,
The last strict inequality follows because the degree-eighteen Taylor lower bound for the exponential satisfies
All quantities here are rational, so this is an integer comparison after clearing the positive denominators. Define . Direct subtraction shows that it is enough to prove
Suppose first that . If , Eq. (16) follows from
Otherwise use the levels from [KKO21, proof of Lemma 7.3], now defined by the thresholds , , and . They still satisfy . In the first subcase, [KKO21, Lemma 5.25] and [KKO21, Claim 7.4]] reduce the required saving to
When the level-j mass is below , the retained top mass is greater than ; applying [KKO21, Claim 7.5] with parameter r gives
In the second main case the same claim applies to retained mass greater than , and
These are exactly the three non-bottom alternatives in the source proof.
If , then ; write the upward mass as for bad top, good top, and bottom mass, and let . Fix a good top edge and one endpoint event , where . The conditioning-and-factorization argument leading to Eq. (10) is parameter-free: Lemma 4 makes the thinning coin independent of the tree, [KKO21, Fact 2.8] factors the internal tree from the contracted tree after the endpoint is made a tree, and the preceding factorization together with [KKO21, Lemma 2.23] gives
Because , [KKO21, uniformly over the conditioned boundary count, therefore gives
Averaging this bound over the two endpoint events gives . Thus its saving coefficient is at least . The three corresponding saving coefficients in the left side of Eq. (16) are at least 1, , and c, respectively. Since c is the smallest of these coefficients, the available saving is at least . This proves the desired inequality because
Finally suppose . Condition on the parent of u and apply [KKO21, Claim 7.5] with its actual parameter U. The factorization argument in the proof of Lemma 5 is parameter-free and shows that a good top edge supplies saving at least . A bad top edge supplies one unit, and a bottom edge supplies c. Since
every unit of upward mass supplies the right side of Eq. (16). This completes the new-parameter proof. □
The ancestor bound controls the parameter-sensitive endpoint burden in the payment construction. Together with matching feasibility and the synchronized event probability, it yields the edgewise decrease and deterministic cut guarantees used by the slack-vector construction.
Lemma 24
(Reparameterized payment theorem). Let and be the parameters defined in Definition 2. Let and be the parameters defined in Definition 3. Use the common-event probability from Lemma 19 and the matching from Lemma 16. For every hierarchy error and every , define . The payment construction from Lemma 3 has coefficient
There is a coefficient satisfying
More precisely, the construction produces a partition and a payment vector satisfying the following:
- (a)
- every bottom edge is in ;
- (b)
- on and on ;
- (c)
- on , while every bottom edge satisfies ;
- (d)
- the deterministic cut inequalities in Lemma 8 hold.
Proof.
Use the synchronized thinning from Lemma 4, now with the common probability in Lemma 19, and use the matching from Lemma 16. The structural case division and the pointwise lower bound on each payment coordinate are unchanged, giving Items a, b, and d. We verify every affected expectation inequality below.
No old-parameter ancestor statement is invoked here: Lemma 23 establishes the required invariant for the present values of r and . The small-endpoint part of [KKO21, Lemma 7.6] is replaced by the normal and three-atom endpoint calculations below. The bottom-edge lemmas [KKO21, Lemmas 7.8, 7.9, and 7.11] use only the synchronized event probability, the structural alternatives from Lemma 22, and the displayed bounds on ; their three normalized increases are recomputed below. Thus the published assumption is not imported through an unchanged parameter-dependent lemma. The remaining source side conditions also hold: , , , , , and . We also repeat the proof of [KKO21, Corollary 5.11] at the present value of . The replayed [KKO21, Corollary 5.9(iii)] gives with . For , one has for ; since bounds , it follows that . The replayed [KKO21, Corollary 5.9(ii)] also gives . Therefore
and the same argument applies on the right. Hence the conditional polygon estimates and the trivial upward-edge bounds used in [KKO21, Lemmas 7.8, 7.9, and 7.11] apply with the present parameters.
Here is the complete dependency ledger for the replay. It also explains why there is no additional hidden use of the old ratio .
- (i)
- The reduction formulas and the coordinate lower bound in [KKO21, Section 7 and proof of Theorem 4.33] are pointwise algebraic. Their only probabilistic input is that every reduction event has the same probability; this is provided by Lemmas 19 and 4.
- (ii)
- The max-flow capacity inequality and conservation identity formerly supplied by [KKO21, Lemma 6.2] are replaced, for the new endpoint threshold and , by Lemma 16.
- (iii)
- The ancestor burden in [KKO21, Lemma 7.3], including the adaptive use of its Claim 7.5, is replaced by Lemma 23. Hence neither its old good-edge threshold nor its old is reused.
- (iv)
- For a top edge with an endpoint below , the four-or-more-atom case uses only the unchanged factor . The remaining three-atom case is the explicit triangle calculation below, so the parameter-dependent part of [KKO21, Lemma 7.6] is not invoked.
- (v)
- The three bottom-edge configurations of [KKO21, Lemmas 7.8, 7.9, and 7.11] use, respectively, the synchronized paired event and its saved mass, the boundary-polygon estimate, and the interior-polygon estimate. Their complete normalized burdens are the quantities computed below.
- (vi)
- The matching combination in [KKO21, Eq. (39)] and the cut inequalities in Lemma 8 use only the preceding conservation, coordinate, and support statements and contain no numerical relation between r and h.
Define .
The normal top-edge coefficient is
For the ultra-small triangle, use the notation from the proof of Lemma 6. The present matching has , rather than . Conservation at the two large endpoints and matching capacity give the required estimate because all three triangle bundles are good in the three-atom case. Indeed, and , so the matching notation has and . Therefore
The triangle identities give , , , and . Consequently,
Define
Then . The crude burden at the small endpoint and Lemma 23 at the large endpoint now give the normalized decrease
This is a fixed- rederivation of the two endpoint configurations in the proof of Lemma 6; no old numerical conclusion is invoked, and the triangle case is not discarded. Multiplying either normalized decrease by the reduction amount gives at least , which proves the top-edge part of Item c for both the ordinary and three-atom cases.
Finally, replay the exact degree-parent Case 3 calculation from [KKO21, Lemma 7.8]. Let be the polygon partition and let be the degree partition. By [KKO21, Remark 5.20], , , and , while [KKO21, Definition 5.18 and Eq. (25)] gives . For the paired half bundles from Lemma 22, Item c, define and . Their cross bounds and the half-bundle inequalities give
The synchronized reductions make the three Case 3 events have probability p, so their exact contribution on is at most
Thus the saving relative to the trivial contribution on D is at least
For , define
In Cases 1 and 2 of [KKO21, Lemma 7.8], the saved masses are respectively and , where is the set of 2–1–1-good edges in Case 2. Both dominate : their respective excesses are and . Define the three normalized increases
The first quantity applies to a degree parent, the second to a boundary atom with polygon parent, and the third to an interior atom. Each is increasing on . Define
Direct substitution gives
Thus every normalized increase for every is at most , and
This proves Item c; the other three items were pointwise consequences of the construction. Every displayed parameter is rational. The denominators occurring above are positive; for example,
Thus each stated sign follows by clearing positive denominators and comparing the resulting integers. □
4.11. Slack-vector Construction
We convert the payment bounds into a uniform slack vector and then layer the thresholds to obtain the final improvement.
Lemma 25
(Uniform single-threshold certificate). Let h be as defined in Definition 2, and let a and be the coefficients from Lemma 24. Define
For every feasible subtour-LP solution in the standard form of Section 3.1, let x be its restriction to E, let μ be the exact max-entropy spanning-tree law with marginals x, and fix and . There is a random vector such that for every edge and, whenever S is u-near-minimum and is odd, . Moreover,
Proof.
Lemmas 14 and 15 change the degree-parent good-edge mass calculation in Lemma 11 to
The near-cycle and triangle-parent arguments still use bottom-edge support and are unchanged by Lemma 24-a. Thus every non-root one-sided cut in the KKO classification has good-edge mass at least . The root is excluded from this assertion and has even tree boundary almost surely by the final paragraph of Lemma 11.
Define and use the KKO hierarchy for threshold u. By [KKO22, Theorem 6.2 and Fact B.4], its hierarchy error is at most . We analyze it with the conservative envelope , so Lemma 24 supplies the payment vector for this hierarchy and this value of .
Use the sharpened two-sided repair coefficient 10 and retain the published one-sided coefficient 44. Lemma 10 applies to the reparameterized payment vector because the pointwise cut properties in Lemma 24-d, the bottom-edge support in a, and the coordinate lower bound in b are exactly its three payment hypotheses. Define
The combined-vector identities are
Direct rational substitution also gives
Thus all divisions and nonnegative scalings above are valid, and the final inequality is available for the coordinate estimate below. Let be the repair vectors from Lemma 10, and define
On a good edge the payment coordinate bound gives ; on a bad edge the same conclusion follows from . Thus on every edge. On a non-root one-sided cut, the added deterministic good–bad correction is nonnegative because
Lemma 10-b then supplies the remaining one-sided repair. On a two-sided cut, , while Lemma 10-a supplies . Hence all odd near-minimum cuts satisfy the deterministic cut inequality: the one- and two-sided cases cover every non-root cut, while the root is even almost surely by Lemma 11.
Moreover,
so the stronger bottom payment absorbs the complete one-sided repair. Define
On good top edges and bad edges, the support statement for and the identity give
On a bottom edge, the left side is at most , which is no larger than the preceding bound because . This last inequality holds uniformly because its left side is decreasing on and at H it is greater than . Cancelling the common factor q in gives
and hence the expected coefficient is precisely in the statement. Define and finally set . The coordinate, cut, and expectation bounds above scale to the three asserted bounds. □
We now combine the single-threshold certificates over a discretized range of near-minimum-cut thresholds. Using the same sampled tree preserves the pointwise cut guarantees while allowing the expected edgewise savings to add.
Lemma 26
(Layered slack-vector construction). Let H and κ be as defined in Lemma 25. Define and for , and define
There is a random vector such that for every edge and, for every cut with and odd,
Moreover,
Proof.
Sample one tree T from the exact max-entropy law. Conditional on this same tree, jointly realize the auxiliary constructions in Lemma 25 for all , with , and denote the resulting vectors by . Define . This common-tree coupling preserves every pointwise conclusion of the single-threshold lemma, while linearity of expectation gives the asserted edgewise expectation. The coordinate bounds telescope to .
For the cut inequality, write and let j be the largest index in for which . Every layer has and satisfies the cut guarantee, whereas the coordinate bounds on the first j layers lose at most . Since and is increasing,
It remains to bound . Define
so that . On ,
and the derivative of is . Consequently,
All parameters in this expression are rational. Clearing its positive denominators at gives
and hence . □
Acknowledgments
The author used Gemini Pro 3.1, Codex 5.6 Sol and Claude Code Fable 5 to assist with language editing and grammar checking.
References
- Applegate, David L., Robert E. Bixby, Vašek Chvátal, and William J. Cook. 2007. The Traveling Salesman Problem: A Computational Study. Princeton University Press. [Google Scholar]
- Arora, Sanjeev. 1998. Polynomial time approximation schemes for Euclidean traveling salesman and other geometric problems. Journal of the ACM 45, 5: 753–782. [Google Scholar] [CrossRef]
- Christofides, Nicos. 1976. Worst-case analysis of a new heuristic for the traveling salesman problem. Technical Report 388. Graduate School of Industrial Administration, Carnegie-Mellon University.
- Dantzig, George B., D. Ray Fulkerson, and Selmer M. Johnson. 1954. Solution of a large-scale traveling-salesman problem. Operations Research 2, 4: 393–410. [Google Scholar] [CrossRef]
- Gurvits, Leonid, Nathan Klein, and Jonathan Leake. 2024. From trees to polynomials and back again: New capacity bounds with applications to TSP. 51st International Colloquium on Automata, Languages, and Programming (ICALP 2024), Full version; volume 297: 79:1–79:20. [Google Scholar]
- Oveis Gharan, Shayan, Amin Saberi, and Mohit Singh. 2011. A randomized rounding approach to the traveling salesman problem. In Proceedings of the 52nd Annual IEEE Symposium on Foundations of Computer Science (FOCS 2011). IEEE: pp. pages 550–559. [Google Scholar]
- Held, Michael, and Richard M. Karp. 1970. The traveling-salesman problem and minimum spanning trees. Operations Research 18, 6: 1138–1162. [Google Scholar] [CrossRef]
- Karlin, Anna R., Nathan Klein, and Shayan Oveis Gharan. 2020. An improved approximation algorithm for TSP in the half integral case. Proceedings of the 52nd Annual ACM SIGACT Symposium on Theory of Computing (STOC 2020); Association for Computing Machinery, pp. pages 28–39. [Google Scholar]
- Karlin, Anna R., Nathan Klein, and Shayan Oveis Gharan. 2021. A (slightly) improved approximation algorithm for metric TSP. Proceedings of the 53rd Annual ACM SIGACT Symposium on Theory of Computing (STOC 2021), Full version; Association for Computing Machinery, pp. pages 32–45. [Google Scholar]
- Karlin, Anna R., Nathan Klein, and Shayan Oveis Gharan. 2022. A (slightly) improved bound on the integrality gap of the subtour LP for TSP. In Proceedings of the 63rd IEEE Annual Symposium on Foundations of Computer Science (FOCS 2022). Full version. IEEE: pp. pages 832–843. [Google Scholar]
- Karlin, Anna R., Nathan Klein, and Shayan Oveis Gharan. 2023. A deterministic better-than-3/2 approximation algorithm for metric TSP. In Integer Programming and Combinatorial Optimization (IPCO 2023). Springer: vol. ume 13904, pp. pages 261–274. [Google Scholar]
- Karpinski, Marek, Michael Lampis, and Richard Schmied. 2015. New inapproximability bounds for TSP. Journal of Computer and System Sciences 81, 8: 1665–1677. [Google Scholar] [CrossRef]
- Mitchell, Joseph S. B. 1999. Guillotine subdivisions approximate polygonal subdivisions: A simple polynomial-time approximation scheme for geometric TSP, k-MST, and related problems. SIAM Journal on Computing 28, 4: 1298–1309. [Google Scholar] [CrossRef]
- Mömke, Tobias, and Ola Svensson. 2011. Approximating graphic TSP by matchings. In Proceedings of the 52nd Annual IEEE Symposium on Foundations of Computer Science (FOCS 2011). IEEE: pp. pages 560–569. [Google Scholar]
- Mucha, Marcin. 2012. 13/9-approximation for graphic TSP. 29th International Symposium on Theoretical Aspects of Computer Science (STACS 2012) volume 14: pages 30–41. [Google Scholar]
- Serdyukov, Anatoliy I. 1978. O nekotorykh ekstremal’nykh obkhodakh v grafakh. Upravlyaemye Sistemy 17: 76–79. [Google Scholar]
- Sebo, András, and Jens Vygen. 2014. Shorter tours by nicer ears: 7/5-approximation for the graph-TSP, 3/2 for the path version, and 4/3 for two-edge-connected subgraphs. Combinatorica 34, 5: 597–629. [Google Scholar] [CrossRef]
- Straszak, Damian, and Nisheeth K. Vishnoi. 2019. Maximum entropy distributions: Bit complexity and stability. Proceedings of the Thirty-Second Conference on Learning Theory volume 99: pages 2861–2891. [Google Scholar]
- Schalekamp, Frans, David P. Williamson, and Anke van Zuylen. 2014. 2-matchings, the traveling salesman problem, and the subtour LP: A proof of the boyd–carr conjecture. Mathematics of Operations Research 39, 2: 403–417. [Google Scholar] [CrossRef]
- Wolsey, Laurence A. 1980. Heuristic analysis, linear programming and branch and bound. In Mathematical Programming Studies. Springer: vol. ume 13, pp. 121–134. [Google Scholar]
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (http://creativecommons.org/licenses/by/4.0/).
Copyright: This open access article is published under a Creative Commons CC BY 4.0 license, which permit the free download, distribution, and reuse, provided that the author and preprint are cited in any reuse.