
Submitted:
29 August 2026
Posted:
31 August 2026
You are already at the latest version
Abstract
Low-light remote sensing images acquired by a TDI-ICMOS system under photon-limited conditions usually exhibit severe underexposure, amplified random noise, unstable local contrast, and unnatural highlight transitions. These challenges are more difficult in our target setting because the data are real 16-bit grayscale remote sensing images without paired clean references. We propose WISE-Net, a Wavelet-guided Illumination Self-supervised Enhancement framework for low-light remote sensing images. WISE-Net follows a two-stage fully self-supervised design. In Stage 1, the input image is decomposed by Haar wavelets, and only the low-frequency component is modulated by a learned brightness-adaptive gain while the high-frequency sub-bands are preserved for structure-consistent reconstruction. A composite self-supervised objective stabilizes enhancement, protects bright regions, and reduces gain artifacts. In Stage 2, the Stage-1 enhancement network is frozen and a self-supervised blind-spot refinement network suppresses enhancement-amplified noise and local artifacts. Experiments on three real low-light remote sensing test subsets show that WISE-Net achieves the lowest NIQE on all three subsets, the lowest PIQE on test1_2048×1440 and test2_4096×1440, and the highest entropy on all three subsets.
Keywords:
low-light remote sensing
; self-supervised learning
; wavelet transform
; image enhancement
; TDI-ICMOS imaging
1. Introduction
Low-light remote sensing imaging is important in weak-signal observation, nighttime earth observation, long-range monitoring, and other photon-limited scenarios. In these settings, the captured images often suffer simultaneously from severe underexposure, low local contrast, strong stochastic noise, and unstable bright-region rendering. The images considered here are real 16-bit single-channel data acquired by a TDI-ICMOS system, whereas most existing enhancement methods target conventional 8-bit RGB photographs. Extreme low-light acquisition also introduces signal-dependent noise whose statistics differ from those of ordinary rendered images [19,25]. Consequently, a method developed for natural images may not transfer reliably to these data. Brightness amplification can strengthen noise and halo artifacts, while strong denoising can remove weak structures relevant to interpretation.
Low-light enhancement has progressed mainly on natural-image benchmarks. Retinex-based approaches improve visibility by modeling illumination and reflectance [1,2,3,5,6,30]. Supervised deep models and restoration-oriented architectures have also improved illumination recovery and detail reconstruction [4,14,15,16,17,18,19,29]. Unpaired adversarial learning removes the need for matched normal-light targets [7]; zero-reference methods such as Zero-DCE, Zero-DCE++, RUAS, SCI, SCI++, and ZERO-IG optimize enhancement without paired supervision [8,9,10,11,12,13]. The main mismatch with our setting is the combination of high-bit-depth grayscale data, dark-region recovery, bright-region protection, structural preservation, and post-enhancement noise suppression.
Clean paired references are unavailable in our target scenario, and constructing matched ground truth is impractical. This limitation has motivated unpaired enhancement and self-supervised denoising strategies [20,21,22]. A denoiser applied directly to a severely underexposed image cannot recover sufficient visibility. An unconstrained enhancer can amplify random noise. The two operations therefore need to be coordinated without clean targets.
To address this problem, we propose WISE-Net, short for Wavelet-guided Illumination Self-supervised Enhancement Network. WISE-Net is a two-stage fully self-supervised framework for real low-light remote sensing images. Stage 1 decomposes the input into Haar wavelet sub-bands and enhances only the low-frequency component through learned illumination modulation. The training objective combines dual-view consistency with constraints on relative contrast, minimum dark-region gain, bright-region protection, gain smoothness, over-exposure, and gradient exclusion. After Stage 1 is frozen, Stage 2 applies SBR to the enhanced image distribution and suppresses enhancement-amplified noise and local artifacts without clean targets.
The main contributions of this work are summarized as follows:
- 1)
- We propose WISE-Net, a two-stage fully self-supervised framework for enhancing real 16-bit grayscale low-light remote sensing images. The framework separates visibility recovery from post-enhancement refinement and requires neither clean reference images nor unpaired normal-light images.
- 2)
- We develop a wavelet-guided illumination modulation network that updates only the low-frequency Haar component through brightness-aware gain prediction, while directly reusing the original high-frequency sub-bands during reconstruction. The resulting low-frequency update improves scene visibility and limits direct amplification of high-frequency degradation.
- 3)
- We introduce self-supervised blind-spot refinement (SBR) on the Stage-1 enhanced-image distribution. By combining masked-pixel reconstruction with structural regularization, SBR suppresses enhancement-exposed noise and jitter-like blur while retaining the brightness and structural information recovered in Stage 1.
- 4)
- We establish a real 16-bit grayscale low-light remote sensing benchmark acquired with a TDI-ICMOS push-broom imaging system. It comprises a training set and three test subsets with different image widths, supporting evaluation under the training configuration and across different push-broom formats.
2. Related Works
2.1. Low-light Image Enhancement
Low-light enhancement methods can be broadly grouped into Retinex-based, supervised restoration, and zero-reference frameworks. Early Retinex-style methods improve visibility by separating illumination from reflectance and estimating an enhanced illumination field [1,2,3,5,6,30]. Supervised approaches range from autoencoder and RAW-domain enhancement to progressive, SNR-aware, and high-resolution restoration architectures [4,14,15,16,17,18,19,29]. More recent zero-reference methods include curve-estimation strategies [8,9], architecture-search-based enhancement [10], fast zero-reference enhancement [11,12], and joint enhancement-denoising schemes [13]. These methods provide strong baselines, but most were developed for RGB natural-image distributions. Our target data are real 16-bit grayscale remote sensing images with different signal statistics and greater sensitivity to over-enhancement, structural washout, and highlight instability.
2.2. Self-supervised Denoising
Self-supervised denoising avoids the need for clean ground truth and has become an attractive solution for photon-limited imaging. Noise2Noise learns restoration from paired noisy observations [21], whereas Noise2Void removes the paired-data requirement through a blind-spot masking strategy that predicts a pixel from its spatial context only [20]. Neighbor2Neighbor further constructs self-supervised noisy pairs from a single observation [22]. SN2N exploits spatial redundancy in super-resolution microscopy to construct self-supervised training pairs through diagonal resampling and interpolation [34]. We use this construction only to generate the two training views in Stage 1; the illumination model and the subsequent refinement stage are specific to WISE-Net.
2.3. Motivation for WISE-Net
For low-light remote sensing images, direct enhancement and direct denoising face opposite limitations: enhancement restores visibility but amplifies noise, whereas denoising suppresses fluctuations but cannot recover missing brightness. This motivates a staged solution. WISE-Net first recovers scene visibility through wavelet-guided low-frequency illumination modulation while keeping the high-frequency sub-bands unchanged. SBR is then applied to the enhanced image to suppress amplified noise.
3. Proposed Method
The overall architecture of WISE-Net is illustrated in Figure 1. Given a noisy low-light remote sensing image , WISE-Net performs wavelet-guided illumination modulation in Stage 1 and enhancement-oriented self-supervised refinement in Stage 2. The central idea is to separate the recovery of visibility from the suppression of enhancement-amplified noise. Stage 1 establishes a stable brightness-lifted representation in the wavelet domain, and Stage 2 operates on this enhanced distribution to suppress residual noise and local artifacts while preserving the recovered visibility.
The overall pipeline is written as
where denotes the Stage-1 wavelet-guided illumination modulation network and denotes the Stage-2 SBR network. Both stages are trained without clean reference images.
3.1. Stage 1: Wavelet-guided Illumination Modulation
3.1.1. Haar Wavelet Decomposition
To decouple illumination recovery from structure preservation, we decompose the input image using a single-level Haar discrete wavelet transform [24]:
where the low-frequency approximation captures large-scale brightness information and the three high-frequency sub-bands contain edges, textures, and high-frequency noise. In WISE-Net, only is enhanced, while , , and are directly preserved for reconstruction. Restricting enhancement to limits direct amplification of high-frequency noise and preserves structural fidelity.
3.1.2. Low-frequency Illumination Modulation Network
The Stage-1 illumination module is illustrated in Figure 1(a).
The Stage-1 network takes as input and predicts an enhanced low-frequency component together with a spatially varying gain map G. It uses an encoder–bottleneck–decoder built from multi-scale dilated depthwise convolutions and channel-mixing blocks. A lightweight prediction head maps the decoded features to a base gain map .
For low-light remote sensing images, the learned base gain is combined with a brightness-aware modulation term. This assigns stronger enhancement to darker regions:
where p controls the sensitivity to input brightness and limits the admissible gain. Both are fixed throughout training. The enhanced low-frequency component is then obtained by
The brightness-aware gain gives darker regions stronger lifting while limiting unnecessary amplification in already bright regions.
3.1.3. Wavelet Reconstruction
After low-frequency enhancement, the final Stage-1 output is reconstructed by inverse Haar wavelet transform:
Because the original high-frequency sub-bands are directly reused, Stage 1 is guided toward visibility enhancement while retaining the input high-frequency structure. This separates the illumination update from edge regeneration used in plain pixel-domain enhancement.
3.1.4. Self-supervised Dual-View Construction for Stage 1
Stage 1 is trained without clean targets. To provide self-supervised guidance, we construct two content-consistent noisy views from a single raw image through diagonal resampling. For each pixel unit, the top-left and bottom-right pixels are averaged to form one view, while the top-right and bottom-left pixels are averaged to form the other. The resulting two views share nearly identical scene content but retain different noise samples. In the implementation, bilinear interpolation restores both views to the training-patch size; they are denoted by and .
This dual-view construction is inspired by spatially redundant self-supervised denoising, but in WISE-Net it serves as the data-generation mechanism for Stage-1 optimization. The enhancement framework is built on top of these views; the resampling operation itself is not treated as the main contribution.
3.2. Stage 1 Loss Functions
Stage 1 is optimized by combining dual-view self-supervision with enhancement-oriented regularization. The total loss is defined as
where is the dual-view self-supervised consistency term and is the enhancement regularization term. The coefficients and balance self-supervised consistency and illumination regularization.
Dual-view self-supervised consistency. During Stage 1 training, both views are passed through the Stage-1 enhancement network and the auxiliary denoising branch used in the training environment. We enforce consistency between the two final outputs by
The two observations provide a self-supervised signal because they share scene content but contain different noise realizations.
Enhancement regularization. To make Stage 1 produce stable and visually plausible enhancement, we define
The weights , , , , , and balance the six complementary constraints and are kept fixed in all experiments.
The six terms play the following roles:
Relative-contrast preservation maintains local brightness relationships after enhancement.
where is a soft dark-region mask, denotes the required minimum relative gain, and k controls mask softness. The penalty discourages insufficient low-frequency gain without imposing an absolute target intensity.
where is a soft mask for already visible regions. Bright-region protection suppresses unnecessary gain departures from unity in these regions.
Gain-map smoothness suppresses abrupt spatial changes that would otherwise introduce artifacts.
Here denotes a fixed saturation threshold. The over-exposure penalty discourages saturation in both the reconstructed image and the enhanced low-frequency component.
Following the exclusion principle used in unsupervised night enhancement [35], the exclusion loss discourages coincident gradients in and G, reducing gain transitions that track strong luminance edges.
3.3. Stage 2: Enhancement-oriented Self-Supervised Refinement
3.3.1. Architecture Overview
As shown in Figure 1(b), the trained Stage-1 illumination modulation network is frozen and used as a deterministic front-end in Stage 2. The Stage-2 network refines the Stage-1 enhanced image by suppressing enhancement-amplified noise and local artifacts while preserving the visibility established in Stage 1. We refer to this component as self-supervised blind-spot refinement (SBR). During training, the network receives a masked enhanced image ; during inference, it receives the complete Stage-1 output .
3.3.2. SBR Network
The SBR network follows a U-Net-style encoder–decoder architecture with residual prediction [23]. Its encoder aggregates contextual features at progressively coarser scales, while the decoder combines bilinear upsampling with skip connections to recover spatial detail. During training, the network predicts a residual from the masked enhanced image and forms the training prediction
During inference, masking is disabled and the complete Stage-1 output is refined directly:
The same SBR network parameters are used in the training and inference paths.
3.3.3. Blind-spot Masking Strategy
During training, WISE-Net adopts a blind-spot masking strategy. A random mask is generated, and each masked pixel is replaced by a randomly selected neighboring pixel, excluding the pixel itself. The masked enhanced image is then fed to the SBR network, and the loss is computed only on the masked positions. In this way, the network cannot trivially copy the input value of each supervised pixel and must instead infer it from surrounding context. During inference, no masking is applied and the full enhanced image is refined directly.
3.3.4. Stage 2 Loss Function
The Stage-2 objective is
where and balance masked-pixel reconstruction and structural preservation and are kept fixed in all experiments.
The blind-spot reconstruction term compares the training prediction with the Enhanced target and is defined as
where M is the blind-spot mask.
To limit over-smoothing, let denote the Sobel gradient magnitude and let select locations where exceeds its spatial mean. The edge term is
Using the Laplacian operator , the retained high-frequency ratio is
The structural regularizer used in the implementation is
Here, and balance the two structural terms, and specifies the minimum retained high-frequency ratio. These parameters are fixed in all experiments.
| Algorithm 1: Training and inference procedure of WISE-Net. |
|
Input: Low-light grayscale image I. Stage 1 training: 1: Decompose I into Haar wavelet sub-bands. 2: Predict the brightness-aware gain map G from the low-frequency component. 3: Modulate the low-frequency component with G and reconstruct . 4: Optimize the Stage-1 network using the dual-view self-supervised objective and enhancement regularization. Stage 2 training: 5: Freeze the trained Stage-1 network and generate . 6: Randomly mask pixels in and replace them with neighboring pixels to obtain . 7: Feed to the SBR network and predict the residual . 8: Form and optimize the SBR objective on the masked positions. Inference: 9: Feed the complete Stage-1 output to the trained SBR network without masking. 10: Predict and output . |
3.4. Training Strategy
WISE-Net is trained sequentially in two stages.
Stage 1. Two diagonally resampled noisy views are generated online from each raw training image. The Stage-1 illumination modulation network is trained for 50 epochs using patches and batch size 32. In implementation, the training-time cascade includes an auxiliary denoising branch and dual-view consistency supervision. At deployment, Stage 1 supplies the enhanced image to Stage 2.
Stage 2. The Stage-1 enhancement network is frozen, and only the SBR network is trained for 50 epochs on the enhanced image distribution using batch size 64. Freezing Stage 1 separates visibility recovery from refinement and exposes Stage 2 to the same enhanced-image statistics used at inference.
The two stages are optimized separately. Stage 1 uses Adam and Stage 2 uses AdamW; both are initialized with a learning rate of and follow cosine annealing.
4. Experiments
This section evaluates WISE-Net on real low-light remote sensing images captured by the target TDI-ICMOS imaging system. It describes the dataset and evaluation protocol, reports comparisons with representative unsupervised low-light enhancement baselines, and examines the selected components of the two-stage design.
4.1. Dataset and Settings
The data used in this study were acquired under ground-based conditions using a long-range push-broom imaging configuration of a newly developed TDI-ICMOS spaceborne remote sensing camera. The push-broom imaging mode, TDI integration mechanism, and imaging chain were consistent with those used in its remote sensing application, allowing the collected data to represent the characteristic image properties of this camera under low-light push-broom acquisition. All data used in this work were acquired by a TDI-ICMOS scientific camera with line-scanning push-broom imaging and an image-intensifier-coupled imaging chain. The current experiments used ground-to-ground long-range acquisition because air-to-ground collection was unavailable. The push-broom integration and low-light TDI-ICMOS imaging mechanism remained the same as in the target remote sensing setting. Specifically, 1500 real 16-bit single-channel grayscale images at 2048×1440 were collected under the same imaging configuration, of which 1460 images were used for training and the remaining 40 images formed the test1_2048×1440 subset. Two generalization test subsets with different push-broom image widths were also acquired using the same camera system: test2_4096×1440 contains 107 images, and test3_1536×1440 contains 93 images.
Figure 2.
TDI-ICMOS imaging device used to acquire the real low-light grayscale remote sensing data.
Figure 2.
TDI-ICMOS imaging device used to acquire the real low-light grayscale remote sensing data.
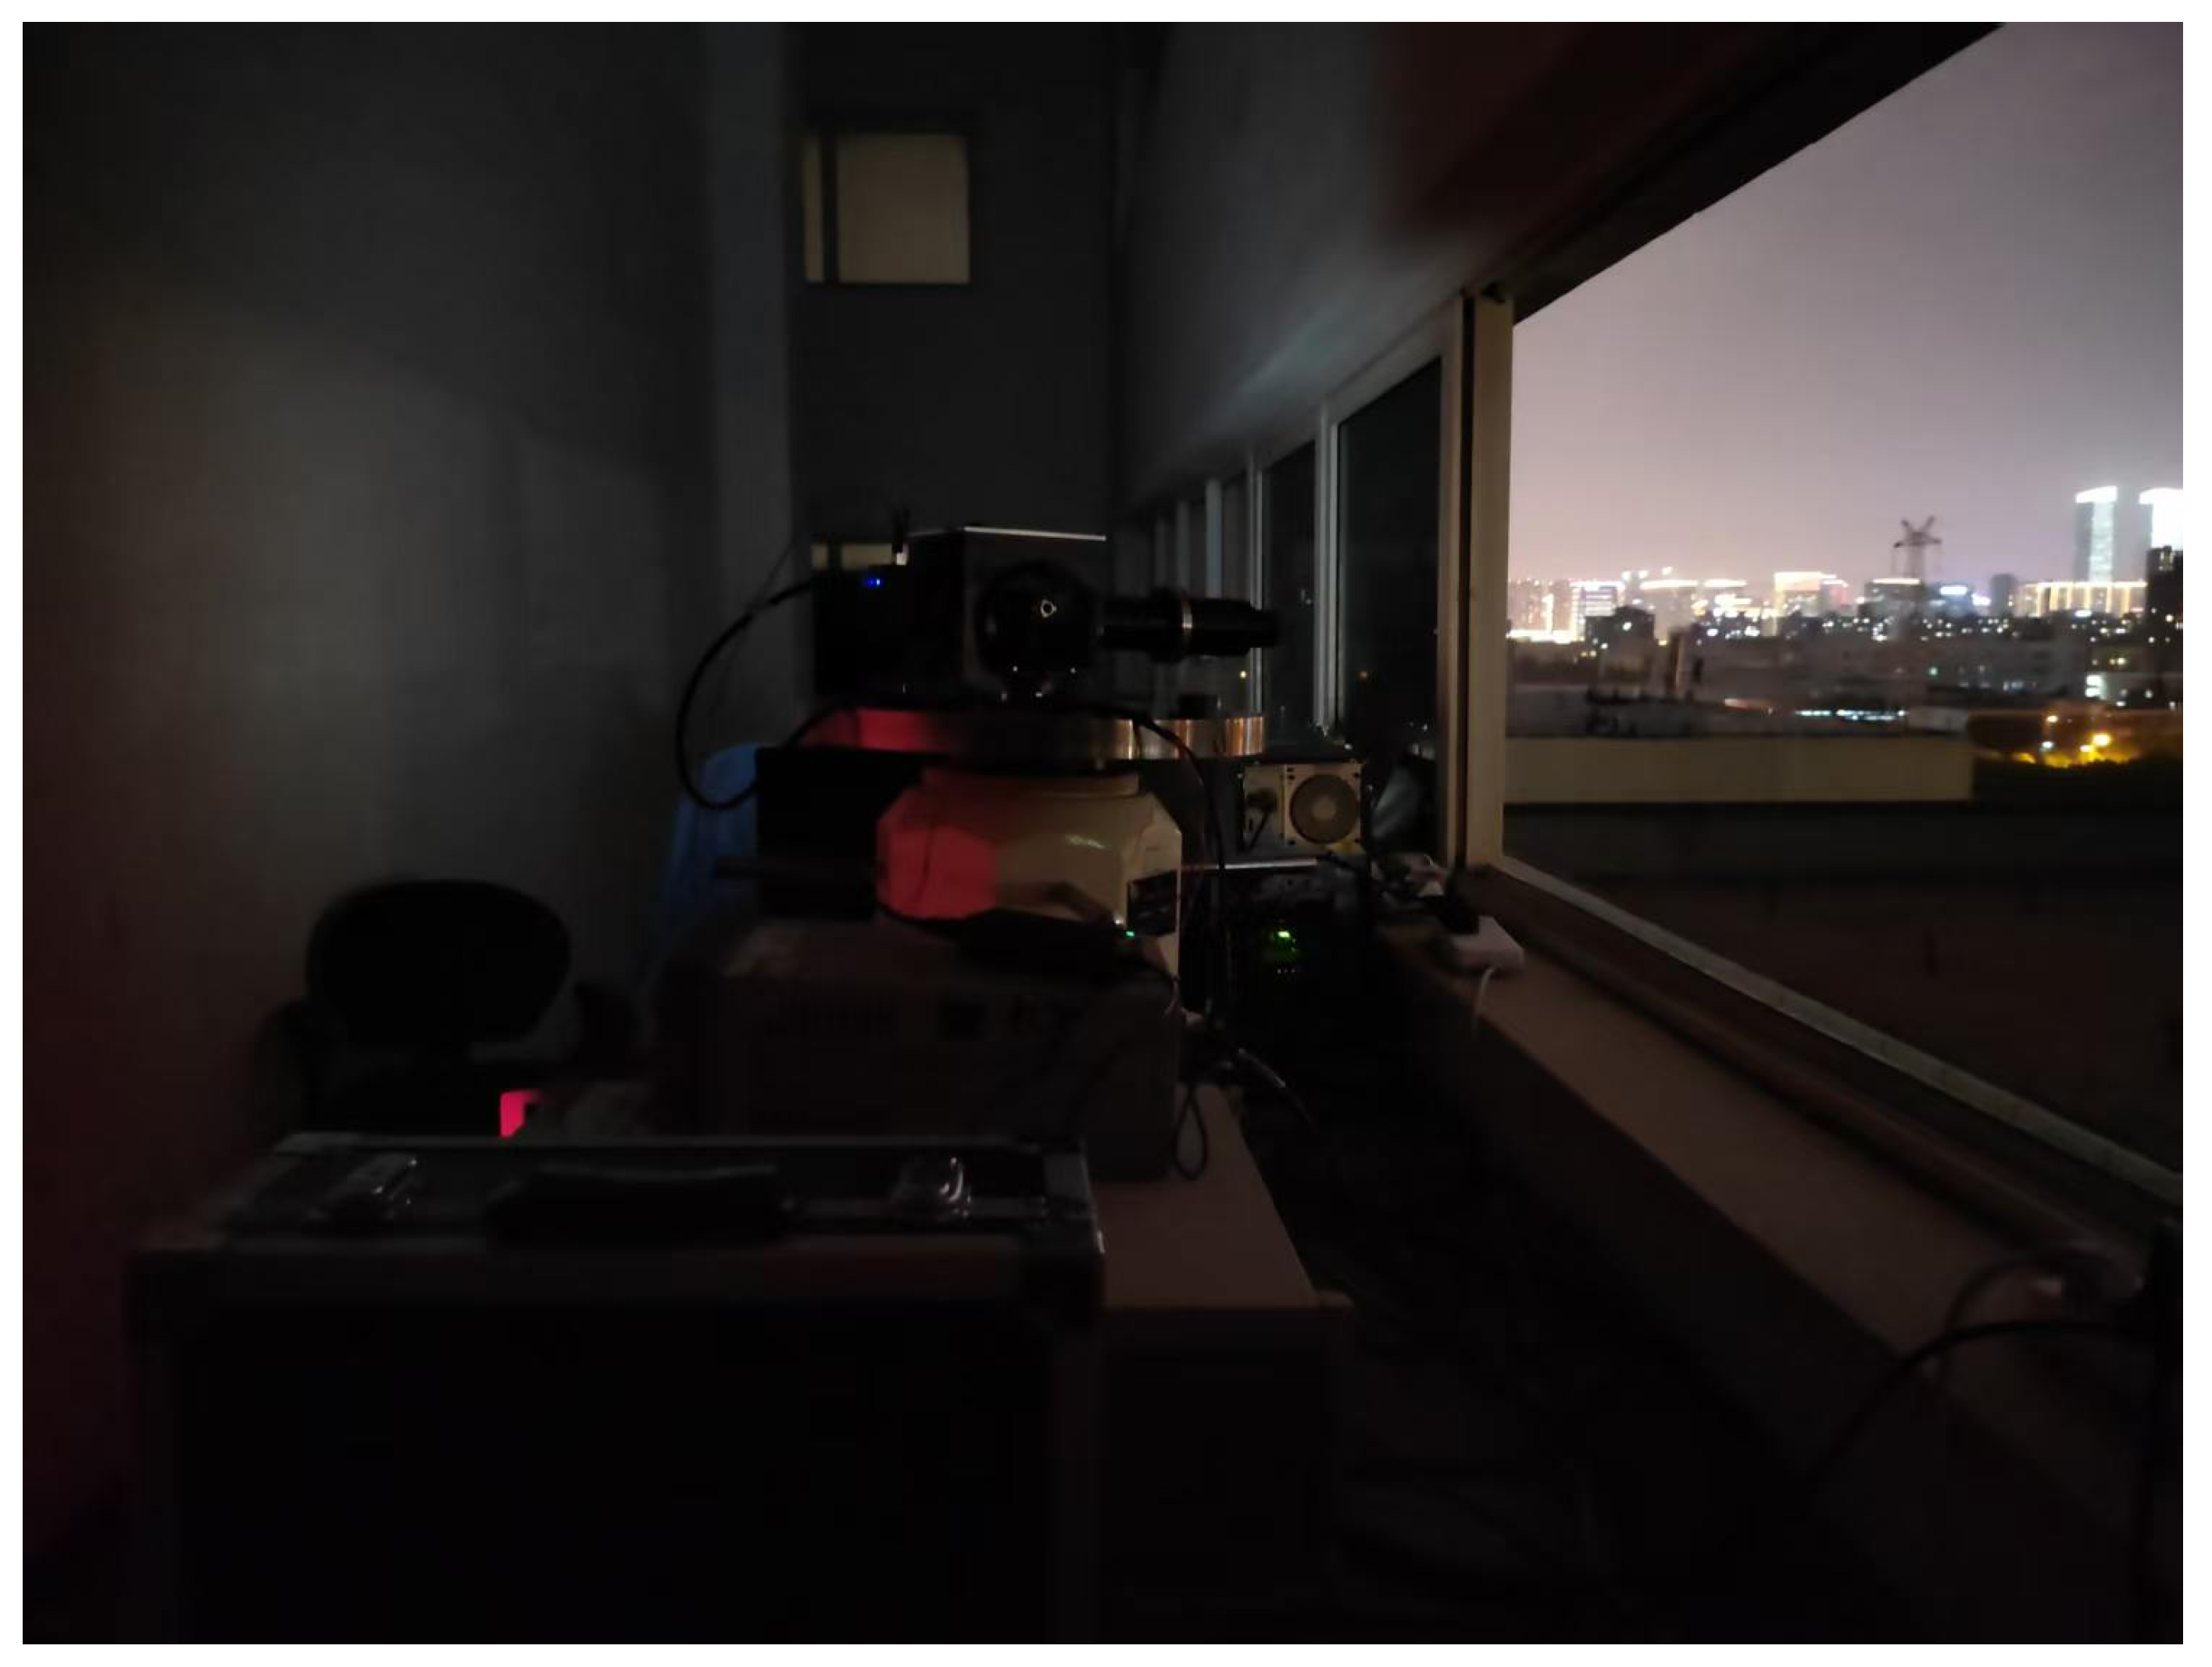
The source data were decoded and retained as 16-bit grayscale images, without prior 8-bit quantization; normalized floating-point values were used for network computation. WISE-Net is optimized sequentially: Stage 1 learns illumination modulation from image patches, after which it is frozen while Stage 2 learns SBR on the enhanced distribution. The proposed method and all compared baselines were implemented on the same computer using PyTorch and an NVIDIA GPU. The dataset composition is summarized in Table 1.
4.2. Quantitative and Qualitative Comparisons
The quantitative and qualitative results are organized by test subset so that each metric table can be read together with its corresponding visual comparison. Bold and underlined entries denote the best and second-best values, respectively.
4.2.1. Results on Test1 _2048×1440
On test1_2048×1440, WISE-Net ranks first in NIQE, PIQE, and entropy (Table 2). SCI and SCI++ have the two lowest BRISQUE values. Figure 3 presents two representative scenes together with enlarged vegetation boundaries and rooftop structures. Zero-DCE++ produces a pale appearance with compressed grayscale variation, whereas RUAS over-enhances large areas and obscures local detail. SCI provides adequate illumination and retains much of the texture, but visible push-broom jitter and blur remain. CoLIE yields insufficient brightness recovery and weakens the separation between vegetation layers. The outputs of ZeroIG and SCI++ are mildly gray and low in local contrast, although less severely than Zero-DCE++. Li et al. produces an excessively bright rendering in which fine vegetation is replaced by diffuse, clumped texture. Di-Retinex remains dark and shows poor tonal separation. WISE-Net provides a more balanced brightness distribution and clearer vegetation transitions, roof tiles, parapet details, and thin rooftop metal structures. The SBR stage also reduces the jitter-like blur associated with TDI push-broom acquisition.
4.2.2. Results on Test2 _4096×1440
For test2_4096×1440, WISE-Net ranks first in NIQE, PIQE, and entropy and second in BRISQUE (Table 3). Figure 4 shows one representative scene with enlarged regions containing a window and its metal frame and handle, a boundary between vegetation layers, and building structures such as eaves and a metal utility pole. Zero-DCE++ produces a pale result with compressed grayscale variation; the window handle becomes difficult to distinguish, and the vegetation layers are weakly separated. RUAS causes extensive overexposure. It saturates the handle region and merges much of the mountain vegetation into a bright area with little discernible texture. SCI recovers illumination and texture more effectively, although push-broom jitter and blur remain. CoLIE provides weaker brightness recovery and limited tonal separation between vegetation layers. ZeroIG exhibits pronounced gray whitening, bringing the vegetation intensity close to that of the sky. SCI++ shows a milder version of this effect. Li et al. produces an overly bright-gray image with diffuse, clumped vegetation texture; the eaves and wall also become less distinguishable. Di-Retinex remains dark and has insufficient local contrast. WISE-Net preserves clearer window hardware, vegetation boundaries, eaves, and pole structures. Its refinement stage also suppresses residual jitter-like blur.
4.2.3. Results on Test3 _1536×1440
On test3_1536×1440, WISE-Net obtains the lowest NIQE and highest entropy and ranks second in PIQE (Table 4); SCI and CoLIE yield the two lowest BRISQUE values. Figure 5 shows two urban samples. The first row contains Input, Zero-DCE++, RUAS, SCI, and CoLIE, while the second row contains ZeroIG, SCI++, Li et al., Di-Retinex, and WISE-Net. The enlarged regions cover a mid-rise residential building, the lower stories of a high-rise building with adjacent trees, and the upper stories and roof of another residential building beside a utility pole. These regions permit direct inspection of wall texture, roof boundaries, vegetation, and regular linear structures.
Zero-DCE++ produces a pale appearance with compressed tonal separation, making the high-rise facade less distinguishable from the trees below. RUAS strongly overexposes the scene; large parts of the facade and sky approach saturation and obscure nearby building information. SCI provides effective illumination recovery and retains much of the scene texture, but jitter-like blur remains along structural edges. CoLIE leaves the scenes relatively dark and provides weaker local contrast. ZeroIG markedly whitens and smooths the high-rise facade, reducing visible wall texture, whereas SCI++ shows a milder but still noticeable gray-white shift. Li et al. produces an overly bright gray tone, with reduced tonal separation on the high-rise facade and residential roof. Di-Retinex exhibits the opposite tendency, retaining a dark gray appearance with insufficient brightness recovery and weak contrast. WISE-Net recovers visibility while maintaining clearer separation between buildings and vegetation. Its Refined output preserves facade and roof textures and reduces jitter-like blur along building edges and the utility-pole outline. The enlarged regions in Figure 5 suggest that SBR improves local edge definition after illumination enhancement.
4.3. Ablation Summary
We conduct representative ablation experiments on test1_2048×1440 to examine four components of WISE-Net: the minimum-gain constraint , the Stage-2 self-supervised blind-spot refinement (SBR), the bright-region protection loss , and the gain-map smoothness loss . Table 5 reports the no-reference metrics, while Figure 6 provides enlarged visual comparisons. The two forms of evidence are considered jointly because global no-reference scores do not always capture residual noise, jitter-like blur, or localized edge instability in regular man-made structures.
Without , the output intensity remains close to the input, while noise and jitter-like blur are still reduced because SBR is retained. The deterioration in all four metrics is consistent with the intended role of the minimum-gain term in activating sufficient low-frequency gain in severely underexposed regions.
Without SBR, global brightness remains close to that of the full model because Stage 1 is unchanged, but the enlarged regions retain conspicuous noise and jitter-like blur. Stage 1 alone recovers visibility but does not adequately remove the degradation exposed by amplification. The higher PIQE and BRISQUE values are consistent with this visual difference.
Removing or changes global brightness only slightly, and both variants remain cleaner than Ours w/o SBR because the refinement stage is present. Their enlarged regions nevertheless show mosaic-like softening around text and other regular edges. For Ours w/o , this behavior is consistent with less constrained gain around bright and high-contrast structures. For Ours w/o , it is consistent with increased spatial variation in the gain map. The visual evidence suggests that these two terms mainly stabilize the Stage-1 image supplied to SBR, with limited influence on the overall enhancement magnitude.
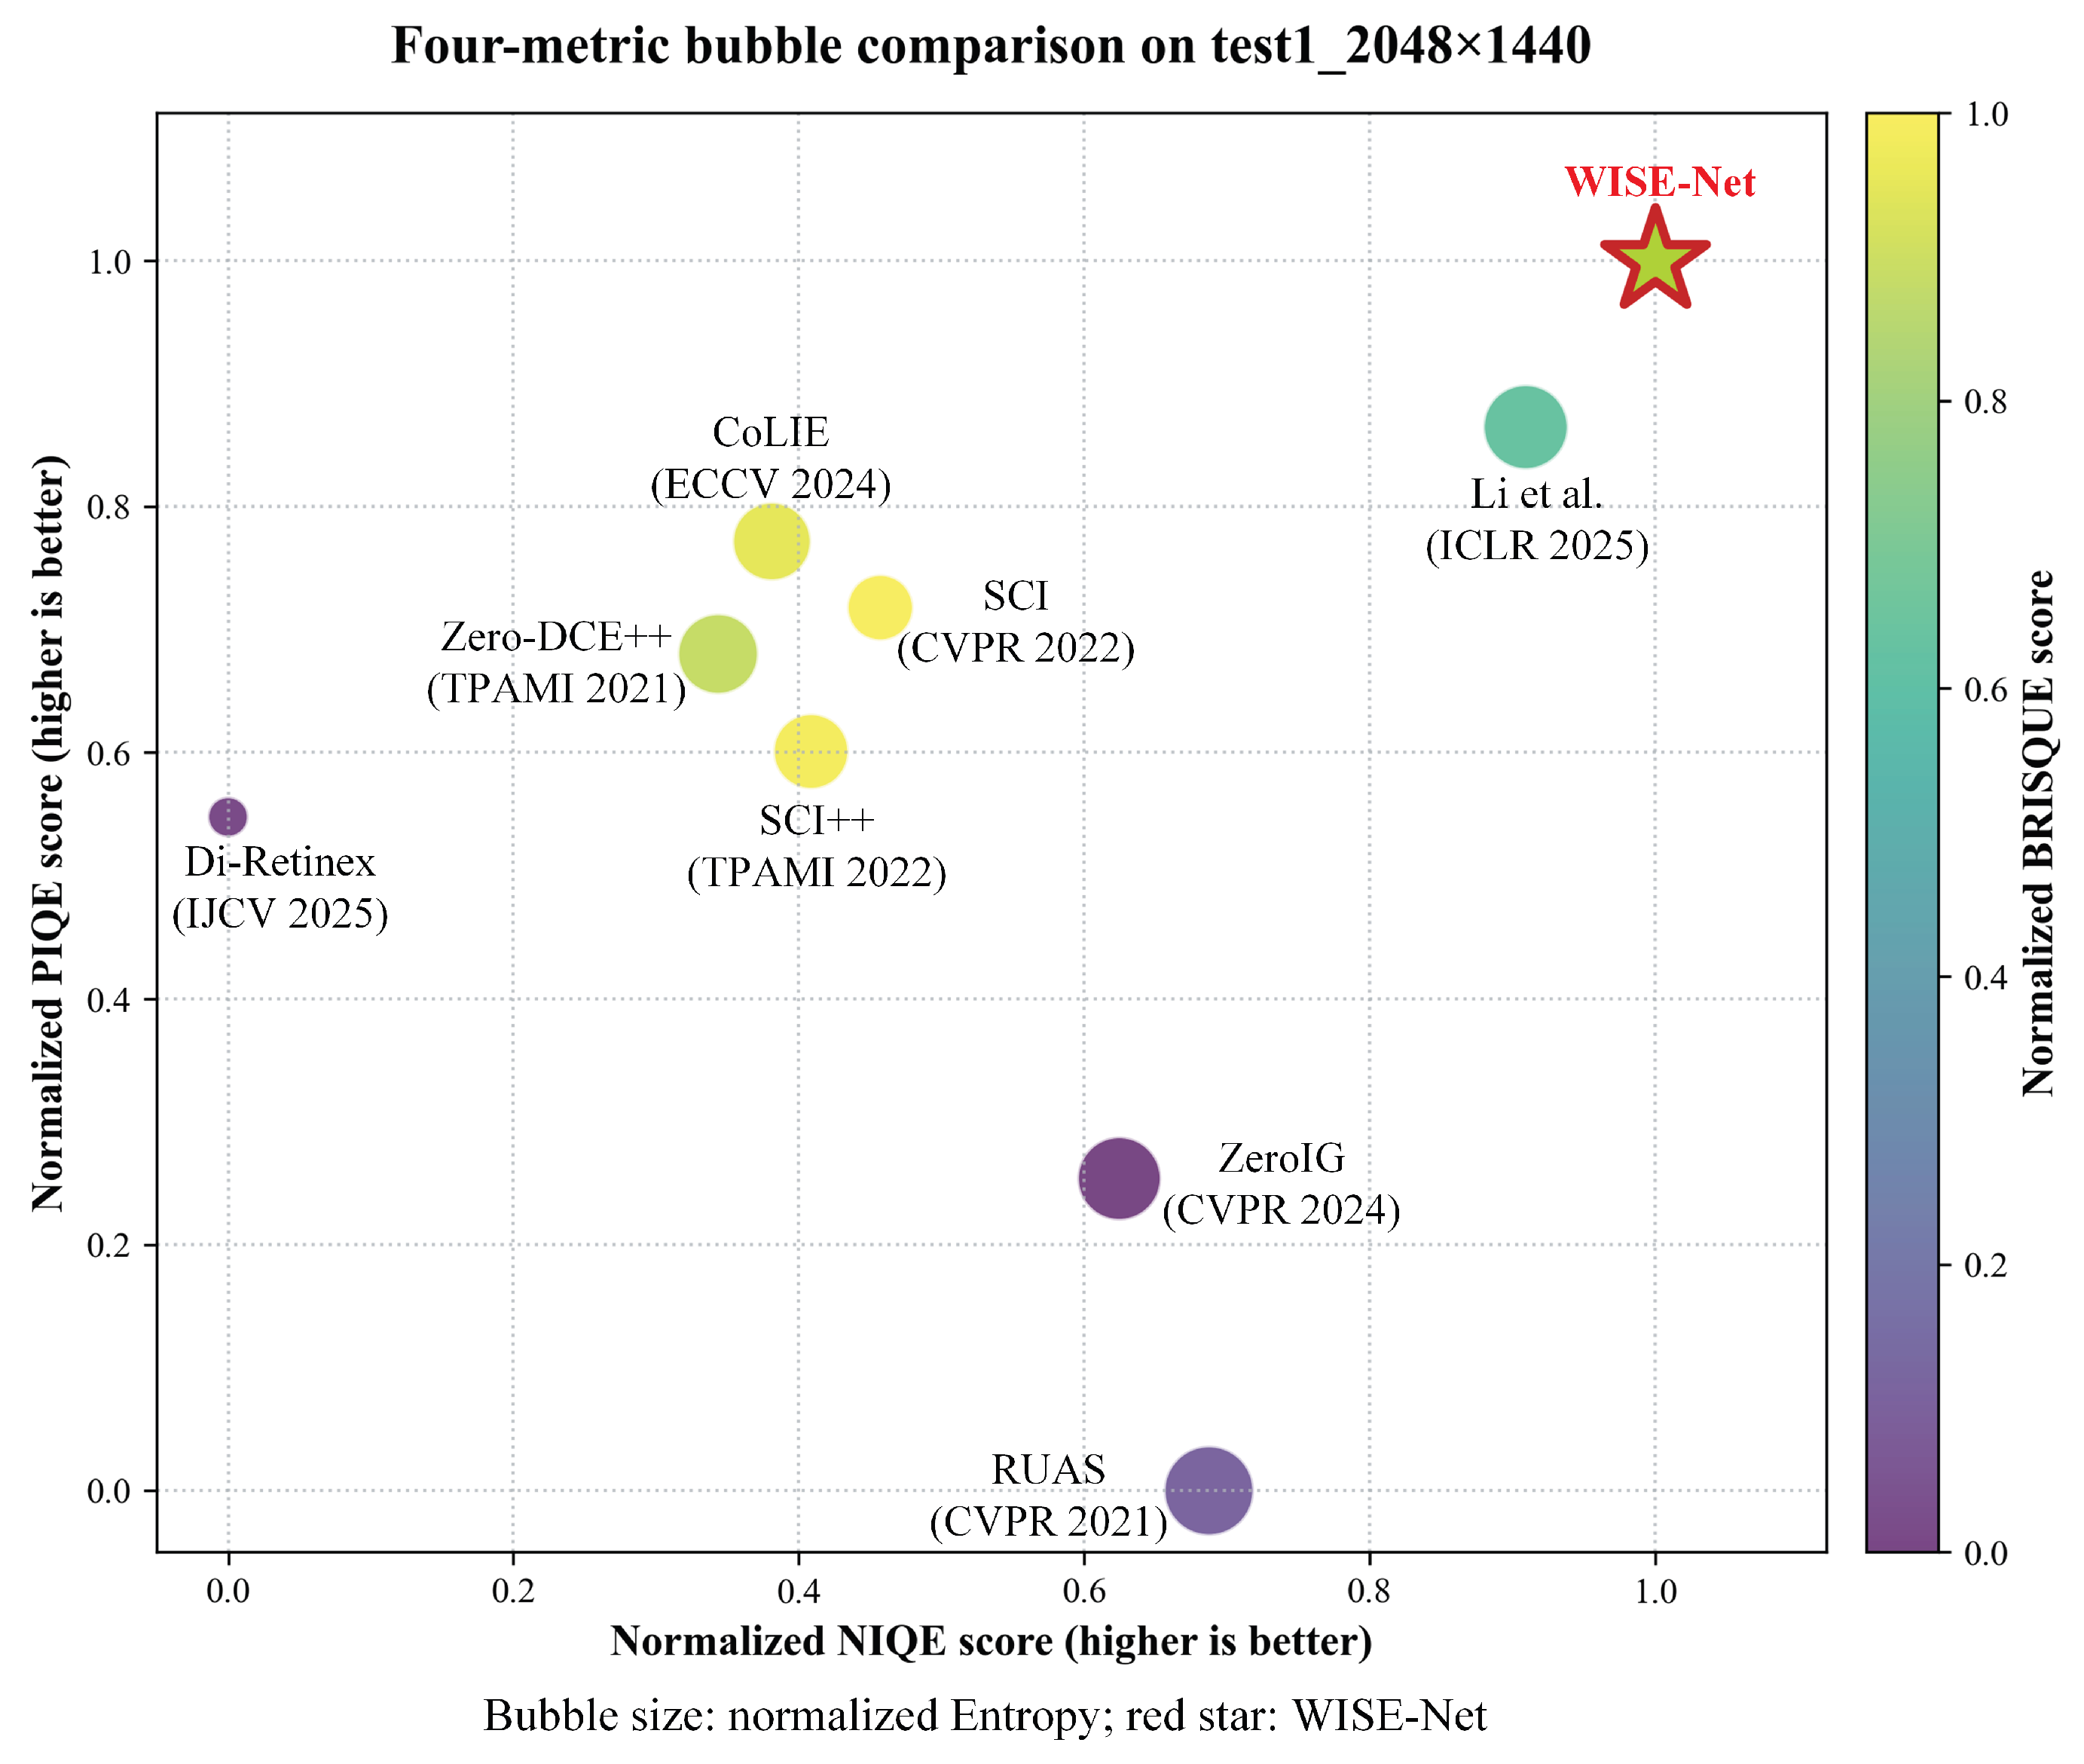
Figure 7.
Four-metric bubble comparison on test1_2048×1440. The chart summarizes the relative NIQE, PIQE, BRISQUE, and entropy values of the nine compared methods.
Figure 7.
Four-metric bubble comparison on test1_2048×1440. The chart summarizes the relative NIQE, PIQE, BRISQUE, and entropy values of the nine compared methods.
5. Conclusions
This paper presented WISE-Net, a fully self-supervised two-stage framework for low-light remote sensing image enhancement. Stage 1 applies a learned brightness-adaptive gain to the low-frequency Haar component and reuses the original high-frequency sub-bands during reconstruction. Stage 2 then applies SBR to the enhanced image distribution, suppressing amplified noise and local artifacts without paired clean targets.
The Stage-1 objective combines dual-view consistency with constraints on relative contrast, minimum dark-region gain, bright-region gain, spatial smoothness, over-exposure, and gradient exclusion. Across the three real 16-bit grayscale test subsets, WISE-Net achieves the lowest NIQE on all three subsets, the lowest PIQE on test1_2048×1440 and test2_4096×1440, and the highest entropy on all three subsets. The ablation results are consistent with distinct roles for the four reported components: governs dark-region activation, SBR removes enhancement-exposed degradation, and and support local stability around regular structures.
The current evaluation is limited to real grayscale data acquired with the same TDI-ICMOS imaging mechanism. Future work will examine airborne acquisitions and a broader range of scene categories.
Author Contributions
Conceptualization, H.D.; methodology, H.D. and H.Z.; software, H.D.; validation, H.D. and Z.J.; formal analysis, H.D., H.Z. and S.W.; investigation, S.L. and Z.J.; resources, H.Z.; data curation, H.D.; writing—original draft preparation, H.D.; writing—review and editing, H.D., H.Z., S.W. and X.F.; visualization, H.D.; supervision, H.Z. and S.W.; project administration, H.Z. and S.W.; funding acquisition, S.W. All authors have read and agreed to the published version of the manuscript.
Funding
This research was funded by the National Natural Science Foundation of China (62403476).
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Land, E.H.; McCann, J.J. Lightness and retinex theory. J. Opt. Soc. Amer. 1971, 61(1), 1–11. [Google Scholar] [CrossRef]
- Jobson, D.J.; Rahman, Z.; Woodell, G.A. Properties and performance of a center/surround retinex. IEEE Trans. Image Process. 1997, 6(3), 451–462. [Google Scholar] [CrossRef]
- Jobson, D.J.; Rahman, Z.; Woodell, G.A. A multiscale retinex for bridging the gap between color images and the human observation of scenes. IEEE Trans. Image Process. 1997, 6(7), 965–976. [Google Scholar] [CrossRef]
- Lore, K.G.; Akintayo, A.; Sarkar, S. LLNet: A deep autoencoder approach to natural low-light image enhancement. Pattern Recognit. 2017, 61, 650–662. [Google Scholar] [CrossRef]
- Wei, C.; Wang, W.; Yang, W.; Liu, J. Deep retinex decomposition for low-light enhancement. arXiv 2018, arXiv:1808.04560. [Google Scholar]
- Zhang, Y.; Zhang, J.; Guo, X. Kindling the darkness: A practical low-light image enhancer. In Proceedings of the 27th ACM Int. Conf. Multimedia, 2019; pp. 1632–1640. [Google Scholar]
- Jiang, Y.; Gong, X.; Liu, D. EnlightenGAN: Deep light enhancement without paired supervision. IEEE Trans. Image Process. 2021, 30, 2340–2349. [Google Scholar] [CrossRef]
- Guo, C.; Li, C.; Guo, J. Zero-reference deep curve estimation for low-light image enhancement. In Proceedings of the IEEE/CVF Conf. Comput. Vis. Pattern Recognit., 2020; pp. 1777–1786. [Google Scholar]
- Li, C.; Guo, C.; Loy, C.C. Learning to enhance low-light image via zero-reference deep curve estimation. IEEE Trans. Pattern Anal. Mach. Intell. 2021, 44(8), 4225–4238. [Google Scholar] [CrossRef]
- Liu, R.; Ma, L.; Zhang, J. Retinex-inspired unrolling with cooperative prior architecture search for low-light image enhancement. In Proceedings of the IEEE/CVF Conf. Comput. Vis. Pattern Recognit., 2021; pp. 10556–10565. [Google Scholar]
- Ma, L.; Ma, T.; Liu, R. Toward fast, flexible, and robust low-light image enhancement. In Proceedings of the IEEE/CVF Conf. Comput. Vis. Pattern Recognit., 2022; pp. 5627–5636. [Google Scholar]
- Ma, L.; Ma, T.; Xu, C. Learning with self-calibrator for fast and robust low-light image enhancement. IEEE Trans. Pattern Anal. Mach. Intell. 2025, 47(10), 9095–9112. [Google Scholar] [CrossRef]
- Shi, Y.; Liu, D.; Zhang, L. ZERO-IG: Zero-shot illumination-guided joint denoising and adaptive enhancement for low-light images. In Proceedings of the IEEE/CVF Conf. Comput. Vis. Pattern Recognit., 2024; pp. 3015–3024. [Google Scholar]
- Li, R.-K.; Li, M.-H.; Chen, S.-Q. Dark2Light: multi-stage progressive learning model for low-light image enhancement. Opt. Express 2023, 31(26), 42887–42900. [Google Scholar] [CrossRef]
- Wang, T.; Zhang, K.; Shen, T.; et al. Ultra-high-definition low-light image enhancement: A benchmark and transformer-based method. Proc. AAAI Conf. Artif. Intell. 2023, Volume 37(No. 3), 2654–2662. [Google Scholar] [CrossRef]
- Zamir, S.W.; Arora, A.; Khan, S. Restormer: Efficient transformer for high-resolution image restoration. In Proceedings of the IEEE/CVF Conf. Comput. Vis. Pattern Recognit., 2022; pp. 5718–5729. [Google Scholar]
- Zamir, S.W.; Arora, A.; Khan, S. Learning enriched features for fast image restoration and enhancement. IEEE Trans. Pattern Anal. Mach. Intell. 2023, 45(2), 1934–1948. [Google Scholar] [CrossRef]
- Xu, X.; Wang, R.; Fu, C.-W. SNR-aware low-light image enhancement. In Proceedings of the IEEE/CVF Conf. Comput. Vis. Pattern Recognit., 2022; pp. 17693–17703. [Google Scholar]
- Chen, C.; Chen, Q.; Xu, J. Learning to see in the dark. In Proceedings of the IEEE/CVF Conf. Comput. Vis. Pattern Recognit., 2018; pp. 3291–3300. [Google Scholar]
- Krull, A.; Buchholz, T.-O.; Jug, F. Noise2Void: learning denoising from single noisy images. In Proceedings of the IEEE/CVF Conf. Comput. Vis. Pattern Recognit., 2019; pp. 2124–2132. [Google Scholar]
- Lehtinen, J.; Munkberg, J.; Hasselgren, J. Noise2Noise: Learning image restoration without clean data. arXiv 2018, arXiv:1803.04189. [Google Scholar]
- Huang, T.; Li, S.; Jia, X. Neighbor2Neighbor: Self-supervised denoising from single noisy images. In Proceedings of the IEEE/CVF Conf. Comput. Vis. Pattern Recognit., 2021; pp. 14776–14785. [Google Scholar]
- Ronneberger, O.; Fischer, P.; Brox, T. U-Net: Convolutional networks for biomedical image segmentation. In Proceedings of the Int. Conf. Med. Image Comput. Comput.-Assist. Intervent., 2015; pp. 234–241. [Google Scholar]
- Mallat, S.G. A theory for multiresolution signal decomposition: The wavelet representation. IEEE Trans. Pattern Anal. Mach. Intell. 1989, 11(7), 674–693. [Google Scholar] [CrossRef]
- Wei, K.; Fu, Y.; Yang, J. A physics-based noise formation model for extreme low-light raw denoising. In Proceedings of the IEEE/CVF Conf. Comput. Vis. Pattern Recognit., 2020; pp. 2755–2764. [Google Scholar]
- Mittal, A.; Moorthy, A.K.; Bovik, A.C. No-reference image quality assessment in the spatial domain. IEEE Trans. Image Process. 2012, 21(12), 4695–4708. [Google Scholar] [CrossRef]
- Mittal, A.; Soundararajan, R.; Bovik, A.C. Making a completely blind image quality analyzer. IEEE Signal Process. Lett. 2012, 20(3), 209–212. [Google Scholar] [CrossRef]
- Venkatanath, N.; Praneeth, D.; Sumohana, S.C. Blind image quality evaluation using perception based features. In Proceedings of the 21st Nat. Conf. Commun. (NCC), 2015; pp. 1–6. [Google Scholar]
- Yang, W.; Wang, S.; Fang, Y. From fidelity to perceptual quality: A semi-supervised approach for low-light image enhancement. In Proceedings of the IEEE/CVF Conf. Comput. Vis. Pattern Recognit., 2020; pp. 3060–3069. [Google Scholar]
- Yang, W.; Wang, W.; Huang, H. Sparse gradient regularized deep Retinex network for robust low-light image enhancement. IEEE Trans. Image Process. 2021, 30, 2072–2086. [Google Scholar] [CrossRef]
- Chobola, T.; Liu, Y.; Zhang, H. Fast context-based low-light image enhancement via neural implicit representations. In Proceedings of the Eur. Conf. Comput. Vis., 2024; pp. 413–430. [Google Scholar]
- Li, H.; Wang, H. Interpretable unsupervised joint denoising and enhancement for real-world low-light scenarios. In Proceedings of the Int. Conf. Learn. Represent., 2025; pp. 39525–39537. [Google Scholar]
- Sun, S.; Ren, W.; Peng, J. DI-Retinex: Digital-imaging Retinex model for low-light image enhancement. Int. J. Comput. Vis. 2025, 133(12), 8293–8314. [Google Scholar] [CrossRef]
- Qu, L.; Zhao, S.; Huang, Y. Self-inspired learning for denoising live-cell super-resolution microscopy. Nat. Methods 2024, 21(10), 1895–1908. [Google Scholar] [CrossRef]
- Jin, Y.; Yang, W.; Tan, R.T. Unsupervised night image enhancement: When layer decomposition meets light-effects suppression. In Proceedings of the Eur. Conf. Comput. Vis., 2022; pp. 404–421. [Google Scholar]
Figure 1.
Architecture of WISE-Net. (a) Stage 1 performs wavelet-guided illumination modulation by enhancing the low-frequency Haar component and preserving the original high-frequency sub-bands for reconstruction. (b) After Stage 1 is frozen, Stage 2 applies self-supervised blind-spot refinement (SBR) to suppress enhancement-amplified noise and local artifacts. The two stages are optimized sequentially without clean reference images.
Figure 1.
Architecture of WISE-Net. (a) Stage 1 performs wavelet-guided illumination modulation by enhancing the low-frequency Haar component and preserving the original high-frequency sub-bands for reconstruction. (b) After Stage 1 is frozen, Stage 2 applies self-supervised blind-spot refinement (SBR) to suppress enhancement-amplified noise and local artifacts. The two stages are optimized sequentially without clean reference images.
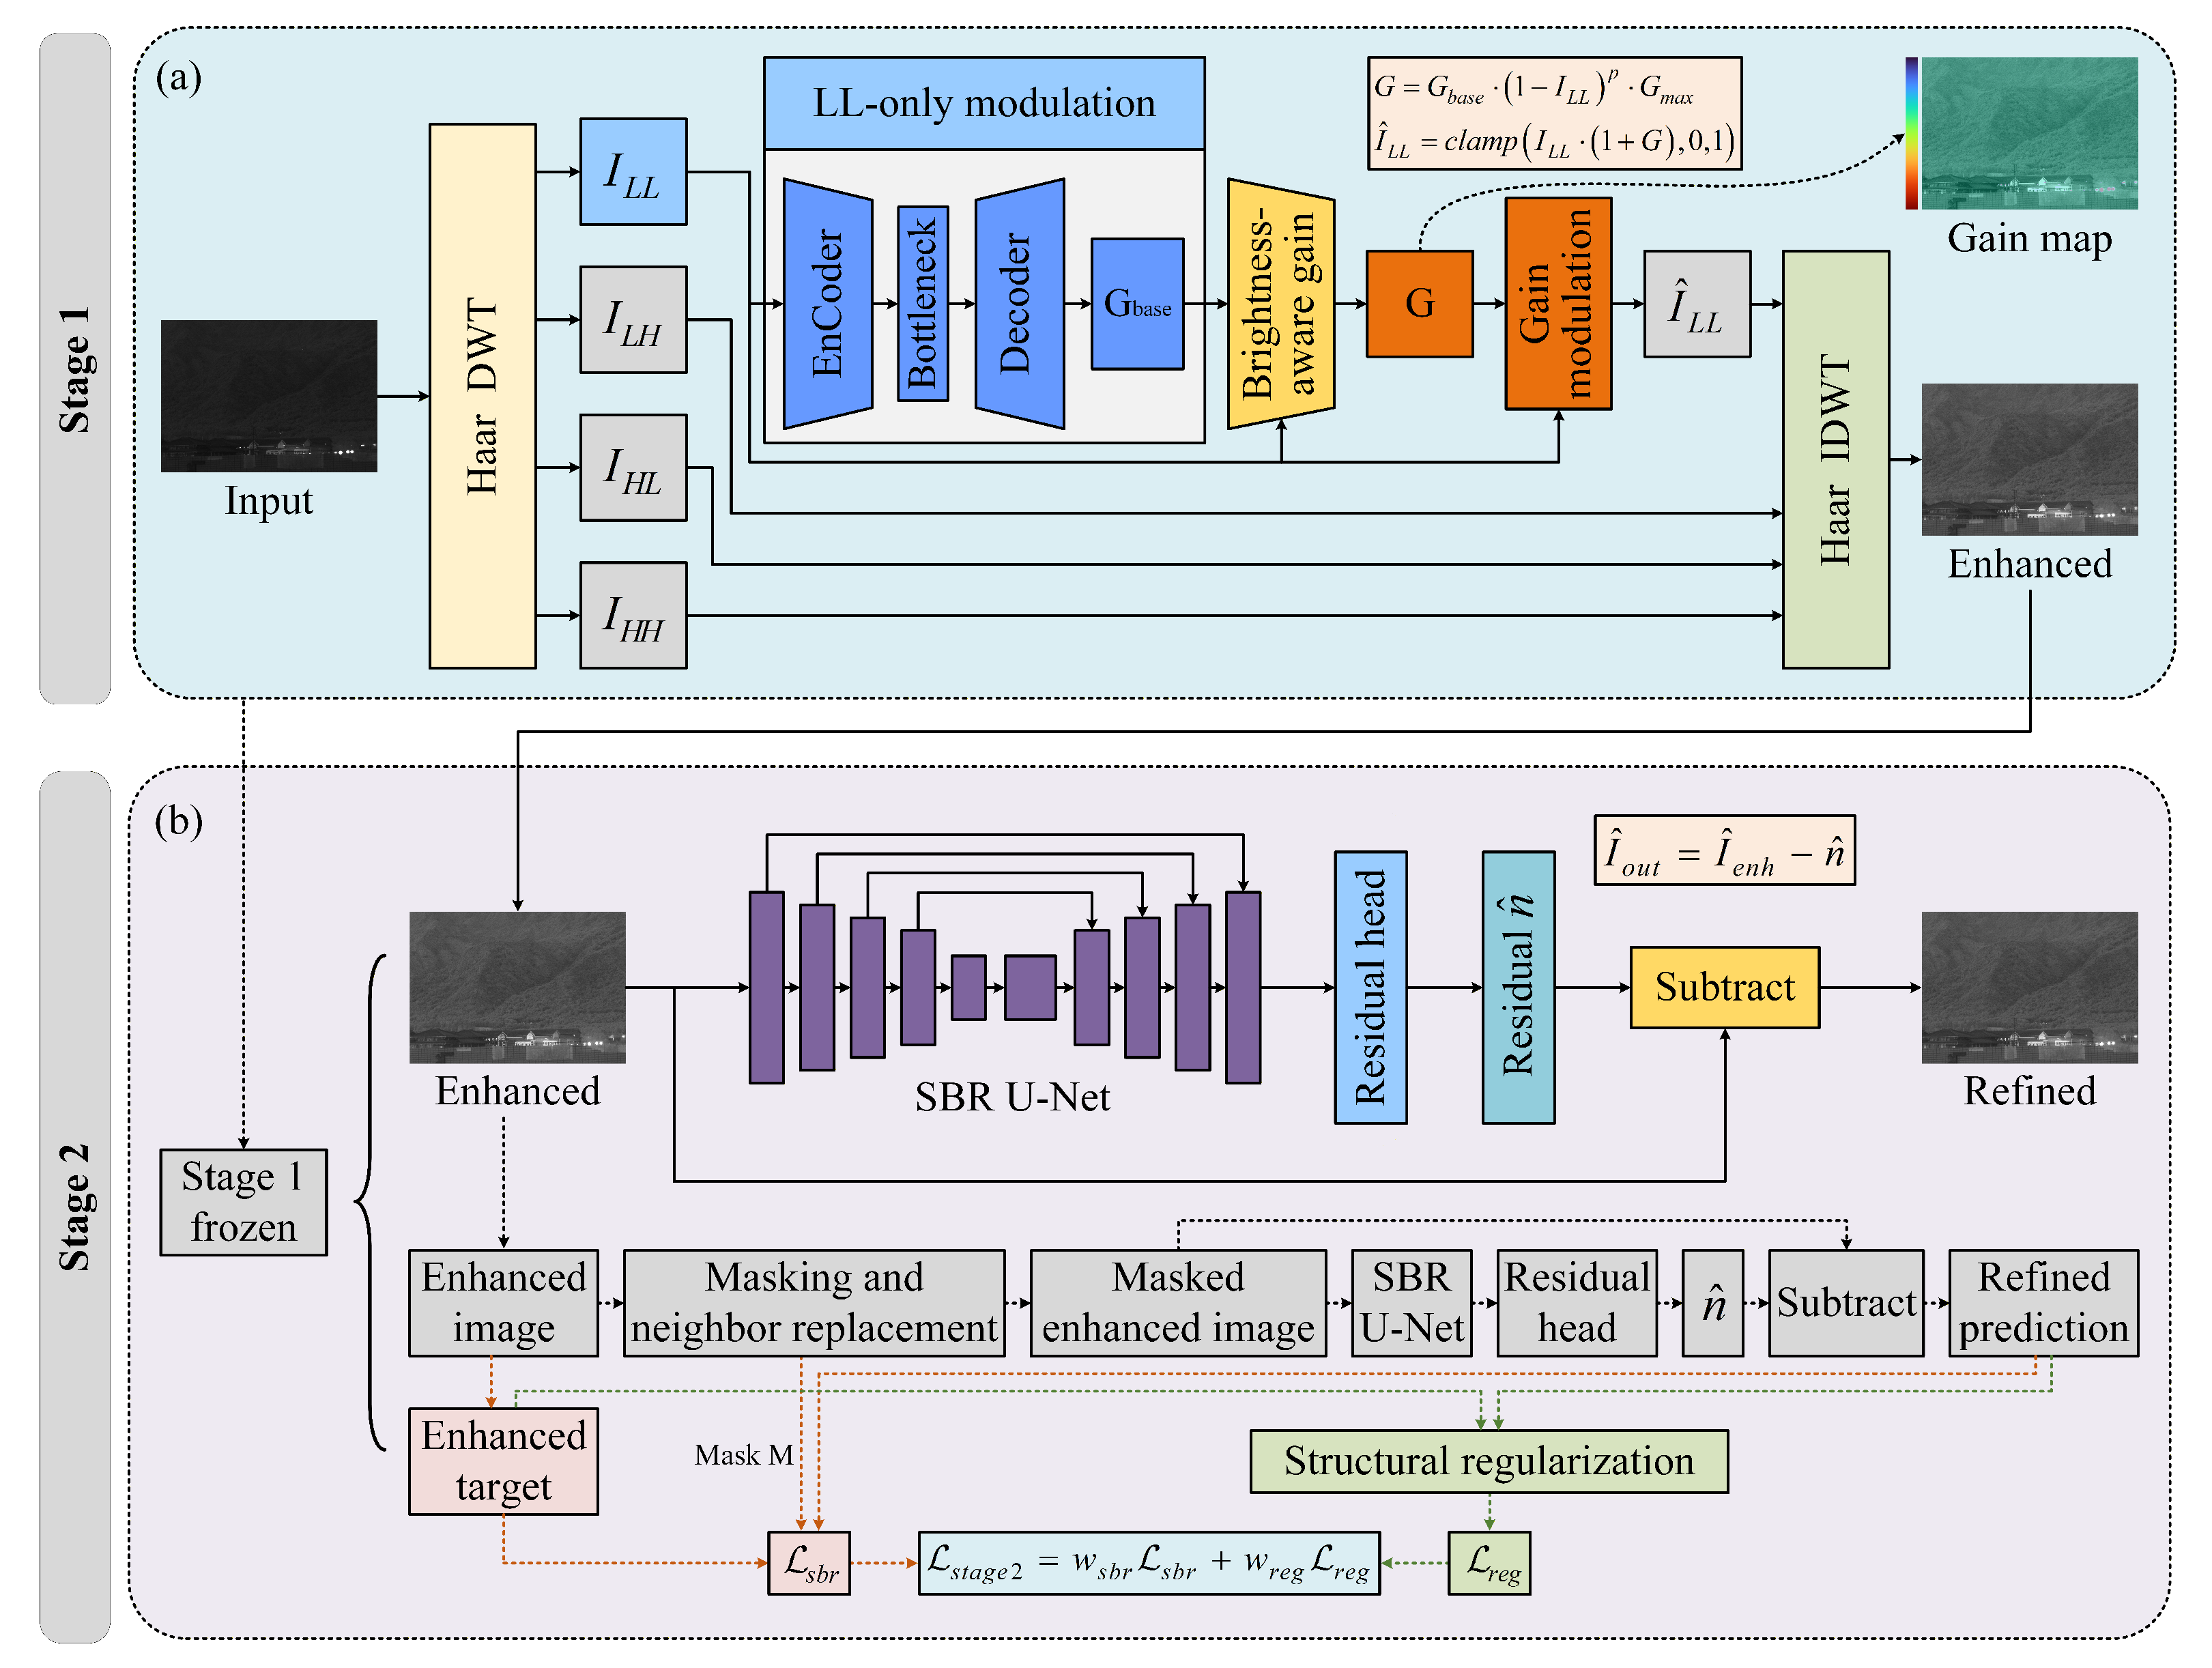
Figure 3.
Qualitative comparison on test1_2048×1440. WISE-Net improves global illumination while preserving weak structures and suppressing enhancement-amplified artifacts.
Figure 3.
Qualitative comparison on test1_2048×1440. WISE-Net improves global illumination while preserving weak structures and suppressing enhancement-amplified artifacts.
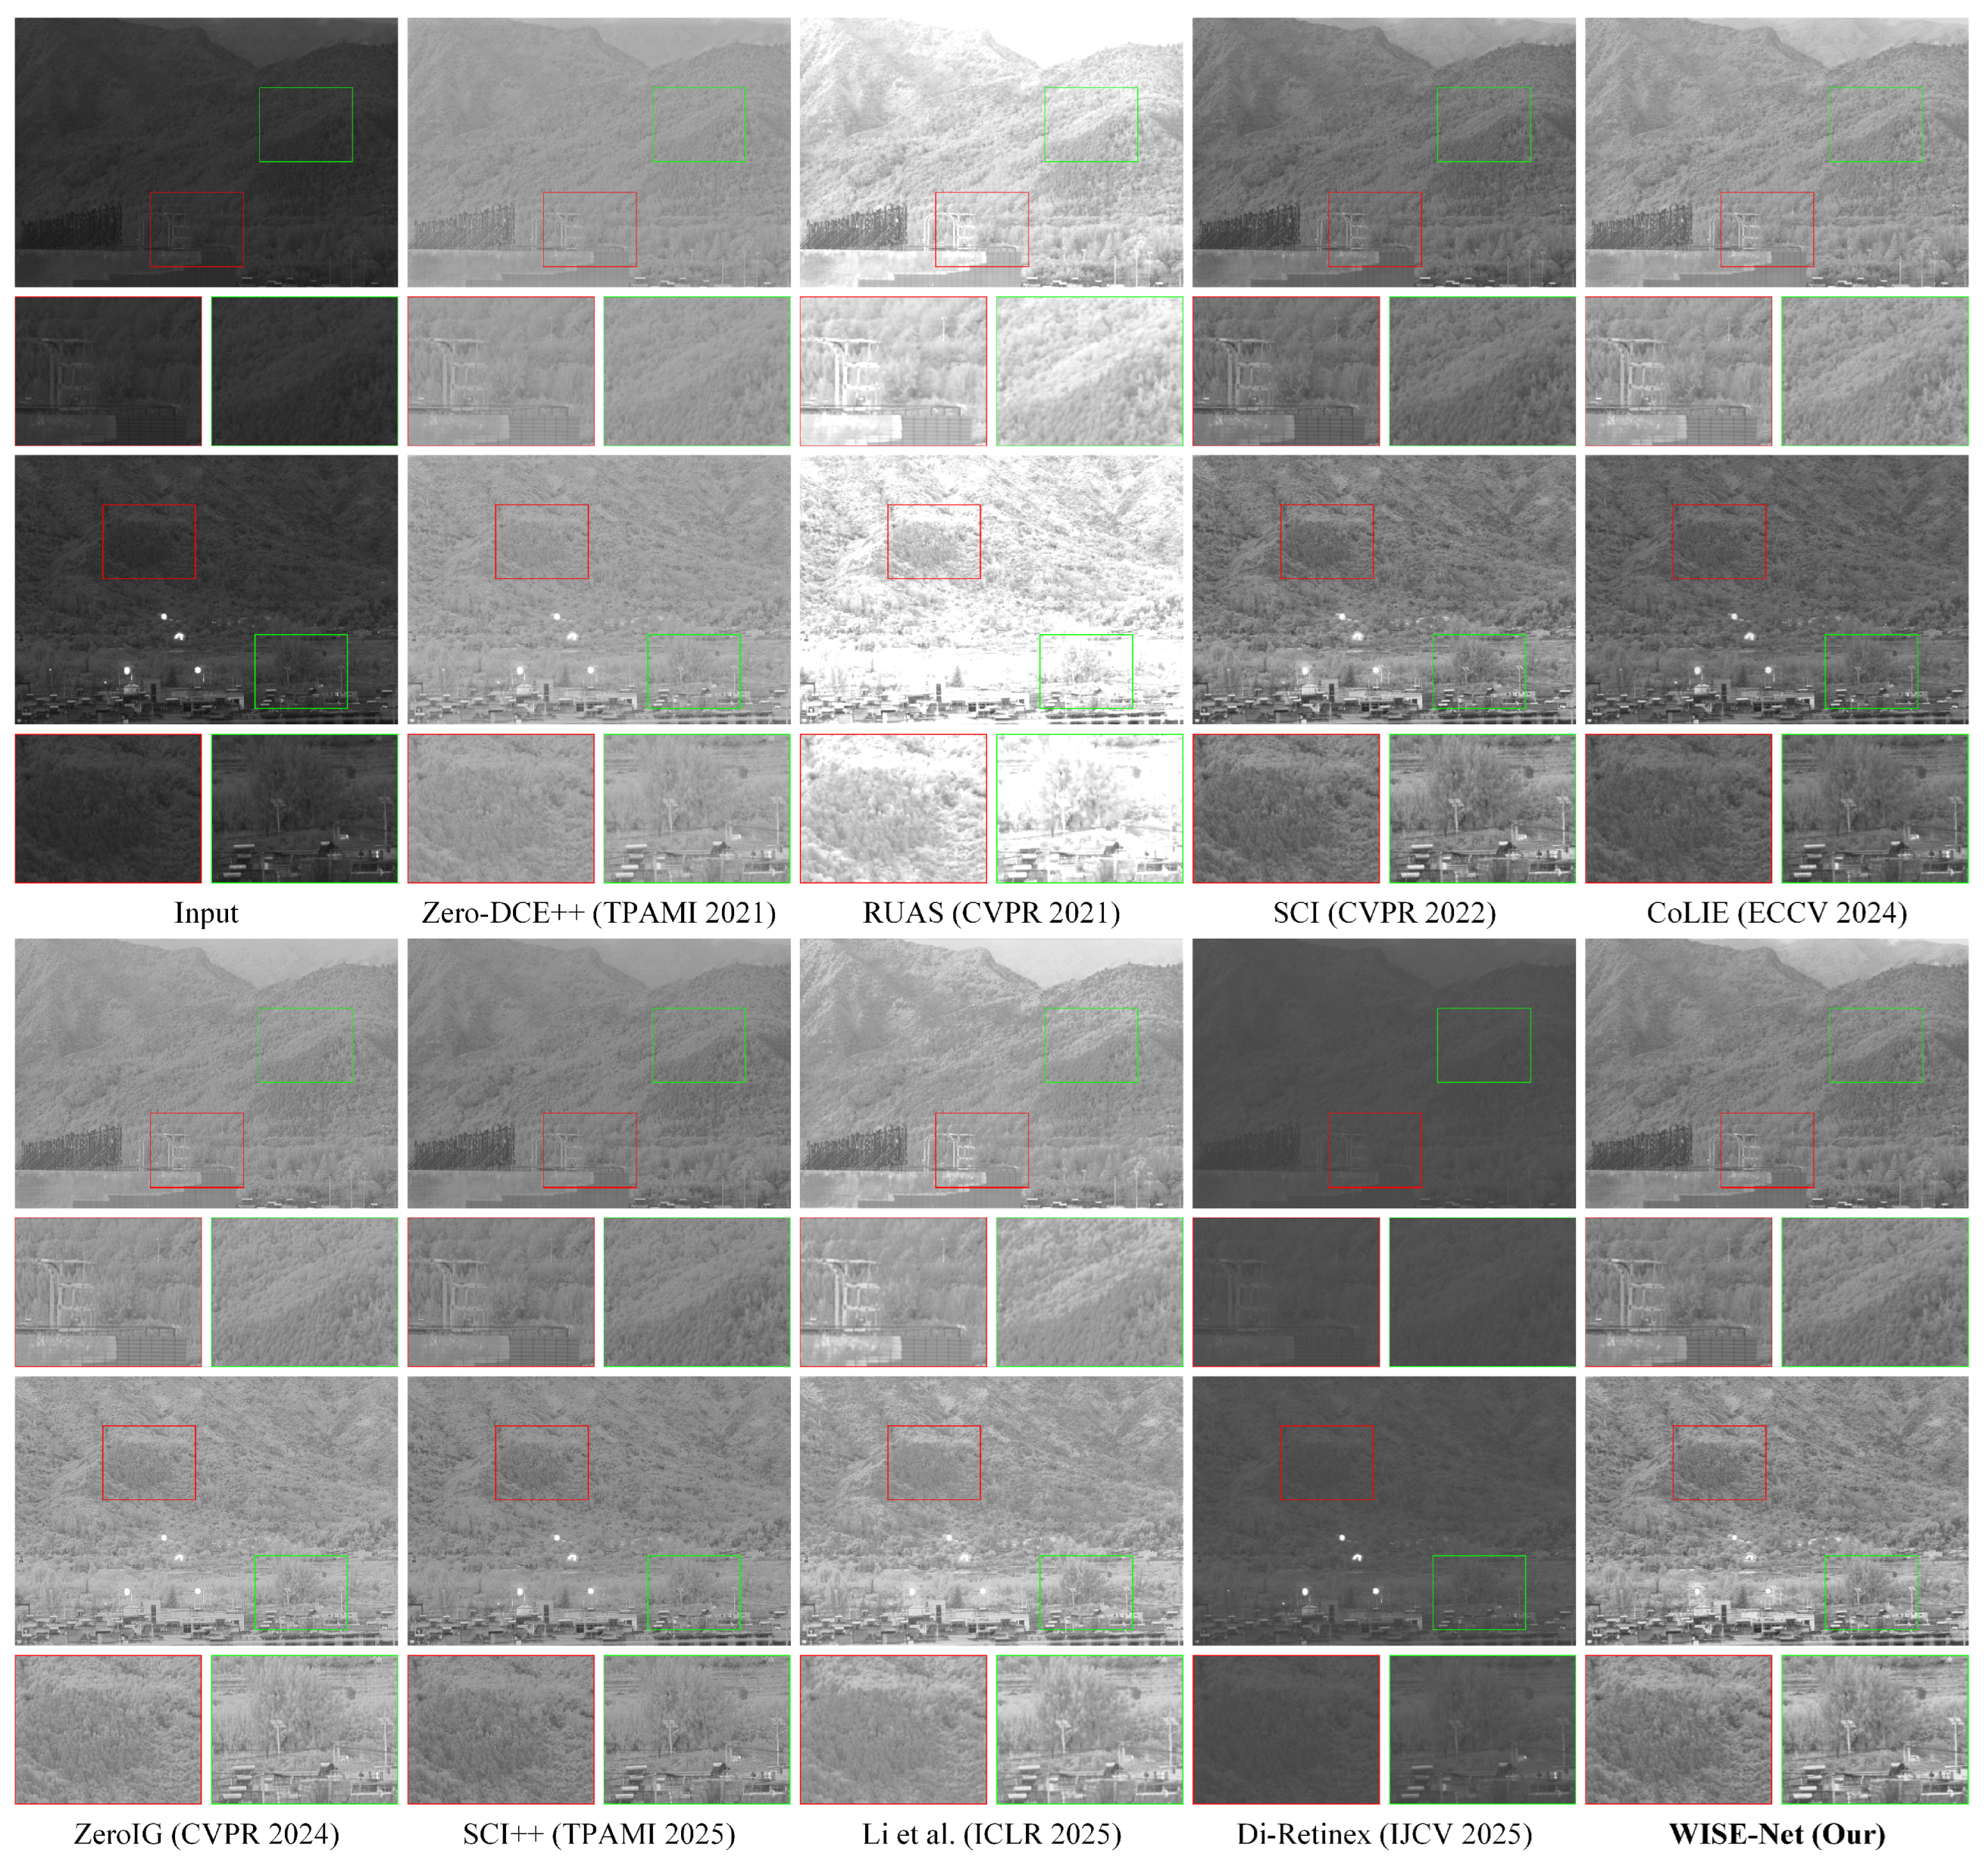
Figure 4.
Qualitative comparison on the wider-format generalization subset test2_4096×1440. WISE-Net maintains structural detail and stable local contrast after brightness lifting.
Figure 4.
Qualitative comparison on the wider-format generalization subset test2_4096×1440. WISE-Net maintains structural detail and stable local contrast after brightness lifting.
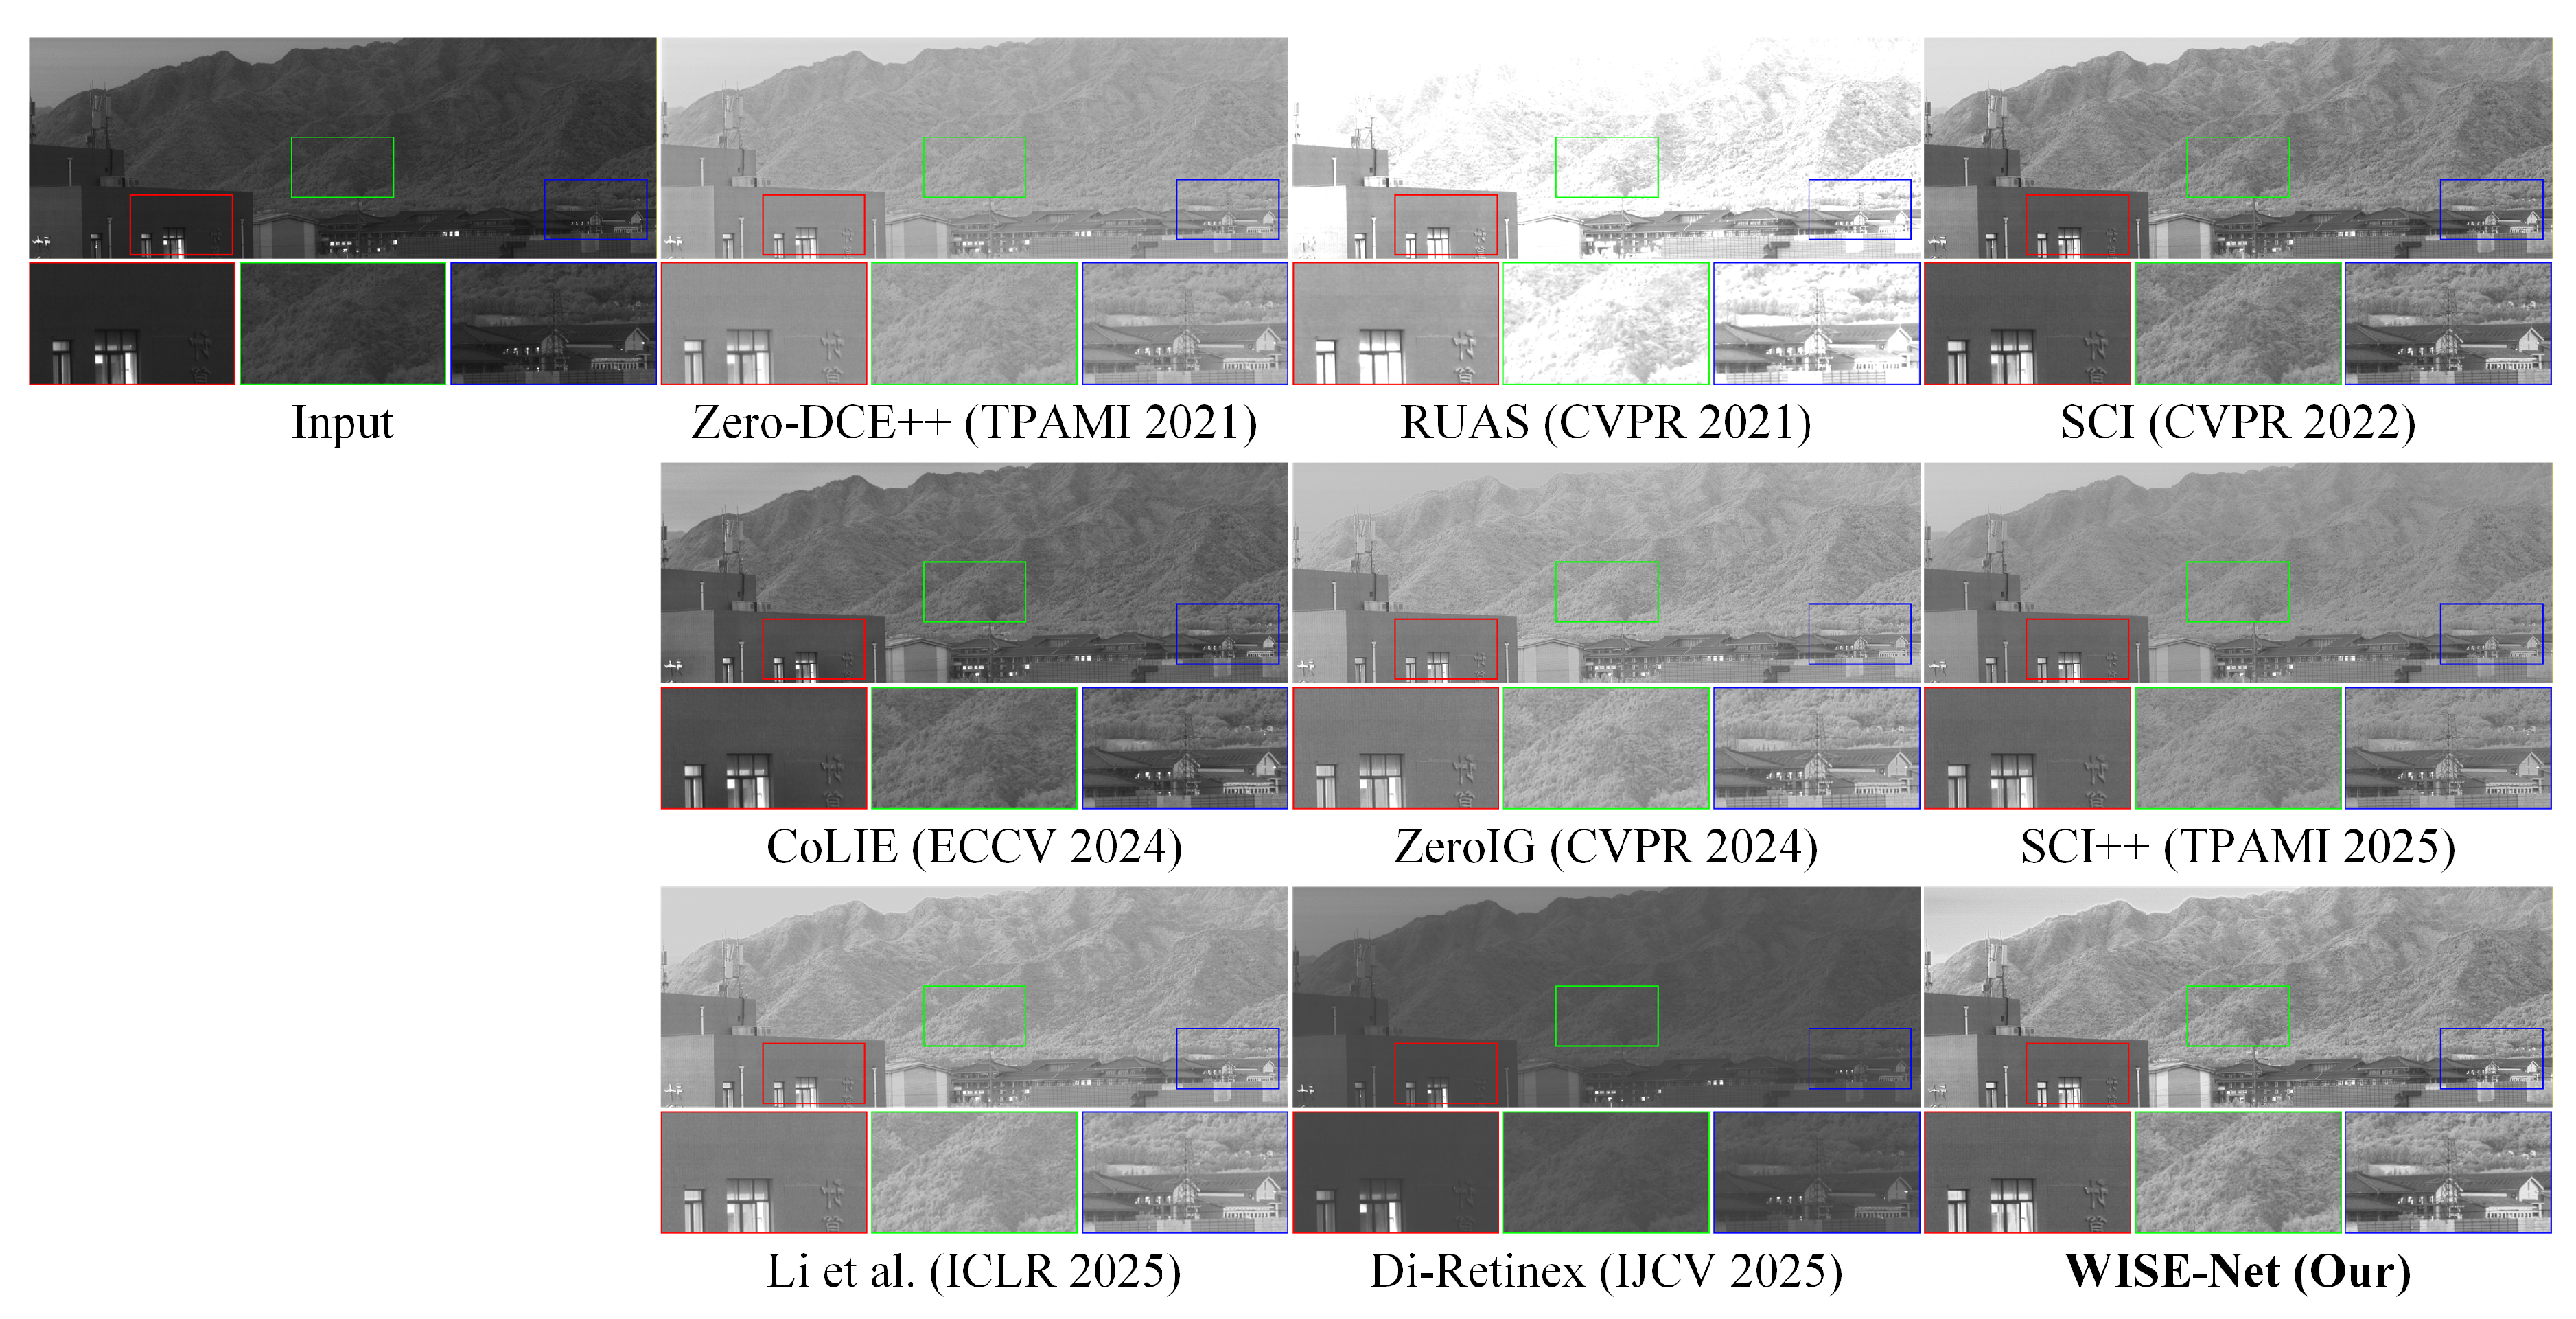
Figure 5.
Qualitative comparison on the narrower-format generalization subset test3_1536×1440. WISE-Net recovers visibility while retaining detail and limiting residual noise.
Figure 5.
Qualitative comparison on the narrower-format generalization subset test3_1536×1440. WISE-Net recovers visibility while retaining detail and limiting residual noise.
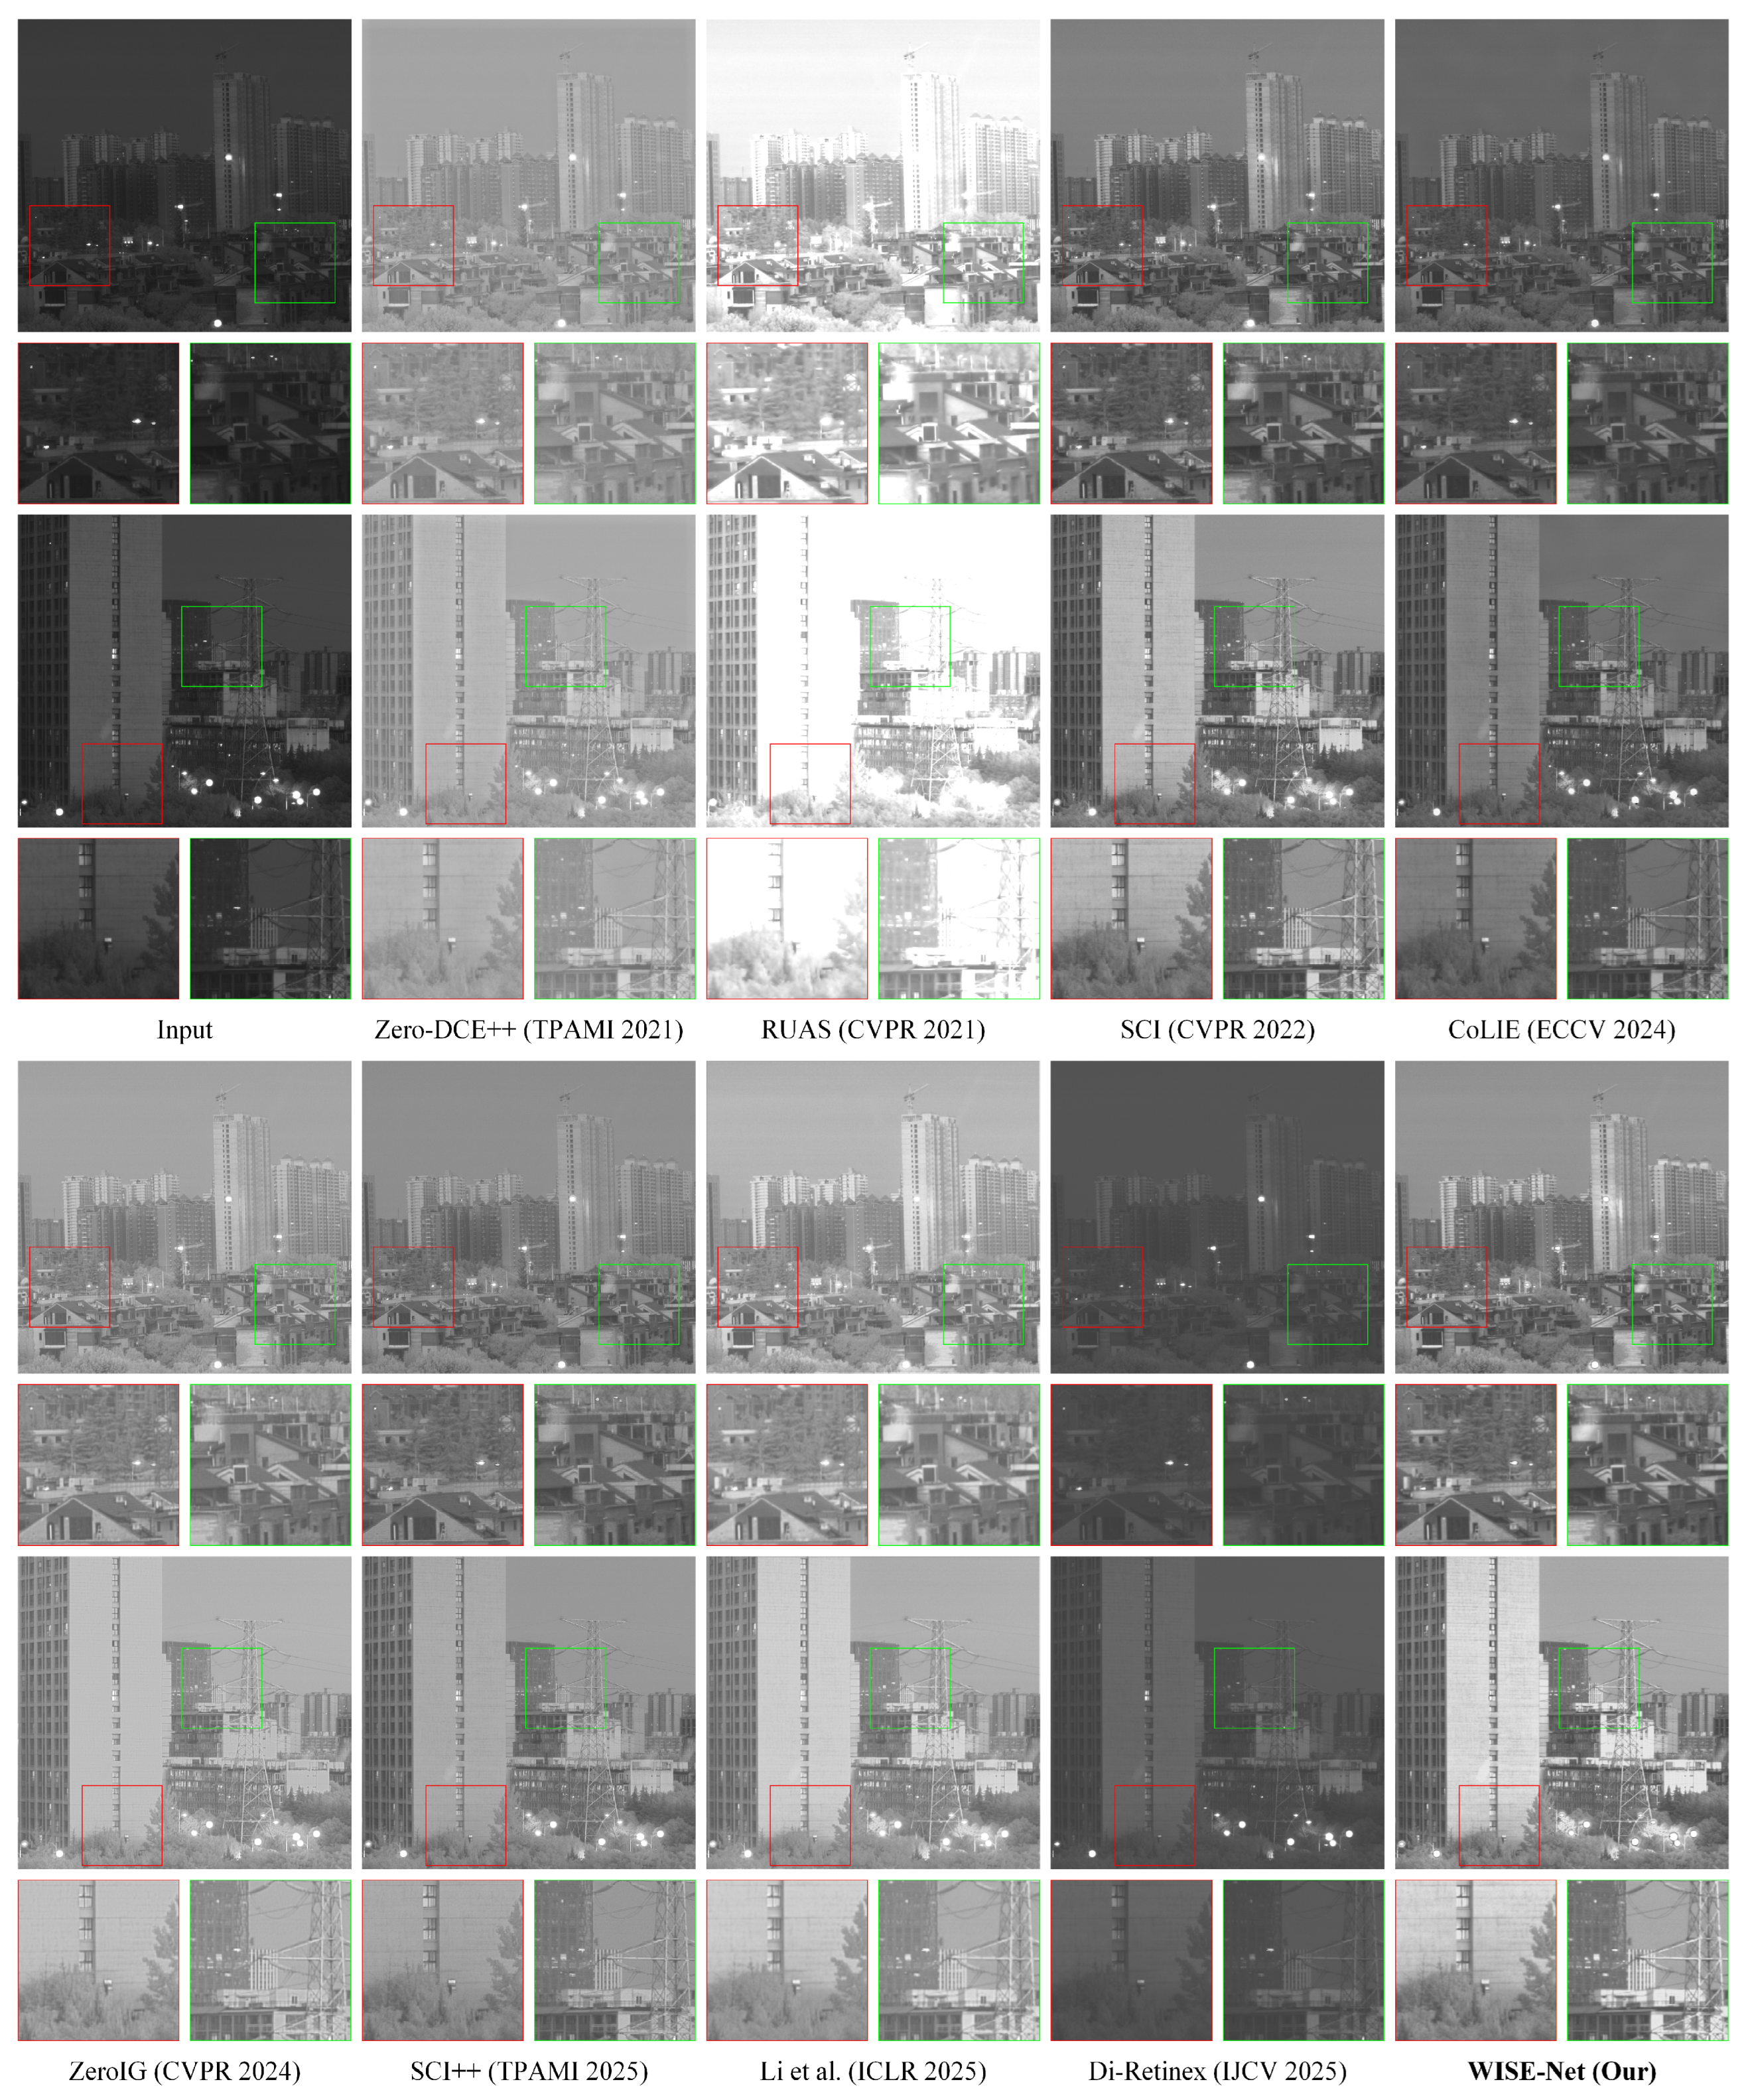
Figure 6.
Visual ablation comparison on a representative scene from test1_2048×1440. From left to right: Input, Ours, Ours w/o , Ours w/o SBR, Ours w/o , and Ours w/o . The enlarged regions highlight the insufficient brightness recovery without , the residual noise and jitter-like blur without SBR, and the mosaic-like edge softening caused by removing or .
Figure 6.
Visual ablation comparison on a representative scene from test1_2048×1440. From left to right: Input, Ours, Ours w/o , Ours w/o SBR, Ours w/o , and Ours w/o . The enlarged regions highlight the insufficient brightness recovery without , the residual noise and jitter-like blur without SBR, and the mosaic-like edge softening caused by removing or .
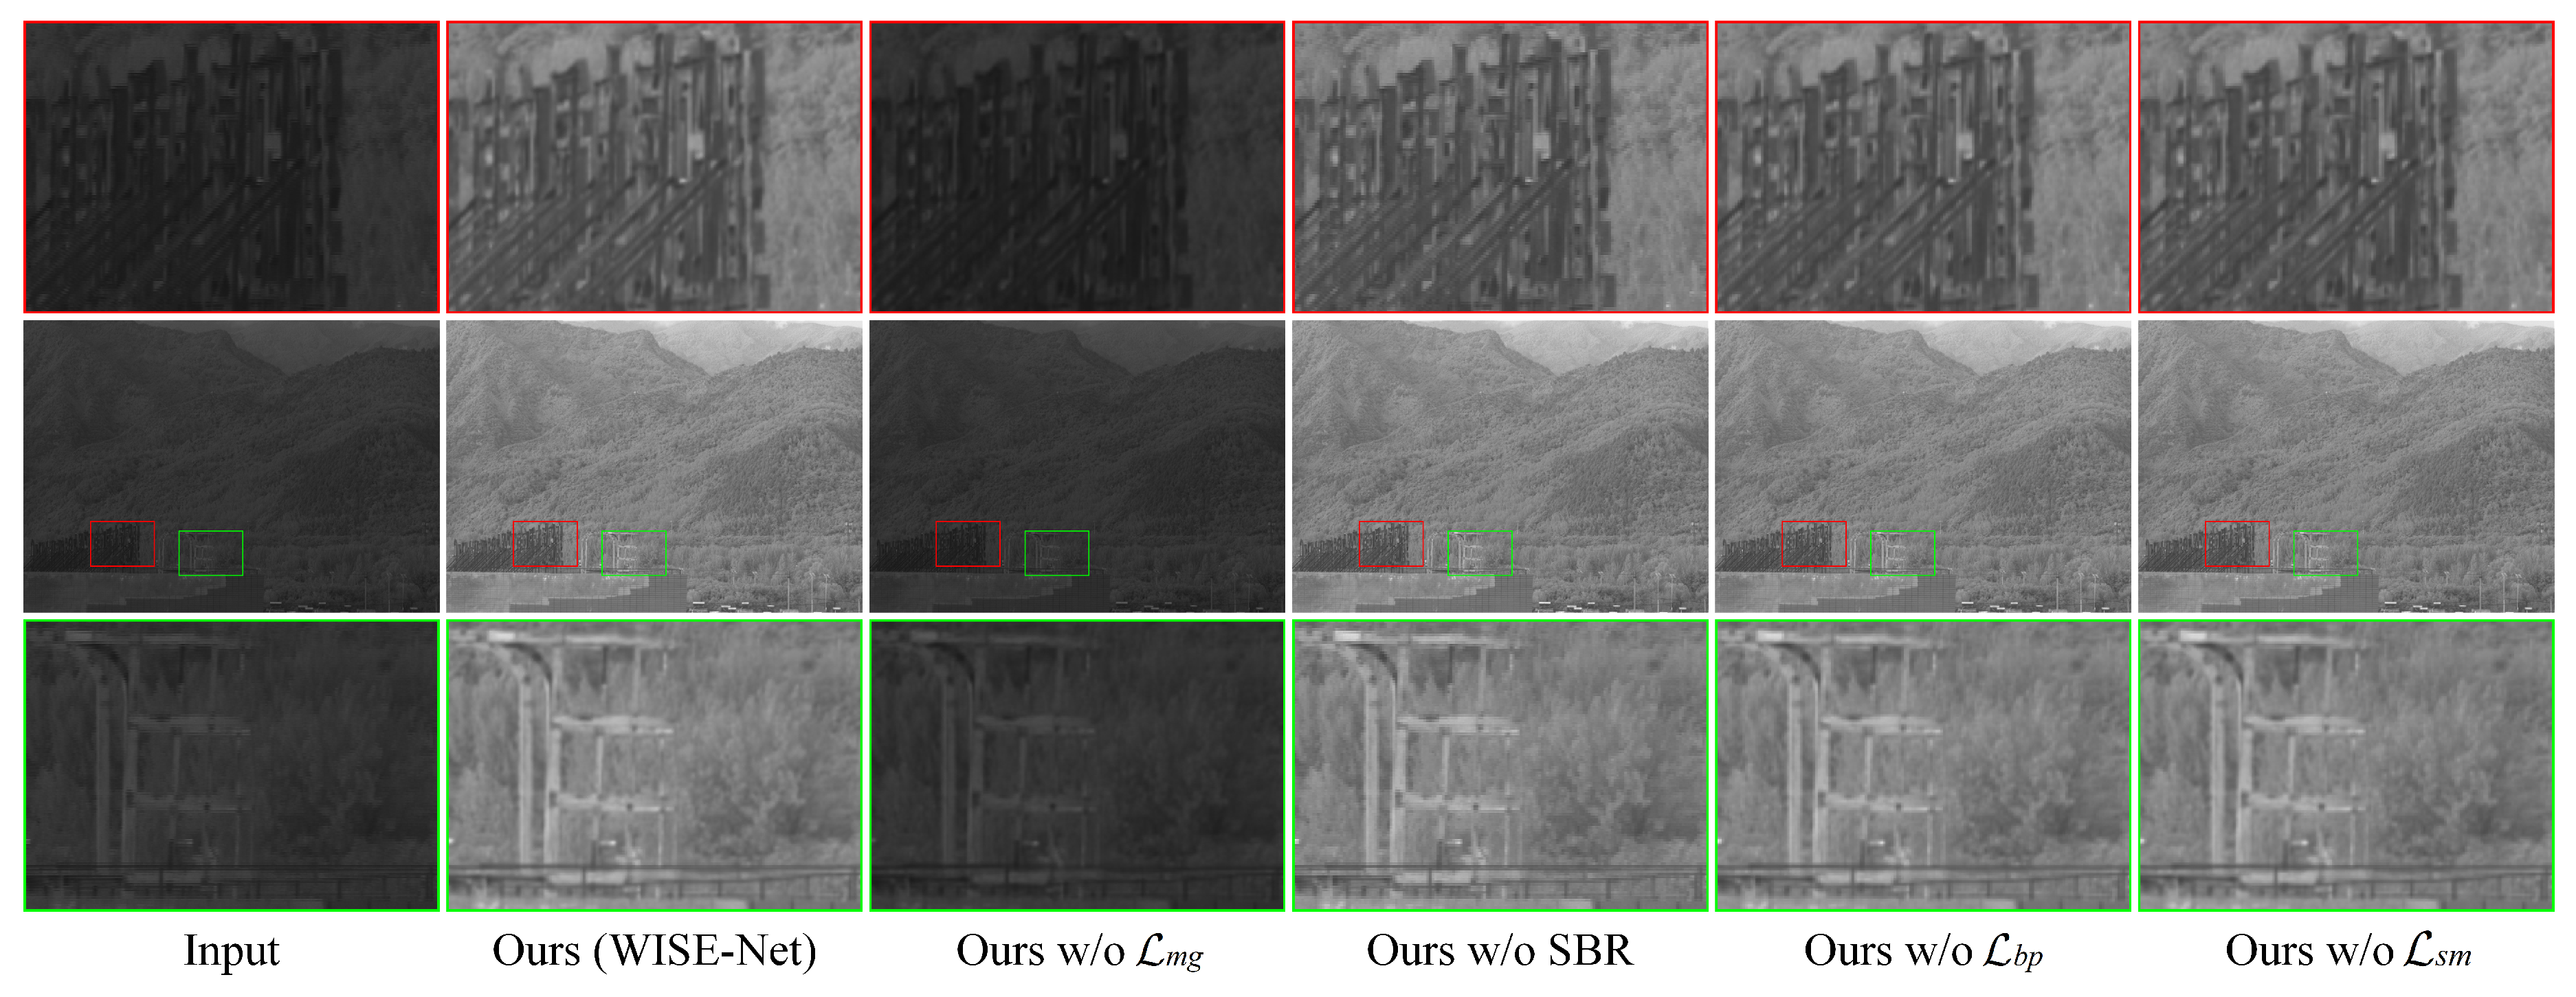

Table 1.
Statistics of the training and evaluation data used for WISE-Net.
| Split | Images | Resolution | Format | Bit depth | Role |
|---|---|---|---|---|---|
| Training | 1460 | 2048×1440 | TIFF | 16-bit | Training |
| test1_2048×1440 | 40 | 2048×1440 | TIFF | 16-bit | Evaluation |
| test2_4096×1440 | 107 | 4096×1440 | TIFF | 16-bit | Generalization |
| test3_1536×1440 | 93 | 1536×1440 | TIFF | 16-bit | Generalization |
Table 2.
Quantitative comparison on test1_2048×1440. Best values are shown in bold, and second-best values are underlined.
Table 2.
Quantitative comparison on test1_2048×1440. Best values are shown in bold, and second-best values are underlined.
| Method | NIQE↓ | PIQE↓ | BRISQUE↓ | Entropy↑ |
|---|---|---|---|---|
| Zero-DCE++ (TPAMI 2021) [9] | 7.4854 | 24.0223 | 43.1332 | 5.2962 |
| RUAS (CVPR 2021) [10] | 6.4797 | 46.0139 | 52.6413 | 5.8234 |
| SCI (CVPR 2022) [11] | 7.1531 | 22.8046 | 41.6851 | 4.5980 |
| CoLIE (ECCV 2024) [31] | 7.3754 | 21.0661 | 42.2756 | 5.1808 |
| ZeroIG (CVPR 2024) [13] | 6.6634 | 37.8086 | 54.0565 | 5.4621 |
| SCI++ (TPAMI 2025) [12] | 7.2950 | 26.5848 | 41.8575 | 5.0347 |
| Li et al. (ICLR 2025) [32] | 5.8307 | 18.0590 | 46.2133 | 5.5287 |
| Di-Retinex (IJCV 2025) [33] | 8.4895 | 28.3053 | 53.8734 | 3.6802 |
| WISE-Net (Our) | 5.5657 | 13.6800 | 43.2031 | 5.9167 |
Table 3.
Quantitative comparison on test2_4096×1440. Best values are shown in bold, and second-best values are underlined.
Table 3.
Quantitative comparison on test2_4096×1440. Best values are shown in bold, and second-best values are underlined.
| Method | NIQE↓ | PIQE↓ | BRISQUE↓ | Entropy↑ |
|---|---|---|---|---|
| Zero-DCE++ (TPAMI 2021) [9] | 7.6608 | 31.1089 | 43.2841 | 5.4586 |
| RUAS (CVPR 2021) [10] | 6.6339 | 37.9125 | 52.3296 | 5.6375 |
| SCI (CVPR 2022) [11] | 7.3265 | 24.3116 | 42.2891 | 4.7171 |
| CoLIE (ECCV 2024) [31] | 7.4923 | 22.9593 | 42.7686 | 5.2443 |
| ZeroIG (CVPR 2024) [13] | 6.8635 | 29.1717 | 53.6837 | 5.4854 |
| SCI++ (TPAMI 2025) [12] | 7.4810 | 30.5791 | 41.5197 | 5.0911 |
| Li et al. (ICLR 2025) [32] | 5.7755 | 14.6675 | 43.1569 | 5.5761 |
| Di-Retinex (IJCV 2025) [33] | 8.7859 | 20.6568 | 52.2714 | 3.7175 |
| WISE-Net (Our) | 5.6513 | 10.0385 | 42.0130 | 5.9698 |
Table 4.
Quantitative comparison on test3_1536×1440. Best values are shown in bold, and second-best values are underlined.
Table 4.
Quantitative comparison on test3_1536×1440. Best values are shown in bold, and second-best values are underlined.
| Method | NIQE↓ | PIQE↓ | BRISQUE↓ | Entropy↑ |
|---|---|---|---|---|
| Zero-DCE++ (TPAMI 2021) [9] | 7.2763 | 15.7598 | 37.5953 | 5.7655 |
| RUAS (CVPR 2021) [10] | 5.9977 | 46.4076 | 54.4205 | 6.3648 |
| SCI (CVPR 2022) [11] | 6.6631 | 20.2412 | 32.4015 | 5.4162 |
| CoLIE (ECCV 2024) [31] | 7.0021 | 17.4580 | 33.3426 | 5.7561 |
| ZeroIG (CVPR 2024) [13] | 5.9598 | 45.0477 | 52.1824 | 6.1888 |
| SCI++ (TPAMI 2025) [12] | 6.8288 | 21.3105 | 35.4894 | 5.7982 |
| Li et al. (ICLR 2025) [32] | 5.8545 | 20.8049 | 42.3929 | 6.2841 |
| Di-Retinex (IJCV 2025) [33] | 7.6053 | 36.7662 | 46.6907 | 4.5505 |
| WISE-Net (Our) | 5.0743 | 17.0166 | 36.4186 | 6.3746 |
Table 5.
Representative ablation results for the key components of WISE-Net on test1_2048×1440.
| Variant | NIQE↓ | PIQE↓ | BRISQUE↓ | Entropy↑ |
|---|---|---|---|---|
| Ours | 5.5657 | 13.6800 | 43.2031 | 5.9167 |
| Ours w/o | 7.1437 | 33.7723 | 51.6359 | 4.3044 |
| Ours w/o SBR | 6.3124 | 30.7389 | 47.1781 | 5.5287 |
| Ours w/o | 5.6443 | 28.8372 | 45.3539 | 5.5293 |
| Ours w/o | 5.4919 | 29.1536 | 44.8655 | 5.5199 |
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (http://creativecommons.org/licenses/by/4.0/).
Copyright: This open access article is published under a Creative Commons CC BY 4.0 license, which permit the free download, distribution, and reuse, provided that the author and preprint are cited in any reuse.