

Submitted:
27 August 2026
Posted:
28 August 2026
You are already at the latest version
Abstract
Multimodal remote sensing classification benefits from complementary spectral, structural, and elevation information. Convolutional neural networks (CNNs) have limited long-range modeling, whereas Transformers incur quadratic computational and memory costs. Although Mamba enables linear-complexity sequence modeling, multimodal Mamba methods usually fuse modalities before selective scanning, limiting the direct use of auxiliary information in parameter generation. We propose Cross-Modal Selective Scan (CM-S6), which uses lightweight projections to condition selective state-space parameters Δ, B, and C on auxiliary information. These parameters regulate state retention, information writing, and state readout, respectively. With input injection, output calibration, and five bounded learnable coefficients, CM-S6 forms an input-parameter-output fusion mechanism without increasing backbone width or depth. Across ten independent runs, CM-S6 achieves OA values of 96.16±0.18%, 91.91±0.49%, and 82.18±0.46% on Houston 2013, Augsburg, and MUUFL Gulfport, respectively, using fewer than 1 M parameters-1.8-2.9% of the strongest compared baselines. Paired tests detected no significant OA difference from the strongest baseline on any dataset, while CM-S6 showed significant OA gains over PICNet and MCAMamba/MTMixer on the respective datasets. CM-S6(L) retains parameter-level modulation, reduces model size to approximately 0.19 M parameters, and increases throughput by 3.86-5.82×, with a dataset-dependent accuracy trade-off. CM-S6 offers an alternative for multimodal fusion under resource constraints.
Keywords:
multimodal remote sensing fusion
; state space model
; selective scanning
; parameter-level cross-modal modulation
; remote sensing classification
1. Introduction
High-precision Earth observation increasingly benefits from the complementary information provided by multimodal remote sensing data. Hyperspectral imagery (HSI) records fine-grained spectral responses across continuous narrow bands, synthetic aperture radar (SAR) captures surface structure and scattering properties, and light detection and ranging (LiDAR) and digital surface models (DSMs) provide three-dimensional geometric information [1,2,3,4,5]. These modalities observe the same land-cover targets from different perspectives, but each is affected by modality-specific limitations. HSI can suffer from spectral confusion in mixed pixels or high-reflectance regions, SAR is sensitive to speckle noise and shadow effects, and LiDAR or DSM responses may become less reliable beneath vegetation canopies or over complex terrain. Multimodal remote sensing classification therefore needs to select and combine complementary evidence according to scene content and spatial context rather than simply aggregate the input modalities.
Existing multimodal remote sensing fusion methods mainly use CNN, Transformer, or Mamba backbones. CNNs are effective at extracting local spatial structures, but may require enlarged receptive fields or deeper operations to model long-range relationships. Transformers establish global token interactions through cross-attention; however, standard global self-attention has quadratic computational and memory scaling with sequence length. Mamba updates hidden states through selective scanning and makes the state-update process input-dependent, enabling long-range dependency modeling with linear scaling in sequence length. MambaHSI [6] and S²-Mamba [7] demonstrate SSM effectiveness for hyperspectral classification; HLMamba [8] and MCAMamba [9] extend SSMs to multisource classification. However, these methods fuse modalities before or outside selective scanning through concatenation, weighting, or attention so auxiliary information alters only the scan input and cannot separately influence state retention (Δ), input writing (B), or state readout (C). Strengthening such indirect interaction typically requires extra attention modules or larger capacity.
Selective SSMs generate token-dependent Δ, B, and C an internal interface that auxiliary information can exploit to influence state evolution directly. Standard S6 generates these parameters solely from the current-modality input, forcing auxiliary information to act indirectly through pre-fused features. We instead condition Δ, B, and C on co-registered auxiliary tokens, extending multimodal fusion from the representation layer to the parameter-generation layer of selective SSMs.
The key question is therefore how auxiliary modalities can move beyond indirect representation-level transmission and participate in distinct selective state-evolution functions while controlling model overhead. To address this question, we propose Cross-Modal Selective Scan (CM-S6): lightweight projections map auxiliary tokens into modulation signals for Δ, B, and C, complemented by cross-modal input injection (CII) before scanning and output calibration after scanning. Five bounded coefficients coordinate this input–parameter–output pathway. A lightweight variant, CM-S6(L), retains all modulation paths while simplifying scan branches for resource-constrained deployment, trading some classification accuracy for greater resource efficiency. Full CM-S6 and CM-S6(L) thus provide accuracy-oriented and efficiency-oriented configurations for different computational budgets.
The main contributions of this work are summarized as follows.
- We propose CM-S6, which conditions the Δ/B/C parameter-generation pathways of selective SSMs on auxiliary-modality signals via lightweight projections, enabling parameter-level cross-modal modulation without widening or deepening the backbone.
- We design the parameter-modulation mechanism with pathway-specific operations: multiplicative perturbation for Δ and additive corrections for B and C, preserving the primary-modality generation baseline while assigning auxiliary information distinct roles in state updating, input writing, and state readout.
- We integrate CII, Δ/B/C modulation, and output calibration into a three-stage mechanism coordinated by five bounded learnable coefficients. Ablations confirm that input/output modulation and internal parameter modulation are complementary, with dataset-dependent relative contributions.
- We develop CM-S6(L), which retains all five modulation paths at ~0.19 M parameters with 3.86–5.82× throughput, providing an efficiency-oriented counterpart to the accuracy-oriented full model.
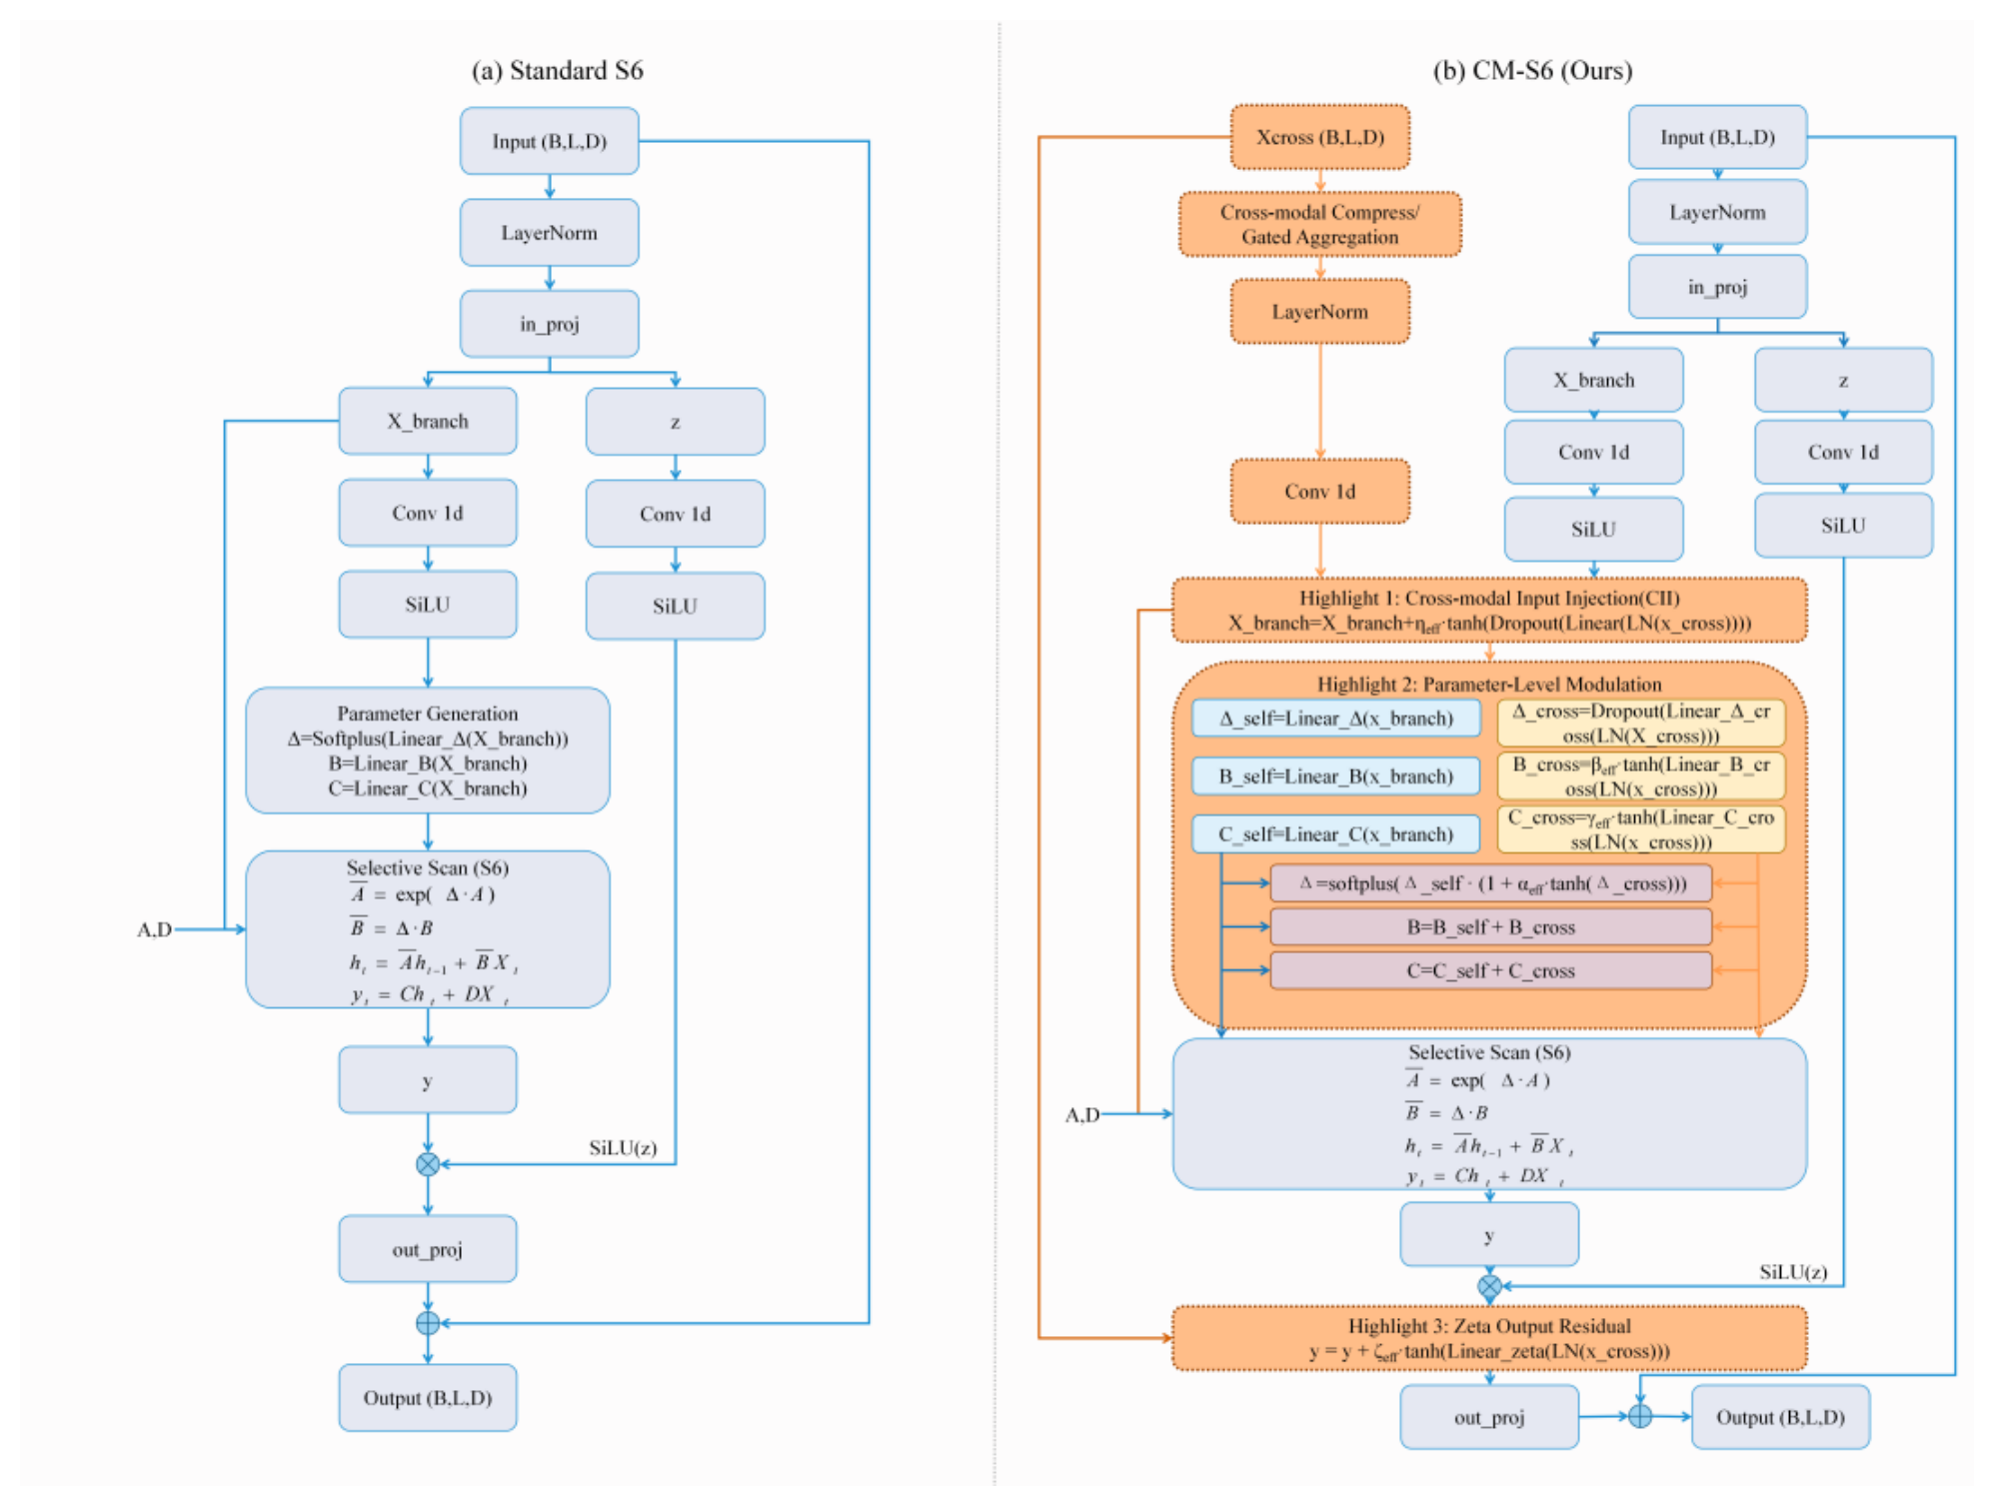
Figure 1.
Conceptual comparison between the standard S6 module and the proposed CM-S6 module.
2. Related Work
2.1. Multisource Remote Sensing Fusion Methods
The goal of multisource remote sensing fusion is to construct complementary representations across modalities. Early CNN-based methods integrated HSI, LiDAR, SAR, and DSM data through multibranch feature extraction, feature concatenation, gated weighting, or multiscale fusion [5,10]. Although effective at local modeling, their fixed receptive fields limit adaptation to modality-specific physical responses, and interaction is generally confined to feature concatenation or channel weighting. Transformers extend fusion to global token interactions [11,12]. MFT organizes modalities as parallel token streams and uses self-attention to model long-range dependencies and cross-modal relationships [13]. PICNet combines prototype-based information compensation with cross-modal feature interaction for joint HSI–LiDAR classification, effectively capturing local discriminative structures and class prototypes [14,15,16]. These methods improve global contextual modeling, but cross-attention and multibranch token processing increase computational and memory costs, while fusion still operates on formed feature representations. Mamba offers a linear-complexity alternative. MSFMamba uses multiscale feature fusion within an SSM backbone for multisource classification [17]. MambaHSI and S²-Mamba demonstrate the effectiveness of SSMs for spatial–spectral hyperspectral modeling [6,7], while HLMamba and MCAMamba extend Mamba to multisource classification [8,9]. MCAMamba achieves strong classification performance by using multilevel cross-modal attention to enhance modality complementarity, but retains feature-level interaction. MTMixer combines Mamba with Transformer/Mixer-style token processing to capture sequential and global dependencies at a relatively high parameter and storage cost [18]. Despite this progression, cross-modal interaction in existing Mamba methods operates at the feature or hidden-state level; the Δ/B/C parameter-generation pathways remain underexploited for cross-modal modulation.
2.2. State Space Models in Remote Sensing
State space models (SSMs) originate from continuous-time dynamical systems. S4 [19,20,21] and Mamba [22] establish structured and selective state-space modeling; Vision Mamba [23,24] extends SSMs to 2D features. In remote sensing, MambaHSI [6], S²-Mamba [7], SpectralMamba [25], and related methods validate SSMs for spatial–spectral classification. These methods treat SSMs as efficient backbones; Δ/B/C selectivity is driven by a single stream and has not been used as a cross-modal fusion interface. Rather than replacing the Mamba backbone, this work introduces auxiliary-modality signals into these parameter-generation pathways so that SSM selectivity participates directly in multisource fusion.
2.3. Taxonomy of Cross-Modal Fusion Paradigms
According to where cross-modal information enters the SSM, multimodal Mamba fusion methods can be categorized into feature-level, hidden-state-level, and parameter-level fusion, as illustrated in Figure 2. Feature-level fusion (e.g., HLMamba [8], MCAMamba [9]) combines modalities before scanning via concatenation or attention, leaving Δ/B/C driven by the fused input. Hidden-state-level fusion (e.g., Coupled Mamba [27], a visual-language model not directly comparable in our remote-sensing setting) couples intermediate states during recurrence but does not alter parameter generation. Parameter-level fusion our approach conditions Δ/B/C directly on auxiliary signals, changing how the SSM responds to each input rather than only changing its inputs or intermediate states. Appendix A discusses this distinction from a function-space perspective.
2.4. Granularity of Cross-Modal Interaction
Cross-modal fusion can also be compared according to the processing stage and granularity at which auxiliary information affects a model. Logit-level methods such as TMC and Evidential Deep Learning combine modalities at the network output through evidence distributions or confidence weighting [28,29]. Because they operate on final class probabilities, they provide limited access to intermediate state processing. Dynamic, conflict-aware, and uncertainty-aware multimodal methods further adapt output- or representation-level interaction to cross-modal discrepancies [30,31,32]. Feature-level methods use cross-attention, token weighting, or channel recalibration to modify formed representations. MFT, for example, establishes fine-grained cross-modal relationships through token interaction [13]. These mechanisms provide local feature adaptation but do not explicitly distinguish how auxiliary information affects state updating, information writing, and state readout. Parameter-level interaction instead conditions the generation of Δ, B, and C. CM-S6 uses this interface to assign auxiliary information to the three state-space functions while complementing internal parameter modulation with input injection and output calibration.
3. Methods
CM-S6 assumes co-registered multimodal inputs. Registration, resampling, and cropping place observations of the same ground location at consistent tensor coordinates across modalities. After lightweight modality-specific encoding, the resulting two-dimensional feature maps are unfolded under the same deterministic scan order, so primary- and auxiliary-modality tokens at a common sequence index retain their spatial correspondence, as expressed in (1).
Here, and denote the primary- and auxiliary-modality tokens at the t-th scan position, respectively, and p(t) denotes the corresponding two-dimensional coordinate. The shared ordering does not by itself align the semantic distributions of different modalities, but it preserves the position-wise correspondence required for cross-modal conditioning. On this basis, CM-S6 conditions the Δ/B/C parameter-generation pathways on auxiliary signals, as detailed below.
3.1. The Selective State Space Model and Cross-Modal Parameter Generation
A state space model represents a continuous-time sequence as the input-driven evolution of a hidden state. Given an input x(t), hidden state h(t), and output y(t), its continuous form is given in (2):
Here, A governs the intrinsic evolution of the hidden state, B controls how the input is written into the state space, and C controls how the hidden state is read out. S4 improves long-sequence modeling through structured parameterization and discretization. Mamba further introduces selectivity by making B, C, and the discretization step Δ dynamic functions of the current input token, as shown in (3):
Zero-order-hold discretization gives (4), and the resulting discrete recurrence is defined in (5):
Equations (2)–(5) show that S6 is an input-adaptive recurrence: Δ, B, and C jointly control state retention, input writing, and state readout at each token position. In standard S6, Δ/B/C are generated solely from the primary input. CM-S6 instead conditions them on co-registered auxiliary tokens (Section 3.3), enabling parameter-level cross-modal modulation.
3.2. Overall Design of CM-S6
CM-S6 takes a pair of aligned modality sequences as input. Let the primary-modality sequence be , with , and the auxiliary-modality sequence be , with . The two sequences are generated by separate lightweight encoding branches and unfolded under the same scan order, producing one-dimensional sequences of equal length. CM-S6 outputs an enhanced sequence from the primary-modality perspective, , where . The primary modality provides the main stream for state-space modeling, while the auxiliary modality modulates input injection, parameter generation, and output calibration. These roles are not permanently assigned to particular sensors. Depending on the network topology, HSI, LiDAR, SAR, or DSM may serve as the primary or auxiliary modality in different modules, enabling alternating modulation in dual- or tri-modal configurations. Cross-modal information enters through five paths: CII (η) before the SSM, Δ/B/C modulation (α/β/γ) inside parameter generation, and output calibration (ζ) after the SSM. These form a three-stage input–parameter–output chain; Figure 3 shows the overall CM-S6 architecture, and Section 3.3 details the corresponding operations.
3.3. The Five-Coefficient Cross-Modal Modulation Mechanism
Building on the primary–auxiliary interaction framework above, this section specifies where the five learnable scalar coefficients act during the CM-S6 forward pass. Let, denote the primary- and auxiliary-modality features at position t, respectively, where D is the channel dimension. The symboldenotes the primary feature after cross-modal input injection, anddenotes the primary-modality output of CM-S6. The coefficients η, α, β, γ, and ζ control input injection, step-size modulation, input-writing modulation, state-readout modulation, and output calibration, respectively.
- Cross-Modal Input Injection: CII acts on the primary-modality stream before the SSM parameter-generation functions are evaluated, as defined in (6):
Here, Wᵢₙ is a lightweight linear projection that aligns the auxiliary feature with the primary channel dimension, and tanh bounds the injected response. Equation (6) preserves the original primary input and adds a bounded correction, so the subsequent Δ, B, and C generation functions operate on the cross-modally calibrated feature . The projected auxiliary response determines token- and channel-specific variations, whereas η controls the overall strength of the injection path. A more discriminative auxiliary response produces a stronger bounded correction, while an uninformative response produces a weaker adjustment.
- Step-Size Modulation: The Δ path applies a multiplicative perturbation to the discretization step. The primary branch produces the original step-size signal Δself through a linear projection of
, while LayerNorm and a separate projection of produce the cross-modal perturbation Δcross, as defined in (7):
The modulated step is obtained by applying softplus to the multiplicatively adjusted signal, as defined in (8):
This multiplicative form adjusts the relative scale of the primary step-size signal before softplus while retaining a positive output step. The factor 1 + α·tanh(Δcross) provides an upward or downward adjustment relative to the primary-modality baseline. Because Δ controls the discretization timescale, this path allows auxiliary features to alter the relative balance between integrating the current input and retaining historical state information.
- 3.
- Input-Writing Matrix Modulation: The B path applies an additive cross-modal perturbation to the B generation function, as defined in (9):
Here, Bself is generated from the pre-aligned sequence produced by (6) through the original input-dependent function of S6. The additive formulation preserves the primary-modality component Bself while introducing a separate cross-modal writing component. Because B determines how input dimensions are written into the hidden state, (9) allows auxiliary information to condition the writing pattern at each token position.
- 4.
- State-Readout Matrix Modulation: The C path adopts an additive structure symmetric to that of B, as defined in (10):
C specifies the channel weights used to read the hidden state in . Equation (9) regulates how information is written, whereas (10) regulates how it is read out. The two paths therefore modulate the input and output sides of state-space information flow.
- 5.
- Output-Level Residual Calibration: The ζ path is the most downstream of the five modulation paths and is defined in (11):
Unlike CII and the Δ/B/C paths, which intervene in parameter generation or state evolution, ζ adds a projected auxiliary response after the selective scan. It provides an output-side correction when auxiliary semantics are not fully retained through the recurrent state representation. This path complements, rather than replaces, the internal parameter-level modulation.
- 6.
- Coordination of the Five Coefficients: Equations (6)–(11) implement the three-stage chain: (6) input injection; (7)–(10) Δ/B/C parameter modulation; (11) output calibration. This grouping directly corresponds to the ablation design in Section 4.3. The bounded reparameterization is defined in (12), and Algorithm 1 summarizes the full forward pass.
| Algorithm 1. CM-S6 Forward Pass for One Layer. |
| Input: Primary modality Auxiliary modality Learnable scalars α, β, γ, η, ζ with bounds αmax, βmax, γmax, ηmax, ζmax pretrained SSM parameters A, D Output: Primary modality output |
| 1: Stage 0: Reparameterize five coefficients 2: for ρ in {α, β, γ, η, ζ} do4: end for |
| 5: Stage 1: Cross-Modal Input Injection |
| 7: Stage 2: Generate Δ, B, C with cross-modal modulation 8: Δself ← Wdt · x̃ |
| 13: Stage 3: Selective scan (ZOH discretization inside) 14: y ← SelectiveScan(x̃M, Δ, A, B, C, D) |
| 15: Stage 4: Output-level Zeta residual |
| 17: Module-level residual |
3.4. Adaptive Modulation Strength
If the five learnable scalars α, β, γ, η, and ζ are used without constraints, their magnitudes may continue to increase during training and cause the cross-modal pathways to overwhelm the primary-modality stream. This risk is particularly relevant during early training, when stable correspondence between primary- and auxiliary-modality representations has not yet formed. CM-S6 therefore applies bounded reparameterization, combining a tanh mapping with interval clipping, as defined in (12):
Here, ρ̂ denotes the underlying learnable real-valued variable. The tanh mapping provides a smooth bounded response over its active range, while explicit clipping enforces the prescribed upper limit. The coefficient bounds are set to αmax = 0.50, βmax = 0.70, γmax = 0.70, ηmax = 0.50, and ζmax = 0.30 according to the numerical sensitivity and intended role of each path. Because Δ directly affects the exponential discretization term, αmax = 0.50 keeps the multiplicative factor Δperturb within [0.5, 1.5], providing a positive relative adjustment around the primary-modality baseline. B and C enter the state equations through additive linear terms and are assigned the less restrictive bounds βmax = γmax = 0.70. CII acts before the SSM, so ηmax = 0.50 limits the extent to which input injection can alter the primary representation. The output calibration path is auxiliary rather than the principal information route, and ζmax is therefore set to 0.30. These bounds prevent any single path from dominating the primary stream. Section 4.5 analyzes the resulting coefficient distributions and stability.
3.5. Model Variants
We construct full CM-S6 and the lightweight CM-S6(L) from the same CM-S6 module and extend the topology to the HSI, SAR, and DSM inputs of Augsburg. All configurations preserve the five-coefficient mechanism defined in Section 3.3; they differ mainly in scan direction, the number of CM-S6 blocks, and the topology of modality interaction. The tri-modal topology expands the number of auxiliary modalities and is not treated as a separate capacity level. Full CM-S6 uses bidirectional scanning. For the dual-modal Houston 2013 and MUUFL tasks, HSI and LiDAR are first mapped into a D-dimensional feature space by separate convolutional embeddings and flattened into sequences with the same token order. Within each layer, the HSI branch is first updated with HSI as the primary modality and LiDAR as the auxiliary modality. The updated HSI representation then modulates the LiDAR branch. The backward branch applies the same chain interaction to reversed token sequences and restores the original order after scanning. This process yields four outputs: forward HSI, backward HSI, forward LiDAR, and backward LiDAR. Learnable weights are normalized by softmax to combine the four sequences, after which global average pooling and a classification head produce the prediction. The chain structure places each modality in both a primary update path and an auxiliary modulation path, yielding bidirectional, alternating cross-modal state updates. Augsburg contains HSI, SAR, and DSM inputs. Each modality serves as the primary stream of its own CM-S6 stack. The HSI stream receives a unified auxiliary signal obtained by attention-gated aggregation of SAR and DSM, while the SAR and DSM streams each receive the modulated HSI representation as their auxiliary signal. The aggregation is defined in (13):
Here, x̄ denotes global mean pooling over the token dimension for each modality sequence, and x̃ denotes an auxiliary token sequence after lightweight compression projection. The aggregated auxiliary signal enters the five-coefficient modulation paths in (6)–(11). The forward and backward outputs of the three modality streams form six sequences. They are combined using softmax-normalized learnable weights and then passed through global average pooling and the classification head. CM-S6(L) retains one forward CM-S6 block and removes both backward scanning and the independent auxiliary-modality output branch. HSI is used as the primary modality, while LiDAR for Houston 2013 and MUUFL, or SAR and DSM for Augsburg, provides the auxiliary input. When multiple auxiliary modalities are available, they are aggregated using (13). The CM-S6 output is passed directly to global average pooling and the classification head. This simplification changes only the scan branches and number of CM-S6 blocks; it preserves the CII, Δ/B/C, and ζ modulation paths.
Figure 4 presents the overall architectures of the full dual- and tri-modal models. CM-S6(L) uses the same modality embeddings and auxiliary-modality aggregation but simplifies the scan structure as described above and is therefore not drawn separately. Appendix A further discusses the conceptual distinction between parameter-generation-pathway modulation and data-level fusion from a function-space perspective.
4. Experiments and Discussion
4.1. Datasets and Implementation Details
We evaluate CM-S6 on three public multisource remote sensing datasets: Houston 2013, Augsburg, and MUUFL Gulfport. These datasets represent two multimodal classification settings: dual-modal HSI–LiDAR fusion and tri-modal HSI–SAR–DSM fusion. Their different modality combinations, class distributions, and training-set sizes allow CM-S6 to be evaluated under several limited-label conditions.
Houston 2013 was released for the 2013 IEEE GRSS Data Fusion Contest [33]. It contains HSI and single-channel LiDAR elevation data covering 349 × 1905 pixels and 15 land-cover classes. The original HSI contains 144 bands. After removing four noisy bands from each end of the spectrum, the remaining 136 bands are normalized using band-wise min–max scaling and reduced to 20 principal components. The LiDAR data are independently normalized using min–max scaling. The available label maps are combined, after which 20 labeled center pixels per class are randomly selected for training, resulting in 300 training samples; all remaining labeled centers are used for testing. The split is generated using a fixed random seed of 42. An 11 × 11 neighborhood centered on each labeled pixel is extracted as the input patch.
The Augsburg dataset contains HSI, SAR, and DSM data with a spatial size of 332 x 485 pixels and seven land-cover classes [34]. The 180-band HSI is normalized band-wise and reduced to 20 principal components. The SAR data contain four polarization channels, whereas the DSM is single-channel. To reduce the influence of extreme scattering values, each SAR channel is clipped at its 1st and 99th percentiles and subsequently normalized. The DSM is normalized using min–max scaling. We use the training and test label masks supplied with the dataset, which contain 761 and 77,533 labeled pixels, respectively. The input patch size is 11 × 11.
MUUFL Gulfport comprises HSI and two-channel LiDAR data with a spatial size of 325 x 220 pixels, 11 land-cover classes, and 53,687 labeled pixels [35,36]. The original HSI contains 72 bands. After removing eight noisy bands, the remaining 64 bands are normalized band-wise and reduced to 20 principal components. The two LiDAR channels are independently normalized using min–max scaling. The available training and test label maps are combined, after which 20 labeled center pixels per class are randomly selected for training using a fixed seed of 42. This produces 220 training samples, while the remaining 53,467 labeled centers are used for testing. The input patch size is 11 × 11.
For all three datasets, normalization parameters, SAR percentile thresholds, and PCA transformations are estimated once from all spatial pixels in the complete co-registered scene before patch extraction. No class labels are used in estimating these preprocessing parameters. Accordingly, the experiments follow the full-scene transductive preprocessing convention commonly used in hyperspectral image classification. Training and test center pixels are mutually exclusive under the adopted splits.
All three datasets follow a common training pipeline. We use AdamW with an initial learning rate of 5 × 10⁻⁴ and a weight decay of 1 × 10⁻⁴ [37]. The batch sizes are 64, 32, and 64 for Houston 2013, Augsburg, and MUUFL, respectively, and all models are trained for 100 epochs. During each run, the test split was excluded from gradient-based optimization and loss computation. For the benchmark results, however, the model was evaluated on the test split after each epoch, and the checkpoint with the highest test OA was retained for reporting. This epoch-wise checkpoint-selection rule was applied identically to CM-S6, CM-S6(L), and all comparison methods. The objective function is class-weighted cross-entropy with label smoothing of 0.1. Following a 10-epoch linear warm-up, the learning rate is reduced to 1 × 10⁻⁶ using cosine annealing, and the gradient norm is clipped at 1.0. For CM-S6 and CM-S6(L), the learning rate assigned to the five learnable modulation scalars is ten times the base learning rate, whereas all other parameters use the base rate. Random horizontal and vertical flips are applied synchronously across modalities, and automatic mixed-precision training is used.
Performance is evaluated using overall accuracy (OA), average accuracy (AA), and the Kappa coefficient. Based on their competitiveness and architectural relevance, MTMixer, MCAMamba, and PICNet are selected for detailed repeated-run comparisons with CM-S6 and CM-S6(L). These five methods are evaluated over ten repeated training runs using aligned random seeds 42–51. This protocol provides run-level observations for estimating the mean, standard deviation, performance variability, and paired statistical differences. The remaining comparison methods are reported using five-run results. The progressive, single-path-removal, and pathway ablations are each repeated five times using seeds 42–46. Unless otherwise stated, repeated-run results are reported as the mean ± standard deviation. All experiments are conducted on a single NVIDIA GeForce RTX 4090 GPU.
4.2. Comparison with Representative Baselines
To systematically evaluate the classification performance of CM-S6, we compare it with eight representative public methods: the single-modal Mamba methods MambaHSI and S²-Mamba [6,7]; the single-modal Transformer method DSFormer [38]; the multimodal Transformer methods MFT and PICNet [13,14]; the Transformer–Mamba hybrid method MTMixer [18]; and the multimodal Mamba methods HLMamba and MCAMamba [8,9]. To ensure a controlled comparison, all methods are trained and evaluated under the same data protocol as CM-S6. Specifically, they use identical training and test partitions, scene-level preprocessing, modality registration, 11 × 11 patch extraction, data augmentation, and evaluation procedures; no method is assigned an additional or method-specific data split. For single-modal baselines, only the HSI component of the corresponding patch is used, whereas multimodal baselines receive the registered auxiliary modalities required by their respective architectures. Therefore, the compared methods use the same sample centers and labels, and the performance differences primarily reflect their model designs. Results on the three datasets are reported in Table 1, Table 2 and Table 3, respectively.
4.2.1. Classification on Houston 2013
The quantitative results on Houston 2013 are reported in Table 1. Over ten independent runs, CM-S6 achieves OA, AA, and Kappa values of 96.16% ± 0.18%, 96.53% ± 0.18%, and 95.85% ± 0.20%, respectively. Its OA differs from that of MCAMamba, 96.21% ± 0.19%, by only 0.052 percentage points, and the paired tests detect no significant difference in OA or Kappa. CM-S6 achieves an AA that is 0.290 percentage points higher than that of MCAMamba, with a statistically significant difference (p = 0.0175), indicating a more balanced class-wise performance. Relative to MTMixer and PICNet, CM-S6 improves OA by 0.929 and 3.447 percentage points, respectively. The complete performance differences, 95% confidence intervals, and paired-test p-values are listed in Table 4.
CM-S6 maintains a small model size while achieving OA and Kappa values for which no statistically significant difference from MCAMamba is detected. Its parameter count is 0.6628M, corresponding to only 2.89% of the 22.9293M parameters of MCAMamba, while the two methods obtain closely matched OA and Kappa values. CM-S6(L) further reduces the parameter count to 0.1879M, a 71.65% reduction relative to the full model, while retaining an OA of 95.60±0.25%. This value is higher than the corresponding OA values of MTMixer, MFT, HLMamba, and PICNet, but is 0.555 percentage points lower than that of full CM-S6, showing the accuracy-model-size trade-off of the lightweight structure. FLOPs, inference latency, and throughput are analyzed jointly in the computational-efficiency analysis below. The class-wise results show that CM-S6 achieves the highest accuracies for Healthy Grass and Residential, at 97.57% and 99.93%, respectively, and reaches 100% on Soil, Tennis Court, and Running Track. CM-S6 does not win every class (e.g., Commercial and Parking Lot 1 are lower than MCAMamba); its gain lies in more balanced class-wise performance, consistent with the significantly higher AA. Class names are listed in Appendix B. Figure 5 presents representative classification results. Compared with several baselines, CM-S6 produces more spatially continuous predictions over grass, residential areas, and small-scale objects, although local confusion remains around commercial areas and parking-lot boundaries. This qualitative pattern is consistent with the class-wise quantitative results.
4.2.2. Classification on Augsburg
Augsburg is the most complex of the three experimental datasets in terms of modality composition and has the lowest proportion of training samples. HSI, SAR, and DSM exhibit clear representational differences, and the training-to-test sample ratio is approximately 1:102. These characteristics impose stringent requirements on few-shot learning and the stability of multimodal fusion. The classification results are reported in Table 2. Over ten independent runs, CM-S6 achieves OA, AA, and Kappa values of 91.91±0.49%, 68.35±1.75%, and 88.40±0.71%, respectively. The corresponding results of MTMixer are 91.93±0.44%, 70.17±2.28%, and 88.44±0.64%, exceeding CM-S6 by 0.026, 1.819, and 0.041 percentage points, respectively. The paired t-test yields p-values of 0.914, 0.110, and 0.904 for OA, AA, and Kappa, respectively. None reaches the 0.05 significance level; therefore, no statistically significant difference between CM-S6 and MTMixer is detected on Augsburg. CM-S6 nevertheless improves OA over MCAMamba and PICNet by 0.748 and 1.406 percentage points, respectively. The complete performance differences, 95% confidence intervals, and paired-test p-values are reported in Table 4.
In terms of model size, CM-S6 contains only 0.9823M parameters, approximately 2.74% of the parameter count of MTMixer. It therefore reduces the parameter count by approximately 97.26%, while no statistically significant difference in OA or Kappa is detected between the two methods. CM-S6(L) further reduces the parameter count to 0.1909M, an 80.57% reduction relative to the full model. Its OA is 89.65±0.51%, higher than those of DSFormer and MFT but 2.256 percentage points lower than that of CM-S6. Thus, CM-S6(L) provides more pronounced compression in the tri-modal setting with a corresponding accuracy cost. The class-wise results also reveal substantial variation among categories in Augsburg. CM-S6 achieves the highest accuracy on Low Plants, at 95.90±0.81%, and reaches 97.44±0.59% on Residential Area. Its accuracy on Water is 39.27±7.41%, lower than those of MCAMamba, PICNet, and MTMixer, while the results for Industrial Area and Commercial Area also show considerable variation. Class-wise gains vary with training-sample size, class separability, and modality complementarity; no single modulation path can be isolated as the sole driver for a given class. Class names are in Appendix B. Figure 6 presents the classification results. CM-S6 preserves spatial continuity in major land-cover regions, but local confusion remains around industrial areas, commercial areas, and water boundaries, consistent with the class-wise quantitative results.
4.2.3. Classification on MUUFL Gulfport
MUUFL consists of HSI and two-channel LiDAR data. Only 20 labeled pixels per class are selected for training, resulting in 220 training samples, whereas the test set contains 53,467 samples. The large test set and limited training set increase the difficulty of modeling within-class variation and exploiting cross-modal information. The quantitative results are reported in Table 3. Over ten independent runs, CM-S6 achieves OA, AA, and Kappa values of 82.18±0.46%, 80.98±0.89%, and 77.15±0.58%, respectively. Its OA and Kappa are the highest mean values in the table. The corresponding results of MTMixer are 81.71±1.49%, 82.34±3.62%, and 76.73±1.76%. CM-S6 exceeds MTMixer by 0.464 and 0.417 percentage points in OA and Kappa, respectively, but has an AA that is 1.360 percentage points lower. The paired t-test yields p-values of 0.362, 0.283, and 0.482 for OA, AA, and Kappa, respectively. None reaches the 0.05 significance level; therefore, no statistically significant difference between CM-S6 and MTMixer is detected on MUUFL. Relative to MCAMamba and PICNet, CM-S6 improves OA by 2.111 and 3.076 percentage points, respectively. The complete performance differences, 95% confidence intervals, and paired-test p-values are reported in Table 4.
CM-S6 contains 0.6632M parameters, only 1.84% of the parameter count of MTMixer. It therefore achieves higher mean OA and Kappa values while reducing the parameter count by approximately 98.16%. CM-S6(L) further reduces the parameter count to 0.1884M, a 71.59% reduction relative to the full model. Its OA is 80.29±0.54%, which is 0.223 and 1.187 percentage points higher than those of MCAMamba and PICNet, respectively, but 1.425 and 1.888 percentage points lower than those of MTMixer and full CM-S6. These results further illustrate the trade-off between parameter size and classification performance in the lightweight model. The class-wise results show that CM-S6 achieves the highest accuracy on Trees, at 86.03±1.59%, and reaches 94.92±1.16% on Building and 99.98±0.07% on Water. Its accuracies on Mostly Grass, Sidewalk, and Yellow Curb are 60.28±4.93%, 50.81±4.27%, and 66.99±7.68%, respectively, and remain below those of some baselines. The overall accuracy of CM-S6 is primarily supported by its strong recognition of Trees, Building, and Water, whereas classes with similar spectral responses, ambiguous spatial boundaries, or complex land-cover composition remain challenging. The detailed correspondence between class indices and class names is provided in Appendix B. Figure 7 presents the MUUFL classification results. The prediction maps of PICNet, MTMixer, and MCAMamba contain varying degrees of stripe-like noise or locally scattered misclassification, whereas CM-S6 and CM-S6(L) produce more continuous spatial distributions over major land-cover regions such as trees, buildings, and roads. Local confusion remains around the boundaries of grass, mixed ground surface, and sidewalks, consistent with the class-wise accuracy results.
4.2.4. Statistical Significance Analysis
To assess performance differences quantitatively, we perform two-sided paired t-tests between CM-S6 and PICNet, MTMixer, and MCAMamba using the ten independent runs aligned by random seeds 42-51. Because three model comparisons are conducted for each dataset, p-values are adjusted using the Holm procedure to control the accumulation of Type I error associated with multiple testing. Table 4 reports OA differences, 95% confidence intervals, and significance-test results for CM-S6 relative to each comparison method; a positive difference indicates higher OA for CM-S6.
On Houston 2013, the OA difference between CM-S6 and MCAMamba is -0.052 percentage points. Its 95% confidence interval crosses zero, and the Holm-adjusted p-value is 0.4876; thus, the test detects no significant difference. CM-S6 improves OA over MTMixer and PICNet by 0.929 and 3.447 percentage points, respectively, with adjusted p-values below 0.001, indicating statistically significant differences. On Augsburg, the OA difference between CM-S6 and MTMixer is only -0.026 percentage points and is not significant. CM-S6 improves OA over MCAMamba and PICNet by 0.748 and 1.406 percentage points, respectively, and both differences remain significant after Holm correction. On MUUFL, CM-S6 improves OA over MTMixer by 0.464 percentage points, but the confidence interval crosses zero and the difference is not significant. Its OA improvements over MCAMamba and PICNet are 2.111 and 3.076 percentage points, respectively, and both differences are statistically significant. For the strongest high-capacity comparison method on each dataset, the paired OA test does not detect a statistically significant difference from CM-S6. CM-S6 also shows statistically significant OA advantages over the other strong baselines considered above. Combined with the parameter counts in Table 1, Table 2 and Table 3, these results indicate that the competitive classification performance of CM-S6 is achieved without expanding model capacity.
4.3. Ablation Study
To identify the sources of the performance gains of CM-S6, we construct an A0-A14 ablation sequence under a unified capacity setting of D = 96 and n_layers = 1. A0 and A1 represent Single-S6 and CatFuse-S6, respectively. A2-A6 progressively introduce η, α, β, γ, and ζ. A7-A11 remove one modulation path at a time from the full model, A12 and A13 retain only CII+ζ and Δ/B/C, respectively, and A14 is the lightweight variant. A0, A1, A6, and A14 are repeated ten times with seeds 42-51, whereas the remaining configurations are repeated five times with seeds 42-46. The complete results are reported in Table 5(a)-5(c), and Figure 8 summarizes the progressive and pathway ablations A0-A13. A14 is analyzed separately as a capacity-accuracy trade-off.
The overall results show that introducing multimodal information can improve classification, but the fusion location affects how effectively complementarity is used. CatFuse-S6 outperforms Single-S6 on all three datasets, indicating that the auxiliary modality can provide useful information for primary-modality discrimination. Full CM-S6 further improves OA over CatFuse-S6 by 0.724, 1.306, and 2.429 percentage points on Houston 2013, Augsburg, and MUUFL, respectively, and all paired comparisons remain significant after Holm correction. Input-level concatenation changes the joint representation entering the backbone, whereas CM-S6 additionally allows the auxiliary modality to participate in state updating, input writing, and state readout. The larger gains on Augsburg and MUUFL are consistent with the more limited training samples and stronger modality differences in these datasets.
As visualized in Figure 8(a)-8(c), the progressive ablation results show that η-controlled input injection provides the first gain in the progressive cross-modal sequence. Relative to A0, A2 improves OA by 1.361, 3.092, and 2.450 percentage points on Houston 2013, Augsburg, and MUUFL, respectively, indicating that establishing a primary-auxiliary relationship before state-space recurrence can improve subsequent sequence modeling. Adding α, β, and γ is non-monotonic: some intermediate configurations dip before recovering. This indicates that Δ/B/C are coupled pathways—the marginal effect of each depends on the presence of the others—rather than independent additive modules. Figure 8(d)-8(f) plots the OA difference between full A6 and each A7-A13 variant, such that a positive bar indicates higher OA for the full model. The three datasets exhibit different sensitivities to single-path removal. On Houston 2013, the OA values of all removal configurations fall within 96.06%-96.17%, and none of the differences is significant. This pattern is consistent with its strong single-modal baseline: HSI already provides substantial spectral discrimination, leaving limited measurable marginal contributions for LiDAR near the accuracy ceiling. On Augsburg, removing η or γ produces clearer mean decreases, but the effects remain trends after correction for multiple comparisons. This pattern may reflect the more complex complementarity among HSI, SAR, and DSM, for which other paths can partly compensate for the loss of one path. MUUFL is more sensitive to η: removing this path decreases OA by 1.152 percentage points, and the difference remains significant after Holm correction (p = 0.0053). This result indicates that input-side injection makes a measurable contribution to relating spectral information to spatial-structural information in the HSI-LiDAR setting of MUUFL.
A12 (CII+ζ only) and A13 (Δ/B/C only) isolate the two pathway groups. Critically, A13 outperforms A1 (CatFuse-S6, feature-level concatenation) by 0.66, 0.88, and 1.95 percentage points on Houston 2013, Augsburg, and MUUFL, respectively, and outperforms A0 (Single-S6) by 1.29–3.10 points. This demonstrates that parameter-level modulation alone—without any input/output injection—can independently exploit auxiliary information and surpass conventional feature-level fusion. Both A12 and A13 exceed the single-modal baseline on all datasets, confirming that the two groups are independently effective. On Houston 2013, neither differs significantly from the full model (high-accuracy ceiling effect). On MUUFL, A13 (81.70%) is closer to the full model (82.18%) than A12 (81.22%), consistent with a stronger role for internal parameter generation when spectral–structural complementarity is high. Across datasets, neither pathway group dominates universally; their relative contributions depend on sensor composition and class structure, and the full model achieves the best or near-best balance on all three datasets.
The lightweight variant further reveals the trade-off between model capacity and cross-modal discriminative ability. CM-S6(L) reduces the parameter count by 71.59%-80.57% across the three datasets, while its OA decreases by 0.555-2.256 percentage points; all corresponding differences are statistically significant. The accuracy decrease is smaller on Houston 2013 and more pronounced on Augsburg and MUUFL, indicating that complex modality combinations and limited training samples place greater demands on representation capacity. CM-S6(L) should therefore be viewed as an accuracy-efficiency trade-off for resource-constrained scenarios rather than a lossless replacement for the full model. The associated computational costs are discussed further in the following efficiency analysis. A0, A1, A6, and A14 use aligned-seed paired tests (10 runs); A6 vs. five-run ablation configurations use Welch approximation with Holm correction. Because the ablation configurations use only five runs, pathway-level conclusions should be interpreted as trends rather than definitive independent-effect estimates.
4.4. Computational Efficiency and Model Size
To evaluate the trade-off between classification accuracy and resource cost, we compare eight baseline methods with CM-S6 and CM-S6(L) in terms of parameter count, FLOPs, inference latency, throughput, and peak memory under a unified environment. All measurements are obtained on an NVIDIA GeForce RTX 4090 using PyTorch 2.1.2, CUDA 12.1, and FP32. Latency is measured with a batch size of 1 after 50 warm-up iterations and over 200 timed repetitions, whereas throughput is measured with a batch size of 16 after 30 warm-up iterations and over 100 repetitions. All three datasets use 11 x 11 input patches. FLOPs are approximated as twice the number of multiply-accumulate operations. Because custom selective-scan operators can introduce bias into theoretical operation counts, FLOPs and measured latency are analyzed separately. To ensure that accuracy and cost refer to the same model instance, Table 6 and Figure 9 use the OA of the checkpoint selected for efficiency evaluation. The multi-run means in Table 1, Table 2 and Table 3 remain the basis for classification-performance and significance conclusions.
Table 6(a) shows that full CM-S6 contains fewer than 1M parameters on all three datasets and achieves the highest selected-checkpoint OA under this efficiency-evaluation protocol. On Houston 2013, its parameter count is only 2.89% of that of MCAMamba, and its OA is 0.319 percentage points higher, although its FLOPs and latency are 18.0% and 20.8% higher, respectively. On Augsburg, the parameter count and FLOPs of CM-S6 are 2.77% and 16.74% of those of MTMixer, respectively, and its OA is 1.438 percentage points higher; however, its latency is approximately 10.05 times that of MTMixer. Together with Table 6(b), these results show that parameter count, FLOPs, and measured speed are not monotonically related. MFT has the lowest FLOPs and latency and the highest throughput on all three datasets, but its accuracy is lower than that of the CM-S6 variants. The main advantage of full CM-S6 is therefore parameter efficiency at high accuracy rather than uniformly superior runtime performance.
Table 6(c) shows that CM-S6(L) exchanges a small decrease in selected-checkpoint OA for substantial parameter compression and runtime acceleration. Its parameter count remains approximately 0.19M across the three datasets. On the Augsburg and MUUFL efficiency-evaluation checkpoints, it achieves higher OA than all external baselines, supporting its intended use in resource-constrained deployment. The reduction in peak memory is smaller than the reductions in parameter count and FLOPs, indicating that memory consumption for the current 11 x 11 inputs is also affected by intermediate activations and framework overhead.
Figure 9 consolidates six accuracy-efficiency views. In Figure 9(a)-9(c), FLOPs are plotted on the horizontal axis and OA on the vertical axis, with bubble area representing parameter count. The corresponding Pareto frontiers comprise MFT, CM-S6(L), MCAMamba, and CM-S6 on Houston 2013, and MFT, CM-S6(L), and CM-S6 on both Augsburg and MUUFL. In Figure 9(d)-9(f), measured latency is plotted against OA, with bubble area representing peak memory. The corresponding frontiers comprise MFT, CM-S6(L), MCAMamba, and CM-S6 on Houston 2013; MFT, MTMixer, CM-S6(L), and CM-S6 on Augsburg; and MFT, DSFormer, CM-S6(L), and CM-S6 on MUUFL. CM-S6(L) lies on the frontier in all six views, whereas full CM-S6 forms the highest-accuracy endpoint, consistent with their resource-trade-off and accuracy-oriented roles, respectively. Each Pareto frontier is computed using only the horizontal and vertical metrics; the third metric encoded by bubble area is provided for auxiliary comparison and does not enter the two-dimensional nondominance calculation.
4.5. Analysis of Learnable Modulation Coefficients
We now examine the five modulation coefficients to characterize how CM-S6 allocates cross-modal control. Recall that η/ζ govern input/output calibration and α/β/γ govern Δ/B/C generation; all are global scalars whose token- and channel-specific variation comes from the auxiliary projections. We note that these coefficients reflect pathway-level activation, not per-token sensor reliability or physical sensor quality.
We track full CM-S6 and CM-S6(L) for 100 epochs on each dataset using run 1 and seed 42, with a coefficient learning rate ten times the base rate. Full-model curves average the effective coefficients over four blocks on Houston 2013 and MUUFL and six on Augsburg; CM-S6(L) has one block. Table 7 reports final values and late-stage stability, Figure 10 shows the trajectories, and Figure 11 isolates the final Full-Lite reallocation. Results are from one run per setting (seed 42) and are descriptive.
Figure 10 shows that all coefficients enter stable nonzero regimes; no pathway remains at its initialization value or collectively decays toward zero. The maximum standard deviation over the final 20 epochs ranges from 2.81x10⁻⁴ to 7.82x10⁻⁴. The stabilization order is dataset-dependent: ζ stabilizes relatively early for full CM-S6 on Houston 2013 and Augsburg, whereas η, β, γ, and ζ stabilize later on MUUFL. In CM-S6(L), α reaches 0.50 early while the other pathways continue to adjust. Thus, the trajectories do not support a universal input-before-output convergence order.
Full CM-S6 exhibits a consistent relative allocation: α is largest at 0.4345-0.4910, η/β/γ lie at 0.2984-0.3675, and ζ remains at 0.0938-0.1139. This pattern is consistent with greater relative use of input injection and internal SSM parameter generation than output calibration. CM-S6(L) reallocates these strengths. On every dataset, α reaches its prescribed bound of 0.5000. Relative to full CM-S6, ζ increases by 0.1277, 0.1404, and 0.1038 on Houston 2013, Augsburg, and MUUFL, while β and γ also increase in most cases. Augsburg shows the clearest redistribution, with η, β, and γ reaching 0.3666, 0.4184, and 0.3677. Figure 11 pairs the final Full and Lite values and reports Lite minus Full. The pattern suggests stronger use of existing pathways under reduced capacity.
The coefficient trajectories complement the ablations: both A12 (CII+ζ) and A13 (Δ/B/C) exceed the single-modal baseline, and A13 is closer to the full model on MUUFL. All coefficients remain in stable nonzero regimes with capacity-dependent reallocation, indicating that the modulation paths are active rather than degenerate.
5. Conclusions
This work addresses the indirect role of auxiliary information in existing multimodal Mamba models, where cross-modal interaction is generally completed before or outside selective scanning. We proposed CM-S6, which conditions the Δ/B/C parameter-generation pathways of selective SSMs on auxiliary-modality signals via lightweight projections, complemented by CII and output calibration and coordinated by five bounded coefficients. CM-S6(L) retains all paths with simplified scan branches for efficiency.
On Houston 2013, no statistically significant difference in OA or Kappa is detected between full CM-S6 and MCAMamba, while CM-S6 achieves a higher AA. On Augsburg, no statistically significant difference in OA or Kappa is detected between CM-S6 and MTMixer. On MUUFL, CM-S6 obtains the highest mean OA and Kappa, although the differences from MTMixer are not statistically significant. The full models contain 0.6628M, 0.9823M, and 0.6632M parameters on the three datasets, respectively, indicating competitive classification performance with a small model size. CM-S6(L) reduces the parameter count to approximately 0.19M and increases throughput by 3.86–5.82 times, with a dataset-dependent accuracy–efficiency trade-off. The efficiency measurements further show that parameter count and FLOPs alone do not fully predict measured inference speed under the tested implementation, leaving room for future optimization of the full CM-S6 selective-scan operators.
The ablation results show that input injection/output calibration and internal Δ/B/C modulation can each exploit auxiliary information when retained separately and act complementarily in the full model, with their relative effects varying across datasets. All coefficients remain in nonzero regimes with capacity-dependent allocation. Overall, full CM-S6 and CM-S6(L) provide accuracy- and efficiency-oriented configurations of the same parameter-level fusion framework.
This study assumes co-registered modalities, fixed-size image patches, and an S6 backbone. Future work will optimize selective-scan and cross-modal projection kernels for hardware execution, investigate parameter-level modulation in state-space architectures such as Mamba-2/SSD [39], and evaluate robustness to missing modalities, noise, misregistration, and inconsistent spatial resolution. Multi-seed tracking and controlled interventions should provide more precise evidence about the contributions of individual modulation paths. Extending CM-S6 to multimodal medical imaging and multi-view video understanding is another relevant direction.
Author Contributions
Conceptualization, J.Z., D.Z. and Z.J.; methodology, J.Z.; software, J.Z.; validation, J.Z.; formal analysis, J.Z.; investigation, J.Z., D.Z. and Z.J.; resources, S.Q.; data curation, D.Z. and Z.J.; writing—original draft preparation, J.Z.; writing-review and editing, J.Z. and S.Q.; visualization, J.Z.; supervision, S.Q.; project administration, S.Q.; funding acquisition, S.Q. All authors have read and agreed to the published version of the manuscript.
Funding
This research was Supported by Heilongjiang Provincial Natural Science Foundation of China, grant number XQ2026D004.
Data Availability Statement
The Houston 2013, Augsburg, and MUUFL Gulfport datasets analyzed in this study are publicly available remote-sensing benchmark datasets. The Houston 2013 dataset is available from the 2013 IEEE GRSS Data Fusion Contest at https://www.grss-ieee.org/community/technical-committees/data-fusion/2013-ieee-grss-data-fusion-contest/. The Augsburg dataset is available at https://doi.org/10.6084/m9.figshare.28112405.v1. The MUUFL Gulfport dataset is available from the GatorSense laboratory at https://github.com/GatorSense/MUUFLGulfport and the University of Florida institutional repository at https://ufdc.ufl.edu/AA00024034/00001. The preprocessed data packages used in this study, including the corresponding modality files, labels, and PCA-transformed features, are also available at https://pan.baidu.com/s/1o8KuwlBxyGRKowOVa102vA (access code: 4tpv). The source code for CM-S6 is included as supplementary material with this submission. No new raw datasets were generated in this study.
Acknowledgments
The authors thank the Heilongjiang Provincial Natural Science Foundation of China for financial support. The authors also thank the IEEE GRSS Data Fusion Contest, the German Aerospace Center (DLR), and the GatorSense Laboratory at the University of Florida for providing the Houston 2013, Augsburg, and MUUFL Gulfport datasets, respectively. The authors gratefully acknowledge the anonymous reviewers for their constructive comments.
Conflicts of Interest
The authors declare no conflicts of interest.
Abbreviations
The following abbreviations are used in this manuscript:
| CM-S6 | Cross-Modal Selective Scan |
| CM-S6(L) | lightweight variant of Cross-Modal Selective Scan |
| S6 | selective state space model (S6) |
| SSM | state space model |
| CII | Cross-Modal Input Injection |
Appendix A
Conceptual Distinction: Parameter-Level Vs. Data-Level Fusion
The proposed parameter-level cross-modal fusion shifts the influence of the auxiliary modality from a shared feature or hidden-state tensor to the parameter-generation layer of the selective state space model. It does not replace feature-level or hidden-state-level fusion; instead, it adds cross-modal control paths aligned with SSM dynamics. We examine this distinction using constrained function families and locally reachable directions.
Let xM and xA denote the primary- and auxiliary-modality sequences, respectively. Omitting shared components such as A, local convolution, and output gating, standard S6 is written as (A1):
where Δ, B, and C are generated solely from xM through input-dependent projections.
Feature-level fusion first combines the modalities through φ, and hidden-state-level fusion modifies recurrent states through ψ. Both can be summarized as changing the data received by the SSM before its established parameter-generation interface performs the update as (A2):
The functions φ and ψ may be token- and channel-adaptive and can indirectly affect Δ, B, and C through the shared parameter-generation pathways. However, cross-modal evidence first enters a common data interface and then uses common generation pathways, without explicitly separating the functions associated with update rate, input writing, and state readout.
CM-S6 instead constructs separate auxiliary-conditioned generation branches for Δ, B, and C and completes the processing chain with input-side CII and output calibration. Ignoring normalization and shared projections, its mapping is (A3).
Equation (A3) assigns auxiliary evidence to three distinct SSM control roles: the Δ branch regulates how much historical state is retained versus how much new input is integrated, the B branch determines what is written into the hidden state, and the C branch determines what is read out. The η and ζ terms provide input injection and output calibration, respectively.
This separation is reflected in the local sensitivity of the output to the auxiliary input. Differentiating ycm with respect to xA yields
Auxiliary gradients can therefore propagate through five functionally distinct paths rather than through a single fusion bottleneck. If the directions learned by the Δ, B, and C projections are not all linearly dependent, the three state-space operations can exhibit different local responses to auxiliary evidence. Parameter-level paths thus complement data-level fusion: data-level fusion constructs the inputs used for computation, whereas parameter-level fusion controls how those inputs drive state evolution. This conceptual distinction is empirically reflected in the A12/A13 ablation, where Δ/B/C modulation alone (A13) outperforms feature-level concatenation (A1) on all three datasets.
Appendix B
Class Index Notation
For compactness of Table 1, Table 2 and Table 3, the class names of the three datasets are represented by indices C1–C15. The correspondence is listed in Table A1.

| Index | Houston 2013 | Augsburg | MUUFL |
|---|---|---|---|
| C1 | Healthy grass | Forest | Trees |
| C2 | Stressed grass | Residential Area | Mostly grass |
| C3 | Synthetic grass | Industrial Area | Mixed ground surface |
| C4 | Trees | Low Plants | Dirt and sand |
| C5 | Soil | Allotment | Road |
| C6 | Water | Commercial Area | Water |
| C7 | Residential | Water | Building shadow |
| C8 | Commercial | - | Building |
| C9 | Road | - | Sidewalk |
| C10 | Highway | - | Yellow curb |
| C11 | Railway | - | Cloth panels |
| C12 | Parking lot 1 | - | - |
| C13 | Parking lot 2 | - | - |
| C14 | Tennis court | - | - |
| C15 | Running track | - | - |
References
- Li, S.; Song, W.; Fang, L.; Chen, Y.; Ghamisi, P.; Benediktsson, J.A. Deep learning for hyperspectral image classification: An overview. IEEE Trans. Geosci. Remote Sens. 2019, 57, 6690–6709. [Google Scholar] [CrossRef]
- Parikh, H.; Patel, S.; Patel, V. Classification of SAR and PolSAR images using deep learning: A review. Int. J. Image Data Fusion 2020, 11, 1–32. [Google Scholar] [CrossRef]
- Diab, A.; Kashef, R.; Shaker, A. Deep learning for LiDAR point cloud classification in remote sensing. Sensors 2022, 22, 7868. [Google Scholar] [CrossRef] [PubMed]
- Zhang, X.; Leng, C.; Hong, Y.; Pei, Z.; Cheng, I.; Basu, A. Multimodal remote sensing image registration methods and advancements: A survey. Remote Sens. 2021, 13, 5128. [Google Scholar] [CrossRef]
- Ghamisi, P.; Rasti, B.; Yokoya, N.; Wang, Q.; Höfle, B.; Bruzzone, L.; Bovolo, F.; Chi, M.; Anders, K.; Gloaguen, R.; et al. Multisource and multitemporal data fusion in remote sensing: A comprehensive review of the state of the art. IEEE Geosci. Remote Sens. Mag. 2019, 7, 6–39. [Google Scholar] [CrossRef]
- Li, Y.; Luo, Y.; Zhang, L.; Wang, Z.; Du, B. MambaHSI: Spatial–spectral Mamba for hyperspectral image classification. IEEE Trans. Geosci. Remote Sens. 2024, 62, 1–16. [Google Scholar] [CrossRef]
- Wang, G.; Zhang, X.; Peng, Z.; Zhang, T.; Jiao, L. S²Mamba: A spatial–spectral state space model for hyperspectral image classification. IEEE Trans. Geosci. Remote Sens. 2025. [Google Scholar] [CrossRef]
- Liao, D.; Wang, Q.; Lai, T.; Huang, H. Joint classification of hyperspectral and LiDAR data based on Mamba. IEEE Trans. Geosci. Remote Sens. 2024, 62, 1–15. [Google Scholar] [CrossRef]
- Dou, M.; Qiu, S.; Hu, M.; Qiao, X.; Ye, H.; Liao, X.; Sun, Z. MCAMamba: Multi-level cross-modal attention-guided state space model for multi-source remote sensing image classification. IEEE Trans. Geosci. Remote Sens. 2025. [Google Scholar] [CrossRef]
- Hang, R.; Li, Z.; Ghamisi, P.; Hong, D.; Xia, G.; Liu, Q. Classification of hyperspectral and LiDAR data using coupled CNNs. IEEE Trans. Geosci. Remote Sens. 2020, 58, 4939–4950. [Google Scholar] [CrossRef]
- Dosovitskiy, A.; Beyer, L.; Kolesnikov, A.; Weissenborn, D.; Zhai, X.; Unterthiner, T.; Dehghani, M.; Minderer, M.; Heigold, G.; Gelly, S.; et al. An image is worth 16x16 words: Transformers for image recognition at scale. arXiv 2020, arXiv:2010.11929. [Google Scholar]
- Vaswani, A.; Shazeer, N.; Parmar, N.; Uszkoreit, J.; Jones, L.; Gomez, A.N.; Kaiser, Ł.; Polosukhin, I. Attention is all you need. In Proceedings of the Advances in Neural Information Processing Systems (NeurIPS), 2017; Volume 30. [Google Scholar]
- Roy, S.K.; Deria, A.; Hong, D.; Rasti, B.; Plaza, A.; Chanussot, J. Multimodal fusion transformer for remote sensing image classification. IEEE Trans. Geosci. Remote Sens. 2023, 61, 1–20. [Google Scholar] [CrossRef]
- Gao, F.; Liu, S.; Gong, C.; Zhou, X.; Wang, J.; Dong, J.; Du, Q. Prototype-based information compensation network for multi-source remote sensing data classification. IEEE Trans. Geosci. Remote Sens. 2025, 63, 1–15. [Google Scholar] [CrossRef]
- Roy, S.K.; Sukul, A.; Jamali, A.; Haut, J.M.; Ghamisi, P. Cross hyperspectral and LiDAR attention transformer: An extended self-attention for land use and land cover classification. IEEE Trans. Geosci. Remote Sens. 2024, 62, 1–15. [Google Scholar] [CrossRef]
- Wang, W.; Li, C.; Ren, P.; Lu, X.; Wang, J.; Ren, G.; Liu, B. Dual-branch feature fusion network based cross-modal enhanced CNN and Transformer for hyperspectral and LiDAR classification. IEEE Geosci. Remote Sens. Lett. 2024, 21, 1–5. [Google Scholar] [CrossRef]
- Gao, F.; Jin, X.; Zhou, X.; Dong, J.; Du, Q. MSFMamba: Multiscale feature fusion state space model for multisource remote sensing image classification. IEEE Trans. Geosci. Remote Sens. 2025, 63, 1–16. [Google Scholar] [CrossRef]
- Cui, X.; Zhang, L. MTMixer: A hybrid Mamba–Transformer architecture for multimodal remote sensing image classification. Int. J. Remote Sens. 2026, 47, 770–799. [Google Scholar] [CrossRef]
- Gu, A.; Dao, T.; Ermon, S.; Rudra, A.; Ré, C. HiPPO: Recurrent memory with optimal polynomial projections. Proc. Adv. Neural Inf. Process. Syst. (NeurIPS) 2020, Volume 33, 1474–1487. [Google Scholar]
- Qu, H.; Ning, L.; An, R.; Fan, W.; Derr, T.; Liu, H.; Xu, X.; Li, Q. A survey of Mamba. arXiv 2024, arXiv:2408.01129. [Google Scholar]
- Gu, A.; Goel, K.; Ré, C. Efficiently modeling long sequences with structured state spaces. arXiv 2021, arXiv:2111.00396. [Google Scholar]
- Gu, A.; Dao, T. Mamba: Linear-time sequence modeling with selective state spaces. arXiv 2023, arXiv:2312.00752. [Google Scholar]
- Zhu, L.; Liao, B.; Zhang, Q.; Wang, X.; Liu, W.; Wang, X. Vision Mamba: Efficient visual representation learning with bidirectional state space model. arXiv 2024, arXiv:2401.09417. [Google Scholar]
- Liu, Y.; Tian, Y.; Zhao, Y.; Yu, H.; Xie, L.; Wang, Y.; Ye, Q.; Jiao, J.; Liu, Y. VMamba: Visual state space model. Proc. Adv. Neural Inf. Process. Syst. (NeurIPS) 2024, Volume 37, 103031–103063. [Google Scholar] [CrossRef]
- Yao, J.; Hong, D.; Li, C.; Chanussot, J. SpectralMamba: Efficient Mamba for hyperspectral image classification. arXiv 2024, arXiv:2404.08489. [Google Scholar]
- Huang, L.; Chen, Y.; He, X. Spectral–spatial Mamba for hyperspectral image classification. Remote Sens. 2024, 16, 2449. [Google Scholar] [CrossRef]
- Li, W.; Zhou, H.; Yu, J.; Song, Z.; Yang, W. Coupled Mamba: Enhanced multimodal fusion with coupled state space model. Proc. Adv. Neural Inf. Process. Syst. (NeurIPS) 2024, Volume 37, 59808–59832. [Google Scholar] [CrossRef]
- Han, Z.; Zhang, C.; Fu, H.; Zhou, J.T. Trusted multi-view classification with dynamic evidential fusion. IEEE Trans. Pattern Anal. Mach. Intell. 2023, 45, 2551–2566. [Google Scholar] [CrossRef] [PubMed]
- Sensoy, M.; Kaplan, L.; Kandemir, M. Evidential deep learning to quantify classification uncertainty. In Proceedings of the Advances in Neural Information Processing Systems (NeurIPS), 2018; Volume 31. [Google Scholar]
- Han, Z.; Yang, F.; Huang, J.; Zhang, C.; Yao, J. Multimodal dynamics: Dynamical fusion for trustworthy multimodal classification. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2022; pp. 20707–20717. [Google Scholar]
- Xu, C.; Si, J.; Guan, Z.; Zhao, W.; Wu, Y.; Gao, X. Reliable conflictive multi-view learning. Proc. AAAI Conf. Artif. Intell. (AAAI) 2024, Volume 38, 16129–16137. [Google Scholar] [CrossRef]
- Wang, H.; Zhang, J.; Chen, Y.; Ma, C.; Avery, J.; Hull, L.; Carneiro, G. Uncertainty-aware multi-modal learning via cross-modal random network prediction. In Proceedings of the European Conference on Computer Vision (ECCV), 2022; pp. 200–217. [Google Scholar]
- Debes, C.; Merentitis, A.; Heremans, R.; Hahn, J.; Frangiadakis, N.; van Kasteren, T.; Liao, W.; Bellens, R.; Pižurica, A.; Gautama, S.; et al. Hyperspectral and LiDAR data fusion: Outcome of the 2013 GRSS Data Fusion Contest. IEEE J. Sel. Top. Appl. Earth Obs. Remote Sens. 2014, 7, 2405–2418. [Google Scholar] [CrossRef]
- Hong, D.; Gao, L.; Yokoya, N.; Yao, J.; Chanussot, J.; Du, Q.; Zhang, B. More diverse means better: Multimodal deep learning meets remote-sensing imagery classification. IEEE Trans. Geosci. Remote Sens. 2021, 59, 4340–4354. [Google Scholar] [CrossRef]
- Du, X.; Zare, A. Multiresolution multimodal sensor fusion for remote sensing data with label uncertainty. IEEE Trans. Geosci. Remote Sens. 2020, 58, 2755–2769. [Google Scholar] [CrossRef]
- Gader, P.; Zare, A.; Close, R.; Aitken, J.; Tuell, G. MUUFL Gulfport Hyperspectral and LiDAR Airborne Data Set; University of Florida: Gainesville, FL, USA, 2013; p. REP-2013-570. Available online: https://ufdc.ufl.edu/AA00024034/00001 (accessed on 25 August 2026).
- Loshchilov, I.; Hutter, F. Decoupled weight decay regularization. arXiv 2017, arXiv:1711.05101. [Google Scholar]
- Xu, Y.; Wang, D.; Zhang, L.; Zhang, L. Dual selective fusion transformer network for hyperspectral image classification. Neural Netw. 2025, 187, 107311. [Google Scholar] [CrossRef] [PubMed]
- Dao, T.; Gu, A. Transformers are SSMs: Generalized models and efficient algorithms through structured state space duality. arXiv 2024, arXiv:2405.21060. [Google Scholar]
Figure 2.
Comparison of multimodal fusion paradigms in SSM-based methods (feature-level / hidden-state-level/parameter-level).
Figure 2.
Comparison of multimodal fusion paradigms in SSM-based methods (feature-level / hidden-state-level/parameter-level).
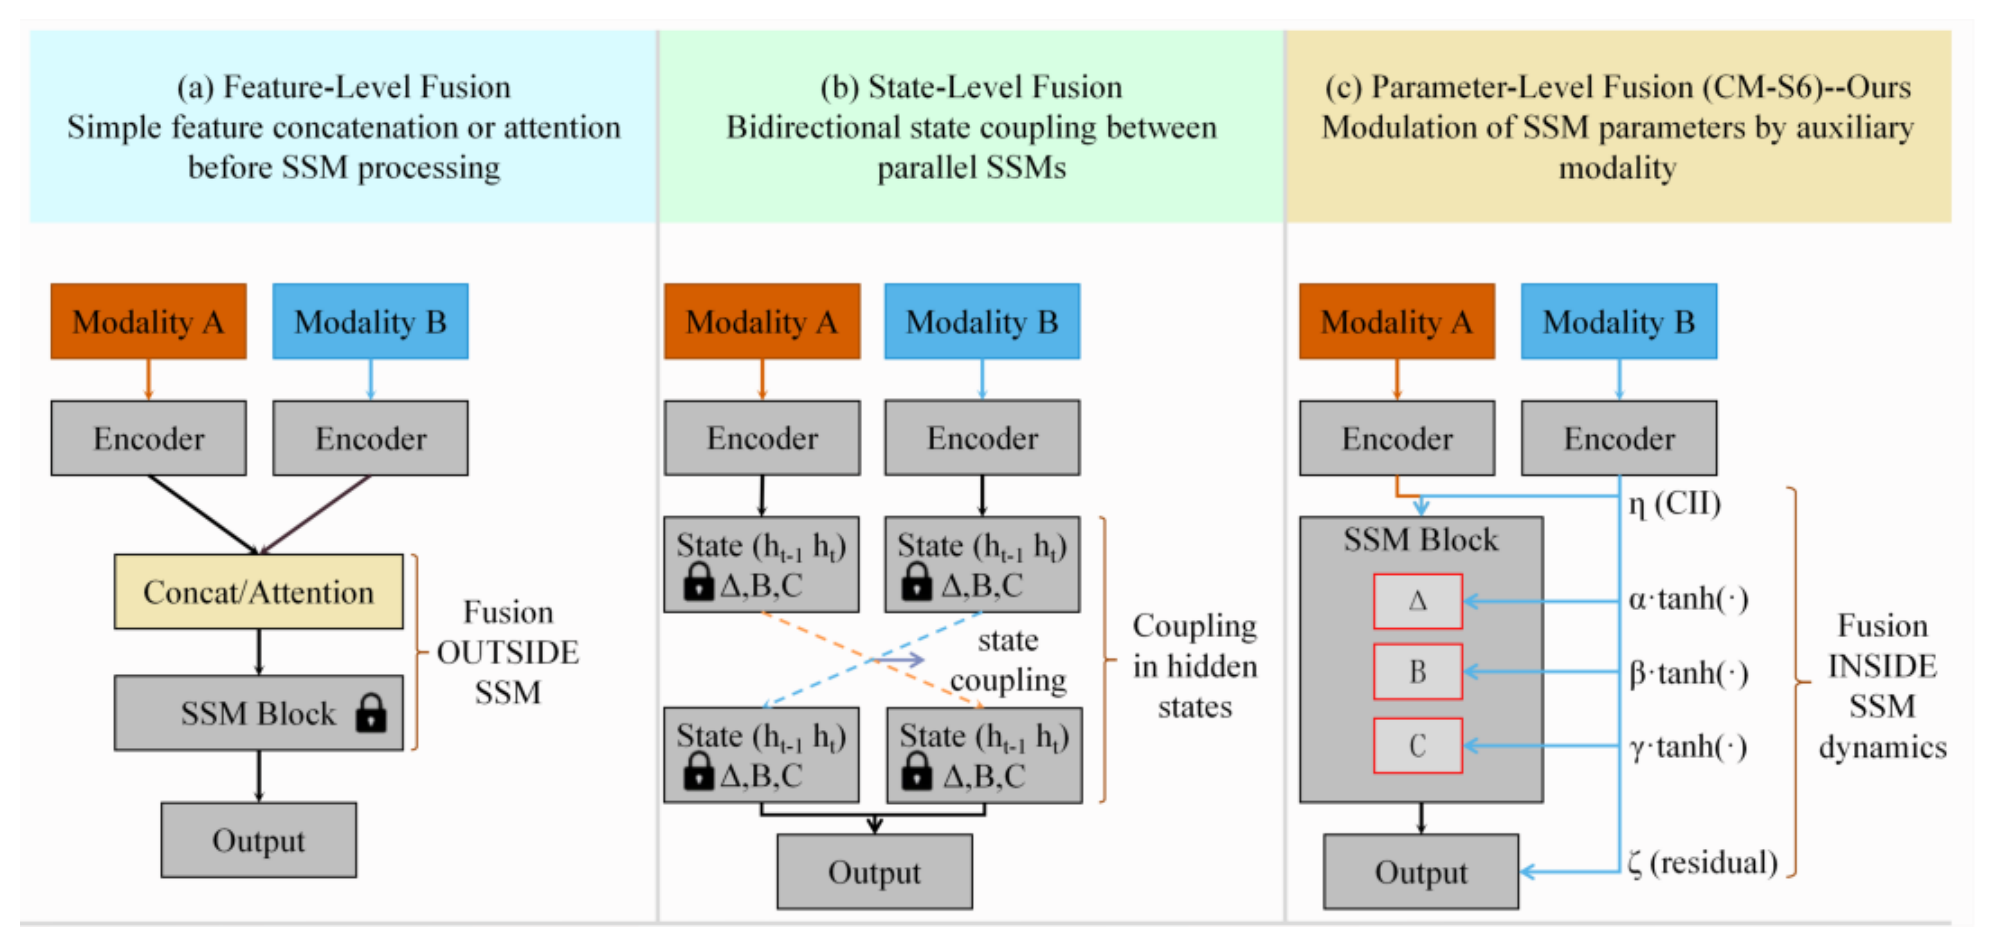
Figure 3.
Detailed architecture of the Cross-Modal Selective Scan module.
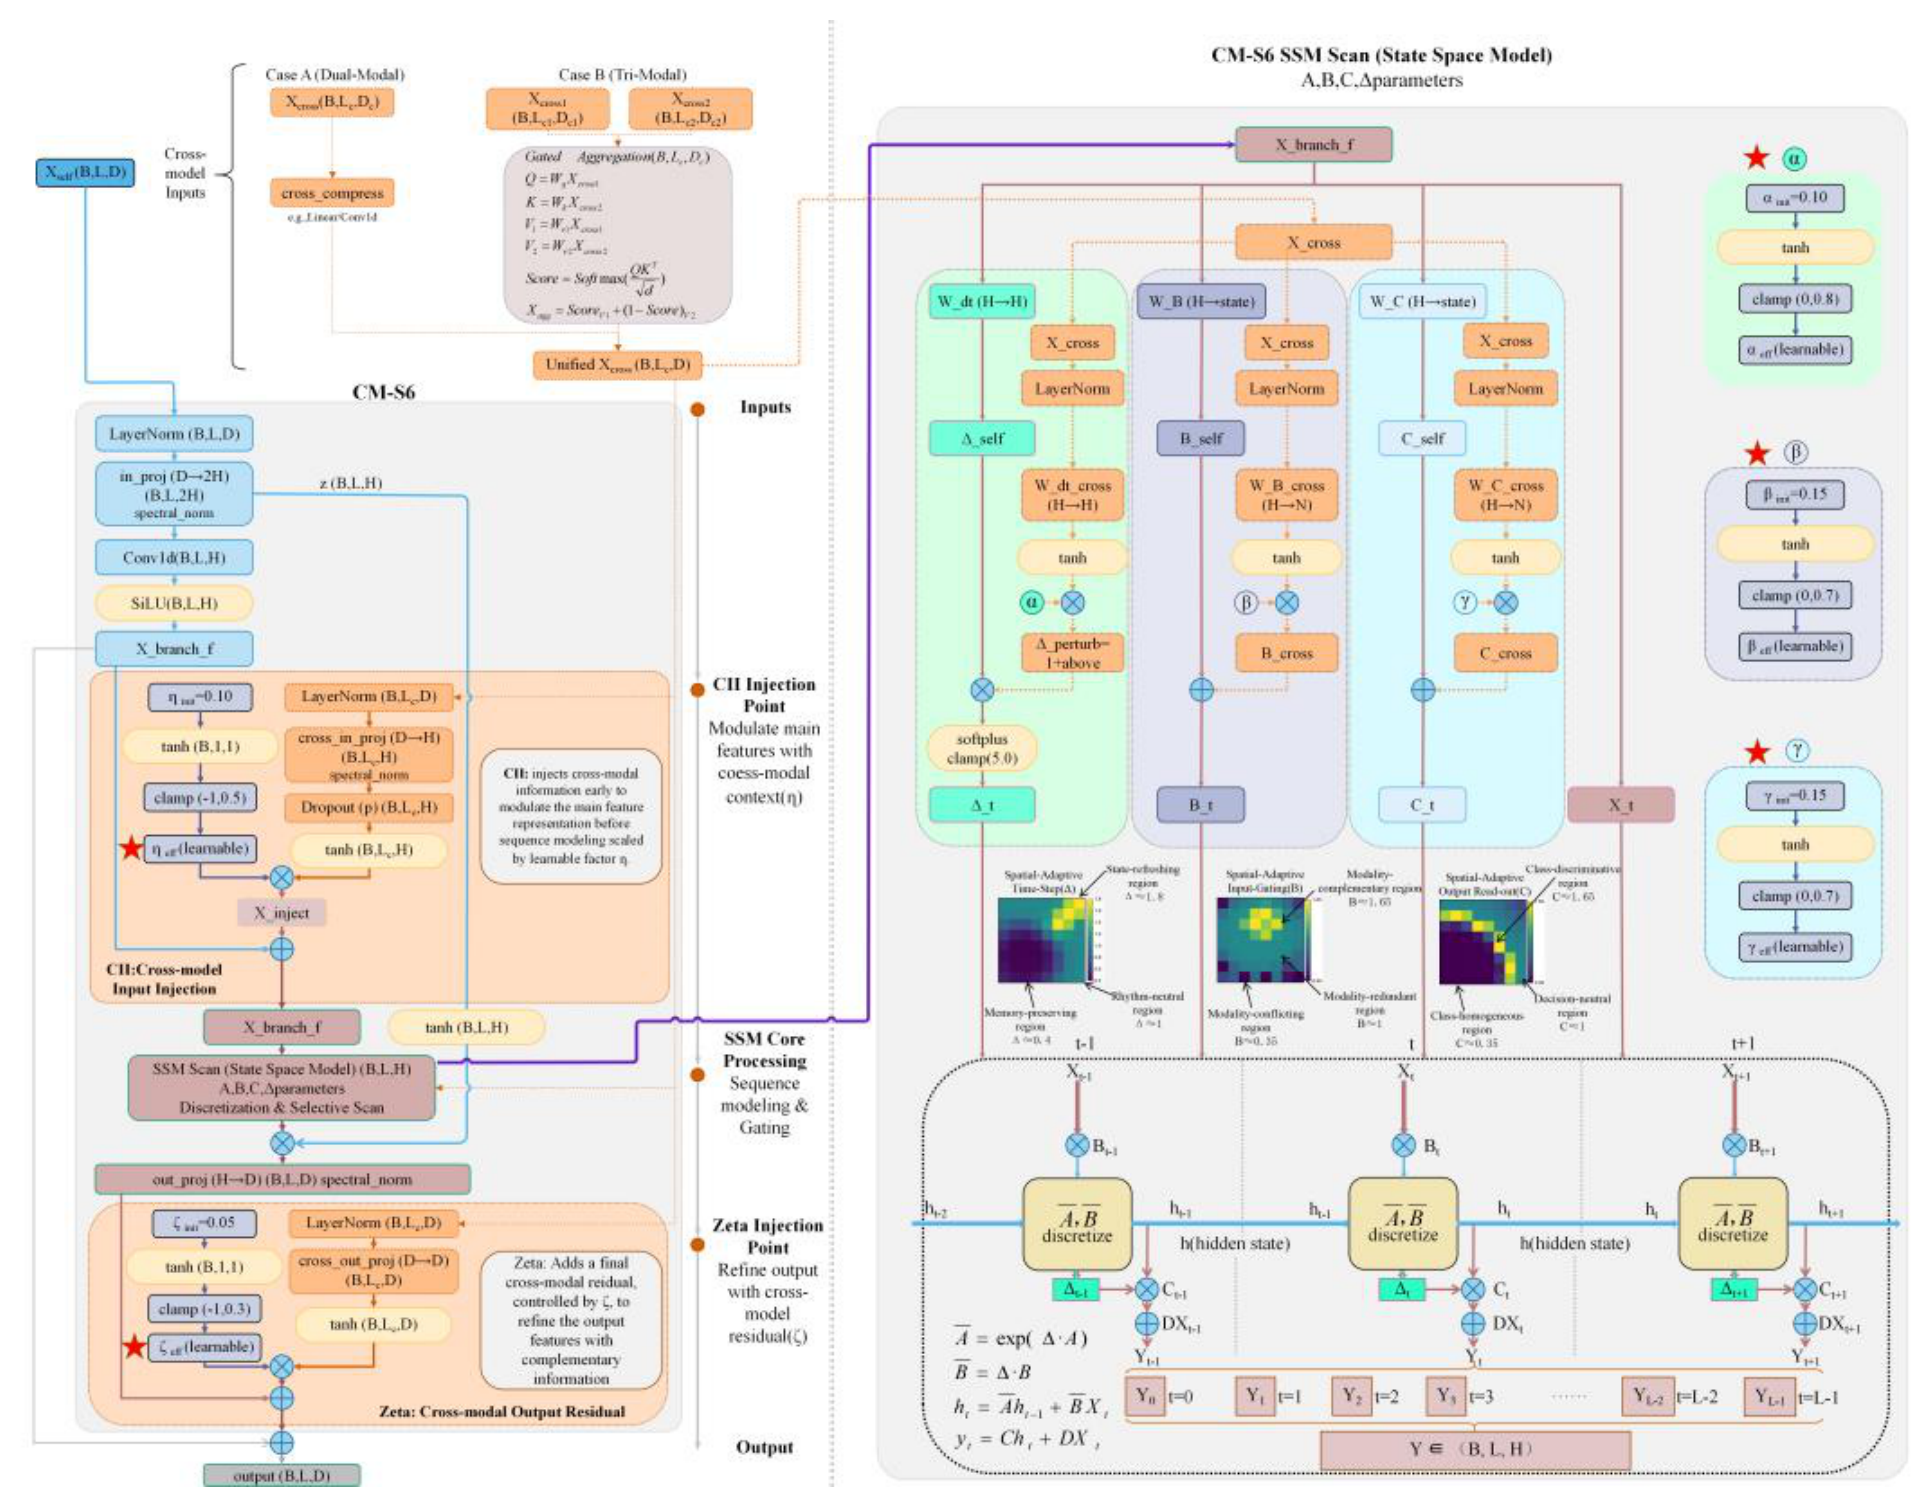
Figure 4.
Overall architecture of CM-S6 for dual-modality and tri-modality classification tasks.
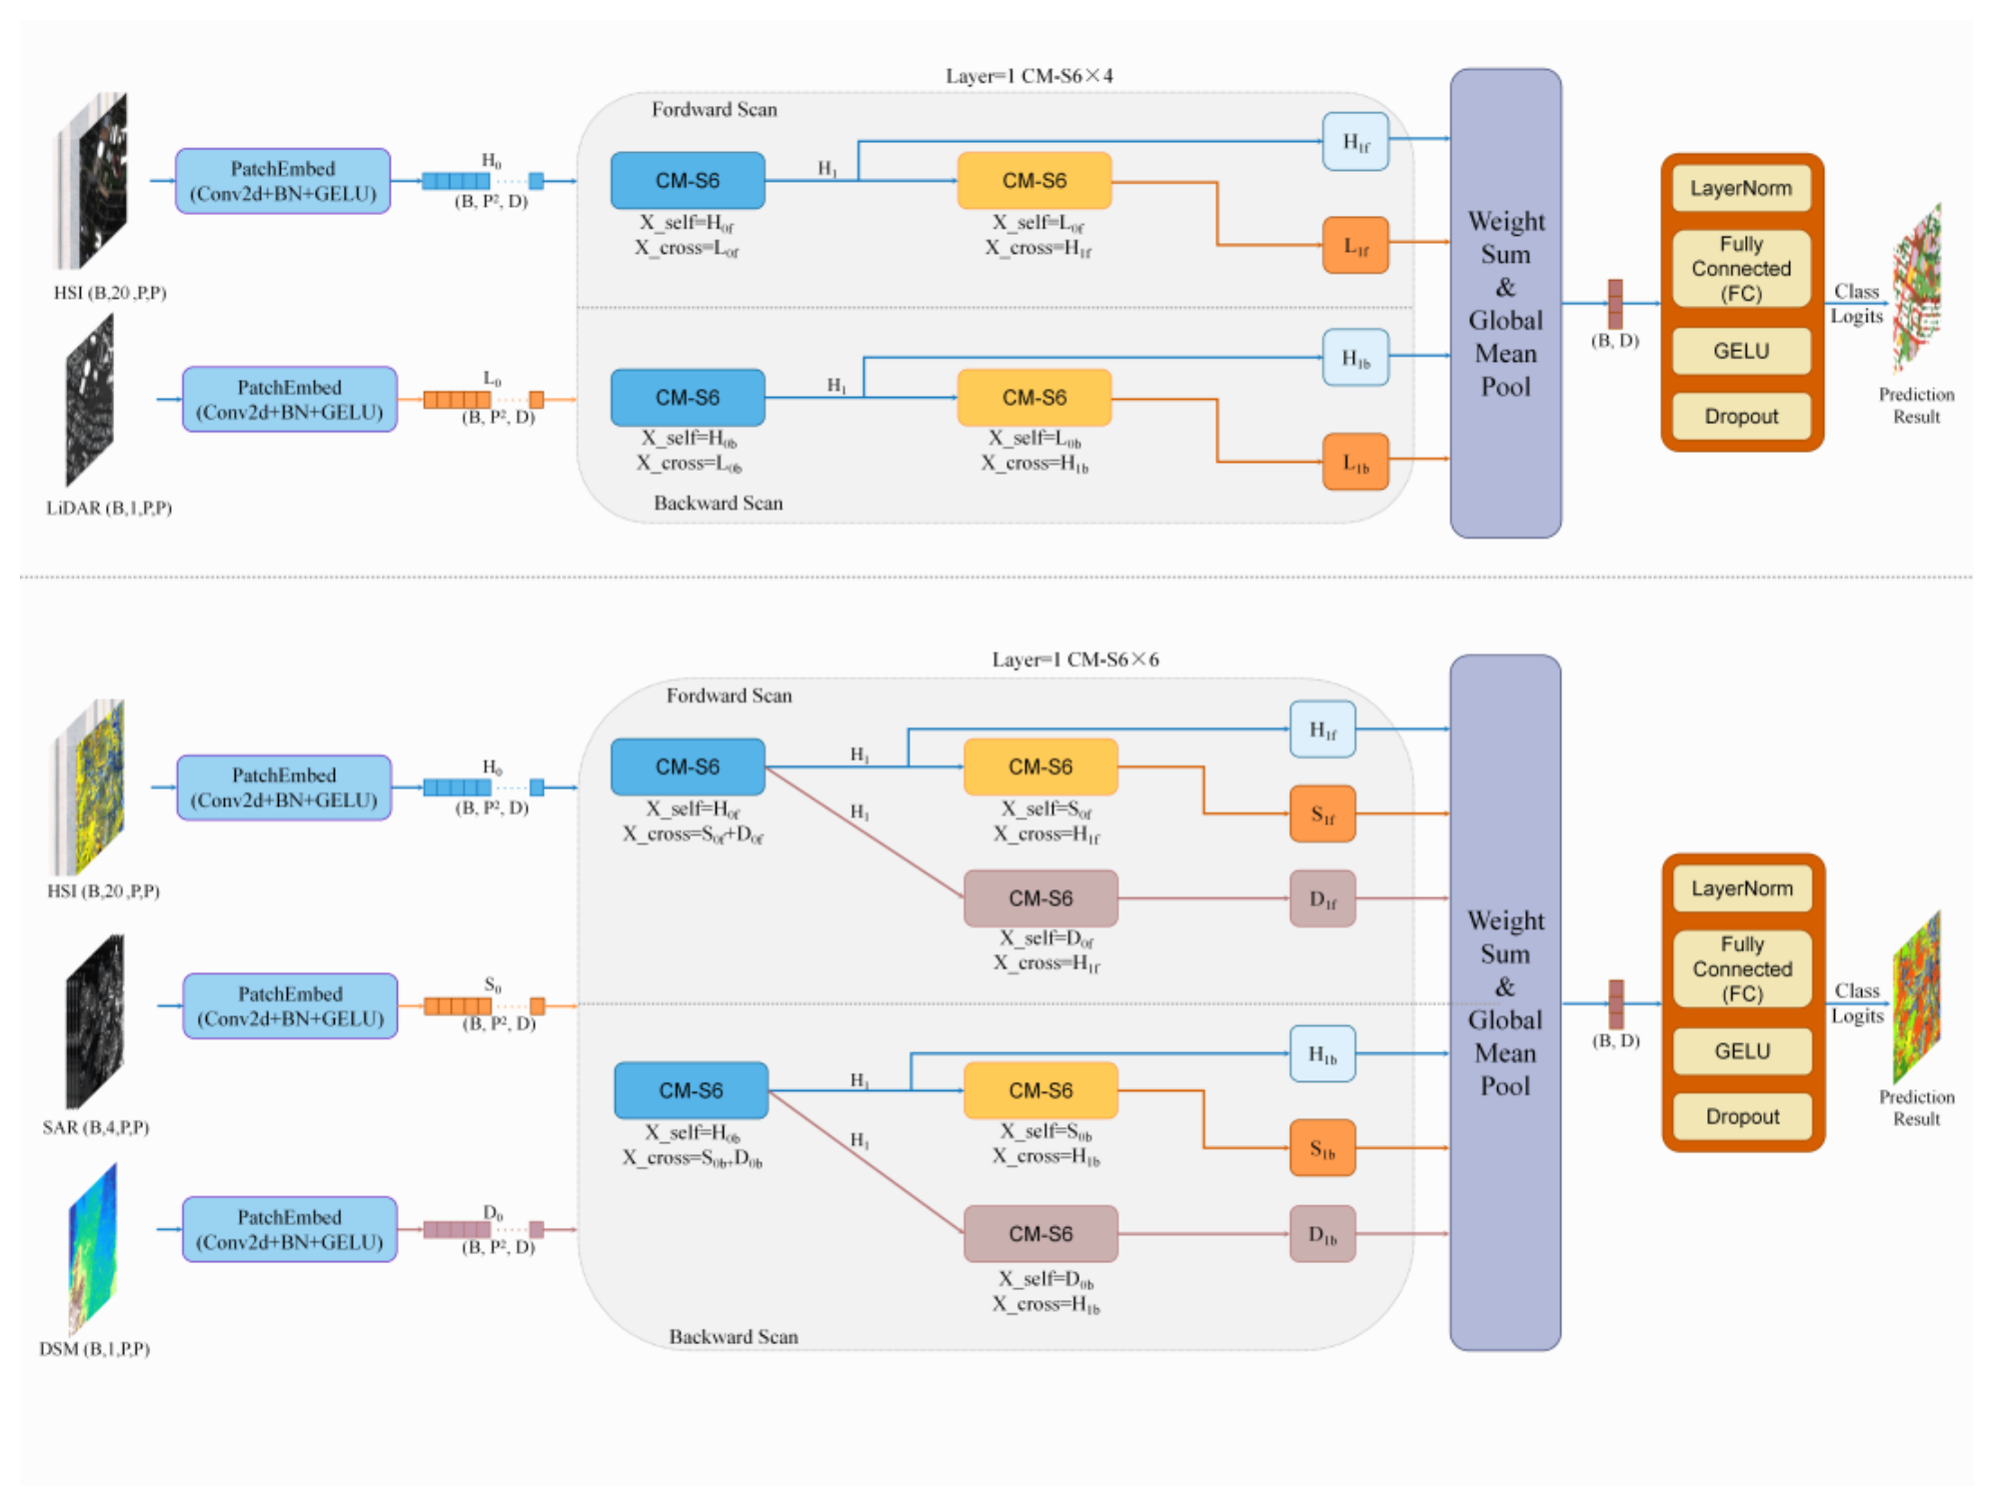
Figure 5.
Comparison of classification prediction maps on the Houston dataset.
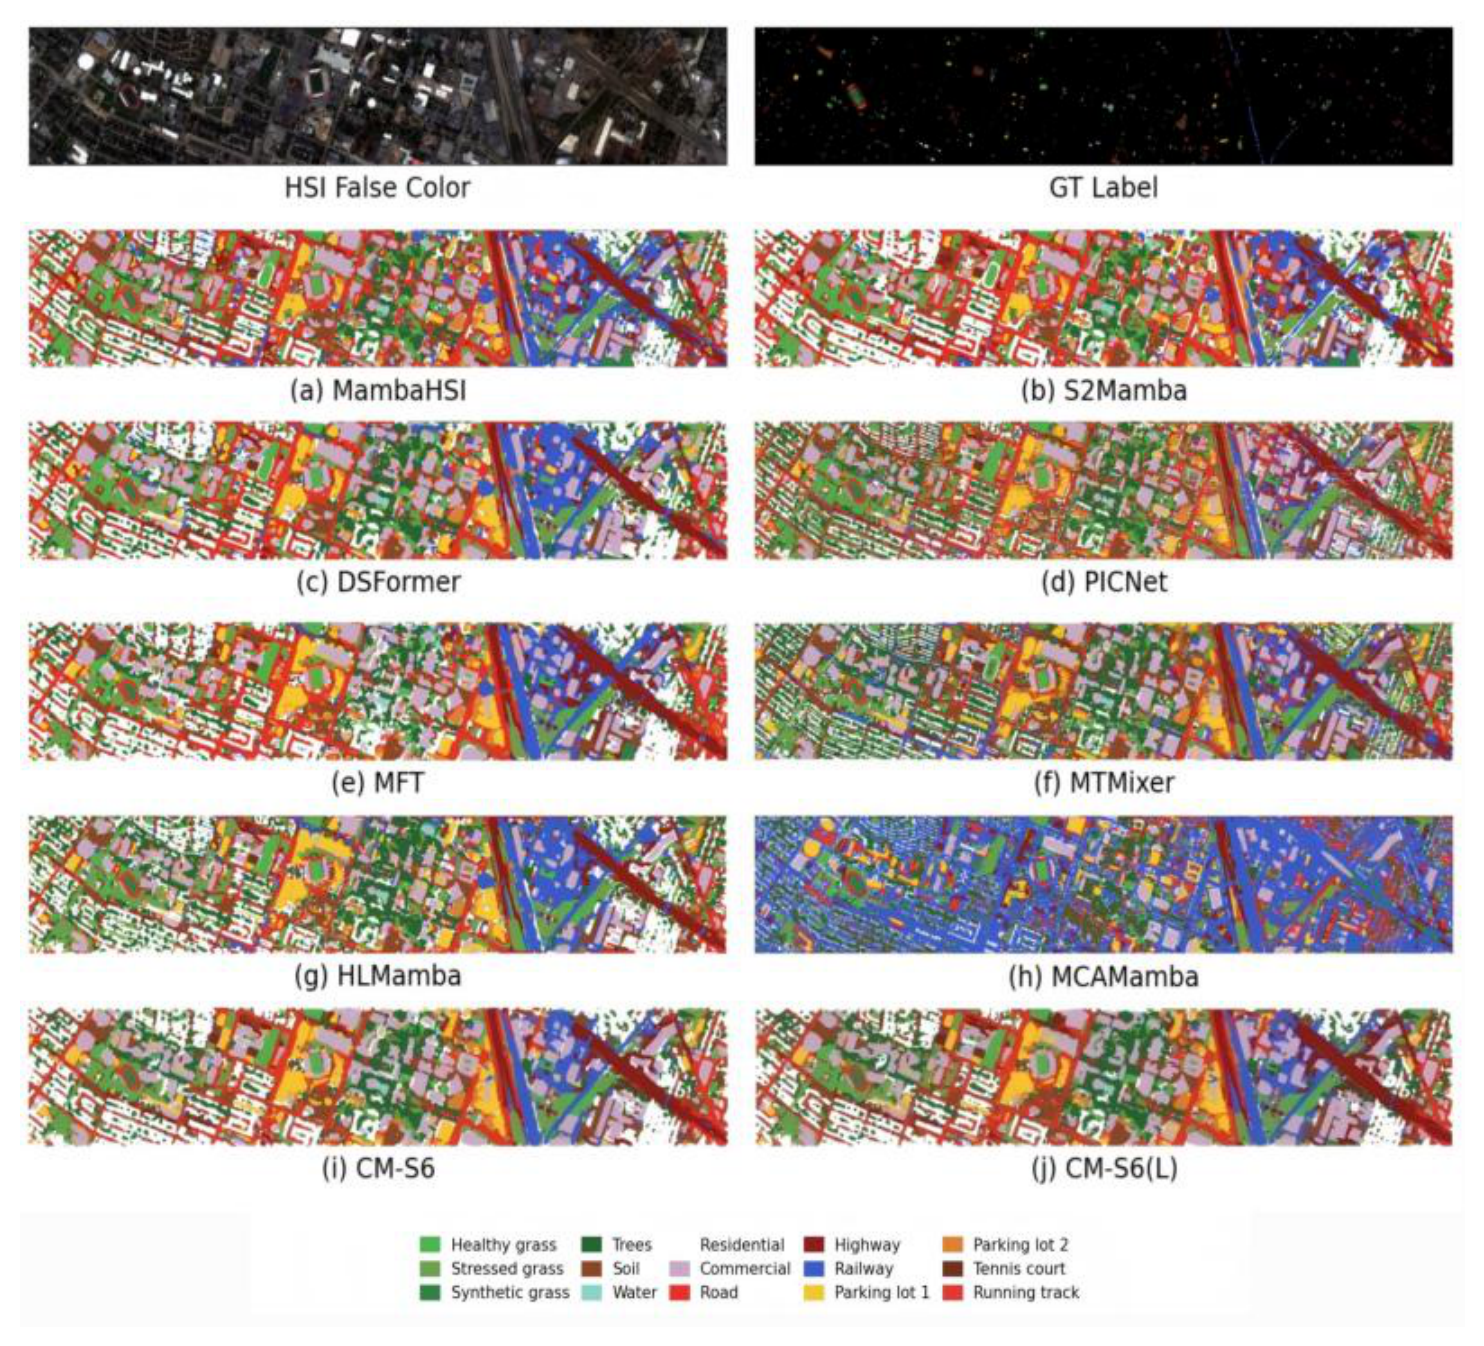
Figure 6.
Comparison of classification prediction maps on the Augsburg dataset.
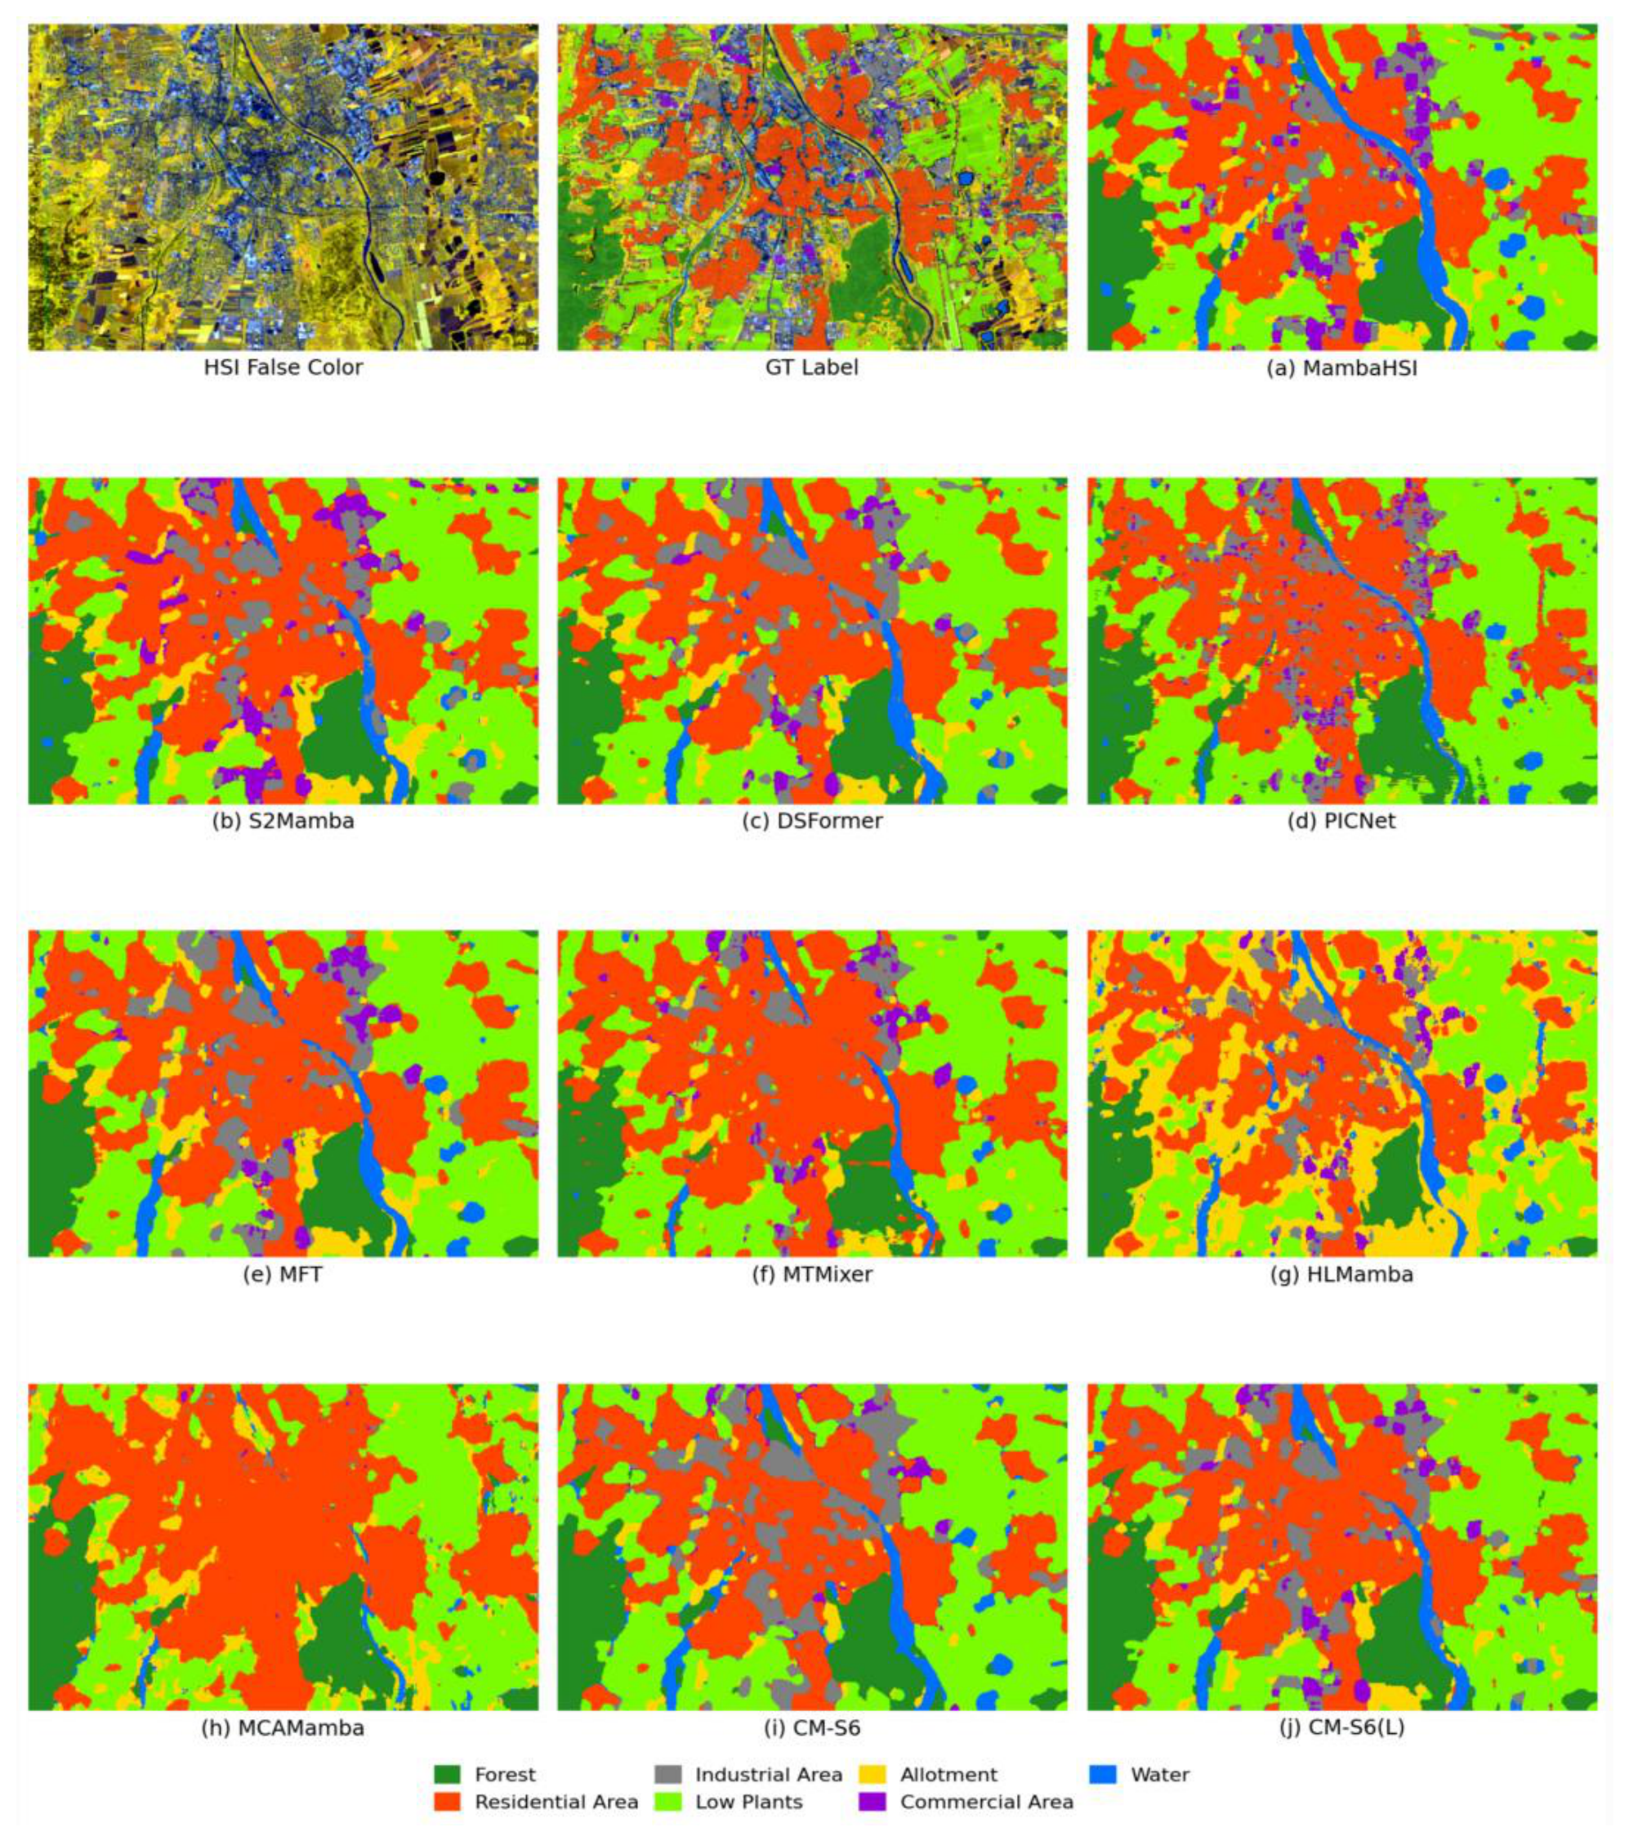
Figure 7.
Comparison of classification prediction maps on the MUUFL Gulfport dataset.
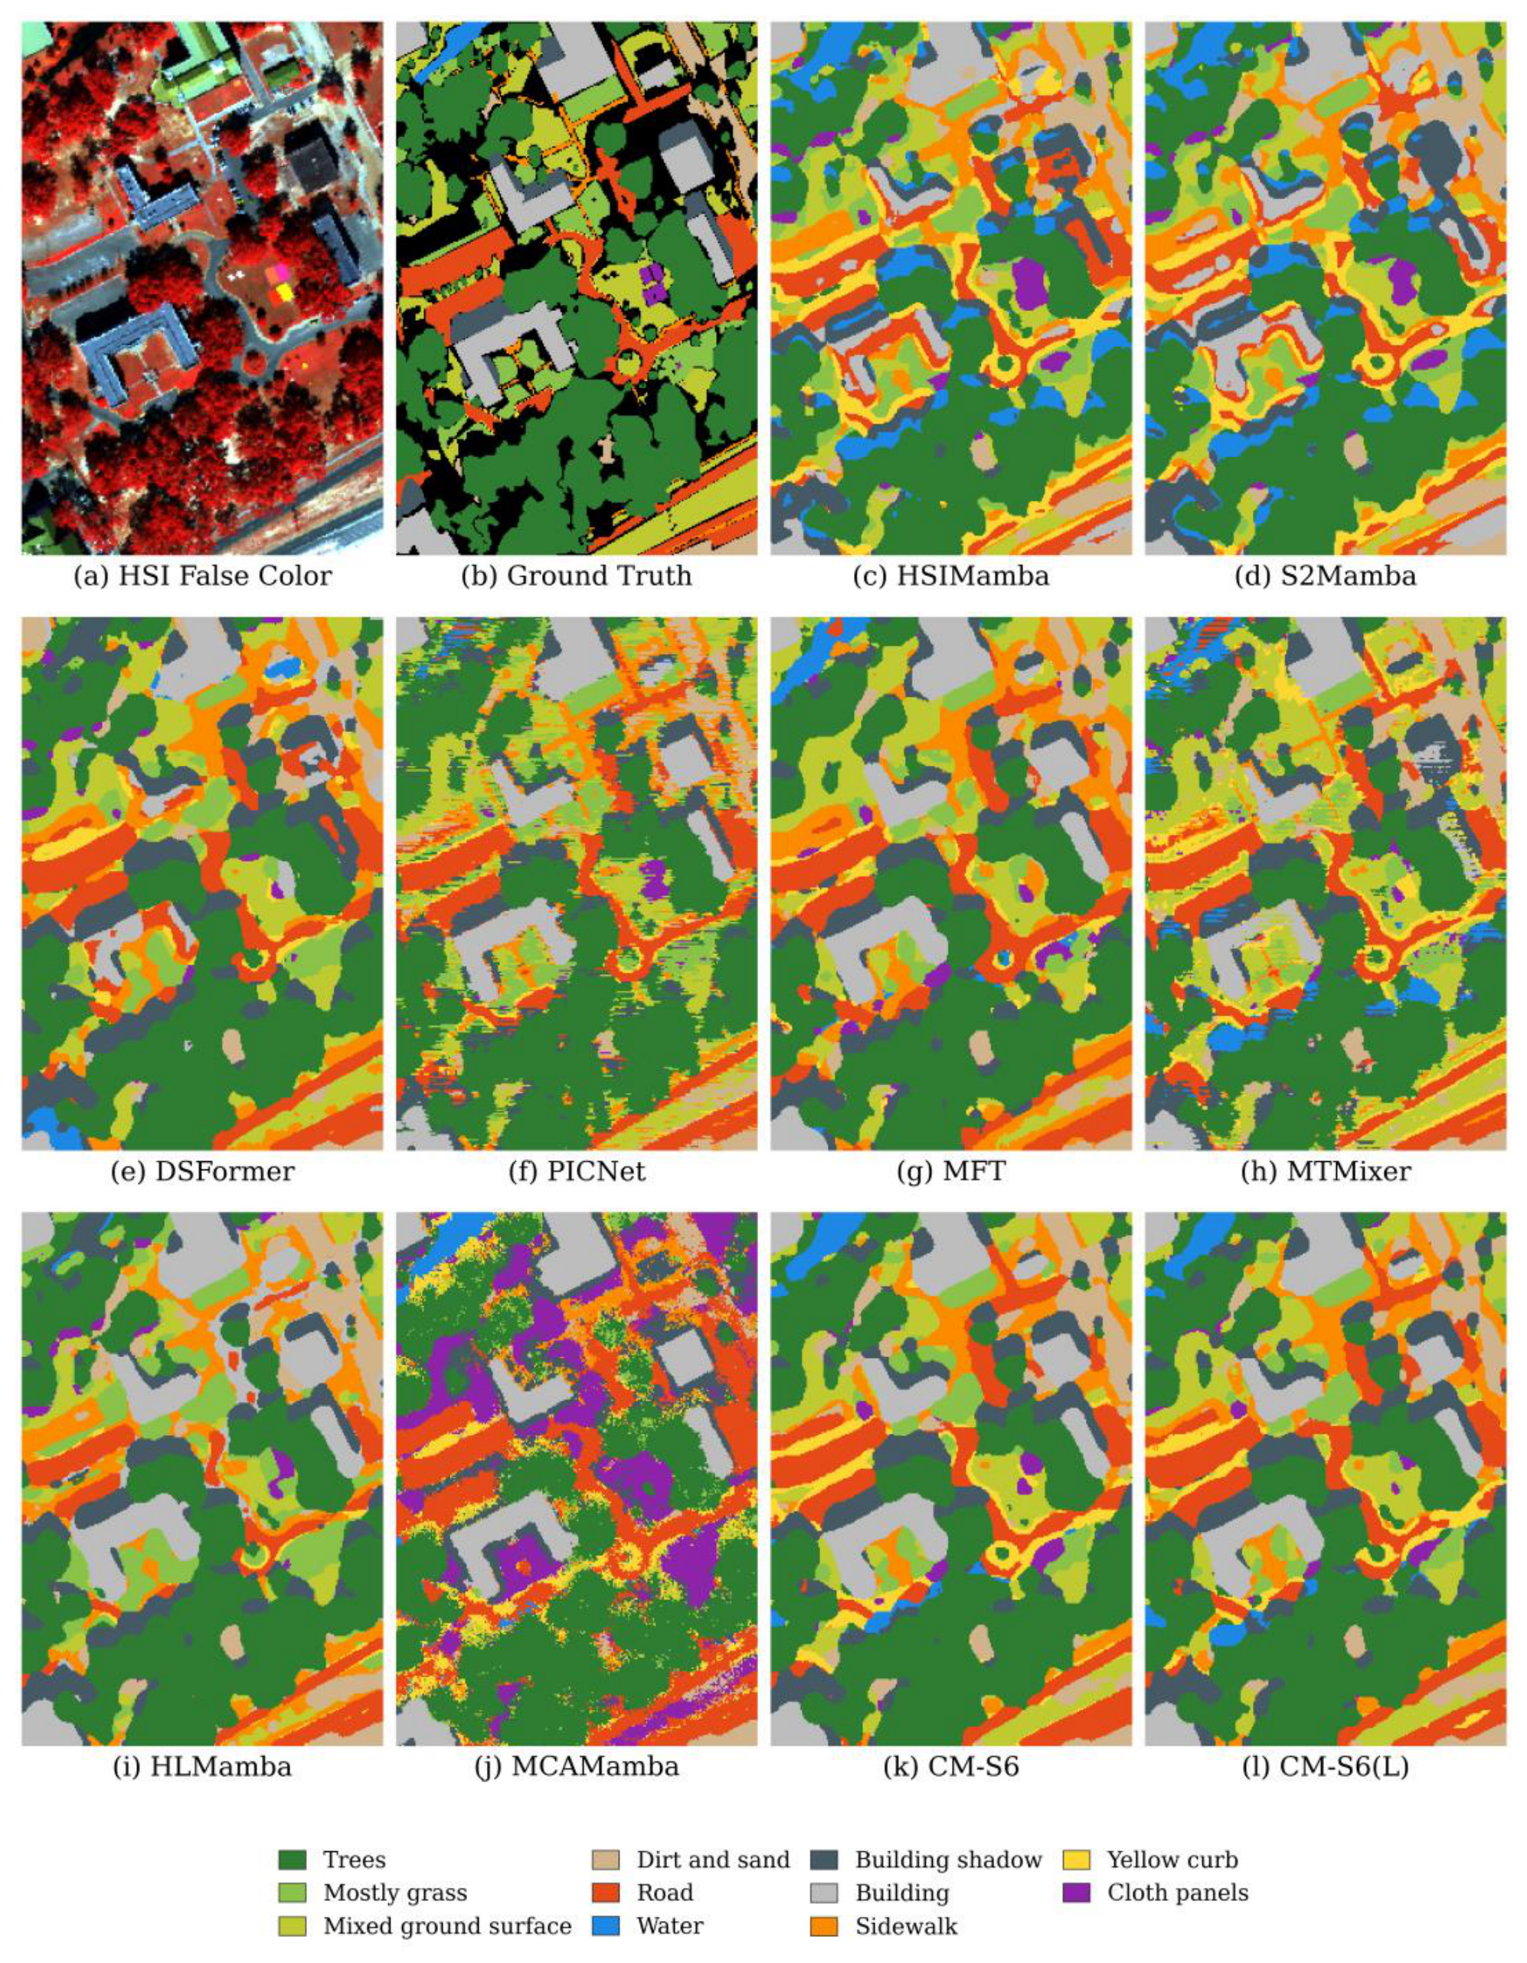
Figure 8.
Ablation summary on Houston 2013, Augsburg, and MUUFL. (a)–(c) OA across the progressive A0–A6 configurations, with points and error bars denoting the mean and standard deviation. A0 and A1 are Single-S6 and CatFuse-S6, while A2–A6 progressively introduce η, α, β, γ, and ζ. (d)–(f) OA differences between full A6 and variants A7–A13; positive values indicate higher OA for A6. A7–A11 remove one modulation path at a time, whereas A12 and A13 retain CII+ζ and Δ/B/C, respectively. A0, A1, and A6 use ten runs, and the remaining configurations use five runs.
Figure 8.
Ablation summary on Houston 2013, Augsburg, and MUUFL. (a)–(c) OA across the progressive A0–A6 configurations, with points and error bars denoting the mean and standard deviation. A0 and A1 are Single-S6 and CatFuse-S6, while A2–A6 progressively introduce η, α, β, γ, and ζ. (d)–(f) OA differences between full A6 and variants A7–A13; positive values indicate higher OA for A6. A7–A11 remove one modulation path at a time, whereas A12 and A13 retain CII+ζ and Δ/B/C, respectively. A0, A1, and A6 use ten runs, and the remaining configurations use five runs.
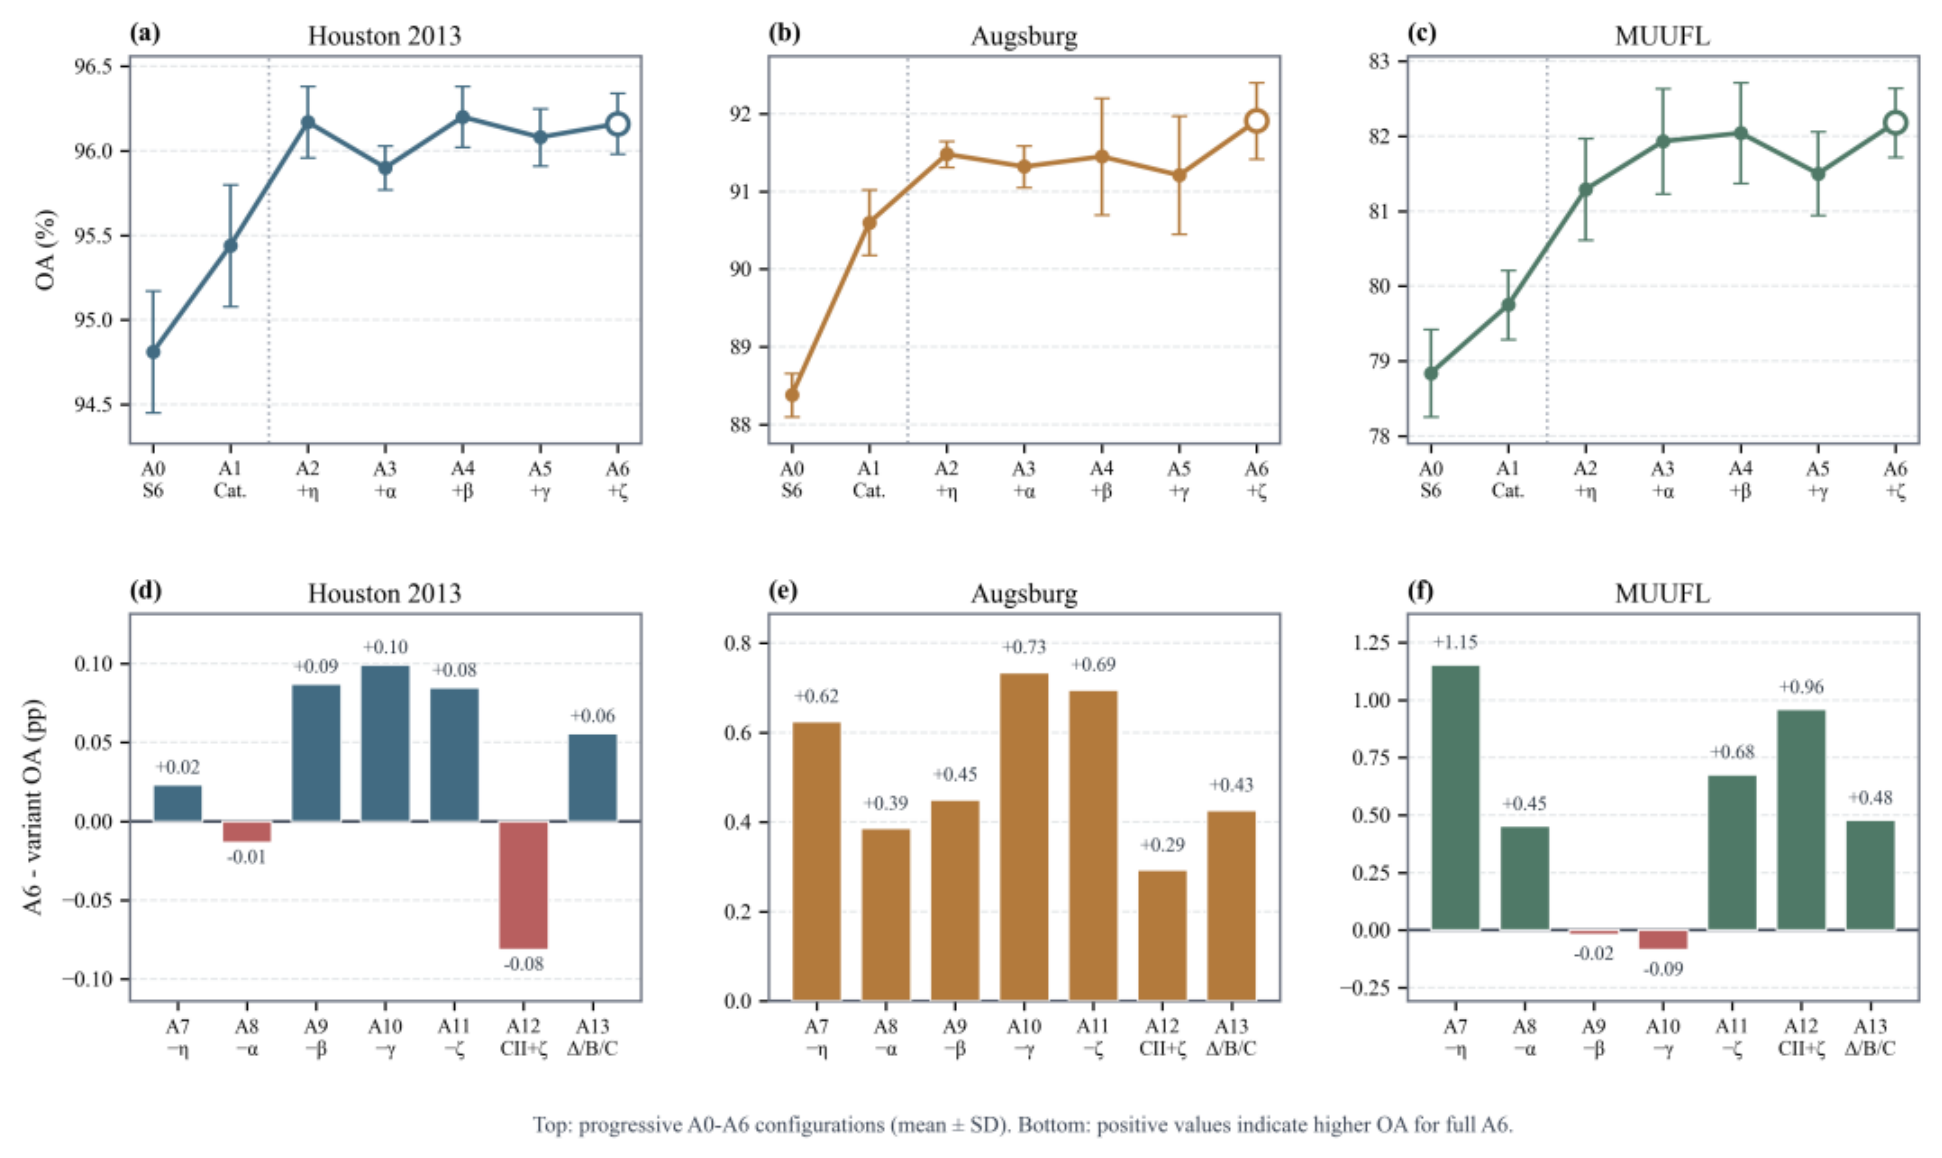
Figure 9.
Accuracy–efficiency Pareto analysis on the three datasets. (a)–(c) OA versus FLOPs, with bubble area representing parameter count. (d)–(f) OA versus latency, with bubble area representing peak memory. All values are obtained from the checkpoints selected under the unified efficiency-evaluation protocol.
Figure 9.
Accuracy–efficiency Pareto analysis on the three datasets. (a)–(c) OA versus FLOPs, with bubble area representing parameter count. (d)–(f) OA versus latency, with bubble area representing peak memory. All values are obtained from the checkpoints selected under the unified efficiency-evaluation protocol.
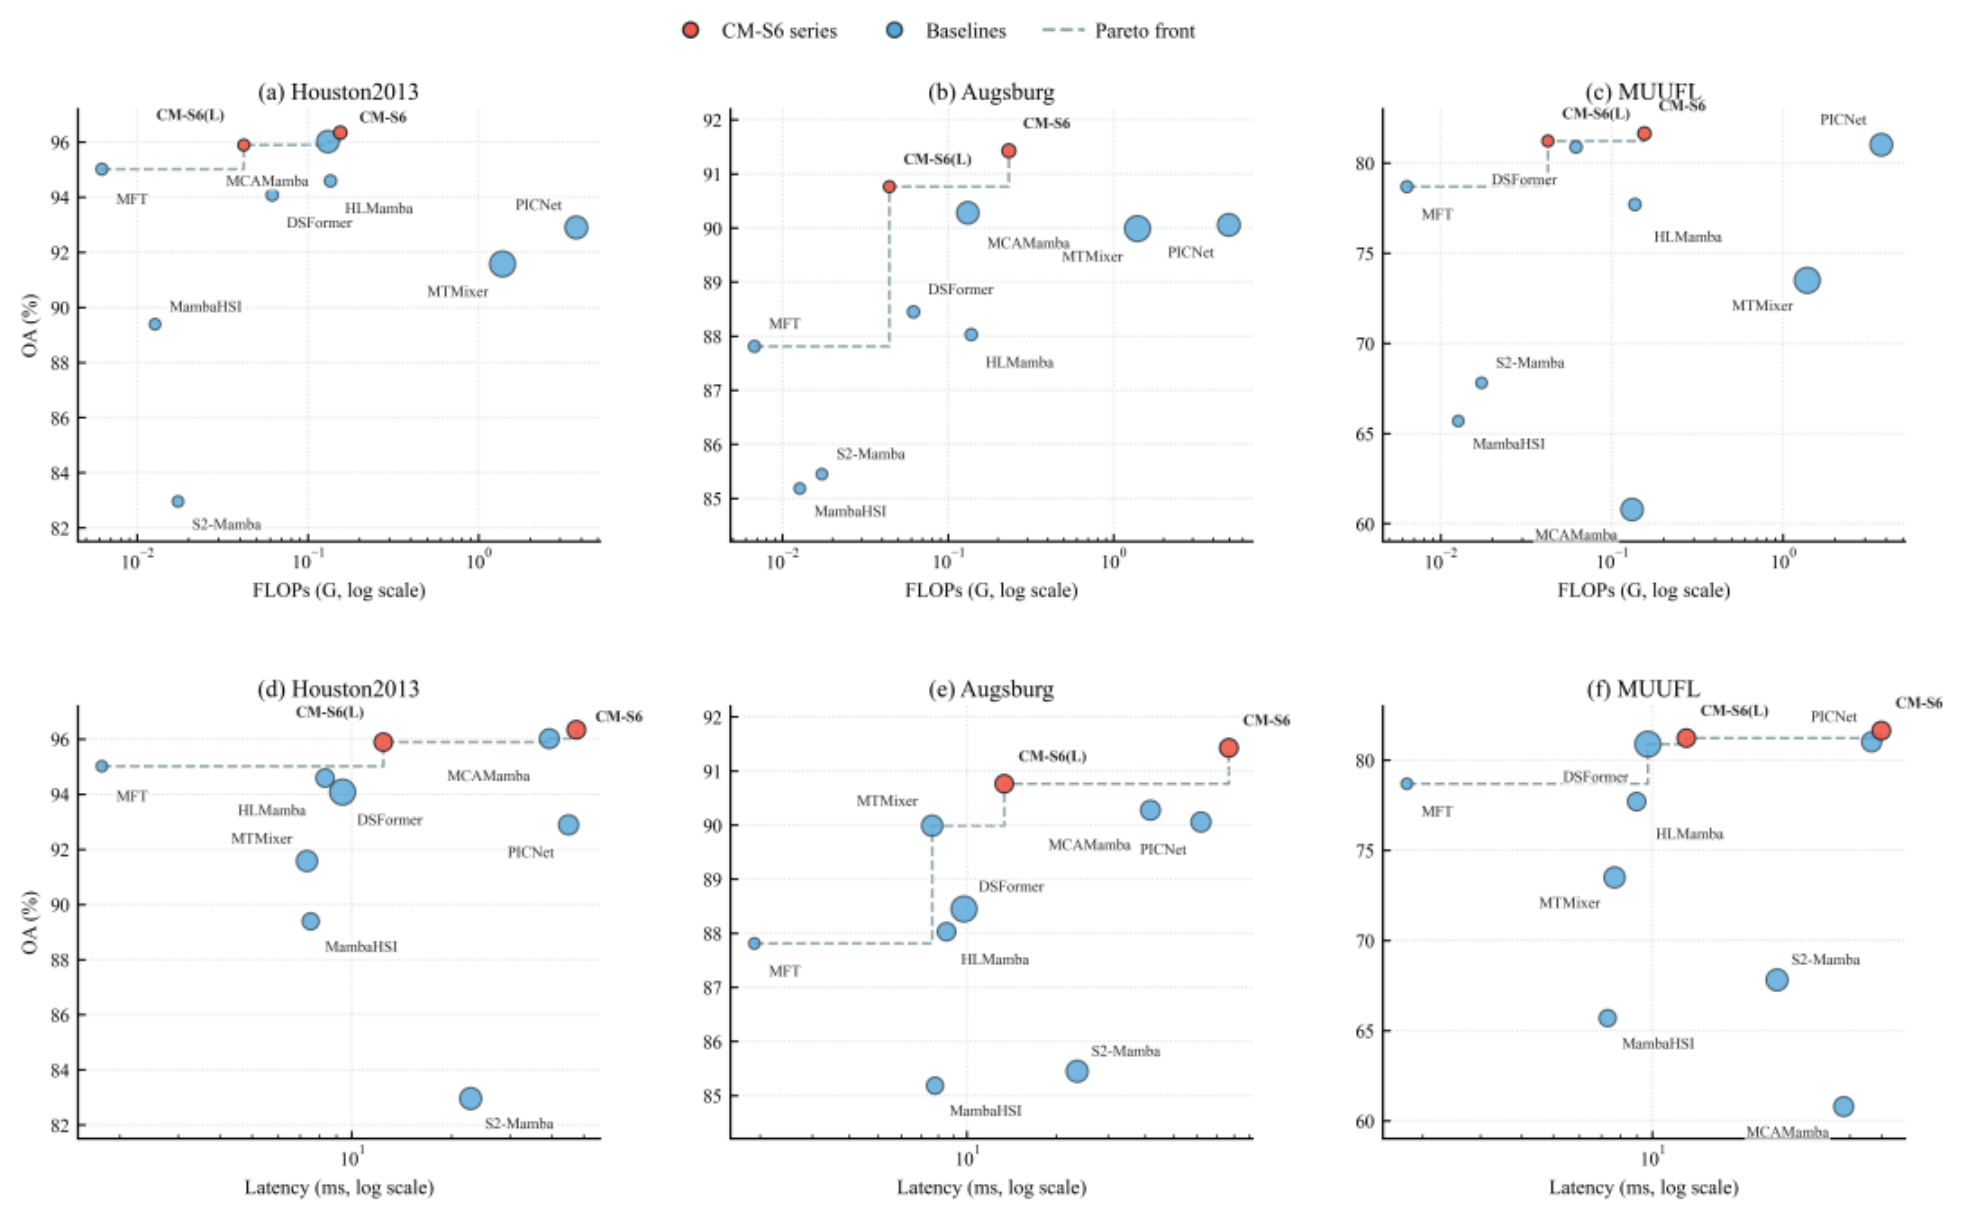
Figure 10.
Training trajectories of the five effective modulation coefficients for CM-S6 and CM-S6(L) on Houston 2013, Augsburg, and MUUFL. Each curve is the mean effective coefficient across all modulation blocks at each epoch. The shaded region denotes epochs 81–100 used for tail-stability statistics, and the markers denote the final values at epoch 100.
Figure 10.
Training trajectories of the five effective modulation coefficients for CM-S6 and CM-S6(L) on Houston 2013, Augsburg, and MUUFL. Each curve is the mean effective coefficient across all modulation blocks at each epoch. The shaded region denotes epochs 81–100 used for tail-stability statistics, and the markers denote the final values at epoch 100.
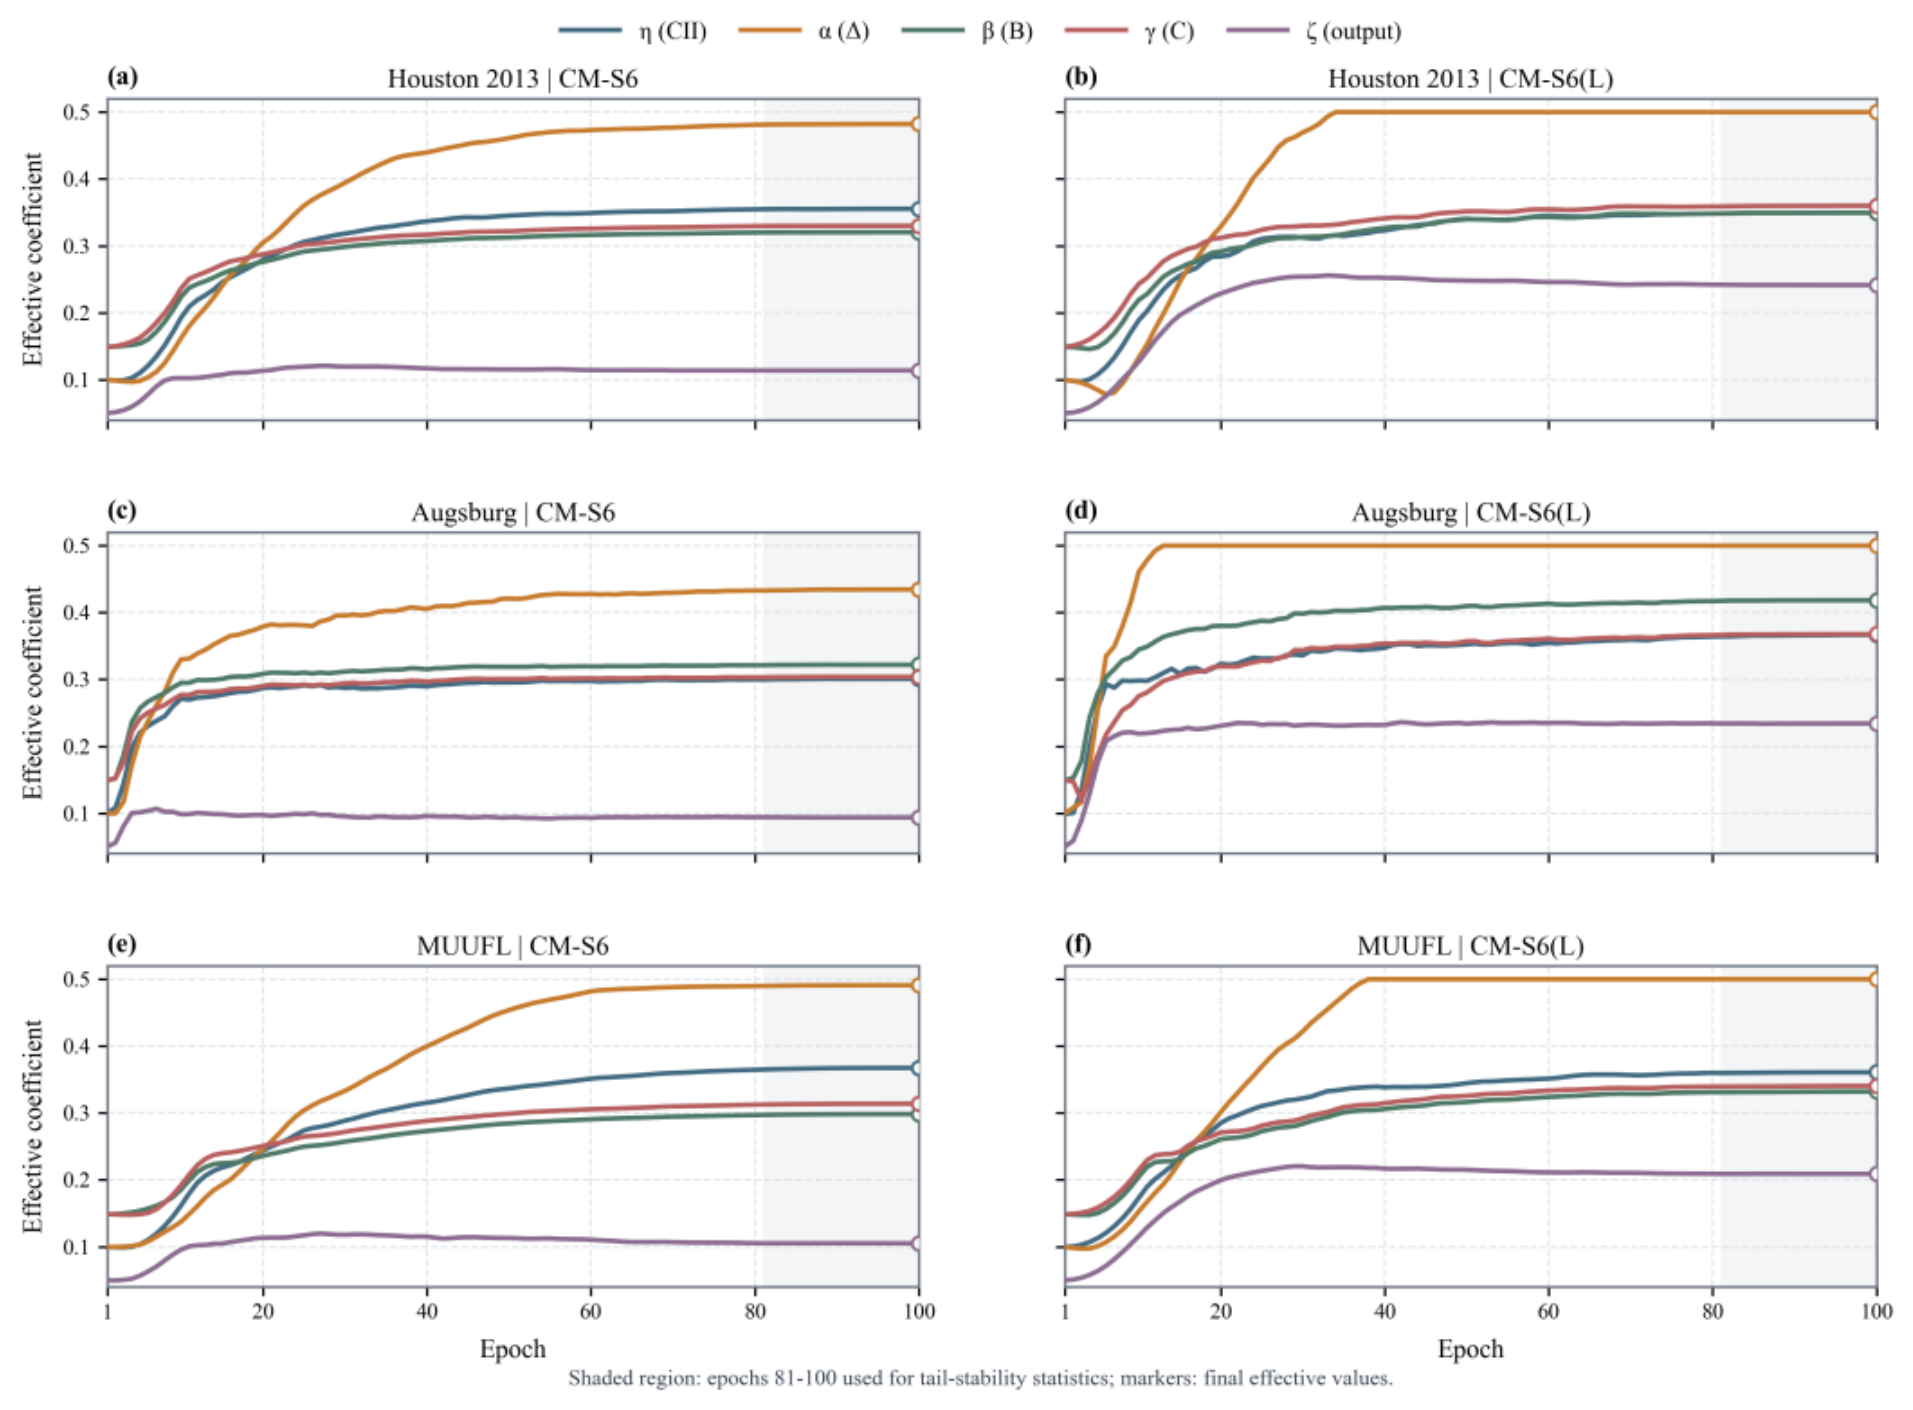
Figure 11.
Capacity-dependent reallocation of the final effective coefficients on the three datasets. Circles and squares denote CM-S6 and CM-S6(L), respectively, and the rightmost values report CM-S6(L) minus CM-S6. All values are taken from epoch 100 of run 1 with seed 42 and are descriptive rather than estimates of cross-run uncertainty.
Figure 11.
Capacity-dependent reallocation of the final effective coefficients on the three datasets. Circles and squares denote CM-S6 and CM-S6(L), respectively, and the rightmost values report CM-S6(L) minus CM-S6. All values are taken from epoch 100 of run 1 with seed 42 and are descriptive rather than estimates of cross-run uncertainty.
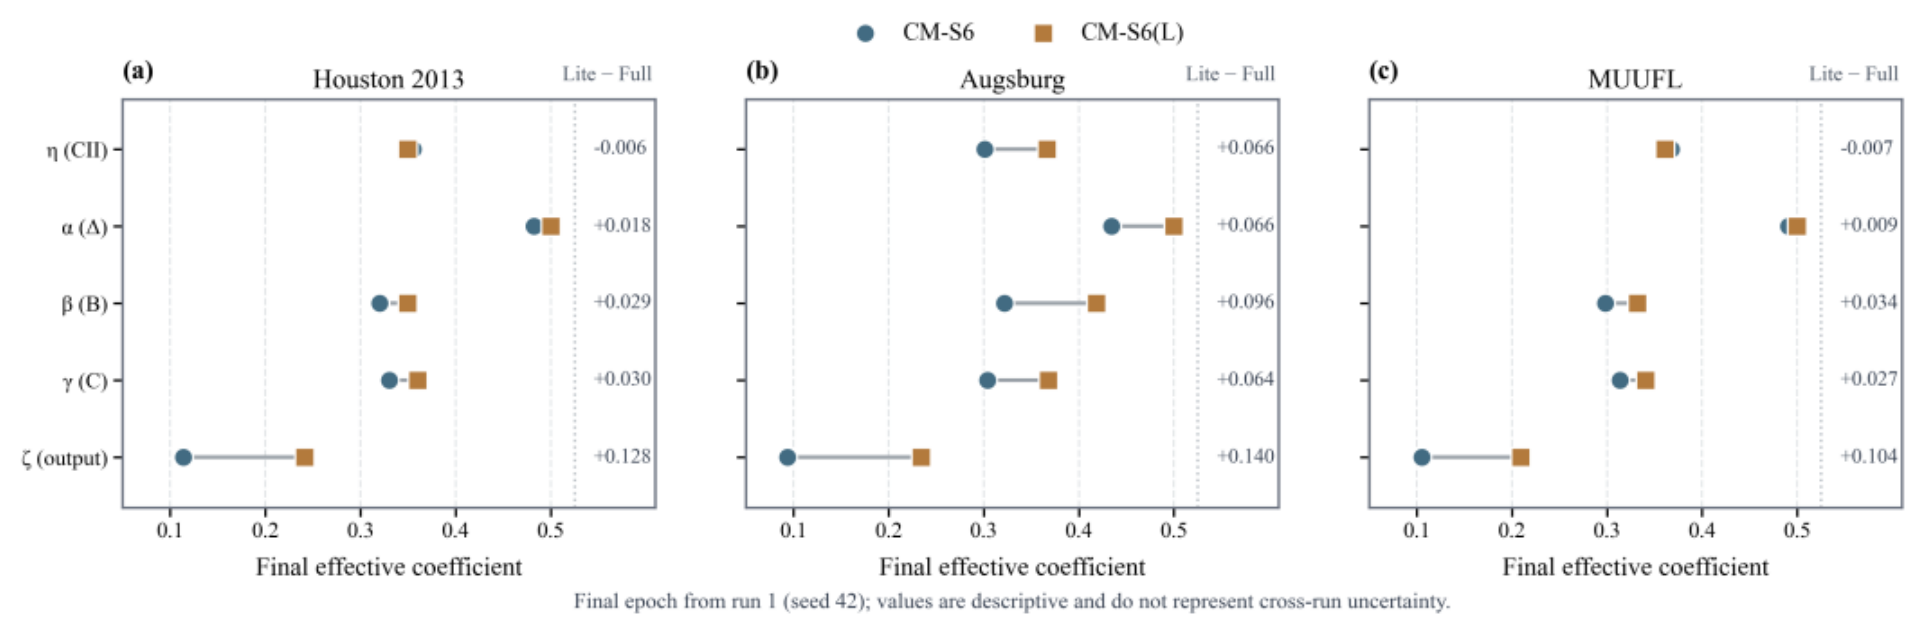
Table 1.
Comparison Results on the Houston 2013 Dataset.
| Class | Single-modal model | Multimodal model | ||||||||
|---|---|---|---|---|---|---|---|---|---|---|
| MambaHSI [6] | S2Mamba [7] |
DSFormer [38] |
PICNet [14] |
MFT [13] |
MTMixer [18] |
HLMamba [8] | MCAMamba [9] | CM-S6 (ours) |
CM-S6(L) (ours) |
|
| C1 | 89.36±1.20 | 86.81±0.91 | 96.47±0.76 | 95.08±1.13 | 95.24±1.28 | 96.51±1.14 | 96.23±1.26 | 95.41±1.41 | 97.57±0.40 | 97.20±0.61 |
| C2 | 92.97±1.15 | 87.07±7.06 | 97.96±0.54 | 94.99±1.66 | 96.55±1.29 | 96.61±2.61 | 98.48±0.52 | 98.60±0.30 | 96.54±0.88 | 95.73±0.80 |
| C3 | 98.60±0.17 | 99.50±0.15 | 99.32±0.12 | 99.82±0.25 | 99.38±0.06 | 99.87±0.19 | 99.70±0.16 | 99.96±0.07 | 99.66±0.18 | 99.53±0.09 |
| C4 | 97.30±1.15 | 89.38±4.35 | 98.24±0.73 | 99.08±0.50 | 97.81±0.68 | 99.48±0.51 | 99.98±0.03 | 99.03±0.51 | 98.91±0.31 | 98.43±0.43 |
| C5 | 95.68±1.62 | 97.23±2.69 | 99.92±0.09 | 99.74±0.39 | 100.00±0.0 | 100.00±0.0 | 99.80±0.23 | 99.98±0.03 | 100.00±0.0 | 100.00±0.0 |
| C6 | 88.93±3.78 | 85.44±0.39 | 94.43±2.14 | 95.38±2.49 | 96.46±2.01 | 96.72±2.14 | 98.89±1.11 | 92.72±4.91 | 97.87±0.52 | 94.20±1.87 |
| C7 | 95.47±0.29 | 94.97±0.85 | 97.20±0.64 | 90.58±1.95 | 95.00±0.64 | 97.66±1.37 | 98.81±0.81 | 97.04±0.83 | 99.93±0.11 | 98.29±1.03 |
| C8 | 76.76±2.49 | 61.98±7.00 | 83.87±3.41 | 86.81±1.61 | 94.97±1.75 | 93.37±2.16 | 87.60±5.16 | 94.31±2.12 | 92.01±1.25 | 93.16±2.51 |
| C9 | 83.14±0.23 | 80.76±2.26 | 80.03±0.38 | 83.47±2.40 | 85.81±1.61 | 84.70±1.69 | 81.22±1.68 | 84.31±1.66 | 84.03±2.08 | 83.43±1.01 |
| C10 | 93.23±2.51 | 86.79±5.41 | 99.32±0.88 | 90.85±2.12 | 97.80±0.28 | 98.35±1.75 | 94.95±4.33 | 99.67±0.35 | 99.41±0.70 | 99.23±1.21 |
| C11 | 89.44±1.59 | 88.71±5.04 | 99.18±0.63 | 93.23±3.59 | 99.06±0.31 | 97.75±1.89 | 98.39±0.64 | 98.28±0.91 | 99.75±0.42 | 99.98±0.08 |
| C12 | 75.84±3.67 | 58.04±4.95 | 84.50±2.73 | 82.62±3.53 | 84.95±3.77 | 81.53±0.74 | 85.16±5.37 | 92.92±0.33 | 88.80±2.28 | 85.79±2.78 |
| C13 | 94.49±0.29 | 94.48±0.59 | 95.32±0.28 | 93.83±0.85 | 94.08±0.23 | 93.34±1.73 | 95.23±0.39 | 91.34±1.65 | 93.43±1.85 | 93.59±0.42 |
| C14 | 92.16±2.37 | 99.71±0.24 | 99.61±0.45 | 98.21±1.23 | 98.92±0.99 | 99.95±0.16 | 99.36±0.59 | 100.00±0.0 | 100.00±0.0 | 100.00±0.0 |
| C15 | 99.73±0.28 | 100.00±0.0 | 100.00±0.0 | 99.97±0.07 | 100.00±0.0 | 100.00±0.0 | 100.00±0.0 | 100.00±0.0 | 100.00±0.0 | 100.00±0.0 |
| Params(M) | 0.12 | 0.12 | 0.30 | 19.13 | 0.22 | 36.08 | 0.28 | 22.93 | 0.66 | 0.19 |
| OA (%) |
90.11±0.68 | 85.54±2.39 | 94.43±0.28 | 92.71±0.44 | 95.29±0.28 | 95.23±0.26 | 94.87±0.75 | 96.21±0.19 | 96.16±0.18 | 95.60±0.25 |
| AA (%) |
90.87±0.64 | 87.39±1.92 | 95.02±0.22 | 93.58±0.37 | 95.73±0.29 | 95.72±0.27 | 95.59±0.63 | 96.24±0.34 | 96.53±0.18 | 95.90±0.24 |
| Kappa (%) |
89.31±0.74 | 84.37±2.57 | 93.98±0.30 | 92.12±0.48 | 94.91±0.30 | 94.84±0.28 | 94.45±0.81 | 95.90±0.21 | 95.85±0.20 | 95.25±0.27 |
Table 2.
Comparison Results on the Augsburg Dataset.
| Class | Single-modal model | Multimodal model | ||||||||
|---|---|---|---|---|---|---|---|---|---|---|
| MambaHSI [6] | S2Mamba [7] |
DSFormer [38] |
PICNet [14] |
MFT [13] |
MTMixer [18] |
HLMamba [8] | MCAMamba [9] | CM-S6 (ours) |
CM-S6(L) (ours) |
|
| C1 | 88.83±0.22 | 90.34±1.61 | 91.40±0.40 | 94.77±1.76 | 91.89±1.86 | 95.56±1.96 | 91.18±3.72 | 95.91±1.02 | 94.68±1.01 | 93.51±1.20 |
| C2 | 93.69±0.96 | 95.86±1.06 | 97.26±0.95 | 95.47±0.70 | 97.42±0.39 | 97.64±1.05 | 97.34±0.85 | 96.22±0.56 | 97.44±0.59 | 96.89±0.64 |
| C3 | 53.46±3.17 | 76.89±7.01 | 73.52±6.33 | 60.05±9.26 | 65.88±6.29 | 64.15±12.6 | 73.52±10.8 | 65.03±8.74 | 63.91±9.17 | 70.71±5.14 |
| C4 | 85.73±1.91 | 83.00±1.65 | 89.59±0.93 | 94.10±1.85 | 89.77±1.36 | 94.72±1.71 | 91.49±1.63 | 93.83±1.21 | 95.90±0.81 | 90.73±1.07 |
| C5 | 58.89±2.53 | 58.01±1.00 | 59.04±4.07 | 57.95±4.31 | 60.65±5.40 | 64.53±12.0 | 64.20±8.20 | 55.64±3.59 | 60.38±5.32 | 59.62±2.99 |
| C6 | 31.58±2.14 | 17.85±10.2 | 13.06±1.16 | 23.72±6.14 | 15.64±3.74 | 25.02±13.5 | 14.88±6.55 | 25.20±8.54 | 26.89±11.3 | 15.83±5.46 |
| C7 | 41.86±11.2 | 29.20±11.2 | 33.80±7.29 | 51.17±5.29 | 45.55±9.53 | 49.58±5.50 | 39.30±17.2 | 51.44±6.21 | 39.27±7.41 | 30.87±9.90 |
| Params(M) | 0.12 | 0.12 | 0.3 | 18.67 | 0.22 | 35.8 | 0.28 | 22.92 | 0.98 | 0.19 |
| OA (%) |
85.58±0.51 | 86.36±0.51 | 89.17±0.40 | 90.50±0.63 | 89.30±1.00 | 91.93±0.44 | 90.00±1.20 | 91.16±0.43 | 91.91±0.49 | 89.65±0.51 |
| AA (%) |
64.86±1.93 | 64.45±1.48 | 65.38±0.70 | 68.18±0.86 | 66.69±1.50 | 70.17±2.28 | 67.41±2.39 | 69.04±1.43 | 68.35±1.75 | 65.45±1.31 |
| Kappa (%) |
79.72±0.69 | 80.82±0.68 | 84.62±0.50 | 86.50±0.87 | 84.83±1.40 | 88.44±0.64 | 85.86±1.60 | 87.43±0.55 | 88.40±0.71 | 85.30±0.69 |
Table 3.
Comparison Results on the MUUFL Gulfport Dataset.
| Class | Single-modal model | Multimodal model | ||||||||
|---|---|---|---|---|---|---|---|---|---|---|
| MambaHSI [6] | S2Mamba [7] |
DSFormer [38] |
PICNet [14] |
MFT [13] |
MTMixer [18] |
HLMamba [8] | MCAMamba [9] | CM-S6 (ours) |
CM-S6(L) (ours) |
|
| C1 | 80.97±1.48 | 79.88±0.49 | 85.29±1.61 | 78.96±3.24 | 83.52±1.43 | 82.49±2.87 | 82.03±2.46 | 80.82±1.42 | 86.03±1.59 | 83.28±1.56 |
| C2 | 55.68±1.58 | 60.01±5.28 | 55.37±7.62 | 71.73±3.97 | 58.78±5.94 | 68.94±9.97 | 85.00±4.10 | 72.55±3.54 | 60.28±4.93 | 61.15±4.35 |
| C3 | 46.59±7.33 | 49.86±5.00 | 75.66±2.84 | 65.66±4.39 | 67.79±1.67 | 74.79±8.70 | 62.01±14.9 | 66.47±4.31 | 70.29±3.15 | 67.05±2.34 |
| C4 | 86.08±2.13 | 93.20±0.52 | 91.32±1.32 | 86.56±3.71 | 90.84±0.68 | 92.20±2.91 | 95.64±1.67 | 92.98±2.06 | 91.16±1.88 | 92.14±2.13 |
| C5 | 59.23±1.50 | 61.72±8.42 | 83.47±4.41 | 83.08±2.56 | 81.46±1.85 | 85.30±4.31 | 78.65±8.99 | 81.50±1.31 | 83.94±4.09 | 81.17±3.14 |
| C6 | 99.01±0.41 | 99.46±0.20 | 100.00±0.0 | 99.71±0.32 | 100.00±0.0 | 90.09±31.3 | 61.03±44.4 | 100.00±0.0 | 99.98±0.07 | 99.96±0.09 |
| C7 | 70.78±2.93 | 77.85±4.09 | 83.25±2.21 | 89.43±5.11 | 86.82±4.26 | 89.55±5.01 | 82.16±4.60 | 90.60±3.28 | 87.15±1.94 | 87.81±2.74 |
| C8 | 58.27±5.09 | 57.30±2.33 | 90.86±2.80 | 90.99±1.09 | 93.14±2.34 | 89.80±6.38 | 95.33±2.50 | 91.82±1.00 | 94.92±1.16 | 93.78±1.36 |
| C9 | 50.14±1.34 | 49.14±3.13 | 50.80±5.04 | 61.25±5.04 | 46.62±3.38 | 56.81±9.55 | 54.90±3.76 | 52.95±2.72 | 50.81±4.27 | 53.17±2.79 |
| C10 | 64.91±2.58 | 75.34±3.51 | 72.02±8.01 | 81.35±4.96 | 69.20±1.91 | 76.99±13.1 | 50.92±30.5 | 90.92±3.24 | 66.99±7.68 | 69.51±3.98 |
| C11 | 99.60±0.00 | 99.60±0.00 | 99.36±0.54 | 98.27±1.67 | 99.44±0.22 | 98.76±1.20 | 99.44±0.36 | 99.60±0.00 | 99.20±0.89 | 99.56±0.13 |
| Params (M) | 0.12 | 0.12 | 0.3 | 19.1 | 0.22 | 36.08 | 0.3 | 22.93 | 0.66 | 0.19 |
| OA (%) | 68.35±1.80 | 69.38±1.55 | 81.48±0.64 | 79.10±1.17 | 80.01±0.89 | 81.71±1.49 | 80.41±1.56 | 80.07±0.35 | 82.18±0.46 | 80.29±0.54 |
| AA (%) | 70.11±0.99 | 73.03±1.99 | 80.67±0.85 | 82.45±1.18 | 79.78±0.56 | 82.34±3.62 | 77.01±5.91 | 83.65±0.46 | 80.98±0.89 | 80.78±0.55 |
| Kappa (%) | 60.24±2.12 | 61.61±1.90 | 76.26±0.73 | 73.63±1.31 | 74.53±1.06 | 76.73±1.76 | 75.14±2.08 | 74.80±0.38 | 77.15±0.58 | 74.94±0.62 |
Table 4.
Paired significance tests of OA between CM-S6 and three strong baselines. The difference is computed as CM-S6 minus the comparison method.
Table 4.
Paired significance tests of OA between CM-S6 and three strong baselines. The difference is computed as CM-S6 minus the comparison method.
| Dataset | Baseline | OA difference (pp) | 95% CI (pp) | Raw p-value | Holm-adjusted p-value |
|---|---|---|---|---|---|
| Houston 2013 | PICNet | +3.447 | [3.064, 3.830] | 7.70×10⁻⁹* | 2.31×10⁻⁸* |
| Houston 2013 | MTMixer | +0.929 | [0.767, 1.091] | 3.98×10⁻⁷* | 7.96×10⁻⁷* |
| Houston 2013 | MCAMamba | −0.052 | [−0.213, 0.110] | 0.4876 | 0.4876 |
| Augsburg | PICNet | +1.406 | [0.795, 2.017] | 5.61×10⁻⁴* | 1.68×10⁻³* |
| Augsburg | MTMixer | −0.026 | [−0.551, 0.499] | 0.9140 | 0.9140 |
| Augsburg | MCAMamba | +0.748 | [0.399, 1.097] | 9.16×10⁻⁴* | 1.83×10⁻³* |
| MUUFL | PICNet | +3.076 | [2.407, 3.745] | 2.57×10⁻⁶* | 5.13×10⁻⁶* |
| MUUFL | MTMixer | +0.464 | [−0.630, 1.557] | 0.3624 | 0.3624 |
| MUUFL | MCAMamba | +2.111 | [1.784, 2.438] | 1.42×10⁻⁷* | 4.27×10⁻⁷* |
Table 5.
(a). Ablation results on the Houston 2013 dataset. (b). Ablation results on the Augsburg dataset. (c). Ablation results on the MUUFL Gulfport dataset.
Table 5.
(a). Ablation results on the Houston 2013 dataset. (b). Ablation results on the Augsburg dataset. (c). Ablation results on the MUUFL Gulfport dataset.
| (a) | |||||||||
| Settings | ղ | α | β | γ | ζ | Params(M) | OA(%) | AA(%) | Kappa(%) |
| A0 | × | × | × | × | × | 0.4787 | 94.81±0.36 | 94.98±0.32 | 94.39±0.39 |
| A1 | × | × | × | × | × | 0.4804 | 95.44±0.36 | 95.88±0.29 | 95.06±0.39 |
| A2 | √ | × | × | × | × | 0.5368 | 96.17±0.21 | 96.53±0.18 | 95.86±0.23 |
| A3 | √ | √ | × | × | × | 0.6113 | 95.90±0.13 | 96.30±0.13 | 95.57±0.14 |
| A4 | √ | √ | √ | × | × | 0.6182 | 96.20±0.18 | 96.57±0.15 | 95.89±0.19 |
| A5 | √ | √ | √ | √ | × | 0.6251 | 96.08±0.17 | 96.12±0.22 | 95.79±0.18 |
| A6 | √ | √ | √ | √ | √ | 0.6628 | 96.16±0.17 | 96.60±0.17 | 95.88±0.19 |
| A7 | × | √ | √ | √ | √ | 0.5883 | 96.14±0.18 | 96.54±0.16 | 95.82±0.20 |
| A8 | √ | × | √ | √ | √ | 0.5883 | 96.17±0.33 | 96.56±0.22 | 95.86±0.36 |
| A9 | √ | √ | × | √ | √ | 0.6558 | 96.07±0.38 | 96.47±0.34 | 95.75±0.41 |
| A10 | √ | √ | √ | × | √ | 0.6558 | 96.06±0.34 | 96.44±0.33 | 95.74±0.37 |
| A11 | √ | √ | √ | √ | × | 0.6251 | 96.08±0.17 | 96.12±0.22 | 95.79±0.18 |
| A12 | √ | × | × | × | √ | 0.5744 | 96.24±0.29 | 96.61±0.23 | 95.94±0.31 |
| A13 | × | √ | √ | √ | × | 0.5506 | 96.10±0.12 | 96.48±0.12 | 95.79±0.13 |
| A14 | √ | √ | √ | √ | √ | 0.1879 | 95.60±0.25 | 95.90±0.24 | 95.25±0.27 |
| (b) | |||||||||
| Settings | ղ | α | β | γ | ζ | Params(M) | OA(%) | AA(%) | Kappa(%) |
| A0 | × | × | × | × | × | 0.7118 | 88.38±0.28 | 63.51±0.68 | 83.52±0.40 |
| A1 | × | × | × | × | × | 0.7248 | 90.60±0.42 | 67.08±0.93 | 86.59±0.58 |
| A2 | √ | × | × | × | × | 0.7933 | 91.48±0.17 | 69.23±1.51 | 87.80±0.25 |
| A3 | √ | √ | × | × | × | 0.9051 | 91.32±0.27 | 66.68±1.86 | 87.55±0.42 |
| A4 | √ | √ | √ | × | × | 0.9154 | 91.45±0.75 | 67.70±1.92 | 87.72±1.05 |
| A5 | √ | √ | √ | √ | × | 0.9258 | 91.21±0.76 | 66.83±2.31 | 87.42±1.04 |
| A6 | √ | √ | √ | √ | √ | 0.9823 | 91.91±0.47 | 68.35±1.66 | 88.40±0.67 |
| A7 | × | √ | √ | √ | √ | 0.8705 | 91.29±0.33 | 67.37±2.90 | 87.51±0.48 |
| A8 | √ | × | √ | √ | √ | 0.8705 | 91.52±0.31 | 68.81±0.93 | 87.85±0.44 |
| A9 | √ | √ | × | √ | √ | 0.9719 | 91.46±0.64 | 68.09±1.97 | 87.78±0.90 |
| A10 | √ | √ | √ | × | √ | 0.9719 | 91.18±0.42 | 68.35±1.28 | 87.39±0.59 |
| A11 | √ | √ | √ | √ | × | 0.9258 | 91.21±0.76 | 66.83±2.31 | 87.42±1.04 |
| A12 | √ | × | × | × | √ | 0.8498 | 91.62±0.65 | 67.92±1.06 | 87.99±0.89 |
| A13 | × | √ | √ | √ | × | 0.8141 | 91.48±0.45 | 66.31±0.50 | 87.76±0.62 |
| A14 | √ | √ | √ | √ | √ | 0.1909 | 89.65±0.51 | 65.45±1.31 | 85.30±0.69 |
| (c) | |||||||||
| Settings | ղ | α | β | γ | ζ | Params(M) | OA(%) | AA(%) | Kappa(%) |
| A0 | × | × | × | × | × | 0.4783 | 78.84±0.58 | 78.93±0.33 | 73.04±0.65 |
| A1 | × | × | × | × | × | 0.4818 | 79.75±0.46 | 79.59±0.93 | 74.24±0.52 |
| A2 | √ | × | × | × | × | 0.5373 | 81.29±0.68 | 80.52±0.90 | 76.05±0.80 |
| A3 | √ | √ | × | × | × | 0.6118 | 81.93±0.70 | 81.57±0.33 | 76.87±0.84 |
| A4 | √ | √ | √ | × | × | 0.6187 | 82.04±0.67 | 81.39±0.53 | 77.02±0.82 |
| A5 | √ | √ | √ | √ | × | 0.6256 | 81.50±0.56 | 81.07±0.76 | 76.32±0.68 |
| A6 | √ | √ | √ | √ | √ | 0.6632 | 82.18±0.46 | 80.98±0.89 | 77.15±0.58 |
| A7 | × | √ | √ | √ | √ | 0.5887 | 81.02±0.43 | 80.76±0.38 | 75.73±0.48 |
| A8 | √ | × | √ | √ | √ | 0.5887 | 81.73±0.90 | 81.22±0.62 | 76.62±1.08 |
| A9 | √ | √ | × | √ | √ | 0.6563 | 82.20±0.78 | 81.04±0.49 | 77.17±0.92 |
| A10 | √ | √ | √ | × | √ | 0.6563 | 82.26±0.69 | 81.06±0.62 | 77.25±0.81 |
| A11 | √ | √ | √ | √ | × | 0.6256 | 81.50±0.56 | 81.07±0.76 | 76.32±0.68 |
| A12 | √ | × | × | × | √ | 0.5749 | 81.22±0.28 | 80.47±0.50 | 75.94±0.34 |
| A13 | × | √ | √ | √ | × | 0.5511 | 81.70±0.87 | 81.09±0.67 | 76.57±1.05 |
| A14 | √ | √ | √ | √ | √ | 0.1884 | 80.29±0.54 | 80.78±0.55 | 74.94±0.62 |
Table 6.
(a). Model size, FLOPs, and selected-checkpoint OA on the three datasets. (b). Measured runtime efficiency on the three datasets. (c). Efficiency changes of CM-S6(L) relative to full CM-S6. The OA gap is computed as full-model OA minus lightweight-model OA.
Table 6.
(a). Model size, FLOPs, and selected-checkpoint OA on the three datasets. (b). Measured runtime efficiency on the three datasets. (c). Efficiency changes of CM-S6(L) relative to full CM-S6. The OA gap is computed as full-model OA minus lightweight-model OA.
| (a) | |||||||||||||||||||||
| Models | Houston 2013 | Augsburg | MUUFL | ||||||||||||||||||
|
Params (M) |
FLOPs (G) |
OA (%) |
Params (M) |
FLOPs (G) |
OA (%) |
Params (M) |
FLOPs (G) |
OA (%) |
|||||||||||||
| MambaHSI | 0.1210 | 0.0127 | 89.39 | 0.1200 | 0.0127 | 85.19 | 0.1205 | 0.0127 | 65.69 | ||||||||||||
| S²Mamba | 0.1155 | 0.0173 | 82.97 | 0.1150 | 0.0173 | 85.45 | 0.1153 | 0.0173 | 67.81 | ||||||||||||
| DSFormer | 0.3026 | 0.0618 | 94.08 | 0.3021 | 0.0618 | 88.45 | 0.3023 | 0.0618 | 80.89 | ||||||||||||
| PICNet | 19.1257 | 3.7389 | 92.90 | 18.6686 | 4.9596 | 90.06 | 18.4867 | 3.7389 | 81.02 | ||||||||||||
| MFT | 0.2227 | 0.0062 | 95.02 | 0.2245 | 0.0068 | 87.81 | 0.2230 | 0.0063 | 78.70 | ||||||||||||
| MTMixer | 35.4540 | 1.3823 | 91.58 | 35.4270 | 1.3905 | 89.99 | 35.4530 | 1.3823 | 73.50 | ||||||||||||
| HLMamba | 0.2997 | 0.1355 | 94.60 | 0.2998 | 0.1377 | 88.03 | 0.2995 | 0.1360 | 77.71 | ||||||||||||
| MCAMamba | 22.9309 | 0.1310 | 96.02 | 23.9161 | 0.1316 | 90.28 | 22.9307 | 0.1312 | 60.78 | ||||||||||||
| CM-S6 | 0.6628 | 0.1546 | 96.34 | 0.9823 | 0.2327 | 91.43 | 0.6632 | 0.1548 | 81.65 | ||||||||||||
| CM-S6(L) | 0.1879 | 0.0421 | 95.90 | 0.1909 | 0.0441 | 90.76 | 0.1884 | 0.0423 | 81.23 | ||||||||||||
| (b) | |||||||||||||||||||||
| Models | Houston 2013 | Augsburg | MUUFL | ||||||||||||||||||
|
Latency (ms) |
Through put (sample/s) |
Peak memory (MB) |
Latency (ms) |
Through put (sample/s) |
Peak memory (MB) |
Latency (ms) |
Through put (sample/s) |
Peak memory (MB) |
|||||||||||||
| MambaHSI | 7.520 | 1599.12 | 103.09 | 7.798 | 1740.57 | 103.16 | 7.306 | 1782.39 | 103.10 | ||||||||||||
| S²Mamba | 22.794 | 705.69 | 330.79 | 23.548 | 689.81 | 330.86 | 23.960 | 681.27 | 330.80 | ||||||||||||
| DSFormer | 9.382 | 576.24 | 681.48 | 9.777 | 572.29 | 681.54 | 9.687 | 576.21 | 681.49 | ||||||||||||
| PICNet | 44.999 | 343.10 | 218.73 | 61.697 | 247.74 | 216.18 | 46.251 | 338.45 | 215.43 | ||||||||||||
| MFT | 1.764 | 8770.65 | 11.40 | 1.910 | 8085.47 | 11.47 | 1.788 | 8744.63 | 11.41 | ||||||||||||
| MTMixer | 7.323 | 2141.86 | 280.53 | 7.630 | 2081.16 | 280.49 | 7.679 | 2108.65 | 280.53 | ||||||||||||
| HLMamba | 8.305 | 1952.22 | 145.74 | 8.518 | 1885.91 | 146.01 | 8.954 | 1832.63 | 145.80 | ||||||||||||
| MCAMamba | 39.363 | 405.08 | 207.41 | 41.648 | 381.31 | 207.46 | 38.210 | 421.52 | 207.41 | ||||||||||||
| CM-S6 | 47.535 | 341.87 | 149.54 | 76.713 | 212.35 | 153.36 | 49.777 | 312.49 | 149.55 | ||||||||||||
| CM-S6(L) | 12.446 | 1319.79 | 144.30 | 13.349 | 1235.27 | 145.09 | 12.685 | 1265.29 | 144.31 | ||||||||||||
| (c) | |||||||||||||||||||||
| Dataset | Params ↓ | FLOPs ↓ | Latency ↓ | Throughput↑ |
OA gap (pp) |
||||||||||||||||
| Houston 2013 | 71.65% | 72.77% | 72.82% | 3.86× | 0.441 | ||||||||||||||||
| Augsburg | 80.57% | 81.03% | 82.60% | 5.82× | 0.663 | ||||||||||||||||
| MUUFL | 71.59% | 72.67% | 74.52% | 4.05× | 0.423 | ||||||||||||||||
Table 7.
Final effective values of the five coefficients for CM-S6 and CM-S6(L) on the three datasets. Max tail std is the largest standard deviation among the five coefficients over the final 20 epochs. The stable-epoch range is computed using |ρₜ − ρ₁₀₀| ≤ 0.005.
Table 7.
Final effective values of the five coefficients for CM-S6 and CM-S6(L) on the three datasets. Max tail std is the largest standard deviation among the five coefficients over the final 20 epochs. The stable-epoch range is computed using |ρₜ − ρ₁₀₀| ≤ 0.005.
| Dataset | Variant | η | α | β | γ | ζ | Max tail std | Stable epoch range |
| Houston 2013 | CM-S6 | 0.3554 | 0.4822 | 0.3204 | 0.3301 | 0.1139 | 2.81×10⁻⁴ | 37–71 |
| Houston 2013 | CM-S6(L) | 0.3495 | 0.5000 | 0.3496 | 0.3600 | 0.2415 | 3.60×10⁻⁴ | 34–67 |
| Augsburg | CM-S6 | 0.3009 | 0.4345 | 0.3219 | 0.3038 | 0.0938 | 5.31×10⁻⁴ | 27–70 |
| Augsburg | CM-S6(L) | 0.3666 | 0.5000 | 0.4184 | 0.3677 | 0.2342 | 7.15×10⁻⁴ | 13–75 |
| MUUFL | CM-S6 | 0.3675 | 0.4910 | 0.2984 | 0.3139 | 0.1053 | 7.82×10⁻⁴ | 61–75 |
| MUUFL | CM-S6(L) | 0.3608 | 0.5000 | 0.3321 | 0.3405 | 0.2091 | 3.77×10⁻⁴ | 38–66 |
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.
Copyright: This open access article is published under a Creative Commons CC BY 4.0 license, which permit the free download, distribution, and reuse, provided that the author and preprint are cited in any reuse.