

Submitted:
30 September 2026
Posted:
02 October 2026
You are already at the latest version
Abstract
Following Livadiotis G. and McComas D. J. (2023) [1], we propose a new type of single-stand (ss)DNA/RNA frameshift mutations that occur spontaneously due to information exchange between the ssDNA sequence of length bases (N) and the mutation sequence of length bases (M), and respect the kappa-addition symbol ⊕κ. We call these proposed mutations Kappa-Frameshift Background (KFB) mutations. We find that entropy defects originate in the interdependence of the information length systems (or their interconnectedness, that is, the state in which systems with a significant number of constituents (information length bases) depend on, or are connected with each other by the proposed KFB-mutation). We also quantify the correlation among ssDNA/RNA information length bases (N) and (M) due to information exchange. In the presence of entropy defects, the Landauer’s bound and minimal metabolic rate for a biological system is modified. We observe that the different N and κ scales are manifested in the double evolutionary emergence of the proposed biological system through subsystems correlations. For specific values of the kappa parameter we can expect deterministic laws associated with a single biological polymer in the short term; over time, before the polymer explores all the possible ways it can exist.
Keywords:
informational‐entropy
; mutations
; correlations
; ssDNA/RNA base sequences
1. Introduction
Informational entropy analysis is often used in biology. The meaning of information entropy in molecular biology and evolution, however, should be distinguished from that of thermodynamic entropy [2,3,4,5,6,7,8,9,10,11,12,13,14,15,16,17,18,19,20,21,22,23,24,25,26]. The genetic information in DNA supplies straightforward examples for the informational entropy concept. The characteristic nucleotide sequence of the four bases (Adenine A, Guanine G, Cytosine C, and Thymine T) in an organism’s DNA is the same in all cells of the organism, and results in the combination of random mutations and functional selection during biological evolution. There is no preference for a specific sequence; different ssDNA sequences are equally possible (with being the number of bases in the ssDNA sequence, ranging from one million in bacteria to billions in many animals and plants), and the actual ssDNA sequence in an organism has only a probability. Therefore, the space of the possible configurations of molecules within an organism is astronomically large. We may assume that the system is “non-ergodic” in the sense that not every part of the configuration space can be explored [3,27,28,29,30]. There are several major reasons to expect convergence [3]. Firstly, all evolutionary trajectories occur under certain generic selective constraints, such as the laws of mathematics, physics, and chemistry; these should lead to some universal features [31,32]. For instance, a novel quantum system (quantum dots) recently proposed by the author (2024) [33], due its peculiar quantum state–a Diophantine Markov state, would be trapped in a sequence of self-replicating states. This system would never reach a classical limit, no matter how big the cube the since gaps between states are always finite). Secondly, many of these spaces are not explored randomly [34,35,36,37,38,39,40,41,42,43]. Finally, evolutionary trajectories happen within a certain system: Darwinian evolution will act on populations of entities which emerge within assembly spaces [44,45,46]. They are constructed from components over evolutionary timescales. These factors shape evolution, and shift the way one should think about sequence search conditioned on the past. The logic of assembly spaces may lead to certain types of universal convergence [3,46].
DNA replication can lead to the introduction of small insertions or deletions of base pairs (insertion or deletion mutations, respectively). As shown in [47], the loss or addition of a single nucleotide causes all of the subsequent three-letter codons to change [48]. These mutations are called frameshift mutations because the frame of the triplet reading is altered during translation. A frameshift mutation occurs when any number of bases are added or deleted, except multiples of three which reestablish the initial reading frame.
Kappa-distributions emerge within the framework of statistical mechanics by maximizing the associated kappa-entropy under the constraints of the canonical ensemble (e.g., Livadiotis G. and McComas D. J. (2009, 2014, 2023) [1,49,50]). Kappa-distributions are consistent with thermodynamics, but this consistency alone cannot justify their generation and existence. Examples of kappa-distribution include super-statistics [51,52,53,54,55,56], the effect of shock waves [57], turbulence [58,59,60], the effect of pickup ions [61,62,63], the pump acceleration mechanism [64], colloidal particles [65], and polytropic behavior [66,67]. For all these phenomena, there is a unique thermodynamic origin. The existence of correlations among the particles of a system does not permit the usage of the classical framework based on Boltzmann [68]—Gibbs [69] (BG) entropy and the Maxwell–Boltzmann (MB)[70] canonical distribution of particle velocity (). The thermodynamic origin of kappa-distributions has recently been connected to the new concept of “entropy defect”, proposed by G. Livadiotis G. and D.J. McComas (2021) [71,72]. Recently, Livadiotis and McComas (2023) [1] introduced a specific algebra of the addition rule with entropy defect. The addition rule forms a mathematical Abelian group on the set of any measurable physical-quantity (including entropy), called the kapa-addition and referred to by the symbol. The physical meaning of the kappa index can be understood through particle (subsystems) correlations: the kappa index provides a measure of the loss (for ) or gain (for ) of entropy after the mixing of the partial systems A and B to compose the combined system [1].
Shannon, Rényie and Tsallis entropy analysis of DNA have been cited by J.A. Tenreiro Machadoa et.al [73]. Dynamics of a single base point genome mutation (T into A) using non-equilibrium information theory have been stated by Melvin M. Vopson, Samuel C. Robson [74,75]. Following Livadiotis and McComas (2023) [1], we propose a new type of ssDNA frameshift mutations that occur spontaneously due to information exchange between the ssDNA sequence of length bases () and the mutation sequence of length base (M), and respect the kappa-addition symbol . We call these proposed mutations Kappa-Frameshift Background (KFB) Mutations. We find that the origin of an entropy defect is based on the interdependence of the information length systems (or their interconnectedness, that is, the dependence, or connection, of systems with a significant number of constituents (information length bases). The proposed KFB mutations quantify the correlations among the information length bases–constituents of these systems–due to information exchanges. In the presence of entropy defects, the Landauer’s bound and the minimal metabolic rate for a biological system are modified. We observe that the different and scales are manifested in the evolution of the proposed biological system through subsystems correlations. In this evolution, for short time scales and specific values of the kappa-parameter, we can expect deterministic laws associated with a single biological polymer.
2. Kappa-Frameshift Background Single-Stand DNA Mutations
Spontaneous DNA mutations occur suddenly and their origin is unknown. Such mutations, also called “background mutations”, have been reported in many organisms, such as Oenothera, maize, bread molds, microorganisms (bacteria and viruses), Drosophila, mice, humans, etc. (see Ref [48] for details). A frameshift mutation occurs when any number of bases are added or deleted during DNA replication, except multiples of three which reestablish the initial reading frame. Mutations of multiples of three nucleotides just add one or several reading frames into the sequence without altering the composition of those reading frames thereafter. It is possible, however, that the frameshift mutation causes early termination of the translation (e.g., when a 3-nucleotide stop codon sequence is introduced). Frameshift mutations can, therefore, have very severe results if they occur early in the coding sequence. Frameshift mutations can occur at microsatellites (tandem repeats of 1–6 base pairs per repeat unit) and also at non-iterated or short repetitive sequences. Proofreading can remove insertion or deletion mutations in short repetitive and non-iterated sequences with almost the same efficiency as that for point mutations; however, it is much less efficient in removing frameshift mutations in homopolymeric runs [47]. These mutations are removed efficiently by mismatch repair systems. The instability of microsatellite sequences is associated with many diseases, including cancer [48].
Since DNA is double-stranded (ds), bases should be base pairs. In the present paper we only use the 5'–3' sequence, while the other sequence is implied. The 5'–3' sequence denotes a single strand of a nucleic acid (ssDNA or RNA). Following Livadiotis and McComas (2023) [1], we propose a new type of ssDNA frameshift mutations that occur spontaneously due to information exchange between the ssDNA sequence of base lengths () and the mutation sequence of base lengths (M), and respect the kappa addition (). We call these proposed mutations Kappa-Frameshift Background (KFB) mutations. KFB mutations will occur when any number of basesare added or deleted to the initial ssDNA sequencewhile respecting (except multiples of three, which will reestablish the initial reading frame). In the case of the kappa-addition of any number of bases to the initial ssDNA base sequence, we define the set of kappa-natural numbers as the set of natural numbers that satisfies kappa-addition law. The proposed KFB mutations are then given as follows:
whereare not multiples of three, are multiples of three,are not multiples of three, and, which brings the usual sum as a particular case of ⊕∞ ≡ +. Relation 1 can be expressed in the convenient product form [1]:
whereis the initial length of information (string length) of the ssDNA or biological polymer that is being copied and (no multiples of three) is the length of information (string length) of the mutation added to the initial base . The κ-sum is commutative (N⊕κM = M⊕κN) and associative (N⊕κ(M⊕κX) = (N⊕κM)⊕κX), but not distributive in relation to the usual multiplication (α(N⊕κM)≠(αN⊕καM)). The neutral element of the κ-sum is zero, N⊕κ0 = N.
Similarly, in the case of κ-deletion of any number of bases (no multiples of three) from the initial ssDNA base sequence, the proposed KFB mutation (see Table.1) is given by the following:
where is not multiples of three, is multiples of three, (not multiples of three), and. Equation (3) is κ-subtraction, the inverse operation of κ-addition (1): physically, it means that some base(s) are deducted from the initial DNA or biological polymer.
The κ-difference obeys N⊕κm̅=⊕κm̅⊕κN and N⊕κ(m̅⊕κX) = (N⊕κm̅)⊕κX, but α(N⊕κm̅) ≠ (αN⊕καm̅). For both κ-addition to and κ-subtraction from the initial baseof any bases which are multiples of three, we obtain the KFB changes of the information length of the ssDNA or biological polymer being copied. The KFB mutation just adds one or several reading frames into the sequence without altering the composition of those reading frames thereafter. The meaning of the kappa index in the proposed KFB mutation can be understood through the subsystem (subbases) of correlations betweenanddue to information exchanges within a given length of information (string length) in the ssDNA or biological polymer being copied. In fact, a simple relation exists between the Pearson correlation coefficient and the kappa index :
where for subbases with -degrees of freedom [71].
The largest value of kappa,, corresponds to an ssDNA or biological polymer characterized by the absence of any correlations between subbases of :
where is not multiples of three ,is multiples of three andis not multiples of three. This condition is the frameshift mutation. The smallest possible kappa value, , corresponds to the state furthest from the ordinary frameshift mutation of an ssDNA or biological polymer, and is characterized by the strongest correlation between N and M due to information exchange. The parameter provides a measure of the loss ( ) or gain () of information after the mixing of the partial bases and to compose the combined finial ssDNA or biological polymer. To ensure that the values of Equation (1) are not divisible by 3, the positive integers ,and must satisfy the following conditions:
: Information length of the initial sequence; any nuclide “letter” of the initial ss -DNA/RNA sequence is multiple of 3.
: Information length of the insert sequence; any nuclide “letter” of the adding ss DNA/RNA sequence is not divisible by 3.
, : Any positive factor of such that either:
1. has fewer factors of 3 than does, or
2. has exactly the same number of factors of 3 as does, provided that .The details of the insert KFB mutation are given in the Table.1

Table 1.
Details of κ-frameshift background mutation (1). The traditional reading frame and κ-reading frame used for the definition of the KFB mutation are given in Table 2 and Table 3, respectively.
| Information length of the initial sequence; Number of nuclide “letters” of the initial ss DNA/RNA sequence not divisible by 3. | |
| Information length of the insert sequence; Number of nuclide “letters” of the adding mutation in the ss DNA/RNA sequence not divisible by 3. | |
| Maximum of non-correlated number of nuclide “letters” of the mutated ss DNA/RNA sequence not divisible by 3. | |
| Information defect: the correlated number of nuclide “letters” of the mutated ss DNA/RNA sequence. | |
| Number of nuclide “letters” of the mutated ss DNA/RNA sequence not divisible by 3, for specific values of the κ parameter. |
Table 2.
Traditional reading frame.
| Traditional reading | |||
| 3 | 1 | 3 + 1 = 4 | frameshift ( Y is not div. by 3) |
| 6 | 1 | 6 + 1 = 7 | frameshift ( Y is not div. by 3) |
| 3 | 1 | 3 + 1 = 4 | frameshift ( Y is not div. by 3) |
| 3 | 2 | 3 + 2= 6 | In frame (Y is div. by 3) |
| 6 | 1 | 6 + 1 =7 | frameshift ( Y is not div. by 3) |
Table 3.
κ-reading frame.
| κ-reading frame | ||||
| 1 | 3 | 1 | 3 + 1-3 = 1 | κ=1-frameshift ( is not div. by 3) |
| 2 | 6 | 1 | 6 + 1-3 = 4 | κ=2-frameshift ( is not div. by 3) |
| 3 | 3 | 1 | 3 + 1-1 = 3 | In κ=3-frame (is div. by 3) |
| 3 | 3 | 2 | 3 + 2-2 = 3 | In κ=3-frame ( is div. by 3) |
| 3 | 6 | 1 | 6 + 1-2 = 5 | κ=3-frameshift ( is not div. by 3) |
In-frame refers to the reading of the genetic code in the correct sequence of three-letter units (codons). Because DNA is read in sets of three nucleotides, maintaining the traditional reading frame ensures that the cell translates the genetic message into the proper sequence of amino acids to build a functional protein. A traditional reading frame (Table 2) is the specific starting point that dictates which triplets are read.
κ-frame refers to that reading of the genetic code in the correct sequence of three-letter units (codons) that is achieved only for specific values of the κ index. The DNA is read in sets of three nucleotides with respects to the κ-index. Maintaining the κ-reading frame may yield translations different to the traditional in-frame translations. κ-frame may thus translate the genetic message into a sequence of amino acids that build a function different to the know traditional function. We note that a κ-frame reading (Table 3) is the specific starting point that dictates which triplets are read only for specific values of the κ-index.
Example 1: Let a very large string of A, C, G, and T letters, which stand for the nucleotides adenine (A), cytosine (C), guanine (G), and thymine (T) (or uracil (U) replacing T in RNA). Let us consider a random ssDNA subset, consisting of N=15 letters:
The M=1 base G frameshift mutation at index 6 (insert G) yields to the following mutated subset:
Now let the corresponding insert KFB-mutation diagram of the frameshift diagram (Β) be:
Let us assume that κ=1, meaning that only one letter is non-correlated – for example the insert letter G. Evaluating Diagram (Γ) yields the following KFB-mutated subset:
In the case of all the letters being non-correlated and κ having non-integer values, it is:
Evaluating Diagram (Γ) using Diagram (Ε) yields the following subset:
Diagram (Ζ) is in the null κ-frame for same non-integer values of κ.
3. Information Defects in the ssDNA/RNA or Biological Polymer
Following Ricard Solé et al. (2024) [3], the size of the sequence space associated with a biological polymer of information length, built from a molecular alphabet of size , is:
For example, the space of possible proteins with a length base of 1000 amino acids is – a space too large to be explored [27]. The space of possible molecular configurations within an organism is astronomically large. The probability for such a protein to exist in nature is . We may assume that biological systems are “non-ergodic” in the sense that not every part of their configuration space can be explored [28,29,30].
In statistical physics, an ergodic system is one which, over sufficiently long time-scales, explores all possible microstates that are consistent with its macroscopic properties. Mathematically, for any physically observable , where is the microstate that specifies all of the system’s coordinates , the long-time average of converges to the ensemble average, so:
In intuitive terms, an ergodic system explores (over time) all the possible ways it can exist. Given enough time, the system will visit all its available configurations or states [3]. There are several major reasons to expect convergence [3]. Firstly, all evolutionary trajectories occur under certain generic selective constraints, such as the laws of mathematics, physics, and chemistry. These constrains should lead to universal features [31,32]. Secondly, many of these states are not explored randomly. Finally, evolutionary trajectories form within a certain system: Darwinian evolution acts on populations of entities, which emerge within the system in assembly spaces [44, 45, and 46].
The second law of thermodynamics states that a physical process must generate an overall increasein the entropy of a system () and its environment ():
Therefore, living systems can only perform processes that reduce entropy internally if, at the same time, they produce an even greater increase in entropy in the environment. Thus, the universal thermodynamic logic of life is that low-entropy input (“resource”) is turned into high-entropy output (“waste”), which can be expressed as:
where
is the entropy production in the environment, is the amount of heat released, is the thermal reservoir at temperature Boltzmann’s constant.
This suggests that all lifeforms face the problem of maintaining low internal entropy in a race against the second law of thermodynamics.
In non-equilibrium thermodynamics [3], the rate of entropy production per unit time τ can be expressed as an integral:
for a system of volume , with the specific entropy production rate, , written as follows:
In Equation (12),indicates a set of “forces" (such as temperature gradients or chemical affinities) and is the set of conjugate fluxes (e.g., heat flows, reaction rates). According to Shannon’s formula [2,22,23,24], the evolution of the base sequences of modern organisms from an unspecified base sequence resulted in a gain of information (a decrease in entropy: negative), as follows:
For the case of writing a specific string from a set of unordered letters (), we have:
Then
is the number of unique elements (or letters) in the informational system and is the length of information (the string length) that is being copied.
Let us now examine the possible evolutionary events resulting from the combination of the proposed KFB mutations and functional selection during biological evolution in the presence of information exchanges between the length bases. This examination involves the following steps: Firstly, we introduce the kappa-multiplication () acting on the space of a possible ssDNA/RNA or biological polymer, and , with a length base of and , respectively. In a similar way that the κ-addition results from the usual additionin Equation (1), the kappa-addition of bases and in Equation (6) gives the following:
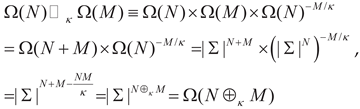
for and . Equation (16α) shows the proposed KFB mutation space of the two possible ssDNA/RNA or a biological polymers (see Table 1 and Diagrams A–Z), with being a molecular alphabet of size. Equation (16α) is the standard morphism from to. Morphism (16α) is defined with the help of the morphisms: and from to . We note that the standard morphism (16α) brings the standard morphism as a particular case of ⊙∞ ≡ × and ⊕∞ ≡ + for (κ→∞). By reciprocity, the logarithm function is the standard morphism from to; namely:
Equation (16b) brings the standard morphism:
from to as a particular case of ⊙∞ ≡ × and ⊕∞ ≡ + for (κ→∞).
We impose the condition:
for, (see Table.1), and.This implies the following restriction to the values of the κ-parameter:
For subbases with degrees of freedom [71], using Equation (4), we obtain the following restriction to the values of the correlation coefficient :
The largest value of kappa,, corresponds to ssDNA/RNA or biological polymer without any correlation between the subbases of information length and given by Equation (5). The space of the two possible proteins (Equation (16α)) then becomes:
for and . This is the frameshift mutation space of the two possible proteins. We may write Equation (16a) as follows:
for,. In Equation (21), the correlation space of the two possible ssDNA/RNA or biological polymers, and (with a length base and , respectively) due to information exchange is given by:
,The κ-product (16α) is commutative (Ω(N)⊙κΩ(M)=Ω(N)⊙κΩ(M)) and associative (Ω(N) ⊙κ(Ω(M)⊙κΩ(X))=(Ω(N)⊙κΩ(M))⊙κΩ(X)). The number 1 is the neutral element of the κ-product (Ω(N)⊙κ1=Ω(N). This permits us to define the inverse multiplicative, 1⊙κ Ω(Nˉ), by means of Ω(N)⊙κ(1⊙κΩ(Nˉ)) ≡ 1.
Similarly, in the case of the deletion of any number of bases (except multiples of three – see Table 1) from the initial ssDNA sequence of base, the space of the two possible ssDNA/RNA or biological polymers, Ω(M) and Ω(M), respectively, is:
Using Equations (13)–(15), the kappa-gain of information (a decrease in kappa-entropy: negative) of the system (ssDNA or biological polymer) during the proposed KFB mutations (see Diagrams (A-Z)) is given by:
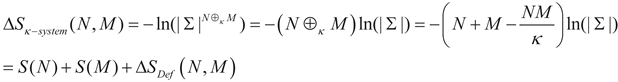
(N,M) is the entropy of a composite system (ssDNA or biological polymer) with correlations between N and M, where:
Equation (27) is the proposed entropy defect for the ssDNA or biological polymer.
The characteristic non-additive rule of the kappa entropy [1] was first derived on a physical basis through the concept of entropy defect [1]. Then, it was demonstrated that the entropy defect can lead to the generalized, kappa-associated entropy [1].Here, we explain the origin of entropy defects based on the interdependence of information length systems (or the interconnectedness of these systems: the condition whereby systems with a significant number of constituents (information length bases) dependent on, and/or are connected to, each other). The proposed KFB mutation quantifies the correlations among the information length of the bases (ssDNA or polymer constituents) due to information exchanges. Interdependence induces order and reduces the entropy-information in ssDNA or biological polymer systems thus producing entropy-information defects. Interdependence is measured through the magnitude of the entropy-information defect, defined as:
where(see Equation (24)) is the entropy-information of the system with correlations among its constituents (e.g., information length bases), while
denotes the entropy-information of this system if there was no correlation among the information length bases. The smallest possible kappa value,, corresponds to the state furthest from the ordinary frameshift mutation of a ssDNA or biological polymer, characterized by the highest correlations between bases due to information exchange. The parameter provides a measure of the loss ( ) or gain () of information after the mixing of the partial bases and to compose the combined final ssDNA or biological polymer.
The entropy of a biological system with correlations is lower than the entropy of the biological system without correlations, because the correlations add order to the biological system. In a composite biological system, its entropy differs from that of the sum of the entropies of its constituent biological subsystems by the entropy defect.
4. Properties of the Information-Entropy Defect in ssDNA/RNA or Biological Polymers
The information defect determines how the information of the ssDNA or biological polymer partitions into the entropy information of its constituents. The participation of each constituent’s entropy-information in the information defect must be (1) separable, (2) symmetric, and (3) (upper- or lower-) bounded for information loss () or gain (). Below, we analyze the physical meaning and mathematical formulation of the three properties that constitute the foundations of information defect:
(1) Separable. The entropy-information defect relates to the constituent’s entropies (information) through a separable function:
(for details see Ref [1])
(2) Symmetric. The information of the total system is symmetric to the and bases:
The same holds for the information defect:
(for details see Ref [1])
(3) Bounded. This means that the entropic information has an upper () or lower () limit for information loss () or gain ().
We note that the upper limit tends to infinity in the classical thermal equilibrium: or for information loss () or gain (), respectively. This indicates that, in the classical case, entropy changes can constantly increase or decrease tending to infinity, and eventually can attain any possible positive or negative values for information loss () or gain (), respectively [1].
Example.2: Following Melvin M. Vopson and Samuel C. Robson [74,75] and applying information theory, our set of independent and distinctive events becomes Σ = {A, C, G, T}, so |Σ| = 4 and probabilities P ={PA ,PC ,PG ,PT }. Using digital bits b = 2, for |Σ| = 4, we need 2 bits per letter (H = log |Σ| = 2 bits) to encode the message: A = 00, C = 01, G = 10, T = 11. If the letters within this subset would have equal probabilities to occur (1/4), then the subset given by Diagram (A) in Example.1 would have H = 2b and a total entropy of NH = 30 bits of information. However, the original subset given by Diagram (A) in Example.1 has the following probability distribution and information entropy:
Therefore, the information entropy of the original subset is 1.751bits and the total information encoded is NHorig=26.26bits. The traditional insert frameshift-mutated subset as κ → ∞ (see Diagram (B)) has the following probability distribution and information entropy:
The information entropy of the insert frameshift-mutated genome subset is 1.849bits (Equation (35)), and the total information encoded is NHfsh= 29.59bits. Hence the information entropy difference between the original and insert frameshift-mutated subsets is ΔHfsh=|Hfsh- Horig|=0,099bits, and the difference in the total information encoded is NΔHfsh= 1,584bits. Using Equation (16β), the KFB-mutated subset (Diagram (Γ)) has the following information entropy:
where denotes the information-entropy defects. The information entropy difference between the original and insert-mutated subsets (see Diagrams (Β-Ζ)), and the differences in the total information encoded are calculated in Table 4.
Table 4 demonstrates the concept of using κ-information theory to study genetic mutations.
Example.3: For instance, biologically, there is symmetry between sequence N and mutation M. Does this symmetry imply that insertion and deletion KFB mutations are equivalent in terms of information entropy loss? To answer this question, we consider the M=1 base κ-frameshift mutation at index 6 (insert). This mutation yields the following delete KFB mutated subset:
The corresponding delete KFB-mutation diagram of the insert KFB-mutation is as follows (Diagram (Γ), Example, 1):
From Equation (3) and using Equation (24), we obtain:
Where
The information-entropy defect for the delete KFB mutation can be written as follows:
whereis the information-entropy defect for the insert KFB mutation Equation.(27). Now, from Equations (37) and (27) we derive the information entropy loss for insert and delete KFB-mutations in terms of information-entropy defects, respectively:
By using Equation (39), the relation between the information entropy loss for insert and delete KFB-mutations is given as follows:
Example.4: Following J.A. Tenreiro Machado et al [73], we consider the counting of n-tuple sequences, n = {1,...,10}, along each initial ssDNA, and the counting of the m-tuple sequences, m = {1,...,10} inserted along each additional ssDNA to the initial system. Note that the insert of m-tuple sequences to the initial n-tuple sequences does not necessarily yield to the KFB mutation; therefore, after the m-tuple sequences are inserted to the initial n-tuple sequences the system under consideration could be either in the κ-frame or κ-frameshift. The states distribution of the system is given by
where
and
for some. The states distribution (42) approaches the traditional states distribution as κ approaches large values:
Here, we consider a word length ranging from (n,m,κ) = (1,0,κ), representing merely a static counting of
states, up to (n,m,κ) = (10,10,κ), representing the dynamics of a system with
states. Therefore, for (n,m,κ) = (1,0,κ), we adopt a state diagram with short bins, such as
up to the diagram with long sequence-counting bins, such as
for (n,m,κ) = (10,10,κ). The comparison plot of distribution functions (47), (45) is given in Figure 1.
The comparison plot of distribution functions (Figure 1a, b) shows the impact of varying correlation strengths on the spatial state distribution of sequences. The contrast between the traditional distribution as κ approaches large values (Figure 1b) with the distribution curve under small κ values (Figure 1a) demonstrates the core argument proposed here: that mutual dependence induces order. This comparison also reveals how the κ exponent constrains the range of exportable states in biological polymers by altering the concentration of κ-probability:
where are the probabilities of the n-tuple and m-tuple sequences, and; the probability of the informational defect.
5. Kappa Metabolic Rate in the Presence of Information Defects
Landauer’s bound [76] gives the minimal energy required to perform an abstract computation and many string-writing operations, including the copying and transformation of ssDNA or biological polymers [77]. We may ask if the available energy is sufficient for the string copying and processing of a very small amount of stored information. The fundamental bounds of information can be connected to metabolism via Landauer’s bound by calculating the minimal metabolic rate, W, needed to replicate genetic information for a given genome length and cellular growth rate [3,76,78]. In the presence of entropy defects, Landauer’s bound is modified due to the KFB mutations, as follows:
where is the kappa heat released to a bath at temperature , is Boltzmann’s constant, and and are the initial and final kappa system entropy, respectively. This is nothing more than the expression of the second law of thermodynamics (Equations (13–15)), where. To write a specific string from a set of unordered letters (), we have and
In Equation (50), terms,and are calculated from Equations (25–27); is the number of unique elements, or letters in the informational system (Equation(6)); is the length of information (the string length) that is being copied; and is the length of information (the string length) of the KFB mutation. Here, is the kappa-composed length of information (the composed string length) after the action of the KFB mutation (Equation (1)). Using Equations (25–27) and (50), the kappa-modified Landauer’s bound becomes:
where
is the heat released to a bath at temperature independent of the kappa index, and
is the heat released to a bath at temperature dependent on the kappa index, and corresponding to the entropy-information defects of the ssDNA or biological polymer. The term in Equation (53) is the correlation between the information lengths N and M due to information exchange after the action of the KFB mutation.
We can convert the kappa-modified Landauer’s bound into a kappa-modified metabolic ratedue to the presence of entropy defects by considering how fast the information is copied. Given a division time, (seconds), the kappa-modified minimal metabolic rate of copying is:
where
is the minimal metabolic rate independent of the kappa index, and
is the minimal metabolic rate dependent on the kappa index, and corresponding to the entropy-information defects of the ssDNA or a biological polymer. Again, at limit (29) Equations (51) and (54) become
Equation (57) denotes Landauer’s bound whereas Equation (58) shows the minimal metabolic rate for a biological system without any correlation among the information length bases. The minimal metabolic rate formula (54) is highly dependent on environmental temperature T. By Equation (24), we have:
For, the entropy defects are diminished on minimal metabolic rate while for, the entropy defects are amplified on minimal metabolic rate.
6. Discussion
In the MB probability distribution for ssDNA/RNA or a biological polymer,, entropy is zero only when a specific information string is written from a set of unordered letters (). The probability value for such an unordered information string is. Furthermore, in the MB statistical mechanics for a specific information string from a set of ordered letters (), there is no preference for a specific sequence: if , different ssDNA sequences are equally possible, and the actual ssDNA/RNA sequence has only a probability in the ssDNA sequence, ranging from one million in bacteria to billions in many animals and plants. For example, the space of possible proteins with a base length of 1000 amino acids is – a space so large that it could never be explored in our universe [27]. The space of possible molecular configurations within an organism is astronomically larger. The probability of such a protein (ordered information string) to exist in nature is . The requirements of longer evolutionary time and a larger number of individuals are even more conducive to the observation of deterministic laws associated with the base length. The evolutionary fitness of organisms relates to the progressive reduction of the entropy production rate. This, and the Boltzmann’s ergodic principle, allow us to consider organisms as evolving chemical entities (Sabater 2006, 2009 [2,4]). Accordingly, the time-average state of a single individual over a long period (evolutionary time) coincides with the average state of a sufficiently large number of individuals for shorter time periods [5]. We note that Sabater (2009[5]) worked with an alternative theory of biological time arrows, showing that deterministic behavior can arise in a biological system.
Let us now examine the evolutionary events that could result from the combination of functional selection during biological evolution and information exchange between the base lengths of biological polymers, represented by the kappa parameter. For ssDNA/RNA or a biological polymer with the kappa-probability distribution (Equation (48) derived from the kappa entropy (Equation (24) under the constraint of normalized, we observe that the different and scales in Equations (24) and (48) are manifested in the double evolutionary emergence of the proposed biological polymer through correlations between its bases. For specific values of the kappa parameter: (), deterministic laws associated with a single biological polymer can be expected for short timescales. Thus, for the kappa-probability distribution, we have the short-timescale possibilities for an individual. Let us now consider a general example for a () state characterized by the highest correlation between bases due to information exchange. By writing a specific initial information string from a set of unordered letters for kappa values (,), we have:
if and only if,,.We then obtain the entropy changes:
where is the final entropy of the “mathematical” biological polymer. Equation (61) is the iso-entropic process for a given “mathematical” biological polymer, and is adiabatic and reversible [83–86], with equal initial and final probability (that is, ). Using Equations (54) and (61), the iso-entropic changes for the proposed “mathematical’’ biological polymer yield to the zero kappa-minimal metabolic rate. This implies that, at this optimum state (), to protect itself from damage it cannot endure, the “mathematical” biological polymer must not waste energy (produce entropy) in reactions. We call this state of the “mathematical” protein the kappa-functional optimum state. This state is given by Equation (61). In nature, it may be possible for a real biological polymer to approximate the kappa-functional optimum state with increasing correlation between its parts. Due to the strongest correlation between its parts, such a protein would need to waste much less energy (produce less entropy) in reactions, and would be less susceptible to damage than what the classical information theory predicts.
7. Conclusions
Following Livadiotis G. and McComas D. J, (2023) [1], we propose a new type of ssDNA/RNA frameshift mutations: Kappa-Frameshift Background (KFB) mutations. KFB mutations occur spontaneously due to information exchange between the ssDNA/RNA sequence of length base () and the mutation sequence of length base (M), and respect the kappa-addition symbol . KFB mutations occur when any number of bases are added to or deleted from the initial ssDNA sequence of bases. This repeats the kappa-addition , except in the case of multiples of three, which reestablish the initial reading frame. In the proposed KFB mutation, the kappa index can be understood through the subsystem (subbase) of information length correlation between and due to information exchange within the given length of ssDNA or biological polymer (the string length) that is being copied.
We find that entropy defects originate in the interdependence of information length systems (or their interconnectedness: the state at which systems with a significant number of constituents (information length bases) depend on, or are connected with, each other) by the proposed KFB mutations. In general, interdependence induces order in the systems involved (ssDNA or biological polymers) and reduces their entropy-information, thus producing entropy-information defect. The entropy of a biological system with correlations is lower than the entropy of a biological system without correlations, because correlations add order to the biological system. In a composite biological system, its entropy differs from the sum of the entropy of the biological subsystems that constitute it by the entropy defect.
In the presence of entropy defects, the Landauer’s bound and minimal metabolic rate for a biological system is modified. We observe that that the different n-tuple sequences and scales in Equations (24) and (48) are manifested in the double evolutionary emergence of proposed biological polymers due to subsystem correlations. In this process, for specific values of the kappa parameter, we can expect deterministic laws associated with a single biological polymer for short timescales. We find that the possible evolutionary events resulting from the combined effects of functional selection during biological evolution and information exchange between the length bases of the biological polymer are represented by the kappa parameter. Using a proposed “mathematical” biological polymer, we find that iso-entropic changes in this biological polymer yield to the zero kappa-minimal metabolic rate. This implies that, at the optimum state given by the half of the harmonic means of n-tuple and m-tuple sequences, (), to protect itself from damage it cannot endure, the “mathematical” biological polymer must not waste energy (produce entropy) in reactions. We call this state of the “mathematical” biological polymer the kappa-functional optimum state. In nature, with increasing correlation between its parts, a real protein may approximate the kappa-functional optimum state. Due to the strongest correlation between its parts, such a protein would waste much less energy (produce less entropy) in reactions, and would be less susceptible to damage, than what the classical information theory predicts.
Data Availability Statement
Data will be made available on reasonable request. [Author’s comment: The datasets generated during and/or analyzed during the current study are available from the corresponding author on reasonable request.]
Code Availability Statement: This manuscript has no associated code/software. [Author’s comment: No code/software was generated or analyzed during the current study.]
Competing Interests: The author declares no competing interests.
References
- George Livadiotis and David J. McComas 2023 EPL 144 21001.
- B.Sabater, Entropy Perspectives of Molecular and Evolutionary Biology. Int. J. Mol. Sci. (2022), 23, 4098. [CrossRef]
- Solé, R. Kempes, C.P. Corominas-Murtra, B. De Domenico, M. Kolchinsky, A. Lachmann, M. Libby, E. Saavedra, S. Smith, E. Wolpert, D. Fundamental Constraints to the Logic of Living Systems. Interface Focus (2024), 14. [CrossRef]
- B.Sabater,Are organisms committed to lower their rates of entropy production? Possible relevance to evolution of the Prigogine theorem and the ergodic hypothesis. Biosystems (2006) 83: 10–17.
- B.Sabater, Time arrows and determinism in Biology, Biological Theory 4(2) (2009), 174–182.
- Martyushev, L.M. Entropy and entropy production: Old Misconceptions and new breakthroughs. Entropy (2013), 15, 1152–1170. [CrossRef]
- Baez, J.C. Blake, S.; Pollard, B.S. Relative Entropy in Biological Systems. Entropy (2016), 18, 46.
- Roach, T.N.F. Use and abuse of entropy in Biology: A case for Caliber. Entropy (2020), 22, 1335. [CrossRef]
- Demetrius, L. Directionality principles in thermodynamics and evolution. Proc. Natl. Acad. Sci. USA (1997), 94, 3491–3498. [CrossRef]
- Skene, K.R. Life’s a gas: A thermodynamic theory of biological evolution. Entropy (2015), 17, 5522–5548. [CrossRef]
- Skene, K.R. Thermodynamics, ecology and evolutionary biology: A bridge over troubled water or common ground? Acta Oecol. (2017), 85, 116–125. [CrossRef]
- Doyle, S.R.; Carusela, F. Guala, S. Momo, F. A null model for testing thermodynamic optimization in ecological systems. (2019), arXiv:1111.2019v1.
- Dewar, R.C. Maximum entropy production and plant optimization theories. Phil. Trans. R. Soc. B (2010), 365, 1429–1435. [CrossRef]
- Kondepudi, D.K.De Bari, B.Dixon, J.A. Dissipative structures, organisms and evolution. Entropy (2020), 22, 1305.
- Dobovišek, A. Županovi´c, P. Brumen, M. Bonaˇci´c-Loši´c, Z. Kui´c, D. Juretic, D. Enzyme kinetics and the maximum entropy production principle. Biophys. Chem. (2011), 154, 49–55.
- Gaiseanu, F. What is life: An informational model of the living structures. Biochem. Mol. Biol. (2020), 5, 18–28. [CrossRef]
- Pulselli, R.M. Simoncini, E.Tiezzi, E. Self-organization in dissipative structures: A thermodynamic theory for the emergence of prebiotic cells and their epigenetic evolution. Biosystems (2009), 96, 237–241. [CrossRef]
- Annila, A.Kuismanen, E. Natural hierarchy emerges from energy dispersal. Biosystems (2009), 95, 227–233.
- Hui, D.Liao-Fu, L.Lin Hao, L. Entropy production rate changes in lysogeny/lysis switch regulation of bacteriophage Lambda. Commun. Theor. Phys. (2011), 55, 371.
- Trevors, J.T.Saier, M.H., Jr. Thermodynamic perspectives on genetic instructions, the laws of biology and diseased states. Comptes Rendus Biol. (2011), 334, 1–5.
- Tretiakov, K.V. Szleifer, I.Grzybowski, B.A. The rate of energy dissipation determines probabilities of non-equilibrium assemblies. Angew. Chem. Int. Ed. Engl. (2013), 52, 10304–10308. [CrossRef]
- Shannon, C.E. A mathematical theory of communication. Bell Syst. Technol. J. (1948), 27, 623–656.
- Adami, C. Ofria, C.Collier, T.C. Evolution of biological complexity. Proc. Natl. Acad. Sci. USA (2000), 97, 4463–4468.
- Vingaa, S.Almeida, J.S. Rényi continuous entropy of DNA sequences. J. Theor. Biol. (2004), 231, 377–388.
- Demetrius, L. Thermodynamics and evolution. J. Theor. Biol. (2000), 206, 1–16.
- Rakoczy, R. Kordas, M. Story, G.Konopacki, M. The characterization of the residence time distribution in a magnetic mixer by means of the information entropy. Chem. Engin. Sci. (2014), 105, 191–197. [CrossRef]
- Dryden, D.T. Thomson, A.R.White, J.H. How much of protein sequence space has been explored by life on Earth? Journal of The Royal Society Interface (2008), 5, 953–956. [CrossRef]
- Kauffman. Investigations; Oxford University Press, (2000).
- Kauffman, S.A.; Roli, A. A third transition in science? Interface Focus (2023), 13, 20220063.
- Kauffman, S.A. Prolegomenon to patterns in evolution. Biosystems (2014), 123, 3–8.
- Kempes, C.P.Koehl, M.West, G.B. The scales that limit: the physical boundaries of evolution. Frontiers in Ecology and Evolution (2019), 7, 242.
- Kempes, C.P.Krakauer, D.C. The multiple paths to multiple life. Journal of molecular evolution (2021), 89, 415–426.
- Koorambas, E. Particle in a Markov Cube by the Non-Classical Information Entropy Space. Int J Theor Phys 63, 81 (2024). [CrossRef]
- Aguirre, J.Catalán, P.Cuesta, J.A.Manrubia, S. On the networked architecture of genotype spaces and its critical effects on molecular evolution. Open biology (2018), 8, 180069.
- Manrubia, S. The simple emergence of complex molecular function. Philosophical Transactions of the Royal Society A (2022), 380, 20200422. [CrossRef]
- Alberch, P. From genes to phenotype: dynamical systems and evolvability. Genetica (1991), 84, 5–11. [CrossRef]
- Gavrilets, S. Gravner, J. Percolation on the fitness hypercube and the evolution of reproductive isolation. Journal of theoretical biology (1997), 184, 51–64. [CrossRef]
- Fontana, W. Modelling ‘evo-devo’with RNA. BioEssays (2002), 24, 1164–1177.
- Schultes, E.A. Bartel, D.P. One sequence, two ribozymes: implications for the emergence of new ribozyme folds. Science (2000), 289, 448–452. [CrossRef]
- Li, H. Helling, R.Tang, C. Wingreen, N. Emergence of preferred structures in a simple model of protein folding. Science (1996), 273, 666–669. [CrossRef]
- Li, H. Tang, C. Wingreen, N. Are protein folds atypical? Proc. Nat. Acad. Sci. USA (1998), 95, 4987–4990.
- Denton, M. The Protein Folds as Platonic Forms: New Support for the Pre-Darwinian Conception of Evolution by Natural Law. J. Theor. Biol. (2002), 219, 325–342. [CrossRef]
- Banavar, J.R. Maritan, A. Colloquium: Geometrical approach to protein folding: a tube picture. Reviews of Modern Physics (2003), 75, 23. [CrossRef]
- Marshall, S.M. Mathis, C. Carrick, E. Keenan, G. Cooper, G.J. Graham, H. Craven, M. Gromski, P.S. Moore, D.G. Walker, S.I. others. Identifying molecules as biosignatures with assembly theory and mass spectrometry. Nature communications (2021), 12, 3033.
- Ahnert, S.E. Johnston, I.G. Fink, T.M. Doye, J.P. Louis, A.A. Self-assembly, modularity, and physical complexity. Physical Review E (2010), 82, 026117.
- Sharma, A. Czégel, D. Lachmann, M.; Kempes, C.P. Walker, S.I. Cronin, L. Assembly theory explains and quantifies selection and evolution. Nature (2023), 622, 321–328.
- N.V. Bhagavan, Medical Biochemistry, United States (2002), ISBN978-0-12-095440-7, New York (2002), Elsevier Inc.
- Chang-Hui Shen, Diagnostic Molecular Biology, United States (2023), ISBN 978-0-323-91788-9 New York (2023) Elsevier Inc. [CrossRef]
- Livadiotis G. and McComas D. J., Entropy, 23 (2021) 1683.
- Livadiotis G., Entropy, 16 (2014) 4290.
- Beck, C. & Cohen, E. G. D. Superstatistics. Phys. A 322, 267–275 (2003).
- Schwadron, N. A. et al. Superposition of stochastic processes and the resulting particle distributions. Astrophys. J. 713, 1386–1392 (2010). [CrossRef]
- Hanel, R., Turner, S. & Gell-Mann, M. Generalized entropies and the transformation group of superstatistics. Proc. Natl. Acad. Sci. U.S.A. (2012) 108, 6. [CrossRef]
- Livadiotis, G., Assas, L., Dennis, B., Elaydi, S. & Kwessi, E. Kappa function as a unifying framework for discrete population modelling. Nat. Res. Mod. 29, 130–144 (2016). [CrossRef]
- Livadiotis, G. Rankine-Hugoniot shock conditions for space and astrophysical plasmas described by Kappa distributions. Astrophys. J. 886, 3 (2019). [CrossRef]
- Gravanis, E., Akylas, E. & Livadiotis, G. Physical meaning of temperature in superstatistics. Europhys. Lett. 130, 30005 (2020). [CrossRef]
- Zank, G. P. et al. Particle acceleration at perpendicular shock waves: Model and observations. J. Geophys. Res. 111, A06108 (2006). [CrossRef]
- Bian, N., Emslie, G. A., Stackhouse, D. J. & Kontar, E. P. Te formation of a kappa-distribution accelerated electron populations in solar fares. Astrophys. J. 796, 142 (2014).
- Yoon, P. H. Electron kappa distribution and steady-state Langmuir turbulence. Plasma Phys. 19, 052301 (2012). [CrossRef]
- Yoon, P. H. Electron kappa distribution and quasi-thermal noise. J. Geophys. Res. 119, 7074 (2014). [CrossRef]
- Livadiotis, G. & McComas, D. J. Exploring transitions of space plasmas out of equilibrium. Astrophys. J. 714, 971–987 (2010). [CrossRef]
- Livadiotis, G. & McComas, D. J. Infuence of pickup ions on space plasma distributions. Astrophys. J. 738, 64 (2011). [CrossRef]
- Livadiotis, G., McComas D. J., Transport equation of kappa distributions in the heliosphere. Astrophys. J., to appear (2023). [CrossRef]
- Fisk, L. A. & Gloeckler, G. The case for a common spectrum of particles accelerated in the heliosphere: Observations and theory. J. Geophys. Res. 119, 8733–8749 (2014). [CrossRef]
- Peterson, J., Dixit, P. D. & Dill, K. A. A maximum entropy framework for non-exponential distributions. Proc. Natl. Acad. Sci. U.S.A. 110, 20380–20385 (2013). [CrossRef]
- Livadiotis, G., Desai, M. I. & Wilson, L. B. III. Generation of kappa distributions in solar wind at 1 AU. Astrophys. J. 853, 142 (2018). [CrossRef]
- Livadiotis, G. On the origin of polytropic behavior in space and astrophysical plasmas. Astrophys. J. 874, 10 (2019).390–6394 (2011). [CrossRef]
- Boltzmann, L. Über die Mechanische Bedeutung des Zweiten Hauptsatzes der Wärmetheorie. Wiener Berichte 53, 195–220 (1866).
- Gibbs, J. W. Elementary principles in statistical mechanics (Scribner’s sons, 1902).
- Maxwell, J. C. Illustrations of the dynamical theory of gases, on the motions and collisions of perfectly elastic spheres. Philos. Mag. 19, 19–32 (1860). [CrossRef]
- Livadiotis, G.; McComas, D.J. Invariant kappa distribution in space plasmas out of equilibrium. Astrophys. J. (2011), 741, 88. [CrossRef]
- Livadiotis, G. Kappa and q indices: Dependence on the degrees of freedom. Entropy (2015), 17, 2062–2081. [CrossRef]
- J.A. Tenreiro Machadoa, , António C. Costa , Maria Dulce Quelhas . Shannon, Rényie and Tsallis entropy analysis of DNA using phase plane Nonlinear Analysis: Real World Applications 12 (2011) 3135–3144. [CrossRef]
- Melvin M. Vopson, Samuel C. Robson, A new method to study genome mutations using the information entropy . [CrossRef]
- Melvin M. Vopson , Information theory of non-equilibrium states IPI Letters 2023, (1): 22 – 29.
- Landauer, R. Irreversibility and heat generation in the computing process. IBM journal of research and development (1961), 5, 183–191. [CrossRef]
- Kolchinsky, A. Corominas-Murtra, B. Decomposing information into copying versus transformation. Journal of the Royal Society Interface (2020), 17, 20190623. [CrossRef]
- Kempes, C.P. Wolpert, D. Cohen, Z Pérez-Mercader, J. The thermodynamic efficiency of computations made in cells across the range of life. Philosophical Transactions of the Royal Society A: Mathematical, Physical and Engineering Sciences (2017), 375, 20160343.
Figure 1.
Comparison plot of distribution functions for a) finite small κ values (κ=5), and b) finite large κ values (κ=100). For κ=100, the distribution approaches the traditional distribution.
Figure 1.
Comparison plot of distribution functions for a) finite small κ values (κ=5), and b) finite large κ values (κ=100). For κ=100, the distribution approaches the traditional distribution.
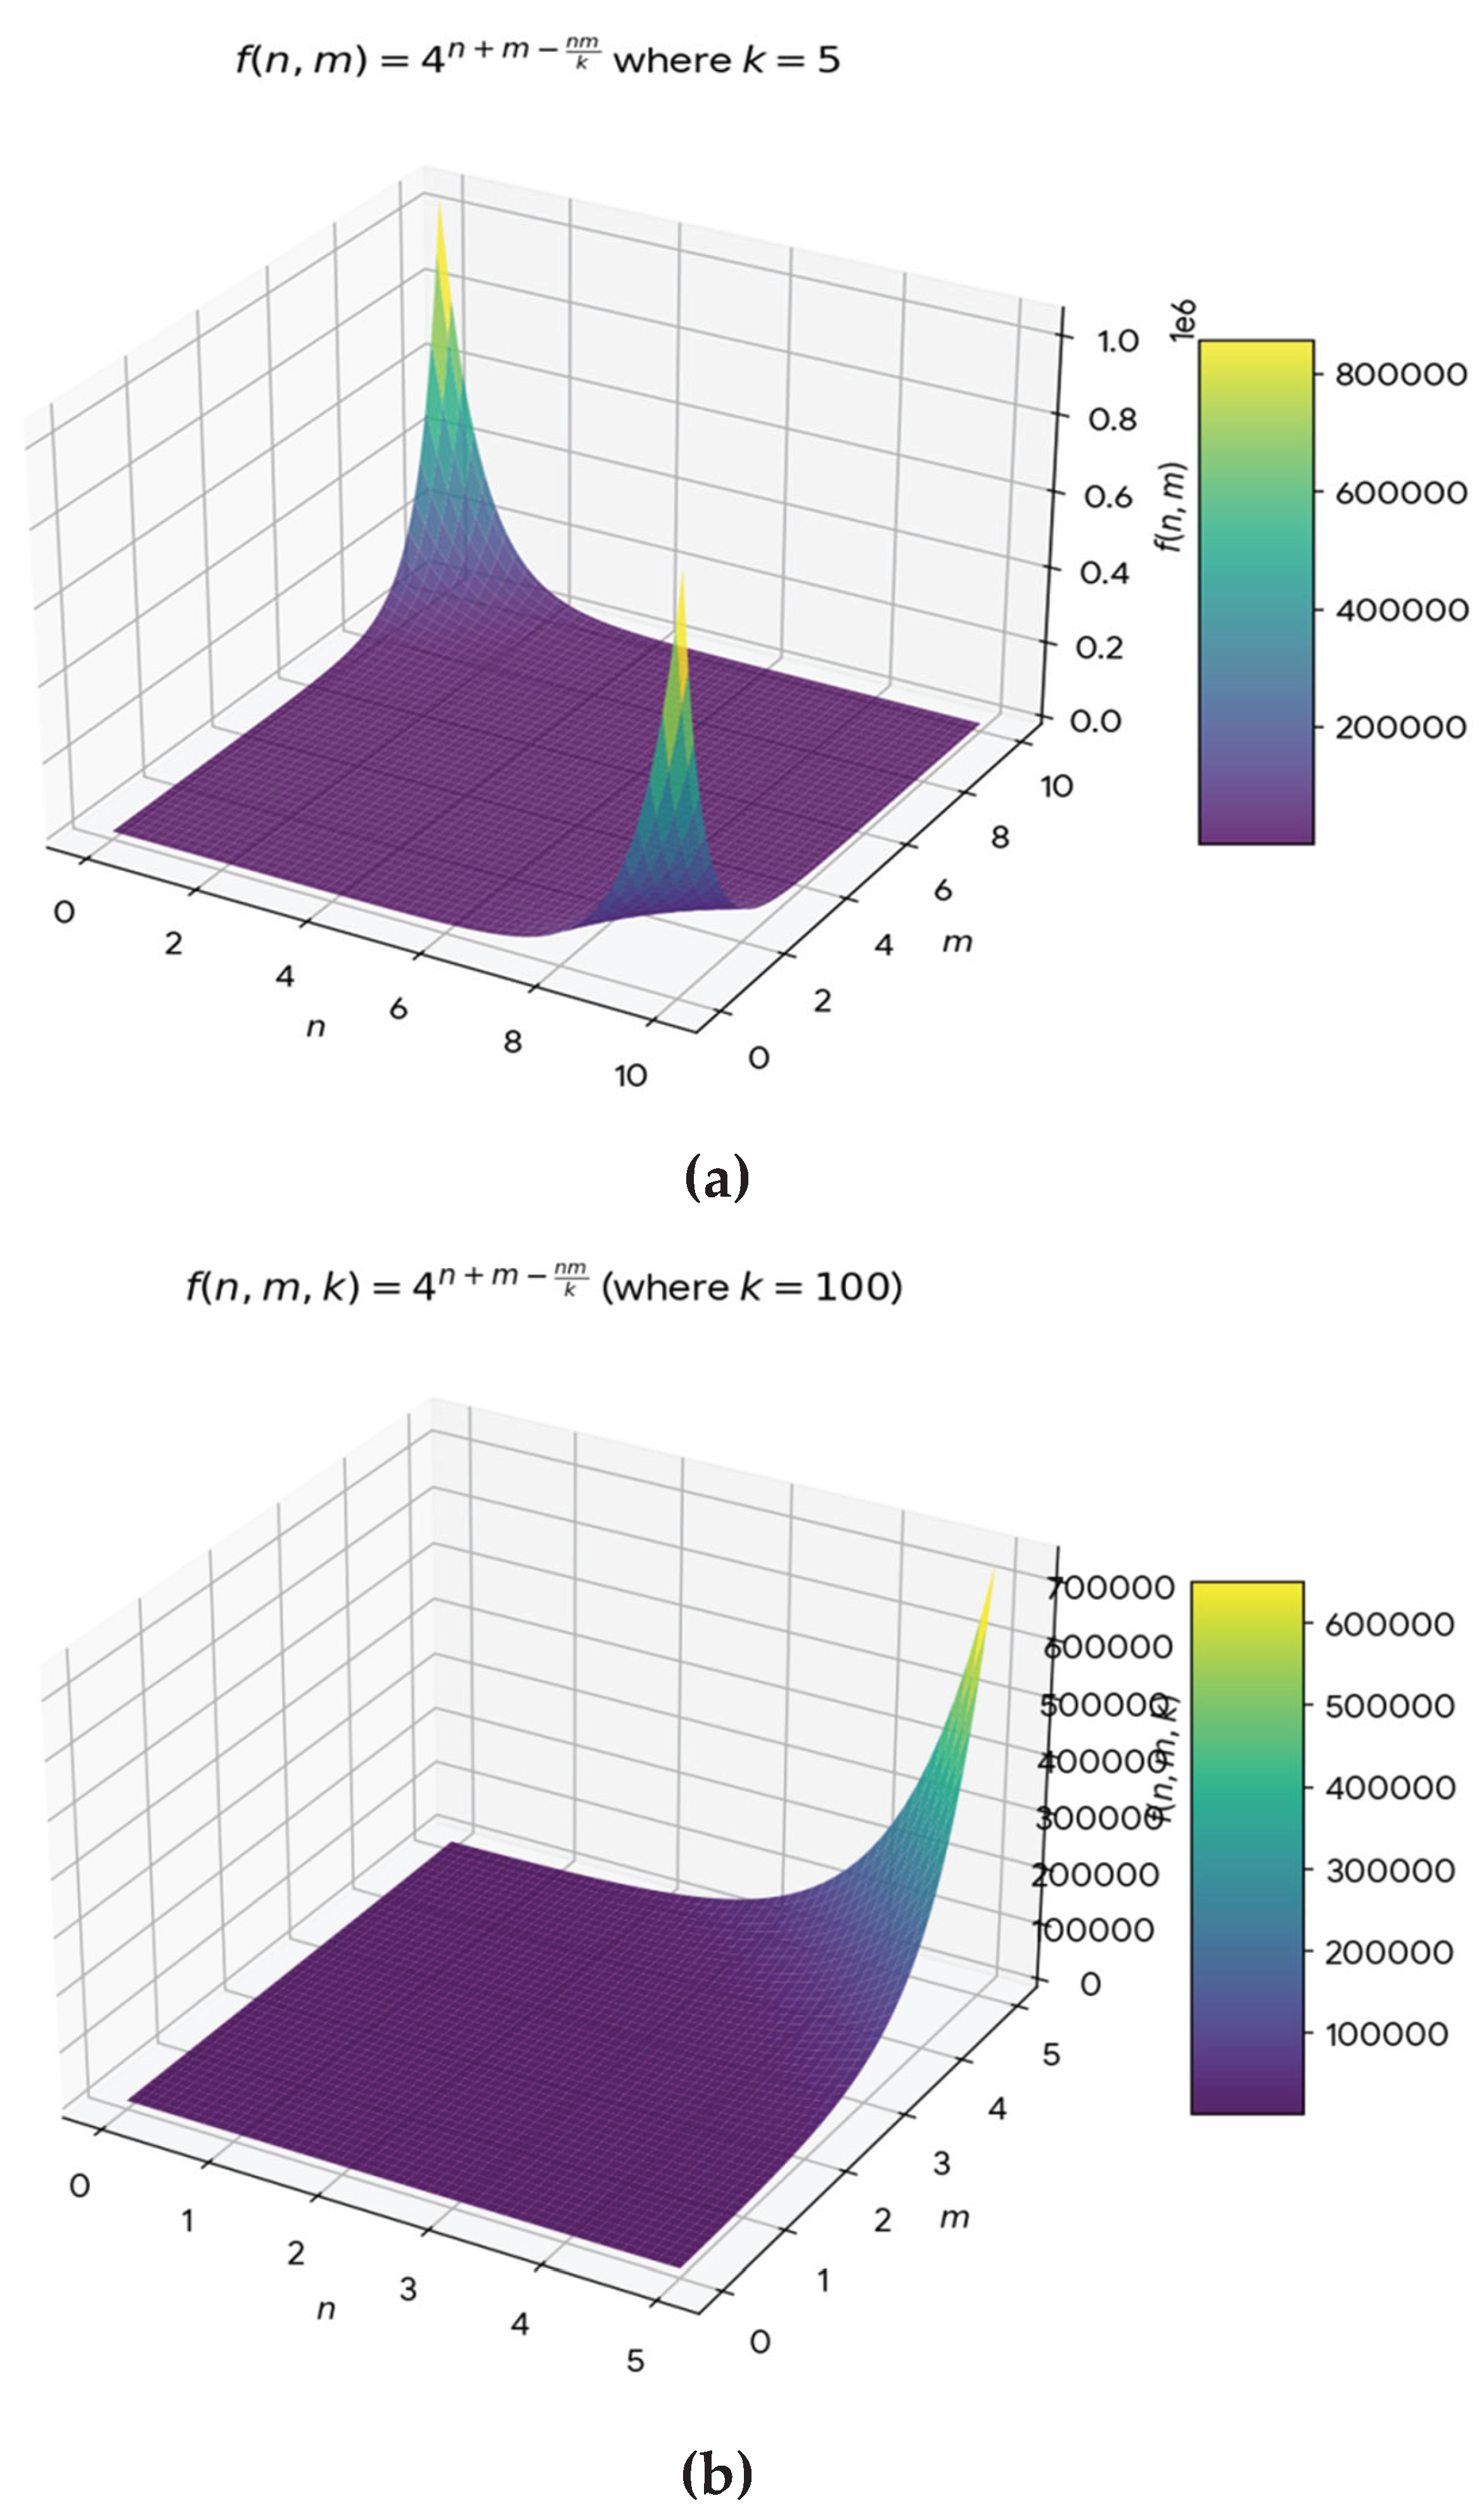
Table 4.
Conpariosn of information entropy and the resulting genome subset by insert G with respect to different κ-values for Diagrams (Β–Ζ).
Table 4.
Conpariosn of information entropy and the resulting genome subset by insert G with respect to different κ-values for Diagrams (Β–Ζ).
| κ-values(bits) | Information (bits) | Total information (bits) | Diff (bits) | Total-diff (bits) | Genome- subsets |
| κ → ∞ | 1.849 | 29.56 | 0,099 | 1,584 | Frame-shift |
| κ=1 | 1 | 1 | 0,849 | 28,56 | KFB |
| κ=HorigHG/Horg+HG | 0 | 0 | 0 | 0 | In null κ-frame |
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the author. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.
Copyright: This open access article is published under a Creative Commons CC BY 4.0 license, which permit the free download, distribution, and reuse, provided that the author and preprint are cited in any reuse.