

Submitted:
12 December 2024
Posted:
13 December 2024
You are already at the latest version
Abstract
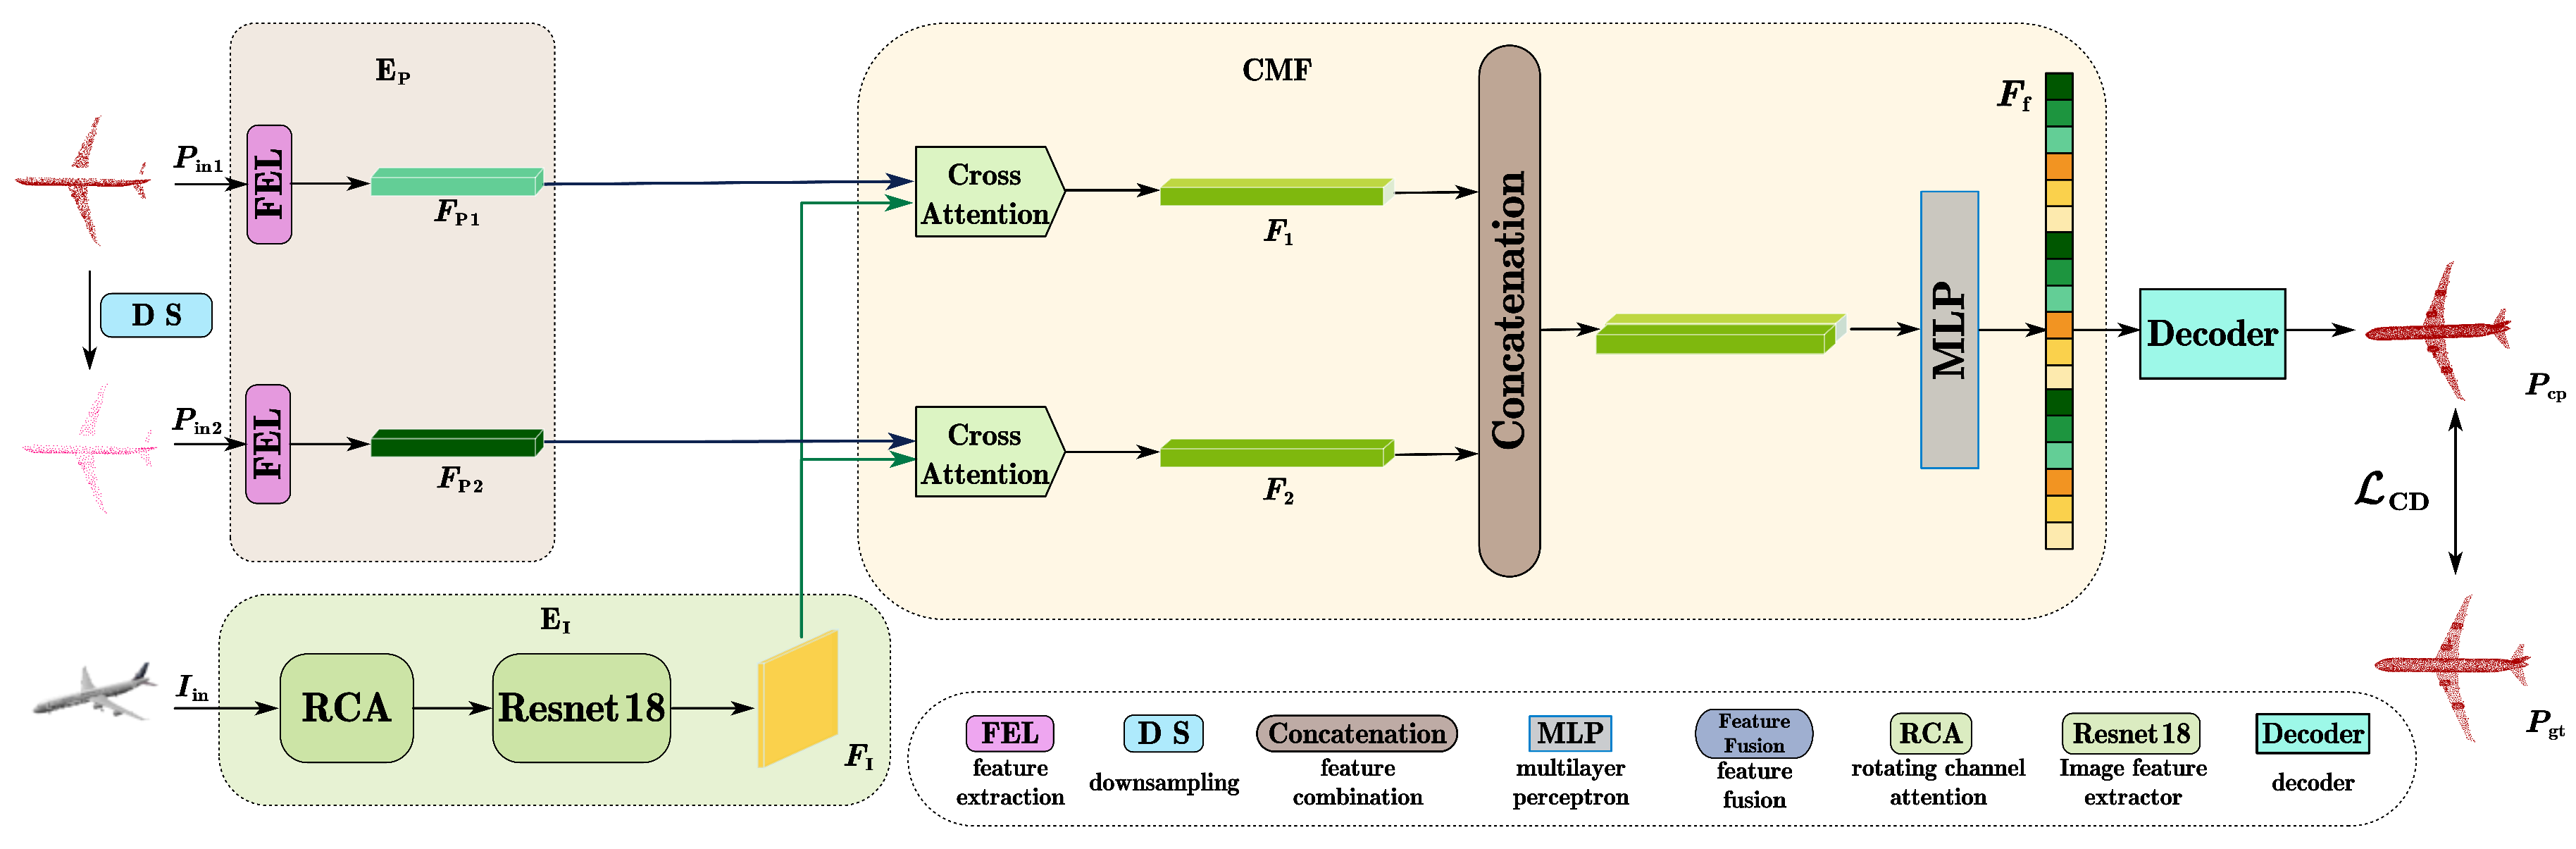
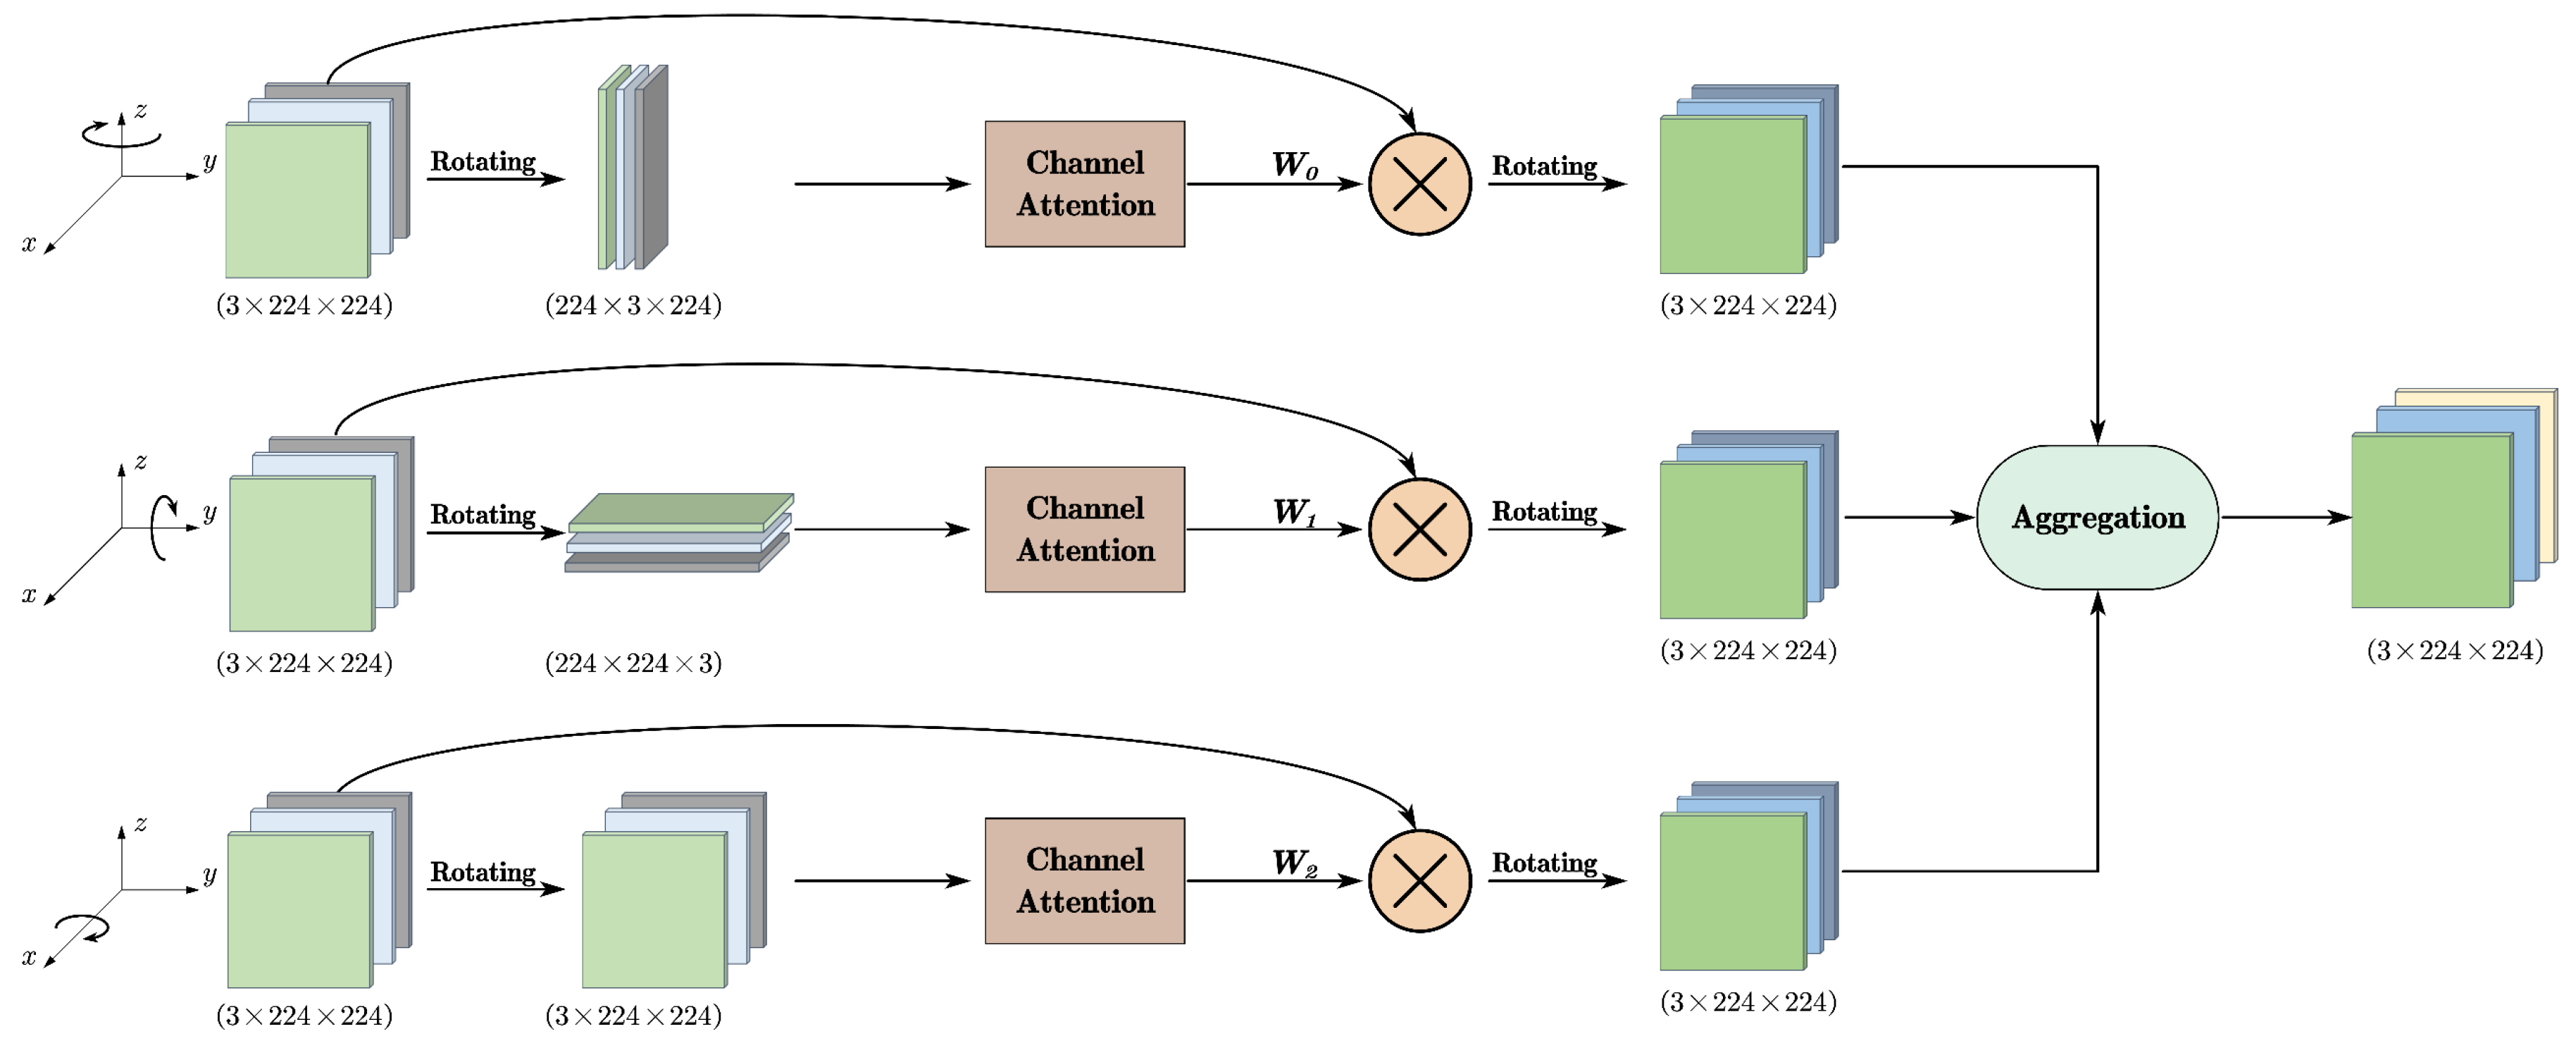
To address the issues of severe information loss and suboptimal fusion effects in multimodal feature extraction and integration during multimodal point cloud shape completion using autoencoder structures, which results in difficulty in balancing local and global feature information of point clouds and significant loss of structural information in images, this paper proposes a LiDAR point cloud multi-scale completion algorithm guided by image rotation attention mechanisms, with a focus on the study of feature extraction from point clouds and images. The network employs an encoder-decoder structure, where the image feature extractor in the encoder utilizes rotation attention mechanisms to enhance the capability of image feature extraction. The point cloud feature extractor employs multi-scale methods to improve the global and local information of point cloud features and employs multi-level self-attention mechanisms to achieve multimodal feature fusion. The decoder then employs a multi-branch completion method to accomplish the point cloud completion task, with the network trained using chamfer distance guidance. Comparatively, our algorithm outperforms eight related algorithms on the ShapeNet-ViPC dataset across various metrics. Compared to the state-of-the-art network XMFnet, the category-averaged Chamfer Distance (CD) value is reduced by 11.71\%. The proposed algorithm in this paper can better extract image structural information, and the feature extraction of in-complete point clouds can consider both global and local information. Furthermore, through multi-level progressive feature fusion, the algorithm enhances the complementarity of information between different modalities, leading to more accurate point cloud completion results.
Keywords:
1. Introduction
2. Related Works
3. Methodology
3.1. Overall Framework of Network
3.2. Point Cloud Multi-Scale Extractor
3.3. Image Feature Extractor
3.4. Point Cloud Similarity Evaluation Metrics
4. Result and Discussion
4.1. Datasets and Experimental Configuration
4.2. Expriment Result Analysis

| Methods | Avg | Airplane | Cabinet | Car | Chair | Lamp | Sofa | Table | Watercraft | |
|---|---|---|---|---|---|---|---|---|---|---|
| Single modal | AtlasNet [7] | 6.062 | 5.032 | 6.414 | 4.868 | 8.161 | 7.182 | 6.023 | 6.561 | 4.261 |
| FoldingNet [20] | 6.271 | 5.242 | 6.958 | 5.307 | 8.823 | 6.504 | 6.368 | 7.080 | 3.882 | |
| PCN [9] | 5.619 | 4.246 | 6.409 | 4.840 | 7.441 | 6.331 | 5.668 | 6.508 | 3.510 | |
| TopNet [6] | 4.976 | 3.710 | 5.629 | 4.530 | 6.391 | 5.547 | 5.281 | 5.381 | 3.350 | |
| ECG [21] | 4.957 | 2.952 | 6.721 | 5.243 | 5.867 | 4.602 | 6.813 | 4.332 | 3.127 | |
| VRC-Net [22] | 4.598 | 2.813 | 6.108 | 4.932 | 5.342 | 4.103 | 6.614 | 3.953 | 2.925 | |
| Multi-modal | ViPC [12] | 3.308 | 1.760 | 4.558 | 3.183 | 2.476 | 2.867 | 4.481 | 4.990 | 2.197 |
| XMFnet [14] | 1.443 | 0.572 | 1.980 | 1.754 | 1.403 | 1.810 | 1.702 | 1.386 | 0.945 | |
| Ours | 1.274 | 0.561 | 1.796 | 1.686 | 1.376 | 1.061 | 1.582 | 1.342 | 0.788 |
| Methods | Avg | Airplane | Cabinet | Car | Chair | Lamp | Sofa | Table | Watercraft | |
|---|---|---|---|---|---|---|---|---|---|---|
| Single modal | AtlasNet [7] | 0.410 | 0.509 | 0.304 | 0.379 | 0.326 | 0.426 | 0.318 | 0.469 | 0.551 |
| FoldingNet [20] | 0.331 | 0.432 | 0.237 | 0.300 | 0.204 | 0.360 | 0.249 | 0.351 | 0.518 | |
| PCN [9] | 0.407 | 0.578 | 0.270 | 0.331 | 0.323 | 0.456 | 0.293 | 0.431 | 0.577 | |
| TopNet [6] | 0.467 | 0.593 | 0.358 | 0.405 | 0.388 | 0.491 | 0.361 | 0.528 | 0.615 | |
| ECG [21] | 0.704 | 0.880 | 0.542 | 0.713 | 0.671 | 0.689 | 0.534 | 0.792 | 0.810 | |
| VRC-Net [22] | 0.764 | 0.902 | 0.621 | 0.753 | 0.722 | 0.823 | 0.654 | 0.810 | 0.832 | |
| Multi-modal | ViPC [12] | 0.591 | 0.803 | 0.451 | 0.512 | 0.529 | 0.706 | 0.434 | 0.594 | 0.730 |
| XMFnet [14] | 0.796 | 0.961 | 0.662 | 0.691 | 0.809 | 0.792 | 0.723 | 0.830 | 0.901 | |
| Ours | 0.822 | 0.968 | 0.696 | 0.710 | 0.812 | 0.879 | 0.748 | 0.835 | 0.929 |
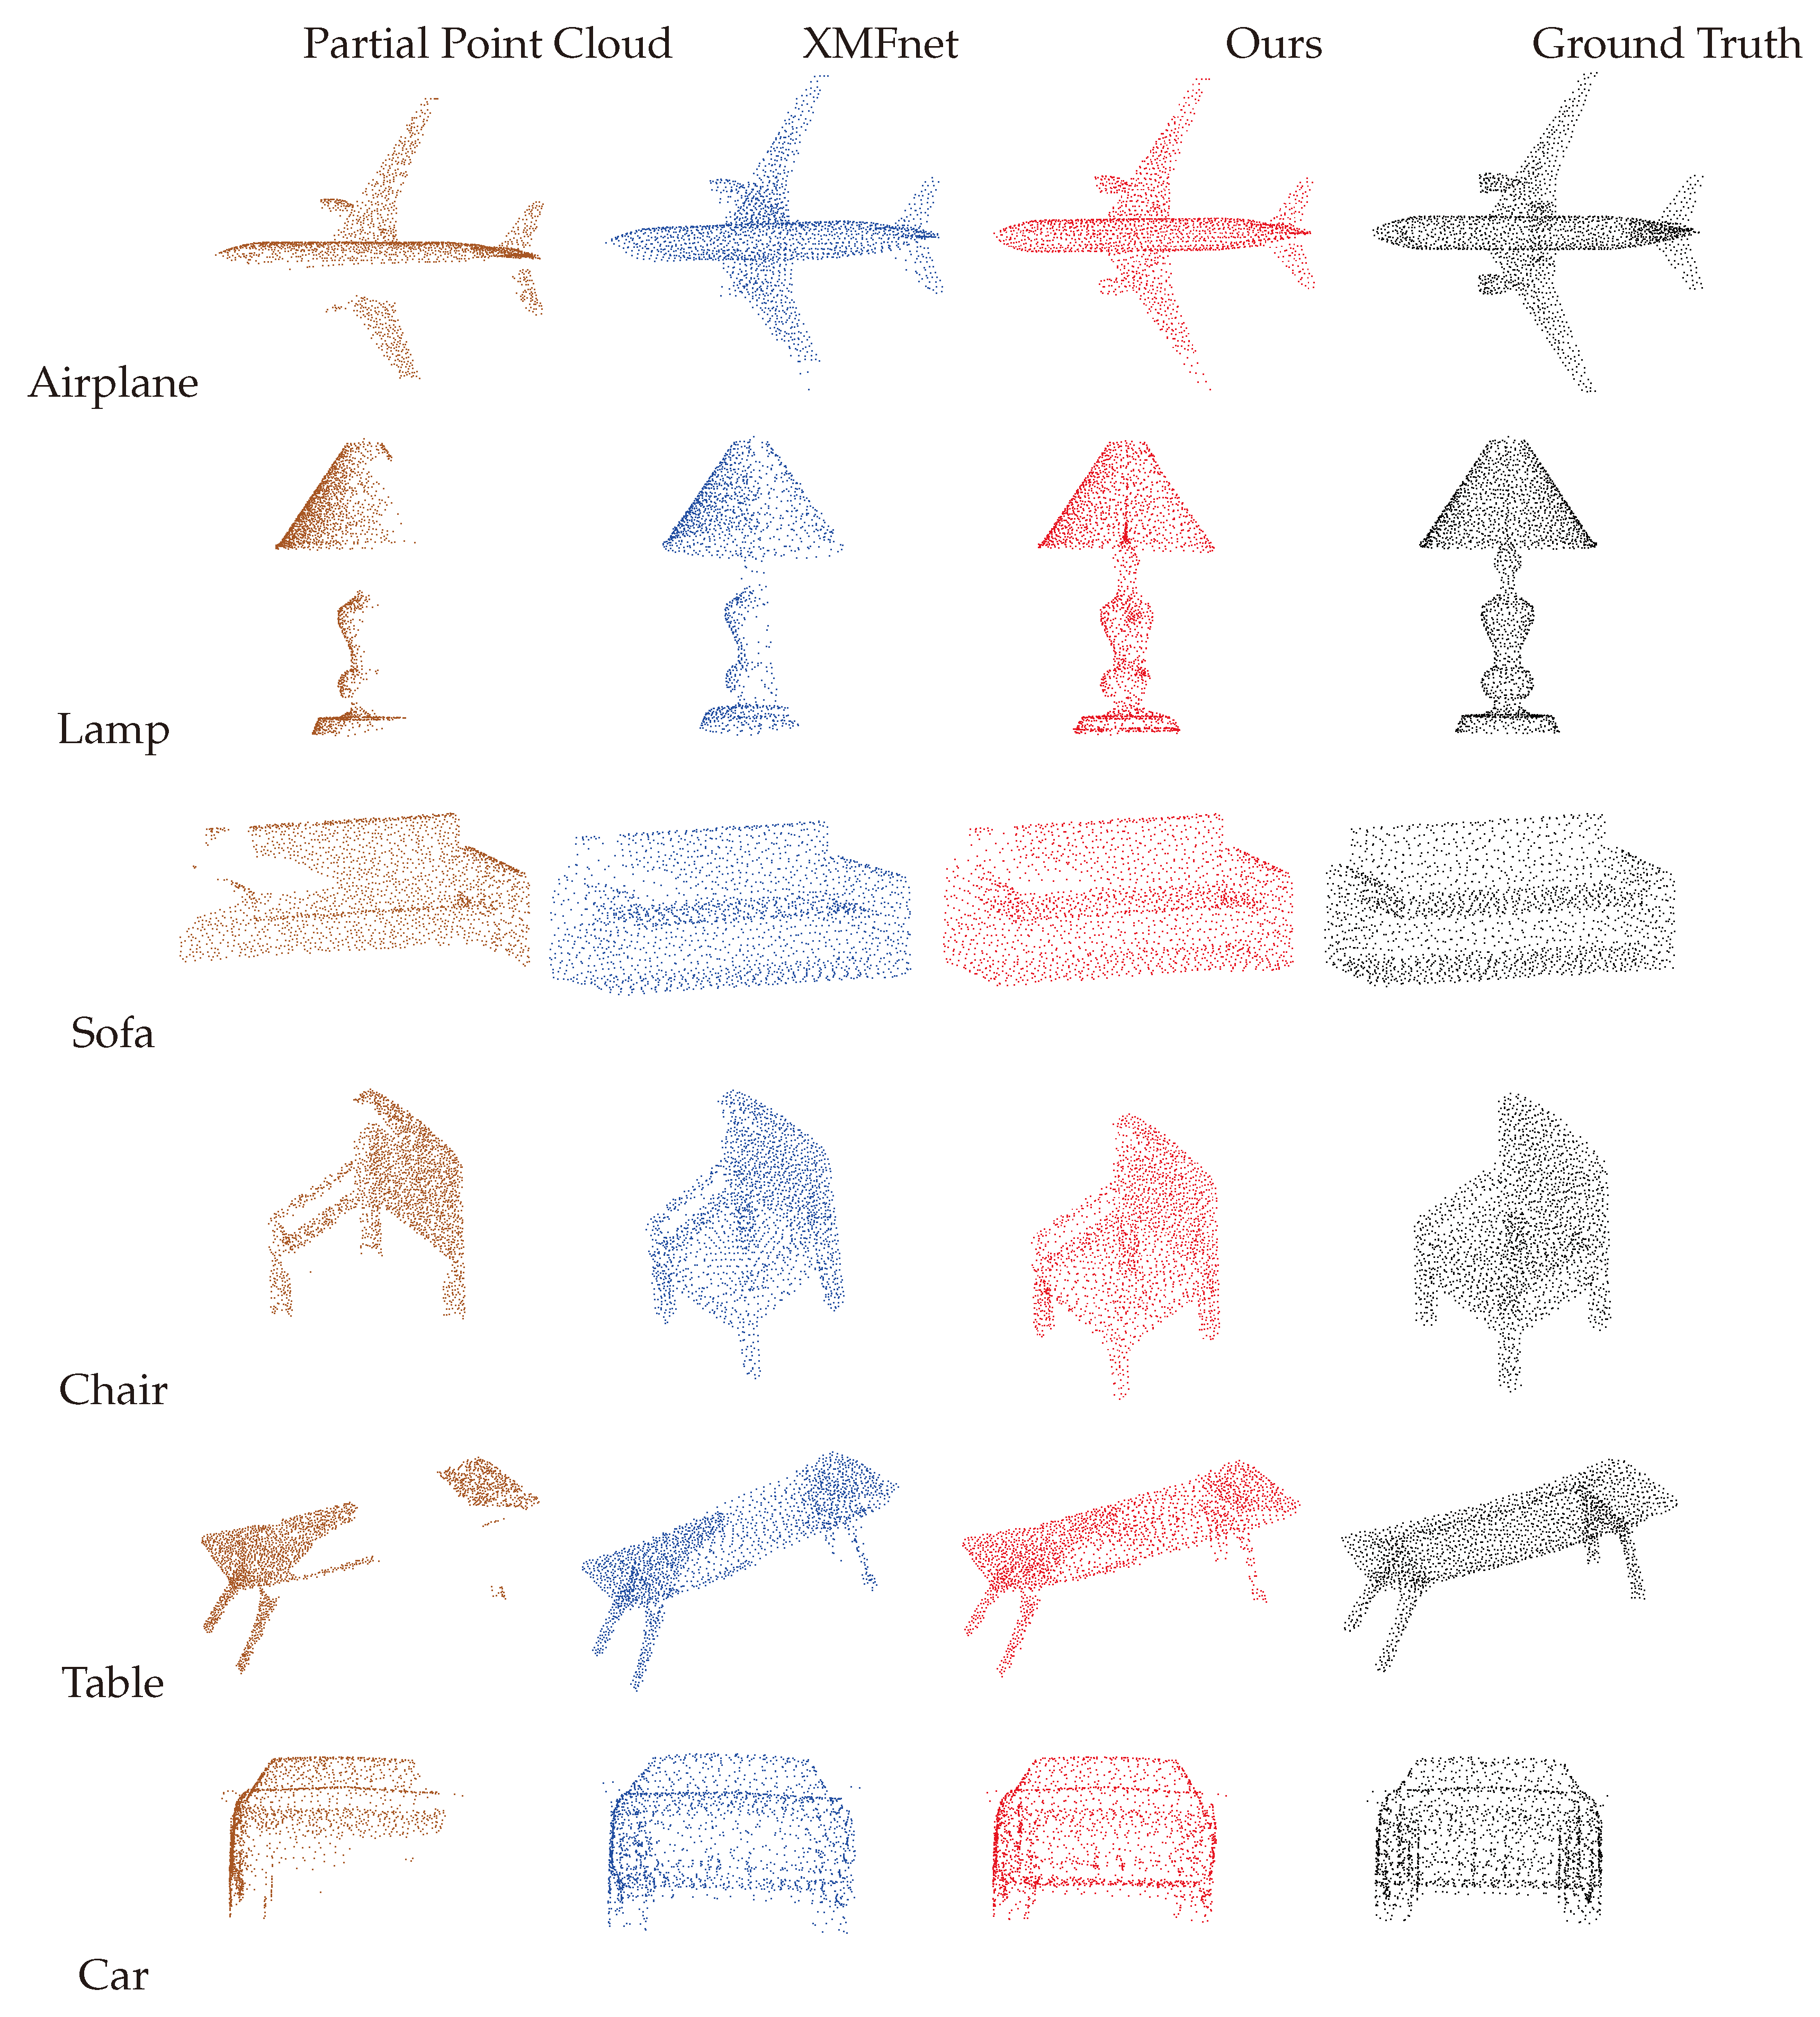
4.3. Visualization
4.4. Ablation
5. Conclusions
Author Contributions
Funding
Conflicts of Interest
References
- Guo, Y.; Wang, H.; Hu, Q.; Liu, H.; Liu, L.; Bennamoun, M. Deep Learning for 3D Point Clouds: A Survey. IEEE Trans. Pattern Anal. Mach. Intell. 2021, 43, 4338–4364. [Google Scholar] [CrossRef] [PubMed]
- Mitra, N.J.; Pauly, M.; Wand, M.; Ceylan, D. Symmetry in 3D Geometry: Extraction and Applications. Comput. Graph. Forum 2013, 32, 1–23. [Google Scholar] [CrossRef]
- Li, Y.; Dai, A.; Guibas, L.J.; Nießner, M. Database-Assisted Object Retrieval for Real-Time 3D Reconstruction. Comput. Graph. Forum 2015, 34, 435–446. [Google Scholar] [CrossRef]
- Qi, C.R.; Su, H.; Mo, K.; Guibas, L.J. PointNet: Deep Learning on Point Sets for 3D Classification and Segmentation. In Proceedings of the 2017 IEEE Conference on Computer Vision and Pattern Recognition, CVPR 2017, Honolulu, HI, USA, 21–26 July 2017; IEEE Computer Society, 2017; pp. 77–85. [Google Scholar] [CrossRef]
- Qi, C.R.; Yi, L.; Su, H.; Guibas, L.J. PointNet++: Deep Hierarchical Feature Learning on Point Sets in a Metric Space. In Proceedings of the Advances in Neural Information Processing Systems 30: Annual Conference on Neural Information Processing Systems 2017, Long Beach, CA, USA, 4–9 December 2017; Guyon, I., von Luxburg, U., Bengio, S., Wallach, H.M., Fergus, R., Vishwanathan, S.V.N., Garnett, R., Eds.; 2017; pp. 5099–5108. [Google Scholar]
- Tchapmi, L.P.; Kosaraju, V.; Rezatofighi, H.; Reid, I.D.; Savarese, S. TopNet: Structural Point Cloud Decoder. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, CVPR 2019, Long Beach, CA, USA, 16–20 June 2019; Computer Vision Foundation / IEEE, 2019; pp. 383–392. [Google Scholar] [CrossRef]
- Schnabel, R.; Degener, P.; Klein, R. Completion and Reconstruction with Primitive Shapes. Comput. Graph. Forum 2009, 28, 503–512. [Google Scholar] [CrossRef]
- Liu, M.; Sheng, L.; Yang, S.; Shao, J.; Hu, S. Morphing and Sampling Network for Dense Point Cloud Completion. In Proceedings of the The Thirty-Fourth AAAI Conference on Artificial Intelligence, AAAI 2020, The Thirty-Second Innovative Applications of Artificial Intelligence Conference, IAAI 2020, The Tenth AAAI Symposium on Educational Advances in Artificial Intelligence, EAAI 2020, New York, NY, USA, 7–12 February 2020; AAAI Press, 2020; pp. 11596–11603. [Google Scholar] [CrossRef]
- Yuan, W.; Khot, T.; Held, D.; Mertz, C.; Hebert, M. PCN: Point Completion Network. In Proceedings of the 2018 International Conference on 3D Vision, 3DV 2018, Verona, Italy, 5–8 September 2018; IEEE Computer Society, 2018; pp. 728–737. [Google Scholar] [CrossRef]
- Yu, X.; Rao, Y.; Wang, Z.; Liu, Z.; Lu, J.; Zhou, J. PoinTr: Diverse Point Cloud Completion with Geometry-Aware Transformers. In Proceedings of the 2021 IEEE/CVF International Conference on Computer Vision, ICCV 2021, Montreal, QC, Canada, 10–17 October 2021; IEEE, 2021; pp. 12478–12487. [Google Scholar] [CrossRef]
- Xiang, P.; Wen, X.; Liu, Y.; Cao, Y.; Wan, P.; Zheng, W.; Han, Z. SnowflakeNet: Point Cloud Completion by Snowflake Point Deconvolution with Skip-Transformer. In Proceedings of the 2021 IEEE/CVF International Conference on Computer Vision, ICCV 2021, Montreal, QC, Canada, 10–17 October 2021; IEEE, 2021; pp. 5479–5489. [Google Scholar] [CrossRef]
- Zhang, X.; Feng, Y.; Li, S.; Zou, C.; Wan, H.; Zhao, X.; Guo, Y.; Gao, Y. View-Guided Point Cloud Completion. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, CVPR 2021, virtual, 19–25 June 2021; Computer Vision Foundation / IEEE, 2021; pp. 15890–15899. [Google Scholar] [CrossRef]
- Zhu, Z.; Nan, L.; Xie, H.; Chen, H.; Wang, J.; Wei, M.; Qin, J. CSDN: Cross-Modal Shape-Transfer Dual-Refinement Network for Point Cloud Completion. IEEE Trans. Vis. Comput. Graph. 2024, 30, 3545–3563. [Google Scholar] [CrossRef] [PubMed]
- Aiello, E.; Valsesia, D.; Magli, E. Cross-modal Learning for Image-Guided Point Cloud Shape Completion. In Proceedings of the Advances in Neural Information Processing Systems 35: Annual Conference on Neural Information Processing Systems 2022, NeurIPS 2022, New Orleans, LA, USA, 28 November–9 December 2022; Koyejo, S., Mohamed, S., Agarwal, A., Belgrave, D., Cho, K., Oh, A., Eds.; 2022. [Google Scholar]
- Vaswani, A.; Shazeer, N.; Parmar, N.; Uszkoreit, J.; Jones, L.; Gomez, A.N.; Kaiser, L.; Polosukhin, I. Attention is All you Need. In Proceedings of the Advances in Neural Information Processing Systems 30: Annual Conference on Neural Information Processing Systems 2017, Long Beach, CA, USA, 4–9 December 2017; Guyon, I., von Luxburg, U., Bengio, S., Wallach, H.M., Fergus, R., Vishwanathan, S.V.N., Garnett, R., Eds.; 2017; pp. 5998–6008. [Google Scholar]
- Fan, H.; Su, H.; Guibas, L.J. A Point Set Generation Network for 3D Object Reconstruction from a Single Image. In Proceedings of the 2017 IEEE Conference on Computer Vision and Pattern Recognition, CVPR 2017, Honolulu, HI, USA, 21–26 July 2017; IEEE Computer Society, 2017; pp. 2463–2471. [Google Scholar] [CrossRef]
- Wang, Y.; Sun, Y.; Liu, Z.; Sarma, S.E.; Bronstein, M.M.; Solomon, J.M. Dynamic Graph CNN for Learning on Point Clouds. ACM Trans. Graph. 2019, 38, 146–1. [Google Scholar] [CrossRef]
- He, K.; Zhang, X.; Ren, S.; Sun, J. Identity Mappings in Deep Residual Networks. In Proceedings of the Computer Vision - ECCV 2016 - 14th European Conference, Amsterdam, The Netherlands, 11–14 October 2016; Proceedings, Part IV. Leibe, B., Matas, J., Sebe, N., Welling, M., Eds.; Springer, 2016; Vol. 9908, Lecture Notes in Computer Science. pp. 630–645. [Google Scholar] [CrossRef]
- Kingma, D.P.; Ba, J. Adam: A Method for Stochastic Optimization. In Proceedings of the 3rd International Conference on Learning Representations, ICLR 2015, San Diego, CA, USA, 7–9 May 2015; Conference Track Proceedings. Bengio, Y., LeCun, Y., Eds.; 2015. [Google Scholar]
- Yang, Y.; Feng, C.; Shen, Y.; Tian, D. FoldingNet: Point Cloud Auto-Encoder via Deep Grid Deformation. In Proceedings of the 2018 IEEE Conference on Computer Vision and Pattern Recognition, CVPR 2018, Salt Lake City, UT, USA, 18–22 June 2018; Computer Vision Foundation / IEEE Computer Society, 2018; pp. 206–215. [Google Scholar] [CrossRef]
- Pan, L. ECG: Edge-aware Point Cloud Completion with Graph Convolution. IEEE Robotics Autom. Lett. 2020, 5, 4392–4398. [Google Scholar] [CrossRef]
- Pan, L.; Chen, X.; Cai, Z.; Zhang, J.; Zhao, H.; Yi, S.; Liu, Z. Variational Relational Point Completion Network for Robust 3D Classification. IEEE Trans. Pattern Anal. Mach. Intell. 2023, 45, 11340–11351. [Google Scholar] [CrossRef] [PubMed]
| RCA | Multi-scale | XMFnet | CMFN | ||
|---|---|---|---|---|---|
| 512 | 1024 | RCA+Multi-scale | |||
| Lamp | 1.490 | 1.327 | 1.452 | 1.810 | 1.061 |
| Watercraft | 0.823 | 0.828 | 0.838 | 0.945 | 0.788 |
| Cabinet | 1.936 | 1.877 | 1.915 | 1.980 | 1.796 |
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2024 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (http://creativecommons.org/licenses/by/4.0/).