

Submitted:
04 November 2026
Posted:
05 November 2026
You are already at the latest version
Abstract
Spam-filter scores are difficult to interpret when split construction, attack denominators, and candidate validity are not retained. We evaluate an auditable RMF-PC protocol using word and character TF-IDF views, structural cues, calibrated fusion, and an optional paraphrase-consistency gate. The protocol freezes data, fitting, attacks, predictions, and review decisions; separates deterministic L1 rewrites from human-adjudicated L2/L3 candidates; and keeps exact-deduplicated Track A distinct from group-near-deduplicated Track B. On Track A (seed 42), gated RMF-PC achieved clean F1 97.937%, L1 F1 98.117%, and L1 spam FNR 1.971% (11/558). Its FNR difference from linear SVM was -0.538 percentage points (exact McNemar p=0.5078; paired-bootstrap 95% interval -1.613 to +0.538), so superiority is unresolved. On Track B, the same comparison had a raw p=0.0215 but a Holm-adjusted p=0.0859, showing that cohort policy can affect an inferential conclusion. Two reviewers and adjudication retained 38 L2 and 55 L3 candidates; observed misses were 1/38 and 0/55. Enron and third-party Zenodo-curated TREC tracks show corpus sensitivity and fixed 5%/10% adaptation results. Findings are limited to the retained local protocols.
Keywords:
email spam detection
; adversarial robustness
; paraphrase attack
; reproducibility
; cross-corpus evaluation
; sparse machine learning
1. Introduction
Email filters must preserve spam recall, limit false positives, and fit local deployment constraints. Large language models can generate fluent malicious text and can support semantic detection controls, but their compute and data-governance demands differ from a local CPU pipeline. We ask what a local detector can support when its attack, corpus, split, evaluation files, and uncertainty analysis are all recorded. Classical spam-filter evaluation and the Enron-Spam benchmark motivate the retained baselines [1,2], while TREC 2007 is retained as a historical spam-track reference [3].
Recent work documents both the ability of large language models to create convincing phishing text and their use as spam-detection controls [4]. Rather than extrapolating external headline metrics, this manuscript reports a local, frozen protocol and names the attack capabilities that were actually tested.
The paper records separate L1, L2, and L3 protocols and denominators; separates Track A in-domain results from Track B transfer and adaptation results; and compares traditional models with MiniLM and DistilBERT embedding-plus-logistic-regression controls on frozen IDs. Its claims follow the frozen predictions, adjudication files, confidence intervals, and paired tests. This artifact-centered framing follows reproducibility and dataset-documentation practice: retain code, data version, environment, and the evaluation record needed to inspect a result [5,6,7,8,9].

Table 1.
Evaluated paraphrase threat levels and reporting boundary.
| Level | Generator and feedback | Evaluation denominator | Interpretation boundary |
|---|---|---|---|
| L1 | Deterministic surface rewriting; no model feedback | All 558 Track-A test spam | Controlled surface-form perturbation |
| L2 | Local generator; non-adaptive | 38 human-valid candidates from 100 screened | No target-prediction feedback |
| L3 | Local generator; at most three target queries | 55 human-valid candidates from 100 screened | Bounded local adaptive setting; not commercial full restructuring |
2. Related Work and Research Scope
2.1. Learning-Based Email Filtering
Learning-based spam filtering has long been framed as text categorization with asymmetric operational costs: a false positive can suppress legitimate mail, whereas a false negative exposes a user to unwanted or harmful content. Early Naive Bayes evaluations established corpus-specific training and evaluation protocols [1], while later work compared alternative Bayes formulations and preprocessing choices [2]. Text categorization research also established sparse high-dimensional learning as a practical setting for support-vector methods [10]. Recent phishing research shows that language models can remove superficial writing cues and support iterative, context-dependent message generation [11,12]. At the same time, recent benchmark studies warn that unrepresentative benchmark populations, duplicate overlaps, and opaque model exposure can inflate apparent results [13,14]. Support-vector filtering demonstrated that sparse textual representations could give competitive performance and practical training time [15]. These studies motivate the retained classical baselines, but they do not remove the need to audit duplicate messages, temporal or source overlap, and metric denominators in current reproductions.
A classifier score is only one part of the result. The cohort, split manifest, text normalization, fitted vocabulary, calibration partition, attack generator, and paired prediction vector determine what that score means. Without them, an accuracy difference can reflect a different evaluation population. This is common in public mail collections assembled from multiple folders or republished in curated form.
This protocol-oriented position is related to established work on online supervised spam-filter evaluation, which formalized the need to specify the evaluation population, contamination controls, and metric denominators for a spam-filter score [16]. It differs in retaining both attack-side review decisions and paired prediction artifacts. Deduplication studies show that overlap between training and test data can degrade learned representations [17]; dataset-documentation and contamination-tracing work shows that a reported score needs a stated population, a stated overlap policy, and a stated exposure boundary [6,7,8]. A recent re-evaluation of phishing-email benchmarks finds that near-perfect in-dataset results can conceal limited realism and motivates transparent reimplementation and dataset documentation [14]. The present work therefore treats exact and group-near deduplication as explicitly different cohort policies rather than interchangeable preprocessing details.
2.2. Paraphrase Attacks and Language-Model Controls
Natural-language adversarial evaluation differs from image perturbation evaluation because candidate validity cannot be inferred from edit distance alone. Word substitutions may change an entity, add a harmful promise, reverse an instruction, or yield unreadable text. NLP attack studies based on substitutions, semantic constraints, and saliency [18,19,20,21,22] motivate explicit candidate-validity controls. Recent phishing work further shows critique-refinement generation [12] and multi-round fraud inducements [23], reinforcing the need to distinguish fluent output from a comparable, valid attack sample. In the email setting, language models can produce fluent phishing material [4,24], while recent benchmark work evaluates conventional and language-model detectors under a common phishing-email protocol [14]. Those findings justify testing a bounded local generator, but they do not justify claims about a different commercial model, an unrestricted attack budget, or a message with changed operational intent.
The modern controls use fixed all-MiniLM-L6-v2 or DistilBERT-base-uncased embeddings followed by logistic regression. Transformer self-attention provides the architectural basis [25], BERT provides the contextual pretraining basis [26], Sentence-BERT provides the embedding formulation [27], and DistilBERT and MiniLM document compression routes for Transformer representations [28,29]. These controls test representation transfer on the same frozen manifests. They are not fully fine-tuned email detectors.
Table 2.
Scope of related approaches and their role in this study.
| Approach | What it contributes | What is not inferred here | Study role |
|---|---|---|---|
| Classical sparse text filters | Interpretable local baseline | Universal robustness | NB, SVM, RF and RMF-PC |
| Embedding plus linear controls | Fixed contextual representation | Fine-tuned Transformer ranking | MiniLM and DistilBERT controls |
| Rule surface rewrite | Deterministic rule-defined perturbation; Appendix A2 | Semantic preservation by itself | L1 test |
| Local LLM paraphrase | Fluent candidate generation | Commercial or unlimited attacks | L2/L3 after human review |
2.3. Research Questions and Evidence Boundary
The study is organized around four questions. RQ1 asks whether a sparse local detector maintains useful L1 spam recall on an exact-deduplicated in-domain split. RQ2 asks whether the word, character, fusion, augmentation, and gate components change that result under the same attack list. RQ3 asks whether the observed behavior persists when the source-trained models are evaluated on separately prepared Enron and curated TREC targets and when a small, isolated target-domain label budget is introduced. RQ4 asks whether a human-validated local LLM paraphrase set changes the empirical miss rate within an explicitly bounded attack budget. Each question has a separate denominator and cannot be pooled into a single universal robustness score.
Table 3.
Evidence map and non-claims.
| Question | Primary evidence | Supported statement | Explicit non-claim |
|---|---|---|---|
| RQ1 | Track-A frozen clean/L1 vectors | Protocol-specific in-domain FNR | Robustness to all paraphrases |
| RQ2 | Component ablations and paired tests | Observed component differences | Statistical superiority when interval crosses zero |
| RQ3 | Track-B targets and isolated adaptation splits | Distribution shift and limited adaptation behavior | Official raw TREC performance or general domain invariance |
| RQ4 | Review and adjudication records | Human-validated bounded local attack outcome | Success rate for unreviewed candidates or unrestricted LLMs |
3. RMF-PC Method and Design Rationale
3.1. RMF-PC and Deployment Boundary
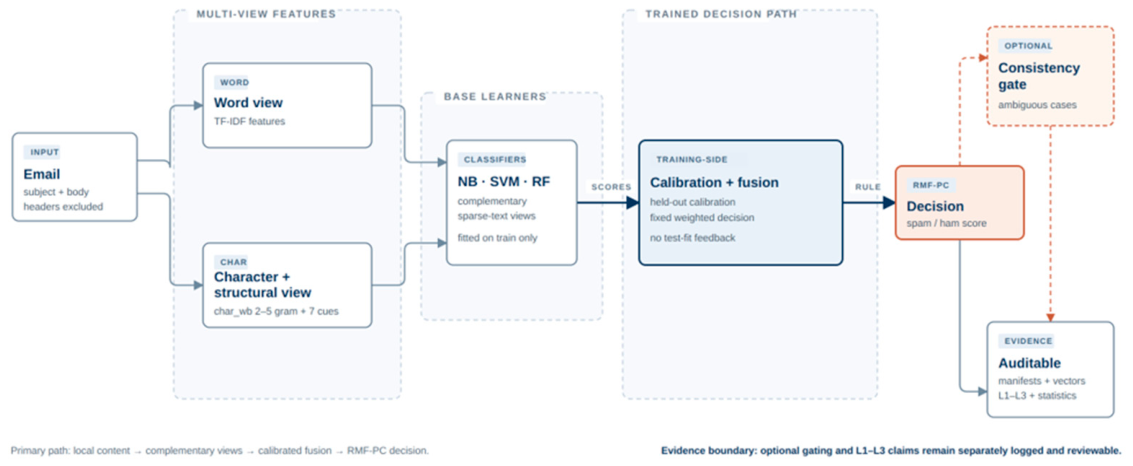
RMF-PC operates on subject and body text. Its word view is 1-2 gram TF-IDF (English stop words removed, min_df=2, sublinear term frequency) and its character view is char_wb 2-5 gram TF-IDF concatenated with seven standardized structural features: length, word count, URL count, phone-number count, digit ratio, uppercase ratio, and punctuation count. The structural features are therefore part of the character-plus-structural logistic-regression branch, not a third separately weighted fusion input. The word classifier is a linear SVM with hinge-loss labels t=2y-1; when its score is fused with probabilistic outputs, calibration is fitted only within the training or validation partitions. The optional gate is activated only near the probability decision threshold, creates three rewrite copies, and aggregates their predictions. It is an optional defense-in-depth mechanism rather than a universal improvement.
The linear SVM and random-forest baselines follow standard formulations [30,31], and all TF-IDF, calibration, classification, and metric calculations use the documented scikit-learn implementation [32].
Figure 1.
Core RMF-PC architecture and evidence boundary. Fitting, calibration and fusion are confined to training-side partitions; the consistency gate is optional and logged separately.
Figure 1.
Core RMF-PC architecture and evidence boundary. Fitting, calibration and fusion are confined to training-side partitions; the consistency gate is optional and logged separately.
3.2. Fitting Order and Decision Rule
All data-dependent transformations are fitted after the split. For each model, the training manifest fixes the message IDs and labels; the vectorizer vocabulary and inverse-document-frequency statistics are fitted on training text only. Where a calibration or fusion rule is needed, its inputs are generated from a training-side validation partition rather than the held-out evaluation files. Augmentation is applied only to training documents, and attack candidates are generated only after the evaluation samples have been frozen. This order prevents an attacked test message, a test-domain token frequency, or a test probability from influencing the fitted representation or threshold; it also avoids the leakage and evaluation malpractices documented for repeatedly reused or opaque evaluation data [33].
Let x_w denote the word TF-IDF vector and let x_cs denote the concatenation of character TF-IDF and standardized structural features. The word classifier uses a signed linear decision function f_w(x_w), with the hinge-loss label convention t=2y-1. Training-side calibration produces p_w, while a logistic-regression classifier produces p_cs. The fused probability is p=0.45p_w+0.55p_cs; there is no unreported third structural weight. The gate is invoked when |p-0.5|<0.20, i.e., p lies strictly between 0.30 and 0.70. It creates three deterministic local surface variants, predicts them with the frozen classifier, and takes the median of the original and three variant probabilities. The retained experiment did not log the natural test-traffic gate-trigger prevalence; accordingly, no amortized gate-cost or operational value claim is made.
Algorithm 1 gives the experimental order rather than a claim that the procedure is optimal. It provides the minimum sequence required for the reported result to be reproducible. The step that consumes the attack generator is deliberately downstream of model fitting and test-manifest freezing.
Algorithm 1. Leakage-controlled RMF-PC evaluation procedure.
| Step | Operation | Artifact retained |
| 1 | Audit archives; remove duplicates according to the declared track policy | Archive hashes and retained IDs |
| 2 | Create stratified seed-42 source split before any augmentation | Train/test manifests |
| 3 | Fit vectorizers, classifiers, calibrators and fusion only on training-side data | Serialized configuration and versions |
| 4 | Freeze clean predictions; generate L1, L2 or L3 candidates from test IDs | Prediction and attack manifests |
| 5 | Review L2/L3 candidate validity before formal denominators are formed | Reviewer forms and adjudication |
| 6 | Compute paired metrics and intervals from frozen vectors | Metric, bootstrap and test outputs |
3.3. Frozen Implementation Specification
The frozen run uses word TF-IDF with 1-2 grams, English stop-word removal, min_df=2 and sublinear term frequency; character TF-IDF uses char_wb 2-5 grams, min_df=2, sublinear term frequency, and at most 100,000 features. The character-plus-structural branch is LogisticRegression(max_iter=1000, random_state=42). The word SVM is CalibratedClassifierCV(LinearSVC(random_state=42), cv=3, method=“sigmoid”); scikit-learn defaults therefore set C=1.0 and class_weight=None. RMF-PC uses p=0.55p_cs+0.45p_w, ambiguity band delta=0.20, and k=3 gate variants. Training augmentation appends two L1 variants to each training message. Baselines are default Naive Bayes, LinearSVC (random state 42), and RandomForestClassifier with 200 trees, random state 42, and one worker. These values describe the retained implementation; they were not tuned on the test set.
L1 is a deterministic rule-defined surface transformation. It preserves URL, email-address, currency, and numeric spans; independently applies synonym substitutions with probability 0.85, single-letter u/r expansions with probability 0.70, reversal of one contiguous four-word span only for segments of at least 12 words with probability 0.60, a greeting prefix with probability 0.85, and a closing line with probability 0.70. The complete synonym mapping and protected-token expression are listed in Appendix A2. Each training message receives two seeded L1 variants; each test attack receives one deterministic seeded variant. L1 is not a semantic-preservation proof. L2/L3 decoding fields retained in the frozen record are seed 42, temperature 0.7, top-p 0.9, maximum 192 tokens, and the L3 maximum of three target queries. A human-readable generator release label, full prompt text, and complete candidate-selection policy were not retained; the manuscript therefore does not make generator-specific or yield-wide claims.
3.4. Complexity and Practical Deployment Implications
For sparse linear text models, prediction scales approximately with the nonzero feature count, while the random-forest cost additionally depends on the number and depth of trees. The character view offers tolerance to superficial token changes but can increase sparsity and feature extraction cost. The gate triggers extra preprocessing and prediction only for threshold-adjacent messages. Because a natural test-traffic trigger prevalence was not retained, the present work does not estimate its amortized service cost or make a lightweight-latency claim.
The evaluation distinguishes local inference, CPU feasibility, latency, and robustness. A strict service-level target is not claimed. The retained timing evidence supports only the stated same-machine comparison between the two modern controls; it does not support a numerical latency ranking against RMF-PC.
4. Experimental Protocol and Reproducibility
4.1. Data Tracks, Provenance, and Leakage Controls
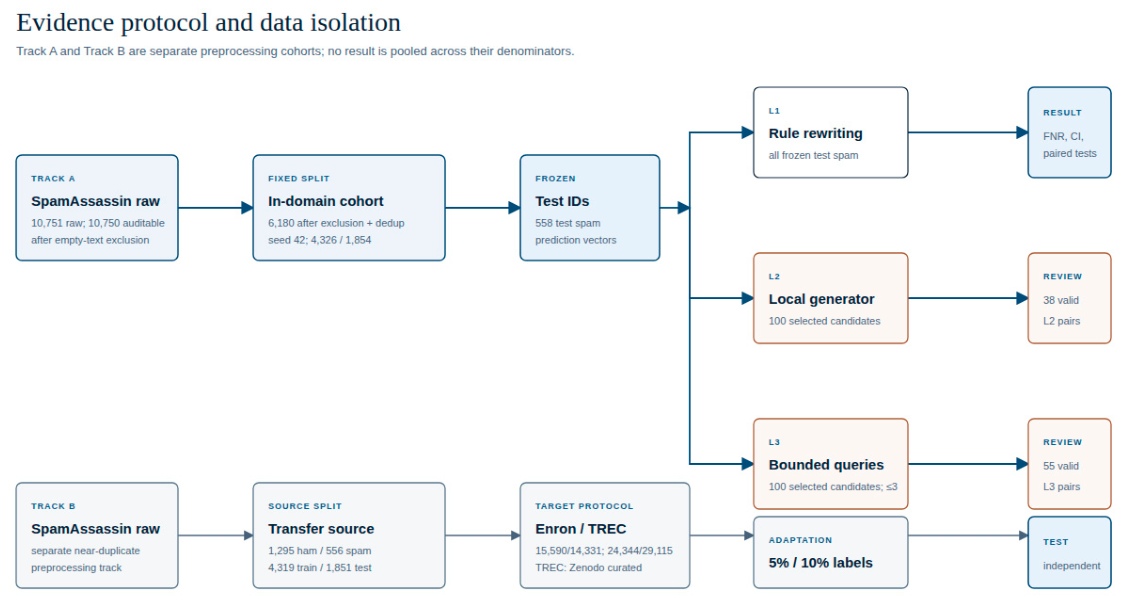
Track A used 10,751 raw Apache SpamAssassin messages obtained from nine public-corpus archives [34]: 6,954 ham and 3,797 spam. The category composition was easy_ham 5,052, easy_ham_2 1,401, hard_ham 501, spam 1,002, and spam_2 2,795. One message yielded empty extracted text and was excluded before exact-content auditing; no unreadable files were recorded. The remaining 10,750 messages contained 4,225 duplicate groups (4,570 duplicate messages beyond the first) and no cross-label duplicate group. Exact duplicate removal therefore retained 6,180 messages; the stratified seed-42 manifest contains 3,025 ham / 1,301 spam in training and 1,296 ham / 558 spam in test. Archive-level SHA-256 values are retained in Appendix A, along with names and counts.
Track B is a separate group-near-deduplicated source cohort: 6,170 messages split into 4,319 source training and 1,851 source test messages (1,295 ham; 556 spam). It supports transfer and adaptation only and is never pooled with Track A. Enron retained 29,921 target messages (15,590 ham; 14,331 spam) after cross-source screening. The TREC target contains 53,459 normalized messages (24,344 ham; 29,115 spam) from the third-party Zenodo TREC_07.csv curated version (record 8339691), not an official NIST raw-corpus download; all TREC claims are limited to that frozen curated input [35,36]. Public corpus provenance does not demonstrate that a benchmark was absent from the pretraining data of every language model, so the manuscript does not make that claim [37]. The retained target labels were not independently reconciled against an official raw-corpus mapping. No raw email body or attachment is redistributed with the reproducibility package. Source-specific license or access terms govern downstream retrieval and redistribution; where no SPDX license field was retained in the local audit, the manuscript does not infer one.
Exact deduplication identifies byte- or normalized-content-identical messages within the Track-A corpus. Group-near deduplication is a stricter cross-source policy used for Track B to suppress highly similar messages before transfer evaluation. These policies create different retained cohorts and are therefore reported as separate tracks rather than alternative preprocessing of a shared denominator. File presence, category assignment, archive hash, duplicate counts, class proportions, and split IDs were retained in dataset-audit and manifest outputs. No target-domain test message was used to choose a source-trained hyperparameter.
Table 4.
Data and evaluation isolation.
| Track | Source / target | Split or target size | Use |
|---|---|---|---|
| A | SpamAssassin, exact deduplication | 4,326 train / 1,854 test; 558 test spam | In-domain L1, ablation, L2/L3 |
| B | SpamAssassin, group-near deduplication | 4,319 source train / 1,851 source test | Source-trained transfer and adaptation |
| B target | Enron after cross-source screening | 29,921: 15,590 ham / 14,331 spam | Transfer and independent adaptation test |
| B target | TREC 2007 Zenodo curated version | 53,459: 24,344 ham / 29,115 spam | Transfer and independent adaptation test |
Figure 2.
Experimental evidence and data-isolation protocol. One Track-A message with empty extracted text is excluded before the exact-deduplication audit. Track A and Track B use separate preprocessing cohorts and are never pooled.
Figure 2.
Experimental evidence and data-isolation protocol. One Track-A message with empty extracted text is excluded before the exact-deduplication audit. Track A and Track B use separate preprocessing cohorts and are never pooled.
Nine frozen prediction pipelines are compared: Naive Bayes, linear SVM, random forest, RMF word, RMF character, RMF fusion, RMF gated fusion, all-MiniLM-L6-v2 embeddings plus logistic regression, and DistilBERT-base-uncased embeddings plus logistic regression. The transformer controls are offline embedding-plus-linear models, not transformer fine-tuning. Sentence-BERT style embedding models and distilled Transformers motivate these controls [27,28].
4.2. Threat Model and Candidate-Validity Review
The capability framework separates the threat from the test artifact. C1 is a surface-form capability: spelling, punctuation, whitespace, or limited synonym changes. C2 is a semantically constrained paraphrase capability that aims to preserve the message proposition. C3 adds bounded query feedback to a local target model. C4 would allow unrestricted semantic restructuring, multi-turn planning, external tools, or a commercial LLM; it is out of scope. L1 operationalizes C1 using deterministic rules; L2 operationalizes a fixed local model without target feedback; L3 operationalizes a fixed local model with at most three target queries. No C4 result is reported.
For L2 and L3, a candidate enters the formal denominator only after independent assessment of four criteria: semantic preservation, named-entity preservation, absence of newly introduced harmful content, and fluency. A failed criterion means the candidate may remain in a screening log but cannot count as a successful evasion or a tested attack. Adjudication resolves reviewer disagreement. This is a conservative choice: it reduces the effective sample size but avoids reporting a prediction change for a meaning-changed email as a paraphrase evasion.
Table 5.
Human-review rubric for L2/L3 candidate eligibility.
| Criterion | Pass condition | Examples requiring exclusion |
|---|---|---|
| Semantic preservation | Core request, offer and intended action are unchanged | A payment request becomes a meeting invitation |
| Entity preservation | People, organizations, amounts, URLs and dates are retained or equivalently masked | Replacing a named bank, amount, or destination URL |
| No harm addition | No new coercion, credential request, malware claim or financial promise | Adding a threat or a new credential-harvesting step |
| Fluency | Message is comprehensible English without obvious corruption | Broken fragments or nonsensical substitutions |
4.3. Metrics and Statistical Analysis
Accuracy, precision, recall, F1, false-positive rate (FPR), and spam miss rate FNR=FN/(TP+FN) are calculated from frozen prediction vectors. FPR and ROC-oriented diagnostic thinking follow standard classifier-evaluation practice [38]. L1 FNR uses every test-spam message. L2/L3 all-effective-candidate miss rate uses only human-adjudicated effective candidates; conditional attack success is calculated only among candidates whose originals were correctly detected. Wilson intervals are used for binomial FNR [39]. Pairwise comparisons use 10,000 matched bootstrap replicates [40] and two-sided exact McNemar tests [41]; Track-B family-wise p values are Holm-adjusted [42].
Wilson intervals quantify uncertainty in a binomial miss rate. Matched bootstrap intervals quantify the difference between two models on the same messages. McNemar tests discordant paired decisions. They answer different questions, and a non-significant paired result does not make two models equivalent. Calibration is kept separate from evaluation because score-to-probability fitting must not use test outcomes [43,44,45]. We use paired, per-corpus inference rather than pooling corpora or comparing independently computed summaries [46] and report the confusion-matrix measures described by Sokolova and Lapalme [47]. The analysis output retains Holm-adjusted p values for Track-B comparisons; the F1/FNR tables remain descriptive because corpus shift rules out a single global ranking.
4.4. Execution Environment and Reproducibility Record
The fixed random seed is 42. The reproducibility record captures Python and library versions, operating-system and CPU information, archive SHA-256 values, commands, input manifests, model configuration, output hashes, and elapsed time. The modern-control timing uses the Ubuntu VM stated in Section 5.4. No cross-model latency comparison is made because no same-machine RMF-PC latency record is retained.
Table 6.
Reproducibility artifacts retained with the experiment.
| Artifact | Purpose | Use in audit |
|---|---|---|
| Dataset audit JSON and Markdown | Archive identity, extraction and duplicate policy | Verify input provenance |
| Split and prediction manifests | Stable IDs, labels and frozen outputs | Recompute paired metrics |
| Attack trajectory and candidate files | L1 rule output and L2/L3 generation trace | Separate screening from formal samples |
| Reviewer and adjudication CSVs | Eligibility decisions and reasons | Freeze L2/L3 denominator |
| Environment and execution logs | Versions, CPU, commands and runtime | Repeat implementation path |
5. Results
5.1. Track A Fixed-Split L1 Results
Gated RMF-PC produced a 1.971% L1 FNR (11/558), compared with 2.509% (14/558) for linear SVM. The paired comparison has only nine discordant decisions and does not establish superiority: exact McNemar p=0.5078125 and the paired-bootstrap FNR-difference interval crosses zero. It should not be read as equivalence either: no equivalence margin or minimum detectable effect was prespecified. F1 is shown alongside FNR and FPR because an attacked F1 can increase while false-positive behavior changes.
On the same frozen Track-A IDs, DistilBERT plus logistic regression had a lower L1 FNR than gated RMF-PC (0.896%, 5/558 versus 1.971%, 11/558), whereas gated RMF-PC had the higher L1 F1 (98.117% versus 96.763%). The paired gated-minus-DistilBERT FNR difference is +1.075 percentage points (95% bootstrap interval 0.000 to 2.330; exact McNemar p=0.1460). These results are reported as a trade-off on this cohort, not as a universal ranking.
Table 7.
Track-A fixed-split L1 comparison (seed 42; 1,296 ham and 558 spam).
| Model | Clean F1% | L1 F1% | L1 FPR % | L1 spam FNR % |
|---|---|---|---|---|
| Naive Bayes | 88.801 | 87.800 | 0.231 | 21.326 |
| Linear SVM | 96.804 | 98.018 | 0.617 | 2.509 |
| Random forest | 96.596 | 96.310 | 0.309 | 6.452 |
| RMF-PC word | 96.751 | 97.948 | 1.080 | 1.613 |
| RMF-PC char | 97.080 | 97.464 | 0.617 | 3.584 |
| RMF-PC fusion | 97.838 | 98.025 | 0.772 | 2.151 |
| RMF-PC gated fusion | 97.937 | 98.117 | 0.772 | 1.971 |
| DistilBERT embedding + LR | 97.948 | 96.763 | 2.469 | 0.896 |
Audit note: DistilBERT Clean and RMF-PC word L1 have the same aggregate confusion counts (TN=1,282, FP=14, FN=9, TP=549), and therefore the same rounded six metrics. They are not copied predictions: the retained vectors differ on 32 of 1,854 IDs. Table D0 reports the complete independently recomputed rows.
Table 8.
Track-A RMF-PC ablations under the same L1 attack.
| Configuration | Clean F1% | L1 F1% | L1 FNR % | Interpretation |
|---|---|---|---|---|
| Word only | 96.751 | 97.948 | 1.613 | Lowest observed component FNR |
| Char only | 97.080 | 97.464 | 3.584 | Higher FNR than word view |
| Fusion | 97.838 | 98.025 | 2.151 | Optional combination |
| Gated fusion | 97.937 | 98.117 | 1.971 | Small observed difference; no superiority claim |
| Fusion without augmentation | 97.561 | 97.926 | 2.688 | +0.537 pp vs augmented fusion |
| Gated fusion without augmentation | 98.018 | 97.930 | 2.509 | +0.538 pp vs augmented gated fusion |
The equality between selected values in Table 8 and the linear-SVM L1 row of Table 7 is not a copied entry. The gated no-augmentation and linear-SVM L1 vectors share the same spam miss count (14/558), but differ on 13 of 1,854 IDs; on spam, the paired discordances are n01/n10=5/5 (exact McNemar p=1.000). The no-augmentation metrics are independently derived from the retained no-augmentation prediction bundle. The configurations nevertheless differ, and Table 8 should be interpreted only as the stated ablation comparison.
5.2. Human-Adjudicated Local LLM Attacks
Automatic screening was not treated as a formal attack-success rate. Two reviewers independently assessed semantic preservation, entity preservation, absence of added harm, and fluency; disagreements were adjudicated. From 100 selected candidates per protocol, 38 L2 and 55 L3 candidates were retained as effective. Every retained original was correctly detected, so conditional success equals the reported miss count over the effective denominator. The record does not retain the full generator yield or selection rule before these 100 selected candidates; the results are therefore limited to the adjudicated candidate sets.
Table 9.
Human-adjudicated local-generator L2/L3 feasibility observations.
| Protocol | Selected / effective | Misses | All-effective miss rate | Conditional success | Boundary |
|---|---|---|---|---|---|
| L2 non-adaptive | 100 / 38 | 1 | 2.632% (Wilson 0.466–13.495%) | 1 / 38 | No target feedback |
| L3 bounded adaptive | 100 / 55 | 0 | 0.000% (Wilson upper 6.529%) | 0 / 55 | At most 3 queries |
The frozen generator summaries identify the local generator by SHA-256 8ffcf166d3467df1c38991fa6196c8798b7e2bb9101d8fa34f6cd3c186913f14. A human-readable generator release label was not retained in the frozen summary, so it is not retroactively inferred here. L2 and L3 parameters and agreement figures are reported in Appendix B; the pre-human L3 automated evasion count remains a screening field and is not used in Table 9.
Table 9.
a. Retained L2/L3 generation and review metadata.
| Field. | L2 non-adaptive | L3 bounded adaptive |
|---|---|---|
| Seed / selected candidates | 42 / 100 | 42 / 100 |
| Threat feedback | None | Frozen gated RMF-PC; max. 3 queries |
| Temperature / top-p / max tokens | 0.7 / 0.9 / 192 | 0.7 / 0.9 / 192 |
| Threads / context | 8 / not recorded | 8 / 2,048 |
| Generator yield / selection policy | Not retained | Not retained |
| Model identifier | SHA-256 retained; release label absent | SHA-256 retained; release label absent |
5.3. Track B Cross-Corpus Transfer and Adaptation
Track-B values are descriptive source-trained transfer results on frozen target IDs. Table 10 and Table 11 and Appendix D2–D3 are full frozen target-corpus transfer evaluations: Enron covers 29,921 messages (15,590 ham and 14,331 spam), and TREC covers 53,459 messages (24,344 ham and 29,115 spam). They show substantial domain sensitivity and should not be interpreted as a universal corpus ranking (Figure 3). Section 6.5 discusses the protocol sensitivity of the Track-B source-holdout comparison. These full-target transfer cohorts are distinct from the target-domain adaptation models, which use a 30% independent target test set; 5% and 10% label budgets are drawn only from a disjoint 70% adaptation pool. Enron adaptation test contains 4,677 ham and 4,300 spam (n=8,977); TREC adaptation test contains 7,303 ham and 8,735 spam (n=16,038). The retained audit does not preserve the per-class counts sampled into each 5%/10% adaptation subset, so no stronger class-balance claim is made.
Table 12 is evaluated on a different population from the Enron and TREC columns of Table 10 and Table 11: the adaptation models are tested on the independent 30% target test set, whereas the source-trained transfer rows in Table 10 and Table 11 are evaluated on the full target corpus. The two are therefore not directly comparable and must not be differenced.
A model can score well on the SpamAssassin source and lose F1 and spam recall on a target collection. Figure 3 shows the consequence for model selection: RMF-PC char degrades from 6.47% to 72.51% spam FNR on Enron, while DistilBERT + LR also degrades, from 4.50% to 22.96% on Enron and 24.94% on TREC, and is nonetheless the best target-corpus detector of the nine. A source holdout therefore selects a different detector than the target corpora do. Neither L1 rewriting nor an embedding representation removes the need to measure the target distribution. The tested 5% and 10% label budgets improved outcomes on their fixed pools and independent target tests; they do not define a universal labeling requirement.
5.4. Same-CPU Modern-Control Latency
MiniLM and DistilBERT controls were measured on the same Ubuntu VM (Intel Xeon E7-4830 v3 at 2.10 GHz; 15 GiB RAM; Python 3.12.3; PyTorch 2.14.1+cpu). One thread, batch size one, ten warm-up items, 100 fixed IDs, and five repeats produced 500 timed items per control. These values compare the two modern controls only; no same-machine RMF-PC timing exists.
Table 13.
Same-CPU modern embedding-control latency (ms; 500 timed items each).
| Pipeline | Feature mean | Predict mean | E2E mean | Median | P95 | P99 | Max | Items/s |
|---|---|---|---|---|---|---|---|---|
| MiniLM + LR | 428.286 | 0.667 | 428.953 | 483.963 | 512.894 | 526.829 | 668.683 | 2.331 |
| DistilBERT + LR | 1397.511 | 0.793 | 1398.304 | 1584.746 | 1620.046 | 1650.847 | 1748.803 | 0.715 |
The preserved timing summary does not retain per-item minima or quartile counts, so these values are not reconstructed. Mean, median, upper quantiles, and maxima are reported exactly as retained. In both controls, the mean is lower than the median, indicating faster observations in the retained timed set; without per-item timings, the lower tail cannot be characterized further.
6. Discussion
6.1. Interpretation of the In-Domain Result
Track A is a controlled comparison. Word-only RMF-PC had the lowest observed L1 FNR among the listed RMF components, while gated fusion had the highest L1 F1. The difference between gated fusion and linear SVM did not meet the paired-test criterion. Rounded F1 alone would hide FNR, false-positive behavior, paired discordance, and latency.
Augmentation reduced the observed L1 FNR for fusion and gated fusion relative to the listed no-augmentation forms. Because training augmentation and the L1 test derive from the same deterministic rule family, this is a within-family robustness measurement: it shows the effect of exposure to that family, not robustness to unseen transformations, unrestricted paraphrases, or semantic attacks.
The L1 condition is a fixed deterministic perturbation, not a monotone difficulty increase. Table D0 shows a lower observed FNR for six of the eight pipelines, including two baselines that received no L1 augmentation (linear SVM: 28 to 14 of 558; DistilBERT: 9 to 5); it rises for Naive Bayes and random forest. The rule family combines potentially opposing changes: synonym substitution weakens some lexical spam markers, while independently sampled prefix and closing insertion add repeated boilerplate to many messages. These changes affect lexical, character, and embedding representations differently; for example, DistilBERT false positives rise from 14 to 32 while its spam misses fall from 9 to 5. Thus the L1 miss rate is a measurement under one specified perturbation family, not an ordering of attack strength. The within-family ablation difference associated with augmentation is consequently not the only contributor to the observed clean-to-L1 changes.
6.2. Human Review as a Measurement Control
L2/L3 review controls the measurement. A local generator can produce fluent text that changes a bank name, monetary amount, action request, or harm level. Counting it as evasion would mix changed message content with a detection failure. The formal L2/L3 denominators follow four-criterion review and adjudication. We retain selected totals to show the reviewed cohort, and use Wilson intervals because the effective totals are small. These L2/L3 results are a protocol demonstration, not a generator-wide security estimate.
L3 had zero misses among 55 effective candidates, but its two-sided Wilson upper bound is 6.529%. The result cannot support a zero-risk claim or resistance to a general adaptive LLM adversary. A larger study should preregister the prompt and query budget, retain complete trajectories, and use at least two independent reviewers with a documented adjudication rule.
6.3. Cross-Corpus Behavior and Model Selection
The transfer tables show domain shift. Source-trained sparse and embedding controls have materially different FNR values on Enron and the curated TREC target. A practitioner should treat a source-trained score as a screening baseline, audit target-language and source overlap, and reserve an isolated target test set before accepting an adapted classifier. The measured 5% and 10% configurations improved the fixed-split results; they do not specify a universal labeling policy.
MiniLM and DistilBERT serve a second role: they prevent an historical-only comparison. Their transfer behavior is reported alongside the traditional pipelines and their modern-control latency is measured on the same machine. The CPU measurements demonstrate a large feature-extraction cost for these frozen embedding pipelines relative to their logistic-regression head. They are not a cross-model latency comparison, because no same-machine RMF-PC latency measurement is retained.
6.4. Evidence Synthesis Across the Evaluation Layers
The experiment layers are complementary rather than interchangeable. L1 supplies a full, deterministic denominator for an auditable surface-form stress test. L2 and L3 contribute fluent local-generator candidates, but only after validity review reduces the sample to messages that remain comparable to their originals. Cross-corpus transfer measures a different question: whether a source-trained decision rule travels to a different collection. Target-domain adaptation measures whether a bounded amount of new-domain labeling changes an independently held-out target result. A conclusion can be strong within one layer while remaining untested in another.
This separation avoids two common aggregation errors. First, it would be invalid to average Track-A and Track-B FNR values because their duplicate policy, population, and evaluation purpose differ. Second, it would be invalid to replace the human-reviewed L2/L3 denominator with the 100 screened candidates merely because that produces a simpler percentage. The report instead uses the smallest denominator that matches the claim and exposes both the screened and effective counts.
6.5. Cohort Policy as an Experimental Variable
The two SpamAssassin tracks provide a direct protocol-sensitivity case. Under the same gated-versus-linear-SVM L1 comparison, Track A (exact deduplication; 558 test spam) gives an FNR difference of -0.538 percentage points, exact McNemar p=0.5078, and bootstrap interval [-1.613, +0.538]. Track B source holdout (group-near deduplication; 556 spam) gives -1.439 percentage points, raw exact McNemar p=0.0215, and bootstrap interval [-2.518, -0.360]. The cohorts are similar in size but differ in construction; these results show that a deduplication and cohort policy can change an inferential conclusion even when headline FNRs are close. This cohort sensitivity is consistent with, and complements, recent evidence that phishing-email benchmarks can sustain near-perfect in-dataset results whose realism does not transfer [14]. It is not evidence that one policy is universally preferable.
For Track B, the raw p value is below 0.05 and the bootstrap interval excludes zero, but the Holm-adjusted p value across the pre-specified Track-B comparison family is 0.0859. This manuscript treats the Holm-adjusted p value as the family-wise significance decision and reports the bootstrap interval as an effect-estimate uncertainty measure. Thus the Track-B result is described as a protocol-sensitive effect with a negative interval, not as an unqualified family-wise significant superiority claim. Track A remains unresolved under both summaries.
Figure 4 shows the corresponding paired differences and intervals for every retained comparator. The highlighted comparison is the one analysed in this section. Of the seven comparisons available in both cohorts, two change their relation to zero: gated RMF-PC versus linear SVM (Track A [-1.613, +0.538] includes zero; Track B [-2.518, -0.360] excludes it) and gated RMF-PC versus DistilBERT + LR (Track A [+0.000, +2.330] includes zero; Track B [-3.777, -0.180] excludes it). Intervals with a printed bound of +0.000 are treated as including zero. That the same comparator can fall on either side of zero depending on the cohort policy is why this section reports a protocol-sensitivity case rather than a detector ranking.
Table 14.
How the reported evidence should be used.
| Evidence layer | Question answered | Allowed conclusion | Not a substitute for |
|---|---|---|---|
| Track-A L1 | Surface robustness on fixed in-domain spam | Observed FNR under one deterministic transformation | Semantic LLM robustness |
| Reviewed L2/L3 | Bounded local paraphrase behavior | Observed miss rate after validity controls | Unrestricted adaptive attack estimate |
| Track-B transfer | Sensitivity to new corpus distributions | Source-trained target performance | Deployment acceptance test |
| Target adaptation | Value of the stated local label budgets | Outcome on the fixed independent target test | A universal labeling rule |
| Latency microbenchmark | Relative modern-control CPU cost | Batch-one timing on stated VM | End-to-end service SLO |
7. Operational Implications, Replication, and Future Evaluation
7.1. Decision Process for a Local Deployment Candidate
A sparse detector should be evaluated as a candidate component in a mail-processing workflow, not as a stand-alone claim of security. The operational decision begins with the false-positive tolerance, the allowed miss rate, the expected language and source mix, and the local compute budget. A sparse source-trained model may be appropriate for a constrained on-premise deployment, but an organization should first collect a legally permitted local calibration set, remove cross-partition duplicates, and reserve a final target test set that is not opened during threshold selection.
Organizational studies of LLM-generated phishing and quishing show why a content-only offline score should not be read as an organization-level exposure estimate [48]. The operational implications here are therefore limited to the retained corpus and stated local workflow assumptions.
The measured results suggest a practical sequence. First, reproduce a clean target baseline with the frozen source model to make distribution shift visible. Second, decide whether target-domain labels are available and, if so, use an isolated adaptation pool rather than the final target test set. Third, choose a threshold by a stated operational objective such as maximum allowed FPR or FNR; this study does not claim that the default 0.5 probability threshold is universally optimal. Fourth, evaluate both clean and prespecified attack conditions, and record the selected operating point. Finally, monitor post-deployment drift and route ambiguous cases to a review or a higher-cost control when the risk policy permits.
7.2. What Must Be Reproduced Before a Comparison Is Credible
A future comparison should reproduce the data version and not only the model name. Minimum requirements are the archive identity, deduplication function, fixed ID list, label mapping, text-extraction policy, train/validation/test boundaries, random seed, vectorizer settings, classifier settings, calibration procedure, attack parameters, and score-to-label threshold. A separate manifest should identify every message removed for duplication or parsing failure so that an apparent performance gain can be traced to a population change.
For modern embedding controls, the model identifier alone is also insufficient. The tokenizer, maximum length, pooling policy, feature normalization, logistic-regression configuration, CPU thread count, warm-up count, batch size, and timing-clock boundaries affect both performance and latency. The present experiment calls these pipelines “embeddings plus logistic regression” precisely to prevent readers from interpreting the result as end-to-end fine-tuning. Such distinctions make the comparison replicable even when a future study substitutes a newer encoder.
Table 15.
Pre-deployment reproduction checklist.
| Stage | Required control | Failure prevented |
|---|---|---|
| Data intake | Hash archives and retain extraction report | Unknown or changed corpus |
| Partitioning | Split and group-deduplicate before fitting | Train-test overlap |
| Fitting | Fit vocabulary, calibration and augmentation on training side | Test information leakage |
| Attack evaluation | Freeze originals, parameters and validity decision | Changing denominator or meaning |
| Reporting | Retain predictions and paired statistics | Unverifiable aggregate claim |
| Performance | State CPU, threads, batch, warm-up and timing scope | Non-comparable latency |
7.3. Stronger Evidence and Realistic Workload Evaluation
Future evaluation should extend the retained protocol rather than substitute a new, less auditable benchmark. Candidate extensions include source-authorized corpus releases, end-to-end fine-tuned controls under a common compute budget, and a service-level workload that includes MIME/HTML parsing, queueing, concurrent workers, cache behavior, model loading, alerting, tail latency, and failure handling. Such a study should state the local cost of false positives and false negatives before selecting an operating threshold. Across extensions, a zero observed count must retain its interval, a curated target must retain its provenance label, a non-significant paired result must remain inconclusive, and values from different hardware must not be converted into a common latency ranking.
8. Threats to Validity and Limitations
8.1. Construct and Internal Validity
Spam labels, email text extraction, and the definition of a valid paraphrase are constructs that can be imperfect. Exact and group-near duplicate policies reduce a concrete leakage risk but cannot prove that every related campaign or template has been removed. The pipeline addresses a more direct internal-validity risk by freezing splits before augmentation and vectorizer fitting, and by using frozen paired prediction vectors for uncertainty analysis. Calibration and gate configuration are described as training-side operations; they must not be re-tuned from the evaluation files.
8.2. External Validity
Apache SpamAssassin, Enron, and the third-party curated TREC version are historical English-language collections with collection-specific label and formatting characteristics. They do not represent contemporary multilingual mail, attachment-heavy abuse, header manipulation, HTML rendering, or enterprise mail-routing policies. The TREC evaluation used a Zenodo-hosted curated CSV whose retained labels were not independently reconciled against an official raw-corpus mapping. Results are intentionally scoped to the retained data version and manifests.
Recent benchmark reassessments identify the historical age of widely used phishing-email data, incomplete realism, and conflation risks as material threats to external validity, including for SpamAssassin-derived evaluations [14]. This study does not dispute those concerns and does not present Track-A results as a general estimate of contemporary spam or phishing detection. Instead, SpamAssassin is used to demonstrate an auditable protocol with fixed manifests and paired prediction records; the Track-B cohort-policy comparison shows that a single benchmark cannot settle a broad effectiveness claim.
8.3. Attack and Deployment Validity
L1 is deterministic and therefore reproducible, but it is not a natural-language adversary. L2 and L3 use a local generator with retained decoding settings and a bounded query budget, but its human-readable release label, full prompt text, and complete candidate-selection policy were not retained. They do not support claims about proprietary models, retrieval-augmented attackers, tool use, unlimited adaptive search, or deliberate semantic restructuring. Similarly, the latency protocol is a single-CPU, batch-size-one microbenchmark with fixed inputs. It is not a service-level workload test and omits concurrent requests, message parsing from mail servers, network queues, and model-loading amortization.
8.4. Reproducibility and Ethics
The study retains audit outputs so readers can check aggregate numbers. Public corpora and third-party derived files require license and provenance checks before redistribution. Attack artifacts should use access controls because they support evaluation and could otherwise aid phishing. The protocol includes only the detail needed to reproduce measurement.
8.5. Retained-Scope Limitations
All reported results use one seed (42). The Track-A gated-versus-linear-SVM comparison is unresolved (p=0.5078), whereas the Track-B source-holdout comparison yields p=0.0215 before Holm adjustment and 0.0859 after it; stability across seeds was not tested, so no seed-level claim is made. No per-category easy_ham, hard_ham, spam, or spam_2 result is reported; aggregate F1 is not a per-category estimate. Gate-trigger prevalence on natural traffic was not logged, so no amortized gate cost is estimated.
No same-machine RMF-PC latency record was retained. The timing table therefore compares the two modern embedding controls only and supports no cross-model latency ranking. L2/L3 remain protocol demonstrations: they use small human-adjudicated candidate sets and do not estimate a generator-wide evasion rate. Finally, the Track-A MiniLM prediction vector was not retained, so no MiniLM Track-A metric or paired comparison is reconstructed. These limitations delimit the claims above rather than constitute unreported negative results.
9. Conclusion
This paper combines in-domain L1 evaluation, human-adjudicated local L2/L3 candidates, cross-corpus transfer, limited target-domain adaptation, and same-CPU embedding controls. Freezing cohorts, splits, attacks, review decisions, and paired prediction vectors keeps observed model differences tied to identifiable protocols. RMF-PC performed well under the named protocols, but the study does not cover unrestricted LLM-generated spam.
For the exact-deduplicated Track-A split, the measured L1 FNR for gated RMF-PC was 1.971%, and its paired difference from linear SVM was not statistically conclusive under the stated exact McNemar and paired-bootstrap analyses (p=0.5078; interval -1.613 to +0.538 percentage points). The same comparison in the separately constructed group-near-deduplicated Track-B source holdout gave a raw p=0.0215 and a negative interval, but a Holm-adjusted p=0.0859. This reversal does not establish superiority; it demonstrates that cohort policy can change an inferential conclusion and must be treated as an experimental variable. For human-adjudicated local attacks, one L2 miss was observed in 38 effective candidates and no L3 misses were observed in 55 effective candidates; the associated interval bounds require cautious interpretation. Across the separate Track-B cohort, source-trained results changed materially by target corpus, while the stated 5% and 10% target-label budgets improved the results on fixed independent target tests.
Future work should preserve corpus provenance, prevent split leakage before feature fitting or augmentation, report attack eligibility separately from generator yield, use paired uncertainty analyses for shared examples, and state hardware boundaries for latency. These records show whether a changed result came from the detector, the corpus, or the claim.
Table 16.
Final claims and their evidence limits.
| Claim | Evidence retained | Limit that remains |
|---|---|---|
| Track-A L1 behavior | Exact-deduplicated split and frozen paired predictions | One corpus, seed and deterministic attack |
| L2/L3 local attack outcome | Two-reviewer adjudicated effective candidate sets | Small samples and bounded local generator |
| Cross-corpus sensitivity | Separate group-near-dedup transfer outputs | Curated rather than official raw TREC target |
| Adaptation benefit | Fixed 5%/10% label budgets and independent target tests | No universal target-label recommendation |
| Modern-control cost | Same-CPU microbenchmark for two embedding controls | No same-machine RMF-PC latency claim |
Author Contributions
Conceptualization, Xin Ge, Minnan Yue; Methodology, Xin Ge, Minnan Yue; Software, Xin Ge, Shanshan Wang, Ye Xu; Formal analysis, Xin Ge, Dan Wang; Data curation, Xin Ge, Sizheng Zhu; Investigation, Xin Ge, Sizheng Zhu, Shanshan Wang; Validation, Sizheng Zhu, Dan Wang; Resources, Shanshan Wang, Ye Xu; Writing – Original Draft Preparation, Xin Ge, Sizheng Zhu, Shanshan Wang; Writing – Review & Editing, Minnan Yue, Dan Wang, Ye Xu; Visualization, Xin Ge, Shanshan Wang; Supervision, Minnan Yue; Project administration, Minnan Yue, Ye Xu; Funding acquisition, Minnan Yue. All authors have read and agreed to the published version of the manuscript.
Funding
This work was supported in part by the National Key Research and Development Program of China [grant number 2024YFA1012501] and in part by the National Natural Science Foundation of China [grant numbers 52476212 and 52576221]. The funders had no role in the study design, data collection and analysis, decision to publish, or preparation of the manuscript.
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
The replication package contains source archive hashes, duplicate policies, split manifests, frozen prediction files, attack manifests, human-review and adjudication records, environment versions, and statistical outputs. It is available from the corresponding author on reasonable request, subject to the terms governing the underlying corpora. The TREC evaluation uses the stated third-party Zenodo curated version and is not a substitute for an official raw NIST release. The contents of this section follow data-statement practice for natural-language and machine-learning artifacts [6,49], listing retained artifacts, provenance, and redistribution conditions.
Acknowledgments
We thank the High-Performance Computing Center of the University of Shanghai for Science and Technology for its support during this research. During the preparation of this manuscript/study, the author(s) used a locally hosted language model for the purposes of generating the L2 and L3 candidate text under the documented evaluation protocol, and generative-AI assistance was used for language editing during manuscript preparation. The authors have reviewed and edited the output and take full responsibility for the content of this publication.
Conflicts of Interest
The authors declare no conflicts of interest.
Abbreviations
| AI | Artificial intelligence |
| CCI | Consecutive character injection |
| CI | Confidence interval |
| FNR | False negative rate |
| FPR | False positive rate |
| LLM | Large language model |
| RMF-PC | Reproducible Mail Filter Protocol with Cohort provenance, defined in this work |
| SHA-256 | Secure Hash Algorithm 256-bit |
| TF-IDF | Term frequency–inverse document frequency |
Appendix A: Reproducibility Record
The reproduction package uses immutable identifiers, not only aggregate tables. The dataset audit records archive names, SHA-256 digests, extraction checks, category counts, duplicate decisions, and the selected cohort. Split manifests retain a message ID, label, partition, and, where applicable, source group. Clean and attacked prediction files retain input ID, prediction, score where applicable, and model configuration ID. An independent statistician can reconstruct a confusion matrix or paired comparison without re-running a generator.
Table A0. Apache SpamAssassin archive identities and SHA-256 digests.
| Archive | Bytes | SHA-256 |
| 20021010_easy_ham.tar.bz2 | 1,677,144 | f9fc56e1f68780f9afdc6d23a2e24c4584af988afc58bbfabae500e51f3a2f36 |
| 20021010_hard_ham.tar.bz2 | 1,021,126 | 7cd46378877e00caa4e943920a854e2ef95ac29e296cf2a3ce691fb4104c4fbd |
| 20021010_spam.tar.bz2 | 1,192,582 | 048c2d2e61ff13f7cef88788c7184ee57dbc9049c58e5bd706fdb8537e9bac81 |
| 20030228_easy_ham.tar.bz2 | 1,612,216 | 2b7b65904bcfcc31d2b5f51946f2d261370b257402cbbd62930b46ab83367438 |
| 20030228_easy_ham_2.tar.bz2 | 1,077,892 | b4bd3dc5ae5b40f38e99a0e41ad7d16b428b56e818e3a6ffa07330d62004dd38 |
| 20030228_hard_ham.tar.bz2 | 1,029,898 | ce2ce67880643dbde65ea7f85bffbfe4417349c4bd80b6b0de56262ae6b0a9c9 |
| 20030228_spam.tar.bz2 | 1,183,768 | c08debc32413804949a866be45ef78195cec2cbafd1da744ed76cdb860589743 |
| 20030228_spam_2.tar.bz2 | 2,059,563 | 40bc444c596ff3e71505ae334f115b16f9b946786ee68f09b921b6b99217fd00 |
| 20050311_spam_2.tar.bz2 | 2,059,029 | 44280a0e28bf7645b2279e8e42659271ad82c6f40bf8d364dbda7f1df344a765 |
The execution record also retains the Python and package versions, CPU and memory observations, operating system, random seed, fixed thread setting, input file hashes, commands, completion times, and output hashes. This provenance focus addresses reproducibility failures that can arise when leakage risks and evaluation assumptions are not captured [50]. The use of a single seed does not replace multi-seed replication; it makes the reported run identifiable. A later multi-seed study should pre-specify the aggregation rule and should retain each seed-specific manifest rather than only averaging final metrics.
Table A1. Minimum fields in the retained evidence package.
| Record | Minimum retained fields | Why it matters |
| Dataset audit | Archive name, SHA-256, category, duplicate decision | Provenance and leakage audit |
| Split manifest | Stable ID, label, partition, group if applicable | Prevents hidden split changes |
| Prediction manifest | ID, clean/attacked condition, prediction, model ID | Permits paired recomputation |
| Attack record | Prompt family, parameters, candidate text, query count | Defines the tested capability |
| Review record | Criterion decisions, reason, reviewer, adjudication | Defines formal L2/L3 denominator |
Appendix A2: Deterministic L1 Rule Specification
Before any modification, protected spans matching URLs (http(s):// or www.), email addresses, dollar amounts, and numeric tokens are segmented out and copied unchanged. On each remaining text segment, synonym replacement is applied with probability 0.85, u/r expansion with probability 0.70, and one reversal of a contiguous four-word span with probability 0.60 only when that segment contains at least 12 whitespace-delimited words. A greeting prefix “Dear customer, please note: “ is added with probability 0.85 and a closing line “Thank you for your attention.” with probability 0.70. All Bernoulli draws use Python random.Random(seed); test seed is derived deterministically from base seed 42 and stable message ID. Training uses replicate identifiers 1 and 2; gate variants use 100, 101, and 102.
Implementation rule: on the original tokens of each unprotected segment, one case-insensitive, word-boundary regular-expression pass replaces every matched token by its dictionary value. Replacement text is not scanned again. Thus each original token is changed at most once, map order is irrelevant, and apparent value-to-key chains such as urgent->important and important->significant do not compose. If the u/r draw succeeds, standalone u maps to you and standalone r maps to are. If the reversal draw succeeds, its start position is sampled uniformly by the seeded generator from 0 through len(words)-4; the selected four-token window is reversed once.
The synonym map is: free->complimentary; win->obtain; winner->recipient; offer->proposal; urgent->important; buy->purchase; cheap->affordable; money/cash->funds; click->select; deal->opportunity; limited->restricted; bonus->extra; now->today; gift->present; special->exclusive; claim->request; price->cost; discount->reduction; earn->receive; prize->reward; visit->access; save->retain; customer->client; help->assist; account->profile; verify->confirm; notice->message; update->refresh; secure->protected; service->support; today->currently; immediately->promptly; exclusive->select; payment->remittance; important->significant; reply->respond; message->note; contact->reach; hello->greetings; thanks->appreciation; business->enterprise; request->inquiry; receive->obtain; available->accessible. This rule set is deterministic but is not a semantic-preservation guarantee.
Appendix B: Candidate Review and Metric Definitions
A reviewer first reads the original and candidate together, then records a pass, fail, or uncertain decision for semantic preservation, entity preservation, absence of newly added harm, and fluency. An uncertain decision is not silently converted to a pass. If two reviewers disagree, the candidate is sent to adjudication and the final decision is recorded separately from both initial decisions. The formal L2/L3 set contains only final passes. The retained files contain 100 selected candidates per protocol but not total generator yield or the pre-selection rule; selected counts therefore do not describe generator-wide evasion rates.
Table B1. Independent-review agreement before adjudication (100 candidates per protocol).
| Protocol | Criterion | Observed agreement % | Cohen kappa | Composite pair counts (TT/FF/TF/FT) |
| L2 | Meaning preserved | 99 | 0.961 | - |
| L2 | Entities preserved | 83 | 0.669 | - |
| L2 | No added harm | 100 | 1.000 | - |
| L2 | Fluency | 88 | 0.585 | - |
| L2 | Eligibility composite | 86 | 0.706 | 32 / 54 / 7 / 7 |
| L3 | Meaning preserved | 88 | 0.683 | - |
| L3 | Entities preserved | 92 | 0.832 | - |
| L3 | No added harm | 96 | 0.322 | - |
| L3 | Fluency | 70 | 0.302 | - |
| L3 | Eligibility composite | 89 | 0.779 | 48 / 41 / 7 / 4 |
TT and FF denote agreement on eligible and ineligible, respectively; TF and FT denote the two disagreement directions. Kappa values are reported beside raw agreement because low prevalence can affect kappa even when raw agreement is high. Consensus inclusion required yes, yes, no, yes across the four criteria; disagreements were resolved by the recorded adjudication. L2 included 32 consensus and 6 adjudicated candidates; L3 included 48 consensus and 7 adjudicated candidates.
For binary predictions, TP is spam predicted as spam, FN is spam predicted as ham, FP is ham predicted as spam, and TN is ham predicted as ham. FNR=FN/(TP+FN) and FPR=FP/(FP+TN). Precision=TP/(TP+FP), recall=TP/(TP+FN), and F1=2TP/(2TP+FP+FN). The conditional L2/L3 attack success rate has a different denominator: it uses only eligible attack candidates for which the original email was correctly detected. This conditional number must always be reported beside the all-effective-candidate miss rate and its confidence interval.
Appendix C: Statistical Reporting Notes
Wilson intervals are attached to L2 and L3 binomial miss rates because the effective denominators are 38 and 55; this manuscript uses z = 1.96. Exact McNemar compares a pair of prediction vectors by their discordant cases; it is not a test of independently computed F1 summaries. The paired bootstrap resamples message indices jointly for the two predictors, preserving their paired relationship. For Track A exact deduplication, the gated-RMF-PC-minus-linear-SVM L1 FNR interval [-1.613, +0.538] includes zero and therefore does not support an unqualified superiority statement. The separate Track-B source-holdout interval is reported in Table D4 and must be interpreted with its Holm-adjusted p value.
Cross-corpus tables are stratified by target corpus, condition, and data-preparation track. An apparent difference across two different tracks is not a paired test. Where multiple Track-B model comparisons are inspected, adjusted values are retained using the Holm procedure. The manuscript deliberately foregrounds effect estimates and their data scope rather than treating a thresholded p value as the sole measure of practical relevance.
Appendix D: Frozen Full Metrics and Paired Statistics
All values in this appendix are generated from immutable seed-42 prediction bundles. Accuracy, precision, recall, F1, FPR, and FNR are percentages. Bracketed intervals are 95% Wilson intervals for the spam population represented by the corresponding confusion matrix. Table D0 uses 558 Track-A test spam and Table D1 uses 556 Track-B source-holdout spam; Tables D2 and D3 report full frozen target-corpus evaluations and therefore use all 14,331 Enron and 29,115 TREC spam messages, respectively. These full-target transfer cohorts are distinct from the 30% independent target tests used only for the adaptation rows in Table 12. Track A (exact deduplication) and Track B (group-near deduplication) are distinct and are not averaged. The L1 paired tests compare RMF-PC gated with the named model on the same attacked IDs; negative FNR differences favor the gated model. Holm adjustment applies only to the 24 Track-B comparisons retained in the frozen statistical output.
Table D0. Full frozen Track-A exact-deduplication metrics (%, seed 42; 1,296 ham and 558 spam).
| Model | Condition | Accuracy | Precision | Recall | F1 | FPR | FNR [Wilson 95% CI] |
| Linear SVM | Clean | 98.112 | 98.696 | 94.982 | 96.804 | 0.540 | 5.018 [3.494, 7.157] |
| Linear SVM | L1 | 98.813 | 98.551 | 97.491 | 98.018 | 0.617 | 2.509 [1.500, 4.167] |
| Naive Bayes | Clean | 93.905 | 99.335 | 80.287 | 88.801 | 0.231 | 19.713 [16.624, 23.216] |
| Naive Bayes | L1 | 93.420 | 99.321 | 78.674 | 87.800 | 0.231 | 21.326 [18.130, 24.915] |
| Random forest | Clean | 98.004 | 99.244 | 94.086 | 96.596 | 0.309 | 5.914 [4.242, 8.189] |
| Random forest | L1 | 97.843 | 99.240 | 93.548 | 96.310 | 0.309 | 6.452 [4.696, 8.802] |
| RMF-PC char | Clean | 98.274 | 98.885 | 95.341 | 97.080 | 0.463 | 4.659 [3.199, 6.740] |
| RMF-PC char | L1 | 98.490 | 98.535 | 96.416 | 97.464 | 0.617 | 3.584 [2.332, 5.471] |
| RMF-PC fusion | Clean | 98.706 | 98.370 | 97.312 | 97.838 | 0.694 | 2.688 [1.636, 4.388] |
| RMF-PC fusion | L1 | 98.813 | 98.201 | 97.849 | 98.025 | 0.772 | 2.151 [1.234, 3.721] |
| RMF-PC gated | Clean | 98.759 | 98.025 | 97.849 | 97.937 | 0.849 | 2.151 [1.234, 3.721] |
| RMF-PC gated | L1 | 98.867 | 98.205 | 98.029 | 98.117 | 0.772 | 1.971 [1.104, 3.495] |
| RMF-PC word | Clean | 98.058 | 97.455 | 96.057 | 96.751 | 1.080 | 3.943 [2.618, 5.897] |
| RMF-PC word | L1 | 98.759 | 97.513 | 98.387 | 97.948 | 1.080 | 1.613 [0.851, 3.037] |
| DistilBERT + LR | Clean | 98.759 | 97.513 | 98.387 | 97.948 | 1.080 | 1.613 [0.851, 3.037] |
| DistilBERT + LR | L1 | 98.004 | 94.530 | 99.104 | 96.763 | 2.469 | 0.896 [0.383, 2.080] |
Table D0a. Track-A L1 paired statistics from retained frozen predictions (gated RMF-PC minus comparator).
| Cohort | Comparison | Delta FNR pp | Bootstrap 95% CI pp | n01/n10 | Exact p | Adjustment | Interpretation |
| Track A exact dedup | gated vs naive bayes | -19.355 | [-22.760, -16.129] | 109/1 | 1.71e-31 | Not family-adjusted | Descriptive paired result |
| Track A exact dedup | gated vs linear svm | -0.538 | [-1.613, 0.538] | 6/3 | 0.508 | Not family-adjusted | Descriptive paired result |
| Track A exact dedup | gated vs rmf word | 0.358 | [-0.358, 1.075] | 1/3 | 0.625 | Not family-adjusted | Descriptive paired result |
| Track A exact dedup | gated vs rmf fusion | -0.179 | [-0.538, 0.000] | 1/0 | 1 | Not family-adjusted | Descriptive paired result |
| Track A exact dedup | gated vs RMF-PC char | -1.613 | [-2.867, -0.538] | 10/1 | 0.0117 | Not family-adjusted | Descriptive paired result |
| Track A exact dedup | gated vs Random forest | -4.480 | [-6.452, -2.509] | 29/4 | 1.09e-05 | Not family-adjusted | Descriptive paired result |
| Track A exact dedup | gated vs DistilBERT + LR | 1.075 | [0.000, 2.330] | 3/9 | 0.146 | Not family-adjusted | Descriptive paired result |
Table D0 includes the retained DistilBERT prediction vector on the same 1,854 Track-A IDs, and Table D0a adds the available char, random-forest, and DistilBERT comparisons. The DistilBERT Clean and RMF-PC word L1 rows have identical aggregate confusion counts but differ on 32 individual predictions. On the spam subset, their discordant error counts are n01/n10=7/7 (two-sided exact McNemar p=1.000); on ham, the prediction discordances are likewise balanced at 9/9. The coincidence of rounded row metrics is therefore genuine and not a duplicated vector. A Track-A MiniLM prediction vector was not retained, so no MiniLM Track-A metric or paired comparison is reconstructed.
Table D1. Full frozen Track-B SpamAssassin source holdout metrics (%, seed 42).
| Model | Condition | Accuracy | Precision | Recall | F1 | FPR | FNR [Wilson 95% CI] |
| RMF-PC char | Clean | 97.677 | 98.672 | 93.525 | 96.030 | 0.541 | 6.475 [4.713, 8.834] |
| RMF-PC char | L1 | 98.109 | 98.510 | 95.144 | 96.798 | 0.618 | 4.856 [3.359, 6.973] |
| RMF-PC gated | Clean | 98.703 | 97.670 | 98.022 | 97.846 | 1.004 | 1.978 [1.108, 3.508] |
| RMF-PC gated | L1 | 98.757 | 97.336 | 98.561 | 97.945 | 1.158 | 1.439 [0.731, 2.813] |
| RMF-PC word | Clean | 98.325 | 97.814 | 96.583 | 97.195 | 0.927 | 3.417 [2.198, 5.275] |
| RMF-PC word | L1 | 98.541 | 96.980 | 98.201 | 97.587 | 1.313 | 1.799 [0.980, 3.279] |
| Random forest | Clean | 98.055 | 98.507 | 94.964 | 96.703 | 0.618 | 5.036 [3.507, 7.182] |
| Random forest | L1 | 98.001 | 98.505 | 94.784 | 96.609 | 0.618 | 5.216 [3.656, 7.390] |
| Linear SVM | Clean | 98.055 | 98.148 | 95.324 | 96.715 | 0.772 | 4.676 [3.211, 6.764] |
| Linear SVM | L1 | 98.325 | 97.297 | 97.122 | 97.210 | 1.158 | 2.878 [1.779, 4.623] |
| RMF-PC fusion | Clean | 98.595 | 98.182 | 97.122 | 97.649 | 0.772 | 2.878 [1.779, 4.623] |
| RMF-PC fusion | L1 | 98.649 | 97.496 | 98.022 | 97.758 | 1.081 | 1.978 [1.108, 3.508] |
| Naive Bayes | Clean | 92.491 | 99.525 | 75.360 | 85.773 | 0.154 | 24.640 [21.241, 28.388] |
| Naive Bayes | L1 | 91.950 | 99.513 | 73.561 | 84.592 | 0.154 | 26.439 [22.944, 30.257] |
| MiniLM + LR | Clean | 94.976 | 94.778 | 88.129 | 91.333 | 2.085 | 11.871 [9.440, 14.824] |
| MiniLM + LR | L1 | 94.652 | 90.731 | 91.547 | 91.137 | 4.015 | 8.453 [6.416, 11.060] |
| DistilBERT + LR | Clean | 97.623 | 96.545 | 95.504 | 96.022 | 1.467 | 4.496 [3.064, 6.553] |
| DistilBERT + LR | L1 | 97.299 | 94.542 | 96.583 | 95.552 | 2.394 | 3.417 [2.198, 5.275] |
Table D2. Full frozen Enron metrics (%, seed 42).
| Model | Condition | Accuracy | Precision | Recall | F1 | FPR | FNR [Wilson 95% CI] |
| RMF-PC fusion | Clean | 73.604 | 83.983 | 55.467 | 66.810 | 9.724 | 44.533 [43.721, 45.348] |
| RMF-PC fusion | L1 | 73.684 | 75.834 | 66.129 | 70.650 | 19.371 | 33.871 [33.100, 34.650] |
| RMF-PC gated | Clean | 73.985 | 77.725 | 64.036 | 70.220 | 16.870 | 35.964 [35.182, 36.753] |
| RMF-PC gated | L1 | 73.470 | 73.031 | 70.728 | 71.861 | 24.009 | 29.272 [28.533, 30.023] |
| Naive Bayes | Clean | 58.263 | 99.147 | 12.972 | 22.942 | 0.103 | 87.028 [86.468, 87.568] |
| Naive Bayes | L1 | 58.093 | 98.537 | 12.693 | 22.489 | 0.173 | 87.307 [86.752, 87.842] |
| Linear SVM | Clean | 74.095 | 78.475 | 63.268 | 70.056 | 15.953 | 36.732 [35.946, 37.524] |
| Linear SVM | L1 | 72.678 | 68.979 | 78.062 | 73.240 | 32.271 | 21.938 [21.268, 22.623] |
| RMF-PC char | Clean | 64.613 | 95.260 | 27.486 | 42.662 | 1.257 | 72.514 [71.777, 73.239] |
| RMF-PC char | L1 | 68.327 | 89.787 | 38.218 | 53.615 | 3.996 | 61.782 [60.984, 62.574] |
| RMF-PC word | Clean | 73.908 | 72.646 | 73.017 | 72.831 | 25.273 | 26.983 [26.263, 27.716] |
| RMF-PC word | L1 | 72.023 | 67.056 | 81.753 | 73.679 | 36.921 | 18.247 [17.623, 18.888] |
| Random forest | Clean | 63.795 | 73.584 | 38.078 | 50.186 | 12.566 | 61.922 [61.124, 62.713] |
| Random forest | L1 | 66.575 | 79.162 | 41.009 | 54.029 | 9.923 | 58.991 [58.183, 59.794] |
| MiniLM + LR | Clean | 76.064 | 76.589 | 72.047 | 74.249 | 20.244 | 27.953 [27.225, 28.694] |
| MiniLM + LR | L1 | 74.566 | 71.316 | 78.452 | 74.714 | 29.006 | 21.548 [20.882, 22.228] |
| DistilBERT + LR | Clean | 76.257 | 74.325 | 77.043 | 75.660 | 24.464 | 22.957 [22.276, 23.653] |
| DistilBERT + LR | L1 | 73.811 | 68.801 | 82.925 | 75.206 | 34.567 | 17.075 [16.468, 17.700] |
Table D3. Full frozen TREC 2007 Zenodo curated metrics (%, seed 42).
| Model | Condition | Accuracy | Precision | Recall | F1 | FPR | FNR [Wilson 95% CI] |
| RMF-PC gated | Clean | 76.309 | 89.528 | 63.984 | 74.631 | 8.951 | 36.016 [35.466, 36.569] |
| RMF-PC gated | L1 | 77.491 | 89.057 | 66.890 | 76.398 | 9.830 | 33.110 [32.572, 33.653] |
| RMF-PC word | Clean | 75.639 | 91.304 | 61.089 | 73.201 | 6.959 | 38.911 [38.353, 39.473] |
| RMF-PC word | L1 | 78.468 | 90.476 | 67.577 | 77.368 | 8.507 | 32.423 [31.888, 32.963] |
| Naive Bayes | Clean | 49.922 | 99.451 | 8.095 | 14.972 | 0.053 | 91.905 [91.586, 92.212] |
| Naive Bayes | L1 | 49.851 | 99.913 | 7.927 | 14.689 | 0.008 | 92.073 [91.757, 92.378] |
| RMF-PC fusion | Clean | 74.457 | 90.328 | 59.468 | 71.719 | 7.616 | 40.532 [39.970, 41.098] |
| RMF-PC fusion | L1 | 76.584 | 89.342 | 64.726 | 75.068 | 9.234 | 35.274 [34.727, 35.825] |
| Random forest | Clean | 58.617 | 90.813 | 26.718 | 41.289 | 3.233 | 73.282 [72.771, 73.787] |
| Random forest | L1 | 61.026 | 93.930 | 30.404 | 45.938 | 2.350 | 69.596 [69.065, 70.122] |
| RMF-PC char | Clean | 68.235 | 86.165 | 49.648 | 62.997 | 9.534 | 50.352 [49.778, 50.926] |
| RMF-PC char | L1 | 71.000 | 86.221 | 55.645 | 67.638 | 10.635 | 44.355 [43.785, 44.927] |
| Linear SVM | Clean | 74.066 | 94.147 | 55.854 | 70.113 | 4.153 | 44.146 [43.576, 44.717] |
| Linear SVM | L1 | 78.997 | 94.564 | 65.183 | 77.171 | 4.482 | 34.817 [34.272, 35.366] |
| MiniLM + LR | Clean | 80.110 | 95.495 | 66.622 | 78.487 | 3.759 | 33.378 [32.839, 33.922] |
| MiniLM + LR | L1 | 81.876 | 93.327 | 71.860 | 81.198 | 6.145 | 28.140 [27.627, 28.660] |
| DistilBERT + LR | Clean | 83.758 | 93.894 | 75.058 | 83.426 | 5.837 | 24.942 [24.449, 25.443] |
| DistilBERT + LR | L1 | 84.826 | 92.190 | 78.815 | 84.979 | 7.986 | 21.185 [20.719, 21.658] |
Table D4. Frozen paired L1 bootstrap and exact McNemar tests.
| Corpus | Comparison | Delta FNR pp | Bootstrap 95% CI pp | n01/n10 | Exact p | Holm p | Significant |
| SpamAssassin (Track B source holdout) | gated vs rmf_char | -3.417 | [-5.036, -1.978] | 19/0 | 3.81e-06 | 2.29e-05 | yes |
| SpamAssassin (Track B source holdout) | gated vs rmf_word | -0.360 | [-1.259, 0.540] | 4/2 | 0.688 | 0.688 | no |
| SpamAssassin (Track B source holdout) | gated vs random_forest | -3.777 | [-5.576, -2.158] | 23/2 | 1.94e-05 | 9.72e-05 | yes |
| SpamAssassin (Track B source holdout) | gated vs linear_svm | -1.439 | [-2.518, -0.360] | 9/1 | 0.0215 | 0.0859 | no |
| SpamAssassin (Track B source holdout) | gated vs rmf_fusion | -0.540 | [-1.259, 0.000] | 3/0 | 0.25 | 0.5 | no |
| SpamAssassin (Track B source holdout) | gated vs naive_bayes | -25.000 | [-28.597, -21.403] | 139/0 | 2.87e-42 | 2.87e-41 | yes |
| SpamAssassin (Track B source holdout) | gated vs minilm_logreg | -7.014 | [-9.532, -4.676] | 44/5 | 7.6e-09 | 6.08e-08 | yes |
| SpamAssassin (Track B source holdout) | gated vs distilbert_logreg | -1.978 | [-3.777, -0.180] | 18/7 | 0.0433 | 0.13 | no |
| Enron | gated vs rmf_fusion | -4.598 | [-4.954, -4.250] | 667/8 | 1.32e-185 | 1.99e-184 | yes |
| Enron | gated vs naive_bayes | -58.035 | [-58.837, -57.233] | 8321/4 | <1e-300 | <1e-300 | yes |
| Enron | gated vs linear_svm | 7.334 | [6.748, 7.913] | 415/1466 | 4.33e-137 | 5.63e-136 | yes |
| Enron | gated vs rmf_char | -32.510 | [-33.278, -31.742] | 4662/3 | <1e-300 | <1e-300 | yes |
| Enron | gated vs rmf_word | 11.025 | [10.488, 11.562] | 60/1640 | <1e-300 | <1e-300 | yes |
| Enron | gated vs random_forest | -29.719 | [-30.521, -28.916] | 4457/198 | <1e-300 | <1e-300 | yes |
| Enron | gated vs minilm_logreg | 7.725 | [6.880, 8.583] | 1396/2503 | 3.82e-71 | 4.2e-70 | yes |
| Enron | gated vs distilbert_logreg | 12.197 | [11.493, 12.916] | 607/2355 | 2.75e-241 | 4.4e-240 | yes |
| TREC 2007 Zenodo curated | gated vs rmf_word | 0.687 | [0.416, 0.958] | 687/887 | 5.1e-07 | 3.57e-06 | yes |
| TREC 2007 Zenodo curated | gated vs naive_bayes | -58.963 | [-59.519, -58.393] | 17167/0 | <1e-300 | <1e-300 | yes |
| TREC 2007 Zenodo curated | gated vs rmf_fusion | -2.164 | [-2.336, -1.996] | 639/9 | 9.12e-176 | 1.28e-174 | yes |
| TREC 2007 Zenodo curated | gated vs random_forest | -36.486 | [-37.050, -35.913] | 10804/181 | <1e-300 | <1e-300 | yes |
| TREC 2007 Zenodo curated | gated vs rmf_char | -11.245 | [-11.647, -10.843] | 3585/311 | <1e-300 | <1e-300 | yes |
| TREC 2007 Zenodo curated | gated vs linear_svm | -1.707 | [-2.047, -1.377] | 1468/971 | 6.91e-24 | 6.22e-23 | yes |
| TREC 2007 Zenodo curated | gated vs minilm_logreg | 4.970 | [4.486, 5.454] | 1799/3246 | 2.09e-93 | 2.51e-92 | yes |
| TREC 2007 Zenodo curated | gated vs distilbert_logreg | 11.925 | [11.448, 12.406] | 967/4439 | <1e-300 | <1e-300 | yes |
The first D4 cohort is Track B source holdout (556 spam), not Track A (558 spam). Track-A paired statistics are reported separately in Table D0a and must not be pooled with the Track-B Holm family.
References
- Androutsopoulos, I.; Koutsias, J.; Chandrinos, K.; Paliouras, G.; Spyropoulos, C. An Evaluation of Naive Bayesian Anti-Spam Filtering. arXiv 2000, arXiv:cs/0006013 2000. [Google Scholar] [CrossRef]
- Metsis, V.; Androutsopoulos, I.; Paliouras, G. Spam Filtering with Naive Bayes—Which Naive Bayes? In Proceedings of the 2006 Conference on Email and Web Security (CEAS); 2006. [Google Scholar]
- Cormack, G.V. TREC 2007 Spam Track Overview. In The Sixteenth Text REtrieval Conference (TREC); 2007; NIST: Gaithersburg, MD, USA. [Google Scholar]
- Heiding, F.; Schneier, B.; Vishwanath, A.; Bernstein, J.; Park, P.S. Devising and Detecting Phishing: Large Language Models vs. Smaller Human Models. arXiv 2023, arXiv:2308.12287. [Google Scholar] [CrossRef]
- Pineau, J.; Vincent-Lamarre, P.; Sinha, K.; Larivière, V.; Beygelzimer, A.; d’Alché-Buc, F.; Fox, E.; Larochelle, H. Improving Reproducibility in Machine Learning Research: A Report from the NeurIPS 2019 Reproducibility Program. J. Mach. Learn. Res. 2021, 22, 164. Available online: https://jmlr.org/papers/v22/20-303.html.
- Gebru, T.; Morgenstern, J.; Vecchione, B.; Vaughan, J.W.; Wallach, H.; Daumé, H., III; Crawford, K. Datasheets for Datasets. Commun. ACM 2021, 64, 86–92. [Google Scholar] [CrossRef]
- Golchin, S.; Surdeanu, M. Time Travel in LLMs: Tracing Data Contamination in Large Language Models. In Proceedings of the 12th International Conference on Learning Representations; 2024. [Google Scholar]
- Xu, C.; Yan, N.; Guan, S.; Jin, C.; Mei, Y.; Guo, Y.; Kechadi, M.-T. DCR: Quantifying Data Contamination in LLMs Evaluation. In Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing; 2025; pp. 23002–23020. [Google Scholar] [CrossRef]
- Dodge, J.; Sap, M.; Marasović, A.; Agnew, W.; Ilharco, G.; Groeneveld, D.; Mitchell, M.; Gardner, M. Documenting Large Webtext Corpora: A Case Study on the Colossal Clean Crawled Corpus. In Proceedings of the 2021 Conference on Empirical Methods in Natural Language Processing; 2021; pp. 1286–1305. [Google Scholar] [CrossRef]
- Joachims, T. Text Categorization with Support Vector Machines: Learning with Many Relevant Features. In Proceedings of the 9th European Conference on Machine Learning (ECML); 1998; pp. 137–142. [Google Scholar] [CrossRef]
- Bethany, M.; Galiopoulos, A.; Bethany, E.; Bahrami Karkevandi, M.; Beebe, N.; Vishwamitra, N.; Najafirad, P. Lateral Phishing with Large Language Models: A Large Organization Comparative Study. IEEE Access 2025, 13, 60684–60701. [Google Scholar] [CrossRef]
- Qi, Q.; Luo, Y.; Xu, Y.; Guo, W.; Fang, Y. SpearBot: Leveraging Large Language Models in a Generative-Critique Framework for Spear-Phishing Email Generation. Inf. Fusion 2025, 122, 103176. [Google Scholar] [CrossRef]
- Sainz, O.; Campos, J.A.; García-Ferrero, I.; Etxaniz, J.; Lopez de Lacalle, O.; Agirre, E. NLP Evaluation in Trouble: On the Need to Measure LLM Data Contamination for Each Benchmark. In Findings of the Association for Computational Linguistics: EMNLP 2023, 2023; pp. 10776–10787. [CrossRef]
- Pajola, L.; Caripoti, E.; Banzer, S.; Pizzi, S.; Conti, M.; Apruzzese, G. E-PhishGen: Unlocking Novel Research in Phishing Email Detection. In Proceedings of the 2025 Workshop on Artificial Intelligence and Security (AISec ’25); 2025; pp. 64–76. [Google Scholar] [CrossRef]
- Drucker, H.; Wu, D.; Vapnik, V.N. Support Vector Machines for Spam Categorization. IEEE Trans. Neural Netw. 1999, 10, 1048–1054. [Google Scholar] [CrossRef]
- Cormack, G.V.; Lynam, T. Online Supervised Spam Filter Evaluation. ACM Trans. Inf. Syst. 2007, 25, 11. [Google Scholar] [CrossRef]
- Lee, K.; Ippolito, D.; Nystrom, A.; Zhang, C.; Eck, D.; Callison-Burch, C.; Carlini, N. Deduplicating Training Data Makes Language Models Better. In Proceedings of the 60th Annual Meeting of the Association for Computational Linguistics; 2022; pp. 8424–8445. [Google Scholar] [CrossRef]
- Jin, D.; Jin, Z.; Zhou, J.T.; Szolovits, P. Is BERT Really Robust? A Strong Baseline for Natural Language Attack on Text Classification and Entailment. In Proceedings of the AAAI Conference on Artificial Intelligence, 2020; Volume 34, pp. 8018–8025. [CrossRef]
- Morris, M.; Lifland, E.; Yoo, J.Y.; Grigsby, J.; Jin, D.; Qi, Y. TextAttack: A Framework for Adversarial Attacks, Data Augmentation, and Adversarial Training in NLP. In Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing: System Demonstrations; 2020; pp. 119–126. [Google Scholar] [CrossRef]
- Alzantot, M.; Sharma, Y.; Elgohary, A.; Ho, B.; Srivastava, M.; Chang, K.-W. Generating Natural Language Adversarial Examples. In Proceedings of the 2018 Conference on Empirical Methods in Natural Language Processing; 2018; pp. 2890–2896. [Google Scholar] [CrossRef]
- Jia, R.; Liang, P. Adversarial Examples for Evaluating Reading Comprehension Systems. In Proceedings of the 2017 Conference on Empirical Methods in Natural Language Processing; 2017; pp. 2021–2031. [Google Scholar] [CrossRef]
- Ren, S.; Deng, Y.; He, K.; Che, W. Generating Natural Language Adversarial Examples through Probability Weighted Word Saliency. In Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics; 2019; pp. 1085–1097. [Google Scholar] [CrossRef]
- Yang, S.; Zhu, S.; Wu, Z.; Wang, K.; Yao, J.; Wu, J.; Hu, L.; Li, M.; Wong, D.F.; Wang, D. Fraud-R1: A Multi- Round Benchmark for Assessing the Robustness of LLM Against Augmented Fraud and Phishing Inducements. In Findings of the Association for Computational Linguistics: ACL 2025, 2025; pp. 4374–4420. [CrossRef]
- Afane, K.; Wei, W.; Mao, Y.; Farooq, J.; Chen, J. Next-Generation Phishing: How LLM Agents Empower Cyber Attackers. arXiv 2024, arXiv:2411.13874. [Google Scholar] [CrossRef]
- Vaswani, A.; Shazeer, N.; Parmar, N.; Uszkoreit, J.; Jones, L.; Gomez, A.N.; Kaiser, Ł.; Polosukhin, I. Attention Is All You Need. In Advances in Neural Information Processing Systems; 2017; Volume 30. [Google Scholar]
- Devlin, J.; Chang, M.-W.; Lee, K.; Toutanova, K. BERT: Pre-Training of Deep Bidirectional Transformers for Language Understanding. In Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (NAACL-HLT); 2019; pp. 4171–4186. [Google Scholar] [CrossRef]
- Reimers, N.; Gurevych, I. Sentence-BERT: Sentence Embeddings Using Siamese BERT-Networks. In Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing (EMNLP-IJCNLP); 2019; pp. 3982–3992. [Google Scholar] [CrossRef]
- Sanh, V.; Debut, L.; Chaumond, J.; Wolf, T. DistilBERT, a Distilled Version of BERT: Smaller, Faster, Cheaper and Lighter. arXiv 2019, arXiv:1910.01108. [Google Scholar] [CrossRef]
- Wang, W.; Wei, F.; Dong, L.; Bao, H.; Yang, N.; Zhou, M. MiniLM: Deep Self-Attention Distillation for Task-Agnostic Compression of Pre-Trained Transformers. In Advances in Neural Information Processing Systems; 2020; Volume 33, pp. 5776–5788. [Google Scholar]
- Cortes, C.; Vapnik, V. Support-Vector Networks. Mach. Learn. 1995, 20, 273–297. [Google Scholar] [CrossRef]
- Breiman, L. Random Forests. Mach. Learn. 2001, 45, 5–32. [Google Scholar] [CrossRef]
- Pedregosa, F.; Varoquaux, G.; Gramfort, A.; Michel, V.; Thirion, B.; Grisel, O.; Blondel, M.; Prettenhofer, P.; Weiss, R.; Dubourg, V.; Vanderplas, J.; Passos, A.; Cournapeau, D.; Brucher, M.; Perrot, M.; Duchesnay, E. Scikit-learn: Machine Learning in Python. J. Mach. Learn. Res. 2011, 12, 2825–2830. [Google Scholar]
- Balloccu, S.; Schmidtová, P.; Lango, M.; Dušek, O. Leak, Cheat, Repeat: Data Contamination and Evaluation Malpractices in Closed-Source LLMs. In Proceedings of the 18th Conference of the European Chapter of the Association for Computational Linguistics (EACL 2024); 2024; Volume 1, pp. 67–93. [Google Scholar] [CrossRef]
- Apache SpamAssassin. Public Corpus. Available online: https://spamassassin.apache.org/old/publiccorpus/ (accessed on 24 October 2026).
- Cormack, G.V. TREC 2007 Spam Track Corpus Information. Available online: https://plg.uwaterloo.ca/~gvcormac/treccorpus07/ (accessed on 24 October 2026).
- Zenodo. TREC_07.csv Curated Dataset, Record 8339691. Available online: https://zenodo.org/records/8339691 (accessed on 24 October 2026).
- Deng, C.; Zhao, Y.; Tang, X.; Gerstein, M.; Cohan, A. Investigating Data Contamination in Modern Benchmarks for Large Language Models. In Proceedings of the 2024 Conference of the North American Chapter of the Association for Computational Linguistics (NAACL 2024); 2024; Volume 1, pp. 8706–8719. [Google Scholar] [CrossRef]
- Fawcett, T. An Introduction to ROC Analysis. Pattern Recognit. Lett. 2006, 27, 861–874. [Google Scholar] [CrossRef]
- Wilson, E.B. Probable Inference, the Law of Succession, and Statistical Inference. J. Am. Stat. Assoc. 1927, 22, 209–212. [Google Scholar] [CrossRef]
- Efron, B.; Tibshirani, R.J. An Introduction to the Bootstrap; Chapman and Hall: New York, NY, USA, 1993. [Google Scholar]
- McNemar, Q. Note on the Sampling Error of the Difference between Correlated Proportions or Percentages. Psychometrika 1947, 12, 153–157. [Google Scholar] [CrossRef]
- Holm, S. A Simple Sequentially Rejective Multiple Test Procedure. Scand. J. Stat. 1979, 6, 65–70. [Google Scholar]
- Platt, J. Probabilistic Outputs for Support Vector Machines and Comparisons to Regularized Likelihood Methods. In Advances in Large Margin Classifiers; MIT Press: Cambridge, MA, USA, 1999; pp. 61–74. [Google Scholar]
- Niculescu-Mizil, A.; Caruana, R. Predicting Good Probabilities with Supervised Learning. In Proceedings of the 22nd International Conference on Machine Learning (ICML); 2005; pp. 625–632. [Google Scholar] [CrossRef]
- Guo, C.; Pleiss, G.; Sun, Y.; Weinberger, K.Q. On Calibration of Modern Neural Networks. In Proceedings of the 34th International Conference on Machine Learning (ICML); 2017; pp. 1321–1330. [Google Scholar]
- Demšar, J. Statistical Comparisons of Classifiers over Multiple Data Sets. J. Mach. Learn. Res. 2006, 7, 1–30. [Google Scholar]
- Sokolova, M.; Lapalme, G. A Systematic Analysis of Performance Measures for Classification Tasks. Inf. Process. Manag. 2009, 45, 427–437. [Google Scholar] [CrossRef]
- Weinz, M.; Zannone, N.; Allodi, L.; Apruzzese, G. The Impact of Emerging Phishing Threats: Assessing Quishing and LLM-Generated Phishing Emails against Organizations. In Proceedings of the 2025 ACM Asia Conference on Computer and Communications Security (ASIA CCS ’25); 2025; pp. 1550–1566. [Google Scholar] [CrossRef]
- Bender, E.M.; Friedman, B. Data Statements for Natural Language Processing: Toward Mitigating System Bias and Enabling Better Science. Trans. Assoc. Comput. Linguist. 2018, 6, 587–604. [Google Scholar] [CrossRef]
- Kapoor, S.; Narayanan, A. Leakage and the Reproducibility Crisis in ML-Based Science. Patterns 2023, 4, 100804. [Google Scholar] [CrossRef]
- 由MiniMax AI生成
Figure 3.
Spam miss rate (FNR) of the nine retained detectors on the SpamAssassin source holdout and on the two target corpora, for clean messages (panel a) and L1-rewritten messages (panel b). Values are plotted directly from Table 10 and Table 11; no new computation or re-estimation was performed, and each plotted value equals the corresponding value in ables D1, D2 and D3. The source holdout is the Track-B group-near-deduplicated SpamAssassin cohort (1,295 ham / 556 spam). The Enron and TREC columns report full frozen target-corpus evaluations (29,921 and 53,459 messages); the separate 30% independent target test sets (8,977 and 16,038 messages) apply only to the target-adaptation rows of Table 12 and are not plotted here. Wilson intervals for these FNR values are reported in ables D1-D3; corresponding F1 values are reported in Table 10 and Table 11. Lower FNR is better; marker shape and colour both encode the corpus.
Figure 3.
Spam miss rate (FNR) of the nine retained detectors on the SpamAssassin source holdout and on the two target corpora, for clean messages (panel a) and L1-rewritten messages (panel b). Values are plotted directly from Table 10 and Table 11; no new computation or re-estimation was performed, and each plotted value equals the corresponding value in ables D1, D2 and D3. The source holdout is the Track-B group-near-deduplicated SpamAssassin cohort (1,295 ham / 556 spam). The Enron and TREC columns report full frozen target-corpus evaluations (29,921 and 53,459 messages); the separate 30% independent target test sets (8,977 and 16,038 messages) apply only to the target-adaptation rows of Table 12 and are not plotted here. Wilson intervals for these FNR values are reported in ables D1-D3; corresponding F1 values are reported in Table 10 and Table 11. Lower FNR is better; marker shape and colour both encode the corpus.
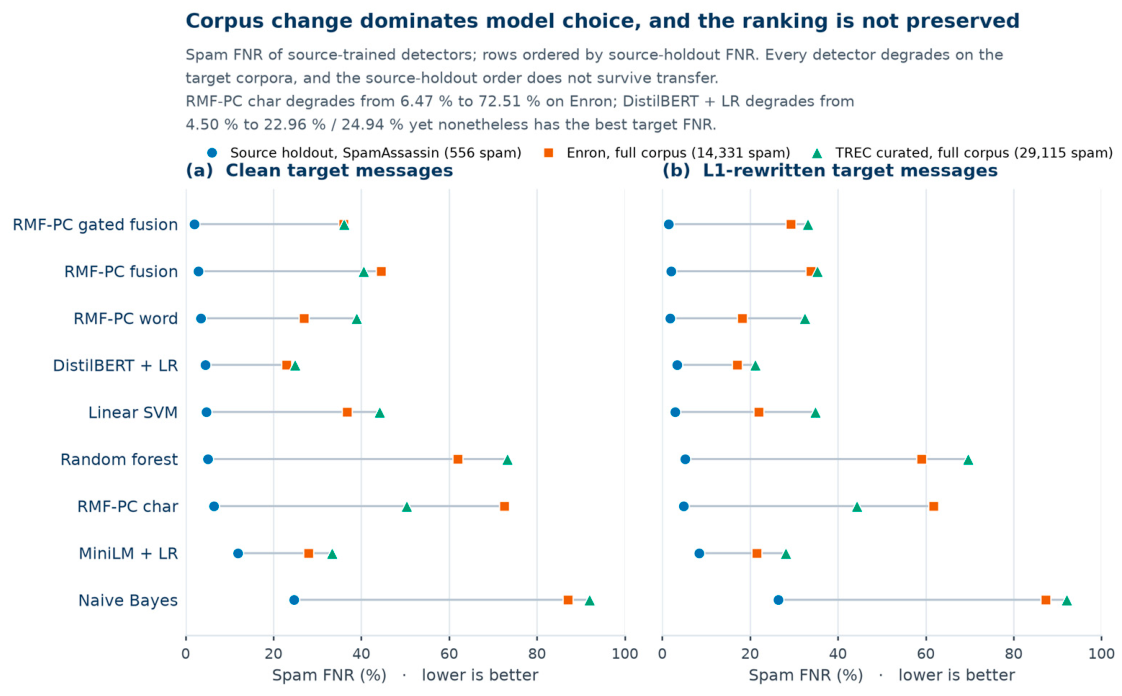
Figure 4.
Paired differences in spam FNR for gated RMF-PC against each retained comparator, with matched paired-bootstrap 95% intervals (10,000 replicates) computed on the frozen seed-42 prediction bundles. Negative values favour the gated model. Plotted directly from the values printed in Table D0a and Table D4; no new computation or re-estimation was performed. Track A and Track B are distinct cohorts and their rows are never pooled. Raw and Holm-adjusted exact McNemar p values are reported in Table D0a and Table D4.
Figure 4.
Paired differences in spam FNR for gated RMF-PC against each retained comparator, with matched paired-bootstrap 95% intervals (10,000 replicates) computed on the frozen seed-42 prediction bundles. Negative values favour the gated model. Plotted directly from the values printed in Table D0a and Table D4; no new computation or re-estimation was performed. Track A and Track B are distinct cohorts and their rows are never pooled. Raw and Holm-adjusted exact McNemar p values are reported in Table D0a and Table D4.
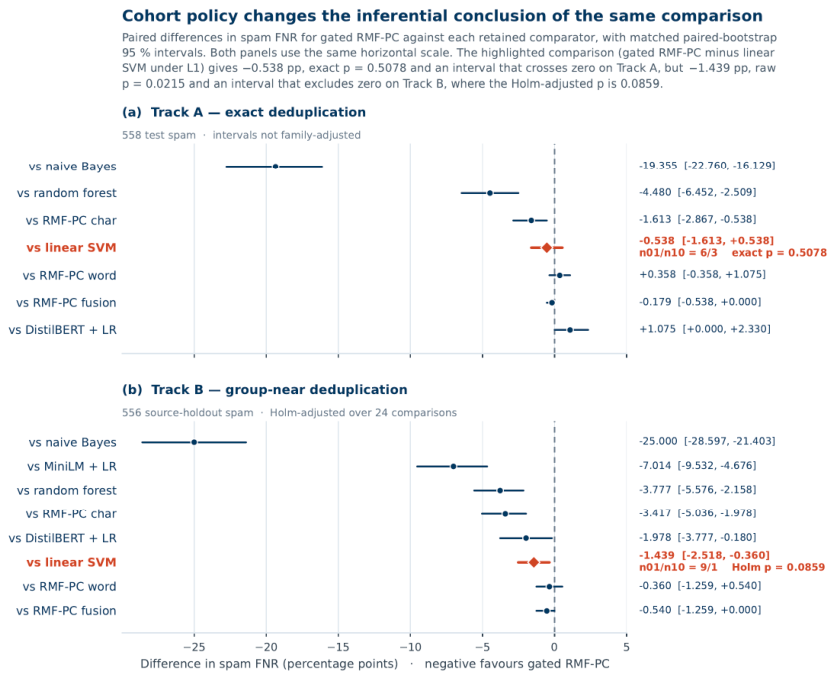
Table 10.
Track-B clean source-trained transfer (F1 / FNR, %).
| Model | Source holdout | Enron | TREC Zenodo curated |
|---|---|---|---|
| Naive Bayes | 85.77 / 24.64 | 22.94 / 87.03 | 14.97 / 91.90 |
| Linear SVM | 96.72 / 4.68 | 70.06 / 36.73 | 70.11 / 44.15 |
| Random forest | 96.70 / 5.04 | 50.19 / 61.92 | 41.29 / 73.28 |
| RMF word | 97.19 / 3.42 | 72.83 / 26.98 | 73.20 / 38.91 |
| RMF char | 96.03 / 6.47 | 42.66 / 72.51 | 63.00 / 50.35 |
| RMF fusion | 97.65 / 2.88 | 66.81 / 44.53 | 71.72 / 40.53 |
| RMF gated | 97.85 / 1.98 | 70.22 / 35.96 | 74.63 / 36.02 |
| MiniLM + LR | 91.33 / 11.87 | 74.25 / 27.95 | 78.49 / 33.38 |
| DistilBERT + LR | 96.02 / 4.50 | 75.66 / 22.96 | 83.43 / 24.94 |
Table 11.
Track-B L1 transfer on identical attacked inputs (F1 / FNR, %).
| Model | Source holdout | Enron | TREC Zenodo curated |
|---|---|---|---|
| Naive Bayes | 84.59 / 26.44 | 22.49 / 87.31 | 14.69 / 92.07 |
| Linear SVM | 97.21 / 2.88 | 73.24 / 21.94 | 77.17 / 34.82 |
| Random forest | 96.61 / 5.22 | 54.03 / 58.99 | 45.94 / 69.60 |
| RMF word | 97.59 / 1.80 | 73.68 / 18.25 | 77.37 / 32.42 |
| RMF char | 96.80 / 4.86 | 53.61 / 61.78 | 67.64 / 44.36 |
| RMF fusion | 97.76 / 1.98 | 70.65 / 33.87 | 75.07 / 35.27 |
| RMF gated | 97.94 / 1.44 | 71.86 / 29.27 | 76.40 / 33.11 |
| MiniLM + LR | 91.14 / 8.45 | 74.71 / 21.55 | 81.20 / 28.14 |
| DistilBERT + LR | 95.55 / 3.42 | 75.21 / 17.07 | 84.98 / 21.18 |
Table 12.
Strict target-domain adaptation with independent target tests.
| Target | Target labels | Train n | Independent test n | F1% | FNR % |
|---|---|---|---|---|---|
| Enron | 5% of 20,944 pool | 5,366 | 8,977 | 95.07 | 7.00 |
| Enron | 10% of 20,944 pool | 6,413 | 8,977 | 96.70 | 4.21 |
| TREC Zenodo curated | 5% of 37,421 pool | 6,190 | 16,038 | 96.85 | 5.27 |
| TREC Zenodo curated | 10% of 37,421 pool | 8,061 | 16,038 | 98.17 | 2.88 |
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.
Copyright: This open access article is published under a Creative Commons CC BY 4.0 license, which permit the free download, distribution, and reuse, provided that the author and preprint are cited in any reuse.