

Submitted:
16 September 2026
Posted:
16 September 2026
You are already at the latest version
Abstract
Mobile mapping systems (MMS) are moving from sensor-centric survey platforms toward intelligencedriven components of the remote sensing ecosystem. This review analyzes rather than catalogs that shift, organizing it around four structural trends: the replacement of per-frame geometric optimization in simultaneous localization and mapping bylearned, feed-forwardgeometry, arrangedalongalatencyfidelity axis; the emergence of tokenization economics—how points become, and are pruned from, attention tokens—as the governing principle of 3D perception efficiency; the migration of radiancefield reconstruction from visualization toward measurement, where explicit representations such as 3D Gaussian Splatting yield updatable digital twins; and the transition from perception to agency, coupling MMS evidence to Earth foundationmodels. Eachtrendistested against the two environments where mobile mapping is most deployed, city and forest, whose contrasting geometry and satellite visibility expose how far each advance generalizes. Seven recurring pitfalls are then consolidated, among them efficiency claims measured on heterogeneous hardware, parameter count used as an efficiency proxy, and architecture rankings assumed to transfer between domains as dissimilar as urban corridors and forest plots. Controlled same-hardware benchmarks supply measured evidence for the efficiency pitfalls, and a research agenda for the photogrammetry and remote sensing communities follows.
Keywords:
mobile mapping systems
; forest inventory
; under-canopy laser scanning
; point cloud transformers
; 3D Gaussian Splatting
; semantic and instance segmentation
; Earth foundation models
; benchmarking
; geospatial intelligence
1. Introduction
Remote sensing has historically focused on the acquisition and systematic analysis of spatial data from airborne and satellite platforms, prioritizing extensive areal coverage, radiometric consistency, and the generation of standardized data products. Over the last three decades, Mobile Mapping Systems (MMS) have emerged as a complementary sensing modality, providing high-resolution, ground-based observations that capture urban environments, transportation corridors, infrastructure, and forest stands with centimeter-level accuracy. The two environments in which the technology is most heavily deployed—the built city and the forest—impose sharply different constraints on the same hardware, and the contrast between them is used throughout this review as a test of how well each surveyed advance generalizes: an urban corridor offers planar, high-return surfaces and intermittent satellite visibility, whereas a forest stand offers thin, self-similar, wind-perturbed geometry under a canopy that denies satellite positioning almost entirely. Early MMS research centered on precise trajectory estimation and geometric reconstruction through the integration of Global Navigation Satellite Systems (GNSS), Inertial Measurement Units (IMU), cameras, and LiDAR sensors [1,2].
Although these systems demonstrated substantial metric fidelity, their outputs—comprising dense point clouds, meshes, and textured models—remained largely unstructured and required significant post-processing to facilitate downstream remote sensing applications such as land-use mapping, infrastructure monitoring, or change detection [3]. Consequently, MMS have traditionally occupied a peripheral role within the aerial and satellite mapping ecosystem, functioning primarily as high-resolution data sources rather than integrated components of automated geospatial intelligence workflows: reviews of the field have consistently organized it by sensor and platform rather than by the analytical products the platform enables [1,3].
Recent developments in machine learning and artificial intelligence have begun to fundamentally alter this role. Advances in deep learning for 3D perception, and particularly transformer-based architectures [4,5,6], enable MMS to move beyond geometric reconstruction toward semantic understanding of complex environments [7,8]. In parallel, radiance-field reconstruction has introduced continuous, photorealistic scene representations that challenge conventional distinctions between mapping, visualization, and analysis. Two representatives of this family are treated separately throughout this review because they differ in kind and not only in speed: Neural Radiance Fields (NeRF) encode a scene in the weights of a multilayer perceptron that must be evaluated at every sample along every ray, and are therefore neural rendering in the strict sense [9,10]; 3D Gaussian Splatting (3DGS) instead stores an explicit set of anisotropic Gaussian primitives that are rasterized directly, with no network evaluated in the rendering path [11]. This distinction is maintained deliberately here, since it determines editability, incremental updatability, and the cost model of each representation (Section 5). These developments coincide with the emergence of Earth-scale foundation models, which aim to unify heterogeneous remote sensing data—including satellite imagery, airborne LiDAR, and in situ observations—within shared representation spaces capable of supporting general-purpose geospatial reasoning [12,13,14].
Within this context, MMS is increasingly positioned as a bridge between local-scale sensing and Earth observation. Ground-based mobile platforms provide dense geometric and semantic detail that complements the wide coverage of airborne and satellite sensors, enabling multi-scale integration across remote sensing workflows. Two concrete mechanisms make this complementarity operational rather than rhetorical. First, airborne LiDAR observes the urban scene from a single, near-nadir viewing geometry, so its classification of vertical structure—facades, poles, street furniture, under-canopy ground—is inferred from sparse, obliquely sampled returns; a co-registered MMS pass observes exactly those surfaces at one to two orders of magnitude higher density and from the side, and can therefore be used as an independent reference against which airborne class labels are checked and the associated per-class confusion is quantified. Benchmarks that deliberately co-register the two viewing geometries over one site, such as Hessigheim 3D, exist precisely to make this kind of cross-platform reference possible [15], and they are the empirical basis of the claim made here. Second, an explicit radiance-field reconstruction of a street corridor is a directly renderable, incrementally updatable geometric asset, which is the form that city-scale digital twins used for planning, flood and shading simulation, and visibility analysis require as input [11,16]. These synergies motivate a reassessment of MMS not merely as a data acquisition technology, but as an active contributor to intelligence-driven remote sensing systems.
A key driver of this transition is the rapid maturation of transformer architectures for 3D data [4,5,17]. Unlike earlier convolutional or point-based networks [18,19,20,21], transformers offer global receptive fields and flexible cross-modal attention mechanisms, making them well suited for large-scale, heterogeneous remote sensing data [7,22]. Recent models such as Point Transformer V3, SAT-Former, and lightweight adaptive variants demonstrate that carefully designed tokenization and attention strategies can achieve strong semantic segmentation performance while approaching the computational constraints required for mobile deployment [6,23,24]. These advances are particularly relevant for remote sensing applications that demand consistent labeling across extended spatial extents and diverse urban morphologies.
In parallel, the evolution of Simultaneous Localization and Mapping (SLAM) from classical optimization-based pipelines [25,26,27] to learning-enhanced and feed-forward architectures [28,29,30] further strengthens the integration between MMS and remote sensing. Transformer-grounded SLAM systems embed geometric priors directly into attention mechanisms and regress scene geometry in a single forward pass rather than by per-frame optimization, which has been reported to reduce drift and improve robustness in texture-poor and partially GNSS-denied environments [30,31]. Such capabilities are increasingly important for urban remote sensing scenarios where satellite visibility is limited and dynamic scene elements challenge the static-world assumptions of classical back-ends [32].
Radiance-field reconstruction represents a second transformative axis [10,33]. Although classical photogrammetry remains central to remote sensing, these methods introduce new possibilities for continuous view synthesis, improved handling of complex materials, and tighter coupling between geometry, appearance, and semantics [9,34]. Explicit radiance representations, such as 3DGS, offer real-time rendering performance and incremental update capabilities that are well aligned with mobile mapping workflows and interactive digital twin applications [11,35,36]. These methods do not replace traditional remote sensing products, but rather extend them toward immersive and task-oriented representations.
At the largest scale, Earth Foundation Models (EFMs) [12,13,14] and agentic geospatial reasoning frameworks [37] signal a shift from perception-centric remote sensing toward decision-oriented geospatial intelligence. By integrating MMS outputs with satellite imagery, environmental data, and textual knowledge—in the spirit of generalist multi-modal agents [38]—these systems enable complex spatial queries and adaptive analysis pipelines that transcend individual sensing modalities. For MMS, this shift implies a transition from passive data collection to active participation in closed-loop remote sensing systems, where acquisition, interpretation, and reasoning are tightly coupled.
Despite these advances, significant challenges remain. Transformer-based models face scalability and memory constraints when applied to large point clouds [6,17], to the point that—as the controlled measurements in sec:pcbench show—no current backbone ingests a ten-million-point neighborhood in a single forward pass on a 24 GB GPU, while operational urban datasets contain hundreds of millions to billions of points [39,40,41]. Radiance-field pipelines impose substantial optimization and storage demands [9,11], and foundation models raise concerns related to cloud dependence, data governance, and privacy [42]. Moreover, the increasing integration of high-resolution ground-based data into global remote sensing frameworks necessitates careful consideration of ethical, regulatory, and societal impacts.
This article is a critical review that addresses the underlying trends, pitfalls, and open research directions of the field. The analysis is organized around four questions: (Q1) which structural trends, rather than individual models, explain the trajectory of the field; (Q2) which recurring pitfalls weaken the reliability of reported progress; (Q3) where the idealized edge-to-cloud pipeline fractures in practice; and (Q4) which concrete research problems, if solved, would close those fractures. The main contributions of this review are:
- 1.
- Four cross-cutting trends are identified from the surveyed literature—from optimized to learned geometry (Section 3), tokenization economics as the governing principle of 3D perception (Section 4), the migration of radiance-field reconstruction from visualization to measurement (Section 5), and the transition from perception to agency (Section 6)—and each trend is stated as a claim and evaluated against its supporting and contradicting evidence;
- 2.
- Seven recurring pitfalls are consolidated (Section 7) that could change how results in this area are produced and read; a controlled, same-hardware benchmark of four point-cloud backbones on urban mobile-laser-scanning and photogrammetric data (sec:pcbench) provides measured evidence for the efficiency-related pitfalls;
- 3.
- Three systemic convergence bottlenecks are located that fracture the edge-to-cloud pipeline (Section 9);
- 4.
- A research agenda with concrete, evaluable problems is formulated (Section 10).
Figure 1 presents the architectural taxonomy that frames this analysis, mapping the transition from raw multi-modal acquisition through transformer-based perception and radiance-field synthesis to agentic geospatial decision-making.
1.0.0.1. Scope and literature selection
The review covers peer-reviewed and preprint literature from 2017 to early 2026, selected along the four pillars of the taxonomy in Figure 1: metric SLAM and sensor fusion; transformer-based 3D semantic perception; radiance-field representations (both neural and explicit); and Earth foundation models with agentic reasoning. Works were included when they either (a) introduced an architectural principle adopted by subsequent systems, (b) reported state-of-the-art results on benchmarks relevant to mobile mapping, or (c) provided evidence about deployment behavior (efficiency, robustness, generalization) under mobile-mapping constraints. Prior reviews have surveyed these strands as separate literatures: mobile-mapping sensor systems and their applications [1,3]; deep learning on 3D point clouds in general [7,22] and point-cloud semantic segmentation for remote sensing in particular [8]; neural rendering and neural fields [10,33]; and, most recently, 3D Gaussian Splatting [36,43] and city-scale digital twins [16]. Each is authoritative within its strand, and this review does not attempt to re-cover that ground; readers seeking exhaustive per-method coverage are referred to them. What none of these reviews takes as its unit of analysis is the mobile mapping system—the deployed edge-to-cloud pipeline in which these techniques must coexist under a shared latency, memory, and energy budget. That is the niche this review occupies, and it is the reason its organizing categories are trends, pitfalls, and bottlenecks rather than method families.
2. Background: The Multi-Scale Sensing Hierarchy
Remote sensing systems operate across a hierarchy of spatial scales, sensing geometries, and operational constraints. Within this hierarchy, MMS, airborne platforms, and satellite sensors play complementary roles that collectively enable comprehensive geospatial intelligence. Understanding their respective strengths and limitations is essential for designing integrated, multi-scale remote sensing workflows. At the local scale, MMS provide ground-based, high-resolution observations characterized by dense geometry, rich appearance information, and flexible sensing configurations. By operating at street level or within close proximity to target objects, MMS capture fine-scale structural and semantic details that are difficult or impossible to observe from overhead perspectives. That same proximity is what removes the satellite constellation from view: in urban canyons, tunnels, building interiors, and beneath a closed forest canopy the platform must fall back on positioning infrastructure whose standardization is still consolidating [44], which is one reason the SLAM back-end analyzed in Section 3 carries more of the metric burden in mobile mapping than in airborne or satellite sensing.
Forest and urban deployments sit at opposite ends of this hierarchy’s most demanding axis, and both are treated throughout this review. In forest environments the ground-based tier is not merely complementary to overhead sensing but corrective: canopy closure prevents airborne and satellite instruments from resolving the stem attributes—diameter at breast height, stem curve, taper, and volume—on which inventory and biomass estimation depend, so those quantities must be measured from beneath. Terrestrial and mobile laser scanning have consequently become the reference instruments for plot-level forest measurement [45,46], and the resulting stem-level observations propagate upward as the calibration and validation data for airborne and spaceborne biomass products. The complementarity argued above for urban scenes therefore holds in forests with the roles sharpened: overhead sensing supplies extent, the ground-based platform supplies the attributes that extent alone cannot yield. Typical MMS outputs—such as centimeter-resolution point clouds, textured meshes, and neural renderings—are particularly valuable for urban infrastructure mapping, asset inventory, change detection, and validation of coarser remote sensing products [1,2].
Airborne remote sensing operates between these two extremes: a single flight covers a much larger area than a ground-based survey, while its spatial resolution remains finer than that of satellite imagery. Platforms equipped with LiDAR, multispectral, or hyperspectral sensors provide region-scale observations with consistent viewing geometry and controlled acquisition parameters. Airborne data often serve as the primary source for terrain modeling, land-cover classification, and regional infrastructure assessment. In integrated workflows, airborne LiDAR and imagery act as a geometric and radiometric bridge between MMS and satellite observations. MMS-derived semantic labels and high-fidelity reconstructions can be used to calibrate, validate, or refine airborne classifications, while airborne products provide contextual priors that guide MMS interpretation in complex environments.
At the global scale, satellite remote sensing offers unparalleled spatial and temporal coverage, enabling long-term monitoring of environmental processes, urban expansion, and climate-related phenomena. However, satellite observations are constrained by spatial resolution, viewing geometry, and atmospheric effects, which limit their ability to resolve fine-scale urban structure. MMS and airborne data therefore play a critical role in anchoring satellite-derived analyses to physical reality. High-resolution ground and aerial observations support training and validation of satellite-based models, while Earth-scale foundation models increasingly integrate data across all three modalities to achieve consistent, multi-resolution geospatial representations [14].
Recent advances in deep learning further blur traditional boundaries between these sensing tiers. Transformer-based architectures enable shared representation spaces across MMS, airborne, and satellite data, facilitating cross-scale transfer learning and multimodal fusion. Neural rendering methods extend this integration by providing continuous scene representations that can incorporate observations from multiple viewpoints and altitudes. In this emerging paradigm, MMS function not only as local data acquisition platforms, but as adaptive, intelligence-driven sensors embedded within larger remote sensing ecosystems, contributing fine-scale detail, semantic richness, and real-time situational awareness to multi-scale geospatial analysis pipelines.
One further point of orientation is needed before the four trends are examined, because it governs how they should be read. The technological strands that constitute next-generation mobile mapping did not arrive as a succession of eras in which each generation retired the last; they accumulated, and all of them remain in production use today. Figure 2 sets the five strands—geometric MMS, optimization-based SLAM, learned 3D perception, radiance fields, and foundation models—on a common timeline to make this concurrency explicit. The trends analyzed in Section 3, Section 4, Section 5 and Section 6 are therefore shifts in the balance among coexisting strands rather than replacements, and the recurring temptation to read them as replacements is itself a source of several of the pitfalls consolidated in Section 7.
3. Trend 1: From Optimized Geometry to Learned Geometry
Over the last decade, per-frame geometric optimization in SLAM has gradually been displaced by learned, feed-forward geometry. In this review, the surveyed systems are organized along a single latency–fidelity axis rather than as competing camps: classical bundle adjustment (BA) pipelines provide metric guarantees at the cost of brittleness in challenging scenes; feed-forward transformer SLAM replaces per-frame optimization with learned priors, trading guaranteed reprojection consistency for speed and robustness; and neural-implicit SLAM sacrifices real-time operation to achieve dense reconstruction with the additional ability to fill in unobserved regions. The evidence for this reading is presented in this section, together with an important guarantee that no current system delivers.
Modern MMS platforms are characterized by modular, multi-sensor configurations integrating synchronized multi-camera arrays, high-frequency solid-state LiDAR, hyperspectral sensors, and event-based cameras [2]. This diversification is not merely additive; it enables complementary observability under precisely the conditions that defeat any single modality—dynamic urban scenes, occlusions, or partial GNSS denial. The design objective has correspondingly expanded from pose estimation alone to globally consistent metric mapping, in which 2D appearance and 3D structure coexist within a single representation space [1].
The architectural evolution of modern MMS reflects a shift from loosely coupled sensor aggregation toward tightly integrated, geometry-aware perception stacks. Early platforms primarily fused GNSS, IMU, and LiDAR measurements through deterministic filtering and smoothing frameworks. Although effective for trajectory estimation, these pipelines treated sensing modalities as largely independent information streams. Contemporary systems, by contrast, increasingly adopt unified representation paradigms in which geometric, photometric, and semantic signals are jointly optimized within a single computational backbone.
A key enabler of this transition is the redefinition of SLAM from an optimization-heavy geometric pipeline into a hybrid learning–geometry framework. Classical SLAM architectures relied on feature extraction, correspondence matching, BA, and pose-graph optimization. Although these methods achieved centimeter-level accuracy in controlled conditions, they exhibited limitations in texture-poor regions, large-scale drift accumulation, and dynamic scene robustness. Recent transformer-grounded approaches—such as DUSt3R [28], MASt3R [29], and the Visual Geometry Grounded Transformer (VGGT) [30]—address these limitations by embedding spatial priors directly into attention mechanisms, allowing networks to model long-range geometric dependencies implicitly.
3.1. VGGT-SLAM 2.0 and Feed-Forward Mapping
SLAM has transitioned from classical multi-view geometry toward hybrid systems grounded in geometric foundation models [31]. One distinction is maintained carefully throughout this section, because the trend under analysis is precisely the separation of the two: VGGT is a feed-forward transformer backbone that regresses scene geometry from a set of views in a single pass [30], whereas VGGT-SLAM is the SLAM system built on that backbone, which creates and aligns submaps to deliver dense RGB SLAM [47]. Attributing the SLAM system’s properties to the backbone, or the reverse, obscures where the learned component actually sits in the pipeline.
Feed-forward SLAM architectures represent a substantial departure from iterative geometric optimization. VGGT-SLAM generates and aligns submaps through transformer-based feature aggregation rather than solely through classical reprojection error minimization [47]. The backbone it inherits treats multi-view observations as tokens within a shared attention space, so spatial consistency constraints are learned rather than imposed [30]; VGGT in turn builds on the feed-forward pointmap paradigm pioneered by DUSt3R [28] and extended with metric matching in MASt3R [29], which replaced classical correspondence-and-BA pipelines with a single forward pass.
The second-generation VGGT-SLAM 2.0 further enhances global consistency by enforcing strict overlap constraints between keyframes and solving for a single metric scale factor across submaps [31]. This approach mitigates high-dimensional drift and reduces error propagation across long trajectories. Empirical evaluation on benchmark datasets demonstrates significant reductions in Absolute Trajectory Error (ATE), indicating that feed-forward architectures can approach—and in some cases surpass—the accuracy of traditional optimization pipelines while reducing computational complexity.
A further departure lies in loop-closure verification, which is delegated to the attention layers rather than to a handcrafted similarity metric—a change whose consequences are set out against the classical baselines below.
3.1.1. Comparative Analysis: VGGT-SLAM vs. Established Baselines
The transition from classical optimization to hybrid feed-forward mapping is best understood through a direct comparison with established baselines such as ORB-SLAM3 [26] and LIO-SAM [27]. Although these systems represent the state-of-the-art in geometry-centric mapping, they differ fundamentally from transformer-grounded approaches in their handling of uncertainty, drift, and scene representation.
- Algorithmic Paradigm: ORB-SLAM3 relies on a classical multi-view geometry pipeline involving handcrafted feature extraction (ORB), iterative BA, and pose-graph optimization to minimize reprojection error. In contrast, VGGT-SLAM utilizes a feed-forward neural process where dense submaps are generated and aligned through transformer-based feature aggregation. This eliminates the need for iterative geometric optimization at every frame, significantly reducing computational latency in complex scenes.
- Drift and Global Consistency:LIO-SAM, a benchmark for LiDAR-inertial fusion, uses deterministic filtering and factor-graph optimization to maintain trajectory accuracy, but such systems can accumulate high-dimensional drift where geometric constraints are sparse. The single-scale, overlap-constrained formulation described above attacks the same failure from the opposite direction: rather than constraining the trajectory incrementally, it constrains the submap graph globally.
- Robustness to Perceptual Aliasing:Classical systems often suffer from perceptual aliasing in repetitive urban corridors, producing incorrect loop closures. ORB-SLAM3 addresses place recognition with a bag-of-words model over handcrafted descriptors; the learned relational embeddings noted above instead separate true revisitations from merely similar textures, which is the harder discrimination in repetitive urban morphologies.
- Metric Scaling:While LIO-SAM achieves absolute scale through direct LiDAR measurements, monocular systems like ORB-SLAM3 inherently struggle with scale ambiguity. VGGT-SLAM 2.0 mitigates this by embedding geometric priors directly into its attention mechanism, allowing it to approach the metric fidelity of sensor-fused systems even in monocular configurations.
Across all four axes the comparison points the same way: classical pipelines retain the advantage in precision within feature-rich, controlled environments, while feed-forward architectures supply the scalability and robustness that high-resolution mobile mapping requires at survey scale. What the comparison does not establish—and what Section 7 returns to as Pitfall P6—is that matching a baseline’s accuracy on benchmark trajectories is the same thing as inheriting its guarantees.
3.2. Neural Implicit SLAM: Dense Representations and Map Completion
Despite the fact that feed-forward architectures prioritize real-time tracking, Neural Implicit SLAM focuses on generating continuous, photorealistic environmental models. These systems encode geometry within a neural network—typically a hierarchical feature grid or Multi-Layer Perceptron (MLP)—as exemplified by NICE-SLAM [48]. This line extends to collaborative, point-based neural SLAM, in which multiple agents jointly construct and fuse a shared neural map for multi-agent deployment [49].
- Predictive Scene Completion: Unlike explicit point clouds, implicit models can estimate geometry for unobserved or sparsely sampled regions by learning a continuous scene function.
- Hierarchical Scaling: Modern implicit SLAM variants use partitioned grids to scale from single rooms to larger urban corridors, reducing the “over-smoothing” issues found in early global MLP models.
The trade-off between the two branches, summarized in Table 1, is fundamentally one of latency against density. Feed-forward systems such as VGGT-SLAM suit high-speed mobile platforms where metric consistency and low latency are critical, whereas neural-implicit systems, whose computational footprint remains a hurdle for real-time mobile deployment, are indispensable for generating “analysis-ready” digital twins where visual fidelity and geometric completeness are required for downstream reasoning. This dual-track development allows an MMS to select its SLAM backbone according to whether the primary mission is real-time navigation or high-fidelity asset inventory.
3.3. The Under-Canopy Case: Where the Trend Is Already Forced
Forest mobile mapping is worth examining separately here, because it removes the option that urban deployment retains. In a street corridor, satellite positioning degrades intermittently and a trajectory can often be re-anchored when the sky reopens; beneath a closed canopy it is absent for the duration of the survey, so the entire metric frame rests on the SLAM back-end and its drift is bounded by nothing external. The displacement of optimized geometry by learned geometry that this section traces is therefore not a design preference in forests but a structural condition, and forest platforms have moved toward SLAM-centric operation faster than urban ones for that reason.
The platform lineage reflects this. Static terrestrial laser scanning delivers the reference measurement of stem attributes but requires multi-scan registration per plot, which bounds throughput [45,46]. Hand-held and backpack personal laser scanning replaced the tripod with a continuously moving operator and a SLAM solution, trading a controlled registration problem for an estimation one, and studies comparing the two report that the mobile variants achieve comparable stem-diameter accuracy at a small fraction of the plot time [50,51]. Under-canopy UAV laser scanning extends the same principle to a flying platform operating below the canopy ceiling, where GNSS is unavailable and the vehicle must localize entirely from its own returns; such systems have been shown to recover stem curve and diameter at accuracies competitive with terrestrial reference measurements [52], and controlled benchmarks now compare under- and above-canopy solutions on the same plots [53]. Real-time handheld inventory systems close the loop further by computing tree attributes on-device during the walk rather than in post-processing [54].
Two consequences matter for the argument of this review. First, the latency–fidelity axis introduced above is traversed in forests under a harder constraint: there is no bundle-adjusted external frame to fall back on, so Pitfall P6—empirical accuracy mistaken for metric assurance (Section 7)—binds more tightly, since an unbounded drift in a forest plot cannot be detected by the operator and propagates directly into the inventory attribute. Second, the geometry itself is adversarial to the assumptions of feed-forward reconstruction: stems are thin, mutually occluding, and self-similar across a stand, and foliage moves between passes. Whether learned geometry transfers from the planar, texture-rich urban scenes on which it is predominantly trained to this regime is, at present, an open empirical question rather than a demonstrated result.
3.4. Cross-Modal Sensor Fusion
Monocular SLAM systems inherently suffer from scale ambiguity and susceptibility to illumination variation [25,26]. To address these limitations, next-generation MMS platforms increasingly employ cross-modal transformer architectures that integrate LiDAR depth cues directly into visual feature embeddings. LiDAR-augmented transformer variants incorporate sparse range measurements as positional priors within the attention mechanism, enabling consistent metric scaling without external calibration loops. More recent adaptations of classical tightly-coupled estimators extend this principle to full LiDAR–visual–inertial operation in degraded and dynamic environments [27,32]. Closely related lines in autonomous driving have established the effectiveness of LiDAR–camera fusion, from point decoration [55] and query-based transformer fusion [56] to unified bird’s-eye-view representations [57].
Beyond simple bimodal fusion, emerging architectures adopt an omni-modal paradigm, in which text, imagery, LiDAR, and auxiliary environmental signals are embedded into a unified token space. This design allows contextual reasoning across modalities—for example, associating textual semantic priors with geometric structures or integrating environmental metadata into reconstruction confidence estimation. The result is not merely improved pose estimation, but enhanced semantic–geometric coherence across the mapping pipeline.
From a systems perspective, cross-modal fusion reduces redundancy by allowing each modality to compensate for the weaknesses of others. LiDAR stabilizes scale and geometry in low-texture regions; cameras contribute dense appearance information; IMU ensures short-term motion smoothness; and learned attention mechanisms integrate these cues adaptively based on scene context. This adaptive weighting contrasts sharply with earlier deterministic sensor fusion frameworks that relied on fixed covariance assumptions.
However, the computational footprint of transformer-based multimodal fusion remains substantial. Attention complexity grows quadratically with token count, and high-resolution LiDAR–image fusion increases memory demands. Efficient token pruning, hierarchical attention, and edge-aware compression techniques are therefore active research areas aimed at enabling real-time deployment on mobile platforms.
3.5. Photogrammetric Neural Reconstruction: The Geometric Anchor
Radiance-field reconstruction has redefined the visual fidelity of 3D models; however, its utility in geospatial intelligence depends on metric integrity. The emerging paradigm of photogrammetric neural reconstruction combines the rigorous geometric constraints of traditional photogrammetry with the representational power of learned or differentiably optimized radiance representations to achieve outputs that rival traditional LiDAR-based systems [58,59].
Modern MMS architectures prioritize high-resolution multi-camera arrays with synchronized triggers and fixed extrinsic parameters to maintain a constant geometric baseline. This structural rigidity is critical for reducing scale ambiguity and ensuring that neural radiance representations remain metrically consistent throughout the acquisition trajectory. Unlike pure-learning approaches that rely on latent spatial priors, this framework utilizes classical BA to minimize reprojection error across dense feature correspondences. By establishing a high-precision sparse backbone through BA, the system effectively “anchors” the subsequent radiance-field optimization to a globally consistent metric frame, mitigating the structural drift common in unconstrained reconstructions. The two representations are anchored by different mechanisms and this distinction should not be elided: for a NeRF, the BA solution fixes the camera poses under which the network is trained [9]; for 3DGS, no network is trained at all—the BA sparse point cloud additionally supplies the initial primitive positions that differentiable rasterization then optimizes, so the photogrammetric solution enters the representation directly rather than only through the loss [11].
Furthermore, while LiDAR provides direct range measurements, it is often limited by discrete sampling and specific viewing geometries. Photogrammetric neural reconstruction can achieve higher information density by leveraging continuous radiometric signals from RGB sensors, allowing the model to capture fine-scale structural details and complex materials, such as glass or metallic surfaces, with a level of completeness that often challenges active sensors. It is this hybrid rigor—a photogrammetric solution carrying the metric frame, a learned or differentiably optimized representation carrying the appearance—that makes the measurement-grade radiance-field products of Section 5 possible at all; those products, and the evidence for their accuracy, are treated there rather than here. Extending the same rigor toward task-aware semantics, recent work lifts noisy 2D aerial labels into consistent 3D urban semantic and building-instance maps using neural radiance fields across multiple flight altitudes [59].
3.6. Critical Synthesis: A Latency–Fidelity Division of Labor
The SLAM literature surveyed in this section could be better understood as a division of labor along a single latency–fidelity axis, rather than as three competing paradigms. Classical optimization back-ends and their multi-sensor extensions [26,27,32] purchase metric guarantees through explicit BA, at the cost of brittleness in texture-poor or dynamic scenes; feed-forward transformer SLAM [28,29,30,31] amortizes that per-frame optimization into learned geometric priors, trading guaranteed reprojection consistency for speed and robustness; and neural-implicit systems [48,49,60] trade real-time operation for dense reconstruction that can also complete unobserved regions. The decisive question for mobile mapping is therefore not which paradigm is “best,” but which point on this axis a task demands: corridor-scale trajectory estimation rewards feed-forward speed, whereas digital-twin generation rewards implicit completeness. What none of these systems yet resolves is the simultaneous delivery of BA-grade metric assurance and dense semantic completion at survey scale. The convergence toward geometry-grounded learning is genuine, but whether learned attention can guarantee—rather than empirically approach—metric accuracy remains the field’s central open question, and it is precisely this guarantee that safety-critical MMS applications such as infrastructure inspection require.
4. Trend 2: Tokenization Economics Governs 3D Perception
The progression from PointNet to Point Transformer V3, SAT-Former, and LitePT is usually presented as a succession of attention mechanisms. This section argues that the succession is better read as an economic one, in which the decisive design variable is not the attention operator but the token set it is given. The argument is developed in three steps—the lineage that produced the current backbones, the three mutually exclusive ways they construct that token set, and what a common measurement protocol reveals about the resulting costs—and it closes with two caveats that the headline figures conceal.
Semantic segmentation of 3D point clouds constitutes a foundational capability for geospatial intelligence, enabling infrastructure classification, terrain modeling, asset monitoring, and autonomous navigation. In contrast to pure geometric reconstruction, segmentation assigns categorical labels to each point within a spatially irregular set, transforming raw coordinates into semantically structured representations [1]. The challenge arises from the unordered, sparse, and non-uniform nature of point clouds, which complicates the direct application of convolutional architectures originally designed for grid-based images.
Early deep learning solutions such as PointNet [18] and PointNet++ [19] introduced permutation-invariant multilayer perceptron architectures capable of directly processing raw point sets. Although these models successfully captured local geometric structure through hierarchical neighborhood aggregation, they exhibited limited capacity to model long-range contextual dependencies—a critical requirement in urban-scale mapping where object identity often depends on large spatial context. Two complementary families subsequently dominated large-scale point cloud segmentation: kernel- and voxel-based convolutional methods that impose locality and near-linear scaling—including deformable kernel-point convolution [20], submanifold sparse convolution [61], Minkowski 4D spatio-temporal convolution [21], and the random-sampling RandLA-Net for very large clouds [62]—and attention-based methods that prioritize global context.
The introduction of transformer architectures [4] fundamentally altered this landscape by enabling global receptive fields through self-attention mechanisms. In 3D perception, transformers allow each point token to attend to all other tokens, thereby capturing global geometric relationships without explicit neighborhood construction. This lineage progressed from the original Point Transformer [5] through grouped vector attention in Point Transformer V2 [17], window-based stratified attention [63], and octree-structured attention [64]. Related designs broaden this scope further: group-in-group relation modeling captures global–local spatial structure for remote-sensing point clouds [65], while transformer-based non-rigid registration demonstrates the flexibility of attention under dynamic deformation [66]. However, naive application of full self-attention scales quadratically with token count, rendering direct implementation computationally prohibitive for large-scale point clouds.
Recent research has therefore focused on designing efficient transformer backbones tailored to 3D data, balancing global contextual modeling with computational feasibility.
4.0.0.1. Why this section examines three architectures rather than surveying the field
The space of 3D semantic segmentation backbones is large, and it has already been cataloged: general surveys of deep learning on point clouds [7,22] and of point-cloud semantic segmentation for remote sensing [8] enumerate dozens of architectures together with their benchmark scores, and this review does not repeat that enumeration. The three backbones examined below—PTv3 [6], SAT-Former [23] and LitePT [24]—are not presented as the three most accurate models, and the ranking of accuracy on any single leaderboard is not the criterion by which they were chosen. They are examined because they constitute three mutually exclusive answers to the one design question this section argues is decisive, namely how the token set given to attention is constructed: PTv3 reorders points along space-filling curves and leaves their number unchanged; SAT-Former merges points into semantically homogeneous clusters and thereby reduces their number before attention; LitePT relocates attention to the deep, low-resolution stages and lets convolution handle the high-resolution ones, so that the expensive operator never sees the full token set. Every other efficiency mechanism in the recent literature—hierarchical windows [63], octree structuring [64], token pruning [67]—is a variant or a combination of these three moves. Their benefit relative to the many alternatives cataloged in the surveys above is therefore not claimed here to be a benefit in accuracy; it is that they isolate the three levers cleanly, which is what makes the governing principle visible. Whether the efficiency each of them claims survives a common measurement protocol is a separate question, and one the surveys cannot answer because the published figures are not commensurable; sec:pcbench answers it by measuring PTv3 and LitePT, together with a sparse-convolution and a grouped-vector-attention reference, on one GPU under one protocol.
4.1. Point Transformer V3 and the Scaling Principle
Point Transformer V3 (PTv3) represents a significant milestone in transformer-based 3D perception [6]. Unlike earlier point transformers that relied heavily on k-nearest neighbor (kNN) grouping—an operation with non-trivial computational overhead—PTv3 introduces a serialize-and-patch paradigm. Points are ordered along space-filling curves, effectively converting unstructured 3D data into structured 1D sequences that can be processed efficiently using patch-based attention.
This restructuring enables substantial improvements in scalability. PTv3 expands receptive fields from localized neighborhoods (e.g., 16 points) to global patches containing up to 1024 points, while simultaneously achieving approximately 3.3× faster processing and a 10.2× reduction in memory usage relative to PTv2 [6,17]. The design philosophy emphasizes architectural simplicity, demonstrating that carefully structured tokenization can outperform increasingly complex attention variants.
Importantly, PTv3 empirically validates a broader scaling principle in 3D transformers: performance improves predictably with token count and model capacity when computational constraints are properly managed. This mirrors trends observed in large-scale vision and language models, suggesting that transformer scaling laws extend into geometric domains.
4.2. Efficiency vs. Accuracy: SAT-Former and LitePT
Although PTv3 advances scalability, deployment on mobile and edge platforms requires a further reduction in computational overhead. The Semantic Aggregated Point Tokenizer (SAT-Former) addresses this challenge by rethinking token generation [23]. Rather than uniformly sampling neighborhoods, SAT-Former constructs semantically homogeneous clusters before attention processing. This aggregation reduces redundancy and mitigates what the authors term “semantic confusion,” wherein heterogeneous neighborhoods degrade feature discrimination.
Empirical evaluations report up to 30× faster inference relative to baseline transformer models while maintaining over 95 percent relative accuracy [23]. This demonstrates that intelligent token aggregation can substantially improve efficiency without catastrophic information loss. LitePT extends this philosophy from a complementary direction, organizing the network around the principle that convolutions are best suited to capturing low-level geometry in early, high-resolution stages while attention is reserved for high-level semantic relations in deeper, low-resolution stages, supported by a parameter-free 3D positional encoding [24]. The resulting model attains accuracy comparable to (and in places exceeding) PTv3 with roughly 3.6× fewer parameters, about 2× faster inference, and approximately half the memory footprint. These architectural gains are reinforced by complementary evidence on token redundancy: systematic analysis shows that retaining only the most informative 5–10 percent of tokens—equivalently, merging or pruning the remaining 90–95 percent—preserves near-identical accuracy across diverse 3D tasks [67].
As summarized in Table 2, these findings challenge the assumption that dense tokenization is necessary for high-accuracy segmentation. Instead, they suggest that information density, rather than raw point density, governs transformer effectiveness in 3D tasks.
4.3. Architectural Trends and Emerging Directions
Four directions recur across transformer-based 3D perception, and each is a further expression of the same token economy rather than an independent development. Hierarchical attention confines the quadratic term to a window or an octree node, so that multi-scale token hierarchies preserve global context without paying for it globally [63,64]. Sparse and linear attention variants attack the same term analytically, through kernelized or locality-constrained formulations that target sub-quadratic scaling. Hybrid CNN–transformer architectures assign local geometry to convolution and global context to attention, which is the lever LitePT formalizes [24,68]. Pretrained 3D foundation backbones extend the vision-transformer recipe to large LiDAR corpora in the hope of transfer across mapping tasks—the direction with the weakest evidence in the mobile-mapping setting, since the cross-domain studies that would test it do not yet exist (Pitfall P3).
Moreover, integration with SLAM pipelines is increasingly common. Transformer-based segmentation outputs can inform dynamic object filtering, loop closure validation, and map compression strategies, thereby linking semantic understanding with geometric consistency.
4.4. Computational and Deployment Considerations
Despite performance gains, several constraints remain for the seamless integration of transformer-based models in mobile mapping. Standard self-attention remains computationally expensive for million-point clouds due to quadratic memory growth. Furthermore, real-time MMS applications are commonly held to a sub-100 ms inference budget. That figure is not a measured constant but a derived one, and it is worth stating where it comes from: a survey vehicle travelling at covers approximately 1.4 m in 100 ms, so a perception stack that is to label the scene at roughly meter granularity as the platform moves must close its loop within that budget. Slower budgets remain admissible for offline post-processing; the constraint binds only for on-line perception. This is particularly challenging given edge hardware limitations, where mobile GPUs and embedded accelerators impose strict memory ceilings. Additionally, energy efficiency is a major factor, as continuous 3D inference significantly increases power consumption in autonomous platforms. Consequently, practical deployment necessitates a strategic combination of token pruning, hierarchical processing, and hardware-aware model compression techniques, such as quantization and distillation.
4.5. Remote Sensing Benchmarks, Datasets, and Evaluation Metrics
Transformer-based point cloud segmentation models are often evaluated on computer vision benchmarks; however, their relevance to remote sensing depends on performance across datasets that reflect real-world sensing geometries, scales, and class taxonomies. In the remote sensing community, several benchmark datasets are widely used to assess semantic segmentation performance under urban and regional mapping conditions.
Common terrestrial and MMS-oriented datasets include Semantic3D [69], Toronto-3D [70], and Paris-Lille-3D [39], which feature large-scale urban point clouds acquired from ground-based and mobile platforms, while driving-oriented suites such as SemanticKITTI [71], nuScenes [72], the Waymo Open Dataset [73], and the more recent KITTI-360 [74], which adds dense 2D–3D correspondences and full coverage, provide multi-sensor street-level sequences. These datasets emphasize dense geometry, class imbalance, and complex object boundaries characteristic of street-level mapping, and indoor benchmarks such as S3DIS [75] and ScanNet [76] remain standard for close-range evaluation.
Airborne and photogrammetric benchmarks form the second, and for mobile mapping the more diagnostic, group. DALES [40] and the ISPRS Vaihingen 3D labeling benchmark [77] evaluate segmentation under overhead viewing geometries and lower point densities, and urban-scale photogrammetric benchmarks such as SensatUrban [41] bridge ground and aerial perspectives. Three more recent additions matter specifically for the cross-platform question raised in Section 7. Hessigheim 3D (H3D) [15] is, to our knowledge, the only public benchmark that provides co-registered UAV LiDAR point clouds and Multi-View-Stereo textured meshes of the same site, annotated under one class taxonomy and repeated across epochs; it is therefore the natural testbed for the cross-representation and multi-temporal transfer that mobile mapping actually requires, and its omission from most transformer evaluations is itself evidence for the benchmark-transfer pitfall (P3). STPLS3D [78] pairs real aerial photogrammetric point clouds with a large synthetic counterpart generated under controlled conditions, which makes the synthetic-to-real gap measurable rather than assumed. FRACTAL [79] extends aerial LiDAR evaluation to national scale and to deliberately diverse landscapes, addressing the geographic-monoculture problem that single-city benchmarks cannot.
The scale of these resources also sets the operating point that any deployable backbone must meet, and it is larger than the figures usually quoted in architecture papers. Paris-Lille-3D contains roughly 143 million annotated points over about two kilometers of street [39]; DALES contains over half a billion [40]; SensatUrban comprises nearly three billion points across some 7. of urban area, with individual tiles such as birmingham_block_1 holding around 59 million points in a single m block [41]. A single tile of a contemporary benchmark thus already exceeds, by an order of magnitude, the point counts at which transformer backbones are typically profiled—a discrepancy quantified directly in sec:pcbench.
Forest point clouds form a third group, and they are the sharpest available test of the benchmark-transfer question because they differ from the urban and driving corpora on every axis that a tokenization scheme is sensitive to. Density is extremely non-uniform, dominated by near-range foliage returns; the objects of interest are thin, mutually occluding, and self-similar across a stand rather than planar and distinct; the semantic taxonomy is shallow but the instance count per scene is high, since the operational task is separating individual trees rather than labeling surfaces; and the classes that matter for inventory—stem versus branch versus foliage—are distinguished by local geometric structure rather than by the global context that attention is introduced to supply. FOR-instance provides co-registered UAV laser scanning plots from five countries with manually delineated individual trees and semantic classes, and is explicitly constructed for instance and semantic segmentation benchmarking [80]. Learned segmentation on this data is now an active line in its own right: TreeLearn segments individual trees directly from ground-based forest point clouds without hand-tuned priors [81], work on generalizable tree instance segmentation addresses transfer across acquisition setups [82], and machine- and deep-learning wood–leaf separation and species classification operate on terrestrial laser scanning at the stem level [83]. What is almost entirely absent is the cross-evaluation that would settle the matter: the point transformers surveyed in this section are ranked on indoor and driving benchmarks and are seldom evaluated on forest data at all, and the forest segmentation literature has largely developed its own architectures rather than adopting them. That the two literatures barely intersect is itself the strongest available evidence for Pitfall P3.
For satellite and multi-modal remote sensing, datasets integrating LiDAR, imagery, and ancillary data are increasingly used to evaluate cross-scale transferability. These datasets stress robustness to varying resolution, noise characteristics, and class definitions—key requirements for foundation-level models. Evaluation typically relies on metrics standard in remote sensing, including Overall Accuracy (OA), mean Intersection over Union (mIoU), per-class F1-score, and Kappa coefficient. Unlike pure computer vision benchmarks, remote sensing evaluations often emphasize class-wise performance and spatial consistency due to strong class imbalance and application-driven priorities. For urban mapping tasks, metrics assessing boundary accuracy and object completeness are also relevant, particularly when segmentation outputs feed downstream modeling or decision-making processes.
Recent transformer-based models such as Point Transformer V3, SAT-Former, and LitePT demonstrate strong performance across both MMS and airborne benchmarks, suggesting that carefully designed tokenization and attention strategies can generalize across sensing modalities; their core innovations and reported deployment characteristics are summarized in Table 3. However, systematic cross-dataset evaluation remains limited. Establishing standardized protocols that jointly assess MMS, airborne, and satellite datasets is therefore a critical research direction for aligning transformer-based 3D perception with the needs of the remote sensing community.
4.6. Comparative Analysis: Sparse Convolutions vs. Transformers
Transformers have redefined global scene understanding; however, they have not entirely replaced CNN-based and sparse voxel architectures in mobile mapping. The choice of architecture involves a fundamental trade-off between local efficiency and global context, summarized in Table 4.
There are several situations in which CNNs and sparse methods still outperform transformers. The most important of these situations are the following:
- The Low-FLOP Regime: In embedded environments where the computational budget is constrained (e.g., <1 GFLOP), lightweight CNNs (e.g., MobileNet-style inverted-residual designs [84]) and Sparse Voxel Convolutions still dominate. Transformers often require a “critical mass” of parameters and data to outperform these established baselines, making them less efficient for extremely small models.
- Fine-Grained Geometry: CNNs excel at capturing local, high-frequency geometric details because their filters are explicitly designed for local neighborhood aggregation. In tasks requiring centimeter-level boundary precision without the need for global context, sparse methods can achieve comparable accuracy with significantly lower latency.
- Extreme Point Densities: The relevant scale here is easily understated. Contemporary urban benchmarks are not measured in millions of points but in hundreds of millions to billions—roughly 143 million for Paris-Lille-3D [39], over 500 million for DALES [40], and close to three billion for SensatUrban [41]—so no current architecture, transformer or convolutional, processes such a cloud in a single pass. The operative question is therefore not whether a backbone can ingest a whole dataset, which none can, but how gracefully its cost grows with the size of the tile into which the cloud must be partitioned, since tile size determines how much spatial context each inference sees and how many boundary artifacts must later be reconciled. On this question the measurements in sec:pcbench are unambiguous: on a 24 GB GPU, grouped vector attention (PTv2) exhausts memory at a one-million-point contiguous crop of SensatUrban on two of the three tiles measured, PTv3 exhausts it between three and five million, and no backbone tested—including the sparse-convolution baseline—completes a ten-million-point crop, in that last case through failures inside custom CUDA kernels rather than through device capacity. Sparse voxel methods such as MinkowskiNet [21] retain the advantage that their memory growth is predictable and close to linear in the number of occupied voxels, which makes tile budgeting a calculation rather than an experiment; but the measurements show that this advantage buys a larger tile, not an unbounded one.
The current research frontier is moving toward hybrid CNN–Transformer models. These architectures use convolutional layers for initial feature extraction and local geometry capture, then pass high-level tokens to attention layers for global geospatial reasoning. This approach leverages the efficiency of CNNs for “seeing” and the power of Transformers for “understanding”.
4.7. Critical Synthesis: Tokenization Economics as the Governing Principle
The most consistent lesson of the transition from PointNet through PTv3, SAT-Former, and LitePT [6,18,23,24] is that progress has been driven less by novel attention mechanisms than by the economics of tokenization, i.e., how raw points are converted into, and pruned from, the set of tokens that attention must process. Space-filling-curve serialization [6], semantic aggregation [23], convolution-then-attention placement [24], and the empirical finding that 5–10% of tokens suffice [67] are different expressions of one principle: accuracy-per-FLOP is governed by information density rather than point density, and our controlled benchmark (sec:efficiency) exhibits the architecture-general version of the same effect. Two critical caveats temper the literature’s headline figures. First, the reported speedups are measured against heterogeneous baselines on heterogeneous hardware and are therefore not directly comparable; a standardized, MMS-specific efficiency protocol (Section 4.5) remains absent. Second, these gains are typically demonstrated only after dense-corpus pre-training, leaving generalization across the heterogeneous urban morphologies of operational mobile mapping largely unverified. For edge MMS the rational default is consequently a token-economy backbone—but adopted with explicit awareness that its transfer behavior, not its FLOP count, is the binding risk.
5. Trend 3: Radiance-Field Reconstruction from Visualization to Measurement
The development from implicit NeRFs through accelerated variants to explicit Gaussian splatting is usually presented as a race for speed and photorealism. For mobile mapping, a more consequential axis is the migration of rendering from visualization toward measurement, where task-aware products—true orthophotos, multi-altitude semantic lifting, and updatable digital twins—gradually replace novel-view synthesis as the main object of interest. The trade-off along this axis is considerable: implicit fields are continuous and queryable but slow and scene-overfitted, while explicit primitives are fast and incrementally updatable but memory-intensive and equally scene-specific. Currently, no representation is natively metric and semantically queryable in a common space. The supporting evidence is presented in this section.
5.0.0.2. A terminological distinction maintained throughout this section
The two representations discussed below are frequently grouped under the single label neural rendering, and that grouping obscures the property that matters most for mobile mapping. In a NeRF, the scene is a neural network: a multilayer perceptron is queried at every sample along every ray, so rendering cost is dominated by network evaluation and the representation is not directly editable [9,10]. In 3DGS, no neural network is present in the rendering path at all; the scene is an explicit list of anisotropic Gaussian primitives, optimized by differentiable rasterization—gradient descent on primitive parameters, not the training of a network—and rendered by a sorted alpha-blended rasterizer [11,36]. 3DGS is therefore a radiance-field method but not a neural rendering method, and it is described as such here. The umbrella term used in this review for both is radiance-field reconstruction; neural rendering is reserved for the NeRF family.
Radiance-field reconstruction has become a cornerstone technology for transforming mobile mapping outputs into immersive, analysis-ready digital twins. Unlike classical photogrammetry, which relies on explicit surface reconstruction and texture baking, these methods encode appearance and geometry within an optimized radiance representation. This shift enables continuous view synthesis, improved handling of reflective or translucent materials, and tighter integration with learning-based perception pipelines [9,10,35].
5.1. From Implicit NeRFs to Explicit Radiance Representations
NeRFs model scenes as continuous volumetric functions that map spatial coordinates and viewing directions to emitted radiance and density. This formulation enables highly accurate view interpolation and photorealistic rendering, making NeRFs attractive for digital twin generation in complex environments. However, their reliance on dense ray marching during both training and inference imposes severe computational constraints. Training times scale poorly with scene size, and baseline rendering remains unsuitable for real-time navigation without aggressive acceleration strategies [9]. Recent research has therefore focused on accelerating NeRF pipelines through explicit or hybrid representations. Techniques such as multi-resolution hash encoding [85], voxel- and tensor-factorized scene decomposition [86,87], and anti-aliased multi-scale sampling [34,88] reduce unnecessary ray evaluations, enabling interactive performance for bounded scenes; modular frameworks such as Nerfstudio [89] have consolidated these advances into reproducible pipelines. Despite these advances, implicit NeRF formulations remain computationally intensive for city-scale deployment, particularly within mobile mapping workflows that demand rapid model updates.
5.2. 3DGS and Real-Time Urban Visualization
3DGS represents a paradigm shift from implicit volumetric fields to explicit radiance primitives. Scenes are modeled as collections of anisotropic Gaussian ellipsoids, each carrying color, opacity, and covariance parameters. This explicit formulation enables efficient rasterization using GPU pipelines, achieving real-time rendering at 100+ frames per second for large scenes [11]. For mobile mapping systems, 3DGS offers several advantages over classical NeRFs. First, rendering latency is sufficiently low to support continuous navigation, eliminating the discrete viewpoint transitions typical of panorama-based virtual tours. Second, explicit primitives facilitate incremental updates, allowing newly captured data to be fused into existing models without full retraining, as demonstrated by Gaussian-splatting SLAM systems such as SplaTAM [90] and MonoGS [91]. Third, the representation aligns well with downstream tasks such as visibility analysis, change detection, and semantic annotation. Nevertheless, scalability introduces new challenges. Urban-scale reconstructions may require millions of Gaussian primitives, increasing memory consumption and rasterization overhead. Active research directions therefore focus on adaptive primitive pruning, level-of-detail hierarchies, and semantic-aware Gaussian clustering to balance fidelity with efficiency [35]; representative advances include anti-aliased Mip-Splatting [92], geometry-accurate 2D Gaussian Splatting [93], and the structured, view-adaptive Scaffold-GS [94].
5.3. Large-Scale and Task-Oriented Radiance-Field Reconstruction
To extend radiance-field reconstruction beyond visualization, recent systems integrate rendering directly with geospatial analysis tasks. Partitioned architectures such as UE4-NeRF decompose large environments into sub-scenes that can be streamed and rendered on demand, enabling interactive exploration of city-scale models [95]. Similarly, Ortho-NeRF demonstrates that implicit neural representations can generate TDOMs with reduced distortion and competitive accuracy compared to classical photogrammetric pipelines, while lowering manual processing requirements [58]. These developments signal a transition from visualization-centric rendering toward task-aware digital twins, where rendering, measurement, and semantic reasoning coexist within a unified representation. For mobile mapping, this convergence enables continuous links between perception, visualization, and decision-making.
Table 5 summarizes how the three representations discussed above differ on the axes that decide their suitability for mobile mapping: whether the scene is stored implicitly or explicitly, the cost of training and of rendering, the urban scale each has been demonstrated at, and whether real-time operation is attainable. The pattern to note is that the explicit representation dominates on every deployment axis without a corresponding loss of fidelity, which is what makes the migration toward measurement—rather than a mere speed race—the consequential reading of this literature.
5.4. Failure Mode Analysis: Robustness and Generalization Bottlenecks
The visual fidelity of NeRFs and the speed of 3DGS are transformative; however, their transition from controlled research environments to “in-the-wild” urban mapping reveals several critical failure modes. Moving beyond the “realism and speed” narrative, these hurdles fall into three groups, distinguished by what each one violates: an assumption about the scene, an assumption about the illumination, or an assumption about transfer. The first two supply the evidence for Pitfall P5 and the third for Pitfall P4 (Section 7).
5.4.0.3. Violations of the static-world assumption
Both NeRF and 3DGS natively assume a static world. In mobile mapping this assumption is violated continuously, by moving vehicles, pedestrians, and foliage.
- Ghosting and Floaters: Moving objects often appear as semi-transparent “ghosts” or blurred artifacts that corrupt the geometric integrity of the digital twin.
- Temporal Inconsistency: 3DGS, in particular, may struggle to distinguish between a static street-side object and a transient one, leading to “floaters”—stray Gaussian primitives that interfere with navigation and visibility analysis.
5.4.0.4. Violations of the constant-illumination assumption
Mobile mapping data are often collected over extended periods under varying sky conditions, solar angles, and exposure settings, none of which the representation separates from the scene itself.
- Shadow Baking: Both NeRF and 3DGS reconstructions tend to “bake” shadows into the scene representation, making the model inaccurate for analysis at a different time of day.
- Specular and Reflective Artifacts: While NeRFs handle complex materials better than classical methods, highly reflective urban surfaces (e.g., glass skyscrapers) still cause “shimmering” or depth-estimation errors when viewed from novel angles.
- Thin, Moving Structure: Vegetation combines the two failure modes above with a third. Foliage is geometrically thin relative to the primitive scale, self-similar across a stand, and in continuous motion, so a radiance field fitted to a forest plot distributes primitives across positions the surface never simultaneously occupied. The photometric loss is nonetheless satisfied, because a blurred canopy renders plausibly from the training views—which makes this the case where photorealism and metric validity diverge most completely, and the reason radiance-field products remain of limited use for the stem-level attributes that forest inventory requires (Section 3.3).
5.4.0.5. Absence of zero-shot generalization
The most consequential bottleneck for large-scale geospatial intelligence is that a radiance field optimized in one place transfers to no other, and that the resulting degradation is not visible in the rendering.
- Scene-Specific Overfitting: Most current radiance-field frameworks are optimized for a specific, bounded scene. They do not naturally “transfer” their learned knowledge of urban structures to a new city with different architectural morphologies.
- Structural Drift in Unseen Environments: When 3DGS models are applied to unfamiliar urban layouts, they fail to maintain metric accuracy. Because these representations lack the geometric priors that constrain classical photogrammetric pipelines, they are susceptible to metric inconsistency; in novel environments depth estimation degrades, causing the digital twin to “warp” or lose its centimeter-level fidelity.
- Mismatched Boundaries: A photorealistic rendering may look perfect while the underlying semantic labels fail to align with the visual boundaries of objects—the clearest case of photorealism masking an error that propagates into automated infrastructure monitoring and change detection.
To resolve these failures, next-generation MMS must adopt a hybridized optimization strategy. By integrating “Geometric Anchors”—derived from classical BA or raw LiDAR depth cues—directly into the neural training loss, systems can “pin” the radiance field to a globally consistent metric frame. This prevents the structural drift common in pure-neural approaches and ensures that the photorealistic rendering remains aligned with the underlying semantic boundaries required for automated infrastructure monitoring.
5.5. Scaling Metrics: Primitive Density and Memory Curves
The transition from street-scale to city-scale modeling is not merely a matter of data volume but a shift in primitive density and computational complexity. The primitive counts involved are worth stating as orders of magnitude, since they determine which hardware class a reconstruction can target; the figures below are engineering estimates for typical urban capture rather than measurements from a controlled study, and are given only to fix the scale of the problem. High-fidelity mapping of a street-level segment (roughly 100–500 m) requires primitives in the low millions, which remains manageable on a high-end mobile GPU. Extending to several city blocks moves the count into the tens of millions and creates a memory ceiling on consumer-grade hardware, at which adaptive primitive pruning becomes necessary to maintain frame rates. A comprehensive urban digital twin lies in the hundreds of millions; at that magnitude monolithic rasterization is no longer viable, and partitioned architectures such as UE4-NeRF, which stream sub-scenes on demand, become a structural requirement rather than an optimization [95].
The computational overhead also differs fundamentally between the rendering and perception layers of the MMS pipeline. The memory of 3DGS rendering scales approximately linearly, , with the number of primitives, and GPU rasterization memory becomes the primary bottleneck as the primitive count enters the hundreds of millions. In contrast, standard self-attention in the perception layer scales quadratically, , with the token count T; even with the serialize-and-patch paradigm of PTv3, which achieves a 10.2× memory reduction, million-point clouds remain a dominant constraint for real-time edge hardware—in the controlled measurements of sec:pcbench, PTv3 requires just over 4 GB of activation memory at a single million-point crop, and exhausts a 24 GB device between three and five million.
The storage requirement follows directly from the representation and can be stated exactly rather than estimated. An uncompressed Gaussian carrying full degree-3 spherical harmonics stores 59 float32 attributes—three for position, three for scale, four for the rotation quaternion, one for opacity, and 48 for the color coefficients—or 236 bytes per primitive [11]. A 500-million-primitive city model therefore occupies approximately 118 GB for the representation alone, roughly five times the memory of the 24 GB accelerator used in sec:pcbench. Truncating the harmonics to their DC term reduces this to 14 attributes, or 56 bytes, at the cost of view-dependent appearance. The gap between these two figures is precisely the design space that attribute quantization and hierarchical level-of-detail strategies exist to exploit, and it is why mobile-ready digital twins are a compression problem before they are a rendering problem.
5.6. Critical Synthesis: From Visualization to Measurement
The development from implicit NeRFs through accelerated variants to explicit Gaussian splatting [9,11,85,94] is usually presented as a race for speed and photorealism. For mobile mapping, however, a more consequential axis is the migration from rendering as visualization to rendering as measurement. Along that axis the trade-off is sharp: implicit fields are continuous, compact, and queryable yet slow and scene-overfit, whereas explicit primitives are fast and incrementally updatable—a property that aligns directly with the streaming, ever-changing nature of MMS acquisition—but heavy and equally scene-specific. The emergence of task-aware neural products, from true-orthophoto generation [58] to multi-altitude semantic and instance lifting [59], signals that the field’s center of gravity is shifting from “how realistic” to “how measurable and how semantically structured.” Yet a limitation cuts across all of these representations: none is natively metric and semantically queryable within a common space—the concrete manifestation, at the rendering layer, of the latent-representation gap analyzed in Section 9. The near-term value of neural rendering for MMS therefore lies less in replacing photogrammetric products than in supplying continuously updatable, analysis-ready twins whose metric grounding is, for now, externally enforced rather than intrinsic.
6. Trend 4: From Perception to Agency
Read on its own terms, the foundation-model literature is a satellite-scale enterprise with little evident bearing on street-level survey. This section argues the opposite, and the argument turns on a single asymmetry: what these models are good at is exactly what mobile mapping cannot do, and vice versa. Two things follow from that asymmetry, and the section takes them in turn—first the orchestration architecture that makes an interlock between the two scales technically plausible, then the grounding failure that currently prevents it from closing. The synthesis at the end of the section states what this implies for where effort should go.
The rapid expansion of multimodal Earth observation data has motivated the development of EFMs—large-scale architectures trained across imagery, LiDAR, environmental variables, and textual data to support general-purpose geospatial reasoning [14]. This direction builds on a rapidly growing lineage of Earth-observation foundation models that pre-train masked autoencoders or spectral transformers on large satellite corpora—including SatMAE [96], Scale-MAE [38], the continually pre-trained GFM [13], the multispectral Prithvi model [12], and the spectral SpectralGPT [97]—and, extending beyond purely visual satellite data toward dynamic land-surface geoscience, the masked-autoencoder model StefaLand [98]. Unlike task-specific models, these systems aim to learn transferable spatial representations that can be adapted to diverse applications, from disaster response to infrastructure monitoring.
6.1. Technical Architecture: The Geospatial Orchestrator
The transition from task-specific perception to agentic reasoning is characterized by a “Model-as-Orchestrator” architecture. Systems of this kind—Google Earth AI is the most fully documented example [14]—do not function as a single monolithic network but as a modular reasoning stack. The four components below are described as that system reports them; no independent evaluation of the stack as a whole is currently available, which is itself part of the auditability problem raised in Section 6.
- The Reasoning Core (Gemini-powered Agent): Operates at the apex of the stack, utilizing Large Language Models (LLMs) to parse high-level natural language queries into a structured execution graph, paralleling the autonomous-GIS paradigm in which LLM agents self-generate and self-execute spatial-analysis workflows [37].
- Tool-Aware Orchestration: The agent dynamically calls upon specialized sub-models—such as high-resolution vision models for asset detection, population density estimators, and environmental simulation engines—based on the specific spatial query.
- Multi-Modal Injection: MMS contribute dense local “evidence” (e.g., 3DGS streams or semantic tokens) that are injected into the agent’s context window to refine global satellite-scale predictions.
- Agentic Feedback Loop: The system can trigger “active sensing” requests, where the EFM identifies a region of high uncertainty and tasks local MMS platforms to prioritize data collection in those specific coordinates.
6.2. Implications for Mobile Mapping Systems
For mobile mapping, EFMs redefine the role of MMS from data acquisition platforms to active contributors within larger geospatial intelligence ecosystems. MMS outputs—dense point clouds, trajectories, and radiance-field reconstructions—can serve as high-resolution local context injected into global foundation models. Conversely, foundation models can provide priors that guide on-device perception, such as expected object classes, anomaly detection thresholds, or risk indicators. This bidirectional interaction enables adaptive mapping strategies, where data collection is dynamically prioritized based on downstream information value rather than uniform coverage. However, it also introduces new challenges related to latency, cloud dependence, and data governance, as most foundation models currently operate at data-center scale.
6.3. What Currently Constrains Deployment
Three constraints, specific to this trend, limit how far the interlock can be taken today. Training an EFM requires vast, heterogeneous corpora with consistent spatial alignment, which is a data-curation problem before it is a modeling one. Inference remains tied to cloud infrastructure, which restricts applicability precisely in the bandwidth-constrained and privacy-sensitive settings where mobile mapping often operates—and which makes the edge–cloud partitioning question of Section 8.1, illustrated in Figure 3, a prerequisite rather than an optimization. Finally, agentic reasoning introduces transparency, auditability, and bias concerns that have no counterpart in the purely geometric pipeline it augments; these are taken up as Pitfall P7 and, as a research problem, in Section 10.
6.4. Risk Mitigation: Hallucination and Spatial Grounding
Despite their reasoning capabilities, EFMs introduce a unique class of geospatial hallucinations that can undermine the reliability of the entire mapping ecosystem. A primary technical challenge is spatial grounding, i.e., the ability of an LLM to link linguistic concepts (e.g., “damaged power line”) to specific 3D coordinates and geometric topologies without creating ghost features. Beyond mislocalization, agents may hallucinate plausible environmental features, such as road extensions or vegetation patterns, that appear consistent with the surrounding context but have no basis in physical reality.
These risks could be mitigated in three complementary ways. First, physics-based priors or LiDAR-derived geometric anchors could be embedded directly into the reasoning process to prevent the agent from proposing spatially impossible solutions. Second, a cross-platform verification step could be implemented, in which agentic conclusions must be validated against raw ground-level MMS data before they are integrated into the global digital twin. Third, moving from deterministic outputs to probabilistic spatial distributions would allow the system to flag hallucination-prone queries for human audit.
6.5. Critical Synthesis: Complementarity, Not Competition
The foundation-model and agentic literature could easily be read as a separate, satellite-scale enterprise; however, its significance for mobile mapping lies in an almost exact complementarity. Earth foundation models [12,13,38,96,97,98] derive their power from cross-scale, cross-modal invariance and zero-shot transfer—precisely the capabilities that ground-based MMS, with its centimeter-level but spatially local and task-specific evidence, lacks; conversely, MMS supplies the fine-grained physical ground truth that globally trained models cannot resolve. The two are thus not competitors along a single quality axis but opposite, interlocking ends of a scale spectrum, which is the technical substance of this review’s bridging thesis. What currently prevents the interlock from closing is not model capability but representational interfacing: agentic systems [14,37] reason fluently at the level of language and region while remaining unable to address centimeter-scale geometry without spatial hallucination. The binding constraint on decision-oriented geospatial intelligence is therefore a grounding problem (Section 9), and progress will come from differentiable registries that bind macroscopic semantics to fine-scale topology rather than from ever-larger foundation models.
7. Pitfalls: Recurring Failure Patterns Across the Field
The four trends analyzed above are real; however, the literature that documents them exhibits recurring methodological and conceptual failure patterns that inflate the apparent progress and complicate deployment decisions. In this section, these failure patterns are consolidated as seven pitfalls. Each pitfall is stated as a caution, grounded in the evidence reviewed in Section 3, Section 4, Section 5 and Section 6, and paired with a concrete recommendation on how results in this area should be produced or read. The efficiency-related pitfalls (P1, P2) are additionally supported by two controlled, same-hardware benchmarks reported in the appendices: an architecture-general study of six two-dimensional segmentation backbones on an edge-class GPU (sec:efficiency), and a point-cloud study that profiles four of the backbones surveyed in Section 4—including PTv2, PTv3, and LitePT themselves—on one GPU under one protocol (sec:pcbench).
7.0.0.6. P1 — Incommensurable efficiency claims
The headline efficiency figures that anchor the 3D perception literature—“ faster,” “up to faster inference,” “ fewer parameters” (Table 2)—are measured against heterogeneous baselines, on heterogeneous hardware, at heterogeneous input regimes, and are therefore not mutually comparable. A reader cannot conclude from them which architecture is more deployable on a given platform. Our controlled benchmarks demonstrate how strongly the numbers move once hardware, precision, input size, and measurement protocol are fixed. This is shown most directly in sec:pcbench, where three of the architectures behind those very figures—PTv2, PTv3, and LitePT—are re-measured on one GPU, at one precision, on identical contiguous crops. Two things change under that common protocol. First, the magnitudes: the published advantage of PTv3 over PTv2 is measured here at at points, and LitePT’s reported advantage over PTv3 at —so the headline ratios understate the true separation by factors of roughly five and 1.6 respectively, in a direction the reader has no way to anticipate. Second, and more consequentially, the frame: a sparse-convolution baseline that appears in none of these headline comparisons is measured faster than PTv3, so the pairwise speedups on which the literature’s narrative rests do not reveal that a non-attentional architecture already occupies the operating point being competed for. sec:efficiency establishes the same point in architecture-general form on a second hardware class. Recommendation: efficiency claims should be reported with hardware, precision, batch size, input regime, and measurement protocol, ideally accompanied by a same-hardware comparison against at least one common public baseline.
7.0.0.7. P2 — The parameter-count fallacy
Parameter count is routinely headlined as an efficiency metric, yet it correlates poorly with the quantities that constrain deployment: latency, throughput, and peak activation memory. Our controlled measurements show this in both settings the appendices cover. On point clouds—the setting these claims are actually made about—PTv2 has fewer parameters than PTv3 yet is slower, requires more activation memory, and consumes more energy per forward pass; across the four backbones profiled, the rank correlation between parameter count and latency is , so in that sample parameter count does not merely fail to predict cost, it orders it very slightly the wrong way (sec:pcbench). The two-dimensional study shows the same decoupling architecture-generally: a 52.3M-parameter hybrid transformer runs faster than a 36.6M-parameter densely connected CNN, because dense feature reuse—not model size—dominates runtime cost (sec:efficiency). Recommendation: report forward compute (FLOPs) and peak activation memory alongside parameters; treat parameter reductions as a storage claim, not a speed claim.
7.0.0.8. P3 — The benchmark-transfer assumption
Architecture rankings established on indoor RGB-D and autonomous-driving LiDAR benchmarks (Section 4.5) are implicitly assumed to transfer to mobile-mapping and photogrammetric data, whose attribute sets, noise structure, density variation, and class taxonomies differ systematically. Systematic cross-dataset evaluation of the leading backbones remains absent, and reported generalization is typically demonstrated only after dense-corpus pre-training. The clearest case is forest data, where the divergence is not a matter of degree: density is dominated by near-range foliage returns, the objects of interest are thin and mutually occluding rather than planar, the operational task is instance separation of individual trees rather than surface labeling, and the decisive stem–branch–foliage distinction rests on local geometric structure rather than the global context that attention exists to supply (Section 4.5). The two literatures have consequently developed in parallel: the point transformers ranked on indoor and driving benchmarks are seldom evaluated on forest plots, while forest segmentation has grown its own architectures [80,81,82]. Neither community has produced the cross-evaluation that would establish whether the rankings transfer. Recommendation: evaluations intended to inform MMS practice should include at least one MMS-relevant benchmark (e.g., Toronto-3D, SensatUrban, DALES) and, where the claim is general rather than urban, at least one structurally dissimilar domain such as FOR-instance; zero-shot as well as fine-tuned performance should be reported in both.
7.0.0.9. P4 — Scene-specific overfitting of radiance-field reconstruction
NeRF- and 3DGS-based products are optimized per scene and do not transfer learned structure to new environments; in unseen zones, depth estimation degrades and metric fidelity is lost (Section 5). Photorealism could mask this failure to a considerable extent: a rendering may look correct although the underlying geometry has drifted. Recommendation: neural-rendering results intended for mapping should report metric accuracy against surveyed ground truth—not only image-space quality metrics such as PSNR/SSIM—and should state explicitly whether evaluation views lie inside the training trajectory’s coverage.
7.0.0.10. P5 — The static-world assumption
Both NeRF and 3DGS natively assume a static scene; operational MMS acquisition violates this continuously (moving vehicles, pedestrians, vegetation, illumination change), producing ghosting, floaters, and baked shadows that corrupt downstream analysis (Section 5). Benchmark scenes systematically under-represent these conditions. Forest acquisition is the limiting case and is worth stating separately: wind-driven foliage moves continuously and at every scale during a survey, so there is no interval over which the scene is static, and the moving structure is not a sparse set of removable objects—as vehicles and pedestrians are in a street scene—but the majority of the returns. A representation that assumes stationarity cannot be repaired by filtering here, because filtering the non-stationary content would remove the canopy itself. Recommendation: treat dynamic-scene robustness as a first-class evaluation axis; report performance on sequences with documented dynamic content—including wind conditions for forest acquisitions—rather than curated static captures.
7.0.0.11. P6 — Empirical accuracy mistaken for metric assurance
Learned SLAM systems now approach—and in some cases surpass—the accuracy of optimization-based pipelines on benchmark trajectories (Section 3), and this is often interpreted as equivalence. This interpretation is problematic: BA provides an auditable optimality criterion, whereas learned attention provides empirical accuracy without such a guarantee, and safety-critical applications such as infrastructure inspection require the guarantee. Recommendation: distinguish claims of accuracy from claims of assurance; hybrid systems that retain an optimization-based verification layer should be preferred where liability attaches to the map.
7.0.0.12. P7 — Ungrounded reasoning
Agentic geospatial systems parse language fluently and reason at regional scale, but lack a mechanism binding linguistic concepts to centimeter-scale geometry; the result is spatial hallucination—plausible but false topography, ghost features, and mislocalized assessments (Section 6). Recommendation: agentic outputs that feed maps or decisions should pass through a geometric verification step against raw sensor evidence, and hallucination rates should be quantified and reported per task rather than anecdotally.
7.1. Cross-Paradigm Evidence: A Quantitative Meta-Comparison
To contextualize the operational boundaries of the surveyed paradigms, Table 6 presents a synthesis of reported technical metrics across geometry-grounded SLAM, 3D perception, radiance-field reconstruction, and geospatial foundation models. One caveat governs how it must be read, and it is P1 applied to this review itself. Every figure in the table is drawn from a different evaluation: different datasets, hardware, precisions, and measurement protocols. They are therefore not mutually commensurable, and no cell may be compared with a cell in another row as though both had been measured under one protocol. The table is included precisely because that is the state of the evidence: it is an exhibit of P1, not an exception to it, and it is offered to expose cross-paradigm trade-offs rather than to rank individual systems. Where a figure can be replaced by a controlled measurement, the appendices do so, and those values are marked in the table.
Read with that caveat, the table nevertheless reveals a consistent tension that does not depend on the precision of any single cell: the paradigms that excel in metric fidelity and edge operation sit at the opposite end of the generalization axis from the cloud-scale foundation models that excel at transfer but cannot meet edge latency and memory budgets. That trade-off is structural, and it is the reason the bottlenecks of Section 9 are representational rather than a matter of further scaling.
8. Discussion: System-Level Implications
The transition from sensor-centric mobile mapping to intelligence-driven geospatial systems represents a structural shift rather than an incremental technological upgrade. As demonstrated throughout this review, advances in transformer-based 3D perception, neural rendering, and Earth-scale foundation models are converging toward unified pipelines capable of perception, reasoning, and decision support. However, this convergence exposes several systemic bottlenecks that will shape the next decade of research and deployment.
8.1. Computational Scalability and Edge–Cloud Partitioning
Despite substantial efficiency gains achieved by architectures such as PTv3, SAT-Former, LitePT, and 3DGS, computational scalability remains the dominant constraint in real-world mobile mapping systems. Transformer-based models continue to exhibit unfavorable memory scaling with scene size, while radiance-field pipelines impose heavy optimization and storage demands. These limitations are particularly acute in edge deployments, where mobile GPUs and embedded accelerators operate under strict power, memory, and thermal budgets.
A key research direction lies in principled edge–cloud partitioning. Rather than treating edge and cloud computation as separate stages, future MMS architectures are likely to adopt adaptive execution strategies in which perception, compression, and reasoning are dynamically distributed based on bandwidth availability, latency constraints, and privacy requirements. Lightweight transformers and incremental neural rendering models can operate on-device to provide immediate situational awareness, while cloud-based foundation models perform global reasoning, long-term change analysis, and cross-region knowledge integration.
8.2. Representation Convergence and System Integration
Another emerging theme is the convergence of geometric, semantic, and radiometric representations. Classical MMS pipelines maintained strict separation between mapping, segmentation, and visualization. In contrast, modern systems increasingly rely on shared latent representations that simultaneously support localization, semantic understanding, and photorealistic rendering. Explicit radiance representations such as 3DGS further blur the boundary between analysis and visualization, enabling digital twins that are both navigable and queryable.
This convergence raises important system-design questions. Unified representations reduce redundancy and improve consistency but increase coupling between components, potentially amplifying error propagation. Robust MMS architectures must therefore incorporate uncertainty modeling, modular abstraction layers, and fail-safe degradation modes to ensure reliability in safety-critical applications such as autonomous navigation and infrastructure inspection.
8.3. Data Governance, Privacy, and Ethical Constraints
As mobile mapping systems achieve unprecedented spatial resolution and coverage, ethical and regulatory considerations become inseparable from technical design. Pervasive 3D capture risks exposing sensitive infrastructure, private property, and human activity patterns. These concerns are amplified when MMS outputs are integrated into large-scale foundation models capable of cross-referencing heterogeneous data sources.
Future research must prioritize privacy-aware mapping techniques, including on-device anonymization, semantic redaction, formal differential privacy [42], and access-controlled digital twins. In parallel, standardized governance frameworks are needed to regulate data ownership, retention, and downstream usage. Without such safeguards, the societal costs of large-scale geospatial intelligence may outweigh its operational benefits.
8.4. Two System-Level Challenges Outside the Research Agenda
The three fractures analyzed in Section 9 and the five research problems derived from them in Section 10 account for most of what currently blocks deployment, and they are not restated here. Two further challenges are worth naming separately, because they are properties of the operating system rather than of any representation, and so admit no architectural fix.
The first is continuous training. Every architecture surveyed in this review is trained offline on a fixed corpus and then deployed frozen, whereas an operational MMS fleet generates a non-stationary stream in which the scene, the sensor configuration, and the class distribution all drift between campaigns. Enabling near-real-time training or adaptation on that stream—without catastrophic forgetting of earlier surveys, and under the edge budgets discussed above—is unaddressed by any of the four trends. The second is auditability. Section 10 proposes neuro-symbolic grounding as a technical route to verifiable agent reasoning, but interpretability for a human operator is a stronger requirement than a verifiable symbolic index: a municipality acting on an automated structural-risk assessment needs to know why the assessment was made, not only that it can be traced to geometry. Progress on either challenge will require closer collaboration between the computer vision, robotics, remote sensing, and geospatial analytics communities than any single one of them currently sustains.
9. Convergence Bottlenecks: A Systemic Gap Analysis
The four-tier architecture of Figure 1 maps an idealized data flow from edge to cloud; however, deep structural fractures exist between these layers that inhibit deployment in production-grade geospatial workflows. Figure 4 locates the three most consequential of these fractures.
9.0.0.13. The metric–semantic mismatch (Tier 1 → Tier 2)
Classical mobile mapping platforms offer strict metric assurances derived from raw LiDAR returns and rigorous photogrammetric BA, whereas deep transformer architectures operate on quantized semantic tokens. There is currently no widely adopted formulation that enforces hard geometric or physical constraints—such as topological continuity or multi-view consistency—directly inside the self-attention matrices of 3D point cloud transformers. Consequently, a model can attain a high overall mIoU while emitting geometrically impossible object boundaries that invalidate downstream asset inspection.
9.0.0.14. The latent representation gap (Tier 2 → Tier 3)
A fundamental mismatch separates the spatial abstractions used for real-time tracking from those used for high-fidelity rendering. Edge SLAM engines output sparse, decoupled feature points or coordinate maps, whereas Tier-3 synthesis layers require continuous volumetric fields (NeRF) or anisotropic primitives (3DGS). Because these representations do not share a common latent space, streaming raw data from the edge incurs heavy bandwidth cost; the community currently lacks a standardized “geospatial tokenizer” capable of compressing geometry, appearance, and semantics jointly into streamable bitstreams.
9.0.0.15. The grounding gap (Tier 3 → Tier 4)
Large language model agents and Earth foundation models demonstrate strong macroscopic cross-modal reasoning but lack microscopic spatial awareness. When an EFM processes a high-level request (e.g., “assess structural vulnerabilities along the light-rail corridor”), it cannot map linguistic concepts directly to the centimeter-level geometry of a Gaussian splat or coordinate submap without severe spatial hallucination. The grounding gap is the absence of a unified, differentiable coordinate registry binding high-level semantics to fine-scale physical topology.
These three fractures are architectural rather than incidental, and they are compounded by a component-level constraint: the individual building blocks of the pipeline are not equally ready for the edge. Table 7 summarizes, for each major component, the dominant cost, the current state of edge readiness, and the specific bottleneck that limits it. Read together with the three gaps above, the pattern is that the components that are most nearly edge-ready are precisely those that carry the weakest metric or semantic guarantees, so that partitioning decisions cannot be made on compute grounds alone—a point developed further in Section 8.1 and taken up as an agenda item in Section 10.
10. A Research Agenda
The pitfalls of Section 7 and the bottlenecks of Section 9 could be translated into a concrete research agenda. In this section, the agenda is formulated as five research problems, and each problem is paired with the evidence that a credible solution must exhibit; Table 8 summarizes the mapping from gap to problem to success criterion. The first three problems directly address the convergence bottlenecks, while the remaining two concern the evaluation practices of the field, without which progress on the first three could not be measured credibly.
10.0.0.16. Physics-infused self-attention for 3D transformers
Future point-cloud segmentation architectures should move beyond purely unconstrained, data-driven learning toward physics-infused attention. Where standard scaled dot-product attention computes from appearance-derived similarity alone, the proposal is to condition that similarity on geometry explicitly,
where G is a structural-consistency matrix whose entry encodes a photogrammetric invariant relating points i and j—an epipolar or surface-normal compatibility, or a local geometric distance—and sets how strongly that prior is enforced. Written additively in the logits, G acts as a multiplicative prior on the attention distribution, so a pair of points that is geometrically incompatible is suppressed before the softmax normalizes rather than being left for the network to unlearn from data. The recoverable special case is ordinary attention, which makes the constraint auditable: a claim that the prior is doing work is testable by sweeping . Injecting classical photogrammetric invariants into the backbone in this form could enforce metric integrity at object boundaries and suppress the semantic confusion that arises in high-density urban corridors.
10.0.0.17. Standardized omni-modal spatial tokenization
To make edge-to-cloud workflows operational under realistic bandwidth, the community needs an open, hierarchical neural geospatial tokenizer. Analogous to how vector-quantized variational autoencoders compress images into discrete tokens, a 3D spatiotemporal tokenizer would compress raw multi-sensor input at the edge into low-bandwidth semantic–radiometric primitives, allowing cloud instances to incrementally reconstruct both photorealistic digital twins (3DGS) and structured vector maps without transferring raw point clouds.
10.0.0.18. Neuro-symbolic spatial grounding fields for agentic GIS
Bridging reasoning and physical reality calls for neuro-symbolic radiance fields, in which Gaussian primitives or implicit hash-grid cells carry an explicit symbolic index channel linked to a standardized geospatial knowledge graph (e.g., CityGML or OpenStreetMap ontologies). An agent tasked with change detection would then query the symbolic channel embedded within the radiance field, anchoring every reasoning step to verified 3D coordinates and eliminating geometric hallucination.
10.0.0.19. A standardized MMS efficiency and reporting protocol
Pitfalls P1 and P2 persist because no community protocol constrains how efficiency is measured and reported for 3D perception under mobile-mapping conditions. What is needed is the MMS analog of MLPerf: a small set of fixed hardware classes (edge accelerator, laptop GPU, server GPU), fixed precisions and input regimes (point counts spanning –), and mandatory reporting of latency, throughput, peak activation memory, and energy alongside accuracy. The two controlled benchmarks in sec:efficiency and sec:pcbench are deliberately small-scale demonstrations that such measurements are cheap to produce and materially change conclusions; sec:pcbench in particular already implements the input-regime sweep proposed here, on two acquisition modalities, and shows both that the published ratios move substantially under a fixed protocol and that the point at which each backbone ceases to run at all—the quantity that actually governs tile budgeting—is absent from the literature entirely. Scaling this into a community standard is an organizational rather than technical challenge, and one to which benchmark-hosting bodies such as ISPRS are well suited.
10.0.0.20. Cross-domain generalization studies on mobile-mapping data
Pitfall P3 will not be retired by argument but by measurement: same-protocol training and evaluation of the leading architecture families across LiDAR, terrestrial MMS, and photogrammetric benchmarks, reporting zero-shot transfer and label-efficiency curves in addition to fine-tuned accuracy, and including the dynamic-scene and degraded-input conditions of P4 and P5. Such a study should span the urban–forest contrast deliberately rather than sampling within one of them, because that pairing varies every property a tokenization scheme is sensitive to at once—density uniformity, object thinness and mutual occlusion, instance count per scene, and whether the decisive class distinction is local or contextual. A backbone that holds its ranking from SensatUrban to FOR-instance has demonstrated something that no amount of within-domain benchmarking can establish; one that does not has located exactly where the token-economy argument stops being general. Until such studies exist, every deployment decision in mobile mapping extrapolates from benchmarks whose relevance to the target data is assumed rather than demonstrated.
11. Conclusion
In this review, the convergence of deep transformers, radiance-field reconstruction, and foundation models on mobile mapping was analyzed rather than merely enumerated. Three main conclusions could be drawn from the analysis. First, the trajectory of the field is explained by four structural trends—from optimized to learned geometry, tokenization economics as the governing principle of 3D perception, the migration of rendering from visualization to measurement, and the transition from perception to agency—and each trend is currently further along in capability than in assurance: modern systems approach classical accuracy without providing classical guarantees. Second, the apparent pace of progress is inflated by seven recurring pitfalls—efficiency claims that are not mutually comparable, the use of parameter count as an efficiency metric, unverified benchmark transfer, scene-overfitted rendering, the static-world assumption, empirical accuracy mistaken for metric assurance, and ungrounded reasoning—and the common root of these pitfalls lies in evaluation practice rather than in architecture; the two controlled benchmarks reported in sec:efficiency and sec:pcbench demonstrate that the efficiency-related distortions could be corrected at a modest cost. Third, the gap that separates the impressive individual components of today from deployable geospatial intelligence is caused not by model capability but by three representational fractures—the metric–semantic mismatch, the latent representation gap, and the grounding gap—and each fracture admits a concrete research program (Section 10). A fourth conclusion follows from reading the three above against the two environments in which mobile mapping is most heavily deployed. The urban corridor and the forest plot stress the same pipeline along different axes—the first with intermittent satellite visibility and planar, high-return surfaces, the second with total canopy denial and thin, self-similar, wind-perturbed geometry—and the surveyed advances are demonstrated almost exclusively on the former. Where the contrast has been examined, it sharpens rather than softens the pitfalls: the metric burden that Trend 1 shifts onto learned geometry is unbounded under canopy, where no external frame remains to detect drift; the benchmark-transfer assumption of P3 spans a gap in forests that no reported study has yet measured; and the static-world assumption of P5 fails there not occasionally but continuously. Environmental applications are consequently not a downstream special case of urban mobile mapping but its most demanding test, and the trends analyzed here should be read as provisional until that test is run.
For the photogrammetry and remote sensing communities, the opportunity is considerable. The disciplines that maintain metric rigor, BA, and survey-grade evaluation are well positioned to supply what the learning-driven literature currently lacks. If the agenda outlined in this review is pursued—physics-infused attention, standardized spatial tokenization, neuro-symbolic grounding, and community benchmarking protocols—mobile mapping systems could become an essential connective layer that binds centimeter-scale ground truth to Earth-scale observation and reasoning.
Author Contributions
Conceptualization, E.K.; methodology, E.K.; software, E.K.; validation, E.K.; formal analysis, E.K.; investigation, E.K.; data curation, E.K.; writing—original draft preparation, E.K.; writing—review and editing, E.K.; visualization, E.K. The author has read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
The benchmark code, raw measurements, and figure-generation scripts that support the appendices are available from the author on reasonable request. All other data discussed in this review are from the cited publications and their public benchmark releases.
Acknowledgments
This research was supported by the Department of Geographical and Historical Studies at the University of Eastern Finland.
Conflicts of Interest
The author declares no conflicts of interest.
Abbreviations
The following abbreviations are used in this manuscript:
| 3DGS | 3D Gaussian Splatting |
| EFM | Earth Foundation Model |
| GNSS | Global Navigation Satellite System |
| IMU | Inertial Measurement Unit |
| LiDAR | Light Detection and Ranging |
| MLS | Mobile Laser Scanning |
| MMS | Mobile Mapping System |
| NeRF | Neural Radiance Field |
| PTv3 | Point Transformer V3 |
| SLAM | Simultaneous Localization and Mapping |
| VGGT | Visual Geometry Grounded Transformer |
Appendix A. A Controlled Efficiency Benchmark Supporting Pitfalls P1–P2
This appendix reports the controlled measurement study referenced by Pitfalls P1 and P2 (Section 7) and by the standardized-protocol agenda item (Section 10). It is included as an appendix deliberately: its role is evidentiary—demonstrating that same-hardware measurement is inexpensive and materially changes conclusions—rather than a primary contribution of the review.
The efficiency figures reported across the surveyed literature—“ faster,” “up to faster inference,” “ fewer parameters” (Table 2)—originate from heterogeneous hardware, input modalities, and measurement protocols, which makes direct comparison difficult and obscures why one architecture is more deployable than another. To provide a controlled, reproducible counterpart to these second-hand numbers, this section reports a same-hardware benchmark of six representative semantic segmentation architectures spanning the design spectrum discussed in Section 4.6: classical convolutional encoder–decoders (UNet), densely connected variants (UNet++), attention-gated convolutional networks (Attention-UNet), multi-scale and atrous backbones built on ResNet-50 (FPN, DeepLabV3+), and a hybrid CNN–Transformer (TransUNet). The benchmark is deliberately run on an edge-class laptop GPU, mirroring the on-device deployment scenario that motivates the edge–cloud partitioning argument of Section 8.1.
We use an operational aerial-imagery segmentation configuration as the measurement substrate: per-pixel classification of six-band multispectral tiles into three classes, a representative ground/airborne mapping workload. We emphasize that this is a two-dimensional dense-image proxy rather than the sparse point-cloud setting of PTv3, SAT-Former, or LitePT; absolute throughput will not transfer to those models. The value of the analysis lies in the architecture-general efficiency principles it isolates—the cost of dense feature reuse, the effect of where attention is applied, and the weak coupling between parameter count and runtime cost—which provide controlled, measured support for the qualitative claims made throughout Section 4.2, Section 4.3 and Section 4.4 and for the hybrid-architecture synthesis advanced in Section 4.6.
Appendix A.1. Experimental Setup
All measurements were obtained on a single NVIDIA RTX 500 Ada Generation Laptop GPU (4 GB VRAM) using PyTorch 2.10 / CUDA 12.8, with single-precision (float32) weights and inputs of for classes. The six architectures were instantiated directly from this project’s training code so that the benchmark reflects the exact networks used in practice (the GroupNorm “robust” UNet, UNet++, and DeepLabV3+ variants, the ResNet-50 FPN, the attention-gated UNet, and the ResNet-50/two-block-Transformer TransUNet).
For each model we report: (i) trainable parameters; (ii) forward floating-point operations for a single tile, counted with PyTorch’s FlopCounterMode (multiply–accumulate convention); (iii) GPU inference latency and throughput at batch sizes 1 and 8, measured over 50 timed iterations after 10 warm-up iterations with explicit CUDA synchronization; (iv) GPU peak activation memory at batch 1 via max_memory_allocated; and (v) CPU latency at batch 1. The complete procedure, raw measurements, and figure-generation code are released as efficiency_benchmark.py, make_efficiency_figures.py, and efficiency_results.csv for exact reproducibility.
Appendix A.2. Results
Table A1 reports the complete measurements, and Figure A1 and Figure A2 visualize the computational profile and the throughput–compute trade-off. Three robust patterns emerge.

Table A1.
Controlled efficiency benchmark of six segmentation architectures on a single edge-class GPU (NVIDIA RTX 500 Ada, 4 GB), inputs, . Latency and throughput are measured over 50 timed iterations after warm-up; peak memory and FLOPs are at batch 1. Best value per column in bold.
Table A1.
Controlled efficiency benchmark of six segmentation architectures on a single edge-class GPU (NVIDIA RTX 500 Ada, 4 GB), inputs, . Latency and throughput are measured over 50 timed iterations after warm-up; peak memory and FLOPs are at batch 1. Best value per column in bold.
| Model | Family | Params | FLOPs | GPU lat. | GPU thr. | GPU thr. | Peak mem | CPU lat. |
|---|---|---|---|---|---|---|---|---|
| (M) | (G) | bs1 (ms) | bs1 (fps) | bs8 (fps) | bs1 (MB) | bs1 (ms) | ||
| FPN | CNN pyramid (R50) | 26.9 | 16.9 | 6.21 | 161.1 | 165.6 | 190.0 | 88.4 |
| TransUNet | Hybrid CNN–Transformer | 52.3 | 37.4 | 11.57 | 86.4 | 116.6 | 288.5 | 257.7 |
| DeepLabV3+ | CNN atrous (R50) | 39.8 | 91.5 | 16.07 | 62.2 | 55.1 | 230.3 | 575.7 |
| UNet | CNN encoder–decoder | 31.0 | 96.6 | 19.55 | 51.2 | 48.0 | 247.1 | 276.9 |
| Attention-UNet | CNN + attention gates | 31.4 | 98.7 | 21.34 | 46.9 | 42.7 | 263.4 | 296.6 |
| UNet++ | CNN dense skip | 36.6 | 275.9 | 55.05 | 18.2 | 17.7 | 399.6 | 695.5 |
Figure A1.
Computational profile of the six segmentation architectures on an edge-class GPU: trainable parameters, forward compute (GFLOPs per tile), GPU inference latency (ms, batch 1), and GPU peak activation memory (MB, batch 1). Architectures are ordered by latency. Parameter count is a poor predictor of runtime cost: the densely connected UNet++ has fewer parameters than DeepLabV3+ or TransUNet yet incurs the highest compute, latency, and memory.
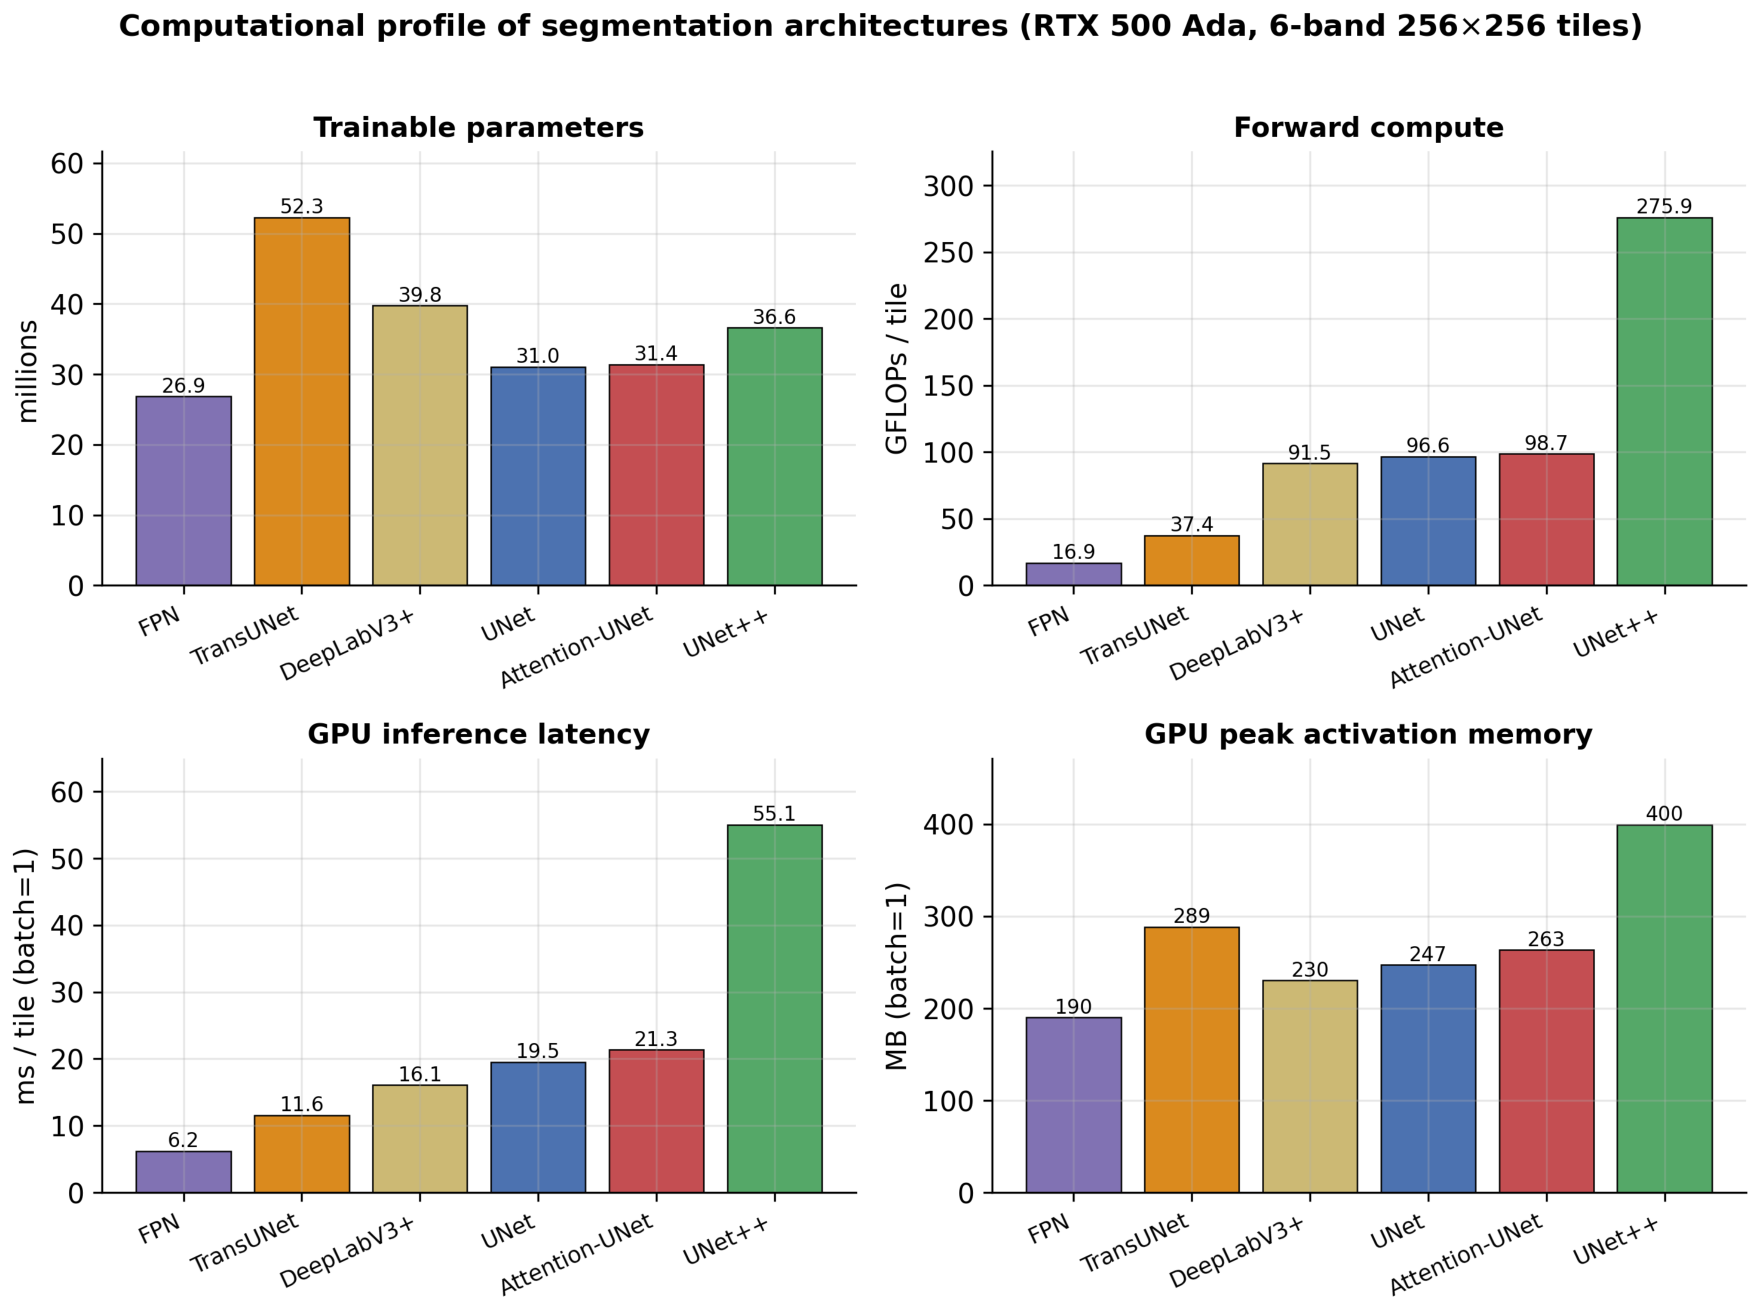
Figure A2.
Efficiency landscape: GPU throughput (frames , batch 1) versus forward compute per tile, with bubble area proportional to trainable parameters. Efficient designs occupy the upper-left region. FPN and the hybrid TransUNet form the practical efficiency frontier, whereas the densely connected UNet++ is isolated in the high-compute, low-throughput corner despite a moderate parameter budget.
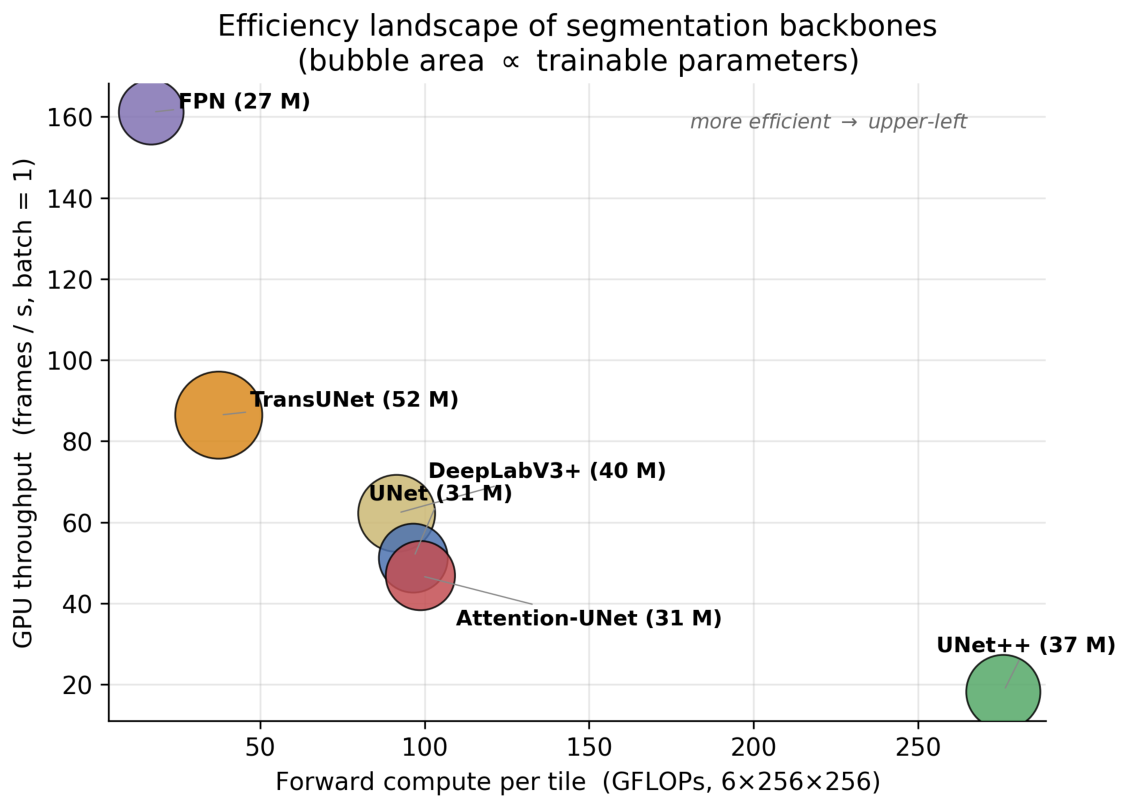
Dense feature reuse is the dominant cost driver
UNet++, whose nested dense skip pathways recompute and concatenate features at every decoder stage, requires GFLOPs per tile— that of FPN and that of DeepLabV3+—translating into the highest latency ( ms, slower than FPN) and the largest activation footprint ( MB). Critically, UNet++ achieves this not through a larger parameter count (at M it is lighter than DeepLabV3+ and TransUNet) but through denser computation per parameter. This is a direct empirical analog of the central argument advanced for SAT-Former and LitePT in Section 4.2: that information density, rather than raw representational density, governs efficiency, and that pruning or aggregating redundant computation—rather than reducing model size—is the effective lever for edge deployment.
Where attention is applied determines its cost
TransUNet carries the largest parameter budget ( M, owing to its ResNet-50 encoder and Transformer blocks) yet requires only GFLOPs and sustains fps—second only to FPN. The reason is structural: its self-attention operates on the feature grid produced after full encoder downsampling, so the quadratic term in attention acts on only 64 tokens. This concretely illustrates the scaling principle emphasized for PTv3 (Section 4.1) and the quadratic-memory caveat of Section 4.4: transformer cost is governed by token count and the resolution at which attention is evaluated, not by the mere presence of attention. The same model also shows the largest batching gain (throughput rising from to fps from batch 1 to 8), consistent with attention’s higher arithmetic intensity and better GPU utilization under batching, and it empirically substantiates the “efficiency of CNNs for seeing, power of Transformers for understanding” hybrid synthesis of Section 4.6.
Parameters are a weak proxy for deployability
Across the six models, parameter count correlates poorly with latency and memory (Figure A1): the M TransUNet is faster than the M UNet++. Forward FLOPs and peak activation memory are substantially better predictors of edge cost. This finding cautions against the common practice—visible in the surveyed efficiency claims of Table 2—of headlining parameter-count reductions (e.g., “ fewer parameters”) as a primary efficiency metric, and argues for reporting compute and activation memory alongside parameters, consistent with the standardized benchmarking direction identified in Section 4.5.
Appendix A.3. Implications for Edge Deployment
The measurements quantify the edge-readiness ratings asserted qualitatively in Table 7. Against the sub-100 ms real-time target stated in Section 4.4, all six architectures meet the threshold at batch 1 on this 4 GB GPU, but with a spread in latency (– ms for five models, rising to ms for UNet++) and a spread in activation memory (190–400 MB). The memory headroom indicates that, for tiles, the binding constraint on this class of accelerator is throughput rather than capacity. The CPU results tell a sharper story: only FPN approaches interactive rates without a GPU (88 ms, fps), while atrous and dense designs degrade severely on CPU (576 ms for DeepLabV3+, 695 ms for UNet++), underscoring why the lightweight transformers surveyed in Section 4.2 and the edge–cloud partitioning strategy of Section 8.1 are necessary rather than merely desirable for genuinely accelerator-constrained platforms.
Appendix A.4. Scope and Relation to Point-Cloud Transformers
Two limitations bound the interpretation of these results. First, the benchmark uses dense two-dimensional imagery; the absolute latency, FLOPs, and memory of sparse point-cloud transformers such as PTv3 and SAT-Former depend on serialization, neighborhood construction, and point density, and will differ in magnitude. Second, accuracy is held outside the scope of this efficiency study, and the reader should not infer an accuracy ordering from a cost ordering. Only one of the six configurations was additionally evaluated for accuracy on this task: UNet++, the most expensive model in the table, attains a mean IoU of and an F1 of under ten-fold cross-validation on the same six-band aerial data. That single measurement is consistent with a genuine efficiency–accuracy trade-off rather than a free lunch, but one point cannot establish the shape of the trade-off curve, and no claim about the relative accuracy of the other five architectures is made or implied here. Establishing that curve would require evaluating all six under one training protocol, which is a distinct study from the one reported. Notwithstanding these bounds, the three principles isolated here—dense computation as the primary cost driver, the decisive role of attention placement and token count, and the unreliability of parameter count as an efficiency proxy—are architecture-general. They provide controlled, reproducible empirical support for the otherwise qualitative efficiency and deployment arguments that run through this review, and they reinforce its core recommendation: that progress toward deployable geospatial intelligence will be driven by computational and information density management, not by model scale alone.
Appendix B. A Controlled Same-Hardware Benchmark of Point-Cloud Backbones
The benchmark in sec:efficiency fixes the measurement protocol for two-dimensional segmentation backbones on an edge device. It does not, however, speak to the question that governs the tokenization argument of Section 4: how the cost of a point-cloud backbone grows with the size of the tile it is asked to ingest, and where that growth stops. That question cannot be answered from the literature, because the published figures are measured at different point counts, on different hardware, at different precisions, and after different amounts of subsampling. This appendix answers it by measurement instead.
Four backbones spanning the design spectrum of Section 4.6 are profiled on identical inputs on one GPU: a sparse-convolution U-Net (SpUNet) [21,61] as the non-attentional baseline, grouped vector attention (PTv2) [17], space-filling-curve serialization (PTv3) [6], and a convolution-then-attention hybrid (LitePT) [24]. As in sec:efficiency, only efficiency is measured; no training is performed and no accuracy is claimed, so nothing reported here may be read as a quality ranking.
Appendix B.1. Experimental Setup
Hardware and software. All measurements were taken on a single NVIDIA GeForce RTX 5090 Laptop GPU (24 GB, Blackwell, sm_120) at float32, using PyTorch 2.7.0+cu128 [99] with CUDA 12.8, driver 595.84, spconv-cu126 2.3.8, and model implementations resolved from a pinned Pointcept commit [100]. Latency is the median of 20 timed iterations after five warm-up iterations; board power is sampled from nvidia-smi and integrated per forward pass; peak activation memory is the max_memory_allocated delta, which excludes weights. Each measurement runs in its own subprocess, so no allocator state is inherited from a previous model. The random seed is fixed at 0 and the voxelization grid at 0.05 m.
Data and input regimes. Two datasets are used, one from each of the acquisition modalities that concern mobile mapping: Paris-Lille-3D, acquired by mobile laser scanning [39], and SensatUrban, acquired by UAV photogrammetry [41]. Measurements are taken on two Paris-Lille-3D clouds (Lille1_1, Paris) and three SensatUrban tiles (birmingham_block_1, birmingham_block_3, cambridge_block_2); each tabulated value is the median over the clouds of its dataset. Six input regimes are requested, from to points.
Three protocol choices materially affect how the numbers should be read, and are stated explicitly because leaving them implicit is itself a form of Pitfall P1. First, each input regime is a spatially contiguous crop—the smallest horizontal neighborhood around a fixed seed point containing the requested number of points—and not a random subsample. Random subsampling thins local density and would systematically flatter the serialization, voxelization, and neighborhood-construction costs that this benchmark exists to measure, which is precisely the token-economy overhead analyzed in Section 4. Second, every backbone at a given regime receives the same points and is fitted with the same linear classification head, so no model is charged for a decoder the others lack. Third, the FLOP counts are dispatcher-level and cannot see custom CUDA kernels: spconv’s gather–GEMM–scatter and torch_scatter segment operations are invisible to the counter. Affected values are marked as lower bounds in Table A2 rather than being allowed to pass silently, and FLOPs should be compared only within a coverage class.
Appendix B.2. Parameter Count Does Not Predict Cost
Table A2 reports the full cost profile of the four backbones at a common operating point of one million points, and Figure A3 plots the two quantities that are most often conflated. The result is unambiguous and is the point-cloud counterpart of the P2 evidence in sec:efficiency: on Paris-Lille-3D at points, PTv2 has fewer parameters than PTv3, yet is slower, requires more activation memory, and consumes more energy per forward pass. LitePT, the smallest model after PTv2, is simultaneously the fastest and the most memory-frugal. Over the four backbones the Spearman rank correlation between parameter count and latency is : in this sample, parameter count does not merely fail to predict latency, it orders it very slightly the wrong way.
The mechanism is the one identified in Section 4. PTv2 spends its budget on grouped vector attention within neighborhoods that must be constructed explicitly, so its cost is set by the number of query–neighbor pairs rather than by its weight count; PTv3 replaces that construction with a serialization that is nearly free, and pays for a larger weight matrix instead. Parameters are a storage quantity. Latency, activation memory, and energy are governed by how many tokens the architecture forms and how it gathers them—which is exactly why a parameter reduction cannot be reported as a speed claim.
Table A2.
Controlled same-hardware cost profile of four point-cloud backbones at a common operating point of points on Paris-Lille-3D. All models are measured on one 24 GB GPU at float32 on identical contiguous crops; each value is the median over the two clouds of the dataset. Values marked † exclude custom CUDA kernels and are therefore lower bounds. Rows are ordered by latency. Parameter count neither predicts nor even orders the deployment costs: the smallest model (PTv2) is the most expensive on every other column, and the largest (PTv3) is cheaper on every axis than the smallest.
| Model | Family | Params | FLOPs | Latency | Peak act. | Energy |
|---|---|---|---|---|---|---|
| (M) | (G) | (ms) | (MB) | (J) | ||
| LitePT | Hybrid convolution/attention | 12.7 | 180. | 129.5 | 2118 | 14.0 |
| SpUNet | Sparse convolution U-Net | 39.2 | 34. | 187.1 | 3020 | 19.9 |
| PTv3 | Serialized transformer | 46.2 | 654. | 407.6 | 4111 | 44.1 |
| PTv2 | Grouped vector attention | 11.3 | 2416.1 | 6564.8 | 19646 | 690.9 |
Figure A3.
Trainable parameters against median forward latency at points, pooled over both datasets. If parameter count were an efficiency proxy, the points would trend upward; instead the smallest model is an order of magnitude the slowest, and the two largest are among the three fastest. This is the point-cloud form of Pitfall P2. The annotated is the ratio pooled over both datasets; Table A2 gives on Paris-Lille-3D alone.
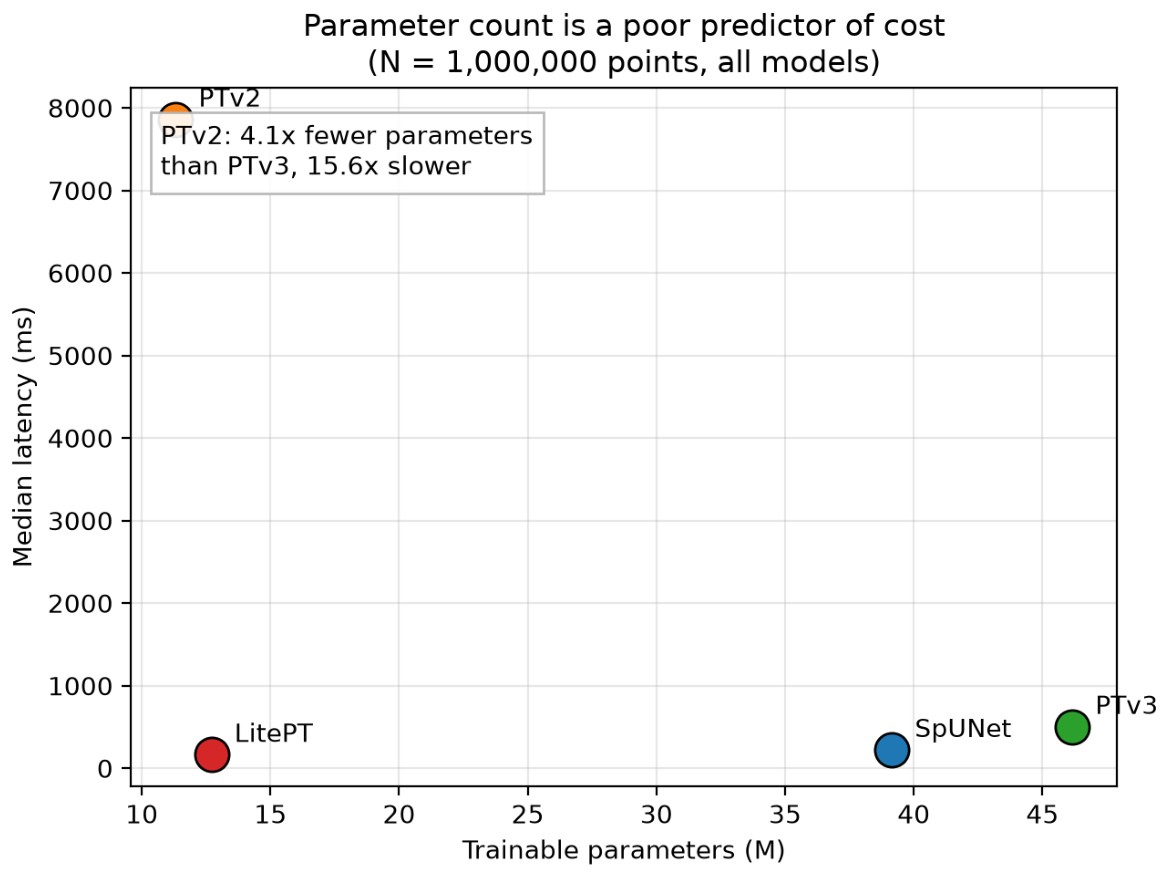
Appendix B.3. Where the Backbones Stop
Table A3 and Figure A4 report how cost grows with tile size, and—more consequentially for deployment—at what tile size each backbone ceases to run at all. Within the regimes that complete, latency and activation memory are close to linear in the number of input points for all four backbones, so throughput is roughly flat: the serialized and hybrid designs do not merely start cheaper than grouped vector attention, they retain a near-constant cost per point over one and a half orders of magnitude. PTv2 is the exception in level rather than in slope; it is between and slower than the hybrid at every regime it survives.
The ceilings are where the practical argument of Section 4 is settled. On a 24 GB device, grouped vector attention (PTv2) exhausts memory at a three-million-point crop of Paris-Lille-3D and already at one million points on two of the three SensatUrban tiles; PTv3 completes three million and exhausts memory at five; LitePT reaches five million; and no backbone tested—including the sparse-convolution baseline, whose memory growth is the most predictable of the four—completes a ten-million-point crop. Since a single birmingham_block_1 tile holds roughly 59 million points [41] and the full SensatUrban release approaches three billion, tiling is not an implementation detail that a larger GPU will retire. It is a structural property of the current architecture space, and the quantity that distinguishes these backbones operationally is how large a tile each admits, because tile size determines how much spatial context one inference sees and how many boundary artifacts must afterwards be reconciled.
The two ceilings have different causes, and conflating them would itself be a P1 error. The PTv2 and PTv3 failures are clean out-of-memory conditions: the allocator reports exhaustion of the 24 GB device, and a larger device would move the ceiling. The failures at five million points for SpUNet and at ten million for all four backbones are not. SpUNet fails inside an spconv size assertion on the product of point count and channel width, and every backbone fails at ten million points with an illegal memory access raised asynchronously inside a custom CUDA kernel—a signature consistent with 32-bit indexing overflow in hand-written kernels rather than with device capacity. The operational conclusion is unchanged, and is what the body of this review relies on: no tested backbone processes a ten-million-point neighborhood in a single forward pass on this hardware. But the cause is an implementation limit in the kernels of the current ecosystem, not a memory limit, and it must not be reported as one. Which of the two it is determines whether the remedy is a larger accelerator or a corrected kernel—and that distinction is invisible in any published figure that reports only the largest input a model was shown to handle.
Table A3.
Scaling and failure behavior across input regimes. Upper panel: median forward latency (ms). Lower panel: peak activation memory (MB). Each value is the median over the clouds of its dataset (two for Paris-Lille-3D, three for SensatUrban). oom denotes a clean exhaustion of the 24 GB device; err a fault inside a custom CUDA kernel that does not surface as a catchable out-of-memory condition—the two are distinguished deliberately, because they imply different remedies. A parenthesized value is a median over fewer clouds than the dataset contains, the remainder having failed. PL3D: Paris-Lille-3D; SU: SensatUrban.
| Input points N | |||||||
|---|---|---|---|---|---|---|---|
| Model | Data | ||||||
| Median forward latency (ms) | |||||||
| LitePT | PL3D | 23.2 | 40.2 | 129.5 | 489.2 | 795.0 | err |
| SU | 26.1 | 57.7 | 202.2 | 618.6 | 1072.2 | err | |
| SpUNet | PL3D | 23.3 | 61.9 | 187.1 | 648.6 | err | err |
| SU | 29.8 | 77.1 | 261.3 | 761.0 | err | err | |
| PTv3 | PL3D | 46.7 | 120.6 | 407.6 | 1389.0 | oom | err |
| SU | 58.3 | 171.2 | 600.2 | 1755.2 | oom | err | |
| PTv2 | PL3D | 241.9 | 1003.5 | 6564.8 | oom | oom | oom |
| SU | 460.7 | 1693.9 | (9160.4) | oom | oom | oom | |
| Peak activation memory (MB) | |||||||
| LitePT | PL3D | 221 | 640 | 2118 | 6402 | 10627 | err |
| SU | 236 | 684 | 2242 | 6700 | 11165 | err | |
| SpUNet | PL3D | 310 | 915 | 3020 | 9066 | err | err |
| SU | 316 | 931 | 3070 | 9175 | err | err | |
| PTv3 | PL3D | 421 | 1240 | 4111 | 12356 | oom | err |
| SU | 431 | 1270 | 4192 | 12551 | oom | err | |
| PTv2 | PL3D | 1972 | 5897 | 19646 | oom | oom | oom |
| SU | 2575 | 7317 | (20678) | oom | oom | oom | |
Figure A4.
Scaling of median latency (left), peak activation memory (center), and throughput (right) with input size, for Paris-Lille-3D (top row) and SensatUrban (bottom row). Latency and memory axes are logarithmic. Within the regimes that complete, all four backbones grow close to linearly in the number of points, so throughput is roughly flat and the architectures separate by a constant factor rather than by asymptotic order; grouped vector attention (PTv2) is displaced upward by more than an order of magnitude and meets the 24 GB device limit (dashed line) first. Series terminate where the backbone stops completing, and the causes of those terminations differ—see Table A3.
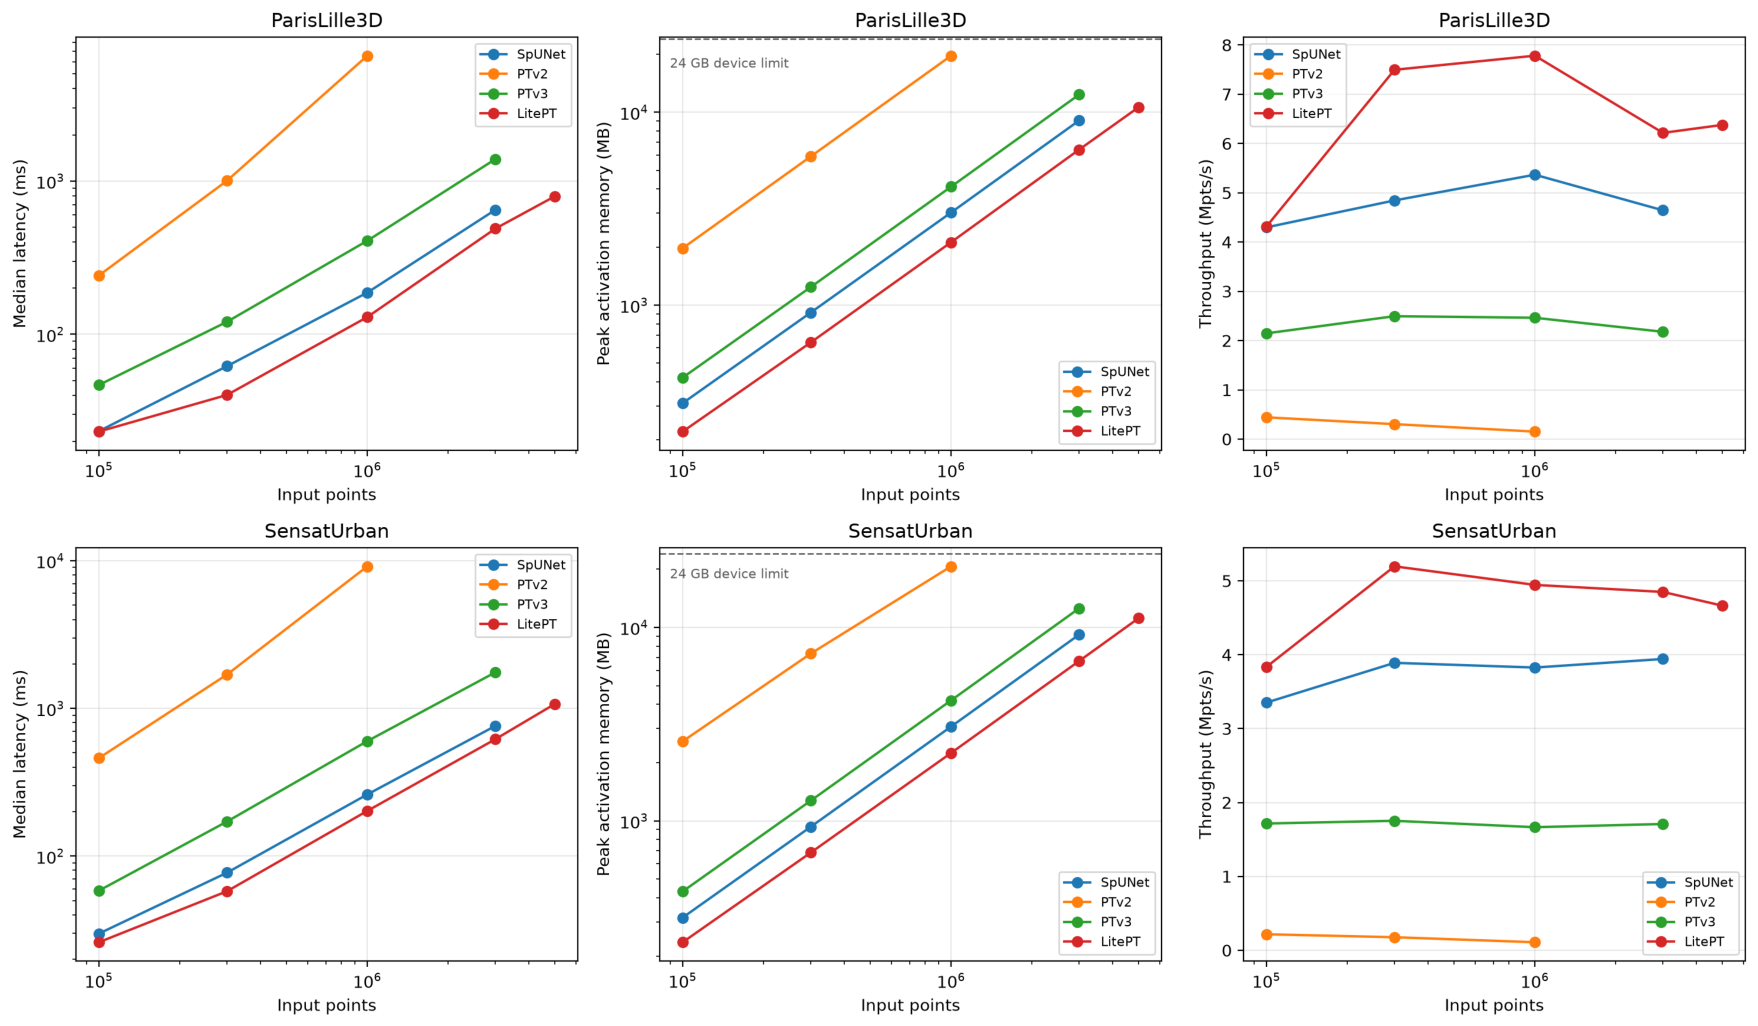
Appendix B.4. What These Measurements Do and Do Not Establish
The absolute latencies are specific to one accelerator and would change on another; the claim is not that these are the costs of these architectures in general, but that they are their costs relative to one another when hardware, precision, input, head, and protocol are held fixed. That is precisely the comparison the literature does not currently license, and it is obtainable at the cost of a single afternoon of compute—which is the argument of the standardized-protocol agenda item in Section 4.5.
Three limitations bound the reading. Accuracy is out of scope, so the efficiency ordering here carries no implication about segmentation quality and must not be used as a proxy for it. The FLOP counts of three of the four backbones are lower bounds, for the reason given in sec:pcbench-setup, and so bear less weight than the directly measured latency and memory. And the sample is four backbones on two datasets: enough to falsify parameter count as an efficiency proxy and to locate the tiling ceilings on this hardware, not enough to characterize the architecture space. Extending it is exactly the community task that Section 10 argues for.
References
- Ravi, R.; Lin, Y.J.; Elbahnasawy, M.; Shamseldin, T.; Habib, A. Simultaneous System Calibration of a Multi-LiDAR Multicamera Mobile Mapping Platform. IEEE J. Sel. Top. Appl. Earth Obs. Remote Sens. 2018, 11, 1694–1714. [Google Scholar] [CrossRef]
- Khoramshahi, E.; Nezami, S.; Pellikka, P.; Honkavaara, E.; Chen, Y.; Habib, A. A Taxonomy of Sensors, Calibration and Computational Methods, and Applications of Mobile Mapping Systems: A Comprehensive Review. Remote Sens. 2025, 17, 1502. [Google Scholar] [CrossRef]
- Elhashash, M.; Albanwan, H.; Qin, R. A Review of Mobile Mapping Systems: From Sensors to Applications. Sensors 2022, 22, 4262. [Google Scholar] [CrossRef] [PubMed]
- Vaswani, A.; Shazeer, N.; Parmar, N.; Uszkoreit, J.; Jones, L.; Gomez, A.N.; Kaiser; Polosukhin, I. Attention Is All You Need. In Proceedings of the Advances in Neural Information Processing Systems (NeurIPS), Long Beach, CA, USA, 4–9 December 2017; Vol. 30. [Google Scholar]
- Zhao, H.; Jiang, L.; Jia, J.; Torr, P.; Koltun, V. Point Transformer. In Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), Montreal, QC, Canada, 10–17 October 2021; pp. 16239–16248. [Google Scholar] [CrossRef]
- Wu, X.; Jiang, L.; Wang, P.S.; Liu, Z.; Liu, X.; Qiao, Y.; Ouyang, W.; He, T.; Zhao, H. Point Transformer V3: Simpler, Faster, Stronger. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, WA, USA, 16–22 June 2024; pp. 4840–4851. [Google Scholar] [CrossRef]
- Guo, Y.; Wang, H.; Hu, Q.; Liu, H.; Liu, L.; Bennamoun, M. Deep Learning for 3D Point Clouds: A Survey. IEEE Trans. Pattern Anal. Mach. Intell. 2021, 43, 4338–4364. [Google Scholar] [CrossRef] [PubMed]
- Xie, Y.; Tian, J.; Zhu, X.X. Linking Points With Labels in 3D: A Review of Point Cloud Semantic Segmentation. IEEE Geosci. Remote Sens. Mag. 2020, 8, 38–59. [Google Scholar] [CrossRef]
- Mildenhall, B.; Srinivasan, P.P.; Tancik, M.; Barron, J.T.; Ramamoorthi, R.; Ng, R. NeRF: Representing Scenes as Neural Radiance Fields for View Synthesis. In Proceedings of the European Conference on Computer Vision (ECCV), Glasgow, UK, 23–28 August 2020; pp. 405–421. [Google Scholar] [CrossRef]
- Tewari, A.; Thies, J.; Mildenhall, B.; Srinivasan, P.; Tretschk, E.; Yifan, W.; Lassner, C.; Sitzmann, V.; Martin-Brualla, R.; Lombardi, S.; et al. Advances in Neural Rendering. Comput. Graph. Forum 2022, 41, 703–735. [Google Scholar] [CrossRef]
- Kerbl, B.; Kopanas, G.; Leimkühler, T.; Drettakis, G. 3D Gaussian Splatting for Real-Time Radiance Field Rendering. ACM Trans. Graph. 2023, 42, 1–14. [Google Scholar] [CrossRef]
- Jakubik, J.; Roy, S.; Phillips, C.E.; Fraccaro, P.; Godwin, D.; Zadrozny, B.; Szwarcman, D.; Gomes, C.; Nyirjesy, G.; Edwards, B.; et al. Foundation Models for Generalist Geospatial Artificial Intelligence. arXiv 2023, arXiv:2310.18660. [Google Scholar] [CrossRef]
- Mendieta, M.; Han, B.; Shi, X.; Zhu, Y.; Chen, C.; Li, M. Towards Geospatial Foundation Models via Continual Pretraining. In Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), Paris, France, 1–6 October 2023; pp. 16760–16770. [Google Scholar] [CrossRef]
- Bell, A.; Aides, A.; Helmy, A.; Muslim, A.; Barzilai, A.; Slobodkin, A.; Jaber, B.; Schottlander, D.; Leifman, G.; Paul, J.; et al. Earth AI: Unlocking Geospatial Insights with Foundation Models and Cross-Modal Reasoning. arXiv 2025, arXiv:2510.18318. [Google Scholar] [CrossRef]
- Kölle, M.; Laupheimer, D.; Schmohl, S.; Haala, N.; Rothermel, M.; Tuttas, S.; Stilla, U. The Hessigheim 3D (H3D) benchmark on semantic segmentation of high-resolution 3D point clouds and textured meshes from UAV LiDAR and Multi-View-Stereo. ISPRS Open J. Photogramm. Remote Sens. 2021, 1, 100001. [Google Scholar] [CrossRef]
- Lehtola, V.V.; Koeva, M.; Oude Elberink, S.; Raposo, P.; Virtanen, J.P.; Vahdatikhaki, F.; Borsci, S. Digital twin of a city: Review of technology serving city needs. Int. J. Appl. Earth Obs. Geoinf. 2022, 114, 102915. [Google Scholar] [CrossRef]
- Wu, X.; Lao, Y.; Jiang, L.; Liu, X.; Zhao, H. Point Transformer V2: Grouped Vector Attention and Partition-Based Pooling. In Proceedings of the Advances in Neural Information Processing Systems (NeurIPS), New Orleans, Louisiana, USA, 28 November–9 December 2022; pp. 33330–33342. [Google Scholar] [CrossRef]
- Qi, C.R.; Su, H.; Mo, K.; Guibas, L.J. PointNet: Deep Learning on Point Sets for 3D Classification and Segmentation. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Honolulu, HI, USA, 21–26 July 2017; pp. 77–85. [Google Scholar] [CrossRef]
- Qi, C.R.; Yi, L.; Su, H.; Guibas, L.J. PointNet++: Deep Hierarchical Feature Learning on Point Sets in a Metric Space. In Proceedings of the Advances in Neural Information Processing Systems (NeurIPS), Long Beach, CA, USA, 4–9 December 2017. [Google Scholar]
- Thomas, H.; Qi, C.R.; Deschaud, J.E.; Marcotegui, B.; Goulette, F.; Guibas, L.J. KPConv: Flexible and Deformable Convolution for Point Clouds. In Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), Seoul, Republic of Korea, 27 October–2 November 2019; pp. 6410–6419. [Google Scholar] [CrossRef]
- Choy, C.; Gwak, J.; Savarese, S. 4D Spatio-Temporal ConvNets: Minkowski Convolutional Neural Networks. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Long Beach, CA, USA, 15–20 June 2019; pp. 3070–3079. [Google Scholar] [CrossRef]
- Bello, S.A.; Yu, S.; Wang, C.; Adam, J.M.; Li, J. Review: Deep Learning on 3D Point Clouds. Remote Sens. 2020, 12, 1729. [Google Scholar] [CrossRef]
- Wang, X.; Zhang, Y.; Shao, R.; Chen, S.; Li, H.; Chen, X. SAT-Former: An Efficient 3-D Transformer with Semantic Aggregated Point Tokenizer for Point Cloud Semantic Segmentation in Urban Scenes. IEEE J. Sel. Top. Appl. Earth Obs. Remote Sens. 2025, 18, 28326–28342. [Google Scholar] [CrossRef]
- Yue, Y.; Robert, D.; Wang, J.; Hong, S.; Wegner, J.D.; Rupprecht, C.; Schindler, K. LitePT: Lighter Yet Stronger Point Transformer. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026. [Google Scholar] [CrossRef]
- Strasdat, H.; Montiel, J.M.M.; Davison, A.J. Scale Drift-Aware Large Scale Monocular SLAM. In Proceedings of the Robotics: Science and Systems (RSS), Zaragoza, Spain, 27–30 June 2010. [Google Scholar] [CrossRef]
- Campos, C.; Elvira, R.; Gómez Rodríguez, J.J.; Montiel, J.M.M.; Tardós, J.D. ORB-SLAM3: An Accurate Open-Source Library for Visual, Visual–Inertial, and Multimap SLAM. IEEE Trans. Robot. 2021, 37, 1874–1890. [Google Scholar] [CrossRef]
- Shan, T.; Englot, B.; Meyers, D.; Wang, W.; Ratti, C.; Rus, D. LIO-SAM: Tightly-Coupled Lidar Inertial Odometry via Smoothing and Mapping. In Proceedings of the IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS), Las Vegas, NV, USA, 25–29 October 2020; pp. 5135–5142. [Google Scholar] [CrossRef]
- Wang, S.; Leroy, V.; Cabon, Y.; Chidlovskii, B.; Revaud, J. DUSt3R: Geometric 3D Vision Made Easy. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, WA, USA, 16–22 June 2024; pp. 20697–20709. [Google Scholar] [CrossRef]
- Leroy, V.; Cabon, Y.; Revaud, J. Grounding Image Matching in 3D with MASt3R. In Proceedings of the European Conference on Computer Vision (ECCV), Milan, Italy, 29 September–4 October 2024; pp. 71–91. [Google Scholar] [CrossRef]
- Wang, J.; Chen, M.; Karaev, N.; Vedaldi, A.; Rupprecht, C.; Novotny, D. VGGT: Visual Geometry Grounded Transformer. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Nashville, TN, USA, 10–17 June 2025; pp. 5294–5306. [Google Scholar] [CrossRef]
- Maggio, D.; Carlone, L. VGGT-SLAM 2.0: Real-Time Dense Feed-Forward Scene Reconstruction. arXiv Accepted to Robotics: Science and Systems (RSS). 2026, arXiv:2601.19887. [Google Scholar] [CrossRef]
- Wang, W.; Li, H.; Yu, H.; Xie, Q.; Dong, J.; Sun, X.; Liu, H.; Sun, C.; Li, B.; Zheng, F. SLAM Algorithm for Mobile Robots Based on Improved LVI-SAM in Complex Environments. Sensors 2024, 24, 7214. [Google Scholar] [CrossRef] [PubMed]
- Xie, Y.; Takikawa, T.; Saito, S.; Litany, O.; Yan, S.; Khan, N.; Tombari, F.; Tompkin, J.; Sitzmann, V.; Sridhar, S. Neural Fields in Visual Computing and Beyond. Comput. Graph. Forum 2022, 41, 641–676. [Google Scholar] [CrossRef]
- Barron, J.T.; Mildenhall, B.; Verbin, D.; Srinivasan, P.P.; Hedman, P. Mip-NeRF 360: Unbounded Anti-Aliased Neural Radiance Fields. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), New Orleans, LA, USA, 18–24 June 2022; pp. 5460–5469. [Google Scholar] [CrossRef]
- Atik, M.E. Comparative Assessment of Neural Radiance Fields and 3D Gaussian Splatting for Point Cloud Generation from UAV Imagery. Sensors 2025, 25, 2995. [Google Scholar] [CrossRef] [PubMed]
- Chen, G.; Wang, W. A Survey on 3D Gaussian Splatting. arXiv 2024, arXiv:2401.03890. [Google Scholar] [CrossRef]
- Li, Z.; Ning, H. Autonomous GIS: The Next-Generation AI-Powered GIS. Int. J. Digit. Earth 2023, 16, 4668–4686. [Google Scholar] [CrossRef]
- Reed, C.J.; Gupta, R.; Li, S.; Brockman, S.; Funk, C.; Clipp, B.; Keutzer, K.; Candido, S.; Uyttendaele, M.; Darrell, T. Scale-MAE: A Scale-Aware Masked Autoencoder for Multiscale Geospatial Representation Learning. In Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), Paris, France, 1–6 October 2023; pp. 4065–4076. [Google Scholar] [CrossRef]
- Roynard, X.; Deschaud, J.E.; Goulette, F. Paris-Lille-3D: A Large and High-Quality Ground-Truth Urban Point Cloud Dataset for Automatic Segmentation and Classification. Int. J. Robot. Res. 2018, 37, 545–557. [Google Scholar] [CrossRef]
- Varney, N.; Asari, V.K.; Graehling, Q. DALES: A Large-Scale Aerial LiDAR Data Set for Semantic Segmentation. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW), Seattle, WA, USA, 14–19 June 2020; pp. 717–726. [Google Scholar] [CrossRef]
- Hu, Q.; Yang, B.; Khalid, S.; Xiao, W.; Trigoni, N.; Markham, A. Towards Semantic Segmentation of Urban-Scale 3D Point Clouds: A Dataset, Benchmarks and Challenges. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Nashville, TN, USA, 20–25 June 2021; pp. 4975–4985. [Google Scholar] [CrossRef]
- Dwork, C. Differential Privacy. In Proceedings of the International Colloquium on Automata, Languages and Programming (ICALP), Venice, Italy, 10–14 July 2006; pp. 1–12. [Google Scholar] [CrossRef]
- Fei, B.; Xu, J.; Zhang, R.; Zhou, Q.; Yang, W.; He, Y. 3D Gaussian Splatting as New Era: A Survey. IEEE Trans. Vis. Comput. Graph. 2025, 31, 4429–4449. [Google Scholar] [CrossRef] [PubMed]
- Deng, Y.; Ai, H.; Deng, Z.; Gao, W.; Shang, J. An Overview of Indoor Positioning and Mapping Technology Standards. Standards 2022, 2, 157–183. [Google Scholar] [CrossRef]
- Liang, X.; Hyyppä, J.; Kaartinen, H.; Lehtomäki, M.; Pyörälä, J.; Pfeifer, N.; Holopainen, M.; Brolly, G.; Francesco, P.; Hackenberg, J.; et al. International benchmarking of terrestrial laser scanning approaches for forest inventories. ISPRS J. Photogramm. Remote Sens. 2018, 144, 137–179. [Google Scholar] [CrossRef]
- Calders, K.; Adams, J.; Armston, J.; Bartholomeus, H.; Bauwens, S.; Bentley, L.P.; Chave, J.; Danson, F.M.; Demol, M.; Disney, M.; et al. Terrestrial laser scanning in forest ecology: Expanding the horizon. Remote Sens. Environ. 2020, 251, 112102. [Google Scholar] [CrossRef]
- Maggio, D.; Lim, H.; Carlone, L. VGGT-SLAM: Dense RGB SLAM Optimized on the SL(4) Manifold. In Proceedings of the Advances in Neural Information Processing Systems (NeurIPS), San Diego, CA, USA and Mexico City, Mexico, 30 November–7 December 2025; pp. 143976–144004. [Google Scholar] [CrossRef]
- Zhu, Z.; Peng, S.; Larsson, V.; Xu, W.; Bao, H.; Cui, Z.; Oswald, M.R.; Pollefeys, M. NICE-SLAM: Neural Implicit Scalable Encoding for SLAM. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), New Orleans, LA, USA, 18–24 June 2022; pp. 12776–12786. [Google Scholar] [CrossRef]
- Hu, J.; Mao, M.; Bao, H.; Zhang, G.; Cui, Z. CP-SLAM: Collaborative Neural Point-Based SLAM System. In Proceedings of the Advances in Neural Information Processing Systems (NeurIPS), New Orleans, Louisiana, USA, 10–16 December 2023; pp. 39429–39442. [Google Scholar] [CrossRef]
- Bauwens, S.; Bartholomeus, H.; Calders, K.; Lejeune, P. Forest Inventory with Terrestrial LiDAR: A Comparison of Static and Hand-Held Mobile Laser Scanning. Forests 2016, 7, 127. [Google Scholar] [CrossRef]
- Cabo, C.; Del Pozo, S.; Rodr’iguez-Gonz’alvez, P.; Ord’oñez, C.; Gonz’alez-Aguilera, D. Comparing Terrestrial Laser Scanning (TLS) and Wearable Laser Scanning (WLS) for Individual Tree Modeling at Plot Level. Remote Sens. 2018, 10, 540. [Google Scholar] [CrossRef]
- Hyyppä, E.; Hyyppä, J.; Hakala, T.; Kukko, A.; Wulder, M.A.; White, J.C.; Pyörälä, J.; Yu, X.; Wang, Y.; Virtanen, J.P.; et al. Under-canopy UAV laser scanning for accurate forest field measurements. ISPRS J. Photogramm. Remote Sens. 2020, 164, 41–60. [Google Scholar] [CrossRef]
- Muhojoki, J.; Tavi, D.; Hyyppä, E.; Lehtomäki, M.; Faitli, T.; Kaartinen, H.; Kukko, A.; Hakala, T.; Hyyppä, J. Benchmarking Under- and Above-Canopy Laser Scanning Solutions for Deriving Stem Curve and Volume in Easy and Difficult Boreal Forest Conditions. Remote Sens. 2024, 16, 1721. [Google Scholar] [CrossRef]
- Proudman, A.; Ramezani, M.; Digumarti, S.T.; Chebrolu, N.; Fallon, M. Towards real-time forest inventory using handheld LiDAR. Robot. Auton. Syst. 2022, 157, 104240. [Google Scholar] [CrossRef]
- Vora, S.; Lang, A.H.; Helou, B.; Beijbom, O. PointPainting: Sequential Fusion for 3D Object Detection. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, WA, USA, 13–19 June 2020; pp. 4603–4611. [Google Scholar] [CrossRef]
- Bai, X.; Hu, Z.; Zhu, X.; Huang, Q.; Chen, Y.; Fu, H.; Tai, C.L. TransFusion: Robust LiDAR-Camera Fusion for 3D Object Detection with Transformers. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), New Orleans, LA, USA, 18–24 June 2022; pp. 1080–1089. [Google Scholar] [CrossRef]
- Liu, Z.; Tang, H.; Amini, A.; Yang, X.; Mao, H.; Rus, D.; Han, S. BEVFusion: Multi-Task Multi-Sensor Fusion with Unified Bird’s-Eye View Representation. In Proceedings of the IEEE International Conference on Robotics and Automation (ICRA), London, United Kingdom, 29 May–2 June 2023; pp. 2774–2781. [Google Scholar] [CrossRef]
- Chen, S.; Yan, Q.; Qu, Y.; Gao, W.; Yang, J.; Deng, F. Ortho-NeRF: Generating a True Digital Orthophoto Map Using the Neural Radiance Field from Unmanned Aerial Vehicle Images. Geo-Spat. Inf. Sci. 2024, 28, 741–760. [Google Scholar] [CrossRef]
- Zhang, Y.; Chen, G.; Chen, J.; Cui, S. Aerial Lifting: Neural Urban Semantic and Building Instance Lifting from Aerial Imagery. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, WA, USA, 16–22 June 2024; pp. 21092–21103. [Google Scholar] [CrossRef]
- Wang, H.; Wang, J.; Agapito, L. Co-SLAM: Joint Coordinate and Sparse Parametric Encodings for Neural Real-Time SLAM. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Vancouver, BC, Canada, 17–24 June 2023; pp. 13293–13302. [Google Scholar] [CrossRef]
- Graham, B.; Engelcke, M.; van der Maaten, L. 3D Semantic Segmentation with Submanifold Sparse Convolutional Networks. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Salt Lake City, UT, USA, 18–23 June 2018; pp. 9224–9232. [Google Scholar] [CrossRef]
- Hu, Q.; Yang, B.; Xie, L.; Rosa, S.; Guo, Y.; Wang, Z.; Trigoni, N.; Markham, A. RandLA-Net: Efficient Semantic Segmentation of Large-Scale Point Clouds. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, WA, USA, 13–19 June 2020; pp. 11105–11114. [Google Scholar] [CrossRef]
- Lai, X.; Liu, J.; Jiang, L.; Wang, L.; Zhao, H.; Liu, S.; Qi, X.; Jia, J. Stratified Transformer for 3D Point Cloud Segmentation. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), New Orleans, LA, USA, 18–24 June 2022; pp. 8490–8499. [Google Scholar] [CrossRef]
- Wang, P.S. OctFormer: Octree-Based Transformers for 3D Point Clouds. ACM Trans. Graph. (SIGGRAPH) 2023, 42, 1–11. [Google Scholar] [CrossRef]
- Liu, S.; Fu, K.; Wang, M.; Song, Z. Group-in-Group Relation-Based Transformer for 3D Point Cloud Learning. Remote Sens. 2022, 14, 1563. [Google Scholar] [CrossRef]
- Monji-Azad, S.; Kinz, M.; Kothari, S.; Khanna, R.; Mihan, A.C.; Maennel, D.; Scherl, C.; Hesser, J. DefTransNet: A Transformer-Based Method for Non-Rigid Point Cloud Registration in the Simulation of Soft Tissue Deformation. Meas. Sci. Technol. 2025, 36, 076006. [Google Scholar] [CrossRef]
- Tran, T.A.; Nguyen, D.M.H.; Tran, H.C.; Barz, M.; Doan, K.D.; Wattenhofer, R.; Vien, N.A.; Niepert, M.; Sonntag, D.; Swoboda, P. How Many Tokens Do 3D Point Cloud Transformer Architectures Really Need? In Proceedings of the Advances in Neural Information Processing Systems (NeurIPS), San Diego, CA, USA and Mexico City, Mexico, 30 November–7 December 2025; pp. 15106–15138. [Google Scholar] [CrossRef]
- Lu, D.; Xie, Q.; Gao, K.; Xu, L.; Li, J. 3DCTN: 3D Convolution-Transformer Network for Point Cloud Classification. IEEE Trans. Intell. Transp. Syst. 2022, 23, 24854–24865. [Google Scholar] [CrossRef]
- Hackel, T.; Savinov, N.; Ladicky, L.; Wegner, J.D.; Schindler, K.; Pollefeys, M. Semantic3D.net: A New Large-Scale Point Cloud Classification Benchmark. ISPRS Ann. Photogramm. Remote Sens. Spat. Inf. Sci. 2017, IV-1/W1, 91–98. [Google Scholar] [CrossRef]
- Tan, W.; Qin, N.; Ma, L.; Li, Y.; Du, J.; Cai, G.; Yang, K.; Li, J. Toronto-3D: A Large-Scale Mobile LiDAR Dataset for Semantic Segmentation of Urban Roadways. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW), Seattle, WA, USA, 14–19 June 2020; pp. 797–806. [Google Scholar] [CrossRef]
- Behley, J.; Garbade, M.; Milioto, A.; Quenzel, J.; Behnke, S.; Stachniss, C.; Gall, J. SemanticKITTI: A Dataset for Semantic Scene Understanding of LiDAR Sequences. In Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), Seoul, Republic of Korea, 27 October–2 November 2019; pp. 9296–9306. [Google Scholar] [CrossRef]
- Caesar, H.; Bankiti, V.; Lang, A.H.; Vora, S.; Liong, V.E.; Xu, Q.; Krishnan, A.; Pan, Y.; Baldan, G.; Beijbom, O. nuScenes: A Multimodal Dataset for Autonomous Driving. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, WA, USA, 13–19 June 2020; pp. 11618–11628. [Google Scholar] [CrossRef]
- Sun, P.; Kretzschmar, H.; Dotiwalla, X.; Chouard, A.; Patnaik, V.; Tsui, P.; Guo, J.; Zhou, Y.; Chai, Y.; Caine, B.; et al. Scalability in Perception for Autonomous Driving: Waymo Open Dataset. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, WA, USA, 13–19 June 2020; pp. 2443–2451. [Google Scholar] [CrossRef]
- Liao, Y.; Xie, J.; Geiger, A. KITTI-360: A Novel Dataset and Benchmarks for Urban Scene Understanding in 2D and 3D. IEEE Trans. Pattern Anal. Mach. Intell. 2023, 45, 3292–3310. [Google Scholar] [CrossRef] [PubMed]
- Armeni, I.; Sener, O.; Zamir, A.R.; Jiang, H.; Brilakis, I.; Fischer, M.; Savarese, S. 3D Semantic Parsing of Large-Scale Indoor Spaces. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Las Vegas, NV, USA, 27–30 June 2016; pp. 1534–1543. [Google Scholar] [CrossRef]
- Dai, A.; Chang, A.X.; Savva, M.; Halber, M.; Funkhouser, T.; Nießner, M. ScanNet: Richly-Annotated 3D Reconstructions of Indoor Scenes. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Honolulu, HI, USA, 21–26 July 2017; pp. 2432–2443. [Google Scholar] [CrossRef]
- Rottensteiner, F.; Sohn, G.; Jung, J.; Gerke, M.; Baillard, C.; Benitez, S.; Breitkopf, U. The ISPRS Benchmark on Urban Object Classification and 3D Building Reconstruction. ISPRS Ann. Photogramm. Remote Sens. Spat. Inf. Sci. 2012, I-3, 293–298. [Google Scholar] [CrossRef]
- Chen, M.; Hu, Q.; Yu, Z.; Thomas, H.; Feng, A.; Hou, Y.; McCullough, K.; Ren, F.; Soibelman, L. STPLS3D: A Large-Scale Synthetic and Real Aerial Photogrammetry 3D Point Cloud Dataset. In Proceedings of the Proceedings of the British Machine Vision Conference (BMVC), London, UK, 21–24 November 2022. [Google Scholar]
- Gaydon, C.; Daab, M.; Roche, F. FRACTAL: An ultra-large-scale aerial lidar dataset for 3D semantic segmentation of diverse landscapes. arXiv 2024, arXiv:2405.04634. [Google Scholar] [CrossRef]
- Puliti, S.; Pearse, G.; Surový, P.; Wallace, L.; Hollaus, M.; Wielgosz, M.; Astrup, R. FOR-instance: A UAV Laser Scanning Benchmark Dataset for Semantic and Instance Segmentation of Individual Trees. arXiv 2023, arXiv:2309.01279. [Google Scholar] [CrossRef]
- Henrich, J.; van Delden, J.; Seidel, D.; Kneib, T.; Ecker, A.S. TreeLearn: A deep learning method for segmenting individual trees from ground-based LiDAR forest point clouds. Ecol. Inform. 2024, 84, 102888. [Google Scholar] [CrossRef]
- Henrich, J.; van Delden, J. Towards General Deep-Learning-Based Tree Instance Segmentation Models. arXiv 2024, arXiv:2405.02061. [Google Scholar] [CrossRef]
- Xi, Z.; Hopkinson, C.; Rood, S.B.; Peddle, D.R. See the forest and the trees: Effective machine and deep learning algorithms for wood filtering and tree species classification from terrestrial laser scanning. ISPRS J. Photogramm. Remote Sens. 2020, 168, 1–16. [Google Scholar] [CrossRef]
- Sandler, M.; Howard, A.; Zhu, M.; Zhmoginov, A.; Chen, L.C. MobileNetV2: Inverted Residuals and Linear Bottlenecks. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Salt Lake City, UT, USA, 18–23 June 2018; pp. 4510–4520. [Google Scholar] [CrossRef]
- Müller, T.; Evans, A.; Schied, C.; Keller, A. Instant Neural Graphics Primitives with a Multiresolution Hash Encoding. ACM Trans. Graph. (SIGGRAPH) 2022, 41, 1–15. [Google Scholar] [CrossRef]
- Fridovich-Keil, S.; Yu, A.; Tancik, M.; Chen, Q.; Recht, B.; Kanazawa, A. Plenoxels: Radiance Fields Without Neural Networks. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), New Orleans, LA, USA, 18–24 June 2022; pp. 5491–5500. [Google Scholar] [CrossRef]
- Chen, A.; Xu, Z.; Geiger, A.; Yu, J.; Su, H. TensoRF: Tensorial Radiance Fields. In Proceedings of the European Conference on Computer Vision (ECCV), Tel Aviv, Israel, 23–27 October 2022; pp. 333–350. [Google Scholar] [CrossRef]
- Barron, J.T.; Mildenhall, B.; Verbin, D.; Srinivasan, P.P.; Hedman, P. Zip-NeRF: Anti-Aliased Grid-Based Neural Radiance Fields. In Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), Paris, France, 1–6 October 2023; pp. 19640–19648. [Google Scholar] [CrossRef]
- Tancik, M.; Weber, E.; Ng, E.; Li, R.; Yi, B.; Kerr, J.; Wang, T.; Kristoffersen, A.; Austin, J.; Salahi, K.; et al. Nerfstudio: A Modular Framework for Neural Radiance Field Development. In Proceedings of the ACM SIGGRAPH Conference Proceedings, Los Angeles, CA, USA, 6–10 August 2023; pp. 1–12. [Google Scholar] [CrossRef]
- Keetha, N.; Karhade, J.; Jatavallabhula, K.M.; Yang, G.; Scherer, S.; Ramanan, D.; Luiten, J. SplaTAM: Splat, Track and Map 3D Gaussians for Dense RGB-D SLAM. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, WA, USA, 16–22 June 2024; pp. 21357–21366. [Google Scholar] [CrossRef]
- Matsuki, H.; Murai, R.; Kelly, P.H.J.; Davison, A.J. Gaussian Splatting SLAM. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, WA, USA, 16–22 June 2024; pp. 18039–18048. [Google Scholar] [CrossRef]
- Yu, Z.; Chen, A.; Huang, B.; Sattler, T.; Geiger, A. Mip-Splatting: Alias-Free 3D Gaussian Splatting. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, WA, USA, 16–22 June 2024; pp. 19447–19456. [Google Scholar] [CrossRef]
- Huang, B.; Yu, Z.; Chen, A.; Geiger, A.; Gao, S. 2D Gaussian Splatting for Geometrically Accurate Radiance Fields. In Proceedings of the ACM SIGGRAPH Conference Proceedings, Denver, CO, USA, 28 July–1 August 2024; pp. 1–11. [Google Scholar] [CrossRef]
- Lu, T.; Yu, M.; Xu, L.; Xiangli, Y.; Wang, L.; Lin, D.; Dai, B. Scaffold-GS: Structured 3D Gaussians for View-Adaptive Rendering. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, WA, USA, 16–22 June 2024; pp. 20654–20664. [Google Scholar] [CrossRef]
- Gu, J.; Jiang, M.; Li, H.; Lu, X.; Zhu, G.; Shah, S.A.A.; Zhang, L.; Bennamoun, M. UE4-NeRF: Neural Radiance Field for Real-Time Rendering of Large-Scale Scene. In Proceedings of the Advances in Neural Information Processing Systems (NeurIPS), New Orleans, Louisiana, USA, 10–16 December 2023; pp. 59124–59136. [Google Scholar] [CrossRef]
- Cong, Y.; Khanna, S.; Meng, C.; Liu, P.; Rozi, E.; He, Y.; Burke, M.; Lobell, D.; Ermon, S. SatMAE: Pre-Training Transformers for Temporal and Multi-Spectral Satellite Imagery. In Proceedings of the Advances in Neural Information Processing Systems (NeurIPS), New Orleans, Louisiana, USA, 28 November–9 December 2022; New Orleans, Louisiana, USA, 28 November–9 December 2022; pp. 197–211. [Google Scholar] [CrossRef]
- Hong, D.; Zhang, B.; Li, X.; Li, Y.; Li, C.; Yao, J.; Yokoya, N.; Li, H.; Ghamisi, P.; Jia, X.; et al. SpectralGPT: Spectral Remote Sensing Foundation Model. IEEE Trans. Pattern Anal. Mach. Intell. 2024, 46, 5227–5244. [Google Scholar] [CrossRef] [PubMed]
- Kraabel, N.; Liu, J.; Bian, Y.; Kifer, D.; Shen, C. StefaLand: An Efficient Geoscience Foundation Model That Improves Dynamic Land-Surface Predictions. arXiv 2025, arXiv:2509.17942. [Google Scholar] [CrossRef]
- Paszke, A.; Gross, S.; Massa, F.; Lerer, A.; Bradbury, J.; Chanan, G.; Killeen, T.; Lin, Z.; Gimelshein, N.; Antiga, L.; et al. PyTorch: An Imperative Style, High-Performance Deep Learning Library. In Proceedings of the Advances in Neural Information Processing Systems (NeurIPS), Vancouver, BC, Canada, 8–14 December 2019; Vol. 32. [Google Scholar]
- Pointcept Contributors. Pointcept: A Codebase for Point Cloud Perception Research. 2023. Available online: https://github.com/Pointcept/Pointcept.
Figure 1.
Architectural taxonomy of next-generation mobile mapping systems: a unified, four-tier pipeline spanning the edge and cloud layers. Multi-modal sensor acquisition (Tier 1) feeds a hybrid geometric–semantic perception backbone (Tier 2); tokenized features are streamed to the cloud for radiance-field-based functional synthesis and digital twins (Tier 3) and agentic, foundation-model reasoning (Tier 4), which closes the loop by tasking active sensing in high-uncertainty areas.
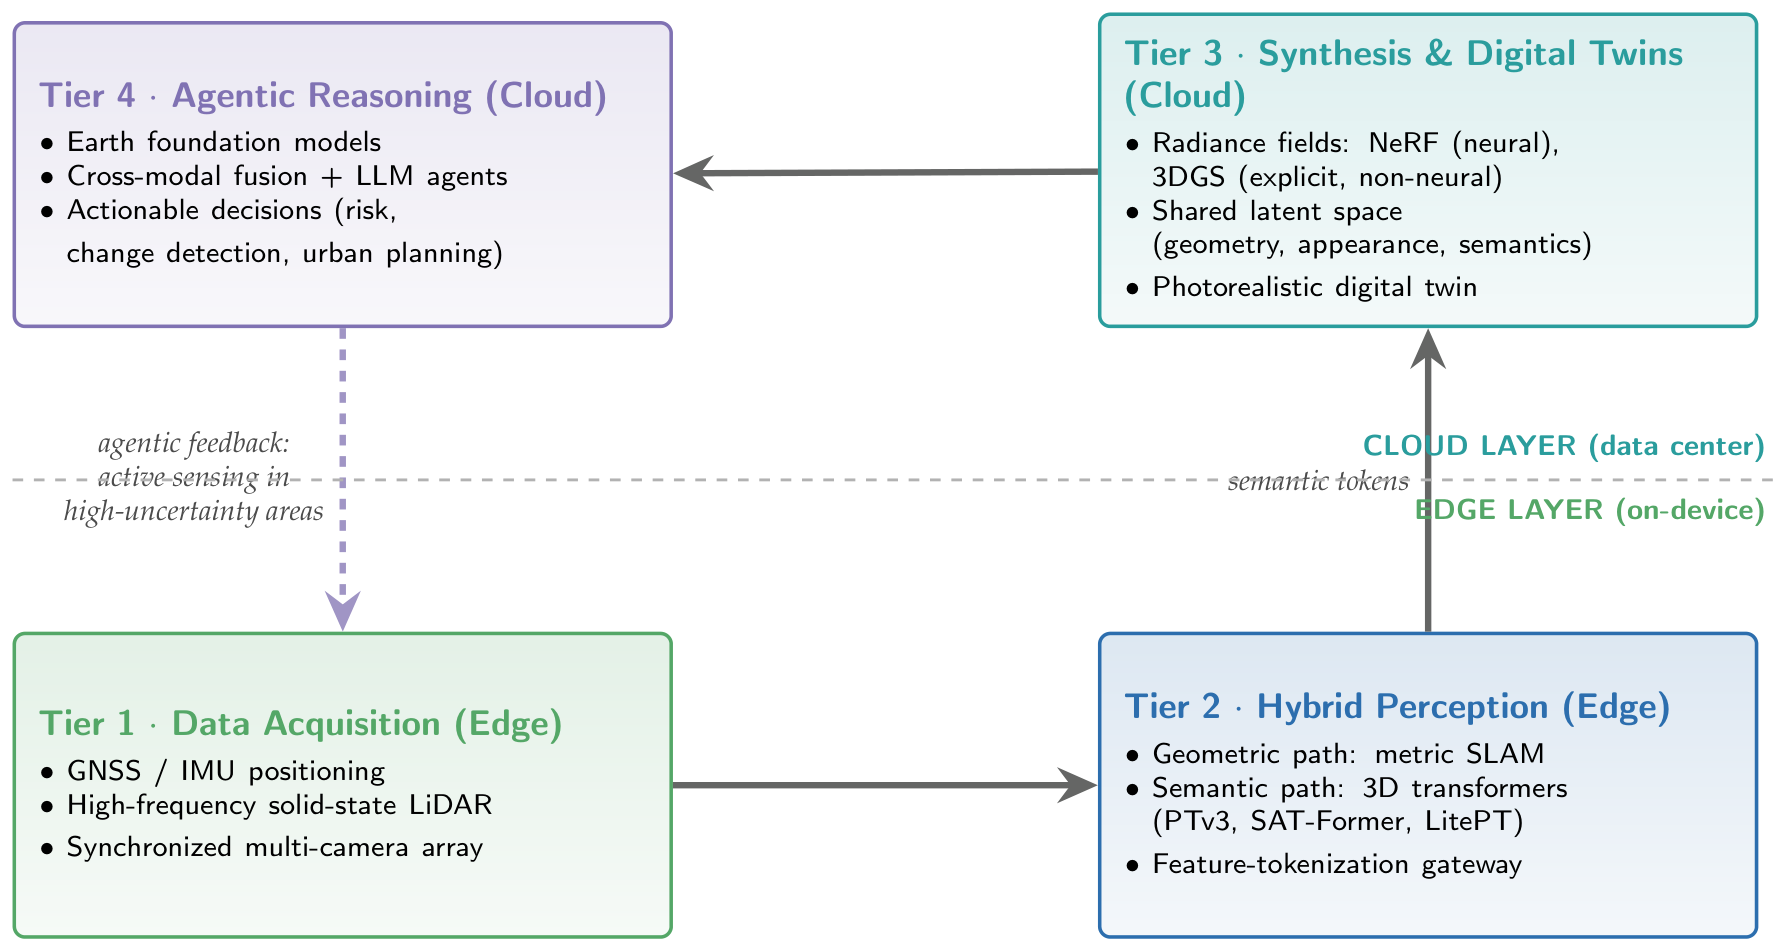
Figure 2.
Concurrent development of the five technological strands that constitute next-generation mobile mapping. Each bar spans the period over which the strand has been actively developed, and the right-hand arrows indicate that all five remain active today; the figure is deliberately not a succession of eras. Geometric MMS and optimization-based SLAM are not historical stages that learned perception replaced—they remain the metric backbone on which the newer strands depend (Section 3), and radiance-field reconstruction is contemporaneous with, rather than subsequent to, the point-transformer line. Note also that the two radiance-field milestones differ in kind: NeRF is a neural representation, whereas 3DGS contains no neural network (Section 5). Only milestones that can be labeled at their own date without crowding are marked, and labels are abbreviated for the same reason: SAT-Former is contemporaneous with the LitePT marker, and the accelerated NeRF variants that fall between the NeRF and 3DGS markers—Instant-NGP, Plenoxels, TensoRF—are omitted here and treated in Section 5.
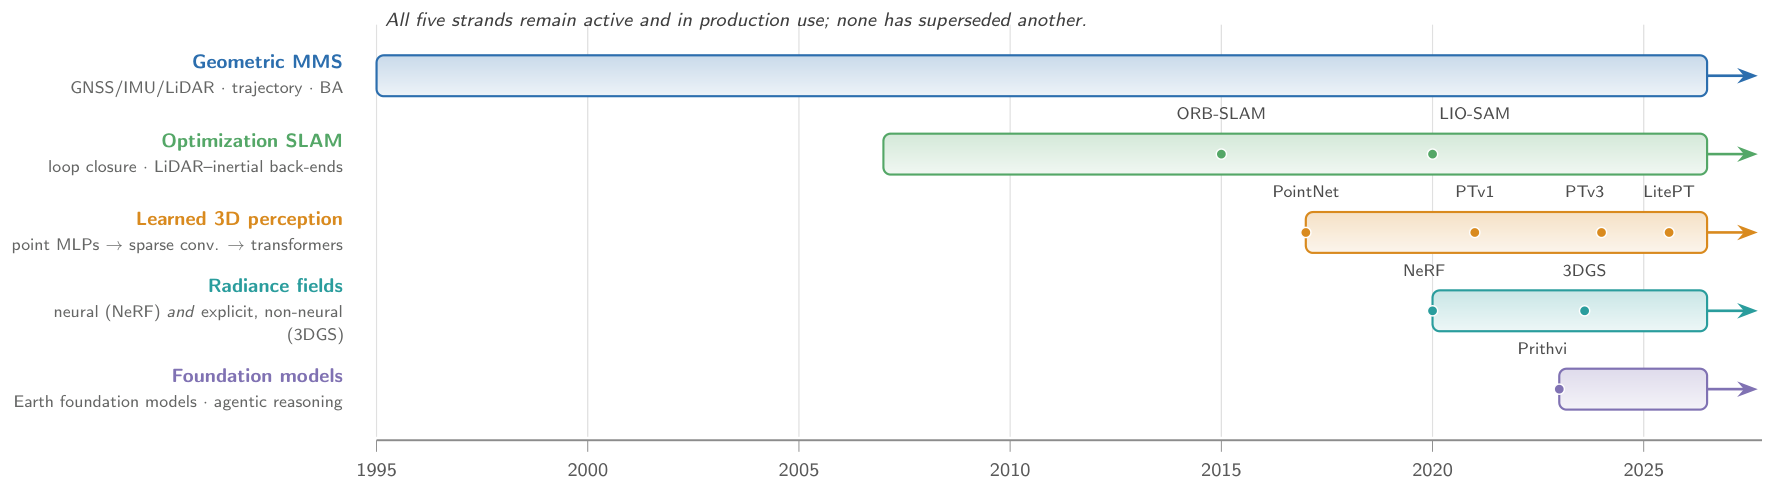
Figure 3.
Schematic of adaptive edge–cloud partitioning in next-generation MMS. The edge layer handles real-time perception and feature tokenization, while the cloud layer orchestrates EFMs for complex geospatial reasoning and city-scale digital twin updates.
Figure 3.
Schematic of adaptive edge–cloud partitioning in next-generation MMS. The edge layer handles real-time perception and feature tokenization, while the cloud layer orchestrates EFMs for complex geospatial reasoning and city-scale digital twin updates.
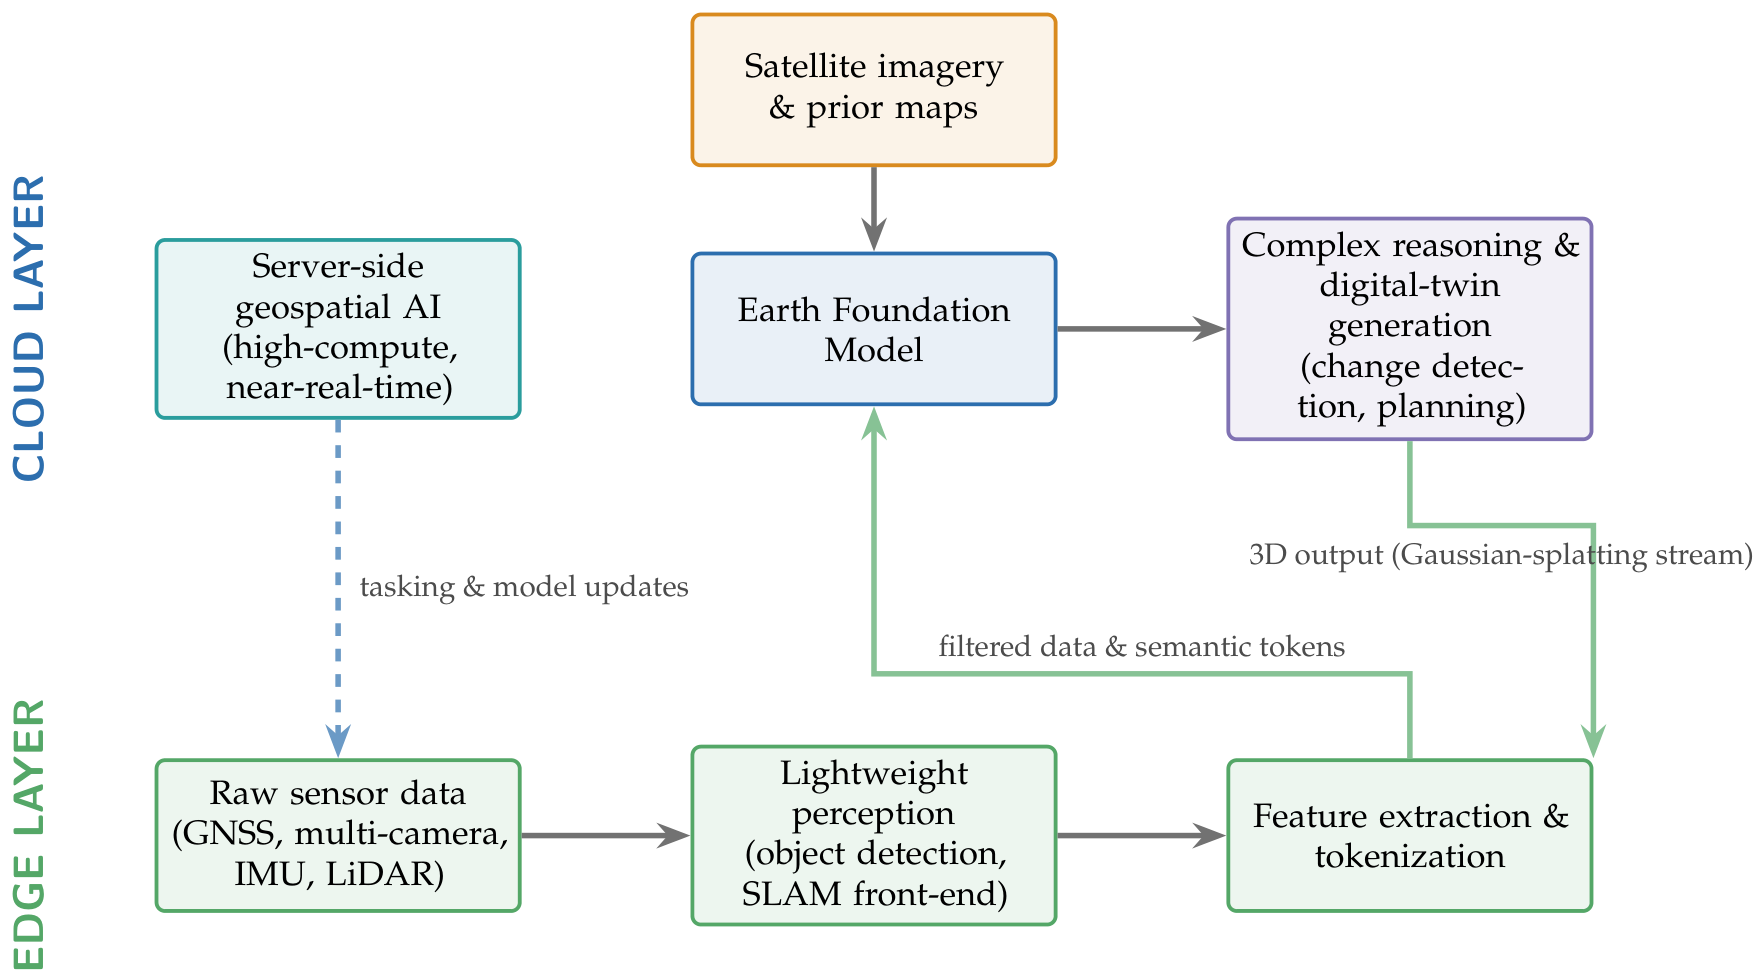
Figure 4.
The three convergence bottlenecks that fracture the idealized edge-to-cloud pipeline of Figure 1: a metric–semantic mismatch between raw sensing and tokenized perception, a latent-representation gap between tracking and rendering abstractions, and a grounding gap between macroscopic agentic reasoning and centimeter-scale geometry.
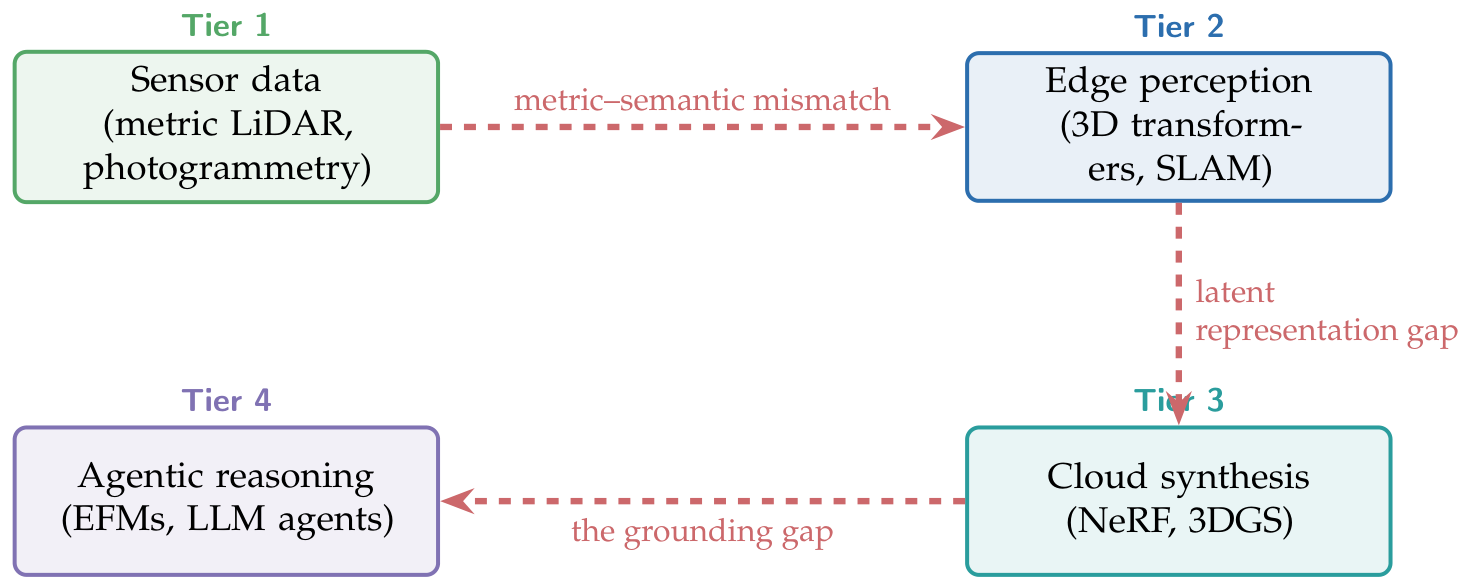
Table 1.
Conceptual comparison of feed-forward and neural-implicit SLAM paradigms for mobile mapping.
Table 1.
Conceptual comparison of feed-forward and neural-implicit SLAM paradigms for mobile mapping.
| Feature | Feed-Forward (e.g., VGGT-SLAM) | Neural Implicit (e.g., NICE-SLAM) |
|---|---|---|
| Primary Goal | High-speed tracking and metric consistency. | Dense, photorealistic scene completion. |
| Representation | Submap alignment and feature aggregation. | Continuous volumetric neural fields. |
| Computational Load | Low (feed-forward inference). | Very high (ray marching and optimization). |
| Drift Correction | Strong (global scale factors and loop closure). | Traditionally weaker; requires hybrid tracking modules. |
| Map Utility | Best for navigation and metric reconstruction. | Best for digital twins and immersive visualization. |
Table 2.
Reported efficiency and accuracy of recent point-cloud transformer backbones. Values are as stated in the cited sources; evaluation benchmarks differ and are named explicitly. “–” denotes a figure not reported on a comparable benchmark.
Table 2.
Reported efficiency and accuracy of recent point-cloud transformer backbones. Values are as stated in the cited sources; evaluation benchmarks differ and are named explicitly. “–” denotes a figure not reported on a comparable benchmark.
| Model | Params (M) | Reported accuracy | Headline efficiency claim |
|---|---|---|---|
| PTv3 [6] | 46.1 | 80.4 mIoU (nuScenes val) | faster, lower memory vs. PTv2 |
| LitePT-S [24] | 12.7 | 82.2 mIoU (nuScenes val) | fewer params, faster, lower memory vs. PTv3 |
| SAT-Former [23] | – | >95% relative accuracy (urban scenes) | Up to faster inference vs. baseline transformer |
Table 3.
The three architectures as three mutually exclusive answers to one design question: how the token set presented to attention is constructed. Reported efficiency and accuracy figures are given separately in Table 2 and are not repeated here.
Table 3.
The three architectures as three mutually exclusive answers to one design question: how the token set presented to attention is constructed. Reported efficiency and accuracy figures are given separately in Table 2 and are not repeated here.
| Model | Operation on the token set | Core innovation | Deployment suitability |
|---|---|---|---|
| Point Transformer V3 (PTv3) | Reorders; token count unchanged | Serialize-and-patch: points ordered along space-filling curves, replacing explicit kNN neighborhood construction with a near-free serialization | High-performance GPU systems |
| SAT-Former | Merges; count reduced before attention | Semantic Aggregated Point Tokenizer: semantically homogeneous clusters formed prior to attention, reducing redundancy and mitigating semantic confusion | Edge-capable with optimization |
| LitePT | Relocates; attention never sees the full set | Convolution for low-level geometry at high resolution, attention for high-level semantics at low resolution, with a parameter-free 3D positional encoding | Mobile and embedded deployment |
Table 4.
Architectural trade-offs between CNN/sparse-convolution and transformer-based backbones for 3D point cloud understanding in mobile mapping. The entries are qualitative by design: absolute latency and memory figures depend on hardware, precision, and input regime, and are therefore reported only where they were measured under a fixed protocol (sec:pcbench) rather than asserted as architecture-wide constants.
| Feature | CNNs / Sparse Convolutions | 3D Transformers (e.g., PTv3) |
|---|---|---|
| Contextual Range | Primarily local (limited by kernel size). | Global (self-attention receptive field). |
| Computational Scaling | Linear with the number of active voxels/points. | Historically quadratic; now sub-quadratic. |
| Hardware Latency | Lower, and predictable in the point count. | Higher, and governed by the token count rather than by the point count. |
| Resource Efficiency | Low memory footprint; efficient on mobile GPUs. | High GPU memory demand; high parameter count. |
Table 5.
Comparative analysis of NeRF-based and Gaussian Splatting rendering frameworks in mobile mapping systems.
Table 5.
Comparative analysis of NeRF-based and Gaussian Splatting rendering frameworks in mobile mapping systems.
| Method | Type | Training | Rendering | Urban Scale | Real-Time |
|---|---|---|---|---|---|
| NeRF | Implicit | Slow | Slow | Moderate | No |
| 3DGS | Explicit | Fast | 100+ FPS | Strong | Yes |
| UE4-NeRF | Partitioned | Accelerated | Interactive | Very High | Near real-time |
Table 6.
Cross-paradigm comparison across the mobile-mapping pillars. Values are as reported by the cited sources and are not mutually commensurable—each was obtained on different data, hardware, and measurement protocols, which is itself the substance of Pitfall P1. Ranges reflect variation across datasets and configurations rather than single-benchmark results. Entries annotated sec:pcbench are controlled same-hardware measurements from this review and are mutually comparable with one another. The table is intended to expose structural trade-offs between paradigms, not to rank individual systems.
| Paradigm / core architecture | Primary data substrate | Accuracy / quality | Throughput & latency | Memory & storage | Zero-shot generalization |
|---|---|---|---|---|---|
| Geometry-grounded feed-forward SLAM (VGGT-SLAM 2.0, MASt3R) [29,31] | Multi-view RGB sequences | Absolute trajectory error at the centimeter-to-decimeter scale on the indoor and small-scale sequences these systems are evaluated on; no published urban-corridor evaluation (P3) | Forward inference per keyframe pair, without per-frame optimization; real-time operation reported under the authors’ own configurations rather than under a common protocol | Scales in keyframes; compact feed-forward weights | High as claimed; geometry-grounded attention maps to physical invariants |
| Neural implicit SLAM (NICE-SLAM, Co-SLAM) [48,60] | Synchronized RGB-D / monocular | Reconstruction ∼1.5–3.0 cm Chamfer distance | Iterative optimization ∼10–17 Hz; ray marching limits map updates | hash-grid/voxel; memory grows with grid size | Low; scene-specific MLPs overfit to local illumination/geometry |
| Serialized point transformers (PTv3) [6] | Large-scale 3D point clouds | 80.4% mIoU (nuScenes val); ∼75–78% on SemanticKITTI / Toronto-3D | ∼3.3× faster than PTv2 as reported; measured under a fixed protocol, at 408 ms per points (sec:pcbench) | 10.2× lower attention memory via space-filling-curve serialization | Moderate; needs dense-corpus pre-training across morphologies |
| Semantically aggregated tokens (SAT-Former) [23] | Terrestrial MMS point clouds | >95% relative to the dense transformer baseline (urban scenes; absolute mIoU not reported) | Up to 30× faster via semantic clustering | Reduced by aggregation; not separately quantified | Moderate–low; cluster features can be scene-dependent |
| Convolution-then-attention hybrid (LitePT) [24] | Terrestrial MMS point clouds | 82.2% mIoU (nuScenes val), i.e., above PTv3 on the same benchmark | faster than PTv3 as reported; measured here (sec:pcbench) | ∼3.6× fewer parameters; lower VRAM vs. PTv3 | Moderate–low; transfer across morphologies unverified |
| Explicit radiance fields (3DGS, Scaffold-GS) [11,94] | Synchronized multi-camera RGB | Novel-view synthesis >28–32 dB PSNR; SSIM >0.90 | 100+ FPS at 1080p; training <10–15 min for street scenes | primitives; 236 bytes per uncompressed degree-3 Gaussian, 56 bytes with DC-only harmonics (Section 5) | None; scene-specific overfitting; degrades in unseen zones |
| Earth foundation models (SpectralGPT, Prithvi) [12,97] | Multispectral / satellite / airborne LiDAR | +5–12% mIoU over random initialization on downstream tasks | Cloud-scale inference (seconds–minutes); unsuited to edge navigation | 100M–1B+ parameters; multi-gigabyte hosting | Very high; cross-modal masking yields cross-scale invariant features |
Table 7.
Computational and operational limitations of next-generation geospatial intelligence pipelines.
Table 7.
Computational and operational limitations of next-generation geospatial intelligence pipelines.
| Component | Cost | Edge Readiness | Primary Bottleneck |
|---|---|---|---|
| Transformer Segmentation | High GPU memory | Moderate | Attention memory growth |
| Lightweight Transformers | Moderate | High | Accuracy–efficiency tradeoff |
| NeRF-based Rendering | Very high (training) | Low | Training time |
| 3DGS | Moderate | Moderate–High | GPU rasterization memory |
Table 8.
The research agenda at a glance: open problems, the gap or pitfall each addresses, and the evidence a credible solution must exhibit.
Table 8.
The research agenda at a glance: open problems, the gap or pitfall each addresses, and the evidence a credible solution must exhibit.
| Open problem | Addresses | Success criterion |
|---|---|---|
| Physics-infused self-attention | Metric–semantic mismatch (§Section 9); P6 | Segmentation backbone whose object boundaries provably satisfy multi-view / topological constraints at unchanged mIoU |
| Omni-modal spatial tokenizer | Latent representation gap (§Section 9) | Open bitstream standard: edge-encoded geometry+appearance+semantics reconstructable in cloud to both 3DGS twin and vector map under stated bandwidth |
| Neuro-symbolic grounding fields | Grounding gap (§Section 9); P7 | Agent queries resolved against radiance-field symbolic index with quantified, near-zero spatial-hallucination rate |
| Standardized MMS efficiency protocol | P1, P2 | Community benchmark fixing hardware classes, precision, input regimes; adopted by ≥2 major venues’ reporting guidelines |
| Cross-domain generalization studies | P3, P4, P5 | Same-protocol evaluation of leading backbones across LiDAR, MMS, and photogrammetric benchmarks incl. zero-shot and dynamic-scene conditions |
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (http://creativecommons.org/licenses/by/4.0/).
Copyright: This open access article is published under a Creative Commons CC BY 4.0 license, which permit the free download, distribution, and reuse, provided that the author and preprint are cited in any reuse.