

Submitted:
14 July 2026
Posted:
15 July 2026
You are already at the latest version
Abstract
Tabular anomaly detection (TAD) assigns anomaly scores to unusual samples in tables and supports applications in finance, healthcare, cybersecurity, industrial monitoring, and data-quality assurance. Its central challenge stems from the heterogeneous and weakly structured nature of tabular data: unlike images, sequences, and graphs, tables lack native spatial, temporal, or relational structure while mixing heterogeneous feature types without a common metric, so the notions of distance, density, and dependency that detectors rely on must be induced through representation and encoding choices. Part of what defines an anomaly may also reside outside processed values, in column semantics, domain rules, or schema information that standard pipelines discard. Recent TAD research spans non-deep detectors, deep task-specific models, large language model-based methods, and foundation model-based methods. These directions differ in supervision, information access, evaluation protocols, and downstream use, yet existing surveys examine neighboring areas largely in isolation. This survey provides a unified account of TAD by organizing existing detectors according to how they form anomaly scores. Beyond method taxonomy, it reviews enhancement and adaptation for deployment, benchmarks and evaluation protocols, and downstream tasks built on TAD outputs. It aims to clarify method assumptions and provide a more comparable basis for future TAD research.
Keywords:
tabular anomaly detection
; non-deep methods
; deep neural networks
; large language models
; foundation models
1. Introduction
Tabular anomaly detection (TAD) assigns anomaly scores to unusual samples in tables, one of the most common forms of structured data in real-world applications [1,2]. In TAD, each row is a sample and each column is a feature; samples whose values or feature relationships appear unusual are assigned higher scores, as illustrated in Figure 1. These scores help prioritize suspicious cases in fraud detection [3], healthcare monitoring [4], cyber-intrusion analysis [5], and industrial fault diagnosis [6]. Like anomaly detection more broadly, TAD often operate under rare, diverse, and often incompletely labeled abnormal patterns that may arise from faults, attacks, fraud, rare diseases, data corruption, or genuinely novel phenomena [7,8,9].
TAD is distinctive because a standalone table usually lacks built-in spatial locality, temporal order, or explicit edge structure that detectors can exploit in images, sequences, and graphs. Its columns may mix numerical, categorical, textual, and missing entries, yet unlike pixels or tokens, heterogeneous features offer no inherent similarity measure, and the dependencies among them are less regular than the spatial or semantic structure found in images and text [10,11]. Consequently, the notions of distance, density, and dependency used by many detectors must be induced through representation, encoding, scaling, and information-retention choices rather than read directly from the data. These choices are not neutral: for instance, one-hot encoding treats all categories as equally dissimilar, while ordinal encoding imposes a numeric ordering that may not reflect their true relationships; a missing entry may represent noise, absence, or a domain-specific event. Part of what defines an anomaly may also lie outside the processed values, in column names, units, valid ranges, category meanings, schema descriptions, or domain rules. Anomaly in a table is therefore not a fixed geometric property, but a judgment shaped by representation and retained information.
TAD research has grown rapidly in recent years: detectors now range from fixed statistical rules [12,13] to learned neural representations [14,15,16], from processing only numerical values to exploiting schema text, domain knowledge, and language-model reasoning [17,18,19], and from training on a single table to transferring across many [20,21]. This rapid proliferation has made the field difficult to compare systematically, as studies vary in the information available to the detector, the label assumptions they adopt, and the evaluation protocols used to support meaningful comparisons.
We observe that every TAD method, regardless of era or supervision, reduces to a scoring function that maps a sample to an anomaly score. Two choices embedded in that function determine where a method sits in the field, yet existing accounts seldom make them explicit. The first is the information boundary: whether the scoring function operates on preprocessed values alone or also retains column semantics, schema descriptions, and domain knowledge. The second is the normality model: how the scoring function turns its available evidence into a notion of what is normal. Making these two axes explicit reveals each method’s assumptions and scope.
This survey organizes detectors along these two axes into four families that trace the successive waves of technique in TAD. Non-deep-learning-based and deep task-specific methods share a value-only information boundary, differing in whether normality is captured by fixed rules [12,13,22] or learned per-table representations [14,15,23]; Large language model (LLM)-based and foundation model-based methods widen the boundary, the former through semantic reasoning over retained column meanings and domain rules [17,18,19], the latter through cross-table pretraining or shared priors [20,21]. Beyond detector design, we review enhancement and adaptation for deployment, including data augmentation, score calibration, constrained deployment, and human feedback. We also summarize benchmark practices, covering data sources, anomaly construction, supervision settings, protocol access, and evaluation metrics, and examine downstream tasks built on TAD outputs, including explanation, localization, semantic diagnosis, and data repair. Figure 2 provides the full roadmap. By decoupling what information the detector sees from how it models normality, this framing clarifies what each detector can in principle detect, thus providing the practitioner with a clear criterion for method selection. It also reframes benchmark choice as alignment between what the detector needs and what the data preserves, and positions enhancement for deployment and downstream use not as isolated add-ons but as responses to each family’s capabilities and limits.
Several existing surveys touch on parts of this landscape, but none provides a unified treatment of tabular anomaly detection. General and method-specific anomaly-detection surveys [7,8,9,24,25] treat tabular data as one modality among images, time series, text, and graphs, leaving unexamined the specific challenges that feature heterogeneity, non-neutral encoding, and discarded semantic information pose for anomaly scoring. Surveys that do center on tabular data have not filled this gap: they address supervised prediction and representation learning [10,26,27], synthetic data generation [28], or LLMs and foundation models for tabular data [29,30], rather than anomaly scoring under label scarcity and contamination. Explainable anomaly detection [31] and data-cleaning surveys [32] address interpretation, repair, and data-quality workflows, yet enter after a detector exists and do not study the scoring step itself. The common gap is that no prior work unifies non-deep, deep, LLM-based, and foundation model-based TAD under a single account of what is scored, what information the detector receives, how scores are evaluated, and how they are later adapted or consumed.
This survey makes three contributions. First, it provides a TAD-centered taxonomy that organizes non-deep detectors, deep task-specific methods, LLM-based methods, and foundation model-based methods along two axes, information boundary and normality model, within a common view of tabular anomaly scoring. Second, it reviews the main dimensions for comparing TAD methods, including anomaly manifestation, retained table information, supervision setting, and evaluation practice, clarifying how comparisons in the literature should be interpreted. Third, it connects detector families to two forms of practical use: enhancement and adaptation for deploying existing detectors, and downstream tasks that consume TAD outputs for explanation, localization, semantic diagnosis, and data repair.
2. Problem Formulation
2.1. Task Definition
Tabular anomaly detection (TAD) is usually defined as the task of learning an anomaly scoring function from a training table and applying it to samples in a test table. In a table, each row is a sample and each column is a feature. A sample may contain numerical, categorical, textual, or missing entries. Let denote the training table, where each sample is represented by d features and is the number of samples. The form of depends on the supervision setting. It may be unlabeled, contain only normal samples, include a small labeled subset, or provide full labels; these cases are detailed in Section 2.2. Let denote the test table. In standard evaluation, may contain both normal and anomalous samples, whose labels are used only for evaluation.
The goal of TAD is to learn an anomaly scoring function (also called detector) f from . During inference, the scoring function f takes sample as input and outputs the predicted anomaly score of :
where a higher score indicates a higher confidence that is an anomaly. The scores are used to rank samples so that suspicious ones can be prioritized for inspection.
Some methods score a sample using not only its values but also auxiliary table or task information, such as column names, units, valid ranges, category meanings, schema descriptions, or domain rules. Denoting this information collectively by , the score becomes:
We refer to Equation (1) as the value-only setting, in which the detector sees only preprocessed values, and to Equation (2) as the information-preserving setting, in which is retained. The distinction matters for comparison: some anomalies are visible only through , for instance a value that is plausible in one unit but impossible in another, so a detector evaluated with and one evaluated without it solve different problems even on the same table.
2.2. Supervision Settings
The detector f must be fitted on training set before it can score new samples. Let denote the anomaly label, with indicating an anomaly and indicating a normal sample. We distinguish four training-label regimes.
Unsupervised setting. The training set is unlabeled:
The detector must infer normality from the observed mixture. Since may already contain anomalies, the primary difficulty is contamination: the detector may incorporate some anomalous samples into its model of normality, thereby blurring the boundary between normal and abnormal support.
One-class setting. The training set contains only samples known or assumed to be normal:
The detector learns patterns of normality from and flags deviations at test time. Its central difficulty is that anomaly is defined only by absence: no anomalous examples are available to specify which deviations matter, how far from normal support a sample must be, or which rare but valid modes should remain normal. The clean-normal assumption is therefore necessary but not sufficient; even with clean training data, the anomaly boundary is underdetermined without counterexamples or domain information.
Semi-supervised or weakly supervised setting. A small labeled subset accompanies a larger unlabeled subset:
The labeled subset may contain a few confirmed anomalies and normal samples, or weak labels depending on the protocol. The detector uses these labels to orient anomaly scoring, while still relying heavily on unlabeled data. The main difficulty is that labeled anomalies are scarce, biased toward previously observed failure modes, and often noisy [33,34]; a semi-supervised detector may therefore learn to rank known anomaly types while missing novel ones.
Supervised setting. All training samples are labeled:
Fully supervised classifiers serve as label-budget upper bounds. They quantify the gap between full supervision and label-scarce detectors, but should not be compared as if they solved the same problem as unsupervised or one-class TAD [1].
2.3. Anomaly Types
Tabular anomalies do not conform to a single canonical form. We distinguish five recurring types, illustrated in Figure 2, by how the abnormality becomes observable. The first four are statistical: they are visible in the feature values alone and correspond to the value-based types studied in ADBench [1]. The fifth is semantic: it becomes visible only through the retained information , as highlighted by recent semantics-preserving benchmarks [19,35].
Global anomalies are individual samples that fall in regions of the joint feature space where the normal data is absent. The reference is the entire table: a sample is suspicious because it is far from all normal data clusters, regardless of the direction. No single feature needs to be extreme; rather, the combination of feature values lands the sample in a part of the feature space that the normal distribution does not occupy. Such anomalies are the easiest to detect when the normal data forms compact clusters, because they are isolated in the overall geometry. The key risk is that in high-dimensional or sparse settings, most of the feature space is empty, and the gap between genuine anomalies and rare but legitimate samples can become unclear.
Local anomalies are individual samples that appear plausible from a global perspective but are abnormal relative to their immediate neighborhood in the feature space. Unlike global anomalies, local anomalies fall within or near a normal cluster, yet they deviate from the local pattern of that cluster. For example, a sample may lie in the general region of a normal group but be displaced enough that it no longer matches the density or spread of its closest neighbors. Detectors that rely on global statistics, such as bounding-box isolation or marginal tail estimation, may overlook these cases because the sample is not extreme in any overall sense. The key difficulty is that detecting local anomalies requires a notion of local normality, and the appropriate neighborhood scale is rarely known in advance.
Dependency anomalies are samples whose individual feature values are plausible but whose joint configuration is unlikely. Each feature, viewed alone, falls within its normal range; the evidence lies in the relationships among features. For instance, a medical record may show an age of 25 and a diagnosis of Alzheimer’s disease; both values are individually ordinary, but their combination violates the dependency structure of the normal population. Detectors that score features independently can miss these cases entirely, because no single feature needs to be abnormal.
Clustered anomalies are small groups of suspicious samples that are coherent with each other but unusual as a group relative to the main data distribution. Each member has close neighbors within its own abnormal group, so detectors that rely on point-level isolation may not flag them quickly. These anomalies test whether a detector can distinguish a compact abnormal cluster from a legitimate minority mode. For example, a batch of coordinated fraudulent transactions may share similar patterns and form a tight group far from any legitimate cluster.
Semantic anomalies are violations that become visible only when retained table information is available. They may conflict with units, valid ranges, category definitions, schema descriptions, or domain rules. A value can be statistically plausible in the processed array but impossible under its column meaning; such an anomaly may disappear if the table is anonymized, unit information is removed, or categorical meanings are stripped away.
These types are not mutually exclusive: real-world datasets typically contain an unknown mixture whose composition is not disclosed. Detectors rarely declare which types they target; their coverage is implicit in their scoring assumptions. This gap motivates controlled benchmarks that inject specific anomaly types into real data to test what a detector actually captures [1,35,36]. We discuss type-aware evaluation protocols in Section 9.
3. Overview of TAD Methods
The preceding section defines the TAD task: a detector assigns an anomaly score , or when auxiliary table or task information is retained. The detector f is fitted on a training set under one of the supervision settings defined in Section 2.2. This section translates that formulation into the organizational structure of the survey. The key organizing question is: how does a method represent normality and turn a tabular sample into an anomaly score? We give an overview of the four detector families in Table 1.
Non-deep-learning-based TAD (Section 4) employs fixed geometric or statistical principles after preprocessing. These methods score samples through neighborhood proximity, density estimation, isolation, one-class boundary estimation, and projection-based deviation. A generic scoring form is , where the scoring principle is determined by algorithm design rather than end-to-end neural parameter learning.
Deep task-specific TAD (Section 5) trains a neural scorer for a particular table, written generically as . Anomaly scores may derive from reconstruction error, contrastive and transformation-based self-supervised objectives, or learned representations. The parameters are optimized on and are typically not transferred across tables.
LLM-based TAD (Section 6) broadens the information available to the scorer. Its generic form is , where may include column names, valid ranges, category meanings, task descriptions, domain rules, or other semantic information that value-only detectors discard. Some methods in this family use an LLM directly for anomaly scoring; others use an LLM to generate features, rules, code, or critiques for a conventional detector. The central question is whether LLM reasoning over retained semantic information yields anomaly judgments that value-only scoring cannot reach.
Foundation model-based TAD (Section 7) reuses a prior learned across many tables instead of fitting a detector from scratch for each one. This prior is obtained either by designing a model for cross-table use, typically pretrained on many (often synthetic) detection tasks, or by adapting an existing pretrained foundation or language model to detection. Its generic form is , where denotes pretrained parameters or priors reused across tables under zero-shot, in-context, or limited adaptation.
Enhancement and adaptation for deployment (Section 8) is not a fifth detector family. Instead, it modifies how a chosen detector is enhanced, calibrated, constrained, or updated for operational use. Examples include augmenting the training data with proxy anomalies, boosting or calibrating raw anomaly scores, deploying under privacy or resource constraints, and incorporating analyst feedback. This layer can wrap around several detector families because it acts on the training signal, output scores, operating environment, or feedback loop rather than defining the basic scoring principle.
4. Non-Deep-Learning-Based TAD
Non-deep-learning-based methods, i.e., detectors that score samples with fixed geometric or statistical rules rather than learned neural representations, remain essential baselines for TAD. They remain important in TAD because many such detectors are simple, transparent, and competitive under careful evaluation [1,96].
4.1. Neighborhood-Based Methods
Neighborhood-based detectors score a sample by evaluating its proximity to surrounding points under a chosen metric. A generic formulation is:
where denotes the k-nearest neighbors of , is a distance metric, and G is an aggregation function such as mean distance, k-th neighbor distance, or a local density ratio. These methods assume that anomalies lack strong local support in the induced feature geometry.
The KNN detector [13] scores each sample by its aggregate distance to the k nearest neighbors: a large distance indicates that the sample resides in a sparse region, far from the bulk of the data, and is therefore more likely anomalous. Since naive evaluation requires computing all pairwise distances, the method incurs quadratic time in the number of samples, which typically necessitates approximations such as grid partitioning or random subsampling [97] at the cost of precision in sparse or imbalanced regions. Because global distance thresholds fail under irregular density distributions, LOF [37] instead measures the degree to which a point is locally isolated by comparing its local reachability density with those of its nearest neighbors. LOF sits at the boundary between neighborhood and density methods: it relies on a k-NN graph for support, but its score is a local-density contrast rather than a raw distance. Several variants address its limitations: COF [38] uses shortest-path graphs to handle manifold-structured data, while CBLOF [39] uses coarse clusters as a proxy for local neighborhoods to reduce computation. When distances become unreliable in high dimensions, ABOD [40] offers an alternative by measuring variance in pairwise angular directions rather than spatial proximity.
The principal limitation of neighborhood methods in tabular settings is their strict dependence on a meaningful metric space. Geometric distances are easily distorted by categorical encodings, and local densities can be artificially skewed by missing-value imputation. Consequently, while these methods are effective for identifying global spatial outliers, they cannot capture anomalies defined by semantic logic or conditional rules that do not project faithfully into the induced geometry.
4.2. Density-Estimation Methods
Density and statistical estimators score a sample by how unlikely it is under a fitted or empirical distribution. A generic form is:
where represents a modeled probability density function or an empirical tail probability, parameterized by . Low estimated probability yields a high anomaly score.
Among parametric approaches, a Gaussian Mixture Model (GMM) [41] fits the data as a weighted sum of several Gaussian components, each with its own mean and covariance, and flags samples that fall in low-probability regions under the fitted mixture; it can accommodate normal data that form multiple distinct clusters, provided the dimensionality is low enough for reliable covariance estimation. The Minimum Covariance Determinant (MCD) estimator [42] fits its covariance to the most tightly concentrated subset of a given size, so that anomalies in the remaining data cannot distort the estimate and mask themselves. Among non-parametric approaches, DBSCAN [43] forms clusters by connecting samples whose local neighborhoods exceed a fixed density threshold and treats all remaining samples as anomalies; however, its single global threshold cannot simultaneously resolve clusters at different density scales. HDBSCAN [44] removes this restriction by building a cluster hierarchy over all density levels, using a smoothed pairwise distance metric that suppresses the influence of sparse bridge points between clusters and enables stable extraction of varying-density structure.
Pure non-parametric estimators such as KDE [98] suffer from bandwidth selection difficulties in high-dimensional, sparse tabular data. To address the curse of dimensionality and computational cost, fast marginal estimators impose feature independence to achieve scalability. HBOS [45] aggregates univariate histograms, reducing time complexity to linear in both the number of samples and the number of features. COPOD [46] and ECOD [47] are more accurately described as marginal tail-probability scorers than full joint density estimators: they use empirical copulas or cumulative distribution functions to assess extremeness while avoiding pairwise distance computations and complex distribution fitting.
In tabular settings, the efficiency of these estimators is often compromised by modeling assumptions. Parametric approaches such as GMMs and MCD become brittle in high dimensions due to rank deficiency. Topological algorithms such as HDBSCAN suffer from distance degradation across sparse manifolds. Most critically, the feature independence assumption that makes marginal methods such as HBOS, COPOD, and ECOD fast simultaneously prevents them from detecting anomalies that arise from coupled feature interactions. By scoring each feature independently, these methods are blind to structural irregularities that manifest only through cross-feature dependencies.
4.3. Isolation-Based Methods
Isolation methods invert the density estimation paradigm: they assume anomalies are “few and different”, and identify them by how easily they can be separated through randomized partitioning. For Isolation Forest (IForest), the standard anomaly score is:
where is the path length of in a random isolation tree, is its expectation across the ensemble, and normalizes by the expected path length for n samples. Shorter average path lengths produce larger anomaly scores.
IForest [12] recursively selects a random feature and a random split value between its value bounds, identifying anomalies via the shortest average path length without computing pairwise distances or densities. Because standard IForest enforces strictly axis-parallel splits, it creates rigid axis-aligned partitions and can produce “ghost” regions that obscure local anomalies. SCiForest [48] and EIF [49] replace axis-parallel splits with random oblique hyperplanes, enabling partitions that better align with correlated feature structure. DIF [81] further extends this idea by applying isolation after nonlinear deep representation mapping. To localize the mechanism, iNNE [50] replaces global partitions with localized hyperspheres that adapt to varying density manifolds. This sphere-based paradigm has led to mathematically rigorous similarity measures such as the Isolation Kernel [51] and Isolation Distributional Kernel [52], while recent methods such as ADERH [99] refine hypersphere-based isolation boundaries.
Isolation-based methods are scalable and remain strong unsupervised baselines. The main limitation of standard IForest lies in its use of rigid axis-parallel splits, which provide only an approximate isolation measure. This can lead to reduced sensitivity when anomalies arise from specific feature combinations, subgroup-specific normality, or coherent groups of points. Subsequent extensions, such as oblique and hypersphere-based splits, as well as kernelized isolation methods, have addressed many of these limitations, improving detection of clustered anomalies.
4.4. One-Class Boundary Methods
We define one-class boundary methods as detectors that characterize normality through a compact region enclosing the normal data and score a sample by its deviation from that region. A common support-estimation form is:
where is a feature map (potentially nonlinear via a kernel), is the center of the normal support, and R is a radius or margin parameter. Positive scores indicate that the sample lies outside the learned boundary.
OCSVM [22] maps data into a kernel feature space and learns a maximum-margin hyperplane that separates normal samples from the origin. SVDD [53] instead encloses normal data within a minimum-volume hypersphere, using slack terms to tolerate boundary noise. These methods are mathematically principled and can perform well when normal data occupy a compact support under a suitable kernel.
However, their effectiveness depends critically on kernel hyperparameter selection, and a single compact boundary often fails to enclose normal data that form several disjoint clusters, a density structure common in tabular data. Attempting to enclose mixed-type samples within a continuous geometric enclosure regularly leads to model collapse. Moreover, dense kernel-matrix optimization requires quadratic memory and, for standard OCSVM solvers, cubic worst-case time in the number of training samples. When tabular anomalies stem from categorical inconsistencies rather than spatial deviations, the fitted boundaries may incur high computational cost while missing genuine non-spatial irregularities.
4.5. Projection-Based Methods
Projection-based methods assume that normal samples lie near a lower-dimensional structure and score anomalies by their deviation from that structure. If is an orthonormal basis spanning an r-dimensional subspace () with , a typical reconstruction-residual score is:
where the residual is large when a sample is poorly explained by the dominant r-dimensional subspace. When tabular datasets grow wide, full-dimensional distance and density metrics become unreliable, making subspace projections a natural alternative.
PCA [54] retains the principal components that capture most of the variance in the training data and scores each sample by its reconstruction residual—the portion that the retained subspace cannot explain. Anomalies manifest as samples with large residual energy along the minor components, indicating a violation of the normal correlation structure. KPCA [55] extends this idea to nonlinear structure by performing PCA in an implicit kernel feature space, so that the residual measures deviation from a nonlinear manifold rather than a linear subspace. ROD [56] applies random rotations before computing axis-wise distances, preventing anomalies aligned with the original coordinate axes from being masked by standard projections. SOD [57] builds a local subspace from each sample’s shared nearest neighbors and scores the sample by its deviation from that subspace, thereby detecting anomalies visible only within specific feature subsets.
The primary risk of projection and subspace methods in tabular settings is semantic distortion. Linear projections, nonlinear kernels, rotations, and subspace constructions all operate on numerical representations. If categorical features and missingness indicators are coerced into continuous vectors, the projection residual may reflect preprocessing artifacts rather than genuine abnormality. These methods are most informative when the table exhibits meaningful low-rank or clustered structure that is preserved after preprocessing.
5. Deep Task-Specific TAD
Deep task-specific TAD trains a neural network to score samples for an individual table and/or protocol. Compared with non-deep detectors, these models can learn nonlinear feature interactions and task-specific representations directly from data. They are most effective when the learned representation matches the anomaly manifestation; their main risk is that expressive networks can optimize a surrogate objective that is only weakly related to the anomalies of interest.
5.1. Reconstruction-Based Methods
Reconstruction methods learn an encoder-decoder or conditional prediction model and score samples by reconstruction error. The intuition is that a model trained to reconstruct normal samples will produce larger errors on anomalous samples, which deviate from the learned normal patterns. A generic formulation is:
where maps the input to a latent representation, reconstructs the sample from that representation, and is the reconstruction loss chosen to match the feature types (e.g., squared error for numerical features, cross-entropy for categorical features).
5.1.1. Probabilistic and Generative Models
Probabilistic reconstruction models map tabular inputs into latent distributions and isolate anomalies through reconstruction error or likelihood penalties. Standard Autoencoders [41] are the canonical reconstruction baseline, but over-parameterized networks can learn an identity mapping and reconstruct anomalies as well as normal samples. VAE [14] address this by enforcing a probabilistic prior on the latent space. To handle tabular-specific challenges, -VAE [100] applies stronger latent regularization to encourage disentangled representations, while FeaWAD [58] uses feature-weighted reconstruction to reduce the influence of uninformative dimensions.
Diffusion models have recently been adapted for tabular anomaly detection. The core idea is to gradually corrupt data with noise through a forward diffusion process and to train a model that reverses this process; anomalies, which lie in low-density regions of the data distribution, are then identifiable because the model struggles to denoise or reconstruct them accurately. DTE [59] avoids the expensive iterative reverse chain by instead estimating the distribution over diffusion timesteps for each input. Because normal samples reside in high-density regions, they are associated with shorter diffusion times, whereas anomalies require longer diffusion paths; the estimated timestep therefore serves directly as the anomaly score. TabADM [60] integrates rejection sampling into the training pipeline to reduce the influence of contaminating anomalies, and TCCM [61] replaces the multi-step reverse process with a single-step velocity field, enabling scoring in a single forward pass and addressing the inference latency of standard diffusion pipelines. Generative models can capture complex nonlinear feature interactions, but they risk over-calibrating to irrelevant dimensions. For deployment, the inference cost and calibration behavior of diffusion-based methods must be weighed against their ranking improvements.
5.1.2. Masked-Prediction and Dependency-Modeling Methods
Masked prediction shifts the paradigm from global reconstruction to conditional dependence modeling. Instead of reconstructing entire samples, these methods corrupt or mask a subset of features and train the model to infer the masked values from the remaining features. Anomalies are then identified as samples whose feature values are hard to predict from context:
where M denotes the set of masked features, are their true values, and are the predictions conditioned on the unmasked features. This formulation targets dependency anomalies: a sample is suspicious when its feature values are inconsistent with what the remaining features predict.
MCM [62] trains a learnable mask generator that produces multiple diverse soft masks over the input features; a reconstruction network then recovers the original values from each masked version. A diversity loss ensures that different masks expose complementary inter-feature correlations. During inference, anomalous samples violate these learned correlations and incur high average reconstruction error across masks. NPT-AD [63] builds on Non-Parametric Transformers and introduces two complementary attention mechanisms: attention between features captures intra-sample dependencies, while attention between datapoints allows each test sample to draw on the entire training set during inference. Because both attention mechanisms are trained exclusively on normal samples, anomalous inputs receive weaker contextual support and produce larger prediction errors. RAAD [64] reduces the quadratic cost of this operation through retrieval-augmented neighbor injection. To address feature entanglement, SemanticMask [65], Dist-TAD [66], and PTAD [67] leverage column semantics, disentangled reconstruction, and global prototypes respectively. Masked prediction aligns naturally with dependency anomalies in tabular data, but it is susceptible to proxy mismatch: if the masking distribution does not reflect the dependencies that define real anomalies, a model can solve the pretext task while missing deployment-relevant abnormality.
5.1.3. GAN-Based Methods
Generative adversarial networks (GANs) consist of a generator that learns to produce realistic samples from the normal data distribution and a discriminator that distinguishes generated samples from real ones. For anomaly detection, the key idea is that a GAN trained on normal data can serve as a reference model of normality: anomalies are samples that the generator cannot faithfully reproduce or that the discriminator recognizes as inconsistent with the learned distribution. AnoGAN [68] operationalizes this by searching, at test time, for the latent code whose generated output is closest to the input; the residual between the input and its best reconstruction serves as the anomaly score, though this iterative search is computationally expensive. ALAD [69] eliminates the test-time optimization by jointly training an encoder alongside the generator, so that both mapping directions are available in a single forward pass. For high-dimensional tabular spaces, MO-GAAL [70] synthesizes pseudo-anomalies near the fringe of the normal support to sharpen the discriminator boundary, while ATDAD [71] uses dual encoders with cycle consistency to handle mixed numerical and categorical features. GAN-based methods can learn discriminative boundaries without explicit anomaly labels, but they are sensitive to training instability and mode collapse on imbalanced, mixed-type data. Therefore, reported gains should be interpreted alongside stability analyses and contamination sensitivity.
5.2. Contrastive and Transformation-Based Self-Supervised Methods
Standard self-supervised augmentations designed for images, such as rotation [101] or cropping [102], exploit spatial locality and continuity that tabular data does not possess: columns have no inherent ordering, and each feature carries its own type and scale [23]. This family instead designs tabular-native surrogate tasks whose error or representation inconsistency serves as the anomaly signal:
where is a tabular-specific transformation, masking rule, or view construction, and measures prediction, alignment, or ranking error. Unlike image-based pretexts, tabular transformations must preserve the intrinsic inter-feature dependencies; otherwise the surrogate task may introduce artificial patterns that do not correspond to real anomalies.
Among transformation-based methods, RDP [72] trains a neural network to predict pairwise distances between samples in a randomly projected subspace; the learned representation preserves the distance structure that separates normal data from anomalies. NeuTralAD [15] learns a set of neural-network transformations end-to-end alongside an encoder via a deterministic contrastive loss: each transformation maps a sample to a different view, and normal samples maintain consistent cross-view relationships, while anomalies break this consistency. SLA2P [73] injects adversarial perturbations around random projection pseudo-classes to expose predictive uncertainty, while SLAD [74] treats the relationship between feature-subset dimensionality and its latent-space dimensionality as a supervisory signal for capturing scale-invariant normal patterns. In contrastive formulations, the primary challenge is constructing valid positive and negative pairs without treating hidden anomalies as normal exemplars. ICL [16] addresses this by generating views from single samples through masking, while PCLAD [75] constructs proxy negatives through feature subspace partitioning and recombination. Semi-supervised variants incorporate limited labels: PReNet [76] predicts pairwise relational boundaries, RCA [77] uses dual collaborative autoencoders to filter contamination, and RoSAS [78] employs contamination-resilient ranking objectives.
The principal advantage of self-supervised methods is their ability to derive supervisory signals without anomaly labels. Their critical weakness is proxy mismatch: if the surrogate task teaches the model to be invariant to the exact feature interactions that define a real anomaly, the detector can achieve low surrogate loss while failing to flag meaningful abnormalities at deployment.
5.3. Representation Learning-Based Methods
While reconstruction and proxy tasks optimize indirect objectives, representation learning methods directly shape the latent feature space to separate normal and anomalous patterns. Samples are first mapped to latent vectors:
and scored by a simple rule in this learned space. The goal is to learn a representation in which a straightforward detector, such as a distance to a center or a neighborhood-based score, becomes more effective than in the raw feature space. A typical scoring form is:
where is a learned geometric center, is a latent distance metric, denotes the k-nearest neighbors, and G aggregates neighborhood information.
5.3.1. Boundary-Based Learning
These methods learn a neural feature map that concentrates normal samples into a compact latent region and score each sample by how far it falls outside that region. DeepSVDD [79] established this paradigm by jointly training a deep network and a minimum-volume hypersphere: the network maps inputs to a latent space while the objective pulls all normal representations toward a common center, so that samples distant from the center receive high anomaly scores. AE1SVM [103] scales the approach by replacing the kernel trick with Random Fourier Features. To incorporate limited supervision, DeepSAD [33] adds a repulsion term that pushes labeled anomalies away from the normal center, and DevNet [34] optimizes deviation scores against a prior reference distribution to establish explicit discriminative margins. VOS [104] addresses boundary overconfidence by synthesizing virtual outliers in low-density latent regions. A single compact hypersphere may, however, fail to capture normal data that form several disjoint clusters, and boundary parameters set in sparsely populated latent regions risk overconfident predictions.
5.3.2. Distance-Based Learning
We group under distance-based learning those methods that, rather than committing to a single geometric center, learn a latent space that preserves relative proximity structure so that anomalies are identifiable by their displacement from normal neighbors. REPEN [80] trains a representation network with a triplet ranking loss derived from random distance-based outlier scores: the network learns to embed samples such that the distance-based ranking in the latent space is consistent with the ranking in random subspaces. DIF [81] projects samples through multiple independently trained deep networks into diverse subspaces and applies isolation-based scoring in each, aggregating the results to reduce the bias of any single projection. DRL [23] employs orthogonal basis weighting to decompose the representation into independent components, reducing the feature entanglement that causes normal and anomalous samples to overlap. These methods handle high dimensionality effectively, but latent distance metrics remain sensitive to categorical embeddings and numerical scaling: rare but legitimate subgroups may receive high anomaly scores if the learned representation does not preserve their relationship to the majority.
5.3.3. Graph-Based Learning
We refer to graph-based learning as methods that impose a relational topology on tabular samples, which inherently lack such structure, and then apply graph neural networks (GNNs) to learn from it. The typical construction builds a k-nearest-neighbor graph in the feature space, where each sample is a node and edges connect it to its closest neighbors. GNN message passing then aggregates neighborhood information: a normal sample surrounded by similar neighbors receives consistent messages that reinforce its representation, whereas an anomaly embedded among dissimilar neighbors produces discordant aggregations that elevate its anomaly score. LUNAR [82] implements this idea by encoding local distance vectors as edge features in a trainable GNN. RDRN [83] uses sparse self-representation to select the most informative neighbors under noise, R-Graph [84] models anomalies as transient states in a Markov random walk over the constructed graph, and GAE [85] applies graph convolutions to amplify the structural dissonance of low-deviation outliers. These methods can capture relational anomalies hidden within dense clusters, but their effectiveness depends on graph construction quality: if the graph-building heuristic misrepresents heterogeneous feature interactions, message passing amplifies preprocessing artifacts rather than genuine anomaly signals.
6. LLM-Based TAD
LLMs have introduced a new dimension to TAD by enabling additional context and metadata to be incorporated into anomaly detection through semantic interpretation and reasoning. Unlike traditional detectors that operate on preprocessed tabular data alone, LLM-based methods can exploit schema descriptions, column names, units, category descriptions, and domain rules, information that is typically discarded by standard encoding pipelines. The key question is whether the LLMs can effectively leverage the auxiliary information introduced in Equation (2) to make more informed and reliable anomaly judgments. Based on the functional role of the language model in the detection pipeline, LLM-based TAD methods fall into two categories. Direct detection methods use the language model itself to produce anomaly scores or classifications. LLM-assisted enhancement methods use language models to support conventional detectors through feature generation, algorithm enhancement, or result critique, while the final anomaly scores may still be computed by non-LLM models.
6.1. LLM-Based Direct Detection
Direct LLM-based TAD converts tabular data into textual representations and leverages the semantic and reasoning capabilities of an LLM for anomaly assessment. Because LLMs natively process token sequences rather than structured tables, each sample must first be serialized, that is, transformed from a set of feature–value pairs into a textual sequence [29,105]. Common serialization formats include natural-language descriptions, key–value sequences, and JSON-like representations [86,105]. The appeal of this approach is its ability to exploit textual priors, schema semantics, and categorical meanings that are invisible to traditional encoding methods. A generic formulation serializes a sample and its auxiliary information:
where is the serialization template that converts sample and auxiliary information into a textual prompt, may include column descriptions, dataset context, and task instructions, and is the resulting textual input to the LLM. For example, a sample with , , and can be serialized as “The individual is 35 years old, works as a technician, and has an annual income of 50,000.” The function denotes an LLM-based anomaly scoring function parameterized by , where represents the LLM parameters. denotes the resulting anomaly score for , either produced directly by the LLM or derived from its output. The LLM may additionally provide an anomaly label, a textual judgment or explanation, localized anomalous features, or a likelihood estimate, depending on the prompting and output design. Two primary techniques are used: prompting, in which is kept frozen, and fine-tuning, in which or a subset of trainable parameters is updated for the target TAD task.
6.1.1. LLM Prompting for TAD
Prompting-based methods keep LLM parameters fixed and guide anomaly assessment through task instructions, schema descriptions, demonstrations, or structured reasoning templates. ReTabAD [19] serializes each record with semantic context, including dataset background, feature descriptions, normal-value ranges, and domain knowledge. The LLM then produces an anomaly score, identifies the features most responsible for the judgment, and provides a textual explanation. TABARD [35] targets fine-grained cell-level anomalies by asking the LLM to locate suspicious cells. Its multi-path strategy generates independent chain-of-thought analyses, verifies candidate cells within each path, and aggregates the results by majority voting, whereas its single-path variant performs detection and verification without cross-path aggregation. TAD-GP [86] targets cybersecurity data under resource-constrained settings. It represents each network record in a JSON-like format and enriches the prompt with normal and anomalous demonstrations and predefined anomaly categories. Chain-of-thought reasoning, multi-turn interaction, and repeated emphasis on task-relevant information guide a smaller LLM in classifying each record. Together, these methods show that prompting can integrate schema semantics, domain knowledge, demonstrations, anomaly taxonomies, and explicit reasoning without task-specific parameter updates. However, performance remains sensitive to numerical representation, serialization and column order, prompt and demonstration design, context-window limits, and the inference cost of processing samples or table segments individually.
6.1.2. LLM Fine-Tuning for TAD
Fine-tuning adapts a pretrained LLM to TAD by updating either its full parameter set or a smaller set of trainable parameters. Let denote the parameters optimized during fine-tuning. Under full-parameter fine-tuning, includes all model parameters; under parameter-efficient fine-tuning, it includes only the additional trainable parameters introduced by methods such as LoRA [106]. A generic objective is
where is the fine-tuning dataset, is the serialized input, and is its corresponding training target. Depending on the learning formulation, may be an anomaly label, a textual sequence identifying anomalous samples, or the next token in a serialized normal record. The optimized parameters are denoted by , and denotes the fine-tuning loss, such as a token-level generation loss for anomaly decision learning or an autoregressive negative log-likelihood for normality modeling.
Li et al. [17] performs supervised fine-tuning on synthetic batches containing normal and anomalous samples. For continuous features, the two groups are sampled from narrow and broad Gaussian distributions, respectively; for categorical features, they are sampled from different categorical distributions. LoRA parameters are optimized with a token-level generation loss, enabling direct generation of anomalous record indices. AnoLLM [18] instead performs unsupervised normality modeling on anomaly-free samples by fine-tuning a small open-source LLM. Autoregressive next-token prediction assigns high likelihood to feature values and combinations typical of normal data, while higher negative log-likelihood at test time indicates greater anomalousness. CausalTAD [87] follows the same likelihood objective but introduces causal column ordering and causal-aware scoring. It predicts each feature from causally relevant predecessors rather than an arbitrary column sequence and combines column-wise negative log-likelihoods using causal weights, assigning high scores when expected causal relations are violated.
6.2. LLM-Assisted Enhancement
Direct LLM-based detection offers a flexible language interface but may suffer from numerical imprecision, serialization sensitivity, high context costs, and potential data-exposure risks. This motivates an indirect paradigm in which the LLM assists rather than replaces a conventional detector. Leveraging pretrained algorithmic and domain knowledge, the LLM can analyze detector assumptions, identify failure modes, and generate features, code, or critiques, while the conventional model retains responsibility for scalable and numerically grounded anomaly scoring. A generic abstraction is:
where denotes the method-specific context provided to the LLM, which may include the sample, training data, dataset metadata, detector descriptions, or intermediate evidence. The function denotes the LLM-assisted module, and is the generated auxiliary signal, such as features, code, model configurations, or evidence critiques. The signal may be sample-specific or shared across samples. The function denotes the numerical detection pipeline, which incorporates and produces the final anomaly score . This formulation separates language-mediated enhancement from numerical anomaly scoring.
MAD [88] treats tree-based, deep tabular, and tabular foundation models as detection agents. Each reports an anomaly score, confidence, and structured evidence. An LLM critic checks evidence–score consistency and conflicts, while a coordinator updates agent weights and produces a final score with an auditable debate trace. LLM-DAS [89] uses the LLM as an algorithm designer. Given a base detector’s description and pseudocode, it analyzes weaknesses and generates reusable Python code. Executed locally with the training data and fitted detector, the code uses training statistics and the scoring function to synthesize detector-specific hard anomalies. These samples train an enhancement classifier combined with the base detector. FLEX-AD [107] integrates LLM-generated feature-engineering code into AutoML. Candidate features are evaluated across models, useful ones retained, and selected models combined through weighted soft voting.
7. Foundation Model-Based TAD
Foundation model-based methods aim to reduce the need to train an anomaly detector from scratch for each dataset by reusing knowledge acquired through pretraining. We distinguish these methods according to what is pretrained and how the pretrained knowledge is transferred to TAD. Cross-table pretraining methods directly pretrain a shared TAD model on multiple source tables or synthetic detection tasks and apply it to unseen tables without target-specific parameter updates. Pretrained-model adaptation methods instead start from an existing general-purpose tabular or language model and adapt its pretrained knowledge to anomaly detection. The former enables direct cross-table reuse, whereas the latter reduces the cost of building a TAD model from scratch but may still require target-specific adaptation.
7.1. Cross-Table Pretraining Methods
We define cross-table pretraining methods as approaches that learn reusable anomaly-scoring knowledge from multiple source tables or synthetic TAD tasks. The resulting model can be applied to unseen target tables without target-specific parameter updates, avoiding the need to fit a separate detector for each dataset.
A compact scoring form is:
where denotes a pretrained TAD model whose shared parameters are learned across source tables or synthetic TAD tasks. The optional context contains information from the target table that is available at inference time, such as anomaly-free support samples, unlabeled samples, or partially labelled examples, while represents optional metadata or task information. The context is used to condition anomaly predictions without updating ; for methods that require no target-table context, . Unlike the task-specific models discussed in Section 5, remains fixed when the model is applied to the target table.
A prominent route builds on Prior-data Fitted Networks (PFNs), which are pretrained on synthetic tasks sampled from a prior over possible data-generating mechanisms. This task-level pretraining allows a Transformer to learn a reusable prediction procedure and perform inference on a new table from a context set without gradient-based parameter updates. TabPFN [20] is a representative application of this paradigm to supervised tabular prediction. Recent TAD methods adapt the same PFN framework to anomaly detection. FoMo-0D [21] applies the PFN framework to zero-shot tabular outlier detection. Its synthetic tasks sample inliers from Gaussian mixture models and generate subspace outliers by inflating the covariance along randomly selected dimensions. Given an inlier-only context set and a query sample, the frozen model directly predicts whether the query is normal or anomalous. OutFormer [90] broadens this synthetic distribution by combining Gaussian-mixture, structural-causal, and copula-based priors, and introduces a self-evolving curriculum to balance heterogeneous tasks. ICLAD [91] extends the paradigm across one-class, unsupervised, and semi-supervised settings by varying context contamination and label availability during pretraining. TACTIC [92] uses anomaly-focused synthetic tasks that vary the anomaly type, anomaly rate, and context contamination level, improving robustness in fully unsupervised target settings. Beyond PFN-style synthetic-task pretraining, OFA-TAD [93] learns a transferable distance-based anomaly scorer across source tables. It represents samples through normalized nearest-neighbour distance profiles in multiple transformed metric spaces. View-specific experts score these profiles, and a gating network combines their outputs. The MoE [108] scorer is trained on source-table normal samples and synthetic pseudo-anomalies, then applied to target tables without target-specific retraining or fine-tuning, using target normal samples for neighbour retrieval and distance normalization.
7.2. Pretrained-Model Adaptation Methods
We define pretrained-model adaptation methods as approaches that adapt existing pretrained tabular or language models to TAD instead of training a dedicated TAD foundation model from scratch. By reusing pretrained structural or semantic knowledge, they reduce data and computational costs. The main challenge is to align these generic representations with anomaly-sensitive patterns under limited or noisy supervision. Anomaly scoring can be written as:
where denotes the parameters obtained by adapting an existing pretrained tabular or language model to TAD. Depending on the method, adaptation may use source-task data, target-table samples, or task information. The adapted detector assigns an anomaly score to the target sample , optionally conditioned on target-table context and task information .
ICAD-LLM [94] adapts a pretrained LLM to anomaly detection across heterogeneous tasks and modalities. A modality-aware encoder first projects tabular samples and other inputs into the LLM embedding space. The LLM jointly encodes a target sample and a normal reference set, while contextual contrastive learning draws normal targets closer to the reference representation and pushes anomalies farther away. Once trained across source tasks, the model scores unseen samples according to their discrepancy from the provided normal references without target-specific parameter updates. ProFiT [95] instead adapts a pretrained tabular in-context learning model to a specific target table using its unlabeled samples. It constructs proxy tasks by selecting one feature as the prediction target and correlated feature subsets as inputs, and fine-tunes the model using proxy-prediction and cross-view consistency losses. At inference time, labelled anomalies and detector-selected pseudo-normal samples form the support set for few-shot anomaly classification.
8. Enhancement and Adaptation for Deployment
Designing or selecting a TAD detector is not the end of building a usable TAD system. The detectors reviewed in Section 4 to Section 7 return anomaly scores or a ranked list of suspicious samples, but deployment raises further questions. Can the training signal be strengthened through data augmentation (Section 8.1)? Can the scores of one or more detectors be corrected, calibrated, or made cheaper to use (Section 8.2)? Can the detector operate when privacy or data-ownership restrictions prevent the data from being gathered in one place for training, or when the computation budget is limited (Section 8.3)? Can limited analyst review improve later rankings (Section 8.4)? This section reviews these operations as practical enhancements and adaptations to an already available detector, rather than introducing a fifth detector family.
8.1. Data Augmentation for Existing Detectors
Many TAD settings provide abundant unlabeled or mostly normal samples but few verified anomalies. A detector trained under this imbalance may learn a weak notion of abnormality: it models common samples well, yet it receives little direct evidence about the deviations that should be ranked highly. Data augmentation addresses this gap by adding proxy abnormal samples during training. The detector itself is not replaced; its training data are enriched so that normal samples and generated abnormal samples become easier to separate.
LLM-DAS applies this idea in a detector-aware way. Rather than asking an LLM to judge table rows directly, it asks the LLM to write anomaly-synthesis code that targets the weaknesses of a chosen detector, so the generated hard anomalies expose exactly the cases the detector would otherwise score poorly [89]. Deep Noise Evaluation takes a broader, noise-based route: it produces abnormal samples by injecting diverse noise into the training table and trains a neural detector to distinguish clean samples from their noisy counterparts [109]. Both methods strengthen the training signal with auxiliary abnormal samples, but their motivations differ: blind-spot exposure is central to LLM-DAS, whereas Deep Noise Evaluation uses noise mainly as a general source of contrast.
The main limitation is proxy mismatch. Synthetic or noise-based anomalies can be too easy, too artificial, or too close to the generation rule used by a benchmark, so improvements on proxy samples do not guarantee that real domain anomalies will be found. Future work should make augmentation more domain-aware, quantify how generated anomalies differ from true anomalies when labels permit, and verify that augmentation improves the cases analysts actually review rather than only aggregate ranking scores.
8.2. Score Adaptation and Reuse
After training, a detector’s raw score is rarely the final deployment artifact. Score scales are unstable across datasets, a single detector may miss certain anomaly patterns, and running a large set of detectors naively may be too expensive. Score adaptation methods operate at this stage: they take the outputs of existing detectors as given and make those outputs more accurate, more comparable, or cheaper to obtain.
UADB is a post-hoc booster for unsupervised detectors: it treats the scores of a source detector as pseudo labels, trains a booster network on them, and uses the disagreement between source and booster to iteratively refine the pseudo labels, correcting the original ranking without redefining the detector [110]. CTAD also starts from an existing score but aims at calibration: it uses optimal transport to estimate how strongly a test sample perturbs the structure of the normal data, yielding scores with more stable meaning across detectors and tables [111]. SUOD addresses a cost problem rather than an accuracy problem: when practitioners want to run a large pool of heterogeneous detectors, it combines random projection, pseudo-supervised approximation of slow detectors, and balanced parallel scheduling to keep the full pool within practical time and memory budgets [112].
These methods should not be mistaken for a complete alerting policy: boosted, calibrated, or accelerated scores must still be consumed by a downstream rule, such as a fixed review budget, a contamination assumption, or a domain-specific threshold. Their limitations also differ. UADB inherits the quality of its source detector and can amplify its mistakes; CTAD requires a meaningful reference set of normal data and adds calibration cost; SUOD makes large detector pools feasible, but which detectors to include and how to balance speed against accuracy remain open design choices. Future work should therefore report not only AUROC or AUPRC, but also how many samples are reviewed, how thresholds are chosen, and the runtime and memory budget the adapted scores require.
8.3. Deployment Under Access and Resource Constraints
Real tabular data are constrained by ownership, privacy, scale, and inference cost. A TAD study intended for deployment should therefore specify not only which detector is used, but also where the data reside, what information may be shared, and what computational budget is available.
Federated and privacy-preserving settings make the access constraint explicit. FedAD-Bench evaluates unsupervised anomaly detection on federated tabular data, where samples are distributed across clients and cannot be pooled into a centralized training table; its results show that client partitioning, heterogeneity, aggregation behavior, and communication cost all shape the conclusions, so centralized accuracy alone is not a valid reference [113]. PIF provides a privacy-preserving example built on isolation forests: parties holding horizontally or vertically partitioned tables collaboratively grow isolation trees without exposing their raw samples to any single party, reaching accuracy comparable to a centralized iForest [114].
Resource constraints arise even when access is simple. Methods that run many detectors at once, such as SUOD, must justify that training and scoring all of them fit the available time and memory [112]. The LLM-based detectors of Section 6 introduce yet another cost profile: in AnoLLM and TAD-GP, row serialization, prompt length, model size, and per-sample inference cost become part of the method’s practical behavior, and TAD-GP adopts a small language model precisely because of such budgets [18,86]. The limitation across this literature is that these costs are reported far less systematically than ranking accuracy. Deployment studies should disclose inference mode, hardware, batch size, latency or throughput, memory, token usage where applicable, and communication cost in distributed settings.
8.4. Human-in-the-Loop Review and Feedback
In many applications, the final definition of an anomaly is semantic and domain-specific: whether a suspicious transaction, a medical record, or a data-quality issue truly matters is decided by an analyst. Human-in-the-loop TAD treats this review as part of the system. The detector proposes candidates, an analyst inspects a limited number of them, and the feedback is used to improve later rankings or detector combinations.
Active Anomaly Discovery makes the loop explicit: an expert labels selected high-priority instances, and the detector ensemble is re-weighted toward the expert’s notion of interesting anomalies [115]. Feedback-guided anomaly discovery studies the same loop under a limited inspection budget and optimizes the scorer online so that true anomalies are discovered faster than a static ranking would allow [116]. GLAD uses feedback to learn local relevance weights for a pre-trained detector ensemble, so different detectors can be trusted in different regions of the feature space [117].
The key caveat is that feedback changes the supervision regime: once analyst labels update the ranking, the system is no longer purely unsupervised, even if the initial detector was. Results consequently depend on the review protocol, including how many samples are shown per round, how candidates are selected, how noisy the feedback is, and how often the model is updated. Future work should report cumulative discovery curves, precision among reviewed cases, and time-to-discovery, because these reflect a review workflow far better than a single final ranking metric.
9. Benchmarks and Evaluation Protocols
Benchmarks determine which empirical claims about TAD are meaningful and which are not. A benchmark encodes a set of design choices, including data sources, anomaly construction, semantic context, supervision setting, contamination level, detection granularity, and evaluation metric. Each choice constrains the conclusions that benchmark results can support. This section reviews the major public TAD benchmarks along these dimensions. Table 2 provides a side-by-side comparison of scale, data types, anomaly categories, supervision regimes, and metrics; the text below highlights the distinctions that matter most to interpret and design experiments.
9.1. Landscape of Existing Benchmarks
Table 2 summarizes eight representative benchmarks discussed here.They span three generations of benchmark design.
Early benchmarks by Emmott et al. [118] and Campos et al. [119] largely repurposed existing tabular classification datasets, many drawn from or related to the UCI Repository [120], a widely used collection of real-world machine-learning datasets. These studies established an early empirical basis for comparing unsupervised detectors by systematizing dataset variants, preprocessing choices, and evaluation measures. However, they were limited to numerical features, derived from only several source datasets, and relied on anomaly definitions that often conflated class rarity with abnormality.
A second generation pursued scale, standardization, and controlled anomaly construction. Steinbuss and Böhm [36] introduced realistic synthetic anomalies with controllable types (global, local, and dependency), motivated by the observation that anomalies in existing benchmarks have mixed and unknown characteristics that make it difficult to judge why a detector succeeds or fails. OAB [121] provided an open evaluation framework, aiming to standardize key benchmarking steps such as preprocessing, sampling, train–test splitting, and metric computation while supporting reproducible and extensible comparison of anomaly detection algorithms. ADBench [1] became the most widely adopted benchmark in this generation, offering 47 real-world tabular datasets from diverse domains (healthcare, finance, cybersecurity, and others), partly consolidated from earlier resources such as the ODDS Library [122], together with 10 datasets derived from image and text embeddings, three supervision regimes (unsupervised, semi-supervised, and fully supervised), and standardized evaluation of 30 algorithms.
The most recent generation shifts toward semantics-preserving and LLM-oriented evaluation. These resources advance the evaluation of how detectors utilize semantic context, moving beyond evaluation paradigms based solely on numerical metrics. TABARD [35] introduces the first LLM-oriented cell-level anomaly benchmark with 5,295 perturbed tables sourced from WikiTQ, FeTaQA, Spider, and BEAVER, eight semantic anomaly categories (value, factual, logical, temporal, calcaulation-based, security, normalization and data consistency). ReTabAD [19] curates 20 real-world datasets and restores column names, textual values, and structured JSON metadata (dataset descriptions, column descriptions, normal value ranges, and domain knowledge) that earlier benchmarks had stripped away. MacrOData [123] is a recent large-scale TAD benchmark that combines statistical outlier detection with semantic anomaly analysis by providing semantic metadata and semantic anomaly definitions. It includes OddBench for semantic anomalies, OvRBench for statistical outliers constructed via one-vs-rest repurposing, and SynBench for synthetic statistical outliers generated from diverse data priors.
9.2. Key Dimensions of Variation
The benchmarks in Table 2 vary across multiple dimensions that determine the evidential scope of evaluation.
9.2.1. Anomaly Provenance
The benchmarks in Table 2 mainly adopt three anomaly provenance modes. Real-world anomalies, used in Emmott et al. [118], Campos et al. [119], ADBench [1], ReTabAD [19], and parts of MacrOData [123], preserve practical relevance because anomalous instances or labels come from existing datasets or domain records. However, such anomalies often mix multiple anomaly types, making it difficult to determine which detection capability a method actually demonstrates. Statistical synthesis, adopted by Steinbuss and B"ohm [36], OAB [121], ADBench, and MacrOData, injects anomalies with controlled statistical properties, enabling scalable and interpretable evaluation across global, local, dependency, and clustered anomalies. Its limitation is that it may simplify the mechanisms behind authentic anomalies. Semantic synthesis, represented by TABARD [35], uses LLM perturbations to create typed cell-level anomalies for evaluating semantic reasoning and evidence localization. Its validity depends on the available table semantics and the reliability of the perturbation process. These provenance modes broaden the evaluation scope of TAD, but also make cross-benchmark comparison more complicated.
9.2.2. Semantic Context
Earlier mainstream TAD benchmarks usually retain only numerical features and remove column descriptions, thereby discarding semantic information. This makes semantic anomalies (Section 2) difficult to detect and limits meaningful evaluation of recent LLM-based methods (Section 6). Recent benchmarks have therefore proposed to preserve semantic metadata. MacrOData retains column names and dataset keywords. ReTabAD provides the richest semantic layer, including structured JSON metadata with dataset descriptions, column descriptions, measurement units, normal value ranges, and domain knowledge. TABAR preserves raw column names and textual cell values, enabling evaluation of LLM-based detection through semantic understanding.
9.2.3. Detection Granularity
Most benchmarks, such as ADBench, MacrOData and ReTabAD, operate at the sample level: each row is labeled normal or anomalous, and evaluation asks whether suspicious rows are ranked above normal ones. TABARD is the exception. It provides cell-level labels for fine-grained anomalies indicating cells within a row contain anomalous evidence for localization (related to Section 10). TABARD is the exception. It provides cell-level labels for fine-grained anomalies, indicating which cells within a row contain anomalous clues for evidence localization (Section 10).
9.2.4. Supervision Settings
Training supervision follows the definitions in Section 2. All benchmarks formally support unsupervised training that involves no labels. ADBench, OAB, and MacrOData further support semi-supervised evaluation with limited labels and one-class evaluation with normal-only training, while ADBench also includes fully supervised evaluation with labeled anomalies. TABARD and ReTabAD are broadly associated with unsupervised or one-class protocols, with LLM-oriented evaluation performed through zero-shot or in-context prompting without task-specific training.
9.2.5. Anomaly Ratio
Anomaly ratio denotes the proportion of anomalous instances in a benchmark, affecting class imbalance and metric interpretation. Table 2 reports the anomaly ratios used by each benchmark. Emmott et al. control contamination between 0.1% and 10%; ADBench inherits per-dataset contamination rates ranging from 0.17% to 39.91%; TABARD uses 50% contamination at the cell level; and MacrOData fixes contamination at 5%–20%. When comparing results across benchmarks, differences in anomaly ratio level can be as consequential as differences in detector design.
9.3. Evaluation Metrics
TAD evaluation commonly relies on threshold-free ranking metrics for sample-level detection and set-based retrieval metrics for finer-grained tasks, reflecting different emphases.
For sample-level detection, earlier TAD benchmarks report metrics such as Average Precision (AP) [124] and Precision@n (P@n) [125], but recent ones mainly standardize evaluation around the Area Under the Receiver Operating Characteristic Curve (AUROC) [79] and the Area Under the Precision-Recall Curve (AUPRC) [126], as they provide threshold-free ranking summaries and better support comparison under varying anomaly ratios. AUROC can be interpreted as the probability that a labeled anomalous sample receives a higher anomaly score than a labeled normal sample. It provides a threshold-free summary of ranking quality, but can be insensitive to differences in regions with low false positive rates when anomalies are rare. AUPRC summarizes the trade-off between precision and recall across thresholds and is generally more informative under severe class imbalance, which is the norm in TAD. For cell-level detection tasks such as TABARD, precision, recall, and F1 score are more appropriate because evaluation concerns whether individual anomalous cells are correctly localized. Precision penalizes excessive false cell-level alarms, recall measures coverage of true anomalous cells, and F1 score summarizes their balance.
9.4. Matching Benchmarks to Research Claims
Different benchmarks support different kinds of empirical claims. Mismatching a benchmark to a claim undermines the evidence, regardless of the detector’s performance. The following guidelines discuss benchmark selection across scenarios.
General-purpose detector comparison under conventional supervision settings is best served by ADBench and MacrOData. ADBench offers the most comprehensive protocol across unsupervised, semi-supervised, and supervised regimes on 57 datasets with real-world anomalies from diverse application domains; MacrOData tests whether conclusions generalize at much larger scale (2,446 datasets) under unsupervised and one-class settings, while revealing the limits of smaller suites. Both are primarily value-based benchmarks and therefore are not sufficient on their own for evaluating semantic-aware or metadata-aware detection.
Controlled anomaly-type analysis examines a detector’s sensitivity to predefined anomaly types. For global, local, dependency, and clustered anomalies, suitable benchmarks include ADBench, Steinbuss and Böhm, and MacrOData, which use controlled synthetic anomaly injection to decouple these anomaly types and evaluate them separately. Moreover, Semantic anomalies extend this analysis beyond statistical deviation, as they require retained table metadata and semantic context. For this setting, ReTabAD supports sample-level semantic anomaly ranking under zero-shot LLM protocols, while TABARD supports cell-level semantic anomaly localization across predefined categories.
Cross-benchmark validation strengthens any claim. A result that holds on both a broad value-only benchmark (ADBench or MacrOData) and a semantics-preserving benchmark (ReTabAD) provides stronger evidence than either alone, because it indicates robustness to statistical anomalies while showing that semantic reasoning adds genuine value rather than merely compensating for weak value-level detection.
10. Downstream Tasks Built on TAD Outputs
Tabular anomaly detection (TAD) is centered on sample-level scoring: a detector ranks rows according to how suspicious they are. In practice, however, a ranked list is only the starting point for further investigation. Users may need to explain why a score is high, localize the cells or feature relations that carry the suspicious evidence, diagnose the abnormality under schema, units, category semantics, or domain rules, and repair erroneous values when the alert reflects a data error. We refer to these uses as downstream tasks. They consume TAD outputs, but differ from the TAD task in their questions, outputs, annotations, and evaluation criteria.
Score Explanation. Score explanation turns a scalar anomaly score into an inspectable object, such as feature-level contributions, additive score components, local perturbation effects, or prototype comparisons. In a TAD workflow, the detector identifies which rows should be inspected, while the explanation task makes the resulting score inspectable by showing how features, feature relations, or model components contribute to it. One route is intrinsic explanation, where interpretability is built into the detector. DIAD [127] is the main TAD-specific example in the current reference set. It adapts generalized additive models, a white-box model class, to tabular anomaly detection. Its anomaly score is represented through additive feature functions, so feature-level contributions are part of the scoring model rather than a post-hoc approximation. DIAD can also use a small amount of labeled data, matching practical settings where confirmed anomalies are scarce. Another route is post-hoc attribution. SHAP [128] is a representative general-purpose method for interpreting individual model predictions. In TAD, the prediction being explained can be an anomaly score or a binary alert derived from that score. SHAP-style explanations therefore provide an auxiliary task for inspecting how feature perturbations or feature coalitions affect the detector’s output. Such explanations support triage and review, but they should still be read as explanations of a score, not as proof that the highlighted feature is the true data error or the full cause of the abnormality.
Evidence Localization and Cell-Level Analysis. Evidence localization asks where the suspicious evidence lies inside a flagged record. It is related to explanation, but the target is different. Explanation is model-centered: it asks how the detector’s score was formed. Localization is evidence-centered: it asks which cell, column, interaction, or constraint is responsible for the abnormality. A row may be suspicious because of one impossible value, an unusual pair of ordinary values, a formatting irregularity, or a rule violation. Localization turns a row-level alert into a concrete target for inspection. TABARD [35] is the most relevant representative work for this task. It introduces a benchmark for tabular anomaly analysis, reasoning, and detection by perturbing tables from WikiTQ, FeTaQA, Spider, and BEAVER. The benchmark contains paired clean and corrupted tables and covers value, factual, logical, temporal, calculation-based, security, normalization, and data-consistency anomalies. Its setting is fine-grained and cell-level: models are expected to identify anomalous cells rather than only declare a table or row abnormal. For TAD, a row-level detector can first surface candidate records, while a TABARD-style task asks which cells or relations make those records suspicious.
Semantic Diagnosis and Reasoning. Semantic diagnosis asks what a detected abnormality means under the semantics of the table. It is different from score explanation and evidence localization. Explanation describes how a score was formed, and localization identifies where the suspicious evidence lies. Diagnosis interprets that evidence: whether it reflects an invalid range, an inconsistent category, a unit mismatch, a factual contradiction, a calculation error, or another domain-specific violation. This step often requires information that is not present in a value-only array, such as column names, feature descriptions, units, normal ranges, category meanings, dataset background, and domain rules. ReTabAD [19] is representative because it restores the semantic context needed to interpret tabular anomalies. It augments tabular datasets with structured metadata, including dataset-level and column-level descriptions, logical types, measurement units when available, label-level anomaly definitions, domain knowledge, feature descriptions, and normal statistics. It also provides a zero-shot LLM framework for using this context in anomaly detection. From a downstream perspective, ReTabAD shows that the same value may be normal or abnormal depending on its column meaning, unit, valid range, and domain convention. TABARD [35] further illustrates the reasoning side of semantic diagnosis. Its anomaly categories require models to interpret table content rather than only detect numerical deviation: factual anomalies depend on real-world knowledge, logical anomalies involve relationships between columns, temporal anomalies depend on event order or plausibility, and calculation-based anomalies require arithmetic consistency. In a TAD workflow, semantic diagnosis gives meaning to a flagged row by identifying the semantic or domain rule that has been violated.
Data Repair. Data repair corrects values that have already been confirmed as erroneous. Repair methods infer plausible replacements using integrity constraints, statistical dependencies, external reference data, or domain knowledge [32]. Unlike TAD, which ranks suspicious rows, data repair produces corrected values or candidate corrections for specific cells. HoloClean [129] formulates repair as probabilistic inference. For each target cell, it constructs a set of candidate values and prunes unlikely candidates using value co-occurrence statistics. It then combines integrity constraints, correlations among columns, external dictionaries, and a preference for retaining the observed value in a factor-graph model. Clean cells are used to learn the importance of these signals, and inference assigns a probability to each candidate; the most probable value is returned as the repair together with a confidence score. In a TAD workflow, anomaly scores can prioritize records for repair, while the repair module determines the actual correction. Repair quality is evaluated by correction accuracy, constraint satisfaction, and the utility of the repaired table.
11. Open Challenges and Future Directions
Several open problems remain in tabular anomaly detection. In this section, we highlight those we consider most fundamental for future research.
Robust dataset-specific detection for heterogeneous tabular data. Non-deep detectors remain strong baselines because they are simple, scalable, and often competitive under matched protocols. Their weakness is also clear: neighborhood, density, isolation, boundary, and projection principles all depend on an induced representation of mixed-type data. Categorical encodings, missing-value conventions, sparse one-hot spaces, and high-dimensional feature expansion can change the geometry that these methods rely on. Deep task-specific detectors address part of this issue by learning representations, but they introduce their own difficulties: reconstruction objectives can learn identity mappings, self-supervised proxies may not match the anomaly of interest, and expressive models can be slower and less stable than non-deep alternatives. Future TAD methods should therefore make their scoring assumptions explicit and test whether the assumed anomaly evidence survives preprocessing, representation learning, and high-dimensional compression [10,40,51,52]. A useful direction is not simply to replace non-deep detectors with deep ones, but to design detectors whose representations preserve mixed-type structure while keeping the reliability and efficiency that make non-deep methods difficult to dismiss.
The position of LLMs in TAD. LLMs offer semantic reasoning, code generation, and prior knowledge, but it remains unclear what their best role is in TAD. Directly serializing table rows into text can expose raw values, struggle with numerical and categorical representation, depend on prompt order, and become costly under long or wide tables [29]. Fine-tuning or in-context learning also raises questions about data access, privacy, input length, and whether language models are being asked to process a modality for which they are not naturally designed. Recent work suggests alternative interfaces. LLM-DAS uses the LLM as an algorithmist: the LLM reasons about detector logic and generates data-agnostic code for synthesizing hard anomalies, avoiding direct exposure of raw tabular samples [89]. DeLTa uses decision-tree rules as an intermediate representation, avoiding row serialization and LLM fine-tuning while leveraging LLM reasoning over structured rules [130]. These directions suggest a broader open question: should LLMs act as detectors, metadata interpreters, rule refiners, anomaly synthesizers, or pipeline assistants? Future TAD work should clarify this role, disclose what information the LLM sees, and evaluate privacy, numerical fidelity, prompt sensitivity, cost, and reproducibility alongside detection quality.
Toward anomaly-aware tabular foundation models. Foundation models for TAD are motivated by a defining difficulty of anomaly detection: the type of anomaly is rarely known in advance, and what counts as abnormal depends on the domain, schema, and context (Section 2). Cross-table pretraining promises to learn reusable detection priors from many tables [20,21,30,91,92,93], but the approach faces obstacles absent in classification. Tabular data lacks the structural priors that anchor foundation models in other modalities. Column order is arbitrary, feature types are heterogeneous, and no spatial or sequential structure guides cross-table representation learning, making it unclear what architectural choices enable genuine transfer rather than dataset-specific memorization. Cross-table transfer also introduces normality conflicts: a feature pattern anomalous in one schema may be entirely normal in another, and naive source aggregation risks averaging away discriminative signal. Current synthetic priors encode narrow distributional assumptions such as Gaussian covariance inflation, GMM outliers, and fixed contamination rates [21,90,92], and miss the dependency violations, conditional abnormalities, and semantic conflicts that constitute much of real-world anomaly diversity. Even at the target table, the anomaly distribution is typically unknown: training data may be contaminated, and no labels indicate which deviations matter. Progress requires joint advances in pretraining data curation, prior design spanning the full anomaly taxonomy, architectures that respect tabular properties such as permutation invariance and mixed types, and transfer mechanisms that adapt to a target table’s normality without anomaly supervision.
Anomaly detection in relational and multimodal settings. TAD operates almost exclusively on single preprocessed tables, yet real data is richer in two respects. First, many datasets reside in relational databases where multiple tables are linked by foreign keys [131]. An anomaly may be invisible in one table but become apparent when records are joined. Unlike the cross-table pretraining in Section 7, the challenge here is to detect anomalies arising from dependencies within the same database. Relational deep learning [131] and data cleaning methods [129] offer relevant infrastructure, but the former targets prediction and the latter typically requires predefined rules or labeled errors. Second, tables often coexist with images, text, or time series. Multimodal tabular learning has advanced rapidly for prediction [132,133], and cross-modal error detection has shown that some tabular errors are discoverable only via another modality [134], yet multimodal TAD itself remains unexplored.
12. Conclusions
Tabular anomaly detection has grown from classical scoring techniques into a broad field spanning non-deep detectors, deep task-specific models, LLM-based methods, and emerging foundation model-based methods. This breadth creates opportunities, but also makes comparisons difficult, as studies differ in anomaly manifestations, label regimes, information access, benchmark protocols, and score-use settings. This survey provides a unified account of TAD by organizing methods into major detector families and relating them to evaluation practice, enhancement and adaptation for deployment, and downstream use. We clarified the table-specific challenges that distinguish TAD from anomaly detection on images, sequences, and graphs; reviewed detector families by their modeling assumptions and targeted anomaly forms; summarized adaptation techniques, benchmark practices, and evaluation protocols; and discussed downstream tasks for score explanation, evidence localization, semantic diagnosis, and data repair. These perspectives show that progress in TAD depends not only on stronger detectors, but also on explicit assumptions about retained information, protocol access, contamination, evaluation, and score interpretation. This survey provides a clearer basis for understanding existing TAD research and for developing future methods with more comparable evaluation evidence and stronger practical relevance.
Acknowledgments
In this work, Hangting Ye, Jinhan Liu, Yong Yao, Jinmeng Li, Peng Wang, Dandan Guo and Yi Chang are supported by the National Key R&D Program of China under Grant (No. 2023YFF0905400), the National Natural Science Foundation of China (No. 623B2043, No. U2341229, No. 62306125), the Fundamental and Interdisciplinary Disciplines Breakthrough Plan of the Ministry of Education of China (No. JYB2025XDXM903), and the New Cornerstone Science Foundation through the XPLORER PRIZE. Hongyuan Zha’s research is supported in part by Shenzhen Stability Science Program 2023, and National Natural Science Foundation of China (No. 72495131).
References
- Han, S.; Hu, X.; Huang, H.; Jiang, M.; Zhao, Y. Adbench: Anomaly detection benchmark. Advances in neural information processing systems 2022, 35, 32142–32159.
- Borisov, V.; Leemann, T.; Seßler, K.; Haug, J.; Pawelczyk, M.; Kasneci, G. Deep neural networks and tabular data: A survey. IEEE Transactions on Neural Networks and Learning Systems 2022.
- Bolton, R.J.; Hand, D.J. Statistical Fraud Detection: A Review. Statistical Science 2002, 17, 235–255. [CrossRef]
- Bauder, R.A.; Khoshgoftaar, T.M.; Seliya, N. A Survey on the State of Healthcare Upcoding Fraud Analysis and Detection. Health Services and Outcomes Research Methodology 2017, 17, 31–55. [CrossRef]
- Buczak, A.L.; Guven, E. A Survey of Data Mining and Machine Learning Methods for Cyber Security Intrusion Detection. IEEE Communications Surveys & Tutorials 2016, 18, 1153–1176. [CrossRef]
- Ge, Z.; Song, Z.; Ding, S.X.; Huang, B. Data Mining and Analytics in the Process Industry: The Role of Machine Learning. IEEE Access 2017, 5, 20590–20616. [CrossRef]
- Chandola, V.; Banerjee, A.; Kumar, V. Anomaly Detection: A Survey. ACM Computing Surveys 2009, 41, 1–58.
- Ruff, L.; Kauffmann, J.R.; Vandermeulen, R.A.; Montavon, G.; Samek, W.; Kloft, M.; Dietterich, T.G.; Müller, K.R. A Unifying Review of Deep and Shallow Anomaly Detection. Proceedings of the IEEE 2021, 109, 756–795. [CrossRef]
- Pang, G.; Shen, C.; Cao, L.; van den Hengel, A. Deep Learning for Anomaly Detection: A Review. ACM Computing Surveys 2021, 54, 1–38.
- Borisov, V.; Leemann, T.; Seßler, K.; Haug, J.; Pawelczyk, M.; Kasneci, G. Deep Neural Networks and Tabular Data: A Survey. IEEE Transactions on Neural Networks and Learning Systems 2024, 35, 7499–7519.
- Ye, H.; Wang, P.; Fan, W.; Song, X.; Zhao, H.; Guo, D.; Chang, Y. Deep Tabular Representation Corrector. IEEE Transactions on Pattern Analysis and Machine Intelligence 2026, 48, 3368–3382. [CrossRef]
- Liu, F.T.; Ting, K.M.; Zhou, Z.H. Isolation forest. In Proceedings of the 2008 eighth ieee international conference on data mining. IEEE, 2008, pp. 413–422.
- Angiulli, F.; Pizzuti, C. Fast outlier detection in high dimensional spaces. In Proceedings of the European conference on principles of data mining and knowledge discovery. Springer, 2002, pp. 15–27.
- Kingma, D.P.; Welling, M. Auto-encoding variational bayes. arXiv preprint arXiv:1312.6114 2013.
- Qiu, C.; Pfrommer, T.; Kloft, M.; Mandt, S.; Rudolph, M. Neural transformation learning for deep anomaly detection beyond images. In Proceedings of the International conference on machine learning. PMLR, 2021, pp. 8703–8714.
- Shenkar, T.; Wolf, L. Anomaly detection for tabular data with internal contrastive learning. In Proceedings of the International conference on learning representations, 2022.
- Li, A.; Zhao, Y.; Qiu, C.; Kloft, M.; Smyth, P.; Rudolph, M.; Mandt, S. Anomaly Detection of Tabular Data Using LLMs. arXiv preprint arXiv:2406.16308 2024. [CrossRef]
- Tsai, C.P.; Teng, G.; Wallis, P.; Ding, W. AnoLLM: Large Language Models for Tabular Anomaly Detection. In Proceedings of the International Conference on Learning Representations, 2025.
- Yoon, S.; Kim, D.; Yoon, S.; Sim, Y.S.; Yoa, S.; Cho, H.S.; Lee, S.; Lee, H.; Lim, W. ReTabAD: A Benchmark for Restoring Semantic Context in Tabular Anomaly Detection. In Proceedings of the International Conference on Learning Representations, 2026.
- Hollmann, N.; Müller, S.; Purucker, L.; Krishnakumar, A.; Körfer, M.; Hoo, S.B.; Schirrmeister, R.T.; Hutter, F. Accurate Predictions on Small Data with a Tabular Foundation Model. Nature 2025, 637, 319–326. [CrossRef]
- Shen, Y.; Wen, H.; Akoglu, L. FoMo-0D: A Foundation Model for Zero-shot Tabular Outlier Detection. Transactions on Machine Learning Research 2025.
- Schölkopf, B.; Platt, J.C.; Shawe-Taylor, J.; Smola, A.J.; Williamson, R.C. Estimating the support of a high-dimensional distribution. Neural computation 2001, 13, 1443–1471.
- Ye, H.; Zhao, H.; Fan, W.; Zhou, M.; dan Guo, D.; Chang, Y. DRL: Decomposed Representation Learning for Tabular Anomaly Detection. In Proceedings of the The Thirteenth International Conference on Learning Representations, 2025.
- Huang, H.; Wang, P.; Pei, J.; Wang, J.; Alexanian, S.; Niyato, D. Deep learning advancements in anomaly detection: A comprehensive survey. IEEE Internet of Things Journal 2025.
- Cao, Y.; Xiang, H.; Zhang, H.; Zhu, Y.; Ting, K.M. Anomaly Detection Based on Isolation Mechanisms: A Survey. Machine Intelligence Research 2025, 22, 849–865. [CrossRef]
- Ye, H.J.; Liu, S.Y.; Cai, H.R.; Zhou, Q.L.; Zhan, D.C. A Closer Look at Deep Learning Methods on Tabular Datasets. arXiv preprint arXiv:2407.00956 2024. [CrossRef]
- Jiang, J.P.; Liu, S.Y.; Cai, H.R.; Zhou, Q.L.; Ye, H.J. Representation learning for tabular data: A comprehensive survey. IEEE Transactions on Pattern Analysis and Machine Intelligence 2026.
- Shi, R.; Wang, Y.; Du, M.; Shen, X.; Chang, Y.; Wang, X. A comprehensive survey of synthetic tabular data generation. arXiv preprint arXiv:2504.16506 2025.
- Fang, X.; Xu, W.; Tan, F.A.; Hu, Z.; Zhang, J.; Qi, Y.; Sengamedu, S.H.; Faloutsos, C. Large Language Models (LLMs) on Tabular Data: Prediction, Generation, and Understanding - A Survey. Transactions on Machine Learning Research 2024.
- Van Breugel, B.; Van Der Schaar, M. Position: why tabular foundation models should be a research priority. In Proceedings of the Proceedings of the 41st International Conference on Machine Learning, 2024, pp. 48976–48993.
- Li, Z.; Zhu, Y.; Van Leeuwen, M. A survey on explainable anomaly detection. ACM Transactions on Knowledge Discovery from Data 2023, 18, 1–54.
- Zhu, J.; Zhao, X.; Sun, Y.; Song, S.; Yuan, X. Relational Data Cleaning Meets Artificial Intelligence: A Survey. Data Science and Engineering 2025, 10, 147–174. [CrossRef]
- Ruff, L.; Vandermeulen, R.A.; Görnitz, N.; Binder, A.; Müller, E.; Müller, K.R.; Kloft, M. Deep semi-supervised anomaly detection. arXiv preprint arXiv:1906.02694 2019.
- Pang, G.; Shen, C.; Van Den Hengel, A. Deep anomaly detection with deviation networks. In Proceedings of the Proceedings of the 25th ACM SIGKDD international conference on knowledge discovery & data mining, 2019, pp. 353–362.
- Choudhury, M.R.; Iyengar, A.I.K.N.; Siingh, S.; Puranam, S.; Gupta, V. TABARD: A Novel Benchmark for Tabular Anomaly Analysis, Reasoning and Detection. In Proceedings of the Findings of the Association for Computational Linguistics: EMNLP 2025, 2025, pp. 21783–21817.
- Steinbuss, G.; Böhm, K. Benchmarking unsupervised outlier detection with realistic synthetic data. ACM Transactions on Knowledge Discovery from Data (TKDD) 2021, 15, 1–20.
- Breunig, M.M.; Kriegel, H.P.; Ng, R.T.; Sander, J. LOF: Identifying Density-Based Local Outliers. In Proceedings of the Proceedings of the 2000 ACM SIGMOD International Conference on Management of Data, 2000, pp. 93–104.
- Tang, J.; Chen, Z.; Fu, A.W.C.; Cheung, D.W. Enhancing effectiveness of outlier detections for low density patterns. In Proceedings of the Pacific-Asia conference on knowledge discovery and data mining. Springer, 2002, pp. 535–548.
- He, Z.; Xu, X.; Deng, S. Discovering cluster-based local outliers. Pattern recognition letters 2003, 24, 1641–1650.
- Kriegel, H.P.; Schubert, M.; Zimek, A. Angle-based outlier detection in high-dimensional data. In Proceedings of the Proceedings of the 14th ACM SIGKDD international conference on Knowledge discovery and data mining, 2008, pp. 444–452.
- Aggarwal, C.C. An introduction to outlier analysis. In Outlier analysis; Springer, 2016; pp. 1–34.
- Hubert, M.; Debruyne, M. Minimum covariance determinant. Wiley interdisciplinary reviews: Computational statistics 2010, 2, 36–43.
- Ester, M.; Kriegel, H.P.; Sander, J.; Xu, X.; et al. A density-based algorithm for discovering clusters in large spatial databases with noise. In Proceedings of the kdd, 1996, Vol. 96, pp. 226–231.
- Campello, R.J.; Moulavi, D.; Sander, J. Density-based clustering based on hierarchical density estimates. In Proceedings of the Pacific-Asia conference on knowledge discovery and data mining. Springer, 2013, pp. 160–172.
- Goldstein, M.; Dengel, A. Histogram-based outlier score (hbos): A fast unsupervised anomaly detection algorithm. KI-2012: poster and demo track 2012, 1, 59–63.
- Li, Z.; Zhao, Y.; Botta, N.; Ionescu, C.; Hu, X. Copod: copula-based outlier detection. In Proceedings of the 2020 IEEE international conference on data mining (ICDM). IEEE, 2020, pp. 1118–1123.
- Li, Z.; Zhao, Y.; Hu, X.; Botta, N.; Ionescu, C.; Chen, G.H. Ecod: Unsupervised outlier detection using empirical cumulative distribution functions. IEEE Transactions on Knowledge and Data Engineering 2022, 35, 12181–12193.
- Liu, Fei Tony and Ting, Kai Ming and Zhou, Zhi-Hua. On detecting clustered anomalies using sciforest. In Proceedings of the Joint European conference on machine learning and knowledge discovery in databases. Springer, 2010, pp. 274–290.
- Hariri, S.; Kind, M.C.; Brunner, R.J. Extended isolation forest. IEEE transactions on knowledge and data engineering 2019, 33, 1479–1489.
- Bandaragoda, T.R.; Ting, K.M.; Albrecht, D.; Liu, F.T.; Zhu, Y.; Wells, J.R. Isolation-based anomaly detection using nearest-neighbor ensembles. Computational Intelligence 2018, 34, 968–998.
- Xu, B.C.; Ting, K.M.; Zhou, Z.H. Isolation set-kernel and its application to multi-instance learning. In Proceedings of the Proceedings of the 25th ACM SIGKDD international conference on knowledge discovery & data mining, 2019, pp. 941–949.
- Ting, K.M.; Xu, B.C.; Washio, T.; Zhou, Z.H. Isolation distributional kernel: A new tool for kernel based anomaly detection. In Proceedings of the Proceedings of the 26th ACM SIGKDD international conference on knowledge discovery & data mining, 2020, pp. 198–206.
- Tax, D.M.; Duin, R.P. Support vector data description. Machine learning 2004, 54, 45–66.
- Shyu, M.L.; Chen, S.C.; Sarinnapakorn, K.; Chang, L. A novel anomaly detection scheme based on principal component classifier. In Proceedings of the Proceedings of the IEEE Foundations and New Directions of Data Mining Workshop, 2003, pp. 171–179.
- Schölkopf, B.; Smola, A.; Müller, K.R. Kernel principal component analysis. In Proceedings of the International conference on artificial neural networks. Springer, 1997, pp. 583–588.
- Almardeny, Y.; Boujnah, N.; Cleary, F. A novel outlier detection method for multivariate data. IEEE Transactions on Knowledge and Data Engineering 2020, 34, 4052–4062.
- Kriegel, H.P.; Kröger, P.; Schubert, E.; Zimek, A. Outlier detection in axis-parallel subspaces of high dimensional data. In Proceedings of the Pacific-asia conference on knowledge discovery and data mining. Springer, 2009, pp. 831–838.
- Zhou, Y.; Song, X.; Zhang, Y.; Liu, F.; Zhu, C.; Liu, L. Feature encoding with autoencoders for weakly supervised anomaly detection. IEEE Transactions on Neural Networks and Learning Systems 2021, 33, 2454–2465.
- Livernoche, V.; Jain, V.; Hezaveh, Y.; Ravanbakhsh, S. On diffusion modeling for anomaly detection. In Proceedings of the International Conference on Learning Representations, 2024, Vol. 2024, pp. 25836–25866.
- Zamberg, G.; Salhov, M.; Lindenbaum, O.; Averbuch, A. TabADM: Unsupervised Tabular Anomaly Detection with Diffusion Models. arXiv preprint arXiv:2307.12336 2023. [CrossRef]
- Li, Z.; Huang, Q.; Zhu, Y.; Yang, L.; Mohammadi Amiri, M.; van Stein, N.; van Leeuwen, M. Scalable, explainable and provably robust anomaly detection with one-step flow matching. In Proceedings of the Advances in Neural Information Processing Systems, 2025, Vol. 38, pp. 87834–87899.
- Yin, J.; Qiao, Y.; Zhou, Z.; Wang, X.; Yang, J. MCM: Masked Cell Modeling for Anomaly Detection in Tabular Data. In Proceedings of the International Conference on Learning Representations, 2024.
- Thimonier, Hugo and Popineau, Fabrice and Rimmel, Arpad and Doan, Bich Liên. Beyond individual input for deep anomaly detection on tabular data. arXiv preprint arXiv:2305.15121 2023.
- Thimonier, H.; Popineau, F.; Rimmel, A.; Doan, B.L. Retrieval augmented deep anomaly detection for tabular data. In Proceedings of the Proceedings of the 33rd ACM international conference on information and knowledge management, 2024, pp. 2250–2259.
- Tao, S.; Zhu, T.; Wang, H.; Meng, X. SemanticMask: A Contrastive View Design for Anomaly Detection in Tabular Data. In Proceedings of the IJCAI, 2024, pp. 2370–2378.
- Ye, J.; Tan, Z.; Hu, Y.; Yang, X.; Cheng, G.; Huang, K. Disentangling tabular data towards better one-class anomaly detection. In Proceedings of the Proceedings of the AAAI Conference on Artificial Intelligence, 2025, Vol. 39, pp. 13061–13068.
- Lu, R.; Liu, J.; Du, C.; Guo, D. Investigating Mask-aware Prototype Learning for Tabular Anomaly Detection. arXiv preprint arXiv:2506.02757 2025.
- Schlegl, T.; Seeböck, P.; Waldstein, S.M.; Schmidt-Erfurth, U.; Langs, G. Unsupervised Anomaly Detection with Generative Adversarial Networks to Guide Marker Discovery, 2017, [arXiv:cs.CV/1703.05921].
- Zenati, H.; Romain, M.; Foo, C.S.; Lecouat, B.; Chandrasekhar, V. Adversarially learned anomaly detection. In Proceedings of the 2018 IEEE International conference on data mining (ICDM). IEEE, 2018, pp. 727–736.
- Liu, Y.; Li, Z.; Zhou, C.; Jiang, Y.; Sun, J.; Wang, M.; He, X. Generative adversarial active learning for unsupervised outlier detection. IEEE Transactions on Knowledge and Data Engineering 2019, 32, 1517–1528.
- Yang, X.; Li, X. ATDAD: One-class adversarial learning for tabular data anomaly detection. Computers & Security 2023, 134, 103449.
- Wang, H.; Pang, G.; Shen, C.; Ma, C. Unsupervised representation learning by predicting random distances. arXiv preprint arXiv:1912.12186 2019.
- Wang, Y.; Qin, C.; Wei, R.; Xu, Y.; Bai, Y.; Fu, Y. SLA2P: Self-Supervised Anomaly Detection With Adversarial Perturbation. IEEE Transactions on Knowledge and Data Engineering 2024, 36, 9282–9293.
- Xu, H.; Wang, Y.; Wei, J.; Jian, S.; Li, Y.; Liu, N. Fascinating supervisory signals and where to find them: Deep anomaly detection with scale learning. In Proceedings of the International Conference on Machine Learning. PMLR, 2023, pp. 38655–38673.
- Li, Y.; Wang, Y.; Xu, H.; Li, B.; Zhou, X. Deep anomaly detection with partition contrastive learning for tabular data. Data Mining and Knowledge Discovery 2025, 39, 30.
- Pang, G.; Shen, C.; Jin, H.; Van Den Hengel, A. Deep weakly-supervised anomaly detection. In Proceedings of the Proceedings of the 29th ACM SIGKDD conference on knowledge discovery and data mining, 2023, pp. 1795–1807.
- Liu, B.; Wang, D.; Lin, K.; Tan, P.N.; Zhou, J. Rca: A deep collaborative autoencoder approach for anomaly detection. In Proceedings of the IJCAI: proceedings of the conference, 2021, Vol. 2021, p. 1505.
- Xu, H.; Wang, Y.; Pang, G.; Jian, S.; Liu, N.; Wang, Y. RoSAS: Deep Semi-Supervised Anomaly Detection with Contamination-Resilient Continuous Supervision. Information Processing & Management 2023, 60, 103459. [CrossRef]
- Ruff, L.; Vandermeulen, R.; Goernitz, N.; Deecke, L.; Siddiqui, S.A.; Binder, A.; Müller, E.; Kloft, M. Deep one-class classification. In Proceedings of the International conference on machine learning. PMLR, 2018, pp. 4393–4402.
- Pang, G.; Cao, L.; Chen, L.; Liu, H. Learning representations of ultrahigh-dimensional data for random distance-based outlier detection. In Proceedings of the Proceedings of the 24th ACM SIGKDD international conference on knowledge discovery & data mining, 2018, pp. 2041–2050.
- Xu, H.; Pang, G.; Wang, Y.; Wang, Y. Deep isolation forest for anomaly detection. IEEE transactions on knowledge and data engineering 2023, 35, 12591–12604.
- Goodge, A.; Hooi, B.; Ng, S.K.; Ng, W.S. Lunar: Unifying local outlier detection methods via graph neural networks. In Proceedings of the Proceedings of the AAAI conference on artificial intelligence, 2022, Vol. 36, pp. 6737–6745.
- Liu, H.; Xu, X.; Li, E.; Zhang, S.; Li, X. Anomaly detection with representative neighbors. IEEE Transactions on Neural Networks and Learning Systems 2021, 34, 2831–2841.
- You, C.; Robinson, D.P.; Vidal, R. Provable self-representation based outlier detection in a union of subspaces. In Proceedings of the Proceedings of the IEEE conference on computer vision and pattern recognition, 2017, pp. 3395–3404.
- Song, Y.; Wang, D. Learning on graphs with out-of-distribution nodes. In Proceedings of the Proceedings of the 28th ACM SIGKDD Conference on Knowledge Discovery and Data Mining, 2022, pp. 1635–1645.
- Zhao, X.; Leng, X.; Wang, L.; Wang, N.; Liu, Y. Efficient Anomaly Detection in Tabular Cybersecurity Data Using Large Language Models. Scientific Reports 2025, 15, 3344. [CrossRef]
- Wang, R.; Liu, R.; Chen, R.; Suo, H.; Peng, Z.; Tang, Z.; Chen, C. CausalTAD: Injecting Causal Knowledge into Large Language Models for Tabular Anomaly Detection. arXiv preprint arXiv:2602.07798 2026.
- Wang, P.; Li, S. Multi-Agent Debate: A Unified Agentic Framework for Tabular Anomaly Detection. arXiv preprint arXiv:2602.14251 2026.
- Ye, H.; Li, J.; Zhao, H.; Zhuge, M.; Guo, D.; Chang, Y.; Zha, H. LLM as an Algorithmist: Enhancing Anomaly Detectors via Programmatic Synthesis. In Proceedings of the The Fourteenth International Conference on Learning Representations, 2026.
- Ding, X.; Wen, H.; Klütterman, S.; Akoglu, L. From Zero to Hero: Advancing Zero-Shot Foundation Models for Tabular Outlier Detection. arXiv preprint arXiv:2602.03018 2026.
- Wei, J.Y.; Armanfard, N. ICLAD: In-Context Learning for Unified Tabular Anomaly Detection Across Supervision Regimes. arXiv preprint arXiv:2603.19497 2026. [CrossRef]
- Marszałek, P.; Kuśmierczyk, T.; Śmieja, M. TACTIC for Navigating the Unknown: Tabular Anomaly deteCTion via In-Context inference. arXiv preprint arXiv:2603.14171 2026.
- Li, S.; Liu, Y.; Zheng, Y.; Cao, X.; Pan, S.; Shen, H.T. Towards One-for-All Anomaly Detection for Tabular Data. arXiv preprint arXiv:2603.14407 2026.
- Wu, Z.; Wang, J.; Cheng, Z.; Zhou, Y.; Wang, W.; Pu, J.; Li, C.; Ma, C. Icad-llm: One-for-all anomaly detection via in-context learning with large language models. In Proceedings of the Proceedings of the AAAI Conference on Artificial Intelligence, 2026, Vol. 40, pp. 15986–15994.
- Song, K.; Guo, H.; Zhang, Y. ProFit: Unsupervised Fine-Tuning of Tabular Models via Proxy Tasks for Label-Scarce Anomaly Detection. OpenReview preprint 2025.
- Bouman, R.; Bukhsh, Z.; Heskes, T. Unsupervised anomaly detection algorithms on real-world data: how many do we need? Journal of Machine Learning Research 2024, 25, 1–34.
- Sugiyama, M.; Borgwardt, K. Rapid distance-based outlier detection via sampling. Advances in neural information processing systems 2013, 26.
- Latecki, L.J.; Lazarevic, A.; Pokrajac, D. Outlier detection with kernel density functions. In Proceedings of the International workshop on machine learning and data mining in pattern recognition. Springer, 2007, pp. 61–75.
- Durani, W.; Leiber, C.; Durani, K.; Plant, C.; Böhm, C. Anomaly Detection by an Ensemble of Random Pairs of Hyperspheres. In Proceedings of the Advances in Neural Information Processing Systems, 2025, Vol. 38, pp. 166168–166207.
- Burgess, C.P.; Higgins, I.; Pal, A.; Matthey, L.; Watters, N.; Desjardins, G.; Lerchner, A. Understanding disentangling in β-VAE. arXiv preprint arXiv:1804.03599 2018.
- Gidaris, S.; Singh, P.; Komodakis, N. Unsupervised representation learning by predicting image rotations. arXiv preprint arXiv:1803.07728 2018.
- Doersch, C.; Gupta, A.; Efros, A.A. Unsupervised visual representation learning by context prediction. In Proceedings of the Proceedings of the IEEE international conference on computer vision, 2015, pp. 1422–1430.
- Nguyen, M.N.; Vien, N.A. Scalable and interpretable one-class svms with deep learning and random fourier features. In Proceedings of the Joint European Conference on Machine Learning and Knowledge Discovery in Databases. Springer, 2018, pp. 157–172.
- Wang, C.; Liu, Z.; Gao, H.; Fu, Y. VOS: A new outlier detection model using virtual graph. Knowledge-Based Systems 2019, 185, 104907.
- Hegselmann, S.; Buendia, A.; Lang, H.; Agrawal, M.; Jiang, X.; Sontag, D. Tabllm: Few-shot classification of tabular data with large language models. In Proceedings of the International conference on artificial intelligence and statistics. PMLR, 2023, pp. 5549–5581.
- Hu, E.J.; yelong shen.; Wallis, P.; Allen-Zhu, Z.; Li, Y.; Wang, S.; Wang, L.; Chen, W. LoRA: Low-Rank Adaptation of Large Language Models. In Proceedings of the International Conference on Learning Representations, 2022.
- Gong, Z.; Gu, J.; Chen, X.; Luo, X.; Liu, Z.; Yu, H. FLEX-AD: AutoML for Anomaly Detection via LLM-Guided Feature Generation and Selective Ensembling. In Proceedings of the Pacific Rim International Conference on Artificial Intelligence. Springer, 2025, pp. 321–336.
- Jacobs, R.A.; Jordan, M.I.; Nowlan, S.J.; Hinton, G.E. Adaptive Mixtures of Local Experts. Neural Computation 1991, 3, 79–87. [CrossRef]
- Dai, W.; Hwang, K.; Fan, J. Unsupervised anomaly detection for tabular data using deep noise evaluation. In Proceedings of the Proceedings of the AAAI conference on artificial intelligence, 2025, Vol. 39, pp. 11553–11562.
- Ye, H.; Liu, Z.; Shen, X.; Cao, W.; Zheng, S.; Gui, X.; Zhang, H.; Chang, Y.; Bian, J. Uadb: Unsupervised anomaly detection booster. In Proceedings of the 2023 IEEE 39th International Conference on Data Engineering (ICDE). IEEE, 2023, pp. 2593–2606.
- Ye, H.; Zhao, H.; Fan, W.; Song, X.; Guo, D.; Chang, Y.; Zha, H. Calibrating Tabular Anomaly Detection via Optimal Transport. arXiv preprint arXiv:2602.06810 2026.
- Zhao, Y.; Hu, X.; Cheng, C.; Wang, C.; Wan, C.; Wang, W.; Yang, J.; Bai, H.; Li, Z.; Xiao, C.; et al. SUOD: Accelerating Large-Scale Unsupervised Heterogeneous Outlier Detection. In Proceedings of the Proceedings of Machine Learning and Systems, 2021, Vol. 3, pp. 463–478.
- Anwar, A.; Moser, B.; Herurkar, D.; Raue, F.; Hegiste, V.; Legler, T.; Dengel, A. Fedad-bench: A unified benchmark for federated unsupervised anomaly detection in tabular data. In Proceedings of the 2024 2nd International Conference on Federated Learning Technologies and Applications (FLTA). IEEE, 2024, pp. 115–122.
- Lu, G.; Duan, C.; Zhou, G.; Ding, X.; Liu, Y. Privacy-preserving outlier detection with high efficiency over distributed datasets. In Proceedings of the IEEE INFOCOM 2021-IEEE Conference on Computer Communications. IEEE, 2021, pp. 1–10.
- Das, S.; Wong, W.K.; Dietterich, T.; Fern, A.; Emmott, A. Incorporating Expert Feedback into Active Anomaly Discovery. In Proceedings of the 2016 IEEE 16th International Conference on Data Mining, 2016, pp. 853–858. [CrossRef]
- Siddiqui, M.A.; Fern, A.; Dietterich, T.G.; Wright, R.; Theriault, A.; Archer, D.W. Feedback-guided anomaly discovery via online optimization. In Proceedings of the Proceedings of the 24th ACM SIGKDD international conference on knowledge discovery & data mining, 2018, pp. 2200–2209.
- Islam, M.R.; Das, S.; Doppa, J.R.; Natarajan, S. Glad: Glocalized anomaly detection via human-in-the-loop learning. arXiv preprint arXiv:1810.01403 2018.
- Emmott, A.; Das, S.; Dietterich, T.; Fern, A.; Wong, W.K. A meta-analysis of the anomaly detection problem. arXiv preprint arXiv:1503.01158 2015.
- Campos, G.O.; Zimek, A.; Sander, J.; Campello, R.J.G.B.; Micenková, B.; Schubert, E.; Assent, I.; Houle, M.E. On the Evaluation of Unsupervised Outlier Detection: Measures, Datasets, and an Empirical Study. Data Mining and Knowledge Discovery 2016, 30, 891–927. [CrossRef]
- Lichman, M.; et al. UCI machine learning repository, 2013.
- Lohrer, A.; Deller, J.; Hünemörder, M.; Kröger, P. OAB-an open anomaly benchmark framework for unsupervised and semisupervised anomaly detection on image and tabular data sets. In Proceedings of the 2021 International Conference on Data Mining Workshops (ICDMW). IEEE, 2021, pp. 991–1000.
- Rayana, S. ODDS library. Stony Brook University, Department of Computer Sciences 2016.
- Ding, X.; Klüttermann, S.; Wen, H.; Chen, Y.; Akoglu, L. MacrOData: New Benchmarks of Thousands of Datasets for Tabular Outlier Detection. arXiv preprint arXiv:2602.09329 2026.
- Zhang, E.; Zhang, Y. Average precision. Encyclopedia of database systems 2009, pp. 192–193.
- Craswell, N. Precision at n. Encyclopedia of database systems 2009, pp. 2127–2128.
- Saito, T.; Rehmsmeier, M. The precision-recall plot is more informative than the ROC plot when evaluating binary classifiers on imbalanced datasets. PloS one 2015, 10, e0118432.
- Chang, C.H.; Yoon, J.; Arik, S.Ö.; Udell, M.; Pfister, T. Data-Efficient and Interpretable Tabular Anomaly Detection. In Proceedings of the Proceedings of the 29th ACM SIGKDD Conference on Knowledge Discovery and Data Mining, 2023, pp. 190–201. [CrossRef]
- Lundberg, S.M.; Lee, S.I. A Unified Approach to Interpreting Model Predictions. In Proceedings of the Advances in Neural Information Processing Systems, 2017, Vol. 30.
- Rekatsinas, T.; Chu, X.; Ilyas, I.F.; Ré, C. HoloClean: Holistic Data Repairs with Probabilistic Inference. Proceedings of the VLDB Endowment 2017, 10.
- Ye, H.; Li, J.; Zhao, H.; Guo, D.; Chang, Y. LLM Meeting Decision Trees on Tabular Data. In Proceedings of the The Thirty-ninth Annual Conference on Neural Information Processing Systems, 2026.
- Robinson, J.; Ranjan, R.; Hu, W.; Huang, K.; Han, J.; Dobles, A.; Fey, M.; Lenssen, J.E.; Yuan, Y.; Zhang, Z.; et al. Relbench: A benchmark for deep learning on relational databases. Advances in Neural Information Processing Systems 2024, 37, 21330–21341.
- Ebrahimi, S.; Arik, S.O.; Dong, Y.; Pfister, T. Lanistr: Multimodal learning from structured and unstructured data. arXiv preprint arXiv:2305.16556 2023.
- Kim, W.; Song, C.; Kim, H. Multimodalpfn: Extending prior-data fitted networks for multimodal tabular learning. In Proceedings of the Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 2026, pp. 30357–30367.
- Ovcharenko, O.; Schelter, S. Towards Cross-Modal Error Detection with Tables and Images. arXiv preprint arXiv:2510.12383 2025.
Figure 1.
A brief introduction to tabular anomaly detection. Each row represents a sample and each column corresponds to a specific feature, which can be numerical, categorical or textual.
Figure 1.
A brief introduction to tabular anomaly detection. Each row represents a sample and each column corresponds to a specific feature, which can be numerical, categorical or textual.
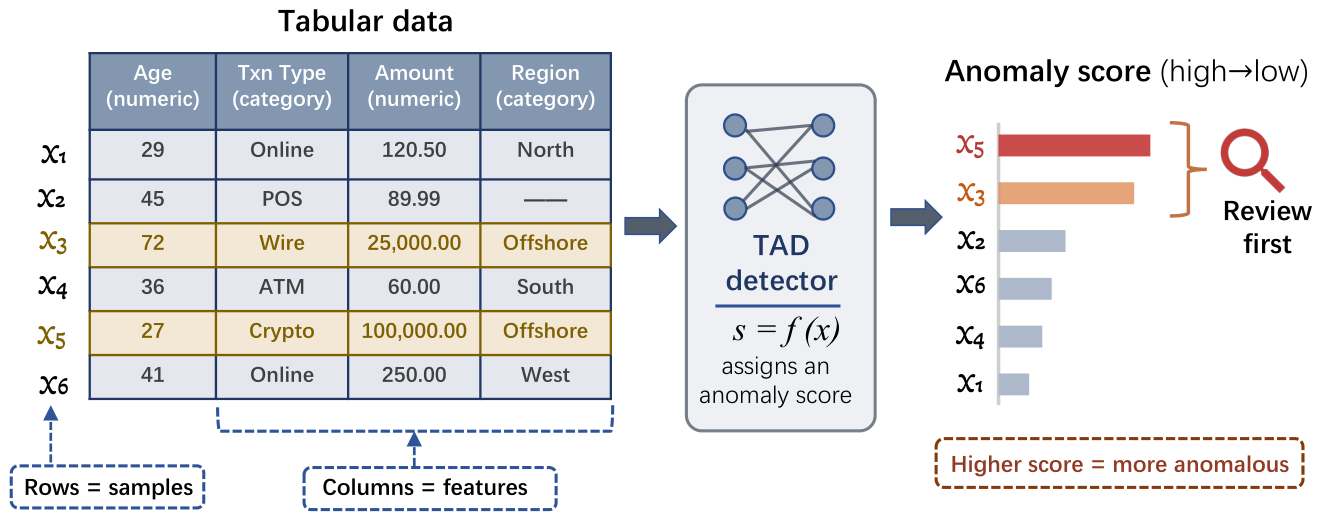
Figure 2.
Roadmap of the survey. The survey places TAD method families at the center, and then relates them to table information, anomaly types, benchmark practices, adaptation beyond standalone detector design, and downstream tasks built on TAD outputs.
Figure 2.
Roadmap of the survey. The survey places TAD method families at the center, and then relates them to table information, anomaly types, benchmark practices, adaptation beyond standalone detector design, and downstream tasks built on TAD outputs.
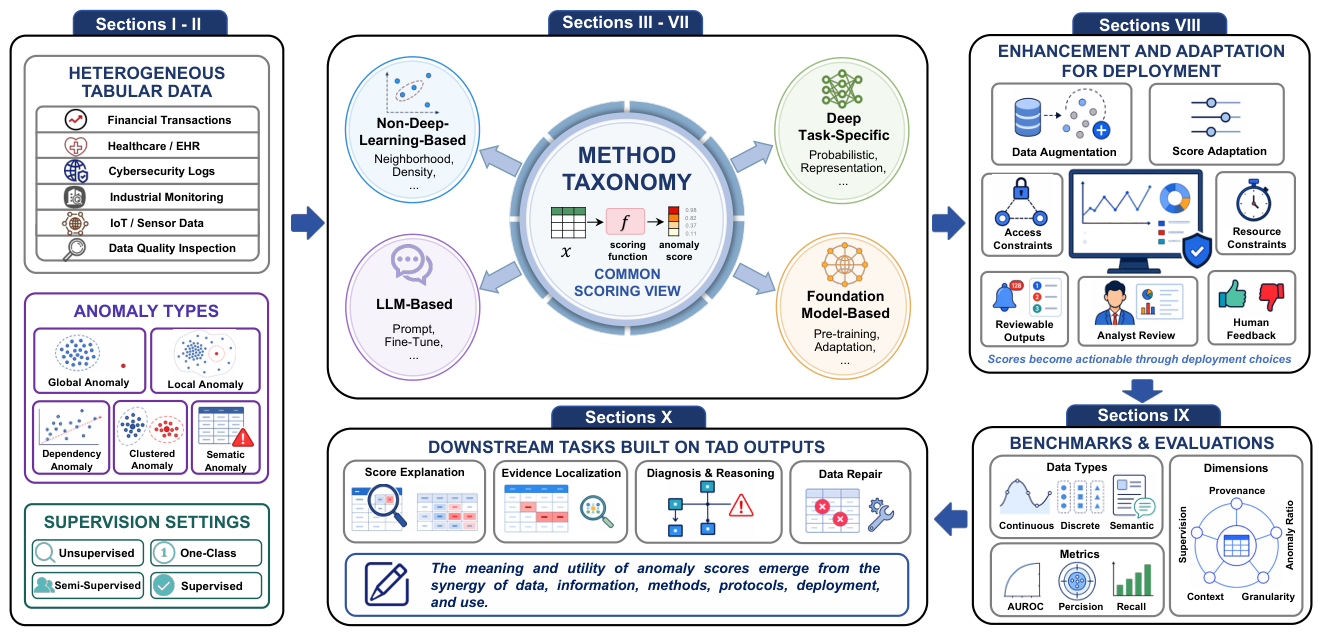

Table 1.
Representative TAD method modules organized by scoring principle. In the representative-reference column, method names are color-coded by the supervision setting in Section 2.2: unsupervised, one-class, semi-/weakly supervised, and supervised.
Table 1.
Representative TAD method modules organized by scoring principle. In the representative-reference column, method names are color-coded by the supervision setting in Section 2.2: unsupervised, one-class, semi-/weakly supervised, and supervised.
| Family | Module | Scoring function | Detection principle | Key limitation | Representative references |
|---|---|---|---|---|---|
| Neighborhood-Based Methods | ; distance, local density ratio, angular variance | Anomalies lack local support: distant from or sparser than their neighbors | Distance metrics distorted by categorical encoding and missing-value imputation | KNN [13], LOF [37], COF/CBLOF [38,39], ABOD [40] | |
| Density-Estimation Methods | ; empirical tail or density-reachability score | Anomalies reside in low-density regions of the estimated data distribution | Fast marginal variants assume feature independence and miss dependency anomalies; parametric fits brittle in high dimensions | GMM/MCD [41,42], DBSCAN/HDBSCAN [43,44], HBOS/COPOD/ECOD [45,46,47] | |
|
Non-Deep- Learning-Based TAD |
Isolation-Based Methods | ; short path or local isolation radius | Anomalies are few and different, hence easily isolated by random partitioning | Standard axis-parallel splits create blind spots for correlated-feature and clustered anomalies | IForest [12], SCiForest/EIF [48,49], iNNE [50], Isolation kernels [51,52] |
| One-Class Boundary Methods | or one-class margin | Anomalies fall outside a compact boundary enclosing normal data | Single boundary fails when normal data forms disjoint clusters; kernel selection critical | OCSVM [22], SVDD [53] | |
| Projection-Based Methods | ; projection-residual | Anomalies deviate from the low-dimensional structure of normal data | Projection residuals may reflect encoding artifacts rather than genuine anomalies | PCA/KPCA [54,55], ROD [56], SOD [57] | |
| Probabilistic and Generative Models | , likelihood, or diffusion density | Anomalies incur high reconstruction error or low likelihood under a model trained on normal data | Over-parameterized networks may reconstruct anomalies equally well; diffusion models add iterative inference cost | AE/VAE [14,41], FEAWAD [58], TabADM/DTE-U/DTE-OC [59,60], TCCM [61] | |
| Masked-Prediction and Dependency-Modeling Methods | Anomalies have feature values inconsistent with what remaining features predict | Masking distribution may not match real anomaly patterns, causing proxy mismatch | MCM [62], NPT-AD/RAAD [63,64], SemanticMask/Dist-TAD/PTAD [65,66,67] | ||
|
Deep Task-Specific TAD |
GAN-Based Methods | discriminator margin or adversarial reconstruction score | Anomalies cannot be faithfully reproduced by a generator trained on normal data | Training instability and mode collapse on imbalanced, mixed-type tabular data | AnoGAN/ALAD [68,69], GAAL [70], ATDAD [71] |
| Contrastive and Transformation-Based Self-Supervised Methods | ; alignment, ranking, or transformation loss | Anomalies break consistency under tabular-specific transformations or contrastive views | Surrogate task may not align with real anomaly patterns, causing proxy mismatch | RDP [72], NeuTralAD [15], SLA2P/SLAD [73,74], ICL/PCLAD [16,75], PReNet/RCA/RoSAS [76,77,78] | |
| Representation Learning-Based Methods | ; center distance, latent neighborhood, isolation, or GNN propagation | Anomalies become separable in a learned latent space where simple scoring rules suffice | Single-center boundaries fail for multi-cluster normality; latent distances sensitive to categorical embeddings and may misscore rare legitimate subgroups | DeepSVDD/DeepSAD [33,79], DevNet [34], REPEN(U)/(SS)/DIF/DRL [23,80,81], LUNAR/RDRN/R-Graph/GAE [82,83,84,85] | |
| LLM Prompting for TAD | ; | Anomalies violate semantic rules, domain knowledge, or schema constraints accessible through text | Sensitive to serialization order, prompt design, and numerical fidelity; high per-sample cost | ReTabAD [19], TABARD [35], TAD-GP [86] | |
| LLM-Based TAD | LLM Fine-Tuning for TAD | via fine-tuning; score by logits, likelihood, or generated label | Fine-tuned language prior captures anomaly patterns in serialized tabular context | Requires labeled or synthetic anomalies for tuning; adapter capacity and data access become protocol factors | LLMAD [17], AnoLLM [18], CausalTAD [87] |
| LLM-Assisted Enhancement | ; . | LLM augments a base detector via generated rules, features, code, or ensemble decisions | Inherits base detector limitations; LLM-generated artifacts require additional validation | MAD-S/MAD-OC [88], LLM-DAS [89] | |
|
Foundation Model- Based TAD |
Cross-Table Pretraining Methods | with cross-table pretraining | Reusable priors from cross-table pretraining enable zero-shot or in-context anomaly ranking | May transfer benchmark regularities rather than genuine anomaly semantics across domains | FoMo-0D [21], OutFormer [90], ICLAD-U/ICLAD-OC/ICLAD-S [91], TACTIC [92], OFA-TAD [93] |
| Pretrained-Model Adaptation Methods | Adapts a pretrained tabular or language model to target anomaly semantics | Effectiveness depends on alignment between source pretraining and target anomaly types | ICAD-LLM [94], ProFiT [95] |
Table 2.
Evaluation protocol overview of representative tabular anomaly detection benchmarks. Anomaly Provenance characterizes the source and construction process of anomalies. Datasets denote the number of all base datasets and variants. Samples, Features, and Anomaly Ratio denote their range. Semantic Context indicates whether semantic metadata is available.
Table 2.
Evaluation protocol overview of representative tabular anomaly detection benchmarks. Anomaly Provenance characterizes the source and construction process of anomalies. Datasets denote the number of all base datasets and variants. Samples, Features, and Anomaly Ratio denote their range. Semantic Context indicates whether semantic metadata is available.
| Benchmark | Anomaly Provenance | Datasets | Samples | Features | Anomaly Ratio | Data Type | Semantic Context | Supervision | Metrics | Main Characteristics | Code |
|---|---|---|---|---|---|---|---|---|---|---|---|
| Emmott et al. (2015) [118] | Real-world | 25685 | 1K–6K | N/A–200 | 0.1%–10% | Numerical | No | Unsupervised | AUROC, AP | Meta-analysis of algorithm and dataset factors. | http://ir.library.oregonstate.edu/xmlui/handle/1957/59114 |
| Campos et al. (2016) [119] | Real-world | ≈1K | 80–60.6K | 3-1555 | 0.20%–75.38% | Numerical | No | Unsupervised | AUROC, P@n, AP, AdjP@n, AdjAP | An empirical study of unsupervised outlier detection measures. | https://www.dbs.ifi.lmu.de/research/outlier-evaluation/DAMI/ |
| Steinbuss and Böhm (2021) [36] | Statistical synthesis | 23 | 80–60.6K | 5–38 | N/A–5% | Numerical | No | Unsupervised | AUPRC | Realistic synthetic outliers with controllable local, dependency, and global anomaly types. | http://ipd.kit.edu/mitarbeiter/steinbussg/synth-benchmark-code-V3.zip |
| OAB (2021) [121] | Real-world + Statistical synthesis | 14 | 350–70K | 5–196608 | 5.33% – 90.15% | Numerical | No | Unsupervised, Semi-supervised, One-class | AUROC, AUPRC, P@n, AP, AdjP@n, AdjAP | An open benchmark framework emphasizing reproducibility, comparability, and extensibility. | https://github.com/ISDM-CAU-Kiel/oab |
| ADBench (2022) [1] | Real-world + Statistical synthesis | 57 | 80–619.3K | 3–1555 | 0.03%–39.91% | Numerical | No | Supervised, Semi-supervised, Unsupervised | AUROC, AUPRC | Systematical evaluations across supervision regimes, anomaly types, and robustness settings. | https://github.com/Minqi824/ADBench |
| TABARD (2025) [35] | Real-world + Semantic synthesis | 5295 | 2–30K | 2–37 | N/A (cell-level) | Numerical, Categorical, Textual | Yes | Unsupervised (Zero-shot LLM) | Precision, Recall, F1 | Diverse types of fine-grained cell-lelvel anomalies detected by LLMs. | https://coral-lab-asu.github.io/tabard/ |
| ReTabAD (2025) [19] | Real-world | 20 | 159–50K | 6–42 | 0.96%–33.29% | Numerical, Categorical | Yes | One-class (Zero-shot LLM) | AUROC, AUPRC | Context-aware sample-level TAD with textual metadata. | https://github.com/yoonsanghyu/ReTabAD |
| MacrOData (2026) [123] | Real-world + Statistical synthesis | 2446 | 1K–2.2M | 2–10935 | 5%–20% | Numerical, Categorical | Yes | Unsupervised, One-class | AUROC, AUPRC | Large-scale statistical, semantic, and synthetic benchmark. | https://huggingface.co/MacroData-CMU |
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (http://creativecommons.org/licenses/by/4.0/).
Copyright: This open access article is published under a Creative Commons CC BY 4.0 license, which permit the free download, distribution, and reuse, provided that the author and preprint are cited in any reuse.