

Submitted:
21 August 2026
Posted:
28 August 2026
You are already at the latest version
Abstract
Industrial anomaly detection supports automated quality inspection. Traditionally, each product has required its own detector, trained on images without defects and evaluated on benchmarks with fixed classes. Recent studies use vision encoders pretrained on web data, multimodal large language models, expert mixtures, and generative models to relax this setup. They transfer visual features, add reasoning through language, share models across categories and modalities, or generate abnormal training data. Existing taxonomies centered on reconstruction, embedding, distillation, and memory do not describe these developments well. We therefore organize the literature published over the past three years according to five sources of information that replace training on normal samples for each category, namely visual, reasoning, geometric and multimodal, universal, and synthesis priors. Reported results show progress on curated benchmarks, but evidence remains limited under domain shift, protocols for open world settings, and operating points with low false positive rates. We also analyze recent benchmarks and recurring deployment bottlenecks. Industrial video grounded in physical dynamics provides an emerging direction beyond inspection of single frames. The evidence points to a change in research focus, although current methods do not yet provide a general replacement for separate training on normal data for each product in deployed inspection.
Keywords:
industrial anomaly detection
; foundation models
; vision-language models
; zero-shot anomaly detection
; anomaly synthesis
; benchmark evaluation
1. Introduction
Industrial anomaly detection (IAD) accumulated a stable method taxonomy through 2023, covering reconstruction, embedding, distillation, memory-bank, and one-class classification. Anchored to MVTec-AD (Bergmann et al. 2019), most methods shared the category-specific normal-only training assumption, with a separate detector trained on defect-free samples for each product (history covered in (Cao et al. 2024b,Liu et al. 2024,Xie et al. 2024a)). Work published from 2024 to 2026 increasingly relaxes this assumption. Frozen CLIP/DINOv2/SAM encoders (Kirillov et al. 2023,Oquab et al. 2024,Radford et al. 2021) support zero- and few-shot detection; MLLMs post-trained with RL add defect reasoning; mixture-of-experts models share capacity across modalities; and language-controlled generators supply abnormal training examples. New benchmarks (Höfer et al. 2025,Ni et al. 2026,Yao et al. 2026,Zhang et al. 2026b) also target limitations of the MVTec-AD-era protocol. This survey examines these developments (Figure 1).
These papers draw on distinct sources of generalization and do not yet provide uniform deployment evidence. We distinguish five mechanisms, each addressing a different limitation of the closed-set, normal-only baseline. The survey asks what replaces category-specific normal-only training?
1.1. What Is Industrial Anomaly Detection?
Industrial anomaly detection is the computer-vision task at the heart of automated industrial quality inspection. On a production line, it must decide whether a manufactured item is defective and localize the defect, be it a surface scratch, dent, contamination, missing or misplaced part, or structural or logical irregularity. Because defects are rare, diverse, and costly to collect at scale, the dominant formulation learns the appearance of normal (defect-free) products and flags deviations from it. Formally, an IAD method receives normal training images and, in supervised variants, a small labeled anomalous subset . For each test image , it produces an image-level anomaly score and a pixel-level anomaly map , thresholded against deployment operating points. The task admits three supervision settings, namely unsupervised / normal-only (PatchCore (Roth et al. 2022)), one-class density estimation, and supervised training with a small labeled abnormal subset (Rolih et al. 2025). It also admits four shot regimes, namely full-shot (≳100 normals/category, the MVTec-AD default), few-shot (1–20 refs), one-shot, and zero-shot (no per-category training, WinCLIP (Jeong et al. 2023)). Recent work increasingly studies few- and zero-shot settings.
Methods are evaluated by four core metrics, including I-AUROC for image-level binary detection; P-AUROC and PRO (Bergmann et al. 2020) for pixel-level localisation; and bound-FPR metrics (AP at FPR≤1%, recall at fixed precision) for deployment-faithful operating points where false positives drive production stoppages (Xie et al. 2024b). Three cross-cutting axes distinguish single- from multi-class, closed-set from open-world, and single-modality from multimodal settings (RGB / point cloud / depth / multi-view / text). The recent literature covers each of these settings.
1.2. The Five Generalization Mechanisms
We organize the literature by what source of generalization information replaces normal-only per-category training. This yields five mechanisms, denoted M1 pretrained visual priors (Section 3), M2 language and reasoning priors (Section 4), M3 geometric and multimodal priors (Section 5), M4 universal task priors (Section 6), and M5 generated abnormal priors (Section 7). Each addresses a different limitation of the closed-set, normal-only baseline (anchors and predecessors mapped in Table 2).
- Pretrained visual priors (Section 3). CLIP/DINOv2/DINOv3/SAM serve as zero/few-shot detectors, with or without text (CLIP vs. pure-VFM) and with or without prompt engineering (FAPrompt (Zhu et al. 2025a) vs. SubspaceAD (Lendering et al. 2026) and FoundAD (Zhai et al. 2026)). This mechanism replaces the closed-set era.
- Language and reasoning priors (Section 4). MLLMs are post-trained with GRPO to produce detection + explanation in one forward pass, replacing the AnomalyGPT (Gu et al. 2024)-era SFT pipeline.
- Geometric and multimodal priors (Section 5). Point cloud / RGB-D / multi-view / language-grounded multimodal detectors replace the M3DM (Wang et al. 2023) / CPMF (Cao et al. 2024a) memory-bank monoculture.
- Universal task priors (Section 6). Generalist / unified / mixture-of-experts detectors replace the UniAD (You et al. 2022)-era one-model-per-dataset paradigm.
- Generated abnormal priors (Section 7). Diffusion- and VLM-grounded synthesis becomes a first-class building block, replacing the AnomalyDiffusion (Hu et al. 2024b)-era category-specific-finetune monoculture.
These five mechanisms are neither mutually exclusive nor pitched at the same level. M1–M3 reuse feature representations pretrained outside IAD (visual, linguistic, geometric), M4 changes the task formulation (one detector shared across categories, modalities or datasets), and M5 constructs the training data itself (synthesized abnormal samples). We use “foundation-model prior” as an umbrella term for information that recent methods reuse rather than train per product, and “prior” and “generalization mechanism/axis” interchangeably. The grouping is an analytic lens rather than a strict partition; cross-cutting hybrids are common (e.g., MoECLIP combines M1+M4, BTP/GS-CLIP combine M3+M1, AnomalyPainter/Anomagic combine M5+M2), and each chapter flags such cross-references inline. Figure 2 maps representative works onto these mechanisms and the evaluation frontier.
1.3. Why this Article
The prior surveys and benchmark studies (Cao et al. 2024b,Liang et al. 2025,Lin et al. 2025,Liu et al. 2024,Wang et al. 2025e,Xie et al. 2024a) remain the right reference for the era they organise, and we do not aim to replace them. The case for a new review is structural. The normal-only per-category assumption that gave the closed-set taxonomy its coherence has been broken across the entire wave (Section 2), so the new methods no longer fit as a “next chapter” of the same taxonomy. Organising them requires a different question, what source of generalisation replaces category-specific normal-only training?, and a different mechanism partition (Section 1.2); that reorganisation is the contribution of this article. We review the foundation-model-driven slice; medical-imaging AD (Li et al. 2026a,Lu et al. 2026c) appears only as cross-domain comparison (Section 9.1), and a comprehensive medical-AD review belongs to a different article.
1.4. Comparison with Prior IAD Surveys
Table 1 maps coverage of this review against seven prior IAD surveys spanning 2023–2025. It uses two complementary sets of axes. These comprise (a) the topics emphasized by recent work (columns 1–7), and (b) two reciprocal axes where prior surveys have genuine advantages over this review (columns 8–9). The three-symbol coverage key is defined in the table caption.
Most prior surveys are deep on their declared topic and shallow on the rest, as expected for specialist surveys. One exception is Lin et al. (2025), which is broad across detection paradigms (2D, 3D, multimodal, FM, MLLM) and the closest in axis-coverage to this article. The difference lies in positioning. That survey organizes by modality (RGB / 3D / multimodal as top-level chapters), whereas the present article organizes by generalization mechanism and reserves open-world benchmarking (column 6) and evaluation audit (column 7) as first-class axes. Every prior survey, Lin et al. (2025, including), is weak or absent on those two axes. The reciprocal-axis columns (earlier-era method depth, cross-domain/medical) document where prior work remains stronger; readers needing those should continue with (Lin et al. 2025,Liu et al. 2024).
1.5. Scope and Corpus
We survey three cohorts from the 2024–2026 IAD literature. The first contains top-venue IAD method papers from the 2025–2026 cycle (CVPR/ICLR/AAAI/ICML/ECCV 2026, NeurIPS/ICCV/ICML/KDD/ACM MM 2025, with CVPR 2025 retained as a predecessor), where the industrial domain is primary and the contribution advances detection methodology rather than reporting a dataset alone. The second contains benchmark and dataset releases at top venues or journals from 2024–2026, enumerated in Table 5. The third is a complementary selection of 2026 preprints. We date works by publication (venue) year, so a 2024 method published in 2025 falls within the 2024–2026 wave. Out of scope. General surveillance video AD, network-traffic AD, tabular AD, and medical-imaging AD are excluded (medical imaging is touched only as cross-domain comparison in Section 9.1). We include physics-grounded industrial video selectively in Section 9.4 because it tests anomalies that depend on object-state evolution rather than single-frame appearance.
Search and selection. Candidate works were gathered from the proceedings of the venues above, an arXiv (cs.CV, 2024–2026) query on industrial/anomaly/defect terms, and the continuously-updated companion list1. From this broad pool we screened titles and abstracts against two inclusion criteria. Industrial imaging had to be the primary domain, and the contribution had to be either a new detection method, a benchmark or dataset, or an evaluation study of the 2024–2026 cycle. We read the survivors in full and retained roughly one hundred works for in-depth analysis together with foundational and cross-referenced predecessors (about two hundred works cited in total). The selection is deliberately analytical rather than exhaustive. Within each mechanism we prioritize landmark results, methodological firsts, and papers that expose a deployment bottleneck over incremental leaderboard entries, so the survey argues a thesis rather than tabulating every entry. Conflict-of-interest disclosures are itemized in the [sec:coi]Disclosures at the end of the paper.
1.6. Roadmap
Table 2 summarizes the article’s organization. Each chapter from Section 2 to Section 9 is paired with the generalization mechanism or audit theme it covers, its anchor methods, the closed-set, normal-only baseline it replaces, and the central tension on which the chapter’s honest-assessment subsection turns. Read column-wise, the table is a quick-reference map; read row-wise, it tracks one chapter’s thesis from problem to open question. The remainder of the article elaborates each row in turn.
We treat the five-mechanism partition as a summary of the current literature rather than a deep-structural claim. The evidence supports method-level advances across the mechanisms, but deployment validation remains insufficient for a broad paradigm-shift claim. The research targets in Section 9.5 specify the evidence needed to reassess that conclusion.
2. The Established Baseline Being Replaced
Each generalization mechanism in Section 3, Section 4, Section 5, Section 6 and Section 7 is a response to a specific limitation of an established method line. This section gives the minimum baseline; readers are referred to prior surveys (Cao et al. 2024b,Liu et al. 2024) for the complete pre-wave method taxonomy, to the IM-IAD benchmark study (Xie et al. 2024a) for deployment-realistic protocols, to two recent living surveys covering the same window from different angles (Cheng et al. 2026a,Wang et al. 2025e), and to two specialty surveys for 3D and multimodal (Liang et al. 2025,Lin et al. 2025). Their conclusions on pre-wave work are largely consistent with ours, which lets this article concentrate on the subsequent transition. The differentiator here is the five-mechanism organization plus the eight-bottleneck cross-cutting matrix (Section 9); we frame this article as a complement to, not a replacement for, those references. Figure 3 frames the transition around the normal-only baseline reviewed in this section (left) and the five foundation-model priors covered in the rest of the article (right).
2.1. Established Method Lines and Their Saturation
- The closed-set, normal-only era and its saturation.
The closed-set, normal-only paradigm trains one detector per category from normal samples. Its main forms are memory-bank (Bachem et al. 2017,Roth et al. 2022), distillation (Batzner et al. 2024,Deng and Li 2022), and reconstruction (Liu et al. 2023b,Zavrtanik et al. 2021,Zavrtanik et al. 2022), with SuperSimpleNet (Rolih et al. 2025) later unifying unsupervised and supervised training under the same backbone. PatchCore reached 99.1% I-AUROC on MVTec-AD (Bergmann et al. 2019) in 2022; Section 8.1 shows this number has not been beaten in any apples-to-apples comparison through 2026. The MVTec-AD ceiling sits inside the test-set noise floor, and every subsequent generalization mechanism tries to escape this saturated axis rather than climb it.2
- The first multi-class wave: UniAD and one-model-per-dataset.
UniAD (You et al. 2022) and descendants ( , ,Lu et al. 2023) formalized multi-class unsupervised AD with one model across all categories within one dataset. Section 6 extends this line toward genuine cross-dataset transfer.
- The first foundation-model bridge: WinCLIP descendants and their saturation.
WinCLIP (Jeong et al. 2023) projected image patches into a frozen CLIP (Radford et al. 2021) space, scored against handcrafted defect-text prompts, and reached 91.8% MVTec-AD zero-shot I-AUROC. The first foundation-model bridges (Cao et al. 2024c,Cao et al. 2025,Li et al. 2025a,Li et al. 2024b,Qu et al. 2024,Zhou et al. 2024a) added learnable prompts, visual adapters, and SAM-driven masks. Across 18 months, these changes yielded only a 0.2–0.5% gain, indicating prompt-learning saturation. Section 3 covers the response.
- The first MLLM bridge: AnomalyGPT and MMAD.
AnomalyGPT (Gu et al. 2024) introduced a LLaVA-style 7B VLM fine-tuned on simulated MVTec-style VQA, producing detection plus natural-language description in one forward pass; successors (Cao et al. 2023,Deng et al. 2026a,Xu et al. 2025a,Zhang et al. 2025b) established the SFT-on-defect-prompts pattern, and MMAD (Jiang et al. 2025) became the de-facto MLLM-AD VQA leaderboard. Section 4 takes up both lines.
- Multimodal and 3D foundations.
The pre-wave 3D/multimodal line built frozen per-modality encoders with memory-bank scoring. Representative methods include M3DM (Wang et al. 2023) (Point-MAE (Pang et al. 2022) + DINO (Caron et al. 2021)), CPMF (Cao et al. 2024a), Real3D-AD (Liu et al. 2023a) (the first full-point-cloud benchmark beyond MVTec-3D-AD (Bergmann et al. 2022)), and PointAD (Zhou et al. 2024b) (ULIP/PointCLIP-style zero-shot). Section 5 takes the line forward.
- Anomaly synthesis foundations.
CutPaste (Li et al. 2021), DRAEM (Zavrtanik et al. 2021), AnomalyDiffusion (Hu et al. 2024b), RealNet (Zhang et al. 2024b), and AnomalyXFusion (Hu et al. 2024a) defined the pre-wave synthesis pattern. It combined a category-specific LDM, a hand-crafted mask, and ∼1000 DDIM steps evaluated by FID/KID and downstream lift. Section 7 shows this pattern breaking apart.
2.2. The Established Benchmark Ecosystem
The established benchmark set provides the context needed to interpret subsequent claims.
- MVTec-AD (Bergmann et al. 2019) has 15 categories and has been saturated above 99% I-AUROC since 2022.
- VisA (Zou et al. 2022) has 12 categories, harder per-pixel metrics, and remains active.
- MPDD (Jezek et al. 2021) and BTAD (Mishra et al. 2021) are smaller niche benchmarks.
- Real-IAD (Wang et al. 2024) has 30 categories, ∼150K images, and five viewpoints per part.
- MVTec-3D-AD (Bergmann et al. 2022), Real3D-AD (Liu et al. 2023a), and Anomaly-ShapeNet (Li et al. 2024a) are 3D and RGB-D benchmarks.
- MMAD (Jiang et al. 2025) is the MLLM-AD VQA leaderboard.
- IM-IAD (Xie et al. 2024b) provides a deployment-realistic protocol based on FPR-bound recall.
These benchmarks share the assumptions the wave sets out to break, including curated category sets, predominantly full-shot normal-only training, lab-controlled imaging, and a single dominant modality. They are being superseded for two reasons. First, the headline detection sets (MVTec-AD, VisA, MVTec-3D-AD) are saturated, with top scores now sitting inside the test-set noise floor (Section 8.1) and no longer separating competing methods. Second, even where unsaturated, they probe only a narrow slice of deployment reality. None exposes open-world product diversity, pose and identity variation, distribution drift, cross-domain transfer, or false-positive-bounded operating points, the failure modes that actually break deployed inspection (Section 9). The wave therefore forks the ecosystem along precisely these axes; Section 8.2 catalogues the 20+ new benchmarks, each built to expose one such failure mode.
3. Generalization Mechanism 1: Pretrained Visual Priors
The largest cluster of papers in the 2024–2026 wave draws generalization power from pretrained vision encoders (CLIP, DINOv2, DINOv3, RADIO, and point-language models), on the premise that pretraining already encodes enough appearance knowledge to separate normal from anomalous patches given the right adaptation. Figure 4 summarises how the field reacts to CLIP-adapter saturation. The 91–93% MVTec-AD I-AUROC band the 2023–2025 adapter generations sit in is crossed only in 2026, and only by methods that change the architecture rather than the adapter (MoECLIP MoE routing, MRAD retrieval memory, CoPS learned subspaces). These responses divide into three architectural branches (pure-VFM, retrieval-augmented, and training-free; Section 3.2) and two cross-modal bridges, to reasoning and to 3D (Section 3.3).
3.1. The CLIP Prompt-Engineering Line and Its Saturation
WinCLIP (Jeong et al. 2023) (Section 2) set a zero-shot mark of 91.8% MVTec-AD I-AUROC that its successors orbit rather than beat. Text-side refinements (AnomalyCLIP’s learnable object-agnostic prompts (Zhou et al. 2024a), PromptAD’s multi-shot template distillation (Li et al. 2024b)) and visual-side ones (AdaCLIP’s static-plus-dynamic visual context tokens (Cao et al. 2024c), VCP-CLIP’s nearest-neighbour visual prompts (Qu et al. 2024)) each reposition the prompt interface without changing what the frozen encoder can represent, which is why none escapes the band. AdaptCLIP (Gao et al. 2026) extends the branch to twelve-dataset adapter training (cross-domain behaviour in Section 6).
Recent papers continue both axes without escaping the band. FAPrompt (Zhu et al. 2025a) uses ten orthogonally-constrained abnormality prompt sets plus a data-dependent prior and lands squarely inside it; DAPO (Nazer et al. 2026) similarly optimizes hybrid fixed/learnable defect prompts on frozen CLIP for zero-shot multi-type detection and segmentation. Bayes-PFL (Qu et al. 2025a) swaps deterministic prompt fitting for a Bayesian flow with calibrated uncertainty, which is useful when bound-FPR metrics depend on threshold sharpness. AA-CLIP (Ma et al. 2025) adds an anomaly-aware re-projection without extra text supervision. PromptMoE (Shao et al. 2026) routes among eight prompt experts per layer and holds its accuracy across seven industrial datasets rather than one; MoECLIP (Park et al. 2026) adds patch-level routing with Frozen Orthogonal Feature Separation and an ETF loss, becoming the first prompt-line method to clear the band (93.9% MVTec-AD). CoPS (Chen et al. 2026b) samples per-image class/prototype tokens via a VAE, edging past FAPrompt; FB-CLIP (Hu et al. 2026) disentangles foreground/background tokens.
The aggregate trajectory (WinCLIP 91.8 → AdaCLIP 89.2 → FAPrompt 91.9 → MoECLIP 93.9) spans only ∼2 pp MVTec-AD I-AUROC over three years, non-monotone and with no generation clearing 94% (Figure 4). The 2026 break comes from architectural change in MoE routing, retrieval memory, and learned subspaces, motivating the three branches below.
Regime caveat. The 91–93% band describes strict zero-shot single-image inference. Several Section 3.2 numbers above the band are measured under different regimes. MuSc (Li et al. 2026c) and RareCLIP (He et al. 2025) are transductive; AnomalyVFM (Fučka et al. 2026) and FoundAD (Zhai et al. 2026) train LoRA / a Manifold Projector on synthetic anomaly pairs before their “zero-shot” test phase; SubspaceAD (Lendering et al. 2026) and FoundAD require 1–4 normal references at test. In a matched comparison, AnomalyVFM scores 94.1 and MRAD 94.0 vs. MoECLIP 93.9. The visible 4–6 pp gap therefore collapses to ∼0.1–0.2 pp. DIVE (Lu et al. 2026a) examines the diversity of anomalies in the auxiliary source as a separate regime variable. It injects text embeddings at shallow and deep visual layers and disentangles object semantics from object-agnostic anomaly prompts. It reports results on twelve datasets under a restricted auxiliary-prior budget.
Beyond zero-shot prompting. The frozen CLIP prior is also exploited in two non-zero-shot forms. FocusPatch AD (Ding et al. 2025) builds a vision-language few-shot multi-class detector that binds anomaly-state keywords to discrete local patches, concentrating cross-category attention while suppressing background false positives under one unified model. tGARD (Qiang et al. 2025) instead turns CLIP into a semantic controller for reconstruction. Dynamic text embeddings from the CLIP encoder condition an adversarial discriminator so that normal-image reconstruction becomes semantically steerable, while a high-frequency branch preserves detail. Both stay bounded by the same frozen-CLIP prior, but show its reach extends past prompt-only zero-shot classification into few-shot multi-class and reconstruction pipelines.
3.2. Architectural Responses
- Text-free visual encoders.
Several studies test whether competitive zero- and few-shot detection requires vision-language alignment. SubspaceAD (Lendering et al. 2026) applies PCA to frozen DINOv2 patches from one to four normal references, without a text branch or trained parameters. It reports 97.1% MVTec-AD 1-shot I-AUROC, +6 pp over AnomalyDINO (Damm et al. 2025). FoundAD (Zhai et al. 2026) instead trains one lightweight Manifold Projector via CutPaste synthesis for all categories, matching prior few-shot leaders at roughly a tenth of their parameter count.
AnomalyVFM (Fučka et al. 2026) LoRA-tunes RADIO on purely synthetic anomaly pairs and ties the strongest CLIP adapters zero-shot at real-time latency. VisualAD (Hou et al. 2026) (cross-ref Section 6) removes the text branch with a two-order-of-magnitude reduction in trainable parameters and essentially no accuracy cost. On the reported benchmarks, these results question whether text supervision is necessary for competitive ZSAD. The interpretation remains limited by SubspaceAD’s Gaussian-feature assumption and by the combination of RADIO features and synthesis supervision in AnomalyVFM’s “zero-shot” setting.
- Retrieval-augmented and memory-driven.
Retrieval-based methods extend PatchCore with cross-dataset labeled memory or learned cost-volume denoising. MRAD (Xu et al. 2026a) stores labeled patch prototypes from an auxiliary dataset and scores via soft-max cross-attention. Its train-free variant beats WinCLIP, and the full variant reports results across sixteen datasets rather than the usual two. RareCLIP (He et al. 2025) accumulates cross-image statistics online through Sequential Coreset and Patch-image Similarity banks with k-NN rarity proxies. Its gains are transductive and incur streaming latency, so the regime caveat above applies.
RAID (Cai et al. 2026b) uses a three-level DINOv2 vector database with MoE cost-volume denoising. Its main gain is in fine-grained localisation, where pixel-AP is some ten points above AnomalyDINO; image-level scores are already close to saturation. FastRef (Tian et al. 2025) provides a plug-in test-time adaptation that converges in two iterations. These results narrow the zero-shot/full-shot gap, but localisation remains less saturated than image-level classification.
- Training-free, non-conformity, and geometric variants.
DictAS (Qu et al. 2025b) reformulates few-shot AS as dictionary lookup with self-supervised K/V generators and a Sparse Probability Module, leading five industrial few-shot-segmentation benchmarks and transferring to MVTec-3D without any 3D adaptation. Three CVPR 2026 papers instantiate non-conformity scoring in non-Euclidean spaces (graph Laplacian, semantic graviton fields, hyperbolic feature synthesis). Odd-One-Out (Bhunia et al. 2025) replaces stored-normality matching with nearest-neighbour comparison, sidestepping the per-category training assumption that fails on Kaputt-style open-world deployment. DPDL (Wang et al. 2025a) handles the supervised open-set case via distribution-prototype diffusion with calibrated scores. Across these approaches, generalization is less tightly coupled to category-specific trainable parameters.
3.3. Cross-Modal Bridges
- LMM-assisted zero-shot segmentation (bridge to Section 4).
AG-VAS (Qu et al. 2026) is the first 2026 7B-MLLM zero-shot segmentation system, combining LLaVA-OneVision-7B, SAM-ViT-H, three learnable anchor tokens ([SEG]/[NOR]/[ANO]), Semantic-Pixel Alignment, and an Anchor-Guided Mask Decoder; it lifts MVTec-AD segmentation AP far above the strongest CLIP-adapter baseline (51.0 vs. 29.9) and transfers to medical imagery without medical training. Absolute pixel scores still trail CLIP adapters, but normal-region reasoning and instruction-following segmentation are qualitatively distinct capabilities the adapters do not have.
- 3D-meets-VFM (bridge to Section 5).
Two CVPR 2026 papers extend zero-shot VFMs to 3D. BTP (Li et al. 2026b) uses a ULIP2 Point-Language Model + Multi-Granularity Feature Embedding (PLM + learned geometric + CLS features), reaching 84.5% Real3D-AD point-AUROC (+11.0 pp over PointAD) but only 61.4% O-AUROC; localization gains do not transfer to global detection. GS-CLIP (Deng et al. 2026c) keeps 2D projection but adds geometry-aware prompts (PointNet++ + Geometric Defect Distillation) and a LoRA-adapted depth branch, +1–2 pp O-AUROC across four datasets. Neither closes the 3D–2D zero-shot gap.
3.4. Evidence Under Matched Regimes
Current results suggest that text supervision is not always required in few- and zero-shot settings. SubspaceAD reaches 97.1% MVTec-AD 1-shot I-AUROC with PCA over DINOv2-G and no text or trained parameters. AnomalyVFM ties the adapter methods zero-shot (94.1% vs MoECLIP 93.9%), while AG-VAS reports reasoning-oriented segmentation from a 7B model with ≤3 anchor tokens.
The frequently reported 4–6 pp advantage of pure VFMs over CLIP adapters is largely caused by regime mismatch. Once MuSc/RareCLIP are identified as transductive and AnomalyVFM/FoundAD as synthetic-trained, the matched-regime gap is ∼0.1–0.2 pp. None of these methods is evaluated on Kaputt or another Tier-1 open-world benchmark at bound-FPR operating points (Section 8.3); UniSpector’s 69.1%→14.1% cross-domain drop (Section 6.4) illustrates the scale of degradation that remains possible. A stronger test would report a Section 3 method on a Tier-1 benchmark, such as Kaputt’s ≤3-reference protocol, Real-IAD-Variety, or MANTA, together with a bound-FPR metric (AP at FPR≤1% or F1 at fixed precision) and AUROC.
4. Generalization Mechanism 2: Language and Reasoning Priors
The AnomalyGPT–MMAD line (Section 2.1) established the 2024 SFT-on-industrial-VQA template.3 The 2024–2026 wave identifies three weaknesses in that template. SFT stalls at reasoning-answer inconsistency, models lack inference-time domain knowledge, and standard architectures encode comparison images independently. It builds partially overlapping replacement mechanisms (Figure 5).
4.1. Capability Axes: Detection Versus Reasoning
Detection means producing a binary label or pixel anomaly score evaluated by AUROC, the axis on which PatchCore (Roth et al. 2022), EfficientAD (Batzner et al. 2024), and IM-IAD (Xie et al. 2024b) operate. Reasoning means producing a structured response covering one or more of the seven MMAD subtasks (Jiang et al. 2025), namely discrimination, classification, localization, description, analysis, object classification, and object analysis, evaluated by VQA accuracy. The two axes are related but not equivalent, and recent papers occupy four positions in this space (Table 3). Provenance disclosures for MMAD and several M-3LAB-adjacent works mentioned below are consolidated in [sec:coi]Disclosures.
4.2. Approaches to Reasoning-Oriented Adaptation
- Training-paradigm shift: SFT to GRPO/RL.
AnomalyGPT-era SFT (Gu et al. 2024) trained on supervised VQA pairs with no signal about reasoning-path validity. Recent studies instead use GRPO-based post-training. IAD-R1 (Li et al. 2026d) pairs PA-SFT with Structured-Control GRPO using four simultaneous rewards (86.1% mean binary across six datasets), while AD-FM (Liao et al. 2026) uses a continuous GIoU reward that fixes GRPO reward-variance collapse (83.56% MMAD, LoRA only).
JUDO (Kang et al. 2026a) runs a three-stage curriculum of juxtaposed segmentation, GPT-4o domain QA, and GRPO, reaching 81.20% MMAD, on par with Gemini-2.5-Pro. ReADL (Jin et al. 2026)’s CGRO reward recovers pixel localisation from image-level supervision. These are balanced binary numbers rather than AUROC at low FPR (see Section 4.5). SFT-only baselines Triad (Li et al. 2025d) and MAU-GPT (Wang et al. 2026e) trail on MMAD breadth, and AnomalyR1 (Chao et al. 2025) is the preprint that first established the GRPO recipe.
- Knowledge-grounded inference.
Domain knowledge can also be retrieved at inference rather than incorporated through post-training. ADSeeker (Zhang et al. 2026a) is a plug-and-play RAG with Q2K retrieval over SEEK-M&V (69.90% MMAD; 94.3/91.5% MVTec/VisA zero-shot AUROC). Reason-IAD (Chen et al. 2026a) uses training-free latent reasoning over continuous think tokens with RAKI category retrieval (79.43% MMAD on Qwen3-VL-8B). EAGLE (Peng et al. 2026) connects a frozen PatchCore expert to a frozen MLLM through Distribution-Based Thresholding and Confidence-Aware Attention Steering; IAD-GPT (Li et al. 2025e) is the train-time analogue. This approach avoids task-specific post-training but currently trails GRPO. JUDO’s ablation gives SFT+RAG 76.29% vs. SFT+GRPO 77.29%; ADSeeker has 17% retrieval failure on test-split MVTec/VisA categories; and Reason-IAD’s entropy reward is self-referential. GLLS (Deng et al. 2026b) performs training-free verification. Its Part-Aware Visual-Logical Atlas organizes normal references and specifications. A global stream checks their logic, while Monte Carlo tree search selects local evidence crops under a fixed budget. This in-context protocol is not directly comparable with SFT/GRPO training.
- Visual comparison: the new architectural frontier.
Standard MLLM architectures encode query and reference images independently, leaving comparison to language-space attention. Several systems add explicit visual-comparison components for subtle pixel-level differences. AD-Copilot (Jiang et al. 2026b) uses a DETR-style Comparison Encoder under a four-stage curriculum (82.3% MMAD, BBox gain), while JUDO(Kang et al. 2026a) Stage-1 juxtaposed segmentation contributes +11.84 pp MMAD localisation, the single largest per-stage ablation gain. Triad(Li et al. 2025d) pipes MuSc/AnomalyCLIP through an Expert-Guided RoI tokeniser (+1.4–2.5% trained, −14–23% zero-shot). SAGE (Zang et al. 2025) and OmniAD (Zhao et al. 2025) add Self-Guided Fact Enhancement and unified detection-plus-explanation respectively. The ablations in AD-Copilot and JUDO suggest that direct comparison between query and reference features is important, although current studies do not establish whether an end-to-end comparator is preferable to frozen-expert injection.
4.3. Benchmarks: From MMAD to the Second Generation
MMAD (Jiang et al. 2025), with 39,672 multiple-choice questions over 8,366 images across seven subtasks, gave recent MLLM-AD studies a shared multi-subtask protocol in place of binary AUROC.
Second-generation benchmarks. MMR-AD (Yao et al. 2026) is the largest training-and-evaluation set, with 127K samples, 188 categories, 395 anomaly types, and 112,875 manual bounding boxes paired with Qwen2.5-VL-72B-generated CoT rationales. MAU-Set (Wang et al. 2026e) emphasises breadth (35 product types, 224K QA pairs over 6 industrial domains); MAU-GPT scores 82.12% discriminative on MAU-Set but only 61.41% on MMAD, suggesting distribution-locality. Chat-AD (Jiang et al. 2026b) (620K+ samples, 327 categories) is the largest training corpus but remains partly proprietary. M3-AD targets the multimodality gap (RGB-D, thermal, point cloud). Dataset scale moved from MMAD’s 8K to 620K within 18 months.
4.4. Failure Modes
Detection-reasoning trade-off. GRPO-trained models scoring high on MMAD reasoning often show degraded binary discrimination. JUDO reports 65.04% post-training vs. 71.39% for base Qwen2.5-VL-7B (−6.35 pp on the simplest IAD task). No paper resolves the tension; JUDO Stage 1 and AD-FM’s <rethink> narrow but do not close the gap, which matters because binary detection is the primary deployment function.
- Hallucination and visual grounding. Linguistically plausible but visually ungrounded responses pass MMAD subtask scoring through text similarity for description and a coarse grid for localisation, while failing pixel-precise inspection. ADSeeker’s 17% retrieval failure has no recovery path; Reason-IAD’s entropy reward incentivises confident wrongness; the grid-vs-pixel gap is evaluated only in MMAD-BBox, reported so far only by AD-Copilot.
- Benchmark circularity. MMAD’s creators currently hold the top MMAD score; JUDO’s Stage 2 derives training QA from MMAD’s knowledge snippets; ADSeeker’s SEEK-M&V knowledge base covers exactly MMAD’s MVTec/VisA categories. These structural overlaps do not automatically invalidate the numbers but make it hard to disentangle reasoning capability from MMAD-distribution adaptation. Cross-group benchmark governance is needed (Section 9.6).
- Deployment-faithful evaluation gap. No Section 4 method evaluates precision-recall at industrial false-positive rates (e.g., <1% FPR, the IM-IAD (Xie et al. 2024b) protocol); none is compared to PatchCore (Roth et al. 2022) or EfficientAD (Batzner et al. 2024) at deployment-realistic operating points. This is the most critical open gap in the entire MLLM-AD subfield.
4.5. Evidence Across Reasoning and Detection Tasks
Across different backbones and reward designs, IAD-R1, AD-FM, JUDO, and ReADL report gains from SFT→GRPO. On the same Qwen2.5-VL-7B backbone, ADSeeker 69.90% → JUDO 81.20% is larger than any SFT-era MMAD improvement. Visual-comparison ablations also provide evidence for paired-image processing. JUDO Stage-1 improves localisation by +11.84 pp, and AD-Copilot reports a BBox gain.
These gains are concentrated in reasoning-oriented benchmarks. MMAD benchmark circularity, where its creators top the leaderboard, is compounded by JUDO’s −6.35 pp binary detection regression after GRPO post-training. No MLLM in this batch beats PatchCore or EfficientAD at deployment-faithful operating points, while SALAD (Fučka et al. 2025) reaches 96.1% AUROC on MVTec LOCO without a language component. A deployment-relevant result would require cross-group evaluation on MMR-AD by groups not on MMAD authorship, together with an MLLM-AD method that matches PatchCore-level binary detection on VisA at FPR≤1% while exceeding 80% MMAD-overall accuracy.
5. Generalization Mechanism 3: Geometric and Multimodal Priors
The third mechanism treats sensing modality as inductive bias, building representations from point clouds, depth, multi-view, and image-text pairs.4 Building on the pre-wave memory-bank baseline (M3DM (Wang et al. 2023), CPMF (Cao et al. 2024a), Real3D-AD (Liu et al. 2023a), PointAD (Zhou et al. 2024b); Section 2), the 2024–2026 wave responds to benchmark saturation, mismatched geometric representations, and missing language grounding. Scope. SCoNE (Xu et al. 2026c) (tabular) and Wave-MambaAD (Zhang et al. 2025a) (2D) are excluded.
5.1. The MVTec-3D-AD Saturation Problem
MVTec-3D-AD (Bergmann et al. 2022) was pushed above 97% by CFM (Costanzino et al. 2024), leaving little headroom; G2SF (Tao et al. 2025) and IB-IUMAD (Long et al. 2026) extract only marginal gains. MiniShift (Cheng et al. 2026b) introduces 2,577 point clouds at 500k points with sub-1% anomaly coverage; deep backbones approach random on the hard tier while handcrafted multi-scale descriptors outperform transformers at >20 FPS. SiM3D (Costanzino et al. 2025) trains on a single nominal instance and adds a CAD-to-real synth2real protocol where all five adapted baselines (BTF, M3DM, CFM, AST, EfficientAD) degrade substantially, using voxel-based Anomaly Volumes instead of 2D maps. Both expose that resolution has been too coarse and training scenarios too generous (Figure 6).
5.2. Stronger Geometric and Multimodal Representations
- Rotation-invariance and geometric-feature rethinking.
Recent methods revise different parts of the PointMAE + FPFH + Euclidean-memory pipeline. CASL (Zha et al. 2026) diagnoses a coordinate-to-coordinate SSL shortcut and substitutes multi-scale curvature (+5.6% O-AUROC on Real3D-AD). PO3AD (Ye et al. 2025) predicts per-point offsets toward a learnt normal field. Reg2Inv (Yu et al. 2025b) jointly trains registration and AD via a Geometric Transformer with RIConv++, beating Reg3D-AD (Huang et al. 2022) and Group3AD (Zhu et al. 2024).
PASDF (Zheng et al. 2025) replaces discrete points with a continuous SDF that also provides a repair template (80.2/90.0% O-AUROC on Real3D-AD/AS). HPF-APC (Kang et al. 2026b) targets planar/angular deformations through MinkUNet34C and a multi-scale patch codebook with RoPE (84.2/87.6%). These methods do not provide zero-shot or language-grounded results (Table 4).
- RGB-D fusion quality.
G2SF (Tao et al. 2025) replaces isotropic Euclidean distance with an anisotropic Local Scale Prediction metric (SOTA AUPRO@1% on MVTec-3D / Eyecandies). PIRN (Li et al. 2026e) attacks few-shot multimodal where CFM/M3DM degrade, using a prototype codebook with balanced OT and adaptive GRU, dominating baselines at 1–10 shots on Eyecandies. CIF (Lin et al. 2026) uses hypergraph-enhanced memory for query/few-shot co-occurrence. CMDS-AD (Cai et al. 2026a) decouples the modalities in a cross-modal dual-stream and uses diffusion to augment scarce few-shot data. U-MV (Chen et al. 2026c) introduces progressive homography-guided alignment so multi-view 3D AD no longer needs known camera pose. PADFormer (Wang et al. 2026c) instead learns masked cross-view reconstruction from sparse normal references. It aligns features without camera poses or 3D reconstruction. This image-space route extends the pose-agnostic setting without supplying a native 3D prior. 2M3DF (Asad et al. 2025) fuses multi-view RGB and point-cloud features from pretrained extractors on a pixel-to-point basis and fits a multivariate Gaussian to the fused normal distribution, reporting gains on MVTec-3D-AD and Eyecandies; it stays within the pretrained-backbone-plus-distribution-modelling family rather than introducing a native 3D prior.
5.3. Generalist, Language-Grounded, and Zero-Shot 3D
- Multi-class unified 3D and multimodal AD.
UniAD-style models now extend to 3D and multimodal settings. SeDiR (Kim et al. 2026b) addresses Inter-Category Entanglement with Coarse-to-Fine Tokenisation, Category-Conditioned Contrastive, and a Geometry-Guided Decoder, reporting higher performance than MC3D-AD (Cheng et al. 2025). UniMMAD (Zhao et al. 2026) trains one model on 9 datasets / 12 modalities / 66 categories through a Cross-MoE decoder, providing an example of MoE scaling in 3D/multimodal IAD. IB-IUMAD (Long et al. 2026) pairs Information Bottleneck Fusion with a Mamba decoder in the incremental setting, edging past IUF (Tang et al. 2024) at a fraction of M3DM’s runtime. All three need category labels at training.
- Language-grounded industrial defects.
IMDD-1M (Ni et al. 2026) supplies 1.24M image-text pairs across 63 manufacturing domains and 421 defect types, roughly 18× Real-IAD (Wang et al. 2024). An 860M text-conditioned diffusion U-Net with implicit captioner and Mask2Former head handles segmentation, detection, retrieval, and captioning, reportedly matching specialised models with <5% task data. Although 2D-only, it supplies the text substrate future native-3D grounding will need. The relevant cross-tags are Section 3.2 (pure-VFM few-shot) and Section 4.3 (MLLM-AD training data), addressing the knowledge-base gap of ADSeeker (Zhang et al. 2026a) and Reason-IAD (Chen et al. 2026a).
- 3D-Meets-VFM revisited.
BTP (Li et al. 2026b) (cross-tag Section 3.3) projects point clouds to 2D for CLIP plus geometric point features; it is zero-shot but discards 3D information like PointAD. GS-CLIP (Deng et al. 2026c) (cross-tag Section 3.3) augments CLIP with curvature/normal prompts, beating PointAD zero-shot on Real3D-AD and AS but still projection-dependent. CoGeoAD (Xu et al. 2026b) renders pixel-aligned color and geometric views, aggregates them with data-driven multi-view attention, and fuses multi-level frozen-CLIP features. Its protocol trains on one of MVTec3D-AD and Eyecandies and tests on the other; this is cross-dataset zero-shot transfer, not strict zero-shot evaluation with neither benchmark used for training.
5.4. Open Problems
Current 3D priors are limited by the absence of a counterpart to CLIP/DINOv2. Point-cloud pretraining with Point-MAE, PointGPT, or ULIP uses corpora orders of magnitude smaller than web-scale image data, and no natively pretrained 3D representation in the surveyed literature supports zero-shot detection on its own. PointAD, BTP, and GS-CLIP therefore route through 2D projection to borrow a 2D foundation model’s prior, discarding some of the geometric information that motivates 3D sensing. Native 3D-language grounding also remains open. IMDD-1M supplies a text substrate, but no jointly trained 3D-language space exists.
Multimodal fusion is also underdetermined. Existing methods combine RGB and geometry through per-modality memory banks (M3DM), cross-modal feature mapping (CFM), score-level fusion (G2SF), information-bottleneck fusion (IB-IUMAD), or dual-stream decoupling (CMDS-AD). No study establishes which fusion level is appropriate for a given defect type. These choices are validated almost exclusively on saturated MVTec-3D-AD, while the documented tendency of RGB features to dominate weaker geometric features remains unresolved.
SiM3D exposes a separate CAD-to-production problem. Every adapted baseline degrades under its synth2real protocol. Current results therefore do not support a CAD-first workflow in which a model is trained before real scans from a new production line are available. Active Real-to-Twin inspection (Liu et al. 2026) scores physical observations against geometrically matched CAD digital twins under active viewpoint selection, but remains an early prototype.
PASDF (Zheng et al. 2025) combines detection and repair through an SDF, although its evidence is qualitative and limited to clean registration. Benchmark adoption remains fragmented. MVTec-3D-AD is common despite saturation, Real3D-AD and AS are used inconsistently, and MiniShift/SiM3D have not become secondary standards.
5.5. Evidence Beyond MVTec-3D-AD
Current evidence supports progress in curvature and registration objectives, including CASL’s Real3D-AD gain and PASDF’s detection-plus-repair formulation. UniMMAD covers 12 modalities × 66 classes in one checkpoint, while IMDD-1M provides 1.24M industrial-defect image-text pairs for language-grounded work.
The evidence outside curated benchmarks is much thinner. MVTec-3D-AD is saturated, while “zero-shot 3D” bridges such as GS-CLIP and BTP are evaluated only on per-instance-aligned-scan benchmarks and inherit their priors from 2D projection. No Section 5 method reports on SiM3D’s CAD-to-production synth2real protocol, which breaks every adapted baseline, or on bound-FPR metrics.
A stronger result would include SiM3D synth2real evaluation for a new method in this section, zero-shot 3D evidence from a natively pretrained 3D representation rather than another 2D-projection bridge, and an ablation isolating the contribution of the fusion level.
6. Generalization Mechanism 4: Universal Task Priors
Unlike the mechanisms in Section 3, Section 4 and Section 5 that borrow generalization from external sources (visual backbones, language models, and 3D priors), the methods here attempt to build a single internal representation spanning anomaly types, categories, and modalities, a universal task prior learned from variation within IAD itself. Current results are partial. MoE routing, CLIP adapters, and visual-only meta-learning improve performance within their evaluated settings, but none transfers to a truly unseen industrial domain without target-domain data.
Cross-tag note. Three MoE-based papers primarily housed elsewhere have their routing mechanics unpacked here. They are PromptMoE (Shao et al. 2026) and MoECLIP (Park et al. 2026) from Section 3.1, and UniMMAD (Zhao et al. 2026) from Section 5.3.
Figure 7 sketches both the design-pattern shift (per-dataset detector stack → single backbone + convergent MoE routing) and the class-count axis the section operates along (C=1 specialists to the CCL scaling wall at C=81).
6.1. The Arc from "One Model Per Class" to "One Model Per Domain"
The closed-set era trained per-category detectors (Batzner et al. 2024,Deng and Li 2022,Roth et al. 2022); UniAD (You et al. 2022) and its descendants (Section 2) broke this with joint multi-class training within a dataset, but without cross-dataset transfer claims. The subsequent generalist phase, driven by WinCLIP-style CLIP transfer (Jeong et al. 2023) and cross-dataset meta-learning (Yao et al. 2024,Zhu and Pang 2024), attempts the per-class → per-dataset → across-domains step. However, “cross-domain” in 2026 still means transfer between curated suites sharing an ImageNet-like prior (Section 6.5).
6.2. Routing and Adapter Generalists
- Mixture-of-experts routing.
Mixture-of-experts routing appears independently in several recent IAD systems that handle heterogeneous inputs. AnomalyMoE (Gu et al. 2026) routes through three expert groups (structural, component, and global-logical) on a frozen DINOv2 backbone with Top-K sparse gating, mutual-information repulsion, and selection balancing. Its gate ablations indicate that the expert groups carry non-redundant information, with the global expert contributing most on logical benchmarks. One unified model remains near saturation on the standard industrial suites while also covering logical, medical, 3D, and video anomaly benchmarks.
UniMMAD (Zhao et al. 2026) extends MoE routing to modality (RGB / depth / point-cloud / infrared), PromptMoE (Shao et al. 2026) routes prompt experts, and MoECLIP (Park et al. 2026) replaces CLIP adapters with MoE layers. Although these studies are not directly comparable, their results motivate sparse routing when the input domains or modalities are heterogeneous.
- CLIP-adapter universal detectors.
This sub-branch treats CLIP (Radford et al. 2021) as a frozen universal encoder and asks how little fine-tuning suffices for cross-domain IAD. AdaptCLIP (Gao et al. 2026) evaluates on 12 datasets across industrial and medical domains in zero- to 4-shot settings. Three adapters (visual MLP, text prompts, and prompt-query residual) attach at CLIP’s input/output and must be trained alternately because joint training degrades. They add under half a million parameters while staying competitive at both the industrial and medical ends. AnoPLe (Lee et al. 2026) uses class names alone with bidirectional text-visual prompt coupling, degrading roughly four times less than INP-Former (Luo et al. 2025) on held-out categories; UniVAD (Gu et al. 2025) provides a training-free comparison. MultiADS (Sadikaj et al. 2025) extends binary to K+1 states via a manually-curated KBA for zero-shot multi-type defect segmentation, but its per-defect-type localisation remains poor. Across these methods, the attainable domain boundary remains constrained by the CLIP prior.
6.3. Reference- and Prototype-Based Generalists
- Language-free visual generalists.
VisualAD (Hou et al. 2026) challenges the necessity of language. Removing AnomalyCLIP’s (Zhou et al. 2024a) text encoder causes negligible degradation while cutting trainable parameters by over 99%. Two learnable global tokens (anomaly + normal) prepend to a frozen CLIP ViT-L/14 with Spatial-Aware Cross-Attention and a cosine-margin contrastive loss. The result suggests that, on the reported benchmarks, two visual prototypes can provide much of the function attributed to learned text prompts. The evidence is backbone-dependent, and the weaker medical results show that this visual generalization does not transfer uniformly across settings.
- Meta-learning with richer reference sets.
NAGL (Wang et al. 2025d) extends InCTRL/ResAD meta-learning with one abnormal reference alongside the normal references. The instructive finding concerns how the abnormal reference helps. Naive score fusion actually degrades performance, and the gain only materialises through a learned Residual Mining module plus cross-attention. On a frozen ViT-S it runs an order of magnitude faster than InCTRL and transfers well across industrial suites, but drops sharply on medical data. Its advantage applies only when the abnormal reference matches the test defect type; otherwise it collapses to the normal-only variant.
6.4. Multi-Class Unified and Open-Set Tracks
- Multi-class unified track.
Two papers remain in the UniAD lineage without universality claims but clarify why naive joint training does not scale. MaskAD (Lu et al. 2026b) uses the MAE “identical shortcut” as a measurement device, measuring Sinkhorn distance between reconstruction-error distributions under parallel masking. It edges out MambaAD (He et al. 2024) and the UniAD/DiAD line on both detection and localisation, although its coreset stays tied to the training distribution. CCL (Fan et al. 2025b) diagnoses inter-class confusion and addresses it through K-Means class-aware contrastive learning. The harder COCOAD reveals a scaling wall, with 65.2% at vs. above 90% at . UniMF (Jiang et al. 2026a) pushes the unified multi-class setting into the multimodal, few-normal regime, training one model across categories from as few as 1–4 normal samples each and reporting cross-dataset multimodal results, in contrast to the one-for-one paradigm’s per-class sample budget.
Dinomaly (Guo et al. 2025c) uses a DINOv2 ViT-B, a minimal linear head, and joint training. It saturates the standard suites and holds up on Real-IAD; Dinomaly2 (Guo et al. 2025b) extends the design across single-/multi-/few-shot settings under one checkpoint. These results place more weight on backbone quality as a source of multi-class performance, but do not isolate it from architectural effects. RAD (Zhang et al. 2026c) further tests whether task-specific training is needed by using frozen-feature retrieval for training-free multi-class detection. INP-Former (Luo et al. 2025), UniNet (Wei et al. 2025), CostFilter-AD (Zhang et al. 2025c), DecAD (Wang et al. 2025c), and DeCo-Diff (Beizaee et al. 2025) add complementary approaches; none reports transfer outside the curated suite.
- Unified logical and structural anomalies.
LogiCo (Zhang et al. 2026d) maps DINOv3 features into a component-level space, then reconstructs component and patch features jointly; a segmentation-map discriminator handles count errors. Here, “unified” refers to logical and structural anomaly types on four benchmarks, not transfer to an unseen domain.
- Open-set supervised multi-prototype priors.
DPDL (Wang et al. 2025a) learns prototype-distribution transport from limited labeled anomalies. MPFM (Wang et al. 2026b) builds on this line by mapping normal features to a structured Gaussian-mixture prototype space and learning mode-aware transport with conditional flow matching. Mutual-information regularization limits component collapse and preserves normal modes that a unimodal boundary may flag as defects. The hard protocol trains on anomalies from one category and tests on anomalies that include unseen categories. Under this protocol, MPFM exceeds DPDL on all six reported datasets in both one- and ten-shot settings. These image-level results use labeled anomalies and CutMix; they do not establish pixel localization or unchanged transfer across domains.
- Open-set defect recognition.
UniSpector (Kim et al. 2026a) addresses open-set defect recognition via visual prompting from annotated exemplars, using a DETR-style architecture with spatial-spectral and angular-margin contrastive prompt encoders. On the new InsA benchmark (six datasets), in-domain Real-IAD scores 69.1 , but cross-domain 3CAD drops to 14.1. This near-fivefold decrease provides a quantitative example of the transfer limitation discussed in Section 6.5. IMDD-1M (Ni et al. 2026) and MAU-GPT (Wang et al. 2026e) are the open-vocabulary siblings of UniSpector (Section 8.3).
6.5. Generalization Beyond Curated Suites
The strongest evidence in this section concerns mechanisms within curated suites. AnomalyMoE’s gate ablations support task-adaptive specialization under heterogeneous routing. VisualAD reports negligible degradation after removing the text branch, and NAGL finds that abnormal references help through learned residual cross-attention rather than score fusion. ADPretrain (Yao et al. 2025) trains AD-specific representations on Real-IAD with angle/norm-oriented contrastive losses and reports that ImageNet pretraining is a sub-optimal prior even when frozen.
Evidence for zero-data deployment remains absent. AnomalyMoE is trained jointly on all eight of its evaluation datasets; UniSpector drops 69.1%→14.1% AP50b cross-domain; and CCL’s COCOAD results fall from 90.6% I-AUROC at C=60 to 65.2% at C=81. A convincing generalist result would reach >90% AUROC on a held-out industrial domain (wafer / X-ray / audio anomaly) without target-domain fine-tuning and would evaluate above C=81.
7. Generalization Mechanism 5: Generated Abnormal Priors
The fifth mechanism addresses the supply of abnormal training examples. Since AnomalyDiffusion (Hu et al. 2024b) (Section 2), synthesis methods have changed their conditioning signals, adaptation regimes, runtime, output format, and model architecture.5
7.1. Changes Since AnomalyDiffusion
Text and VLM conditioning now appear throughout the synthesis pipeline (Figure 8). Examples include CLIP in AnoStyler (So and Kang 2026) and Anomagic (Jiang et al. 2026d), GPT-4V in AnomalyPainter (Lai et al. 2026), Qwen2.5-VL-32B in ARAS (Qian et al. 2026), and Qwen2-VL in SynSur (Kühn et al. 2026). Adaptation requirements also vary. O2MAG (Rao et al. 2026) and TF-IDG (Xu et al. 2025b) freeze the diffusion prior, whereas MAGIC (Choi et al. 2026) and SeaS (Dai et al. 2025) use 5–20 reference images.
Runtime and output formats have changed alongside conditioning. FAST (Xu et al. 2025c) compresses 1,000 sampling steps to 10 through its AIAS trajectory, and ARAS reports a 5× generation speedup over diffusion. SeaS and FAST generate an image and mask in one forward pass. The underlying architectures now include SDXL + ControlNet (AnomalyPainter), Anydoor (TF-IDG), Infinity-8B autoregressive tokens (ARAS), Flux.1-dev DiT (SynSur), and a CLIP-guided U-Net without diffusion (AnoStyler).
7.2. Method Families
- Few-shot fine-tuning: MAGIC and SeaS.
MAGIC (Choi et al. 2026) fine-tunes SD2-inpainting via DreamBooth, Gaussian Prompt Perturbation, Spatially Adaptive Guidance, and Context-Aware Mask Alignment, cutting the AnomalyDiffusion-era KID by more than half while keeping downstream detection at the ceiling; DefectFill (Song et al. 2025) is the sibling inpainting baseline. SeaS (Dai et al. 2025) fine-tunes SD v1.4 under a separation-and-sharing principle (Unique-Anomaly tokens for defects, shared tokens for texture, plus Direct-Anomaly / Normal-Alignment / Reverse-Mask losses), posting the cohort-best generation quality by a wide margin and the largest downstream pixel-AP gain; DualAnoDiff (Jin et al. 2025) is the dual-diffusion alternative. Both still pay per-category fine-tuning, which is manageable at 15 categories but problematic for Real-IAD’s 30 or open-world deployment. APO (Wang et al. 2026a) casts anomaly generation as per-category preference optimization over diffusion denoising trajectories and uses a few real anomalous references. Its reported evaluation is confined to MVTec-AD.
- Training-free one-shot: O2MAG and TF-IDG.
O2MAG (Rao et al. 2026) freezes SD v1.5 and grafts reference self-attention keys/values into target-texture and background branches (Triple Attention Grafting) with Attention-Guided Optimization. TF-IDG (Xu et al. 2025b) adapts Anydoor with Sinkhorn-aligned DINOv2 features + dynamic Anomaly Area Masking + AdaIN. The two methods report downstream results within a fraction of a point of fine-tuned MAGIC/SeaS, suggesting that one reference and frozen-diffusion attention may be sufficient for similar detection gains. Fine-tuning still provides a large image-quality margin (three orders of magnitude in KID). The training-free methods also require inference-time loops with hundreds of optimization steps or iterative Sinkhorn, a cost not captured by the training-free label.
- Cross-domain injection without generation: Stones.
Stones (Wang et al. 2026d) steps outside the generate-from-a-prior framing altogether. Its Cross-domain Anomaly Injection transplants real anomalies harvested from other industrial domains into normal target images training-free, on the premise that cross-domain defects are abundant even where domain-specific ones are not. Using real material sidesteps the generator-realism question, but relocates it. Whether cross-domain defect statistics match the target product’s actual failure modes is precisely the physical-plausibility gap examined in Section 7.3.
- Zero-shot VLM grounding: AnomalyPainter, Anomagic, and AnoStyler.
AnomalyPainter (Lai et al. 2026) pairs Tex-9K texture retrieval, GPT-4V defect captions, and SDXL + ControlNet-Canny with Texture-Aware Layout Injection, lifting RealNet’s VisA detection and localisation by several points (GPT-4V latency unanalysed). Anomaly Anything (Sun et al. 2025) is the prompt-engineering lower bound (no training, no retrieval). Anomagic (Jiang et al. 2026d) pre-trains a Crossmodal Prompt Encoder on AnomVerse (12,987 triplets across 13 datasets) driving frozen SD v1.5 + LoRA, edging past AnoGen downstream. AnoStyler (So and Kang 2026) counters the scale assumption from below through a sub-million-parameter CLIP-guided U-Net style transfer with SAM. It is single-pass and stays competitive downstream through text guidance without billion-parameter diffusion.
- Architecture alternatives: ARAS/QARAD and SynSur.
ARAS/QARAD (Qian et al. 2026), the autoregressive synthesis editor (ARAS) and quality-aware detector (QARAD) of a single work, replaces diffusion with the Infinity-8B autoregressive token model under local token masking. Conditioned by Qwen2.5-VL-32B, it generates roughly five times faster than its diffusion baseline at ceiling-level detection. The same work adds quality-aware language conditioning with local generation control; low-CLIPScore samples are down-weighted rather than discarded. However, it reports no FID/KID and evaluates only where AUROC is already saturated, so the architectural claim rests on speed, not demonstrated quality.
SynSur (Kühn et al. 2026) fine-tunes the 12B Flux.1-dev DiT with LoRA, using Qwen2-VL captions, DreamSim/CLIPScore filtering, and SAM-3 masks. Its main contribution for this review is the evaluation domain and the negative result discussed next.
7.3. Evaluating Synthesis: What Current Protocols Miss
The main unresolved issue is evaluation. Current generation metrics do not reliably predict detector utility, and gains on curated benchmarks do not establish transfer to production domains. In addition, mask accuracy and the physical plausibility of generated defects are usually assumed from the generation procedure rather than independently verified.
- Realism does not predict utility.
ASBench (Zhang et al. 2026b) evaluates synthesis rather than detection methods, and its central finding is methodological. Across a large factorial grid of generators and detectors, generation-quality metrics (FID/SSIM/LPIPS) do not significantly correlate with downstream detection lift. It proposes a tripartite protocol comprising generation realism on a held-out real anomaly set, mask-IoU against ground-truth annotations, and downstream detection delta on a fixed, named detector as the minimum credible evaluation; we adopt this framing in Section 9.2. ASBench originates within the broader M-3LAB ecosystem ([sec:coi]Disclosures); independent re-evaluation by outside groups would strengthen the protocol’s standing.
- Curated gains shrink in production domains.
Positive downstream gains recur across independent synthesis implementations and detector architectures, but almost all are measured on MVTec-AD or VisA. SynSur (Kühn et al. 2026) is the one exception. On production-adjacent surface-defect data with realistic lighting and defect-size variation, augmentation still helps, but the lift shrinks by an order of magnitude relative to curated-benchmark gains, and a synthetic-only training regime fails outright. A controlled cross-benchmark ablation is needed to distinguish whether MVTec-AD/VisA are in-distribution for pretrained diffusion priors or whether synthesis gains are broadly useful but benchmark-dependent. SynSur provides a concrete, modest upper bound in one realistic domain (Section 9.2, Section 9.6).
- Assumed, not verified: mask fidelity and physical plausibility.
The emitted mask is usually the generation condition, such as an inpainting region, an attention map, or a SAM proposal. It is not an independent measurement of where the generated defect appears. Diffusion edits can spill outside or under-fill the conditioned region, making the resulting mask supervision optimistic. This label noise affects the pixels used to train a localisation head but is not visible to image-level AUROC. For purely synthetic pairs, mask fidelity would need to be checked by an external segmenter or human audit; no paper in this section reports either.
Physical plausibility requires a separate check. Language-grounded pipelines inherit generic web-scale terms such as “scratch”, “crack”, and “contamination”, and may generate defects that are visually plausible but incompatible with the target product or manufacturing process. Realism metrics and downstream lift on the same synthetic distribution do not reveal this mismatch. Addressing it requires an independent mask-verification loop and process knowledge, including failure-mode catalogs, materials, and process parameters, rather than captions alone. No benchmark currently scores physical plausibility separately from visual realism.
Note on InvAD. The manifest places InvAD (Sakai et al. 2026) in the synthesis bucket, but PF-ODE inversion is an anomaly scoring mechanism, not generation; it is therefore outside this chapter’s scope.
7.4. What Current Synthesis Evidence Supports
Since AnomalyDiffusion, synthesis methods have added language grounding, training-free regimes, faster sampling, joint image-and-mask outputs, and architectures beyond the LDM UNet. SeaS reports the strongest generation-quality results in the cohort, and FAST compresses thousand-step sampling to ten with comparable downstream lift.
The evaluation evidence remains limited. FID/SSIM/IS/LPIPS do not predict downstream detection in ASBench, and papers published after it have not adopted the tripartite protocol. Evaluation remains concentrated on MVTec-AD/VisA, while the single production-adjacent test shows the lift shrinking by an order of magnitude. Current metrics also leave mask fidelity and physical plausibility largely unexamined.
A stronger synthesis result would report the tripartite evaluation (FID/KID + mask-IoU + downstream-detection-delta on a fixed-named detector) on a non-MVTec/VisA benchmark with bound-FPR operating points. It should also audit emitted masks against an independent segmenter and compare generated defect types with the target product’s actual failure modes.
8. Evaluation Frontier: What Counts as a Real Advance?
Each Section 3, Section 4, Section 5, Section 6 and Section 7 chapter notes that its mechanism delivers real method-level advances but routinely overstates them in headline numbers. This section asks what evaluation can show that a 2024–2026 IAD method genuinely advances the state of the art.
8.1. Established Benchmarks Are Saturated or Constrained
MVTec-AD (Bergmann et al. 2019), VisA (Zou et al. 2022), and MVTec-3D-AD (Bergmann et al. 2022) are established benchmarks rather than contributions of this review, and their headline I-AUROC differences now lie inside the test-set noise floor. PatchCore (Roth et al. 2022) reported 99.1% on MVTec-AD in 2022; the best apples-to-apples recent results (Dinomaly (Guo et al. 2025c) 99.6%, AnomalyMoE (Gu et al. 2026) 99.5%, CCL (Fan et al. 2025b) 99.1%) are within 0.5 pp of that figure on a benchmark with ∼115 test images per category. IM-IAD (Xie et al. 2024b) made the same argument in 2024. We therefore treat a +0.3% I-AUROC improvement over a 2022 MVTec-AD baseline as insufficient evidence of a practical advance. PRO (Bergmann et al. 2020) and bound-FPR metrics are not saturated. The best 2026 PRO results are 94–96%, and these metrics better reflect deployment behavior.
8.2. The New Benchmark Catalog
The 2024–2026 benchmark corpus produces, by our count, more than twenty new IAD benchmarks, the largest three-year output in the field’s history. Table 5 groups them by the deployment failure mode each was built to expose. Methods claiming to address a failure mode should report on benchmarks from the corresponding row.
The proliferation of new benchmarks provides one quantitative indication that evaluation requirements are changing. Instead of consolidating around two or three datasets, recent work has introduced protocols for distinct failure modes. Phys-AD separates unsupervised, weakly supervised, and video-understanding settings and adds PAEval for physical explanations. Results under these settings should remain separate from static image- and pixel-level AUROC.
Representative numerical anchors. The following results recur throughout the article. Each is reported by the cited source paper and was not recomputed by us.
- MVTec-AD saturation (Section 8.1). PatchCore’s 99.1% I-AUROC (2022) is within 0.5 pp of the best 2026 numbers, inside the test-set noise floor (Fan et al. 2025b,Gu et al. 2026,Guo et al. 2025c,Roth et al. 2022).
- Open-world ceiling. Kaputt best unsupervised AUROC is 56.96% under the prescribed ≤3-reference protocol over 48,376 unique items; no method clears 60% (Höfer et al. 2025).
- Cross-domain transfer wall. UniSpector InsA drops from 69.1% to 14.1% AP50 between Real-IAD and 3CAD, a five-fold drop in the same model across imaging conditions (Kim et al. 2026a).
- Class-count scaling wall. CCL drops from 90.6% I-AUROC in the all-in-all setting (MVTec+VisA+BTAD) to 65.2% on the COCO-derived COCOAD (), a sharp bend rather than gradual decay (Fan et al. 2025b).
- MLLM detection-vs-reasoning trade-off. JUDO’s binary Anomaly-Discrimination sits at 65.04% versus 71.39% for its base Qwen2.5-VL-7B, with the gap arising mainly from the chain-of-thought answer format rather than the training objective. No MLLM in our corpus reports low-false-positive-rate operating points, so none is shown to reach the deployment-FPR behaviour of a language-free detector such as SALAD (96.1% MVTec LOCO I-AUROC). This is an absence-of-evidence gap, not a demonstrated ranking (Fučka et al. 2025,Kang et al. 2026a).
8.3. Evaluation Tiers by Claim Type
We group evaluation protocols by the claim each is intended to test. Strong performance in one tier does not establish performance on the settings covered by the others.
Tier 1 covers deployment-realistic open-world evaluation. It is required for any open-world claim. Candidates are Kaputt (Höfer et al. 2025), Real-IAD-Variety (Zhu et al. 2026), Real-IAD D3 (Zhu et al. 2025b), 3CAD (Yang et al. 2025b), MANTA (Fan et al. 2025a), and M2AD (Cao et al. 2026); each releases a different MVTec-AD-era assumption (identity, viewpoint, tiny-object, illumination, real-3C distribution). A method beating one does not automatically beat the others; reporting a single Tier-1 number is uninformative. Methods must report AUROC and a bound-FPR metric. As a quantitative anchor, no method clears 60% on Kaputt under the ≤3-reference protocol (Section 8.2), making progress measurable. Section 9.5 problem 1 is defined against this tier.
Tier 2 covers general-purpose multi-class and multi-domain evaluation. It is required for any generality claim. Its anchors are Real-IAD D3 (Zhu et al. 2025b), Omni-AD (Shi et al. 2026), MVTec-AD 2 (Heckler-Kram et al. 2026), and Real-IAD (Wang et al. 2024). The Tier-2 floor sits in the 80–90% AUROC band on Real-IAD D3 (PRO several pp lower), where multi-class progress is still measurable. MVTec-AD remains reportable but marked saturated. PRO and bound-FPR metrics are required; methods training jointly on all evaluation domains (e.g., AnomalyMoE (Gu et al. 2026)) must disclose the joint training, not imply zero-data deployment. Section 9.5 problem 5 targets this tier.
Tier 3 covers domain-specific specialized inspection. It is required for any specialized capability claim. Heterogeneous candidates expose distinct deployment regimes, including CPS2D-AD (Yu et al. 2025a) (IC-substrate); BraTS / BrainMRI (medical cross-domain); 3D-ADAM (McHard et al. 2026) / IEC3D-AD (Guo et al. 2025a) / SiM3D (Costanzino et al. 2025) (high-res 3D, SiM3D’s synth-to-real breaking every adapted baseline); LTOAD (Yang et al. 2025a) (long-tail online); Phys-AD (Li et al. 2025b) (physical dynamics); ASBench (Zhang et al. 2026b) (synthesis-vs-detection lift); and CableInspect-AD / InsPLAD / WFDD / HSS-IAD (niche industries). Open-vocabulary defect understanding includes IMDD-1M (Ni et al. 2026), UniSpector (Kim et al. 2026a), and MAU-Set (Wang et al. 2026e), an evaluation frontier cutting across Section 3, Section 4, Section 5 and Section 6. UniSpector’s 69.1%→14.1% cross-domain mAP drop provides one quantitative anchor. Headline metrics should match the target industry (e.g., micrometer-scale recall for IC, regulator-bound FPR for medical, video/frame localization plus PAEval for Phys-AD) rather than defaulting to generic AUROC. Several of the largest absolute gains appear in Tier 3 (Section 9.1).
A method paper should therefore report results across the relevant Tier-1/2/3 benchmarks in Table 5, with metrics matched to its intended deployment claim.
Protocols and Threshold Rationale
The thresholds above are directional, not statistical; we make their derivation explicit so downstream papers can adjust them as evidence accrues.
Metric formulas. (a) Bound-FPR AP, a metric we recommend here rather than a standard one, is average precision restricted to the portion of the precision–recall curve at operating thresholds whose false-positive rate is ≤1% of the normal set; we report it normalized to that FPR sub-range. IM-IAD (Xie et al. 2024b) argues for reporting AUROC, AP/AUPR, PRO, sPRO and FM at deployment-realistic operating points, but does not itself define this FPR≤1% restriction; the choice is ours. (b) F1 at fixed precision is F1 at the operating threshold whose precision reaches ≥0.95 on a held-out split (if attainable), mimicking an in-line system’s false-stop tolerance. (c) For PRO (per-region overlap, Bergmann et al. 2020), the fraction of each ground-truth defect connected component that the prediction covers is measured at each false-positive-rate threshold and averaged over components (equal weight per region, not per pixel). PRO is the area under this per-region-overlap-versus-FPR curve integrated over FPR and normalized to that range. Reporting AUROC alone is deployment-incompatible because it averages over operating points the line cannot tolerate.
Reference-budget rationale (Tier 1). Kaputt caps reference images at ≤3 per identity. With 48,376 unique items, a larger budget is economically infeasible (a fulfillment-center conveyor cannot acquire 100 references per SKU). This is the published Kaputt value, not one we set.
Threshold rationale. All three numbers are recommended challenge thresholds meant to make progress observable, not acceptance criteria or statistical claims. The 60% Tier-1 value sits just above Kaputt’s current best (56.96% AUROC), so clearing it marks a publication-worthy advance on the strongest open-world benchmark. The Section 9.5 deployment target is better stated as an operating point than as an average, requiring high recall (TPR) at a fixed low false-positive rate together with a precision floor at that recall. A cautionary arithmetic motivates the shift away from averaged scores. At a 1% defect prevalence, even a perfect detector run at 1% FPR reaches only ∼50% precision, so a 95%-precision line requires an FPR well below 0.1%, a constraint AUROC and AP average away entirely. We therefore state the deployment target as recall-at-fixed-FPR and precision-at-fixed-recall (or a full operating-point cost), not as a single AP or AUROC number. The 80–90% Tier-2 band on Real-IAD D3 reflects the current state of the art (MaskAD, AnomalyMoE) and the range where multi-class progress stays measurable below MVTec saturation. All will need updating as the field reports a richer bound-FPR evidence base.
Benchmarks spanning tiers. A benchmark’s tier follows the protocol used, not its identity. Real-IAD D3 is Tier-1 under the ≤3-reference protocol but Tier-2 under the full-shot 30-domain protocol, and SiM3D is Tier-1 only under its synth-to-real protocol, else Tier-3. Beating Real-IAD D3 full-shot does not address the open-world failure mode Tier-1 diagnoses.
8.4. Evaluation Is the Bottleneck
Methods in Section 3, Section 4, Section 5, Section 6 and Section 7 are improving on their reported benchmarks, but those benchmarks do not cover several deployment-relevant failure modes. The evaluation tiers in Section 8.3, anchored in Table 5, connect benchmark choice to the claim being made. Section 9 catalogs the cross-cutting failures that remain unresolved.
9. Cross-Cutting Bottlenecks and Research Agenda
Each Section 3, Section 4, Section 5, Section 6 and Section 7 chapter closes with an honest-assessment subsection, and this section aggregates them. Eight bottlenecks recur across mechanisms; no included paper provides convincing evidence on more than one at deployment-relevant operating points, and they are structurally coupled in ways single-mechanism advances cannot address. Real method-level progress (Section 3, Section 4, Section 5, Section 6 and Section 7) coexists with evaluation infrastructure that has not kept up (Section 8, Figure 9). We close the section by turning the matrix into a concrete research agenda.
9.1. Generalization and Transfer Failures
The cross-domain generalization gap. Results across the mechanism chapters show a recurring difference between transfer within curated suites and transfer under domain shift. Visual-prior methods (VisualAD (Hou et al. 2026), AdaptCLIP (Gao et al. 2026), FAPrompt (Zhu et al. 2025a)) degrade from industrial to medical benchmarks, and AnomalyVFM (Fučka et al. 2026)’s 94.1% zero-shot result drops to 88.0% on Real-IAD, which remains an industrial dataset. GRPO-trained MLLM-AD methods (IAD-R1 (Li et al. 2026d), JUDO (Kang et al. 2026a), AD-FM (Liao et al. 2026)) train and evaluate only on MMAD or its derivatives, without a held-out industrial domain.
The same limitation appears in other settings. IB-IUMAD and SiM3D (Costanzino et al. 2025) diagnose cross-modal and synth2real gaps in 3D. UniSpector (Kim et al. 2026a) drops from 69.1% in-domain mAP to 14.1% cross-domain, while AnomalyMoE (Gu et al. 2026) requires joint training on all eight evaluation datasets. In synthesis, SynSur (Kühn et al. 2026), the only paper on non-MVTec/VisA data, sees a +1.4 pp MVTec-AD gain shrink to +0.015 AP on BSData. Taken together, these results support cautious framing of the transition beyond curated benchmarks.
Pose and identity variation. Kaputt (Höfer et al. 2025) pairs 48,376 unique product items with arbitrary poses and ≤3 reference images each; PatchCore drops from 99.1% on MVTec-AD to 54.69% on Kaputt, and no method clears 60%. The bottleneck couples pose variation (breaking per-pose normality in memory banks) with identity variation (violating the assumption that learned normality covers the test-time category). Few-reference learning at this scale needs either pose-invariant features beyond CLIP/DINO/VFM or a non-image supervision modality (e.g., product-catalog descriptions), the structural promise of Section 4 MLLM-AD.
Temporal non-stationarity. Real production lines have non-stationary inputs, including new SKUs without labels, distribution drift, and supplier substitution, that the static benchmark monoculture does not test. LTOAD (Yang et al. 2025a) attacks this directly with +4.63% offline I-AUROC but leaves online deployment largely open; ReplayCAD (Hu et al. 2025) addresses continual class growth without scaling to fulfilment-style daily SKU churn. No single corpus solution suffices; Section 7 synthesis has plausible leverage because realistic defects for newly-introduced categories from a single normal image could keep an online detector calibrated as the catalogue grows.
Medical–industrial transfer. PDD (Lu et al. 2026c) achieves +11.8% AUROC on HeadCT, +5.1% on BrainMRI, and +8.5% on ZhangLab; FDP (Li et al. 2026a) achieves +17.63% DICE on BraTS20. These are among the largest single-paper gains in the IAD literature reviewed here, yet they occur on medical benchmarks where MVTec-AD-saturated methods do not compete and use none of the foundation-model mechanisms reviewed here. Foundation-model methods therefore account for only part of the recent progress across anomaly-detection domains.
9.2. Reasoning-, Synthesis-, and 3D-Specific Failures
The detection-vs-reasoning trade-off in MLLM-AD. In JUDO’s (Kang et al. 2026a) ablation, binary anomaly-discrimination on base Qwen2.5-VL falls most when the model is switched from direct answers to chain-of-thought (71.39%→61.90%), and is roughly flat (∼65%) across the subsequent training stages. Thus, the loss tracks the CoT answer format, not the RL objective in isolation. IAD-R1 (Li et al. 2026d), conversely, reports overall gains across seven base VLMs. We therefore do not claim reasoning training causes detection regression. The narrower, safer reading is that no reasoning-oriented post-training pipeline has yet been shown to preserve a base model’s binary-detection accuracy while adding structured reasoning, and which stage costs the accuracy differs by method. Section 9.5 Problem 2 targets closing this gap.
The MLLM grounding gap. A second Section 4 failure mode is that MLLMs produce plausible language outputs that are not visually grounded. AD-Copilot’s (Jiang et al. 2026b) Comparison Encoder ablation lifts MMAD bounding-box IoU , yet its MMAD-overall accuracy (∼82.3%) is only modestly above strong general-purpose visual MLLMs (GPT-4o, Qwen2.5-VL-72B; ∼75%), so the absolute gain from anomaly-specific training stays small. Triad (Li et al. 2025d) and SAGE (Zang et al. 2025) attack it with ROI tokens and entropy-aware fact-enhancement, but gains stay incremental.
The generation–detection evaluation gap. Across ASBench’s (Zhang et al. 2026b) 19,680 configurations spanning twelve synthesis methods, FID/SSIM/IS/LPIPS do not predict downstream detection improvement, and the lowest-FID method does not yield the largest I-AUROC lift. Combined with (a) downstream lift not generalising beyond MVTec-AD/VisA (SynSur on BSData, +0.015 AP) and (b) synthesis methods rarely reporting on harder benchmarks, synthesis usefulness for deployment has not been measured by anyone in our corpus. Section 9.5 Problem 4 targets it.
The CAD-to-production gap (3D). SiM3D (Costanzino et al. 2025) introduced the first benchmark requiring training on CAD models and testing on real scans. Existing 3D AD methods (Costanzino et al. 2024,Horwitz and Hoshen 2023,Wang et al. 2023) drop to near-baseline under synth2real shift, and the closing strategies known for RGB synth2real (domain randomisation, gradient reversal) do not transfer cleanly to 3D point clouds. PASDF (Zheng et al. 2025)’s continuous SDF representation is the closest 2026 candidate but is not evaluated on the SiM3D synth2real protocol; the Active Real-to-Twin formulation (Liu et al. 2026) attacks the gap from the deployment side, scoring real observations against geometrically matched CAD digital twins with actively selected viewpoints, but remains an early zero-shot prototype. This is the most under-served research gap in the 3D AD literature.
9.3. Failure-Mode Summary Matrix

Table 6.
Cross-cutting bottleneck × mechanism matrix. × = applies directly; (×) = derivative/indirect form; — = does not apply. M1–M5 are the five mechanisms (Section 3, Section 4, Section 5, Section 6 and Section 7). Three bottlenecks (cross-domain generalization, temporal non-stationarity, medical-industrial transfer) affect every column directly; five more affect multiple mechanisms.
Table 6.
Cross-cutting bottleneck × mechanism matrix. × = applies directly; (×) = derivative/indirect form; — = does not apply. M1–M5 are the five mechanisms (Section 3, Section 4, Section 5, Section 6 and Section 7). Three bottlenecks (cross-domain generalization, temporal non-stationarity, medical-industrial transfer) affect every column directly; five more affect multiple mechanisms.
| Bottleneck | M1 Visual |
M2 Reasoning |
M3 Geometric |
M4 Universal |
M5 Synthesis |
|---|---|---|---|---|---|
| Cross-domain generalization | × | × | × | × | × |
| Pose-and-identity | × | × | — | × | — |
| Temporal non-stationarity | × | × | × | × | × |
| Detection-vs-reasoning | — | × | — | (×) | (×) |
| MLLM grounding | — | × | — | — | — |
| Generation–detection evaluation | — | — | — | — | × |
| CAD-to-production | — | — | × | — | × |
| Medical-industrial transfer | × | × | × | × | × |
The matrix records which bottlenecks apply to each mechanism (columns M1–M5); it is not a per-paper resolution count, and a method may span several mechanisms. In our coding of the corpus, no included paper provides convincing evidence on more than one of these bottlenecks at deployment-relevant operating points. This corpus-level finding may change as unified region-grounded models emerging in 2026 are evaluated more broadly.
Cross-domain transfer and temporal non-stationarity apply to every mechanism in the matrix, which limits broad claims about open-world IAD. The parenthesised entries show how one bottleneck can extend across families. The detection-vs-reasoning tension (Section 9.2) is most directly observed in reasoning-tuned MLLMs (M2), while generalist VQA+detection heads (M4) and detectors trained on synthetic “explainable” artifacts (M5) face a related tension between fluent explanations and calibrated binary decisions. Section 9.5 translates these gaps into measurable research targets.
9.4. Emerging Frontier: Industrial Video Anomaly Detection
Temporal non-stationarity concerns drift across deployment time. Industrial video IAD instead tests whether a state transition within one process violates physical or procedural constraints. Phys-AD (Li et al. 2025b) provides a benchmark of 6,434 videos across 22 object categories and 47 anomaly types. It includes robot and motor interactions such as pressing, rotation, and grasping. The benchmark separates unsupervised, weakly supervised, and video-understanding settings; PAEval scores explanations of the physical failure.
O-VAD (Yuan et al. 2026) addresses this setting with a training-free pipeline. It discovers objects, constructs spatiotemporal tracks, records open-ended state changes, and reasons over those trajectories before visually checking candidate anomalies. The method reports video- and frame-level results on Phys-AD, LiquidAD, and IPAD, but depends on large VLM and segmentation/tracking components. The current industrial-video evidence base remains small and does not support a sixth prior mechanism or a general conclusion about video AD.
9.5. Research Targets
The bottlenecks above motivate the measurable targets below. Each is linked to a failure mode in Section 9 and to the mechanisms most relevant to it.
- Open-world Tier-1 performance (Section 9.1). The target is >80% AUROC and AP@bound-FPR on ≥2 Tier-1 benchmarks at ≤3 references per identity. Relevant directions include Section 3 pure-VFM detectors, Section 4 product-catalog reasoning, and Section 6 abnormal-reference meta-learning.
- Detection AUC preserved while adding MLLM reasoning (Section 9.2). The target is an MLLM matching PatchCore binary detection on VisA while exceeding 80% MMAD. A relevant direction is head decoupling (frozen detector backbone + reasoning head); AD-Copilot’s Comparison Encoder is the closest precedent.
- Zero-shot 3D AD with native language grounding (Section 9.2). The target is >85% O-AUROC and >90% point-AUROC without 2D projection. Relevant directions include the point-language models in Section 5 and Section 3, fine-tuned on IMDD-1M.
- A predictive synthesis-quality metric (Section 9.2). The target is a metric over (synthetic, real, detector) with rank correlation to downstream lift across ≥3 detectors. A relevant direction is to measure boundary realism in the detector’s own representation, requiring no new generator but a careful study of ASBench’s matrix.
- A generalist above 90% AUROC on a held-out industrial domain (Section 9.1). The target excludes target-domain fine-tuning. Relevant directions combine Section 3, Section 6, and Section 7, plausibly as an industrial-defect-grounded foundation model that does not yet exist; solving it retires the “paradigm shift is overclaimed” critique.
9.6. Evaluation and Benchmark Governance
Report against the Section 8.3 tiers (Tier-1 for open-world claims, Tier-2 for generality, and Tier-3 for specialized capability), with MVTec-AD marked saturated. Reviewers should treat methods reporting only on MVTec-AD or VisA as not validated for the open-world setting they claim; benchmark adoption follows reviewer expectation.
For any anomaly-synthesis paper, require the Section 9.2 tripartite report covering generation quality (FID/KID on held-out real anomalies), mask-fidelity (IoU), and downstream-detection delta on a fixed detector. It costs nothing to adopt, aligns with ASBench, and forecloses the “pretty pictures, no downstream lift” failure mode within one review cycle.
MLLM-AD benchmarks also need blinded leaderboards, community-curated held-out test sets, and mandatory pre-registration of training data and prompts. MMAD, MMR-AD, M3-AD should be governed by a multi-group consortium rather than through single-group benchmark/method co-development. A practical first step is a held-out MMAD test set curated by groups not publishing on it, made in light of the disclosed MMAD authorship ([sec:coi]Disclosures), on which Section 4’s long-term credibility depends.
9.7. Directions the Field Will Likely Absorb, and Deployment Economics
Open-vocabulary defect understanding is a near-term direction specific to IAD. IMDD-1M (Ni et al. 2026) supplies a million-scale image–text substrate, UniSpector (Kim et al. 2026a) provides a cross-domain diagnostic, and MAU-Set (Wang et al. 2026e) covers multi-domain VQA. Combining these resources with a Tier-1 open-world benchmark (Section 8.3) would test whether foundation-model methods support open-world defect understanding.
Other directions adapt ideas from the broader AI literature to inspection. Embodied/VLA systems could address Kaputt’s pose-and-identity problem (Section 9.1) through active viewpoint selection. Unified generative–perception backbones would combine the functions reviewed in Section 3, Section 4 and Section 7, while world models could generate physically plausible defect sequences for new SKUs under temporal non-stationarity (Section 9.1). These proposals remain largely unevaluated in IAD.
Reasoning may also be moved offline and distilled into a small in-line detector. A related design uses multi-agent orchestration, with a fast detector, a synthesizer, and a reasoning MLLM cooperating through tool use; AnomalyClaw (Jiang et al. 2026c) is an IAD-adjacent example. In both cases, the <100 ms/image throughput ceiling keeps slow generative or agentic components in offline root-cause roles, with EfficientAD (Batzner et al. 2024) as the current baseline. The physics-grounded industrial-video setting is discussed in Section 9.4. Active inspection, object-state tracking, and physics-aware evaluation remain open.
Deployment choices also depend on costs that current papers rarely report. Per-line inference cost compares EfficientAD’s sub-100 ms with an order of magnitude more for 7B MLLM-AD, over – images/line/day. Data sovereignty means proprietary defect data rules out GPT-4V/Gemini APIs and pushes toward small on-prem distilled models. Certification and audit trails matter because automotive, medical, aerospace and food regimes require traceable, frozen-model deployment, which MLLM sampling non-determinism complicates. Long-tail SKU onboarding cost favors few-shot foundation-model methods (Section 3, Section 6), and evaluation should report onboarding time per new SKU. Any “deployment-realistic” claim without a cost-per-image figure is incomplete, and this gap is most likely to be addressed through industry–academia collaboration rather than method papers alone.
10. Conclusion
Recent IAD research increasingly replaces category-specific normal-only training with pretrained visual, reasoning, geometric/multimodal, universal, or synthesis priors. This organization captures method-level changes without requiring a single paradigm-shift claim. The reported gains are strongest on curated benchmark suites and substantially weaker under deployment-oriented evaluation. No method clears 60% AUROC on Kaputt under its ≤3-reference open-world protocol. MLLM-AD methods have not matched PatchCore at industrial false-positive rates, and current generalists do not transfer cleanly to a held-out industrial domain. Section 9 shows that these limitations recur across mechanisms.
The five mechanisms describe the field’s current responses to the question what replaces category-specific normal-only training? The targets in Section 9.5 specify the evidence still needed. Phys-AD and O-VAD extend this discussion to physical state changes in industrial video, but the evidence comes from a small benchmark and method cohort. A stronger transition claim would require independent progress on deployment benchmarks and reproduction of MMAD results by groups outside the benchmark authorship. Over the next 12–18 months, Tier-1 benchmarks, cross-group MLLM-AD evaluation, and tripartite synthesis evaluation would provide more informative evidence than further optimization on saturated MVTec-AD results.
Author Contributions
Xi Jiang contributed to conceptualization, methodology, investigation, and writing the original draft. Bingzhang Hu contributed to validation, review, and editing. Yunkang Cao contributed to review and editing. Jinbao Wang contributed to review and editing. Feng Zheng contributed to supervision, review, and editing.
Funding
The authors declare that no funding was received for the preparation of this work.
Data Availability Statement
This article is a review; no new datasets were generated. The curated paper list underlying the analysis is publicly available at https://github.com/M-3LAB/awesome-industrial-anomaly-detection.
Conflicts of Interest
The authors declare no competing financial interests or personal relationships that could have influenced this work. Several cited works originate in the authors’ research group and should be read with that provenance in mind: the MMAD benchmark (Jiang et al. 2025), the AD-Copilot assistant (Jiang et al. 2026b), the AnomalyClaw agent (Jiang et al. 2026c), the earlier IAD survey (Liu et al. 2024), the IM-IAD benchmark and deployment-realistic protocol (Xie et al. 2024a,Xie et al. 2024b), and the Real3D-AD dataset (Liu et al. 2023a). The group also maintains the curated IAD list at https://github.com/M-3LAB/awesome-industrial-anomaly-detection used as the corpus index in Section 1.5. Co-author Yunkang Cao authored several works cited here, notably two related surveys (Cao et al. 2024b,Liang et al. 2025), the SAA (Cao et al. 2025), AdaCLIP (Cao et al. 2024c), and CPMF (Cao et al. 2024a) methods, and the M2AD (Cao et al. 2026) and MiniShift (Cheng et al. 2026b) benchmarks. Other resources come from outside the group and are used on methodological merit, including Real-IAD (Wang et al. 2024) (a collaborators’ dataset) and ASBench (Zhang et al. 2026b) (a related group’s). Independent outside re-evaluation would further strengthen the conclusions.
References
- Arodi, A., M. Luck, and J.L. Bedwani. 2024. Cableinspect-ad: An expert-annotated anomaly detection dataset. In Advances in Neural Information Processing Systems datasets and Benchmarks Track. pp. 64703–64716. [Google Scholar]
- Asad, M., W. Azeem, and H. Jiang. 2025. 2m3df: Advancing 3d industrial defect detection with multi-perspective multimodal fusion network. IEEE Trans. Circuits Syst. Video Technol. [Google Scholar] [CrossRef]
- Bachem, O., M. Lucic, and A. Krause. 2017. Practical coreset constructions for machine learning. arXiv. Available online: https://arxiv.org/abs/1703.06476.
- Bai, H., S. Mou, and T. Likhomanenko. Vision datasets: A benchmark for vision-based industrial inspection. Presented at the CVPR 2023 Workshop on Vision-Based Industrial Inspection, 2023; Available online: https://arxiv.org/abs/2306.07890.
- Batzner, K., L. Heckler, and R. König. Efficientad: Accurate visual anomaly detection at millisecond-level latencies. Proceedings of the IEEE/CVF Winter Conference on Applications of Computer Vision (WACV), 2024; pp. 127–137. [Google Scholar] [CrossRef]
- Beizaee, F., G.A. Lodygensky, and C. Desrosiers. Correcting deviations from normality: A reformulated diffusion model for multi-class unsupervised anomaly detection. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2025; pp. 19088–19097. [Google Scholar] [CrossRef]
- Bergmann, P., M. Fauser, and D. Sattlegger. Mvtec ad – a comprehensive real-world dataset for unsupervised anomaly detection. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2019; pp. 9592–9600. [Google Scholar] [CrossRef]
- Bergmann, P., M. Fauser, and D. Sattlegger. Uninformed students: Student-teacher anomaly detection with discriminative latent embeddings. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2020; pp. 4183–4192. [Google Scholar] [CrossRef]
- Bergmann, P., X. Jin, and D. Sattlegger. 2022. The mvtec 3d-ad dataset for unsupervised 3d anomaly detection and localization. Proceedings of the 17th International Joint Conference on Computer Vision, Imaging and Computer Graphics Theory and Applications (VISIGRAPP 2022) - Volume 5: 202–213. [Google Scholar] [CrossRef]
- Bhunia, A., C. Li, and H. Bilen. Odd-one-out: Anomaly detection by comparing with neighbors. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2025; pp. 20395–20404. [Google Scholar]
- Cai, J., J. Chen, and D. Zeng. CMDS-AD: Cross-modal dual-stream decoupling for few-shot anomaly detection. Proceedings of the European Conference on Computer Vision (ECCV), 2026a. [Google Scholar]
- Cai, M., Z. Zhang, and G. Wu. Raid: Retrieval-augmented anomaly detection. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026b; pp. 21367–21378. [Google Scholar]
- Cao, Y., X. Xu, and C. Sun. 2023. Towards generic anomaly detection and understanding: Large-scale visual-linguistic model (gpt-4v) takes the lead. arXiv. Available online: https://arxiv.org/abs/2311.02782.
- Cao, Y., X. Xu, and W. Shen. 2024a. Complementary pseudo multimodal feature for point cloud anomaly detection. Pattern Recognit. 156: 110761. [Google Scholar] [CrossRef]
- Cao, Y., X. Xu, and J. Zhang. 2024b. A survey on visual anomaly detection: Challenge, approach, and prospect. https://doi.org/10.48550/arXiv.2401.16402, cite key retained as `xieanomalysurvey2024’ for backward compatibility; actual first author is Cao, https://arxiv.org/abs/2401.16402. arXiv arXiv:2401.16402. [Google Scholar]
- Cao, Y., J. Zhang, and L. Frittoli. 2024c. Adaclip: Adapting clip with hybrid learnable prompts for zero-shot anomaly detection. In Computer Vision – ECCV 2024, Lecture Notes in Computer Science. Springer Nature Switzerland: vol 15093, pp. 55–72. [Google Scholar] [CrossRef]
- Cao, Y., X. Xu, and Y. Cheng. 2025. Personalizing vision-language models with hybrid prompts for zero-shot anomaly detection. IEEE Trans. Cybern. 55, 4: 1917–1929. [Google Scholar] [CrossRef]
- Cao, Y., Y. Cheng, and Y. Zhang. 2026. Visual anomaly detection under complex view-illumination interplay: A large-scale benchmark. Pattern Recognit. 179: 113666. [Google Scholar] [CrossRef]
- Caron, M., H. Touvron, and I. Misra. Emerging properties in self-supervised vision transformers. Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), 2021; pp. 9630–9640. [Google Scholar] [CrossRef]
- Chao, Y., J. Liu, and J. Tang. 2025. Anomalyr1: A grpo-based end-to-end mllm for industrial anomaly detection. arXiv. Available online: https://arxiv.org/abs/2504.11914.
- Chen, P., C. Huang, and Y. Cao. 2026a. Towards explainable industrial anomaly detection via knowledge-guided latent reasoning. arXiv. Available online: https://arxiv.org/abs/2602.09850.
- Chen, Q., H. Luo, and C. Lv. 2024. A unified anomaly synthesis strategy with gradient ascent for industrial anomaly detection and localization. In Computer Vision – ECCV 2024, Lecture Notes in Computer Science. Springer: vol 15125, pp. 37–54. [Google Scholar] [CrossRef]
- Chen, Q., Z. Qu, and W. Luo. Cops: Conditional prompt synthesis for zero-shot anomaly detection. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) Findings, 2026b. [Google Scholar]
- Chen, X., X. Xu, and B. Zheng. Unsupervised multi-view visual anomaly detection via progressive homography-guided alignment. Proceedings of the AAAI Conference on Artificial Intelligence (AAAI), 2026c; pp. 3065–3073. [Google Scholar] [CrossRef]
- Cheng, J., C. Gao, and J. Zhou. Mc3d-ad: A unified geometry-aware reconstruction model for multi-category 3d anomaly detection. Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence (IJCAI), 2025; pp. 837–845. [Google Scholar] [CrossRef]
- Cheng, Y., Y. Cao, and H. Yao. 2026a. A comprehensive survey for real-world industrial surface defect detection: Challenges, approaches, and prospects. J. Manuf. Syst. 84: 152–172. [Google Scholar] [CrossRef]
- Cheng, Y., Y. Sun, and H. Zhang. Towards high-resolution 3d anomaly detection: A scalable dataset and real-time framework for subtle industrial defects. Proceedings of the AAAI Conference on Artificial Intelligence (AAAI), 2026b; pp. 3327–3334. [Google Scholar] [CrossRef]
- Choi, J., M. Kim, and J.H. Hong. Magic: Few-shot mask-guided anomaly inpainting with prompt perturbation, spatially adaptive guidance, and context awareness. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) Findings, 2026. [Google Scholar]
- Costanzino, A., P.Z. Ramirez, and G. Lisanti. Multimodal industrial anomaly detection by crossmodal feature mapping. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2024; pp. 17234–17243. [Google Scholar] [CrossRef]
- Costanzino, A., P.Z. Ramirez, and L. Lella. Sim3d: Single-instance multiview multimodal and multisetup 3d anomaly detection benchmark. Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), 2025; pp. 20944–20953. [Google Scholar]
- Dai, Z., S. Zeng, and H. Liu. Seas: Few-shot industrial anomaly image generation with separation and sharing fine-tuning. Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), 2025; pp. 23135–23144. [Google Scholar]
- Damm, S., M. Laszkiewicz, and J. Lederer. Anomalydino: Boosting patch-based few-shot anomaly detection with dinov2. Proceedings of the IEEE/CVF Winter Conference on Applications of Computer Vision (WACV), 2025; pp. 1319–1329. [Google Scholar] [CrossRef]
- Deng, H., and X. Li. Anomaly detection via reverse distillation from one-class embedding. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2022; pp. 9737–9746. [Google Scholar]
- Deng, H., H. Luo, and W. Zhai. 2026a. Vmad: Visual-enhanced multimodal large language model for zero-shot anomaly detection. IEEE Trans. Autom. Sci. Eng. 23: 3607–3618. [Google Scholar] [CrossRef]
- Deng, R., Y. Hu, and Y. Zhong. Global logic and local search: Dual-stream multimodal in-context learning for verifiable industrial anomaly detection. Proceedings of the European Conference on Computer Vision (ECCV), 2026b. [Google Scholar]
- Deng, Z., A. Liu, and Y. Wang. Gs-clip: Zero-shot 3d anomaly detection by geometry-aware prompt and synergistic view representation learning. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026c; pp. 35587–35596. [Google Scholar]
- Ding, X., X. Li, and M. Chen. 2025. Focuspatch ad: Few-shot multi-class anomaly detection with unified keywords patch prompts. IEEE Trans. Image Process. 34. [Google Scholar] [CrossRef]
- Fan, L., D. Fan, and Z. Hu. Manta: A large-scale multi-view and visual-text anomaly detection dataset for tiny objects. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2025a; pp. 25518–25527. [Google Scholar]
- Fan, L., J. Huang, and D. Di. Salvaging the overlooked: Leveraging class-aware contrastive learning for multi-class anomaly detection. Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), 2025b; pp. 21419–21428. [Google Scholar] [CrossRef]
- Fučka, M., V. Zavrtanik, and D. Skočaj. Salad – semantics-aware logical anomaly detection. Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), 2025; pp. 21843–21852. [Google Scholar]
- Fučka, M., V. Zavrtanik, and D. Skočaj. Anomalyvfm – transforming vision foundation models into zero-shot anomaly detectors. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026; pp. 35555–35566. [Google Scholar]
- Gao, B.B. 2024a. Learning to detect multi-class anomalies with just one normal image prompt. In Computer Vision – ECCV 2024. Springer: pp. 454–470. [Google Scholar] [CrossRef]
- Gao, B.B. Metauas: Universal anomaly segmentation with one-prompt meta-learning. Advances in Neural Information Processing Systems, 2024b. [Google Scholar]
- Gao, B.B., Y. Zhou, and J. Yan. Adaptclip: Adapting clip for universal visual anomaly detection. Proceedings of the AAAI Conference on Artificial Intelligence (AAAI), 2026; pp. 4095–4103. [Google Scholar] [CrossRef]
- Gu, Z., B. Zhu, and G. Zhu. Anomalygpt: Detecting industrial anomalies using large vision-language models. Proceedings of the AAAI Conference on Artificial Intelligence (AAAI), 2024; pp. 1932–1940. [Google Scholar] [CrossRef]
- Gu, Z., B. Zhu, and G. Zhu. Univad: A training-free unified model for few-shot visual anomaly detection. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2025; pp. 15194–15203. [Google Scholar]
- Gu, Z., B. Zhu, and G. Zhu. Anomalymoe: Towards a language-free generalist model for unified visual anomaly detection. Proceedings of the AAAI Conference on Artificial Intelligence (AAAI), 2026; pp. 4348–4356. [Google Scholar] [CrossRef]
- Guo, B., H. Li, and R. Yu. 2025a. Iec3d-ad: A 3d dataset of industrial equipment components for unsupervised point cloud anomaly detection. arXiv. Available online: https://arxiv.org/abs/2511.03267.
- Guo, J., S. Lu, and L. Fan. 2025b. One dinomaly2 detect them all: A unified framework for full-spectrum unsupervised anomaly detection. arXiv. Available online: https://arxiv.org/abs/2510.17611.
- Guo, J., S. Lu, and W. Zhang. Dinomaly: The less is more philosophy in multi-class unsupervised anomaly detection. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2025c; pp. 20405–20415. [Google Scholar] [CrossRef]
- He, H., Y. Bai, and J. Zhang. Mambaad: Exploring state space models for multi-class unsupervised anomaly detection. Advances in Neural Information Processing Systems, 2024. [Google Scholar]
- He, J., M. Cao, and S. Peng. Rareclip: Rarity-aware online zero-shot industrial anomaly detection. Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), 2025; pp. 24478–24487. [Google Scholar]
- Heckler-Kram, L., J.H. Neudeck, and U. Scheler. 2026. The mvtec ad 2 dataset: Advanced scenarios for unsupervised anomaly detection. Int. J. Comput. Vis. 134, 4: 175. [Google Scholar] [CrossRef]
- Höfer, S., D.F. Henning, and A. Amiranashvili. Kaputt: A large-scale dataset for visual defect detection. Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), 2025; pp. 24224–24233. [Google Scholar]
- Horwitz, E., and Y. Hoshen. Back to the feature: Classical 3d features are (almost) all you need for 3d anomaly detection. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) Workshops, 2023; pp. 2968–2977. [Google Scholar] [CrossRef]
- Hou, Y., P. Li, and Z. Liu. Visualad: Language-free zero-shot anomaly detection via vision transformer. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026. [Google Scholar]
- Hu, J., Y. Huang, and Y. Lu. 2024a. Anomalyxfusion: Multi-modal anomaly synthesis with diffusion. arXiv. Available online: https://arxiv.org/abs/2404.19444.
- Hu, L., Z. Gan, and L. Deng. Replaycad: Generative diffusion replay for continual anomaly detection. Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence (IJCAI), 2025; pp. 2946–2954. [Google Scholar] [CrossRef]
- Hu, M., Y. Huo, and M. Dou. 2026. Fb-clip: Fine-grained zero-shot anomaly detection with foreground-background disentanglement. arXiv. Available online: https://arxiv.org/abs/2603.19608.
- Hu, T., J. Zhang, and R. Yi. Anomalydiffusion: Few-shot anomaly image generation with diffusion model. Proceedings of the AAAI Conference on Artificial Intelligence (AAAI), 2024b; pp. 8526–8534. [Google Scholar] [CrossRef]
- Huang, C., H. Guan, and A. Jiang. 2022. Registration based few-shot anomaly detection. In Computer Vision – ECCV 2022, Lecture Notes in Computer Science. Springer: vol 13684, pp. 303–319. [Google Scholar] [CrossRef]
- Huang, C., Y. Li, and Y. Cao. 2026. M3-ad: Reflection-aware multi-modal, multi-category, and multi-dimensional benchmark and framework for industrial anomaly detection. arXiv. Available online: https://arxiv.org/abs/2603.00055.
- Jeong, J., Y. Zou, and T. Kim. Winclip: Zero-/few-shot anomaly classification and segmentation. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2023; pp. 19606–19616. [Google Scholar] [CrossRef]
- Jezek, S., M. Jonak, and R. Burget. Deep learning-based defect detection of metal parts: Evaluating current methods in complex conditions. 2021 13th International Congress on Ultra Modern Telecommunications and Control Systems and Workshops (ICUMT), 2021; pp. 66–71. [Google Scholar] [CrossRef]
- Jiang, S., Y. Ma, and J. Zhou. 2026a. Unified multimodal industrial anomaly detection via few normal samples. IEEE Trans. Ind. Inform. [Google Scholar] [CrossRef]
- Jiang, X., J. Li, and H. Deng. Mmad: A comprehensive benchmark for multimodal large language models in industrial anomaly detection. The Thirteenth International Conference on Learning Representations (ICLR), 2025. [Google Scholar]
- Jiang, X., Y. Guo, and J. Li. 2026b. Ad-copilot: A vision-language assistant for industrial anomaly detection via visual in-context comparison. arXiv. Available online: https://arxiv.org/abs/2603.13779.
- Jiang, X., Y. Zhao, and Z. Yang. 2026c. Anomalyclaw: A universal visual anomaly detection agent via tool-grounded refutation. arXiv. Available online: https://arxiv.org/abs/2605.10397.
- Jiang, Y., W. Luo, and H. Zhang. Anomagic: Crossmodal prompt-driven zero-shot anomaly generation. Proceedings of the AAAI Conference on Artificial Intelligence (AAAI), 2026d; pp. 5485–5493. [Google Scholar] [CrossRef]
- Jin, Y., J. Peng, and Q. He. Dual-interrelated diffusion model for few-shot anomaly image generation. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2025; pp. 30420–30429. [Google Scholar] [CrossRef]
- Jin, Y., Y. Feng, and J. Zhang. Reasoning-driven anomaly detection and localization with image-level supervision. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026. [Google Scholar]
- Kang, H., W. Lee, and J. Kim. Judo: A juxtaposed domain-oriented multimodal reasoner for industrial anomaly qa. International Conference on Learning Representations (ICLR), 2026a. [Google Scholar]
- Kang, X., Z. Li, and T. Lan. Hierarchical point-patch fusion with adaptive patch codebook for 3d shape anomaly detection. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026b. [Google Scholar]
- Kim, G., M. Kim, and K. Lee. Unispector: Towards universal open-set defect recognition via spectral-contrastive visual prompting. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026a; pp. 6261–6270. [Google Scholar]
- Kim, S., W. Lee, and M. Cho. A semantically disentangled unified model for multi-category 3d anomaly detection. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026b; pp. 33036–33045. [Google Scholar]
- Kirillov, A., E. Mintun, and N. Ravi. Segment anything. Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), 2023; pp. 4015–4026. [Google Scholar]
- Kühn, P.J., M. Pommeranz, and A. Kuijper. 2026. Synsur: An end-to-end generative pipeline for synthetic industrial surface defect generation and detection. arXiv. Available online: https://arxiv.org/abs/2604.26633.
- Lai, Z., Y. Lu, and X. Li. Anomalypainter: Vision-language-diffusion synergy for realistic and diverse unseen industrial anomaly synthesis. Proceedings of the AAAI Conference on Artificial Intelligence (AAAI), 2026; pp. 5800–5808. [Google Scholar] [CrossRef]
- Lee, Y., S. Kim, and D. Moon. Bidirectional multimodal prompt learning with scale-aware training for few-shot multi-class anomaly detection. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026; pp. 35577–35586. [Google Scholar]
- Lei, T., B. Wang, and S. Chen. 2024. Texture-AD: An anomaly detection dataset and benchmark for real algorithm development. arXiv. Available online: https://arxiv.org/abs/2409.06367.
- Lendering, C., E. Akdag, and E. Bondarau. Subspacead: Training-free few-shot anomaly detection via subspace modeling. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026; pp. 28557–28566. [Google Scholar]
- Li, C.L., K. Sohn, and J. Yoon. Cutpaste: Self-supervised learning for anomaly detection and localization. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2021; pp. 9664–9674. [Google Scholar] [CrossRef]
- Li, H., Z. Zhuang, and J. Lin. Fdp: A frequency-decomposition preprocessing pipeline for unsupervised anomaly detection in brain mri. Proceedings of the AAAI Conference on Artificial Intelligence (AAAI), 2026a; pp. 6118–6126. [Google Scholar] [CrossRef]
- Li, K., G. Li, and M. Zhou. Back to point: Exploring point-language models for zero-shot 3d anomaly detection. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026b; pp. 14167–14177. [Google Scholar]
- Li, S., J. Cao, and P. Ye. 2025a. Clipsam: Clip and sam collaboration for zero-shot anomaly segmentation. Neurocomputing 618: 129122. [Google Scholar] [CrossRef]
- Li, W., X. Xu, and Y. Gu. Towards scalable 3d anomaly detection and localization: A benchmark via 3d anomaly synthesis and a self-supervised learning network. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2024a; pp. 22207–22216. [Google Scholar] [CrossRef]
- Li, W., Y. Gu, and X. Chen. Towards visual discrimination and reasoning of real-world physical dynamics: Physics-grounded anomaly detection. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2025b; pp. 30409–30419. [Google Scholar] [CrossRef]
- Li, W., B. Zheng, and X. Xu. Multi-sensor object anomaly detection: Unifying appearance, geometry, and internal properties. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2025c; pp. 9984–9993. [Google Scholar]
- Li, X., Z. Zhang, and X. Tan. Promptad: Learning prompts with only normal samples for few-shot anomaly detection. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2024b; pp. 16838–16848. [Google Scholar] [CrossRef]
- Li, X., F. Xue, and Y. Zhou. 2026c. Musc-v2: Zero-shot multimodal industrial anomaly classification and segmentation with mutual scoring of unlabeled samples. IEEE Trans. Pattern Anal. Mach. Intell. early Access. [Google Scholar] [CrossRef]
- Li, Y., S. Yuan, and H. Wang. Triad: Empowering lmm-based anomaly detection with expert-guided region-of-interest tokenizer and manufacturing process. Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), 2025d; pp. 21917–21926. [Google Scholar]
- Li, Y., Y. Cao, and C. Liu. 2026d. Iad-r1: Reinforcing consistent reasoning in industrial anomaly detection. Proc. AAAI Conf. Artif. Intell. 40, 8: 6583–6591. [Google Scholar] [CrossRef]
- Li, Y., X. Yang, and J. Zhang. Pirn: Prototypical-based intra-modal reconstruction with normality communication for multi-modal anomaly detection. The Fourteenth International Conference on Learning Representations (ICLR), 2026e. [Google Scholar]
- Li, Z., Z. Yu, and Q. Ye. 2025e. Iad-gpt: Advancing visual knowledge in multimodal large language model for industrial anomaly detection. IEEE Trans. Instrum. Meas. 74: 1–12. [Google Scholar] [CrossRef]
- Liang, H., B. Guo, and Y. Huang. 2025. 3d anomaly detection: A survey. ResearchGate preprint. Available online: https://github.com/M-3LAB/awesome-3d-anomaly-detection. [CrossRef]
- Liao, J., Y. Su, and R.C. Tu. Ad-fm: Multimodal llms for anomaly detection via multi-stage reasoning and fine-grained reward optimization. Proceedings of the AAAI Conference on Artificial Intelligence (AAAI), 2026; pp. 15234–15242. [Google Scholar] [CrossRef]
- Lin, Y., Y. Chang, and X. Tong. 2025. A survey on rgb, 3d, and multimodal approaches for unsupervised industrial image anomaly detection. Inf. Fusion 121: 103139. [Google Scholar] [CrossRef]
- Lin, Y., H. Yan, and X. Tong. Commonality in few: Few-shot multimodal anomaly detection via hypergraph-enhanced memory. Proceedings of the AAAI Conference on Artificial Intelligence (AAAI), 2026; pp. 7015–7023. [Google Scholar] [CrossRef]
- Liu, J., G. Xie, and R. Chen. Real3d-ad: A dataset of point cloud anomaly detection. Advances in Neural Information Processing Systems, datasets and Benchmarks Track, 2023a. [Google Scholar]
- Liu, J., G. Xie, and J. Wang. 2024. Deep industrial image anomaly detection: A survey. Mach. Intell. Res. 21, 1: 104–135. [Google Scholar] [CrossRef]
- Liu, J., Y. Cao, and Y. Chen. 2026. Towards active real-to-twin inspection: A new paradigm for zero-shot anomaly detection. arXiv. Available online: https://arxiv.org/abs/2605.25407.
- Liu, Z., Y. Zhou, and Y. Xu. Simplenet: A simple network for image anomaly detection and localization. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2023b; pp. 20402–20411. [Google Scholar]
- Long, K., L. Ma, and J. Liu. Towards an incremental unified multimodal anomaly detection: Augmenting multimodal denoising from an information bottleneck perspective. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026; pp. 14116–14125. [Google Scholar]
- Lu, G., F. Zhou, and C. Jin. Robust zero-shot anomaly detection under limited auxiliary anomaly priors. Proceedings of the European Conference on Computer Vision (ECCV), 2026a. [Google Scholar]
- Lu, R., Y. Wu, and L. Tian. Hierarchical vector quantized transformer for multi-class unsupervised anomaly detection. Advances in Neural Information Processing Systems, 2023. [Google Scholar]
- Lu, R., G. Liu, and K. Li. Maskad: Parallel masked autoencoder for multi-class unsupervised anomaly detection. Proceedings of the AAAI Conference on Artificial Intelligence (AAAI), 2026b; pp. 15457–15465. [Google Scholar] [CrossRef]
- Lu, X., H. Liu, and F. Shang. Pdd: Manifold-prior diverse distillation for medical anomaly detection. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026c; pp. 28534–28544. [Google Scholar]
- Luo, W., Y. Cao, and H. Yao. Exploring intrinsic normal prototypes within a single image for universal anomaly detection. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2025; pp. 9974–9983. [Google Scholar]
- Ma, W., X. Zhang, and Q. Yao. Aa-clip: Enhancing zero-shot anomaly detection via anomaly-aware clip. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2025; pp. 4744–4754. [Google Scholar]
- McHard, P.M., F.P. Audonnet, and O. Summerell. 3d-adam: A dataset for 3d anomaly detection in additive manufacturing. Proceedings of the 2026 IEEE International Conference on Robotics and Automation (ICRA), 2026. [Google Scholar]
- Mishra, P., R. Verk, and D. Fornasier. Vt-adl: A vision transformer network for image anomaly detection and localization. 2021 IEEE 30th International Symposium on Industrial Electronics (ISIE), 2021; pp. 1–6. [Google Scholar] [CrossRef]
- Nazer, N., H. Zhou, and L. Halilaj. Defect-aware hybrid prompt optimization via progressive tuning for zero-shot multi-type anomaly detection and segmentation. Proceedings of the European Conference on Computer Vision (ECCV), 2026. [Google Scholar]
- Ni, T.C., C.C. Chen, and Y.F. Yang. Towards open-vocabulary industrial defect understanding with a large-scale multimodal dataset. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026; pp. 13059–13068. [Google Scholar]
- Oquab, M., T. Darcet, and T. Moutakanni. Dinov2: Learning robust visual features without supervision. Transactions on Machine Learning Research, 2024. [Google Scholar]
- Pang, Y., W. Wang, and F.E.H. Tay. 2022. Masked autoencoders for point cloud self-supervised learning. In Computer Vision – ECCV 2022, Lecture Notes in Computer Science. Springer: vol 13662, pp. 604–621. [Google Scholar] [CrossRef]
- Park, J.Y., J. Seo, and M. Kang. Moeclip: Patch-specialized experts for zero-shot anomaly detection. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026; pp. 35534–35544. [Google Scholar]
- Peng, X., X. Huang, and S.H. Choi. 2026. Eagle: Expert-augmented attention guidance for tuning-free industrial anomaly detection in multimodal large language models. arXiv. Available online: https://arxiv.org/abs/2602.17419.
- Qian, L., B. Zhu, and Y. Chen. Quality-aware language-conditioned local auto-regressive anomaly synthesis and detection. Proceedings of the AAAI Conference on Artificial Intelligence (AAAI), 2026; pp. 15626–15634. [Google Scholar] [CrossRef]
- Qiang, Y., J. Cao, and S. Zhou. 2025. tgard: Text-guided adversarial reconstruction for industrial anomaly detection. IEEE Trans. Ind. Inform. [Google Scholar] [CrossRef]
- Qu, Z., X. Tao, and M. Prasad. 2024. Vcp-clip: A visual context prompting model for zero-shot anomaly segmentation. In Computer Vision – ECCV. vol. 2024, pp. 301–317. [Google Scholar] [CrossRef]
- Qu, Z., X. Tao, and X. Gong. Bayesian prompt flow learning for zero-shot anomaly detection. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2025a; pp. 30398–30408. [Google Scholar] [CrossRef]
- Qu, Z., X. Tao, and X. Gong. Dictas: A framework for class-generalizable few-shot anomaly segmentation via dictionary lookup. Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), 2025b; pp. 20519–20528. [Google Scholar]
- Qu, Z., X. Tao, and X. Bao. Ag-vas: Anchor-guided zero-shot visual anomaly segmentation with large multimodal models. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026; pp. 14126–14136. [Google Scholar]
- Radford, A., J.W. Kim, and C. Hallacy. 2021. Learning transferable visual models from natural language supervision. Proceedings of the 38th International Conference on Machine Learning, Proceedings of Machine Learning Research vol 139. PMLR: 8748–8763. [Google Scholar]
- Rao, H., Z. Wang, and C. Si. One-to-more: High-fidelity training-free anomaly generation with attention control. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026. [Google Scholar]
- Rolih, B., M. Fučka, and D. Skočaj. 2025. Supersimplenet: Unifying unsupervised and supervised learning for fast and reliable surface defect detection. In Pattern Recognition: 27th International Conference, ICPR 2024, Proceedings, Part X, Lecture Notes in Computer Science. Springer: vol 15310, pp. 47–65. [Google Scholar] [CrossRef]
- Roth, K., L. Pemula, and J. Zepeda. Towards total recall in industrial anomaly detection. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2022; pp. 14318–14328. [Google Scholar] [CrossRef]
- Sadikaj, Y., H. Zhou, and L. Halilaj. Multiads: Defect-aware supervision for multi-type anomaly detection and segmentation in zero-shot learning. Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), 2025; pp. 22978–22988. [Google Scholar]
- Sakai, S., X. He, and C. Gu. Invad: Inversion-based reconstruction-free anomaly detection with diffusion models. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026. [Google Scholar]
- Shao, Y., L. Wang, and C. Li. Promptmoe: Generalizable zero-shot anomaly detection via visually-guided prompt mixtures. Proceedings of the AAAI Conference on Artificial Intelligence (AAAI), 2026; pp. 8878–8886. [Google Scholar] [CrossRef]
- Shi, D., C. He, and S. Zhang. Omni-ad: A large-scale and versatile benchmark for industrial anomaly detection. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026; pp. 14157–14166. [Google Scholar]
- Vieira e Silva, A.L.B., HdC Felix, and Simões FPMa. 2023. Insplad: A dataset and benchmark for power line asset inspection in uav images. Int. J. Remote Sens. 44, 23: 7294–7320. [Google Scholar] [CrossRef]
- So, Y., and S. Kang. Anostyler: Text-driven localized anomaly generation via lightweight style transfer. Proceedings of the AAAI Conference on Artificial Intelligence (AAAI), 2026; pp. 15734–15742. [Google Scholar] [CrossRef]
- Song, J., D. Park, and K. Baek. Defectfill: Realistic defect generation with inpainting diffusion model for visual inspection. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2025; pp. 18718–18727. [Google Scholar] [CrossRef]
- Sun, H., Y. Cao, and H. Dong. Unseen visual anomaly generation. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2025; pp. 25508–25517. [Google Scholar]
- Tang, J., H. Lu, and X. Xu. 2024. An incremental unified framework for small defect inspection. In Computer Vision – ECCV 2024, Lecture Notes in Computer Science. pp. 307–324. [Google Scholar] [CrossRef]
- Tao, C., X. Cao, and J. Du. G2sf: Geometry-guided score fusion for multimodal industrial anomaly detection. Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), 2025; pp. 20551–20560. [Google Scholar]
- Tian, L., Y. Li, and Y. Dai. 2025. Fastref: Fast prototype refinement for few-shot industrial anomaly detection. arXiv. Available online: https://arxiv.org/abs/2506.21398.
- Wang, C., W. Zhu, and B.B. Gao. Real-iad: A real-world multi-view dataset for benchmarking versatile industrial anomaly detection. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2024; pp. 22883–22892. [Google Scholar]
- Wang, F., T. Zhang, and Y. Wang. Distribution prototype diffusion learning for open-set supervised anomaly detection. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2025a; pp. 20416–20426. [Google Scholar] [CrossRef]
- Wang, F., Y. Wang, and X. Guo. Anomaly-preference image generation. Proceedings of the 43rd International Conference on Machine Learning (ICML), 2026a. [Google Scholar]
- Wang, F., Y. Wang, and X. Guo. Mixture prototype flow matching for open-set supervised anomaly detection. Proceedings of the 43rd International Conference on Machine Learning (ICML), Proceedings of Machine Learning Research, 2026b, vol 306. PMLR. [Google Scholar]
- Wang, Q., S. Gao, and J. Hu. Hss-iad: A heterogeneous same-sort industrial anomaly detection dataset. 2025 IEEE International Conference on Multimedia and Expo (ICME), 2025b; pp. 1–6. [Google Scholar] [CrossRef]
- Wang, R., Y. Qian, and F. Yu. PADFormer: Pose-agnostic anomaly detection from sparse view images. Proceedings of the European Conference on Computer Vision (ECCV), 2026c. [Google Scholar]
- Wang, S., Y. Hu, and X. Liu. 2026d. “stones from other hills can polish jade”: Zero-shot anomaly synthesis via cross-domain anomaly injection. IEEE Trans. Image Process. early Access. [Google Scholar] [CrossRef]
- Wang, X., X. Wang, and H. Bai. Decad: Decoupling anomalies in latent space for multi-class unsupervised anomaly detection. Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), 2025c; pp. 21568–21577. [Google Scholar]
- Wang, Y., J. Peng, and J. Zhang. Multimodal industrial anomaly detection via hybrid fusion. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2023; pp. 8032–8041. [Google Scholar]
- Wang, Y., X. Wang, and Y. Gong. 2025d. Normal-abnormal guided generalist anomaly detection. Adv. Neural Inf. Process. Syst. [Google Scholar] [CrossRef]
- Wang, Y., X. Xu, and J. Liu. 2025e. A survey on industrial anomalies synthesis. arXiv. Available online: https://arxiv.org/abs/2502.16412, https://arxiv.org/abs/2502.16412. [CrossRef]
- Wang, Z., Z. Fan, and S. Tan. Mau-gpt: Enhancing multi-type industrial anomaly understanding via anomaly-aware and generalist experts adaptation. Proceedings of the AAAI Conference on Artificial Intelligence (AAAI), 2026e; pp. 26787–26795. [Google Scholar] [CrossRef]
- Wei, S., J. Jiang, and X. Xu. Uninet: A contrastive learning-guided unified framework with feature selection for anomaly detection. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2025; pp. 9994–10003. [Google Scholar]
- Xie, G., J. Wang, and J. Liu. 2024a. IM-IAD: Industrial image anomaly detection benchmark in manufacturing. IEEE Trans. Cybern. 54, 5: 2720–2733. [Google Scholar] [CrossRef]
- Xie, G., J. Wang, and J. Liu. 2024b. Im-iad: Industrial image anomaly detection benchmark in manufacturing. IEEE Trans. Cybern. 54, 5: 2720–2733. [Google Scholar] [CrossRef]
- Xu, C., C. Lv, and Q. Chen. Mrad: Zero-shot anomaly detection with memory-driven retrieval. The Fourteenth International Conference on Learning Representations (ICLR), 2026a. [Google Scholar]
- Xu, J., S.Y. Lo, and B. Safaei. Towards zero-shot anomaly detection and reasoning with multimodal large language models. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2025a; pp. 20370–20382. [Google Scholar]
- Xu, K., X. Wang, and Y. Hou. CoGeoAD: Hierarchical color-geometric fusion with multi-view attention for zero-shot 3d anomaly detection. Proceedings of the 43rd International Conference on Machine Learning (ICML), Proceedings of Machine Learning Research, 2026b, vol 306. PMLR. [Google Scholar]
- Xu, R., Y.T. Chiu, and T.I. Chen. Training-free industrial defect generation with diffusion models. Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), 2025b; pp. 24214–24223. [Google Scholar]
- Xu, X., Y. Wang, and J. Wang. 2025c. Fast: Foreground-aware diffusion with accelerated sampling trajectory for segmentation-oriented anomaly synthesis. Adv. Neural Inf. Process. Syst. [Google Scholar] [CrossRef]
- Xu, Y., H. Zhang, and Y. Ma. 2026c. Scone: Spherical consistent neighborhoods ensemble for effective and efficient multi-view anomaly detection. Proc. AAAI Conf. Artif. Intell. 40, 19: 16083–16090. [Google Scholar] [CrossRef]
- Yang, C.A., K.C. Peng, and R.A. Yeh. Toward long-tailed online anomaly detection through class-agnostic concepts. Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), 2025a; pp. 23419–23430. [Google Scholar]
- Yang, E., P. Xing, and H. Sun. 2025b. 3cad: A large-scale real-world 3c product dataset for unsupervised anomaly detection. Proc. AAAI Conf. Artif. Intell. 39, 9: 9175–9183. [Google Scholar] [CrossRef]
- Yang, S., Z. Chen, and P. Chen. 2025c. Defect spectrum: A granular look of large-scale defect datasets with rich semantics. In Computer Vision – ECCV 2024, Lecture Notes in Computer Science. Springer: vol 15065, pp. 187–203. [Google Scholar] [CrossRef]
- Yao, X., Z. Chen, and C. Gao. 2024. Resad: A simple framework for class generalizable anomaly detection. In Advances in Neural Information Processing Systems. pp. 125287–125311. [Google Scholar]
- Yao, X., Y. Luo, and Z. Qian. 2025. Adpretrain: Advancing industrial anomaly detection via anomaly representation pretraining. Adv. Neural Inf. Process. Syst. [Google Scholar] [CrossRef]
- Yao, X., Z. Qian, and C. Shi. Mmr-ad: A large-scale multimodal dataset for benchmarking general anomaly detection with multimodal large language models. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026; pp. 43072–43082. [Google Scholar]
- Ye, J., W. Zhao, and X. Yang. Po3ad: Predicting point offsets toward better 3d point cloud anomaly detection. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2025; pp. 1353–1362. [Google Scholar]
- You, Z., L. Cui, and Y. Shen. 2022. A unified model for multi-class anomaly detection. In Advances in Neural Information Processing Systems. pp. 4571–4584. [Google Scholar]
- Yu, R., B. Guo, and H. Li. Anomaly detection of integrated circuits package substrates using the large vision model saic: Dataset construction, methodology, and application. Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), 2025a; pp. 22563–22574. [Google Scholar]
- Yu, Y., Z. Chen, and X. Xu. 2025b. Registration is a powerful rotation-invariance learner for 3d anomaly detection. Adv. Neural Inf. Process. Syst. [Google Scholar] [CrossRef]
- Yuan, M., Q. Long, and Q. Wu. O-VAD: Industrial video anomaly detection through object-centric tracking and reasoning. Proceedings of the European Conference on Computer Vision (ECCV), 2026. [Google Scholar]
- Zang, G., X. Li, and D. Di. Sage: A visual language model for anomaly detection via fact enhancement and entropy-aware alignment. Proceedings of the 33rd ACM International Conference on Multimedia, 2025; pp. 5030–5039. [Google Scholar] [CrossRef]
- Zavrtanik, V., M. Kristan, and D. Skočaj. Draem - a discriminatively trained reconstruction embedding for surface anomaly detection. Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), 2021; pp. 8330–8339. [Google Scholar] [CrossRef]
- Zavrtanik, V., M. Kristan, and D. Skočaj. 2022. Dsr - a dual subspace re-projection network for surface anomaly detection. In Computer Vision – ECCV 2022, Lecture Notes in Computer Science. Springer: vol 13691, pp. 539–554. [Google Scholar] [CrossRef]
- Zha, Y., Y. Xue, and C. Fan. Casl: Curvature-augmented self-supervised learning for 3d anomaly detection. Proceedings of the AAAI Conference on Artificial Intelligence (AAAI), 2026; pp. 12340–12348. [Google Scholar] [CrossRef]
- Zhai, G., Y. Zhou, and X. Deng. Foundation visual encoders are secretly few-shot anomaly detectors. International Conference on Learning Representations (ICLR), 2026. [Google Scholar]
- Zhang, J., R. Ding, and M. Ban. 2024a. Pku-goodsad: A supermarket goods dataset for unsupervised anomaly detection and segmentation. IEEE Robot. Autom. Lett. 9, 3: 2008–2015. [Google Scholar] [CrossRef]
- Zhang, K., Z. Zhang, and X. Sun. Adseeker: A knowledge-grounded reasoning framework for industry anomaly detection and reasoning. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026a; pp. 21379–21388. [Google Scholar]
- Zhang, Q., M. Shao, and X. Chen. Wave-mambaad: Wavelet-driven state space model for multi-class unsupervised anomaly detection. Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), 2025a; pp. 20868–20877. [Google Scholar]
- Zhang, Q., S. Zhang, and J. Liu. Asbench: Image anomalies synthesis benchmark for anomaly detection. IEEE Transactions on Artificial Intelligence Accepted for publication, 2026b. [Google Scholar]
- Zhang, X., M. Xu, and X. Zhou. Realnet: A feature selection network with realistic synthetic anomaly for anomaly detection. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2024b; pp. 16699–16708. [Google Scholar]
- Zhang, X., G. Li, and P. Henderson. Is training necessary for anomaly detection? Proceedings of the 43rd International Conference on Machine Learning (ICML), 2026c. [Google Scholar]
- Zhang, X., M. Xu, and X. Zhou. LogiCo: A unified framework for logical and structural anomaly detection. Proceedings of the European Conference on Computer Vision (ECCV), 2026d. [Google Scholar]
- Zhang, Y., Y. Cao, and X. Xu. 2025b. Logicode: An llm-driven framework for logical anomaly detection. IEEE Trans. Autom. Sci. Eng. 22: 7712–7723. [Google Scholar] [CrossRef]
- Zhang, Z., M. Cai, and H. Wang. 2025c. Costfilter-ad: Enhancing anomaly detection through matching cost filtering. Proceedings of the 42nd International Conference on Machine Learning, Proceedings of Machine Learning Research vol 267. PMLR: 74540–74564. [Google Scholar]
- Zhao, S., Y. Lin, and L. Han. 2025. Omniad: Detect and understand industrial anomaly via multimodal reasoning. arXiv. Available online: https://arxiv.org/abs/2505.22039.
- Zhao, Y., Y. Pang, and L. Zhang. Unimmad: Unified multi-modal and multi-class anomaly detection via moe-driven feature decompression. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026; pp. 28502–28511. [Google Scholar]
- Zheng, B., J. Gan, and X. Xu. Bridging 3d anomaly localization and repair via high-quality continuous geometric representation. Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), 2025. [Google Scholar]
- Zhou, Q., G. Pang, and Y. Tian. Anomalyclip: Object-agnostic prompt learning for zero-shot anomaly detection. International Conference on Learning Representations (ICLR), 2024a. [Google Scholar]
- Zhou, Q., J. Yan, and S. He. 2024b. Pointad: Comprehending 3d anomalies from points and pixels for zero-shot 3d anomaly detection. In Advances in Neural Information Processing Systems. pp. 84866–84896. [Google Scholar]
- Zhu, H., G. Xie, and C. Hou. Towards high-resolution 3d anomaly detection via group-level feature contrastive learning. Proceedings of the 32nd ACM International Conference on Multimedia, 2024; pp. 4680–4689. [Google Scholar]
- Zhu, J., and G. Pang. Toward generalist anomaly detection via in-context residual learning with few-shot sample prompts. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2024; pp. 17826–17836. [Google Scholar]
- Zhu, J., Y.S. Ong, and C. Shen. Fine-grained abnormality prompt learning for zero-shot anomaly detection. Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), 2025a; pp. 22241–22251. [Google Scholar] [CrossRef]
- Zhu, W., L. Wang, and Z. Zhou. Real-iad d3: A real-world 2d/pseudo-3d/3d dataset for industrial anomaly detection. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2025b; pp. 15214–15223. [Google Scholar]
- Zhu, W., C. Wang, and B.B. Gao. 2026. Real-iad variety: Pushing industrial anomaly detection dataset to a modern era. Pattern Recognit. [Google Scholar] [CrossRef]
- Zou, Y., J. Jeong, and L. Pemula. 2022. Spot-the-difference self-supervised pre-training for anomaly detection and segmentation. In Computer Vision – ECCV 2022. pp. 392–408. [Google Scholar] [CrossRef]
| 1 | |
| 2 |
IAD metric vocabulary.I-AUROC (image-level AUROC) measures whole-image normal/abnormal classification. P-AUROC (pixel-level AUROC) applies the same measure per pixel and evaluates localization. PRO (Per-Region Overlap, Bergmann et al. 2020) measures mean predicted/ground-truth region overlap and is more deployment-faithful than P-AUROC on small defects. AP (Average Precision) is the area under the precision–recall curve. Bound-FPR metrics, such as AP at FPR≤1% or recall at fixed precision, measure performance at manufacturing operating points where false positives stop production. |
| 3 |
MLLM-AD training vocabulary.MLLM / VLM denotes a large language model with a vision encoder that jointly processes image and text. VQA is a visual question-answering protocol. SFT (supervised fine-tuning) trains on (input, gold-answer) pairs with cross-entropy. GRPO (group relative policy optimization, from DeepSeek-R1) is an RL-style post-training step that rewards correct, well-structured answers over the model’s own samples and is applied after SFT. RAG (retrieval-augmented generation) retrieves knowledge into context at inference. DPO and RLVR are other post-training objectives. CoT denotes chain-of-thought. |
| 4 |
3D/multimodal vocabulary. A point cloud is a set of unordered 3D points; RGB-D pairs RGB with depth; and MV denotes multi-view RGB. O-AUROC and P-AUROC are object- and point/pixel-level AUROC. Synth2real means training on synthetic data, such as CAD, and testing on real scans. Point-MAE / Point-BERT / PointGPT provide 3D self-supervised pretraining, while ULIP / PointCLIP provide 3D–language alignment. SDF denotes a signed-distance function, FPFH is a hand-crafted 3D feature (fast point-feature histogram), and MoE denotes mixture-of-experts routing. |
| 5 |
Diffusion / synthesis vocabulary. An LDM (latent diffusion model) performs diffusion in a learned latent space, as in Stable Diffusion. DDIM is a deterministic sampler with ∼1000 or fewer steps. SDXL is a larger LDM with two text encoders, while ControlNet conditions LDM output on edges, depth, or masks. A DiT (diffusion transformer) uses a transformer diffusion backbone, such as Flux. LoRA provides low-rank parameter-efficient fine-tuning, and DreamBooth provides subject-specific LDM fine-tuning from a few references. CLIPScore / DreamSim are image–text / image–image similarity metrics. FID / KID / LPIPS / IS are generation-quality metrics (lower is better for FID/KID/LPIPS, while higher is better for IS). |
Figure 1.
Timeline of IAD method families, 2019–2026. The 2023 line marks the foundation-model transition; recent activity concentrates in the CLIP/VFM, MLLM, and synthesis lanes, while the embedding/memory-bank line slows.
Figure 1.
Timeline of IAD method families, 2019–2026. The 2023 line marks the foundation-model transition; recent activity concentrates in the CLIP/VFM, MLLM, and synthesis lanes, while the embedding/memory-bank line slows.
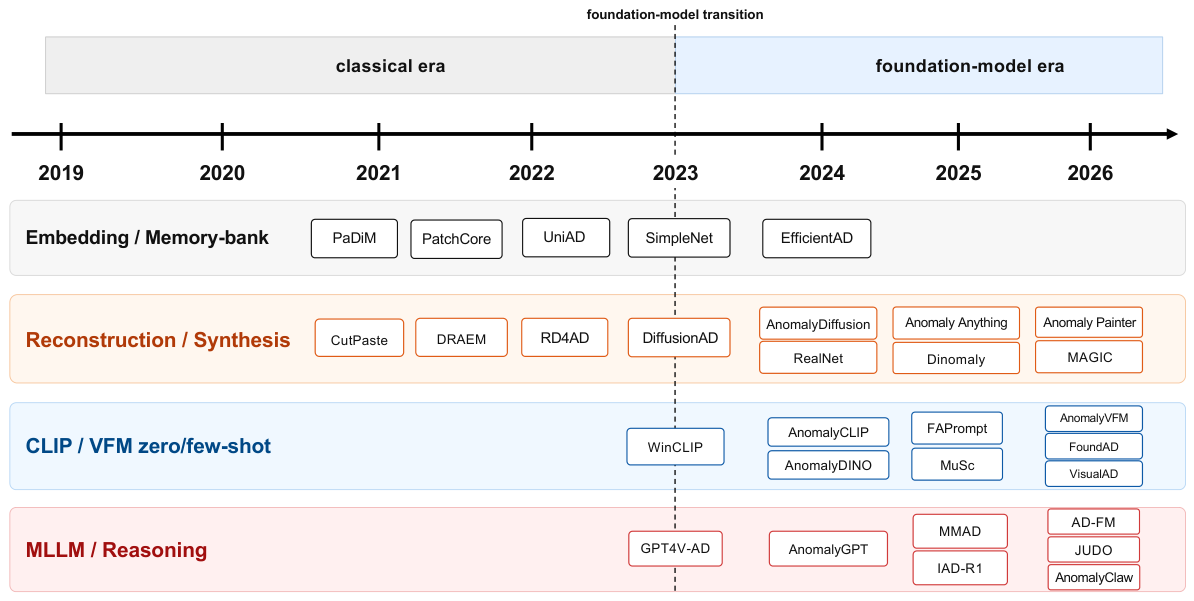
Figure 2.
Representative methods from 2025–2026, grouped by primary generalization mechanism (M1 visual, M2 reasoning, M3 geometric, M4 universal, and M5 synthesis priors) and the evaluation frontier (EV), sorted by year within each group. In each row a solid cell marks the primary mechanism targeted by a paper’s central claimed contribution, and a hatched cell marks a secondary (cross-tag) mechanism that it also uses but does not centre. Bold marks landmark/anchor works. Assignments were made by the authors from each paper’s stated contribution and are judgment calls at the boundaries. Curated, not exhaustive.
Figure 2.
Representative methods from 2025–2026, grouped by primary generalization mechanism (M1 visual, M2 reasoning, M3 geometric, M4 universal, and M5 synthesis priors) and the evaluation frontier (EV), sorted by year within each group. In each row a solid cell marks the primary mechanism targeted by a paper’s central claimed contribution, and a hatched cell marks a secondary (cross-tag) mechanism that it also uses but does not centre. Bold marks landmark/anchor works. Assignments were made by the authors from each paper’s stated contribution and are judgment calls at the boundaries. Curated, not exhaustive.
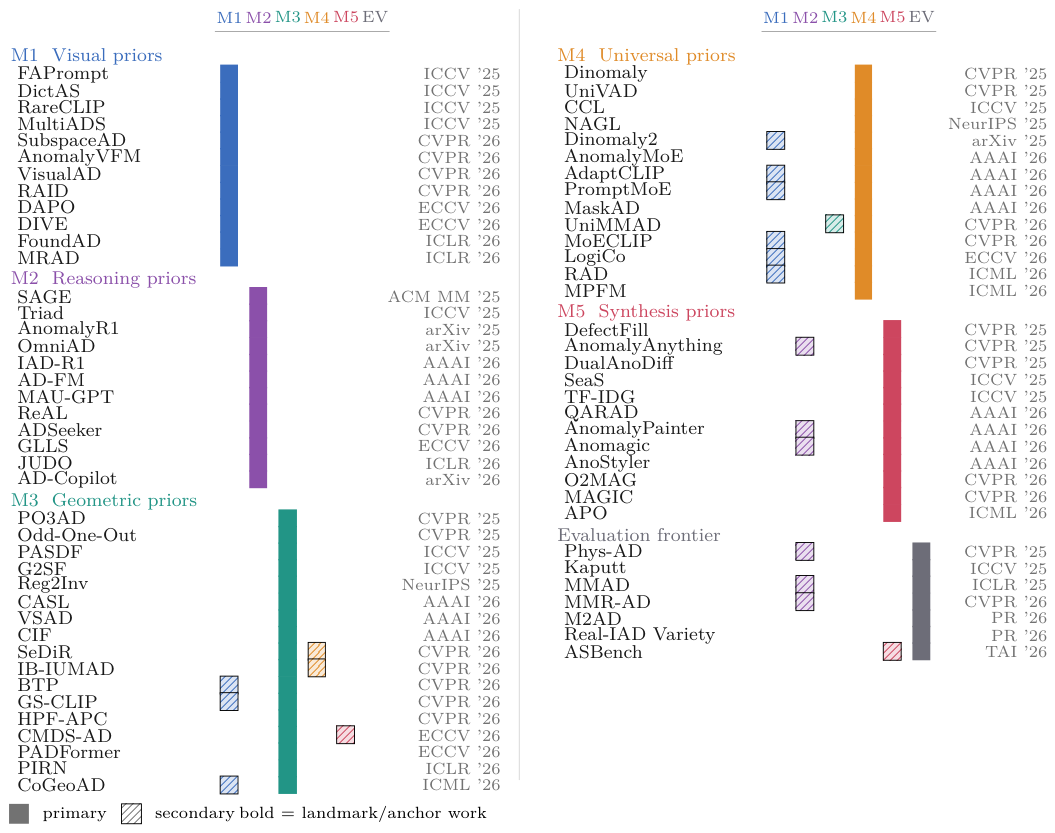
Figure 3.
From normal-only, per-category training to foundation-model priors. On the left, the established baseline trains a separate detector per product on defect-free images alone, and consequently (i) flags normal appearance variation as false alarms, (ii) misses subtle or unseen defects, (iii) needs its own model and fresh normal images for every new product, and (iv) returns an anomaly score without an explanation. On the right, the 2024–2026 wave instead reuses a single frozen, web-pretrained model. Different priors bring different gains. Visual priors enable zero-shot detection on products never seen in training, reasoning localizes and explains defects in language, geometric priors provide 3D cues that 2D views miss, universal priors support one model across many products and modalities, and synthesis generates scarce abnormal data. Example images are real samples from MVTec-AD (Bergmann et al. 2019), VisA (Zou et al. 2022), and Real-IAD (Wang et al. 2024); the 3D point cloud and the generated defects are reproduced from the cited works.
Figure 3.
From normal-only, per-category training to foundation-model priors. On the left, the established baseline trains a separate detector per product on defect-free images alone, and consequently (i) flags normal appearance variation as false alarms, (ii) misses subtle or unseen defects, (iii) needs its own model and fresh normal images for every new product, and (iv) returns an anomaly score without an explanation. On the right, the 2024–2026 wave instead reuses a single frozen, web-pretrained model. Different priors bring different gains. Visual priors enable zero-shot detection on products never seen in training, reasoning localizes and explains defects in language, geometric priors provide 3D cues that 2D views miss, universal priors support one model across many products and modalities, and synthesis generates scarce abnormal data. Example images are real samples from MVTec-AD (Bergmann et al. 2019), VisA (Zou et al. 2022), and Real-IAD (Wang et al. 2024); the 3D point cloud and the generated defects are reproduced from the cited works.
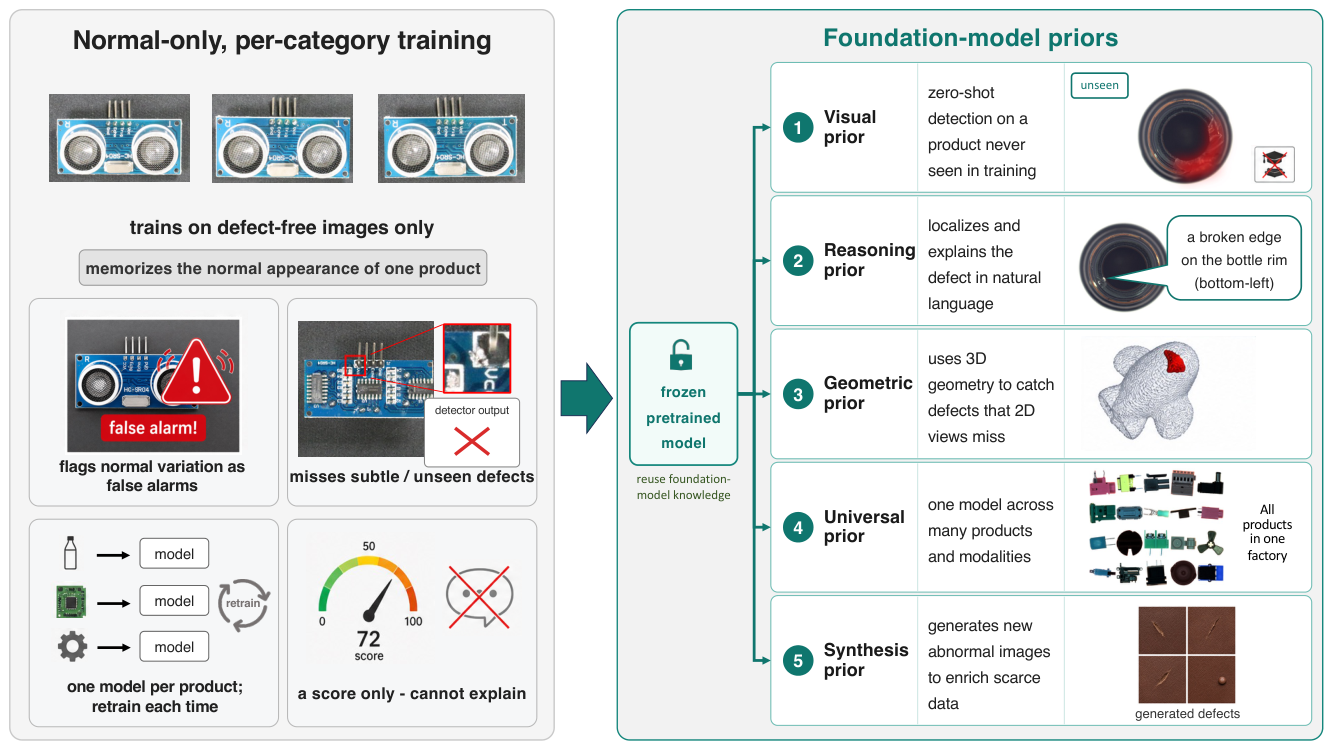
Figure 4.
Visual-prior responses to CLIP-adapter saturation on MVTec-AD I-AUROC. Color = mechanism family; marker = shot regime. The 2023–2025 adapter generations sit in the shaded 91–93% band; only the 2026 architectural cluster (MoECLIP, MRAD, CoPS) crosses it. Scores above the band use different regimes.
† denotes transductive inference (MuSc, RareCLIP),
‡ denotes synthetic-anomaly training (AnomalyVFM, FoundAD), and SubspaceAD/FoundAD use 1–4 references. See Section 3.1.
Figure 4.
Visual-prior responses to CLIP-adapter saturation on MVTec-AD I-AUROC. Color = mechanism family; marker = shot regime. The 2023–2025 adapter generations sit in the shaded 91–93% band; only the 2026 architectural cluster (MoECLIP, MRAD, CoPS) crosses it. Scores above the band use different regimes.
† denotes transductive inference (MuSc, RareCLIP),
‡ denotes synthetic-anomaly training (AnomalyVFM, FoundAD), and SubspaceAD/FoundAD use 1–4 references. See Section 3.1.
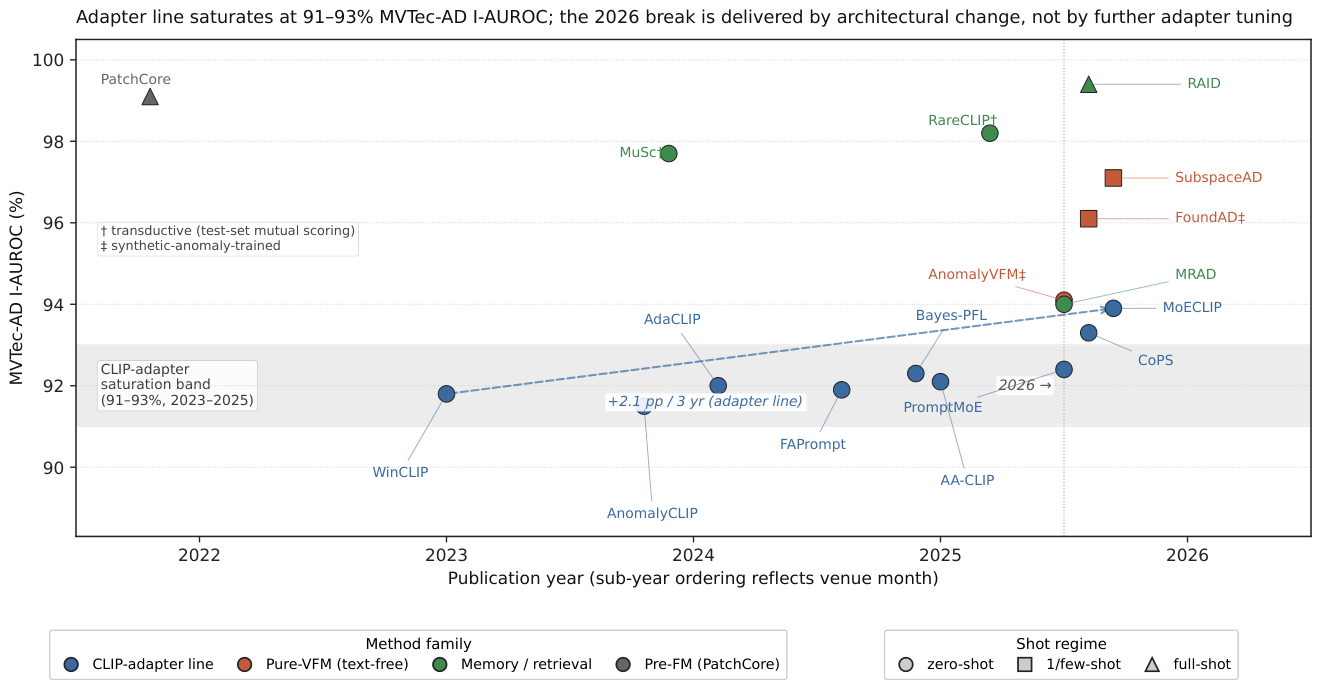
Figure 5.
MLLM-AD training paradigm tree. The SFT-only baseline (AnomalyGPT, Triad) branches into SFT+RAG (knowledge-grounded; ADSeeker, IAD-GPT), SFT+GRPO (RL post-training, the dominant branch; AnomalyR1, IAD-R1, AD-FM, JUDO, ReADL, EMIT), and tuning-free outliers (Reason-IAD, EAGLE). The GRPO branch splits into four reward designs (IAD-R1 structured, AD-FM continuous-IoU, JUDO domain-knowledge, EMIT difficulty-aware). Orthogonal to training, the 2026 architectural addition is the visual-comparison module (VCM, purple), layered on any paradigm above (AD-Copilot, JUDO, SAGE, OmniAD). The right panel shows three failure modes (Section 4.4).
Figure 5.
MLLM-AD training paradigm tree. The SFT-only baseline (AnomalyGPT, Triad) branches into SFT+RAG (knowledge-grounded; ADSeeker, IAD-GPT), SFT+GRPO (RL post-training, the dominant branch; AnomalyR1, IAD-R1, AD-FM, JUDO, ReADL, EMIT), and tuning-free outliers (Reason-IAD, EAGLE). The GRPO branch splits into four reward designs (IAD-R1 structured, AD-FM continuous-IoU, JUDO domain-knowledge, EMIT difficulty-aware). Orthogonal to training, the 2026 architectural addition is the visual-comparison module (VCM, purple), layered on any paradigm above (AD-Copilot, JUDO, SAGE, OmniAD). The right panel shows three failure modes (Section 4.4).
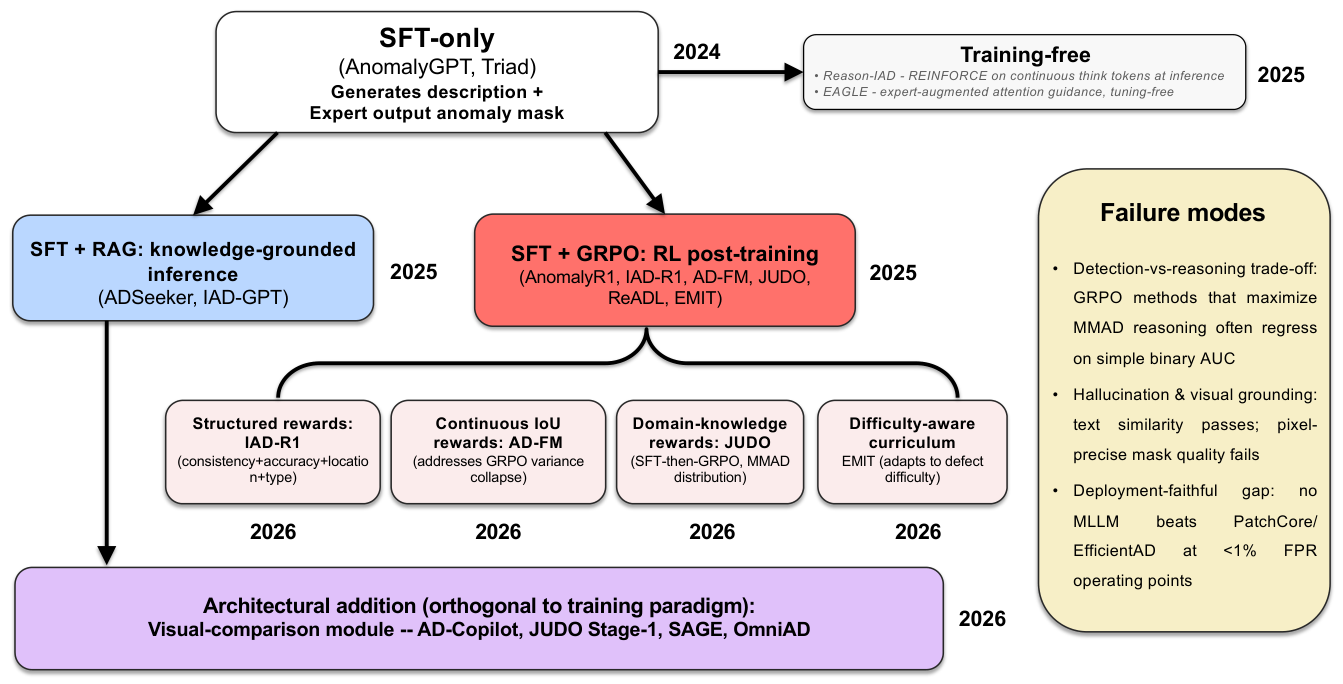
Figure 6.
3D-AD benchmark space comparing scan resolution (log scale) with anomaly coverage. Point size encodes headroom (100 − best AUROC). MVTec-3D-AD (top-left, gray, saturated ∼99%) sits in the easy regime; the newer benchmarks MiniShift, 3D-ADAM, IEC3D-AD, SiM3D move toward the deployment-realistic corner (bottom-right, high-res, low anomaly coverage).
Figure 6.
3D-AD benchmark space comparing scan resolution (log scale) with anomaly coverage. Point size encodes headroom (100 − best AUROC). MVTec-3D-AD (top-left, gray, saturated ∼99%) sits in the easy regime; the newer benchmarks MiniShift, 3D-ADAM, IEC3D-AD, SiM3D move toward the deployment-realistic corner (bottom-right, high-res, low anomaly coverage).
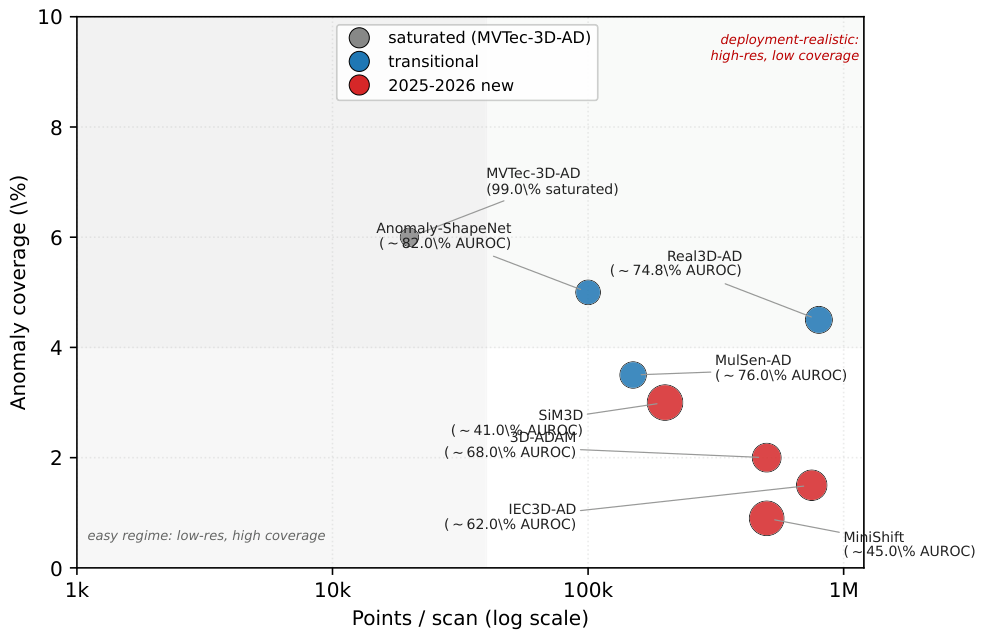
Figure 7.
From per-class detectors to generalist + MoE, with the class-count scaling axis. The top panel shows one model per dataset (UniAD-era) → a single backbone plus MoE routing across datasets through four variants, namely AnomalyMoE (anomaly-type), UniMMAD (modality), PromptMoE (prompt-expert), and MoECLIP (adapter MoE). The bottom panel shows the implicit class-count axis, from per-class specialists (C=1) through AnomalyMoE (C=8), AdaptCLIP (C=12), UniMMAD (C=66) to the CCL scaling wall at C=81 (Section 6.5).
Figure 7.
From per-class detectors to generalist + MoE, with the class-count scaling axis. The top panel shows one model per dataset (UniAD-era) → a single backbone plus MoE routing across datasets through four variants, namely AnomalyMoE (anomaly-type), UniMMAD (modality), PromptMoE (prompt-expert), and MoECLIP (adapter MoE). The bottom panel shows the implicit class-count axis, from per-class specialists (C=1) through AnomalyMoE (C=8), AdaptCLIP (C=12), UniMMAD (C=66) to the CCL scaling wall at C=81 (Section 6.5).
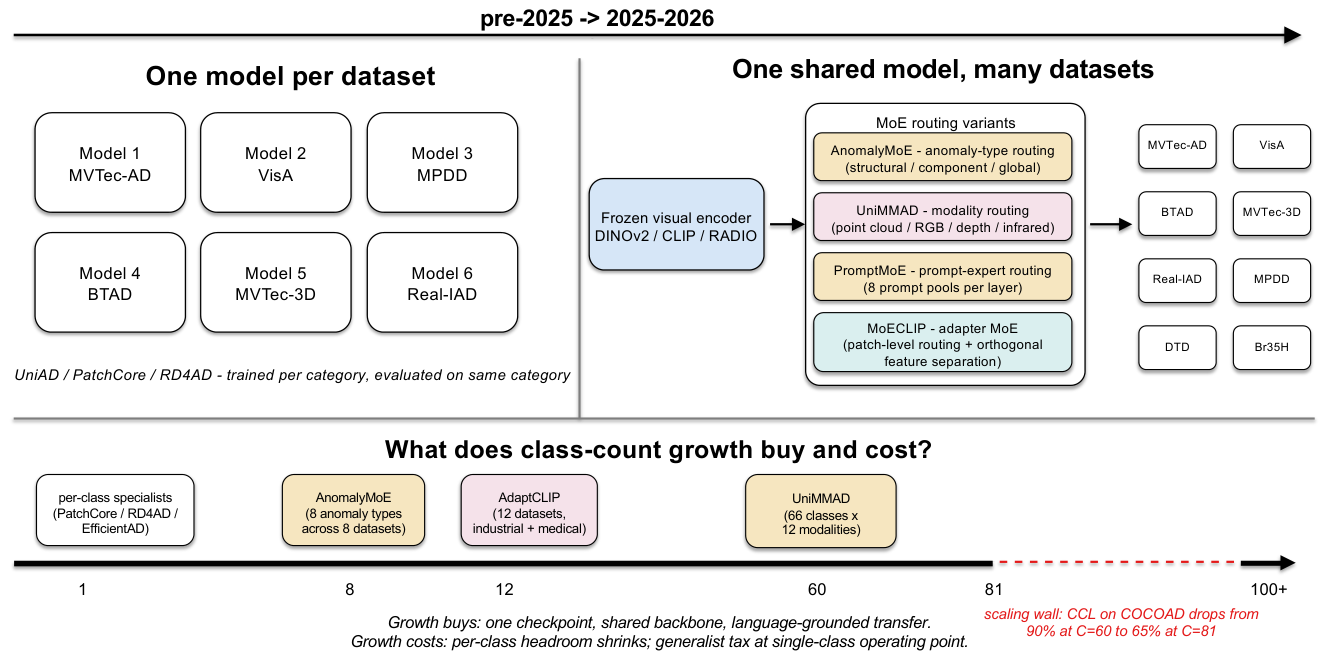
Figure 8.
Synthesis pipeline diversification from the 2024 single-paradigm era (top) to five parallel 2026 sub-paradigms (bottom). The top shows per-category diffusion fine-tune → hand-crafted mask →∼1000-step DDIM (AnomalyDiffusion, RealNet, AnomalyXFusion, DefectFill). At the bottom, reference images branch into (a) few-shot LoRA fine-tune, (b) training-free attention grafting, (c) zero-shot VLM-grounded generation, (d) architecture alternatives (autoregressive ARAS/QARAD; DiT SynSur), and (e) joint image+mask in one pass. The footer contrasts the field’s gains (language grounding, speedup, mask co-generation, FID gap closed 2–3×) with its limits (no tripartite benchmark; evaluation confined to MVTec-AD/VisA; no bound-FPR operating points).
Figure 8.
Synthesis pipeline diversification from the 2024 single-paradigm era (top) to five parallel 2026 sub-paradigms (bottom). The top shows per-category diffusion fine-tune → hand-crafted mask →∼1000-step DDIM (AnomalyDiffusion, RealNet, AnomalyXFusion, DefectFill). At the bottom, reference images branch into (a) few-shot LoRA fine-tune, (b) training-free attention grafting, (c) zero-shot VLM-grounded generation, (d) architecture alternatives (autoregressive ARAS/QARAD; DiT SynSur), and (e) joint image+mask in one pass. The footer contrasts the field’s gains (language grounding, speedup, mask co-generation, FID gap closed 2–3×) with its limits (no tripartite benchmark; evaluation confined to MVTec-AD/VisA; no bound-FPR operating points).
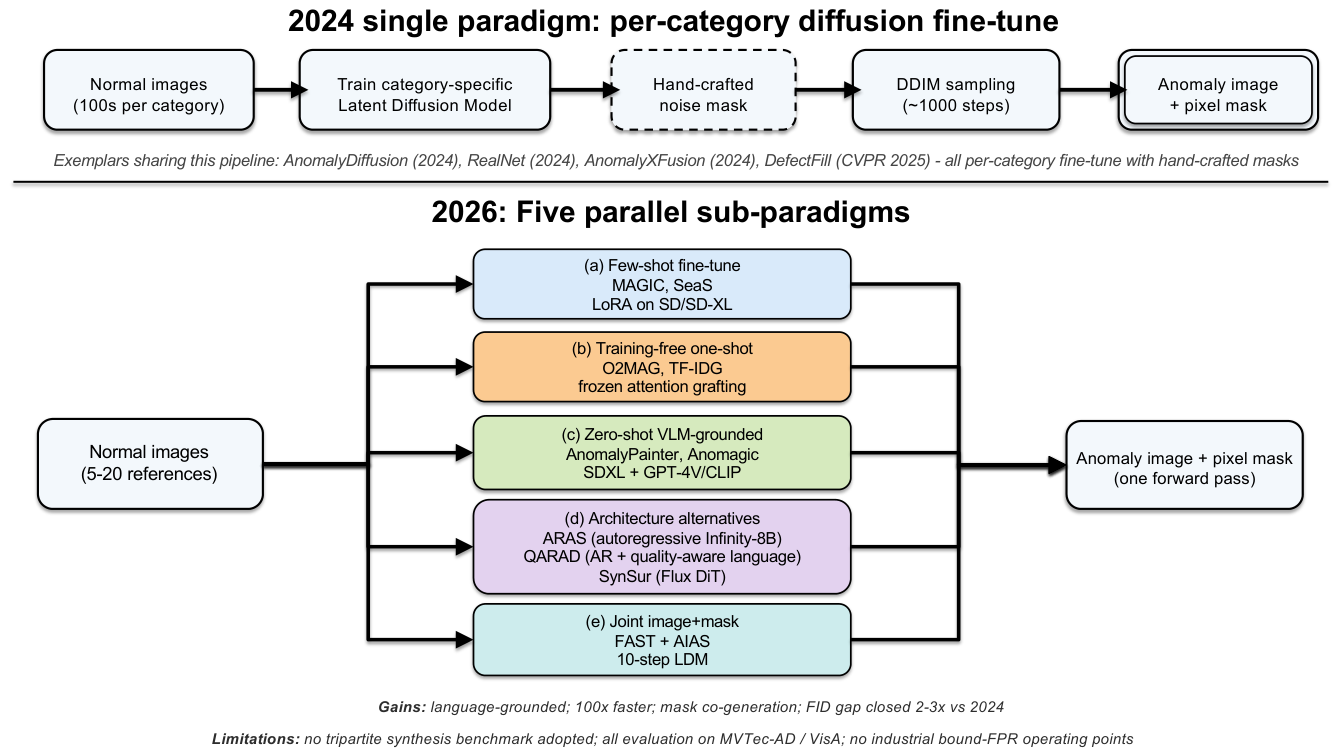
Figure 9.
Cross-cutting bottlenecks aggregated across the five mechanisms. The left panel shows the eight recurring bottlenecks (Section 9.1Section 9.2). The right panel shows, for each mechanism M1–M5, where it is (strongest result to date) and what it still needs (closest unresolved bottleneck), along an increasing-maturity axis. The pattern is consistent. Each mechanism has one empirical anchor at the frontier and at least one bottleneck no paper in its family addresses.
Figure 9.
Cross-cutting bottlenecks aggregated across the five mechanisms. The left panel shows the eight recurring bottlenecks (Section 9.1Section 9.2). The right panel shows, for each mechanism M1–M5, where it is (strongest result to date) and what it still needs (closest unresolved bottleneck), along an increasing-maturity axis. The pattern is consistent. Each mechanism has one empirical anchor at the frontier and at least one bottleneck no paper in its family addresses.
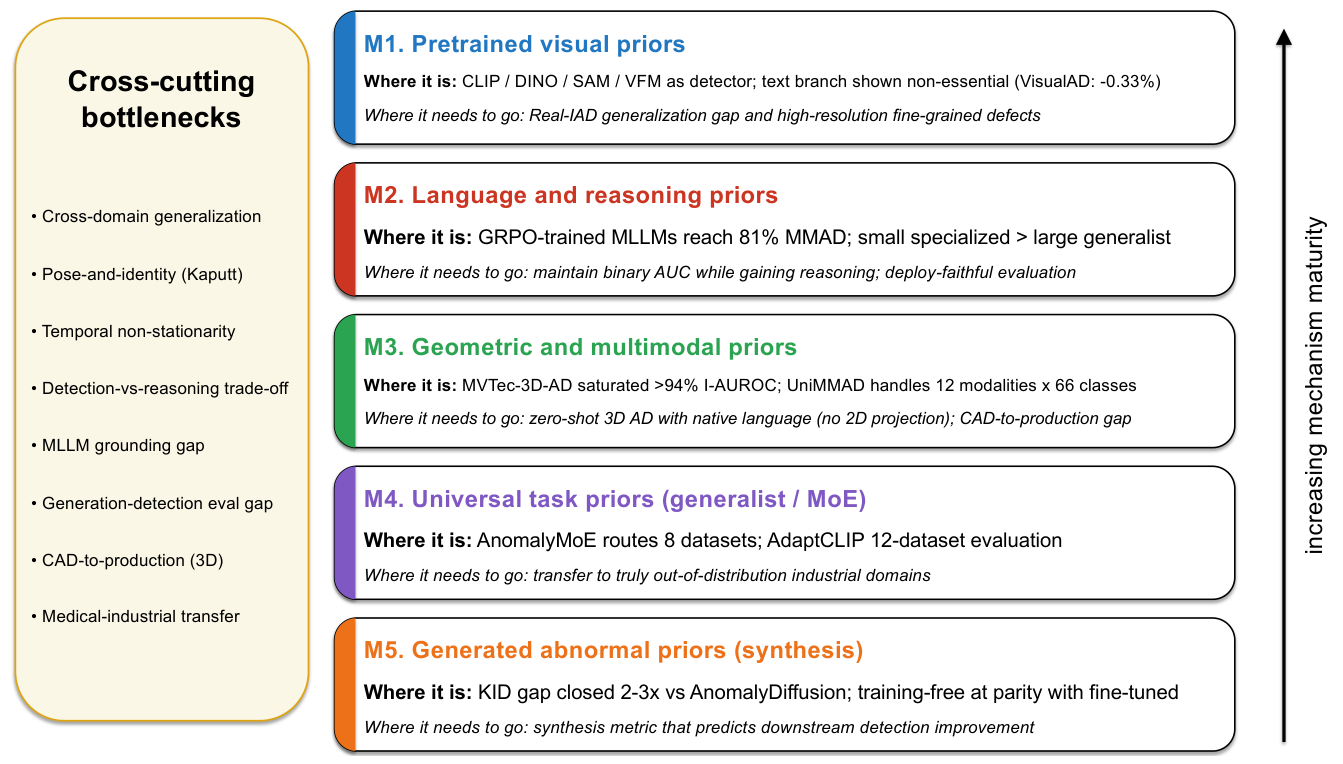
Table 1.
Coverage of this review against seven prior IAD surveys/benchmark studies, along the topics emphasized by recent work (cols 1–7) and two reciprocal axes where prior work retains advantages (cols 8–9). Markings are from a section-level audit (table of contents plus chapter-level reading). • = deep coverage (≥1 dedicated chapter or major subsection, ≥5% of body, comparing ≥3 methods/datasets); ∘ = brief coverage (a paragraph or table entry naming representative methods, no chapter-level treatment); — = not covered (absent or a passing citation). † IM-IAD is a benchmark/protocol study, included for completeness.
Table 1.
Coverage of this review against seven prior IAD surveys/benchmark studies, along the topics emphasized by recent work (cols 1–7) and two reciprocal axes where prior work retains advantages (cols 8–9). Markings are from a section-level audit (table of contents plus chapter-level reading). • = deep coverage (≥1 dedicated chapter or major subsection, ≥5% of body, comparing ≥3 methods/datasets); ∘ = brief coverage (a paragraph or table entry naming representative methods, no chapter-level treatment); — = not covered (absent or a passing citation). † IM-IAD is a benchmark/protocol study, included for completeness.
| Topics emphasized by recent work | Reciprocal axes | |||||||||
|---|---|---|---|---|---|---|---|---|---|---|
| Prior work | Year |
Closed-set 2D |
FM era (CLIP/VFM) |
MLLM- AD |
3D / multimodal |
Synthesis |
Open-world bench |
Eval audit |
Earlier-era method depth |
Cross-domain (med./aerial) |
| Liu et al. 2024 | 2024 | • | ∘ | — | ∘ | ∘ | — | • | • | — |
| Xie et al. 2024a† | 2024 | • | ∘ | ∘ | — | ∘ | — | • | • | — |
| Cao et al. 2024b | 2024 | • | • | ∘ | • | ∘ | — | ∘ | • | — |
| Liang et al. 2025 | 2025 | — | ∘ | ∘ | • | ∘ | — | — | ∘ | — |
| Lin et al. 2025 | 2025 | • | • | • | • | • | — | • | • | — |
| Wang et al. 2025e | 2025 | — | — | ∘ | — | • | — | — | — | — |
| Cheng et al. 2026a | 2026 | • | ∘ | ∘ | • | ∘ | ∘ | — | • | — |
| This review | 2026 | ∘ | • | • | • | • | • | • | ∘ | — |
Table 2.
Section overview of this review. “Anchor methods” lists representative recent methods; “replaces what” identifies the earlier-era baseline the chapter is positioned against; “central tension” is the open question foregrounded in the chapter’s evidence assessment.
Table 2.
Section overview of this review. “Anchor methods” lists representative recent methods; “replaces what” identifies the earlier-era baseline the chapter is positioned against; “central tension” is the open question foregrounded in the chapter’s evidence assessment.
| Section | Mechanism / topic | Anchor methods | Replaces what | Central tension |
|---|---|---|---|---|
| Section 2 | Established baseline | PatchCore, EfficientAD, DRAEM | — | MVTec-AD saturated |
| Section 3 | M1 Visual priors | CLIP, DINOv2, AnomalyVFM, MoECLIP | WinCLIP CLIP-adapter saturation | Saturation band crossed only by architectural change |
| Section 4 | M2 Reasoning priors | IAD-R1, JUDO, AD-FM, EAGLE | AnomalyGPT SFT-only template | MMAD reasoning gains not shown to preserve binary AUC |
| Section 5 | M3 Geometric / multimodal | UniMMAD, GS-CLIP, SiM3D | M3DM/CPMF memory-bank monoculture | MVTec-3D saturated; CAD-to-production gap unresolved |
| Section 6 | M4 Universal / MoE | AnomalyMoE, AdaptCLIP, UniSpector | UniAD per-dataset | Cross-domain transfer wall (UniSpector AP50 69.1%→14.1%) |
| Section 7 | M5 Synthesis priors | ARAS, QARAD, MAGIC, FAST | AnomalyDiffusion per-category | No tripartite synthesis benchmark adopted |
| Section 8 | Evaluation frontier | Kaputt, MMR-AD, ASBench | MVTec/VisA single-tier evaluation | Tier-1 benchmarks wide open |
| Section 9 | Bottlenecks + research agenda | Phys-AD, O-VAD; 8 gaps, 5 targets | — | No paper shows convincing progress on >1 bottleneck; evidence still needed for a strong-version paradigm shift |
Table 3.
Comparison of recent MLLM-AD methods by base model, training paradigm, MMAD accuracy (1-shot), and binary detection performance. All numbers are as reported in the respective papers; the entries themselves note when a metric is non-standard (relative gain, non-MMAD subset, or qualitative).
Table 3.
Comparison of recent MLLM-AD methods by base model, training paradigm, MMAD accuracy (1-shot), and binary detection performance. All numbers are as reported in the respective papers; the entries themselves note when a metric is non-standard (relative gain, non-MMAD subset, or qualitative).
| Method | Venue | Base model | Paradigm | MMAD (1-shot) | Binary detection |
|---|---|---|---|---|---|
| AnomalyGPT | AAAI 2024 | LLaVA-7B | SFT | 36.52% | ∼60% acc. |
| AnomalyR1 | preprint 2025 | Qwen2-VL-3B | SFT+GRPO | 76.96% | ∼70% acc. |
| IAD-R1 | AAAI 2026 | LLaVA-OV-7B | PA-SFT+SC-GRPO | — | 86.1% acc. |
| JUDO | ICLR 2026 | Qwen2.5-VL-7B | SFT×2+GRPO | 81.20% | 65.04% |
| AD-FM | AAAI 2026 | Qwen2.5-VL-7B | GRPO (GIoU) | 83.56% | 73.15% |
| ADSeeker | CVPR 2026 | Qwen2.5-VL-7B | RAG (no RL) | 69.90% | ∼74% |
| Reason-IAD | preprint | Qwen3-VL-8B | Training-free | 79.43% | — |
| EAGLE | preprint 2026 | PatchCore+MLLM | Tuning-free | not reported | expert-aug. |
| Triad | ICCV 2025 | LLaVA-OV-7B | SFT | — | 94.1% |
| SAGE | ACM MM 2025 | InternVL2 | SFT+DPO | not reported | MANTA/MPDD |
| AD-Copilot | preprint | Qwen2.5-VL-7B | 4-stage+RLVR | 82.3% | 3.35× BBox |
| MAU-GPT | AAAI 2026 | ∼4B LLaVA-style | SFT (AMoE-LoRA) | 61.41% | — |
| ReADL | CVPR 2026 | unspecified | GRPO+CGRO | — | competitive |
Table 4.
Representative 3D and multimodal AD methods, 2023–2026 (foundation baselines in the first block; the curated 2025–2026 cohort below). AS = Anomaly-ShapeNet; PC = point cloud.
Table 4.
Representative 3D and multimodal AD methods, 2023–2026 (foundation baselines in the first block; the curated 2025–2026 cohort below). AS = Anomaly-ShapeNet; PC = point cloud.
| Method | Venue | Modality | Benchmark(s) | Key metric | Notes |
|---|---|---|---|---|---|
| M3DM (Wang et al. 2023) | CVPR 2023 | RGB-D | MVTec-3D-AD | 94.0% O-AUROC | Foundation baseline |
| CPMF (Cao et al. 2024a) | PR 2024 | RGB-D | MVTec-3D-AD | >95% O-AUROC | Per-modality scoring |
| PointAD (Zhou et al. 2024b) | NeurIPS 2024 | Point cloud | Real3D-AD, AS | Zero-shot 3D AD | PLM zero-shot scoring |
| G2SF (Tao et al. 2025) | ICCV 2025 | RGB-D | MVTec-3D-AD, Eyecandies | SOTA AUPRO@1% | Anisotropic memory metric |
| PASDF (Zheng et al. 2025) | ICCV 2025 | Point cloud | Real3D-AD, AS | 80.2% O-AUROC | First detect-plus-repair via continuous SDF |
| SiM3D (Costanzino et al. 2025) | ICCV 2025 | RGB+PC, multi-view | SiM3D | Baselines fail synth2real | Single-instance; CAD-to-real benchmark |
| Reg2Inv (Yu et al. 2025b) | NeurIPS 2025 | Point cloud | Real3D-AD, AS | SOTA on both | Registration-as-learning |
| CASL (Zha et al. 2026) | AAAI 2026 | Point cloud | Real3D-AD, AS | +5.6% O-AUROC vs. SSL | Multi-scale curvature beats PointMAE |
| MiniShift (Cheng et al. 2026b) | AAAI 2026 | Point cloud | MiniShift, Real3D-AD, AS | 80.4/92.3% O-AUROC | 500k-pt, <1% anomaly cov.; deep nets near-random |
| U-MV (Chen et al. 2026c) | AAAI 2026 | Multi-view RGB | Real-IAD, MANTA | SOTA on both | Homography alignment; pose-free; 2D only |
| 2M3DF (Asad et al. 2025) | TCSVT 2025 | MV RGB+PC | MVTec-3D-AD, Eyecandies | Multivariate Gaussian | Pixel-to-point fusion; pretrained backbone |
| HPF-APC (Kang et al. 2026b) | CVPR 2026 | Point cloud | Real3D-AD, AS | 84.2% O-AUROC | Patch codebook; angular/planar deformation |
| SeDiR (Kim et al. 2026b) | CVPR 2026 | Point cloud | Real3D-AD, AS | +2.8/+9.1% vs. MC3D-AD | Multi-class; category-entanglement fix |
| UniMMAD (Zhao et al. 2026) | CVPR 2026 | 12 modalities | 9 datasets, 66 classes | SOTA on all 9 | Cross-MoE decoder; anchor paper |
| IB-IUMAD (Long et al. 2026) | CVPR 2026 | RGB-D | MVTec-3D-AD, Eyecandies | 91.0% O-AUROC | Info-bottleneck fusion; incremental |
| PIRN (Li et al. 2026e) | ICLR 2026 | RGB-D | MVTec-3D-AD, Eyecandies | Best 10-shot Eyecandies | Prototype codebook; few-shot multimodal |
| IMDD-1M (Ni et al. 2026) | CVPR 2026 | RGB+text | IMDD-1M | <5% data ≈ expert | 1.24M image-text pairs; 2D only |
| BTP (Li et al. 2026b) | CVPR 2026 | PC+CLIP 2D proj. | Real3D-AD, AS | Zero-shot; >PointAD pt-level | Cross-tag Section 3.3 |
| GS-CLIP (Deng et al. 2026c) | CVPR 2026 | PC+CLIP 2D proj. | Real3D-AD, AS | Zero-shot SOTA | Geometry-aware prompts; cf. Section 3.3 |
Table 5.
Candidate post-MVTec benchmarks from the 2024–2026 IAD corpus, grouped by the deployment failure mode each was built to expose. The Pri. task columns cover 2D detection, 3D point-cloud, RGB-D, MV (multi-view), Text (image–text), and VQA (multimodal QA). Methods claiming to address a given failure mode should report on at least one benchmark in the corresponding row.
Table 5.
Candidate post-MVTec benchmarks from the 2024–2026 IAD corpus, grouped by the deployment failure mode each was built to expose. The Pri. task columns cover 2D detection, 3D point-cloud, RGB-D, MV (multi-view), Text (image–text), and VQA (multimodal QA). Methods claiming to address a given failure mode should report on at least one benchmark in the corresponding row.
| Failure mode exposed | Recommended benchmarks | Pri. task | What is hard |
|---|---|---|---|
| Open-world product diversity | Kaputt (Höfer et al. 2025); Real-IAD-Variety (Zhu et al. 2026); Real-IAD D3 (Zhu et al. 2025b); 3CAD (Yang et al. 2025b); PKU-GoodsAD (Zhang et al. 2024a); MANTA (Fan et al. 2025a) | 2D, RGB-D, MV, Text | 48k items, arbitrary poses, ≤3 refs; viewpoint+material variation, tiny objects, real 3C parts |
| Multi-domain breadth, “one model many domains” | ADNet (380 categories); MMR-AD (Yao et al. 2026); Omni-AD (Shi et al. 2026); M3-AD (Huang et al. 2026); MMAD (Jiang et al. 2025) | 2D, VQA | 380+ categories across 8+ domains; reflection-aware multi-dimensional |
| High-resolution / 3D realism | MiniShift (Cheng et al. 2026b); 3D-ADAM (McHard et al. 2026); IEC3D-AD (Guo et al. 2025a); SiM3D (Costanzino et al. 2025); MulSen-AD (Li et al. 2025c); Real-IAD D3 (Zhu et al. 2025b) | 3D / RGB-D | 500k pts, % anomaly cov.; synth-to-real (CAD→scan); single-instance multiview |
| View-illumination interplay / harder 2D realism | M2AD (Cao et al. 2026); MVTec-AD 2 (Heckler-Kram et al. 2026); VISION Datasets (Bai et al. 2023); Texture-AD (Lei et al. 2024); HSS-IAD (Wang et al. 2025b) | 2D | illumination drift, harder logical anomalies, heterogeneous same-sort |
| Domain-specific specialized inspection | CPS2D-AD (Yu et al. 2025a) (IC substrates); WFDD (Chen et al. 2024) (fabrics); InsPLAD (Vieira e Silva et al. 2023) (power lines); CableInspect-AD (Arodi et al. 2024); CrashCar101; PeanutAD; CID; CXR-AD; RAD | 2D | micrometer-scale defects; specialized appearance and supervision |
| MLLM / VQA / reasoning evaluation | MMAD (Jiang et al. 2025); MMR-AD (Yao et al. 2026); M3-AD (Huang et al. 2026); MAU-Set (Wang et al. 2026e); Chat-AD (Jiang et al. 2026b); Anomaly-OV (Xu et al. 2025a) | VQA | multiple-choice and free-form defect QA; reasoning consistency |
| Open-vocabulary defect understanding | IMDD-1M (Ni et al. 2026) (1.24M pairs, 63 domains); UniSpector (Kim et al. 2026a); MAU-Set (Wang et al. 2026e) | 2D, Text | language-grounded defect classes; cross-domain open-set |
| Synthesis evaluation (decoupled from detection) | ASBench (Zhang et al. 2026b); Defect Spectrum (Yang et al. 2025c) | 2D | synthesis quality vs. downstream detection delta |
| Long-tail / online / deployment dynamics | LTOAD (Yang et al. 2025a) (eight streaming configs) | 2D | long-tailed online updates; class-agnostic concepts |
| Temporal physical dynamics / interactions | Phys-AD (Li et al. 2025b) | Video, VQA | state changes and physical failures that a single frame cannot resolve |
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.
Copyright: This open access article is published under a Creative Commons CC BY 4.0 license, which permit the free download, distribution, and reuse, provided that the author and preprint are cited in any reuse.