
Submitted:
04 October 2025
Posted:
06 October 2025
You are already at the latest version
Abstract
Human Activity Recognition (HAR) is vital for healthcare, behavioral monitoring, and smart environments, yet robust recognition under multimodal and low-light conditions remains challenging. We introduce a benchmark multimodal WBAN dataset combining thermal and infrared imaging with accelerometer data from Raspberry Pi 4.0, covering five core activities: eating, sleeping, staying, standing, and sitting. To model cross-modal spatio- temporal dependencies, we propose MotionXNet, a hybrid network integrating CNN feature extraction, residual BiLSTM encoding, positional embeddings, and multi-head temporal attention. Ablation studies confirm the importance of each component, with attention and positional encoding proving critical for sequence alignment and fine-grained discrimination. Compared with state-of-the-art HAR models (SenTAT, DeepConvLSTM, BiLSTM, DanHAR, MobileHART), MotionXNet achieves 96% accuracy, a macro-F1 of 0.96, and ROC-AUC of 0.9986, establishing a new benchmark for multimodal HAR.

Keywords:
temporal attention
; human activity
; multi-head residual
1. Introduction
Human Activity Recognition (HAR) has emerged as a critical enabler for applications in healthcare monitoring, behavioral analytics, and smart environments. Accurate recognition of daily activities such as eating, sleeping, or sitting plays a central role in personalized health management, elderly care, and rehabilitation systems, where continuous monitoring of patient routines is essential for early anomaly detection and intervention [1,2]. The increasing integration of wearable and ambient sensors has led to a growing focus on multimodal HAR, where multiple sensing modalities are combined to overcome the limitations of individual sources [3].
Traditional HAR methods have relied heavily on wearable accelerometers or gyroscopes for motion capture [4]. While effective, such unimodal signals often lack robustness in low-light or occluded environments where visual sensing would provide complementary information. Conversely, vision-based HAR approaches using RGB cameras suffer from privacy concerns, illumination dependence, and difficulties in deployment in health-sensitive settings [5,6]. To bridge these limitations, recent work has investigated thermal and infrared (IR) imaging, which captures human body contours and heat signatures without revealing personal appearance, thereby offering a privacy-preserving alternative [7].
Despite these advances, robust multimodal fusion remains an open challenge. Aligning spatio-temporal patterns across heterogeneous sources—such as accelerometer streams and thermal imagery—requires models that can integrate sequential dependencies, handle modality-specific noise, and adapt to variable sampling rates. Recent advances in deep learning, including convolutional neural networks (CNNs), recurrent neural networks (RNNs), and attention mechanisms, have shown promise in capturing such complexities [8,9]. However, most existing HAR frameworks either underexploit positional encoding for sequence alignment or lack sufficient temporal attention to capture fine-grained dependencies across modalities.
In this paper, we make two key contributions.
- First, we introduce a new benchmark multimodal WBAN dataset that combines thermal and IR imagery with accelerometer signals collected using Raspberry Pi 4.0 devices. The dataset encompasses five representative daily activities—eating, sleeping, staying, standing, and sitting—captured under low-light and realistic environmental conditions.
- Second, we propose MotionXNet, a hybrid architecture that integrates CNN-based feature extraction, residual BiLSTM encoding, positional embeddings, and multi-head temporal attention. Extensive ablation studies confirm the contribution of each component, while comparative experiments with state-of-the-art models such as SenTAT, DeepConvLSTM, BiLSTM, DanHAR, and MobileHART demonstrate MotionXNet’s superior performance, achieving 96% accuracy, macro-F1 of 0.96, and ROC-AUC of 0.9986.
Through this integration of a new dataset and a novel spatio-temporal attention architecture, our work establishes a new foundation for multimodal HAR, particularly in healthcare and privacy-sensitive monitoring domains.
2. Methods and Experiment
2.1. Dataset Details
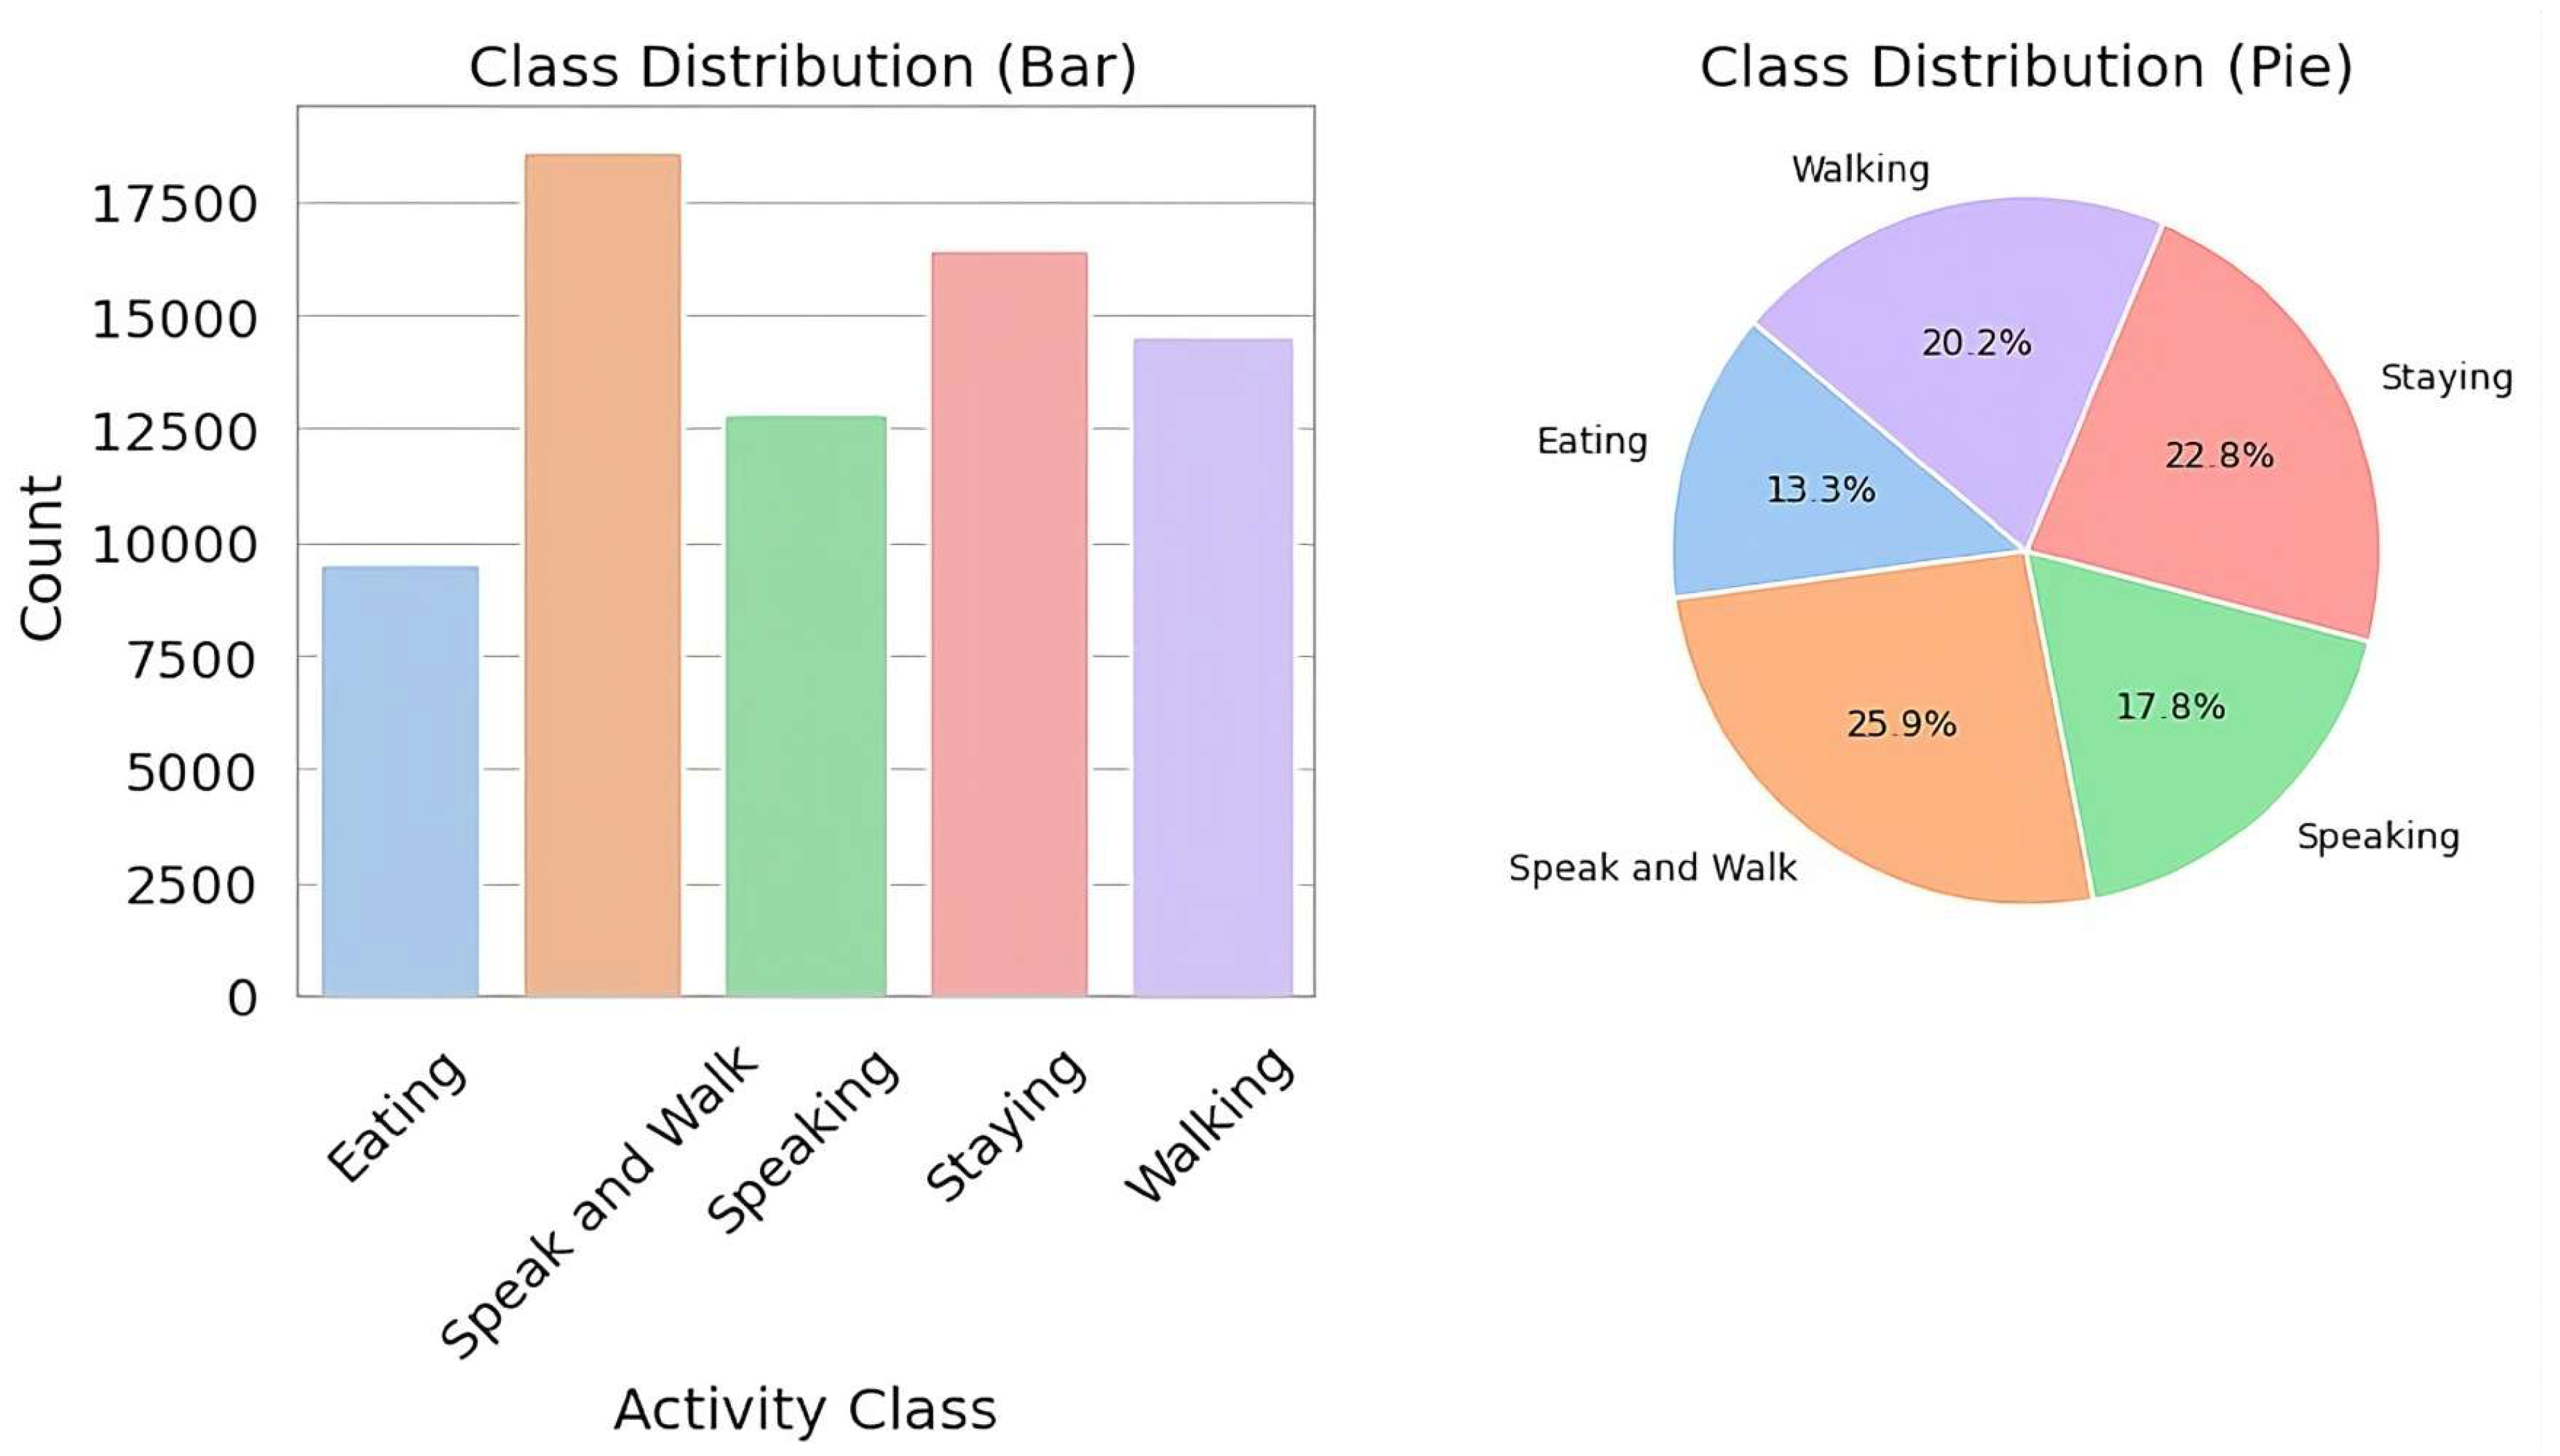
The proposed study introduces a benchmark multimodal WBAN dataset designed specifically for activity recognition under constrained conditions such as darkness and low visibility. Data were collected from two complementary sources: Thermal and infrared imaging was used to record the contour and heat signatures of participants. Unlike RGB images, these modalities do not capture identifiable facial or clothing details, ensuring privacy preservation. Each image frame was sampled at fixed intervals and resized to maintain a consistent spatial resolution across subjects. Inertial sensor streams were collected using Raspberry Pi 4.0 devices equipped with a tri-axial accelerometer. Signals were captured at uniform sampling rates and synchronized with the imaging stream. The accelerometer captured micro-movements and posture shifts that were often invisible to camera-only modalities. The dataset covers five fundamental human activities: eating, speak and walk, staying, speaking, and walking. Recordings were made across different sessions and subjects to ensure inter-class diversity. Each sample is labeled with the corresponding activity class and stored in a synchronized multimodal format. The first step was to examine class balance across the five activities: eating, sleeping, staying, standing, and sitting. A combined bar chart and pie chart revealed that standing and sitting together constituted the largest proportion of samples, reflecting the natural dominance of stationary postures in daily routines. Sleeping and staying also showed substantial representation, whereas eating was the least frequent class. This imbalance motivated the later use of weighted metrics such as macro F1-score, ensuring that underrepresented behaviors were not overshadowed during evaluation.
Figure 1.
Overall Methodology Diagram.

Figure 2.
Dataset class distribution.
2.2. Data Analysis
To ensure the quality and interpretability of the proposed multimodal WBAN dataset, we conducted an extensive exploratory analysis combining both statistical and visual approaches. The following subsections summarize the main findings, supported by a series of diagnostic plots produced in the companion notebook.
2.2.1. Sensor Feature Histograms
Histograms were plotted for each accelerometer and gyroscope axis. Clear separability was visible between activities; for instance, sleeping displayed tightly clustered low-variance distributions, while eating and standing showed wider spread in acceleration magnitudes. The histograms highlighted that different activities project distinct statistical signatures, confirming the value of inertial sensing.
Figure 3.
Feature Histograms diagram.
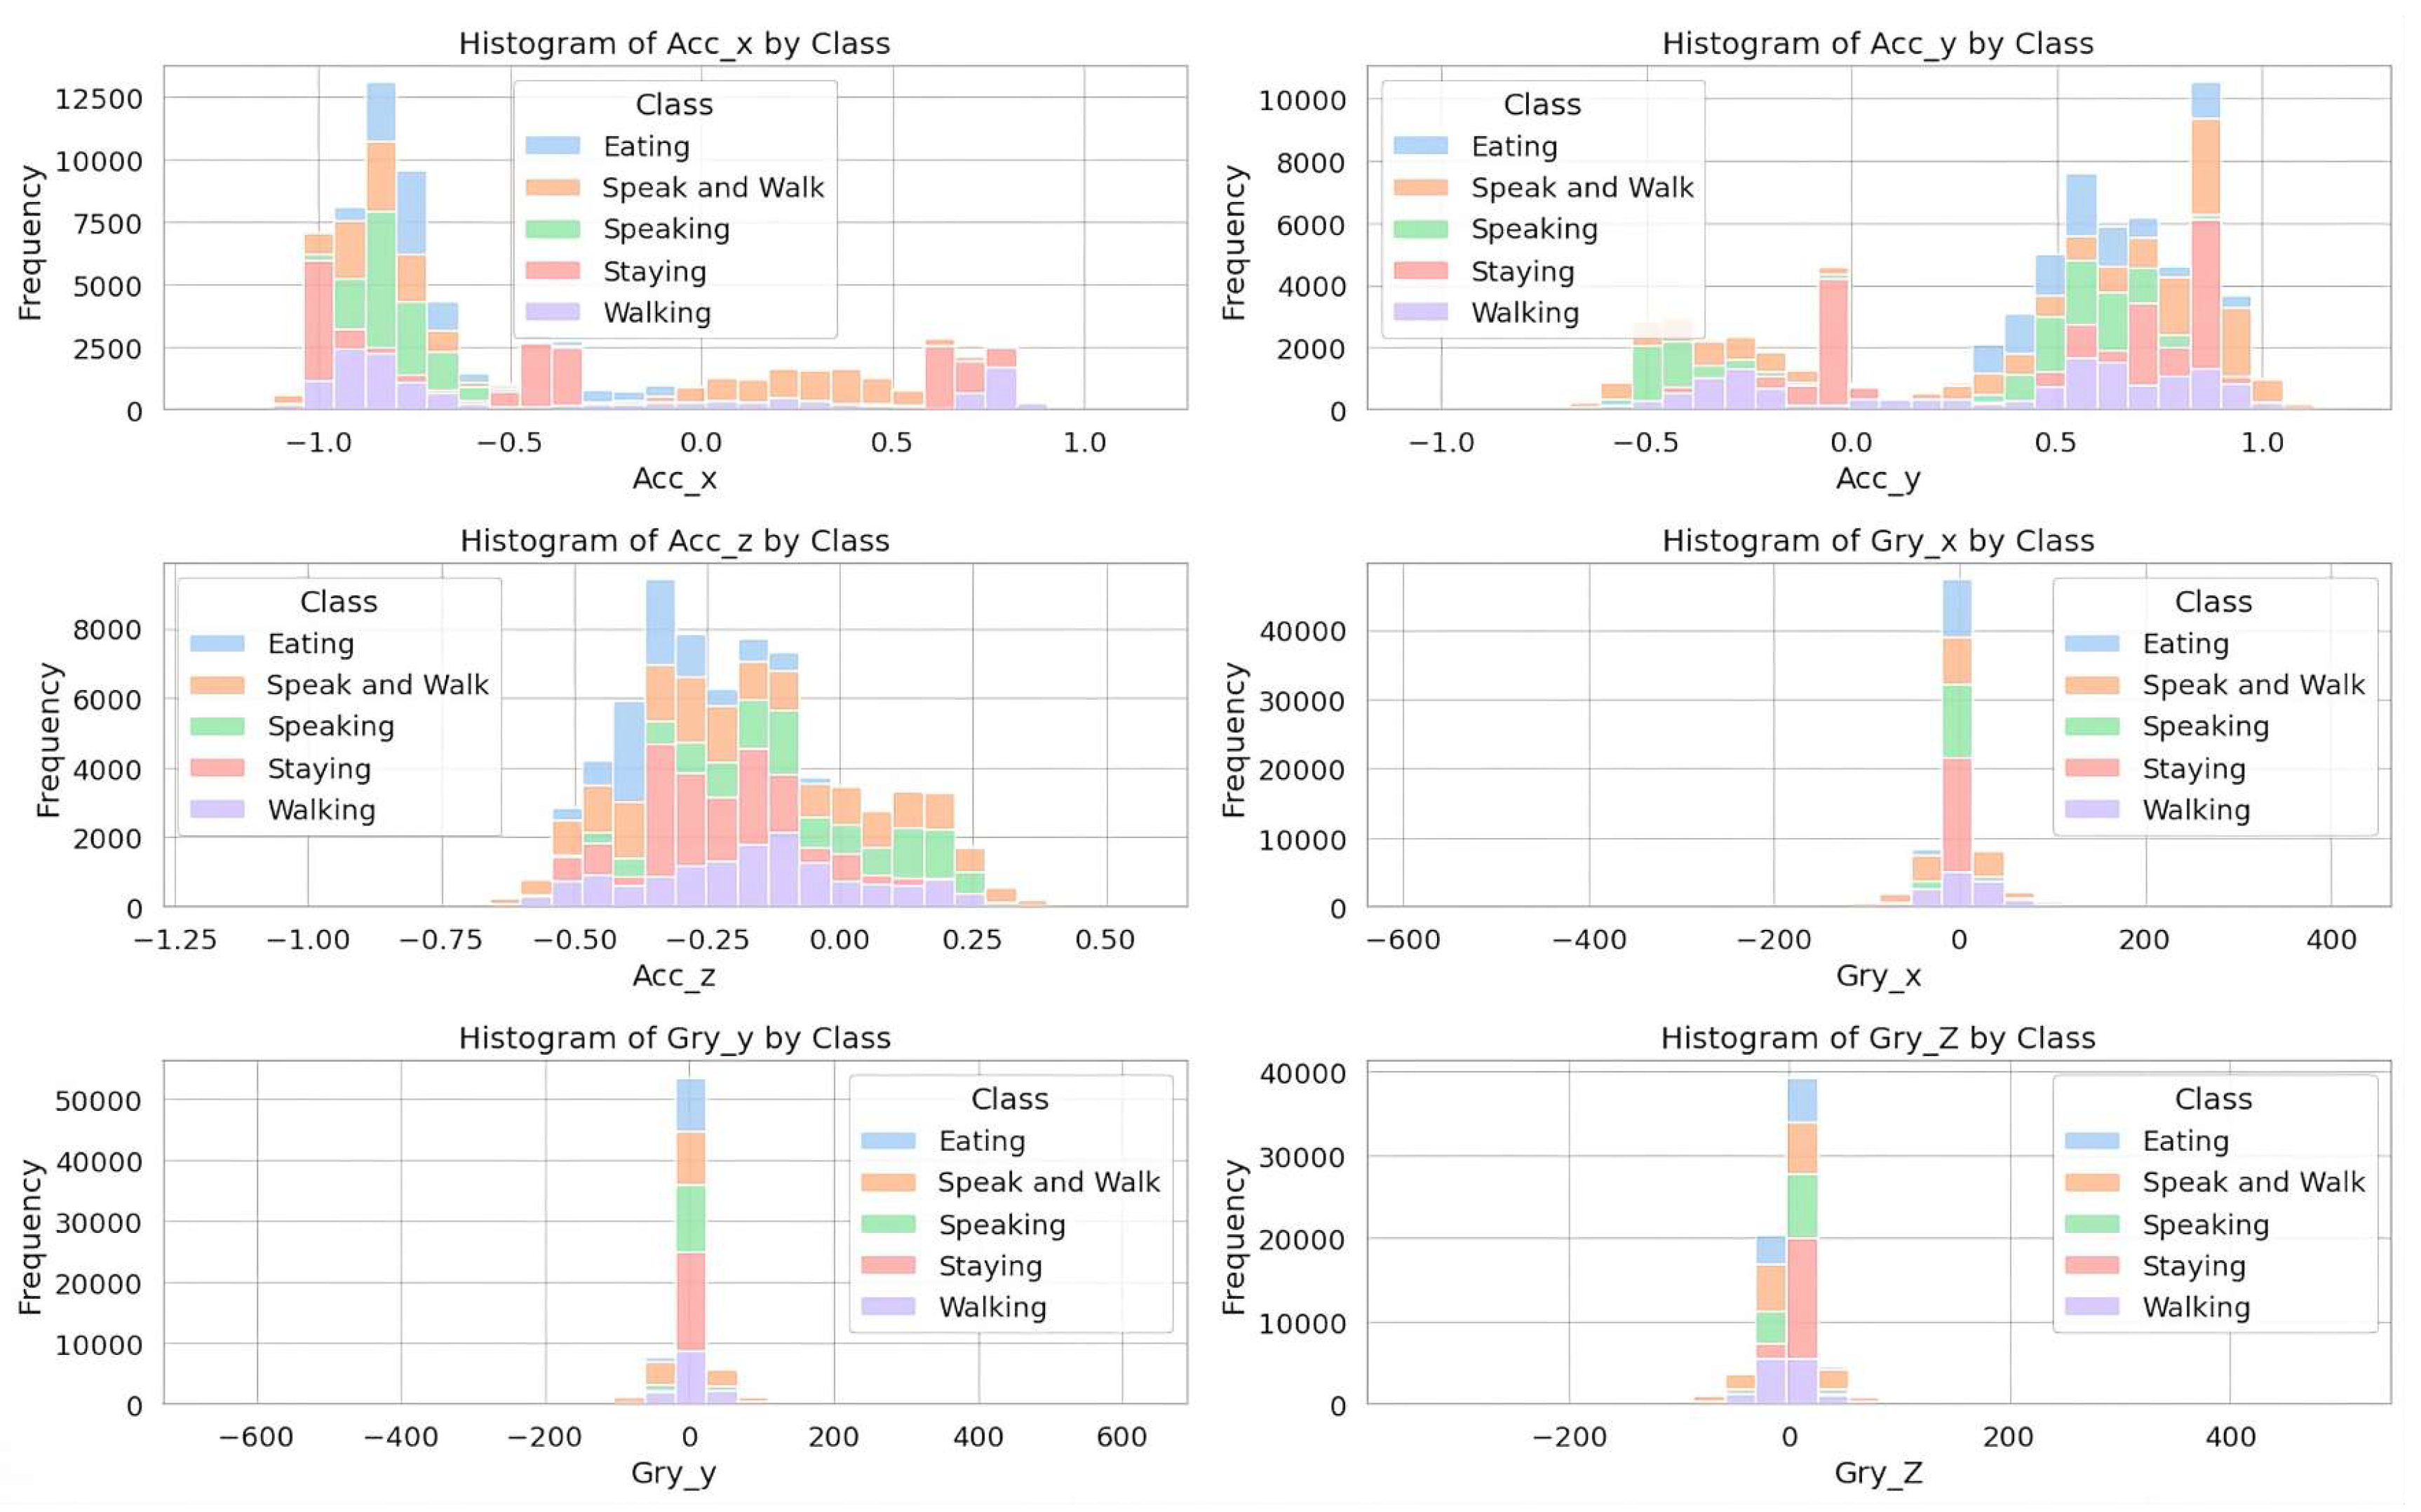
Figure 4.
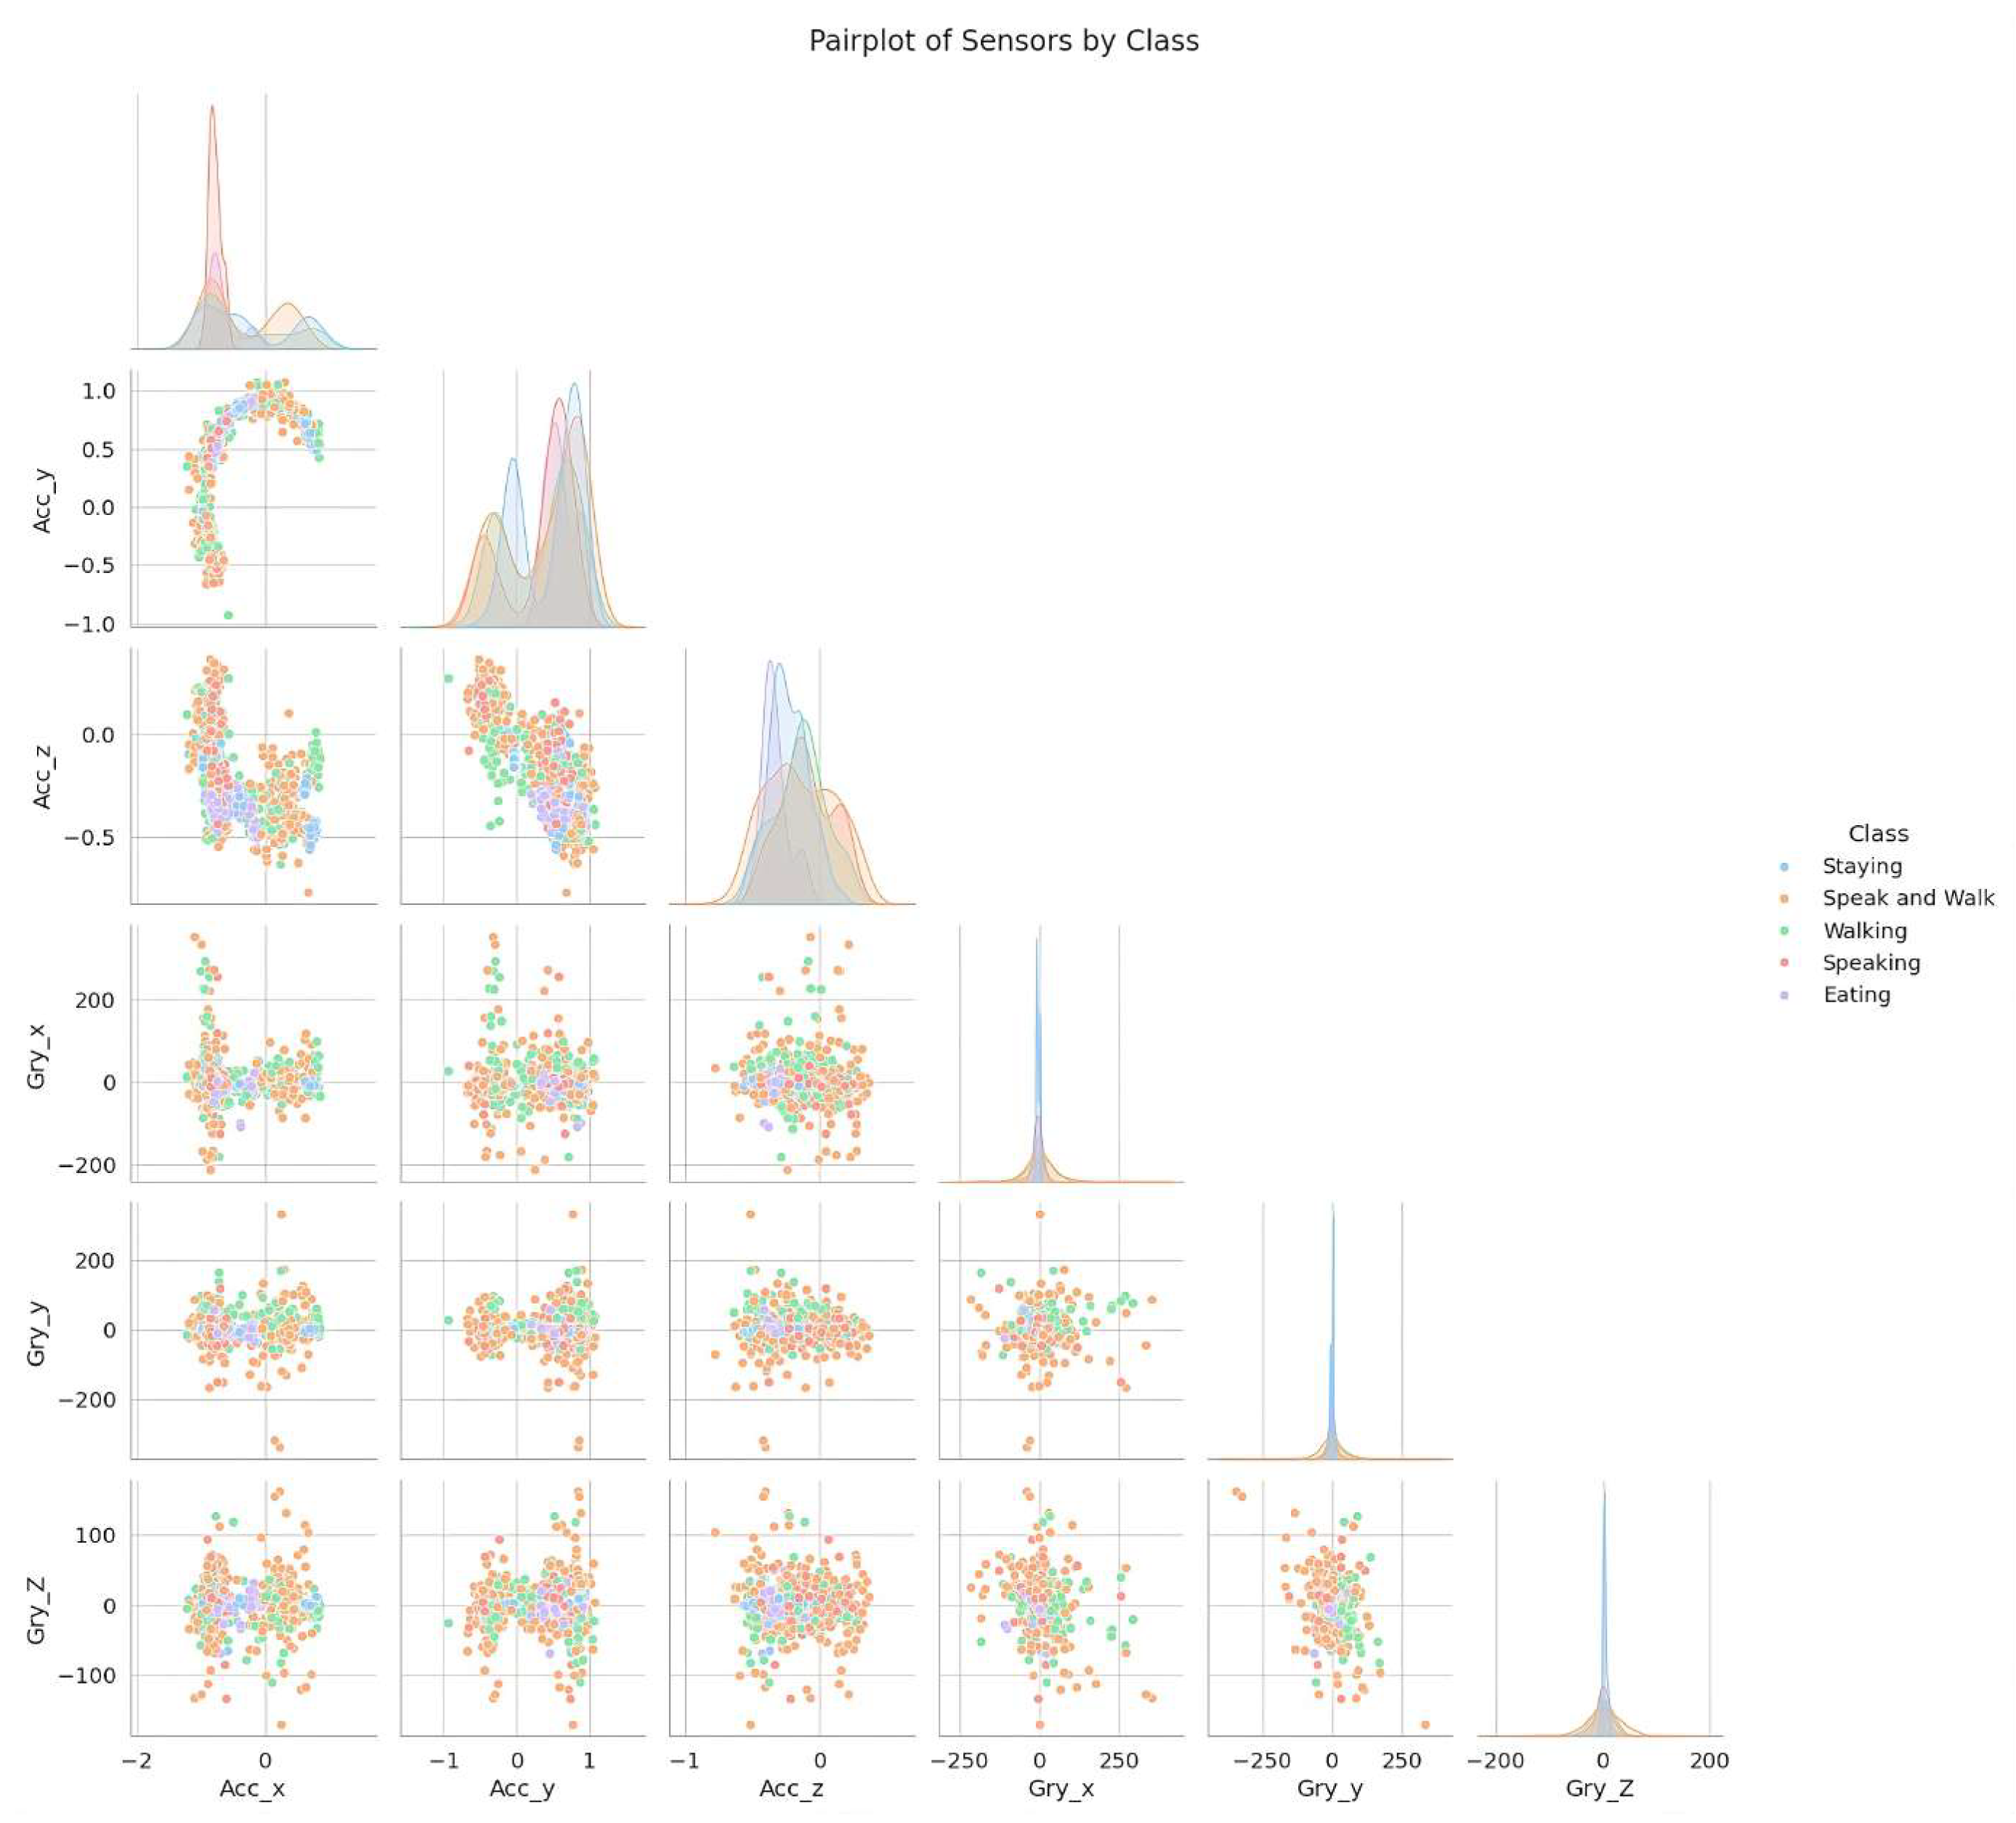
Pairwise Feature Relationships.
2.2.2. Boxplots of Sensor Features
To better understand variability, we plotted boxplots for each sensor axis conditioned on activity class. The plots confirmed differences in medians and interquartile ranges across classes. For example, Acc_z consistently exhibited higher median values during standing compared to sitting, reflecting the gravitational alignment of body posture. Outliers were also informative, revealing transitional movements that do not conform neatly to class labels but are important for robust model generalization.
2.2.3. Pairwise Feature Relationships
A pairplot of sampled data points was generated to visualize feature interactions. Clusters emerged naturally in the accelerometer feature space, with sleeping forming a distinct, compact cluster, while eating overlapped partially with sitting and staying. These overlaps suggested that unimodal inertial sensing may not fully separate classes, hence the importance of multimodal fusion with thermal/infrared imaging.
2.2.4. Aggregate Sensor Profiles per Transition (Radar)
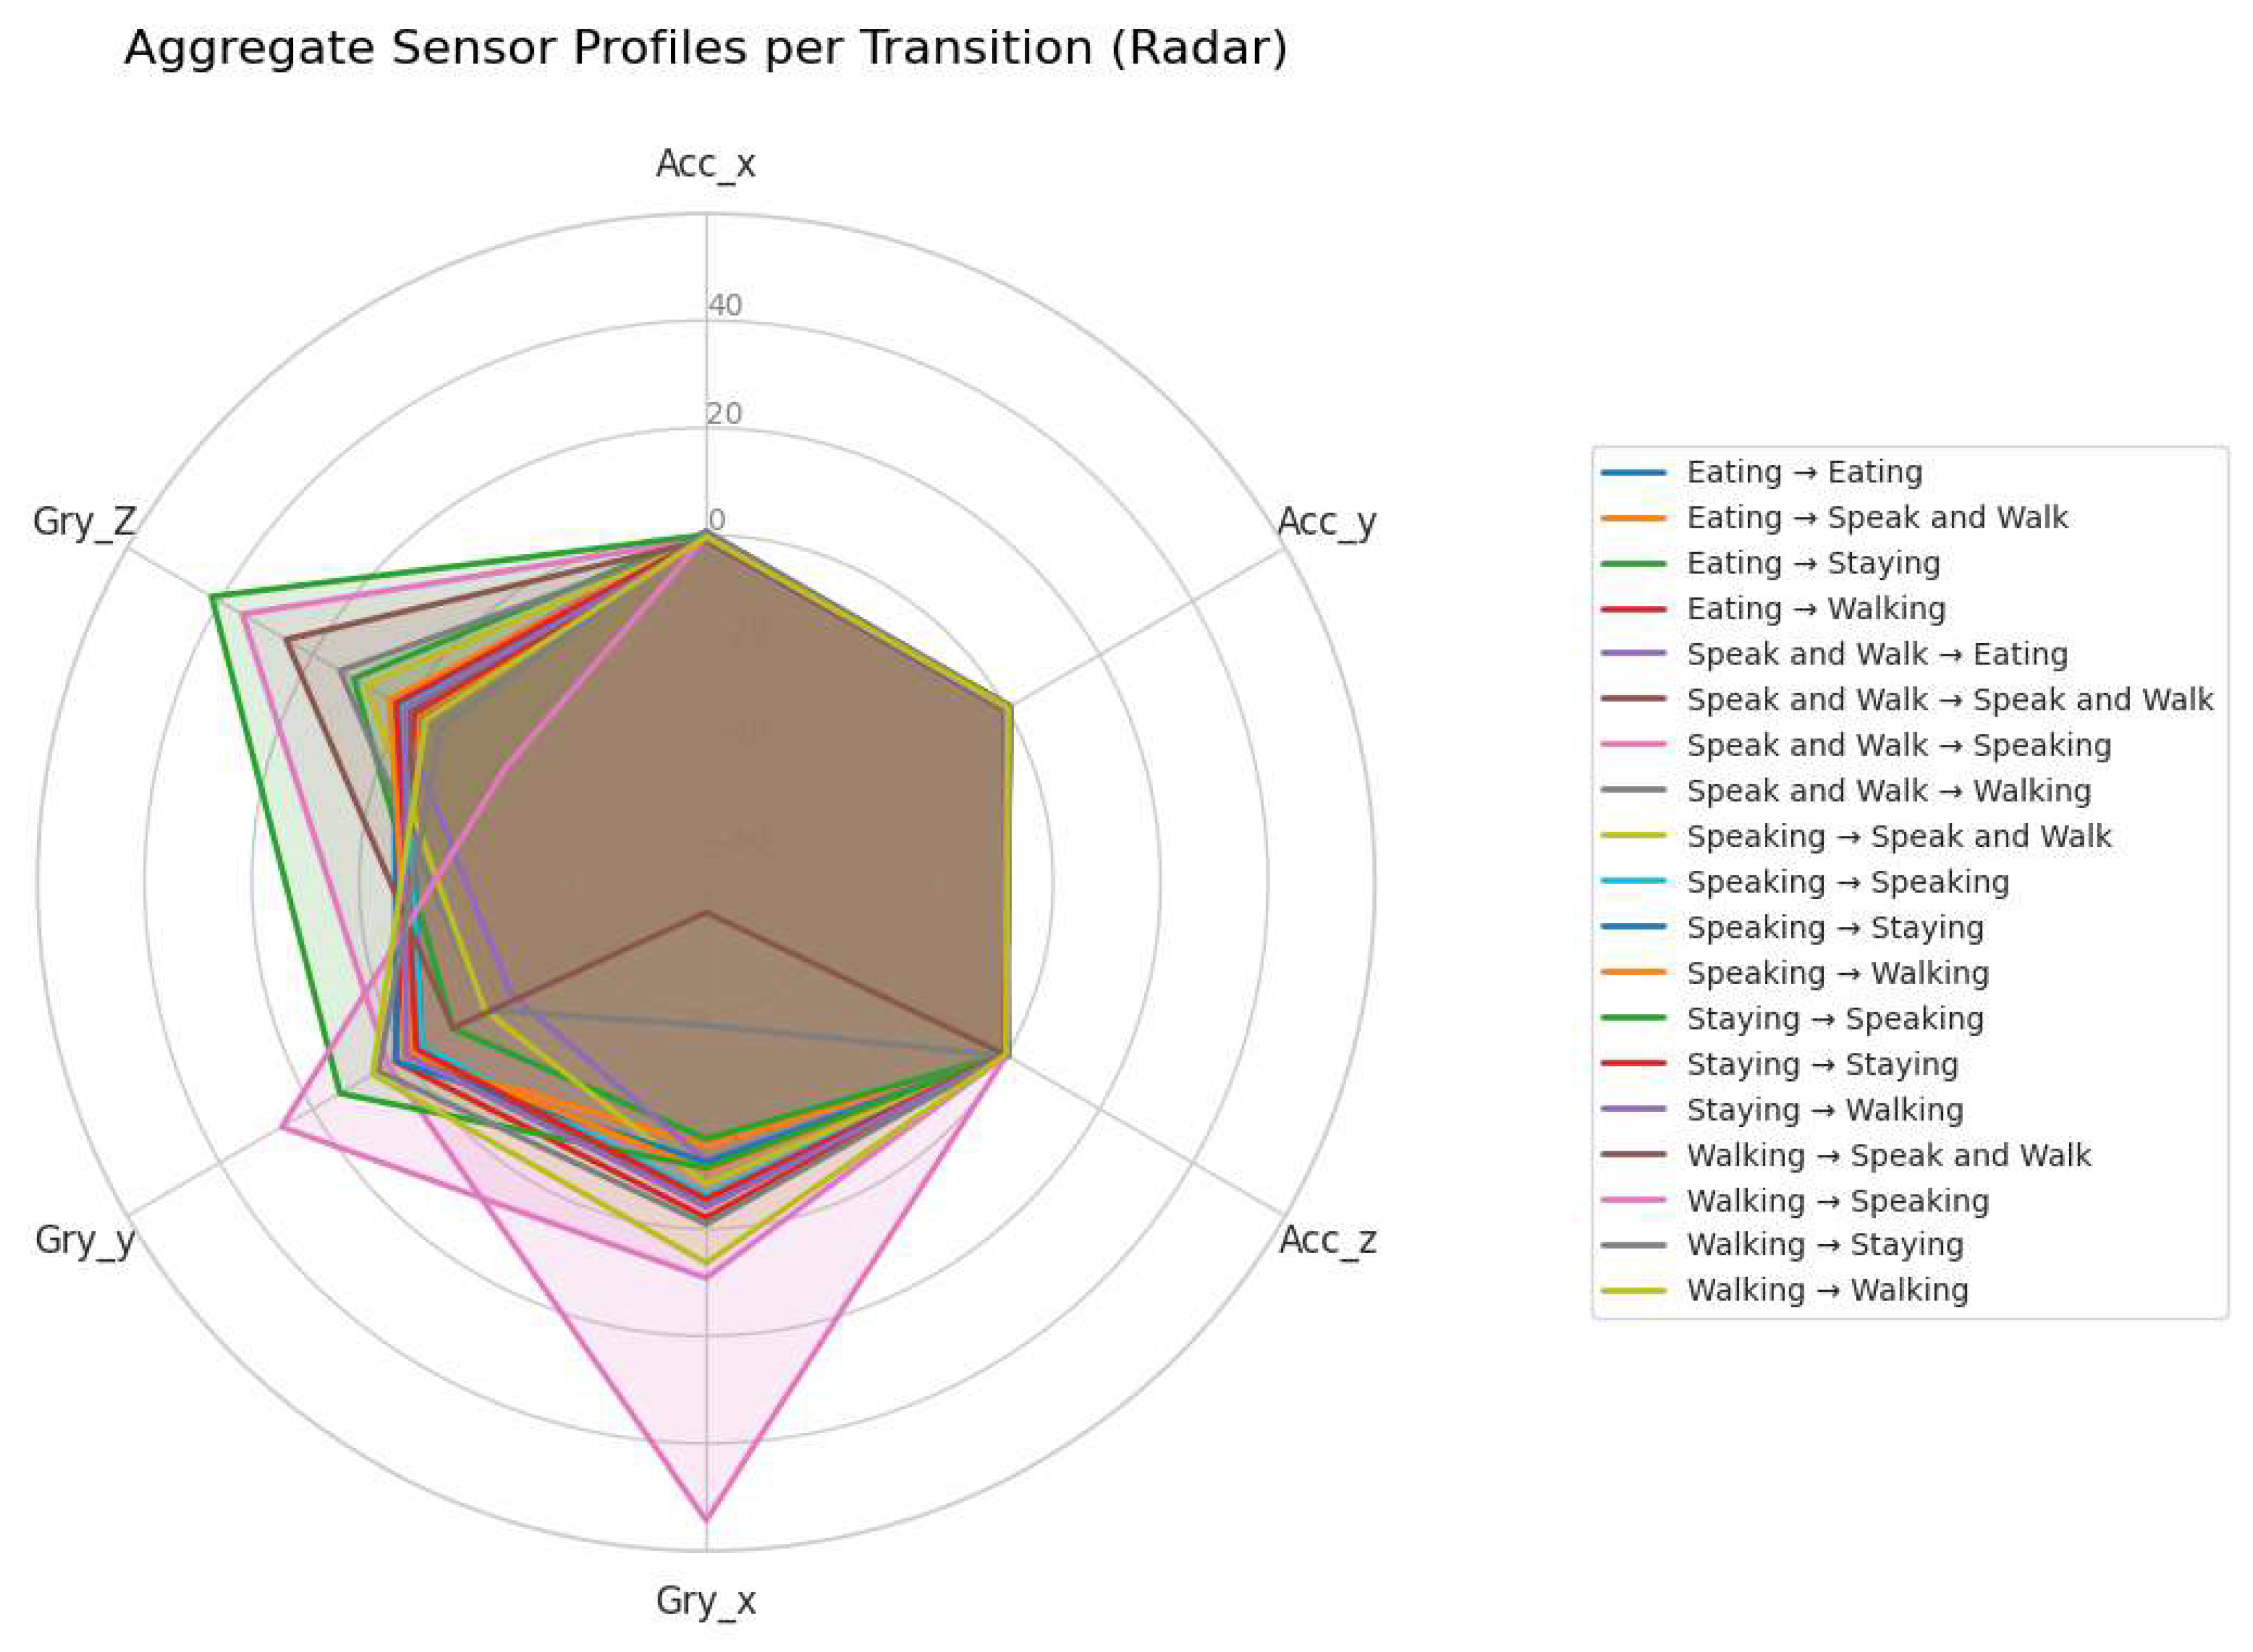
The radar plot illustrates the aggregated accelerometer and gyroscope sensor profiles across activity transitions. Each line corresponds to a transition between two activities, for example, Eating → Staying or Walking → Speaking. The axes represent the normalized sensor axes (Acc_x, Acc_y, Acc_z, Gry_x, Gry_y, Gry_z). Distinct patterns emerge across transitions, particularly in the gyroscope axes (Gry_x and Gry_z), which show sharper deviations during transitions involving locomotion (e.g., Walking → Staying) compared to stationary transitions (e.g., Staying → Staying). This suggests that gyroscope signals are highly sensitive to rotational dynamics and capture micro-movements often missed by accelerometers.
Figure 5.
Aggregate Sensor Profiles per Transition (Radar) diagram.
2.2.5. Joint Feature Heatmaps per Transition
To analyze transitions at the feature level, we computed average sensor feature values conditioned on pairs of consecutive activities and displayed them in heatmaps. These revealed that certain features spike during specific transitions; for example, gyroscope axes showed pronounced changes during sitting → standing transitions, whereas accelerometer axes shifted most during standing → sleeping. These insights confirm that activity transitions encode discriminative information that should be modeled explicitly rather than ignored.
Figure 6.
Joint Feature Heatmaps.
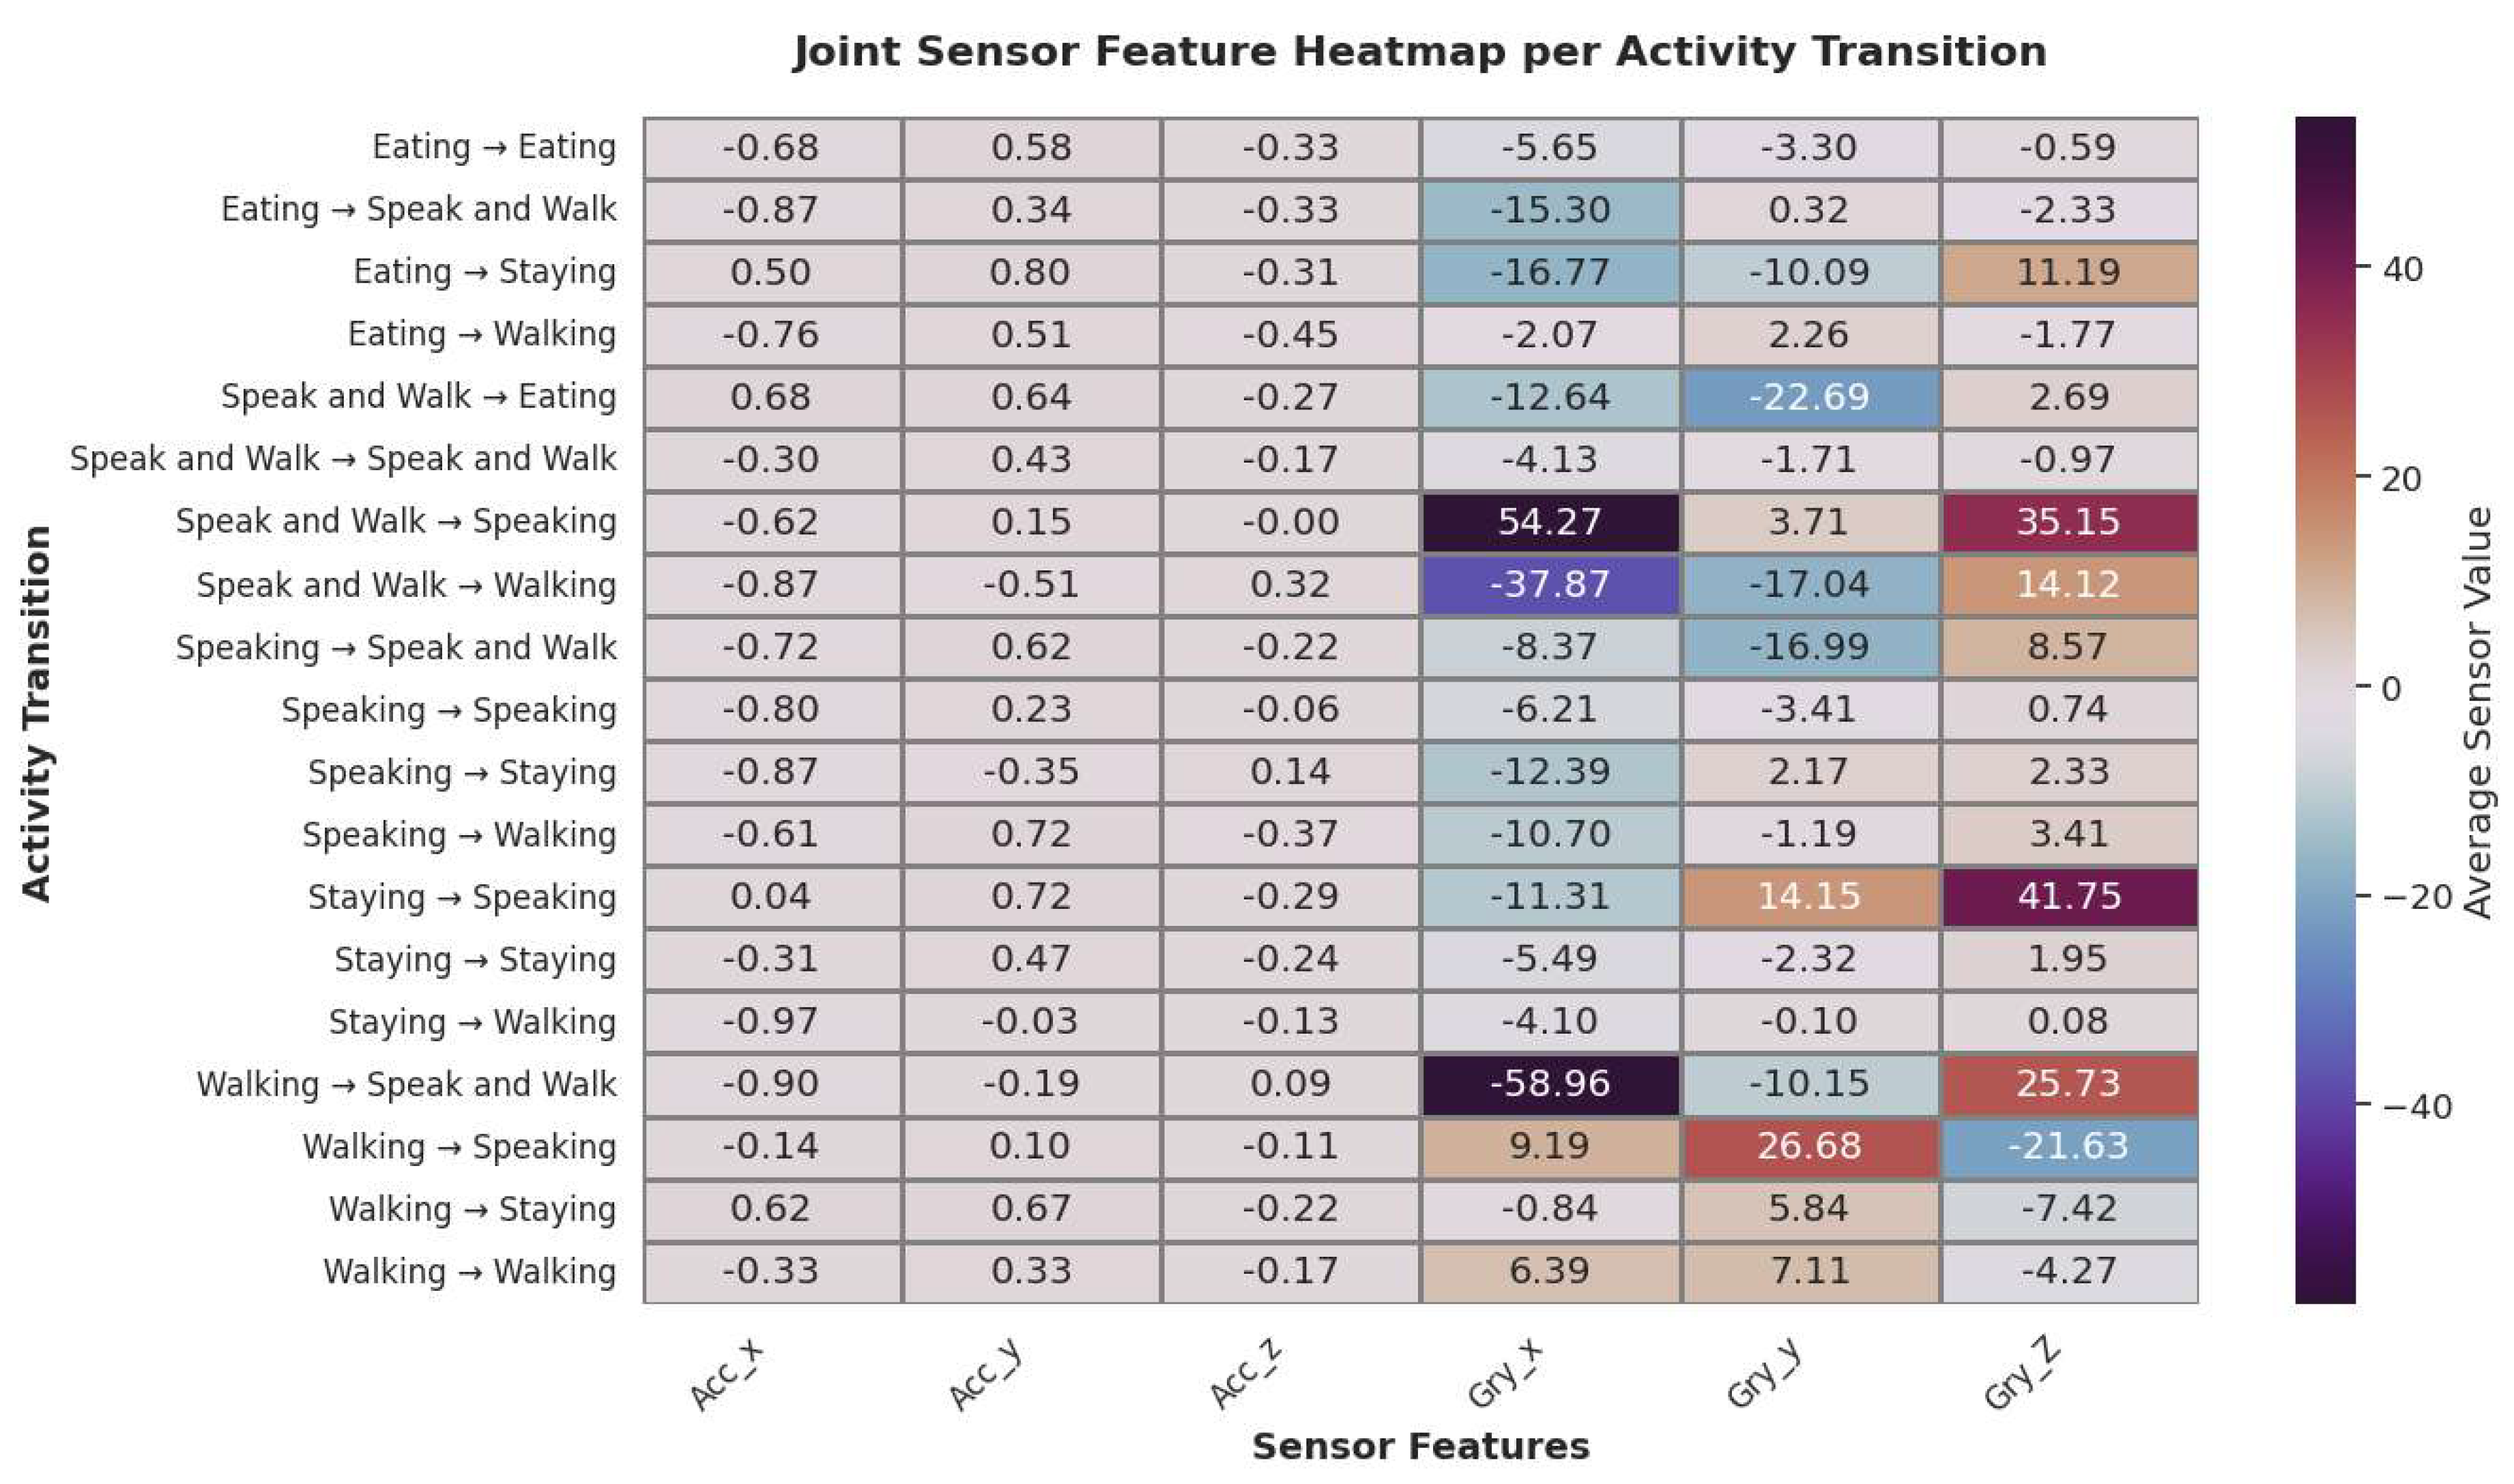
Figure 7.
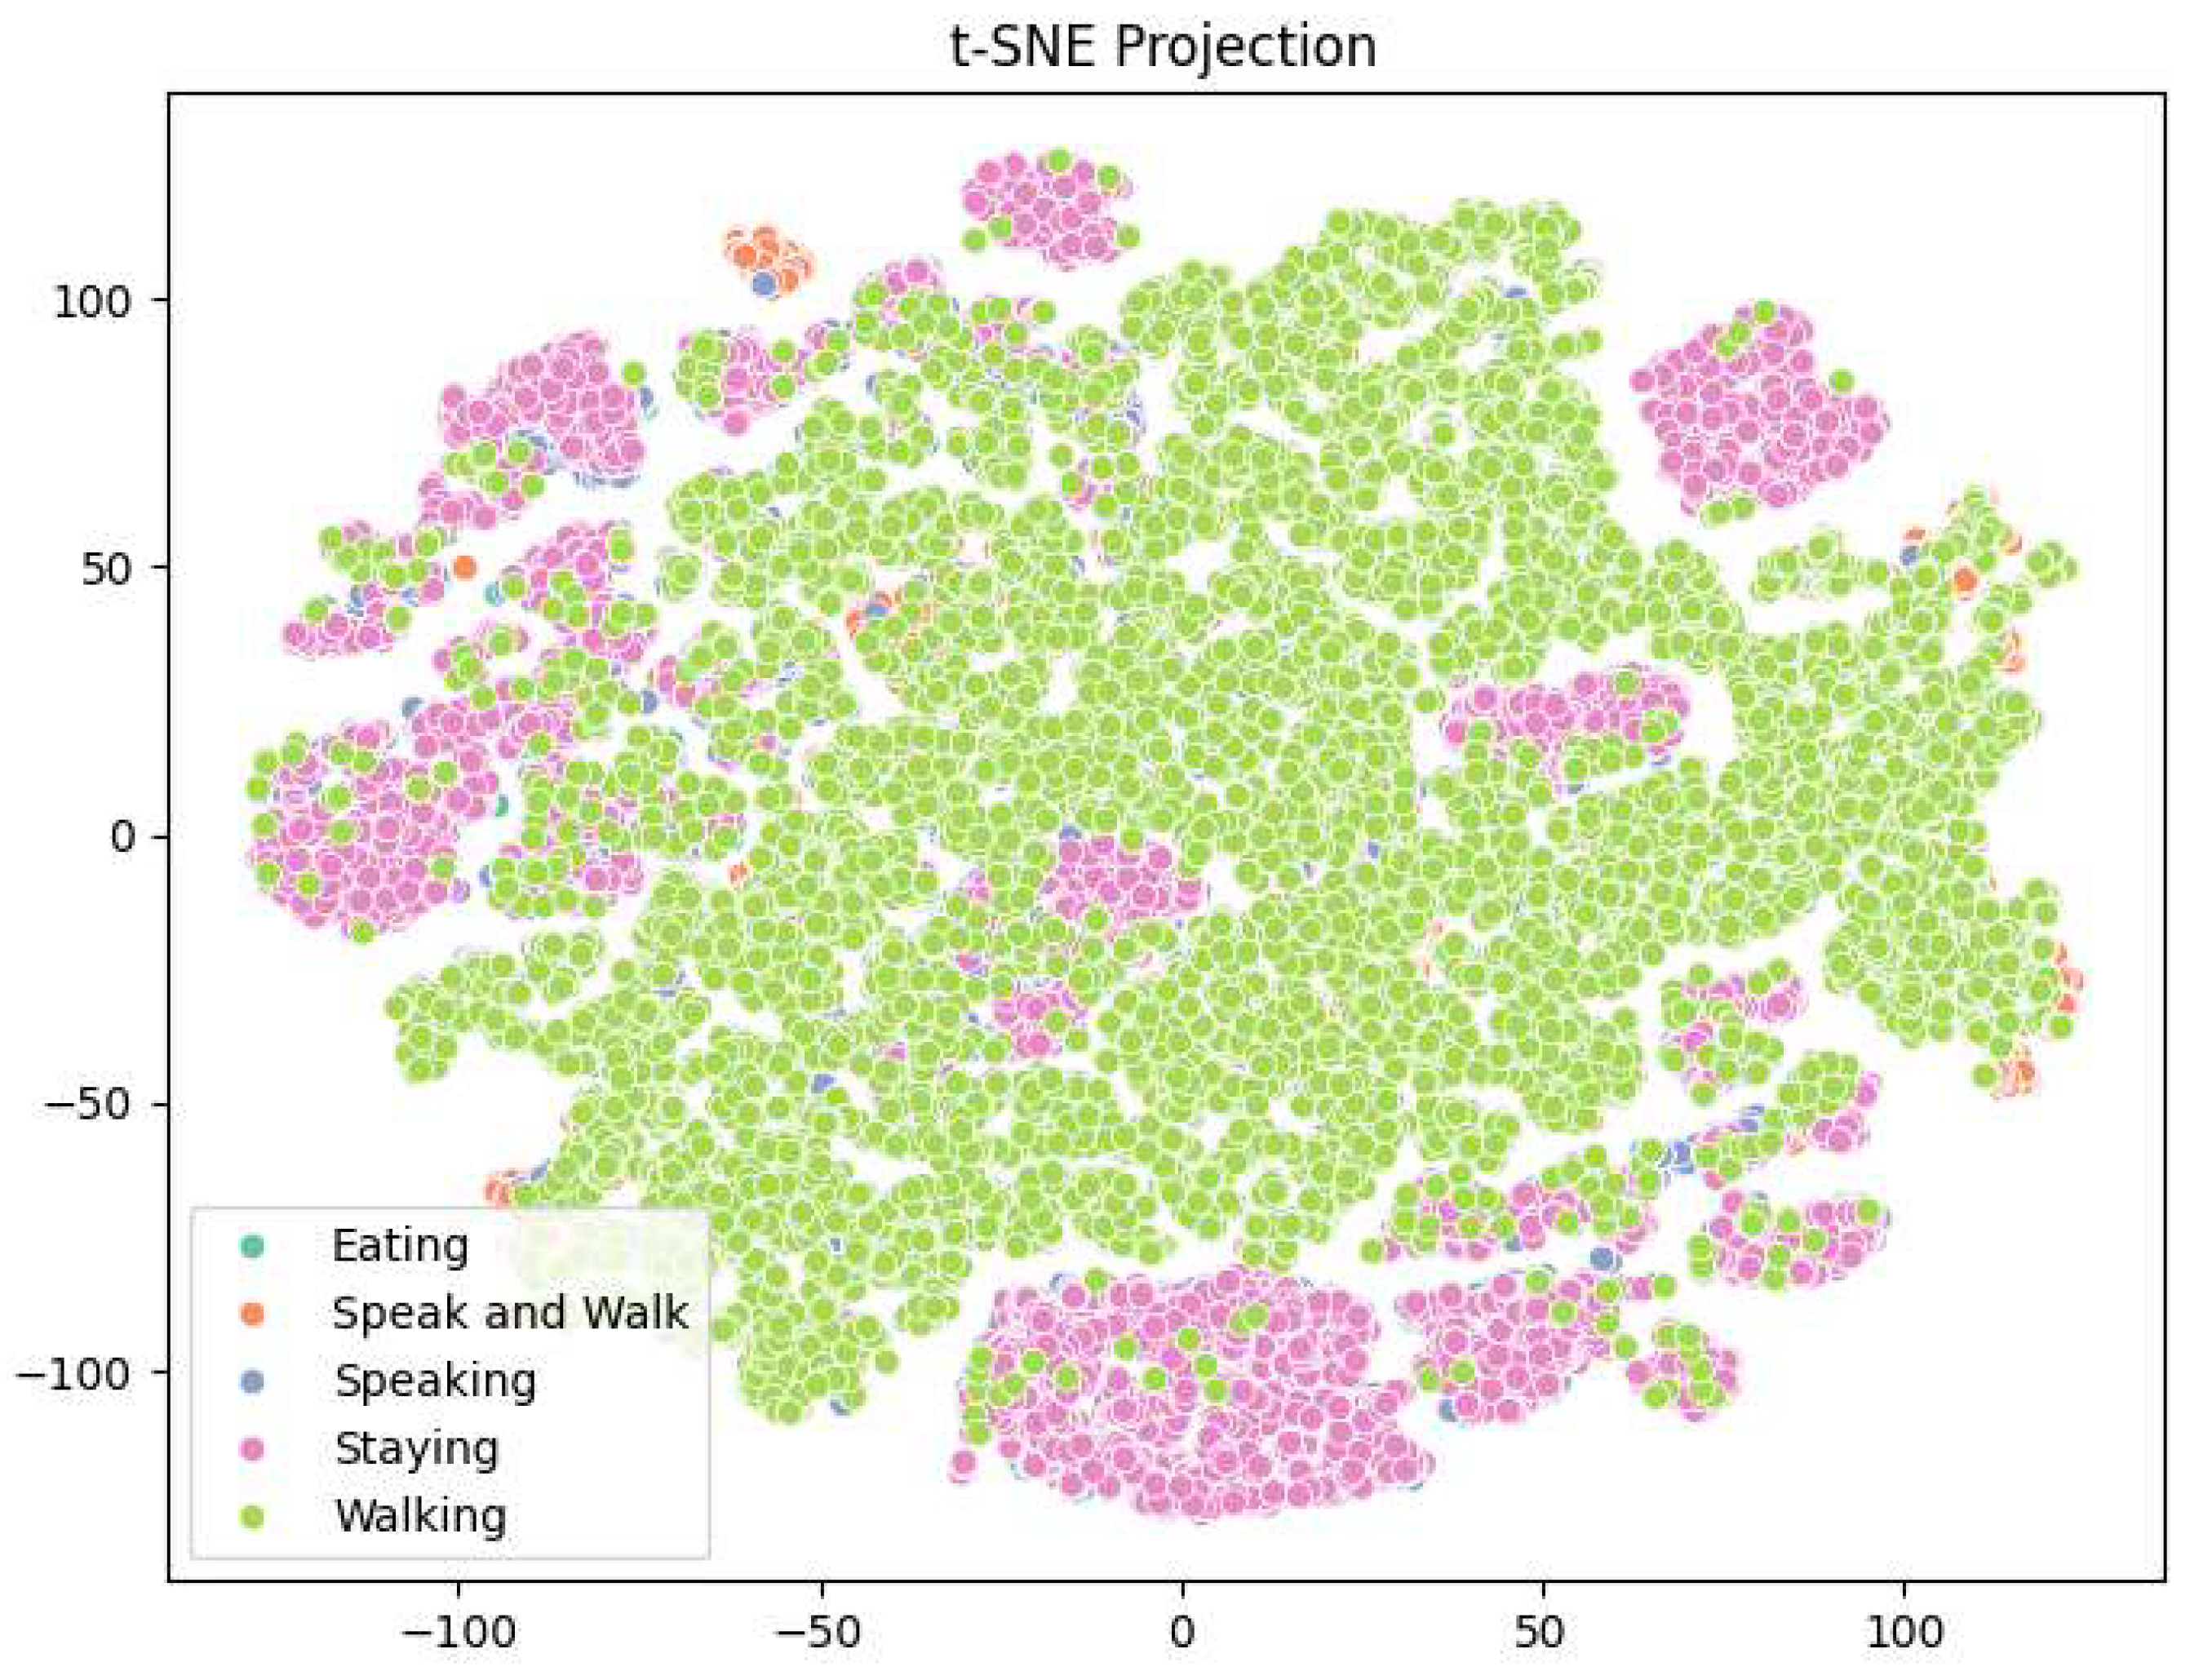
t-SNE Projection of Multimodal Features.
2.2.6. t-SNE Projection
The t-SNE projection provides a two-dimensional embedding of the multimodal feature space, integrating accelerometer and gyroscope data with corresponding visual modality features. Activity classes are color-coded, revealing clear local clustering of Staying and Walking, while activities such as Eating and Speaking appear more interspersed due to their subtle motion signatures. The mixed boundaries emphasize the challenge of distinguishing semi-static behaviors that share overlapping motion dynamics, especially in transitions such as Eating versus Speaking. This visualization highlights the non-linear separability of classes in the raw feature space and underscores the role of MotionXNet’s positional encoding and multi-head temporal attention in disentangling these overlapping clusters for robust classification.
2.3. Model Architecture
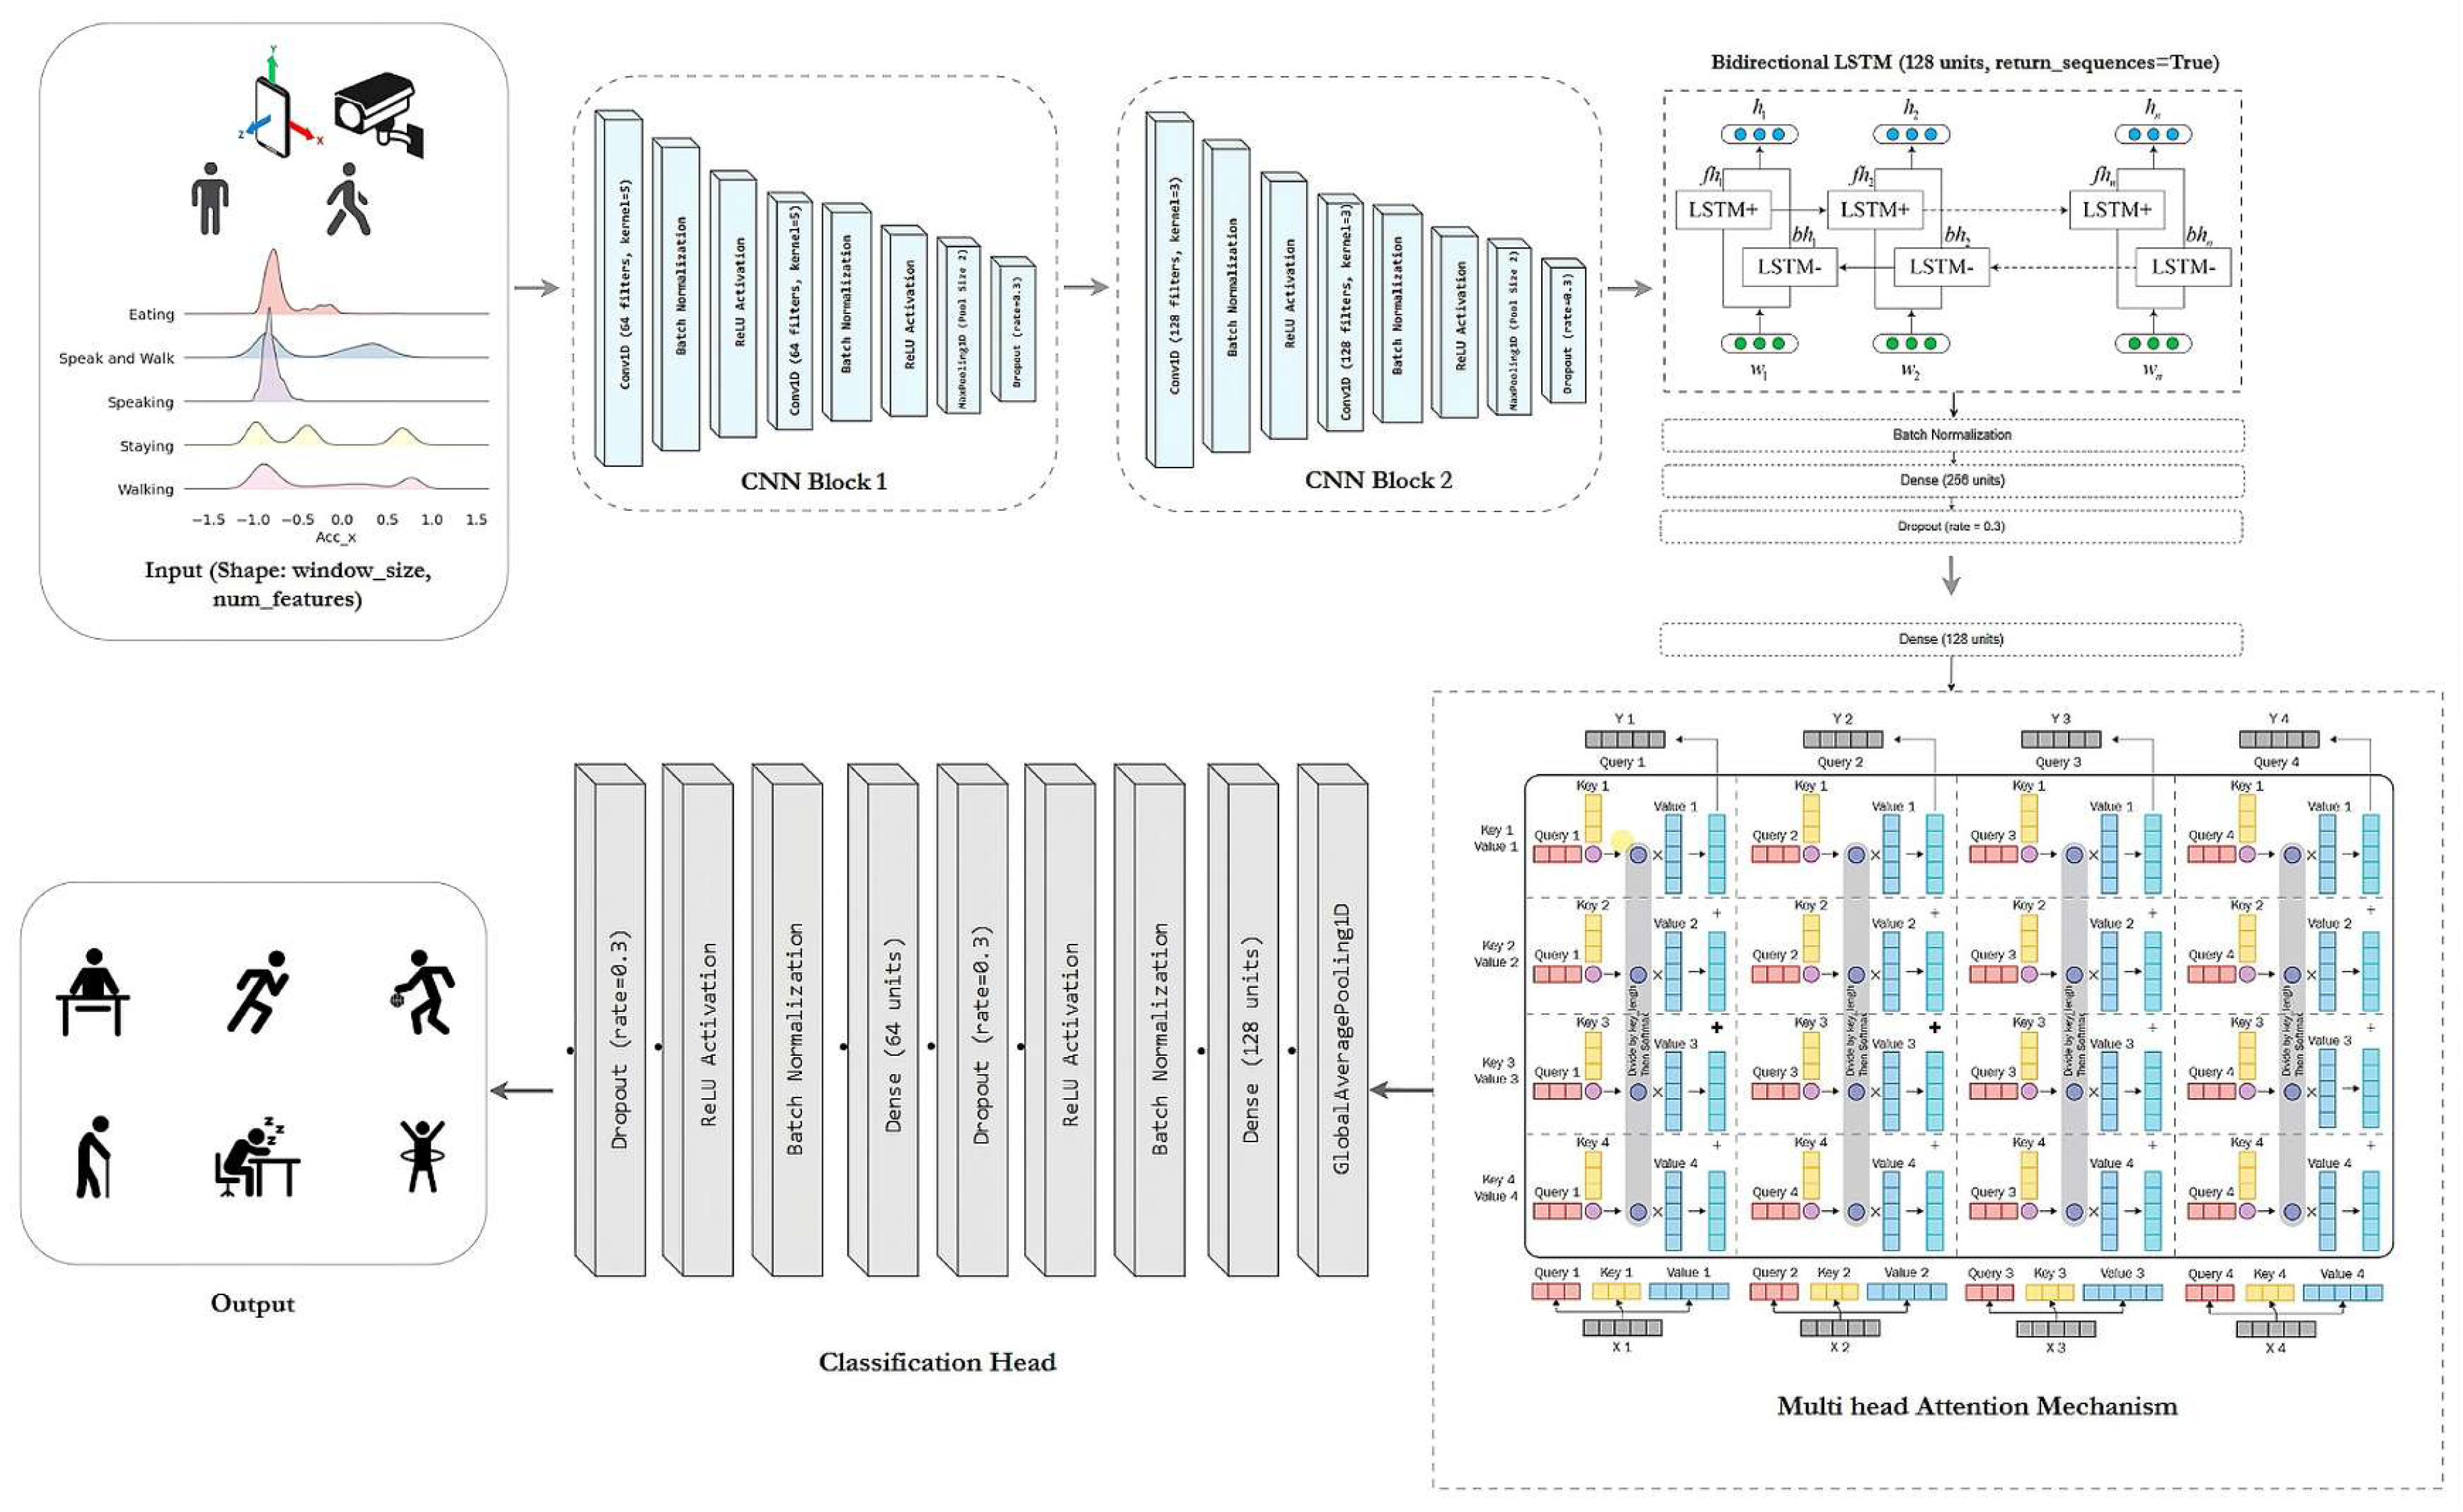
We propose MotionXNet, a hybrid deep learning architecture integrating convolutional, recurrent, and attention-based components with positional encoding. MotionXNet is designed to model multimodal human activity sequences by integrating convolutional, recurrent, and attention-based components. Each stage is carefully designed to extract, encode, and fuse temporal and spatial features from heterogeneous inputs such as image-derived embeddings and accelerometer signals. The model is designed to align and fuse multimodal sequences, while emphasizing fine-grained temporal dependencies. The architecture consists of four main stages:
Figure 8.
Overall Model architecture.
2.3.1. 1D Convolutional Feature Extraction
The first stage employs a 1D convolutional backbone to capture local temporal patterns in the input sequence X. Formally, the operation is defined as:
Here represents the input sequence of length T and feature dimension , which may include embeddings derived from images or raw sensor measurements. Conv1D applies a one-dimensional convolution to capture local dependencies across the temporal dimension. BN denotes batch normalization, which stabilizes and accelerates training by normalizing feature distributions. ReLU introduces non-linearity, enabling the model to learn complex patterns beyond linear correlations. is the output feature map after convolution and non-linearity, where is the number of convolutional filters. This stage emphasizes local, short-term dependencies while producing features suitable for sequential modeling.
2.3.2. Residual BiLSTM Encoding
To capture bidirectional temporal dependencies, a residual BiLSTM encoder is applied to the convolutional features:
Where BiLSTM denotes a bidirectional Long Short-Term Memory network, which processes the sequence in both forward and backward directions to capture past and future context. is the hidden representation from the BiLSTM. is a learnable projection matrix aligning convolutional outputs to the BiLSTM hidden space. LayerNorm stabilizes the summed residual representation, improving convergence. represents the residual-enhanced sequence embedding, combining local and contextual features.
2.3.3. Positional Encoding
Since the attention mechanism is permutation-invariant, we inject explicit positional information using sinusoidal encoding:
Where pos indicates the position index in the sequence. i is the dimension index in the embedding space. is the dimensionality of the model embedding. is the resulting sequence embedding augmented with positional information, which enables the attention mechanism to reason about temporal order.
2.3.4. Multi-Head Temporal Attention
To model long-range dependencies and refine temporal relationships, multi-head attention is applied:
Here h is the number of attention heads. are the query, key, and value matrices for head j, obtained via learnable projections . is the attention output for head j, computed via scaled dot-product attention. Z concatenates all head outputs and projects them with . is the layer-normalized attention-enhanced sequence representation.
2.3.5. Classification Head
The final classification is obtained via global average pooling and a softmax layer:
Where GlobalAveragePooling collapses the temporal dimension, producing a fixed-length representation. W and b are learnable weight and bias matrices for the classification layer. represents the predicted probabilities for C activity classes.
2.3.6. Training Objective
The model is trained using categorical cross-entropy loss:
Where B is the batch size. is the one-hot ground-truth label for sample i. is the predicted probability distribution. penalizes incorrect predictions and guides the model to maximize likelihood of the correct class. This combination of convolutional, residual recurrent, positional, and attention-based processing enables MotionXNet to learn both short-term and long-range dependencies in multimodal human activity sequences effectively.
| Algorithm 1 Training the MotionXNet Model |
|
Require: Training dataset , window length L, initial learning rate , batch size B, number of epochs E Ensure: Trained MotionXNet model M with optimized parameters
|

Table 1.
Notation and symbol definitions for the MotionXNet training algorithm.
| Symbol | Description |
|---|---|
| Training dataset, | |
| Input sequence (sensor or image embeddings) for sample i | |
| Ground truth label for sample i | |
| N | Number of samples in the training dataset |
| L | Window length of the input sequence |
| B | Batch size for training |
| E | Total number of training epochs |
| Trainable parameters of MotionXNet model | |
| Learning rate for the optimizer | |
| Hidden states of the bidirectional LSTM | |
| Residual-enhanced output after BiLSTM and projection | |
| Learnable projection matrix for residual connection | |
| Positional encoding vector for sequence positions | |
| Sequence embedding after adding positional encoding | |
| Query, Key, and Value matrices for attention head j | |
| Output of attention head j after scaled dot-product attention | |
| h | Number of attention heads |
| Dimensionality of each attention head | |
| Z | Concatenated output of all attention heads after linear projection |
| F | Feed-forward network (FFN) output in attention block |
| Output of multi-head attention after layer normalization | |
| Temporally pooled feature vector (global average pooling) | |
| Predicted class probabilities after softmax | |
| Weight and bias parameters of the classification layer | |
| Categorical cross-entropy loss function | |
| Gradient of the loss with respect to model parameters |
2.4. Comparison with State-of-the-Art
We benchmarked MotionXNet against popular HAR models such as SenTAT, DeepConvLSTM, LSTM, BiLSTM, DanHAR, and HART/MobileHART, which cover convolutional, recurrent, and attention-based families.
While BiLSTMs capture bidirectional dependencies effectively, they often struggle to generalize across multimodal inputs. Transformer-based models, such as SenTAT, exploit self-attention but require large datasets and underperform on smaller sensor-driven corpora. MotionXNet bridges this gap by combining residual recurrent pathways with attention-enhanced positional embeddings, improving accuracy, macro F1, and ROC-AUC.
2.5. Ablation Study
An ablation study involves selectively removing components, features, or layers from a model to understand their individual contributions to the model’s overall performance. By observing how performance changes after ablation, researchers can identify essential, redundant, or influential elements, thereby improving model understanding, refinement, and robustness. To evaluate the contribution of each component, we performed an ablation study with six configurations:
Table 2.
Ablation experiment configurations.
| Experiment ID | Architecture | Description |
|---|---|---|
| Exp-00 (Full Model) | CNN + BiLSTM + PE + | Our proposed full architecture, combining CNN feature |
| Multi-Head Attention | extractor, BiLSTM with residual connections, positional | |
| encoding, and multi-head temporal attention. | ||
| Exp-01 (Attention | CNN + BiLSTM + PE only | Evaluates the contribution of multi-head attention by |
| removed) | removing it, while keeping positional encoding intact. | |
| Exp-02 (PE removed) | CNN + BiLSTM + | Assesses the impact of positional encoding by excluding it, |
| Attention only | retaining multi-head attention. | |
| Exp-03 (BiLSTM removed) | CNN + PE + Attention | Tests the importance of temporal recurrent modeling by |
| removing BiLSTM, retaining only CNN features with | ||
| attention. | ||
| Exp-04 (CNN removed) | BiLSTM + PE + Attention | Evaluates the role of CNN feature extraction by removing |
| CNN layers, leaving BiLSTM with positional encoding and | ||
| attention. | ||
| Exp-05 (Alternate | CNN + BiLSTM + GRU | Replaces the Transformer-based attention block with GRU |
| temporal module) | layers to compare standard temporal modeling with our | |
| attention-based module. |
3. Conclusion
This work demonstrates that MotionXNet, when combined with our newly introduced multimodal WBAN dataset, offers a powerful and reliable framework for Human Activity Recognition in complex conditions. By integrating CNN feature extraction, residual BiLSTM encoding, positional embeddings, and multi-head temporal attention, our model captures fine-grained temporal dependencies and achieves superior performance over state-of-the-art baselines. The ablation studies validate the necessity of each architectural component, especially attention and positional encoding for robust sequence alignment. With 96% accuracy, a macro-F1 of 0.96, and ROC-AUC of 0.9986, MotionXNet not only advances the frontier of multimodal HAR but also establishes a practical benchmark for future research in healthcare, behavioral monitoring, and smart environment applications.
References
- O. D. Lara and M. A. Labrador, “A survey on human activity recognition using wearable sensors,” IEEE Communications Surveys & Tutorials, vol. 15, no. 3, pp. 1192–1209, 2013.
- A. Bulling, U. Blanke, and B. Schiele, “A tutorial on human activity recognition using body-worn inertial sensors,” ACM Computing Surveys, vol. 46, no. 3, pp. 1–33, 2014.
- T. Plötz, N. Y. Hammerla, and P. Olivier, “Feature learning for activity recognition in ubiquitous computing,” in Proc. 22nd Int. Joint Conf. on Artificial Intelligence, 2011, pp. 1729–1734.
- D. Anguita, A. Ghio, L. Oneto, X. Parra, and J. L. Reyes-Ortiz, “A public domain dataset for human activity recognition using smartphones,” in Proc. 21st Eur. Symp. on Artificial Neural Networks, Computational Intelligence and Machine Learning, 2013, pp. 437–442.
- H. Wang, A. Klauser, and J. See, “RGB-based human activity recognition: A survey,” Comput. Vision Image Underst., vol. 218, p. 103406, 2022.
- Y. Kong and Y. Fu, “Human action recognition and prediction: A survey,” Int. J. Comput. Vision, vol. 130, pp. 1366–1401, 2022.
- Y. Zhao, F. Chen, X. Jin, and J. Yang, “Privacy-preserving human activity recognition from thermal imaging sensors,” IEEE Internet Things J., vol. 7, no. 9, pp. 8906–8917, 2020.
- H. Ordóñez and D. Roggen, “Deep convolutional and LSTM recurrent neural networks for multimodal wearable activity recognition,” Sensors, vol. 16, no. 1, p. 115, 2016.
- A. Vaswani et al., “Attention is all you need,” in Adv. Neural Inf. Process. Syst., 2017, pp. 5998–6008.
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2025 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (http://creativecommons.org/licenses/by/4.0/).
Copyright: This open access article is published under a Creative Commons CC BY 4.0 license, which permit the free download, distribution, and reuse, provided that the author and preprint are cited in any reuse.